diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/INSTALLER b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/INSTALLER
new file mode 100644
index 0000000000000000000000000000000000000000..a1b589e38a32041e49332e5e81c2d363dc418d68
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/INSTALLER
@@ -0,0 +1 @@
+pip
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/LICENSE b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/LICENSE
new file mode 100644
index 0000000000000000000000000000000000000000..68b7d66c97d66c58de883ed0c451af2b3183e6f3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/LICENSE
@@ -0,0 +1,203 @@
+Copyright 2018- The Hugging Face team. All rights reserved.
+
+ Apache License
+ Version 2.0, January 2004
+ http://www.apache.org/licenses/
+
+ TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
+
+ 1. Definitions.
+
+ "License" shall mean the terms and conditions for use, reproduction,
+ and distribution as defined by Sections 1 through 9 of this document.
+
+ "Licensor" shall mean the copyright owner or entity authorized by
+ the copyright owner that is granting the License.
+
+ "Legal Entity" shall mean the union of the acting entity and all
+ other entities that control, are controlled by, or are under common
+ control with that entity. For the purposes of this definition,
+ "control" means (i) the power, direct or indirect, to cause the
+ direction or management of such entity, whether by contract or
+ otherwise, or (ii) ownership of fifty percent (50%) or more of the
+ outstanding shares, or (iii) beneficial ownership of such entity.
+
+ "You" (or "Your") shall mean an individual or Legal Entity
+ exercising permissions granted by this License.
+
+ "Source" form shall mean the preferred form for making modifications,
+ including but not limited to software source code, documentation
+ source, and configuration files.
+
+ "Object" form shall mean any form resulting from mechanical
+ transformation or translation of a Source form, including but
+ not limited to compiled object code, generated documentation,
+ and conversions to other media types.
+
+ "Work" shall mean the work of authorship, whether in Source or
+ Object form, made available under the License, as indicated by a
+ copyright notice that is included in or attached to the work
+ (an example is provided in the Appendix below).
+
+ "Derivative Works" shall mean any work, whether in Source or Object
+ form, that is based on (or derived from) the Work and for which the
+ editorial revisions, annotations, elaborations, or other modifications
+ represent, as a whole, an original work of authorship. For the purposes
+ of this License, Derivative Works shall not include works that remain
+ separable from, or merely link (or bind by name) to the interfaces of,
+ the Work and Derivative Works thereof.
+
+ "Contribution" shall mean any work of authorship, including
+ the original version of the Work and any modifications or additions
+ to that Work or Derivative Works thereof, that is intentionally
+ submitted to Licensor for inclusion in the Work by the copyright owner
+ or by an individual or Legal Entity authorized to submit on behalf of
+ the copyright owner. For the purposes of this definition, "submitted"
+ means any form of electronic, verbal, or written communication sent
+ to the Licensor or its representatives, including but not limited to
+ communication on electronic mailing lists, source code control systems,
+ and issue tracking systems that are managed by, or on behalf of, the
+ Licensor for the purpose of discussing and improving the Work, but
+ excluding communication that is conspicuously marked or otherwise
+ designated in writing by the copyright owner as "Not a Contribution."
+
+ "Contributor" shall mean Licensor and any individual or Legal Entity
+ on behalf of whom a Contribution has been received by Licensor and
+ subsequently incorporated within the Work.
+
+ 2. Grant of Copyright License. Subject to the terms and conditions of
+ this License, each Contributor hereby grants to You a perpetual,
+ worldwide, non-exclusive, no-charge, royalty-free, irrevocable
+ copyright license to reproduce, prepare Derivative Works of,
+ publicly display, publicly perform, sublicense, and distribute the
+ Work and such Derivative Works in Source or Object form.
+
+ 3. Grant of Patent License. Subject to the terms and conditions of
+ this License, each Contributor hereby grants to You a perpetual,
+ worldwide, non-exclusive, no-charge, royalty-free, irrevocable
+ (except as stated in this section) patent license to make, have made,
+ use, offer to sell, sell, import, and otherwise transfer the Work,
+ where such license applies only to those patent claims licensable
+ by such Contributor that are necessarily infringed by their
+ Contribution(s) alone or by combination of their Contribution(s)
+ with the Work to which such Contribution(s) was submitted. If You
+ institute patent litigation against any entity (including a
+ cross-claim or counterclaim in a lawsuit) alleging that the Work
+ or a Contribution incorporated within the Work constitutes direct
+ or contributory patent infringement, then any patent licenses
+ granted to You under this License for that Work shall terminate
+ as of the date such litigation is filed.
+
+ 4. Redistribution. You may reproduce and distribute copies of the
+ Work or Derivative Works thereof in any medium, with or without
+ modifications, and in Source or Object form, provided that You
+ meet the following conditions:
+
+ (a) You must give any other recipients of the Work or
+ Derivative Works a copy of this License; and
+
+ (b) You must cause any modified files to carry prominent notices
+ stating that You changed the files; and
+
+ (c) You must retain, in the Source form of any Derivative Works
+ that You distribute, all copyright, patent, trademark, and
+ attribution notices from the Source form of the Work,
+ excluding those notices that do not pertain to any part of
+ the Derivative Works; and
+
+ (d) If the Work includes a "NOTICE" text file as part of its
+ distribution, then any Derivative Works that You distribute must
+ include a readable copy of the attribution notices contained
+ within such NOTICE file, excluding those notices that do not
+ pertain to any part of the Derivative Works, in at least one
+ of the following places: within a NOTICE text file distributed
+ as part of the Derivative Works; within the Source form or
+ documentation, if provided along with the Derivative Works; or,
+ within a display generated by the Derivative Works, if and
+ wherever such third-party notices normally appear. The contents
+ of the NOTICE file are for informational purposes only and
+ do not modify the License. You may add Your own attribution
+ notices within Derivative Works that You distribute, alongside
+ or as an addendum to the NOTICE text from the Work, provided
+ that such additional attribution notices cannot be construed
+ as modifying the License.
+
+ You may add Your own copyright statement to Your modifications and
+ may provide additional or different license terms and conditions
+ for use, reproduction, or distribution of Your modifications, or
+ for any such Derivative Works as a whole, provided Your use,
+ reproduction, and distribution of the Work otherwise complies with
+ the conditions stated in this License.
+
+ 5. Submission of Contributions. Unless You explicitly state otherwise,
+ any Contribution intentionally submitted for inclusion in the Work
+ by You to the Licensor shall be under the terms and conditions of
+ this License, without any additional terms or conditions.
+ Notwithstanding the above, nothing herein shall supersede or modify
+ the terms of any separate license agreement you may have executed
+ with Licensor regarding such Contributions.
+
+ 6. Trademarks. This License does not grant permission to use the trade
+ names, trademarks, service marks, or product names of the Licensor,
+ except as required for reasonable and customary use in describing the
+ origin of the Work and reproducing the content of the NOTICE file.
+
+ 7. Disclaimer of Warranty. Unless required by applicable law or
+ agreed to in writing, Licensor provides the Work (and each
+ Contributor provides its Contributions) on an "AS IS" BASIS,
+ WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
+ implied, including, without limitation, any warranties or conditions
+ of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
+ PARTICULAR PURPOSE. You are solely responsible for determining the
+ appropriateness of using or redistributing the Work and assume any
+ risks associated with Your exercise of permissions under this License.
+
+ 8. Limitation of Liability. In no event and under no legal theory,
+ whether in tort (including negligence), contract, or otherwise,
+ unless required by applicable law (such as deliberate and grossly
+ negligent acts) or agreed to in writing, shall any Contributor be
+ liable to You for damages, including any direct, indirect, special,
+ incidental, or consequential damages of any character arising as a
+ result of this License or out of the use or inability to use the
+ Work (including but not limited to damages for loss of goodwill,
+ work stoppage, computer failure or malfunction, or any and all
+ other commercial damages or losses), even if such Contributor
+ has been advised of the possibility of such damages.
+
+ 9. Accepting Warranty or Additional Liability. While redistributing
+ the Work or Derivative Works thereof, You may choose to offer,
+ and charge a fee for, acceptance of support, warranty, indemnity,
+ or other liability obligations and/or rights consistent with this
+ License. However, in accepting such obligations, You may act only
+ on Your own behalf and on Your sole responsibility, not on behalf
+ of any other Contributor, and only if You agree to indemnify,
+ defend, and hold each Contributor harmless for any liability
+ incurred by, or claims asserted against, such Contributor by reason
+ of your accepting any such warranty or additional liability.
+
+ END OF TERMS AND CONDITIONS
+
+ APPENDIX: How to apply the Apache License to your work.
+
+ To apply the Apache License to your work, attach the following
+ boilerplate notice, with the fields enclosed by brackets "[]"
+ replaced with your own identifying information. (Don't include
+ the brackets!) The text should be enclosed in the appropriate
+ comment syntax for the file format. We also recommend that a
+ file or class name and description of purpose be included on the
+ same "printed page" as the copyright notice for easier
+ identification within third-party archives.
+
+ Copyright [yyyy] [name of copyright owner]
+
+ Licensed under the Apache License, Version 2.0 (the "License");
+ you may not use this file except in compliance with the License.
+ You may obtain a copy of the License at
+
+ http://www.apache.org/licenses/LICENSE-2.0
+
+ Unless required by applicable law or agreed to in writing, software
+ distributed under the License is distributed on an "AS IS" BASIS,
+ WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+ See the License for the specific language governing permissions and
+ limitations under the License.
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/METADATA b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/METADATA
new file mode 100644
index 0000000000000000000000000000000000000000..cda2ef3420f757e927f863278c00ccc1a40af205
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/METADATA
@@ -0,0 +1,805 @@
+Metadata-Version: 2.1
+Name: transformers
+Version: 4.56.2
+Summary: State-of-the-art Machine Learning for JAX, PyTorch and TensorFlow
+Home-page: https://github.com/huggingface/transformers
+Author: The Hugging Face team (past and future) with the help of all our contributors (https://github.com/huggingface/transformers/graphs/contributors)
+Author-email: transformers@huggingface.co
+License: Apache 2.0 License
+Keywords: NLP vision speech deep learning transformer pytorch tensorflow jax BERT GPT-2 Wav2Vec2 ViT
+Classifier: Development Status :: 5 - Production/Stable
+Classifier: Intended Audience :: Developers
+Classifier: Intended Audience :: Education
+Classifier: Intended Audience :: Science/Research
+Classifier: License :: OSI Approved :: Apache Software License
+Classifier: Operating System :: OS Independent
+Classifier: Programming Language :: Python :: 3
+Classifier: Programming Language :: Python :: 3.9
+Classifier: Programming Language :: Python :: 3.10
+Classifier: Programming Language :: Python :: 3.11
+Classifier: Programming Language :: Python :: 3.12
+Classifier: Programming Language :: Python :: 3.13
+Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
+Requires-Python: >=3.9.0
+Description-Content-Type: text/markdown
+License-File: LICENSE
+Requires-Dist: filelock
+Requires-Dist: huggingface-hub<1.0,>=0.34.0
+Requires-Dist: numpy>=1.17
+Requires-Dist: packaging>=20.0
+Requires-Dist: pyyaml>=5.1
+Requires-Dist: regex!=2019.12.17
+Requires-Dist: requests
+Requires-Dist: tokenizers<=0.23.0,>=0.22.0
+Requires-Dist: safetensors>=0.4.3
+Requires-Dist: tqdm>=4.27
+Provides-Extra: accelerate
+Requires-Dist: accelerate>=0.26.0; extra == "accelerate"
+Provides-Extra: all
+Requires-Dist: tensorflow<2.16,>2.9; extra == "all"
+Requires-Dist: onnxconverter-common; extra == "all"
+Requires-Dist: tf2onnx; extra == "all"
+Requires-Dist: tensorflow-text<2.16; extra == "all"
+Requires-Dist: keras-nlp<0.14.0,>=0.3.1; extra == "all"
+Requires-Dist: torch>=2.2; extra == "all"
+Requires-Dist: accelerate>=0.26.0; extra == "all"
+Requires-Dist: jax<=0.4.13,>=0.4.1; extra == "all"
+Requires-Dist: jaxlib<=0.4.13,>=0.4.1; extra == "all"
+Requires-Dist: flax<=0.7.0,>=0.4.1; extra == "all"
+Requires-Dist: optax<=0.1.4,>=0.0.8; extra == "all"
+Requires-Dist: scipy<1.13.0; extra == "all"
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "all"
+Requires-Dist: protobuf; extra == "all"
+Requires-Dist: tokenizers<=0.23.0,>=0.22.0; extra == "all"
+Requires-Dist: torchaudio; extra == "all"
+Requires-Dist: librosa; extra == "all"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "all"
+Requires-Dist: phonemizer; extra == "all"
+Requires-Dist: kenlm; extra == "all"
+Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "all"
+Requires-Dist: kernels<=0.9,>=0.6.1; extra == "all"
+Requires-Dist: optuna; extra == "all"
+Requires-Dist: ray[tune]>=2.7.0; extra == "all"
+Requires-Dist: sigopt; extra == "all"
+Requires-Dist: timm!=1.0.18,<=1.0.19; extra == "all"
+Requires-Dist: torchvision; extra == "all"
+Requires-Dist: codecarbon>=2.8.1; extra == "all"
+Requires-Dist: av; extra == "all"
+Requires-Dist: num2words; extra == "all"
+Requires-Dist: mistral-common[opencv]>=1.6.3; extra == "all"
+Requires-Dist: jinja2>=3.1.0; extra == "all"
+Provides-Extra: audio
+Requires-Dist: librosa; extra == "audio"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "audio"
+Requires-Dist: phonemizer; extra == "audio"
+Requires-Dist: kenlm; extra == "audio"
+Provides-Extra: benchmark
+Requires-Dist: optimum-benchmark>=0.3.0; extra == "benchmark"
+Provides-Extra: chat_template
+Requires-Dist: jinja2>=3.1.0; extra == "chat-template"
+Provides-Extra: codecarbon
+Requires-Dist: codecarbon>=2.8.1; extra == "codecarbon"
+Provides-Extra: deepspeed
+Requires-Dist: deepspeed>=0.9.3; extra == "deepspeed"
+Requires-Dist: accelerate>=0.26.0; extra == "deepspeed"
+Provides-Extra: deepspeed-testing
+Requires-Dist: deepspeed>=0.9.3; extra == "deepspeed-testing"
+Requires-Dist: accelerate>=0.26.0; extra == "deepspeed-testing"
+Requires-Dist: pytest>=7.2.0; extra == "deepspeed-testing"
+Requires-Dist: pytest-asyncio; extra == "deepspeed-testing"
+Requires-Dist: pytest-rich; extra == "deepspeed-testing"
+Requires-Dist: pytest-xdist; extra == "deepspeed-testing"
+Requires-Dist: pytest-order; extra == "deepspeed-testing"
+Requires-Dist: pytest-rerunfailures; extra == "deepspeed-testing"
+Requires-Dist: timeout-decorator; extra == "deepspeed-testing"
+Requires-Dist: parameterized>=0.9; extra == "deepspeed-testing"
+Requires-Dist: psutil; extra == "deepspeed-testing"
+Requires-Dist: datasets>=2.15.0; extra == "deepspeed-testing"
+Requires-Dist: dill<0.3.5; extra == "deepspeed-testing"
+Requires-Dist: evaluate>=0.2.0; extra == "deepspeed-testing"
+Requires-Dist: pytest-timeout; extra == "deepspeed-testing"
+Requires-Dist: ruff==0.11.2; extra == "deepspeed-testing"
+Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "deepspeed-testing"
+Requires-Dist: nltk<=3.8.1; extra == "deepspeed-testing"
+Requires-Dist: GitPython<3.1.19; extra == "deepspeed-testing"
+Requires-Dist: sacremoses; extra == "deepspeed-testing"
+Requires-Dist: rjieba; extra == "deepspeed-testing"
+Requires-Dist: beautifulsoup4; extra == "deepspeed-testing"
+Requires-Dist: tensorboard; extra == "deepspeed-testing"
+Requires-Dist: pydantic>=2; extra == "deepspeed-testing"
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "deepspeed-testing"
+Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "deepspeed-testing"
+Requires-Dist: libcst; extra == "deepspeed-testing"
+Requires-Dist: faiss-cpu; extra == "deepspeed-testing"
+Requires-Dist: cookiecutter==1.7.3; extra == "deepspeed-testing"
+Requires-Dist: mistral-common[opencv]>=1.6.3; extra == "deepspeed-testing"
+Requires-Dist: optuna; extra == "deepspeed-testing"
+Requires-Dist: protobuf; extra == "deepspeed-testing"
+Provides-Extra: dev
+Requires-Dist: tensorflow<2.16,>2.9; extra == "dev"
+Requires-Dist: onnxconverter-common; extra == "dev"
+Requires-Dist: tf2onnx; extra == "dev"
+Requires-Dist: tensorflow-text<2.16; extra == "dev"
+Requires-Dist: keras-nlp<0.14.0,>=0.3.1; extra == "dev"
+Requires-Dist: torch>=2.2; extra == "dev"
+Requires-Dist: accelerate>=0.26.0; extra == "dev"
+Requires-Dist: jax<=0.4.13,>=0.4.1; extra == "dev"
+Requires-Dist: jaxlib<=0.4.13,>=0.4.1; extra == "dev"
+Requires-Dist: flax<=0.7.0,>=0.4.1; extra == "dev"
+Requires-Dist: optax<=0.1.4,>=0.0.8; extra == "dev"
+Requires-Dist: scipy<1.13.0; extra == "dev"
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "dev"
+Requires-Dist: protobuf; extra == "dev"
+Requires-Dist: tokenizers<=0.23.0,>=0.22.0; extra == "dev"
+Requires-Dist: torchaudio; extra == "dev"
+Requires-Dist: librosa; extra == "dev"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "dev"
+Requires-Dist: phonemizer; extra == "dev"
+Requires-Dist: kenlm; extra == "dev"
+Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "dev"
+Requires-Dist: kernels<=0.9,>=0.6.1; extra == "dev"
+Requires-Dist: optuna; extra == "dev"
+Requires-Dist: ray[tune]>=2.7.0; extra == "dev"
+Requires-Dist: sigopt; extra == "dev"
+Requires-Dist: timm!=1.0.18,<=1.0.19; extra == "dev"
+Requires-Dist: torchvision; extra == "dev"
+Requires-Dist: codecarbon>=2.8.1; extra == "dev"
+Requires-Dist: av; extra == "dev"
+Requires-Dist: num2words; extra == "dev"
+Requires-Dist: mistral-common[opencv]>=1.6.3; extra == "dev"
+Requires-Dist: jinja2>=3.1.0; extra == "dev"
+Requires-Dist: pytest>=7.2.0; extra == "dev"
+Requires-Dist: pytest-asyncio; extra == "dev"
+Requires-Dist: pytest-rich; extra == "dev"
+Requires-Dist: pytest-xdist; extra == "dev"
+Requires-Dist: pytest-order; extra == "dev"
+Requires-Dist: pytest-rerunfailures; extra == "dev"
+Requires-Dist: timeout-decorator; extra == "dev"
+Requires-Dist: parameterized>=0.9; extra == "dev"
+Requires-Dist: psutil; extra == "dev"
+Requires-Dist: datasets>=2.15.0; extra == "dev"
+Requires-Dist: dill<0.3.5; extra == "dev"
+Requires-Dist: evaluate>=0.2.0; extra == "dev"
+Requires-Dist: pytest-timeout; extra == "dev"
+Requires-Dist: ruff==0.11.2; extra == "dev"
+Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "dev"
+Requires-Dist: nltk<=3.8.1; extra == "dev"
+Requires-Dist: GitPython<3.1.19; extra == "dev"
+Requires-Dist: sacremoses; extra == "dev"
+Requires-Dist: rjieba; extra == "dev"
+Requires-Dist: beautifulsoup4; extra == "dev"
+Requires-Dist: tensorboard; extra == "dev"
+Requires-Dist: pydantic>=2; extra == "dev"
+Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "dev"
+Requires-Dist: libcst; extra == "dev"
+Requires-Dist: faiss-cpu; extra == "dev"
+Requires-Dist: cookiecutter==1.7.3; extra == "dev"
+Requires-Dist: urllib3<2.0.0; extra == "dev"
+Requires-Dist: rich; extra == "dev"
+Requires-Dist: pandas<2.3.0; extra == "dev"
+Requires-Dist: fugashi>=1.0; extra == "dev"
+Requires-Dist: ipadic<2.0,>=1.0.0; extra == "dev"
+Requires-Dist: unidic-lite>=1.0.7; extra == "dev"
+Requires-Dist: unidic>=1.0.2; extra == "dev"
+Requires-Dist: sudachipy>=0.6.6; extra == "dev"
+Requires-Dist: sudachidict-core>=20220729; extra == "dev"
+Requires-Dist: rhoknp<1.3.1,>=1.1.0; extra == "dev"
+Requires-Dist: scikit-learn; extra == "dev"
+Provides-Extra: dev-tensorflow
+Requires-Dist: pytest>=7.2.0; extra == "dev-tensorflow"
+Requires-Dist: pytest-asyncio; extra == "dev-tensorflow"
+Requires-Dist: pytest-rich; extra == "dev-tensorflow"
+Requires-Dist: pytest-xdist; extra == "dev-tensorflow"
+Requires-Dist: pytest-order; extra == "dev-tensorflow"
+Requires-Dist: pytest-rerunfailures; extra == "dev-tensorflow"
+Requires-Dist: timeout-decorator; extra == "dev-tensorflow"
+Requires-Dist: parameterized>=0.9; extra == "dev-tensorflow"
+Requires-Dist: psutil; extra == "dev-tensorflow"
+Requires-Dist: datasets>=2.15.0; extra == "dev-tensorflow"
+Requires-Dist: dill<0.3.5; extra == "dev-tensorflow"
+Requires-Dist: evaluate>=0.2.0; extra == "dev-tensorflow"
+Requires-Dist: pytest-timeout; extra == "dev-tensorflow"
+Requires-Dist: ruff==0.11.2; extra == "dev-tensorflow"
+Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "dev-tensorflow"
+Requires-Dist: nltk<=3.8.1; extra == "dev-tensorflow"
+Requires-Dist: GitPython<3.1.19; extra == "dev-tensorflow"
+Requires-Dist: sacremoses; extra == "dev-tensorflow"
+Requires-Dist: rjieba; extra == "dev-tensorflow"
+Requires-Dist: beautifulsoup4; extra == "dev-tensorflow"
+Requires-Dist: tensorboard; extra == "dev-tensorflow"
+Requires-Dist: pydantic>=2; extra == "dev-tensorflow"
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "dev-tensorflow"
+Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "dev-tensorflow"
+Requires-Dist: libcst; extra == "dev-tensorflow"
+Requires-Dist: faiss-cpu; extra == "dev-tensorflow"
+Requires-Dist: cookiecutter==1.7.3; extra == "dev-tensorflow"
+Requires-Dist: mistral-common[opencv]>=1.6.3; extra == "dev-tensorflow"
+Requires-Dist: tensorflow<2.16,>2.9; extra == "dev-tensorflow"
+Requires-Dist: onnxconverter-common; extra == "dev-tensorflow"
+Requires-Dist: tf2onnx; extra == "dev-tensorflow"
+Requires-Dist: tensorflow-text<2.16; extra == "dev-tensorflow"
+Requires-Dist: keras-nlp<0.14.0,>=0.3.1; extra == "dev-tensorflow"
+Requires-Dist: protobuf; extra == "dev-tensorflow"
+Requires-Dist: tokenizers<=0.23.0,>=0.22.0; extra == "dev-tensorflow"
+Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "dev-tensorflow"
+Requires-Dist: urllib3<2.0.0; extra == "dev-tensorflow"
+Requires-Dist: rich; extra == "dev-tensorflow"
+Requires-Dist: pandas<2.3.0; extra == "dev-tensorflow"
+Requires-Dist: scikit-learn; extra == "dev-tensorflow"
+Requires-Dist: onnxruntime>=1.4.0; extra == "dev-tensorflow"
+Requires-Dist: onnxruntime-tools>=1.4.2; extra == "dev-tensorflow"
+Requires-Dist: librosa; extra == "dev-tensorflow"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "dev-tensorflow"
+Requires-Dist: phonemizer; extra == "dev-tensorflow"
+Requires-Dist: kenlm; extra == "dev-tensorflow"
+Provides-Extra: dev-torch
+Requires-Dist: pytest>=7.2.0; extra == "dev-torch"
+Requires-Dist: pytest-asyncio; extra == "dev-torch"
+Requires-Dist: pytest-rich; extra == "dev-torch"
+Requires-Dist: pytest-xdist; extra == "dev-torch"
+Requires-Dist: pytest-order; extra == "dev-torch"
+Requires-Dist: pytest-rerunfailures; extra == "dev-torch"
+Requires-Dist: timeout-decorator; extra == "dev-torch"
+Requires-Dist: parameterized>=0.9; extra == "dev-torch"
+Requires-Dist: psutil; extra == "dev-torch"
+Requires-Dist: datasets>=2.15.0; extra == "dev-torch"
+Requires-Dist: dill<0.3.5; extra == "dev-torch"
+Requires-Dist: evaluate>=0.2.0; extra == "dev-torch"
+Requires-Dist: pytest-timeout; extra == "dev-torch"
+Requires-Dist: ruff==0.11.2; extra == "dev-torch"
+Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "dev-torch"
+Requires-Dist: nltk<=3.8.1; extra == "dev-torch"
+Requires-Dist: GitPython<3.1.19; extra == "dev-torch"
+Requires-Dist: sacremoses; extra == "dev-torch"
+Requires-Dist: rjieba; extra == "dev-torch"
+Requires-Dist: beautifulsoup4; extra == "dev-torch"
+Requires-Dist: tensorboard; extra == "dev-torch"
+Requires-Dist: pydantic>=2; extra == "dev-torch"
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "dev-torch"
+Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "dev-torch"
+Requires-Dist: libcst; extra == "dev-torch"
+Requires-Dist: faiss-cpu; extra == "dev-torch"
+Requires-Dist: cookiecutter==1.7.3; extra == "dev-torch"
+Requires-Dist: mistral-common[opencv]>=1.6.3; extra == "dev-torch"
+Requires-Dist: torch>=2.2; extra == "dev-torch"
+Requires-Dist: accelerate>=0.26.0; extra == "dev-torch"
+Requires-Dist: protobuf; extra == "dev-torch"
+Requires-Dist: tokenizers<=0.23.0,>=0.22.0; extra == "dev-torch"
+Requires-Dist: torchaudio; extra == "dev-torch"
+Requires-Dist: librosa; extra == "dev-torch"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "dev-torch"
+Requires-Dist: phonemizer; extra == "dev-torch"
+Requires-Dist: kenlm; extra == "dev-torch"
+Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "dev-torch"
+Requires-Dist: kernels<=0.9,>=0.6.1; extra == "dev-torch"
+Requires-Dist: optuna; extra == "dev-torch"
+Requires-Dist: ray[tune]>=2.7.0; extra == "dev-torch"
+Requires-Dist: sigopt; extra == "dev-torch"
+Requires-Dist: timm!=1.0.18,<=1.0.19; extra == "dev-torch"
+Requires-Dist: torchvision; extra == "dev-torch"
+Requires-Dist: codecarbon>=2.8.1; extra == "dev-torch"
+Requires-Dist: urllib3<2.0.0; extra == "dev-torch"
+Requires-Dist: rich; extra == "dev-torch"
+Requires-Dist: pandas<2.3.0; extra == "dev-torch"
+Requires-Dist: fugashi>=1.0; extra == "dev-torch"
+Requires-Dist: ipadic<2.0,>=1.0.0; extra == "dev-torch"
+Requires-Dist: unidic-lite>=1.0.7; extra == "dev-torch"
+Requires-Dist: unidic>=1.0.2; extra == "dev-torch"
+Requires-Dist: sudachipy>=0.6.6; extra == "dev-torch"
+Requires-Dist: sudachidict-core>=20220729; extra == "dev-torch"
+Requires-Dist: rhoknp<1.3.1,>=1.1.0; extra == "dev-torch"
+Requires-Dist: scikit-learn; extra == "dev-torch"
+Requires-Dist: onnxruntime>=1.4.0; extra == "dev-torch"
+Requires-Dist: onnxruntime-tools>=1.4.2; extra == "dev-torch"
+Requires-Dist: num2words; extra == "dev-torch"
+Provides-Extra: flax
+Requires-Dist: jax<=0.4.13,>=0.4.1; extra == "flax"
+Requires-Dist: jaxlib<=0.4.13,>=0.4.1; extra == "flax"
+Requires-Dist: flax<=0.7.0,>=0.4.1; extra == "flax"
+Requires-Dist: optax<=0.1.4,>=0.0.8; extra == "flax"
+Requires-Dist: scipy<1.13.0; extra == "flax"
+Provides-Extra: flax-speech
+Requires-Dist: librosa; extra == "flax-speech"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "flax-speech"
+Requires-Dist: phonemizer; extra == "flax-speech"
+Requires-Dist: kenlm; extra == "flax-speech"
+Provides-Extra: ftfy
+Requires-Dist: ftfy; extra == "ftfy"
+Provides-Extra: hf_xet
+Requires-Dist: hf-xet; extra == "hf-xet"
+Provides-Extra: hub-kernels
+Requires-Dist: kernels<=0.9,>=0.6.1; extra == "hub-kernels"
+Provides-Extra: integrations
+Requires-Dist: kernels<=0.9,>=0.6.1; extra == "integrations"
+Requires-Dist: optuna; extra == "integrations"
+Requires-Dist: ray[tune]>=2.7.0; extra == "integrations"
+Requires-Dist: sigopt; extra == "integrations"
+Provides-Extra: ja
+Requires-Dist: fugashi>=1.0; extra == "ja"
+Requires-Dist: ipadic<2.0,>=1.0.0; extra == "ja"
+Requires-Dist: unidic-lite>=1.0.7; extra == "ja"
+Requires-Dist: unidic>=1.0.2; extra == "ja"
+Requires-Dist: sudachipy>=0.6.6; extra == "ja"
+Requires-Dist: sudachidict-core>=20220729; extra == "ja"
+Requires-Dist: rhoknp<1.3.1,>=1.1.0; extra == "ja"
+Provides-Extra: mistral-common
+Requires-Dist: mistral-common[opencv]>=1.6.3; extra == "mistral-common"
+Provides-Extra: modelcreation
+Requires-Dist: cookiecutter==1.7.3; extra == "modelcreation"
+Provides-Extra: natten
+Requires-Dist: natten<0.15.0,>=0.14.6; extra == "natten"
+Provides-Extra: num2words
+Requires-Dist: num2words; extra == "num2words"
+Provides-Extra: onnx
+Requires-Dist: onnxconverter-common; extra == "onnx"
+Requires-Dist: tf2onnx; extra == "onnx"
+Requires-Dist: onnxruntime>=1.4.0; extra == "onnx"
+Requires-Dist: onnxruntime-tools>=1.4.2; extra == "onnx"
+Provides-Extra: onnxruntime
+Requires-Dist: onnxruntime>=1.4.0; extra == "onnxruntime"
+Requires-Dist: onnxruntime-tools>=1.4.2; extra == "onnxruntime"
+Provides-Extra: open-telemetry
+Requires-Dist: opentelemetry-api; extra == "open-telemetry"
+Requires-Dist: opentelemetry-exporter-otlp; extra == "open-telemetry"
+Requires-Dist: opentelemetry-sdk; extra == "open-telemetry"
+Provides-Extra: optuna
+Requires-Dist: optuna; extra == "optuna"
+Provides-Extra: quality
+Requires-Dist: datasets>=2.15.0; extra == "quality"
+Requires-Dist: ruff==0.11.2; extra == "quality"
+Requires-Dist: GitPython<3.1.19; extra == "quality"
+Requires-Dist: urllib3<2.0.0; extra == "quality"
+Requires-Dist: libcst; extra == "quality"
+Requires-Dist: rich; extra == "quality"
+Requires-Dist: pandas<2.3.0; extra == "quality"
+Provides-Extra: ray
+Requires-Dist: ray[tune]>=2.7.0; extra == "ray"
+Provides-Extra: retrieval
+Requires-Dist: faiss-cpu; extra == "retrieval"
+Requires-Dist: datasets>=2.15.0; extra == "retrieval"
+Provides-Extra: ruff
+Requires-Dist: ruff==0.11.2; extra == "ruff"
+Provides-Extra: sagemaker
+Requires-Dist: sagemaker>=2.31.0; extra == "sagemaker"
+Provides-Extra: sentencepiece
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "sentencepiece"
+Requires-Dist: protobuf; extra == "sentencepiece"
+Provides-Extra: serving
+Requires-Dist: openai>=1.98.0; extra == "serving"
+Requires-Dist: pydantic>=2; extra == "serving"
+Requires-Dist: uvicorn; extra == "serving"
+Requires-Dist: fastapi; extra == "serving"
+Requires-Dist: starlette; extra == "serving"
+Requires-Dist: torch>=2.2; extra == "serving"
+Requires-Dist: accelerate>=0.26.0; extra == "serving"
+Provides-Extra: sigopt
+Requires-Dist: sigopt; extra == "sigopt"
+Provides-Extra: sklearn
+Requires-Dist: scikit-learn; extra == "sklearn"
+Provides-Extra: speech
+Requires-Dist: torchaudio; extra == "speech"
+Requires-Dist: librosa; extra == "speech"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "speech"
+Requires-Dist: phonemizer; extra == "speech"
+Requires-Dist: kenlm; extra == "speech"
+Provides-Extra: testing
+Requires-Dist: pytest>=7.2.0; extra == "testing"
+Requires-Dist: pytest-asyncio; extra == "testing"
+Requires-Dist: pytest-rich; extra == "testing"
+Requires-Dist: pytest-xdist; extra == "testing"
+Requires-Dist: pytest-order; extra == "testing"
+Requires-Dist: pytest-rerunfailures; extra == "testing"
+Requires-Dist: timeout-decorator; extra == "testing"
+Requires-Dist: parameterized>=0.9; extra == "testing"
+Requires-Dist: psutil; extra == "testing"
+Requires-Dist: datasets>=2.15.0; extra == "testing"
+Requires-Dist: dill<0.3.5; extra == "testing"
+Requires-Dist: evaluate>=0.2.0; extra == "testing"
+Requires-Dist: pytest-timeout; extra == "testing"
+Requires-Dist: ruff==0.11.2; extra == "testing"
+Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "testing"
+Requires-Dist: nltk<=3.8.1; extra == "testing"
+Requires-Dist: GitPython<3.1.19; extra == "testing"
+Requires-Dist: sacremoses; extra == "testing"
+Requires-Dist: rjieba; extra == "testing"
+Requires-Dist: beautifulsoup4; extra == "testing"
+Requires-Dist: tensorboard; extra == "testing"
+Requires-Dist: pydantic>=2; extra == "testing"
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "testing"
+Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "testing"
+Requires-Dist: libcst; extra == "testing"
+Requires-Dist: faiss-cpu; extra == "testing"
+Requires-Dist: cookiecutter==1.7.3; extra == "testing"
+Requires-Dist: mistral-common[opencv]>=1.6.3; extra == "testing"
+Provides-Extra: tf
+Requires-Dist: tensorflow<2.16,>2.9; extra == "tf"
+Requires-Dist: onnxconverter-common; extra == "tf"
+Requires-Dist: tf2onnx; extra == "tf"
+Requires-Dist: tensorflow-text<2.16; extra == "tf"
+Requires-Dist: keras-nlp<0.14.0,>=0.3.1; extra == "tf"
+Provides-Extra: tf-cpu
+Requires-Dist: keras<2.16,>2.9; extra == "tf-cpu"
+Requires-Dist: tensorflow-cpu<2.16,>2.9; extra == "tf-cpu"
+Requires-Dist: onnxconverter-common; extra == "tf-cpu"
+Requires-Dist: tf2onnx; extra == "tf-cpu"
+Requires-Dist: tensorflow-text<2.16; extra == "tf-cpu"
+Requires-Dist: keras-nlp<0.14.0,>=0.3.1; extra == "tf-cpu"
+Requires-Dist: tensorflow-probability<0.24; extra == "tf-cpu"
+Provides-Extra: tf-speech
+Requires-Dist: librosa; extra == "tf-speech"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "tf-speech"
+Requires-Dist: phonemizer; extra == "tf-speech"
+Requires-Dist: kenlm; extra == "tf-speech"
+Provides-Extra: tiktoken
+Requires-Dist: tiktoken; extra == "tiktoken"
+Requires-Dist: blobfile; extra == "tiktoken"
+Provides-Extra: timm
+Requires-Dist: timm!=1.0.18,<=1.0.19; extra == "timm"
+Provides-Extra: tokenizers
+Requires-Dist: tokenizers<=0.23.0,>=0.22.0; extra == "tokenizers"
+Provides-Extra: torch
+Requires-Dist: torch>=2.2; extra == "torch"
+Requires-Dist: accelerate>=0.26.0; extra == "torch"
+Provides-Extra: torch-speech
+Requires-Dist: torchaudio; extra == "torch-speech"
+Requires-Dist: librosa; extra == "torch-speech"
+Requires-Dist: pyctcdecode>=0.4.0; extra == "torch-speech"
+Requires-Dist: phonemizer; extra == "torch-speech"
+Requires-Dist: kenlm; extra == "torch-speech"
+Provides-Extra: torch-vision
+Requires-Dist: torchvision; extra == "torch-vision"
+Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "torch-vision"
+Provides-Extra: torchhub
+Requires-Dist: filelock; extra == "torchhub"
+Requires-Dist: huggingface-hub<1.0,>=0.34.0; extra == "torchhub"
+Requires-Dist: importlib-metadata; extra == "torchhub"
+Requires-Dist: numpy>=1.17; extra == "torchhub"
+Requires-Dist: packaging>=20.0; extra == "torchhub"
+Requires-Dist: protobuf; extra == "torchhub"
+Requires-Dist: regex!=2019.12.17; extra == "torchhub"
+Requires-Dist: requests; extra == "torchhub"
+Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "torchhub"
+Requires-Dist: torch>=2.2; extra == "torchhub"
+Requires-Dist: tokenizers<=0.23.0,>=0.22.0; extra == "torchhub"
+Requires-Dist: tqdm>=4.27; extra == "torchhub"
+Provides-Extra: video
+Requires-Dist: av; extra == "video"
+Provides-Extra: vision
+Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "vision"
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+ English |
+ 简体中文 |
+ 繁體中文 |
+ 한국어 |
+ Español |
+ 日本語 |
+ हिन्दी |
+ Русский |
+ Português |
+ తెలుగు |
+ Français |
+ Deutsch |
+ Tiếng Việt |
+ العربية |
+ اردو |
+
+
+
+
+ State-of-the-art pretrained models for inference and training
+
+
+
+
+
+
+Transformers acts as the model-definition framework for state-of-the-art machine learning models in text, computer
+vision, audio, video, and multimodal model, for both inference and training.
+
+It centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the
+pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
+frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
+and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`.
+
+We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be
+simple, customizable, and efficient.
+
+There are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.com/models) you can use.
+
+Explore the [Hub](https://huggingface.com/) today to find a model and use Transformers to help you get started right away.
+
+## Installation
+
+Transformers works with Python 3.9+ [PyTorch](https://pytorch.org/get-started/locally/) 2.1+, [TensorFlow](https://www.tensorflow.org/install/pip) 2.6+, and [Flax](https://flax.readthedocs.io/en/latest/) 0.4.1+.
+
+Create and activate a virtual environment with [venv](https://docs.python.org/3/library/venv.html) or [uv](https://docs.astral.sh/uv/), a fast Rust-based Python package and project manager.
+
+```py
+# venv
+python -m venv .my-env
+source .my-env/bin/activate
+# uv
+uv venv .my-env
+source .my-env/bin/activate
+```
+
+Install Transformers in your virtual environment.
+
+```py
+# pip
+pip install "transformers[torch]"
+
+# uv
+uv pip install "transformers[torch]"
+```
+
+Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the *latest* version may not be stable. Feel free to open an [issue](https://github.com/huggingface/transformers/issues) if you encounter an error.
+
+```shell
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+
+# pip
+pip install .[torch]
+
+# uv
+uv pip install .[torch]
+```
+
+## Quickstart
+
+Get started with Transformers right away with the [Pipeline](https://huggingface.co/docs/transformers/pipeline_tutorial) API. The `Pipeline` is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
+
+Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
+
+```py
+from transformers import pipeline
+
+pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
+pipeline("the secret to baking a really good cake is ")
+[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
+```
+
+To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to `Pipeline`) between you and the system.
+
+> [!TIP]
+> You can also chat with a model directly from the command line.
+> ```shell
+> transformers chat Qwen/Qwen2.5-0.5B-Instruct
+> ```
+
+```py
+import torch
+from transformers import pipeline
+
+chat = [
+ {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
+ {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
+]
+
+pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
+response = pipeline(chat, max_new_tokens=512)
+print(response[0]["generated_text"][-1]["content"])
+```
+
+Expand the examples below to see how `Pipeline` works for different modalities and tasks.
+
+
+Automatic speech recognition
+
+```py
+from transformers import pipeline
+
+pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
+pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+
+
+
+Image classification
+
+
+
+
+```py
+from transformers import pipeline
+
+pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
+pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
+[{'label': 'macaw', 'score': 0.997848391532898},
+ {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
+ 'score': 0.0016551691805943847},
+ {'label': 'lorikeet', 'score': 0.00018523589824326336},
+ {'label': 'African grey, African gray, Psittacus erithacus',
+ 'score': 7.85409429227002e-05},
+ {'label': 'quail', 'score': 5.502637941390276e-05}]
+```
+
+
+
+
+Visual question answering
+
+
+
+
+
+```py
+from transformers import pipeline
+
+pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
+pipeline(
+ image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
+ question="What is in the image?",
+)
+[{'answer': 'statue of liberty'}]
+```
+
+
+
+## Why should I use Transformers?
+
+1. Easy-to-use state-of-the-art models:
+ - High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
+ - Low barrier to entry for researchers, engineers, and developers.
+ - Few user-facing abstractions with just three classes to learn.
+ - A unified API for using all our pretrained models.
+
+1. Lower compute costs, smaller carbon footprint:
+ - Share trained models instead of training from scratch.
+ - Reduce compute time and production costs.
+ - Dozens of model architectures with 1M+ pretrained checkpoints across all modalities.
+
+1. Choose the right framework for every part of a models lifetime:
+ - Train state-of-the-art models in 3 lines of code.
+ - Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
+ - Pick the right framework for training, evaluation, and production.
+
+1. Easily customize a model or an example to your needs:
+ - We provide examples for each architecture to reproduce the results published by its original authors.
+ - Model internals are exposed as consistently as possible.
+ - Model files can be used independently of the library for quick experiments.
+
+
+
+Audio
+
+- Audio classification with [Whisper](https://huggingface.co/openai/whisper-large-v3-turbo)
+- Automatic speech recognition with [Moonshine](https://huggingface.co/UsefulSensors/moonshine)
+- Keyword spotting with [Wav2Vec2](https://huggingface.co/superb/wav2vec2-base-superb-ks)
+- Speech to speech generation with [Moshi](https://huggingface.co/kyutai/moshiko-pytorch-bf16)
+- Text to audio with [MusicGen](https://huggingface.co/facebook/musicgen-large)
+- Text to speech with [Bark](https://huggingface.co/suno/bark)
+
+
+
+
+Computer vision
+
+- Automatic mask generation with [SAM](https://huggingface.co/facebook/sam-vit-base)
+- Depth estimation with [DepthPro](https://huggingface.co/apple/DepthPro-hf)
+- Image classification with [DINO v2](https://huggingface.co/facebook/dinov2-base)
+- Keypoint detection with [SuperPoint](https://huggingface.co/magic-leap-community/superpoint)
+- Keypoint matching with [SuperGlue](https://huggingface.co/magic-leap-community/superglue_outdoor)
+- Object detection with [RT-DETRv2](https://huggingface.co/PekingU/rtdetr_v2_r50vd)
+- Pose Estimation with [VitPose](https://huggingface.co/usyd-community/vitpose-base-simple)
+- Universal segmentation with [OneFormer](https://huggingface.co/shi-labs/oneformer_ade20k_swin_large)
+- Video classification with [VideoMAE](https://huggingface.co/MCG-NJU/videomae-large)
+
+
+
+
+Multimodal
+
+- Audio or text to text with [Qwen2-Audio](https://huggingface.co/Qwen/Qwen2-Audio-7B)
+- Document question answering with [LayoutLMv3](https://huggingface.co/microsoft/layoutlmv3-base)
+- Image or text to text with [Qwen-VL](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct)
+- Image captioning [BLIP-2](https://huggingface.co/Salesforce/blip2-opt-2.7b)
+- OCR-based document understanding with [GOT-OCR2](https://huggingface.co/stepfun-ai/GOT-OCR-2.0-hf)
+- Table question answering with [TAPAS](https://huggingface.co/google/tapas-base)
+- Unified multimodal understanding and generation with [Emu3](https://huggingface.co/BAAI/Emu3-Gen)
+- Vision to text with [Llava-OneVision](https://huggingface.co/llava-hf/llava-onevision-qwen2-0.5b-ov-hf)
+- Visual question answering with [Llava](https://huggingface.co/llava-hf/llava-1.5-7b-hf)
+- Visual referring expression segmentation with [Kosmos-2](https://huggingface.co/microsoft/kosmos-2-patch14-224)
+
+
+
+
+NLP
+
+- Masked word completion with [ModernBERT](https://huggingface.co/answerdotai/ModernBERT-base)
+- Named entity recognition with [Gemma](https://huggingface.co/google/gemma-2-2b)
+- Question answering with [Mixtral](https://huggingface.co/mistralai/Mixtral-8x7B-v0.1)
+- Summarization with [BART](https://huggingface.co/facebook/bart-large-cnn)
+- Translation with [T5](https://huggingface.co/google-t5/t5-base)
+- Text generation with [Llama](https://huggingface.co/meta-llama/Llama-3.2-1B)
+- Text classification with [Qwen](https://huggingface.co/Qwen/Qwen2.5-0.5B)
+
+
+
+## Citation
+
+We now have a [paper](https://www.aclweb.org/anthology/2020.emnlp-demos.6/) you can cite for the 🤗 Transformers library:
+```bibtex
+@inproceedings{wolf-etal-2020-transformers,
+ title = "Transformers: State-of-the-Art Natural Language Processing",
+ author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
+ booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
+ month = oct,
+ year = "2020",
+ address = "Online",
+ publisher = "Association for Computational Linguistics",
+ url = "https://www.aclweb.org/anthology/2020.emnlp-demos.6",
+ pages = "38--45"
+}
+```
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/RECORD b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/RECORD
new file mode 100644
index 0000000000000000000000000000000000000000..e405a1cdff4bf8db78f97f5281d3b9514f0e356e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/RECORD
@@ -0,0 +1,4330 @@
+../../../bin/transformers,sha256=V3EfM8seYhOGVvqA7RHiyjqRj92U8PfK-ntwSrKU7wE,259
+../../../bin/transformers-cli,sha256=3bqwr-pjR6P-LkFLcZ2qcAO_q-ZgpqdKhP6tmopM8Us,267
+transformers-4.56.2.dist-info/INSTALLER,sha256=zuuue4knoyJ-UwPPXg8fezS7VCrXJQrAP7zeNuwvFQg,4
+transformers-4.56.2.dist-info/LICENSE,sha256=d_1HEN757DwPYiWADgI18VpCWr1KiwNVkSf814JhIEk,11418
+transformers-4.56.2.dist-info/METADATA,sha256=OlZZfFqzsBpif3A0Jkx7DV5Eq7Waf8NnidZSNMhSEis,40130
+transformers-4.56.2.dist-info/RECORD,,
+transformers-4.56.2.dist-info/REQUESTED,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
+transformers-4.56.2.dist-info/WHEEL,sha256=tZoeGjtWxWRfdplE7E3d45VPlLNQnvbKiYnx7gwAy8A,92
+transformers-4.56.2.dist-info/entry_points.txt,sha256=Zra3dVQyt6Q3fU_suoD3gF81JV3WeV8gH66vzoev408,144
+transformers-4.56.2.dist-info/top_level.txt,sha256=GLBaeTo_CSdhnHvbxQ0kzpEHdlLuA_33foIogaWxntI,13
+transformers/__init__.py,sha256=L5K1p7hdLLzmQNqDtIwDLRv2s4OWOneaFFjJTy9K6J0,46645
+transformers/__pycache__/__init__.cpython-310.pyc,,
+transformers/__pycache__/activations.cpython-310.pyc,,
+transformers/__pycache__/activations_tf.cpython-310.pyc,,
+transformers/__pycache__/audio_utils.cpython-310.pyc,,
+transformers/__pycache__/cache_utils.cpython-310.pyc,,
+transformers/__pycache__/configuration_utils.cpython-310.pyc,,
+transformers/__pycache__/convert_graph_to_onnx.cpython-310.pyc,,
+transformers/__pycache__/convert_pytorch_checkpoint_to_tf2.cpython-310.pyc,,
+transformers/__pycache__/convert_slow_tokenizer.cpython-310.pyc,,
+transformers/__pycache__/convert_slow_tokenizers_checkpoints_to_fast.cpython-310.pyc,,
+transformers/__pycache__/convert_tf_hub_seq_to_seq_bert_to_pytorch.cpython-310.pyc,,
+transformers/__pycache__/debug_utils.cpython-310.pyc,,
+transformers/__pycache__/dependency_versions_check.cpython-310.pyc,,
+transformers/__pycache__/dependency_versions_table.cpython-310.pyc,,
+transformers/__pycache__/dynamic_module_utils.cpython-310.pyc,,
+transformers/__pycache__/feature_extraction_sequence_utils.cpython-310.pyc,,
+transformers/__pycache__/feature_extraction_utils.cpython-310.pyc,,
+transformers/__pycache__/file_utils.cpython-310.pyc,,
+transformers/__pycache__/hf_argparser.cpython-310.pyc,,
+transformers/__pycache__/hyperparameter_search.cpython-310.pyc,,
+transformers/__pycache__/image_processing_base.cpython-310.pyc,,
+transformers/__pycache__/image_processing_utils.cpython-310.pyc,,
+transformers/__pycache__/image_processing_utils_fast.cpython-310.pyc,,
+transformers/__pycache__/image_transforms.cpython-310.pyc,,
+transformers/__pycache__/image_utils.cpython-310.pyc,,
+transformers/__pycache__/keras_callbacks.cpython-310.pyc,,
+transformers/__pycache__/masking_utils.cpython-310.pyc,,
+transformers/__pycache__/model_debugging_utils.cpython-310.pyc,,
+transformers/__pycache__/modelcard.cpython-310.pyc,,
+transformers/__pycache__/modeling_attn_mask_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_flash_attention_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_flax_outputs.cpython-310.pyc,,
+transformers/__pycache__/modeling_flax_pytorch_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_flax_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_gguf_pytorch_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_layers.cpython-310.pyc,,
+transformers/__pycache__/modeling_outputs.cpython-310.pyc,,
+transformers/__pycache__/modeling_rope_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_tf_outputs.cpython-310.pyc,,
+transformers/__pycache__/modeling_tf_pytorch_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_tf_utils.cpython-310.pyc,,
+transformers/__pycache__/modeling_utils.cpython-310.pyc,,
+transformers/__pycache__/optimization.cpython-310.pyc,,
+transformers/__pycache__/optimization_tf.cpython-310.pyc,,
+transformers/__pycache__/processing_utils.cpython-310.pyc,,
+transformers/__pycache__/pytorch_utils.cpython-310.pyc,,
+transformers/__pycache__/safetensors_conversion.cpython-310.pyc,,
+transformers/__pycache__/testing_utils.cpython-310.pyc,,
+transformers/__pycache__/tf_utils.cpython-310.pyc,,
+transformers/__pycache__/time_series_utils.cpython-310.pyc,,
+transformers/__pycache__/tokenization_mistral_common.cpython-310.pyc,,
+transformers/__pycache__/tokenization_utils.cpython-310.pyc,,
+transformers/__pycache__/tokenization_utils_base.cpython-310.pyc,,
+transformers/__pycache__/tokenization_utils_fast.cpython-310.pyc,,
+transformers/__pycache__/trainer.cpython-310.pyc,,
+transformers/__pycache__/trainer_callback.cpython-310.pyc,,
+transformers/__pycache__/trainer_pt_utils.cpython-310.pyc,,
+transformers/__pycache__/trainer_seq2seq.cpython-310.pyc,,
+transformers/__pycache__/trainer_utils.cpython-310.pyc,,
+transformers/__pycache__/training_args.cpython-310.pyc,,
+transformers/__pycache__/training_args_seq2seq.cpython-310.pyc,,
+transformers/__pycache__/training_args_tf.cpython-310.pyc,,
+transformers/__pycache__/video_processing_utils.cpython-310.pyc,,
+transformers/__pycache__/video_utils.cpython-310.pyc,,
+transformers/activations.py,sha256=e4PLAhJ2dqIuavaFWqe9a6ql25u1r82qhDonFVLyd3M,11673
+transformers/activations_tf.py,sha256=TGmah3loMs_pERwxpjWb5-AUeHLoBAyDxFYWVuLC7FU,4729
+transformers/audio_utils.py,sha256=nEF5o70oWawJQFbgg_c10RoE4CtAFLuIBZw4DaZUdvU,54305
+transformers/cache_utils.py,sha256=kZLFMxS11rMb2O-R5W5VkDWWGnZDAfyC5uf2Q2VAWDY,68319
+transformers/commands/__init__.py,sha256=aFO3I7C6G9OLA9JZSc_yMaZl0glOQtjNPjqMFfu9wfQ,923
+transformers/commands/__pycache__/__init__.cpython-310.pyc,,
+transformers/commands/__pycache__/add_fast_image_processor.cpython-310.pyc,,
+transformers/commands/__pycache__/add_new_model_like.cpython-310.pyc,,
+transformers/commands/__pycache__/chat.cpython-310.pyc,,
+transformers/commands/__pycache__/convert.cpython-310.pyc,,
+transformers/commands/__pycache__/download.cpython-310.pyc,,
+transformers/commands/__pycache__/env.cpython-310.pyc,,
+transformers/commands/__pycache__/run.cpython-310.pyc,,
+transformers/commands/__pycache__/serving.cpython-310.pyc,,
+transformers/commands/__pycache__/train.cpython-310.pyc,,
+transformers/commands/__pycache__/transformers_cli.cpython-310.pyc,,
+transformers/commands/add_fast_image_processor.py,sha256=HIVXaU8NERWdsSJuyjnSp8bAnXxHojrwPCegX9IcfYU,24141
+transformers/commands/add_new_model_like.py,sha256=ERxo137DUb3qzWryowEzKe-AB7TUrwpJA27ih0Fu2yY,33369
+transformers/commands/chat.py,sha256=7ezDxh7uZVBRil_iitaNHkilfXYf4Cba5m4y6ho96SY,31770
+transformers/commands/convert.py,sha256=IhyqKqO33anJiIwneOBCogxREJkfH7qIP_3At2xnoVE,7064
+transformers/commands/download.py,sha256=GKPadx-YGBL7dHJSEcUp-QNOP3R2L71-gPGP0z6NNQI,2395
+transformers/commands/env.py,sha256=lC6D4ssqBQc_CEyFsJ_sHKj7lsvs7g1EfQG73IVvnFs,7024
+transformers/commands/run.py,sha256=nyEe2lOoj6e0EOxjKeF08hdW9WVWa101r9hWXl9v3Jo,4249
+transformers/commands/serving.py,sha256=BvwNC0ST-LtoKgQnn7RJ-bhru4AREfQfZfCYCqAV_2Y,67183
+transformers/commands/train.py,sha256=SDGD_DF2-y9n2sqW2c77j5a4B9Lj8sRWHZ-VU4bnx_U,6337
+transformers/commands/transformers_cli.py,sha256=cFlXM_DHUCFgf6KnjpAcvebihZL5UKKIOlZtixopBVw,2281
+transformers/configuration_utils.py,sha256=02vWknX9Rz98OmBys7nLhkGzRGf2SWeBpL5twoZTTR0,64346
+transformers/convert_graph_to_onnx.py,sha256=g-BvJuYIq2wDmHxQ0Ng2DrpwqNshxAbQNk4zjegX4nw,20130
+transformers/convert_pytorch_checkpoint_to_tf2.py,sha256=xNNks70V1s5Hesk4_xr65VgurQGd3Jv-pRw70isWjQc,14415
+transformers/convert_slow_tokenizer.py,sha256=jle2J9QvNOARfWMJC8etj1xm6AKMF4h9Pkx-rpkL2Ss,63658
+transformers/convert_slow_tokenizers_checkpoints_to_fast.py,sha256=Sa8NS-oVEYDgqYEhUfg-WuB4a8RsLReIu067twp8uCA,5061
+transformers/convert_tf_hub_seq_to_seq_bert_to_pytorch.py,sha256=02fwRNsiK3zmmL9O_hgsduomBuTDHWh8vcTyk2GOlz8,2895
+transformers/data/__init__.py,sha256=MuXSchTzRSaUtUDC1uSeDkHiSbjtrQZg4IoKeKHoH6A,1490
+transformers/data/__pycache__/__init__.cpython-310.pyc,,
+transformers/data/__pycache__/data_collator.cpython-310.pyc,,
+transformers/data/data_collator.py,sha256=ibI2TwvDIh2dZ1dNFfoMUKqkcH2q58snZAIVnuSilQ0,101088
+transformers/data/datasets/__init__.py,sha256=PGzUJjdmTPOPMyjV4-Tj3sNrmmh-lspjyxrVbrfJoX8,909
+transformers/data/datasets/__pycache__/__init__.cpython-310.pyc,,
+transformers/data/datasets/__pycache__/glue.cpython-310.pyc,,
+transformers/data/datasets/__pycache__/language_modeling.cpython-310.pyc,,
+transformers/data/datasets/__pycache__/squad.cpython-310.pyc,,
+transformers/data/datasets/glue.py,sha256=d2ys4oU49fQJ3ZXLpGGyou54lWOY2UJMUbZcdqaBNxg,6245
+transformers/data/datasets/language_modeling.py,sha256=tNZvgig_gzJzuEjc0wGVQa86Jx2wUaQMATDCBrqN-z8,23709
+transformers/data/datasets/squad.py,sha256=uEA-pVJFVKtZlliRBE_TU5MtWenJfJtacKtZLtOG_3w,9295
+transformers/data/metrics/__init__.py,sha256=o9t_VTQtqU3lEhqvocDzFMm7OvAKD-uxrjPWy0r74BI,3632
+transformers/data/metrics/__pycache__/__init__.cpython-310.pyc,,
+transformers/data/metrics/__pycache__/squad_metrics.cpython-310.pyc,,
+transformers/data/metrics/squad_metrics.py,sha256=fKA4MXBLgyB4p7EaPCiaLMR-CW5NDweXSDZh1qO02NM,29699
+transformers/data/processors/__init__.py,sha256=lvN5mp9mdrr5v6QvZT6VcoZ78zZUvXiumTm6Gdvlgvo,1014
+transformers/data/processors/__pycache__/__init__.cpython-310.pyc,,
+transformers/data/processors/__pycache__/glue.cpython-310.pyc,,
+transformers/data/processors/__pycache__/squad.cpython-310.pyc,,
+transformers/data/processors/__pycache__/utils.cpython-310.pyc,,
+transformers/data/processors/__pycache__/xnli.cpython-310.pyc,,
+transformers/data/processors/glue.py,sha256=IGwrYOn1sg6mztFzwfA_Eb9KyuvIYL4iYBDe5b-m83Y,23214
+transformers/data/processors/squad.py,sha256=aKeAhkB_zAZliI0n8V4rYHFPGJChND3OZ0AN9wHs2c8,33303
+transformers/data/processors/utils.py,sha256=tljqv-RDmkbfutIo2cUYbJuL75PfXMB3IP2mOM4gQJA,13823
+transformers/data/processors/xnli.py,sha256=sgcYz9YSfHY9NS0LO_YeFRRjq-nJFsDhFUP4NJeu-Q4,3481
+transformers/debug_utils.py,sha256=6m6Ks51IXFlIhEPdbXbsFi_3ZWjM34kpxV5l7-LR4bU,12891
+transformers/dependency_versions_check.py,sha256=6HbgtT2Wp-QZGOAdyUOklHvNA4rOVITGHrX34dtMOqg,2115
+transformers/dependency_versions_table.py,sha256=DXNuInQe5WTQEgtpTiCI3ofrsxW9k0bLS68h5xDbCrQ,3872
+transformers/distributed/__init__.py,sha256=ds-xiU6Hko8BN-XiIF2cJZPCjrQ-JFlodRARkPK8g-0,978
+transformers/distributed/__pycache__/__init__.cpython-310.pyc,,
+transformers/distributed/__pycache__/configuration_utils.cpython-310.pyc,,
+transformers/distributed/configuration_utils.py,sha256=rBPisXQ4szdnjxqxtFWOJYjOtnQ7JSCdbWs4_3xA1fU,4438
+transformers/dynamic_module_utils.py,sha256=H9GL_o7jxZP5kGTryHCBfqBL4Lbnuwpyo66u0HedUDA,34717
+transformers/feature_extraction_sequence_utils.py,sha256=U60TIDSbdFI_MD0Jxoe_aEGrwjoqEafP6eGMYKpF9jE,18273
+transformers/feature_extraction_utils.py,sha256=ZnXmWq8ypthTP1Bt2ddXeqPjMO7xdIch82x8wNVrki8,30700
+transformers/file_utils.py,sha256=qGXLORUv3xflV0GcJdJryr_aWc6w8PJ4S-eQGTaYxpQ,3698
+transformers/generation/__init__.py,sha256=DX3zYcNeKVjWjzeax92L6e3xM8zNQC-WhqZrSS1Jo5s,12472
+transformers/generation/__pycache__/__init__.cpython-310.pyc,,
+transformers/generation/__pycache__/beam_constraints.cpython-310.pyc,,
+transformers/generation/__pycache__/beam_search.cpython-310.pyc,,
+transformers/generation/__pycache__/candidate_generator.cpython-310.pyc,,
+transformers/generation/__pycache__/configuration_utils.cpython-310.pyc,,
+transformers/generation/__pycache__/flax_logits_process.cpython-310.pyc,,
+transformers/generation/__pycache__/flax_utils.cpython-310.pyc,,
+transformers/generation/__pycache__/logits_process.cpython-310.pyc,,
+transformers/generation/__pycache__/stopping_criteria.cpython-310.pyc,,
+transformers/generation/__pycache__/streamers.cpython-310.pyc,,
+transformers/generation/__pycache__/tf_logits_process.cpython-310.pyc,,
+transformers/generation/__pycache__/tf_utils.cpython-310.pyc,,
+transformers/generation/__pycache__/utils.cpython-310.pyc,,
+transformers/generation/__pycache__/watermarking.cpython-310.pyc,,
+transformers/generation/beam_constraints.py,sha256=ctpz6PYBFnyJWXS7tgZPG-fRTzMkf2qOoKzGwWK2JwQ,19268
+transformers/generation/beam_search.py,sha256=aSRPHw1Vp8oiCR_4HScMMc66ofty8adVAmj80_1ObAA,49497
+transformers/generation/candidate_generator.py,sha256=aItvWhLA3S4HE7mro-wSsngsZBcQM9rMOCyALOkQJOA,60742
+transformers/generation/configuration_utils.py,sha256=actcS1riv0bppjTvu2dKjH8zRHKgztNrv6gdADtgavs,81462
+transformers/generation/continuous_batching/__init__.py,sha256=6dKLub3cKc6cdNtQkfY0YzXM9BKsxLpwVuiojRZUitI,880
+transformers/generation/continuous_batching/__pycache__/__init__.cpython-310.pyc,,
+transformers/generation/continuous_batching/__pycache__/cache.cpython-310.pyc,,
+transformers/generation/continuous_batching/__pycache__/classes.cpython-310.pyc,,
+transformers/generation/continuous_batching/__pycache__/continuous_api.cpython-310.pyc,,
+transformers/generation/continuous_batching/__pycache__/scheduler.cpython-310.pyc,,
+transformers/generation/continuous_batching/cache.py,sha256=5y1DfLP2i6lQh2hg6e4H7AYpv-CUYWpNF2F0B_NaYs4,18182
+transformers/generation/continuous_batching/classes.py,sha256=F_zNl-ieWtA--P0_WX4Dl7JR4lJMaKiAFV5beYZuihk,8892
+transformers/generation/continuous_batching/continuous_api.py,sha256=sG9MiXYSxrQoWsu4AOGhqdo6a6-2EHgocgx6d5SDnYk,34927
+transformers/generation/continuous_batching/scheduler.py,sha256=Z8Hu2wtVZlKY4cZic4pR_oez2pFVUZZHOVMERmeKx_c,13620
+transformers/generation/flax_logits_process.py,sha256=d9K9Np1169WLpcXRnS_MwtWVKNAgDzKSA2fq5rom9FI,23008
+transformers/generation/flax_utils.py,sha256=M04Chm6S0EiGgt9XSBE70iSL8YYHGhu4QeAsFX1dBCI,50641
+transformers/generation/logits_process.py,sha256=kOXyCrk1R5jhTLeK8rsOcMlPMrTFFeAniQQNIuDHI84,152193
+transformers/generation/stopping_criteria.py,sha256=FqN7zP4qlPt9GSRtibBiHapcjcy3A1QZIIVRAk6XMWQ,28932
+transformers/generation/streamers.py,sha256=Mj_bPFPCh4225Z_oFLc5wLegJPCUzF83ppojDdh19mA,12985
+transformers/generation/tf_logits_process.py,sha256=q9KY6Fx6pfQ15_7Lm_oAD4_Eyr3ApM4pmhjeNcNeF4M,28639
+transformers/generation/tf_utils.py,sha256=6B48u3CpCO7AEtSdhSxOjNVfqDpzcIIQqNR9NmTUCbo,175687
+transformers/generation/utils.py,sha256=3x1jDXcfgC5_D528je2bv7UZdxSl-qjuMHB5RXvWhg4,242859
+transformers/generation/watermarking.py,sha256=IbT_aNam8yTFCZl0oXpyLDi4ilZnyIqySHKOq6Py--E,24526
+transformers/hf_argparser.py,sha256=qIhpTm1qGgJAOi9m-qGyXbqnYD7oFfm8LbfU7HayXoI,20672
+transformers/hyperparameter_search.py,sha256=1PGHNbFHqQD8Y0FSWgDec6OxbzJWJCJe2uWDX5r4vwE,4194
+transformers/image_processing_base.py,sha256=w3Zq2w3wjKrG8nj1N4wYZCBa87ldie86zdhmyABw8k8,24947
+transformers/image_processing_utils.py,sha256=dA0f7L3ySYNThEOyTZIVtQxJS4q-1GA0a82PPD1p0kk,13787
+transformers/image_processing_utils_fast.py,sha256=u96Djj-RudxXnbV7XXrWjtz_2d9ltRsop0qo_8EW9N0,27737
+transformers/image_transforms.py,sha256=FjVWpHJzMZGv6M2G4INI1Zm9iOsjcKN0fKaHscFKZpE,41500
+transformers/image_utils.py,sha256=kEb8dKUEWK2E2Z4vrCeeCb-Zh6HD259yQqe-tGNHY8Y,37821
+transformers/integrations/__init__.py,sha256=wZwGxaqGuJQ3nXPwOudGvKy0ZxIpQ0IjGIjz86JeM64,9565
+transformers/integrations/__pycache__/__init__.cpython-310.pyc,,
+transformers/integrations/__pycache__/accelerate.cpython-310.pyc,,
+transformers/integrations/__pycache__/aqlm.cpython-310.pyc,,
+transformers/integrations/__pycache__/awq.cpython-310.pyc,,
+transformers/integrations/__pycache__/bitnet.cpython-310.pyc,,
+transformers/integrations/__pycache__/bitsandbytes.cpython-310.pyc,,
+transformers/integrations/__pycache__/deepspeed.cpython-310.pyc,,
+transformers/integrations/__pycache__/eager_paged.cpython-310.pyc,,
+transformers/integrations/__pycache__/eetq.cpython-310.pyc,,
+transformers/integrations/__pycache__/executorch.cpython-310.pyc,,
+transformers/integrations/__pycache__/fbgemm_fp8.cpython-310.pyc,,
+transformers/integrations/__pycache__/finegrained_fp8.cpython-310.pyc,,
+transformers/integrations/__pycache__/flash_attention.cpython-310.pyc,,
+transformers/integrations/__pycache__/flash_paged.cpython-310.pyc,,
+transformers/integrations/__pycache__/flex_attention.cpython-310.pyc,,
+transformers/integrations/__pycache__/fp_quant.cpython-310.pyc,,
+transformers/integrations/__pycache__/fsdp.cpython-310.pyc,,
+transformers/integrations/__pycache__/ggml.cpython-310.pyc,,
+transformers/integrations/__pycache__/higgs.cpython-310.pyc,,
+transformers/integrations/__pycache__/hqq.cpython-310.pyc,,
+transformers/integrations/__pycache__/hub_kernels.cpython-310.pyc,,
+transformers/integrations/__pycache__/integration_utils.cpython-310.pyc,,
+transformers/integrations/__pycache__/mistral.cpython-310.pyc,,
+transformers/integrations/__pycache__/mxfp4.cpython-310.pyc,,
+transformers/integrations/__pycache__/npu_flash_attention.cpython-310.pyc,,
+transformers/integrations/__pycache__/peft.cpython-310.pyc,,
+transformers/integrations/__pycache__/quanto.cpython-310.pyc,,
+transformers/integrations/__pycache__/sdpa_attention.cpython-310.pyc,,
+transformers/integrations/__pycache__/sdpa_paged.cpython-310.pyc,,
+transformers/integrations/__pycache__/spqr.cpython-310.pyc,,
+transformers/integrations/__pycache__/tensor_parallel.cpython-310.pyc,,
+transformers/integrations/__pycache__/tiktoken.cpython-310.pyc,,
+transformers/integrations/__pycache__/tpu.cpython-310.pyc,,
+transformers/integrations/__pycache__/vptq.cpython-310.pyc,,
+transformers/integrations/accelerate.py,sha256=nEQ-TMOFaXomnuKMogrzU_J4PNCZM-Bs6GPddPGbuW0,7351
+transformers/integrations/aqlm.py,sha256=T2gpCoj62L5hkyJzm6tJlP_emhJlepezKN4y1HWueVI,4535
+transformers/integrations/awq.py,sha256=gIAEOj3Tepd_eQadBbPkeMpRlHc3it4tDFzQf8XOKF4,20579
+transformers/integrations/bitnet.py,sha256=-AQ7JCa7cOcuq4tGreVgyME_k7i3D5BVUT9OYM-tg-w,15718
+transformers/integrations/bitsandbytes.py,sha256=UR7BOYCcnYDgiyrmzXzLQ5EIdTK8HxtNlDtZMNqeVHo,23901
+transformers/integrations/deepspeed.py,sha256=ioCDBbFddzR_TcdtaI_x4r7DZw-rOcSSfx95qi1xlMQ,21805
+transformers/integrations/eager_paged.py,sha256=zX9wO8snknsWMaXephsWHM4S1yQpj24XRAm_YNmFSsI,1667
+transformers/integrations/eetq.py,sha256=wpofdy55HcvaTaOXrO_VMbmG1Rfly-kN1JfzOxw5X0U,5364
+transformers/integrations/executorch.py,sha256=fMMR8i5MIlnKf2WdV0d51SwwGUFEi80GJ5diLAo-Wc8,52326
+transformers/integrations/fbgemm_fp8.py,sha256=jwTi8hC_Y12YSKktXqUktCCtl_qO-Ncx3uvIyFcni1o,12441
+transformers/integrations/finegrained_fp8.py,sha256=AlhRxjh7bjn-0DwonNrWhiXtBQiClrrF3hHJf3dlYLw,15120
+transformers/integrations/flash_attention.py,sha256=hQqmP5RzORGIw1dFTPtqiTOTlNJvYCTMviRvAPY0QUQ,3125
+transformers/integrations/flash_paged.py,sha256=iwilADgEi_eaM84gltKoSowB0s73jldc1JdzmSqXFlY,3224
+transformers/integrations/flex_attention.py,sha256=zgAF94fK2-bJXnLpj5VjzZnaLoNp_4YEAL3xX2Ruo2c,12708
+transformers/integrations/fp_quant.py,sha256=MLC4bZucw-tTDoWjQIHUbj0nEYDM702t03KPjUZxExc,1672
+transformers/integrations/fsdp.py,sha256=Fs0aCRYb5JZqKhzWPbL8Jgy4VRbgduhhqLdAjzKCqrs,1545
+transformers/integrations/ggml.py,sha256=o6zTjIQPSoJQUwukxRpMmMYg11U2ekoivy2Zo5NRCOM,29208
+transformers/integrations/higgs.py,sha256=HHLtzd2kwM2CVSF64yxAG0E8sHf5YD266tCAZiYc5fY,31476
+transformers/integrations/hqq.py,sha256=GeTogGSqPyrgTvTHzxwt5TZhpc1vRj_lb2DdWy5BKkI,5075
+transformers/integrations/hub_kernels.py,sha256=z285adFTT6rsf_3mYnQ3SepySZzZRxBZLhImY92iYCg,6499
+transformers/integrations/integration_utils.py,sha256=3FuNFwfaD4RWqHP0hUVjBO_7rMw_C_7PtDvnzxLDgak,112945
+transformers/integrations/mistral.py,sha256=xMEkFF5aKOLcXWS_cnRXma4RMOSXn94uacKy1OVIRJU,4017
+transformers/integrations/mxfp4.py,sha256=ysfmzhrklfBLTAXARD6I4cl5bcGynuyFPHRJ0w7cizE,17908
+transformers/integrations/npu_flash_attention.py,sha256=5YBiW6jSW1dlYP-0dLfQJ0XFcX5zqLRUS6qRlESf5s4,4189
+transformers/integrations/peft.py,sha256=oLCG7bvXtEl7kIwOI8DBy3vlQn3ZgBa2QSpozdY4kkE,28747
+transformers/integrations/quanto.py,sha256=m3tz7fCciceEe3mJc1i8GNVWcKTQ--GopPGwU4ctZ4I,4377
+transformers/integrations/sdpa_attention.py,sha256=Ksyzw3FLp33Y0pClHAteAvmqZj4Q3wHHTdlKXF4ygRQ,4261
+transformers/integrations/sdpa_paged.py,sha256=uv9gOkGrJk7t_YX1JyT43SFcZzpVvcHjqaSR0dSvVM8,1721
+transformers/integrations/spqr.py,sha256=nHTdlyfkCc5vJO60TMZuE9pUiTTPfaqYV7kVLF6PMd0,5525
+transformers/integrations/tensor_parallel.py,sha256=jFwhwDCit-j_IaQtH0eDadSZ_cwcO_X0SYNEJYLmXek,48804
+transformers/integrations/tiktoken.py,sha256=2s3O3_3dsA7pbsz1Lu_eLA2SrloMZWVpg0NklRxPMlY,1627
+transformers/integrations/tpu.py,sha256=JtzQLGX0mnci_xKVxoXPDqrAT_YLSCaw2WK-4IssCu4,1394
+transformers/integrations/vptq.py,sha256=he6YX2nhHu0kBzA9-F6QU-WEjEMi0B7v__zEJTn66X8,4540
+transformers/keras_callbacks.py,sha256=M9ZvQaJ52k79RlgM7WNootiXoD_hNirmiMNaPxI3tik,20611
+transformers/kernels/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
+transformers/kernels/__pycache__/__init__.cpython-310.pyc,,
+transformers/kernels/deta/cpu/ms_deform_attn_cpu.cpp,sha256=VcCGm9IrvgVvmyZt0KyP16Q-ONmbeg6bKwccP6KadL0,1255
+transformers/kernels/deta/cpu/ms_deform_attn_cpu.h,sha256=nvVsKj9nabQ7IaNY4di5xVx6u-0lIifQvLg2JCoxiik,1138
+transformers/kernels/deta/cuda/ms_deform_attn_cuda.cu,sha256=M5-bW9g5z-upTFMNPIfnyLAqKTxGMCjAPqBr0GmWHX8,7360
+transformers/kernels/deta/cuda/ms_deform_attn_cuda.cuh,sha256=hygB20Vh3RttOSdCuTFz8V0d3CXNp-Q89x22rYmD258,61433
+transformers/kernels/deta/cuda/ms_deform_attn_cuda.h,sha256=rPWOOMo3QyFdB5kMiexpApLFZ4dnRtx4CluEAGwsfO8,1139
+transformers/kernels/deta/cuda/ms_deform_im2col_cuda.cuh,sha256=BRN8-yfSHY8ChLij8jFl2_z2LL0LEFKuVF6Byi-YLAY,54695
+transformers/kernels/deta/ms_deform_attn.h,sha256=H2bBXGyl0R-v2DqGVz11asoRvxbjZ9iWB9djomZTpgY,1837
+transformers/kernels/deta/vision.cpp,sha256=8RvZy7P_MMx5QEszo_MwNODddJLQ8mKcmmMfgLYC_HA,798
+transformers/kernels/falcon_mamba/__init__.py,sha256=bt0j851F1uuH7flSsTvIqdh9zdKVTOVKWt3datb15SI,721
+transformers/kernels/falcon_mamba/__pycache__/__init__.cpython-310.pyc,,
+transformers/kernels/falcon_mamba/__pycache__/selective_scan_with_ln_interface.cpython-310.pyc,,
+transformers/kernels/falcon_mamba/selective_scan_with_ln_interface.py,sha256=649oJD0sox1I-TCkZuRMjYm3tWQkQ3VoPXLNeOcN_ss,19731
+transformers/kernels/mra/cuda_kernel.cu,sha256=LxxRYTymSoBEQpWXHA0PMzwZwpolcwX7mFAjwU8-ZMc,11678
+transformers/kernels/mra/cuda_kernel.h,sha256=UJvYq_MDzhcp07bZpYcOBn8ZGFcf_Ax1dynuiVTBvmA,1682
+transformers/kernels/mra/cuda_launch.cu,sha256=Ox5MTACriC30CGyn-g1Kb5EgQSMAZSaN6fpit3xLFWc,4072
+transformers/kernels/mra/cuda_launch.h,sha256=RVCkN_euasvgPK0zADNRvRYGWd4ah5l9X-7UG_AcdH8,707
+transformers/kernels/mra/torch_extension.cpp,sha256=N0YdBLVX0lZabckJzV_RYTHS2atCNvn13E4Ivobt25g,1405
+transformers/kernels/rwkv/wkv_cuda.cu,sha256=EvaUrEnw_qr2EjMKP-Pq7VPzFfGlMJnFhdHNLtn1fPU,6219
+transformers/kernels/rwkv/wkv_cuda_bf16.cu,sha256=DG9hTtOAlrnpDFahjt-MmnOxjMuhGU55GPsmV21HtrQ,6633
+transformers/kernels/rwkv/wkv_op.cpp,sha256=qSExhKdT6p3hyaTv5SypCnH_c7EmaX6HbhTcCntvZWg,4022
+transformers/kernels/yoso/common.h,sha256=Tq2rOUtE8Y4DRAUrRISvwIwVI3u8JBf21WgWSAYiDlQ,273
+transformers/kernels/yoso/common_cuda.h,sha256=Sji70AuVcuZSotLF7Gotmun9MJuOHo8wEkxizKXLRtc,258
+transformers/kernels/yoso/common_cuda_device.h,sha256=y6WUgAiapnMKqthRMS5s-DMSWNVkar_i8g4KPFvqiuk,2063
+transformers/kernels/yoso/fast_lsh_cumulation.cu,sha256=LA4LGNgyXT3osIyQtFBcRanSyNQWm8yqmpz7AeLP7cw,19061
+transformers/kernels/yoso/fast_lsh_cumulation.h,sha256=1cTWZjOm751HGiEB5P-UPJ8SE1VO7XRyXmBgyxYDyjI,1575
+transformers/kernels/yoso/fast_lsh_cumulation_cuda.cu,sha256=HKGLWl-WFz5BXjaAPHTNTbG6IUkJjhBdvFf2K7hrDVQ,32870
+transformers/kernels/yoso/fast_lsh_cumulation_cuda.h,sha256=_KGI8HQbVFtCN5KAcSGpyiJ2foGi26RKen138CUc2fY,5490
+transformers/kernels/yoso/fast_lsh_cumulation_torch.cpp,sha256=-Rh7o39Z3rtOPwNnEM-c51TCqywpVdK0WVaA7VRrXbQ,3154
+transformers/loss/__init__.py,sha256=qETsqCwayu6Ymj_J4_A_eiwiaMRHQ0noWKM35naanzc,606
+transformers/loss/__pycache__/__init__.cpython-310.pyc,,
+transformers/loss/__pycache__/loss_d_fine.cpython-310.pyc,,
+transformers/loss/__pycache__/loss_deformable_detr.cpython-310.pyc,,
+transformers/loss/__pycache__/loss_for_object_detection.cpython-310.pyc,,
+transformers/loss/__pycache__/loss_grounding_dino.cpython-310.pyc,,
+transformers/loss/__pycache__/loss_rt_detr.cpython-310.pyc,,
+transformers/loss/__pycache__/loss_utils.cpython-310.pyc,,
+transformers/loss/loss_d_fine.py,sha256=pyVihlU1CQraOzUjFLrPXIsVSHxHhCun2SIzvOZFEDs,15881
+transformers/loss/loss_deformable_detr.py,sha256=pUwwrAVxEwa2qamyoTIqlxpll_rBTXCOn67bW73ZKuc,7321
+transformers/loss/loss_for_object_detection.py,sha256=fZuLWKzaCtGvCmlpevpHnIGp4BFIPJIIU4GcFqDO7r0,24581
+transformers/loss/loss_grounding_dino.py,sha256=Efh5GmRzZHjK3ZoNCNCRhU1GV9pcBtHDKxFbrJwr3K0,11190
+transformers/loss/loss_rt_detr.py,sha256=rGk8fFh1qoPgsRL0-vHw3FrjL3wRNV81-XQTFrElTeM,22130
+transformers/loss/loss_utils.py,sha256=-mXxizFn9FmJ16i6hkMqQdMiM4-XicyJsI1dfyDxELc,7046
+transformers/masking_utils.py,sha256=XYg6AZFAZRAAghnnW0ycNco2pTRQcoaHlSWgWG8Oufg,59975
+transformers/model_debugging_utils.py,sha256=-Oluu4wdKkVqaVFMs5m8WfSc0y0CBIK2rPti52fdCWs,17074
+transformers/modelcard.py,sha256=LGTf5iHPFz6bC1celbGk21gabAr9baqC2Jph_bBMYjs,35854
+transformers/modeling_attn_mask_utils.py,sha256=oIEM72sNYJO_2qNJs63eLmM_06a-UHPYC14IsvEsNUs,21517
+transformers/modeling_flash_attention_utils.py,sha256=uifB-gkmixf-D-CP51qyC5bXGld5uICkbggwPt1DyWY,30042
+transformers/modeling_flax_outputs.py,sha256=1RQh6VTIIVgh2OME-EkUdJc2NdBi5TEXBHCFCupFASs,42188
+transformers/modeling_flax_pytorch_utils.py,sha256=rhewsql7OtuXPqpORVigrGzw8sAPcTK7D0z4lWwAYz0,21550
+transformers/modeling_flax_utils.py,sha256=TbaDBlsD6A4nh9xkeBW1H7bxYcxsQXA4ZesXY2ReJSc,61240
+transformers/modeling_gguf_pytorch_utils.py,sha256=Yo7_KWnBw_sZ4d0A-L4RuBiOMFpwbmuRo9Fk5Y2dkiI,20571
+transformers/modeling_layers.py,sha256=N2gxqUSKqbRvAJteODMp1im-qruGKYf0D6CG7S6GEoY,11562
+transformers/modeling_outputs.py,sha256=sdgyoU6iT2PxgcutfkEL0VpDCCgzIh_2mAhZpsf9NX4,109642
+transformers/modeling_rope_utils.py,sha256=Q2Wpcr9qxFcpwzpOuWhQ4TBiIfNpd8XcmyB8sYbdk_k,31993
+transformers/modeling_tf_outputs.py,sha256=6THINWzeA-DZyxAdvE3lu3p3h4ZpeBl8sjrOhj9wb9Y,56248
+transformers/modeling_tf_pytorch_utils.py,sha256=Q7-5aDeI2ec3-NYgH6Fp9OpAMmymqyp1mDZGWYve_Io,27982
+transformers/modeling_tf_utils.py,sha256=Rqc7BVljDxocTRTXu2IuiUtpMAFijjtxXx46dZIDsbE,166141
+transformers/modeling_utils.py,sha256=_eN-7sEzPSAiufklkH9wdQPUGZt5RqiQrb0XC5w6MH8,314691
+transformers/models/__init__.py,sha256=i6CDAHcEP0MUFZSMaigpu2_gA2LVxWOc6uBy5KqIUoQ,10977
+transformers/models/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/aimv2/__init__.py,sha256=cDli19QT_YABtn4DPLYfoWHtkmOQYGipAgPKGuRje4c,991
+transformers/models/aimv2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/aimv2/__pycache__/configuration_aimv2.cpython-310.pyc,,
+transformers/models/aimv2/__pycache__/modeling_aimv2.cpython-310.pyc,,
+transformers/models/aimv2/__pycache__/modular_aimv2.cpython-310.pyc,,
+transformers/models/aimv2/configuration_aimv2.py,sha256=K0yaVDpIlBtlYi8xDfhpU7ndTASqTu8nV_rCoWAAAyM,13740
+transformers/models/aimv2/modeling_aimv2.py,sha256=Np3XgOWSmN-_-8MPM1e9F8za6kqRWoEpHII0fLwmtoY,33372
+transformers/models/aimv2/modular_aimv2.py,sha256=L0Avd7SuJwLyr60tequcU5TkmqCgfNcJMzuqpRpmWpo,29213
+transformers/models/albert/__init__.py,sha256=WjQ4NtNxKNj7Hvk9lA2OXmdgD_SNFp1wLS2eeL3-WoE,1154
+transformers/models/albert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/albert/__pycache__/configuration_albert.cpython-310.pyc,,
+transformers/models/albert/__pycache__/modeling_albert.cpython-310.pyc,,
+transformers/models/albert/__pycache__/modeling_flax_albert.cpython-310.pyc,,
+transformers/models/albert/__pycache__/modeling_tf_albert.cpython-310.pyc,,
+transformers/models/albert/__pycache__/tokenization_albert.cpython-310.pyc,,
+transformers/models/albert/__pycache__/tokenization_albert_fast.cpython-310.pyc,,
+transformers/models/albert/configuration_albert.py,sha256=1jz6sQm_Ki_o_EHJj7mzULanRt3xFoPv3tt_rQg6Ct4,8162
+transformers/models/albert/modeling_albert.py,sha256=WfQVwAz1_INOKBMAnjE5K0qIA__DUV6PHpkki2J7E-8,57681
+transformers/models/albert/modeling_flax_albert.py,sha256=-QrqU89tM44jANMS-haQlSARp2uxVuUXCpUnlE8lT58,41035
+transformers/models/albert/modeling_tf_albert.py,sha256=nfIkDUf5d0ORzk1vG-3F-PWTyLSt-7uIUsBpdR9r_wg,68993
+transformers/models/albert/tokenization_albert.py,sha256=kV5S_i-EPu2mZ8f1tr7T-IRsd_W_eshGVGO_veSgQi8,13391
+transformers/models/albert/tokenization_albert_fast.py,sha256=m4Xl3Pb038gBQzlGPAvWFf2G3LrEDdPWhASLBrLucz8,7609
+transformers/models/align/__init__.py,sha256=QqTKk-Z4BylY6EkBSlYvKXVhT2te-m2Al626OUAz-r4,1027
+transformers/models/align/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/align/__pycache__/configuration_align.cpython-310.pyc,,
+transformers/models/align/__pycache__/modeling_align.cpython-310.pyc,,
+transformers/models/align/__pycache__/processing_align.cpython-310.pyc,,
+transformers/models/align/configuration_align.py,sha256=T3yiaW_5C9VNHouwd-FGLgwFJd8M8h-a9gBIod0Ys2c,15999
+transformers/models/align/modeling_align.py,sha256=CJaKVRKPFyYRu2HS8fhMWnJc51B2ZVv1nc67FBjeHdI,52106
+transformers/models/align/processing_align.py,sha256=tHTyfs4Jy0YsnC7x6yxDCltv6MyDDuu5BSrWEa2GmBY,6249
+transformers/models/altclip/__init__.py,sha256=405IijUCYr1EGvOqg1xzds_GHOlxCl0HCsf1rI0wtPY,1033
+transformers/models/altclip/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/altclip/__pycache__/configuration_altclip.cpython-310.pyc,,
+transformers/models/altclip/__pycache__/modeling_altclip.cpython-310.pyc,,
+transformers/models/altclip/__pycache__/processing_altclip.cpython-310.pyc,,
+transformers/models/altclip/configuration_altclip.py,sha256=Usb29EWjpdtZATW-jxZ8VBmms57H2v4UtoGtQ_mvYB4,18498
+transformers/models/altclip/modeling_altclip.py,sha256=UWbCZjbf9I9vbPsQmMy-9DQyhgrJcSFjIlg99reS9qs,61593
+transformers/models/altclip/processing_altclip.py,sha256=V-vHFSMYzTLd-U4VuQF_O1MNuc3yQH-7YuxlAKnVj5k,6026
+transformers/models/apertus/__init__.py,sha256=zY0UTl5pr-BSjXXoYMrQRQm0vhGnSykqKJ2n7mxl_ig,1271
+transformers/models/apertus/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/apertus/__pycache__/configuration_apertus.cpython-310.pyc,,
+transformers/models/apertus/__pycache__/modeling_apertus.cpython-310.pyc,,
+transformers/models/apertus/__pycache__/modular_apertus.cpython-310.pyc,,
+transformers/models/apertus/configuration_apertus.py,sha256=1Hcuelq3r20FYICxtEqyEBut6FlO8BMUdGa203DFfhs,11922
+transformers/models/apertus/modeling_apertus.py,sha256=3pErV25SDDlZWU86uPGrMgFiKRa-xBcY4BhKzbAMFLw,21169
+transformers/models/apertus/modular_apertus.py,sha256=PfZfJ4CY3UXq7JxxPyYYDNERoyOi_Eu1YFNZWWVTcy0,16833
+transformers/models/arcee/__init__.py,sha256=bysIumYEa1Z1bCLBaaP_SCT_6poh8zFLgxt_4Ib-Diw,1009
+transformers/models/arcee/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/arcee/__pycache__/configuration_arcee.cpython-310.pyc,,
+transformers/models/arcee/__pycache__/modeling_arcee.cpython-310.pyc,,
+transformers/models/arcee/__pycache__/modular_arcee.cpython-310.pyc,,
+transformers/models/arcee/configuration_arcee.py,sha256=S4OeiCsHV_Qbow6q6X-ZPwg5UFz7jvpK6r06Gf3KCZw,10764
+transformers/models/arcee/modeling_arcee.py,sha256=eD_mj6MFABbwPxUFVI4i8ZZB0YkjUGIzy6PULji7yu0,21243
+transformers/models/arcee/modular_arcee.py,sha256=pcUF5I9TfPIPjrJpWJKf_odVorR_pLwgKhvSqLMwWpA,10133
+transformers/models/aria/__init__.py,sha256=I3vYPjV-sDl0OAILLADGZ7hUkk9ZsmyZ8CEf9tie_dY,1066
+transformers/models/aria/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/aria/__pycache__/configuration_aria.cpython-310.pyc,,
+transformers/models/aria/__pycache__/image_processing_aria.cpython-310.pyc,,
+transformers/models/aria/__pycache__/modeling_aria.cpython-310.pyc,,
+transformers/models/aria/__pycache__/modular_aria.cpython-310.pyc,,
+transformers/models/aria/__pycache__/processing_aria.cpython-310.pyc,,
+transformers/models/aria/configuration_aria.py,sha256=OfA722tTQm4EEsYxmZM-Wm12cnoH8sQ702bHQSBSBEw,16425
+transformers/models/aria/image_processing_aria.py,sha256=tocGmgXGxNMFYNW1nUJ5Uxg05KRs4vkyduot18Po73I,24795
+transformers/models/aria/modeling_aria.py,sha256=h-4Jpzkuwxco671anMHnwau-632I8QoOzoIHZ3jjm-o,52370
+transformers/models/aria/modular_aria.py,sha256=3P8LoKT997s25RlIcYP-1ZCT6UQ_1nLg8rsz1fwlrNc,70855
+transformers/models/aria/processing_aria.py,sha256=mb4Si17gdG4NyCxmfWS0WTRkvp6nDF9D3JoKvm6ky5c,9291
+transformers/models/audio_spectrogram_transformer/__init__.py,sha256=a_YVwB1p4_PPeqPFWqFsGSGSQVTaSUXY0xsOd_Gflqs,1107
+transformers/models/audio_spectrogram_transformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/audio_spectrogram_transformer/__pycache__/configuration_audio_spectrogram_transformer.cpython-310.pyc,,
+transformers/models/audio_spectrogram_transformer/__pycache__/feature_extraction_audio_spectrogram_transformer.cpython-310.pyc,,
+transformers/models/audio_spectrogram_transformer/__pycache__/modeling_audio_spectrogram_transformer.cpython-310.pyc,,
+transformers/models/audio_spectrogram_transformer/configuration_audio_spectrogram_transformer.py,sha256=HAhLugn_E6Ajr3-3n3qohG5ifAPqNfSuucQ0B2S7tCM,5901
+transformers/models/audio_spectrogram_transformer/feature_extraction_audio_spectrogram_transformer.py,sha256=vPBynKfjgNCc2c6T3kd5AKxsstjKBI5Z-oNwtRAH7VY,9929
+transformers/models/audio_spectrogram_transformer/modeling_audio_spectrogram_transformer.py,sha256=wEoYOG9uCHSVpDM929lVeexMo_zKF27qa8BDQIX7faU,20618
+transformers/models/auto/__init__.py,sha256=wX3m7QJXMmkNMTL6ef7HH18vXdZ0cgUIkHgpVLpGZ_4,1292
+transformers/models/auto/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/auto/__pycache__/auto_factory.cpython-310.pyc,,
+transformers/models/auto/__pycache__/configuration_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/feature_extraction_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/image_processing_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/modeling_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/modeling_flax_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/modeling_tf_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/processing_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/tokenization_auto.cpython-310.pyc,,
+transformers/models/auto/__pycache__/video_processing_auto.cpython-310.pyc,,
+transformers/models/auto/auto_factory.py,sha256=BMC2EJfFM0Wez3Tui51zCr1P67v6Sp9zhB-3_0nI7uI,47212
+transformers/models/auto/configuration_auto.py,sha256=WuNVHXunReiZr1ZkKG5fPKI0akFfY5AVPMESmE8jxuc,53343
+transformers/models/auto/feature_extraction_auto.py,sha256=pGwqBOVlipFV5wCMOAx7l6HTdWJCYRHYqASIUv9Za40,20390
+transformers/models/auto/image_processing_auto.py,sha256=NKRjmVnmUT2Ecbtio9i1HPDR4Q2Vwp-MvrL6An9LlPI,38879
+transformers/models/auto/modeling_auto.py,sha256=ol1bfCiqjyt5pDNDI_h1lBa0r7itAnGoyHvz8jYN6NU,96469
+transformers/models/auto/modeling_flax_auto.py,sha256=jljyZ4H_wWjcxuVbLUDtO0acB104wm78aXyVNeGu_Zk,15709
+transformers/models/auto/modeling_tf_auto.py,sha256=YWaGWUmrGNg5eieun1OTG_EmtzWy8CU_Ebt9gw6mxyw,30313
+transformers/models/auto/processing_auto.py,sha256=QCa2IjxIeffNhKdUYHrfRIzlTxrzgMc_UEdlVqTY7k4,20634
+transformers/models/auto/tokenization_auto.py,sha256=sM0lcCqZv98c2T7csfN5On1CLtW08FPUqecc9ni3n6A,56944
+transformers/models/auto/video_processing_auto.py,sha256=p4MPIpkfD_EBu8eSigl19pmvL-kFJzVaVGourpIxz8U,19122
+transformers/models/autoformer/__init__.py,sha256=EzGIA8hECx9XytdzTifaGyGp7hrXqlyP0slqAq8xBNY,1001
+transformers/models/autoformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/autoformer/__pycache__/configuration_autoformer.cpython-310.pyc,,
+transformers/models/autoformer/__pycache__/modeling_autoformer.cpython-310.pyc,,
+transformers/models/autoformer/configuration_autoformer.py,sha256=hSn6Waq6CuyDFOxAecr9IhFaq4fEAEHn0uiaC_tsa3s,12192
+transformers/models/autoformer/modeling_autoformer.py,sha256=SrznJCagysZ4EJ-xATs4ukrMlzt-FdKdsPq1yK1hgKU,106831
+transformers/models/aya_vision/__init__.py,sha256=-DIHmMjkXOyNGbMtZJkHtLiOzdxOYSrKq4_mmR09cfk,1042
+transformers/models/aya_vision/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/aya_vision/__pycache__/configuration_aya_vision.cpython-310.pyc,,
+transformers/models/aya_vision/__pycache__/modeling_aya_vision.cpython-310.pyc,,
+transformers/models/aya_vision/__pycache__/modular_aya_vision.cpython-310.pyc,,
+transformers/models/aya_vision/__pycache__/processing_aya_vision.cpython-310.pyc,,
+transformers/models/aya_vision/configuration_aya_vision.py,sha256=oW_qdNAfXS5UnxCVQRtGM8ALI5XzBGRHa3Frx-ECr9s,4790
+transformers/models/aya_vision/modeling_aya_vision.py,sha256=4ae4aBxweDOxFIJSPhRDYtNhs4G6TqfhfwuO21JLHPY,23503
+transformers/models/aya_vision/modular_aya_vision.py,sha256=qsWjbo5m7xb_sxZ1MvnBXWTg47zVDVzcnxNauLwcrmY,13277
+transformers/models/aya_vision/processing_aya_vision.py,sha256=voI-Z4FtSKIlEGyQGqkZu3L4aOh22bTX_V9OUVAucWc,11961
+transformers/models/bamba/__init__.py,sha256=gtebRUrAdiwq-rJmlM5qpbtbGEg-xxA3pjivOHJvaRs,1040
+transformers/models/bamba/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bamba/__pycache__/configuration_bamba.cpython-310.pyc,,
+transformers/models/bamba/__pycache__/modeling_bamba.cpython-310.pyc,,
+transformers/models/bamba/__pycache__/modular_bamba.cpython-310.pyc,,
+transformers/models/bamba/configuration_bamba.py,sha256=zo-wvX5wz8wWepdJLwQnm2yyZdpHx0lMsE85Quf8RYE,10134
+transformers/models/bamba/modeling_bamba.py,sha256=r6s9bU5Jrf7GNuaM1jH8a1tKXn3Xdd6THnjvcQdicp4,69413
+transformers/models/bamba/modular_bamba.py,sha256=xM_OnUGkC67va4FRKjm7sdYHMYe3IAIWAiqKz4NnXA0,55311
+transformers/models/bark/__init__.py,sha256=fIlOQ6RPBARVhUKdjNx2Nvf09azEI6AiPv3lyWjk0Gc,1024
+transformers/models/bark/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bark/__pycache__/configuration_bark.cpython-310.pyc,,
+transformers/models/bark/__pycache__/generation_configuration_bark.cpython-310.pyc,,
+transformers/models/bark/__pycache__/modeling_bark.cpython-310.pyc,,
+transformers/models/bark/__pycache__/processing_bark.cpython-310.pyc,,
+transformers/models/bark/configuration_bark.py,sha256=p9Upfi8NXf4bHj9d2C75qseupR7X7F3JYWFATkVFh7c,11907
+transformers/models/bark/generation_configuration_bark.py,sha256=cI5vwf3ll9YIBKiXpb7HKZwu1-wDrhnlktpYy8i9X94,14955
+transformers/models/bark/modeling_bark.py,sha256=6t4b05EoBCNKPlN0-ewwQcOfXaS70sBm4ooeoWJrnfU,72208
+transformers/models/bark/processing_bark.py,sha256=2Vu4KGa57Ruqwxc60fYYW_uKsYQ3FffZaUwIn3YEVX4,13834
+transformers/models/bart/__init__.py,sha256=1_kCOlvj4hcCbNiAsAhH0PYAK4zopuVKAYKZ_64O3_c,1142
+transformers/models/bart/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bart/__pycache__/configuration_bart.cpython-310.pyc,,
+transformers/models/bart/__pycache__/modeling_bart.cpython-310.pyc,,
+transformers/models/bart/__pycache__/modeling_flax_bart.cpython-310.pyc,,
+transformers/models/bart/__pycache__/modeling_tf_bart.cpython-310.pyc,,
+transformers/models/bart/__pycache__/tokenization_bart.cpython-310.pyc,,
+transformers/models/bart/__pycache__/tokenization_bart_fast.cpython-310.pyc,,
+transformers/models/bart/configuration_bart.py,sha256=0BemB9DKkzjpDV-39iIC96OkQHY9sevzmYUmWdG5fHg,18871
+transformers/models/bart/modeling_bart.py,sha256=DItsJOM7FvfDhRGpIbSsHJ-VgXaTTnIO4whflR6NKes,90022
+transformers/models/bart/modeling_flax_bart.py,sha256=T8dSDHTYEZBOhc5MAgmtCal_ns_hFCOn98b9dPS3Tho,83070
+transformers/models/bart/modeling_tf_bart.py,sha256=Kb_NgfqI4LdvaLE4Ji6vzTqc9P7zdY7ijjr0osDd0lQ,80645
+transformers/models/bart/tokenization_bart.py,sha256=kSDfbiku7CuiLkGRu2WN4rvk4Ub-fIyM7h1tw8W4Ids,16265
+transformers/models/bart/tokenization_bart_fast.py,sha256=KT0ISbLlAUn8i77zti_Oe3yebxVSM65gXGMFS3PaeU8,11275
+transformers/models/barthez/__init__.py,sha256=21WBGVafx-0kV-K_2jBdpBg0NBWsRKJqJowo03g2S9A,1003
+transformers/models/barthez/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/barthez/__pycache__/tokenization_barthez.cpython-310.pyc,,
+transformers/models/barthez/__pycache__/tokenization_barthez_fast.cpython-310.pyc,,
+transformers/models/barthez/tokenization_barthez.py,sha256=_uwi3euB_QpCr9lakhVXRWMK0G-RYTD5WyLhbI4qF6Y,12160
+transformers/models/barthez/tokenization_barthez_fast.py,sha256=7gExI5ls2M0YNtk7Dp5AHW1PAggk5zMzz2tKtQ3x54s,7721
+transformers/models/bartpho/__init__.py,sha256=DN0zgU4dM841Kqqo6wN8FpWFeWYHCBxIq3lxrg5vUoU,958
+transformers/models/bartpho/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bartpho/__pycache__/tokenization_bartpho.cpython-310.pyc,,
+transformers/models/bartpho/tokenization_bartpho.py,sha256=fpW_x46y9RWaXd3i1aWRWZN-hAeXnph8DzzLwPWwf10,13619
+transformers/models/beit/__init__.py,sha256=t99cV1TicuPrQlZaHjwkrEi5d7tMQeK7TTooGJIn6-Q,1157
+transformers/models/beit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/beit/__pycache__/configuration_beit.cpython-310.pyc,,
+transformers/models/beit/__pycache__/feature_extraction_beit.cpython-310.pyc,,
+transformers/models/beit/__pycache__/image_processing_beit.cpython-310.pyc,,
+transformers/models/beit/__pycache__/image_processing_beit_fast.cpython-310.pyc,,
+transformers/models/beit/__pycache__/modeling_beit.cpython-310.pyc,,
+transformers/models/beit/__pycache__/modeling_flax_beit.cpython-310.pyc,,
+transformers/models/beit/configuration_beit.py,sha256=zT9actpT-E-p_5LLb6aDvYM8xClvu2pddJWK6wlIfgU,11602
+transformers/models/beit/feature_extraction_beit.py,sha256=I3Hxy2MRCaAr0m4taNn5y8_9_fAXCNpcYZi6gQa5tXY,1284
+transformers/models/beit/image_processing_beit.py,sha256=tnbamvPrXoZIeiIqJb3OJjqPcn2tjCUJ5R9Ctxgho4s,24074
+transformers/models/beit/image_processing_beit_fast.py,sha256=-SKWE4nhnoEmNCLIgdRNgUi7UIpwy99a-b_hE4RMRqQ,9211
+transformers/models/beit/modeling_beit.py,sha256=YLQj01W8r5zUyEcQJxx8hwccn8fB8y6c1b5xtuk_DkE,65520
+transformers/models/beit/modeling_flax_beit.py,sha256=g6QwQOBdYd5kheWIzaO7Xpok4MFPJWwtopojVj5jLfU,37136
+transformers/models/bert/__init__.py,sha256=8IqoRT5cO4DU3GmQHsJgW-n6MclOZTmho5VYkKDMbnU,1182
+transformers/models/bert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bert/__pycache__/configuration_bert.cpython-310.pyc,,
+transformers/models/bert/__pycache__/modeling_bert.cpython-310.pyc,,
+transformers/models/bert/__pycache__/modeling_flax_bert.cpython-310.pyc,,
+transformers/models/bert/__pycache__/modeling_tf_bert.cpython-310.pyc,,
+transformers/models/bert/__pycache__/tokenization_bert.cpython-310.pyc,,
+transformers/models/bert/__pycache__/tokenization_bert_fast.cpython-310.pyc,,
+transformers/models/bert/__pycache__/tokenization_bert_tf.cpython-310.pyc,,
+transformers/models/bert/configuration_bert.py,sha256=dv6OswIVpNUrWtI7WmM3XaAA8C8ZB-S3Lzs5Jl9LkVk,7314
+transformers/models/bert/modeling_bert.py,sha256=gkQmqMjis8d7xV8UJglktSaMtdBculkTibLLiLp3oh0,78257
+transformers/models/bert/modeling_flax_bert.py,sha256=xhjDVfsHDHsdFNHwjNRwjHq9wQW5usH-iKpINjBQ7SQ,64027
+transformers/models/bert/modeling_tf_bert.py,sha256=e7HT05UokKQ8fhpOwvksEcSGY0HDsoBAc7Nzb64xOik,94415
+transformers/models/bert/tokenization_bert.py,sha256=Ffkso5F6UuKyFQ_4Ao4op0k9o1Df90qeA9IJpYj2t98,19766
+transformers/models/bert/tokenization_bert_fast.py,sha256=QE60mWbUbQf8D96L5evCqqrN0hRbKz6LKXhg2Hf8T_A,6557
+transformers/models/bert/tokenization_bert_tf.py,sha256=jmvu68QDk-uMMGM3cHF_1n4PtAMf-PLmgk3xtMBzC90,12060
+transformers/models/bert_generation/__init__.py,sha256=sLEyyFf2yI6QflP1lTI9LXUF5PvWBvu-fsaFbjund5I,1059
+transformers/models/bert_generation/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bert_generation/__pycache__/configuration_bert_generation.cpython-310.pyc,,
+transformers/models/bert_generation/__pycache__/modeling_bert_generation.cpython-310.pyc,,
+transformers/models/bert_generation/__pycache__/tokenization_bert_generation.cpython-310.pyc,,
+transformers/models/bert_generation/configuration_bert_generation.py,sha256=KHse7kMgoXgcldz0LMonkb6mmNoVRbQ2U07Q3_p6_fI,6393
+transformers/models/bert_generation/modeling_bert_generation.py,sha256=uM5dlGlRmv_u6gRJgkMt9VmQmx_kxsvubcNn8OvYvzw,39905
+transformers/models/bert_generation/tokenization_bert_generation.py,sha256=yu2PgCmCenfHfutzdLJioGoI2_8r8dbqBL7WmJ6JTZs,7179
+transformers/models/bert_japanese/__init__.py,sha256=94xfgVPnIQuHQxvmc55_EedJlJQTnHiL4va6Ry6x3LE,964
+transformers/models/bert_japanese/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bert_japanese/__pycache__/tokenization_bert_japanese.cpython-310.pyc,,
+transformers/models/bert_japanese/tokenization_bert_japanese.py,sha256=-ehwXShgMWynj6owRC5JCJJOusGVpUFCejcuvbVxPrU,37815
+transformers/models/bertweet/__init__.py,sha256=EZegs0rWTTCiOC_eY-M8eV7bCcwU60dB0HsM1S1VDzQ,959
+transformers/models/bertweet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bertweet/__pycache__/tokenization_bertweet.cpython-310.pyc,,
+transformers/models/bertweet/tokenization_bertweet.py,sha256=9WQZwFonhHf2CvY-r7Xa4TG3x_eLY4BZrNHvmA1hdKg,27007
+transformers/models/big_bird/__init__.py,sha256=3rloOuQNKURURWgk5Td4OBQBAzBdTJ2_fM_CI6yPrV0,1126
+transformers/models/big_bird/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/big_bird/__pycache__/configuration_big_bird.cpython-310.pyc,,
+transformers/models/big_bird/__pycache__/modeling_big_bird.cpython-310.pyc,,
+transformers/models/big_bird/__pycache__/modeling_flax_big_bird.cpython-310.pyc,,
+transformers/models/big_bird/__pycache__/tokenization_big_bird.cpython-310.pyc,,
+transformers/models/big_bird/__pycache__/tokenization_big_bird_fast.cpython-310.pyc,,
+transformers/models/big_bird/configuration_big_bird.py,sha256=qb_lyze6oqg-PSGaAOSUQkHyeg8ApLGP0c76lZ-aFMI,7892
+transformers/models/big_bird/modeling_big_bird.py,sha256=lPW_0_wiz0h0plfPsjHmZjdUthc-oXzVjneT2fqEfRo,130241
+transformers/models/big_bird/modeling_flax_big_bird.py,sha256=ZNo_0dB2U0PWW2sX_sbg3PBC7DpQv5RMfdpES-ZzTUM,109894
+transformers/models/big_bird/tokenization_big_bird.py,sha256=h0RLGmqUBycIt1lo1gMDd3DNVP4dEz__sF5E4XY23yw,13249
+transformers/models/big_bird/tokenization_big_bird_fast.py,sha256=EmJBuqogH76ZeE9ZjX3DIAloL-MyT-Bl7PpmozcntfA,8946
+transformers/models/bigbird_pegasus/__init__.py,sha256=7zOl1EhO8W2S9jE0FsyEoW8kV6yn5bLA0dspGFM1mLQ,1011
+transformers/models/bigbird_pegasus/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bigbird_pegasus/__pycache__/configuration_bigbird_pegasus.cpython-310.pyc,,
+transformers/models/bigbird_pegasus/__pycache__/modeling_bigbird_pegasus.cpython-310.pyc,,
+transformers/models/bigbird_pegasus/configuration_bigbird_pegasus.py,sha256=KCIddfmLPMNb3LIrJY9xSCMasUjRHP6WB-jnedBOeNI,19323
+transformers/models/bigbird_pegasus/modeling_bigbird_pegasus.py,sha256=maUYJFmcm7hI3OkbMz0LgWe1zOdNIDQjpsj8L8AQDtk,142211
+transformers/models/biogpt/__init__.py,sha256=pZxVjmVzt7FXlkMO_5fMg01eyPvvHYXmDA33MKhp6Yk,1032
+transformers/models/biogpt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/biogpt/__pycache__/configuration_biogpt.cpython-310.pyc,,
+transformers/models/biogpt/__pycache__/modeling_biogpt.cpython-310.pyc,,
+transformers/models/biogpt/__pycache__/modular_biogpt.cpython-310.pyc,,
+transformers/models/biogpt/__pycache__/tokenization_biogpt.cpython-310.pyc,,
+transformers/models/biogpt/configuration_biogpt.py,sha256=t544SePN3AO-BjY3nzMW4CH-lMAdxs1TombK682z4fI,6215
+transformers/models/biogpt/modeling_biogpt.py,sha256=ttCQFbuIlVtnQpQHzuvxJYdUbndHEkvACqTCMXb9RjM,42227
+transformers/models/biogpt/modular_biogpt.py,sha256=Qfse7UQO8UsXX3U4Nyw46EYEEe2OSKW2xvLuIEG0m0M,33643
+transformers/models/biogpt/tokenization_biogpt.py,sha256=8Lh_IRa00R-tyz6kAF4zTr48Yl6AcCfvG54ysueGsVU,12157
+transformers/models/bit/__init__.py,sha256=I9z2RYsPRokD1ycMBRLaesbyMKK4MwLPM5oTles2KmQ,1072
+transformers/models/bit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bit/__pycache__/configuration_bit.cpython-310.pyc,,
+transformers/models/bit/__pycache__/image_processing_bit.cpython-310.pyc,,
+transformers/models/bit/__pycache__/image_processing_bit_fast.cpython-310.pyc,,
+transformers/models/bit/__pycache__/modeling_bit.cpython-310.pyc,,
+transformers/models/bit/configuration_bit.py,sha256=wZFP76CJYV7Hn-M4aSRmXn-SxXAsmUUHOLNHP6By6lI,6295
+transformers/models/bit/image_processing_bit.py,sha256=YW-8pzn8uS2Mr0Nof3QBZxuAhXmDCpaNxaWXFJdl_VU,15912
+transformers/models/bit/image_processing_bit_fast.py,sha256=JY4UL4OH2nQ8S66PyIYQaLFFjfhc7rIPaA-hCgmAo6Y,1327
+transformers/models/bit/modeling_bit.py,sha256=qEK3RwKxbKVJHQpMfaQBOOq9D9mNiO3MIAWUO-HBnz4,29643
+transformers/models/bitnet/__init__.py,sha256=0u3B40Xd6dJ7J7TBxJzSQWcyUe2ZWJTbT6iaWVod_-A,1018
+transformers/models/bitnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bitnet/__pycache__/configuration_bitnet.cpython-310.pyc,,
+transformers/models/bitnet/__pycache__/modeling_bitnet.cpython-310.pyc,,
+transformers/models/bitnet/__pycache__/modular_bitnet.cpython-310.pyc,,
+transformers/models/bitnet/configuration_bitnet.py,sha256=H5hN7Qc_TWBcMr3xmF04oRrg36gd_IIs_X-wUMTs47k,6652
+transformers/models/bitnet/modeling_bitnet.py,sha256=TGL5PMhvHp1di-ujQ-pNmkeRYhghfXuMjxwL1i30-V4,21443
+transformers/models/bitnet/modular_bitnet.py,sha256=5VncHTdQ1vaLC6KxEjUPT0q9eZhc5IFomIzzMaF0gLg,5857
+transformers/models/blenderbot/__init__.py,sha256=kdNRND4x54J18VhDVLH6usun5IblSN_9NYaLZfvaysc,1178
+transformers/models/blenderbot/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/blenderbot/__pycache__/configuration_blenderbot.cpython-310.pyc,,
+transformers/models/blenderbot/__pycache__/modeling_blenderbot.cpython-310.pyc,,
+transformers/models/blenderbot/__pycache__/modeling_flax_blenderbot.cpython-310.pyc,,
+transformers/models/blenderbot/__pycache__/modeling_tf_blenderbot.cpython-310.pyc,,
+transformers/models/blenderbot/__pycache__/tokenization_blenderbot.cpython-310.pyc,,
+transformers/models/blenderbot/__pycache__/tokenization_blenderbot_fast.cpython-310.pyc,,
+transformers/models/blenderbot/configuration_blenderbot.py,sha256=NRqxofcj8VdtIozBg7xniPOiyFy1fb3MX4STphPVB8A,18881
+transformers/models/blenderbot/modeling_blenderbot.py,sha256=E8WfnycbGndjFs6RJgP3cOEmRPEXSemsnCrsy6lk90Y,73737
+transformers/models/blenderbot/modeling_flax_blenderbot.py,sha256=ETs29jtKfDjSBL-y7VJcdnHPHu_OGsvr4U5vmeVtRo8,65181
+transformers/models/blenderbot/modeling_tf_blenderbot.py,sha256=zzZt4rlKifDEhE7H-EsSDbavzBRCZl2XJE6mQgOe7-4,72662
+transformers/models/blenderbot/tokenization_blenderbot.py,sha256=sfqSGJEl-owb9-MHxG97G4BQdB6rSv9d17y7xlbLJCw,18223
+transformers/models/blenderbot/tokenization_blenderbot_fast.py,sha256=Bn6KZaUr2-LwmvHQmOMo6TfqwLxbm_-AXarQw4iP9bQ,12448
+transformers/models/blenderbot_small/__init__.py,sha256=QsmmBSPdTC43EIyYBwo-xTyJjLLVqm4Cx-KFJ9O2mfE,1214
+transformers/models/blenderbot_small/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/blenderbot_small/__pycache__/configuration_blenderbot_small.cpython-310.pyc,,
+transformers/models/blenderbot_small/__pycache__/modeling_blenderbot_small.cpython-310.pyc,,
+transformers/models/blenderbot_small/__pycache__/modeling_flax_blenderbot_small.cpython-310.pyc,,
+transformers/models/blenderbot_small/__pycache__/modeling_tf_blenderbot_small.cpython-310.pyc,,
+transformers/models/blenderbot_small/__pycache__/tokenization_blenderbot_small.cpython-310.pyc,,
+transformers/models/blenderbot_small/__pycache__/tokenization_blenderbot_small_fast.cpython-310.pyc,,
+transformers/models/blenderbot_small/configuration_blenderbot_small.py,sha256=mok0lacLLkSC3LlQ6C6UxDBHZRBWW1pEUGyjAbamVco,18323
+transformers/models/blenderbot_small/modeling_blenderbot_small.py,sha256=gZGoqT8_1iHCgFeiS3QiTuqJbHFUaGJZbQEDqffrHvI,71983
+transformers/models/blenderbot_small/modeling_flax_blenderbot_small.py,sha256=4gn7JguFgvff3qE1Yspggo998Ai1ycs6CwJFXJv9zok,66171
+transformers/models/blenderbot_small/modeling_tf_blenderbot_small.py,sha256=9yF-h3X3_ZH-YC4R_WTi4VuQRV8vupHwP6AaNrrs3B4,71604
+transformers/models/blenderbot_small/tokenization_blenderbot_small.py,sha256=ygaUGnIJLrPKz1jOJY9tgL97t9-OUMFegcNJXm9wnRU,7945
+transformers/models/blenderbot_small/tokenization_blenderbot_small_fast.py,sha256=v28mfjk2dPGKH3YLRhol45ZsYFqXTfTCXlPtk4MK9-A,3361
+transformers/models/blip/__init__.py,sha256=aWgKd8B53KWjNBpR7xREMajO43tIo4sRcEjZUGMt8TI,1226
+transformers/models/blip/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/blip/__pycache__/configuration_blip.cpython-310.pyc,,
+transformers/models/blip/__pycache__/image_processing_blip.cpython-310.pyc,,
+transformers/models/blip/__pycache__/image_processing_blip_fast.cpython-310.pyc,,
+transformers/models/blip/__pycache__/modeling_blip.cpython-310.pyc,,
+transformers/models/blip/__pycache__/modeling_blip_text.cpython-310.pyc,,
+transformers/models/blip/__pycache__/modeling_tf_blip.cpython-310.pyc,,
+transformers/models/blip/__pycache__/modeling_tf_blip_text.cpython-310.pyc,,
+transformers/models/blip/__pycache__/processing_blip.cpython-310.pyc,,
+transformers/models/blip/configuration_blip.py,sha256=_i_EKea4_h_16az8_o0jL9-Os0nXbP6iNwQaqrlnz44,14430
+transformers/models/blip/image_processing_blip.py,sha256=GvrRHRmVWtgy1Seu96IAzeW_S4Lu9_LFIk8DYO8U16Q,15320
+transformers/models/blip/image_processing_blip_fast.py,sha256=0gEkLRg06PJYQk6gpm15N3nQsPZtstosy_kxMkY8CS8,1312
+transformers/models/blip/modeling_blip.py,sha256=YVDZiLsYp56NKaI05xcWKgmnnZ95ZdySLII_6sRBwt4,59265
+transformers/models/blip/modeling_blip_text.py,sha256=XC5dIdfZwunZfd_UO-V65xMtlLjE3jeYNWaKzIjj7us,45511
+transformers/models/blip/modeling_tf_blip.py,sha256=M1B1RZxL9JDZIvhM05QMI0VL6Y3tKqwZdvT9FJM58xE,71427
+transformers/models/blip/modeling_tf_blip_text.py,sha256=asEmINloo3IGhWYpwzPsj7IxjMlOlxe5cDGO3yZpHXU,49960
+transformers/models/blip/processing_blip.py,sha256=jvqZtIMf7xApS3N_xWjVBixdf6RSPVU2i3WviL3JiXE,5367
+transformers/models/blip_2/__init__.py,sha256=kj_6H0rQ7dLoQk-COIb06LlDRnbORu3GLU3m4EdMkAM,1030
+transformers/models/blip_2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/blip_2/__pycache__/configuration_blip_2.cpython-310.pyc,,
+transformers/models/blip_2/__pycache__/modeling_blip_2.cpython-310.pyc,,
+transformers/models/blip_2/__pycache__/processing_blip_2.cpython-310.pyc,,
+transformers/models/blip_2/configuration_blip_2.py,sha256=Ysb_dx8tf5TRrNw3vIjwp1xuKQF4-L_U2TyUOZdepR8,16177
+transformers/models/blip_2/modeling_blip_2.py,sha256=eDP4d1fBCRqCh4C8vnETTaA7jaNm6TM4E1QyA_T-kRc,104909
+transformers/models/blip_2/processing_blip_2.py,sha256=8iDZKICKYMwjTU-bByDSaxAxf-daYCIW6ZRNyIBijhI,7087
+transformers/models/bloom/__init__.py,sha256=lcq09Py2vSezUf26aaBG4yp2DpLZ-mAPt-fybvY_C-Q,1073
+transformers/models/bloom/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bloom/__pycache__/configuration_bloom.cpython-310.pyc,,
+transformers/models/bloom/__pycache__/modeling_bloom.cpython-310.pyc,,
+transformers/models/bloom/__pycache__/modeling_flax_bloom.cpython-310.pyc,,
+transformers/models/bloom/__pycache__/tokenization_bloom_fast.cpython-310.pyc,,
+transformers/models/bloom/configuration_bloom.py,sha256=O9X_juvNPqEuxlwJQN-jPJqj8d0SROTHERYlSCEf_C4,10216
+transformers/models/bloom/modeling_bloom.py,sha256=5QbTnU8v3yTCZnQA_HNYz_J3U_quxtBlLVE3kF9gd2s,56179
+transformers/models/bloom/modeling_flax_bloom.py,sha256=JRj-42JcNa40WjWRnQ6Q-aAsZVxd1zuNN59lf1MGinM,30197
+transformers/models/bloom/tokenization_bloom_fast.py,sha256=ViQsNhssK_0gFtEHraJXLRJyHVgjAbBp0tmRbIsviVg,6277
+transformers/models/bridgetower/__init__.py,sha256=S9u22GAHi1LVcS3OYGBzfBVTjDvk_WU9JZGPTEo6zxw,1146
+transformers/models/bridgetower/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bridgetower/__pycache__/configuration_bridgetower.cpython-310.pyc,,
+transformers/models/bridgetower/__pycache__/image_processing_bridgetower.cpython-310.pyc,,
+transformers/models/bridgetower/__pycache__/image_processing_bridgetower_fast.cpython-310.pyc,,
+transformers/models/bridgetower/__pycache__/modeling_bridgetower.cpython-310.pyc,,
+transformers/models/bridgetower/__pycache__/processing_bridgetower.cpython-310.pyc,,
+transformers/models/bridgetower/configuration_bridgetower.py,sha256=EtrVtgjiemvmV-CjJnnl98BQGepG77YRYUrK1lMsORU,14416
+transformers/models/bridgetower/image_processing_bridgetower.py,sha256=1Br7smH6p2N58Mp5Iieri4iMlzD5BJsBVimczjIj9Yg,26443
+transformers/models/bridgetower/image_processing_bridgetower_fast.py,sha256=rKe-NvlESU0wYt2_V_iW9BdRWX-qhyeMMWVgTHIzIfo,13284
+transformers/models/bridgetower/modeling_bridgetower.py,sha256=tm5nnv4kjL2nbdFFdlP58jQlj2fFMMDcLoaNKeYqZzg,85201
+transformers/models/bridgetower/processing_bridgetower.py,sha256=fxkBfPSD_fVS_hfrc9ebvt2RcTkmg8aeC-bV_FGil9k,3537
+transformers/models/bros/__init__.py,sha256=wT0avJ_J50-WK6jOB-6UbgN5kjHiBwG-NNT_iefMXr8,1024
+transformers/models/bros/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/bros/__pycache__/configuration_bros.cpython-310.pyc,,
+transformers/models/bros/__pycache__/modeling_bros.cpython-310.pyc,,
+transformers/models/bros/__pycache__/processing_bros.cpython-310.pyc,,
+transformers/models/bros/configuration_bros.py,sha256=9Vgmvk3hZ-VccsOGhB8OlUPjM5ojPufSIBHa2oY4I5I,6418
+transformers/models/bros/modeling_bros.py,sha256=a28uSFQ7cTiUjj-B4fTWvJINa0ImNHwMZSMu-9KTdSo,49250
+transformers/models/bros/processing_bros.py,sha256=5Jetwbbq4Id-3n9X5bK2mDA5VSKZLRPA1xFzRXHNFIg,3436
+transformers/models/byt5/__init__.py,sha256=O7yXvHyqMZ7stkKX67knnddmJ81pPHoKrY_7NCAauU4,955
+transformers/models/byt5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/byt5/__pycache__/tokenization_byt5.cpython-310.pyc,,
+transformers/models/byt5/tokenization_byt5.py,sha256=ALgzHke0kQEe_3bopDv8r2TXfkaq2tQAM61DmzmQ8MU,10046
+transformers/models/camembert/__init__.py,sha256=hfxYgJYchvXLwio03yWsATGmrU2hgKOoiw7gaNoVgj8,1129
+transformers/models/camembert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/camembert/__pycache__/configuration_camembert.cpython-310.pyc,,
+transformers/models/camembert/__pycache__/modeling_camembert.cpython-310.pyc,,
+transformers/models/camembert/__pycache__/modeling_tf_camembert.cpython-310.pyc,,
+transformers/models/camembert/__pycache__/tokenization_camembert.cpython-310.pyc,,
+transformers/models/camembert/__pycache__/tokenization_camembert_fast.cpython-310.pyc,,
+transformers/models/camembert/configuration_camembert.py,sha256=kf91zHJLL5_C_1OnJwPthKDj_636CNffChcfRs-epqg,7429
+transformers/models/camembert/modeling_camembert.py,sha256=_pKo3EBwzrjmyg2JH4FmiRXSw6HvE8FZ2zF5VgQKU24,72426
+transformers/models/camembert/modeling_tf_camembert.py,sha256=onjWfIs2bL12BpsnRUkjmBlGUCbDJ_2zsFYd89q6uEQ,81596
+transformers/models/camembert/tokenization_camembert.py,sha256=OaoBvDD4XRNLdCgRGCJCFnjznbVNt_ApfKkGj76WxHM,14075
+transformers/models/camembert/tokenization_camembert_fast.py,sha256=dDsFP_EvbYbt3kDWcj5BXEf-mbYQ-i4VNordbhOk5_E,8159
+transformers/models/canine/__init__.py,sha256=ThkEqO6wPzWCnAplx0EWCUqVaKKsNYQKXQhWfTblEBU,1032
+transformers/models/canine/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/canine/__pycache__/configuration_canine.cpython-310.pyc,,
+transformers/models/canine/__pycache__/modeling_canine.cpython-310.pyc,,
+transformers/models/canine/__pycache__/tokenization_canine.cpython-310.pyc,,
+transformers/models/canine/configuration_canine.py,sha256=8Rlt-y-lkY4Jwzi4Aa7NXN4TJtDoQylbogUOjt_q9IA,6584
+transformers/models/canine/modeling_canine.py,sha256=qNGPHXpKMBxa9IdP5VLm7K2jmFIWkvsXS-i3X5QsfKw,68562
+transformers/models/canine/tokenization_canine.py,sha256=hgz1yAdqqYWg6LkijfpzgataobP19GiOqwcUhQJZvtI,8194
+transformers/models/chameleon/__init__.py,sha256=EJ5kOvTyCFQjjWv9h4CMGHDRjQZ3CJ6j9Ygk2bEylA0,1136
+transformers/models/chameleon/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/chameleon/__pycache__/configuration_chameleon.cpython-310.pyc,,
+transformers/models/chameleon/__pycache__/image_processing_chameleon.cpython-310.pyc,,
+transformers/models/chameleon/__pycache__/image_processing_chameleon_fast.cpython-310.pyc,,
+transformers/models/chameleon/__pycache__/modeling_chameleon.cpython-310.pyc,,
+transformers/models/chameleon/__pycache__/processing_chameleon.cpython-310.pyc,,
+transformers/models/chameleon/configuration_chameleon.py,sha256=hZwZ8pOjKFZa-urI7HFe-Nsk_4rWDKCDxDP-o3NjzvE,13413
+transformers/models/chameleon/image_processing_chameleon.py,sha256=W27Q49dJ7g8wLujPwHtCKMFctcDFR01t23HdQUKWcsM,16927
+transformers/models/chameleon/image_processing_chameleon_fast.py,sha256=6ALWS-g82vjxaAYQ52EkPGd_zjsEe1o5zmoA9XOmfNc,4334
+transformers/models/chameleon/modeling_chameleon.py,sha256=ehoQbPDG18dAPXOMlEg_FZnl_p1JDUiWTLTuuE76epU,51181
+transformers/models/chameleon/processing_chameleon.py,sha256=imJTMQ_-y7Q_EMIE76o1WNZwqor7mKHueFyHuNircn4,9170
+transformers/models/chinese_clip/__init__.py,sha256=-koN80ZGdGEDnTkLDGSDlzQ3fZcahTtaOgjtl3sddSE,1202
+transformers/models/chinese_clip/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/chinese_clip/__pycache__/configuration_chinese_clip.cpython-310.pyc,,
+transformers/models/chinese_clip/__pycache__/feature_extraction_chinese_clip.cpython-310.pyc,,
+transformers/models/chinese_clip/__pycache__/image_processing_chinese_clip.cpython-310.pyc,,
+transformers/models/chinese_clip/__pycache__/image_processing_chinese_clip_fast.cpython-310.pyc,,
+transformers/models/chinese_clip/__pycache__/modeling_chinese_clip.cpython-310.pyc,,
+transformers/models/chinese_clip/__pycache__/processing_chinese_clip.cpython-310.pyc,,
+transformers/models/chinese_clip/configuration_chinese_clip.py,sha256=aut4tOdmgvWV5LN3D75LJRhKTNDRHMt9KJ6bmJQDrEw,20310
+transformers/models/chinese_clip/feature_extraction_chinese_clip.py,sha256=hZDBWu4SqNaqbxgA6EE-WZd4Qs8tmqPgXQjveRB5bnU,1366
+transformers/models/chinese_clip/image_processing_chinese_clip.py,sha256=aXemdDs0TG7UtL6dfjZyEawug-KdzJbiicthNYVBD1k,15548
+transformers/models/chinese_clip/image_processing_chinese_clip_fast.py,sha256=XkNJybi8fcwuB7_uN33KN61wDRJcNvXSuY7yUKKSr2k,1347
+transformers/models/chinese_clip/modeling_chinese_clip.py,sha256=ZyxO6a22OPQwEMkywnMIP8hHYksdxaEAteB0pgGDvtw,53611
+transformers/models/chinese_clip/processing_chinese_clip.py,sha256=1p7CCAeRV2a8O9lYe9xiTqeDetvzaP30ef7ygo2Mn3Y,6670
+transformers/models/clap/__init__.py,sha256=751udHbsD7FBLGAByjx_8Z4XPLly1MaQQ4wKN_9vbOY,1067
+transformers/models/clap/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/clap/__pycache__/configuration_clap.cpython-310.pyc,,
+transformers/models/clap/__pycache__/feature_extraction_clap.cpython-310.pyc,,
+transformers/models/clap/__pycache__/modeling_clap.cpython-310.pyc,,
+transformers/models/clap/__pycache__/processing_clap.cpython-310.pyc,,
+transformers/models/clap/configuration_clap.py,sha256=jTnfuJQv3FHs0rP7nfJPMRk4bz6MtsjHXdS1ZL_um-I,18343
+transformers/models/clap/feature_extraction_clap.py,sha256=b-WKqQwRdmTU9kC3mVwx4wpcBOTA4s3XiovfnvyyfZM,18828
+transformers/models/clap/modeling_clap.py,sha256=8mzf8kx4EhYDsUf0kgai1Zslrvb6_KA7fPAuSRRyykU,83842
+transformers/models/clap/processing_clap.py,sha256=GH3RWJTe54ZmBLfCspCaDp_-HqYvmqSnjJ79g_1OxGY,4808
+transformers/models/clip/__init__.py,sha256=bkfM4LH7u_ab8C6cctpvdgySHyQmUaSlWphG4CkcQtg,1307
+transformers/models/clip/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/clip/__pycache__/configuration_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/feature_extraction_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/image_processing_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/image_processing_clip_fast.cpython-310.pyc,,
+transformers/models/clip/__pycache__/modeling_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/modeling_flax_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/modeling_tf_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/processing_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/tokenization_clip.cpython-310.pyc,,
+transformers/models/clip/__pycache__/tokenization_clip_fast.cpython-310.pyc,,
+transformers/models/clip/configuration_clip.py,sha256=mxIZbRQW7zJ0hcCTvI-95tMuJsrrr0-e8wOekflDfXw,18900
+transformers/models/clip/feature_extraction_clip.py,sha256=45gMszIrxGAwWmVEjEOF7GmpoWAkUnG9YQnb60wT_7I,1284
+transformers/models/clip/image_processing_clip.py,sha256=Y2HZoKOiYDAbMHlVzHL-icjm7DIiSuo4_Huzg-1SsKg,17019
+transformers/models/clip/image_processing_clip_fast.py,sha256=19Xm-DXHVL7IU8xmCwJJEuiiIMDFwWw0uBQFaVAi4So,1407
+transformers/models/clip/modeling_clip.py,sha256=EU6uPDPqqLqDp1jBbxIWwkGtIjJ9j7gnWszpnST5zGU,52925
+transformers/models/clip/modeling_flax_clip.py,sha256=LrZPnOAh57jEZwhEMXzX1hsPf_RliNPYtjsnMYk_TOg,50791
+transformers/models/clip/modeling_tf_clip.py,sha256=Mcc1NH0iwm6sqsfznhjNCpXzaX105CnC7PID1GWndV0,60317
+transformers/models/clip/processing_clip.py,sha256=CHYZ5g_B6VMIZpdeIbbB8oN5F9ITQXVQ_yRtrYg95AI,6291
+transformers/models/clip/tokenization_clip.py,sha256=-WrPr-t8Kr-HXnL3tdXbj_FFladaDPLMNk78I7ROK5Y,20554
+transformers/models/clip/tokenization_clip_fast.py,sha256=Z9_w8hpW0NwYpF-HZPP6-gLuKwrq_rcHYcliP5EU3VM,6766
+transformers/models/clipseg/__init__.py,sha256=12Y-b3sRDKM3Hy8-6rK4GUF2a91V1S3nLUF7559AALw,1033
+transformers/models/clipseg/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/clipseg/__pycache__/configuration_clipseg.cpython-310.pyc,,
+transformers/models/clipseg/__pycache__/modeling_clipseg.cpython-310.pyc,,
+transformers/models/clipseg/__pycache__/processing_clipseg.cpython-310.pyc,,
+transformers/models/clipseg/configuration_clipseg.py,sha256=VxzkSvhASsaxVNzM4Ypp5XygKiDO-eo2EhznIVVsRIc,18855
+transformers/models/clipseg/modeling_clipseg.py,sha256=cJ3CODleX4MPQ25DMyHYc6O6ZwEIBXBZqFwMYXQw5c4,59417
+transformers/models/clipseg/processing_clipseg.py,sha256=XhZ7ueGxVSVCgLCBxV5qooSeNDcgoWA_pixTlZmCad0,7240
+transformers/models/clvp/__init__.py,sha256=RRnPofxkr_llgSxCP9tcAhu3xCR7E_m1PkrHv7KLMzo,1104
+transformers/models/clvp/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/clvp/__pycache__/configuration_clvp.cpython-310.pyc,,
+transformers/models/clvp/__pycache__/feature_extraction_clvp.cpython-310.pyc,,
+transformers/models/clvp/__pycache__/modeling_clvp.cpython-310.pyc,,
+transformers/models/clvp/__pycache__/number_normalizer.cpython-310.pyc,,
+transformers/models/clvp/__pycache__/processing_clvp.cpython-310.pyc,,
+transformers/models/clvp/__pycache__/tokenization_clvp.cpython-310.pyc,,
+transformers/models/clvp/configuration_clvp.py,sha256=-coBzCPB5o6HbwdQ-b0JWxMERxkAWPFM4mTI5fazcQs,20257
+transformers/models/clvp/feature_extraction_clvp.py,sha256=l6Jr-23VBpVr1cZVATLVxTh9vNeuA3cKZkqrL83sSPI,10995
+transformers/models/clvp/modeling_clvp.py,sha256=GwO0tyeUQEtgrNcxWNUl_Q0yz2y6LFKLilW7th5eWjk,86797
+transformers/models/clvp/number_normalizer.py,sha256=0zNI1TWJCMJ4i9VxrirCDeX_wjEV02G0_Ig8xdmD-LY,8933
+transformers/models/clvp/processing_clvp.py,sha256=qZrSHn8_TGPfxFp-bZ51pdqBBAmeyF7XViFeUg9GLcc,2810
+transformers/models/clvp/tokenization_clvp.py,sha256=G5O6ykpxfuJLaej8mgkjty3UNEnTL47e5RfvVVJ7P8Q,14808
+transformers/models/code_llama/__init__.py,sha256=aZJA9qTifG-RGtJKMzfspfxuQkaBryVva7Ah_uGNMoM,1009
+transformers/models/code_llama/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/code_llama/__pycache__/tokenization_code_llama.cpython-310.pyc,,
+transformers/models/code_llama/__pycache__/tokenization_code_llama_fast.cpython-310.pyc,,
+transformers/models/code_llama/tokenization_code_llama.py,sha256=BLEp72WT3fN8px65zzBn9bcwv30ThoDflE2267TJ8Xk,19314
+transformers/models/code_llama/tokenization_code_llama_fast.py,sha256=1ca69b8iic_Q61Fy9frmt6maw8DnQxxSBhBexILkltw,15832
+transformers/models/codegen/__init__.py,sha256=NeUIbS8szfu5R9-7CX_G6730RHOODzTfmrapJH2ApMk,1080
+transformers/models/codegen/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/codegen/__pycache__/configuration_codegen.cpython-310.pyc,,
+transformers/models/codegen/__pycache__/modeling_codegen.cpython-310.pyc,,
+transformers/models/codegen/__pycache__/tokenization_codegen.cpython-310.pyc,,
+transformers/models/codegen/__pycache__/tokenization_codegen_fast.cpython-310.pyc,,
+transformers/models/codegen/configuration_codegen.py,sha256=c0KsyyBNKsPFMf2TL_5lOS_DztoS-cOphRasNOI2e5I,9574
+transformers/models/codegen/modeling_codegen.py,sha256=WYfoq5REqFX45vvglCQ7farK8kJyhtvbmUcqd4x9lCo,29594
+transformers/models/codegen/tokenization_codegen.py,sha256=ih2YU6A9RW2oPI6dyXsxx8WUHeKcibwmtyWOu3vbuHY,15365
+transformers/models/codegen/tokenization_codegen_fast.py,sha256=wiHxam7coCyQR5L1LAgcYCBgwCUUhaLZwyF2lr7WK7w,9650
+transformers/models/cohere/__init__.py,sha256=1Tg-6WGc5wgGduSR__N-jGZvPje9kNs92DW78vN0Auo,1037
+transformers/models/cohere/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/cohere/__pycache__/configuration_cohere.cpython-310.pyc,,
+transformers/models/cohere/__pycache__/modeling_cohere.cpython-310.pyc,,
+transformers/models/cohere/__pycache__/modular_cohere.cpython-310.pyc,,
+transformers/models/cohere/__pycache__/tokenization_cohere_fast.cpython-310.pyc,,
+transformers/models/cohere/configuration_cohere.py,sha256=cuNOpFFmlh-aqWbY7M771gr1Efo4ScohzJ7AXN1cXAs,11162
+transformers/models/cohere/modeling_cohere.py,sha256=ZfNMK0DN30sMltpO8q224greulgBzaZbvjxd2jmTsDE,24370
+transformers/models/cohere/modular_cohere.py,sha256=RIWt_QY7uCt_dXGzT8ZYTcftZApp2eaOxi0VelmZsBw,16238
+transformers/models/cohere/tokenization_cohere_fast.py,sha256=SFaANeLr0Kw4zx-ItLTA13UBGZulMlBdO7d9FqJBxnU,28818
+transformers/models/cohere2/__init__.py,sha256=6Cx_c-uTSNopbO3NLWCgMmEB2-5hzkrunUWmMrb8YSU,1011
+transformers/models/cohere2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/cohere2/__pycache__/configuration_cohere2.cpython-310.pyc,,
+transformers/models/cohere2/__pycache__/modeling_cohere2.cpython-310.pyc,,
+transformers/models/cohere2/__pycache__/modular_cohere2.cpython-310.pyc,,
+transformers/models/cohere2/configuration_cohere2.py,sha256=7tHWlR5FLhOWwR9d_JTMBs1sbFugq-NM6UN4UeOq1qk,13024
+transformers/models/cohere2/modeling_cohere2.py,sha256=SxCdm6Qvpz6oD0EI2pBrWxM5sC2HtIDEtucfzVlnB7I,23712
+transformers/models/cohere2/modular_cohere2.py,sha256=_4hi9xiTE-S3rRs1tjVyAq7N0IjnlVbxldc-GCrS8Zw,20964
+transformers/models/cohere2_vision/__init__.py,sha256=VZPnI0ugmeUt8tHNLXhSF1X4maFa0T4pqnm3VAPEyo0,1110
+transformers/models/cohere2_vision/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/cohere2_vision/__pycache__/configuration_cohere2_vision.cpython-310.pyc,,
+transformers/models/cohere2_vision/__pycache__/image_processing_cohere2_vision_fast.cpython-310.pyc,,
+transformers/models/cohere2_vision/__pycache__/modeling_cohere2_vision.cpython-310.pyc,,
+transformers/models/cohere2_vision/__pycache__/modular_cohere2_vision.cpython-310.pyc,,
+transformers/models/cohere2_vision/__pycache__/processing_cohere2_vision.cpython-310.pyc,,
+transformers/models/cohere2_vision/configuration_cohere2_vision.py,sha256=-TEQe4n_754S1-kA224CiSpwDccDWeqAgBRQiN6zZZ8,3516
+transformers/models/cohere2_vision/image_processing_cohere2_vision_fast.py,sha256=xzqwNkVZMDJ1Y5ofKjnADzvpb6-VksRdsNy5jpXT76I,13827
+transformers/models/cohere2_vision/modeling_cohere2_vision.py,sha256=GnX0VrEULILwHuveElxqnymIpUT35ETYeac7pvcHqpM,18375
+transformers/models/cohere2_vision/modular_cohere2_vision.py,sha256=0yQKZAXdAfsQgnhHgLIVELyU7eObmupLA_wnU7H-610,12984
+transformers/models/cohere2_vision/processing_cohere2_vision.py,sha256=V12UAVRARxMMXrp9uQC16mkdYxGp_LanFeCoEc_Pzrw,9865
+transformers/models/colpali/__init__.py,sha256=eG-nOojo-DPkgZJACn6hbJqqfnGE97uKmLkpWVin66A,1033
+transformers/models/colpali/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/colpali/__pycache__/configuration_colpali.cpython-310.pyc,,
+transformers/models/colpali/__pycache__/modeling_colpali.cpython-310.pyc,,
+transformers/models/colpali/__pycache__/modular_colpali.cpython-310.pyc,,
+transformers/models/colpali/__pycache__/processing_colpali.cpython-310.pyc,,
+transformers/models/colpali/configuration_colpali.py,sha256=823j9kFkFOZCVfi0VVC7ActtstXkK2LDfD_Ra9wVv9c,4346
+transformers/models/colpali/modeling_colpali.py,sha256=I-kKuahUTZ1HAll9QjXp2f-UgxDHYm5EBlvfnnDep6s,8584
+transformers/models/colpali/modular_colpali.py,sha256=UTMBS_Ua8GGfQLwb1JwgOBZ8GlMr7mfb4VUwbdLI5yE,15862
+transformers/models/colpali/processing_colpali.py,sha256=2TBONSrAthmzaCr9PY9Z_JZ7iDFntftJTp7-mIpm_bQ,19547
+transformers/models/colqwen2/__init__.py,sha256=GBrOYGkXcXTOuCd6AhVMss6TVb2igEKFcrAkgJbbg-Q,1036
+transformers/models/colqwen2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/colqwen2/__pycache__/configuration_colqwen2.cpython-310.pyc,,
+transformers/models/colqwen2/__pycache__/modeling_colqwen2.cpython-310.pyc,,
+transformers/models/colqwen2/__pycache__/modular_colqwen2.cpython-310.pyc,,
+transformers/models/colqwen2/__pycache__/processing_colqwen2.cpython-310.pyc,,
+transformers/models/colqwen2/configuration_colqwen2.py,sha256=PVLfu66wcfoFKs9MBlafVDYQjUrzOwAbWUpf2YsZjng,3710
+transformers/models/colqwen2/modeling_colqwen2.py,sha256=_eVoPMhdPNXacujicVFNJ8qecYuhCVS4sOU9UtnbS2c,11193
+transformers/models/colqwen2/modular_colqwen2.py,sha256=mFNndOnywVLY_Rg0c-6ApCmEryshc4r6JY06b8FDiso,19188
+transformers/models/colqwen2/processing_colqwen2.py,sha256=_FoTNPOp5Bkt-YCYFdbIH2xKDOQ51u1hu7oOPlHb5Yw,19733
+transformers/models/conditional_detr/__init__.py,sha256=p8luCb38qMZvKdI7GLvBTx1eiKGFMv8Obd5iKaqoVe8,1179
+transformers/models/conditional_detr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/conditional_detr/__pycache__/configuration_conditional_detr.cpython-310.pyc,,
+transformers/models/conditional_detr/__pycache__/feature_extraction_conditional_detr.cpython-310.pyc,,
+transformers/models/conditional_detr/__pycache__/image_processing_conditional_detr.cpython-310.pyc,,
+transformers/models/conditional_detr/__pycache__/image_processing_conditional_detr_fast.cpython-310.pyc,,
+transformers/models/conditional_detr/__pycache__/modeling_conditional_detr.cpython-310.pyc,,
+transformers/models/conditional_detr/__pycache__/modular_conditional_detr.cpython-310.pyc,,
+transformers/models/conditional_detr/configuration_conditional_detr.py,sha256=J0SMZqyKvQ0Bu_og74WVqwm2MuxmYOZQFe1Iw-fVliE,13739
+transformers/models/conditional_detr/feature_extraction_conditional_detr.py,sha256=QwZ7PwpcYVGjSFPluSXbT5oTGM4UgeYSL_q-sybwHgY,1676
+transformers/models/conditional_detr/image_processing_conditional_detr.py,sha256=i_Q6vpJfLv4UDMHCrAJaHS15pp10ZgkHyi_qi2ORRfw,85841
+transformers/models/conditional_detr/image_processing_conditional_detr_fast.py,sha256=3fSuKYzO_fmmiivUq07b2aud9nwfuYaJuoEabh2-WSM,48403
+transformers/models/conditional_detr/modeling_conditional_detr.py,sha256=HWEg5Get6oWAyGazkv2Kb7HKeu29G2cvCy_z2qfvfsY,93497
+transformers/models/conditional_detr/modular_conditional_detr.py,sha256=_Nnn5kIrM4rE9KIqSjC7wBW2ETjE85ky3pVXEmmpv6c,6082
+transformers/models/convbert/__init__.py,sha256=x1Rv5-rurTKFifp3w8N_CNcZ3sHvuFwqpw_Zn1BAenw,1124
+transformers/models/convbert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/convbert/__pycache__/configuration_convbert.cpython-310.pyc,,
+transformers/models/convbert/__pycache__/modeling_convbert.cpython-310.pyc,,
+transformers/models/convbert/__pycache__/modeling_tf_convbert.cpython-310.pyc,,
+transformers/models/convbert/__pycache__/tokenization_convbert.cpython-310.pyc,,
+transformers/models/convbert/__pycache__/tokenization_convbert_fast.cpython-310.pyc,,
+transformers/models/convbert/configuration_convbert.py,sha256=Ml8UytHYCv4-BAeyPTUzUY5ynnX8dIkCIGoumPTqaCc,6895
+transformers/models/convbert/modeling_convbert.py,sha256=H2kKGuwm0g-IiHa4vR7TRRgZLfnBdLfUSy1cVeCN0mA,58383
+transformers/models/convbert/modeling_tf_convbert.py,sha256=mvR9901jo5L-GOvp6QtoY0nORRpwRURQpSxEs3T5X5c,61487
+transformers/models/convbert/tokenization_convbert.py,sha256=nt9KjwTDvJV-IGV_7PsznPWF1_uZj2aR3oL9-Ie56VM,20170
+transformers/models/convbert/tokenization_convbert_fast.py,sha256=3TKalVIkHf4iWJ5mxhbdjS7s6svBsEQUWVdhLSK07G8,6686
+transformers/models/convnext/__init__.py,sha256=QAUm2k3PH0pqhHzPXIhkEmqzMWKYCs4bo0gNVnH_bBw,1179
+transformers/models/convnext/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/convnext/__pycache__/configuration_convnext.cpython-310.pyc,,
+transformers/models/convnext/__pycache__/feature_extraction_convnext.cpython-310.pyc,,
+transformers/models/convnext/__pycache__/image_processing_convnext.cpython-310.pyc,,
+transformers/models/convnext/__pycache__/image_processing_convnext_fast.cpython-310.pyc,,
+transformers/models/convnext/__pycache__/modeling_convnext.cpython-310.pyc,,
+transformers/models/convnext/__pycache__/modeling_tf_convnext.cpython-310.pyc,,
+transformers/models/convnext/configuration_convnext.py,sha256=9m5oXY9Vx3BdADw0k7EeM4n3KrkCb3JA-WOPUlbtr74,6192
+transformers/models/convnext/feature_extraction_convnext.py,sha256=7oC8UpEVxpiIhXIC8Rc3I5YnJExAPEEezSdAUnn1hnw,1316
+transformers/models/convnext/image_processing_convnext.py,sha256=DLLgSmlBRKoZuOCIt3IHTqDqV4SS-jLpERtLmfvqnko,16015
+transformers/models/convnext/image_processing_convnext_fast.py,sha256=40nvdfgAtQHGWNwNLa5MLvnqWKSEOd4MvoEtiZv8750,7200
+transformers/models/convnext/modeling_convnext.py,sha256=41cTskvVVkegIxls_N2JiziZl9Eh9qxcVqTu06u5nCs,17056
+transformers/models/convnext/modeling_tf_convnext.py,sha256=ff7TMHAtYN0Isoaivj1T34Mhzbvx_94YRFZqi8C3u5A,27197
+transformers/models/convnextv2/__init__.py,sha256=kOl9JbYIk9ioImF_hd0BS_mGDC8SG2k5LvO0-7WroRo,1043
+transformers/models/convnextv2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/convnextv2/__pycache__/configuration_convnextv2.cpython-310.pyc,,
+transformers/models/convnextv2/__pycache__/modeling_convnextv2.cpython-310.pyc,,
+transformers/models/convnextv2/__pycache__/modeling_tf_convnextv2.cpython-310.pyc,,
+transformers/models/convnextv2/configuration_convnextv2.py,sha256=bUeneirJLhh_eL1rQZ1Mk_ZSCCzJlg-CwcNNEk0fVjY,5564
+transformers/models/convnextv2/modeling_convnextv2.py,sha256=42gOUxmlxRenX7vMvIW1x_QeIWTUz84cfrK9fkS6XqE,18545
+transformers/models/convnextv2/modeling_tf_convnextv2.py,sha256=KwiYjUc4VGEjurV9SsGN_V28RiGYPn7g7v1MgRgOQ5A,27603
+transformers/models/cpm/__init__.py,sha256=5Oz79wRruzXHciBLUAOGeo6PIH70Vs4ta8ffsMyT1Yg,995
+transformers/models/cpm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/cpm/__pycache__/tokenization_cpm.cpython-310.pyc,,
+transformers/models/cpm/__pycache__/tokenization_cpm_fast.cpython-310.pyc,,
+transformers/models/cpm/tokenization_cpm.py,sha256=FoFU7yUwJTGuny6ZYyjn97gCO3gGGjldWStRPjnKdPY,15114
+transformers/models/cpm/tokenization_cpm_fast.py,sha256=2-jf6ZXKnBM1x38CE2SIpHDkZ_aJs7PN0A-kM_dw5YA,10307
+transformers/models/cpmant/__init__.py,sha256=RfkbbhNqdbioJ5XVaTtxBLnZRt1GFnXugS3UFXHYV0c,1032
+transformers/models/cpmant/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/cpmant/__pycache__/configuration_cpmant.cpython-310.pyc,,
+transformers/models/cpmant/__pycache__/modeling_cpmant.cpython-310.pyc,,
+transformers/models/cpmant/__pycache__/tokenization_cpmant.cpython-310.pyc,,
+transformers/models/cpmant/configuration_cpmant.py,sha256=RvgmQH8lQazRopzpfK5-Hf4eePtXXfvMJ3ar1VQC2vE,5145
+transformers/models/cpmant/modeling_cpmant.py,sha256=YPPI5wlDcwWHIZ_gBRylA99VEcPxI360l0r-tzF2uSI,33731
+transformers/models/cpmant/tokenization_cpmant.py,sha256=v-Ra7sTNzfxA6TPHjglkvlx0D-awCHm9P5VSUoyaTF8,9747
+transformers/models/csm/__init__.py,sha256=n-AQHwxZwD8imEHipiQoTDRf_OMo5zJhQ0tKKWMCPYs,1021
+transformers/models/csm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/csm/__pycache__/configuration_csm.cpython-310.pyc,,
+transformers/models/csm/__pycache__/generation_csm.cpython-310.pyc,,
+transformers/models/csm/__pycache__/modeling_csm.cpython-310.pyc,,
+transformers/models/csm/__pycache__/modular_csm.cpython-310.pyc,,
+transformers/models/csm/__pycache__/processing_csm.cpython-310.pyc,,
+transformers/models/csm/configuration_csm.py,sha256=xhRBdgZbc76V3OMJAcF4EL9wQEi9FVQV8g3f_ZuwxGo,23791
+transformers/models/csm/generation_csm.py,sha256=pYZltTDah__he6zoN70qda4YLH1wdaCHoxS4Whzsmkw,25692
+transformers/models/csm/modeling_csm.py,sha256=VM_J1tINrvuBIDGB8NRVBGbcp8NV3VstjJhDCsayyA8,51017
+transformers/models/csm/modular_csm.py,sha256=0t1qmXCRg2B5IIofNaOkrlLi75vXEcya_URPDU6a8B0,35562
+transformers/models/csm/processing_csm.py,sha256=MdqnSAulUmSKeesqgNaTwQhwgtveg3boY9Q4nzgPlAE,16613
+transformers/models/ctrl/__init__.py,sha256=bVtGijL4n9ewNyhcJt7lpsRhXU8yo4nY0xIlRbpismk,1062
+transformers/models/ctrl/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/ctrl/__pycache__/configuration_ctrl.cpython-310.pyc,,
+transformers/models/ctrl/__pycache__/modeling_ctrl.cpython-310.pyc,,
+transformers/models/ctrl/__pycache__/modeling_tf_ctrl.cpython-310.pyc,,
+transformers/models/ctrl/__pycache__/tokenization_ctrl.cpython-310.pyc,,
+transformers/models/ctrl/configuration_ctrl.py,sha256=Vg6ZFqal5MCr-t2K5pp5mtN2TJSeojgKL8IgbZkd81k,4684
+transformers/models/ctrl/modeling_ctrl.py,sha256=a-mu7ybtVQKicmXwm-fjLq4QfdriIqdtWxkQW_wP-v0,32147
+transformers/models/ctrl/modeling_tf_ctrl.py,sha256=7C954SzmkF6m4uraWukQ2Q_vhD3slx7usn9AXI26YsE,39279
+transformers/models/ctrl/tokenization_ctrl.py,sha256=N6D_85X_YHRvhltFZMVdR5M4ahJWyUvCuUvcFYOL5Lw,8080
+transformers/models/cvt/__init__.py,sha256=i1847SsjrXEIbrXsDEAiUlrtgLZRHtCSVG0rvCPXE9I,1022
+transformers/models/cvt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/cvt/__pycache__/configuration_cvt.cpython-310.pyc,,
+transformers/models/cvt/__pycache__/modeling_cvt.cpython-310.pyc,,
+transformers/models/cvt/__pycache__/modeling_tf_cvt.cpython-310.pyc,,
+transformers/models/cvt/configuration_cvt.py,sha256=zVX0Ht69OHm8ttnbAYbzxtV0kNDKV_qpbSDwToqJMKI,6684
+transformers/models/cvt/modeling_cvt.py,sha256=-gPvYYk8NAfhPiLECVf1yrzY0Fv9lqCd_Mx5j8PFvRo,25898
+transformers/models/cvt/modeling_tf_cvt.py,sha256=cytBTMqcUMvyCbJnEtZY3att6LkoJqDlAN-iX8ucyAQ,43455
+transformers/models/d_fine/__init__.py,sha256=1gNscomeWytwZT7K2GJBwyXxDkfVNLhRjuDwyde2A0s,995
+transformers/models/d_fine/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/d_fine/__pycache__/configuration_d_fine.cpython-310.pyc,,
+transformers/models/d_fine/__pycache__/modeling_d_fine.cpython-310.pyc,,
+transformers/models/d_fine/__pycache__/modular_d_fine.cpython-310.pyc,,
+transformers/models/d_fine/configuration_d_fine.py,sha256=mFg_xcD2t7-evibX5REKeCKg3RKZIdBQsSRtGWnYN6E,22689
+transformers/models/d_fine/modeling_d_fine.py,sha256=8NBWk1UKMND-BJ2cW9139DY99b4GyKs89ve9B_1qdPA,105305
+transformers/models/d_fine/modular_d_fine.py,sha256=LmiEkBuAoJBHxqtAti84zbbjnZ6AZymU5nznLhPPMLU,56815
+transformers/models/dab_detr/__init__.py,sha256=ZvNYPQyXWplaRQIxFR8CURcsnu_HRPXrwojF5nTmGd4,998
+transformers/models/dab_detr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dab_detr/__pycache__/configuration_dab_detr.cpython-310.pyc,,
+transformers/models/dab_detr/__pycache__/modeling_dab_detr.cpython-310.pyc,,
+transformers/models/dab_detr/configuration_dab_detr.py,sha256=LOpJZP2nJtYS9yU2tshuqgtEWWNIojY__pl6Vuekkgg,13756
+transformers/models/dab_detr/modeling_dab_detr.py,sha256=nAuMXGiFl35XdGyyAZF0eRZwuOHGDJ8qAHkbfVPUoMM,74773
+transformers/models/dac/__init__.py,sha256=UpwXPmSOQOwvbIvklM21-y5HKY7MEIInmTt65xMX6Hw,1029
+transformers/models/dac/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dac/__pycache__/configuration_dac.cpython-310.pyc,,
+transformers/models/dac/__pycache__/feature_extraction_dac.cpython-310.pyc,,
+transformers/models/dac/__pycache__/modeling_dac.cpython-310.pyc,,
+transformers/models/dac/configuration_dac.py,sha256=Exf0bhzmsEvxLxSJTOpdjPL6Pc30SHKW1MZ23aVdt1M,4581
+transformers/models/dac/feature_extraction_dac.py,sha256=P7duIMDqPBeXD-LXJwims_O6ZBCFZaDDGTR1AIOkU_k,8059
+transformers/models/dac/modeling_dac.py,sha256=xg69eTcIVa0WjpoAkjYO8QTvewbJ-CcA5BAkzLi85Cc,28736
+transformers/models/data2vec/__init__.py,sha256=-2iFF1Rb8eF9cccBNLA29zgeFV1ADYaSLoQgf6K6KB8,1238
+transformers/models/data2vec/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/configuration_data2vec_audio.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/configuration_data2vec_text.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/configuration_data2vec_vision.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/modeling_data2vec_audio.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/modeling_data2vec_text.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/modeling_data2vec_vision.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/modeling_tf_data2vec_vision.cpython-310.pyc,,
+transformers/models/data2vec/__pycache__/modular_data2vec_audio.cpython-310.pyc,,
+transformers/models/data2vec/configuration_data2vec_audio.py,sha256=SmJMa0tBoQZudlxPe1RvpSq0YwB10GjTCify0NwL6mg,16373
+transformers/models/data2vec/configuration_data2vec_text.py,sha256=EJRVy6uJcVoDFVdMJfGaIOx_cIIW03A58N5X849i7G4,7361
+transformers/models/data2vec/configuration_data2vec_vision.py,sha256=8LsGPjPhFaBXpMF6LrtndMoXTE33pTnfZ1p9Lz06c7k,9314
+transformers/models/data2vec/modeling_data2vec_audio.py,sha256=q2RKNuqtdsxTCa3SKPoq7jG_J1ZxX0V5Aw5t8bvdvAA,59332
+transformers/models/data2vec/modeling_data2vec_text.py,sha256=QLB1sFegKxOBh4xlwLJtERZTsnc62Up_HEgmcffZuOs,60823
+transformers/models/data2vec/modeling_data2vec_vision.py,sha256=OHQVk9dGzXTO1HsPG6kVnlOlPwwcICCyZbUyBp7K_Z8,59610
+transformers/models/data2vec/modeling_tf_data2vec_vision.py,sha256=GO5cK8C7P1jtULl88FYw0T8Thao7E09IMx4whTzq6H0,73392
+transformers/models/data2vec/modular_data2vec_audio.py,sha256=y_ux_oMsO0Gul9oyTl_KJmGwC8nfKkNXPQE_nfviuaA,9355
+transformers/models/dbrx/__init__.py,sha256=Kzn3gm0QHW9RKEmog_IfdCGam5TXSCzkOs_WHC43sgM,989
+transformers/models/dbrx/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dbrx/__pycache__/configuration_dbrx.cpython-310.pyc,,
+transformers/models/dbrx/__pycache__/modeling_dbrx.cpython-310.pyc,,
+transformers/models/dbrx/configuration_dbrx.py,sha256=URihH21WVlyfVL-hRw1YhQ2PtIvQXY77Ig1AiWTsT0o,9946
+transformers/models/dbrx/modeling_dbrx.py,sha256=7yXSlIIA9rESqhZc1BwQ207XzK5mWNgD1YfU4-2Ibj8,55671
+transformers/models/deberta/__init__.py,sha256=diL764eL8gu80XkBDQU9nI6Zy39ArO0d85MtcZ4_NPw,1119
+transformers/models/deberta/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deberta/__pycache__/configuration_deberta.cpython-310.pyc,,
+transformers/models/deberta/__pycache__/modeling_deberta.cpython-310.pyc,,
+transformers/models/deberta/__pycache__/modeling_tf_deberta.cpython-310.pyc,,
+transformers/models/deberta/__pycache__/tokenization_deberta.cpython-310.pyc,,
+transformers/models/deberta/__pycache__/tokenization_deberta_fast.cpython-310.pyc,,
+transformers/models/deberta/configuration_deberta.py,sha256=GFkrPn9TgA3QRrRTYsxFnQRsFRzFHPlpDJwS_HCo9Go,9024
+transformers/models/deberta/modeling_deberta.py,sha256=DLuOBnWZEyRw3p75kK1WRagzXTXReJsB3Er1AdPQ87o,48815
+transformers/models/deberta/modeling_tf_deberta.py,sha256=6rH8jdCWMoxKnurItq1ilWZ8KbaM-IbUGkPECrUMR9M,69231
+transformers/models/deberta/tokenization_deberta.py,sha256=sEbB4J8F0BdwyxfkOnkwPc4AWBHcwRyVE7Ql9AN8R-Q,15951
+transformers/models/deberta/tokenization_deberta_fast.py,sha256=uoJE9AssyGms5uRMxIy3awKj0W8nJ7sYFB0XiZXz47k,9121
+transformers/models/deberta_v2/__init__.py,sha256=N6wcSGakSmmHDW_QelFsn58zuDFTuvbctgkyC0OfQ5Y,1134
+transformers/models/deberta_v2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deberta_v2/__pycache__/configuration_deberta_v2.cpython-310.pyc,,
+transformers/models/deberta_v2/__pycache__/modeling_deberta_v2.cpython-310.pyc,,
+transformers/models/deberta_v2/__pycache__/modeling_tf_deberta_v2.cpython-310.pyc,,
+transformers/models/deberta_v2/__pycache__/tokenization_deberta_v2.cpython-310.pyc,,
+transformers/models/deberta_v2/__pycache__/tokenization_deberta_v2_fast.cpython-310.pyc,,
+transformers/models/deberta_v2/configuration_deberta_v2.py,sha256=96TOPpbrNSW2e-Mvs2D3S-AuKyb8r_kLtStv0TRH_rY,8964
+transformers/models/deberta_v2/modeling_deberta_v2.py,sha256=mPo5j2LkRuH2MD_2f6es7drE90ahpgEyJolsP6TmzdY,56783
+transformers/models/deberta_v2/modeling_tf_deberta_v2.py,sha256=3eJKDG8GQCcDXSKO8AWikBsCQuUZzOOC-tYO1j3yaL0,81610
+transformers/models/deberta_v2/tokenization_deberta_v2.py,sha256=WhRgGdG440RsyEZp6yV9IudKT0F2W8uXf2zLuTvcdY4,19731
+transformers/models/deberta_v2/tokenization_deberta_v2_fast.py,sha256=_i28i-MLIDWhqACnNKhrDcDOopjy2ulJb3R0HYqxBtc,8593
+transformers/models/decision_transformer/__init__.py,sha256=8XAHnFrFv8IFz495cQLTeaAk2G1AVRT7roauVHCGoJs,1021
+transformers/models/decision_transformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/decision_transformer/__pycache__/configuration_decision_transformer.cpython-310.pyc,,
+transformers/models/decision_transformer/__pycache__/modeling_decision_transformer.cpython-310.pyc,,
+transformers/models/decision_transformer/configuration_decision_transformer.py,sha256=hKOOb_TuM0XU7fDQu9sl2o6iNYYt16Dll3JUCKecFB4,7029
+transformers/models/decision_transformer/modeling_decision_transformer.py,sha256=nRP6i9-Mnx_fQoXomt-WyS-NdDlaAnBg3rnvEJAl_lw,43273
+transformers/models/deepseek_v2/__init__.py,sha256=cRpNT946KLnKXl4i2mGlImi9QLOe2a1ocnWNjBSbK68,1005
+transformers/models/deepseek_v2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deepseek_v2/__pycache__/configuration_deepseek_v2.cpython-310.pyc,,
+transformers/models/deepseek_v2/__pycache__/modeling_deepseek_v2.cpython-310.pyc,,
+transformers/models/deepseek_v2/__pycache__/modular_deepseek_v2.cpython-310.pyc,,
+transformers/models/deepseek_v2/configuration_deepseek_v2.py,sha256=8snqY9qX7eRSMd28UfvOdVe8o19ABxcE21ak1WW1XCw,12231
+transformers/models/deepseek_v2/modeling_deepseek_v2.py,sha256=M1tJVPM936jrlryeZ5RXxbvXIpNb4OumF-5ecZalTKU,27604
+transformers/models/deepseek_v2/modular_deepseek_v2.py,sha256=varkskIYneWo5o6B0ugIvXR1au_F8enDKDXtmTSEWQk,23572
+transformers/models/deepseek_v3/__init__.py,sha256=t-ejxAfULC_tUrUucNLt-x3hbTEIqUQp96m2DRFeaTg,1008
+transformers/models/deepseek_v3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deepseek_v3/__pycache__/configuration_deepseek_v3.cpython-310.pyc,,
+transformers/models/deepseek_v3/__pycache__/modeling_deepseek_v3.cpython-310.pyc,,
+transformers/models/deepseek_v3/__pycache__/modular_deepseek_v3.cpython-310.pyc,,
+transformers/models/deepseek_v3/configuration_deepseek_v3.py,sha256=VEcrAJDOUBn4NmPDqAXDZ47gCRGGjZOaKsGL0qSH5xE,12703
+transformers/models/deepseek_v3/modeling_deepseek_v3.py,sha256=2_ghM8dAgcXB59aFPcWdhH0DeJz8JEfunAAHQD9EGL4,30292
+transformers/models/deepseek_v3/modular_deepseek_v3.py,sha256=jzTuU1U5vvRXA89o3oc_LclnaBirYi4whdEekcyYfrM,15682
+transformers/models/deepseek_vl/__init__.py,sha256=ZjpL2NkjCM_tsGMz_fY7bOQ2HQwimj3RL4cocjrEtHI,1162
+transformers/models/deepseek_vl/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deepseek_vl/__pycache__/configuration_deepseek_vl.cpython-310.pyc,,
+transformers/models/deepseek_vl/__pycache__/image_processing_deepseek_vl.cpython-310.pyc,,
+transformers/models/deepseek_vl/__pycache__/image_processing_deepseek_vl_fast.cpython-310.pyc,,
+transformers/models/deepseek_vl/__pycache__/modeling_deepseek_vl.cpython-310.pyc,,
+transformers/models/deepseek_vl/__pycache__/modular_deepseek_vl.cpython-310.pyc,,
+transformers/models/deepseek_vl/__pycache__/processing_deepseek_vl.cpython-310.pyc,,
+transformers/models/deepseek_vl/configuration_deepseek_vl.py,sha256=gGJkOSpesfQyuwzj74EWC6p0TXnGs_74-cStk3aqDpE,4554
+transformers/models/deepseek_vl/image_processing_deepseek_vl.py,sha256=cBJft1M7s6c5-OFDyZ5ISYVL5KA5BDuHIyeb58JlVJw,21061
+transformers/models/deepseek_vl/image_processing_deepseek_vl_fast.py,sha256=VukS6JjyE6bWso8ZuCZh2kr1CqlG9CUA1Ygc_PUIhSw,8163
+transformers/models/deepseek_vl/modeling_deepseek_vl.py,sha256=Cyd11O_yPGG94rlzAKiyfIcvUAyLglBtm4QsNgTTbfY,15635
+transformers/models/deepseek_vl/modular_deepseek_vl.py,sha256=LNk_EVN9aMWg0TnXczQohYFhVFQ_Y8TSPXonNHTCmGI,13571
+transformers/models/deepseek_vl/processing_deepseek_vl.py,sha256=YtkxMLSzWk3oWf5EhytAy3OWf5IFYbVPtVo2i1KJssM,7946
+transformers/models/deepseek_vl_hybrid/__init__.py,sha256=FjSY1MYTEUP8BbAqIG2DZSAzmLh17w8aZr7pUkC_Gto,1257
+transformers/models/deepseek_vl_hybrid/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deepseek_vl_hybrid/__pycache__/configuration_deepseek_vl_hybrid.cpython-310.pyc,,
+transformers/models/deepseek_vl_hybrid/__pycache__/image_processing_deepseek_vl_hybrid.cpython-310.pyc,,
+transformers/models/deepseek_vl_hybrid/__pycache__/image_processing_deepseek_vl_hybrid_fast.cpython-310.pyc,,
+transformers/models/deepseek_vl_hybrid/__pycache__/modeling_deepseek_vl_hybrid.cpython-310.pyc,,
+transformers/models/deepseek_vl_hybrid/__pycache__/modular_deepseek_vl_hybrid.cpython-310.pyc,,
+transformers/models/deepseek_vl_hybrid/__pycache__/processing_deepseek_vl_hybrid.cpython-310.pyc,,
+transformers/models/deepseek_vl_hybrid/configuration_deepseek_vl_hybrid.py,sha256=0wPzB5AuZjiPr3RYugMklRgxOw2QrKVFFHJWfWnlpw4,5448
+transformers/models/deepseek_vl_hybrid/image_processing_deepseek_vl_hybrid.py,sha256=5canobnDUax7ALGK3scDDhgBXCbK-8bX8NpiKF-mJZw,26056
+transformers/models/deepseek_vl_hybrid/image_processing_deepseek_vl_hybrid_fast.py,sha256=mhfYNiwfiiHTI8aMBbH_eRczpBJzo67AsIDTol5O_F8,15025
+transformers/models/deepseek_vl_hybrid/modeling_deepseek_vl_hybrid.py,sha256=mCUqwrtW00OEstmFayTkKqrKDmTGHUkw-bMUGn_Y3iA,22700
+transformers/models/deepseek_vl_hybrid/modular_deepseek_vl_hybrid.py,sha256=gucjMHWEf6M05NyTK8wRzfQ9g5IuAGajLw55fkLCJeg,47664
+transformers/models/deepseek_vl_hybrid/processing_deepseek_vl_hybrid.py,sha256=J_XhJeawMudDkACWSXAXO_gIyiH4mf8Uo-WPYde12Ys,8156
+transformers/models/deformable_detr/__init__.py,sha256=_ae-sABBY17hOT28SN_d0GLeRVjya0W4aqniH8u8Bcw,1176
+transformers/models/deformable_detr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deformable_detr/__pycache__/configuration_deformable_detr.cpython-310.pyc,,
+transformers/models/deformable_detr/__pycache__/feature_extraction_deformable_detr.cpython-310.pyc,,
+transformers/models/deformable_detr/__pycache__/image_processing_deformable_detr.cpython-310.pyc,,
+transformers/models/deformable_detr/__pycache__/image_processing_deformable_detr_fast.cpython-310.pyc,,
+transformers/models/deformable_detr/__pycache__/modeling_deformable_detr.cpython-310.pyc,,
+transformers/models/deformable_detr/__pycache__/modular_deformable_detr.cpython-310.pyc,,
+transformers/models/deformable_detr/configuration_deformable_detr.py,sha256=5CRV4cdMS_5N4NS8Qa9ymAKocEaGIegCQ0xFmwA-Ijw,14794
+transformers/models/deformable_detr/feature_extraction_deformable_detr.py,sha256=ifv-_D_b2_5GsavP72mH6etQoobhFYmf2NB4Fyl9nP0,1668
+transformers/models/deformable_detr/image_processing_deformable_detr.py,sha256=H_uocXcWTi-TJFckX6s-IepwMsOW7mCq4XlZ1p5iuM0,73297
+transformers/models/deformable_detr/image_processing_deformable_detr_fast.py,sha256=TtQiEJcmYLKq54oUvLwQt1qD85cd2nu2nFPRyirf4iM,36378
+transformers/models/deformable_detr/modeling_deformable_detr.py,sha256=uY7H7hijV90awF5LSW7laGtdBpfLmwJ0ZccS_-iJ0S0,88573
+transformers/models/deformable_detr/modular_deformable_detr.py,sha256=pFFZknbkPCW6EaA8JC_vJv8weqzwtUfQ7aHa4SpCscg,6573
+transformers/models/deit/__init__.py,sha256=8S1h-sIvhRy1EiQ7DKXHqqNEgR0_juhrAyQZ2AU1rVw,1155
+transformers/models/deit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deit/__pycache__/configuration_deit.cpython-310.pyc,,
+transformers/models/deit/__pycache__/feature_extraction_deit.cpython-310.pyc,,
+transformers/models/deit/__pycache__/image_processing_deit.cpython-310.pyc,,
+transformers/models/deit/__pycache__/image_processing_deit_fast.cpython-310.pyc,,
+transformers/models/deit/__pycache__/modeling_deit.cpython-310.pyc,,
+transformers/models/deit/__pycache__/modeling_tf_deit.cpython-310.pyc,,
+transformers/models/deit/configuration_deit.py,sha256=qd4pscfJKPWbxhmdCzj1Fdv19o8KPIuXwJpUI04Puf4,6375
+transformers/models/deit/feature_extraction_deit.py,sha256=0kfS_x_-B8O9b6ECuj3kosuPP9bwHKO_ZzjuvkBnPsc,1284
+transformers/models/deit/image_processing_deit.py,sha256=5n6oeHNAsl8GrCKNLO6mR6qhQlFkUOBWxKkzE_wzlE8,15332
+transformers/models/deit/image_processing_deit_fast.py,sha256=DrJaX0I_Pu2tihvqPrsUZRdIWFTtH4BrTKT22RqVfYU,1399
+transformers/models/deit/modeling_deit.py,sha256=JHXN_GzhASwcopI7-OBqfvBZzU9JROYVlilJgDF4mbY,32912
+transformers/models/deit/modeling_tf_deit.py,sha256=iGVk1mPqdtOAbd6jo5j3gbueqXA30JVy7XBs2tE9kRY,51676
+transformers/models/deprecated/__init__.py,sha256=upBgfMVSzFMxNZYSd4AXNGvd0IkwHZ-ygfdf34srafo,1596
+transformers/models/deprecated/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/bort/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
+transformers/models/deprecated/bort/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/deta/__init__.py,sha256=WNvQWU-pO4wBtGZPE5TAHF0OF1RPjEIgql1GC9wnmf8,1032
+transformers/models/deprecated/deta/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/deta/__pycache__/configuration_deta.cpython-310.pyc,,
+transformers/models/deprecated/deta/__pycache__/image_processing_deta.cpython-310.pyc,,
+transformers/models/deprecated/deta/__pycache__/modeling_deta.cpython-310.pyc,,
+transformers/models/deprecated/deta/configuration_deta.py,sha256=Hvr4QZAIruQw-s7C2JarGwAzrXzqg8FU40Co6g7Hhlc,14198
+transformers/models/deprecated/deta/image_processing_deta.py,sha256=HnnwUSDq_e5aIugcapay6VaE7qVWqQenj0W4Nk64-9M,54964
+transformers/models/deprecated/deta/modeling_deta.py,sha256=vtVskkYOUTAdigObFpVas6plk9dka2xTomcFd74SyFU,135520
+transformers/models/deprecated/efficientformer/__init__.py,sha256=RIMtCzn7AGYDfv279AZxapQ7tM7FFguknlC5CShrV3M,1112
+transformers/models/deprecated/efficientformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/efficientformer/__pycache__/configuration_efficientformer.cpython-310.pyc,,
+transformers/models/deprecated/efficientformer/__pycache__/image_processing_efficientformer.cpython-310.pyc,,
+transformers/models/deprecated/efficientformer/__pycache__/modeling_efficientformer.cpython-310.pyc,,
+transformers/models/deprecated/efficientformer/__pycache__/modeling_tf_efficientformer.cpython-310.pyc,,
+transformers/models/deprecated/efficientformer/configuration_efficientformer.py,sha256=liR9COZM1WNt1Cp7LtY0hBm4HQxcFcTSML5Sokq8Jwc,7739
+transformers/models/deprecated/efficientformer/image_processing_efficientformer.py,sha256=6U_fds9OmhfaRV3Oz21sSMjD370AM_mQ9JA11O3DzYw,15772
+transformers/models/deprecated/efficientformer/modeling_efficientformer.py,sha256=L70Z_gB2hgmxfjkYezlKRbQbOZnKdoqUChXAkc12wlA,33763
+transformers/models/deprecated/efficientformer/modeling_tf_efficientformer.py,sha256=5vHabl_36CmhqvWXoP2Lxbno9i0MXsKErQtY43-bf-U,49406
+transformers/models/deprecated/ernie_m/__init__.py,sha256=LlPR0I3qUe-L3t0xeakW3FKohvQgcWBgRMxENjy6_Ew,1047
+transformers/models/deprecated/ernie_m/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/ernie_m/__pycache__/configuration_ernie_m.cpython-310.pyc,,
+transformers/models/deprecated/ernie_m/__pycache__/modeling_ernie_m.cpython-310.pyc,,
+transformers/models/deprecated/ernie_m/__pycache__/tokenization_ernie_m.cpython-310.pyc,,
+transformers/models/deprecated/ernie_m/configuration_ernie_m.py,sha256=jPmSWmo38ovIiyrzIcHvnj-CdbnzqkogCTcCkPPsf0o,5889
+transformers/models/deprecated/ernie_m/modeling_ernie_m.py,sha256=GlJUwsAZwoagNyyB9nGRuyyjgdqPnFuBRB25ZOqjDD4,47473
+transformers/models/deprecated/ernie_m/tokenization_ernie_m.py,sha256=se3eYEzFrfa1Z_Xnla9l7c4WsXBeF4gePXVh0jf81K4,16250
+transformers/models/deprecated/gptsan_japanese/__init__.py,sha256=Q0KI_MuMRbQNKBzYOEsDgNZLktGUjTUWlm-1-TmdAeE,1061
+transformers/models/deprecated/gptsan_japanese/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/gptsan_japanese/__pycache__/configuration_gptsan_japanese.cpython-310.pyc,,
+transformers/models/deprecated/gptsan_japanese/__pycache__/modeling_gptsan_japanese.cpython-310.pyc,,
+transformers/models/deprecated/gptsan_japanese/__pycache__/tokenization_gptsan_japanese.cpython-310.pyc,,
+transformers/models/deprecated/gptsan_japanese/configuration_gptsan_japanese.py,sha256=UQbzr2Yr4EkjZgUE0hj8HYuelQDZZi0b7nw_vwtOvvk,7169
+transformers/models/deprecated/gptsan_japanese/modeling_gptsan_japanese.py,sha256=7Ff6ENUNaN-G3iLeoKKa2i1mKu4LqIUNWLiFMYPng_Q,65182
+transformers/models/deprecated/gptsan_japanese/tokenization_gptsan_japanese.py,sha256=5SgFlrtT8qCXUay6paKiEIW8h6bh9NN9rq5BJ-iScMI,23347
+transformers/models/deprecated/graphormer/__init__.py,sha256=qvmWWqa8KkAItGYVAHgjatAQlmjcF0bovLch0U0ubc8,1003
+transformers/models/deprecated/graphormer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/graphormer/__pycache__/collating_graphormer.cpython-310.pyc,,
+transformers/models/deprecated/graphormer/__pycache__/configuration_graphormer.cpython-310.pyc,,
+transformers/models/deprecated/graphormer/__pycache__/modeling_graphormer.cpython-310.pyc,,
+transformers/models/deprecated/graphormer/algos_graphormer.pyx,sha256=b_Qlm1hKCHnAqx6oOLGC9LkivAV0K_AZRGgXT9MmBas,3635
+transformers/models/deprecated/graphormer/collating_graphormer.py,sha256=DFDjr0s7B_hG4J3foSOQDoy5mFMsrsK1MCTq_HwXA-I,6088
+transformers/models/deprecated/graphormer/configuration_graphormer.py,sha256=vg6O_wY-Xn_aTVTg5XTYqNREozAomSLCHVo_diH9Pas,10480
+transformers/models/deprecated/graphormer/modeling_graphormer.py,sha256=QbQNmiKzedpILarXhoFiZR9McA29QJ1w_eJ2DVaMdpQ,37118
+transformers/models/deprecated/jukebox/__init__.py,sha256=5boFy1Eld2ll-ZpGhar77TZp4gVN5m-Ks8QumIZeAcI,1037
+transformers/models/deprecated/jukebox/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/jukebox/__pycache__/configuration_jukebox.cpython-310.pyc,,
+transformers/models/deprecated/jukebox/__pycache__/modeling_jukebox.cpython-310.pyc,,
+transformers/models/deprecated/jukebox/__pycache__/tokenization_jukebox.cpython-310.pyc,,
+transformers/models/deprecated/jukebox/configuration_jukebox.py,sha256=etr-yMp1t851E6omXV9ZrZdruQL7NkA1lifBu9h6f6A,26837
+transformers/models/deprecated/jukebox/modeling_jukebox.py,sha256=TsKdCCiOrpbuoEc2cDZV518JyOgV7mkoFUobjcFr0VA,119621
+transformers/models/deprecated/jukebox/tokenization_jukebox.py,sha256=bwpU60IQUNrPoZ0Mg4cobVe9_04tnda-6KU0koLpAC0,17366
+transformers/models/deprecated/mctct/__init__.py,sha256=oL2eRCmC1eKqGcN2nn7WWmVh4Lyq6zvfTK8Fbcct-Cc,1073
+transformers/models/deprecated/mctct/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/mctct/__pycache__/configuration_mctct.cpython-310.pyc,,
+transformers/models/deprecated/mctct/__pycache__/feature_extraction_mctct.cpython-310.pyc,,
+transformers/models/deprecated/mctct/__pycache__/modeling_mctct.cpython-310.pyc,,
+transformers/models/deprecated/mctct/__pycache__/processing_mctct.cpython-310.pyc,,
+transformers/models/deprecated/mctct/configuration_mctct.py,sha256=se5nTkdBsiWJT9eGIbsAju4olV_f-GddUDtba3HUSEk,9101
+transformers/models/deprecated/mctct/feature_extraction_mctct.py,sha256=n6JOh7Mp6IqfGTTZKpNJx9EDyatyoxP5DMFhvEkojO8,13492
+transformers/models/deprecated/mctct/modeling_mctct.py,sha256=5bkenrqGEEHqip1XV0SELbsr-Gd1907qvNJCoLxq29w,32558
+transformers/models/deprecated/mctct/processing_mctct.py,sha256=OcRrtpUDakmEL1HbH9atDrl9QYm4DrlR89QZoHtVwO0,5652
+transformers/models/deprecated/mega/__init__.py,sha256=MAxMoZtbT_fdVUYgMGeBlgwYRYVz07EeK5RyL2GB-ic,991
+transformers/models/deprecated/mega/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/mega/__pycache__/configuration_mega.cpython-310.pyc,,
+transformers/models/deprecated/mega/__pycache__/modeling_mega.cpython-310.pyc,,
+transformers/models/deprecated/mega/configuration_mega.py,sha256=nWdk-zPvpSI7UmUeXnClAwk-hEXCM5f5vt4xxJyAE_E,12642
+transformers/models/deprecated/mega/modeling_mega.py,sha256=it-PecGDyDAuOY4RvGyrJ23U6oKUi8NTvW-e1mcyHhA,109581
+transformers/models/deprecated/mmbt/__init__.py,sha256=X5f5OKVKnz-mOSV_v9IbfPsDFzOpYCf2yU4ktLWWmOA,991
+transformers/models/deprecated/mmbt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/mmbt/__pycache__/configuration_mmbt.cpython-310.pyc,,
+transformers/models/deprecated/mmbt/__pycache__/modeling_mmbt.cpython-310.pyc,,
+transformers/models/deprecated/mmbt/configuration_mmbt.py,sha256=UNksVsSmP6e_52vlf5pa9ETgiQw6M2pM2ocVxq52fWY,1624
+transformers/models/deprecated/mmbt/modeling_mmbt.py,sha256=xil7uW5Q1fHo-0yo4eC0K6egN-sO0LasqBxe2wp9nTE,18983
+transformers/models/deprecated/nat/__init__.py,sha256=Ggl4KcqVEX5Ub66NyyA7fyMz_oBLHOMUlqRTVrYwAYs,989
+transformers/models/deprecated/nat/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/nat/__pycache__/configuration_nat.cpython-310.pyc,,
+transformers/models/deprecated/nat/__pycache__/modeling_nat.cpython-310.pyc,,
+transformers/models/deprecated/nat/configuration_nat.py,sha256=7ZZXfsex0BfTQ5HMdINit2aAC1j_6me30ctX4IDM35o,7001
+transformers/models/deprecated/nat/modeling_nat.py,sha256=ykeIInNhtHJ5JYit22j5sk5ND2fbQwcHNcvMLSGSPDA,39841
+transformers/models/deprecated/nezha/__init__.py,sha256=3WxwqDdNckh4KfXKV4gxIeKvkr_U1GBDA-MdEHux3JM,993
+transformers/models/deprecated/nezha/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/nezha/__pycache__/configuration_nezha.cpython-310.pyc,,
+transformers/models/deprecated/nezha/__pycache__/modeling_nezha.cpython-310.pyc,,
+transformers/models/deprecated/nezha/configuration_nezha.py,sha256=gZvb3NVibiLmMrTrjzlKcChmBET6dOhyAQCjFFDyp0Y,4845
+transformers/models/deprecated/nezha/modeling_nezha.py,sha256=wvIpDAsfBEd2OUmCHHC59rvomES5fOyMasSJ05oysn4,74057
+transformers/models/deprecated/open_llama/__init__.py,sha256=hhWBBxouawhwSYkuWi7Co_dO86xNFofKrtxacOlcmiM,1023
+transformers/models/deprecated/open_llama/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/open_llama/__pycache__/configuration_open_llama.cpython-310.pyc,,
+transformers/models/deprecated/open_llama/__pycache__/modeling_open_llama.cpython-310.pyc,,
+transformers/models/deprecated/open_llama/configuration_open_llama.py,sha256=Iwpxsxa85jUukrVctVnhz1zOswDR889ZYcXbW6-bxuA,7800
+transformers/models/deprecated/open_llama/modeling_open_llama.py,sha256=1srbB207ipcPBFt3DfvFf4Ip0r92Jo27ztR7wqv18DU,42819
+transformers/models/deprecated/qdqbert/__init__.py,sha256=0sVNCbOvGXfJhrGbtQ7zV4v8rctY5pMzYKUvngVcvRg,1020
+transformers/models/deprecated/qdqbert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/qdqbert/__pycache__/configuration_qdqbert.cpython-310.pyc,,
+transformers/models/deprecated/qdqbert/__pycache__/modeling_qdqbert.cpython-310.pyc,,
+transformers/models/deprecated/qdqbert/configuration_qdqbert.py,sha256=HCvSo5NpospAUVinJu8NEGtDo4Oa2KHQX-_1kTkFA6g,5719
+transformers/models/deprecated/qdqbert/modeling_qdqbert.py,sha256=DxdD2e77HyjHjrhzHfpdTN3X_Kw3fxrnNWCMArNilQc,76932
+transformers/models/deprecated/realm/__init__.py,sha256=Cqg86mvi125eaBzeoP10ykpvXvHD-InC6JYTDJXM3Ik,1109
+transformers/models/deprecated/realm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/realm/__pycache__/configuration_realm.cpython-310.pyc,,
+transformers/models/deprecated/realm/__pycache__/modeling_realm.cpython-310.pyc,,
+transformers/models/deprecated/realm/__pycache__/retrieval_realm.cpython-310.pyc,,
+transformers/models/deprecated/realm/__pycache__/tokenization_realm.cpython-310.pyc,,
+transformers/models/deprecated/realm/__pycache__/tokenization_realm_fast.cpython-310.pyc,,
+transformers/models/deprecated/realm/configuration_realm.py,sha256=1CmnEKCJyYUmedP5pXcvLwrT2ThND3YHeuHfaEokz3M,7585
+transformers/models/deprecated/realm/modeling_realm.py,sha256=YPyjCxtUvrK12JXg6yfwcUtD_Vji_HIQ_LMd8fzsAkU,83590
+transformers/models/deprecated/realm/retrieval_realm.py,sha256=bGzuAOl8j59toVMwzUHZbpKkNBuAeP-qo1kg8Wdh0q8,7012
+transformers/models/deprecated/realm/tokenization_realm.py,sha256=c_H4sBrcnU_bXnQZrHyPuPRvMJx_7Coc3jB0Skkyxzs,21995
+transformers/models/deprecated/realm/tokenization_realm_fast.py,sha256=vzueU81dDD3DLcdK5nhZIRJH6avUkPAB2lJ5e8F9jbA,9858
+transformers/models/deprecated/retribert/__init__.py,sha256=bitEp-fOvn6_HvMY2CUlvJCGV5-baV6Bvl7EcbBh1jM,1090
+transformers/models/deprecated/retribert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/retribert/__pycache__/configuration_retribert.cpython-310.pyc,,
+transformers/models/deprecated/retribert/__pycache__/modeling_retribert.cpython-310.pyc,,
+transformers/models/deprecated/retribert/__pycache__/tokenization_retribert.cpython-310.pyc,,
+transformers/models/deprecated/retribert/__pycache__/tokenization_retribert_fast.cpython-310.pyc,,
+transformers/models/deprecated/retribert/configuration_retribert.py,sha256=nAqsKCL46N2eJwlcyfDs2ijqCWo7SDsOInq4rOsDAhs,5232
+transformers/models/deprecated/retribert/modeling_retribert.py,sha256=PzP_j4PTRb0wLpYvS3A6D9CjRFNT-gc99MZos1LwBR8,9349
+transformers/models/deprecated/retribert/tokenization_retribert.py,sha256=Uo7UQxxwhM-SonyGQtjXvpTZK7a9FLs2UTENCOXYIfo,19536
+transformers/models/deprecated/retribert/tokenization_retribert_fast.py,sha256=EXkSqeK6zEF8yng9UPSXjrxKaTHnhyGHWqlRugUsEYQ,6730
+transformers/models/deprecated/speech_to_text_2/__init__.py,sha256=gpV3g4cmZOc1rTvOVZQN9dY1eGoXQvVnSq0LMzYYJm0,1111
+transformers/models/deprecated/speech_to_text_2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/speech_to_text_2/__pycache__/configuration_speech_to_text_2.cpython-310.pyc,,
+transformers/models/deprecated/speech_to_text_2/__pycache__/modeling_speech_to_text_2.cpython-310.pyc,,
+transformers/models/deprecated/speech_to_text_2/__pycache__/processing_speech_to_text_2.cpython-310.pyc,,
+transformers/models/deprecated/speech_to_text_2/__pycache__/tokenization_speech_to_text_2.cpython-310.pyc,,
+transformers/models/deprecated/speech_to_text_2/configuration_speech_to_text_2.py,sha256=0nf8Vrheuc_3fpZhc3fNFfd05fXLfKvCe6n9B5hAcNA,6052
+transformers/models/deprecated/speech_to_text_2/modeling_speech_to_text_2.py,sha256=3yacZAdPKPhvvS60QSo2d8LlPD4l9UoFmgSIkxybRzM,43415
+transformers/models/deprecated/speech_to_text_2/processing_speech_to_text_2.py,sha256=eiJ_HvJhKH4VNOkOW33rZqURdZ5ElyiaY0vg48utC4M,4212
+transformers/models/deprecated/speech_to_text_2/tokenization_speech_to_text_2.py,sha256=vTNJBHuH4CwO6SvtOgx24mWtZzjjdHpY1ee7TZw1XxQ,8424
+transformers/models/deprecated/tapex/__init__.py,sha256=YDgKE4wAmqYPQ9U94PaZXHGDiLkZQAoMt4mNiO3QrXg,958
+transformers/models/deprecated/tapex/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/tapex/__pycache__/tokenization_tapex.cpython-310.pyc,,
+transformers/models/deprecated/tapex/tokenization_tapex.py,sha256=mrRkwgPKHyVUpOKYSI12x9_Pgr3Yyv8uWcePFxKWuI8,64396
+transformers/models/deprecated/trajectory_transformer/__init__.py,sha256=qhJ78kxJOG5Q5d_NDrIiH5_btuaAKfluEzKD_nuESPw,1027
+transformers/models/deprecated/trajectory_transformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/trajectory_transformer/__pycache__/configuration_trajectory_transformer.cpython-310.pyc,,
+transformers/models/deprecated/trajectory_transformer/__pycache__/modeling_trajectory_transformer.cpython-310.pyc,,
+transformers/models/deprecated/trajectory_transformer/configuration_trajectory_transformer.py,sha256=EEkSTX_sw2eYmNqYutj1acxjZnlM-jFldEtqycOwJko,7105
+transformers/models/deprecated/trajectory_transformer/modeling_trajectory_transformer.py,sha256=g5IJaL5QZ1ZDza3GDjD5MpqRV0J2TKgs--PLMOAbqgI,25472
+transformers/models/deprecated/transfo_xl/__init__.py,sha256=_wXu1dOeNxgJemZTynDRPmYOWcMQpYwkxbHIC_070_M,1088
+transformers/models/deprecated/transfo_xl/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/transfo_xl/__pycache__/configuration_transfo_xl.cpython-310.pyc,,
+transformers/models/deprecated/transfo_xl/__pycache__/modeling_tf_transfo_xl.cpython-310.pyc,,
+transformers/models/deprecated/transfo_xl/__pycache__/modeling_tf_transfo_xl_utilities.cpython-310.pyc,,
+transformers/models/deprecated/transfo_xl/__pycache__/modeling_transfo_xl.cpython-310.pyc,,
+transformers/models/deprecated/transfo_xl/__pycache__/modeling_transfo_xl_utilities.cpython-310.pyc,,
+transformers/models/deprecated/transfo_xl/__pycache__/tokenization_transfo_xl.cpython-310.pyc,,
+transformers/models/deprecated/transfo_xl/configuration_transfo_xl.py,sha256=5lUsNUzrmw3wWw_35s4TQgXQhf7C-QovFDkLs7R74Io,7905
+transformers/models/deprecated/transfo_xl/modeling_tf_transfo_xl.py,sha256=j4yoV9YRQ6xroWV1XXTIYH46EEKXgFA9_x8YIIGu76Q,46054
+transformers/models/deprecated/transfo_xl/modeling_tf_transfo_xl_utilities.py,sha256=Dlv3ZzRduWFBnZZHn8RegbW45XeCecuYCzzzZC3bDXs,7633
+transformers/models/deprecated/transfo_xl/modeling_transfo_xl.py,sha256=yBTvTAF0qBlqPU5U4mQ9J733wzzYmfibMgTlgnya1U8,56094
+transformers/models/deprecated/transfo_xl/modeling_transfo_xl_utilities.py,sha256=L1l4K7sj8rwXzvhn7_-RK2UbOnYtfDUF0VdFr4L8nxA,10859
+transformers/models/deprecated/transfo_xl/tokenization_transfo_xl.py,sha256=PcUEB2E_ZkrCDiyWhxtVaHC3oa6DHEBQfja72VZ65bA,32193
+transformers/models/deprecated/tvlt/__init__.py,sha256=5kgH30TJlq9WEsRw6f5Bs7U4MxNFKzw2dvlENb-ZsPM,674
+transformers/models/deprecated/tvlt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/tvlt/__pycache__/configuration_tvlt.cpython-310.pyc,,
+transformers/models/deprecated/tvlt/__pycache__/feature_extraction_tvlt.cpython-310.pyc,,
+transformers/models/deprecated/tvlt/__pycache__/image_processing_tvlt.cpython-310.pyc,,
+transformers/models/deprecated/tvlt/__pycache__/modeling_tvlt.cpython-310.pyc,,
+transformers/models/deprecated/tvlt/__pycache__/processing_tvlt.cpython-310.pyc,,
+transformers/models/deprecated/tvlt/configuration_tvlt.py,sha256=PaJXPttCw4t832Pqo1pV0MBYa9f-oDljfmc2SBMFXCI,8650
+transformers/models/deprecated/tvlt/feature_extraction_tvlt.py,sha256=DnmB8RIloaTfmfYIKTL-9hMGuVtWMgwazIJihx-6dxc,10591
+transformers/models/deprecated/tvlt/image_processing_tvlt.py,sha256=zwfD6pq_rpAKl0Ns_XIlmsNXVMrfPZ8KPzy4a_PMHT4,20296
+transformers/models/deprecated/tvlt/modeling_tvlt.py,sha256=lYo_4VgLoKtIcGmwH5Q5hMg-tyA0vKOrrZWoYDBhTKc,56305
+transformers/models/deprecated/tvlt/processing_tvlt.py,sha256=nfcrdlaKcTk14Zb6DOBAWi5w7dHIgrxskF0ELbGWJxg,3235
+transformers/models/deprecated/van/__init__.py,sha256=zH2jgRuTkGqz0fzogoEi1HhRMNmg8BbWjhZ9dwVWyM0,989
+transformers/models/deprecated/van/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/van/__pycache__/configuration_van.cpython-310.pyc,,
+transformers/models/deprecated/van/__pycache__/modeling_van.cpython-310.pyc,,
+transformers/models/deprecated/van/configuration_van.py,sha256=fTfaChmHuw2qoi_mZxIQxUH7JoVRBdkA38R_qPbrc3E,4683
+transformers/models/deprecated/van/modeling_van.py,sha256=AwO4-4nC0WktnXGICoO5HbuAKEVX6rMCUHQyBeRO0wc,21234
+transformers/models/deprecated/vit_hybrid/__init__.py,sha256=9OIBt-kLfL3VHtfpoj3rVLFzXbpwFu1F5QotHqQAUuM,1050
+transformers/models/deprecated/vit_hybrid/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/vit_hybrid/__pycache__/configuration_vit_hybrid.cpython-310.pyc,,
+transformers/models/deprecated/vit_hybrid/__pycache__/image_processing_vit_hybrid.cpython-310.pyc,,
+transformers/models/deprecated/vit_hybrid/__pycache__/modeling_vit_hybrid.cpython-310.pyc,,
+transformers/models/deprecated/vit_hybrid/configuration_vit_hybrid.py,sha256=Eof6B__quu-2A2SDw7erhD6goglbdVsgB3wqJGEp9WE,8477
+transformers/models/deprecated/vit_hybrid/image_processing_vit_hybrid.py,sha256=LSZhAqrSMnyD-6z-aGFumKc_YeWwgwgC-tl74e9SnyU,16347
+transformers/models/deprecated/vit_hybrid/modeling_vit_hybrid.py,sha256=JCcbErRV1fNL-ENnf0vGb85cyjnu4SOl_HjG-7wTaQg,32420
+transformers/models/deprecated/xlm_prophetnet/__init__.py,sha256=q9zJIXoPqoGPw0x9PQXvpTrpSCw1y1WyYoNCFz-X554,1058
+transformers/models/deprecated/xlm_prophetnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/deprecated/xlm_prophetnet/__pycache__/configuration_xlm_prophetnet.cpython-310.pyc,,
+transformers/models/deprecated/xlm_prophetnet/__pycache__/modeling_xlm_prophetnet.cpython-310.pyc,,
+transformers/models/deprecated/xlm_prophetnet/__pycache__/tokenization_xlm_prophetnet.cpython-310.pyc,,
+transformers/models/deprecated/xlm_prophetnet/configuration_xlm_prophetnet.py,sha256=eFMoiTH5qFKL6R0aLhV9-uqUvB2oVVcgrAia6wuLnAY,8968
+transformers/models/deprecated/xlm_prophetnet/modeling_xlm_prophetnet.py,sha256=eD8RWxuNh-OVg3BWQ8IJTIP_GTMMCCEUq_SK8BQkuiA,114438
+transformers/models/deprecated/xlm_prophetnet/tokenization_xlm_prophetnet.py,sha256=5m053u9Y9NEbmCUJlhprGGdC8ZrXy9VkZF3UGg3fsmo,13153
+transformers/models/depth_anything/__init__.py,sha256=Jbd8LXt-fU3_cTF7jBrkBBw-Kzscv6o7O0YiZy0R8-A,1009
+transformers/models/depth_anything/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/depth_anything/__pycache__/configuration_depth_anything.cpython-310.pyc,,
+transformers/models/depth_anything/__pycache__/modeling_depth_anything.cpython-310.pyc,,
+transformers/models/depth_anything/configuration_depth_anything.py,sha256=s_lwOMcrASuIud4jMw8rBn54vNn2zBzb1RTVVm_1KDU,8189
+transformers/models/depth_anything/modeling_depth_anything.py,sha256=yu1mWSTMWGOfXgkXFzjGn04v-Ywm4eYhHrkr1797oQk,16705
+transformers/models/depth_pro/__init__.py,sha256=5R4N4IVUQuK8bCFtg9qGvJFceJaHXNj4HdCWkcsyELc,1096
+transformers/models/depth_pro/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/depth_pro/__pycache__/configuration_depth_pro.cpython-310.pyc,,
+transformers/models/depth_pro/__pycache__/image_processing_depth_pro.cpython-310.pyc,,
+transformers/models/depth_pro/__pycache__/image_processing_depth_pro_fast.cpython-310.pyc,,
+transformers/models/depth_pro/__pycache__/modeling_depth_pro.cpython-310.pyc,,
+transformers/models/depth_pro/configuration_depth_pro.py,sha256=s6k1XPk6kjjT_nMBTB2pO7sxYuxC5ZdHB1697Wu7dJs,10715
+transformers/models/depth_pro/image_processing_depth_pro.py,sha256=lzDXCL4EUVbydlxF3x8OjTYOULe6O6p-8-_GfyCG3e4,18952
+transformers/models/depth_pro/image_processing_depth_pro_fast.py,sha256=9EAynT5QJN5pNTG--fPNmeDQMh4KiEcg012YkDXiBU0,6947
+transformers/models/depth_pro/modeling_depth_pro.py,sha256=1aSbUIOgQMG9FuNr3tGFv8TeMW8GS8e8d9CYOWGet6E,43108
+transformers/models/detr/__init__.py,sha256=YEWZnoCCgWt4KZNfbSi-v4KNDOJT2-ii2sxanyVDkvY,1120
+transformers/models/detr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/detr/__pycache__/configuration_detr.cpython-310.pyc,,
+transformers/models/detr/__pycache__/feature_extraction_detr.cpython-310.pyc,,
+transformers/models/detr/__pycache__/image_processing_detr.cpython-310.pyc,,
+transformers/models/detr/__pycache__/image_processing_detr_fast.cpython-310.pyc,,
+transformers/models/detr/__pycache__/modeling_detr.cpython-310.pyc,,
+transformers/models/detr/configuration_detr.py,sha256=wSdE-pszgelpLPMBREhmjXk77t8sPYthn9Cj4Qo02Y8,13918
+transformers/models/detr/feature_extraction_detr.py,sha256=VudvO9SXjwtxL9PPT8vM3vFKcpiOGOe6Mt8zbZuIV1I,1586
+transformers/models/detr/image_processing_detr.py,sha256=vHjfBPpnagZLCjg2UyaPx5LpszzI_1xkaouqCIOxGks,94089
+transformers/models/detr/image_processing_detr_fast.py,sha256=bM_SAjpd_uMWLzO9LEP6PANt4QdMtee_zlCecxwn6kg,59886
+transformers/models/detr/modeling_detr.py,sha256=JUhvZIbo4eeazVfnZzXCrq7OY0N4LP9vJ4Dsh2umBxU,77797
+transformers/models/dia/__init__.py,sha256=fvBcwJ7FAFDO6RNyUUMGrdSlUtowciNo3YYv7R2Qz1c,1133
+transformers/models/dia/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dia/__pycache__/configuration_dia.cpython-310.pyc,,
+transformers/models/dia/__pycache__/feature_extraction_dia.cpython-310.pyc,,
+transformers/models/dia/__pycache__/generation_dia.cpython-310.pyc,,
+transformers/models/dia/__pycache__/modeling_dia.cpython-310.pyc,,
+transformers/models/dia/__pycache__/modular_dia.cpython-310.pyc,,
+transformers/models/dia/__pycache__/processing_dia.cpython-310.pyc,,
+transformers/models/dia/__pycache__/tokenization_dia.cpython-310.pyc,,
+transformers/models/dia/configuration_dia.py,sha256=G6BnNf5536gSsmhLIJco3EMulv0tk7u89VDQLkFp3Hw,20609
+transformers/models/dia/feature_extraction_dia.py,sha256=B4cSUOa-nXRyzZEPcJxkhlT52pTAt3ys4xQ3-EJWEo4,8503
+transformers/models/dia/generation_dia.py,sha256=dM8YR9Qb9oqBv0a02j1MgERvx2HqD6COoyDLiFipSIU,21813
+transformers/models/dia/modeling_dia.py,sha256=19q2BMDiq5dF2TD-p3gZwq0LK8aWW635Pb9KMnx9X1w,42571
+transformers/models/dia/modular_dia.py,sha256=kXDVJIFH3cKG5GASwkS-vA-aHvZSQPIUdbwTkh6ld7o,33408
+transformers/models/dia/processing_dia.py,sha256=amS9PaB8pEgZ9RAKytZH_KH_NNK7DVnYA9NBBTuY8jE,19969
+transformers/models/dia/tokenization_dia.py,sha256=O4dTQjoErcFLHF5IbLHp2IdlPj_8POhLfkiRr0p0BNI,4511
+transformers/models/dialogpt/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
+transformers/models/dialogpt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/diffllama/__init__.py,sha256=Yosk5eQ82PblntLff-bL3pfJZ-AVKp5jbQK5R2SLVc8,1004
+transformers/models/diffllama/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/diffllama/__pycache__/configuration_diffllama.cpython-310.pyc,,
+transformers/models/diffllama/__pycache__/modeling_diffllama.cpython-310.pyc,,
+transformers/models/diffllama/__pycache__/modular_diffllama.cpython-310.pyc,,
+transformers/models/diffllama/configuration_diffllama.py,sha256=SQr6FM8h6EQCI-NNYYksvK0JSy2WN8q6aGQNDFbJAgA,10688
+transformers/models/diffllama/modeling_diffllama.py,sha256=5-s9-4khgpEaILoMw61oHAJV8I_WDRuBiPO-jEemD5g,35432
+transformers/models/diffllama/modular_diffllama.py,sha256=vLqMKVVm_LvIYhkoRJ0CHLcEtJ3t_7FXJ5OpFwAMyXE,20679
+transformers/models/dinat/__init__.py,sha256=N0HykajUSY5KsvPQNUxc8jAuuJntmDJ-Dz8Qa8_sJ9E,991
+transformers/models/dinat/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dinat/__pycache__/configuration_dinat.cpython-310.pyc,,
+transformers/models/dinat/__pycache__/modeling_dinat.cpython-310.pyc,,
+transformers/models/dinat/configuration_dinat.py,sha256=fhGXUqRCEkTgWL6rpPUF7J-W7usE4e7gl3DS_J99wMc,7356
+transformers/models/dinat/modeling_dinat.py,sha256=puqCPPJJoKKLD6cl6EU0lvH_I48iVO9fUYytuaWF36w,34939
+transformers/models/dinov2/__init__.py,sha256=fDyp5N-KcJzO-vUeT3fZA8UbC21FfGEhDOlYNvXHHDc,1033
+transformers/models/dinov2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dinov2/__pycache__/configuration_dinov2.cpython-310.pyc,,
+transformers/models/dinov2/__pycache__/modeling_dinov2.cpython-310.pyc,,
+transformers/models/dinov2/__pycache__/modeling_flax_dinov2.cpython-310.pyc,,
+transformers/models/dinov2/configuration_dinov2.py,sha256=020F55Jhk4nwbpzxfDxzi77Poe-5OpuGZ-f-mxEDYFg,8291
+transformers/models/dinov2/modeling_dinov2.py,sha256=gRFqD939PZb50XXMVqIt7RE4LrIbx4dI55sp00Zg-GI,28715
+transformers/models/dinov2/modeling_flax_dinov2.py,sha256=dfmeUz3KQ9d7eoX0X0QqJPKLHZv7c8GOrT2VF9_g7zk,31050
+transformers/models/dinov2_with_registers/__init__.py,sha256=s0cefgSRnlIVcdZYV0qz3Q9X3IEChU7mkGbbnr2IH6E,1023
+transformers/models/dinov2_with_registers/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dinov2_with_registers/__pycache__/configuration_dinov2_with_registers.cpython-310.pyc,,
+transformers/models/dinov2_with_registers/__pycache__/modeling_dinov2_with_registers.cpython-310.pyc,,
+transformers/models/dinov2_with_registers/__pycache__/modular_dinov2_with_registers.cpython-310.pyc,,
+transformers/models/dinov2_with_registers/configuration_dinov2_with_registers.py,sha256=Jv2lhwSt3lSvN8BQuhsK6rmW1IKtSqm4un5Qsvdm6DI,8633
+transformers/models/dinov2_with_registers/modeling_dinov2_with_registers.py,sha256=sxqtH2Ij435COBbsfd3g11fyHaf3i4LYKl-Mj5ucP-c,30980
+transformers/models/dinov2_with_registers/modular_dinov2_with_registers.py,sha256=pyvxe0BgubVWUbRei2p80Hmv7xHtamG-DSKxhZP5mcc,19595
+transformers/models/dinov3_convnext/__init__.py,sha256=8VOE7Jnq3g2JBuwkVcsFoZEerdZF5dn2p5XZ26BMRY4,1011
+transformers/models/dinov3_convnext/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dinov3_convnext/__pycache__/configuration_dinov3_convnext.cpython-310.pyc,,
+transformers/models/dinov3_convnext/__pycache__/modeling_dinov3_convnext.cpython-310.pyc,,
+transformers/models/dinov3_convnext/configuration_dinov3_convnext.py,sha256=1_jX9wksnEI0Ds7Jb4n5qpI8SNRsDRE5KggYETxwlZo,4279
+transformers/models/dinov3_convnext/modeling_dinov3_convnext.py,sha256=yhzpL374D7ChFdDozzzzTlkso6TfxFTgL5AzivdRVqw,11022
+transformers/models/dinov3_vit/__init__.py,sha256=DYSqKAAuJCZAhQyu7pcechuSR025KnzcKNtJIafTq1E,1053
+transformers/models/dinov3_vit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dinov3_vit/__pycache__/configuration_dinov3_vit.cpython-310.pyc,,
+transformers/models/dinov3_vit/__pycache__/image_processing_dinov3_vit_fast.cpython-310.pyc,,
+transformers/models/dinov3_vit/__pycache__/modeling_dinov3_vit.cpython-310.pyc,,
+transformers/models/dinov3_vit/__pycache__/modular_dinov3_vit.cpython-310.pyc,,
+transformers/models/dinov3_vit/configuration_dinov3_vit.py,sha256=GsfLiJ4jFOjK35sL7UPULPsF3ObXMPcZvkOAyKEKikY,7421
+transformers/models/dinov3_vit/image_processing_dinov3_vit_fast.py,sha256=WoSmpyg7d-CgsACFEVDdnQTcVKEbqj0s0-JgPUZp7IA,4167
+transformers/models/dinov3_vit/modeling_dinov3_vit.py,sha256=AGUtkP-MeuMrBH6-Ks0icfl-A_doz1cKwFEEWk4NXPU,22688
+transformers/models/dinov3_vit/modular_dinov3_vit.py,sha256=hivmSTjbQd5nwCc646KavrwxJInWP1mHPljdoJEulKI,17354
+transformers/models/distilbert/__init__.py,sha256=dKwCe9QsyAaNsdUJFMUa-vcuHPSQSuLKFoFBvK3cLEY,1178
+transformers/models/distilbert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/distilbert/__pycache__/configuration_distilbert.cpython-310.pyc,,
+transformers/models/distilbert/__pycache__/modeling_distilbert.cpython-310.pyc,,
+transformers/models/distilbert/__pycache__/modeling_flax_distilbert.cpython-310.pyc,,
+transformers/models/distilbert/__pycache__/modeling_tf_distilbert.cpython-310.pyc,,
+transformers/models/distilbert/__pycache__/tokenization_distilbert.cpython-310.pyc,,
+transformers/models/distilbert/__pycache__/tokenization_distilbert_fast.cpython-310.pyc,,
+transformers/models/distilbert/configuration_distilbert.py,sha256=h2rBKH_a_aEdRDo-5JEHAbVwUf1-6Sy6xpNRjdLvhnE,6055
+transformers/models/distilbert/modeling_distilbert.py,sha256=bsz7SbcQ5nUrg2pqYC7w2yGtm6hcoxnG-DwwhphgkOs,56558
+transformers/models/distilbert/modeling_flax_distilbert.py,sha256=U0jH7nehL1vEt1gPTDwA882r8erT6Ol_QnOhgv7owro,32922
+transformers/models/distilbert/modeling_tf_distilbert.py,sha256=tOX6XGcxJXcy3lPurE3r0pRjX0U4TMWExb-EQbFc4eA,48995
+transformers/models/distilbert/tokenization_distilbert.py,sha256=hpvjVFbpRKQ1rFKW9QoGzUf2Ds3DAYLe_ZRLWi2EdCo,20999
+transformers/models/distilbert/tokenization_distilbert_fast.py,sha256=GfYGXroocFvwRahr1KHTowy-qtYwoqeqmt31MWlf2E0,6827
+transformers/models/dit/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
+transformers/models/dit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/doge/__init__.py,sha256=SU7Ea0BtJ8psgsDda2RcXdb1466OYN0l5IK7aOiuanY,1024
+transformers/models/doge/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/doge/__pycache__/configuration_doge.cpython-310.pyc,,
+transformers/models/doge/__pycache__/modeling_doge.cpython-310.pyc,,
+transformers/models/doge/__pycache__/modular_doge.cpython-310.pyc,,
+transformers/models/doge/configuration_doge.py,sha256=nnuGXqrDVC9o1zt1g2sGqNy2nlwiH1hSv8HUHQQVF-c,13910
+transformers/models/doge/modeling_doge.py,sha256=X30Jotn6DbJcYZJb8hLKBWVFzky0Wkl5LVdqYN7bgHM,36304
+transformers/models/doge/modular_doge.py,sha256=3nkT7x3MPJ0PgFXdqp4hOYS7K5P62avhgD9SpA-ZEUg,37288
+transformers/models/donut/__init__.py,sha256=O1JOQtPxtjcxSfWgC_PUZkmfvcKzjPgNAakujNra1PA,1170
+transformers/models/donut/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/donut/__pycache__/configuration_donut_swin.cpython-310.pyc,,
+transformers/models/donut/__pycache__/feature_extraction_donut.cpython-310.pyc,,
+transformers/models/donut/__pycache__/image_processing_donut.cpython-310.pyc,,
+transformers/models/donut/__pycache__/image_processing_donut_fast.cpython-310.pyc,,
+transformers/models/donut/__pycache__/modeling_donut_swin.cpython-310.pyc,,
+transformers/models/donut/__pycache__/processing_donut.cpython-310.pyc,,
+transformers/models/donut/configuration_donut_swin.py,sha256=mHg0P4MRxMOw_IsHKFtBIuSuuY0tINGN3FmUImMqST8,5785
+transformers/models/donut/feature_extraction_donut.py,sha256=JfpHRB_aTYyBkySWUgofHHwGxIA8hpaS8NilnFsgIAU,1292
+transformers/models/donut/image_processing_donut.py,sha256=IlcGmiUtmw4WbiIFNfmx4-6hpxfRUCYP0A4vydTHyDQ,22469
+transformers/models/donut/image_processing_donut_fast.py,sha256=W9qwI8vceBSJonSm1_gs1T0ct2BjJIMTnDxKS8VALVY,10653
+transformers/models/donut/modeling_donut_swin.py,sha256=zmZC5nK00k4kWZA-3v9x1giz83vYFVAxDonDVPGwn2c,45761
+transformers/models/donut/processing_donut.py,sha256=kGJ5nqp4O_4c9pALighf10xcGjCECqwLYqcuA-HlZ-Q,8817
+transformers/models/dots1/__init__.py,sha256=A2jXARtNWOrbWAW2SIrsvvydm2_2keRyUBbNEz0By-I,991
+transformers/models/dots1/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dots1/__pycache__/configuration_dots1.cpython-310.pyc,,
+transformers/models/dots1/__pycache__/modeling_dots1.cpython-310.pyc,,
+transformers/models/dots1/__pycache__/modular_dots1.cpython-310.pyc,,
+transformers/models/dots1/configuration_dots1.py,sha256=5sZgR6-n_wmbpEd6_DBNXf-GQT7haPQdEsgYyTMLbIY,10080
+transformers/models/dots1/modeling_dots1.py,sha256=0GUi8z2EEVBijain8hL5eySex_YtBNyoC2nLMkHc8Fk,27566
+transformers/models/dots1/modular_dots1.py,sha256=M350mYt43vL3zl2Wzwx2D08eK6mrGZfyMv4xDl23waM,3277
+transformers/models/dpr/__init__.py,sha256=z4FocLkQ_ckWtBZctTh-aeV1haJJY-lXF0ZRKuVbVkc,1099
+transformers/models/dpr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dpr/__pycache__/configuration_dpr.cpython-310.pyc,,
+transformers/models/dpr/__pycache__/modeling_dpr.cpython-310.pyc,,
+transformers/models/dpr/__pycache__/modeling_tf_dpr.cpython-310.pyc,,
+transformers/models/dpr/__pycache__/tokenization_dpr.cpython-310.pyc,,
+transformers/models/dpr/__pycache__/tokenization_dpr_fast.cpython-310.pyc,,
+transformers/models/dpr/configuration_dpr.py,sha256=-DGEGi7rH0bSlWSh2WCFvB6cdZ6bJ8kO3u8xvhDS8mk,6432
+transformers/models/dpr/modeling_dpr.py,sha256=L0Kl_E2Cu740zGQPZCT7wpmLBECZNGaS3V3DzRN2a7A,22826
+transformers/models/dpr/modeling_tf_dpr.py,sha256=VpzB67gC0sMnnuVcAxUhHxxj-Lxjnf658LIOFvhKLRc,33857
+transformers/models/dpr/tokenization_dpr.py,sha256=KuNEnPczArBcq36g3p_eueA2Z5AG4Y7vtgqMFHstzE4,15834
+transformers/models/dpr/tokenization_dpr_fast.py,sha256=ClKoqvgOkO4nnQX8R0KwwMTl5gZhh1VLMURD_9nEN-o,16215
+transformers/models/dpt/__init__.py,sha256=7i4wNFCo8NTFsJQi7TO9u0VGxpZ8xg1_QNvD862jNk4,1114
+transformers/models/dpt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/dpt/__pycache__/configuration_dpt.cpython-310.pyc,,
+transformers/models/dpt/__pycache__/feature_extraction_dpt.cpython-310.pyc,,
+transformers/models/dpt/__pycache__/image_processing_dpt.cpython-310.pyc,,
+transformers/models/dpt/__pycache__/image_processing_dpt_fast.cpython-310.pyc,,
+transformers/models/dpt/__pycache__/modeling_dpt.cpython-310.pyc,,
+transformers/models/dpt/__pycache__/modular_dpt.cpython-310.pyc,,
+transformers/models/dpt/configuration_dpt.py,sha256=jCbSEFTvEZ5V7iHmjL_SxTZ9azTI4N2qEcd9CcGxPGo,14909
+transformers/models/dpt/feature_extraction_dpt.py,sha256=oCMnm3Pf3cDqtuENmJyqiT0F6OOFKKC5AjwldSpx7t8,1276
+transformers/models/dpt/image_processing_dpt.py,sha256=VUTVk0cd4riKrr8Nle4lftL3RGnOgvLc_Id1AgPrXAk,31707
+transformers/models/dpt/image_processing_dpt_fast.py,sha256=WooBfcgCye-snnQS5kFEBGTGynOrMEkcev3cTcVtWCc,17585
+transformers/models/dpt/modeling_dpt.py,sha256=7vqMtHvRiwHjsED1-DdM0UC6jCiV38qPLTjBp3-Y9s8,51083
+transformers/models/dpt/modular_dpt.py,sha256=VAtX-_CLk5gWHKV2xJQ77utPve0X7-Sst8EaXXS3vCc,12359
+transformers/models/efficientloftr/__init__.py,sha256=KLzDB5R1BeMf0LOP0Ypp-RZhDrtn7RhjGk_UfAoq2O0,1060
+transformers/models/efficientloftr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/efficientloftr/__pycache__/configuration_efficientloftr.cpython-310.pyc,,
+transformers/models/efficientloftr/__pycache__/image_processing_efficientloftr.cpython-310.pyc,,
+transformers/models/efficientloftr/__pycache__/modeling_efficientloftr.cpython-310.pyc,,
+transformers/models/efficientloftr/configuration_efficientloftr.py,sha256=135iXYCBwh94XyqkJSSFLohVNZoRFtgra_dfSlNBlQ4,10421
+transformers/models/efficientloftr/image_processing_efficientloftr.py,sha256=AQP5OdDHnqIJzlrxZNUAVUQ0hvWVI0yLei8GzvpzrD0,21495
+transformers/models/efficientloftr/modeling_efficientloftr.py,sha256=mvqNZgZb_6oXGGm68RVOSSqmn8MYJM66Xts48Ut24Is,58711
+transformers/models/efficientnet/__init__.py,sha256=0wxLCBxWBCh8uj4nH1syYJ76kRvUlMS6EUN5E2L2Qwc,1108
+transformers/models/efficientnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/efficientnet/__pycache__/configuration_efficientnet.cpython-310.pyc,,
+transformers/models/efficientnet/__pycache__/image_processing_efficientnet.cpython-310.pyc,,
+transformers/models/efficientnet/__pycache__/image_processing_efficientnet_fast.cpython-310.pyc,,
+transformers/models/efficientnet/__pycache__/modeling_efficientnet.cpython-310.pyc,,
+transformers/models/efficientnet/configuration_efficientnet.py,sha256=pzLFg-QlskKos0hEVJI55TihTkR0Kn_WvxRAtHQEN_E,7660
+transformers/models/efficientnet/image_processing_efficientnet.py,sha256=O8YZLO1cvFSg12m7as3zAcaDkWz19p8b2lEcGAVbFko,18440
+transformers/models/efficientnet/image_processing_efficientnet_fast.py,sha256=etc5FO3clqtf7xbBRYfwf3MhZmXQ1Hs8Sl5SiYYgSSY,8142
+transformers/models/efficientnet/modeling_efficientnet.py,sha256=zt2IRIpvWUbJsX9B9c0eYdbEx0ungj0mOU6Vn255g_o,21370
+transformers/models/electra/__init__.py,sha256=e6DkZL6cjtWVsTx7tamR-zsyv0tuRYLbuYn-r-04P84,1160
+transformers/models/electra/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/electra/__pycache__/configuration_electra.cpython-310.pyc,,
+transformers/models/electra/__pycache__/modeling_electra.cpython-310.pyc,,
+transformers/models/electra/__pycache__/modeling_flax_electra.cpython-310.pyc,,
+transformers/models/electra/__pycache__/modeling_tf_electra.cpython-310.pyc,,
+transformers/models/electra/__pycache__/tokenization_electra.cpython-310.pyc,,
+transformers/models/electra/__pycache__/tokenization_electra_fast.cpython-310.pyc,,
+transformers/models/electra/configuration_electra.py,sha256=Q8udyq_AymQzkwnlrPurj4mdl9f4QU2l0YODKH523uc,9170
+transformers/models/electra/modeling_electra.py,sha256=u0To5MZOkXzz4Mer-SGyaRrQHEc0q2IdW9FZWfXbswI,69820
+transformers/models/electra/modeling_flax_electra.py,sha256=I8aa02ZkCCKL6ch_L38BFxYmQK-EWuMnSEUsT_qUxPE,62613
+transformers/models/electra/modeling_tf_electra.py,sha256=dW-ED6HQKsLpr_QzQy3OqL-nMZBzmT_lhrlRz2bic08,78430
+transformers/models/electra/tokenization_electra.py,sha256=n0A4Wm-kdEhLKUkbn3dFM8nGWPV0vV71AzpH-YigFmk,20108
+transformers/models/electra/tokenization_electra_fast.py,sha256=vIX5oBKDTWD2Vn_CHNOUFX9Y3PB4QTUfxGyZNUswEVY,6590
+transformers/models/emu3/__init__.py,sha256=VEBLADqeToacty2xd3Zu0F_fLQRxvhfiKPkuB9jwcFM,1070
+transformers/models/emu3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/emu3/__pycache__/configuration_emu3.cpython-310.pyc,,
+transformers/models/emu3/__pycache__/image_processing_emu3.cpython-310.pyc,,
+transformers/models/emu3/__pycache__/modeling_emu3.cpython-310.pyc,,
+transformers/models/emu3/__pycache__/modular_emu3.cpython-310.pyc,,
+transformers/models/emu3/__pycache__/processing_emu3.cpython-310.pyc,,
+transformers/models/emu3/configuration_emu3.py,sha256=J1uT2xTI4-w4Z-z6jxPaGucY13t9wASKJD6_A-ee2rI,16175
+transformers/models/emu3/image_processing_emu3.py,sha256=WYss8e0Fd_GpVDQVNsswC9acV6c-kOGFIS5honyjH9Q,27891
+transformers/models/emu3/modeling_emu3.py,sha256=XC10pAtxkxIvwfIxhsLRZCoocNuaZOGjbt3ijklno0Q,65067
+transformers/models/emu3/modular_emu3.py,sha256=u1Ytn0-H_7Zwn8JBaSQCRrCHFsbLOh1GEPTCTNFLRKI,46473
+transformers/models/emu3/processing_emu3.py,sha256=n5WWrzPMphXMAJnQbS9M7uBpk8jVLKtMM6OgYyiF7a8,11793
+transformers/models/encodec/__init__.py,sha256=QbO9yEfCaRwYKbK0vvmwKMbqRAToyos-HTHhRmf7n5s,1041
+transformers/models/encodec/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/encodec/__pycache__/configuration_encodec.cpython-310.pyc,,
+transformers/models/encodec/__pycache__/feature_extraction_encodec.cpython-310.pyc,,
+transformers/models/encodec/__pycache__/modeling_encodec.cpython-310.pyc,,
+transformers/models/encodec/configuration_encodec.py,sha256=yi016nmXOdgM9NgSSWJW6rDDHpzTIPJJ8gG9OHZK83w,8705
+transformers/models/encodec/feature_extraction_encodec.py,sha256=ANwwpLKhArrcXtqC4eLpFFeJ2fZReWsaAtvdDuCcUYg,9944
+transformers/models/encodec/modeling_encodec.py,sha256=hmDympFkHTgJCVlAzeQFz-e90AgSf8aF9gA-OeurUyY,34606
+transformers/models/encoder_decoder/__init__.py,sha256=wxXN9-4nCvYICfq8pE592rdRiQXK7S69V2cWGVQyIkw,1107
+transformers/models/encoder_decoder/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/encoder_decoder/__pycache__/configuration_encoder_decoder.cpython-310.pyc,,
+transformers/models/encoder_decoder/__pycache__/modeling_encoder_decoder.cpython-310.pyc,,
+transformers/models/encoder_decoder/__pycache__/modeling_flax_encoder_decoder.cpython-310.pyc,,
+transformers/models/encoder_decoder/__pycache__/modeling_tf_encoder_decoder.cpython-310.pyc,,
+transformers/models/encoder_decoder/configuration_encoder_decoder.py,sha256=3RReXpXx5UcFH8EEfzAsyQrbJ9FmHuHfZ3vx-Br1-54,4596
+transformers/models/encoder_decoder/modeling_encoder_decoder.py,sha256=hbCf2r48EqSoathpvsyZmhaNtjMxaKh13ltDjtDm1xo,30031
+transformers/models/encoder_decoder/modeling_flax_encoder_decoder.py,sha256=U3bHgOkJxZQRUqXOacW7nExXg4j2zI9850rSDCWoFDU,43595
+transformers/models/encoder_decoder/modeling_tf_encoder_decoder.py,sha256=qS8cY9FGuUbFajw75i496zVBPJJIf17ZxVKkMAfcKQ8,34188
+transformers/models/eomt/__init__.py,sha256=yXVhFSLXI_umGHqTtRHHaTevf4KwrA9LOldvY7DfuFk,1076
+transformers/models/eomt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/eomt/__pycache__/configuration_eomt.cpython-310.pyc,,
+transformers/models/eomt/__pycache__/image_processing_eomt.cpython-310.pyc,,
+transformers/models/eomt/__pycache__/image_processing_eomt_fast.cpython-310.pyc,,
+transformers/models/eomt/__pycache__/modeling_eomt.cpython-310.pyc,,
+transformers/models/eomt/__pycache__/modular_eomt.cpython-310.pyc,,
+transformers/models/eomt/configuration_eomt.py,sha256=nvH6qjar0r7ejH9yM_WWvz8aiVQJG188ZdLedGMTOUw,8069
+transformers/models/eomt/image_processing_eomt.py,sha256=xQiCxYR6THl-kxNzihiywqxxwPexbn5X1dXJUjMJKhs,41142
+transformers/models/eomt/image_processing_eomt_fast.py,sha256=SK-sXtQq3d77xF31B-bKIT1Mf1OZxQ38k8fRChXRYr4,22195
+transformers/models/eomt/modeling_eomt.py,sha256=h3EihHxS3fXEYmers-ado54sQXAF_PUhE-gojUUUjjc,54658
+transformers/models/eomt/modular_eomt.py,sha256=omHulNEoFPh0xGYRnMN2PB8XbylfOgB6R0R1nqLbrY8,25366
+transformers/models/ernie/__init__.py,sha256=TyzaXpzGwu-WqsIn1tavDqa7BCV9X-mPho4JDa9gk0I,991
+transformers/models/ernie/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/ernie/__pycache__/configuration_ernie.cpython-310.pyc,,
+transformers/models/ernie/__pycache__/modeling_ernie.cpython-310.pyc,,
+transformers/models/ernie/configuration_ernie.py,sha256=_1shyRgpTVMQS2z7kEW8FF7spluVDc-azldGq8Clr4Y,7719
+transformers/models/ernie/modeling_ernie.py,sha256=RZtoqxcAGFQW6I9EmEAHmeZhB7e7ROX6D7C628QvTIw,76795
+transformers/models/ernie4_5/__init__.py,sha256=5tqpitaOWvT1CdXTgMtMLCKIkUG683y3jdcTZ8yuwfM,997
+transformers/models/ernie4_5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/ernie4_5/__pycache__/configuration_ernie4_5.cpython-310.pyc,,
+transformers/models/ernie4_5/__pycache__/modeling_ernie4_5.cpython-310.pyc,,
+transformers/models/ernie4_5/__pycache__/modular_ernie4_5.cpython-310.pyc,,
+transformers/models/ernie4_5/configuration_ernie4_5.py,sha256=Sg3qqYRBjErH7dPcyPdfe3CKYnaxSpjo5d2tI5RAVvs,10671
+transformers/models/ernie4_5/modeling_ernie4_5.py,sha256=t6FppbP1O7icRfoOsps_cNQ3KLdvFTikvrK5dAvrGY4,20583
+transformers/models/ernie4_5/modular_ernie4_5.py,sha256=ake2tS9BcYGYQXtIeL2qvCjEsSpqItrWOtaxJTy6_tU,5604
+transformers/models/ernie4_5_moe/__init__.py,sha256=MJaAQxyB3YypXN79FGJpkSvnX6KWt86iunOFXjiA7a4,1005
+transformers/models/ernie4_5_moe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/ernie4_5_moe/__pycache__/configuration_ernie4_5_moe.cpython-310.pyc,,
+transformers/models/ernie4_5_moe/__pycache__/modeling_ernie4_5_moe.cpython-310.pyc,,
+transformers/models/ernie4_5_moe/__pycache__/modular_ernie4_5_moe.cpython-310.pyc,,
+transformers/models/ernie4_5_moe/configuration_ernie4_5_moe.py,sha256=HpcWwQdyQFpvYwFzMBptIsUq90mRDxNVDQEXpJGJUc8,13489
+transformers/models/ernie4_5_moe/modeling_ernie4_5_moe.py,sha256=NL9f4xuvM98vTfn0bft9Gbqpba9lVjP1oVFcp9DbpNU,33574
+transformers/models/ernie4_5_moe/modular_ernie4_5_moe.py,sha256=-VB2OWfxK4TnyFwP1fGqApm1EYYMGYHBdYzuYS3L5UI,14444
+transformers/models/esm/__init__.py,sha256=muSqvVMt6mySkoAm7MjweiFHJVBSj70LlakjHmZ6PEE,1094
+transformers/models/esm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/esm/__pycache__/configuration_esm.cpython-310.pyc,,
+transformers/models/esm/__pycache__/modeling_esm.cpython-310.pyc,,
+transformers/models/esm/__pycache__/modeling_esmfold.cpython-310.pyc,,
+transformers/models/esm/__pycache__/modeling_tf_esm.cpython-310.pyc,,
+transformers/models/esm/__pycache__/tokenization_esm.cpython-310.pyc,,
+transformers/models/esm/configuration_esm.py,sha256=ehwkp9UcXcXXp6dphMO7cqdn-G1Bv1LUB4sohOvWy6Y,14436
+transformers/models/esm/modeling_esm.py,sha256=q2b89mwnYJfwy-sJ2LDwht82KBXQl68onI3_B0d7KmU,43651
+transformers/models/esm/modeling_esmfold.py,sha256=6UdvW40b9GlypLx0sRolDNQF9Y4EWxB9Z9YXUwEu2Mo,86149
+transformers/models/esm/modeling_tf_esm.py,sha256=5GsQDy8NmoHzk0s9rr1PhBQXmGke7FgtKYxd6XN0k_k,68985
+transformers/models/esm/openfold_utils/__init__.py,sha256=Xy2uqvFsLC8Ax-OOce5PgoBDiZgEJgJPqs__p5SBWUY,446
+transformers/models/esm/openfold_utils/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/chunk_utils.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/data_transforms.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/feats.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/loss.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/protein.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/residue_constants.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/rigid_utils.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/__pycache__/tensor_utils.cpython-310.pyc,,
+transformers/models/esm/openfold_utils/chunk_utils.py,sha256=TTDioMfiRFg729vlKdpJnNEX294AJS7RSxIGlf0aTlM,14392
+transformers/models/esm/openfold_utils/data_transforms.py,sha256=Q5J_BpJ_8Fa5fZ8nP6kPB5ops-Y4MydSQkwZ-_yMDBA,3688
+transformers/models/esm/openfold_utils/feats.py,sha256=QCYupsVINo5jJuwYk38TejNYkPlGm6Kfc1YpNUxpI8s,8355
+transformers/models/esm/openfold_utils/loss.py,sha256=sndbYMMXuL0KIHlzq7ZJUlQoIRMy2Q3ZGl3h20BR1rg,3692
+transformers/models/esm/openfold_utils/protein.py,sha256=rx3YMO93zal9R6F9equP6DgCIURENBu_943N-gho8R8,11499
+transformers/models/esm/openfold_utils/residue_constants.py,sha256=-y44cw8jjQJakRSjn4MAMCeGhFSHoPzUCiMv9MfdGes,37875
+transformers/models/esm/openfold_utils/rigid_utils.py,sha256=oM1q5gGBukDtpQqrJosTmfASUEQRjM7Lo-u2PR-W6Cs,41006
+transformers/models/esm/openfold_utils/tensor_utils.py,sha256=94wNOGOftULOVB_WsyH6b-Sv38Ny1QCa4R6he3iRyl8,4763
+transformers/models/esm/tokenization_esm.py,sha256=HcbVQ9J-e7NjuhVSqcHMj-2PIGTtok-5zRRT-YhffdE,5379
+transformers/models/evolla/__init__.py,sha256=pOj8KGoc9jqtS_PYTeNCxZUtQrlFR_txE-kdZpiAkCw,1030
+transformers/models/evolla/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/evolla/__pycache__/configuration_evolla.cpython-310.pyc,,
+transformers/models/evolla/__pycache__/modeling_evolla.cpython-310.pyc,,
+transformers/models/evolla/__pycache__/modular_evolla.cpython-310.pyc,,
+transformers/models/evolla/__pycache__/processing_evolla.cpython-310.pyc,,
+transformers/models/evolla/configuration_evolla.py,sha256=jz9pKidmvndFIVcAAlpjw7BTb3i-Mv94ac9yhLprNlA,13817
+transformers/models/evolla/modeling_evolla.py,sha256=upy4yRn2PgOYdDtCzrRV6tiVN4AK8dZy6wW6VRj0Ds4,68693
+transformers/models/evolla/modular_evolla.py,sha256=DZ4Fr-CBwA80vjUnrFaoxSFZIrG_r21GZINvxqagmn0,41264
+transformers/models/evolla/processing_evolla.py,sha256=l__liYSr-NmfClwzRCL88HoIAUs1TZpFYVyn4edYzlU,11480
+transformers/models/exaone4/__init__.py,sha256=gUDbb0olRjqxaPnB3APYKYKRlDPG2phGkfrmf7mIVD4,1018
+transformers/models/exaone4/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/exaone4/__pycache__/configuration_exaone4.cpython-310.pyc,,
+transformers/models/exaone4/__pycache__/modeling_exaone4.cpython-310.pyc,,
+transformers/models/exaone4/__pycache__/modular_exaone4.cpython-310.pyc,,
+transformers/models/exaone4/configuration_exaone4.py,sha256=B3cPSIibaxW3n3qEgPUyeeKp2hJ5HlFsvzCsoZABUJU,12614
+transformers/models/exaone4/modeling_exaone4.py,sha256=0EXIXqwYuEPJZ8GAlM2DEpdwDrqgzOcBiXmLttORmXs,23795
+transformers/models/exaone4/modular_exaone4.py,sha256=CL-l92J76lA4zJW0ojVNkZADuHiXxVfavaHeDlMFqxY,23853
+transformers/models/falcon/__init__.py,sha256=qmBlF_xusyrueKMfriC2ldVrHzeLIT7ruSdduMODuE4,993
+transformers/models/falcon/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/falcon/__pycache__/configuration_falcon.cpython-310.pyc,,
+transformers/models/falcon/__pycache__/modeling_falcon.cpython-310.pyc,,
+transformers/models/falcon/configuration_falcon.py,sha256=5vh10LAkioX6y3qJh84u3SlXmu3gPArXNMe1apM7f9g,10917
+transformers/models/falcon/modeling_falcon.py,sha256=FJfZn7uxA9D6MfqDoNQ2v30bUar5sZM20ktGTJ_L92Y,64435
+transformers/models/falcon_h1/__init__.py,sha256=cpix3f3f_xMDLf2OLuyYZULnb7enZl3UZapPQuf0YZc,1012
+transformers/models/falcon_h1/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/falcon_h1/__pycache__/configuration_falcon_h1.cpython-310.pyc,,
+transformers/models/falcon_h1/__pycache__/modeling_falcon_h1.cpython-310.pyc,,
+transformers/models/falcon_h1/__pycache__/modular_falcon_h1.cpython-310.pyc,,
+transformers/models/falcon_h1/configuration_falcon_h1.py,sha256=ql8WPS_TKtf2KPz0Ko_WxJpf7NVnyufn-B-j20kewfc,13894
+transformers/models/falcon_h1/modeling_falcon_h1.py,sha256=EIy9gYUJw9_SYLnMUYNgtWw7B4mEWDsEgqt9-nnT73A,73966
+transformers/models/falcon_h1/modular_falcon_h1.py,sha256=2PXtQYf0RJQfQvI1XQXatHtCAyoiuCS9KHHEkDmKvKc,61952
+transformers/models/falcon_mamba/__init__.py,sha256=Czo-T_Nt73nvRbK-yJEZAYsU3Bxu4i1fOxFuPosiFPw,1005
+transformers/models/falcon_mamba/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/falcon_mamba/__pycache__/configuration_falcon_mamba.cpython-310.pyc,,
+transformers/models/falcon_mamba/__pycache__/modeling_falcon_mamba.cpython-310.pyc,,
+transformers/models/falcon_mamba/__pycache__/modular_falcon_mamba.cpython-310.pyc,,
+transformers/models/falcon_mamba/configuration_falcon_mamba.py,sha256=xbRMQ4ZHRpJmNHxVJh2tIYtnMJWAME0aDbKe1oMY_34,8846
+transformers/models/falcon_mamba/modeling_falcon_mamba.py,sha256=Kgi8wE3btuRVqd42YVVbYgBXN3vSTY4JzopyI-tLZ4w,41956
+transformers/models/falcon_mamba/modular_falcon_mamba.py,sha256=92aeda5xTl1aSOv2zTQhlCQ2fZlYAkiRPVow4aHtwtQ,24524
+transformers/models/fastspeech2_conformer/__init__.py,sha256=pILmX51CcqSiFGtl_dsX1yW2S_QugA3UHAT8f4psOtA,1077
+transformers/models/fastspeech2_conformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/fastspeech2_conformer/__pycache__/configuration_fastspeech2_conformer.cpython-310.pyc,,
+transformers/models/fastspeech2_conformer/__pycache__/modeling_fastspeech2_conformer.cpython-310.pyc,,
+transformers/models/fastspeech2_conformer/__pycache__/tokenization_fastspeech2_conformer.cpython-310.pyc,,
+transformers/models/fastspeech2_conformer/configuration_fastspeech2_conformer.py,sha256=TZ6a2rSWE3ikugOBx_sr4tULm2FpX8Qtj2S7MLBdnNQ,24656
+transformers/models/fastspeech2_conformer/modeling_fastspeech2_conformer.py,sha256=H1ysWNoXQ_noF121qoeyRa9n5glBrwGx2rRGhziTZXQ,68521
+transformers/models/fastspeech2_conformer/tokenization_fastspeech2_conformer.py,sha256=x8b0G-lsibtRBg-I3FzLBHC1YhiTmr8A2o6V8LbEz6M,6258
+transformers/models/flaubert/__init__.py,sha256=LdGmxq7pcDPVcvqO1ol7VYtpjKKCAQuiJ1ISrNT9nEs,1078
+transformers/models/flaubert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/flaubert/__pycache__/configuration_flaubert.cpython-310.pyc,,
+transformers/models/flaubert/__pycache__/modeling_flaubert.cpython-310.pyc,,
+transformers/models/flaubert/__pycache__/modeling_tf_flaubert.cpython-310.pyc,,
+transformers/models/flaubert/__pycache__/tokenization_flaubert.cpython-310.pyc,,
+transformers/models/flaubert/configuration_flaubert.py,sha256=920NSmtA4I1NbeTk642E8OvKEWD9TnwBggtaIGyx70U,11250
+transformers/models/flaubert/modeling_flaubert.py,sha256=o91gC3wmWAM4HXfeAtU8BwMQzlqmOv-Po_HZljFL2zM,80054
+transformers/models/flaubert/modeling_tf_flaubert.py,sha256=zeZWpnYi56nPKArmP43f6TTDPOxxObhgjd0CXJ4Y3Qo,57170
+transformers/models/flaubert/tokenization_flaubert.py,sha256=ACYpzkElWcCyW9lJX9mRqh1-uEI9qqV2IQIXSr8JhPk,20970
+transformers/models/flava/__init__.py,sha256=UZ-PnfpalIOh2pPXWj_WSjsxjLgMBh2kKVyyLsNTUOk,1160
+transformers/models/flava/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/flava/__pycache__/configuration_flava.cpython-310.pyc,,
+transformers/models/flava/__pycache__/feature_extraction_flava.cpython-310.pyc,,
+transformers/models/flava/__pycache__/image_processing_flava.cpython-310.pyc,,
+transformers/models/flava/__pycache__/image_processing_flava_fast.cpython-310.pyc,,
+transformers/models/flava/__pycache__/modeling_flava.cpython-310.pyc,,
+transformers/models/flava/__pycache__/processing_flava.cpython-310.pyc,,
+transformers/models/flava/configuration_flava.py,sha256=bYaFpEYjHxYp07JhrUvr9ds5kFubfw51DAy-AAjIGwo,34125
+transformers/models/flava/feature_extraction_flava.py,sha256=fZzf449ea7VNw1xyNfCuoa_e2pMEfGSxqNTX9YdoE5I,1314
+transformers/models/flava/image_processing_flava.py,sha256=9_9CvPqhUtFXrkvtXFppD_Su6xS81IQC4wToozdKt_U,37658
+transformers/models/flava/image_processing_flava_fast.py,sha256=tdd8kCq060YJXgofh0-iXj1zilcYcur-nbe4U9Ppnys,22797
+transformers/models/flava/modeling_flava.py,sha256=XM70a8KIOmUa0OVwQQJu0C9SM4O9UaOOrGfOO3DWQOo,94808
+transformers/models/flava/processing_flava.py,sha256=WRs_usFz1BWofnTFveZNCQyFo_sR5DarmdbL1HaGjs0,5969
+transformers/models/florence2/__init__.py,sha256=H4rJT4tWJithwWolb041i7SM693Y_-oO8hhdePbjYpY,1039
+transformers/models/florence2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/florence2/__pycache__/configuration_florence2.cpython-310.pyc,,
+transformers/models/florence2/__pycache__/modeling_florence2.cpython-310.pyc,,
+transformers/models/florence2/__pycache__/modular_florence2.cpython-310.pyc,,
+transformers/models/florence2/__pycache__/processing_florence2.cpython-310.pyc,,
+transformers/models/florence2/configuration_florence2.py,sha256=elSEHjPwVE3GcOUCJDVktLEINt_lD2BIJCSAnFqlFhU,9623
+transformers/models/florence2/modeling_florence2.py,sha256=gHTEBmPKYa8i3-827H_3-qMdLx4oSO12laOtOwm3CaU,42586
+transformers/models/florence2/modular_florence2.py,sha256=UzUPqNmszPjNDDgc-KroXHJBHBGJvje9yX3XT8oV1L4,78252
+transformers/models/florence2/processing_florence2.py,sha256=3thjuO62hubNH8KREJTbqOo8sM0V4Y26rwiJgyqND1I,36784
+transformers/models/fnet/__init__.py,sha256=V3nuz_DsD_K5-RuL-Gt4hr5FVtNz12s46O_Vtx_xvCY,1068
+transformers/models/fnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/fnet/__pycache__/configuration_fnet.cpython-310.pyc,,
+transformers/models/fnet/__pycache__/modeling_fnet.cpython-310.pyc,,
+transformers/models/fnet/__pycache__/tokenization_fnet.cpython-310.pyc,,
+transformers/models/fnet/__pycache__/tokenization_fnet_fast.cpython-310.pyc,,
+transformers/models/fnet/configuration_fnet.py,sha256=oZVGszdEYsE-nJnpSlmU3r4tENCfwHnNKaL4NmrD7N4,5567
+transformers/models/fnet/modeling_fnet.py,sha256=DD9ndiUWGbr7ikjckfblZGcmJ4xfRqtixb70Bq8MgL8,44223
+transformers/models/fnet/tokenization_fnet.py,sha256=1oHKKZ05BkW9gY2Ibq__USJVrfxIL6ee2_kJK3vTH_Y,13537
+transformers/models/fnet/tokenization_fnet_fast.py,sha256=Ed77wG8t5cE351Rx2shX98ysFjQFasEor4-U0zj2wYk,6841
+transformers/models/focalnet/__init__.py,sha256=kFk7pYv4troBIWdCYosHMKh8PAnpXqjlxaRRQ5adkG0,997
+transformers/models/focalnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/focalnet/__pycache__/configuration_focalnet.cpython-310.pyc,,
+transformers/models/focalnet/__pycache__/modeling_focalnet.cpython-310.pyc,,
+transformers/models/focalnet/configuration_focalnet.py,sha256=L6CS3mcLLDZTIFeiTqweu8W1MogNQq8ZMrIiD_-g1x4,8057
+transformers/models/focalnet/modeling_focalnet.py,sha256=tghosAajG_4vz19akURDE2gZH2PjP_ThcGv_SKZSVtU,38652
+transformers/models/fsmt/__init__.py,sha256=u_Xx7d3qDicqwR_W0js1h2wPiLKWM1RlMu7fsBdIHy4,1026
+transformers/models/fsmt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/fsmt/__pycache__/configuration_fsmt.cpython-310.pyc,,
+transformers/models/fsmt/__pycache__/modeling_fsmt.cpython-310.pyc,,
+transformers/models/fsmt/__pycache__/tokenization_fsmt.cpython-310.pyc,,
+transformers/models/fsmt/configuration_fsmt.py,sha256=TWNVhQROEA1WMCL6j3HX3nRkyhVsB2n2kwNb6QkE4pY,10363
+transformers/models/fsmt/modeling_fsmt.py,sha256=1pfKnAlwqSiQl-x_2keGM7RJmkRtJ402IJVCe5uaens,53160
+transformers/models/fsmt/tokenization_fsmt.py,sha256=86Txz3pYk6fL5nWcqfbpBSo_EuaC-O6tqqHo5zu9GUw,17944
+transformers/models/funnel/__init__.py,sha256=087Y3Xz6y0HA5SgKe-s2z-ZzUIq1u_axxCRh2__gVro,1182
+transformers/models/funnel/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/funnel/__pycache__/configuration_funnel.cpython-310.pyc,,
+transformers/models/funnel/__pycache__/modeling_funnel.cpython-310.pyc,,
+transformers/models/funnel/__pycache__/modeling_tf_funnel.cpython-310.pyc,,
+transformers/models/funnel/__pycache__/tokenization_funnel.cpython-310.pyc,,
+transformers/models/funnel/__pycache__/tokenization_funnel_fast.cpython-310.pyc,,
+transformers/models/funnel/configuration_funnel.py,sha256=b53gi5CW7KpmzFFAM2klOVODwb1Jq30XbzX1rINu7x8,7682
+transformers/models/funnel/modeling_funnel.py,sha256=k5rkMNmHEkJ2YON2bDDmb5a9krS9z-ZjxZR-1OSIuMo,61585
+transformers/models/funnel/modeling_tf_funnel.py,sha256=ZMdqwNPK3WkhzO-HAfaDtbtoctQwEDjGsfiHsJ_CXWg,80735
+transformers/models/funnel/tokenization_funnel.py,sha256=2VRzAH-LPCQcL_gm0LFKsoIPdAKajzCC3gUhrBWuPRE,22685
+transformers/models/funnel/tokenization_funnel_fast.py,sha256=dMo_pnTLyD926bjcPiormC4L_l6oV3W-Xt7xy858Mfs,8666
+transformers/models/fuyu/__init__.py,sha256=NcygIhTFvIZzXPZUReC1WYReGAVINSpG0xW7KqEmd8c,1065
+transformers/models/fuyu/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/fuyu/__pycache__/configuration_fuyu.cpython-310.pyc,,
+transformers/models/fuyu/__pycache__/image_processing_fuyu.cpython-310.pyc,,
+transformers/models/fuyu/__pycache__/modeling_fuyu.cpython-310.pyc,,
+transformers/models/fuyu/__pycache__/processing_fuyu.cpython-310.pyc,,
+transformers/models/fuyu/configuration_fuyu.py,sha256=7jgdM3jnzy-Z-IZGjx3VgAhuS5_bnEa7FIO8y6kVTaw,10198
+transformers/models/fuyu/image_processing_fuyu.py,sha256=Wit3xBHJVI1-pqsdXHqxHa1kv8LlRaP4DBrvtp8Z9e0,33509
+transformers/models/fuyu/modeling_fuyu.py,sha256=adkvthuJOIEYSeVram60zBZLm-toHUwMU-aHaunVuxw,18117
+transformers/models/fuyu/processing_fuyu.py,sha256=fAY3zppuOVhzLjGZDaZBPcT5f7cwFp42GpzhJDSvCe4,36675
+transformers/models/gemma/__init__.py,sha256=xXoIfeCXNQOEnARxU3QucfH5mn-a_AE4wp69YkykT50,1111
+transformers/models/gemma/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gemma/__pycache__/configuration_gemma.cpython-310.pyc,,
+transformers/models/gemma/__pycache__/modeling_flax_gemma.cpython-310.pyc,,
+transformers/models/gemma/__pycache__/modeling_gemma.cpython-310.pyc,,
+transformers/models/gemma/__pycache__/modular_gemma.cpython-310.pyc,,
+transformers/models/gemma/__pycache__/tokenization_gemma.cpython-310.pyc,,
+transformers/models/gemma/__pycache__/tokenization_gemma_fast.cpython-310.pyc,,
+transformers/models/gemma/configuration_gemma.py,sha256=LWnoaGz53xxPIbZT1WzQEuF7Rt_MplPVQ9NvP55XE9I,8375
+transformers/models/gemma/modeling_flax_gemma.py,sha256=rRGlPaBXI_lxtLz47GfwZabrdzM8EHctNgitlXNjz4Q,32439
+transformers/models/gemma/modeling_gemma.py,sha256=v-l00X25xRmwfTMklbc9aiUHvDQw7fypNXFk65_8zDU,21131
+transformers/models/gemma/modular_gemma.py,sha256=ROh1Q48U_qPDxlxY9mZU6m3duacYP5iUWkjwCt8U650,20345
+transformers/models/gemma/tokenization_gemma.py,sha256=AcVuuIvQS7kCoS03rX8VkC86S_ywQYKPUGq4ouFXdUY,14229
+transformers/models/gemma/tokenization_gemma_fast.py,sha256=iEJm0bejSYb1DmmXbb6UuRZaeGX0SLG1uCx5v625hTI,8097
+transformers/models/gemma2/__init__.py,sha256=H0jWJX-AcGRTjdzkGJagKnjB6GnpqVUG4ODFhMF9OWM,993
+transformers/models/gemma2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gemma2/__pycache__/configuration_gemma2.cpython-310.pyc,,
+transformers/models/gemma2/__pycache__/modeling_gemma2.cpython-310.pyc,,
+transformers/models/gemma2/__pycache__/modular_gemma2.cpython-310.pyc,,
+transformers/models/gemma2/configuration_gemma2.py,sha256=d3AKBGul20cPAuq6zFgUlexHzjWPK5GBDW1IcQZv_E8,9578
+transformers/models/gemma2/modeling_gemma2.py,sha256=iaedBf9I8rxnLjTWCEizzsssGQ7BXDKK-i4y2PRUO8Q,25596
+transformers/models/gemma2/modular_gemma2.py,sha256=pl8Lzq2V0c2dKIa2j1kvdQhgpzxXLLX1tfHq3FDvNbM,25160
+transformers/models/gemma3/__init__.py,sha256=yDt-ADg8e57SlRlpfsC7KzQCeYYgUrTz9ZO5VC5v_W4,1121
+transformers/models/gemma3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gemma3/__pycache__/configuration_gemma3.cpython-310.pyc,,
+transformers/models/gemma3/__pycache__/image_processing_gemma3.cpython-310.pyc,,
+transformers/models/gemma3/__pycache__/image_processing_gemma3_fast.cpython-310.pyc,,
+transformers/models/gemma3/__pycache__/modeling_gemma3.cpython-310.pyc,,
+transformers/models/gemma3/__pycache__/modular_gemma3.cpython-310.pyc,,
+transformers/models/gemma3/__pycache__/processing_gemma3.cpython-310.pyc,,
+transformers/models/gemma3/configuration_gemma3.py,sha256=fQ6Dor-5nOBhLaXRKruClkic6hK4CJ3oe1PMNyuJQNc,17748
+transformers/models/gemma3/image_processing_gemma3.py,sha256=HjGxXDHTsqj9S19EX3B92QlY4vMewbxORuEuH1NCNyQ,20130
+transformers/models/gemma3/image_processing_gemma3_fast.py,sha256=8vjmB29Dsx9vvgi26xd-QjJvKseLtQuirqetgieXDmI,11337
+transformers/models/gemma3/modeling_gemma3.py,sha256=tNVSdCpQfeG5F3DDR6eanzXFNURfPGtmknS27cbf68k,57989
+transformers/models/gemma3/modular_gemma3.py,sha256=xxBOeunYBZDCMFSosoKiM6I6Y7MHMgjEwamg2Ybjn7M,52996
+transformers/models/gemma3/processing_gemma3.py,sha256=MzntqO3yJNl9w0AAEhvBeI23afs70zDc8aKtBJWbp9o,7808
+transformers/models/gemma3n/__init__.py,sha256=ZSrv5oSiULGXY7Vszb--vaJh1l7FBe1lrZD_3LX6cj4,1079
+transformers/models/gemma3n/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gemma3n/__pycache__/configuration_gemma3n.cpython-310.pyc,,
+transformers/models/gemma3n/__pycache__/feature_extraction_gemma3n.cpython-310.pyc,,
+transformers/models/gemma3n/__pycache__/modeling_gemma3n.cpython-310.pyc,,
+transformers/models/gemma3n/__pycache__/modular_gemma3n.cpython-310.pyc,,
+transformers/models/gemma3n/__pycache__/processing_gemma3n.cpython-310.pyc,,
+transformers/models/gemma3n/configuration_gemma3n.py,sha256=01bfh2lUwLzY3gqlGn5Pas_L6w7oSQbhho-YnUfZi5s,36413
+transformers/models/gemma3n/feature_extraction_gemma3n.py,sha256=a_e5d6FFT1n6dcniJ531IdrHKWxJiN3FRWec7wwS23s,15129
+transformers/models/gemma3n/modeling_gemma3n.py,sha256=0B6v4OhoB4zdt7lz3sPkFcKnXkwJvo_5PSMj9qfKZS4,113236
+transformers/models/gemma3n/modular_gemma3n.py,sha256=7e9FsZMfv2mTpMhmv9XA3lnXFBccqIsUF-ogDTxjZ2o,130752
+transformers/models/gemma3n/processing_gemma3n.py,sha256=AXaElE0l4ddTOm2cJ587M46r6wHIlCm6ekj18hvOJlc,7054
+transformers/models/git/__init__.py,sha256=jY1iLd7UMOmcCfrKgzoUJawLa0DQ55wHN26L09YSwhc,1021
+transformers/models/git/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/git/__pycache__/configuration_git.cpython-310.pyc,,
+transformers/models/git/__pycache__/modeling_git.cpython-310.pyc,,
+transformers/models/git/__pycache__/processing_git.cpython-310.pyc,,
+transformers/models/git/configuration_git.py,sha256=SNcI2qHfnAuwDcYWfiP8Sb_TQXPtosHlw1vDY8bEl04,10447
+transformers/models/git/modeling_git.py,sha256=j3KDRQnIoefIDfKwh-T-00UQaawibJbQVKJV5179V94,62777
+transformers/models/git/processing_git.py,sha256=7NSxJj4JYp3i4laka-WGnjFnBt8PHE_Az2iVV1YhrT8,5323
+transformers/models/glm/__init__.py,sha256=fIafw6FAflbbeG_nEM_VPJyMJHnu_NbWHTHjECIAvIs,987
+transformers/models/glm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/glm/__pycache__/configuration_glm.cpython-310.pyc,,
+transformers/models/glm/__pycache__/modeling_glm.cpython-310.pyc,,
+transformers/models/glm/__pycache__/modular_glm.cpython-310.pyc,,
+transformers/models/glm/configuration_glm.py,sha256=0i7hGoGPrP308WOqZ2ZbGCw2-06GRiDvxAv_m2Fd-Fg,7535
+transformers/models/glm/modeling_glm.py,sha256=PcmhFjouRkRc3H6RMJ9_ehnjeINdNj4l-IwOM91bI-I,21384
+transformers/models/glm/modular_glm.py,sha256=rOSXBsyECZhENwaJ8M9bBxJ1NK2Lwv7POZu67Uu3xgQ,4093
+transformers/models/glm4/__init__.py,sha256=okqViVxR-MUlkyIdKmSwrDKA7u8pGG49OIKtW9X1hvU,989
+transformers/models/glm4/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/glm4/__pycache__/configuration_glm4.cpython-310.pyc,,
+transformers/models/glm4/__pycache__/modeling_glm4.cpython-310.pyc,,
+transformers/models/glm4/__pycache__/modular_glm4.cpython-310.pyc,,
+transformers/models/glm4/configuration_glm4.py,sha256=lFRWkK1kw_GDnhi0w0BViKnQ9FBpRp0uMEyjLxNW7dY,7551
+transformers/models/glm4/modeling_glm4.py,sha256=o39KNNchsad68SMulHdYSv9C_K3w-L0d514ZPVqafvo,22267
+transformers/models/glm4/modular_glm4.py,sha256=pch-cNrRSb-uoWzp6zKypU-un2Rf8yvzTophNck8yGA,5369
+transformers/models/glm4_moe/__init__.py,sha256=dfmB1kPUzq5-xfXh3zFtfGdSJu7CDDbfL401u_EayjM,997
+transformers/models/glm4_moe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/glm4_moe/__pycache__/configuration_glm4_moe.cpython-310.pyc,,
+transformers/models/glm4_moe/__pycache__/modeling_glm4_moe.cpython-310.pyc,,
+transformers/models/glm4_moe/__pycache__/modular_glm4_moe.cpython-310.pyc,,
+transformers/models/glm4_moe/configuration_glm4_moe.py,sha256=uhNU910obiitL0_IAnbO_STy7uuIBY_uugscT0caAJE,13422
+transformers/models/glm4_moe/modeling_glm4_moe.py,sha256=aont2BgLfv72td8H3cnUp01zpcUutEXH6GY0_coOtCo,26946
+transformers/models/glm4_moe/modular_glm4_moe.py,sha256=-UEihJuE_wIG9DX6RXuGCo8ObLmbmJmGtEsK0M_AOtI,15715
+transformers/models/glm4v/__init__.py,sha256=czqsAA98MYCyclV5YncS0xt0pnQcYUZc7jFgxZUEKmQ,1027
+transformers/models/glm4v/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/glm4v/__pycache__/configuration_glm4v.cpython-310.pyc,,
+transformers/models/glm4v/__pycache__/image_processing_glm4v.cpython-310.pyc,,
+transformers/models/glm4v/__pycache__/image_processing_glm4v_fast.cpython-310.pyc,,
+transformers/models/glm4v/__pycache__/modeling_glm4v.cpython-310.pyc,,
+transformers/models/glm4v/__pycache__/modular_glm4v.cpython-310.pyc,,
+transformers/models/glm4v/__pycache__/processing_glm4v.cpython-310.pyc,,
+transformers/models/glm4v/__pycache__/video_processing_glm4v.cpython-310.pyc,,
+transformers/models/glm4v/configuration_glm4v.py,sha256=zvdVZMe5Jino9jwelMI3MN-vXWJ1fRWH_Lz7ACQEv_0,17661
+transformers/models/glm4v/image_processing_glm4v.py,sha256=SjBio7w_x56Rbi_AUmetrknI5vuG-JDf9H1QOIWLnkE,24149
+transformers/models/glm4v/image_processing_glm4v_fast.py,sha256=Mcku9kVBnRcBLmM7JzG7MPb3L2Q2_zQZp2zjAi6mSbU,7086
+transformers/models/glm4v/modeling_glm4v.py,sha256=0QO5fiKD25yba0PdftTOLuRvW5bMSprvO2ueZBXLrjA,76440
+transformers/models/glm4v/modular_glm4v.py,sha256=GsW0ySPvOA0QS-kJy807s1m-SSY8Rz5IT2S8WfNpgDE,79715
+transformers/models/glm4v/processing_glm4v.py,sha256=QqYzzAivk_3ibot9UvnYXSFS3SXr9wxcwsi6zCidrO8,15254
+transformers/models/glm4v/video_processing_glm4v.py,sha256=21CM_dVYjBGx2qUIKnR9u3QZBIbx-pr0AeoBMiTI8Zo,10396
+transformers/models/glm4v_moe/__init__.py,sha256=4MuhU3oMjO5wL4YHEEhn0uU4qIsXz17DJPMs_xqMyHA,999
+transformers/models/glm4v_moe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/glm4v_moe/__pycache__/configuration_glm4v_moe.cpython-310.pyc,,
+transformers/models/glm4v_moe/__pycache__/modeling_glm4v_moe.cpython-310.pyc,,
+transformers/models/glm4v_moe/__pycache__/modular_glm4v_moe.cpython-310.pyc,,
+transformers/models/glm4v_moe/configuration_glm4v_moe.py,sha256=fYJuCYmxIZ1VacxYnE1EHqKtaIIY9cESoM1yYgC6zyY,19632
+transformers/models/glm4v_moe/modeling_glm4v_moe.py,sha256=-4JhmF0X5FKbCjKwEUgGqq1NTw0ZP1_4HyxP2pQzouE,82172
+transformers/models/glm4v_moe/modular_glm4v_moe.py,sha256=r1FUSTZQkuJt80hvTWMkeYLPXZJHz5l67WtkJmVevs0,21332
+transformers/models/glpn/__init__.py,sha256=YYoaugUj0un_FnfusrkzFfT_UtvUJEjMDaRDS8IcYAE,1073
+transformers/models/glpn/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/glpn/__pycache__/configuration_glpn.cpython-310.pyc,,
+transformers/models/glpn/__pycache__/feature_extraction_glpn.cpython-310.pyc,,
+transformers/models/glpn/__pycache__/image_processing_glpn.cpython-310.pyc,,
+transformers/models/glpn/__pycache__/modeling_glpn.cpython-310.pyc,,
+transformers/models/glpn/configuration_glpn.py,sha256=psEiatDZRceSeLe24Ch77es0_ugLEjzmzP81QthIXcI,5998
+transformers/models/glpn/feature_extraction_glpn.py,sha256=QC_SmxGijm3KyJtR_hEGG16TXPHpvv5pa5_0YrQLq0c,1284
+transformers/models/glpn/image_processing_glpn.py,sha256=pgSdZE05rAFDQsObYqEkDB3Pf_1ME11t-cd5AuAqFWs,12748
+transformers/models/glpn/modeling_glpn.py,sha256=qOE70YSKbsquwBdSiXD2En1oefwUtfZaNOWaVcH_IoM,29086
+transformers/models/got_ocr2/__init__.py,sha256=LBVZP8CBfOxaD9NLC2ZbZpLloHLIX7uDyM8m1-W2m6g,1138
+transformers/models/got_ocr2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/got_ocr2/__pycache__/configuration_got_ocr2.cpython-310.pyc,,
+transformers/models/got_ocr2/__pycache__/image_processing_got_ocr2.cpython-310.pyc,,
+transformers/models/got_ocr2/__pycache__/image_processing_got_ocr2_fast.cpython-310.pyc,,
+transformers/models/got_ocr2/__pycache__/modeling_got_ocr2.cpython-310.pyc,,
+transformers/models/got_ocr2/__pycache__/modular_got_ocr2.cpython-310.pyc,,
+transformers/models/got_ocr2/__pycache__/processing_got_ocr2.cpython-310.pyc,,
+transformers/models/got_ocr2/configuration_got_ocr2.py,sha256=n9a3boLFZN7HMCyFSrZhcZH-ceWk3_Ut9XJz1F_cEkI,9455
+transformers/models/got_ocr2/image_processing_got_ocr2.py,sha256=QNgXNJRXqPiBqIUlbxJ7zpYEJ1mQcnvaUQlLBeumH3w,25623
+transformers/models/got_ocr2/image_processing_got_ocr2_fast.py,sha256=vrL6BzudLGB7MNwQ76t4En4dxBzTFMmXYuRqqsF61ME,10800
+transformers/models/got_ocr2/modeling_got_ocr2.py,sha256=addXiXFVcwLdXXviQ3SXtEdev0mwEeflis1sB9mQL4Y,36414
+transformers/models/got_ocr2/modular_got_ocr2.py,sha256=WMidaQHePsEwVi2oFyuGS9K3Lqg_U9EL1iOCm4amK9Q,19537
+transformers/models/got_ocr2/processing_got_ocr2.py,sha256=u7yQBAq_CGlpU3mDHPHBkhJnZu-MX5WGHSTxyynxZUM,12579
+transformers/models/gpt2/__init__.py,sha256=NRi7aYu3gezDPsiXiiG6dgSpCMHSIvFpC3iI0w-JMA0,1182
+transformers/models/gpt2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gpt2/__pycache__/configuration_gpt2.cpython-310.pyc,,
+transformers/models/gpt2/__pycache__/modeling_flax_gpt2.cpython-310.pyc,,
+transformers/models/gpt2/__pycache__/modeling_gpt2.cpython-310.pyc,,
+transformers/models/gpt2/__pycache__/modeling_tf_gpt2.cpython-310.pyc,,
+transformers/models/gpt2/__pycache__/tokenization_gpt2.cpython-310.pyc,,
+transformers/models/gpt2/__pycache__/tokenization_gpt2_fast.cpython-310.pyc,,
+transformers/models/gpt2/__pycache__/tokenization_gpt2_tf.cpython-310.pyc,,
+transformers/models/gpt2/configuration_gpt2.py,sha256=oWdrBVDmgPqQJ2orzzELbqkbE_hvKk9Op4pwtEXN3hY,12059
+transformers/models/gpt2/modeling_flax_gpt2.py,sha256=IBlHlVFZw-O_BArk5pqMJWk-wsTVNLQLef6MGNDlCRk,32109
+transformers/models/gpt2/modeling_gpt2.py,sha256=i0io0wSexZjcGXll_g_csiUfwU9q5Mq-OBxxGR7Aic8,74479
+transformers/models/gpt2/modeling_tf_gpt2.py,sha256=xWPpjaGyLDObGq4-3zwsb5gQVpuXUZ2ayTZRI4wLB2c,56440
+transformers/models/gpt2/tokenization_gpt2.py,sha256=3bLgxaap-6YpehzZI-DR5s0FU8PM0riJjsmaiqKH_3Q,13154
+transformers/models/gpt2/tokenization_gpt2_fast.py,sha256=pKJ2PVaSzWUSIjXWoLp0r8LiIupthk_8oaTNhD-PhAw,5274
+transformers/models/gpt2/tokenization_gpt2_tf.py,sha256=Ma7Z4lkXDyeJeTw5-wwkJwttvIdUnGptzmnhmvzCX7A,4071
+transformers/models/gpt_bigcode/__init__.py,sha256=KQNb7PO57eZpP345wSbe_C3iL-N4VPscw1GY2mv81uE,1003
+transformers/models/gpt_bigcode/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gpt_bigcode/__pycache__/configuration_gpt_bigcode.cpython-310.pyc,,
+transformers/models/gpt_bigcode/__pycache__/modeling_gpt_bigcode.cpython-310.pyc,,
+transformers/models/gpt_bigcode/configuration_gpt_bigcode.py,sha256=5pL1meyCVQZXvco9WsIFNvDhEdtpAEVgTOg-xg2cWrw,6375
+transformers/models/gpt_bigcode/modeling_gpt_bigcode.py,sha256=amMOnVizstrZCkdatWF5Un3B64FH7mQ3_dd5zYVUIec,40580
+transformers/models/gpt_neo/__init__.py,sha256=b25qxianvucgAd3OxuI00Rr5324o-CRes0zrcEIOCZI,1036
+transformers/models/gpt_neo/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gpt_neo/__pycache__/configuration_gpt_neo.cpython-310.pyc,,
+transformers/models/gpt_neo/__pycache__/modeling_flax_gpt_neo.cpython-310.pyc,,
+transformers/models/gpt_neo/__pycache__/modeling_gpt_neo.cpython-310.pyc,,
+transformers/models/gpt_neo/configuration_gpt_neo.py,sha256=zRidKD8M7zf-YbaDWUYw8ScjQesO5BSI6d7YoHnyjwU,11907
+transformers/models/gpt_neo/modeling_flax_gpt_neo.py,sha256=fD4XijeKuru5evmV7NcPQAtgvQha8H-oEyJm2uNlE4Y,28175
+transformers/models/gpt_neo/modeling_gpt_neo.py,sha256=Uvtu51UjxDGwksNHUjzUWDElfBeb_RJkkD5Xi_B-i0A,51871
+transformers/models/gpt_neox/__init__.py,sha256=6CL92CuqBTIDJ-YH_doFwb-oRylAffw7pwxedv3a-40,1043
+transformers/models/gpt_neox/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gpt_neox/__pycache__/configuration_gpt_neox.cpython-310.pyc,,
+transformers/models/gpt_neox/__pycache__/modeling_gpt_neox.cpython-310.pyc,,
+transformers/models/gpt_neox/__pycache__/modular_gpt_neox.cpython-310.pyc,,
+transformers/models/gpt_neox/__pycache__/tokenization_gpt_neox_fast.cpython-310.pyc,,
+transformers/models/gpt_neox/configuration_gpt_neox.py,sha256=-z9ztrlOAgyorPeZKTp-fOvSVWOoZuqhiAfq0VTBuNM,10982
+transformers/models/gpt_neox/modeling_gpt_neox.py,sha256=PSqfSJkhQ9EtjNJP6Mill14c2QTI_b3eAEXHNRNeTiw,34788
+transformers/models/gpt_neox/modular_gpt_neox.py,sha256=npxPxIzdGVA7ImVNCW28oYzv-OdmShJR_GUkHpdzm34,28940
+transformers/models/gpt_neox/tokenization_gpt_neox_fast.py,sha256=iivrluP4OTkQlBQjqz1kpn0NhIrarqPafDbCgHGc80o,8986
+transformers/models/gpt_neox_japanese/__init__.py,sha256=z4kbUmZSjE-Hs9ba8ul3Yncc9ZJy7ePufbwwRlfqWqw,1065
+transformers/models/gpt_neox_japanese/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gpt_neox_japanese/__pycache__/configuration_gpt_neox_japanese.cpython-310.pyc,,
+transformers/models/gpt_neox_japanese/__pycache__/modeling_gpt_neox_japanese.cpython-310.pyc,,
+transformers/models/gpt_neox_japanese/__pycache__/tokenization_gpt_neox_japanese.cpython-310.pyc,,
+transformers/models/gpt_neox_japanese/configuration_gpt_neox_japanese.py,sha256=Mae05uoCqq3q20e-da1CoCxCegR_Ng6q5R-1hrcacVI,9122
+transformers/models/gpt_neox_japanese/modeling_gpt_neox_japanese.py,sha256=cmkGAVaDpprh6RePEaFGKBkCWDcw--ijvfLO0KpfNTk,32909
+transformers/models/gpt_neox_japanese/tokenization_gpt_neox_japanese.py,sha256=0k_Len46JM8p50cubkBuklZtiAwcZJTaSOys0k8N4SI,16944
+transformers/models/gpt_oss/__init__.py,sha256=a3dnVKgP6RwbuxBJW3kodYKj8oVF5Y6pLJixMthP1yA,995
+transformers/models/gpt_oss/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gpt_oss/__pycache__/configuration_gpt_oss.cpython-310.pyc,,
+transformers/models/gpt_oss/__pycache__/modeling_gpt_oss.cpython-310.pyc,,
+transformers/models/gpt_oss/__pycache__/modular_gpt_oss.cpython-310.pyc,,
+transformers/models/gpt_oss/configuration_gpt_oss.py,sha256=UI580mE87Qag1lJmxQNoD06BzfzRvEbtPq2jiAwwaOY,4857
+transformers/models/gpt_oss/modeling_gpt_oss.py,sha256=LiblbvbbjnjvND-WMxu_bYqxelu8nHUPLU9pIIwcEuA,32367
+transformers/models/gpt_oss/modular_gpt_oss.py,sha256=zNmXw91TImqG3qSVPRAGkCdbzv5ypMyKmBT_QXLp_GU,20307
+transformers/models/gpt_sw3/__init__.py,sha256=-g6WlJ6EhhrJKCCsPf78cgvGD7oWvfeW9GBGBpW6wcM,958
+transformers/models/gpt_sw3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gpt_sw3/__pycache__/tokenization_gpt_sw3.cpython-310.pyc,,
+transformers/models/gpt_sw3/tokenization_gpt_sw3.py,sha256=6z6Yd9eLqFgEKb_Z4ow8kFOuhZVTD0ejrboc9aktNIc,12565
+transformers/models/gptj/__init__.py,sha256=rgFDJcsxcq1ytl7BTZthr7sSmaxqggSbvrIseycmE-s,1063
+transformers/models/gptj/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/gptj/__pycache__/configuration_gptj.cpython-310.pyc,,
+transformers/models/gptj/__pycache__/modeling_flax_gptj.cpython-310.pyc,,
+transformers/models/gptj/__pycache__/modeling_gptj.cpython-310.pyc,,
+transformers/models/gptj/__pycache__/modeling_tf_gptj.cpython-310.pyc,,
+transformers/models/gptj/configuration_gptj.py,sha256=wJU2oz2LYuleopQEzA2soQauHwae7JinCxJi_hGz2YM,8860
+transformers/models/gptj/modeling_flax_gptj.py,sha256=zod4lQZEi_H8sy4zbtmb2Gn5mEiFSmPZjYbffpztX_8,28620
+transformers/models/gptj/modeling_gptj.py,sha256=-jajsfDRdAt1tkExa7AVd5aGYWxqqE6KSd1NWINY3JQ,54327
+transformers/models/gptj/modeling_tf_gptj.py,sha256=RHLHR65JSAH9IC-Rp3ZUVZKFkJfahNJZzlVwW--HMxE,47831
+transformers/models/granite/__init__.py,sha256=cDxmZNuphkDCs2U8W5C95Vhu577kdZHKHUWWaQ3vk5U,1015
+transformers/models/granite/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/granite/__pycache__/configuration_granite.cpython-310.pyc,,
+transformers/models/granite/__pycache__/modeling_granite.cpython-310.pyc,,
+transformers/models/granite/__pycache__/modular_granite.cpython-310.pyc,,
+transformers/models/granite/configuration_granite.py,sha256=U1CQ2gvTYGx753UX0t5IOfcLllikDU7Jupj7NlOX3Dk,9348
+transformers/models/granite/modeling_granite.py,sha256=EL1a8XVsMSU0yP11JkdPAj7OBRRNlA-jgY1WXhjw6Vc,25009
+transformers/models/granite/modular_granite.py,sha256=UdiVEtjsVwEtoIQ8QvaFq_xafbZG0dGEeKWS4UHLpEI,11933
+transformers/models/granite_speech/__init__.py,sha256=xD_zbTTnBiaB6EEG4yinaWd-yza1waa01GNKVhsGL1M,1107
+transformers/models/granite_speech/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/granite_speech/__pycache__/configuration_granite_speech.cpython-310.pyc,,
+transformers/models/granite_speech/__pycache__/feature_extraction_granite_speech.cpython-310.pyc,,
+transformers/models/granite_speech/__pycache__/modeling_granite_speech.cpython-310.pyc,,
+transformers/models/granite_speech/__pycache__/processing_granite_speech.cpython-310.pyc,,
+transformers/models/granite_speech/configuration_granite_speech.py,sha256=EYXvGbPHGa6rTZa4FeeR-kg98I_gW9JTiI1MT8XyZwg,8565
+transformers/models/granite_speech/feature_extraction_granite_speech.py,sha256=CrQoQlWFlY3B3vM0mDdZCFM8t_xp21vjGieZl65gErE,7395
+transformers/models/granite_speech/modeling_granite_speech.py,sha256=RVYjVXjM65qosL28v4pdIcej852Zqa1vyToDJSMgQ4k,26562
+transformers/models/granite_speech/processing_granite_speech.py,sha256=pMT_ByZPVZC3xBkCfFoW8CSLkY-uMdNW_4ufPbTxFP0,3922
+transformers/models/granitemoe/__init__.py,sha256=e4KKtNT7YFkYkPBfcS0VyhpT_1vF0JkR2qdYKPqRUcE,1001
+transformers/models/granitemoe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/granitemoe/__pycache__/configuration_granitemoe.cpython-310.pyc,,
+transformers/models/granitemoe/__pycache__/modeling_granitemoe.cpython-310.pyc,,
+transformers/models/granitemoe/configuration_granitemoe.py,sha256=bZMMl3W8IDz9VfbN98Y39K12K7C2Mm0D1-41vngyxfU,9513
+transformers/models/granitemoe/modeling_granitemoe.py,sha256=25hYrAyWZqItRg6KeY34CGOU6QhORd-TEp0UdN8dtAo,44896
+transformers/models/granitemoehybrid/__init__.py,sha256=yiZusdNxb3DK3MNKdwcVNM2bFfeASr76tKQwQwmSJ68,1043
+transformers/models/granitemoehybrid/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/granitemoehybrid/__pycache__/configuration_granitemoehybrid.cpython-310.pyc,,
+transformers/models/granitemoehybrid/__pycache__/modeling_granitemoehybrid.cpython-310.pyc,,
+transformers/models/granitemoehybrid/__pycache__/modular_granitemoehybrid.cpython-310.pyc,,
+transformers/models/granitemoehybrid/configuration_granitemoehybrid.py,sha256=ePlwYSexpKg8rXCl3X66ccnsejRSAQLrIsQcKR2m26U,12559
+transformers/models/granitemoehybrid/modeling_granitemoehybrid.py,sha256=WdtNenljILhDj_ozSaBlebJQsqBuEGMD0UWJNhbAPhc,84315
+transformers/models/granitemoehybrid/modular_granitemoehybrid.py,sha256=AMce2dc0cB8_JAa1MugDvgre0L3XzFu-mGg3U5PN__o,16752
+transformers/models/granitemoeshared/__init__.py,sha256=vmY98tLts1c_yvkLn9X-xk6CFtXIKskzYvFGMqQAskc,1013
+transformers/models/granitemoeshared/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/granitemoeshared/__pycache__/configuration_granitemoeshared.cpython-310.pyc,,
+transformers/models/granitemoeshared/__pycache__/modeling_granitemoeshared.cpython-310.pyc,,
+transformers/models/granitemoeshared/__pycache__/modular_granitemoeshared.cpython-310.pyc,,
+transformers/models/granitemoeshared/configuration_granitemoeshared.py,sha256=lYbrzbYRHxR5Xf8xb_7GVlw3NAkWGaMe_cVq8H6jIH8,9942
+transformers/models/granitemoeshared/modeling_granitemoeshared.py,sha256=waWe_7TH7vf0wRmYqeJmafLvbCSiO3XyLqNnRhnX4Dg,47286
+transformers/models/granitemoeshared/modular_granitemoeshared.py,sha256=UAQw2xWQ8avgcS5L5C-Al-lg38WMVF4ySXi7zWadlMs,8112
+transformers/models/grounding_dino/__init__.py,sha256=nTxZfZioCpS8hj_L80qZQkgPviMZrTxkz14B9sQQJjk,1161
+transformers/models/grounding_dino/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/grounding_dino/__pycache__/configuration_grounding_dino.cpython-310.pyc,,
+transformers/models/grounding_dino/__pycache__/image_processing_grounding_dino.cpython-310.pyc,,
+transformers/models/grounding_dino/__pycache__/image_processing_grounding_dino_fast.cpython-310.pyc,,
+transformers/models/grounding_dino/__pycache__/modeling_grounding_dino.cpython-310.pyc,,
+transformers/models/grounding_dino/__pycache__/modular_grounding_dino.cpython-310.pyc,,
+transformers/models/grounding_dino/__pycache__/processing_grounding_dino.cpython-310.pyc,,
+transformers/models/grounding_dino/configuration_grounding_dino.py,sha256=v0jseFxOwfmdOxes3oL75e-GmIdjIEngnJdMNPCES_Q,15246
+transformers/models/grounding_dino/image_processing_grounding_dino.py,sha256=ua_SAFOphMhQGNJyr172iibT5Yhiun8SG-bAN7L6ABA,72266
+transformers/models/grounding_dino/image_processing_grounding_dino_fast.py,sha256=s7fFtlpggJjTsOeYZsZecRQ0CQBYYwjaByenZpFTHkg,34950
+transformers/models/grounding_dino/modeling_grounding_dino.py,sha256=BrOXLrd8iF0ax_OfwSuqFqcluWQEpbasyrKPNO5t3Tc,130647
+transformers/models/grounding_dino/modular_grounding_dino.py,sha256=rLbksNDxVIZnhL-3vQD8-ITqeJtBHwhgnn6IrgYF1Rw,5286
+transformers/models/grounding_dino/processing_grounding_dino.py,sha256=3tZZnmoeydzLl-kmbCs5FlmORcLs0ebeM0w8nPgwJXI,12822
+transformers/models/groupvit/__init__.py,sha256=vrJ-tBa1XOd1CloHhXKMCIlggMxOS4M7jCcqlLQxMo4,1037
+transformers/models/groupvit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/groupvit/__pycache__/configuration_groupvit.cpython-310.pyc,,
+transformers/models/groupvit/__pycache__/modeling_groupvit.cpython-310.pyc,,
+transformers/models/groupvit/__pycache__/modeling_tf_groupvit.cpython-310.pyc,,
+transformers/models/groupvit/configuration_groupvit.py,sha256=XzBlYKFnyHGVmGdQN22pgWdPer0OGbvPWnCZvouQL_M,18684
+transformers/models/groupvit/modeling_groupvit.py,sha256=cVYDDVMUkRAZqXkX2XNOi_ikP1wXuA89ThWafIBGLRQ,61501
+transformers/models/groupvit/modeling_tf_groupvit.py,sha256=m65pNT0kRTVJZySd6tWeqY6Zx7KayxucNHSj_B3BSA4,90064
+transformers/models/helium/__init__.py,sha256=b1Senw5Mr129rzZSd1sW6-Ies2kIAUHfplpzgGeuTFE,993
+transformers/models/helium/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/helium/__pycache__/configuration_helium.cpython-310.pyc,,
+transformers/models/helium/__pycache__/modeling_helium.cpython-310.pyc,,
+transformers/models/helium/__pycache__/modular_helium.cpython-310.pyc,,
+transformers/models/helium/configuration_helium.py,sha256=kctXqQTceihfsqRx0vImc_urU3Ii5hyp-cUGy8TUT0E,7380
+transformers/models/helium/modeling_helium.py,sha256=MjwqU7OjiUxdrTWOxauZKIXi0zuRMRqcvdEY-6cUPLs,20908
+transformers/models/helium/modular_helium.py,sha256=6aFkqmryMAWqBC9D35FePAJEPdj6SuNYbvT3gC3j4tE,5501
+transformers/models/herbert/__init__.py,sha256=3i5hlRANc-OFP86y2qzb_OCWVjJQ9XQswiglh5KbU7Y,1003
+transformers/models/herbert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/herbert/__pycache__/tokenization_herbert.cpython-310.pyc,,
+transformers/models/herbert/__pycache__/tokenization_herbert_fast.cpython-310.pyc,,
+transformers/models/herbert/tokenization_herbert.py,sha256=-1q4wQyllXCSydUXL0DO8Nm9OqmAcIGdNhCvgb6rxeg,23808
+transformers/models/herbert/tokenization_herbert_fast.py,sha256=S_47DZCpq7SK9d21QKf8jF5FZvVkRFERzD_iRV2IMg0,4919
+transformers/models/hgnet_v2/__init__.py,sha256=sBFNC0RNpS-oEnOiwtxy2SkUPAJgmI5uXXq2WjSHRd8,999
+transformers/models/hgnet_v2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/hgnet_v2/__pycache__/configuration_hgnet_v2.cpython-310.pyc,,
+transformers/models/hgnet_v2/__pycache__/modeling_hgnet_v2.cpython-310.pyc,,
+transformers/models/hgnet_v2/__pycache__/modular_hgnet_v2.cpython-310.pyc,,
+transformers/models/hgnet_v2/configuration_hgnet_v2.py,sha256=Gr8N48fXLivF_jKgpm62-1mTvqo5QDfw-h0JceCXbjY,8823
+transformers/models/hgnet_v2/modeling_hgnet_v2.py,sha256=ZGFQCl6MrgdaQVRp-eAKcCu282sAYwv6OvRW3NZIh3Y,19002
+transformers/models/hgnet_v2/modular_hgnet_v2.py,sha256=ztJ7t_xoCPgoAWnnTK4TbHqijJ0xpvMk8NjqOJFWB_w,25442
+transformers/models/hiera/__init__.py,sha256=b1kwKtpZVISJZ5Pri421uvH2v3IoRQ6XXHzxFOPHN-g,991
+transformers/models/hiera/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/hiera/__pycache__/configuration_hiera.cpython-310.pyc,,
+transformers/models/hiera/__pycache__/modeling_hiera.cpython-310.pyc,,
+transformers/models/hiera/configuration_hiera.py,sha256=QbF2S73pDapMC0_AoQVnPZTqWgs0tXvWWgSAvjNxEFE,9319
+transformers/models/hiera/modeling_hiera.py,sha256=JgEE7y4yUCT9Ktfuahv_Dq53qOIl6QTqgXecQt2Kr-Y,63049
+transformers/models/hubert/__init__.py,sha256=ai560JtgkksShocy0zcDejelkRZnK4IZPVKaTHCOxPQ,1031
+transformers/models/hubert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/hubert/__pycache__/configuration_hubert.cpython-310.pyc,,
+transformers/models/hubert/__pycache__/modeling_hubert.cpython-310.pyc,,
+transformers/models/hubert/__pycache__/modeling_tf_hubert.cpython-310.pyc,,
+transformers/models/hubert/__pycache__/modular_hubert.cpython-310.pyc,,
+transformers/models/hubert/configuration_hubert.py,sha256=XFh70tUL-ITYtn-RMt-lZl_Ej2qQ24vJLZZyBYF3PwA,14962
+transformers/models/hubert/modeling_hubert.py,sha256=D0WYbO8xGUHMYntJ7ZNyObytNc4DosDc_A3E73ByYgM,54623
+transformers/models/hubert/modeling_tf_hubert.py,sha256=ED9pJy2PK08C_dRaPOdWgkLvd09BZ6sQmKSuqQbOYok,70566
+transformers/models/hubert/modular_hubert.py,sha256=fhDox-l7V90dmRmOWoJ0bGwhkJZHNmEzAlPLP5BdD-E,11949
+transformers/models/hunyuan_v1_dense/__init__.py,sha256=FZn7rOtjmLA5vwEeH99QcgAveRMl1LbHQOyBKhywPWY,442
+transformers/models/hunyuan_v1_dense/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/hunyuan_v1_dense/__pycache__/configuration_hunyuan_v1_dense.cpython-310.pyc,,
+transformers/models/hunyuan_v1_dense/__pycache__/modeling_hunyuan_v1_dense.cpython-310.pyc,,
+transformers/models/hunyuan_v1_dense/__pycache__/modular_hunyuan_v1_dense.cpython-310.pyc,,
+transformers/models/hunyuan_v1_dense/configuration_hunyuan_v1_dense.py,sha256=xfweGl6-PcYJ996VgbIznOxQn4BwrFvQ9hxrtJpNLWM,9921
+transformers/models/hunyuan_v1_dense/modeling_hunyuan_v1_dense.py,sha256=N_fysxaPCJoUwCU6KHiBMxHz_uuSqgTDp9kgnas7uh0,22510
+transformers/models/hunyuan_v1_dense/modular_hunyuan_v1_dense.py,sha256=PMl_5fziNAxK4jykrRlNBxiQSOWRqdsvMfml5Awh4Mo,7640
+transformers/models/hunyuan_v1_moe/__init__.py,sha256=SrgoAMLn102HlTL_4fm7CwAFeFSlAWDvFGZcUU2S_9o,396
+transformers/models/hunyuan_v1_moe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/hunyuan_v1_moe/__pycache__/configuration_hunyuan_v1_moe.cpython-310.pyc,,
+transformers/models/hunyuan_v1_moe/__pycache__/modeling_hunyuan_v1_moe.cpython-310.pyc,,
+transformers/models/hunyuan_v1_moe/__pycache__/modular_hunyuan_v1_moe.cpython-310.pyc,,
+transformers/models/hunyuan_v1_moe/configuration_hunyuan_v1_moe.py,sha256=IQAJOMECCtBk224-2O9W3enCksVQluXIAW7Gu0sX6JQ,10694
+transformers/models/hunyuan_v1_moe/modeling_hunyuan_v1_moe.py,sha256=mqyxxOSENaEhDPJJuxRV7oRHeLP4RIzCVw_WRVVEKwI,26382
+transformers/models/hunyuan_v1_moe/modular_hunyuan_v1_moe.py,sha256=P1r79MB2wDOhP9H3MD70usmRadE6vaDUoTRmTSacdAY,11973
+transformers/models/ibert/__init__.py,sha256=UMTcE54y6O9UNF8l9VV2rrTlJSAHooxeNeHNzPSgr_E,991
+transformers/models/ibert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/ibert/__pycache__/configuration_ibert.cpython-310.pyc,,
+transformers/models/ibert/__pycache__/modeling_ibert.cpython-310.pyc,,
+transformers/models/ibert/__pycache__/quant_modules.cpython-310.pyc,,
+transformers/models/ibert/configuration_ibert.py,sha256=nLRgpOzXz8rNprkGfnz5LVuPKWbYnQfkAubJp9sJYyE,7120
+transformers/models/ibert/modeling_ibert.py,sha256=Z8as-nMx-iaAnfgynZ3JmdVs2kHo02hqHi2OAeouIpw,51526
+transformers/models/ibert/quant_modules.py,sha256=IRq4JOfDn8BBDan2zDy8Fa70bMJ8Wa2gorNDeNVB6uc,30076
+transformers/models/idefics/__init__.py,sha256=zc4m1Vd6-Szs7Urt0Ry6eUScpza8iD-QPG4cq4xX34g,1116
+transformers/models/idefics/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/configuration_idefics.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/image_processing_idefics.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/modeling_idefics.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/modeling_tf_idefics.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/perceiver.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/perceiver_tf.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/processing_idefics.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/vision.cpython-310.pyc,,
+transformers/models/idefics/__pycache__/vision_tf.cpython-310.pyc,,
+transformers/models/idefics/configuration_idefics.py,sha256=4j7sAul74adsu3fXPiq34FePCqJJaafCg2dmHU9h_GU,15304
+transformers/models/idefics/image_processing_idefics.py,sha256=HdPcvLLujawkHb8aQYw_wQe4HiRPYx69DAJjcB2-hvU,9265
+transformers/models/idefics/modeling_idefics.py,sha256=mg2cfaLpkfsXgGzQJtx4vIlUJv6cigyP3B9jx-Hn5ec,69890
+transformers/models/idefics/modeling_tf_idefics.py,sha256=zEU3dTNxi-2GEeBmDznquODfD__z89bfbB1DfxCByUc,79225
+transformers/models/idefics/perceiver.py,sha256=MkJ34X4dgVNJddcn8wUWyDf0rTioVl4WG3dP5GLXR0Q,9426
+transformers/models/idefics/perceiver_tf.py,sha256=XGRP3FaYcbHbxQa9_NoaLkipFfy9tiymgfx2w1GBT6E,9999
+transformers/models/idefics/processing_idefics.py,sha256=ZRwwESw8uACk9drE8GdnGvU6pF_50l_J0oYIDjfSn0U,22964
+transformers/models/idefics/vision.py,sha256=ArKhUWBWkCP1fVn8HVcxXaIVZ_rHNuDsOmABUlxK6W0,21794
+transformers/models/idefics/vision_tf.py,sha256=_NmxcrJPfFVHC5mSl4oPI2IMa44ZrKjvojilfqyPeLw,26013
+transformers/models/idefics2/__init__.py,sha256=YmU2OQi-BTXESv52a4jtTwWC2ingparNU4-rXVCPWzQ,1131
+transformers/models/idefics2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/idefics2/__pycache__/configuration_idefics2.cpython-310.pyc,,
+transformers/models/idefics2/__pycache__/image_processing_idefics2.cpython-310.pyc,,
+transformers/models/idefics2/__pycache__/image_processing_idefics2_fast.cpython-310.pyc,,
+transformers/models/idefics2/__pycache__/modeling_idefics2.cpython-310.pyc,,
+transformers/models/idefics2/__pycache__/processing_idefics2.cpython-310.pyc,,
+transformers/models/idefics2/configuration_idefics2.py,sha256=TUpFg-9WZ_ISWYfKXlVXT3Z5oTh0gxQ4BY-4fbHcRf0,12223
+transformers/models/idefics2/image_processing_idefics2.py,sha256=4XvudzlFAqjYioBhS40hi-dktWaHHHdfJqWuTMQz1UI,26528
+transformers/models/idefics2/image_processing_idefics2_fast.py,sha256=vVxdMrUrChWQFaRCKZJ5dkWJkSMCIKbV_JbFcy-eMj0,12169
+transformers/models/idefics2/modeling_idefics2.py,sha256=8ZWgpfv0adI5TvH2eY1jNZlC7QtqB0GLjleHhyoV32M,59196
+transformers/models/idefics2/processing_idefics2.py,sha256=AF90gJX47d0atDuL69FIuAljUjlFQGdirE4imZ9nkyg,12013
+transformers/models/idefics3/__init__.py,sha256=zLsOtUFi074lvfGbwZEMVSvV08TZgoq0DVhJJagYoRo,1131
+transformers/models/idefics3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/idefics3/__pycache__/configuration_idefics3.cpython-310.pyc,,
+transformers/models/idefics3/__pycache__/image_processing_idefics3.cpython-310.pyc,,
+transformers/models/idefics3/__pycache__/image_processing_idefics3_fast.cpython-310.pyc,,
+transformers/models/idefics3/__pycache__/modeling_idefics3.cpython-310.pyc,,
+transformers/models/idefics3/__pycache__/processing_idefics3.cpython-310.pyc,,
+transformers/models/idefics3/configuration_idefics3.py,sha256=fQYZ0Eo-q7InVjNFat2RjL9RZQmR-9nAIlK9v_XNkZE,8566
+transformers/models/idefics3/image_processing_idefics3.py,sha256=eAra8KyuiiCMQJV9ka3kr_b9TSIZnIsXGVn9hEEfeis,43610
+transformers/models/idefics3/image_processing_idefics3_fast.py,sha256=aghb3FZx5pZbn-bFF6YYR8wIwJn-R132CrOmKMv-ccU,23711
+transformers/models/idefics3/modeling_idefics3.py,sha256=a87nce7VZHpTfadjSbOh_CggnPxolrd-JG_U17WL_8w,48270
+transformers/models/idefics3/processing_idefics3.py,sha256=o0Bak9fRj-gXZcfRFZwfvQqZ2DPqm_F3C48wrE7XxDk,19084
+transformers/models/ijepa/__init__.py,sha256=O0_Jqpy8kmorYC-x0QsoMYSHdqQt3E1j-UZGLQ9aCv0,991
+transformers/models/ijepa/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/ijepa/__pycache__/configuration_ijepa.cpython-310.pyc,,
+transformers/models/ijepa/__pycache__/modeling_ijepa.cpython-310.pyc,,
+transformers/models/ijepa/__pycache__/modular_ijepa.cpython-310.pyc,,
+transformers/models/ijepa/configuration_ijepa.py,sha256=8lO360USWRUnrnBXO2SeiZN0ozKHJNb2K2D0_vCKeX8,5445
+transformers/models/ijepa/modeling_ijepa.py,sha256=iwUvjrxMjogSZ8qcNz0tD_BHGTG9tzgeuiICsHoJLXE,23497
+transformers/models/ijepa/modular_ijepa.py,sha256=YA9MMAQN4WEMJBuwI8vN46HS8cz9PjyMRRryx_iT7WI,7621
+transformers/models/imagegpt/__init__.py,sha256=XxwI4UaVyyvTcGuJQGruvLi-dHHl8MdOvhAum3FXaGo,1089
+transformers/models/imagegpt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/imagegpt/__pycache__/configuration_imagegpt.cpython-310.pyc,,
+transformers/models/imagegpt/__pycache__/feature_extraction_imagegpt.cpython-310.pyc,,
+transformers/models/imagegpt/__pycache__/image_processing_imagegpt.cpython-310.pyc,,
+transformers/models/imagegpt/__pycache__/modeling_imagegpt.cpython-310.pyc,,
+transformers/models/imagegpt/configuration_imagegpt.py,sha256=bp6I42shNZUoPmwpTOWEiyUH3-UQkDzK7AkSLgsMZCo,8799
+transformers/models/imagegpt/feature_extraction_imagegpt.py,sha256=sU7HaHR9bGhzHYLuRDnvcHRCnxlJHkfTVItQYn7ZS5E,1316
+transformers/models/imagegpt/image_processing_imagegpt.py,sha256=Y_wk7hz3Ew6MmdRCesrPu64cW2VYIX3Dyhb8CGbociQ,14448
+transformers/models/imagegpt/modeling_imagegpt.py,sha256=K1K-RVzHYep7j0gCmrKGs2tgBYyuPXIoo3V_icM5HXU,46999
+transformers/models/informer/__init__.py,sha256=L-BwVQfdq5ve06VJJ-OnTh-m_YqSMNcpDQ1z6sbDtNI,997
+transformers/models/informer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/informer/__pycache__/configuration_informer.cpython-310.pyc,,
+transformers/models/informer/__pycache__/modeling_informer.cpython-310.pyc,,
+transformers/models/informer/__pycache__/modular_informer.cpython-310.pyc,,
+transformers/models/informer/configuration_informer.py,sha256=w_Si5k5ZakGLXANemPDBY7RX_j3rfcLQr_NawdVURcA,12488
+transformers/models/informer/modeling_informer.py,sha256=AWKw_cOTbzlNP6mu0y_BaxoMoy301TAo-lvB1dzxKXk,107193
+transformers/models/informer/modular_informer.py,sha256=j13OkfgtG454pLAMzeV6zRkGKlCl2rkckysDWNdGz0c,48569
+transformers/models/instructblip/__init__.py,sha256=gI7F0N1dRSYdZtTumtuoPcIJcuBI8PO4DEOQS4_nWuc,1048
+transformers/models/instructblip/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/instructblip/__pycache__/configuration_instructblip.cpython-310.pyc,,
+transformers/models/instructblip/__pycache__/modeling_instructblip.cpython-310.pyc,,
+transformers/models/instructblip/__pycache__/processing_instructblip.cpython-310.pyc,,
+transformers/models/instructblip/configuration_instructblip.py,sha256=_EYzBIHXuM6DThV5EfpJVuglsL7OCu-axvN0u_Yfk2M,15823
+transformers/models/instructblip/modeling_instructblip.py,sha256=kwF0eov1TxprHb0uTMTcjrRk9HCIteSIZNT4OaK4HHg,78123
+transformers/models/instructblip/processing_instructblip.py,sha256=jjmTkdlE7PEKzDE1IiCdwkSHHAMMMusqwJzqqT2iUIA,8826
+transformers/models/instructblipvideo/__init__.py,sha256=sgK7MEwrqKB6mQyEvhxcgOQc_OAtMDc9tAZqKF0sxfM,1171
+transformers/models/instructblipvideo/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/instructblipvideo/__pycache__/configuration_instructblipvideo.cpython-310.pyc,,
+transformers/models/instructblipvideo/__pycache__/image_processing_instructblipvideo.cpython-310.pyc,,
+transformers/models/instructblipvideo/__pycache__/modeling_instructblipvideo.cpython-310.pyc,,
+transformers/models/instructblipvideo/__pycache__/modular_instructblipvideo.cpython-310.pyc,,
+transformers/models/instructblipvideo/__pycache__/processing_instructblipvideo.cpython-310.pyc,,
+transformers/models/instructblipvideo/__pycache__/video_processing_instructblipvideo.cpython-310.pyc,,
+transformers/models/instructblipvideo/configuration_instructblipvideo.py,sha256=RWJu0fOE-UcvZRLYLCZB0MHmXOUReRv3YhN9lsliQ68,16931
+transformers/models/instructblipvideo/image_processing_instructblipvideo.py,sha256=Y-UrJ6sREhk2eEznUyfMLc5Ehhnng1VT0LC8K9IqO-k,17032
+transformers/models/instructblipvideo/modeling_instructblipvideo.py,sha256=IS59zryK_-Nts1J2l-5zteXvUyKpxbugX9NumDLBBHI,79173
+transformers/models/instructblipvideo/modular_instructblipvideo.py,sha256=ctyzMjv6TkON1kv9nvninvuFXA1hN5bpxawMWfIbKQw,27320
+transformers/models/instructblipvideo/processing_instructblipvideo.py,sha256=eQqMjH4CXEXYvtT8UrtpHq4za-kQCfa_ibR-e8jD1RQ,9761
+transformers/models/instructblipvideo/video_processing_instructblipvideo.py,sha256=K2Ls-xIDsuF9PiuttOrRk8jz8USgTF2M7M6AY1fM6fQ,4646
+transformers/models/internvl/__init__.py,sha256=tNXeZ8TIWlY70CelRiihyPOudKQtRBZp-c9WqglJ8ss,1081
+transformers/models/internvl/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/internvl/__pycache__/configuration_internvl.cpython-310.pyc,,
+transformers/models/internvl/__pycache__/modeling_internvl.cpython-310.pyc,,
+transformers/models/internvl/__pycache__/modular_internvl.cpython-310.pyc,,
+transformers/models/internvl/__pycache__/processing_internvl.cpython-310.pyc,,
+transformers/models/internvl/__pycache__/video_processing_internvl.cpython-310.pyc,,
+transformers/models/internvl/configuration_internvl.py,sha256=pHPwAbDBs-a2mCoadTGA-86y8w9io-9rn-mhFSMFe20,10622
+transformers/models/internvl/modeling_internvl.py,sha256=syR6AyJzPYfU62EYtyWJwpfRyH-KqPhdzyHUC2gRTSM,42164
+transformers/models/internvl/modular_internvl.py,sha256=oFI-1Z_L172R1Q-DRs2QwSDhs4_XBRlKoibNTslUNMA,28050
+transformers/models/internvl/processing_internvl.py,sha256=-_dzBezdxF-dmb0_QgRbNg6_OcFaJDrZBq3WjWx4wRM,15734
+transformers/models/internvl/video_processing_internvl.py,sha256=271dVQtym4vwHllEELeoXWcje4e3zzrmy7IrJ1CMyhA,7176
+transformers/models/jamba/__init__.py,sha256=zN7Rmr--d5GCEJzMA7gxIz-BYFydPN3cyuif85YU0Fk,991
+transformers/models/jamba/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/jamba/__pycache__/configuration_jamba.cpython-310.pyc,,
+transformers/models/jamba/__pycache__/modeling_jamba.cpython-310.pyc,,
+transformers/models/jamba/configuration_jamba.py,sha256=_tAnWFB7DxGv4MF3dq2rSmzJ3Ys-8jamkEtN67mTPWQ,11745
+transformers/models/jamba/modeling_jamba.py,sha256=TW-J4Ipr9vooNuGOOYgiU_3w0eGArSFBMYRBMRs-tfA,68691
+transformers/models/janus/__init__.py,sha256=rTnJnHMmmoPxIVasip4sdS5aZ1wvetOtZUobIMYMHX4,1132
+transformers/models/janus/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/janus/__pycache__/configuration_janus.cpython-310.pyc,,
+transformers/models/janus/__pycache__/image_processing_janus.cpython-310.pyc,,
+transformers/models/janus/__pycache__/image_processing_janus_fast.cpython-310.pyc,,
+transformers/models/janus/__pycache__/modeling_janus.cpython-310.pyc,,
+transformers/models/janus/__pycache__/modular_janus.cpython-310.pyc,,
+transformers/models/janus/__pycache__/processing_janus.cpython-310.pyc,,
+transformers/models/janus/configuration_janus.py,sha256=7fL58_kFc-hWwhpq-6N_BJG82194A3uHz9QEmRK0A14,14908
+transformers/models/janus/image_processing_janus.py,sha256=7H8eDNKZGysCNF0dlcwANSx2ccqbBlKjmE6XQbpGxUE,25706
+transformers/models/janus/image_processing_janus_fast.py,sha256=NuNTOxI-J8F3qLfn62e14PnqCWxfDtINNHSQSSlPLAM,9319
+transformers/models/janus/modeling_janus.py,sha256=QcQcnR4kHkDUJD4rstVLcerUy188ij0wWjWL49Cdoh0,61310
+transformers/models/janus/modular_janus.py,sha256=KYVqa1LXjE7hP5UsErQ1_z4f3yBK7tWoAsFGQGP_Scs,69336
+transformers/models/janus/processing_janus.py,sha256=ucwWH86NIVRTx_X8jG8JnAVu-ylUQ9pv7AfuoMA4EL8,7518
+transformers/models/jetmoe/__init__.py,sha256=zhqtP2ZDCCl3Fp3VBnnuaA044Ztbh7fsUKogAKABOt0,993
+transformers/models/jetmoe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/jetmoe/__pycache__/configuration_jetmoe.cpython-310.pyc,,
+transformers/models/jetmoe/__pycache__/modeling_jetmoe.cpython-310.pyc,,
+transformers/models/jetmoe/configuration_jetmoe.py,sha256=65oV7AlRZZEsz_4BlbWEf4DvdyqywSjew9KjE3Uzj_U,6851
+transformers/models/jetmoe/modeling_jetmoe.py,sha256=W4xalL6L6AYrXhbqHByloZv2ih1xGdBwDGgjtWbsykA,54070
+transformers/models/kosmos2/__init__.py,sha256=Ow8cLelhxl6fm5XvXzNQtPLt1xjIdVmGUwz5NoVVVto,1033
+transformers/models/kosmos2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/kosmos2/__pycache__/configuration_kosmos2.cpython-310.pyc,,
+transformers/models/kosmos2/__pycache__/modeling_kosmos2.cpython-310.pyc,,
+transformers/models/kosmos2/__pycache__/processing_kosmos2.cpython-310.pyc,,
+transformers/models/kosmos2/configuration_kosmos2.py,sha256=J8MCJ8SzDJ03_8DiSMNiYyU46i0tl6LEc2K_u1dnUY8,11888
+transformers/models/kosmos2/modeling_kosmos2.py,sha256=9RtEpUUeK4__9KMky2w0yoD3nN_u2H2g8TJ-Qzcgu_g,83493
+transformers/models/kosmos2/processing_kosmos2.py,sha256=XkaY91wnZiw0NXWR-2bqWZcAGRY0LbCV38pzs09h3sA,30894
+transformers/models/kosmos2_5/__init__.py,sha256=rn3igfupnqkSt_O0QLvLmrTy_fX_N7EIFPdHtr2ud7o,1179
+transformers/models/kosmos2_5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/kosmos2_5/__pycache__/configuration_kosmos2_5.cpython-310.pyc,,
+transformers/models/kosmos2_5/__pycache__/image_processing_kosmos2_5.cpython-310.pyc,,
+transformers/models/kosmos2_5/__pycache__/image_processing_kosmos2_5_fast.cpython-310.pyc,,
+transformers/models/kosmos2_5/__pycache__/modeling_kosmos2_5.cpython-310.pyc,,
+transformers/models/kosmos2_5/__pycache__/processing_kosmos2_5.cpython-310.pyc,,
+transformers/models/kosmos2_5/configuration_kosmos2_5.py,sha256=KwVBazDcAinxR9TQ2Z6wejbw_E9L2F5Scfk-cFaCm9Y,11654
+transformers/models/kosmos2_5/image_processing_kosmos2_5.py,sha256=b1t5hpT_fFaTPoGy-eB1gSIxZD8fi8JYvzt2wmG1jZg,14999
+transformers/models/kosmos2_5/image_processing_kosmos2_5_fast.py,sha256=hfPq3o5HDWdQfZmNYRNOjKaQAO5wiDOwxpyw-mQzycU,12363
+transformers/models/kosmos2_5/modeling_kosmos2_5.py,sha256=vf2fIN9Q-wTPmB5FsAcuV7SnsybkQCKyptFY2hH6Wlk,83404
+transformers/models/kosmos2_5/processing_kosmos2_5.py,sha256=whJUEWWZP434Jm7CEySd0KqO76imn58UuGaz5Mzk3m8,6431
+transformers/models/kyutai_speech_to_text/__init__.py,sha256=KxatXD7pSOmwZWzs7nFOXG9Hc2wxaAS3CYwxg54lq9g,1135
+transformers/models/kyutai_speech_to_text/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/kyutai_speech_to_text/__pycache__/configuration_kyutai_speech_to_text.cpython-310.pyc,,
+transformers/models/kyutai_speech_to_text/__pycache__/feature_extraction_kyutai_speech_to_text.cpython-310.pyc,,
+transformers/models/kyutai_speech_to_text/__pycache__/modeling_kyutai_speech_to_text.cpython-310.pyc,,
+transformers/models/kyutai_speech_to_text/__pycache__/modular_kyutai_speech_to_text.cpython-310.pyc,,
+transformers/models/kyutai_speech_to_text/__pycache__/processing_kyutai_speech_to_text.cpython-310.pyc,,
+transformers/models/kyutai_speech_to_text/configuration_kyutai_speech_to_text.py,sha256=eeBUzFfZnDlhcCuhQzaFchNFT_Wq-2-mBxXPJ_lelnI,9030
+transformers/models/kyutai_speech_to_text/feature_extraction_kyutai_speech_to_text.py,sha256=d70GfDJOpBy6_mbq6XkN0DXXm7-hv19WbxGA7AJBu5A,11809
+transformers/models/kyutai_speech_to_text/modeling_kyutai_speech_to_text.py,sha256=2muwiGxu46qMEQ62JcbFPBw90JCOVoudugofJdR6i5M,64797
+transformers/models/kyutai_speech_to_text/modular_kyutai_speech_to_text.py,sha256=THtsaE9aQdvLBhFSwVumvHMT79TGX52-zTyGxXhOuj4,23366
+transformers/models/kyutai_speech_to_text/processing_kyutai_speech_to_text.py,sha256=mUj4raQgrAlCfALfRF9aWFgZV5sbPzHcbqXAEY7yyyI,3512
+transformers/models/layoutlm/__init__.py,sha256=Mv-k01_9_SxbADuSx2pWoNGBxgUe4IH15Kcg-vc_0OI,1124
+transformers/models/layoutlm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/layoutlm/__pycache__/configuration_layoutlm.cpython-310.pyc,,
+transformers/models/layoutlm/__pycache__/modeling_layoutlm.cpython-310.pyc,,
+transformers/models/layoutlm/__pycache__/modeling_tf_layoutlm.cpython-310.pyc,,
+transformers/models/layoutlm/__pycache__/tokenization_layoutlm.cpython-310.pyc,,
+transformers/models/layoutlm/__pycache__/tokenization_layoutlm_fast.cpython-310.pyc,,
+transformers/models/layoutlm/configuration_layoutlm.py,sha256=dXx_U1hCr7OEKkX1KmnvX28_YFG-3YfhyoohtIKJvuA,9585
+transformers/models/layoutlm/modeling_layoutlm.py,sha256=ME6tc8MDHxIkgLONgWRTOYYkpHTiPbKea9BuZcJaQuM,47621
+transformers/models/layoutlm/modeling_tf_layoutlm.py,sha256=nbnFaMwHF6o4H37KjumFss3PkBG1JvR9bqSaCUgeQO0,73207
+transformers/models/layoutlm/tokenization_layoutlm.py,sha256=xmr9ECm3iKIekmGUFJCh6doTOuto43pZoGRJtOaAsnc,20141
+transformers/models/layoutlm/tokenization_layoutlm_fast.py,sha256=LQl2LTmosc0mhrdir332AMepzHmuwxCDrM8RxYxUrJM,6691
+transformers/models/layoutlmv2/__init__.py,sha256=8f9dWBf1riaQI2KAw-gIrQGNKP4f2uUdJxyRKNVD2lI,1281
+transformers/models/layoutlmv2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/configuration_layoutlmv2.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/feature_extraction_layoutlmv2.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/image_processing_layoutlmv2.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/image_processing_layoutlmv2_fast.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/modeling_layoutlmv2.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/processing_layoutlmv2.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/tokenization_layoutlmv2.cpython-310.pyc,,
+transformers/models/layoutlmv2/__pycache__/tokenization_layoutlmv2_fast.cpython-310.pyc,,
+transformers/models/layoutlmv2/configuration_layoutlmv2.py,sha256=LmhbEBUesm93DINDXZRfWIKrB0Agy3cflhMh7UCMtqY,10914
+transformers/models/layoutlmv2/feature_extraction_layoutlmv2.py,sha256=C-PxmCgb7CMj-nrs7-yOEvGwLcW1okgKjK2OvIsKjHE,1313
+transformers/models/layoutlmv2/image_processing_layoutlmv2.py,sha256=LGi3r1DbOk-Qi7O8Xw-etrkNM6zt_Zp2ucYomH1FaxA,13605
+transformers/models/layoutlmv2/image_processing_layoutlmv2_fast.py,sha256=VBZrKwU79g-NQEfy9RyiVTQxcgRtYbGLg0vqeBnhBVc,5841
+transformers/models/layoutlmv2/modeling_layoutlmv2.py,sha256=x3DUWXBaYRXDaOlKoLfHlEbOj8plIyZ6Ut0ljfROTms,61956
+transformers/models/layoutlmv2/processing_layoutlmv2.py,sha256=mV8gtq2pkHTgnzBzZq4YdX0XWx9bTWvjAS2iQRt03Ps,8718
+transformers/models/layoutlmv2/tokenization_layoutlmv2.py,sha256=NPwb7mXxwLzRHqfDHqcKww8QEXePE8W-25cyJXYpeSg,72137
+transformers/models/layoutlmv2/tokenization_layoutlmv2_fast.py,sha256=kszD7kD1-Zi6tos9t3gSTja-wWCi0k8e3D5uhZjR3ws,37064
+transformers/models/layoutlmv3/__init__.py,sha256=N-Ty2DqEyDqyd5i-k89LMi2qSbojaasZ-ozSTxs1GHo,1323
+transformers/models/layoutlmv3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/configuration_layoutlmv3.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/feature_extraction_layoutlmv3.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/image_processing_layoutlmv3.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/image_processing_layoutlmv3_fast.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/modeling_layoutlmv3.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/modeling_tf_layoutlmv3.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/processing_layoutlmv3.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/tokenization_layoutlmv3.cpython-310.pyc,,
+transformers/models/layoutlmv3/__pycache__/tokenization_layoutlmv3_fast.cpython-310.pyc,,
+transformers/models/layoutlmv3/configuration_layoutlmv3.py,sha256=-FaapM8qkEUrlkfsFAG27v5hPJh-SmkQkXSYb5OiBjU,13288
+transformers/models/layoutlmv3/feature_extraction_layoutlmv3.py,sha256=G2oB86aN-ebGJjw6YMsuEVuSfnIAylsteMWpZR3Gcvs,1313
+transformers/models/layoutlmv3/image_processing_layoutlmv3.py,sha256=myp6OC50cdh60lwE2BX2fj2iPMsjo4SFaAtHtTngG7Y,18571
+transformers/models/layoutlmv3/image_processing_layoutlmv3_fast.py,sha256=HaT1eiU3fvt0m4pdZXaidIPMTNTpcRnLaxKLRdRspRc,6428
+transformers/models/layoutlmv3/modeling_layoutlmv3.py,sha256=As83lqRUQ_wwK8bBy-RTMcjeCVffss-CzZoyyFT6Fo8,53596
+transformers/models/layoutlmv3/modeling_tf_layoutlmv3.py,sha256=QMYgY31NUVETlCDaX9WIwSnPZwb5ZfHl8N0JfwVIEJc,76633
+transformers/models/layoutlmv3/processing_layoutlmv3.py,sha256=gkgapzU2yDoVQU2JM1MAEnpTWr0mBtVPL0qMDn2YpAM,8569
+transformers/models/layoutlmv3/tokenization_layoutlmv3.py,sha256=vazUk6NCQAVRanYrmHJ4LduEwW_RNuLkepmUi25j8QY,73237
+transformers/models/layoutlmv3/tokenization_layoutlmv3_fast.py,sha256=l7JmjZ3uMA3fRimszuxqpQF5_0AFB-wjXwTwSwj7Rcg,39917
+transformers/models/layoutxlm/__init__.py,sha256=djfI2YGJISwww_XDfyf4kCj3a_HiC6Hld1rlaHRtHPg,1047
+transformers/models/layoutxlm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/layoutxlm/__pycache__/processing_layoutxlm.cpython-310.pyc,,
+transformers/models/layoutxlm/__pycache__/tokenization_layoutxlm.cpython-310.pyc,,
+transformers/models/layoutxlm/__pycache__/tokenization_layoutxlm_fast.cpython-310.pyc,,
+transformers/models/layoutxlm/processing_layoutxlm.py,sha256=25iBxlhDKagNfW8ZEBXflkrl0t0jGRrITBRphwW-_mg,8649
+transformers/models/layoutxlm/tokenization_layoutxlm.py,sha256=BLbZIliyQIRcXAtExyWN0sIV2ZRf1FqFdsnlKsB-iIo,58329
+transformers/models/layoutxlm/tokenization_layoutxlm_fast.py,sha256=1J_rW1fGdTsQsJRbLfVhbWngXnKecX-xELBtYmu98QA,40471
+transformers/models/led/__init__.py,sha256=KaOht9jIet9WQrPRli8DwD7q5fzTWsffxf7LK-sQuw4,1099
+transformers/models/led/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/led/__pycache__/configuration_led.cpython-310.pyc,,
+transformers/models/led/__pycache__/modeling_led.cpython-310.pyc,,
+transformers/models/led/__pycache__/modeling_tf_led.cpython-310.pyc,,
+transformers/models/led/__pycache__/tokenization_led.cpython-310.pyc,,
+transformers/models/led/__pycache__/tokenization_led_fast.cpython-310.pyc,,
+transformers/models/led/configuration_led.py,sha256=wuLDY2wIywEU_23WuDfcoGW8-bg_X8SmP843xnYFyZQ,7455
+transformers/models/led/modeling_led.py,sha256=GWmffZC-dfJKd-NNXQKC95BrmSYRlGIckdt2MExo0rk,125508
+transformers/models/led/modeling_tf_led.py,sha256=WPRKVHYflyt5aYEvIum-rqs2lrEj629KCfHFMBSQeKM,123085
+transformers/models/led/tokenization_led.py,sha256=m7FhNIvAQer9k9t_WqYMGSE3k59yn7L5tIuB3JH7uzE,19843
+transformers/models/led/tokenization_led_fast.py,sha256=yO0G0Q6yGmsPCyEII9t-AnYQeEaJ-HQDbLjfAcGI9Cs,14170
+transformers/models/levit/__init__.py,sha256=acEjEeDtpQ9q3a-hf90z6TZ0js04BtZvbCcn4HGWCyk,1124
+transformers/models/levit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/levit/__pycache__/configuration_levit.cpython-310.pyc,,
+transformers/models/levit/__pycache__/feature_extraction_levit.cpython-310.pyc,,
+transformers/models/levit/__pycache__/image_processing_levit.cpython-310.pyc,,
+transformers/models/levit/__pycache__/image_processing_levit_fast.cpython-310.pyc,,
+transformers/models/levit/__pycache__/modeling_levit.cpython-310.pyc,,
+transformers/models/levit/configuration_levit.py,sha256=UOtUDcZK6i4kPrtjYgCoWpZsxf7A1BQZeZjCYoXnMek,5772
+transformers/models/levit/feature_extraction_levit.py,sha256=sR1MZBqvbep8KdqX45Sw3V--ZqCe3fePzC1CT9cv4Js,1317
+transformers/models/levit/image_processing_levit.py,sha256=XHpdCc_BJVuKz8AfDUMObT6cJovSyW06eWri77KprwU,16718
+transformers/models/levit/image_processing_levit_fast.py,sha256=kyf4vXAG0LMRRXpQRZ8swvedueDYr6BrLbI8NRXQrPY,3946
+transformers/models/levit/modeling_levit.py,sha256=YLK0NAfGhQZfUWKDEu7dLAX4lu2qQvo7b4VFzEFOvUM,26365
+transformers/models/lfm2/__init__.py,sha256=9fNMRtqveDp18iRtUjNqCu0XELuvwJOmizUyI1h0zHw,989
+transformers/models/lfm2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/lfm2/__pycache__/configuration_lfm2.cpython-310.pyc,,
+transformers/models/lfm2/__pycache__/modeling_lfm2.cpython-310.pyc,,
+transformers/models/lfm2/__pycache__/modular_lfm2.cpython-310.pyc,,
+transformers/models/lfm2/configuration_lfm2.py,sha256=6jJ2kBds8PYg6DyAHBFdpMIcJW7rBv-bkMrM1LLVgII,7831
+transformers/models/lfm2/modeling_lfm2.py,sha256=qBJgmO0PKj9PLQDASRK5cxT5DRAdGVf1YjeDClimN94,32195
+transformers/models/lfm2/modular_lfm2.py,sha256=XqrhYs6Nl2fjRUqHWlOOZNWjHTwuRia9f4jOFF6_kJE,20988
+transformers/models/lightglue/__init__.py,sha256=xdtDUaVLHRf2vWjlv-l2JWlllw6Obz8ZRZeV297Ds1Y,1045
+transformers/models/lightglue/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/lightglue/__pycache__/configuration_lightglue.cpython-310.pyc,,
+transformers/models/lightglue/__pycache__/image_processing_lightglue.cpython-310.pyc,,
+transformers/models/lightglue/__pycache__/modeling_lightglue.cpython-310.pyc,,
+transformers/models/lightglue/__pycache__/modular_lightglue.cpython-310.pyc,,
+transformers/models/lightglue/configuration_lightglue.py,sha256=jijJsgjlZEZ-MSZARQ1kKUiW_1VU5B-FVlHGtxWX4bc,8135
+transformers/models/lightglue/image_processing_lightglue.py,sha256=sJuqREeqCZ4IJg2p46DPdodfe60oGWVwhaUTyKSBkqk,24854
+transformers/models/lightglue/modeling_lightglue.py,sha256=oICtgzGIGv-HiBLjG1br5-O_dtrdIDVjZI1x-l0X3tk,43339
+transformers/models/lightglue/modular_lightglue.py,sha256=KJGQzs0PwGLiNbILYG8SG8lvkv8g0SxSJPUIUgHIbOA,50977
+transformers/models/lilt/__init__.py,sha256=9XEq7kJwN0mKO469mR0mtlRUdljjq7V80gejpqb59K0,989
+transformers/models/lilt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/lilt/__pycache__/configuration_lilt.cpython-310.pyc,,
+transformers/models/lilt/__pycache__/modeling_lilt.cpython-310.pyc,,
+transformers/models/lilt/configuration_lilt.py,sha256=rPA7P9f9B2f29_Q74Dx93-WXyhK1JT5W67PoSrDOoQc,6737
+transformers/models/lilt/modeling_lilt.py,sha256=LXNnKgQdbsgM3XAH6KXv17y5024NyKW91D13tM6sg7Y,48265
+transformers/models/llama/__init__.py,sha256=k1HnOc4-BwvgSizE8E0IlrkCh_TVgv1XX8G-xozfgLo,1111
+transformers/models/llama/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/llama/__pycache__/configuration_llama.cpython-310.pyc,,
+transformers/models/llama/__pycache__/modeling_flax_llama.cpython-310.pyc,,
+transformers/models/llama/__pycache__/modeling_llama.cpython-310.pyc,,
+transformers/models/llama/__pycache__/tokenization_llama.cpython-310.pyc,,
+transformers/models/llama/__pycache__/tokenization_llama_fast.cpython-310.pyc,,
+transformers/models/llama/configuration_llama.py,sha256=m-ywRVkzFiivG0ty9E1ooHJlvQyV44PRHUxdpe06QI4,12077
+transformers/models/llama/modeling_flax_llama.py,sha256=3_PSmX_OPr7ENnUScfAyuepDwejN-2qFRj5vmy8y-KM,30675
+transformers/models/llama/modeling_llama.py,sha256=Mb9mCmYyWRNDJLxl2k4VWVHcicXKRkcdIyWpk46FniY,20714
+transformers/models/llama/tokenization_llama.py,sha256=KQOtC9Jzm6vs9ugT--SyHjb_XLOUFZ4MwTNZuU6gUm8,18729
+transformers/models/llama/tokenization_llama_fast.py,sha256=nYK5v4GRDhoLkxhtgEoLqq8koigofPTAuRv8-rSvk8U,10965
+transformers/models/llama4/__init__.py,sha256=YLpUGkKivYWky6rr715H2yMb9fCPr_3AV8OwWd2mrpA,1078
+transformers/models/llama4/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/llama4/__pycache__/configuration_llama4.cpython-310.pyc,,
+transformers/models/llama4/__pycache__/image_processing_llama4_fast.cpython-310.pyc,,
+transformers/models/llama4/__pycache__/modeling_llama4.cpython-310.pyc,,
+transformers/models/llama4/__pycache__/processing_llama4.cpython-310.pyc,,
+transformers/models/llama4/configuration_llama4.py,sha256=3YEBDLNEwZx4PaES-yXtoOZfUEPRWx1dUwk5FJapprg,22906
+transformers/models/llama4/image_processing_llama4_fast.py,sha256=pAOHts1dbg6pbr3HCEoirJ1hhIL-4XCglPFZP5LLGf8,18270
+transformers/models/llama4/modeling_llama4.py,sha256=3BxyrL6VCp8nidbTtceUYyqF2IsIvKVU6VgsCqj4JYc,59990
+transformers/models/llama4/processing_llama4.py,sha256=y7ZsQ8JsAYSs_FMzm64a4NpOTLn8L7qnGrRCOzCEhkA,16112
+transformers/models/llava/__init__.py,sha256=h7TDiwhtiqDQbay9v760sbmBGM6yWs3J1tmnIr3PCys,1074
+transformers/models/llava/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/llava/__pycache__/configuration_llava.cpython-310.pyc,,
+transformers/models/llava/__pycache__/image_processing_llava.cpython-310.pyc,,
+transformers/models/llava/__pycache__/image_processing_llava_fast.cpython-310.pyc,,
+transformers/models/llava/__pycache__/modeling_llava.cpython-310.pyc,,
+transformers/models/llava/__pycache__/processing_llava.cpython-310.pyc,,
+transformers/models/llava/configuration_llava.py,sha256=MzKTXjeGMlr-KNFW7L8T4hg0bx-oZ9Yh2bhVtv3QUt4,5760
+transformers/models/llava/image_processing_llava.py,sha256=knead9xd1BycfUt_EPb-CTXJIcc2CsTAXXX0rV0nBes,21245
+transformers/models/llava/image_processing_llava_fast.py,sha256=j1fWNLr0tdm_P5W1B2kQ9TaU00dq3-Qi5HVB_8fmMa8,7262
+transformers/models/llava/modeling_llava.py,sha256=rU69E381xJvaDFmydyzdKEj-yzvmoi8qG2GSYTMZ4IU,22032
+transformers/models/llava/processing_llava.py,sha256=KxW100mpzfVhV_Y3asRGPgIM0O9DkE8joBsEwEZbl_4,10018
+transformers/models/llava_next/__init__.py,sha256=gyT3qcEjuxecgCiFoQoz-tf10ShqzfOL8IzPOhpjfto,1141
+transformers/models/llava_next/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/llava_next/__pycache__/configuration_llava_next.cpython-310.pyc,,
+transformers/models/llava_next/__pycache__/image_processing_llava_next.cpython-310.pyc,,
+transformers/models/llava_next/__pycache__/image_processing_llava_next_fast.cpython-310.pyc,,
+transformers/models/llava_next/__pycache__/modeling_llava_next.cpython-310.pyc,,
+transformers/models/llava_next/__pycache__/processing_llava_next.cpython-310.pyc,,
+transformers/models/llava_next/configuration_llava_next.py,sha256=8LvnjmDgKsNRvsrlqZRkN2NQsuHZXkPmEo-H-8PzkUI,6776
+transformers/models/llava_next/image_processing_llava_next.py,sha256=M4fOkzexaqmTtTZakQn5C1cH39LTpETBQoOqp4PwEcM,35773
+transformers/models/llava_next/image_processing_llava_next_fast.py,sha256=EdEgk36IEoixCAVaPRiO1B_wU5utOgATfxomtBsrtlc,11241
+transformers/models/llava_next/modeling_llava_next.py,sha256=h6t7xTpxINBcgWAZHLP5GlTmOTDXzdcasPAIshqU75A,36053
+transformers/models/llava_next/processing_llava_next.py,sha256=3O6d20vEfUUph7wCkHb2QpkItwE4V-_HK6RKbReu97Q,12774
+transformers/models/llava_next_video/__init__.py,sha256=OGiUL7X9x0bzmsnZi0KA6Sl2ycalLQHkTgOpISYu3q8,1113
+transformers/models/llava_next_video/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/llava_next_video/__pycache__/configuration_llava_next_video.cpython-310.pyc,,
+transformers/models/llava_next_video/__pycache__/image_processing_llava_next_video.cpython-310.pyc,,
+transformers/models/llava_next_video/__pycache__/modeling_llava_next_video.cpython-310.pyc,,
+transformers/models/llava_next_video/__pycache__/modular_llava_next_video.cpython-310.pyc,,
+transformers/models/llava_next_video/__pycache__/processing_llava_next_video.cpython-310.pyc,,
+transformers/models/llava_next_video/__pycache__/video_processing_llava_next_video.cpython-310.pyc,,
+transformers/models/llava_next_video/configuration_llava_next_video.py,sha256=XG-wMKQFmGwGhbQSE8bivrfVS2RPQgSqmW0PEbZRoCU,8266
+transformers/models/llava_next_video/image_processing_llava_next_video.py,sha256=gfpHMel44v5qBVT5v5aOeZY6Bae3mjMHl3fjm1vHUiE,21286
+transformers/models/llava_next_video/modeling_llava_next_video.py,sha256=BlFrOPGnF4hrm-rdfwN6JJBzt9X0FCuz0qKsSjTocGc,46475
+transformers/models/llava_next_video/modular_llava_next_video.py,sha256=oH8d1oxA2zc5LYiPOzjkosMU3rZzx1vKVvgjep15Nmc,34889
+transformers/models/llava_next_video/processing_llava_next_video.py,sha256=4lu4rAPIjTk5dq8ZbOMaO0g4USnnijkDb15FwGSrn34,15542
+transformers/models/llava_next_video/video_processing_llava_next_video.py,sha256=p9YDNQfyNl_fTPVpCtlauIDCde3zugQz8PBcN4zg4fQ,1904
+transformers/models/llava_onevision/__init__.py,sha256=Eeg8yGcfdjCxwjSCg_zoXG48JG6gSYH8_aXBcOxQvnA,1218
+transformers/models/llava_onevision/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/llava_onevision/__pycache__/configuration_llava_onevision.cpython-310.pyc,,
+transformers/models/llava_onevision/__pycache__/image_processing_llava_onevision.cpython-310.pyc,,
+transformers/models/llava_onevision/__pycache__/image_processing_llava_onevision_fast.cpython-310.pyc,,
+transformers/models/llava_onevision/__pycache__/modeling_llava_onevision.cpython-310.pyc,,
+transformers/models/llava_onevision/__pycache__/modular_llava_onevision.cpython-310.pyc,,
+transformers/models/llava_onevision/__pycache__/processing_llava_onevision.cpython-310.pyc,,
+transformers/models/llava_onevision/__pycache__/video_processing_llava_onevision.cpython-310.pyc,,
+transformers/models/llava_onevision/configuration_llava_onevision.py,sha256=eGeC9jBTNHeouYrJ8KP_IUYVLSbjO8ySj0oFNvGIJFA,8061
+transformers/models/llava_onevision/image_processing_llava_onevision.py,sha256=VrWZ6vjxF-t6aQjTBKSZUcyiOYe3uZp42pYvVyXnN6I,38278
+transformers/models/llava_onevision/image_processing_llava_onevision_fast.py,sha256=9Bj_Wzl1NZETLmGjd2pvq1EsKAnaxU29tFAuoGJYEOs,15162
+transformers/models/llava_onevision/modeling_llava_onevision.py,sha256=c-MF5r7rn6qCWZT71s7-kK4Vc8RHnJroFmDPIYud1OQ,45904
+transformers/models/llava_onevision/modular_llava_onevision.py,sha256=xmsi_0Ld3NXt4-AJi2j9O_VMvwAcw-n1DVopywQMed8,35465
+transformers/models/llava_onevision/processing_llava_onevision.py,sha256=Al1_ZlpudcH2JYEOw4_rmCp8yw38pnw53SW3tpJB3pE,16832
+transformers/models/llava_onevision/video_processing_llava_onevision.py,sha256=Ii_ymw2HVSyTupmHhlJTNbcULTBH5KXKS_z9wdgRPB4,1914
+transformers/models/longformer/__init__.py,sha256=vg5ScmyEX2D-xPfnxNNBhdj6-Xj0t3HoPmt709PQjTE,1134
+transformers/models/longformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/longformer/__pycache__/configuration_longformer.cpython-310.pyc,,
+transformers/models/longformer/__pycache__/modeling_longformer.cpython-310.pyc,,
+transformers/models/longformer/__pycache__/modeling_tf_longformer.cpython-310.pyc,,
+transformers/models/longformer/__pycache__/tokenization_longformer.cpython-310.pyc,,
+transformers/models/longformer/__pycache__/tokenization_longformer_fast.cpython-310.pyc,,
+transformers/models/longformer/configuration_longformer.py,sha256=2AwcxPAnCJw5CbCdgTXndYBTlJTWi4QzDnilgG_63T0,8867
+transformers/models/longformer/modeling_longformer.py,sha256=qnjJE4H-N5Jy4zmNxziqBWCxNe4eARTyWZDIjHZmrAA,108088
+transformers/models/longformer/modeling_tf_longformer.py,sha256=u-n2NW5EPB7UBMyIFWd5Jm_stpO7O9nlV74QHNBs-4E,129534
+transformers/models/longformer/tokenization_longformer.py,sha256=cK8ke6cLfMRWXlXw_8FpjTIzLoaBi3iY7Mgf4brMRu8,16818
+transformers/models/longformer/tokenization_longformer_fast.py,sha256=Gg8zvjr0Mwqi4aHupJZLykCilqE7jeXREXbMo59ziqQ,11230
+transformers/models/longt5/__init__.py,sha256=TzoI1JGkvJIf9NlHDQY8_EUuW-upkQZ23wh_8Urtet0,1033
+transformers/models/longt5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/longt5/__pycache__/configuration_longt5.cpython-310.pyc,,
+transformers/models/longt5/__pycache__/modeling_flax_longt5.cpython-310.pyc,,
+transformers/models/longt5/__pycache__/modeling_longt5.cpython-310.pyc,,
+transformers/models/longt5/configuration_longt5.py,sha256=ktQfrCmI60usRiyk-hcZinOpcs7p94zfOV47l_jQnWc,8116
+transformers/models/longt5/modeling_flax_longt5.py,sha256=lNP-l4MlXq4zGNYlo0gyF3oXvcNCk-9qDLQYkBElGE8,105838
+transformers/models/longt5/modeling_longt5.py,sha256=ccfTVUBtQbjDH1KrG7VLC1ZhQZuPG4ehqO3FfWJyb-g,103653
+transformers/models/luke/__init__.py,sha256=YQL403sV6tk5t8sjvi-4hgvx1rvyThx45l7S4T4xpEE,1026
+transformers/models/luke/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/luke/__pycache__/configuration_luke.cpython-310.pyc,,
+transformers/models/luke/__pycache__/modeling_luke.cpython-310.pyc,,
+transformers/models/luke/__pycache__/tokenization_luke.cpython-310.pyc,,
+transformers/models/luke/configuration_luke.py,sha256=q_QLFRDrJfABob9_6-xvSy7ES4VMYKg9A3_gG8DsxAM,6628
+transformers/models/luke/modeling_luke.py,sha256=7ZfaxPaBKmsM0qWTDliSv2pMKhq0D1s9UytTAM7LaTg,98970
+transformers/models/luke/tokenization_luke.py,sha256=SHtnsAm-h1VwdHWjMPXQ0leHSCoqVFVdLA2KEJI2RpE,85643
+transformers/models/lxmert/__init__.py,sha256=iUyLmlBuiz_av7H5ghaQB4RNbpw275N7wwdmiiV0PAc,1114
+transformers/models/lxmert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/lxmert/__pycache__/configuration_lxmert.cpython-310.pyc,,
+transformers/models/lxmert/__pycache__/modeling_lxmert.cpython-310.pyc,,
+transformers/models/lxmert/__pycache__/modeling_tf_lxmert.cpython-310.pyc,,
+transformers/models/lxmert/__pycache__/tokenization_lxmert.cpython-310.pyc,,
+transformers/models/lxmert/__pycache__/tokenization_lxmert_fast.cpython-310.pyc,,
+transformers/models/lxmert/configuration_lxmert.py,sha256=etr-nrYjobgiPW4H9-PTC9VuGgOdR13DRiqifXFkna4,8934
+transformers/models/lxmert/modeling_lxmert.py,sha256=aG5GYE6DL2xFFLOMe_g6t8YSl1ZUSW2kbW8sSArPQns,63580
+transformers/models/lxmert/modeling_tf_lxmert.py,sha256=aGYP4T1uTzZchJkhZZNZXMgACuFe5TFNkHm8jTIX4S4,72722
+transformers/models/lxmert/tokenization_lxmert.py,sha256=He3yKkZAcjAoy0l7rNzc-W3mk_93FAWRB4YX8awnCU4,20165
+transformers/models/lxmert/tokenization_lxmert_fast.py,sha256=5E0lKrkPi1dSrXcZ2BxipbDtMMBVjcwFStrOBVELRv8,6625
+transformers/models/m2m_100/__init__.py,sha256=0uPov299rgQmMwwSyM_m0yGFejP5djgaUY37GkNGnC8,1035
+transformers/models/m2m_100/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/m2m_100/__pycache__/configuration_m2m_100.cpython-310.pyc,,
+transformers/models/m2m_100/__pycache__/modeling_m2m_100.cpython-310.pyc,,
+transformers/models/m2m_100/__pycache__/tokenization_m2m_100.cpython-310.pyc,,
+transformers/models/m2m_100/configuration_m2m_100.py,sha256=iwR_eDM_JlooTz08PGdw8zqeFmXNq3_3ttNe1ivQjj0,13454
+transformers/models/m2m_100/modeling_m2m_100.py,sha256=gsI0XeZtvDq7-uvG_6wIsVlACtFARpJ8-g9z6zbtp5E,67557
+transformers/models/m2m_100/tokenization_m2m_100.py,sha256=ZWAVadNEoJ9YCCDSe7lEzGIvp9tdBC9RfCELTGR1wHg,16416
+transformers/models/mamba/__init__.py,sha256=4oGJySQbwoALRGVWMEwXBm0A6fhKsr4Raly46a5g1G0,991
+transformers/models/mamba/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mamba/__pycache__/configuration_mamba.cpython-310.pyc,,
+transformers/models/mamba/__pycache__/modeling_mamba.cpython-310.pyc,,
+transformers/models/mamba/configuration_mamba.py,sha256=krht7Qj-1yfYxdMr3zB9WhBVqUKiINt2o5BvDC8v-XI,7433
+transformers/models/mamba/modeling_mamba.py,sha256=rSi18aRkpk0eq_lrQjlPQe8yLb5fQnboXU8nNothp5Y,38910
+transformers/models/mamba2/__init__.py,sha256=Ui4j-I2cnPEEszkzRTLSUW42SE4Qg1YTuW6hGeaOFZg,993
+transformers/models/mamba2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mamba2/__pycache__/configuration_mamba2.cpython-310.pyc,,
+transformers/models/mamba2/__pycache__/modeling_mamba2.cpython-310.pyc,,
+transformers/models/mamba2/configuration_mamba2.py,sha256=YWJ7Y_-cEiTLv45b5oChKdzHFh61VWFUMdDZhcjNygU,8214
+transformers/models/mamba2/modeling_mamba2.py,sha256=UvvZ0-n3zuk0ejZXfXYehBJ_J265tARNi4TRunuxqdw,47723
+transformers/models/marian/__init__.py,sha256=Yg8jbvM0Hf6WXua0__v_G-34dvG6zFib5R5e_qHtmYM,1110
+transformers/models/marian/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/marian/__pycache__/configuration_marian.cpython-310.pyc,,
+transformers/models/marian/__pycache__/modeling_flax_marian.cpython-310.pyc,,
+transformers/models/marian/__pycache__/modeling_marian.cpython-310.pyc,,
+transformers/models/marian/__pycache__/modeling_tf_marian.cpython-310.pyc,,
+transformers/models/marian/__pycache__/tokenization_marian.cpython-310.pyc,,
+transformers/models/marian/configuration_marian.py,sha256=2Sv1CzVYYIXvLBnytaLG0T4k-ptoyphVLAJk-zRcsyw,18420
+transformers/models/marian/modeling_flax_marian.py,sha256=qkUUpKC4MPHmESuI0wjGQ95uu0Fs0jIjQMpKU_0-xMM,64429
+transformers/models/marian/modeling_marian.py,sha256=9nqwrajgGkC49faBJRk7R-cCc-1l2toySPFpiPTZlP8,79318
+transformers/models/marian/modeling_tf_marian.py,sha256=5bdZNB0AV82RWOvPMGe86hUelH97WrVQPtqIIxKK4rQ,72668
+transformers/models/marian/tokenization_marian.py,sha256=4Ox1R818g5c4x_pR41JgJfOhAZOaLXTRDgOQPQrOkRU,16868
+transformers/models/markuplm/__init__.py,sha256=PyhrxFsms-oD4SOBO5j3t2mIPLN3PHjKBjTGaUTITMY,1170
+transformers/models/markuplm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/markuplm/__pycache__/configuration_markuplm.cpython-310.pyc,,
+transformers/models/markuplm/__pycache__/feature_extraction_markuplm.cpython-310.pyc,,
+transformers/models/markuplm/__pycache__/modeling_markuplm.cpython-310.pyc,,
+transformers/models/markuplm/__pycache__/processing_markuplm.cpython-310.pyc,,
+transformers/models/markuplm/__pycache__/tokenization_markuplm.cpython-310.pyc,,
+transformers/models/markuplm/__pycache__/tokenization_markuplm_fast.cpython-310.pyc,,
+transformers/models/markuplm/configuration_markuplm.py,sha256=0TPvMhU795p-jmaPyBefVuwBESZGJoHOOIRNk6NgyXc,7747
+transformers/models/markuplm/feature_extraction_markuplm.py,sha256=WquMM3IybHzSpniaKvRUux-liOst9-l3Z1ZmfDNab80,6443
+transformers/models/markuplm/modeling_markuplm.py,sha256=dEbkGzyGJA7OSRNX7k0ElsvWiMcG8CB0nkpT6HNAs6I,43405
+transformers/models/markuplm/processing_markuplm.py,sha256=UtpKUu8Obib8WGnF124p7hzen62ECfbOxgUhtpLzBWI,5629
+transformers/models/markuplm/tokenization_markuplm.py,sha256=dRfXzjXAgSlHgTnXHMQKNUOF9id4l-NbmvQWdsmOlRg,70151
+transformers/models/markuplm/tokenization_markuplm_fast.py,sha256=G_2BWkPgi0FMRqxFlZhL0ecalVeqx2uQVcpthoLBjQE,43320
+transformers/models/mask2former/__init__.py,sha256=ceWZ-4gEaZxvgdhdvM-K18wZxuovtdS8vXkQIFNlfr4,1104
+transformers/models/mask2former/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mask2former/__pycache__/configuration_mask2former.cpython-310.pyc,,
+transformers/models/mask2former/__pycache__/image_processing_mask2former.cpython-310.pyc,,
+transformers/models/mask2former/__pycache__/image_processing_mask2former_fast.cpython-310.pyc,,
+transformers/models/mask2former/__pycache__/modeling_mask2former.cpython-310.pyc,,
+transformers/models/mask2former/__pycache__/modular_mask2former.cpython-310.pyc,,
+transformers/models/mask2former/configuration_mask2former.py,sha256=6fJ8GbDInXB2Cly_QbrYx5xU4hNv-T8TV_9glVUiCtM,12588
+transformers/models/mask2former/image_processing_mask2former.py,sha256=gLJo5jiYScr98EXWlC4LFVFi2V6sLNB1PcgdtNbBpyA,59113
+transformers/models/mask2former/image_processing_mask2former_fast.py,sha256=pjfceFm1VjJVjeTuh_n-ZUklJrRCrc6eswn9K6abwjs,34761
+transformers/models/mask2former/modeling_mask2former.py,sha256=WtSONjAvxv7kWahV8_Z5a53bvdAr_b3gsungaQC8NTM,116981
+transformers/models/mask2former/modular_mask2former.py,sha256=oYG1hqwYXm3mJg957jBDEjxf3d1Y0gTeIf4nRclzwuU,15779
+transformers/models/maskformer/__init__.py,sha256=DWCF0SA7DGofmzu3y-j05x1NLeuKZHADvyyx4XfJwkw,1242
+transformers/models/maskformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/maskformer/__pycache__/configuration_maskformer.cpython-310.pyc,,
+transformers/models/maskformer/__pycache__/configuration_maskformer_swin.cpython-310.pyc,,
+transformers/models/maskformer/__pycache__/feature_extraction_maskformer.cpython-310.pyc,,
+transformers/models/maskformer/__pycache__/image_processing_maskformer.cpython-310.pyc,,
+transformers/models/maskformer/__pycache__/image_processing_maskformer_fast.cpython-310.pyc,,
+transformers/models/maskformer/__pycache__/modeling_maskformer.cpython-310.pyc,,
+transformers/models/maskformer/__pycache__/modeling_maskformer_swin.cpython-310.pyc,,
+transformers/models/maskformer/configuration_maskformer.py,sha256=KBU5bzrkpaNiYZM8f3JX_EfVybtiSls5CeC5iTiXAW0,10673
+transformers/models/maskformer/configuration_maskformer_swin.py,sha256=-72GuV7OyDeU0wCX7OltUAcMPSpKZqwlqJwdsLWlijE,7253
+transformers/models/maskformer/feature_extraction_maskformer.py,sha256=QYnLeWeCeAJDLO9bK1W8hVhZ8QdUslC9nJK-3qNdaUc,1332
+transformers/models/maskformer/image_processing_maskformer.py,sha256=hy0EZozPOehhC9KF7Xl2liAJwP4x8goDQIUhj7nCVaE,59962
+transformers/models/maskformer/image_processing_maskformer_fast.py,sha256=Pa3thY4NwH7oV5kpiSMlrCLf1wvSe37MvA_zCuTaZhk,36102
+transformers/models/maskformer/modeling_maskformer.py,sha256=RnYZSi9Phyd71WinTqYNOCk87aMzQki9eEIR98Udy5A,84619
+transformers/models/maskformer/modeling_maskformer_swin.py,sha256=69IgMj-UTftzpQoo922_IKwNOA0njpllF6RqJH9T_RE,40579
+transformers/models/mbart/__init__.py,sha256=VefKwprf7OVOTgkXowKV2hT8X3mM369sRJXDY5a49ig,1148
+transformers/models/mbart/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mbart/__pycache__/configuration_mbart.cpython-310.pyc,,
+transformers/models/mbart/__pycache__/modeling_flax_mbart.cpython-310.pyc,,
+transformers/models/mbart/__pycache__/modeling_mbart.cpython-310.pyc,,
+transformers/models/mbart/__pycache__/modeling_tf_mbart.cpython-310.pyc,,
+transformers/models/mbart/__pycache__/tokenization_mbart.cpython-310.pyc,,
+transformers/models/mbart/__pycache__/tokenization_mbart_fast.cpython-310.pyc,,
+transformers/models/mbart/configuration_mbart.py,sha256=aWNWjpmHjvRVH6hw6JccAsXbameD2-fXBxuvd7xTmR8,18252
+transformers/models/mbart/modeling_flax_mbart.py,sha256=zKLyi2BuhINSDYU-WfFy48LSzz9hJBBoR3EZmeBBFRI,75373
+transformers/models/mbart/modeling_mbart.py,sha256=0C-DJCP9fvM1Ridq8_sCOuvY3a_uX2k7enJs-XEllmw,89024
+transformers/models/mbart/modeling_tf_mbart.py,sha256=U_LB_z7NNp5ASoQf0HdfEPdPpL_KmeEP-AJ8C60SVHk,74106
+transformers/models/mbart/tokenization_mbart.py,sha256=5Qeg8LmCiYRQA_kgdnsHalP1Nux7VwBYJamfs-E6ERA,14200
+transformers/models/mbart/tokenization_mbart_fast.py,sha256=744tsO1V7FtO_MM_9E0OnGk98UViv9VKHB-g-KK0y-M,10880
+transformers/models/mbart50/__init__.py,sha256=9ukVFi1NqU3OoJcCJ-iKpJUZiu-K0t8yINuJHGltup0,1003
+transformers/models/mbart50/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mbart50/__pycache__/tokenization_mbart50.cpython-310.pyc,,
+transformers/models/mbart50/__pycache__/tokenization_mbart50_fast.cpython-310.pyc,,
+transformers/models/mbart50/tokenization_mbart50.py,sha256=bHfZAjdxNKAsVruUc-gQ6768ga1qPzgLJwugIrarNgU,16403
+transformers/models/mbart50/tokenization_mbart50_fast.py,sha256=cNhawmrk4KjiiA4LVgsh1oUUAWMJzkZgSePFdHMi1Gc,11479
+transformers/models/megatron_bert/__init__.py,sha256=u1UIYjQlrfHcy81i2FzehRDJpt6KNfNJ4AePQYKgwOU,1007
+transformers/models/megatron_bert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/megatron_bert/__pycache__/configuration_megatron_bert.cpython-310.pyc,,
+transformers/models/megatron_bert/__pycache__/modeling_megatron_bert.cpython-310.pyc,,
+transformers/models/megatron_bert/configuration_megatron_bert.py,sha256=Z8A_6hWPyBaC_64AHDlvxGB-08uqpGAyHlX12ty1k2s,6517
+transformers/models/megatron_bert/modeling_megatron_bert.py,sha256=yeyETRXM3rwpoje4IQ8eXU4awqZKEEpIoEB9WAdBuTY,72141
+transformers/models/megatron_gpt2/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
+transformers/models/megatron_gpt2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/megatron_gpt2/__pycache__/checkpoint_reshaping_and_interoperability.cpython-310.pyc,,
+transformers/models/megatron_gpt2/checkpoint_reshaping_and_interoperability.py,sha256=3Oe0z75_0SQSM4OR-hRtH_w24LmhSV9AgsyzwKA2R9Y,37650
+transformers/models/metaclip_2/__init__.py,sha256=S5n45gZa_DwDJ3PtBbKzcjqDd6uOY4sbsSXR227oFZI,1001
+transformers/models/metaclip_2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/metaclip_2/__pycache__/configuration_metaclip_2.cpython-310.pyc,,
+transformers/models/metaclip_2/__pycache__/modeling_metaclip_2.cpython-310.pyc,,
+transformers/models/metaclip_2/__pycache__/modular_metaclip_2.cpython-310.pyc,,
+transformers/models/metaclip_2/configuration_metaclip_2.py,sha256=3uin2WwPXly-waIcvvQ_bsvtoDEl167P1ycfIak5k7E,17717
+transformers/models/metaclip_2/modeling_metaclip_2.py,sha256=-h4EoxpOTgjQ82Bi7heYLifDgVhHyi0_dFf4CSCV1zs,52257
+transformers/models/metaclip_2/modular_metaclip_2.py,sha256=MNy4t7FsD_wBPMjP8I3RCW2iRnJtUuSfoIUAICc4Nio,9006
+transformers/models/mgp_str/__init__.py,sha256=Qb3mXPCrWbQ1ksMRYMeXorrva97OOFNr1zoy4YQg-9k,1073
+transformers/models/mgp_str/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mgp_str/__pycache__/configuration_mgp_str.cpython-310.pyc,,
+transformers/models/mgp_str/__pycache__/modeling_mgp_str.cpython-310.pyc,,
+transformers/models/mgp_str/__pycache__/processing_mgp_str.cpython-310.pyc,,
+transformers/models/mgp_str/__pycache__/tokenization_mgp_str.cpython-310.pyc,,
+transformers/models/mgp_str/configuration_mgp_str.py,sha256=Pvwj6oBIFPp219NkKV3b4kisp77UzkN2JCCy31z2RZQ,5810
+transformers/models/mgp_str/modeling_mgp_str.py,sha256=4nH1YjAgwNfajU3g_BqrMeUMfN0PQ4JcI_OFs0ArC-Y,18932
+transformers/models/mgp_str/processing_mgp_str.py,sha256=MYtqHJoIIi9fPAlLQXeoPsBNOs8qE11HcoaIHo7OacY,9433
+transformers/models/mgp_str/tokenization_mgp_str.py,sha256=VKVCt4TKcIK2yhqPTWgtPdaLz7v1-I2rn6LuoN4OvFw,3793
+transformers/models/mimi/__init__.py,sha256=VXRZ-D8-AyOYcmRGvSxhjwTYQcSNXcCXi5ubks6Qxhk,989
+transformers/models/mimi/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mimi/__pycache__/configuration_mimi.cpython-310.pyc,,
+transformers/models/mimi/__pycache__/modeling_mimi.cpython-310.pyc,,
+transformers/models/mimi/configuration_mimi.py,sha256=7t5b2t3PWpU7F3Vc4Ow6vfe1_8MxwpYsG3RUlyqfKUI,13508
+transformers/models/mimi/modeling_mimi.py,sha256=1pyvtLwCZIU_oO43MZ5Z2HCpnB5fnd3JYZOjooPWu9U,80820
+transformers/models/minimax/__init__.py,sha256=3Ob5TqJX21OU-wQ5NF6aeyRbTRXRmoGzeaFFqtzkf7c,1028
+transformers/models/minimax/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/minimax/__pycache__/configuration_minimax.cpython-310.pyc,,
+transformers/models/minimax/__pycache__/modeling_minimax.cpython-310.pyc,,
+transformers/models/minimax/__pycache__/modular_minimax.cpython-310.pyc,,
+transformers/models/minimax/configuration_minimax.py,sha256=w51CZTNcMLN0t6ANVXIb-P9t3J0uP_SkgxsOQlT8Z9g,11810
+transformers/models/minimax/modeling_minimax.py,sha256=lOVOYz8HMhH1_ca0f6ZBxYTLVmBUIcQlc5yvua-HcAs,42124
+transformers/models/minimax/modular_minimax.py,sha256=Xy8fmKGzT7H-JikUvnjF2py4RAMGRxCfVZXWDlorqNA,27682
+transformers/models/mistral/__init__.py,sha256=PDX9s8k0BrsBlmNShhdijHKAp6zC3QYBUwgl1Dx9EsM,1095
+transformers/models/mistral/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mistral/__pycache__/configuration_mistral.cpython-310.pyc,,
+transformers/models/mistral/__pycache__/modeling_flax_mistral.cpython-310.pyc,,
+transformers/models/mistral/__pycache__/modeling_mistral.cpython-310.pyc,,
+transformers/models/mistral/__pycache__/modeling_tf_mistral.cpython-310.pyc,,
+transformers/models/mistral/__pycache__/modular_mistral.cpython-310.pyc,,
+transformers/models/mistral/configuration_mistral.py,sha256=e423bLQqzKYrnIr6tkVAfcMJVqmReWzlc_jVj4jBH2o,7757
+transformers/models/mistral/modeling_flax_mistral.py,sha256=JVQ590d9nxhPZ2FhmsmOE1316MSrKCmapoDRt8EWZYI,31805
+transformers/models/mistral/modeling_mistral.py,sha256=P7tiAjdqH99XFm0ZndTUP4Eiax4GNOyLYdyxrefeFT4,20743
+transformers/models/mistral/modeling_tf_mistral.py,sha256=_n7kgEEYJkaK7EhpDZQ2v8RdjDZLV7ODikhbjGnJQ-4,44357
+transformers/models/mistral/modular_mistral.py,sha256=GJkCU0nvsbKR5A5fOqjkgerz_TgwxZq31rVGcFBcEdU,7657
+transformers/models/mistral3/__init__.py,sha256=ccR4AQqjFkPl8JVYyVmVvbVm618FlOw4cpwT7N-8ZD4,1036
+transformers/models/mistral3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mistral3/__pycache__/configuration_mistral3.cpython-310.pyc,,
+transformers/models/mistral3/__pycache__/modeling_mistral3.cpython-310.pyc,,
+transformers/models/mistral3/__pycache__/modular_mistral3.cpython-310.pyc,,
+transformers/models/mistral3/configuration_mistral3.py,sha256=__X0uaVt64fl_wrOlXLiMbg7RUMj0Palwyp44-zdAwc,5710
+transformers/models/mistral3/modeling_mistral3.py,sha256=38m9bGgUlqUM219pTmDHggB3SOX6vrNlKdjCdYJkA8Y,23561
+transformers/models/mistral3/modular_mistral3.py,sha256=92Y-e6WxRlT9euLfXXkJFucRlqCesoW7QZe1SuIOKc8,14415
+transformers/models/mixtral/__init__.py,sha256=_i66uHDx5A0-UBwgR2nwibxSf0ZePqpTa_Qsm0Cg_Bs,1015
+transformers/models/mixtral/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mixtral/__pycache__/configuration_mixtral.cpython-310.pyc,,
+transformers/models/mixtral/__pycache__/modeling_mixtral.cpython-310.pyc,,
+transformers/models/mixtral/__pycache__/modular_mixtral.cpython-310.pyc,,
+transformers/models/mixtral/configuration_mixtral.py,sha256=7OMbg8pfaU0WfYnGIIqq5nDzx98x8NPKi-NOb3oSAdk,9073
+transformers/models/mixtral/modeling_mixtral.py,sha256=HxNiszhhlef5gkrRGKwugNw_Bia9Fvqy31G9x6gl3pQ,30294
+transformers/models/mixtral/modular_mixtral.py,sha256=8veN8wdm_Rh9yeRgJdYGJg-MVCIOR2vBUyK1NPV50Gk,18997
+transformers/models/mlcd/__init__.py,sha256=hLiLB1E0jT7sI3s8TraLb_Z1WOpwS69zac5kyHNfx4E,989
+transformers/models/mlcd/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mlcd/__pycache__/configuration_mlcd.cpython-310.pyc,,
+transformers/models/mlcd/__pycache__/modeling_mlcd.cpython-310.pyc,,
+transformers/models/mlcd/__pycache__/modular_mlcd.cpython-310.pyc,,
+transformers/models/mlcd/configuration_mlcd.py,sha256=8WPScG0ONO9SbjrfdhSZtxIGCR5NNOl21sleN6Q4hQI,5805
+transformers/models/mlcd/modeling_mlcd.py,sha256=1HdAYVTP77B7_ucDw2FFupJzE1IktTRSPXYTp1BFumg,27365
+transformers/models/mlcd/modular_mlcd.py,sha256=oasTUnxnhqD37aoliw5Xg5K9w06IJPndIhM1B3zFcZw,23393
+transformers/models/mllama/__init__.py,sha256=2lTGCiL6EZirXNcu4aKV7vSmv50iRsQnCV-c9sahNXg,1073
+transformers/models/mllama/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mllama/__pycache__/configuration_mllama.cpython-310.pyc,,
+transformers/models/mllama/__pycache__/image_processing_mllama.cpython-310.pyc,,
+transformers/models/mllama/__pycache__/modeling_mllama.cpython-310.pyc,,
+transformers/models/mllama/__pycache__/processing_mllama.cpython-310.pyc,,
+transformers/models/mllama/configuration_mllama.py,sha256=xNSwdFPE4V0MAKsiCljoK3UFekwLvRvMdSrNi_L5qZ0,18209
+transformers/models/mllama/image_processing_mllama.py,sha256=JnMDLzSWH34KqYi1SgnSO5XEuV1aSCJmGyT6rFHGs48,38266
+transformers/models/mllama/modeling_mllama.py,sha256=Taq_DjlsoK0Ys5eY9PNEuSmsQPfp4Slh2A5pJDN2qLU,79093
+transformers/models/mllama/processing_mllama.py,sha256=gdkqEUl6teIS38VWjebC6WUbUVYocouyLYjKP_O2N6o,17655
+transformers/models/mluke/__init__.py,sha256=e_3cNftWOmhNXk-zsA1-2DOBT9L56SHr-6qev0xI7Ws,956
+transformers/models/mluke/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mluke/__pycache__/tokenization_mluke.cpython-310.pyc,,
+transformers/models/mluke/tokenization_mluke.py,sha256=PpWmJFXmwp40fIQvDN_m7Xo4LJNtWNAt6x5JH6Wm0us,82153
+transformers/models/mm_grounding_dino/__init__.py,sha256=mk2hUY_rZw6JSjfkqSL4hVYJKxh5ViM3TZfib-09kpc,1015
+transformers/models/mm_grounding_dino/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mm_grounding_dino/__pycache__/configuration_mm_grounding_dino.cpython-310.pyc,,
+transformers/models/mm_grounding_dino/__pycache__/modeling_mm_grounding_dino.cpython-310.pyc,,
+transformers/models/mm_grounding_dino/__pycache__/modular_mm_grounding_dino.cpython-310.pyc,,
+transformers/models/mm_grounding_dino/configuration_mm_grounding_dino.py,sha256=1r6ZcJHNxQdIxGK_PYsvhfXVAmThPIVvIgSEL99T4KE,15282
+transformers/models/mm_grounding_dino/modeling_mm_grounding_dino.py,sha256=QLTDiMroPLN5U5sHAxtt_0ypg-87QtxioAi8VzGEU5I,129423
+transformers/models/mm_grounding_dino/modular_mm_grounding_dino.py,sha256=Njd8tx8Mg6YQwOCXNdNJeSQD3jhq5QsQtsrMLcPC2HI,19389
+transformers/models/mobilebert/__init__.py,sha256=Jy7IZ2oQAjyE_KOoT-I7Z9bqPRVLfsOwx8XY3Y43RFc,1134
+transformers/models/mobilebert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mobilebert/__pycache__/configuration_mobilebert.cpython-310.pyc,,
+transformers/models/mobilebert/__pycache__/modeling_mobilebert.cpython-310.pyc,,
+transformers/models/mobilebert/__pycache__/modeling_tf_mobilebert.cpython-310.pyc,,
+transformers/models/mobilebert/__pycache__/tokenization_mobilebert.cpython-310.pyc,,
+transformers/models/mobilebert/__pycache__/tokenization_mobilebert_fast.cpython-310.pyc,,
+transformers/models/mobilebert/configuration_mobilebert.py,sha256=kSjUZXRAtgvEjp4C2pxC8Po5MS6rM4i4v_xAzvqqHVk,8283
+transformers/models/mobilebert/modeling_mobilebert.py,sha256=icrVzODm-Ep83hkqQzFqygFEKKLpB5yxltVhi1BXc28,63164
+transformers/models/mobilebert/modeling_tf_mobilebert.py,sha256=kTa_oE6_AnYfGoWefuzHT1PXzB7GLMwVmkwocK3kDNw,83932
+transformers/models/mobilebert/tokenization_mobilebert.py,sha256=u3_ex8yv14oHz90QsfBjkELZaDwQDNicgNFgXDgtkvU,20149
+transformers/models/mobilebert/tokenization_mobilebert_fast.py,sha256=_cLnh_Vn7JHMg973Q4kjdkO35VIpNOW9UQt9OIGAvok,6703
+transformers/models/mobilenet_v1/__init__.py,sha256=kS0kf8Q0rDhNcqIJM6iI6iVufztYwEl-TsOzVQZwn-Y,1159
+transformers/models/mobilenet_v1/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mobilenet_v1/__pycache__/configuration_mobilenet_v1.cpython-310.pyc,,
+transformers/models/mobilenet_v1/__pycache__/feature_extraction_mobilenet_v1.cpython-310.pyc,,
+transformers/models/mobilenet_v1/__pycache__/image_processing_mobilenet_v1.cpython-310.pyc,,
+transformers/models/mobilenet_v1/__pycache__/image_processing_mobilenet_v1_fast.cpython-310.pyc,,
+transformers/models/mobilenet_v1/__pycache__/modeling_mobilenet_v1.cpython-310.pyc,,
+transformers/models/mobilenet_v1/configuration_mobilenet_v1.py,sha256=aR3QacEyWEphbgo_mcEvHS7NOVOwxQUhDvoWziA-q54,4939
+transformers/models/mobilenet_v1/feature_extraction_mobilenet_v1.py,sha256=Yydhc-fHuAzWeUOk7qrLrrs-HzMeaLE_IWeploaoOQc,1341
+transformers/models/mobilenet_v1/image_processing_mobilenet_v1.py,sha256=qgVHPsmZfRylHFkY-eTLSV-SgZyiQubTJixR8P0Ysb8,15383
+transformers/models/mobilenet_v1/image_processing_mobilenet_v1_fast.py,sha256=RQI4Ujpx8yV9YFFvXzZEVZxqiZrQ97JSHnP_640V6Bs,1498
+transformers/models/mobilenet_v1/modeling_mobilenet_v1.py,sha256=8k2_ViEsSc0tMeyFwkry-kCV4u4-5aYsqqAc1KsZNSA,16343
+transformers/models/mobilenet_v2/__init__.py,sha256=PGEnF5QRb3bZg_Iux0DuD7VPysu8nA0WxJEd6YOXtmw,1159
+transformers/models/mobilenet_v2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mobilenet_v2/__pycache__/configuration_mobilenet_v2.cpython-310.pyc,,
+transformers/models/mobilenet_v2/__pycache__/feature_extraction_mobilenet_v2.cpython-310.pyc,,
+transformers/models/mobilenet_v2/__pycache__/image_processing_mobilenet_v2.cpython-310.pyc,,
+transformers/models/mobilenet_v2/__pycache__/image_processing_mobilenet_v2_fast.cpython-310.pyc,,
+transformers/models/mobilenet_v2/__pycache__/modeling_mobilenet_v2.cpython-310.pyc,,
+transformers/models/mobilenet_v2/configuration_mobilenet_v2.py,sha256=kEuy8U-ShxevXr2lGluqA4BRAq_3-UsWN4YutMm1yoc,6835
+transformers/models/mobilenet_v2/feature_extraction_mobilenet_v2.py,sha256=aO5lNZnnoRPfhoBEiDiLwuctZkGlFsX1Io-u167A7QU,1341
+transformers/models/mobilenet_v2/image_processing_mobilenet_v2.py,sha256=FQZfha3hB02w2JJRFfAj5XTzB1jQa6Hj_g2cQvKzwVg,24747
+transformers/models/mobilenet_v2/image_processing_mobilenet_v2_fast.py,sha256=8hfed4_SWkjMvIH-fPzMjq57ytC0LjMMA_-aYeghZwA,10092
+transformers/models/mobilenet_v2/modeling_mobilenet_v2.py,sha256=KNRJrJi13pbH8lKXpeSPiGhZK5VwvIU0mUxaXxaKCHQ,32034
+transformers/models/mobilevit/__init__.py,sha256=-pqcwwjQsaYPNEPlRiS9B06Rl9kZf4b8yWGWtW3d4K0,1185
+transformers/models/mobilevit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mobilevit/__pycache__/configuration_mobilevit.cpython-310.pyc,,
+transformers/models/mobilevit/__pycache__/feature_extraction_mobilevit.cpython-310.pyc,,
+transformers/models/mobilevit/__pycache__/image_processing_mobilevit.cpython-310.pyc,,
+transformers/models/mobilevit/__pycache__/image_processing_mobilevit_fast.cpython-310.pyc,,
+transformers/models/mobilevit/__pycache__/modeling_mobilevit.cpython-310.pyc,,
+transformers/models/mobilevit/__pycache__/modeling_tf_mobilevit.cpython-310.pyc,,
+transformers/models/mobilevit/configuration_mobilevit.py,sha256=tyQANkpBRv8MHvXm8nYGlMI_5gQJQekS25pQTQcbfPw,7596
+transformers/models/mobilevit/feature_extraction_mobilevit.py,sha256=rS3UvVaXJwUDc7ZsVoi33DAvQewGdnC4SOgqdxISEwk,1324
+transformers/models/mobilevit/image_processing_mobilevit.py,sha256=DWFDxSuSJ-rhdLwqOfKGRsxrqTRPdzBP_wcNTz9AdBo,23509
+transformers/models/mobilevit/image_processing_mobilevit_fast.py,sha256=pdp9PJm6K0YeOPQcf06sAtqObcfOIHWV1LijCBUU_j4,10249
+transformers/models/mobilevit/modeling_mobilevit.py,sha256=c92G2aQol47HjAXDNrWgLl0oh8rPfljeRS1wgvhxP6c,37819
+transformers/models/mobilevit/modeling_tf_mobilevit.py,sha256=VW-iXvdwlgflYrmmW_tfgb_QKE4ASB1I_5cbrjEvQUM,54753
+transformers/models/mobilevitv2/__init__.py,sha256=pAGk_9X22yOYvlcwbqTc4nm6fL4rPhAhDpdBguna5Q0,1003
+transformers/models/mobilevitv2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mobilevitv2/__pycache__/configuration_mobilevitv2.cpython-310.pyc,,
+transformers/models/mobilevitv2/__pycache__/modeling_mobilevitv2.cpython-310.pyc,,
+transformers/models/mobilevitv2/configuration_mobilevitv2.py,sha256=2mQCHZ8tq2bfrswTfb1fnottcJfY3p_g_vLoWXjkmBE,7159
+transformers/models/mobilevitv2/modeling_mobilevitv2.py,sha256=MXpWQeXenuvWUDQi1zMrvEhWiiB2IgoCHywBtF5xrhs,35568
+transformers/models/modernbert/__init__.py,sha256=BEQFRFfcKvUlphA1ibW3s34Vkbm-MUuyqzaLbrIFiAA,1006
+transformers/models/modernbert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/modernbert/__pycache__/configuration_modernbert.cpython-310.pyc,,
+transformers/models/modernbert/__pycache__/modeling_modernbert.cpython-310.pyc,,
+transformers/models/modernbert/__pycache__/modular_modernbert.cpython-310.pyc,,
+transformers/models/modernbert/configuration_modernbert.py,sha256=HQK0ucX7it6g0ilY3vHTUyRupzHOz50KpLNyNWsP92g,11493
+transformers/models/modernbert/modeling_modernbert.py,sha256=WqWNBZr385EyjgRIpNR9WH_jPRYAtyR1hSrus2EK57o,65979
+transformers/models/modernbert/modular_modernbert.py,sha256=z_oUxkJaLagU1wTsmZ3suhMXO5FbS7xrjnatTcWMb78,71694
+transformers/models/modernbert_decoder/__init__.py,sha256=RjLebVKPcGgNEORY5xypTPd8oYWcnFmbGm3hBqQX-HE,1022
+transformers/models/modernbert_decoder/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/modernbert_decoder/__pycache__/configuration_modernbert_decoder.cpython-310.pyc,,
+transformers/models/modernbert_decoder/__pycache__/modeling_modernbert_decoder.cpython-310.pyc,,
+transformers/models/modernbert_decoder/__pycache__/modular_modernbert_decoder.cpython-310.pyc,,
+transformers/models/modernbert_decoder/configuration_modernbert_decoder.py,sha256=08paqhKhXbw-sTasdy5vNsujOFc5wGVCyxWJmtAqkHk,10629
+transformers/models/modernbert_decoder/modeling_modernbert_decoder.py,sha256=47E1Ei76GfYLbmdh8mYQJV41v2xU_3H3RgHP4XiYmhQ,32356
+transformers/models/modernbert_decoder/modular_modernbert_decoder.py,sha256=pi-DvqalIz1MSuGZvgAaGjbbV8Rvnioz4SbRMq0okss,34854
+transformers/models/moonshine/__init__.py,sha256=eBgvc9LtoDnB6HnNvrObDWL3h_L4Sgn5-D-hepNfAmI,999
+transformers/models/moonshine/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/moonshine/__pycache__/configuration_moonshine.cpython-310.pyc,,
+transformers/models/moonshine/__pycache__/modeling_moonshine.cpython-310.pyc,,
+transformers/models/moonshine/__pycache__/modular_moonshine.cpython-310.pyc,,
+transformers/models/moonshine/configuration_moonshine.py,sha256=FCiqs9BayGl3oUGFh4FIAFz-3eZKlpqQOGusZvhFBZ8,13524
+transformers/models/moonshine/modeling_moonshine.py,sha256=0NtUzUmCyYSowGvfZ9LcKHde-IW8gf_sAn4P4N32OvU,49054
+transformers/models/moonshine/modular_moonshine.py,sha256=XBj2m4oizweDyYADB3eQBFTmFcx9SDI8aJHv_8RDPzg,43684
+transformers/models/moshi/__init__.py,sha256=uW4oqTKZdbmURZaC_xwwHXnYEMyLJrMEJAlfbUzSWO8,991
+transformers/models/moshi/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/moshi/__pycache__/configuration_moshi.cpython-310.pyc,,
+transformers/models/moshi/__pycache__/modeling_moshi.cpython-310.pyc,,
+transformers/models/moshi/configuration_moshi.py,sha256=zVqARdo5wQHERpun-Z1f1mw1_ddLTn0fQsvs2SjE5J8,16104
+transformers/models/moshi/modeling_moshi.py,sha256=IxdI376bR-fn-fmJhQ9kAfvJoiup2iNntq7vXuSvzYc,124980
+transformers/models/mpnet/__init__.py,sha256=agt4uraqHTtlIphsDB17XVAPzCKHaPBKlVaQkKHxRyM,1109
+transformers/models/mpnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mpnet/__pycache__/configuration_mpnet.cpython-310.pyc,,
+transformers/models/mpnet/__pycache__/modeling_mpnet.cpython-310.pyc,,
+transformers/models/mpnet/__pycache__/modeling_tf_mpnet.cpython-310.pyc,,
+transformers/models/mpnet/__pycache__/tokenization_mpnet.cpython-310.pyc,,
+transformers/models/mpnet/__pycache__/tokenization_mpnet_fast.cpython-310.pyc,,
+transformers/models/mpnet/configuration_mpnet.py,sha256=DsCgTVE6hDGcaVxd2yqEPj7Ph-JLE2nPyt1AJlVZkx4,5327
+transformers/models/mpnet/modeling_mpnet.py,sha256=3SI7QLERArtBqN0rRbsTMaskn_GynI-8V7DGSnob9xA,37898
+transformers/models/mpnet/modeling_tf_mpnet.py,sha256=tIjgRjIel676orRDAYK6oQ1YnPsPMY7rlCD0cMBdc_Y,55535
+transformers/models/mpnet/tokenization_mpnet.py,sha256=NNYv8Zwj-6RFWQ7Rynjpe1oIvEZSOBl209DlaBju-Ro,22442
+transformers/models/mpnet/tokenization_mpnet_fast.py,sha256=2j7lcdtgYzsQy52RV-dTbGUwgczxY5qO6siJauxsnuY,9180
+transformers/models/mpt/__init__.py,sha256=DAIIAY0kPL-bXMkPUvxmP97HCXPi-SoM3NLnlJJYarg,987
+transformers/models/mpt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mpt/__pycache__/configuration_mpt.cpython-310.pyc,,
+transformers/models/mpt/__pycache__/modeling_mpt.cpython-310.pyc,,
+transformers/models/mpt/configuration_mpt.py,sha256=S-Ah1uArFpNIGv97PC0mNcW_JBvM5I83TRjM61KjNZ0,10499
+transformers/models/mpt/modeling_mpt.py,sha256=_iJUW2a6A_X2hLTnTSbTzDppJ0qxbrGlT8BcJcguFcU,35630
+transformers/models/mra/__init__.py,sha256=51mnm4DFq6aWxOsmaaVZDL28QozNauXyTtbEihDxUQU,987
+transformers/models/mra/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mra/__pycache__/configuration_mra.cpython-310.pyc,,
+transformers/models/mra/__pycache__/modeling_mra.cpython-310.pyc,,
+transformers/models/mra/configuration_mra.py,sha256=oNhRz6PdvUK_ugoiAhHDuNkGgBNyDguATgQdKeTJBnY,6536
+transformers/models/mra/modeling_mra.py,sha256=PUTNTUScRSfb1bcMzT0gL9v-hMNA7DJEvJNWEoUDpvI,57319
+transformers/models/mt5/__init__.py,sha256=UK8vGX9r6fPdzPaJKCbGJ7RCqKOdIo-7H9V-Qp8rwEg,1095
+transformers/models/mt5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mt5/__pycache__/configuration_mt5.cpython-310.pyc,,
+transformers/models/mt5/__pycache__/modeling_flax_mt5.cpython-310.pyc,,
+transformers/models/mt5/__pycache__/modeling_mt5.cpython-310.pyc,,
+transformers/models/mt5/__pycache__/modeling_tf_mt5.cpython-310.pyc,,
+transformers/models/mt5/__pycache__/tokenization_mt5.cpython-310.pyc,,
+transformers/models/mt5/__pycache__/tokenization_mt5_fast.cpython-310.pyc,,
+transformers/models/mt5/configuration_mt5.py,sha256=oXTmtVxXx5i-S70WEcmaZo_kI1CUKCaxA7aeos5iX7k,8011
+transformers/models/mt5/modeling_flax_mt5.py,sha256=9WjlLB_EV9WDiy-rBxzVUPocsHrv02cEa4OB8lVR6EA,4329
+transformers/models/mt5/modeling_mt5.py,sha256=ejT9O-Jso0tEVeC1HIdsxLXfunXbuNHNyPIUBUyWQts,113640
+transformers/models/mt5/modeling_tf_mt5.py,sha256=EIUkWvuApAbiaX6qhveT1KC43s_NDmQazLrbYT45aao,3406
+transformers/models/mt5/tokenization_mt5.py,sha256=AckaXSw5OojOGLezMhrsv2a9BMZXwzhy5IsT3hvp_Q8,746
+transformers/models/mt5/tokenization_mt5_fast.py,sha256=1npEFH_c4nDQxOFNoqcGNW30KCWe04BpLrrv7aDcDQ8,762
+transformers/models/musicgen/__init__.py,sha256=iwtW9pg6iDe5D2dWVC4IRU8QbNmRK5kMqPCM8fsUSgo,1036
+transformers/models/musicgen/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/musicgen/__pycache__/configuration_musicgen.cpython-310.pyc,,
+transformers/models/musicgen/__pycache__/modeling_musicgen.cpython-310.pyc,,
+transformers/models/musicgen/__pycache__/processing_musicgen.cpython-310.pyc,,
+transformers/models/musicgen/configuration_musicgen.py,sha256=YpsrhRaEqRAOYYlkx5uyelz5iq2dwvU8_mkknRIN9AM,10959
+transformers/models/musicgen/modeling_musicgen.py,sha256=vUyIx6lSpqOGPzxRoPy22qt09qJiYh9stuDU0HT_cbE,118263
+transformers/models/musicgen/processing_musicgen.py,sha256=x4guuKe1ZhQVRimRBMyAgx8JR_fG8LL5F9VcF7bBq9M,5405
+transformers/models/musicgen_melody/__init__.py,sha256=WVEsVs7g0XlpO_yd1X0X4QnMjhG0h_n6T41FpdJcnS8,1011
+transformers/models/musicgen_melody/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/musicgen_melody/__pycache__/configuration_musicgen_melody.cpython-310.pyc,,
+transformers/models/musicgen_melody/__pycache__/feature_extraction_musicgen_melody.cpython-310.pyc,,
+transformers/models/musicgen_melody/__pycache__/modeling_musicgen_melody.cpython-310.pyc,,
+transformers/models/musicgen_melody/__pycache__/processing_musicgen_melody.cpython-310.pyc,,
+transformers/models/musicgen_melody/configuration_musicgen_melody.py,sha256=wlnZBqJQ0XElTRvI2zPc1PGLarzMsWBQaHKYmkensmk,12016
+transformers/models/musicgen_melody/feature_extraction_musicgen_melody.py,sha256=onUVyD4VSztogKli3SlXeuhd6cNn5EnH6PSjx6Lj36Y,15359
+transformers/models/musicgen_melody/modeling_musicgen_melody.py,sha256=v4ONMkUoTze2pAGp2cvkbEOSme5fku0PvAt8mXgq3UI,111580
+transformers/models/musicgen_melody/processing_musicgen_melody.py,sha256=5KuwJO6jrRtC9X3rbEjJXyNTIIg8mbrvc5LEZJERbYk,8365
+transformers/models/mvp/__init__.py,sha256=0e0-wP4EkfzPiO_BlHlmyVUEq-1kb9RHY2Ikbk66W7s,1064
+transformers/models/mvp/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/mvp/__pycache__/configuration_mvp.cpython-310.pyc,,
+transformers/models/mvp/__pycache__/modeling_mvp.cpython-310.pyc,,
+transformers/models/mvp/__pycache__/tokenization_mvp.cpython-310.pyc,,
+transformers/models/mvp/__pycache__/tokenization_mvp_fast.cpython-310.pyc,,
+transformers/models/mvp/configuration_mvp.py,sha256=Ah_EG0nItOD3_y_WDad6cnCcgGY2TXWuJzxuLJQ6fq4,8451
+transformers/models/mvp/modeling_mvp.py,sha256=oTatRI2CMr_tYT0vtmVQ1tg5tix7rNX_ybzyhUQW798,82408
+transformers/models/mvp/tokenization_mvp.py,sha256=7Q1V8hHo1hd9RCKu-A1lv2WNAcTbxhBidKNPHOLjwyc,16206
+transformers/models/mvp/tokenization_mvp_fast.py,sha256=xQrPiI91_CG7II-gQEJs7rtTSMRbKNARc185MOa5JQs,11819
+transformers/models/myt5/__init__.py,sha256=MFQX-RuvZujGb_twBWBQpTt4NZq6FxreEysWmF2fFGI,955
+transformers/models/myt5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/myt5/__pycache__/tokenization_myt5.cpython-310.pyc,,
+transformers/models/myt5/tokenization_myt5.py,sha256=GdQXAMMCaCIbfJI-Hry-9myIFXO2TLpoO6D8VC1HpAs,15535
+transformers/models/nemotron/__init__.py,sha256=ZwaMH1AQ0VIuFnouYe0Sx0HcCGA7PaCp3-_yw3xjeQA,997
+transformers/models/nemotron/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/nemotron/__pycache__/configuration_nemotron.cpython-310.pyc,,
+transformers/models/nemotron/__pycache__/modeling_nemotron.cpython-310.pyc,,
+transformers/models/nemotron/configuration_nemotron.py,sha256=QMH_Mw48ZgCvovfE3MtUM6W_34DVUb7unpr27JaVTIg,7399
+transformers/models/nemotron/modeling_nemotron.py,sha256=pZofHzQse78XI7l7W5oDhpOlXiEq2FNjQYlIPFzfh2A,44035
+transformers/models/nllb/__init__.py,sha256=MLFrxhOJ3xvOAcRulvCEMoKsajLuudllZLMrYDYQOas,997
+transformers/models/nllb/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/nllb/__pycache__/tokenization_nllb.cpython-310.pyc,,
+transformers/models/nllb/__pycache__/tokenization_nllb_fast.cpython-310.pyc,,
+transformers/models/nllb/tokenization_nllb.py,sha256=nHIf5mrI6gDEugszKVOwpB3mWPE5a1KcBFK2qRTrg-E,19158
+transformers/models/nllb/tokenization_nllb_fast.py,sha256=uT2QAtg_upIEJ9W6lKkDi7EDHOqrB08oUH6OTGNagm4,15822
+transformers/models/nllb_moe/__init__.py,sha256=sAfoAnhHK_reU1a2WUoF1rFtPBckeGGrzJCD8gUv54A,997
+transformers/models/nllb_moe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/nllb_moe/__pycache__/configuration_nllb_moe.cpython-310.pyc,,
+transformers/models/nllb_moe/__pycache__/modeling_nllb_moe.cpython-310.pyc,,
+transformers/models/nllb_moe/configuration_nllb_moe.py,sha256=jHKoRpGbrlNEcBiOk3b2fPOo1m6OD7Tx11F9r8SSd1Y,11222
+transformers/models/nllb_moe/modeling_nllb_moe.py,sha256=mhSayupmAoR5UoqWOfvd3mK5iHE4EaPatnEnyZDTA3Q,82318
+transformers/models/nougat/__init__.py,sha256=sFYK9O1tIETKks9tQ5d6X3gGWAFfTXNge06ZdnnKV9s,1090
+transformers/models/nougat/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/nougat/__pycache__/image_processing_nougat.cpython-310.pyc,,
+transformers/models/nougat/__pycache__/image_processing_nougat_fast.cpython-310.pyc,,
+transformers/models/nougat/__pycache__/processing_nougat.cpython-310.pyc,,
+transformers/models/nougat/__pycache__/tokenization_nougat_fast.cpython-310.pyc,,
+transformers/models/nougat/image_processing_nougat.py,sha256=u0IvhghXvVllApUTfDcBHL_4mXpjTqDNM2Ue_autoho,24342
+transformers/models/nougat/image_processing_nougat_fast.py,sha256=-vz4-EYom3g97WnEysl1IYEQSvNlceJFVftVol98-LU,11727
+transformers/models/nougat/processing_nougat.py,sha256=Ml3vN5CQunWQjgWfITWb10Q8mOVVpI9ru4na00_ihEM,6235
+transformers/models/nougat/tokenization_nougat_fast.py,sha256=cECSaLYYmZArdgLFFVFykYiOS37UHUMtfBsbJ6EsVyg,24466
+transformers/models/nystromformer/__init__.py,sha256=CwEg6m4nJW_AfNDws_MIv1O1x5IO3xPp-FYqirlFXwk,1007
+transformers/models/nystromformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/nystromformer/__pycache__/configuration_nystromformer.cpython-310.pyc,,
+transformers/models/nystromformer/__pycache__/modeling_nystromformer.cpython-310.pyc,,
+transformers/models/nystromformer/configuration_nystromformer.py,sha256=UyLmPF2li3_ADTz9tS1h5t4CDY5d5GzsfeC9hG42RzI,6402
+transformers/models/nystromformer/modeling_nystromformer.py,sha256=SAn8GLKjQudRNXxBdtgGOEb4TGfoENs81wFqXjvWvLk,43501
+transformers/models/olmo/__init__.py,sha256=x9u_5vqI52-uBuj89-6aYucGDlvBUEPSOhPLLB1asok,1009
+transformers/models/olmo/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/olmo/__pycache__/configuration_olmo.cpython-310.pyc,,
+transformers/models/olmo/__pycache__/modeling_olmo.cpython-310.pyc,,
+transformers/models/olmo/__pycache__/modular_olmo.cpython-310.pyc,,
+transformers/models/olmo/configuration_olmo.py,sha256=s_YotovUtp-VmB7q9RV4B1TKgjhp3gE6Ucqg72I3GJc,9423
+transformers/models/olmo/modeling_olmo.py,sha256=0umK9ECWQ4j5XD6gMBt1cV4q5tR1cIsAYzchP6rA_ko,19886
+transformers/models/olmo/modular_olmo.py,sha256=aZ4vOt4tHAYiU4lekaaTBTXxdKvKhYTXj97smqTwdIY,7132
+transformers/models/olmo2/__init__.py,sha256=Frt9nEMsfPszod1lkFTAJUobU50IjOFlqI6uJkuQVcY,1011
+transformers/models/olmo2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/olmo2/__pycache__/configuration_olmo2.cpython-310.pyc,,
+transformers/models/olmo2/__pycache__/modeling_olmo2.cpython-310.pyc,,
+transformers/models/olmo2/__pycache__/modular_olmo2.cpython-310.pyc,,
+transformers/models/olmo2/configuration_olmo2.py,sha256=kqBjnAs0k-pZ-Y8zNMRWQ-6gav-YpOpg6oy9LZ-AhpE,9439
+transformers/models/olmo2/modeling_olmo2.py,sha256=lSTTMPbTZyLq8p3PbespqegStM5SmLMNlPa2FqT8ttE,20315
+transformers/models/olmo2/modular_olmo2.py,sha256=vj_YgzQbVRrBffwiiTYSISBI-2STzAkgGKycg2TwLWs,14214
+transformers/models/olmoe/__init__.py,sha256=eQ6mx9aBIcA4RiK3p7dbqORokkuMfQNRss06E8uWNrk,991
+transformers/models/olmoe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/olmoe/__pycache__/configuration_olmoe.cpython-310.pyc,,
+transformers/models/olmoe/__pycache__/modeling_olmoe.cpython-310.pyc,,
+transformers/models/olmoe/configuration_olmoe.py,sha256=_NEJ3nvuHqEOJND_jWjpqfV-mR7-CB9lUnVPoDmhCp4,9069
+transformers/models/olmoe/modeling_olmoe.py,sha256=nxuXRv5Y6TSaMbMsoP1lZGS7YNIDS3b_cNrTfI4AAwc,51818
+transformers/models/omdet_turbo/__init__.py,sha256=XIckpuo9tkT7NB5uTs9wLdpxr9GDedQPVJL2P8XU-7Q,1045
+transformers/models/omdet_turbo/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/omdet_turbo/__pycache__/configuration_omdet_turbo.cpython-310.pyc,,
+transformers/models/omdet_turbo/__pycache__/modeling_omdet_turbo.cpython-310.pyc,,
+transformers/models/omdet_turbo/__pycache__/processing_omdet_turbo.cpython-310.pyc,,
+transformers/models/omdet_turbo/configuration_omdet_turbo.py,sha256=2XMjtVGwInCV4GpQW-FHqsvXCoce1rsiBMT9j2BXevo,14933
+transformers/models/omdet_turbo/modeling_omdet_turbo.py,sha256=w8u1x7UgfKgh6PvxWvJWsBAMSTF4LXCplQq_94bkKCo,74036
+transformers/models/omdet_turbo/processing_omdet_turbo.py,sha256=E8UhsgC7INAwithZbbdoPbKiE6jKjt-zpwwEyp9xUuw,16861
+transformers/models/oneformer/__init__.py,sha256=MrdVp7ZBJOVbWMpwojOPnEzDDW2HSqs5oSZG81jdCQI,1136
+transformers/models/oneformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/oneformer/__pycache__/configuration_oneformer.cpython-310.pyc,,
+transformers/models/oneformer/__pycache__/image_processing_oneformer.cpython-310.pyc,,
+transformers/models/oneformer/__pycache__/image_processing_oneformer_fast.cpython-310.pyc,,
+transformers/models/oneformer/__pycache__/modeling_oneformer.cpython-310.pyc,,
+transformers/models/oneformer/__pycache__/processing_oneformer.cpython-310.pyc,,
+transformers/models/oneformer/configuration_oneformer.py,sha256=GeVa40j8P2XaKbU58JWE9C2EYXNhgUJjY13kUzXliMU,13678
+transformers/models/oneformer/image_processing_oneformer.py,sha256=YkR_m8cWn2NOCtMRBodqf_wFkV2AkWLT7J8cLQn8bAE,60616
+transformers/models/oneformer/image_processing_oneformer_fast.py,sha256=G_nNzcBfykfNFiICp2U71t2NXYOuGE57RaX5CVkQq1I,42048
+transformers/models/oneformer/modeling_oneformer.py,sha256=Q7MVzSsyLMCSnv1WgCF3wFKFsLEXb9AoHvik2nKypLI,139958
+transformers/models/oneformer/processing_oneformer.py,sha256=qOKqFy8VD-IwWzWJL9Z7SUwjwUkk5cCkNSP5ZqAqv2w,9387
+transformers/models/openai/__init__.py,sha256=q0fAl8ajoJyknHe5A3ZHuHH3zww8xdupt_j49lIaObY,1114
+transformers/models/openai/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/openai/__pycache__/configuration_openai.cpython-310.pyc,,
+transformers/models/openai/__pycache__/modeling_openai.cpython-310.pyc,,
+transformers/models/openai/__pycache__/modeling_tf_openai.cpython-310.pyc,,
+transformers/models/openai/__pycache__/tokenization_openai.cpython-310.pyc,,
+transformers/models/openai/__pycache__/tokenization_openai_fast.cpython-310.pyc,,
+transformers/models/openai/configuration_openai.py,sha256=ERFfcrsaGEuG-8WnuBDfYyHR7uc5ihEr9JfItBMGZm0,7109
+transformers/models/openai/modeling_openai.py,sha256=z_DEm4TvLy5l7M3oOccw524Y8Sc2jvPkY9wUfFGBspk,37487
+transformers/models/openai/modeling_tf_openai.py,sha256=mZWr6qc8fCXTR6y6GXLc_E_FgHn5-CB6dzMOhGXbfVM,40857
+transformers/models/openai/tokenization_openai.py,sha256=MhxS6G-hQLHLdmarGxOPBpvMEbNLHuFRZehOjzg-o90,15159
+transformers/models/openai/tokenization_openai_fast.py,sha256=qBalVcRbqq9AZAnzkFvYTbokp4eU-BvgO3QIWYoqndo,2553
+transformers/models/opt/__init__.py,sha256=Xk3Z-OdrOC4Y5J0KOEIB74Pp4PsfAllBI503NT7yFk8,1059
+transformers/models/opt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/opt/__pycache__/configuration_opt.cpython-310.pyc,,
+transformers/models/opt/__pycache__/modeling_flax_opt.cpython-310.pyc,,
+transformers/models/opt/__pycache__/modeling_opt.cpython-310.pyc,,
+transformers/models/opt/__pycache__/modeling_tf_opt.cpython-310.pyc,,
+transformers/models/opt/configuration_opt.py,sha256=nEHN7nBCghjCfcU_vueoTL5TfCMc6JUE6cUH6knhnxM,6694
+transformers/models/opt/modeling_flax_opt.py,sha256=a1OCINHVTj-osjuJUxfYZgTS-1j7r6EPT-TgAD9lP74,31631
+transformers/models/opt/modeling_opt.py,sha256=5T1guptdjUGoPA9W38uwi9dnYzVJpa2mD3yEzH0hoIA,49040
+transformers/models/opt/modeling_tf_opt.py,sha256=gZ8xHAIaZDYmsvHbxNI66ITB0QIaYoYdbLF7uNVuTEg,49360
+transformers/models/ovis2/__init__.py,sha256=df6-Fy8DbIIuQ9a29Ko9XPCSZm0Yh8hNEnTLR4NUgj0,1137
+transformers/models/ovis2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/ovis2/__pycache__/configuration_ovis2.cpython-310.pyc,,
+transformers/models/ovis2/__pycache__/image_processing_ovis2.cpython-310.pyc,,
+transformers/models/ovis2/__pycache__/image_processing_ovis2_fast.cpython-310.pyc,,
+transformers/models/ovis2/__pycache__/modeling_ovis2.cpython-310.pyc,,
+transformers/models/ovis2/__pycache__/modular_ovis2.cpython-310.pyc,,
+transformers/models/ovis2/__pycache__/processing_ovis2.cpython-310.pyc,,
+transformers/models/ovis2/configuration_ovis2.py,sha256=TPLM3X-fnZ5IYjF8vyZ-bxtF9ob8Wu5QvrxX4pR7eWg,8187
+transformers/models/ovis2/image_processing_ovis2.py,sha256=BmZTQvkLhHKfm4btKJ_W0BRvD2pD2Ay_hX1ykU4J6f0,27808
+transformers/models/ovis2/image_processing_ovis2_fast.py,sha256=Ti42Q3dOKSlO8wtpQ59Nu96N4bPlrQLehhqn1xI-2OE,11083
+transformers/models/ovis2/modeling_ovis2.py,sha256=p1g4GZJcyBeziMSqnSFqCEdc5MdePc86fDMPXMQBSBU,37486
+transformers/models/ovis2/modular_ovis2.py,sha256=hsBxGKcMss16SEJJR0D8MD54et0p5zXaNTgYvl-E5rg,17249
+transformers/models/ovis2/processing_ovis2.py,sha256=HXaXqDcV5SmVuiAw-Q8h2PsAzFM-_cZq3MWRsuG680E,7952
+transformers/models/owlv2/__init__.py,sha256=vHnQwYJ0hEc12ofOV3b1k9fHscBgfQEXcLLgo4-H3GU,1116
+transformers/models/owlv2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/owlv2/__pycache__/configuration_owlv2.cpython-310.pyc,,
+transformers/models/owlv2/__pycache__/image_processing_owlv2.cpython-310.pyc,,
+transformers/models/owlv2/__pycache__/image_processing_owlv2_fast.cpython-310.pyc,,
+transformers/models/owlv2/__pycache__/modeling_owlv2.cpython-310.pyc,,
+transformers/models/owlv2/__pycache__/modular_owlv2.cpython-310.pyc,,
+transformers/models/owlv2/__pycache__/processing_owlv2.cpython-310.pyc,,
+transformers/models/owlv2/configuration_owlv2.py,sha256=18Krr0RoZ25eU0eCSPegHXXKAoA64zw-bknsCeBkPTs,13134
+transformers/models/owlv2/image_processing_owlv2.py,sha256=W0HZzjkhSk9himUBqfIKXK_gJ1pJ9nAn9XCt20nQXkw,28039
+transformers/models/owlv2/image_processing_owlv2_fast.py,sha256=hel-tIO6jPRqE_Rl2rksI6zo_GwRSJ8UpfFAQH5H4wk,18488
+transformers/models/owlv2/modeling_owlv2.py,sha256=OGEKTGLaTja5J75toXHtFdRs5fLUylW91chjXPXfC8M,78935
+transformers/models/owlv2/modular_owlv2.py,sha256=DFKAG_1-iIOfCbph-mdAYyzqY7Ezv-_omPxYTOWErfo,9080
+transformers/models/owlv2/processing_owlv2.py,sha256=MVHPoglowqzgwzTZjKX_w6voFqdc1OODeXF72sy6DEM,14535
+transformers/models/owlvit/__init__.py,sha256=Nhrrja_j2RZtj-rQS6TDJ8upQqnMptnFukq49QAkito,1166
+transformers/models/owlvit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/owlvit/__pycache__/configuration_owlvit.cpython-310.pyc,,
+transformers/models/owlvit/__pycache__/feature_extraction_owlvit.cpython-310.pyc,,
+transformers/models/owlvit/__pycache__/image_processing_owlvit.cpython-310.pyc,,
+transformers/models/owlvit/__pycache__/image_processing_owlvit_fast.cpython-310.pyc,,
+transformers/models/owlvit/__pycache__/modeling_owlvit.cpython-310.pyc,,
+transformers/models/owlvit/__pycache__/processing_owlvit.cpython-310.pyc,,
+transformers/models/owlvit/configuration_owlvit.py,sha256=KxKdzp6xBZOAEBDSGu_LRGYBKhjEg7tU8dfqLQXv6wo,14435
+transformers/models/owlvit/feature_extraction_owlvit.py,sha256=49Ic56gmQQtE_WEmzzyE9bVBdS5RMkG3vOK1cBcjc5g,1300
+transformers/models/owlvit/image_processing_owlvit.py,sha256=k0YJn8x5Rdi9Jb1oaXw7_Zf3f_1J16VVPkmiTdESE0w,29461
+transformers/models/owlvit/image_processing_owlvit_fast.py,sha256=7LZLoAn_n89oYr7s2oWltV7K9PzrgaFOQZLY1IqFZeI,10574
+transformers/models/owlvit/modeling_owlvit.py,sha256=n2rzrSHHmXVzjjdMdnox0JR_HNFXl_YqszW1eMhgLyY,74369
+transformers/models/owlvit/processing_owlvit.py,sha256=e5GZPs1yyQIZHc01P8iX13ze5hIEKwI-oz_7P1bSeGE,15488
+transformers/models/paligemma/__init__.py,sha256=nKnTTLC8XYlI7uYfS8h-D4vz3gFhknkNeDlZIwZlZ9w,1039
+transformers/models/paligemma/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/paligemma/__pycache__/configuration_paligemma.cpython-310.pyc,,
+transformers/models/paligemma/__pycache__/modeling_paligemma.cpython-310.pyc,,
+transformers/models/paligemma/__pycache__/processing_paligemma.cpython-310.pyc,,
+transformers/models/paligemma/configuration_paligemma.py,sha256=BTK5bsUZwUovhsGqWHIzYidzy-XyBEtDEROPh3IZJ9w,5362
+transformers/models/paligemma/modeling_paligemma.py,sha256=ZZ8wrD9GhRwfrUHOuF_Pc_xqN_Nn2a3fi2VYsCgqjHU,27832
+transformers/models/paligemma/processing_paligemma.py,sha256=G8bFhaV8SsXri2SA0GRKlU2hmo2lL3b1RgSk62J8Nf8,15369
+transformers/models/patchtsmixer/__init__.py,sha256=deFjF_Tu67XcAcNHaq1PXO77N4kVW9wG80SnXBaeagE,1005
+transformers/models/patchtsmixer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/patchtsmixer/__pycache__/configuration_patchtsmixer.cpython-310.pyc,,
+transformers/models/patchtsmixer/__pycache__/modeling_patchtsmixer.cpython-310.pyc,,
+transformers/models/patchtsmixer/configuration_patchtsmixer.py,sha256=h1w-YRD_Q9AgQUKBRvzxi2JBEW35NbDap8xkdui-c3U,12580
+transformers/models/patchtsmixer/modeling_patchtsmixer.py,sha256=Tb4GZWfKaXEwNt12Rr6TNZp4nQsBXq_lzmUfRR4EyS8,85134
+transformers/models/patchtst/__init__.py,sha256=lrpuBvP25Yq6HZOCyS4yWVYZ47qWzK--rqC0AOIGGPE,997
+transformers/models/patchtst/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/patchtst/__pycache__/configuration_patchtst.cpython-310.pyc,,
+transformers/models/patchtst/__pycache__/modeling_patchtst.cpython-310.pyc,,
+transformers/models/patchtst/configuration_patchtst.py,sha256=FdiHfYFiHvo7kIuOV_zSGPHZ2Q-QYbPEB1ZkqLOc5qE,12309
+transformers/models/patchtst/modeling_patchtst.py,sha256=fYVkC0X1QFCMEmNF9yRMp-hYFphSQPjuwgZTQa-4Rh0,84642
+transformers/models/pegasus/__init__.py,sha256=4b7vCYJfIWUPuKrbcBGTG7LtobUdZ5ZjeQhloScTrXs,1160
+transformers/models/pegasus/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/pegasus/__pycache__/configuration_pegasus.cpython-310.pyc,,
+transformers/models/pegasus/__pycache__/modeling_flax_pegasus.cpython-310.pyc,,
+transformers/models/pegasus/__pycache__/modeling_pegasus.cpython-310.pyc,,
+transformers/models/pegasus/__pycache__/modeling_tf_pegasus.cpython-310.pyc,,
+transformers/models/pegasus/__pycache__/tokenization_pegasus.cpython-310.pyc,,
+transformers/models/pegasus/__pycache__/tokenization_pegasus_fast.cpython-310.pyc,,
+transformers/models/pegasus/configuration_pegasus.py,sha256=78-WMVFtUhigUXXJ4PabYJA8S3VpfQW9-2NcM5t8Hlo,7517
+transformers/models/pegasus/modeling_flax_pegasus.py,sha256=Rkc0964DKuqgYPMmzKNcZx4_g3hOqV8kD5udpqy-wRE,66161
+transformers/models/pegasus/modeling_pegasus.py,sha256=jPFZDcIVqKqOwP8MbdKi1R_OnSJUAcconY9XaAuujoM,78113
+transformers/models/pegasus/modeling_tf_pegasus.py,sha256=_WR-vfHxUBGzBUJVEsw7pajamDJQAeZZYsMvEU_HV_4,74149
+transformers/models/pegasus/tokenization_pegasus.py,sha256=Mlf8ZdllYQGJMktD0ci2aD46NczeKcuw-NZNgt9bkgw,13231
+transformers/models/pegasus/tokenization_pegasus_fast.py,sha256=c6xFEwXqtpScjYMasosqrAlwJMsdJCC_Sjp_BYniK7s,9833
+transformers/models/pegasus_x/__init__.py,sha256=qSLaqKRA1upZOobapHW5MjSZvIEzf-ij-ZmY1VGzqaE,999
+transformers/models/pegasus_x/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/pegasus_x/__pycache__/configuration_pegasus_x.cpython-310.pyc,,
+transformers/models/pegasus_x/__pycache__/modeling_pegasus_x.cpython-310.pyc,,
+transformers/models/pegasus_x/configuration_pegasus_x.py,sha256=RasKHKP1N0ZEvsl81J2Y3jhNAJo0zplnAKI2ZqYJdv4,8132
+transformers/models/pegasus_x/modeling_pegasus_x.py,sha256=CA_DRYdTklPMEu2fc4wykl1lp6TJN2z7xes3fqdCKUY,79316
+transformers/models/perceiver/__init__.py,sha256=LKUlUJfZGRC1jU6TNkG-4kNy8aIeHIqvAnwLI_33AVY,1186
+transformers/models/perceiver/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/perceiver/__pycache__/configuration_perceiver.cpython-310.pyc,,
+transformers/models/perceiver/__pycache__/feature_extraction_perceiver.cpython-310.pyc,,
+transformers/models/perceiver/__pycache__/image_processing_perceiver.cpython-310.pyc,,
+transformers/models/perceiver/__pycache__/image_processing_perceiver_fast.cpython-310.pyc,,
+transformers/models/perceiver/__pycache__/modeling_perceiver.cpython-310.pyc,,
+transformers/models/perceiver/__pycache__/tokenization_perceiver.cpython-310.pyc,,
+transformers/models/perceiver/configuration_perceiver.py,sha256=0h5NCC6iJiA_cOv9gvcpxNgiFc0r25Rvv7PIHh1jp6Q,12236
+transformers/models/perceiver/feature_extraction_perceiver.py,sha256=JK3Y4won5macefR13tx-zdUF_TaHE4RrJllJyYzIhWU,1324
+transformers/models/perceiver/image_processing_perceiver.py,sha256=GmhCl-yDAAds6vhTgOMp-ZPo6JKEiWplFvylFSi7by0,17571
+transformers/models/perceiver/image_processing_perceiver_fast.py,sha256=zyymGbSd8od2ZgNP95LJbxsfa-J-tgY-DCK7KZF7J5E,5282
+transformers/models/perceiver/modeling_perceiver.py,sha256=kk3I_R7ctA2vuaaljOCxMzJrNmJJdPY_ko8gu2zv2UE,140575
+transformers/models/perceiver/tokenization_perceiver.py,sha256=9cCQTtfKJUzwWoUQ3YEBdsh9RrJgsL4N2kxA8fPQuqc,8034
+transformers/models/perception_lm/__init__.py,sha256=RVEjQWlzsHJm3D-3JXLThzBjJLSCMpvFslQMIkvRKiA,1106
+transformers/models/perception_lm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/perception_lm/__pycache__/configuration_perception_lm.cpython-310.pyc,,
+transformers/models/perception_lm/__pycache__/image_processing_perception_lm_fast.cpython-310.pyc,,
+transformers/models/perception_lm/__pycache__/modeling_perception_lm.cpython-310.pyc,,
+transformers/models/perception_lm/__pycache__/modular_perception_lm.cpython-310.pyc,,
+transformers/models/perception_lm/__pycache__/processing_perception_lm.cpython-310.pyc,,
+transformers/models/perception_lm/__pycache__/video_processing_perception_lm.cpython-310.pyc,,
+transformers/models/perception_lm/configuration_perception_lm.py,sha256=O8m8_bm2W3bvHjIpj_F5nKoz4kLsnB69KwO0mcLQUOw,3913
+transformers/models/perception_lm/image_processing_perception_lm_fast.py,sha256=SWHs6zGFfwjhJnb7B1xbjtYyvSPs-2Lb8gFya4y2InM,14104
+transformers/models/perception_lm/modeling_perception_lm.py,sha256=HRuMcicAMQFWhd3S7cJVn5wFCpQYclO8ThrIrRd8aO0,20902
+transformers/models/perception_lm/modular_perception_lm.py,sha256=4EdyoWmkDxFnv1FGgRhsI7NBK8sm81iL1GC6Eb9ZR40,17021
+transformers/models/perception_lm/processing_perception_lm.py,sha256=bY78Yz7_A_OaZJbYRLGCXabwxB8M2deunWHKJ-dup9g,11377
+transformers/models/perception_lm/video_processing_perception_lm.py,sha256=ZcjOvRNlN9Bw1OQbnbokSiExl1Fqgb88G5ZuhUMKrjk,1776
+transformers/models/persimmon/__init__.py,sha256=T1WqyE78N2TO74u9a9QdRIGaMowYqP6vWv8KhPojkLg,999
+transformers/models/persimmon/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/persimmon/__pycache__/configuration_persimmon.cpython-310.pyc,,
+transformers/models/persimmon/__pycache__/modeling_persimmon.cpython-310.pyc,,
+transformers/models/persimmon/configuration_persimmon.py,sha256=6KV-r-B5sqC9d2Ybzind_YDxqnM0lITfbH5zPqGg6K4,9149
+transformers/models/persimmon/modeling_persimmon.py,sha256=jolD2D0CW-vBi_qJPgXmFbYCC0BjLANEzPc5VKeX2QA,33865
+transformers/models/phi/__init__.py,sha256=4DUgmUqGKcGXxzTrxUVGcacZ43uv3SzXsOV_Ke6oeGg,1006
+transformers/models/phi/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/phi/__pycache__/configuration_phi.cpython-310.pyc,,
+transformers/models/phi/__pycache__/modeling_phi.cpython-310.pyc,,
+transformers/models/phi/__pycache__/modular_phi.cpython-310.pyc,,
+transformers/models/phi/configuration_phi.py,sha256=xYk2xva2KXG5k_Dk8ND3JObDjcfPuklUdSkNIT0DYJ8,11172
+transformers/models/phi/modeling_phi.py,sha256=GQmnzp2v5NBzUxDyKvwYrawO4LQyf1QFPC1R2_Dy2cU,22145
+transformers/models/phi/modular_phi.py,sha256=Kd2Tj-bjne-PF6FBjcxIzH_d1AuMzrDfAoDhSQzjpD8,11632
+transformers/models/phi3/__init__.py,sha256=dxyO-jIh0yB6t2Dzs173aRrEnTceVMIYIkg6JxIeyWs,989
+transformers/models/phi3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/phi3/__pycache__/configuration_phi3.cpython-310.pyc,,
+transformers/models/phi3/__pycache__/modeling_phi3.cpython-310.pyc,,
+transformers/models/phi3/__pycache__/modular_phi3.cpython-310.pyc,,
+transformers/models/phi3/configuration_phi3.py,sha256=lzlUJCKk4nJl2v8R5AIK36b2bgr0stkGm9VYPZkurQU,11579
+transformers/models/phi3/modeling_phi3.py,sha256=Oy4ZuDltRyxrrSzIbRCVDDSqWhPevNkojaqO4Cb3w70,23278
+transformers/models/phi3/modular_phi3.py,sha256=onLbm2ftDXE2_u7ffa15cCj68yYm3oI_oVcfHSO5_vw,11162
+transformers/models/phi4_multimodal/__init__.py,sha256=EqoKUvkh9f14qg07g-4MLclztlyiyLfN2qqEp3RGp2w,1170
+transformers/models/phi4_multimodal/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/phi4_multimodal/__pycache__/configuration_phi4_multimodal.cpython-310.pyc,,
+transformers/models/phi4_multimodal/__pycache__/feature_extraction_phi4_multimodal.cpython-310.pyc,,
+transformers/models/phi4_multimodal/__pycache__/image_processing_phi4_multimodal_fast.cpython-310.pyc,,
+transformers/models/phi4_multimodal/__pycache__/modeling_phi4_multimodal.cpython-310.pyc,,
+transformers/models/phi4_multimodal/__pycache__/modular_phi4_multimodal.cpython-310.pyc,,
+transformers/models/phi4_multimodal/__pycache__/processing_phi4_multimodal.cpython-310.pyc,,
+transformers/models/phi4_multimodal/configuration_phi4_multimodal.py,sha256=RIdYbnvcs_8VkFcJY96M06PUEI1kt70WFU_YDE8-9vI,24371
+transformers/models/phi4_multimodal/feature_extraction_phi4_multimodal.py,sha256=T1R76IxQCkMh-_jeP8zrBecywvbDnG5hNt_VJAKs2nk,13413
+transformers/models/phi4_multimodal/image_processing_phi4_multimodal_fast.py,sha256=k1bjVnH8awgbBeWMPNAVquxEOP4M5cATOQ1mtJswkvo,10788
+transformers/models/phi4_multimodal/modeling_phi4_multimodal.py,sha256=GbwJw0JZCRh3NSZPbgN1luV1-4-vPwTqoBdr_ihdnB4,82828
+transformers/models/phi4_multimodal/modular_phi4_multimodal.py,sha256=KHgOMnUZqbg1F0YSiN-VlRcfpKS254TAzVNffL0msSs,77467
+transformers/models/phi4_multimodal/processing_phi4_multimodal.py,sha256=b7t3Pi6-hoTG--QpHfMCtoIZzyYYwmQtvM1EbUriiIs,8107
+transformers/models/phimoe/__init__.py,sha256=wGasPysu0EH_q0QGaZmXqQL57GxfZn8NTsvB2I6U2ro,1013
+transformers/models/phimoe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/phimoe/__pycache__/configuration_phimoe.cpython-310.pyc,,
+transformers/models/phimoe/__pycache__/modeling_phimoe.cpython-310.pyc,,
+transformers/models/phimoe/configuration_phimoe.py,sha256=bmX2NBq89oFKQ5PnFmkcknw5dT6A9w2D9psS8jubltw,10238
+transformers/models/phimoe/modeling_phimoe.py,sha256=iEa0fauq0XIDtVyiSkCM4OAj2Knj8cH0qRpV67FF61Y,60222
+transformers/models/phobert/__init__.py,sha256=mau-2HIOzSk8qGIhxivVBPPYTx3hhdgoKPtnptDF38M,958
+transformers/models/phobert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/phobert/__pycache__/tokenization_phobert.cpython-310.pyc,,
+transformers/models/phobert/tokenization_phobert.py,sha256=0ItqQt-YiRb44Wqyp6e59UQOc_wSmErRFAziorm_w6o,13111
+transformers/models/pix2struct/__init__.py,sha256=ivncogrVjZZ6ag6FYHJ0XqyCMJYbsCYlh5boqxe09Yo,1089
+transformers/models/pix2struct/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/pix2struct/__pycache__/configuration_pix2struct.cpython-310.pyc,,
+transformers/models/pix2struct/__pycache__/image_processing_pix2struct.cpython-310.pyc,,
+transformers/models/pix2struct/__pycache__/modeling_pix2struct.cpython-310.pyc,,
+transformers/models/pix2struct/__pycache__/processing_pix2struct.cpython-310.pyc,,
+transformers/models/pix2struct/configuration_pix2struct.py,sha256=eHg19KzSW5bh2dVTgMH7vhZPZu2yg6iEpy8DNO6bk8U,15370
+transformers/models/pix2struct/image_processing_pix2struct.py,sha256=XiCpqkp1Kl4j0W7zrAR2GYv4iM-8QS4PNGeGZzk3G_c,19788
+transformers/models/pix2struct/modeling_pix2struct.py,sha256=j7GlSTPKK5BXlwAEU140wSJSQfDENW2FMfcjB-FUklM,72206
+transformers/models/pix2struct/processing_pix2struct.py,sha256=d_oNjxTHgeu06zbPe5ZjHUvcignufU4Wql8XBhvvgwk,5677
+transformers/models/pixtral/__init__.py,sha256=WKCxuWpCeTYsYSaTH1XnUcGkIHEx5BIIXwwwqG_E83s,1126
+transformers/models/pixtral/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/pixtral/__pycache__/configuration_pixtral.cpython-310.pyc,,
+transformers/models/pixtral/__pycache__/image_processing_pixtral.cpython-310.pyc,,
+transformers/models/pixtral/__pycache__/image_processing_pixtral_fast.cpython-310.pyc,,
+transformers/models/pixtral/__pycache__/modeling_pixtral.cpython-310.pyc,,
+transformers/models/pixtral/__pycache__/processing_pixtral.cpython-310.pyc,,
+transformers/models/pixtral/configuration_pixtral.py,sha256=86cY74VW7J8XqU1JbvpxLqOXnnzoPh7I_9zja8j3Wng,4237
+transformers/models/pixtral/image_processing_pixtral.py,sha256=RxmiIesBixpB6LEjJ895BZJ1Nl1AW5pNhOzvG9IvPks,22075
+transformers/models/pixtral/image_processing_pixtral_fast.py,sha256=euCOMDJW8MwUUUD_TqVjkpEPuadtu5uxnnvPp-Apdrc,8159
+transformers/models/pixtral/modeling_pixtral.py,sha256=AwBDhr0B8xyBmNRZ7_QYBEWGmNke4Y9sRwQQ4YhGx-s,21443
+transformers/models/pixtral/processing_pixtral.py,sha256=38-FrxYHQm_GSAC9LYYc2p1_hCsQHS7uQHzpsVToIMM,11876
+transformers/models/plbart/__init__.py,sha256=jmP857QTG7jGfr9n0qK3TB_1-hdVDD1ajtJvP6C7FIw,1032
+transformers/models/plbart/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/plbart/__pycache__/configuration_plbart.cpython-310.pyc,,
+transformers/models/plbart/__pycache__/modeling_plbart.cpython-310.pyc,,
+transformers/models/plbart/__pycache__/modular_plbart.cpython-310.pyc,,
+transformers/models/plbart/__pycache__/tokenization_plbart.cpython-310.pyc,,
+transformers/models/plbart/configuration_plbart.py,sha256=N3T4lbCCGP3nYNIHYah1yMvDy1FiJqgpdHIAKJFfcTQ,8621
+transformers/models/plbart/modeling_plbart.py,sha256=HCtjE7xcaybW6NviHzWg-JYVyw_E_hUOWXWdA6sisCA,80739
+transformers/models/plbart/modular_plbart.py,sha256=afA2u6_9FVcBxg0FFVdaX0dvcwXt4bqQVh0sDJMekIU,31250
+transformers/models/plbart/tokenization_plbart.py,sha256=ytGwNtPfgHXoKdK85Qm1fz68tBU-qbrYwdMLd96d2Xs,18910
+transformers/models/poolformer/__init__.py,sha256=FgSXHIGeF8uz-Ye67HSRQefjounknzaqm0ZCOiMj4zo,1149
+transformers/models/poolformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/poolformer/__pycache__/configuration_poolformer.cpython-310.pyc,,
+transformers/models/poolformer/__pycache__/feature_extraction_poolformer.cpython-310.pyc,,
+transformers/models/poolformer/__pycache__/image_processing_poolformer.cpython-310.pyc,,
+transformers/models/poolformer/__pycache__/image_processing_poolformer_fast.cpython-310.pyc,,
+transformers/models/poolformer/__pycache__/modeling_poolformer.cpython-310.pyc,,
+transformers/models/poolformer/configuration_poolformer.py,sha256=mU4fQSyfdSwP-vB3UIAkNuYI6wyqhxu2R3SOupiY2pc,5641
+transformers/models/poolformer/feature_extraction_poolformer.py,sha256=8NBHTCScDnuQAjwNVL1Mxs4xllp9FnJCSonL_ceF_lg,1332
+transformers/models/poolformer/image_processing_poolformer.py,sha256=nSno0MMnMsS8I4Hvw2majioTOt8pze37RH3rNsw05dk,17922
+transformers/models/poolformer/image_processing_poolformer_fast.py,sha256=G-ZZt8KLGKRRkCH5f7XcFVoDccI8p2O70pvSIB3osxU,10569
+transformers/models/poolformer/modeling_poolformer.py,sha256=H0hY5vk3xaARWeFeAfjeiO5XI4mT7crpTSp2drirAX0,15954
+transformers/models/pop2piano/__init__.py,sha256=I2PPcFi-p0X5py7dLqobymv3E9g-mUv1QRn0luyPlIk,999
+transformers/models/pop2piano/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/pop2piano/__pycache__/configuration_pop2piano.cpython-310.pyc,,
+transformers/models/pop2piano/__pycache__/feature_extraction_pop2piano.cpython-310.pyc,,
+transformers/models/pop2piano/__pycache__/modeling_pop2piano.cpython-310.pyc,,
+transformers/models/pop2piano/__pycache__/processing_pop2piano.cpython-310.pyc,,
+transformers/models/pop2piano/__pycache__/tokenization_pop2piano.cpython-310.pyc,,
+transformers/models/pop2piano/configuration_pop2piano.py,sha256=aAnTDZdBrl19Kg6eOuPs13cz1_9ITlN7IgxysOqDGT4,5959
+transformers/models/pop2piano/feature_extraction_pop2piano.py,sha256=DQb7Y7mxkvYfwDbZQ-CQYzdOQ9mX17D-lhcsMMW4538,19974
+transformers/models/pop2piano/modeling_pop2piano.py,sha256=KuO0PsDnj1FpHxHCWYzMMrk-xRlRSHBxzjHwPYlHy6w,63148
+transformers/models/pop2piano/processing_pop2piano.py,sha256=Fdvmle3D5Clhgx6RMjXE2RknTvcNahWWIUo8PltF50c,5399
+transformers/models/pop2piano/tokenization_pop2piano.py,sha256=XGoKjV1wPf14Taef2N-fXQRIi0kU3aZBUBdDl_ve7dw,32802
+transformers/models/prompt_depth_anything/__init__.py,sha256=7hl1iucaCG_JLQIF-336EbE7TmCzeO_BGvNZmN3w5RU,1234
+transformers/models/prompt_depth_anything/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/prompt_depth_anything/__pycache__/configuration_prompt_depth_anything.cpython-310.pyc,,
+transformers/models/prompt_depth_anything/__pycache__/image_processing_prompt_depth_anything.cpython-310.pyc,,
+transformers/models/prompt_depth_anything/__pycache__/modeling_prompt_depth_anything.cpython-310.pyc,,
+transformers/models/prompt_depth_anything/__pycache__/modular_prompt_depth_anything.cpython-310.pyc,,
+transformers/models/prompt_depth_anything/configuration_prompt_depth_anything.py,sha256=vL-HwgUR7moy5eBRTH0t1qPDduSQ40J9F6i9rpNZG-Y,9062
+transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything.py,sha256=20q7lfiocfHNYRVFXbC-WBdffWrlXWSxbxgAaD1FDno,24850
+transformers/models/prompt_depth_anything/modeling_prompt_depth_anything.py,sha256=kpI2MyI32F-vI3I412QykOXfNIJHBaqpVJ13uubaaOg,20407
+transformers/models/prompt_depth_anything/modular_prompt_depth_anything.py,sha256=wP11VynfmVInYHvH4GeJDd1ELl7C7nj8evmivgntkDQ,13755
+transformers/models/prophetnet/__init__.py,sha256=TYI21JDlj449kTgKAOtUBpuxVv5L_I70CDjofSZ627M,1044
+transformers/models/prophetnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/prophetnet/__pycache__/configuration_prophetnet.cpython-310.pyc,,
+transformers/models/prophetnet/__pycache__/modeling_prophetnet.cpython-310.pyc,,
+transformers/models/prophetnet/__pycache__/tokenization_prophetnet.cpython-310.pyc,,
+transformers/models/prophetnet/configuration_prophetnet.py,sha256=XPcB7itQbCqMzONUd3-4Ag6wtBHC4f3-jWb6OUTyxoQ,8893
+transformers/models/prophetnet/modeling_prophetnet.py,sha256=R3QawQplCzFWBZPdDu_WeenL0fPDxbPghcb0lZd8oNE,97178
+transformers/models/prophetnet/tokenization_prophetnet.py,sha256=JsP4EwckyDeORtcAsVlrNlfLXo_YriRbiZwLcKEzFDI,20154
+transformers/models/pvt/__init__.py,sha256=-4ajQRrz2cTp2czAd6D23yxShatfUpHzZrHyyLRsku0,1072
+transformers/models/pvt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/pvt/__pycache__/configuration_pvt.cpython-310.pyc,,
+transformers/models/pvt/__pycache__/image_processing_pvt.cpython-310.pyc,,
+transformers/models/pvt/__pycache__/image_processing_pvt_fast.cpython-310.pyc,,
+transformers/models/pvt/__pycache__/modeling_pvt.cpython-310.pyc,,
+transformers/models/pvt/configuration_pvt.py,sha256=NivJRKXgMQ-F4SOqf7Z3nFNWxJKdsV6iqJ2YdVvrtj0,6983
+transformers/models/pvt/image_processing_pvt.py,sha256=ALCRVpWFt18qSX5fxZuBWBqHEPY8kPmI708bUvnzWYg,13862
+transformers/models/pvt/image_processing_pvt_fast.py,sha256=C2hhtB4aUqbLdVawDaeubuef9fSkC-oNT0c4WJK8Ja0,1341
+transformers/models/pvt/modeling_pvt.py,sha256=BhG1tRpznXNSfEPkJ0cgWCLlq4OpAhMbhLuWk7o9iZE,25801
+transformers/models/pvt_v2/__init__.py,sha256=LkmqeLd7cZGKTFX_2d9_jU0sj_bDlML042kr_vMJTLw,993
+transformers/models/pvt_v2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/pvt_v2/__pycache__/configuration_pvt_v2.cpython-310.pyc,,
+transformers/models/pvt_v2/__pycache__/modeling_pvt_v2.cpython-310.pyc,,
+transformers/models/pvt_v2/configuration_pvt_v2.py,sha256=7LMMRQUgb_xYvWFkGtLxA6k_a10cBFUtSx8vejJup38,7978
+transformers/models/pvt_v2/modeling_pvt_v2.py,sha256=kVdiGbm_R-7zEKGfNXLwgz2NXcgLN0JrZFKUEK_Lyzs,26480
+transformers/models/qwen2/__init__.py,sha256=e49oEzErXujE0UVl_q_agf5XHzHES4vV2kLwmqdk2kg,1095
+transformers/models/qwen2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen2/__pycache__/configuration_qwen2.cpython-310.pyc,,
+transformers/models/qwen2/__pycache__/modeling_qwen2.cpython-310.pyc,,
+transformers/models/qwen2/__pycache__/modular_qwen2.cpython-310.pyc,,
+transformers/models/qwen2/__pycache__/tokenization_qwen2.cpython-310.pyc,,
+transformers/models/qwen2/__pycache__/tokenization_qwen2_fast.cpython-310.pyc,,
+transformers/models/qwen2/configuration_qwen2.py,sha256=pn06fpnCFoGGJj7DVY1wZRIGOrfnn7wtdAJoJ179b9g,11376
+transformers/models/qwen2/modeling_qwen2.py,sha256=pZ-gZSQic2H7QBuvTRdxJKJ67BRrwB7JMSNamrurF8s,21621
+transformers/models/qwen2/modular_qwen2.py,sha256=PEMiuSdFlfj5F0ybC0NAyUm8kDeGlkLmXq0xKSwiTzE,9528
+transformers/models/qwen2/tokenization_qwen2.py,sha256=I_BWl_yvJv5eMoq69STwEFEKK59LouLtydygpAFaCaI,13935
+transformers/models/qwen2/tokenization_qwen2_fast.py,sha256=ECWjuGUmKDvYakR_D-LZkdCXdbMtP9zCM8nkR7BhEEk,5210
+transformers/models/qwen2_5_omni/__init__.py,sha256=YEDAlOoWmhkZ4L6lxmlVqVhe5A0P6aVSJNSziEFSN4E,1071
+transformers/models/qwen2_5_omni/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen2_5_omni/__pycache__/configuration_qwen2_5_omni.cpython-310.pyc,,
+transformers/models/qwen2_5_omni/__pycache__/modeling_qwen2_5_omni.cpython-310.pyc,,
+transformers/models/qwen2_5_omni/__pycache__/modular_qwen2_5_omni.cpython-310.pyc,,
+transformers/models/qwen2_5_omni/__pycache__/processing_qwen2_5_omni.cpython-310.pyc,,
+transformers/models/qwen2_5_omni/configuration_qwen2_5_omni.py,sha256=PY7Uz7j6NGv4jo6FMdRkQrCc0H-VxNXrmEZpwEaP-xU,52790
+transformers/models/qwen2_5_omni/modeling_qwen2_5_omni.py,sha256=6UX1viM-WVRi0pdUiogADnkSOQ97OzbAUuaplMvYCIk,177153
+transformers/models/qwen2_5_omni/modular_qwen2_5_omni.py,sha256=FL-pBnVFhZs4S-I26m8GVa7285JnCbGbcJnzeeaJRYM,191014
+transformers/models/qwen2_5_omni/processing_qwen2_5_omni.py,sha256=ou7RLPGf6EsyIdbTWmk_-QWf4bzhTlMIcVG7WgmsefA,17058
+transformers/models/qwen2_5_vl/__init__.py,sha256=8-dsgLIeeE3n90n6F0XOu-tBZ-80Wotz89pjZi5GqjQ,1065
+transformers/models/qwen2_5_vl/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen2_5_vl/__pycache__/configuration_qwen2_5_vl.cpython-310.pyc,,
+transformers/models/qwen2_5_vl/__pycache__/modeling_qwen2_5_vl.cpython-310.pyc,,
+transformers/models/qwen2_5_vl/__pycache__/modular_qwen2_5_vl.cpython-310.pyc,,
+transformers/models/qwen2_5_vl/__pycache__/processing_qwen2_5_vl.cpython-310.pyc,,
+transformers/models/qwen2_5_vl/configuration_qwen2_5_vl.py,sha256=dLuPdCvod3_PeSHP0UWa3BOkyYm-uStjyDnSLhzRT3U,17154
+transformers/models/qwen2_5_vl/modeling_qwen2_5_vl.py,sha256=rONP_juYNHZlugWz4mCiQ3DpyPZvAhD_C8QRAOHICH8,82912
+transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py,sha256=OyanycKNuaWbjjvV6bZrNRZgsl5UgN95htc7oXCrqko,49489
+transformers/models/qwen2_5_vl/processing_qwen2_5_vl.py,sha256=Ppn5MDz7U_P1eVbXJmqeWzDvc2KEZ53p9OmqPWeoaIY,14887
+transformers/models/qwen2_audio/__init__.py,sha256=KaUmP3FK3GdeWvbunzyp1QjBki0USS4E80NlvhaJ3D8,1045
+transformers/models/qwen2_audio/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen2_audio/__pycache__/configuration_qwen2_audio.cpython-310.pyc,,
+transformers/models/qwen2_audio/__pycache__/modeling_qwen2_audio.cpython-310.pyc,,
+transformers/models/qwen2_audio/__pycache__/processing_qwen2_audio.cpython-310.pyc,,
+transformers/models/qwen2_audio/configuration_qwen2_audio.py,sha256=U37sA7O8GvbrlFOwXgBSvqu28Kz2uKJORqjthqH8UnE,8673
+transformers/models/qwen2_audio/modeling_qwen2_audio.py,sha256=-gMWHKbcAT5rILYmNVypl9kkWEiKOVYKRY6waW6poUQ,41729
+transformers/models/qwen2_audio/processing_qwen2_audio.py,sha256=qPq76lbCyYExr6yYfsvWRTOwsSkRPkTJFz-5NzX78qQ,11312
+transformers/models/qwen2_moe/__init__.py,sha256=TZM20WtUr1UyV-hDDgq5B-qFT4aUulMpjWwSUNdUs2w,999
+transformers/models/qwen2_moe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen2_moe/__pycache__/configuration_qwen2_moe.cpython-310.pyc,,
+transformers/models/qwen2_moe/__pycache__/modeling_qwen2_moe.cpython-310.pyc,,
+transformers/models/qwen2_moe/configuration_qwen2_moe.py,sha256=3BBfpz3Pu3DuaCuTtWaFdY_JK5QrLVWrW-Ri-Ky205I,13228
+transformers/models/qwen2_moe/modeling_qwen2_moe.py,sha256=bTQH5n2UJ6D3Qqn7c808oUiQvieLhtMzFPo-Vz18GfQ,55183
+transformers/models/qwen2_vl/__init__.py,sha256=MtNDD6sEQws-WTLwPxUL5UNd-UyDPrDh8yWzIAsRp-U,1131
+transformers/models/qwen2_vl/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen2_vl/__pycache__/configuration_qwen2_vl.cpython-310.pyc,,
+transformers/models/qwen2_vl/__pycache__/image_processing_qwen2_vl.cpython-310.pyc,,
+transformers/models/qwen2_vl/__pycache__/image_processing_qwen2_vl_fast.cpython-310.pyc,,
+transformers/models/qwen2_vl/__pycache__/modeling_qwen2_vl.cpython-310.pyc,,
+transformers/models/qwen2_vl/__pycache__/processing_qwen2_vl.cpython-310.pyc,,
+transformers/models/qwen2_vl/__pycache__/video_processing_qwen2_vl.cpython-310.pyc,,
+transformers/models/qwen2_vl/configuration_qwen2_vl.py,sha256=S6qKbyCE2CQNczuj7XM5NutobLWJe7bPlLvF10U_YyI,15808
+transformers/models/qwen2_vl/image_processing_qwen2_vl.py,sha256=25RKT2XWbG_oxN7-vAz2ieKq0EXbqcVJWkT8YrGXnGg,26371
+transformers/models/qwen2_vl/image_processing_qwen2_vl_fast.py,sha256=osr_qLgfKhrzwfZqHJPEsv17Mj8vqW56ER4_3NTb8NA,12987
+transformers/models/qwen2_vl/modeling_qwen2_vl.py,sha256=jIWHRm24dcTwlCcxryCtEkiENBFRXGa7_ZTkIXHWx4w,74875
+transformers/models/qwen2_vl/processing_qwen2_vl.py,sha256=bRfdNybKryna-m5M-ERS4ygEFSE5qMtM5uVKNoZpz9o,12781
+transformers/models/qwen2_vl/video_processing_qwen2_vl.py,sha256=ZxgRIPQtrbQV86tbLFB1ZwNSj1XgWudTiAzFvSR62jQ,14417
+transformers/models/qwen3/__init__.py,sha256=5JU8uO9x0AmJ-YjY36MxtbMKT_B38dLJkrnAwLyjcTY,1014
+transformers/models/qwen3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen3/__pycache__/configuration_qwen3.cpython-310.pyc,,
+transformers/models/qwen3/__pycache__/modeling_qwen3.cpython-310.pyc,,
+transformers/models/qwen3/__pycache__/modular_qwen3.cpython-310.pyc,,
+transformers/models/qwen3/configuration_qwen3.py,sha256=Er_c6Ruk-DaiVHVe8-h2Z49BgYtejJuSMsNuu1NFYyA,11786
+transformers/models/qwen3/modeling_qwen3.py,sha256=S5XDcf0m1AxpCD2rNqwer9jPgrQVoLuCcnUJfFrSMFs,23067
+transformers/models/qwen3/modular_qwen3.py,sha256=WA_tIiC8UOyrxynwkbPQl-a8zRTd6bPbVkD5jK9irVs,6199
+transformers/models/qwen3_moe/__init__.py,sha256=q5WfIniJecmOju3Lhy277H3Puu7viwc9vUhUWen3UZY,999
+transformers/models/qwen3_moe/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/qwen3_moe/__pycache__/configuration_qwen3_moe.cpython-310.pyc,,
+transformers/models/qwen3_moe/__pycache__/modeling_qwen3_moe.cpython-310.pyc,,
+transformers/models/qwen3_moe/__pycache__/modular_qwen3_moe.cpython-310.pyc,,
+transformers/models/qwen3_moe/configuration_qwen3_moe.py,sha256=DQzCSiwo1SfPrEUr_wJV14N8qM7iVAIuhGDIt7BZPHw,12862
+transformers/models/qwen3_moe/modeling_qwen3_moe.py,sha256=1aIdBl_4MJTWF2Bs4NtbtDvUZB98EzTQyx9TL3oK-34,32177
+transformers/models/qwen3_moe/modular_qwen3_moe.py,sha256=miRKJO5dv1lYBVJGTCfkHw0O5FgmJvlljlSP013MzOQ,12135
+transformers/models/rag/__init__.py,sha256=89sLlT4QJ96h0U-X6FmTdfSNJ8NjDjTpqyI1yK0L1Cw,1091
+transformers/models/rag/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/rag/__pycache__/configuration_rag.cpython-310.pyc,,
+transformers/models/rag/__pycache__/modeling_rag.cpython-310.pyc,,
+transformers/models/rag/__pycache__/modeling_tf_rag.cpython-310.pyc,,
+transformers/models/rag/__pycache__/retrieval_rag.cpython-310.pyc,,
+transformers/models/rag/__pycache__/tokenization_rag.cpython-310.pyc,,
+transformers/models/rag/configuration_rag.py,sha256=dFbQO0qhT-mKYoTEmZAXlpwHSHaE4CVWNGcY7D7_yGo,8523
+transformers/models/rag/modeling_rag.py,sha256=8WVKQAPKRgYuSvqWVovbjL-9UpSpFTjz257hxfirIkE,89253
+transformers/models/rag/modeling_tf_rag.py,sha256=bVwrivZEwtaAeuegzXIPoCC6sWcYuzYB4LGIiUaDLkQ,89318
+transformers/models/rag/retrieval_rag.py,sha256=fadEhEpbmWHBchZmvmpyNK1GEYqAqbq0fbXw_TuR06E,30164
+transformers/models/rag/tokenization_rag.py,sha256=5UVTej-039v54SV8nC9StpNMSFMIxPCqo0srnrVsnKA,4610
+transformers/models/recurrent_gemma/__init__.py,sha256=i86Cydx-eAdwsVMjNc0yG9hGxe_amyfAdvF5Eg-UCGM,1011
+transformers/models/recurrent_gemma/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/recurrent_gemma/__pycache__/configuration_recurrent_gemma.cpython-310.pyc,,
+transformers/models/recurrent_gemma/__pycache__/modeling_recurrent_gemma.cpython-310.pyc,,
+transformers/models/recurrent_gemma/configuration_recurrent_gemma.py,sha256=w0mD1rnokEkBuvDNCW0mMJlO0DsF0TuG2JyJSmdqGmI,7750
+transformers/models/recurrent_gemma/modeling_recurrent_gemma.py,sha256=HW7PamPnfQMk5bIpn0vtV1gh27h8GwfOx8Ey02UjRuw,35910
+transformers/models/reformer/__init__.py,sha256=zjiMjHIRPssQ8pVa4fQ0zMCCn0ee_mtJt6wc9J23QYQ,1084
+transformers/models/reformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/reformer/__pycache__/configuration_reformer.cpython-310.pyc,,
+transformers/models/reformer/__pycache__/modeling_reformer.cpython-310.pyc,,
+transformers/models/reformer/__pycache__/tokenization_reformer.cpython-310.pyc,,
+transformers/models/reformer/__pycache__/tokenization_reformer_fast.cpython-310.pyc,,
+transformers/models/reformer/configuration_reformer.py,sha256=MnTplogKNnkWOIGQHLRx5qmrZOBqIqXfeyLzZPy89IA,13196
+transformers/models/reformer/modeling_reformer.py,sha256=drguJlSz60BJX8GGRcIyulWFutuCPRA7pC4l7YCDEj4,117834
+transformers/models/reformer/tokenization_reformer.py,sha256=B5EhgmnvgvW8NiLWDq198Mh7IqUmnDYVUKoh0ECgbD4,6823
+transformers/models/reformer/tokenization_reformer_fast.py,sha256=Ow1TJe2MIatlbk0fYAfAZySEfPfWUpaAahzJvDrnAMQ,4137
+transformers/models/regnet/__init__.py,sha256=X_FU3wnZJ5KkCmRi4EyHk6ZUm_f0--YyyTS8lrknS9Y,1071
+transformers/models/regnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/regnet/__pycache__/configuration_regnet.cpython-310.pyc,,
+transformers/models/regnet/__pycache__/modeling_flax_regnet.cpython-310.pyc,,
+transformers/models/regnet/__pycache__/modeling_regnet.cpython-310.pyc,,
+transformers/models/regnet/__pycache__/modeling_tf_regnet.cpython-310.pyc,,
+transformers/models/regnet/configuration_regnet.py,sha256=TgYggQiYssFjcXjzLIe5ZDVrMxP4qQl1ZpmvZhLi2Ig,3974
+transformers/models/regnet/modeling_flax_regnet.py,sha256=ov6SXyXtkFXwNSC9quWte1vMl6AZkeJ49hlqp0l171k,28519
+transformers/models/regnet/modeling_regnet.py,sha256=DPNqyRFpYOaHykOKATThRS91g12G9jxoW_xxO2C02EU,15280
+transformers/models/regnet/modeling_tf_regnet.py,sha256=Rzy-36Qzqu1wRp_qYZAfEj-5sZycNEgWQE210EBGmD8,24394
+transformers/models/rembert/__init__.py,sha256=Gif9TX1kvmD5iVWqsViSjxKYIDhR3FiBfp_QfA7U7i4,1119
+transformers/models/rembert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/rembert/__pycache__/configuration_rembert.cpython-310.pyc,,
+transformers/models/rembert/__pycache__/modeling_rembert.cpython-310.pyc,,
+transformers/models/rembert/__pycache__/modeling_tf_rembert.cpython-310.pyc,,
+transformers/models/rembert/__pycache__/tokenization_rembert.cpython-310.pyc,,
+transformers/models/rembert/__pycache__/tokenization_rembert_fast.cpython-310.pyc,,
+transformers/models/rembert/configuration_rembert.py,sha256=wSBV6VLEvcKMvP2PZw6KgaqelYzyIWhK_NZDV8kzX_8,7300
+transformers/models/rembert/modeling_rembert.py,sha256=zwDvC2g0BVlw74QgS1Zw3mt6oW6uWQ7PYUREe6WqaAI,58441
+transformers/models/rembert/modeling_tf_rembert.py,sha256=ChyRVbTldGrTuWayyNLjm91mS4lOK25Q4SAuNTF5Fzo,77771
+transformers/models/rembert/tokenization_rembert.py,sha256=K_x4GpkaWMCipug1ojjPMKyiPMk-JwJSXBfXiLYIWm0,9566
+transformers/models/rembert/tokenization_rembert_fast.py,sha256=7T60RZ34azXx0zfaxE8Qh-4IJOYx7M-j59QDQO5BDNE,8747
+transformers/models/resnet/__init__.py,sha256=NCgMoczDbEI_XDWkWNWKIKGPYeohOC95f0o2X-Vh2vA,1071
+transformers/models/resnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/resnet/__pycache__/configuration_resnet.cpython-310.pyc,,
+transformers/models/resnet/__pycache__/modeling_flax_resnet.cpython-310.pyc,,
+transformers/models/resnet/__pycache__/modeling_resnet.cpython-310.pyc,,
+transformers/models/resnet/__pycache__/modeling_tf_resnet.cpython-310.pyc,,
+transformers/models/resnet/configuration_resnet.py,sha256=RUWWvz_KwilBJVOlaY1cK0CN078VPXPwzlOs2jZmd6I,6076
+transformers/models/resnet/modeling_flax_resnet.py,sha256=2r5isBIaKQIcGeDKWFtwbsgatGZDTXu0rpEKVbeT5xE,24708
+transformers/models/resnet/modeling_resnet.py,sha256=epK1s0cVIzLLHQAXnrc_aiXlffH2jmYEnH5JBtU2mN0,17234
+transformers/models/resnet/modeling_tf_resnet.py,sha256=FS0VNZqUMq7sXABV-GE3stcUpYd2bVUGVNh2xWLJdro,23774
+transformers/models/roberta/__init__.py,sha256=p1qYu_9qpmxsxMfXuoxK-VrmRQMEshwiM8Ekoij2J1M,1160
+transformers/models/roberta/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/roberta/__pycache__/configuration_roberta.cpython-310.pyc,,
+transformers/models/roberta/__pycache__/modeling_flax_roberta.cpython-310.pyc,,
+transformers/models/roberta/__pycache__/modeling_roberta.cpython-310.pyc,,
+transformers/models/roberta/__pycache__/modeling_tf_roberta.cpython-310.pyc,,
+transformers/models/roberta/__pycache__/tokenization_roberta.cpython-310.pyc,,
+transformers/models/roberta/__pycache__/tokenization_roberta_fast.cpython-310.pyc,,
+transformers/models/roberta/configuration_roberta.py,sha256=BYTjf1lo0Mk9xYqZjNHsZSlxPG7zJPcFl8ttr6LK8Ew,7336
+transformers/models/roberta/modeling_flax_roberta.py,sha256=hW7TxugQammDOpLCTZW3X3TjcJuy81AIdDztOcxzs-A,57284
+transformers/models/roberta/modeling_roberta.py,sha256=J4E-RLOP9Op7eAIefyUs_Mw-aSmt5yQp_NLZisqyMa0,70908
+transformers/models/roberta/modeling_tf_roberta.py,sha256=5wdoYO0aaDfd5u6iwEYjSLuhp3Mti8jODh9OdXWRQt0,79951
+transformers/models/roberta/tokenization_roberta.py,sha256=FtKax5F5Cg4uJR7aWs62l9Tp0uDcVLW2dZKfrYfarrg,16469
+transformers/models/roberta/tokenization_roberta_fast.py,sha256=JYe2lmZugU3J7PEKn_SegaFURSAPLUejM6ckH_SqWmY,10978
+transformers/models/roberta_prelayernorm/__init__.py,sha256=QsVJJaoujnLHyCgwSsz53MV88vI183tTGJNXHDCHCAc,1127
+transformers/models/roberta_prelayernorm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/roberta_prelayernorm/__pycache__/configuration_roberta_prelayernorm.cpython-310.pyc,,
+transformers/models/roberta_prelayernorm/__pycache__/modeling_flax_roberta_prelayernorm.cpython-310.pyc,,
+transformers/models/roberta_prelayernorm/__pycache__/modeling_roberta_prelayernorm.cpython-310.pyc,,
+transformers/models/roberta_prelayernorm/__pycache__/modeling_tf_roberta_prelayernorm.cpython-310.pyc,,
+transformers/models/roberta_prelayernorm/configuration_roberta_prelayernorm.py,sha256=YAxqjJmTFys2-TCyo4-B8Y1mm-kF2ExOqmxiSw5i4C4,7908
+transformers/models/roberta_prelayernorm/modeling_flax_roberta_prelayernorm.py,sha256=fQzWW2x-4ffASPs5V3shK4ctvdvmBlKrqmBeP6mUsEM,60941
+transformers/models/roberta_prelayernorm/modeling_roberta_prelayernorm.py,sha256=KIjNzhAGQi3HxFN25Q_BOjDbWW_dm2t1c0NZhd9_NxI,66846
+transformers/models/roberta_prelayernorm/modeling_tf_roberta_prelayernorm.py,sha256=Cv6jETaFoVnYC4rbko5lk3KL11Q7CuWMqaKJlCufNqs,83224
+transformers/models/roc_bert/__init__.py,sha256=4CveMGU-dY3nV4E6x-Xpb1jicRniwrPuSOrY8-SHIUI,1038
+transformers/models/roc_bert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/roc_bert/__pycache__/configuration_roc_bert.cpython-310.pyc,,
+transformers/models/roc_bert/__pycache__/modeling_roc_bert.cpython-310.pyc,,
+transformers/models/roc_bert/__pycache__/tokenization_roc_bert.cpython-310.pyc,,
+transformers/models/roc_bert/configuration_roc_bert.py,sha256=3w3t43X0ZkziGeftmlFg8yozWj57Pn5kynhbxXUkNMk,8544
+transformers/models/roc_bert/modeling_roc_bert.py,sha256=TyTTc-1EmyuStrMhG0WZwHXJt_VcmcKbgiIrLHAePB8,89017
+transformers/models/roc_bert/tokenization_roc_bert.py,sha256=Zo8YLFlTCOtUMFXU-et41Ktw_S61n9XRHn7DulIJ4tQ,49487
+transformers/models/roformer/__init__.py,sha256=v1CIjowYMq6aN-V9gyl-RWlMi_uQQxopuvEv76geFqk,1166
+transformers/models/roformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/roformer/__pycache__/configuration_roformer.cpython-310.pyc,,
+transformers/models/roformer/__pycache__/modeling_flax_roformer.cpython-310.pyc,,
+transformers/models/roformer/__pycache__/modeling_roformer.cpython-310.pyc,,
+transformers/models/roformer/__pycache__/modeling_tf_roformer.cpython-310.pyc,,
+transformers/models/roformer/__pycache__/tokenization_roformer.cpython-310.pyc,,
+transformers/models/roformer/__pycache__/tokenization_roformer_fast.cpython-310.pyc,,
+transformers/models/roformer/__pycache__/tokenization_utils.cpython-310.pyc,,
+transformers/models/roformer/configuration_roformer.py,sha256=22jMpd4-nBlP7kJAlZADxFmr76zor7BRBd8orUW23go,6865
+transformers/models/roformer/modeling_flax_roformer.py,sha256=RwabkHxAdW4jApBUbJwjXESKCg-xcez9uNBAzya_xP4,39383
+transformers/models/roformer/modeling_roformer.py,sha256=QVwG_ScZ069mvcN3qds37w7vvTx9-7SDvQbmT_2k2Qc,65063
+transformers/models/roformer/modeling_tf_roformer.py,sha256=wevLVlaGrv6P6sP8zY3Mpg9fUsZRqb-PLRdOAT_OpWo,66049
+transformers/models/roformer/tokenization_roformer.py,sha256=Dlj00LiDLK0PSbGRlTOVpTXhYFj9yBvMqFqaEiNQSwk,20858
+transformers/models/roformer/tokenization_roformer_fast.py,sha256=BGhYYclZeX8qFSf0XOvATd9gH8rqlIqW4QCQq-umMXY,5584
+transformers/models/roformer/tokenization_utils.py,sha256=v_Qvq0uBuHpE43oIM64g9kTZcy8BD9oHhOR_ketIyIg,2625
+transformers/models/rt_detr/__init__.py,sha256=c9Y3NeKQwBP46tyFF99kjqTngoIWhLMq7XvzEJOfLaY,1181
+transformers/models/rt_detr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/rt_detr/__pycache__/configuration_rt_detr.cpython-310.pyc,,
+transformers/models/rt_detr/__pycache__/configuration_rt_detr_resnet.cpython-310.pyc,,
+transformers/models/rt_detr/__pycache__/image_processing_rt_detr.cpython-310.pyc,,
+transformers/models/rt_detr/__pycache__/image_processing_rt_detr_fast.cpython-310.pyc,,
+transformers/models/rt_detr/__pycache__/modeling_rt_detr.cpython-310.pyc,,
+transformers/models/rt_detr/__pycache__/modeling_rt_detr_resnet.cpython-310.pyc,,
+transformers/models/rt_detr/__pycache__/modular_rt_detr.cpython-310.pyc,,
+transformers/models/rt_detr/configuration_rt_detr.py,sha256=Khno06NPBiP_2Nq7_uy569OoiR6sb7vdxJ1jMVOtkCA,18295
+transformers/models/rt_detr/configuration_rt_detr_resnet.py,sha256=kBbmglFZkq0cqLsz1VZwTXVLHQnjnLjtFbkfMMbVOmM,5557
+transformers/models/rt_detr/image_processing_rt_detr.py,sha256=eqVRFSxM8sBKw9BWZVs8Uk5aMw1U5gQgdnIg4ah2mP4,51686
+transformers/models/rt_detr/image_processing_rt_detr_fast.py,sha256=4-WHF8JUYGagYGC4wMZGK0JM0PpcVy-5RTas1fDwMLc,26134
+transformers/models/rt_detr/modeling_rt_detr.py,sha256=W7rxYPOAwKzIAU1b1g0FLIW992bowryp1a4HOzYamnw,95382
+transformers/models/rt_detr/modeling_rt_detr_resnet.py,sha256=xlET8ddRbxBzLz2uH4ks_9wuqNPbpj-uanOd0gOp9Dg,15149
+transformers/models/rt_detr/modular_rt_detr.py,sha256=Hwcu73O5HfMSCc1W0lHunLJp2p33QgqqM_S2Qda7qmc,15110
+transformers/models/rt_detr_v2/__init__.py,sha256=7RL5U-hsGt3HQZ5SuWn8iZY_L166EYswBvaQXFRkzRc,1003
+transformers/models/rt_detr_v2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/rt_detr_v2/__pycache__/configuration_rt_detr_v2.cpython-310.pyc,,
+transformers/models/rt_detr_v2/__pycache__/modeling_rt_detr_v2.cpython-310.pyc,,
+transformers/models/rt_detr_v2/__pycache__/modular_rt_detr_v2.cpython-310.pyc,,
+transformers/models/rt_detr_v2/configuration_rt_detr_v2.py,sha256=IjGQgzggWMu4uGoPEn8DHMc00lGJCdTcu2fvZ6NamQs,19837
+transformers/models/rt_detr_v2/modeling_rt_detr_v2.py,sha256=mYzHhnFEJzXvKYhNty5N5ZuS2wKluehRD7PR-ocUkT4,96324
+transformers/models/rt_detr_v2/modular_rt_detr_v2.py,sha256=oFEBxGHsltolRP9fSFLRb_4j2-N22fXAbtwPP8SL8jw,29745
+transformers/models/rwkv/__init__.py,sha256=HAiwEvW1j_xuHj_PbmN25srY9RtA1gLmN_0RWvAyG78,989
+transformers/models/rwkv/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/rwkv/__pycache__/configuration_rwkv.cpython-310.pyc,,
+transformers/models/rwkv/__pycache__/modeling_rwkv.cpython-310.pyc,,
+transformers/models/rwkv/configuration_rwkv.py,sha256=0hwiEhaLNCekxOiYD_D-e95ftq7_aazx9ImRtf0ydWc,5204
+transformers/models/rwkv/modeling_rwkv.py,sha256=G4ssmavN9yaF8dhGtmjztZ_IOXibdndY-uDXLocOqxg,33436
+transformers/models/sam/__init__.py,sha256=ilUO6W284DgX2BijkzdGXaw-OZsSrEo-qjZqiidfOEY,1141
+transformers/models/sam/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/sam/__pycache__/configuration_sam.cpython-310.pyc,,
+transformers/models/sam/__pycache__/image_processing_sam.cpython-310.pyc,,
+transformers/models/sam/__pycache__/image_processing_sam_fast.cpython-310.pyc,,
+transformers/models/sam/__pycache__/modeling_sam.cpython-310.pyc,,
+transformers/models/sam/__pycache__/modeling_tf_sam.cpython-310.pyc,,
+transformers/models/sam/__pycache__/processing_sam.cpython-310.pyc,,
+transformers/models/sam/configuration_sam.py,sha256=q6C10OyYdHicWRfuaudnl_5K9I3LH8nPQj_1wXPGegw,14716
+transformers/models/sam/image_processing_sam.py,sha256=f9pyhLro6KoxT0c9iLRvyrLhVdf5vzy4HeB_okVm-lI,68043
+transformers/models/sam/image_processing_sam_fast.py,sha256=49U3QNVsLMwlJnNVwqBYyh66EHmpIInv_f1IT1xGIDM,34821
+transformers/models/sam/modeling_sam.py,sha256=T2Y55KBS7SeR6jFy863fqlmGBgh09RPoAuIt5fVpatE,61685
+transformers/models/sam/modeling_tf_sam.py,sha256=oUYzLUHdtOgEcoS6wzkV9MDmU12UwXwTGOiAQiV-2WA,77733
+transformers/models/sam/processing_sam.py,sha256=Z-k0KvcBIa038ywfB96GIpKpViO4Px2o2Kb9Nc9i5RU,12120
+transformers/models/sam2/__init__.py,sha256=H7LrRCnUmUZ9fj5C_p_Mp8xNB5Zdtoo1S__LcYcs_i4,1070
+transformers/models/sam2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/sam2/__pycache__/configuration_sam2.cpython-310.pyc,,
+transformers/models/sam2/__pycache__/image_processing_sam2_fast.cpython-310.pyc,,
+transformers/models/sam2/__pycache__/modeling_sam2.cpython-310.pyc,,
+transformers/models/sam2/__pycache__/modular_sam2.cpython-310.pyc,,
+transformers/models/sam2/__pycache__/processing_sam2.cpython-310.pyc,,
+transformers/models/sam2/configuration_sam2.py,sha256=K1inKhLRgSPRgUxd7wGNo7L_W8zpRW0PKtEw5v2stlg,20803
+transformers/models/sam2/image_processing_sam2_fast.py,sha256=qmClWEJm70vNTu2u9qPZ-iVO_q0NtuOiogHw57O3Ul0,30908
+transformers/models/sam2/modeling_sam2.py,sha256=IX3QzvGE6CnmYNM_NIFXZqAuba4uylhXsFAN6dIvr8o,72725
+transformers/models/sam2/modular_sam2.py,sha256=bSSNV04c89WkgyAV-D8X-zj266hc8YMLuRIanM3TAqI,64580
+transformers/models/sam2/processing_sam2.py,sha256=VWY4yVdgTAakirAeLajvZPKdC786IAOvBxgvD1UiTl8,23019
+transformers/models/sam2_video/__init__.py,sha256=WFP70wbKsoPQuuR0Aq6sMpFZ9m2cQJwNgdCpngg4C1o,1089
+transformers/models/sam2_video/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/sam2_video/__pycache__/configuration_sam2_video.cpython-310.pyc,,
+transformers/models/sam2_video/__pycache__/modeling_sam2_video.cpython-310.pyc,,
+transformers/models/sam2_video/__pycache__/modular_sam2_video.cpython-310.pyc,,
+transformers/models/sam2_video/__pycache__/processing_sam2_video.cpython-310.pyc,,
+transformers/models/sam2_video/__pycache__/video_processing_sam2_video.cpython-310.pyc,,
+transformers/models/sam2_video/configuration_sam2_video.py,sha256=uJqHjVF4NnLwoS2sPkZ5bFsGBPkPFQhQldQ_uGxgpCU,20582
+transformers/models/sam2_video/modeling_sam2_video.py,sha256=sthFgdT7-h-ckK-hXdNSg51N4s4rTbUT9f2J7PM2wkw,122545
+transformers/models/sam2_video/modular_sam2_video.py,sha256=znR9iXdwQLywoF49Fl9-CTNWXCiD8QEuz6gzq5AWbJk,115106
+transformers/models/sam2_video/processing_sam2_video.py,sha256=Vu9G_JJ65Wvi4DYR7wRbjlu89s-v4J8F6BG1lCVRy1w,38301
+transformers/models/sam2_video/video_processing_sam2_video.py,sha256=EEQCorsolP6-iTdYAOALjfl4yzJjiXTFxNttdQPdtfA,5147
+transformers/models/sam_hq/__init__.py,sha256=DtfMcRDroMaiZ9FKrgymx4rCyGuP5r1dxr-wzjS0T0Q,1029
+transformers/models/sam_hq/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/sam_hq/__pycache__/configuration_sam_hq.cpython-310.pyc,,
+transformers/models/sam_hq/__pycache__/modeling_sam_hq.cpython-310.pyc,,
+transformers/models/sam_hq/__pycache__/modular_sam_hq.cpython-310.pyc,,
+transformers/models/sam_hq/__pycache__/processing_samhq.cpython-310.pyc,,
+transformers/models/sam_hq/configuration_sam_hq.py,sha256=U3nPcw9lh2M6MdBMe7rK_xniKVPVoRKzgqvPgU-7kzo,14840
+transformers/models/sam_hq/modeling_sam_hq.py,sha256=KwXyTAbgl00P6L3FPNmighvVhzp-GkQaY_oqCQWKHgo,69268
+transformers/models/sam_hq/modular_sam_hq.py,sha256=TjZtgBHN5IHnLjHdCv5GeoafFGSEwnG8-6ZMTM5EKO8,31579
+transformers/models/sam_hq/processing_samhq.py,sha256=5audIn1A3v9gU6zM90o8oLF5YM_PA3QWR-3aFReFcFA,12020
+transformers/models/seamless_m4t/__init__.py,sha256=Y5c_W1E83fh8ToTMqF4NcReXzKZiTDv3A4ePoNUxXDg,1194
+transformers/models/seamless_m4t/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/seamless_m4t/__pycache__/configuration_seamless_m4t.cpython-310.pyc,,
+transformers/models/seamless_m4t/__pycache__/feature_extraction_seamless_m4t.cpython-310.pyc,,
+transformers/models/seamless_m4t/__pycache__/modeling_seamless_m4t.cpython-310.pyc,,
+transformers/models/seamless_m4t/__pycache__/processing_seamless_m4t.cpython-310.pyc,,
+transformers/models/seamless_m4t/__pycache__/tokenization_seamless_m4t.cpython-310.pyc,,
+transformers/models/seamless_m4t/__pycache__/tokenization_seamless_m4t_fast.cpython-310.pyc,,
+transformers/models/seamless_m4t/configuration_seamless_m4t.py,sha256=zvCh7r-KOILwOlujAaJLtv1-Z7B8XgZEfxqYuBMjGK0,23521
+transformers/models/seamless_m4t/feature_extraction_seamless_m4t.py,sha256=VeMODyxbmdHC7O2gb_VOzXO8_cz7gktCWEYIVPmscWQ,13628
+transformers/models/seamless_m4t/modeling_seamless_m4t.py,sha256=F3FRo3T8U_Ydqa02C2dOqcY5v6xJq8Epmqr5UK1fqP4,187175
+transformers/models/seamless_m4t/processing_seamless_m4t.py,sha256=lItidxf1hX6fvFqRimPF07KKHBJz_peTpqvuGi2IRTE,5022
+transformers/models/seamless_m4t/tokenization_seamless_m4t.py,sha256=vRb1fQgr6HzLT5rnhE7dDqAuC5_yT5DCIftiBSZIIak,26076
+transformers/models/seamless_m4t/tokenization_seamless_m4t_fast.py,sha256=NC5GbGQnDiLf9NB6-XQ4DqJjLFQWJ7_0yJXoDthY-z0,19774
+transformers/models/seamless_m4t_v2/__init__.py,sha256=mMY04PBMrOwTIQLq01RHqZjssvrSYl3UDhP5Y5vFifs,1011
+transformers/models/seamless_m4t_v2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/seamless_m4t_v2/__pycache__/configuration_seamless_m4t_v2.cpython-310.pyc,,
+transformers/models/seamless_m4t_v2/__pycache__/modeling_seamless_m4t_v2.cpython-310.pyc,,
+transformers/models/seamless_m4t_v2/configuration_seamless_m4t_v2.py,sha256=ihF9DjqhoOojebAUTijxbQuLNs0nEqJBi9umyR-gHgA,24388
+transformers/models/seamless_m4t_v2/modeling_seamless_m4t_v2.py,sha256=ZuBotmx9J4RSMMmjGuwx6fZDfWKRNGiHpSDisXDf6GE,206325
+transformers/models/seed_oss/__init__.py,sha256=ukqpfG-W3jFJvA9UiL5bI_2jl_CTZFynUL0Tq9WD63M,1025
+transformers/models/seed_oss/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/seed_oss/__pycache__/configuration_seed_oss.cpython-310.pyc,,
+transformers/models/seed_oss/__pycache__/modeling_seed_oss.cpython-310.pyc,,
+transformers/models/seed_oss/__pycache__/modular_seed_oss.cpython-310.pyc,,
+transformers/models/seed_oss/configuration_seed_oss.py,sha256=V_XjuaOrTU7hyAMvrsAQg-Vvmm3exGr-IX9uPgELdH0,12107
+transformers/models/seed_oss/modeling_seed_oss.py,sha256=1HRueKix0pbNLxdZjm_ascQSH8yWMYMERekBnWQYxPc,22009
+transformers/models/seed_oss/modular_seed_oss.py,sha256=kaPESWCrk1VEjMfsy6BoZRDu_JOVs5WwkRZh4gkPwMA,7688
+transformers/models/segformer/__init__.py,sha256=KusPvx7i3IW86Z3RjiVjo3oNu-SsqwmkifgegRkSzKs,1185
+transformers/models/segformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/segformer/__pycache__/configuration_segformer.cpython-310.pyc,,
+transformers/models/segformer/__pycache__/feature_extraction_segformer.cpython-310.pyc,,
+transformers/models/segformer/__pycache__/image_processing_segformer.cpython-310.pyc,,
+transformers/models/segformer/__pycache__/image_processing_segformer_fast.cpython-310.pyc,,
+transformers/models/segformer/__pycache__/modeling_segformer.cpython-310.pyc,,
+transformers/models/segformer/__pycache__/modeling_tf_segformer.cpython-310.pyc,,
+transformers/models/segformer/__pycache__/modular_segformer.cpython-310.pyc,,
+transformers/models/segformer/configuration_segformer.py,sha256=CyvERUX7QyWRo0mG7jwst-3jIqzOyD6YQ2ZdCkoTY_g,7429
+transformers/models/segformer/feature_extraction_segformer.py,sha256=7JHygTUT0pw36WCxl14kgaPvxqNBPFf9AOUuxQKHhlg,1324
+transformers/models/segformer/image_processing_segformer.py,sha256=JnpRUI0bYh5_L9xqJiSrPoqMFhdpYSNAVmdVX_J45uI,22207
+transformers/models/segformer/image_processing_segformer_fast.py,sha256=LrD-_r_U0d61Cmmqgqii9zgRGc8K_xhoAdZIu3SY-Io,10437
+transformers/models/segformer/modeling_segformer.py,sha256=iIYyaC429ZfLaFzpSaupmnhP086pIz-kE-tR5t-9rvQ,32655
+transformers/models/segformer/modeling_tf_segformer.py,sha256=99M87FnHfxDikZXn-2PmCnGiPEcTW4kxQpWC1tTaQw8,43687
+transformers/models/segformer/modular_segformer.py,sha256=K_wQptzu40rQ1gNcSeaaCKIEMrTv44UlGcbA7voCc3w,6177
+transformers/models/seggpt/__init__.py,sha256=RzV8DKCX1lOWGqXv2BlE1R7T4QuEcdYAVy_csccLvEw,1036
+transformers/models/seggpt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/seggpt/__pycache__/configuration_seggpt.cpython-310.pyc,,
+transformers/models/seggpt/__pycache__/image_processing_seggpt.cpython-310.pyc,,
+transformers/models/seggpt/__pycache__/modeling_seggpt.cpython-310.pyc,,
+transformers/models/seggpt/configuration_seggpt.py,sha256=VeHoocblt-EIRF-FO8JkrVGUcBPKbXPWAJMlXRllz44,6492
+transformers/models/seggpt/image_processing_seggpt.py,sha256=9Qa_-JsAuBdo3Jc_0Z_jXKFUn8GOK9v11ossULABnSQ,31475
+transformers/models/seggpt/modeling_seggpt.py,sha256=_1851j2HmzaZJ5P5A-O3HC4vbpIsp6aRO1_-wmOlATg,44680
+transformers/models/sew/__init__.py,sha256=POCF36ZRa_dr7oQhkDU2X17bsZuLoWI5V8DSihqr_vU,987
+transformers/models/sew/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/sew/__pycache__/configuration_sew.cpython-310.pyc,,
+transformers/models/sew/__pycache__/feature_extraction_sew.cpython-310.pyc,,
+transformers/models/sew/__pycache__/modeling_sew.cpython-310.pyc,,
+transformers/models/sew/__pycache__/modular_sew.cpython-310.pyc,,
+transformers/models/sew/configuration_sew.py,sha256=lJIjv2Ktr3PexNd9E8Q2cb3ewzh4W10eCk5M4d-JOyc,14231
+transformers/models/sew/feature_extraction_sew.py,sha256=szQVJwMsEe-9xZxeHiUFb5E-JFHc6gfTQNqwPp_kLiU,1883
+transformers/models/sew/modeling_sew.py,sha256=kYPlJjQM-hfUr9UCgsz1Rk8xlIuItUKvulvo93CA5es,47441
+transformers/models/sew/modular_sew.py,sha256=I_ZREVE3XNh8BMK4LLnu9sGrZPrUzbnSoZzLhOBsQr8,18913
+transformers/models/sew_d/__init__.py,sha256=zE9sw10e_a1d-8-Jsb75z5frCjkFGD0dZMHAXiNgGwk,991
+transformers/models/sew_d/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/sew_d/__pycache__/configuration_sew_d.cpython-310.pyc,,
+transformers/models/sew_d/__pycache__/modeling_sew_d.cpython-310.pyc,,
+transformers/models/sew_d/configuration_sew_d.py,sha256=UXLYoDAIix9cWhSQVuavz4LgbQ2lvCxO5vE_bGsZei0,16191
+transformers/models/sew_d/modeling_sew_d.py,sha256=-LO1nWLrzyhDAQN1zq7nLfCGukkB2B1sm1GJSnA8FsI,69212
+transformers/models/shieldgemma2/__init__.py,sha256=B7eqFJSWi0p49QNvKqUGR8NPyFjQuMdBANevIjTsSxw,1048
+transformers/models/shieldgemma2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/shieldgemma2/__pycache__/configuration_shieldgemma2.cpython-310.pyc,,
+transformers/models/shieldgemma2/__pycache__/modeling_shieldgemma2.cpython-310.pyc,,
+transformers/models/shieldgemma2/__pycache__/processing_shieldgemma2.cpython-310.pyc,,
+transformers/models/shieldgemma2/configuration_shieldgemma2.py,sha256=Cj4MM47fvnQVGqzEXeidaqrkSmz4-i11mYvz6yj4dvU,4805
+transformers/models/shieldgemma2/modeling_shieldgemma2.py,sha256=UrnUYcDjd2nu6G4P8EAwsJKv0dovfYoE-vLhZU3vP2k,6101
+transformers/models/shieldgemma2/processing_shieldgemma2.py,sha256=qIoH1UILQLbqivc-UIQhZcxYU7ih1vwpyuCNqLgBUAQ,7674
+transformers/models/siglip/__init__.py,sha256=CnNqbSQ25tKLz0MGJVmhSXjVyASRDu7v5yjTHWYZ6M4,1160
+transformers/models/siglip/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/siglip/__pycache__/configuration_siglip.cpython-310.pyc,,
+transformers/models/siglip/__pycache__/image_processing_siglip.cpython-310.pyc,,
+transformers/models/siglip/__pycache__/image_processing_siglip_fast.cpython-310.pyc,,
+transformers/models/siglip/__pycache__/modeling_siglip.cpython-310.pyc,,
+transformers/models/siglip/__pycache__/processing_siglip.cpython-310.pyc,,
+transformers/models/siglip/__pycache__/tokenization_siglip.cpython-310.pyc,,
+transformers/models/siglip/configuration_siglip.py,sha256=3GVhImzaW3WCFyQ3IfC-ZM3ZA2qmvA_BEjmZyNOQyfk,11697
+transformers/models/siglip/image_processing_siglip.py,sha256=8W9GVLzJfmTFrCBPQeJjTuvExsUM4-5pq5wPUy850QI,12074
+transformers/models/siglip/image_processing_siglip_fast.py,sha256=3dwic9zjpzgxbCnQC84lUvcDOSnWIlEZrCUJItmi474,1257
+transformers/models/siglip/modeling_siglip.py,sha256=tV2s4iUI3Nqk09w3DB4wKoNbXdTgqDqFgWLI2eCKofE,49380
+transformers/models/siglip/processing_siglip.py,sha256=DooMtNFGtoI1S3-Nq2DYIPReYxFVodqAC62E74YGYz8,6338
+transformers/models/siglip/tokenization_siglip.py,sha256=QXJ1RdlwC6ESO0z3thY-tzXY5JL0VEsMBsWi-OgA4Vg,16047
+transformers/models/siglip2/__init__.py,sha256=dvfEVdLNJzWjugwTPGNp1gfxA6x4ytFLgGtV4Zfhoh4,1126
+transformers/models/siglip2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/siglip2/__pycache__/configuration_siglip2.cpython-310.pyc,,
+transformers/models/siglip2/__pycache__/image_processing_siglip2.cpython-310.pyc,,
+transformers/models/siglip2/__pycache__/image_processing_siglip2_fast.cpython-310.pyc,,
+transformers/models/siglip2/__pycache__/modeling_siglip2.cpython-310.pyc,,
+transformers/models/siglip2/__pycache__/modular_siglip2.cpython-310.pyc,,
+transformers/models/siglip2/__pycache__/processing_siglip2.cpython-310.pyc,,
+transformers/models/siglip2/configuration_siglip2.py,sha256=zs0zqZ9Tog9iwLK6yEN6peJErYCHN5N0iBB11Lp0FpA,12819
+transformers/models/siglip2/image_processing_siglip2.py,sha256=CgxErsXcPSf9OVsc-tXUr85w1l9Qm37gqc_zeo8CgFg,16118
+transformers/models/siglip2/image_processing_siglip2_fast.py,sha256=ZXmKSbmUlhmJUw22JzTKHI7xpZJiRWrBwRN50ez1rGw,6511
+transformers/models/siglip2/modeling_siglip2.py,sha256=jmfyvnAnxPYP-yMbapLbtVL4kooZXpnWFNGD6ULcPWc,54052
+transformers/models/siglip2/modular_siglip2.py,sha256=pQJWyVHTyiAb4_wjoz6KvEpU8_ZiZC0jA8sPe-r4J6c,26863
+transformers/models/siglip2/processing_siglip2.py,sha256=flUsr7lbREq_flWPVohy2F3wFe0o-RftCSa6gaOolvI,7192
+transformers/models/smollm3/__init__.py,sha256=BZA2MiDpGmv2swg1yO14tkgi_SZ0yVg8ndr-PJwY-fI,1000
+transformers/models/smollm3/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/smollm3/__pycache__/configuration_smollm3.cpython-310.pyc,,
+transformers/models/smollm3/__pycache__/modeling_smollm3.cpython-310.pyc,,
+transformers/models/smollm3/__pycache__/modular_smollm3.cpython-310.pyc,,
+transformers/models/smollm3/configuration_smollm3.py,sha256=-WPiKgJnwph8eVAAYFD7qGHljLIeDz7w_lEvTmTI_lo,13350
+transformers/models/smollm3/modeling_smollm3.py,sha256=BoFsQYaadeZtx4RomHx19kNJRQxEyYC3hqILIgQVluw,22491
+transformers/models/smollm3/modular_smollm3.py,sha256=RI-0U4AdCV7V_Vk03OGhQGZZcboY1YgviooYO_RFu1k,16394
+transformers/models/smolvlm/__init__.py,sha256=fE-znTLrbxNe5qkHVgI4xmwFz-paFymZuxTAd2GKkOo,1126
+transformers/models/smolvlm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/smolvlm/__pycache__/configuration_smolvlm.cpython-310.pyc,,
+transformers/models/smolvlm/__pycache__/image_processing_smolvlm.cpython-310.pyc,,
+transformers/models/smolvlm/__pycache__/image_processing_smolvlm_fast.cpython-310.pyc,,
+transformers/models/smolvlm/__pycache__/modeling_smolvlm.cpython-310.pyc,,
+transformers/models/smolvlm/__pycache__/modular_smolvlm.cpython-310.pyc,,
+transformers/models/smolvlm/__pycache__/processing_smolvlm.cpython-310.pyc,,
+transformers/models/smolvlm/__pycache__/video_processing_smolvlm.cpython-310.pyc,,
+transformers/models/smolvlm/configuration_smolvlm.py,sha256=4XHkP6aHHeBOGOoLNn87AuAp5csfYpWo8QKW8TrauYI,9359
+transformers/models/smolvlm/image_processing_smolvlm.py,sha256=y2mQ_j5BVgMByODq8x4eQkxd2e8PEpkvU_HpW0_N-yA,44078
+transformers/models/smolvlm/image_processing_smolvlm_fast.py,sha256=zT8jdeCc-Hwvw9QsJfKMLDwf6oCxkuP_WKQLlx6cFiQ,24026
+transformers/models/smolvlm/modeling_smolvlm.py,sha256=uBA4BwtaSJco_zjid153yb2-L0-oK8pHyIOF-bS5K9o,46236
+transformers/models/smolvlm/modular_smolvlm.py,sha256=zq35OADV4FDEJPG8Lz1RFeP7GfRh5Y2FHNs4YWC3QYs,19046
+transformers/models/smolvlm/processing_smolvlm.py,sha256=lcYo3SlTRROsMaPg52DuuaHOHW-5UMr5F-FEGc8Z5XU,20283
+transformers/models/smolvlm/video_processing_smolvlm.py,sha256=Z6ZNvMGyOyj0fhzfepn2YEWkKQXc6VZXUsnO21Qeg_c,15331
+transformers/models/speech_encoder_decoder/__init__.py,sha256=0MwevN904dCSAb0dvznhDH--q-m3-MzdCtx0B-T5hpk,1081
+transformers/models/speech_encoder_decoder/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/speech_encoder_decoder/__pycache__/configuration_speech_encoder_decoder.cpython-310.pyc,,
+transformers/models/speech_encoder_decoder/__pycache__/modeling_flax_speech_encoder_decoder.cpython-310.pyc,,
+transformers/models/speech_encoder_decoder/__pycache__/modeling_speech_encoder_decoder.cpython-310.pyc,,
+transformers/models/speech_encoder_decoder/configuration_speech_encoder_decoder.py,sha256=2FBAuqwi4KNkbb7chAliDYZ46vYJiIjEwqtSh1oFSKY,4693
+transformers/models/speech_encoder_decoder/modeling_flax_speech_encoder_decoder.py,sha256=KCyHnYvQdlpFChAzDCgDs2UfY546A0i01U8e1YYGT0Q,44860
+transformers/models/speech_encoder_decoder/modeling_speech_encoder_decoder.py,sha256=81wTcmrt05uYx7X66Lbd_3xHj7ZcV5GiukVO465nnQI,25568
+transformers/models/speech_to_text/__init__.py,sha256=qZzt5u1rbSsOjPVmX40R4b4pkL1mxOQZ66q8GPDKao8,1200
+transformers/models/speech_to_text/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/speech_to_text/__pycache__/configuration_speech_to_text.cpython-310.pyc,,
+transformers/models/speech_to_text/__pycache__/feature_extraction_speech_to_text.cpython-310.pyc,,
+transformers/models/speech_to_text/__pycache__/modeling_speech_to_text.cpython-310.pyc,,
+transformers/models/speech_to_text/__pycache__/modeling_tf_speech_to_text.cpython-310.pyc,,
+transformers/models/speech_to_text/__pycache__/processing_speech_to_text.cpython-310.pyc,,
+transformers/models/speech_to_text/__pycache__/tokenization_speech_to_text.cpython-310.pyc,,
+transformers/models/speech_to_text/configuration_speech_to_text.py,sha256=YazgmnHYt_lbYaRQNt2dEYAqgpAfYln36hQl89WPLF4,9825
+transformers/models/speech_to_text/feature_extraction_speech_to_text.py,sha256=r6vxaMiZM7KBxghUnd_WnDJ4brms95HimGR0bkzvglw,13955
+transformers/models/speech_to_text/modeling_speech_to_text.py,sha256=qRgAr8WTF03EqWJPEiBGPZQ5ZUKfOMjaUujO68Yryrs,61906
+transformers/models/speech_to_text/modeling_tf_speech_to_text.py,sha256=-qOZso75ib0DJDvIGE4NcnQdP3Q97uALIiUqlRd5-qc,74289
+transformers/models/speech_to_text/processing_speech_to_text.py,sha256=jg7WkcQYWW00ndyN3PUo98EfswLlNNUc0izl1Iphy5E,4240
+transformers/models/speech_to_text/tokenization_speech_to_text.py,sha256=4VRmhzHQZvrplhvYdQFMN8v9xAWmz0UFW4TY9pI7ygw,11501
+transformers/models/speecht5/__init__.py,sha256=DploRLnZX4ZO40Z7BstCZ7aNWGuZE06tIeMo0GTyR60,1124
+transformers/models/speecht5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/speecht5/__pycache__/configuration_speecht5.cpython-310.pyc,,
+transformers/models/speecht5/__pycache__/feature_extraction_speecht5.cpython-310.pyc,,
+transformers/models/speecht5/__pycache__/modeling_speecht5.cpython-310.pyc,,
+transformers/models/speecht5/__pycache__/number_normalizer.cpython-310.pyc,,
+transformers/models/speecht5/__pycache__/processing_speecht5.cpython-310.pyc,,
+transformers/models/speecht5/__pycache__/tokenization_speecht5.cpython-310.pyc,,
+transformers/models/speecht5/configuration_speecht5.py,sha256=q6TwW_M__spcgD9NOObNlcOZt8_xvL6V5Qm1yQZ1T1I,23466
+transformers/models/speecht5/feature_extraction_speecht5.py,sha256=MqnjfL1S_-VCnJhEEWgfv9kAYp2_nlO9MZ9OtsESJX0,17853
+transformers/models/speecht5/modeling_speecht5.py,sha256=SApmBrEwu7DBy4Pe0VxZBNP7yyq_pza30QAqcKVDK34,148067
+transformers/models/speecht5/number_normalizer.py,sha256=cxnEUdHSISW5eAo15cLuVkZa65zMFuMFaJ8zAOQCsAA,7019
+transformers/models/speecht5/processing_speecht5.py,sha256=PvI7tFsx_a_39n1TME0uDQSqQS3J9neLLFPwbrn40C0,6990
+transformers/models/speecht5/tokenization_speecht5.py,sha256=UfqBVrMUHCRRY_-kVvcU3RJnEfdAlq40ooE0UqV40ps,9009
+transformers/models/splinter/__init__.py,sha256=N3tdgJIqZRPK0g3pfLE3p3-HkGJMRf-GQ189anQ51to,1084
+transformers/models/splinter/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/splinter/__pycache__/configuration_splinter.cpython-310.pyc,,
+transformers/models/splinter/__pycache__/modeling_splinter.cpython-310.pyc,,
+transformers/models/splinter/__pycache__/tokenization_splinter.cpython-310.pyc,,
+transformers/models/splinter/__pycache__/tokenization_splinter_fast.cpython-310.pyc,,
+transformers/models/splinter/configuration_splinter.py,sha256=ZajZPX6f9K7gBqp2PbOtmJg-_fAU8h72tKdTNjyQV0M,5625
+transformers/models/splinter/modeling_splinter.py,sha256=dMJYhHNbuFmTWze5K_QTO2Nc8rM8PfYYDkgLH3Ivk5A,38011
+transformers/models/splinter/tokenization_splinter.py,sha256=ba400uZlqtB6kjdMI3oMgBWs_p-px81zAQItZQx-l6c,20948
+transformers/models/splinter/tokenization_splinter_fast.py,sha256=AG6k691a2HJqtIAiEyn07WuSc4JgqU1HTkfEGC8Tt2c,8590
+transformers/models/squeezebert/__init__.py,sha256=_kzQtfoJetCK99e_FICGZl5DN8S2VVcOUFioGyN0sLI,1096
+transformers/models/squeezebert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/squeezebert/__pycache__/configuration_squeezebert.cpython-310.pyc,,
+transformers/models/squeezebert/__pycache__/modeling_squeezebert.cpython-310.pyc,,
+transformers/models/squeezebert/__pycache__/tokenization_squeezebert.cpython-310.pyc,,
+transformers/models/squeezebert/__pycache__/tokenization_squeezebert_fast.cpython-310.pyc,,
+transformers/models/squeezebert/configuration_squeezebert.py,sha256=9I4mUuqEwKAIrezRjjto3HBfJ-aiWBTkQcIZWuJFFGM,7312
+transformers/models/squeezebert/modeling_squeezebert.py,sha256=XNcULy9rowxidymjHb8D3OWWVFaTsC9rHLPmJQsd5rQ,38738
+transformers/models/squeezebert/tokenization_squeezebert.py,sha256=4ZbPoFCjrt-d2zdbZ9s23IHOsN5iw9VpG11W4sJWCJM,20092
+transformers/models/squeezebert/tokenization_squeezebert_fast.py,sha256=CtqOSIMAYhS66yYjbWxTDpbbxNvAllTkP_lJroEyvfQ,6724
+transformers/models/stablelm/__init__.py,sha256=aVgWTcwBuuiGJDp8H_ZU6BvhYqjmNEqCukU7jEfwd_I,997
+transformers/models/stablelm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/stablelm/__pycache__/configuration_stablelm.cpython-310.pyc,,
+transformers/models/stablelm/__pycache__/modeling_stablelm.cpython-310.pyc,,
+transformers/models/stablelm/configuration_stablelm.py,sha256=GqKL53dgijlmwQMgLsuw4jB6gm1stU4SaCETjqumKVs,10843
+transformers/models/stablelm/modeling_stablelm.py,sha256=ZJPjaa2-eg6Viq2d0AghbyoC8bA-VfgXQ9hLxt5GfIs,45396
+transformers/models/starcoder2/__init__.py,sha256=fZ8HHZCGjxRfVgROe7zuoi9ADIAa4SeqxGHkvKUQiQM,1001
+transformers/models/starcoder2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/starcoder2/__pycache__/configuration_starcoder2.cpython-310.pyc,,
+transformers/models/starcoder2/__pycache__/modeling_starcoder2.cpython-310.pyc,,
+transformers/models/starcoder2/__pycache__/modular_starcoder2.cpython-310.pyc,,
+transformers/models/starcoder2/configuration_starcoder2.py,sha256=wgtxWNUy_mjoly8Hyg4eVBJKFtcy9x2rdK55uzErIXg,10898
+transformers/models/starcoder2/modeling_starcoder2.py,sha256=bFBfPK5y0sjF23tnWkmVkdwpcViyMTzpvph_CrxjXrI,21537
+transformers/models/starcoder2/modular_starcoder2.py,sha256=CuEyxvpXyAoCKEbctN0iFPI43qCf-Nb_EKRAMAqT7Bo,9905
+transformers/models/superglue/__init__.py,sha256=Sg_nfSbBltkVhp40pVc04SthUCnXMX3kWHH_qC_YL4Y,1045
+transformers/models/superglue/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/superglue/__pycache__/configuration_superglue.cpython-310.pyc,,
+transformers/models/superglue/__pycache__/image_processing_superglue.cpython-310.pyc,,
+transformers/models/superglue/__pycache__/modeling_superglue.cpython-310.pyc,,
+transformers/models/superglue/configuration_superglue.py,sha256=WD-orzD73GN0s_3On6qcv0jRS7PwC1yjgNBPNnXpOzc,5473
+transformers/models/superglue/image_processing_superglue.py,sha256=TBf3TVLl1LJlJt-cKFxnUh9ToifooCfWjgwiwdtCoXE,21944
+transformers/models/superglue/modeling_superglue.py,sha256=bBVf-RB3Vp2YO5dnlTfeLCBLcGkI7jCUSx5nad4jTIA,36118
+transformers/models/superpoint/__init__.py,sha256=6fQQ-p4220IUaIQCZseKItiHWVV7KOiA5mXoTdJSJmI,1100
+transformers/models/superpoint/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/superpoint/__pycache__/configuration_superpoint.cpython-310.pyc,,
+transformers/models/superpoint/__pycache__/image_processing_superpoint.cpython-310.pyc,,
+transformers/models/superpoint/__pycache__/image_processing_superpoint_fast.cpython-310.pyc,,
+transformers/models/superpoint/__pycache__/modeling_superpoint.cpython-310.pyc,,
+transformers/models/superpoint/configuration_superpoint.py,sha256=wWW7CLDM2VW-f41M_hLvq4N3j1gt_4QmsaNHifKLd_I,4048
+transformers/models/superpoint/image_processing_superpoint.py,sha256=R_7RqgeGVrMepchnGIH7smiVqbl__inUcCDye0vxZqQ,16394
+transformers/models/superpoint/image_processing_superpoint_fast.py,sha256=cfHNKd8IzIFZp6NaUqt83aLJaX4M7fjeSJz1GmOQW0s,7074
+transformers/models/superpoint/modeling_superpoint.py,sha256=iqN6g4a2Yt8I-tantOd66ajRukiCzl1PcLFUIMDv71I,20071
+transformers/models/swiftformer/__init__.py,sha256=cW3-9efPxdjZV1KziM8j1S8e8wH3wJQhWqMXlULhG6c,1046
+transformers/models/swiftformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/swiftformer/__pycache__/configuration_swiftformer.cpython-310.pyc,,
+transformers/models/swiftformer/__pycache__/modeling_swiftformer.cpython-310.pyc,,
+transformers/models/swiftformer/__pycache__/modeling_tf_swiftformer.cpython-310.pyc,,
+transformers/models/swiftformer/configuration_swiftformer.py,sha256=zc6uduEgdxwc_ApNrsADFqGSKC1qlH-kceHSuUWHQCI,5867
+transformers/models/swiftformer/modeling_swiftformer.py,sha256=1AxEVT8-oh2Fh0CuWAdQm_oVECi1YktoD33Xd7cENmQ,20641
+transformers/models/swiftformer/modeling_tf_swiftformer.py,sha256=BtStZyRloUcoWu3km_TLihPzMPiXA5QT88WQthuMS8Q,34959
+transformers/models/swin/__init__.py,sha256=7pcdahUG9WcEkEDRoUcMVxdonKglhOpXaQLo8xI6KTg,1025
+transformers/models/swin/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/swin/__pycache__/configuration_swin.cpython-310.pyc,,
+transformers/models/swin/__pycache__/modeling_swin.cpython-310.pyc,,
+transformers/models/swin/__pycache__/modeling_tf_swin.cpython-310.pyc,,
+transformers/models/swin/configuration_swin.py,sha256=hcksE44MGT9_rWYNXvhyl94jqU00rQY3XXTDPzTlvmo,7958
+transformers/models/swin/modeling_swin.py,sha256=f3MBhFmvYXXBi6AY_zMGF5FnpdkWh-nqHlRnSInjU5g,54815
+transformers/models/swin/modeling_tf_swin.py,sha256=1ql5W5rY6oxRDd24dj-RGsWy-onKGQbeN1JZ3KaKdj4,70829
+transformers/models/swin2sr/__init__.py,sha256=PLCBXwTQF37hLur2ROcYXUiNropQ6u5Ig_HgK29MOu8,1088
+transformers/models/swin2sr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/swin2sr/__pycache__/configuration_swin2sr.cpython-310.pyc,,
+transformers/models/swin2sr/__pycache__/image_processing_swin2sr.cpython-310.pyc,,
+transformers/models/swin2sr/__pycache__/image_processing_swin2sr_fast.cpython-310.pyc,,
+transformers/models/swin2sr/__pycache__/modeling_swin2sr.cpython-310.pyc,,
+transformers/models/swin2sr/configuration_swin2sr.py,sha256=6ZRVIyo6z1oQvPm13QvkrWcKpf1qjMf0QqwmdHMdvto,6841
+transformers/models/swin2sr/image_processing_swin2sr.py,sha256=r51aVCfgD2RwjQpXx3AmQYwUpTABezPACVCz75imF2w,9246
+transformers/models/swin2sr/image_processing_swin2sr_fast.py,sha256=obhPGADB2acMjySvBMjeh96rQ615Uzf7jnarn6JYQgw,4171
+transformers/models/swin2sr/modeling_swin2sr.py,sha256=C8CzwaXFhYcIx_psS6TE4Ye3QZwAnhEJl8ZtNcFKD90,46918
+transformers/models/swinv2/__init__.py,sha256=njM902tlEQ82mYRN9ZTMOiXpJn1NHnxKbm_LCvn2I-M,993
+transformers/models/swinv2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/swinv2/__pycache__/configuration_swinv2.cpython-310.pyc,,
+transformers/models/swinv2/__pycache__/modeling_swinv2.cpython-310.pyc,,
+transformers/models/swinv2/configuration_swinv2.py,sha256=m2yjnprZXcqtF4dlw2JAv8MWjBBm6khztGzCUAp4rHw,7547
+transformers/models/swinv2/modeling_swinv2.py,sha256=VzsVNFnwumez9FxzFhpwC13R5ezBDclsRJ18eiMjK_I,59029
+transformers/models/switch_transformers/__init__.py,sha256=Iw38A9kfIT5mJ0G00YE-TVN-M_b1DBHYQqb0pEyTZMY,1019
+transformers/models/switch_transformers/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/switch_transformers/__pycache__/configuration_switch_transformers.cpython-310.pyc,,
+transformers/models/switch_transformers/__pycache__/modeling_switch_transformers.cpython-310.pyc,,
+transformers/models/switch_transformers/configuration_switch_transformers.py,sha256=hqXjdBHj-oqNPBPzwH-e5-dKYDPw2lfWgc3oDegHHVE,9054
+transformers/models/switch_transformers/modeling_switch_transformers.py,sha256=6e3aSXSTaD850L3e8nBrc1Ra1hBwzBngbOvLOmrMkl4,84606
+transformers/models/t5/__init__.py,sha256=hCQO8nkKAJqFgMOwC7nxhyDYOUA9fcDT0pDb7DAHt5Y,1130
+transformers/models/t5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/t5/__pycache__/configuration_t5.cpython-310.pyc,,
+transformers/models/t5/__pycache__/modeling_flax_t5.cpython-310.pyc,,
+transformers/models/t5/__pycache__/modeling_t5.cpython-310.pyc,,
+transformers/models/t5/__pycache__/modeling_tf_t5.cpython-310.pyc,,
+transformers/models/t5/__pycache__/tokenization_t5.cpython-310.pyc,,
+transformers/models/t5/__pycache__/tokenization_t5_fast.cpython-310.pyc,,
+transformers/models/t5/configuration_t5.py,sha256=1fXcdM1_SwAjVwAo2pyiWoxXuoZ6meJaqI6btUPH-bU,7381
+transformers/models/t5/modeling_flax_t5.py,sha256=l-uYt9Ze0OemY-eF2BVoCmYomkQeJieRMuozgr7pqk8,74353
+transformers/models/t5/modeling_t5.py,sha256=ILw0da9DaOThpKHRuSV1W-Bh1-HHWRop1C3AjQUFx4w,109901
+transformers/models/t5/modeling_tf_t5.py,sha256=lW4_eVKZY317xGPnXt1L-q0fAp44wSXiRb85vOJEjY8,76956
+transformers/models/t5/tokenization_t5.py,sha256=BZJ_dt1beGBH1qWSpa99UHv-hJ3C_jo1zFHKc07yBhA,19952
+transformers/models/t5/tokenization_t5_fast.py,sha256=E1E_dH9RXXh7ei1c1u9Q_518o-n5x0mrhMJlHvlqLb8,10048
+transformers/models/t5gemma/__init__.py,sha256=2QjFw4aK-Ui2JuImfxWN8oeMkMwokEzurG8wPvKv98Y,1005
+transformers/models/t5gemma/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/t5gemma/__pycache__/configuration_t5gemma.cpython-310.pyc,,
+transformers/models/t5gemma/__pycache__/modeling_t5gemma.cpython-310.pyc,,
+transformers/models/t5gemma/__pycache__/modular_t5gemma.cpython-310.pyc,,
+transformers/models/t5gemma/configuration_t5gemma.py,sha256=VcvWG1dQAStzAZlsvjYZ6mhQfeI2KRMgSTlLK0oDCeo,16350
+transformers/models/t5gemma/modeling_t5gemma.py,sha256=36fm33Zwxhf7UwTcytrIGn5td1deDOT-W56sM4vJV_E,61073
+transformers/models/t5gemma/modular_t5gemma.py,sha256=xUjAeMlFq9z8leP3aaZrM0nrxIGDLoUBx7nKYuE8__4,52850
+transformers/models/table_transformer/__init__.py,sha256=VT-KM0_6LZ6fdOAglbfA8zEhCQuYa6He10Div7WEcD8,1015
+transformers/models/table_transformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/table_transformer/__pycache__/configuration_table_transformer.cpython-310.pyc,,
+transformers/models/table_transformer/__pycache__/modeling_table_transformer.cpython-310.pyc,,
+transformers/models/table_transformer/configuration_table_transformer.py,sha256=sXV9fFcqNqz9K7zYPCFZyDXfjr42GhotJ7th5UCdH54,13613
+transformers/models/table_transformer/modeling_table_transformer.py,sha256=RYS0x53pWkPkh8OiSfhBLTe2ioplGetkvQu-RG8Vj1A,61338
+transformers/models/tapas/__init__.py,sha256=DQTmog2nYukVsXxARy8v35SitI0Iv4ZLCGl7zUlLDuI,1066
+transformers/models/tapas/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/tapas/__pycache__/configuration_tapas.cpython-310.pyc,,
+transformers/models/tapas/__pycache__/modeling_tapas.cpython-310.pyc,,
+transformers/models/tapas/__pycache__/modeling_tf_tapas.cpython-310.pyc,,
+transformers/models/tapas/__pycache__/tokenization_tapas.cpython-310.pyc,,
+transformers/models/tapas/configuration_tapas.py,sha256=i1_a_AArLjS8SkWu0Du8TC7JZBfvMUSku2QteSdfnC4,12293
+transformers/models/tapas/modeling_tapas.py,sha256=FZfiQSssy67t7ZooRmsXF8tgRZkK5w2tHnlSbgveO_o,108788
+transformers/models/tapas/modeling_tf_tapas.py,sha256=HpG3CLwp21ZKZ39Kew6FakiaWuCuv0ZFXmFdMs2WFlw,112267
+transformers/models/tapas/tokenization_tapas.py,sha256=tN5PcvOE_GT9NOYggB4GYI0kRl3mj_gyqUHDQ0bjGXE,118445
+transformers/models/textnet/__init__.py,sha256=nqXafUk5z5F_61jrGF9gK_sI66uj7kq5sUYrit9bsno,1088
+transformers/models/textnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/textnet/__pycache__/configuration_textnet.cpython-310.pyc,,
+transformers/models/textnet/__pycache__/image_processing_textnet.cpython-310.pyc,,
+transformers/models/textnet/__pycache__/image_processing_textnet_fast.cpython-310.pyc,,
+transformers/models/textnet/__pycache__/modeling_textnet.cpython-310.pyc,,
+transformers/models/textnet/configuration_textnet.py,sha256=ZGtG42UxM2RbWr7pSN1IUIBo74aK8Vq79Gg2-vfFWp4,6212
+transformers/models/textnet/image_processing_textnet.py,sha256=fR9wH7_0gal82_n-4MwsLImm4_3i9qPOR-fvtKMupn0,17711
+transformers/models/textnet/image_processing_textnet_fast.py,sha256=aIBISR6O07xc2zL8qDKZHr6pklwy2hG5c84h_FgcYsM,5990
+transformers/models/textnet/modeling_textnet.py,sha256=Odxuf0g2IIInnqRcxR14XAaDtsO7UK6gOgSyCjt5Eos,16601
+transformers/models/time_series_transformer/__init__.py,sha256=3A_3Wog-6NDwCoBIMtkzJv9slc_wXpzDzsOo-xBQ8hE,1027
+transformers/models/time_series_transformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/time_series_transformer/__pycache__/configuration_time_series_transformer.cpython-310.pyc,,
+transformers/models/time_series_transformer/__pycache__/modeling_time_series_transformer.cpython-310.pyc,,
+transformers/models/time_series_transformer/configuration_time_series_transformer.py,sha256=jNs-oZ17yVDy4g-shNyOLoA9pupIt9ZlBbX5BXRLyYo,11695
+transformers/models/time_series_transformer/modeling_time_series_transformer.py,sha256=lUUQeTZptc7S0JB3VSBSXyoO96-0otXNmmSINyyY52s,95671
+transformers/models/timesfm/__init__.py,sha256=gcfLgRAbwZThFP98fst9wsoTMB0fkR28tzWYoQIs5qU,995
+transformers/models/timesfm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/timesfm/__pycache__/configuration_timesfm.cpython-310.pyc,,
+transformers/models/timesfm/__pycache__/modeling_timesfm.cpython-310.pyc,,
+transformers/models/timesfm/__pycache__/modular_timesfm.cpython-310.pyc,,
+transformers/models/timesfm/configuration_timesfm.py,sha256=OBKxwrNeeak-YgKtKL4zTgs705E9to4FCbD7wX0J1Gs,5715
+transformers/models/timesfm/modeling_timesfm.py,sha256=oW_6yao7FOzfvlXxGVAsdK2AZlfX7H1f0R77yUDR-oQ,34502
+transformers/models/timesfm/modular_timesfm.py,sha256=RE1ypm8pygCjjZQ2lUfEfwqiY3v8wYdWHJrEsFIkdeo,32164
+transformers/models/timesformer/__init__.py,sha256=4ODuyNRrYkbgpSbMHJX8XmpJdekHlu__zWey-plUSgI,1003
+transformers/models/timesformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/timesformer/__pycache__/configuration_timesformer.cpython-310.pyc,,
+transformers/models/timesformer/__pycache__/modeling_timesformer.cpython-310.pyc,,
+transformers/models/timesformer/configuration_timesformer.py,sha256=GilCKil_40B_hqjh0-02CWrBupbwEfHhOZ3b5bUpTPI,5568
+transformers/models/timesformer/modeling_timesformer.py,sha256=aUB9d6gCpKSyey0CY_wHlk9_xQsCBz4HT5YWw9exm6o,32838
+transformers/models/timm_backbone/__init__.py,sha256=s0GlTaJ43Yt9ZdzG9-qjJNlp0Ol4vjN-14S6N7gXLsA,1007
+transformers/models/timm_backbone/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/timm_backbone/__pycache__/configuration_timm_backbone.cpython-310.pyc,,
+transformers/models/timm_backbone/__pycache__/modeling_timm_backbone.cpython-310.pyc,,
+transformers/models/timm_backbone/configuration_timm_backbone.py,sha256=CMRsZX3ZQiI1bzBrza3Eqgjy8XEid8dPfJZVuhtLTn8,3186
+transformers/models/timm_backbone/modeling_timm_backbone.py,sha256=8k2tlfAtgX2FguLvxtXc_15jCjbnq4lXKq_BalsgxT8,6635
+transformers/models/timm_wrapper/__init__.py,sha256=nO3xlv8KQmYCoxKqDteADLkli16cLqdLkfTY_G73O6k,1048
+transformers/models/timm_wrapper/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/timm_wrapper/__pycache__/configuration_timm_wrapper.cpython-310.pyc,,
+transformers/models/timm_wrapper/__pycache__/image_processing_timm_wrapper.cpython-310.pyc,,
+transformers/models/timm_wrapper/__pycache__/modeling_timm_wrapper.cpython-310.pyc,,
+transformers/models/timm_wrapper/configuration_timm_wrapper.py,sha256=tHCQEH67F-TXb_ES5751YHxKINpZJQbYtPjiMc0f4gY,5297
+transformers/models/timm_wrapper/image_processing_timm_wrapper.py,sha256=b9aeo2BbC0kWkKsAy9wMCXRgU-P6y6WxgVXiPaMtYq8,5338
+transformers/models/timm_wrapper/modeling_timm_wrapper.py,sha256=ERZgzCnsmZVawGWxbrGpRLxYUOwROZ655VBwPFC3uyQ,16611
+transformers/models/trocr/__init__.py,sha256=Hllbq_42XbGRZyXsGOzYHcb33MOA5_yfijMRKEXJ4n4,1027
+transformers/models/trocr/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/trocr/__pycache__/configuration_trocr.cpython-310.pyc,,
+transformers/models/trocr/__pycache__/modeling_trocr.cpython-310.pyc,,
+transformers/models/trocr/__pycache__/processing_trocr.cpython-310.pyc,,
+transformers/models/trocr/configuration_trocr.py,sha256=mm8gO1FagOM7OpQ9S7TZ9UrNc7or081ymZz-q3uss3s,6558
+transformers/models/trocr/modeling_trocr.py,sha256=W3RYMUKRI05xsVrHd1ld9mg5ohuKp0SWvClpJwerO1s,39475
+transformers/models/trocr/processing_trocr.py,sha256=LdCpIq5HMO2xvy-8FxCJJUwGNWuL9KJ9uJT0xFeQpTI,5925
+transformers/models/tvp/__init__.py,sha256=zY4KwnUt4Q8f_afJGLIxUIfZf8RIyOOCbv9tnAJk1ic,1106
+transformers/models/tvp/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/tvp/__pycache__/configuration_tvp.cpython-310.pyc,,
+transformers/models/tvp/__pycache__/image_processing_tvp.cpython-310.pyc,,
+transformers/models/tvp/__pycache__/image_processing_tvp_fast.cpython-310.pyc,,
+transformers/models/tvp/__pycache__/modeling_tvp.cpython-310.pyc,,
+transformers/models/tvp/__pycache__/processing_tvp.cpython-310.pyc,,
+transformers/models/tvp/configuration_tvp.py,sha256=DpgrPqYGfjA6OSNkh5UsdkLw8RWFF6qh90Zrz6U9pn4,10147
+transformers/models/tvp/image_processing_tvp.py,sha256=ky4Owy0s0wmEVkhPIVGfcL8fTJviPYLUM8uvOJh1L2c,22841
+transformers/models/tvp/image_processing_tvp_fast.py,sha256=xQPgxFt2fKO8hNBpZDy5hFx3o2I7jV8q0zbnCecCqZA,10426
+transformers/models/tvp/modeling_tvp.py,sha256=dpW7PUlmyRVDk8adwMl6DIw-RgQcOMLn_85Kmby4mdc,40062
+transformers/models/tvp/processing_tvp.py,sha256=BLS60Aj3zZVVE2t85c7OLP3Xm2nvahnkm0gqdSIGn-g,6029
+transformers/models/udop/__init__.py,sha256=CqFpHruzC__VtxEcVz31QxxMpBI1mjO77-Lj0RqW4Eo,1103
+transformers/models/udop/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/udop/__pycache__/configuration_udop.cpython-310.pyc,,
+transformers/models/udop/__pycache__/modeling_udop.cpython-310.pyc,,
+transformers/models/udop/__pycache__/processing_udop.cpython-310.pyc,,
+transformers/models/udop/__pycache__/tokenization_udop.cpython-310.pyc,,
+transformers/models/udop/__pycache__/tokenization_udop_fast.cpython-310.pyc,,
+transformers/models/udop/configuration_udop.py,sha256=xzaHEk_1LtY4AqHr10qL2Vt7Yi-CRgCO98Ni_OvRPgg,7675
+transformers/models/udop/modeling_udop.py,sha256=ltzJvdTFGhNtomLN30x0_Sto6YLNqDbCedx4IhOszUI,92339
+transformers/models/udop/processing_udop.py,sha256=Huz5GGRLuRhY6S9P9yxzowgz8JC3LozZkoyZUBfRjIY,8642
+transformers/models/udop/tokenization_udop.py,sha256=8wBBqyD99Y_tcP8q_LHZiIITj26kKdMRtLAeaIH91EU,71827
+transformers/models/udop/tokenization_udop_fast.py,sha256=cvfqL2DiAyd2_d5BL14U6XQScBvM8JoGizTM3tLSik0,49663
+transformers/models/umt5/__init__.py,sha256=FKt6Ap3AvOCIKoeOM-5qY84lNEML9IujaDaYROINJMs,989
+transformers/models/umt5/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/umt5/__pycache__/configuration_umt5.cpython-310.pyc,,
+transformers/models/umt5/__pycache__/modeling_umt5.cpython-310.pyc,,
+transformers/models/umt5/configuration_umt5.py,sha256=W60fZhT2upRLbNTauRSs1-K0HSB5aCV4m79TFSXO1VI,7749
+transformers/models/umt5/modeling_umt5.py,sha256=WpSDxb53kDTlu6TxUJdj68osUg-pOV6wAUgVeIjpOcA,90869
+transformers/models/unispeech/__init__.py,sha256=AXJMExDoYYI71OKNXhAt7lyqcFIvcLHEQ1Fsm171m5w,999
+transformers/models/unispeech/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/unispeech/__pycache__/configuration_unispeech.cpython-310.pyc,,
+transformers/models/unispeech/__pycache__/modeling_unispeech.cpython-310.pyc,,
+transformers/models/unispeech/__pycache__/modular_unispeech.cpython-310.pyc,,
+transformers/models/unispeech/configuration_unispeech.py,sha256=THcTvZNOVsDyoVkiDZ5kKGu5hmNu0qM2lal-P-WPDos,17510
+transformers/models/unispeech/modeling_unispeech.py,sha256=8pZQ3HXzcXXzgp8HpjkzniWKKfERCmGHDtQpjIi7hOU,64373
+transformers/models/unispeech/modular_unispeech.py,sha256=A7tDao9K2QPRdy7WpLGKJLWmYFxpp9f4eqAzkCFvtdE,18207
+transformers/models/unispeech_sat/__init__.py,sha256=P9lCzMg01s4Gj_Pb8t1l36MRAeoOcxUa4d7dbQSe9N4,1007
+transformers/models/unispeech_sat/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/unispeech_sat/__pycache__/configuration_unispeech_sat.cpython-310.pyc,,
+transformers/models/unispeech_sat/__pycache__/modeling_unispeech_sat.cpython-310.pyc,,
+transformers/models/unispeech_sat/__pycache__/modular_unispeech_sat.cpython-310.pyc,,
+transformers/models/unispeech_sat/configuration_unispeech_sat.py,sha256=3CduPVTYRqVQWaZbD_oA3wsCl_7v95Fn4RuWpPi6VhQ,18855
+transformers/models/unispeech_sat/modeling_unispeech_sat.py,sha256=Ri6oR_eW82UilW8mZ0UMIFSx6OPK2KV-Z9izxQaA3I0,78446
+transformers/models/unispeech_sat/modular_unispeech_sat.py,sha256=UsFpwELhczFJTXGNoHClgGFzP-ZFWBFVQ5HQR6S5KQY,18606
+transformers/models/univnet/__init__.py,sha256=hfHyxyKGEfd58p1fUSA3IxK2q6JkVatkGceVaoKuODk,1041
+transformers/models/univnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/univnet/__pycache__/configuration_univnet.cpython-310.pyc,,
+transformers/models/univnet/__pycache__/feature_extraction_univnet.cpython-310.pyc,,
+transformers/models/univnet/__pycache__/modeling_univnet.cpython-310.pyc,,
+transformers/models/univnet/configuration_univnet.py,sha256=dwE48PdXxA4_3tbux06b7HAsdUK9c5-capcOdDeAr9c,6758
+transformers/models/univnet/feature_extraction_univnet.py,sha256=9iNfhNCBNRWaY7odFlzXzMLzauhSzgFGdr20sQ4xPWw,22880
+transformers/models/univnet/modeling_univnet.py,sha256=LTX4W5D4B8B9zK29ba8M5z5XGtqHBbj2n8n8OJP6fis,25779
+transformers/models/upernet/__init__.py,sha256=Wq3u7yXJul5PLmjalxKgx451sa_WuSXbEM45bZsRv3E,995
+transformers/models/upernet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/upernet/__pycache__/configuration_upernet.cpython-310.pyc,,
+transformers/models/upernet/__pycache__/modeling_upernet.cpython-310.pyc,,
+transformers/models/upernet/configuration_upernet.py,sha256=ih_8sDO-OzHJOCqUDhtiBOtRanCrLfhx3c6OBZryILI,6859
+transformers/models/upernet/modeling_upernet.py,sha256=vWF4TKPs6t8AxHBVOGsw2BaHRyXnithQ3RFs-iNRHUM,14577
+transformers/models/video_llava/__init__.py,sha256=bsLGp1WBBO_AvNVRxzOn5k7OYQIbX9SqFhESd24FImc,1093
+transformers/models/video_llava/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/video_llava/__pycache__/configuration_video_llava.cpython-310.pyc,,
+transformers/models/video_llava/__pycache__/image_processing_video_llava.cpython-310.pyc,,
+transformers/models/video_llava/__pycache__/modeling_video_llava.cpython-310.pyc,,
+transformers/models/video_llava/__pycache__/processing_video_llava.cpython-310.pyc,,
+transformers/models/video_llava/__pycache__/video_processing_video_llava.cpython-310.pyc,,
+transformers/models/video_llava/configuration_video_llava.py,sha256=zetmD2cvfHzFEiU8PJn1qWWVPwMgT08YMR3q-DTPukk,6448
+transformers/models/video_llava/image_processing_video_llava.py,sha256=ldr_ux_Ot8qoGfCQJ_Fjn9ZreiiPZtsrKUBaMv5IGaw,19120
+transformers/models/video_llava/modeling_video_llava.py,sha256=YB_5ZKbBO0AZ5Z6RzeLhkouMC5_YiTJqEDCVZboCviA,33607
+transformers/models/video_llava/processing_video_llava.py,sha256=qx1Rut5-VPbN5DwhWS5gQwqno0XsmYMbEVXXmDowIvI,10766
+transformers/models/video_llava/video_processing_video_llava.py,sha256=UQK5S3qUDL1BIIYhqN41Y-iIs7dQL2DNMqZZ_gLBVro,1879
+transformers/models/videomae/__init__.py,sha256=IYw3qXj1-PDmBAp---YaZyqdBsIjdMZQI37xT_-9SgY,1089
+transformers/models/videomae/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/videomae/__pycache__/configuration_videomae.cpython-310.pyc,,
+transformers/models/videomae/__pycache__/feature_extraction_videomae.cpython-310.pyc,,
+transformers/models/videomae/__pycache__/image_processing_videomae.cpython-310.pyc,,
+transformers/models/videomae/__pycache__/modeling_videomae.cpython-310.pyc,,
+transformers/models/videomae/configuration_videomae.py,sha256=O0BwqYZnc9Q5Kpemmel6rOxeDBSj7KKCxgpHfMVCVGE,6600
+transformers/models/videomae/feature_extraction_videomae.py,sha256=YfjgYL2im5-5OtnL_U9Z72Fxm58jNAIQWkUlszLJEtY,1316
+transformers/models/videomae/image_processing_videomae.py,sha256=UhuQHRAS0I_Y4j5pzcAvehONMuDHpEwGPCUjXGhIESA,16771
+transformers/models/videomae/modeling_videomae.py,sha256=uhKZ30-o1U8I4IXBQ8pAofpKMdeM0RZIXoqJN_v_zu0,38299
+transformers/models/vilt/__init__.py,sha256=efaZSTGsk3QhZmBrc6F29q55LkC_1Vb8fNC0MY4881Q,1154
+transformers/models/vilt/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vilt/__pycache__/configuration_vilt.cpython-310.pyc,,
+transformers/models/vilt/__pycache__/feature_extraction_vilt.cpython-310.pyc,,
+transformers/models/vilt/__pycache__/image_processing_vilt.cpython-310.pyc,,
+transformers/models/vilt/__pycache__/image_processing_vilt_fast.cpython-310.pyc,,
+transformers/models/vilt/__pycache__/modeling_vilt.cpython-310.pyc,,
+transformers/models/vilt/__pycache__/processing_vilt.cpython-310.pyc,,
+transformers/models/vilt/configuration_vilt.py,sha256=B7lnWQV7QC5CeliGPQF5TP5Ci-s35bv7_LX4UvOVNUs,6817
+transformers/models/vilt/feature_extraction_vilt.py,sha256=OYz67RYXTxX9oQpJ9b-lSzCduexmgugUpkiPHSfcs9s,1284
+transformers/models/vilt/image_processing_vilt.py,sha256=dwTZIYmMY8rt1q6ey1rdkvwJjMj-YqzIBzxSDknIDYE,23284
+transformers/models/vilt/image_processing_vilt_fast.py,sha256=-U7Sua6PmfA56qq3L39lOyCTQUYTdvklAfOcvGco9Ow,10004
+transformers/models/vilt/modeling_vilt.py,sha256=imU7i_YLvyforJNc7NP6D1dz7zd413dnD-Rug9_CO1M,57590
+transformers/models/vilt/processing_vilt.py,sha256=-1Nyo7jV-3N3IoM6LSUjvPR37G8OlvGXBWZG19WIi7o,5215
+transformers/models/vipllava/__init__.py,sha256=HJ5mZUNdt_bmaC9l-GycD7mVT2r1oN15prmnlBtz6oA,997
+transformers/models/vipllava/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vipllava/__pycache__/configuration_vipllava.cpython-310.pyc,,
+transformers/models/vipllava/__pycache__/modeling_vipllava.cpython-310.pyc,,
+transformers/models/vipllava/__pycache__/modular_vipllava.cpython-310.pyc,,
+transformers/models/vipllava/configuration_vipllava.py,sha256=BUvvdV2CgiEp5h-pWbuEUi7t8bnkl6haqljNtf3en6c,5049
+transformers/models/vipllava/modeling_vipllava.py,sha256=cl5pmchM_M5W0XnWknekTY3zq96J1nXpS1xx6qYKlgI,20674
+transformers/models/vipllava/modular_vipllava.py,sha256=pOBTUbXWhXiJiAYe0oqOuGiR4YFfn2s6qd3qVqNrS80,12299
+transformers/models/vision_encoder_decoder/__init__.py,sha256=xK5xKVeIOZSN1d9Y2nDa3NYkLdGidbwgQ6Es8JhzKzA,1135
+transformers/models/vision_encoder_decoder/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vision_encoder_decoder/__pycache__/configuration_vision_encoder_decoder.cpython-310.pyc,,
+transformers/models/vision_encoder_decoder/__pycache__/modeling_flax_vision_encoder_decoder.cpython-310.pyc,,
+transformers/models/vision_encoder_decoder/__pycache__/modeling_tf_vision_encoder_decoder.cpython-310.pyc,,
+transformers/models/vision_encoder_decoder/__pycache__/modeling_vision_encoder_decoder.cpython-310.pyc,,
+transformers/models/vision_encoder_decoder/configuration_vision_encoder_decoder.py,sha256=6uLyTC16qnr7xboS9yTb1C6OvVWu2snFata6p85Crcs,8475
+transformers/models/vision_encoder_decoder/modeling_flax_vision_encoder_decoder.py,sha256=K_vwvC2W7Sz_j4gh3DbnplwdIH3zRNA5Tlk9v-qbxBw,41615
+transformers/models/vision_encoder_decoder/modeling_tf_vision_encoder_decoder.py,sha256=t7zHO-hBGMm-wlMQQN7x-nCBqUclSXP93U--Iun8iG8,36115
+transformers/models/vision_encoder_decoder/modeling_vision_encoder_decoder.py,sha256=v_NB7MvPBW43uw4u9_fmiyaHxUvl4ov4YxEGbSZKRfM,29366
+transformers/models/vision_text_dual_encoder/__init__.py,sha256=LRXs5oXk4_8AaHuIVaj1IgBO4X1vwP-ehQC1T1xEiAI,1198
+transformers/models/vision_text_dual_encoder/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vision_text_dual_encoder/__pycache__/configuration_vision_text_dual_encoder.cpython-310.pyc,,
+transformers/models/vision_text_dual_encoder/__pycache__/modeling_flax_vision_text_dual_encoder.cpython-310.pyc,,
+transformers/models/vision_text_dual_encoder/__pycache__/modeling_tf_vision_text_dual_encoder.cpython-310.pyc,,
+transformers/models/vision_text_dual_encoder/__pycache__/modeling_vision_text_dual_encoder.cpython-310.pyc,,
+transformers/models/vision_text_dual_encoder/__pycache__/processing_vision_text_dual_encoder.cpython-310.pyc,,
+transformers/models/vision_text_dual_encoder/configuration_vision_text_dual_encoder.py,sha256=Zqb3nGZWG-J3a2FPUY4ocbDYWiLVeZOiFua-MXTDUfQ,5023
+transformers/models/vision_text_dual_encoder/modeling_flax_vision_text_dual_encoder.py,sha256=ejVh6jvNJhfxXc70KAyy0UZxj_xWpcrly7sbUclBi54,26399
+transformers/models/vision_text_dual_encoder/modeling_tf_vision_text_dual_encoder.py,sha256=NnCOaAYtjQ4yUv90Am7cHnxKU9VgDDnXGQqnJSsgEs4,28626
+transformers/models/vision_text_dual_encoder/modeling_vision_text_dual_encoder.py,sha256=el2H0m-8HOaVL4ev5aOxhnVO9W-uCiw8-21aLchm25A,18131
+transformers/models/vision_text_dual_encoder/processing_vision_text_dual_encoder.py,sha256=NaSfdOb-SyoDuXHgAdZxA-tk1pRTlkFB5xFN5dYM-6I,6772
+transformers/models/visual_bert/__init__.py,sha256=zZFHfkE7OUMZUwYvB7v4ZIBXVUW9Mboqoa1QdTQURWM,1003
+transformers/models/visual_bert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/visual_bert/__pycache__/configuration_visual_bert.cpython-310.pyc,,
+transformers/models/visual_bert/__pycache__/modeling_visual_bert.cpython-310.pyc,,
+transformers/models/visual_bert/configuration_visual_bert.py,sha256=4U17YnlSjbOpzsAPdGH_EfvBjv7jppbHWlmLBrchGM4,6767
+transformers/models/visual_bert/modeling_visual_bert.py,sha256=NlRjZauVj-ky_Zk5mFPmsmA-VbO1gyNnKU-mjACIr_o,70241
+transformers/models/vit/__init__.py,sha256=uTQRjeWgJLHyXfc7yVOEyv7wnr42Jhy-8p9k5UUbxAM,1186
+transformers/models/vit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vit/__pycache__/configuration_vit.cpython-310.pyc,,
+transformers/models/vit/__pycache__/feature_extraction_vit.cpython-310.pyc,,
+transformers/models/vit/__pycache__/image_processing_vit.cpython-310.pyc,,
+transformers/models/vit/__pycache__/image_processing_vit_fast.cpython-310.pyc,,
+transformers/models/vit/__pycache__/modeling_flax_vit.cpython-310.pyc,,
+transformers/models/vit/__pycache__/modeling_tf_vit.cpython-310.pyc,,
+transformers/models/vit/__pycache__/modeling_vit.cpython-310.pyc,,
+transformers/models/vit/configuration_vit.py,sha256=qzjqndsRc6Pyd8YiTFvAbe-OIIJyRSPOdUFKVSJB2Fg,6290
+transformers/models/vit/feature_extraction_vit.py,sha256=v5PPSon24ldH0wC-42BQTxGakc-ow2aUh-Egq5D9hJw,1276
+transformers/models/vit/image_processing_vit.py,sha256=MOU1FkkDPH2tVUOENE26fv5sVhWqxDc6n7VaeqYp05o,14429
+transformers/models/vit/image_processing_vit_fast.py,sha256=yrkXCSNPpRXfBiQhsgLao-dFOALdBrWa4dDOwZvGiwQ,1237
+transformers/models/vit/modeling_flax_vit.py,sha256=95SBab3CAIoD3bwgWfN6Y7v44fR6EHNJVDuPqi-FOX8,25503
+transformers/models/vit/modeling_tf_vit.py,sha256=r__S8GF7AS7xbOpnVp_JOdE4ByH1H1WBnv1CZdGLTmE,37321
+transformers/models/vit/modeling_vit.py,sha256=k6LmZos-liCSt4kCsHxcLQFtabBaCBz9eFk5iwBMqik,28910
+transformers/models/vit_mae/__init__.py,sha256=C8NcxWwzXlNMeMOA9DNHfDYvRF9biIuUduuwhoaTTD8,1034
+transformers/models/vit_mae/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vit_mae/__pycache__/configuration_vit_mae.cpython-310.pyc,,
+transformers/models/vit_mae/__pycache__/modeling_tf_vit_mae.cpython-310.pyc,,
+transformers/models/vit_mae/__pycache__/modeling_vit_mae.cpython-310.pyc,,
+transformers/models/vit_mae/configuration_vit_mae.py,sha256=3nnWDAbp6WLfOHLO3taJUNEuGRlk3oAa0qaLEEJgjHQ,6372
+transformers/models/vit_mae/modeling_tf_vit_mae.py,sha256=GKXpysqOcon8KW-3KRQoG9mvLBb5b8mIk2Ix6VQyYhE,58009
+transformers/models/vit_mae/modeling_vit_mae.py,sha256=Svb4ZtsfzsALVitOq4bsywtgtn-gg2Qb-okvLk77VBY,40948
+transformers/models/vit_msn/__init__.py,sha256=Y1g56VRSNr-PxS-g4Cp2IlRR5M9CiaFGlhAQXwszGHo,995
+transformers/models/vit_msn/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vit_msn/__pycache__/configuration_vit_msn.cpython-310.pyc,,
+transformers/models/vit_msn/__pycache__/modeling_vit_msn.cpython-310.pyc,,
+transformers/models/vit_msn/configuration_vit_msn.py,sha256=HeU0UloranISU9zLiPsK0CyooMacqogTNmwE4xp2N-o,4864
+transformers/models/vit_msn/modeling_vit_msn.py,sha256=Kdd1XU5mDESK4v_Jsp6lUgrHVXwmNerslODuj4lNcjU,24236
+transformers/models/vitdet/__init__.py,sha256=13LNGZwvKK3tBrQWVs43rQbxbgqvxLfnM0uMqomHqhM,993
+transformers/models/vitdet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vitdet/__pycache__/configuration_vitdet.cpython-310.pyc,,
+transformers/models/vitdet/__pycache__/modeling_vitdet.cpython-310.pyc,,
+transformers/models/vitdet/configuration_vitdet.py,sha256=CM18kVFmgjDEp7leQPG0L60VKNmBebmxYvEGZN4Kvlg,7541
+transformers/models/vitdet/modeling_vitdet.py,sha256=tGJl5_5BJ1P8NkMkDGicQ5MDoHWUdHjDR2UfBiLmWvQ,32395
+transformers/models/vitmatte/__init__.py,sha256=al6dWrth9LhRLjmVZrxSi0SRcMMUH_UNpMmR5nwflSc,1092
+transformers/models/vitmatte/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vitmatte/__pycache__/configuration_vitmatte.cpython-310.pyc,,
+transformers/models/vitmatte/__pycache__/image_processing_vitmatte.cpython-310.pyc,,
+transformers/models/vitmatte/__pycache__/image_processing_vitmatte_fast.cpython-310.pyc,,
+transformers/models/vitmatte/__pycache__/modeling_vitmatte.cpython-310.pyc,,
+transformers/models/vitmatte/configuration_vitmatte.py,sha256=4o0WTCZLL3RcipC5atxgQU6zO9x8hgrWOs83olgQM2Q,6460
+transformers/models/vitmatte/image_processing_vitmatte.py,sha256=dXRNvL7ix2bEencYaq7-7S2kXlmNtViHYw95CJJaU68,13554
+transformers/models/vitmatte/image_processing_vitmatte_fast.py,sha256=RHVAF8eM5_8tysejotdcWG6p6lYPOkzMdK9B2l3iayg,6765
+transformers/models/vitmatte/modeling_vitmatte.py,sha256=Xw_A4MvjsM34PDy5XxkZ26mbYm7WP8wiYhbVc4O6k0Y,10618
+transformers/models/vitpose/__init__.py,sha256=VA7aRcVMgFJH46i6HurkXJS0Z38BotU3H3o3e2wgyXU,1039
+transformers/models/vitpose/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vitpose/__pycache__/configuration_vitpose.cpython-310.pyc,,
+transformers/models/vitpose/__pycache__/image_processing_vitpose.cpython-310.pyc,,
+transformers/models/vitpose/__pycache__/modeling_vitpose.cpython-310.pyc,,
+transformers/models/vitpose/configuration_vitpose.py,sha256=Ij3xe1cFLDOuIJYUTh-SP2UPKSf9pHwXlLwKRDtcqdc,6015
+transformers/models/vitpose/image_processing_vitpose.py,sha256=3pF3NhIoID8Yw3SDOAdVZBJPUJtxabpAgkwrCArTg34,29590
+transformers/models/vitpose/modeling_vitpose.py,sha256=P0Z-Lkk2Xs78afozLEsvkgoVBq6nBMsTYDDZiJ2appg,11713
+transformers/models/vitpose_backbone/__init__.py,sha256=W5IjP47Ykg5KRs8S9ztAbtfQ__n6sbJUZG4UDIGdGmA,577
+transformers/models/vitpose_backbone/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vitpose_backbone/__pycache__/configuration_vitpose_backbone.cpython-310.pyc,,
+transformers/models/vitpose_backbone/__pycache__/modeling_vitpose_backbone.cpython-310.pyc,,
+transformers/models/vitpose_backbone/configuration_vitpose_backbone.py,sha256=k17SrNK_1I7cE43C3Cu2ZU5V5VnWQA7RsmOSSzXCEME,6651
+transformers/models/vitpose_backbone/modeling_vitpose_backbone.py,sha256=Iacxen1X4uAd-C8EY6gtO8oYTptxdySasqJf-k8HzC4,19298
+transformers/models/vits/__init__.py,sha256=7baZcqGvFlYQxAl721XtMptMZKkzvBOa2ttyOhqhUtk,1026
+transformers/models/vits/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vits/__pycache__/configuration_vits.cpython-310.pyc,,
+transformers/models/vits/__pycache__/modeling_vits.cpython-310.pyc,,
+transformers/models/vits/__pycache__/tokenization_vits.cpython-310.pyc,,
+transformers/models/vits/configuration_vits.py,sha256=OT42q2ihf2Q9r9qm7JJM4gJlOqQSZyVH8Jk3Qsbcji0,13892
+transformers/models/vits/modeling_vits.py,sha256=qNk_ZWLxxwlvoKaEx-HkktFvp1wygyM0TQILF1Sjcsk,61965
+transformers/models/vits/tokenization_vits.py,sha256=hMWf72PabgSlH-UJjN4-ddrNQGb8n5e7d5mSXuGTK9U,9369
+transformers/models/vivit/__init__.py,sha256=LT2FipIBdB69s9UY4viyuB5q2e0v3bCwtQMiOEOj2xg,1033
+transformers/models/vivit/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vivit/__pycache__/configuration_vivit.cpython-310.pyc,,
+transformers/models/vivit/__pycache__/image_processing_vivit.cpython-310.pyc,,
+transformers/models/vivit/__pycache__/modeling_vivit.cpython-310.pyc,,
+transformers/models/vivit/configuration_vivit.py,sha256=TVsjmzoXac2Xh0zcHS8fy0RmFivbol3WsO7kj-gKZik,5142
+transformers/models/vivit/image_processing_vivit.py,sha256=ocG2i431U5hruiWC2kR4z6qnGWyh4L98jnqB9fSSiC0,19245
+transformers/models/vivit/modeling_vivit.py,sha256=39mwrAx7bRnIseFTW0jBZhPUCzlOa7jC-0c1Y9ZRTSQ,28598
+transformers/models/vjepa2/__init__.py,sha256=uG8tvHYoCxXAMjQuCfsT56YCg0l8_2e6H5Nm7L7Ygm0,1056
+transformers/models/vjepa2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/vjepa2/__pycache__/configuration_vjepa2.cpython-310.pyc,,
+transformers/models/vjepa2/__pycache__/modeling_vjepa2.cpython-310.pyc,,
+transformers/models/vjepa2/__pycache__/video_processing_vjepa2.cpython-310.pyc,,
+transformers/models/vjepa2/configuration_vjepa2.py,sha256=mpPeIpTffMjlfOJ5m0mM_wj16znJAKUabh3S1EGvcoM,7055
+transformers/models/vjepa2/modeling_vjepa2.py,sha256=N-GhFhP81EjnSSCIpvj1NNI6mWm5-5sf192YZWZyrC8,50076
+transformers/models/vjepa2/video_processing_vjepa2.py,sha256=nnb_IGGov_QaZRveFkQUI6aEpZs8d0YsJehp6JSb9GQ,2120
+transformers/models/voxtral/__init__.py,sha256=hARPigCbvhSlR0iKCDkHcUnsXtoCgXnLFSgZnw5HQus,1053
+transformers/models/voxtral/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/voxtral/__pycache__/configuration_voxtral.cpython-310.pyc,,
+transformers/models/voxtral/__pycache__/modeling_voxtral.cpython-310.pyc,,
+transformers/models/voxtral/__pycache__/modular_voxtral.cpython-310.pyc,,
+transformers/models/voxtral/__pycache__/processing_voxtral.cpython-310.pyc,,
+transformers/models/voxtral/configuration_voxtral.py,sha256=y_8_udDNsK5Zsy6JAkbIJ7QhMYCDLwHNwp1QhQcYmDs,8474
+transformers/models/voxtral/modeling_voxtral.py,sha256=2gS0appbVSpTEYD_f9FlNuCHGcaV-1rTu-CTwEXWNYY,23093
+transformers/models/voxtral/modular_voxtral.py,sha256=OWGTupoG_2NNsrXJabIjHujHu3blkk8vCINvjlstn9Y,11607
+transformers/models/voxtral/processing_voxtral.py,sha256=ieJGN3rAIGJrKX2r6M1ZTfjr1oBNE4ahaVS3tse2fbo,19847
+transformers/models/wav2vec2/__init__.py,sha256=5nXyY4dA0h9iNUQZrGAUXtjOnU6KbVq2B1gRzEGEUNI,1206
+transformers/models/wav2vec2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/wav2vec2/__pycache__/configuration_wav2vec2.cpython-310.pyc,,
+transformers/models/wav2vec2/__pycache__/feature_extraction_wav2vec2.cpython-310.pyc,,
+transformers/models/wav2vec2/__pycache__/modeling_flax_wav2vec2.cpython-310.pyc,,
+transformers/models/wav2vec2/__pycache__/modeling_tf_wav2vec2.cpython-310.pyc,,
+transformers/models/wav2vec2/__pycache__/modeling_wav2vec2.cpython-310.pyc,,
+transformers/models/wav2vec2/__pycache__/processing_wav2vec2.cpython-310.pyc,,
+transformers/models/wav2vec2/__pycache__/tokenization_wav2vec2.cpython-310.pyc,,
+transformers/models/wav2vec2/configuration_wav2vec2.py,sha256=A4XGuSVpZUfWvd-ZJPkcGhISsBSNtSgUCNU2gN0mZos,20100
+transformers/models/wav2vec2/feature_extraction_wav2vec2.py,sha256=OTlRDKVJjkM2J93nN-PRW8xWetFO6Q7TsoRHLvew2pA,11609
+transformers/models/wav2vec2/modeling_flax_wav2vec2.py,sha256=wNg0oJf6PG6T-CDeMbcnIBjE5Kamo8Rq3LymOCaCWW4,57355
+transformers/models/wav2vec2/modeling_tf_wav2vec2.py,sha256=CLzi1cUuo9m0Dbi9ydK4sS7E4z39ZhVI7tFUOIsxMJM,78572
+transformers/models/wav2vec2/modeling_wav2vec2.py,sha256=4LvnsiwPYGRydknnxUIsCa25iPXmKiN4961zdmmT2rU,101110
+transformers/models/wav2vec2/processing_wav2vec2.py,sha256=QRw1AtMsVbdXWcrjB9_-hRxMeR2ymOdeIasydqNib60,8198
+transformers/models/wav2vec2/tokenization_wav2vec2.py,sha256=xaEOdRxousCdBFo4_snzcolYYFEype-apHZsIhhWxLc,38782
+transformers/models/wav2vec2_bert/__init__.py,sha256=DL010VL3ZV3lAugPH-BOTNSgIedotOEaoy8iHo0sC1Q,1051
+transformers/models/wav2vec2_bert/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/wav2vec2_bert/__pycache__/configuration_wav2vec2_bert.cpython-310.pyc,,
+transformers/models/wav2vec2_bert/__pycache__/modeling_wav2vec2_bert.cpython-310.pyc,,
+transformers/models/wav2vec2_bert/__pycache__/modular_wav2vec2_bert.cpython-310.pyc,,
+transformers/models/wav2vec2_bert/__pycache__/processing_wav2vec2_bert.cpython-310.pyc,,
+transformers/models/wav2vec2_bert/configuration_wav2vec2_bert.py,sha256=XpsUE-kvk4hTixrK5sbClT8A5j46A3XwzBcwWDs5E7g,18142
+transformers/models/wav2vec2_bert/modeling_wav2vec2_bert.py,sha256=Emceflb16OQkPzj9qOSLHuvFvY_iK4RcPOE5HZDAk04,66112
+transformers/models/wav2vec2_bert/modular_wav2vec2_bert.py,sha256=P5aTojdAUWsG0c9Xpwx2_AWJ_uNCaM178AdVgyAl3bs,44968
+transformers/models/wav2vec2_bert/processing_wav2vec2_bert.py,sha256=5djx8gsvNU7U8FRCeIJaT5nL7fa0Qp5w6R1Nf2KR734,7534
+transformers/models/wav2vec2_conformer/__init__.py,sha256=JBpapW8VF3yck4Bk29xKyUiQZqB_CXLSYtYxXGXAu2Q,1017
+transformers/models/wav2vec2_conformer/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/wav2vec2_conformer/__pycache__/configuration_wav2vec2_conformer.cpython-310.pyc,,
+transformers/models/wav2vec2_conformer/__pycache__/modeling_wav2vec2_conformer.cpython-310.pyc,,
+transformers/models/wav2vec2_conformer/__pycache__/modular_wav2vec2_conformer.cpython-310.pyc,,
+transformers/models/wav2vec2_conformer/configuration_wav2vec2_conformer.py,sha256=gBeb_cZC5XCDOmg1llPUQ0ELDS-1u0_eGZRrA98tLxM,20938
+transformers/models/wav2vec2_conformer/modeling_wav2vec2_conformer.py,sha256=B6phrzXQ6dRqei4iYYEHQfLuQKle_Mhzzk1cUKIPNeM,85453
+transformers/models/wav2vec2_conformer/modular_wav2vec2_conformer.py,sha256=cN06htxwL8TzvsONXVG5C7SAFbEnfmUioxdtD-He_1s,30769
+transformers/models/wav2vec2_phoneme/__init__.py,sha256=LV4FKcFYNt0GuJvfsUOwTYVFRVfuzUuclKRybFyN9lk,967
+transformers/models/wav2vec2_phoneme/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/wav2vec2_phoneme/__pycache__/tokenization_wav2vec2_phoneme.cpython-310.pyc,,
+transformers/models/wav2vec2_phoneme/tokenization_wav2vec2_phoneme.py,sha256=DdFdFOAOhnhy5Iq6U-eno8m-bgLbGC-2xiHauNhszd4,23217
+transformers/models/wav2vec2_with_lm/__init__.py,sha256=yZKHsma85j7AMLB8g8uNXL5D_E5Gc3Vqe-D-V2W15oY,965
+transformers/models/wav2vec2_with_lm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/wav2vec2_with_lm/__pycache__/processing_wav2vec2_with_lm.cpython-310.pyc,,
+transformers/models/wav2vec2_with_lm/processing_wav2vec2_with_lm.py,sha256=cxCksE0dl-HONpCWGgzV_gfr-SHiDMhuZaoPB-LTl5Q,30031
+transformers/models/wavlm/__init__.py,sha256=wYnYuOpw2e95lauqDbD7u3OC-Pez8yoRsrgExSh_WJQ,991
+transformers/models/wavlm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/wavlm/__pycache__/configuration_wavlm.cpython-310.pyc,,
+transformers/models/wavlm/__pycache__/modeling_wavlm.cpython-310.pyc,,
+transformers/models/wavlm/__pycache__/modular_wavlm.cpython-310.pyc,,
+transformers/models/wavlm/configuration_wavlm.py,sha256=HrK0dtsxcVB-k3yO2px6RS-TW1lonvx_x8uRkz7iJqQ,18588
+transformers/models/wavlm/modeling_wavlm.py,sha256=O91Gzm72L0nSRG-Q-JiCO0AsLTEJosHza5BsEHh504Q,72556
+transformers/models/wavlm/modular_wavlm.py,sha256=4sgAWhmP5YPHzYuK-T3gjrh-Tu4VjOutEVAf8k4nDgQ,23178
+transformers/models/whisper/__init__.py,sha256=qT70wGFDyOsAGuyaHe9if7kn8fxK2shCe6rovr3onw4,1244
+transformers/models/whisper/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/configuration_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/english_normalizer.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/feature_extraction_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/generation_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/modeling_flax_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/modeling_tf_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/modeling_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/processing_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/tokenization_whisper.cpython-310.pyc,,
+transformers/models/whisper/__pycache__/tokenization_whisper_fast.cpython-310.pyc,,
+transformers/models/whisper/configuration_whisper.py,sha256=CZgcgXbDdSSxvAwvJ0BmsVuhJLFOVgeGKnKn83yz978,17102
+transformers/models/whisper/english_normalizer.py,sha256=GmqBtyvGnsz2HXoksWAVu2wxJJJUclq-CSdH40jP51g,22857
+transformers/models/whisper/feature_extraction_whisper.py,sha256=43vzBLDCjU8a02N8-muLTY2V4Be7Q5D0bSP0kdU334g,16171
+transformers/models/whisper/generation_whisper.py,sha256=jAWD5OSjG-Zg9HKlY7ZwirRXx3Cx1-wdxlddJSwj4LU,110510
+transformers/models/whisper/modeling_flax_whisper.py,sha256=Sdt-z5ZQXvD6I501rsCdPHmX5UuVtz1nWCmpt8ub5YY,74027
+transformers/models/whisper/modeling_tf_whisper.py,sha256=AkTDnM5YLd2hN3yjUnB9ILQ5IOW44DCpCvXnTRvT42I,84663
+transformers/models/whisper/modeling_whisper.py,sha256=dHZ0hIuAOVjL4f_4QBOij1MxyrfUOA2cU5dv0Z9HX-M,74509
+transformers/models/whisper/processing_whisper.py,sha256=HqD-DDmkNIbHgDLFgky6hYu8WeuOv0kV6nFkDNBE4yg,3341
+transformers/models/whisper/tokenization_whisper.py,sha256=JxHC6ryKd8kjOLXOIjKf37jdEf48Y1McdrWcmotRLHc,58409
+transformers/models/whisper/tokenization_whisper_fast.py,sha256=Q6HdLOFUejR-aEIJZo0SkCkIQCtFL7eSSyvSEJWbaJ0,30284
+transformers/models/x_clip/__init__.py,sha256=ufjh6w7SNuNAUjAHp_MK3yRcrHm22-SfhZ0ZfbiXhGw,1030
+transformers/models/x_clip/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/x_clip/__pycache__/configuration_x_clip.cpython-310.pyc,,
+transformers/models/x_clip/__pycache__/modeling_x_clip.cpython-310.pyc,,
+transformers/models/x_clip/__pycache__/processing_x_clip.cpython-310.pyc,,
+transformers/models/x_clip/configuration_x_clip.py,sha256=s3aGXvewhpL5nrY57j9KihuGZYZY62xlJXCmtJ1AYjg,18244
+transformers/models/x_clip/modeling_x_clip.py,sha256=5GnhitjlPp723wj5RuJYzHcOed82z0Uc_eSWDA5ejFs,65591
+transformers/models/x_clip/processing_x_clip.py,sha256=YkI7DdXBWAa5XOsOEV5G-hNDeiota5ZwJBaWUSWZzeE,6190
+transformers/models/xcodec/__init__.py,sha256=X16pTVB3loZ9OMnqHAaxInF1X5EOhxlmHjyxEvoqSWE,993
+transformers/models/xcodec/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xcodec/__pycache__/configuration_xcodec.cpython-310.pyc,,
+transformers/models/xcodec/__pycache__/modeling_xcodec.cpython-310.pyc,,
+transformers/models/xcodec/configuration_xcodec.py,sha256=8V_u-p5JvxnpvH1ajT0GF5kb5Yh_FPrP9tydEusfHqQ,7932
+transformers/models/xcodec/modeling_xcodec.py,sha256=M2Dz0E6vg8CDzUgVSFis1Y-T749Ajag6_ikAOpLJW5U,23050
+transformers/models/xglm/__init__.py,sha256=ZU7tQBmBXzr8wh9MJNDZ5uIrsCRQP8tuNrpGDd2W3OI,1142
+transformers/models/xglm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xglm/__pycache__/configuration_xglm.cpython-310.pyc,,
+transformers/models/xglm/__pycache__/modeling_flax_xglm.cpython-310.pyc,,
+transformers/models/xglm/__pycache__/modeling_tf_xglm.cpython-310.pyc,,
+transformers/models/xglm/__pycache__/modeling_xglm.cpython-310.pyc,,
+transformers/models/xglm/__pycache__/tokenization_xglm.cpython-310.pyc,,
+transformers/models/xglm/__pycache__/tokenization_xglm_fast.cpython-310.pyc,,
+transformers/models/xglm/configuration_xglm.py,sha256=m0sfPYf0qKl0pT9sOd3ssoQv13yt5IWRnUn11aGDa1Q,5881
+transformers/models/xglm/modeling_flax_xglm.py,sha256=BLW965ik0iRDR9fGbbw82SyuDxNs__9qKdQxZLPq7XI,33217
+transformers/models/xglm/modeling_tf_xglm.py,sha256=CHMd92nY-UsHA-lPDKOKdrPXHKUFWh3_7CDEGvmzy3E,45026
+transformers/models/xglm/modeling_xglm.py,sha256=UYC7FOU0Sra8p_nRnETvHDEGwpTfAeri-tS55im_Dws,32784
+transformers/models/xglm/tokenization_xglm.py,sha256=lzdJEYP3S8w-HLa5nX7BAllqXQWnmr49kQsSYl3Cxe4,12576
+transformers/models/xglm/tokenization_xglm_fast.py,sha256=4G278mqxvBG0onsXTichXPRki94OiZJZ3Ioy4t6TfKQ,7470
+transformers/models/xlm/__init__.py,sha256=QevE83gMJ5h41H7EKxRAUN-kmE0zgOsyGj6QzWcpjmk,1058
+transformers/models/xlm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xlm/__pycache__/configuration_xlm.cpython-310.pyc,,
+transformers/models/xlm/__pycache__/modeling_tf_xlm.cpython-310.pyc,,
+transformers/models/xlm/__pycache__/modeling_xlm.cpython-310.pyc,,
+transformers/models/xlm/__pycache__/tokenization_xlm.cpython-310.pyc,,
+transformers/models/xlm/configuration_xlm.py,sha256=k216zyLI3r20HXsFfesj0QQiF-4oCxjUM3ONCxJZtzY,11062
+transformers/models/xlm/modeling_tf_xlm.py,sha256=kEPNqT6vET9FaGDUoo8-wfmCkmFIMnfU3XVPUyAVN8E,56527
+transformers/models/xlm/modeling_xlm.py,sha256=aj4OggkCBXh0bmM4gp56F7QozM9pk1D4lTG0TE-LzBo,75111
+transformers/models/xlm/tokenization_xlm.py,sha256=on-cVBeHILqyhqK5xOY9PP49TIB2HNwItq3Y_9uOtCI,23347
+transformers/models/xlm_roberta/__init__.py,sha256=dhjej7PBi8UrfXRkTxh9CWXnw8wuLZHPT9FYFfCkIHg,1184
+transformers/models/xlm_roberta/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xlm_roberta/__pycache__/configuration_xlm_roberta.cpython-310.pyc,,
+transformers/models/xlm_roberta/__pycache__/modeling_flax_xlm_roberta.cpython-310.pyc,,
+transformers/models/xlm_roberta/__pycache__/modeling_tf_xlm_roberta.cpython-310.pyc,,
+transformers/models/xlm_roberta/__pycache__/modeling_xlm_roberta.cpython-310.pyc,,
+transformers/models/xlm_roberta/__pycache__/tokenization_xlm_roberta.cpython-310.pyc,,
+transformers/models/xlm_roberta/__pycache__/tokenization_xlm_roberta_fast.cpython-310.pyc,,
+transformers/models/xlm_roberta/configuration_xlm_roberta.py,sha256=A_vz0mpN0KhV6dbuOO8FR5qFCXXYeSASknBS_kVLXPM,7596
+transformers/models/xlm_roberta/modeling_flax_xlm_roberta.py,sha256=ndYuXyoj_I5xVW2TWB5SrXt_D3hlqShvbOY-tW0eOkM,58777
+transformers/models/xlm_roberta/modeling_tf_xlm_roberta.py,sha256=pFUXeNncEmL8gNGKg3Mwkh6B-db2yKXgnf5ZvrlN-Go,81896
+transformers/models/xlm_roberta/modeling_xlm_roberta.py,sha256=wU6iR16yeCb1LUdwb5QAlBltsUux9otavSUfwPL1OHc,71844
+transformers/models/xlm_roberta/tokenization_xlm_roberta.py,sha256=GYqlEjrwdzxZ1xdDuCpJRAKEZAIPuBdGWetCD7eXpzw,12804
+transformers/models/xlm_roberta/tokenization_xlm_roberta_fast.py,sha256=ojIIHjd2wELfeiFylqMYN0iYMeEaAtimZFOHVAFYkkM,7808
+transformers/models/xlm_roberta_xl/__init__.py,sha256=V0fXTKk2hQmf5dKogCJ0HSiRBxVX-rs7c414ZoZIh28,1009
+transformers/models/xlm_roberta_xl/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xlm_roberta_xl/__pycache__/configuration_xlm_roberta_xl.cpython-310.pyc,,
+transformers/models/xlm_roberta_xl/__pycache__/modeling_xlm_roberta_xl.cpython-310.pyc,,
+transformers/models/xlm_roberta_xl/configuration_xlm_roberta_xl.py,sha256=f8cw938xnzVrNMZA9C6A0wIQm_mmtUr6EMQAgamN9Sw,7348
+transformers/models/xlm_roberta_xl/modeling_xlm_roberta_xl.py,sha256=BLuHohoPkY18LgkiCkMPaJl34qaGh7ADdo2xAMawovU,66898
+transformers/models/xlnet/__init__.py,sha256=t-UvrFyorGF7VMuATzjrB_cUqKsM-8O9KqxiWjtJqhs,1109
+transformers/models/xlnet/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xlnet/__pycache__/configuration_xlnet.cpython-310.pyc,,
+transformers/models/xlnet/__pycache__/modeling_tf_xlnet.cpython-310.pyc,,
+transformers/models/xlnet/__pycache__/modeling_xlnet.cpython-310.pyc,,
+transformers/models/xlnet/__pycache__/tokenization_xlnet.cpython-310.pyc,,
+transformers/models/xlnet/__pycache__/tokenization_xlnet_fast.cpython-310.pyc,,
+transformers/models/xlnet/configuration_xlnet.py,sha256=U_WpCoqALv86cbvTXgTVnJwOfl3nzcGTgZJd_9SDhvY,10953
+transformers/models/xlnet/modeling_tf_xlnet.py,sha256=FjkGozmhkH6qIPhQO15VCkDJMWOVj2QD7aCR3Nb12wQ,77744
+transformers/models/xlnet/modeling_xlnet.py,sha256=rzkZRV_HSH-iY3LgmwmRYkRriz8uP2mFid-euskYGKE,106723
+transformers/models/xlnet/tokenization_xlnet.py,sha256=8GVn73lPjtz6PljvlLuwvuNCElWfbLHfHtdYaI8XrS8,15800
+transformers/models/xlnet/tokenization_xlnet_fast.py,sha256=ZfWE9TWuq8NC7Q3Z2y-plAofp0o9PtQEu08U4M7Qx6s,9247
+transformers/models/xlstm/__init__.py,sha256=-Vfj7bUcDAD3TguoDgKW0zpzZ8KtOmnUNwSkvL6Df8k,1047
+transformers/models/xlstm/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xlstm/__pycache__/configuration_xlstm.cpython-310.pyc,,
+transformers/models/xlstm/__pycache__/modeling_xlstm.cpython-310.pyc,,
+transformers/models/xlstm/configuration_xlstm.py,sha256=jXCuoIYX4cb4atgAMjgove47wmm6dkTStY4hAFC3wZI,12847
+transformers/models/xlstm/modeling_xlstm.py,sha256=BnotrS9a_bbfzMSOycNp8G7cE2BmSJoTi2kCb8K0vOo,65995
+transformers/models/xmod/__init__.py,sha256=WLxIbzC8oCEkMrerWHTy7GLopz0mqocSaacdcyb_BhQ,989
+transformers/models/xmod/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/xmod/__pycache__/configuration_xmod.cpython-310.pyc,,
+transformers/models/xmod/__pycache__/modeling_xmod.cpython-310.pyc,,
+transformers/models/xmod/configuration_xmod.py,sha256=W5bQLbTh3EhMd-Lvseyl28uQhkVVCdPSdhcRXJO7hcg,9180
+transformers/models/xmod/modeling_xmod.py,sha256=9Zdw_uwjvAoty8lx-jqXnEoraIp2LdcE2sWYWEdrt0k,68666
+transformers/models/yolos/__init__.py,sha256=UlbQDtMQJaGRcin-iz6NOEFWT8otanBndRuw4VrWUiQ,1124
+transformers/models/yolos/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/yolos/__pycache__/configuration_yolos.cpython-310.pyc,,
+transformers/models/yolos/__pycache__/feature_extraction_yolos.cpython-310.pyc,,
+transformers/models/yolos/__pycache__/image_processing_yolos.cpython-310.pyc,,
+transformers/models/yolos/__pycache__/image_processing_yolos_fast.cpython-310.pyc,,
+transformers/models/yolos/__pycache__/modeling_yolos.cpython-310.pyc,,
+transformers/models/yolos/__pycache__/modular_yolos.cpython-310.pyc,,
+transformers/models/yolos/configuration_yolos.py,sha256=3MosWcNOUgTJ1pTBkCQT852fsnIDHomISTyCShOKo2k,7627
+transformers/models/yolos/feature_extraction_yolos.py,sha256=5wVaZnDzK3ROFChjwHYMHGv1aPmtq1IOqmt100yImtE,1594
+transformers/models/yolos/image_processing_yolos.py,sha256=qZ0IAI-zbLNFt4bM91OmeYfury9GxFgaNtdt15cZyHE,67983
+transformers/models/yolos/image_processing_yolos_fast.py,sha256=8IzDHEtMzP1eEBj2AaoGuSs8hni8IAil9Nzcp7B2nA0,37846
+transformers/models/yolos/modeling_yolos.py,sha256=jGee4xfVKFaY18QefuTujfUQDaLuv6uGTWTAbQlkdeA,30708
+transformers/models/yolos/modular_yolos.py,sha256=ZTEyzZtRQI7b1zKqP6wkaxY4TyC9dFbYKb7PQ_0Mwp4,8269
+transformers/models/yoso/__init__.py,sha256=sCXsXYZuOQLFkZMexRb8qY7EJCftR54G_eO7qIUvdss,989
+transformers/models/yoso/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/yoso/__pycache__/configuration_yoso.cpython-310.pyc,,
+transformers/models/yoso/__pycache__/modeling_yoso.cpython-310.pyc,,
+transformers/models/yoso/configuration_yoso.py,sha256=6PQqt0OjHQBTNnnhDE761sdwlq9_tqG48UJ-pBV3rBM,6715
+transformers/models/yoso/modeling_yoso.py,sha256=aWfgWaTtQZvX-w9Of_mJs14gcy52D5JJHHOaig4NZVI,49753
+transformers/models/zamba/__init__.py,sha256=iqZnf8BQ49TLcB4mYwIfuJeF4aGvYhOBRiGI6_74ZFk,991
+transformers/models/zamba/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/zamba/__pycache__/configuration_zamba.cpython-310.pyc,,
+transformers/models/zamba/__pycache__/modeling_zamba.cpython-310.pyc,,
+transformers/models/zamba/configuration_zamba.py,sha256=0sHrNCBHaMWoTLegdBSl2WFQBQtyMj4qb_XNO5cUM64,11292
+transformers/models/zamba/modeling_zamba.py,sha256=BhOKoFA63lcwbi6jYrHaVUFyRkj9PCZWz2rv4-AZRPs,63019
+transformers/models/zamba2/__init__.py,sha256=3FgH8KelorllnKF6ncpKGREwZXt6YwsQ7NPS8W6jcmQ,993
+transformers/models/zamba2/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/zamba2/__pycache__/configuration_zamba2.cpython-310.pyc,,
+transformers/models/zamba2/__pycache__/modeling_zamba2.cpython-310.pyc,,
+transformers/models/zamba2/__pycache__/modular_zamba2.cpython-310.pyc,,
+transformers/models/zamba2/configuration_zamba2.py,sha256=DNZAQNnBwPacTJy1yp7Dd8y9aW7HL3zFwa0xam1Fop8,12734
+transformers/models/zamba2/modeling_zamba2.py,sha256=hl4aac5j4nc_fYIvUS_AOFT-30hMypFR1yEB_lAhH8k,85007
+transformers/models/zamba2/modular_zamba2.py,sha256=asm0ELKFz3nw-57hbtAiul-KiUPlnpixgua2wQD25k8,56114
+transformers/models/zoedepth/__init__.py,sha256=BUGUeWtpJJRRdQGT1dIOi-B5v89Ae8eTTxbEmVqiu0k,1092
+transformers/models/zoedepth/__pycache__/__init__.cpython-310.pyc,,
+transformers/models/zoedepth/__pycache__/configuration_zoedepth.cpython-310.pyc,,
+transformers/models/zoedepth/__pycache__/image_processing_zoedepth.cpython-310.pyc,,
+transformers/models/zoedepth/__pycache__/image_processing_zoedepth_fast.cpython-310.pyc,,
+transformers/models/zoedepth/__pycache__/modeling_zoedepth.cpython-310.pyc,,
+transformers/models/zoedepth/configuration_zoedepth.py,sha256=gRQ2uRqmhfagYNHU3FkWJ4PPirYIe9Ve7GJ7ENW17mk,12972
+transformers/models/zoedepth/image_processing_zoedepth.py,sha256=jUzKeNx4VR-l9ps_VEshhfRC-ZB7pLHWw66ZRTSiX4s,28181
+transformers/models/zoedepth/image_processing_zoedepth_fast.py,sha256=FnYxAEzSeOylTTsxbYBeyxpjUvsHlNwrKD6y0l1CT3g,13761
+transformers/models/zoedepth/modeling_zoedepth.py,sha256=Y1tP8DAQNw2Gf9d0xfCToD5lRTPVzpCIioDbhNgezX0,54587
+transformers/onnx/__init__.py,sha256=wALLY4TPOK2iPrFcfZf_WiEmTRAU6dAWHElxGdexr58,1548
+transformers/onnx/__main__.py,sha256=JZ9ZmeRsnDitwTMWb-dFT8W9AEmMoMKLQ3SvbyCkY0w,9497
+transformers/onnx/__pycache__/__init__.cpython-310.pyc,,
+transformers/onnx/__pycache__/__main__.cpython-310.pyc,,
+transformers/onnx/__pycache__/config.cpython-310.pyc,,
+transformers/onnx/__pycache__/convert.cpython-310.pyc,,
+transformers/onnx/__pycache__/features.cpython-310.pyc,,
+transformers/onnx/__pycache__/utils.cpython-310.pyc,,
+transformers/onnx/config.py,sha256=soohSCWqM_jnG7TIzCeZz8Ugfzv2W_tlEokFb8Z7sRM,32617
+transformers/onnx/convert.py,sha256=1Skizwf9hyB2CQtNNwjwtuJT9EshegWQNcvPdJp4SNg,19418
+transformers/onnx/features.py,sha256=zRhGiYgzMMfvdh7UvCO9j_y0L9cbVbTSL88cItk_PBg,28276
+transformers/onnx/utils.py,sha256=39Uw_GkFBsTb6ZvMIHRTnI289aQDhc6hwfEapaBGE-o,3625
+transformers/optimization.py,sha256=QbCP-ynCaRYmsiXtOJppTMjmFICBghSjXyFbXDkWe_s,39971
+transformers/optimization_tf.py,sha256=JYL8tVbLyB3puGJ0b2i1gGaidCHSxm8_jYmm7z-ZJ-4,16718
+transformers/pipelines/__init__.py,sha256=pbvObirNq5c8koiMt-KelPFq2KfJdN5SO-wuF_xrE6g,85093
+transformers/pipelines/__pycache__/__init__.cpython-310.pyc,,
+transformers/pipelines/__pycache__/audio_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/audio_utils.cpython-310.pyc,,
+transformers/pipelines/__pycache__/automatic_speech_recognition.cpython-310.pyc,,
+transformers/pipelines/__pycache__/base.cpython-310.pyc,,
+transformers/pipelines/__pycache__/depth_estimation.cpython-310.pyc,,
+transformers/pipelines/__pycache__/document_question_answering.cpython-310.pyc,,
+transformers/pipelines/__pycache__/feature_extraction.cpython-310.pyc,,
+transformers/pipelines/__pycache__/fill_mask.cpython-310.pyc,,
+transformers/pipelines/__pycache__/image_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/image_feature_extraction.cpython-310.pyc,,
+transformers/pipelines/__pycache__/image_segmentation.cpython-310.pyc,,
+transformers/pipelines/__pycache__/image_text_to_text.cpython-310.pyc,,
+transformers/pipelines/__pycache__/image_to_image.cpython-310.pyc,,
+transformers/pipelines/__pycache__/image_to_text.cpython-310.pyc,,
+transformers/pipelines/__pycache__/keypoint_matching.cpython-310.pyc,,
+transformers/pipelines/__pycache__/mask_generation.cpython-310.pyc,,
+transformers/pipelines/__pycache__/object_detection.cpython-310.pyc,,
+transformers/pipelines/__pycache__/pt_utils.cpython-310.pyc,,
+transformers/pipelines/__pycache__/question_answering.cpython-310.pyc,,
+transformers/pipelines/__pycache__/table_question_answering.cpython-310.pyc,,
+transformers/pipelines/__pycache__/text2text_generation.cpython-310.pyc,,
+transformers/pipelines/__pycache__/text_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/text_generation.cpython-310.pyc,,
+transformers/pipelines/__pycache__/text_to_audio.cpython-310.pyc,,
+transformers/pipelines/__pycache__/token_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/video_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/visual_question_answering.cpython-310.pyc,,
+transformers/pipelines/__pycache__/zero_shot_audio_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/zero_shot_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/zero_shot_image_classification.cpython-310.pyc,,
+transformers/pipelines/__pycache__/zero_shot_object_detection.cpython-310.pyc,,
+transformers/pipelines/audio_classification.py,sha256=9U6AmVAPfPInduBbdued0nXZpMdj2nWTgV3S0m6golo,11188
+transformers/pipelines/audio_utils.py,sha256=Zy6IbcbsXP4_mJkwlfvUG4VRX88bcKhpH1_ZaxJmrX4,12269
+transformers/pipelines/automatic_speech_recognition.py,sha256=E9lzFQB5eYXPb19mwkNxWBKnG1UKKKF0-F_kD5_1YuU,33599
+transformers/pipelines/base.py,sha256=rj-a7vx0X298Q23MlMpJVbImBN78RDCaDDrRZTphLFU,69114
+transformers/pipelines/depth_estimation.py,sha256=ARwIxnh4S-gn9OgOfJpfNgKpdCD0hQIZg1B925OpPt8,6170
+transformers/pipelines/document_question_answering.py,sha256=eJ1AMIGk-f2xwR9DJOwP_XPKgMjr2kpH_nCz9jlMWyc,25786
+transformers/pipelines/feature_extraction.py,sha256=x6ZmfVcoT9TNWaPyM5S-zep_cCgTsFBFxe7B8QdrVTs,3564
+transformers/pipelines/fill_mask.py,sha256=Y6vPwyDxffya8e6MsxcZLoRnRrSp_dVEBdvjgmXN_Xo,12080
+transformers/pipelines/image_classification.py,sha256=LrAvZRwEC6Cqk9jlST1fD51VO67w6Hjm7q_gMdoxa7k,10232
+transformers/pipelines/image_feature_extraction.py,sha256=A6dLjcVoXGm-420YrBDzU29O3tanJAujT6-KpXw5d7w,4962
+transformers/pipelines/image_segmentation.py,sha256=BcswPSyXzbC_3IW6EYws10dwJxpBPS9JcrlbevBRD10,9976
+transformers/pipelines/image_text_to_text.py,sha256=Bfyy-UvXa2PgucQSQAOMDCzy1uoZqK_lG4RFy5lFMOs,24086
+transformers/pipelines/image_to_image.py,sha256=-4I7xiTDXcxptt8i4reI_n6rm1t-7QWwndm4MpJDD-0,5387
+transformers/pipelines/image_to_text.py,sha256=rn8nvu1PbKwzXYoA8QhPehP4kk8c5Z8urZnS0JzNTRU,10317
+transformers/pipelines/keypoint_matching.py,sha256=Xgi6zbnDIxofFGb2uHp8u1kn_z6UDjQWfU8wfrnol9c,7196
+transformers/pipelines/mask_generation.py,sha256=rzTNT-DLhGmF_oFYXZo0pw5ivLQLX0pc3-fx0tgD0xc,15533
+transformers/pipelines/object_detection.py,sha256=fLCAtvjdL_atexroUzkC9pfurffxQtblOSW5WMgkaoo,8642
+transformers/pipelines/pt_utils.py,sha256=DtNVgO1ud1n0bYMwJclMvnIJqtoNs9aedcXuCvJL_SM,12816
+transformers/pipelines/question_answering.py,sha256=QvTA1VqjEddB2YcW6FsGunRoHiYqHo-C-WS-ItyiSag,31095
+transformers/pipelines/table_question_answering.py,sha256=CyMI1X4A6AZyIPg5TdcNQYj8Thur4G7qm4JzcGSOYoE,20954
+transformers/pipelines/text2text_generation.py,sha256=S9NhbLvTm3cjVD-Ai6AOFrimeSty447OEKEcoeMqCys,18896
+transformers/pipelines/text_classification.py,sha256=LrmS2Etpkb_QCVjXpCxTYfA1Ds72uTUxSSUZ3rQ4yHs,11272
+transformers/pipelines/text_generation.py,sha256=kS9F9Q-dvJsFa1Vo7O8f9nqJhAJ7OmQFDSKSh5eFumE,27414
+transformers/pipelines/text_to_audio.py,sha256=tO1FZlZTND4wVD6RUOPowgD2YNzCrYhtQhjrglGqYGk,10602
+transformers/pipelines/token_classification.py,sha256=ejNCMJQj8yvnx1UD1JWAz8EJh7aFDn5tUt13PHe0oeU,30853
+transformers/pipelines/video_classification.py,sha256=lLXCowAUy7Hsy0AcyXOLJ0g_rZ5Yek1QYOa3McS0lD0,8236
+transformers/pipelines/visual_question_answering.py,sha256=v47WPs2TqnrmMuht-_48oOrLEuMoMtvmDUmmPhDoHVM,9819
+transformers/pipelines/zero_shot_audio_classification.py,sha256=YvLvZXxnvL718wFFWLnj6Glvk3jCUu4FRErCIq6nAc4,7028
+transformers/pipelines/zero_shot_classification.py,sha256=gMfncfItamTLHUldLcSqZhn9USCR2JESCBJfEl1Wzks,12553
+transformers/pipelines/zero_shot_image_classification.py,sha256=YCTIDSWDmmCkJUj50KpnHLbMZ51cBjpgx_s47Zcnrj0,8622
+transformers/pipelines/zero_shot_object_detection.py,sha256=tJNu8fhYCsGNHdh4jiHlWOeUnhcVC8wNs5nvdB7Mp00,10740
+transformers/processing_utils.py,sha256=ZshLPISs6R-4ZugsMLbWyyw-0Npf6tGSGeDtfEVpHXA,83260
+transformers/py.typed,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0
+transformers/pytorch_utils.py,sha256=cwWP0wecU465vOyyaWBPQ0gM1ocfMC0r95DK0UsLXfc,14861
+transformers/quantizers/__init__.py,sha256=S_xTSTbkDOvjLgR3jgR4EAkP_sc3NE8e38T-lllAaNo,800
+transformers/quantizers/__pycache__/__init__.cpython-310.pyc,,
+transformers/quantizers/__pycache__/auto.cpython-310.pyc,,
+transformers/quantizers/__pycache__/base.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_aqlm.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_auto_round.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_awq.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_bitnet.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_bnb_4bit.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_bnb_8bit.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_compressed_tensors.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_eetq.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_fbgemm_fp8.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_finegrained_fp8.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_fp_quant.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_gptq.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_higgs.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_hqq.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_mxfp4.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_quanto.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_quark.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_spqr.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_torchao.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizer_vptq.cpython-310.pyc,,
+transformers/quantizers/__pycache__/quantizers_utils.cpython-310.pyc,,
+transformers/quantizers/auto.py,sha256=03EpZsi5B0Efgw5anqEXwaRqvwgfrPA9NYDOH-u-rgQ,13751
+transformers/quantizers/base.py,sha256=aFUeQwT91APkVFRD9FpzGeD3WMtBENgJOhTG-r77INc,16497
+transformers/quantizers/quantizer_aqlm.py,sha256=t6XKZKBpYzNukrPXkU8AZtCg2j4uX4CYrCii4k2JVRI,3599
+transformers/quantizers/quantizer_auto_round.py,sha256=F2ctpnJwlUI1pnV4TGul4km2_PinHjCNIAadlZvkuLo,3068
+transformers/quantizers/quantizer_awq.py,sha256=W69vAaXoIUWWHVd_QeZ7dUKwfFa_2_ddA02-F-CBIcs,7414
+transformers/quantizers/quantizer_bitnet.py,sha256=9cQ6Nk8qXvgtgbMzmPPwpBu9MDfmqZ1xB6pnBx4aaQU,4669
+transformers/quantizers/quantizer_bnb_4bit.py,sha256=g4rJhsOn9hoHxBco0nDgho61QK7lyFUHFkdblv_jKe8,16510
+transformers/quantizers/quantizer_bnb_8bit.py,sha256=Wj99aNBgdSVTJcR7B4lFdwmLOL9zM8lH5HbktINx5Zo,14254
+transformers/quantizers/quantizer_compressed_tensors.py,sha256=jU7HrDPFidB9E1aAvUWL_n98Woph7cBC1uit8Ka7Mt4,5082
+transformers/quantizers/quantizer_eetq.py,sha256=r_JbZEkTHO38Ik5876yzxZYK83DeQsb_0OXF6azA2r8,7135
+transformers/quantizers/quantizer_fbgemm_fp8.py,sha256=aWkiFpcdJMt870OkspbZZObqS1pYQx32OQS1xYfv5e8,13691
+transformers/quantizers/quantizer_finegrained_fp8.py,sha256=4GQsF8wcMcs8zYJ_wNuxXvvNIi9IppIPzkxs2pN9KzA,9477
+transformers/quantizers/quantizer_fp_quant.py,sha256=0ypZIbsEgThYTo51Ev5KrbscopHDLfw7wTOO0fhlfu8,7369
+transformers/quantizers/quantizer_gptq.py,sha256=81KDChWDLG-rA0V3TkpZEB1hUPVhq2asg_8XfcKoWwU,5585
+transformers/quantizers/quantizer_higgs.py,sha256=AgXGj2rJBIzG89U_I05MHyqNyXGULtu0ca9UPGQoNn8,8700
+transformers/quantizers/quantizer_hqq.py,sha256=bCHZeT3Thvlsp6W4F8_LxXKaxj7VcAspYIGeBwmn-W4,12964
+transformers/quantizers/quantizer_mxfp4.py,sha256=umEOhvdLT5HxLZEZEWvaaOKOEqxt6-6zN5QgD8XiYCw,18159
+transformers/quantizers/quantizer_quanto.py,sha256=vU3Ne-tyJluxgajUIU4DXIdHzAoiyRMmQ1RiG6SlUYM,7616
+transformers/quantizers/quantizer_quark.py,sha256=dXhnSCtjK30AQvXoGbVICqtotYWKekVH8JPOlOWBnjY,3850
+transformers/quantizers/quantizer_spqr.py,sha256=ctTswadhjIb-MHtmmhYgjx4pwFmbC59MptzXXI6___4,3212
+transformers/quantizers/quantizer_torchao.py,sha256=b2gFUjnh3sMjDB1ZbKSldRcime2Vd8OBvw8RVAGPiUw,16341
+transformers/quantizers/quantizer_vptq.py,sha256=3jDRNytkYDJvnyq1vE656ElJpN9olkEyQB4ur0unQ-k,3722
+transformers/quantizers/quantizers_utils.py,sha256=gVf8Up7S6h8mrYHtwmcAJgBENhwQsh3x6cMmoPso6x8,878
+transformers/safetensors_conversion.py,sha256=LjnFRVfXRsOhIHdyiw6pevDJcMdsKwc3kvQ6csPs9wA,4074
+transformers/sagemaker/__init__.py,sha256=fKtKAHamz_CLL9jPGCa2E-1n8RmuS-58qGtzZuKc3qg,730
+transformers/sagemaker/__pycache__/__init__.cpython-310.pyc,,
+transformers/sagemaker/__pycache__/trainer_sm.cpython-310.pyc,,
+transformers/sagemaker/__pycache__/training_args_sm.cpython-310.pyc,,
+transformers/sagemaker/trainer_sm.py,sha256=7GsKLtjdMfKp98OwHD7RcBsl745OOwHAaBswkfLkfsE,1044
+transformers/sagemaker/training_args_sm.py,sha256=4ZnQhITfMwT0y2Y2MvkI11PEB_yfTX5Z7WrPKt0VXD8,5389
+transformers/testing_utils.py,sha256=irluDEzDwoHl5WIts3bAv06atP16uMvIoTKKls9rq3g,123424
+transformers/tf_utils.py,sha256=uiS6uSPmB_ZUaxbV-vMkGy1roDTtY3ujpIgkwuskGmc,11390
+transformers/time_series_utils.py,sha256=fhc___L7NHqLzQ2lvrojW0yGkXJUTVqHGEAt5VDRqNA,7493
+transformers/tokenization_mistral_common.py,sha256=UDqk4dZqayw00ojePbe5ZMPubunxht9uVZ2J0h3UYRU,91450
+transformers/tokenization_utils.py,sha256=kVQ7y82pzGLQjBWmhUyccO-vHTE1kpwRopUCQ-dr1qY,47766
+transformers/tokenization_utils_base.py,sha256=Li2tqGXM5CtzOHJAcWoS_1wKVpd8_WgNyPqTew3A71E,210613
+transformers/tokenization_utils_fast.py,sha256=VG8L7X98l-9_yiURQkps-qLvOc2ClBOGtUKbojTWHxc,41357
+transformers/trainer.py,sha256=Z9hujd3DfmxvxhHVlRZut5Vq-x-qB2MwCAM-Q6wE0JU,277043
+transformers/trainer_callback.py,sha256=hNeWb0OiAI2AdfW66bot9RlJp-4tm7Z6cASSW48qXQk,33611
+transformers/trainer_pt_utils.py,sha256=_ZOVHeXSdotIr6kpcBsiwMYGzhU65QBATZHtZM7hsEw,61454
+transformers/trainer_seq2seq.py,sha256=_GsOuEH9pGY4Jf8gprEpLnH_itU48iz1l_JE7226UmQ,17961
+transformers/trainer_utils.py,sha256=AieUa37RBZU1SHX8P26OONCUQG7r38M_VgDmjiPhZeQ,34121
+transformers/training_args.py,sha256=9ZGV3D89Lbp9qH6F5g6msZB9D6Oubroiim-aVs7x6DY,161576
+transformers/training_args_seq2seq.py,sha256=J9_vJQR4VxWAHWVbRmxjXHSRLd6KSe8inisIVezlbXI,3896
+transformers/training_args_tf.py,sha256=dTx8RireQILOPtoLd4rPc4aQnXfj_Qs3KNLYLiSLUIk,14583
+transformers/utils/__init__.py,sha256=B3Z34orZKaFt68e3rxN2o00sqMJmlRAeYUz61BcV0ic,10473
+transformers/utils/__pycache__/__init__.cpython-310.pyc,,
+transformers/utils/__pycache__/attention_visualizer.cpython-310.pyc,,
+transformers/utils/__pycache__/auto_docstring.cpython-310.pyc,,
+transformers/utils/__pycache__/backbone_utils.cpython-310.pyc,,
+transformers/utils/__pycache__/bitsandbytes.cpython-310.pyc,,
+transformers/utils/__pycache__/chat_template_utils.cpython-310.pyc,,
+transformers/utils/__pycache__/constants.cpython-310.pyc,,
+transformers/utils/__pycache__/deprecation.cpython-310.pyc,,
+transformers/utils/__pycache__/doc.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_detectron2_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_essentia_and_librosa_and_pretty_midi_and_scipy_and_torch_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_flax_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_mistral_common_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_music_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_pt_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_sentencepiece_and_tokenizers_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_sentencepiece_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_speech_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_tensorflow_text_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_tf_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_timm_and_torchvision_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_tokenizers_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_torchaudio_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_torchvision_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/dummy_vision_objects.cpython-310.pyc,,
+transformers/utils/__pycache__/fx.cpython-310.pyc,,
+transformers/utils/__pycache__/generic.cpython-310.pyc,,
+transformers/utils/__pycache__/hp_naming.cpython-310.pyc,,
+transformers/utils/__pycache__/hub.cpython-310.pyc,,
+transformers/utils/__pycache__/import_utils.cpython-310.pyc,,
+transformers/utils/__pycache__/logging.cpython-310.pyc,,
+transformers/utils/__pycache__/metrics.cpython-310.pyc,,
+transformers/utils/__pycache__/model_parallel_utils.cpython-310.pyc,,
+transformers/utils/__pycache__/notebook.cpython-310.pyc,,
+transformers/utils/__pycache__/peft_utils.cpython-310.pyc,,
+transformers/utils/__pycache__/quantization_config.cpython-310.pyc,,
+transformers/utils/__pycache__/sentencepiece_model_pb2.cpython-310.pyc,,
+transformers/utils/__pycache__/sentencepiece_model_pb2_new.cpython-310.pyc,,
+transformers/utils/__pycache__/versions.cpython-310.pyc,,
+transformers/utils/attention_visualizer.py,sha256=3cFo4QHuidz5HThcqh6e-FeShTmcZizqt7F6Vj6Wxaw,10002
+transformers/utils/auto_docstring.py,sha256=bWPN4jnoy1wuauA8MVGoEAHMOubqtM4eXelrpJmB-GA,81502
+transformers/utils/backbone_utils.py,sha256=ifY7uhCZiBDPi8CfLOvqoLQss5XWku1wKpWus7tH9aE,17712
+transformers/utils/bitsandbytes.py,sha256=LzOKwcHWAxxZZv-7Ts9Q0vlEYvHd18affVgVbiR3Tzs,1040
+transformers/utils/chat_template_utils.py,sha256=L9JP7gU8GWXZeuVNRksnN4D2NhDZ-tzKZC9nTzVvx-w,22446
+transformers/utils/constants.py,sha256=sZsUwOnA3CbtN1svs9YoaNLTTsAc9RVaITsgpf8K4iI,282
+transformers/utils/deprecation.py,sha256=rsbc7bbHPmvePSmkpf_nXQ7OIX6ITFSK6nJxHvu0bY4,8065
+transformers/utils/doc.py,sha256=K5MgXYi1j1Bd5OU-ho57ojgp1UftHN4Yu2mpj3x3lQA,52480
+transformers/utils/dummy_detectron2_objects.py,sha256=n7Pt_7sbVBNfohKGcOARB-ZcPcJRbjEAcoLd2vTXndU,340
+transformers/utils/dummy_essentia_and_librosa_and_pretty_midi_and_scipy_and_torch_objects.py,sha256=n6pY4s7zCII3dzo7Ejd0RviHa_pMateuDEwbbHgsTUY,902
+transformers/utils/dummy_flax_objects.py,sha256=lqW9EJzfDmsx7Uj4cm4UHUUwcYI9SFm8-biApCP40HQ,2652
+transformers/utils/dummy_mistral_common_objects.py,sha256=a43f12WAikWuVMOnFPTA1A2rvI9gi2a4POyuBLLFVEs,311
+transformers/utils/dummy_music_objects.py,sha256=1lxIebYUOdHJWMQ_T5IQgPgcO_wp_8YM_HGc3skuGVg,458
+transformers/utils/dummy_pt_objects.py,sha256=QR0AgNozjYlX2ui4ODjUf5AlevknNOWrn5ziG5wb_UQ,15268
+transformers/utils/dummy_sentencepiece_and_tokenizers_objects.py,sha256=BgPLr8Wz8A-17K86x04N21CKXtWNQLJEWx2c4aZRqaA,286
+transformers/utils/dummy_sentencepiece_objects.py,sha256=pBykNNg9IPDeshVOeaw4sxHvgmt3by9X4rIQtz0ONYg,6455
+transformers/utils/dummy_speech_objects.py,sha256=9eFm1cjdsYOPBoAz9JTgP35Bg8WF2C9AZ_y1hFpKZdQ,465
+transformers/utils/dummy_tensorflow_text_objects.py,sha256=43V0IA2kb9gtuL0S1OL1eRFFxzQwKg4pPjMVuXUB5qg,306
+transformers/utils/dummy_tf_objects.py,sha256=8ZPa6w8h-VzRDzwOO9xK26u9evz3T8bkxSLhgxI-lKU,4139
+transformers/utils/dummy_timm_and_torchvision_objects.py,sha256=EFuC5z6IsKOqqowoUGviJ3KgTjzvdTTN7gGQ3it-4t0,324
+transformers/utils/dummy_tokenizers_objects.py,sha256=PFIh5nBDmhWG2XDGuwIyBGldm6b_jdZdL3E8t5A8FsY,304
+transformers/utils/dummy_torchaudio_objects.py,sha256=EG0q0JkedoNb_4ntsf6EyTOE6Nr1whvHOzHPKy1t7x0,847
+transformers/utils/dummy_torchvision_objects.py,sha256=BaUQGsNL0Xfj-HP-pOVXSKYw5UFaNlWD_Iso9D8muGw,479
+transformers/utils/dummy_vision_objects.py,sha256=GDbX7-GrqykExLY91SMhSf508DinS5NSFfavbeDsCMU,630
+transformers/utils/fx.py,sha256=FUmdeA6b8On6KkiO0jircozxUoWP9H8U0vvgO2g4Keg,56895
+transformers/utils/generic.py,sha256=5AQp1iaEpT-fbdYi40oc7z9cHzH3YDGjVhyuaygK4nU,39084
+transformers/utils/hp_naming.py,sha256=vqcOXcDOyqbISWo8-ClUJUOBVbZM1h08EcymTwcRthc,4979
+transformers/utils/hub.py,sha256=cy_7Do3BOJajyO_lCb2VUCDOMT2MIMEitOXQZd50tGw,51693
+transformers/utils/import_utils.py,sha256=jOgSov3CnVE1FwHk4dTx7MYyr4m5RjpG0b9v87EDpk4,108460
+transformers/utils/logging.py,sha256=bM5p5ETn0xrC_KYY0gfWlC6LQWFlg2jB1avHcqwQArI,12251
+transformers/utils/metrics.py,sha256=A301r8MYoZPcSMO8lfpOSJO_J8GFHxhjKHBbxazqTxU,15732
+transformers/utils/model_parallel_utils.py,sha256=dmPsjrVGLxwYHsGXyvFQrcl-aZRQA5hydi4I7_sBAoo,2257
+transformers/utils/notebook.py,sha256=Gkg0GxMhbrTk21Fp6aXVeTuVk49yPDWuGbLc4OCHrPo,15796
+transformers/utils/peft_utils.py,sha256=7XZBVmD_gcZl2hjwTRYztGs-WEHfRc53rqNuUdAlzl0,5193
+transformers/utils/quantization_config.py,sha256=gGY1XYv5_kZhxLt7ROHtOW5kJl2EdJUsv5wBGXrf64M,94559
+transformers/utils/sentencepiece_model_pb2.py,sha256=WcMZRm2-571XwxSfo-6FZih9fDy_Zl5mMwqrDrC1Dlg,50663
+transformers/utils/sentencepiece_model_pb2_new.py,sha256=ahaV--amhGIL3nXFCTHqezqxuGXm8SHr_C3Zvj7KbAY,6598
+transformers/utils/versions.py,sha256=C-Tqr4qGSHH64ygIBCSo8gA6azz7Dbzh8zdc_yjMkX8,4337
+transformers/video_processing_utils.py,sha256=B8alNpd30I_GyJf5lU-u5b5EWUlswG_TusqjakItu5w,41664
+transformers/video_utils.py,sha256=_mgejmY1p7-arTHSmkpZ6H9qxIw9ky-oDhWrjKQZewQ,33836
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/REQUESTED b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/REQUESTED
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/WHEEL b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/WHEEL
new file mode 100644
index 0000000000000000000000000000000000000000..79d5c89a71989389294854aa34e329701325f8b0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/WHEEL
@@ -0,0 +1,5 @@
+Wheel-Version: 1.0
+Generator: bdist_wheel (0.45.1)
+Root-Is-Purelib: true
+Tag: py3-none-any
+
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/entry_points.txt b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/entry_points.txt
new file mode 100644
index 0000000000000000000000000000000000000000..47f047547c476346d81519e9d380af1a6be26155
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/entry_points.txt
@@ -0,0 +1,3 @@
+[console_scripts]
+transformers = transformers.commands.transformers_cli:main
+transformers-cli = transformers.commands.transformers_cli:main_cli
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/top_level.txt b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/top_level.txt
new file mode 100644
index 0000000000000000000000000000000000000000..976a2b1f3998279c10c413279a095be86bf69167
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers-4.56.2.dist-info/top_level.txt
@@ -0,0 +1 @@
+transformers
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/image_processing_siglip.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/image_processing_siglip.py
new file mode 100644
index 0000000000000000000000000000000000000000..152447bb5b873c17eb77787a2f43338579b50c44
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/image_processing_siglip.py
@@ -0,0 +1,245 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for SigLIP."""
+
+from typing import Optional, Union
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import (
+ convert_to_rgb,
+ resize,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_flat_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+if is_vision_available():
+ import PIL
+
+
+class SiglipImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a SigLIP image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by
+ `do_resize` in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"height": 224, "width": 224}`):
+ Size of the image after resizing. Can be overridden by `size` in the `preprocess` method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`):
+ Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in
+ the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess`
+ method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image by the specified mean and standard deviation. Can be overridden by
+ `do_normalize` in the `preprocess` method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_convert_rgb (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to RGB.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BICUBIC,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"height": 224, "width": 224}
+ image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+
+ self.do_resize = do_resize
+ self.size = size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean
+ self.image_std = image_std
+ self.do_convert_rgb = do_convert_rgb
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Optional[ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after resizing.
+ resample (`int`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only
+ has an effect if `do_resize` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image.
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to
+ `True`.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`):
+ Whether to convert the image to RGB.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ size = size if size is not None else self.size
+ size = get_size_dict(size, param_name="size", default_to_square=False)
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb
+
+ images = self.fetch_images(images)
+ images = make_flat_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+ if do_convert_rgb:
+ images = [convert_to_rgb(image) for image in images]
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_resize:
+ height, width = size["height"], size["width"]
+ images = [
+ resize(image=image, size=(height, width), resample=resample, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_normalize:
+ images = [
+ self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images
+ ]
+
+ data = {"pixel_values": images}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["SiglipImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/image_processing_siglip_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/image_processing_siglip_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..de2426e6eb023fdf4ea9f28e1b14e0773e365917
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/image_processing_siglip_fast.py
@@ -0,0 +1,38 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for SigLIP."""
+
+from ...image_processing_utils_fast import BaseImageProcessorFast
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ PILImageResampling,
+)
+from ...utils import auto_docstring
+
+
+@auto_docstring
+class SiglipImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BICUBIC
+ image_mean = IMAGENET_STANDARD_MEAN
+ image_std = IMAGENET_STANDARD_STD
+ size = {"height": 224, "width": 224}
+ default_to_square = False
+ do_resize = True
+ do_rescale = True
+ do_normalize = True
+
+
+__all__ = ["SiglipImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/modeling_siglip.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/modeling_siglip.py
new file mode 100644
index 0000000000000000000000000000000000000000..74e5d7fd5a6f160d6868bc513397ef50549b22d2
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/modeling_siglip.py
@@ -0,0 +1,1222 @@
+# coding=utf-8
+# Copyright 2024 Google AI and The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Siglip model."""
+
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Any, Callable, Optional, Union
+
+import numpy as np
+import torch
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+from torch.nn.init import _calculate_fan_in_and_fan_out
+
+from ...activations import ACT2FN
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, ImageClassifierOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...utils import ModelOutput, auto_docstring, can_return_tuple, torch_int
+from .configuration_siglip import SiglipConfig, SiglipTextConfig, SiglipVisionConfig
+
+
+def _trunc_normal_(tensor, mean, std, a, b):
+ # Cut & paste from PyTorch official master until it's in a few official releases - RW
+ # Method based on https://people.sc.fsu.edu/~jburkardt/presentations/truncated_normal.pdf
+ def norm_cdf(x):
+ # Computes standard normal cumulative distribution function
+ return (1.0 + math.erf(x / math.sqrt(2.0))) / 2.0
+
+ if (mean < a - 2 * std) or (mean > b + 2 * std):
+ warnings.warn(
+ "mean is more than 2 std from [a, b] in nn.init.trunc_normal_. "
+ "The distribution of values may be incorrect.",
+ stacklevel=2,
+ )
+
+ # Values are generated by using a truncated uniform distribution and
+ # then using the inverse CDF for the normal distribution.
+ # Get upper and lower cdf values
+ l = norm_cdf((a - mean) / std)
+ u = norm_cdf((b - mean) / std)
+
+ # Uniformly fill tensor with values from [l, u], then translate to
+ # [2l-1, 2u-1].
+ tensor.uniform_(2 * l - 1, 2 * u - 1)
+
+ # Use inverse cdf transform for normal distribution to get truncated
+ # standard normal
+ tensor.erfinv_()
+
+ # Transform to proper mean, std
+ tensor.mul_(std * math.sqrt(2.0))
+ tensor.add_(mean)
+
+ # Clamp to ensure it's in the proper range
+ tensor.clamp_(min=a, max=b)
+
+
+def trunc_normal_tf_(
+ tensor: torch.Tensor, mean: float = 0.0, std: float = 1.0, a: float = -2.0, b: float = 2.0
+) -> torch.Tensor:
+ """Fills the input Tensor with values drawn from a truncated
+ normal distribution. The values are effectively drawn from the
+ normal distribution :math:`\\mathcal{N}(\text{mean}, \text{std}^2)`
+ with values outside :math:`[a, b]` redrawn until they are within
+ the bounds. The method used for generating the random values works
+ best when :math:`a \\leq \text{mean} \\leq b`.
+
+ NOTE: this 'tf' variant behaves closer to Tensorflow / JAX impl where the
+ bounds [a, b] are applied when sampling the normal distribution with mean=0, std=1.0
+ and the result is subsequently scaled and shifted by the mean and std args.
+
+ Args:
+ tensor: an n-dimensional `torch.Tensor`
+ mean: the mean of the normal distribution
+ std: the standard deviation of the normal distribution
+ a: the minimum cutoff value
+ b: the maximum cutoff value
+ """
+ with torch.no_grad():
+ _trunc_normal_(tensor, 0, 1.0, a, b)
+ tensor.mul_(std).add_(mean)
+
+
+def variance_scaling_(tensor, scale=1.0, mode="fan_in", distribution="normal"):
+ fan_in, fan_out = _calculate_fan_in_and_fan_out(tensor)
+ if mode == "fan_in":
+ denom = fan_in
+ elif mode == "fan_out":
+ denom = fan_out
+ elif mode == "fan_avg":
+ denom = (fan_in + fan_out) / 2
+
+ variance = scale / denom
+
+ if distribution == "truncated_normal":
+ # constant is stddev of standard normal truncated to (-2, 2)
+ trunc_normal_tf_(tensor, std=math.sqrt(variance) / 0.87962566103423978)
+ elif distribution == "normal":
+ with torch.no_grad():
+ tensor.normal_(std=math.sqrt(variance))
+ elif distribution == "uniform":
+ bound = math.sqrt(3 * variance)
+ with torch.no_grad():
+ tensor.uniform_(-bound, bound)
+ else:
+ raise ValueError(f"invalid distribution {distribution}")
+
+
+def lecun_normal_(tensor):
+ variance_scaling_(tensor, mode="fan_in", distribution="truncated_normal")
+
+
+def default_flax_embed_init(tensor):
+ variance_scaling_(tensor, mode="fan_in", distribution="normal")
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for vision model's outputs that also contains image embeddings of the pooling of the last hidden states.
+ """
+)
+# Copied from transformers.models.clip.modeling_clip.CLIPVisionModelOutput with CLIP->Siglip
+class SiglipVisionModelOutput(ModelOutput):
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`):
+ The image embeddings obtained by applying the projection layer to the pooler_output.
+ """
+
+ image_embeds: Optional[torch.FloatTensor] = None
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for text model's outputs that also contains a pooling of the last hidden states.
+ """
+)
+# Copied from transformers.models.clip.modeling_clip.CLIPTextModelOutput with CLIP->Siglip
+class SiglipTextModelOutput(ModelOutput):
+ r"""
+ text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`):
+ The text embeddings obtained by applying the projection layer to the pooler_output.
+ """
+
+ text_embeds: Optional[torch.FloatTensor] = None
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring
+# Copied from transformers.models.clip.modeling_clip.CLIPOutput with CLIP->Siglip
+class SiglipOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `return_loss` is `True`):
+ Contrastive loss for image-text similarity.
+ logits_per_image (`torch.FloatTensor` of shape `(image_batch_size, text_batch_size)`):
+ The scaled dot product scores between `image_embeds` and `text_embeds`. This represents the image-text
+ similarity scores.
+ logits_per_text (`torch.FloatTensor` of shape `(text_batch_size, image_batch_size)`):
+ The scaled dot product scores between `text_embeds` and `image_embeds`. This represents the text-image
+ similarity scores.
+ text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`):
+ The text embeddings obtained by applying the projection layer to the pooled output of [`SiglipTextModel`].
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`):
+ The image embeddings obtained by applying the projection layer to the pooled output of [`SiglipVisionModel`].
+ text_model_output (`BaseModelOutputWithPooling`):
+ The output of the [`SiglipTextModel`].
+ vision_model_output (`BaseModelOutputWithPooling`):
+ The output of the [`SiglipVisionModel`].
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits_per_image: Optional[torch.FloatTensor] = None
+ logits_per_text: Optional[torch.FloatTensor] = None
+ text_embeds: Optional[torch.FloatTensor] = None
+ image_embeds: Optional[torch.FloatTensor] = None
+ text_model_output: BaseModelOutputWithPooling = None
+ vision_model_output: BaseModelOutputWithPooling = None
+
+ def to_tuple(self) -> tuple[Any]:
+ return tuple(
+ self[k] if k not in ["text_model_output", "vision_model_output"] else getattr(self, k).to_tuple()
+ for k in self.keys()
+ )
+
+
+class SiglipVisionEmbeddings(nn.Module):
+ def __init__(self, config: SiglipVisionConfig):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.image_size = config.image_size
+ self.patch_size = config.patch_size
+
+ self.patch_embedding = nn.Conv2d(
+ in_channels=config.num_channels,
+ out_channels=self.embed_dim,
+ kernel_size=self.patch_size,
+ stride=self.patch_size,
+ padding="valid",
+ )
+
+ self.num_patches = (self.image_size // self.patch_size) ** 2
+ self.num_positions = self.num_patches
+ self.position_embedding = nn.Embedding(self.num_positions, self.embed_dim)
+ self.register_buffer("position_ids", torch.arange(self.num_positions).expand((1, -1)), persistent=False)
+
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing and no class embeddings.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1]
+ num_positions = self.position_embedding.weight.shape[0]
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embedding(self.position_ids)
+
+ patch_pos_embed = self.position_embedding.weight.unsqueeze(0)
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+ return patch_pos_embed
+
+ def forward(self, pixel_values: torch.FloatTensor, interpolate_pos_encoding=False) -> torch.Tensor:
+ _, _, height, width = pixel_values.shape
+ target_dtype = self.patch_embedding.weight.dtype
+ patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype)) # shape = [*, width, grid, grid]
+ embeddings = patch_embeds.flatten(2).transpose(1, 2)
+
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embedding(self.position_ids)
+ return embeddings
+
+
+# Copied from transformers.models.clip.modeling_clip.CLIPTextEmbeddings with CLIP->Siglip
+class SiglipTextEmbeddings(nn.Module):
+ def __init__(self, config: SiglipTextConfig):
+ super().__init__()
+ embed_dim = config.hidden_size
+
+ self.token_embedding = nn.Embedding(config.vocab_size, embed_dim)
+ self.position_embedding = nn.Embedding(config.max_position_embeddings, embed_dim)
+
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ ) -> torch.Tensor:
+ seq_length = input_ids.shape[-1] if input_ids is not None else inputs_embeds.shape[-2]
+ max_position_embedding = self.position_embedding.weight.shape[0]
+
+ if seq_length > max_position_embedding:
+ raise ValueError(
+ f"Sequence length must be less than max_position_embeddings (got `sequence length`: "
+ f"{seq_length} and max_position_embeddings: {max_position_embedding}"
+ )
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ if inputs_embeds is None:
+ inputs_embeds = self.token_embedding(input_ids)
+
+ position_embeddings = self.position_embedding(position_ids)
+ embeddings = inputs_embeds + position_embeddings
+
+ return embeddings
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class SiglipAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+ self.is_causal = False
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ batch_size, seq_length, embed_dim = hidden_states.shape
+
+ queries = self.q_proj(hidden_states)
+ keys = self.k_proj(hidden_states)
+ values = self.v_proj(hidden_states)
+
+ queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ queries,
+ keys,
+ values,
+ attention_mask,
+ is_causal=self.is_causal,
+ scaling=self.scale,
+ dropout=0.0 if not self.training else self.dropout,
+ )
+
+ attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.clip.modeling_clip.CLIPMLP with CLIP->Siglip
+class SiglipMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.activation_fn = ACT2FN[config.hidden_act]
+ self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.fc1(hidden_states)
+ hidden_states = self.activation_fn(hidden_states)
+ hidden_states = self.fc2(hidden_states)
+ return hidden_states
+
+
+class SiglipEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: Union[SiglipVisionConfig, SiglipTextConfig]):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.self_attn = SiglipAttention(config)
+ self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.mlp = SiglipMLP(config)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.FloatTensor]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`):
+ Input to the layer of shape `(batch, seq_len, embed_dim)`.
+ attention_mask (`torch.FloatTensor`):
+ Attention mask of shape `(batch, 1, q_len, k_v_seq_len)` where padding elements are indicated by very large negative values.
+ output_attentions (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+@auto_docstring
+class SiglipPreTrainedModel(PreTrainedModel):
+ config: SiglipConfig
+ base_model_prefix = "siglip"
+ supports_gradient_checkpointing = True
+
+ _no_split_modules = [
+ "SiglipTextEmbeddings",
+ "SiglipVisionEmbeddings",
+ "SiglipEncoderLayer",
+ "SiglipMultiheadAttentionPoolingHead",
+ ]
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, SiglipVisionEmbeddings):
+ width = (
+ self.config.vision_config.hidden_size
+ if isinstance(self.config, SiglipConfig)
+ else self.config.hidden_size
+ )
+ nn.init.normal_(module.position_embedding.weight, std=1 / np.sqrt(width))
+ elif isinstance(module, nn.Embedding):
+ default_flax_embed_init(module.weight)
+ elif isinstance(module, SiglipAttention):
+ nn.init.xavier_uniform_(module.q_proj.weight)
+ nn.init.xavier_uniform_(module.k_proj.weight)
+ nn.init.xavier_uniform_(module.v_proj.weight)
+ nn.init.xavier_uniform_(module.out_proj.weight)
+ nn.init.zeros_(module.q_proj.bias)
+ nn.init.zeros_(module.k_proj.bias)
+ nn.init.zeros_(module.v_proj.bias)
+ nn.init.zeros_(module.out_proj.bias)
+ elif isinstance(module, SiglipMLP):
+ nn.init.xavier_uniform_(module.fc1.weight)
+ nn.init.xavier_uniform_(module.fc2.weight)
+ nn.init.normal_(module.fc1.bias, std=1e-6)
+ nn.init.normal_(module.fc2.bias, std=1e-6)
+ elif isinstance(module, SiglipMultiheadAttentionPoolingHead):
+ nn.init.xavier_uniform_(module.probe.data)
+ nn.init.xavier_uniform_(module.attention.in_proj_weight.data)
+ nn.init.zeros_(module.attention.in_proj_bias.data)
+ elif isinstance(module, SiglipModel):
+ logit_scale_init = torch.log(torch.tensor(1.0))
+ module.logit_scale.data.fill_(logit_scale_init)
+ module.logit_bias.data.zero_()
+ elif isinstance(module, SiglipForImageClassification):
+ nn.init.normal_(
+ module.classifier.weight,
+ std=self.config.vision_config.hidden_size**-0.5 * self.config.initializer_factor,
+ )
+ elif isinstance(module, (nn.Linear, nn.Conv2d)):
+ lecun_normal_(module.weight)
+ if module.bias is not None:
+ nn.init.zeros_(module.bias)
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+# Copied from transformers.models.altclip.modeling_altclip.AltCLIPEncoder with AltCLIP->Siglip
+class SiglipEncoder(nn.Module):
+ """
+ Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a
+ [`SiglipEncoderLayer`].
+
+ Args:
+ config: SiglipConfig
+ """
+
+ def __init__(self, config: SiglipConfig):
+ super().__init__()
+ self.config = config
+ self.layers = nn.ModuleList([SiglipEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ # Ignore copy
+ @can_return_tuple
+ def forward(
+ self,
+ inputs_embeds,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutput:
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ hidden_states = inputs_embeds
+ for encoder_layer in self.layers:
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=encoder_states,
+ attentions=all_attentions,
+ )
+
+
+class SiglipTextTransformer(nn.Module):
+ def __init__(self, config: SiglipTextConfig):
+ super().__init__()
+ self.config = config
+ embed_dim = config.hidden_size
+ self.embeddings = SiglipTextEmbeddings(config)
+ self.encoder = SiglipEncoder(config)
+ self.final_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+
+ self.head = nn.Linear(embed_dim, config.projection_size)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ if input_ids is None:
+ raise ValueError("You have to specify input_ids")
+
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+
+ hidden_states = self.embeddings(input_ids=input_ids, position_ids=position_ids)
+
+ # note: SigLIP's text model does not use a causal mask, unlike the original CLIP model.
+ # expand attention_mask
+ uses_flash_attention = "flash" in self.config._attn_implementation
+ if uses_flash_attention:
+ attention_mask = None
+ elif attention_mask is not None and not uses_flash_attention:
+ # [batch_size, seq_len] -> [batch_size, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_states.dtype)
+
+ encoder_outputs: BaseModelOutput = self.encoder(
+ inputs_embeds=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ last_hidden_state = encoder_outputs.last_hidden_state
+ last_hidden_state = self.final_layer_norm(last_hidden_state)
+
+ # The model uses the last token's hidden state, which may be padding.
+ pooled_output = last_hidden_state[:, -1, :]
+ pooled_output = self.head(pooled_output)
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The text model from SigLIP without any head or projection on top.
+ """
+)
+class SiglipTextModel(SiglipPreTrainedModel):
+ config: SiglipTextConfig
+
+ def __init__(self, config: SiglipTextConfig):
+ super().__init__(config)
+ self.text_model = SiglipTextTransformer(config)
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.text_model.embeddings.token_embedding
+
+ def set_input_embeddings(self, value):
+ self.text_model.embeddings.token_embedding = value
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, SiglipTextModel
+
+ >>> model = SiglipTextModel.from_pretrained("google/siglip-base-patch16-224")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip-base-patch16-224")
+
+ >>> # important: make sure to set padding="max_length" as that's how the model was trained
+ >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> last_hidden_state = outputs.last_hidden_state
+ >>> pooled_output = outputs.pooler_output # pooled (EOS token) states
+ ```"""
+
+ return self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+
+class SiglipVisionTransformer(nn.Module):
+ def __init__(self, config: SiglipVisionConfig):
+ super().__init__()
+ self.config = config
+ embed_dim = config.hidden_size
+
+ self.embeddings = SiglipVisionEmbeddings(config)
+ self.encoder = SiglipEncoder(config)
+ self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.use_head = True if not hasattr(config, "vision_use_head") else config.vision_use_head
+ if self.use_head:
+ self.head = SiglipMultiheadAttentionPoolingHead(config)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: Optional[bool] = False,
+ ) -> BaseModelOutputWithPooling:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ hidden_states = self.embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+
+ encoder_outputs: BaseModelOutput = self.encoder(
+ inputs_embeds=hidden_states,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ last_hidden_state = encoder_outputs.last_hidden_state
+ last_hidden_state = self.post_layernorm(last_hidden_state)
+
+ pooler_output = self.head(last_hidden_state) if self.use_head else None
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooler_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class SiglipMultiheadAttentionPoolingHead(nn.Module):
+ """Multihead Attention Pooling."""
+
+ def __init__(self, config: SiglipVisionConfig):
+ super().__init__()
+
+ self.probe = nn.Parameter(torch.randn(1, 1, config.hidden_size))
+ self.attention = torch.nn.MultiheadAttention(config.hidden_size, config.num_attention_heads, batch_first=True)
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.mlp = SiglipMLP(config)
+
+ def forward(self, hidden_state):
+ batch_size = hidden_state.shape[0]
+ probe = self.probe.repeat(batch_size, 1, 1)
+
+ hidden_state = self.attention(probe, hidden_state, hidden_state)[0]
+
+ residual = hidden_state
+ hidden_state = self.layernorm(hidden_state)
+ hidden_state = residual + self.mlp(hidden_state)
+
+ return hidden_state[:, 0]
+
+
+@auto_docstring(
+ custom_intro="""
+ The vision model from SigLIP without any head or projection on top.
+ """
+)
+class SiglipVisionModel(SiglipPreTrainedModel):
+ config: SiglipVisionConfig
+ main_input_name = "pixel_values"
+
+ def __init__(self, config: SiglipVisionConfig):
+ super().__init__(config)
+
+ self.vision_model = SiglipVisionTransformer(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.vision_model.embeddings.patch_embedding
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, SiglipVisionModel
+
+ >>> model = SiglipVisionModel.from_pretrained("google/siglip-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> last_hidden_state = outputs.last_hidden_state
+ >>> pooled_output = outputs.pooler_output # pooled features
+ ```"""
+
+ return self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+
+
+@auto_docstring
+class SiglipModel(SiglipPreTrainedModel):
+ config: SiglipConfig
+
+ def __init__(self, config: SiglipConfig):
+ super().__init__(config)
+
+ if not isinstance(config.text_config, SiglipTextConfig):
+ raise TypeError(
+ "config.text_config is expected to be of type SiglipTextConfig but is of type"
+ f" {type(config.text_config)}."
+ )
+
+ if not isinstance(config.vision_config, SiglipVisionConfig):
+ raise TypeError(
+ "config.vision_config is expected to be of type SiglipVisionConfig but is of type"
+ f" {type(config.vision_config)}."
+ )
+
+ text_config = config.text_config
+ vision_config = config.vision_config
+
+ # First, initialize the text and vision models with proper attention implementation
+ text_model = SiglipTextModel._from_config(text_config)
+ vision_model = SiglipVisionModel._from_config(vision_config)
+
+ # Second, get the text and vision submodules (for backward compatibility)
+ self.text_model = text_model.text_model
+ self.vision_model = vision_model.vision_model
+
+ self.logit_scale = nn.Parameter(torch.randn(1))
+ self.logit_bias = nn.Parameter(torch.randn(1))
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def get_text_features(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> torch.FloatTensor:
+ r"""
+ Returns:
+ text_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The text embeddings obtained by
+ applying the projection layer to the pooled output of [`SiglipTextModel`].
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip-base-patch16-224")
+
+ >>> # important: make sure to set padding="max_length" as that's how the model was trained
+ >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt")
+ >>> with torch.no_grad():
+ ... text_features = model.get_text_features(**inputs)
+ ```"""
+ # Use SigLIP model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ text_outputs: BaseModelOutputWithPooling = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ pooled_output = text_outputs.pooler_output
+
+ return pooled_output
+
+ @auto_docstring
+ def get_image_features(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> torch.FloatTensor:
+ r"""
+ Returns:
+ image_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The image embeddings obtained by
+ applying the projection layer to the pooled output of [`SiglipVisionModel`].
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... image_features = model.get_image_features(**inputs)
+ ```"""
+ # Use SiglipModel's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ vision_outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+
+ pooled_output = vision_outputs.pooler_output
+
+ return pooled_output
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ return_loss: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> SiglipOutput:
+ r"""
+ return_loss (`bool`, *optional*):
+ Whether or not to return the contrastive loss.
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> texts = ["a photo of 2 cats", "a photo of 2 dogs"]
+ >>> # important: we pass `padding=max_length` since the model was trained with this
+ >>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+
+ >>> logits_per_image = outputs.logits_per_image
+ >>> probs = torch.sigmoid(logits_per_image) # these are the probabilities
+ >>> print(f"{probs[0][0]:.1%} that image 0 is '{texts[0]}'")
+ 31.9% that image 0 is 'a photo of 2 cats'
+ ```"""
+ # Use SigLIP model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ vision_outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+
+ text_outputs: BaseModelOutputWithPooling = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ image_embeds = vision_outputs.pooler_output
+ text_embeds = text_outputs.pooler_output
+
+ # normalized features
+ image_embeds = image_embeds / image_embeds.norm(p=2, dim=-1, keepdim=True)
+ text_embeds = text_embeds / text_embeds.norm(p=2, dim=-1, keepdim=True)
+
+ # cosine similarity as logits
+ logits_per_text = torch.matmul(text_embeds, image_embeds.t().to(text_embeds.device))
+
+ logit_scale, logit_bias = self.logit_scale.to(text_embeds.device), self.logit_bias.to(text_embeds.device)
+ logits_per_text = logits_per_text * logit_scale.exp() + logit_bias
+
+ logits_per_image = logits_per_text.t()
+
+ loss = None
+ if return_loss:
+ # Adapted from https://github.com/google-research/big_vision/blob/01edb81a4716f93a48be43b3a4af14e29cdb3a7f/big_vision/trainers/proj/image_text/siglip.py#L287
+ eye = torch.eye(logits_per_text.size(0), device=logits_per_text.device)
+ m1_diag1 = -torch.ones_like(logits_per_text) + 2 * eye
+ loglik = torch.nn.functional.logsigmoid(m1_diag1 * logits_per_text)
+ nll = -torch.sum(loglik, dim=-1)
+ loss = nll.mean()
+
+ return SiglipOutput(
+ loss=loss,
+ logits_per_image=logits_per_image,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ image_embeds=image_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ SigLIP vision encoder with an image classification head on top (a linear layer on top of the pooled final hidden states of
+ the patch tokens) e.g. for ImageNet.
+ """
+)
+class SiglipForImageClassification(SiglipPreTrainedModel):
+ main_input_name = "pixel_values"
+
+ def __init__(self, config: SiglipConfig) -> None:
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+
+ # Create the vision model with proper attention
+ # and take only vision_model submodule (for backward compatibility)
+ vision_model = SiglipVisionModel._from_config(config.vision_config)
+ self.vision_model = vision_model.vision_model
+
+ # Classifier head
+ self.classifier = (
+ nn.Linear(config.vision_config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity()
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> ImageClassifierOutput:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, SiglipForImageClassification
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> # note: we are loading a `SiglipModel` from the hub here,
+ >>> # so the head will be randomly initialized, hence the predictions will be random if seed is not set above.
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/siglip-base-patch16-224")
+ >>> model = SiglipForImageClassification.from_pretrained("google/siglip-base-patch16-224")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> logits = outputs.logits
+ >>> # model predicts one of the two classes
+ >>> predicted_class_idx = logits.argmax(-1).item()
+ >>> print("Predicted class:", model.config.id2label[predicted_class_idx])
+ Predicted class: LABEL_1
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+
+ sequence_output = outputs.last_hidden_state
+
+ # average pool the patch tokens
+ sequence_output = torch.mean(sequence_output, dim=1)
+ # apply classifier
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "SiglipModel",
+ "SiglipPreTrainedModel",
+ "SiglipTextModel",
+ "SiglipVisionModel",
+ "SiglipForImageClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/processing_siglip.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/processing_siglip.py
new file mode 100644
index 0000000000000000000000000000000000000000..8326838e20d35af2656715a007ba0bbad2d28e9b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/processing_siglip.py
@@ -0,0 +1,124 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Image/Text processor class for SigLIP.
+"""
+
+from typing import Optional, Union
+
+from ...feature_extraction_utils import BatchFeature
+from ...image_utils import ImageInput
+from ...processing_utils import ProcessorMixin
+from ...tokenization_utils_base import PaddingStrategy, PreTokenizedInput, TextInput, TruncationStrategy
+from ...utils import TensorType
+
+
+class SiglipProcessor(ProcessorMixin):
+ r"""
+ Constructs a Siglip processor which wraps a Siglip image processor and a Siglip tokenizer into a single processor.
+
+ [`SiglipProcessor`] offers all the functionalities of [`SiglipImageProcessor`] and [`SiglipTokenizer`]. See the
+ [`~SiglipProcessor.__call__`] and [`~SiglipProcessor.decode`] for more information.
+
+ Args:
+ image_processor ([`SiglipImageProcessor`]):
+ The image processor is a required input.
+ tokenizer ([`SiglipTokenizer`]):
+ The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+ image_processor_class = ("SiglipImageProcessor", "SiglipImageProcessorFast")
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(self, image_processor, tokenizer):
+ super().__init__(image_processor, tokenizer)
+
+ def __call__(
+ self,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ images: ImageInput = None,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ return_tensors: Optional[Union[str, TensorType]] = TensorType.PYTORCH,
+ ) -> BatchFeature:
+ """
+ Main method to prepare for the model one or several sequences(s) and image(s). This method forwards the `text`
+ and `kwargs` arguments to SiglipTokenizer's [`~SiglipTokenizer.__call__`] if `text` is not `None` to encode
+ the text. To prepare the image(s), this method forwards the `images` argument to
+ SiglipImageProcessor's [`~SiglipImageProcessor.__call__`] if `images` is not `None`. Please refer to the docstring
+ of the above two methods for more information.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ images (`PIL.Image.Image`, `np.ndarray`, `torch.Tensor`, `list[PIL.Image.Image]`, `list[np.ndarray]`, `list[torch.Tensor]`):
+ The image or batch of images to be prepared. Each image can be a PIL image, NumPy array or PyTorch
+ tensor. Both channels-first and channels-last formats are supported.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding
+ index) among:
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ truncation (`bool`, *optional*):
+ Activates truncation to cut input sequences longer than `max_length` to `max_length`.
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors of a particular framework. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+
+ Returns:
+ [`BatchFeature`]: A [`BatchFeature`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`.
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not
+ `None`).
+ - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is not `None`.
+ """
+
+ if text is None and images is None:
+ raise ValueError("You have to specify either text or images. Both cannot be none.")
+
+ if text is not None:
+ encoding = self.tokenizer(
+ text, return_tensors=return_tensors, padding=padding, truncation=truncation, max_length=max_length
+ )
+
+ if images is not None:
+ image_features = self.image_processor(images, return_tensors=return_tensors)
+
+ if text is not None and images is not None:
+ encoding.update(image_features)
+ return encoding
+ elif text is not None:
+ return encoding
+ else:
+ return BatchFeature(data=dict(**image_features), tensor_type=return_tensors)
+
+
+__all__ = ["SiglipProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/tokenization_siglip.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/tokenization_siglip.py
new file mode 100644
index 0000000000000000000000000000000000000000..7a82a7a411ab3e548d055c22e8bbe7d0bc2b3dd3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip/tokenization_siglip.py
@@ -0,0 +1,380 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for SigLIP model."""
+
+import os
+import re
+import string
+import warnings
+from shutil import copyfile
+from typing import TYPE_CHECKING, Any, Optional
+
+import sentencepiece as spm
+
+from ...convert_slow_tokenizer import import_protobuf
+from ...tokenization_utils import PreTrainedTokenizer
+from ...tokenization_utils_base import AddedToken
+
+
+if TYPE_CHECKING:
+ from ...tokenization_utils_base import TextInput
+from ...utils import logging, requires_backends
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "spiece.model"}
+
+
+SPIECE_UNDERLINE = "▁"
+
+
+@requires(backends=("sentencepiece",))
+class SiglipTokenizer(PreTrainedTokenizer):
+ """
+ Construct a Siglip tokenizer. Based on [SentencePiece](https://github.com/google/sentencepiece).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ [SentencePiece](https://github.com/google/sentencepiece) file (generally has a *.spm* extension) that
+ contains the vocabulary necessary to instantiate a tokenizer.
+ eos_token (`str`, *optional*, defaults to `""`):
+ The end of sequence token.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ additional_special_tokens (`list[str]`, *optional*):
+ Additional special tokens used by the tokenizer.
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+ model_max_length (`int`, *optional*, defaults to 64):
+ The maximum length (in number of tokens) for model inputs.
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ eos_token="",
+ unk_token="",
+ pad_token="",
+ additional_special_tokens=None,
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ model_max_length=64,
+ do_lower_case=True,
+ **kwargs,
+ ) -> None:
+ requires_backends(self, "protobuf")
+
+ pad_token = (
+ AddedToken(pad_token, rstrip=True, lstrip=True, normalized=False, special=True)
+ if isinstance(pad_token, str)
+ else pad_token
+ )
+ unk_token = (
+ AddedToken(unk_token, rstrip=True, lstrip=True, normalized=False, special=True)
+ if isinstance(unk_token, str)
+ else unk_token
+ )
+ eos_token = (
+ AddedToken(eos_token, rstrip=True, lstrip=True, normalized=False, special=True)
+ if isinstance(eos_token, str)
+ else eos_token
+ )
+
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+
+ self.do_lower_case = do_lower_case
+ self.vocab_file = vocab_file
+
+ self.sp_model = self.get_spm_processor()
+ self.vocab_file = vocab_file
+
+ super().__init__(
+ eos_token=eos_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ additional_special_tokens=additional_special_tokens,
+ sp_model_kwargs=self.sp_model_kwargs,
+ model_max_length=model_max_length,
+ do_lower_case=do_lower_case,
+ **kwargs,
+ )
+
+ def get_spm_processor(self):
+ tokenizer = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ with open(self.vocab_file, "rb") as f:
+ sp_model = f.read()
+ model_pb2 = import_protobuf()
+ model = model_pb2.ModelProto.FromString(sp_model)
+ normalizer_spec = model_pb2.NormalizerSpec()
+ normalizer_spec.add_dummy_prefix = False
+ model.normalizer_spec.MergeFrom(normalizer_spec)
+ sp_model = model.SerializeToString()
+ tokenizer.LoadFromSerializedProto(sp_model)
+ return tokenizer
+
+ @property
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.vocab_size
+ def vocab_size(self):
+ return self.sp_model.get_piece_size()
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.get_vocab
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.get_special_tokens_mask
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ # normal case: some special tokens
+ if token_ids_1 is None:
+ return ([0] * len(token_ids_0)) + [1]
+ return ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer._add_eos_if_not_present
+ def _add_eos_if_not_present(self, token_ids: list[int]) -> list[int]:
+ """Do not add eos again if user already added it."""
+ if len(token_ids) > 0 and token_ids[-1] == self.eos_token_id:
+ warnings.warn(
+ f"This sequence already has {self.eos_token}. In future versions this behavior may lead to duplicated"
+ " eos tokens being added."
+ )
+ return token_ids
+ else:
+ return token_ids + [self.eos_token_id]
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.create_token_type_ids_from_sequences
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. T5 does not make
+ use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+ """
+ eos = [self.eos_token_id]
+
+ if token_ids_1 is None:
+ return len(token_ids_0 + eos) * [0]
+ return len(token_ids_0 + eos + token_ids_1 + eos) * [0]
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.build_inputs_with_special_tokens
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. A sequence has the following format:
+
+ - single sequence: `X `
+ - pair of sequences: `A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ token_ids_0 = self._add_eos_if_not_present(token_ids_0)
+ if token_ids_1 is None:
+ return token_ids_0
+ else:
+ token_ids_1 = self._add_eos_if_not_present(token_ids_1)
+ return token_ids_0 + token_ids_1
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.__getstate__
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ return state
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.__setstate__
+ def __setstate__(self, d):
+ self.__dict__ = d
+
+ # for backward compatibility
+ if not hasattr(self, "sp_model_kwargs"):
+ self.sp_model_kwargs = {}
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(self.vocab_file)
+
+ def remove_punctuation(self, text: str) -> str:
+ return text.translate(str.maketrans("", "", string.punctuation))
+
+ # source: https://github.com/google-research/big_vision/blob/3b8e5ab6ad4f96e32b32826f9e1b8fd277914f9c/big_vision/evaluators/proj/image_text/prompt_engineering.py#L94
+ def canonicalize_text(self, text, *, keep_punctuation_exact_string=None):
+ """Returns canonicalized `text` (puncuation removed).
+
+ Args:
+ text (`str`):
+ String to be canonicalized.
+ keep_punctuation_exact_string (`str`, *optional*):
+ If provided, then this exact string is kept. For example providing '{}' will keep any occurrences of '{}'
+ (but will still remove '{' and '}' that appear separately).
+ """
+ if keep_punctuation_exact_string:
+ text = keep_punctuation_exact_string.join(
+ self.remove_punctuation(part) for part in text.split(keep_punctuation_exact_string)
+ )
+ else:
+ text = self.remove_punctuation(text)
+ text = re.sub(r"\s+", " ", text)
+ text = text.strip()
+
+ return text
+
+ def tokenize(self, text: "TextInput", add_special_tokens=False, **kwargs) -> list[str]:
+ """
+ Converts a string to a list of tokens.
+ """
+ tokens = super().tokenize(SPIECE_UNDERLINE + text.replace(SPIECE_UNDERLINE, " "), **kwargs)
+
+ if len(tokens) > 1 and tokens[0] == SPIECE_UNDERLINE and tokens[1] in self.all_special_tokens:
+ tokens = tokens[1:]
+ return tokens
+
+ @property
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.unk_token_length
+ def unk_token_length(self):
+ return len(self.sp_model.encode(str(self.unk_token)))
+
+ def _tokenize(self, text, **kwargs):
+ """
+ Returns a tokenized string.
+
+ We de-activated the `add_dummy_prefix` option, thus the sentencepiece internals will always strip any
+ SPIECE_UNDERLINE.
+
+ For example: `self.sp_model.encode(f"{SPIECE_UNDERLINE}Hey", out_type = str)` will give `['H', 'e', 'y']` instead of `['▁He', 'y']`.
+
+ Thus we always encode `f"{unk_token}text"` and strip the `unk_token`. Here is an example with `unk_token = ""` and `unk_token_length = 4`.
+ `self.tokenizer.sp_model.encode(" Hey", out_type = str)[4:]`.
+ """
+ text = self.canonicalize_text(text, keep_punctuation_exact_string=None)
+ tokens = self.sp_model.encode(text, out_type=str)
+
+ # 1. Encode string + prefix ex: " Hey"
+ tokens = self.sp_model.encode(self.unk_token + text, out_type=str)
+ # 2. Remove self.unk_token from ['<','unk','>', '▁Hey']
+ return tokens[self.unk_token_length :] if len(tokens) >= self.unk_token_length else tokens
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer._convert_token_to_id
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.sp_model.piece_to_id(token)
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer._convert_id_to_token
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ token = self.sp_model.IdToPiece(index)
+ return token
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ current_sub_tokens = []
+ out_string = ""
+ prev_is_special = False
+ for token in tokens:
+ # make sure that special tokens are not decoded using sentencepiece model
+ if token in self.all_special_tokens:
+ if not prev_is_special:
+ out_string += " "
+ out_string += self.sp_model.decode(current_sub_tokens) + token
+ prev_is_special = True
+ current_sub_tokens = []
+ else:
+ current_sub_tokens.append(token)
+ prev_is_special = False
+ out_string += self.sp_model.decode(current_sub_tokens)
+ return out_string.strip()
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.save_vocabulary
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ elif not os.path.isfile(self.vocab_file):
+ with open(out_vocab_file, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["SiglipTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..fe5b732b951367cd130d7edd3299eda74f9dc267
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_siglip2 import *
+ from .image_processing_siglip2 import *
+ from .image_processing_siglip2_fast import *
+ from .modeling_siglip2 import *
+ from .processing_siglip2 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/configuration_siglip2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/configuration_siglip2.py
new file mode 100644
index 0000000000000000000000000000000000000000..67ef9df8f4f8f03608d7ef5c09b269c4cc74433b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/configuration_siglip2.py
@@ -0,0 +1,265 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/siglip2/modular_siglip2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_siglip2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Siglip2TextConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Siglip2TextModel`]. It is used to instantiate a
+ Siglip2 text encoder according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the text encoder of the Siglip2
+ [google/siglip2-base-patch16-224](https://huggingface.co/google/siglip2-base-patch16-224) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32000):
+ Vocabulary size of the Siglip2 text model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`Siglip2Model`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ max_position_embeddings (`int`, *optional*, defaults to 64):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ pad_token_id (`int`, *optional*, defaults to 1):
+ The id of the padding token in the vocabulary.
+ bos_token_id (`int`, *optional*, defaults to 49406):
+ The id of the beginning-of-sequence token in the vocabulary.
+ eos_token_id (`int`, *optional*, defaults to 49407):
+ The id of the end-of-sequence token in the vocabulary.
+ projection_size (`int`, *optional*, defaults to `hidden_size`):
+ The size of the projection head.
+
+ Example:
+
+ ```python
+ >>> from transformers import Siglip2TextConfig, Siglip2TextModel
+
+ >>> # Initializing a Siglip2TextConfig with google/siglip2-base-patch16-224 style configuration
+ >>> configuration = Siglip2TextConfig()
+
+ >>> # Initializing a Siglip2TextModel (with random weights) from the google/siglip2-base-patch16-224 style configuration
+ >>> model = Siglip2TextModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "siglip2_text_model"
+ base_config_key = "text_config"
+
+ def __init__(
+ self,
+ vocab_size=32000,
+ hidden_size=768,
+ intermediate_size=3072,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ max_position_embeddings=64,
+ hidden_act="gelu_pytorch_tanh",
+ layer_norm_eps=1e-6,
+ attention_dropout=0.0,
+ # This differs from `CLIPTokenizer`'s default and from openai/siglip2
+ # See https://github.com/huggingface/transformers/pull/24773#issuecomment-1632287538
+ pad_token_id=1,
+ bos_token_id=49406,
+ eos_token_id=49407,
+ projection_size=None,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.max_position_embeddings = max_position_embeddings
+ self.layer_norm_eps = layer_norm_eps
+ self.hidden_act = hidden_act
+ self.attention_dropout = attention_dropout
+ self.projection_size = projection_size if projection_size is not None else hidden_size
+
+
+class Siglip2VisionConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Siglip2VisionModel`]. It is used to instantiate a
+ Siglip2 vision encoder according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the vision encoder of the Siglip2
+ [google/siglip2-base-patch16-naflex](https://huggingface.co/google/siglip2-base-patch16-naflex) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_channels (`int`, *optional*, defaults to 3):
+ Number of channels in the input images.
+ num_patches (`int`, *optional*, defaults to 256):
+ The number of patches in the image with the size of (`patch_size`, `patch_size`).
+ The image is resized to fill maximum of this number of patches, and to preserve
+ the aspect ratio. In case the resulted number of patches is lower, the image is
+ padded in "patch" dimension.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+
+ Example:
+
+ ```python
+ >>> from transformers import Siglip2VisionConfig, Siglip2VisionModel
+
+ >>> # Initializing a Siglip2VisionConfig with google/siglip2-base-patch16-naflex style configuration
+ >>> configuration = Siglip2VisionConfig()
+
+ >>> # Initializing a Siglip2VisionModel (with random weights) from the google/siglip2-base-patch16-naflex style configuration
+ >>> model = Siglip2VisionModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "siglip2_vision_model"
+ base_config_key = "vision_config"
+
+ def __init__(
+ self,
+ hidden_size=768,
+ intermediate_size=3072,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ num_channels=3,
+ num_patches=256,
+ patch_size=16,
+ hidden_act="gelu_pytorch_tanh",
+ layer_norm_eps=1e-6,
+ attention_dropout=0.0,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.num_channels = num_channels
+ self.patch_size = patch_size
+ self.attention_dropout = attention_dropout
+ self.layer_norm_eps = layer_norm_eps
+ self.hidden_act = hidden_act
+ self.num_patches = num_patches
+
+
+class Siglip2Config(PretrainedConfig):
+ r"""
+ [`Siglip2Config`] is the configuration class to store the configuration of a [`Siglip2Model`]. It is used to
+ instantiate a Siglip2 model according to the specified arguments, defining the text model and vision model configs.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the Siglip2
+ [google/siglip2-base-patch16-224](https://huggingface.co/google/siglip2-base-patch16-224) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ text_config (`dict`, *optional*):
+ Dictionary of configuration options used to initialize [`Siglip2TextConfig`].
+ vision_config (`dict`, *optional*):
+ Dictionary of configuration options used to initialize [`Siglip2VisionConfig`].
+ kwargs (*optional*):
+ Dictionary of keyword arguments.
+
+ Example:
+
+ ```python
+ >>> from transformers import Siglip2Config, Siglip2Model
+
+ >>> # Initializing a Siglip2Config with google/siglip2-base-patch16-224 style configuration
+ >>> configuration = Siglip2Config()
+
+ >>> # Initializing a Siglip2Model (with random weights) from the google/siglip2-base-patch16-224 style configuration
+ >>> model = Siglip2Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+
+ >>> # We can also initialize a Siglip2Config from a Siglip2TextConfig and a Siglip2VisionConfig
+ >>> from transformers import Siglip2TextConfig, Siglip2VisionConfig
+
+ >>> # Initializing a Siglip2Text and Siglip2Vision configuration
+ >>> config_text = Siglip2TextConfig()
+ >>> config_vision = Siglip2VisionConfig()
+
+ >>> config = Siglip2Config.from_text_vision_configs(config_text, config_vision)
+ ```"""
+
+ model_type = "siglip2"
+ sub_configs = {"text_config": Siglip2TextConfig, "vision_config": Siglip2VisionConfig}
+
+ def __init__(self, text_config=None, vision_config=None, **kwargs):
+ super().__init__(**kwargs)
+
+ if text_config is None:
+ text_config = {}
+ logger.info("`text_config` is `None`. Initializing the `Siglip2TextConfig` with default values.")
+
+ if vision_config is None:
+ vision_config = {}
+ logger.info("`vision_config` is `None`. initializing the `Siglip2VisionConfig` with default values.")
+
+ self.text_config = Siglip2TextConfig(**text_config)
+ self.vision_config = Siglip2VisionConfig(**vision_config)
+
+ self.initializer_factor = 1.0
+
+
+__all__ = ["Siglip2Config", "Siglip2TextConfig", "Siglip2VisionConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2.py
new file mode 100644
index 0000000000000000000000000000000000000000..30b5f1b958af2dadd2c7dcc79619f418857086fc
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2.py
@@ -0,0 +1,344 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for SigLIP2."""
+
+import math
+from functools import lru_cache
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature
+from ...image_transforms import (
+ convert_to_rgb,
+ resize,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_flat_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+if is_vision_available():
+ from PIL import Image
+
+
+@lru_cache(maxsize=256)
+def get_image_size_for_max_num_patches(
+ image_height: int, image_width: int, patch_size: int, max_num_patches: int, eps: float = 1e-5
+) -> tuple[int, int]:
+ """
+ Determine image size based on max number of patches, ensure dimensions are divisible by patch size and image is at least 1 patch.
+
+ Args:
+ image_height (`int`):
+ Original image height.
+ image_width (`int`):
+ Original image width.
+ patch_size (`int`):
+ Patch size for processing.
+ max_num_patches (`int`):
+ Maximum number of patches.
+ eps (`float`):
+ Small threshold for binary search.
+
+ Returns:
+ Tuple: (target_height, target_width)
+ """
+
+ def get_scaled_image_size(scale: float, size: int, patch_size: int) -> int:
+ scaled_size = size * scale
+ scaled_size = math.ceil(scaled_size / patch_size) * patch_size # make divisible by patch_size
+ scaled_size = max(patch_size, scaled_size) # ensure at least 1 patch
+ return int(scaled_size)
+
+ # Binary search for optimal scale
+ scale_min, scale_max = eps / 10, 100.0
+ while (scale_max - scale_min) >= eps:
+ scale = (scale_min + scale_max) / 2
+ target_height = get_scaled_image_size(scale, image_height, patch_size)
+ target_width = get_scaled_image_size(scale, image_width, patch_size)
+ num_patches = (target_height / patch_size) * (target_width / patch_size)
+
+ if num_patches <= max_num_patches:
+ scale_min = scale
+ else:
+ scale_max = scale
+
+ scale = scale_min
+ target_height = get_scaled_image_size(scale, image_height, patch_size)
+ target_width = get_scaled_image_size(scale, image_width, patch_size)
+ return target_height, target_width
+
+
+def convert_image_to_patches(image: np.ndarray, patch_size: int) -> np.ndarray:
+ """
+ Convert 3D array image of shape (image_height, image_width, num_channels) into 2D array of patches of shape
+ (num_patches_height * num_patches_width, patch_size * patch_size * num_channels).
+ """
+ image_height, image_width, num_channels = image.shape
+ num_patches_height = image_height // patch_size
+ num_patches_width = image_width // patch_size
+ patched_image = image.reshape(num_patches_height, patch_size, num_patches_width, patch_size, num_channels)
+ patched_image = patched_image.transpose(0, 2, 1, 3, 4)
+ patched_image = patched_image.reshape(num_patches_height * num_patches_width, -1)
+ return patched_image
+
+
+def pad_along_first_dim(array: np.ndarray, target_length: int, pad_value: int = 0) -> tuple[np.ndarray, np.ndarray]:
+ """
+ Pad the array along the first dimension.
+ """
+ current_length = array.shape[0]
+ padding_length = target_length - current_length
+ mask = np.ones((target_length,), dtype=np.int32)
+ if padding_length > 0:
+ paddings = [(0, padding_length)] + [(0, 0)] * (array.ndim - 1)
+ array = np.pad(array, paddings, mode="constant", constant_values=pad_value)
+ mask[-padding_length:] = 0
+ return array, mask
+
+
+class Siglip2ImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a SigLIP2 image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's dimensions to fit `max_num_patches` according to given `patch_size`.
+ Can be overridden by `do_resize` in the `preprocess` method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in
+ the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess`
+ method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image by the specified mean and standard deviation. Can be overridden by
+ `do_normalize` in the `preprocess` method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_convert_rgb (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to RGB.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch the image will be split to.
+ max_num_patches (`int`, *optional*, defaults to 256):
+ The image will be resized to have at most this number of patches,
+ and then padded in "patch" dimension to match this number exactly.
+ """
+
+ model_input_names = ["pixel_values", "pixel_attention_mask", "spatial_shapes"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ resample: "PILImageResampling" = PILImageResampling.BILINEAR,
+ do_rescale: bool = True,
+ rescale_factor: float = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ patch_size: int = 16,
+ max_num_patches: int = 256,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ image_mean = image_mean if image_mean is not None else [0.5, 0.5, 0.5]
+ image_std = image_std if image_std is not None else [0.5, 0.5, 0.5]
+
+ self.do_resize = do_resize
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean
+ self.image_std = image_std
+ self.do_convert_rgb = do_convert_rgb
+ self.patch_size = patch_size
+ self.max_num_patches = max_num_patches
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_resize: Optional[bool] = None,
+ resample: Optional["PILImageResampling"] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ patch_size: Optional[int] = None,
+ max_num_patches: Optional[int] = None,
+ ) -> "Image.Image":
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after resizing.
+ resample (`int`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only
+ has an effect if `do_resize` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image.
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to
+ `True`.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`):
+ Whether to convert the image to RGB.
+ patch_size (`int`, *optional*, defaults to `self.patch_size`):
+ Patch size for processing, same as the patch size used in the model.
+ max_num_patches (`int`, *optional*, defaults to `self.max_num_patches`):
+ Maximum number of patches per image, the image will be resized to have at most this number of patches.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb
+ patch_size = patch_size if patch_size is not None else self.patch_size
+ max_num_patches = max_num_patches if max_num_patches is not None else self.max_num_patches
+
+ # Explicitly specify data format to be channels last for image preprocessing.
+ # Image processor does not support different output formats, because it returns patches.
+ data_format = ChannelDimension.LAST
+
+ images = self.fetch_images(images)
+ images = make_flat_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ )
+ if do_convert_rgb:
+ images = [convert_to_rgb(image) for image in images]
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ pixel_masks = []
+ pixel_values = []
+ spatial_shapes = []
+
+ for image in images:
+ image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+
+ if do_resize:
+ height, width = get_image_size_for_max_num_patches(
+ image_height=image.shape[0],
+ image_width=image.shape[1],
+ patch_size=patch_size,
+ max_num_patches=max_num_patches,
+ )
+ image = resize(image=image, size=(height, width), resample=resample, input_data_format=data_format)
+
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, input_data_format=data_format)
+
+ if do_normalize:
+ image = self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=data_format)
+
+ patches = convert_image_to_patches(image, patch_size)
+ patches, mask = pad_along_first_dim(patches, max_num_patches)
+ num_patches_height = image.shape[0] // patch_size
+ num_patches_width = image.shape[1] // patch_size
+
+ spatial_shapes.append((num_patches_height, num_patches_width))
+ pixel_values.append(patches)
+ pixel_masks.append(mask)
+
+ batch_feature = BatchFeature(
+ data={
+ "pixel_values": pixel_values,
+ "pixel_attention_mask": pixel_masks,
+ "spatial_shapes": spatial_shapes,
+ },
+ tensor_type=return_tensors,
+ )
+
+ return batch_feature
+
+
+__all__ = ["Siglip2ImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..bbab919619624a95cab721b26961881397201eca
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2_fast.py
@@ -0,0 +1,182 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for SigLIP2."""
+
+from typing import Optional, Union
+
+import torch
+
+from ...image_processing_utils import BatchFeature
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ SizeDict,
+)
+from ...image_utils import (
+ ImageInput,
+ PILImageResampling,
+)
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+ logging,
+)
+from .image_processing_siglip2 import get_image_size_for_max_num_patches
+
+
+if is_torch_available():
+ import torch
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+
+logger = logging.get_logger(__name__)
+
+
+def convert_image_to_patches(image: "torch.Tensor", patch_size: int) -> "torch.Tensor":
+ """
+ Convert 3D tensor image of shape (num_channels, image_height, image_width) into 2D tensor of patches of shape
+ (num_patches_height * num_patches_width, patch_size * patch_size * num_channels).
+ """
+ num_channels, image_height, image_width = image.shape
+ num_patches_height = image_height // patch_size
+ num_patches_width = image_width // patch_size
+ patched_image = image.reshape(num_channels, num_patches_height, patch_size, num_patches_width, patch_size)
+ patched_image = patched_image.permute(1, 3, 2, 4, 0)
+ patched_image = patched_image.reshape(num_patches_height * num_patches_width, -1)
+ return patched_image
+
+
+def pad_along_first_dim(
+ tensor: "torch.Tensor", target_length: int, pad_value: int = 0
+) -> tuple["torch.Tensor", "torch.Tensor"]:
+ """
+ Pad the tensor along the first dimension.
+ """
+ current_length = tensor.shape[0]
+ padding_length = target_length - current_length
+ mask = torch.ones((target_length,), dtype=torch.int32)
+ if padding_length > 0:
+ padding = [0, 0] * (tensor.ndim - 1) + [0, padding_length]
+ tensor = torch.nn.functional.pad(tensor, padding, mode="constant", value=pad_value)
+ mask[-padding_length:] = 0
+ return tensor, mask
+
+
+class Siglip2FastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ """
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch the image will be split to.
+ max_num_patches (`int`, *optional*, defaults to 256):
+ The image will be resized to have at most this number of patches,
+ and then padded in "patch" dimension to match this number exactly.
+ """
+
+ patch_size: Optional[int]
+ max_num_patches: Optional[int]
+
+
+@auto_docstring
+class Siglip2ImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BILINEAR
+ image_mean = [0.5, 0.5, 0.5]
+ image_std = [0.5, 0.5, 0.5]
+ do_resize = True
+ do_rescale = True
+ do_normalize = True
+ patch_size = 16
+ max_num_patches = 256
+ valid_kwargs = Siglip2FastImageProcessorKwargs
+ unused_kwargs = ["size", "do_center_crop", "crop_size"]
+
+ def __init__(self, **kwargs: Unpack[Siglip2FastImageProcessorKwargs]):
+ super().__init__(**kwargs)
+
+ def _validate_preprocess_kwargs(self, **kwargs) -> tuple:
+ # Remove do_resize from kwargs to not raise an error as size is None
+ kwargs.pop("do_resize", None)
+ return super()._validate_preprocess_kwargs(**kwargs)
+
+ @auto_docstring
+ def preprocess(self, images: ImageInput, **kwargs: Unpack[Siglip2FastImageProcessorKwargs]) -> BatchFeature:
+ return super().preprocess(images, **kwargs)
+
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ do_resize: bool,
+ patch_size: int,
+ max_num_patches: int,
+ interpolation: Optional["F.InterpolationMode"],
+ do_rescale: bool,
+ rescale_factor: float,
+ do_normalize: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ return_tensors: Optional[Union[str, TensorType]],
+ **kwargs,
+ ) -> BatchFeature:
+ pixel_masks = []
+ pixel_values = []
+ spatial_shapes = []
+
+ for image in images:
+ if do_resize:
+ height, width = get_image_size_for_max_num_patches(
+ image_height=image.shape[1],
+ image_width=image.shape[2],
+ patch_size=patch_size,
+ max_num_patches=max_num_patches,
+ )
+ side_dict = SizeDict(height=height, width=width)
+ image = self.resize(image=image, size=side_dict, interpolation=interpolation)
+
+ image = self.rescale_and_normalize(image, do_rescale, rescale_factor, do_normalize, image_mean, image_std)
+
+ # (num_channels, height, width) -> (num_patches, patch_size * patch_size * num_channels)
+ patches = convert_image_to_patches(image, patch_size)
+ patches, mask = pad_along_first_dim(patches, max_num_patches)
+
+ num_patches_height = image.shape[1] // patch_size
+ num_patches_width = image.shape[2] // patch_size
+
+ spatial_shapes.append((num_patches_height, num_patches_width))
+ pixel_values.append(patches)
+ pixel_masks.append(mask)
+
+ pixel_values = torch.stack(pixel_values)
+ pixel_masks = torch.stack(pixel_masks)
+ spatial_shapes = torch.tensor(spatial_shapes)
+
+ batch_feature = BatchFeature(
+ data={
+ "pixel_values": pixel_values,
+ "pixel_attention_mask": pixel_masks,
+ "spatial_shapes": spatial_shapes,
+ },
+ tensor_type=return_tensors,
+ )
+ return batch_feature
+
+
+__all__ = ["Siglip2ImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/modeling_siglip2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/modeling_siglip2.py
new file mode 100644
index 0000000000000000000000000000000000000000..6e984534afbac566e1a7f0535b6e3ab496b3c310
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/modeling_siglip2.py
@@ -0,0 +1,1303 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/siglip2/modular_siglip2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_siglip2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Any, Callable, Optional, Union
+
+import numpy as np
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+from torch.nn.init import _calculate_fan_in_and_fan_out
+
+from ...activations import ACT2FN
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, ImageClassifierOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...utils import ModelOutput, auto_docstring, can_return_tuple
+from .configuration_siglip2 import Siglip2Config, Siglip2TextConfig, Siglip2VisionConfig
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for vision model's outputs that also contains image embeddings of the pooling of the last hidden states.
+ """
+)
+class Siglip2VisionOutput(ModelOutput):
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`):
+ The image embeddings obtained by applying the projection layer to the pooler_output.
+ """
+
+ image_embeds: Optional[torch.FloatTensor] = None
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for text model's outputs that also contains a pooling of the last hidden states.
+ """
+)
+class Siglip2TextOutput(ModelOutput):
+ r"""
+ text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`):
+ The text embeddings obtained by applying the projection layer to the pooler_output.
+ """
+
+ text_embeds: Optional[torch.FloatTensor] = None
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring
+class Siglip2Output(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `return_loss` is `True`):
+ Contrastive loss for image-text similarity.
+ logits_per_image (`torch.FloatTensor` of shape `(image_batch_size, text_batch_size)`):
+ The scaled dot product scores between `image_embeds` and `text_embeds`. This represents the image-text
+ similarity scores.
+ logits_per_text (`torch.FloatTensor` of shape `(text_batch_size, image_batch_size)`):
+ The scaled dot product scores between `text_embeds` and `image_embeds`. This represents the text-image
+ similarity scores.
+ text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`):
+ The text embeddings obtained by applying the projection layer to the pooled output of [`Siglip2TextModel`].
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`):
+ The image embeddings obtained by applying the projection layer to the pooled output of [`Siglip2VisionModel`].
+ text_model_output (`BaseModelOutputWithPooling`):
+ The output of the [`Siglip2TextModel`].
+ vision_model_output (`BaseModelOutputWithPooling`):
+ The output of the [`Siglip2VisionModel`].
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits_per_image: Optional[torch.FloatTensor] = None
+ logits_per_text: Optional[torch.FloatTensor] = None
+ text_embeds: Optional[torch.FloatTensor] = None
+ image_embeds: Optional[torch.FloatTensor] = None
+ text_model_output: BaseModelOutputWithPooling = None
+ vision_model_output: BaseModelOutputWithPooling = None
+
+ def to_tuple(self) -> tuple[Any]:
+ return tuple(
+ self[k] if k not in ["text_model_output", "vision_model_output"] else getattr(self, k).to_tuple()
+ for k in self.keys()
+ )
+
+
+class Siglip2VisionEmbeddings(nn.Module):
+ def __init__(self, config: Siglip2VisionConfig):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.patch_size = config.patch_size
+
+ self.patch_embedding = nn.Linear(
+ in_features=config.num_channels * self.patch_size * self.patch_size,
+ out_features=self.embed_dim,
+ )
+
+ self.num_patches = config.num_patches
+ self.position_embedding_size = int(self.num_patches**0.5)
+ self.position_embedding = nn.Embedding(self.num_patches, self.embed_dim)
+
+ @staticmethod
+ def resize_positional_embeddings(
+ positional_embeddings: torch.Tensor,
+ spatial_shapes: torch.LongTensor,
+ max_length: int,
+ ) -> torch.Tensor:
+ """
+ Resize positional embeddings to image-specific size and pad to a fixed size.
+
+ Args:
+ positional_embeddings (`torch.Tensor`):
+ Position embeddings of shape (height, width, embed_dim)
+ spatial_shapes (`torch.LongTensor`):
+ Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to
+ max_length (`int`):
+ Maximum length of the positional embeddings to pad resized positional embeddings to
+
+ Returns:
+ `torch.Tensor`: Embeddings of shape (batch_size, max_length, embed_dim)
+ """
+ batch_size = spatial_shapes.shape[0]
+ embed_dim = positional_embeddings.shape[-1]
+ source_dtype = positional_embeddings.dtype
+
+ resulted_positional_embeddings = torch.empty(
+ (batch_size, max_length, embed_dim),
+ device=positional_embeddings.device,
+ dtype=source_dtype,
+ )
+
+ # (height, width, embed_dim) -> (1, embed_dim, height, width) for interpolation
+ positional_embeddings = positional_embeddings.permute(2, 0, 1).unsqueeze(0)
+
+ # Upcast to float32 on CPU because antialias is not supported for bfloat16/float16 on CPU
+ if positional_embeddings.device.type == "cpu":
+ positional_embeddings = positional_embeddings.to(torch.float32)
+
+ for i in range(batch_size):
+ # (1, dim, height, width) -> (1, dim, target_height, target_width)
+ height, width = spatial_shapes[i]
+ resized_embeddings = F.interpolate(
+ positional_embeddings,
+ size=(height, width),
+ mode="bilinear",
+ align_corners=False,
+ antialias=True,
+ )
+
+ # (1, dim, target_height, target_width) -> (target_height * target_width, dim)
+ resized_embeddings = resized_embeddings.reshape(embed_dim, height * width).transpose(0, 1)
+
+ # Cast to original dtype
+ resized_embeddings = resized_embeddings.to(source_dtype)
+
+ resulted_positional_embeddings[i, : height * width] = resized_embeddings
+ resulted_positional_embeddings[i, height * width :] = resized_embeddings[0]
+
+ return resulted_positional_embeddings
+
+ def forward(self, pixel_values: torch.FloatTensor, spatial_shapes: torch.LongTensor) -> torch.Tensor:
+ """
+ Args:
+ pixel_values (`torch.FloatTensor`):
+ Pixel values of shape (batch_size, max_num_patches, num_channels * patch_size * patch_size)
+ spatial_shapes (`list[tuple[int, int]]`):
+ Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to
+ """
+
+ # Apply patch embeddings to already patchified pixel values
+ target_dtype = self.patch_embedding.weight.dtype
+ patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype))
+
+ # Get positional resized and padded positional embeddings
+ positional_embeddings = self.position_embedding.weight.reshape(
+ self.position_embedding_size, self.position_embedding_size, -1
+ )
+ resized_positional_embeddings = self.resize_positional_embeddings(
+ positional_embeddings, spatial_shapes, max_length=pixel_values.shape[1]
+ )
+
+ # Add positional embeddings to patch embeddings
+ embeddings = patch_embeds + resized_positional_embeddings
+ return embeddings
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class Siglip2Attention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+ self.is_causal = False
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ batch_size, seq_length, embed_dim = hidden_states.shape
+
+ queries = self.q_proj(hidden_states)
+ keys = self.k_proj(hidden_states)
+ values = self.v_proj(hidden_states)
+
+ queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ queries,
+ keys,
+ values,
+ attention_mask,
+ is_causal=self.is_causal,
+ scaling=self.scale,
+ dropout=0.0 if not self.training else self.dropout,
+ )
+
+ attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+class Siglip2MLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.activation_fn = ACT2FN[config.hidden_act]
+ self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.fc1(hidden_states)
+ hidden_states = self.activation_fn(hidden_states)
+ hidden_states = self.fc2(hidden_states)
+ return hidden_states
+
+
+class Siglip2EncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: Union[Siglip2VisionConfig, Siglip2TextConfig]):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.self_attn = Siglip2Attention(config)
+ self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.mlp = Siglip2MLP(config)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.FloatTensor]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`):
+ Input to the layer of shape `(batch, seq_len, embed_dim)`.
+ attention_mask (`torch.FloatTensor`):
+ Attention mask of shape `(batch, 1, q_len, k_v_seq_len)` where padding elements are indicated by very large negative values.
+ output_attentions (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class Siglip2Encoder(nn.Module):
+ """
+ Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a
+ [`Siglip2EncoderLayer`].
+
+ Args:
+ config: Siglip2Config
+ """
+
+ def __init__(self, config: Siglip2Config):
+ super().__init__()
+ self.config = config
+ self.layers = nn.ModuleList([Siglip2EncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ # Ignore copy
+ @can_return_tuple
+ def forward(
+ self,
+ inputs_embeds,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutput:
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ hidden_states = inputs_embeds
+ for encoder_layer in self.layers:
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=encoder_states,
+ attentions=all_attentions,
+ )
+
+
+class Siglip2VisionTransformer(nn.Module):
+ def __init__(self, config: Siglip2VisionConfig):
+ super().__init__()
+ self.config = config
+ embed_dim = config.hidden_size
+
+ self.embeddings = Siglip2VisionEmbeddings(config)
+ self.encoder = Siglip2Encoder(config)
+ self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.use_head = True if not hasattr(config, "vision_use_head") else config.vision_use_head
+ if self.use_head:
+ self.head = Siglip2MultiheadAttentionPoolingHead(config)
+ self._use_flash_attention_2 = config._attn_implementation == "flash_attention_2"
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ attention_mask: torch.Tensor,
+ spatial_shapes: torch.LongTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ hidden_states = self.embeddings(pixel_values, spatial_shapes)
+
+ if attention_mask is not None and not self._use_flash_attention_2:
+ # [batch_size, seq_len] -> [batch_size, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_states.dtype)
+ else:
+ encoder_attention_mask = attention_mask
+
+ encoder_outputs: BaseModelOutput = self.encoder(
+ inputs_embeds=hidden_states,
+ attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ last_hidden_state = encoder_outputs.last_hidden_state
+ last_hidden_state = self.post_layernorm(last_hidden_state)
+
+ pooler_output = self.head(last_hidden_state, attention_mask) if self.use_head else None
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooler_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+def _trunc_normal_(tensor, mean, std, a, b):
+ # Cut & paste from PyTorch official master until it's in a few official releases - RW
+ # Method based on https://people.sc.fsu.edu/~jburkardt/presentations/truncated_normal.pdf
+ def norm_cdf(x):
+ # Computes standard normal cumulative distribution function
+ return (1.0 + math.erf(x / math.sqrt(2.0))) / 2.0
+
+ if (mean < a - 2 * std) or (mean > b + 2 * std):
+ warnings.warn(
+ "mean is more than 2 std from [a, b] in nn.init.trunc_normal_. "
+ "The distribution of values may be incorrect.",
+ stacklevel=2,
+ )
+
+ # Values are generated by using a truncated uniform distribution and
+ # then using the inverse CDF for the normal distribution.
+ # Get upper and lower cdf values
+ l = norm_cdf((a - mean) / std)
+ u = norm_cdf((b - mean) / std)
+
+ # Uniformly fill tensor with values from [l, u], then translate to
+ # [2l-1, 2u-1].
+ tensor.uniform_(2 * l - 1, 2 * u - 1)
+
+ # Use inverse cdf transform for normal distribution to get truncated
+ # standard normal
+ tensor.erfinv_()
+
+ # Transform to proper mean, std
+ tensor.mul_(std * math.sqrt(2.0))
+ tensor.add_(mean)
+
+ # Clamp to ensure it's in the proper range
+ tensor.clamp_(min=a, max=b)
+
+
+def trunc_normal_tf_(
+ tensor: torch.Tensor, mean: float = 0.0, std: float = 1.0, a: float = -2.0, b: float = 2.0
+) -> torch.Tensor:
+ """Fills the input Tensor with values drawn from a truncated
+ normal distribution. The values are effectively drawn from the
+ normal distribution :math:`\\mathcal{N}(\text{mean}, \text{std}^2)`
+ with values outside :math:`[a, b]` redrawn until they are within
+ the bounds. The method used for generating the random values works
+ best when :math:`a \\leq \text{mean} \\leq b`.
+
+ NOTE: this 'tf' variant behaves closer to Tensorflow / JAX impl where the
+ bounds [a, b] are applied when sampling the normal distribution with mean=0, std=1.0
+ and the result is subsequently scaled and shifted by the mean and std args.
+
+ Args:
+ tensor: an n-dimensional `torch.Tensor`
+ mean: the mean of the normal distribution
+ std: the standard deviation of the normal distribution
+ a: the minimum cutoff value
+ b: the maximum cutoff value
+ """
+ with torch.no_grad():
+ _trunc_normal_(tensor, 0, 1.0, a, b)
+ tensor.mul_(std).add_(mean)
+
+
+def variance_scaling_(tensor, scale=1.0, mode="fan_in", distribution="normal"):
+ fan_in, fan_out = _calculate_fan_in_and_fan_out(tensor)
+ if mode == "fan_in":
+ denom = fan_in
+ elif mode == "fan_out":
+ denom = fan_out
+ elif mode == "fan_avg":
+ denom = (fan_in + fan_out) / 2
+
+ variance = scale / denom
+
+ if distribution == "truncated_normal":
+ # constant is stddev of standard normal truncated to (-2, 2)
+ trunc_normal_tf_(tensor, std=math.sqrt(variance) / 0.87962566103423978)
+ elif distribution == "normal":
+ with torch.no_grad():
+ tensor.normal_(std=math.sqrt(variance))
+ elif distribution == "uniform":
+ bound = math.sqrt(3 * variance)
+ with torch.no_grad():
+ tensor.uniform_(-bound, bound)
+ else:
+ raise ValueError(f"invalid distribution {distribution}")
+
+
+def lecun_normal_(tensor):
+ variance_scaling_(tensor, mode="fan_in", distribution="truncated_normal")
+
+
+def default_flax_embed_init(tensor):
+ variance_scaling_(tensor, mode="fan_in", distribution="normal")
+
+
+@auto_docstring
+class Siglip2PreTrainedModel(PreTrainedModel):
+ config: Siglip2Config
+ base_model_prefix = "siglip2"
+ supports_gradient_checkpointing = True
+
+ _no_split_modules = [
+ "Siglip2TextEmbeddings",
+ "Siglip2VisionEmbeddings",
+ "Siglip2EncoderLayer",
+ "Siglip2MultiheadAttentionPoolingHead",
+ ]
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, Siglip2VisionEmbeddings):
+ width = (
+ self.config.vision_config.hidden_size
+ if isinstance(self.config, Siglip2Config)
+ else self.config.hidden_size
+ )
+ nn.init.normal_(module.position_embedding.weight, std=1 / np.sqrt(width))
+ elif isinstance(module, nn.Embedding):
+ default_flax_embed_init(module.weight)
+ elif isinstance(module, Siglip2Attention):
+ nn.init.xavier_uniform_(module.q_proj.weight)
+ nn.init.xavier_uniform_(module.k_proj.weight)
+ nn.init.xavier_uniform_(module.v_proj.weight)
+ nn.init.xavier_uniform_(module.out_proj.weight)
+ nn.init.zeros_(module.q_proj.bias)
+ nn.init.zeros_(module.k_proj.bias)
+ nn.init.zeros_(module.v_proj.bias)
+ nn.init.zeros_(module.out_proj.bias)
+ elif isinstance(module, Siglip2MLP):
+ nn.init.xavier_uniform_(module.fc1.weight)
+ nn.init.xavier_uniform_(module.fc2.weight)
+ nn.init.normal_(module.fc1.bias, std=1e-6)
+ nn.init.normal_(module.fc2.bias, std=1e-6)
+ elif isinstance(module, Siglip2MultiheadAttentionPoolingHead):
+ nn.init.xavier_uniform_(module.probe.data)
+ nn.init.xavier_uniform_(module.attention.in_proj_weight.data)
+ nn.init.zeros_(module.attention.in_proj_bias.data)
+ elif isinstance(module, Siglip2Model):
+ logit_scale_init = torch.log(torch.tensor(1.0))
+ module.logit_scale.data.fill_(logit_scale_init)
+ module.logit_bias.data.zero_()
+ elif isinstance(module, Siglip2ForImageClassification):
+ nn.init.normal_(
+ module.classifier.weight,
+ std=self.config.vision_config.hidden_size**-0.5 * self.config.initializer_factor,
+ )
+ elif isinstance(module, (nn.Linear, nn.Conv2d)):
+ lecun_normal_(module.weight)
+ if module.bias is not None:
+ nn.init.zeros_(module.bias)
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+class Siglip2TextEmbeddings(nn.Module):
+ def __init__(self, config: Siglip2TextConfig):
+ super().__init__()
+ embed_dim = config.hidden_size
+
+ self.token_embedding = nn.Embedding(config.vocab_size, embed_dim)
+ self.position_embedding = nn.Embedding(config.max_position_embeddings, embed_dim)
+
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ ) -> torch.Tensor:
+ seq_length = input_ids.shape[-1] if input_ids is not None else inputs_embeds.shape[-2]
+ max_position_embedding = self.position_embedding.weight.shape[0]
+
+ if seq_length > max_position_embedding:
+ raise ValueError(
+ f"Sequence length must be less than max_position_embeddings (got `sequence length`: "
+ f"{seq_length} and max_position_embeddings: {max_position_embedding}"
+ )
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ if inputs_embeds is None:
+ inputs_embeds = self.token_embedding(input_ids)
+
+ position_embeddings = self.position_embedding(position_ids)
+ embeddings = inputs_embeds + position_embeddings
+
+ return embeddings
+
+
+class Siglip2TextTransformer(nn.Module):
+ def __init__(self, config: Siglip2TextConfig):
+ super().__init__()
+ self.config = config
+ embed_dim = config.hidden_size
+ self.embeddings = Siglip2TextEmbeddings(config)
+ self.encoder = Siglip2Encoder(config)
+ self.final_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+
+ self.head = nn.Linear(embed_dim, config.projection_size)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ if input_ids is None:
+ raise ValueError("You have to specify input_ids")
+
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+
+ hidden_states = self.embeddings(input_ids=input_ids, position_ids=position_ids)
+
+ # note: Siglip2's text model does not use a causal mask, unlike the original CLIP model.
+ # expand attention_mask
+ uses_flash_attention = "flash" in self.config._attn_implementation
+ if uses_flash_attention:
+ attention_mask = None
+ elif attention_mask is not None and not uses_flash_attention:
+ # [batch_size, seq_len] -> [batch_size, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_states.dtype)
+
+ encoder_outputs: BaseModelOutput = self.encoder(
+ inputs_embeds=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ last_hidden_state = encoder_outputs.last_hidden_state
+ last_hidden_state = self.final_layer_norm(last_hidden_state)
+
+ # The model uses the last token's hidden state, which may be padding.
+ pooled_output = last_hidden_state[:, -1, :]
+ pooled_output = self.head(pooled_output)
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The text model from Siglip2 without any head or projection on top.
+ """
+)
+class Siglip2TextModel(Siglip2PreTrainedModel):
+ config: Siglip2TextConfig
+
+ def __init__(self, config: Siglip2TextConfig):
+ super().__init__(config)
+ self.text_model = Siglip2TextTransformer(config)
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.text_model.embeddings.token_embedding
+
+ def set_input_embeddings(self, value):
+ self.text_model.embeddings.token_embedding = value
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, Siglip2TextModel
+
+ >>> model = Siglip2TextModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> # important: make sure to set padding="max_length" as that's how the model was trained
+ >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> last_hidden_state = outputs.last_hidden_state
+ >>> pooled_output = outputs.pooler_output # pooled (EOS token) states
+ ```"""
+
+ return self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+
+class Siglip2MultiheadAttentionPoolingHead(nn.Module):
+ """Multihead Attention Pooling."""
+
+ def __init__(self, config: Siglip2VisionConfig):
+ super().__init__()
+
+ self.probe = nn.Parameter(torch.randn(1, 1, config.hidden_size))
+ self.attention = torch.nn.MultiheadAttention(config.hidden_size, config.num_attention_heads, batch_first=True)
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.mlp = Siglip2MLP(config)
+ self.num_heads = config.num_attention_heads
+
+ def forward(self, hidden_state: torch.Tensor, attention_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ batch_size = hidden_state.shape[0]
+ probe = self.probe.repeat(batch_size, 1, 1)
+
+ if attention_mask is not None:
+ target_len, source_len = probe.shape[1], hidden_state.shape[1]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_state.dtype, target_len)
+ attention_mask = attention_mask.repeat(1, self.num_heads, target_len, 1)
+ attention_mask = attention_mask.reshape(-1, target_len, source_len)
+
+ hidden_state = self.attention(probe, hidden_state, hidden_state, attn_mask=attention_mask)[0]
+
+ residual = hidden_state
+ hidden_state = self.layernorm(hidden_state)
+ hidden_state = residual + self.mlp(hidden_state)
+
+ return hidden_state[:, 0]
+
+
+@auto_docstring(
+ custom_intro="""
+ The vision model from Siglip2 without any head or projection on top.
+ """
+)
+class Siglip2VisionModel(Siglip2PreTrainedModel):
+ config: Siglip2VisionConfig
+ main_input_name = "pixel_values"
+
+ def __init__(self, config: Siglip2VisionConfig):
+ super().__init__(config)
+
+ self.vision_model = Siglip2VisionTransformer(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.vision_model.embeddings.patch_embedding
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ pixel_attention_mask: torch.Tensor,
+ spatial_shapes: torch.LongTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, Siglip2VisionModel
+
+ >>> model = Siglip2VisionModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> last_hidden_state = outputs.last_hidden_state
+ >>> pooled_output = outputs.pooler_output # pooled features
+ ```"""
+ return self.vision_model(
+ pixel_values=pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+
+@auto_docstring
+class Siglip2Model(Siglip2PreTrainedModel):
+ config: Siglip2Config
+
+ def __init__(self, config: Siglip2Config):
+ super().__init__(config)
+
+ if not isinstance(config.text_config, Siglip2TextConfig):
+ raise TypeError(
+ "config.text_config is expected to be of type Siglip2TextConfig but is of type"
+ f" {type(config.text_config)}."
+ )
+
+ if not isinstance(config.vision_config, Siglip2VisionConfig):
+ raise TypeError(
+ "config.vision_config is expected to be of type Siglip2VisionConfig but is of type"
+ f" {type(config.vision_config)}."
+ )
+
+ text_config = config.text_config
+ vision_config = config.vision_config
+
+ # First, initialize the text and vision models with proper attention implementation
+ text_model = Siglip2TextModel._from_config(text_config)
+ vision_model = Siglip2VisionModel._from_config(vision_config)
+
+ # Second, get the text and vision submodules (for backward compatibility)
+ self.text_model = text_model.text_model
+ self.vision_model = vision_model.vision_model
+
+ self.logit_scale = nn.Parameter(torch.randn(1))
+ self.logit_bias = nn.Parameter(torch.randn(1))
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def get_text_features(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> torch.FloatTensor:
+ r"""
+ Returns:
+ text_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The text embeddings obtained by
+ applying the projection layer to the pooled output of [`Siglip2TextModel`].
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> # important: make sure to set padding="max_length" as that's how the model was trained
+ >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt")
+ >>> with torch.no_grad():
+ ... text_features = model.get_text_features(**inputs)
+ ```"""
+ # Use Siglip2 model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ text_outputs: BaseModelOutputWithPooling = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ pooled_output = text_outputs.pooler_output
+
+ return pooled_output
+
+ @auto_docstring
+ def get_image_features(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_attention_mask: Optional[torch.Tensor] = None,
+ spatial_shapes: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> torch.FloatTensor:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+
+ Returns:
+ image_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The image embeddings obtained by
+ applying the projection layer to the pooled output of [`Siglip2VisionModel`].
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... image_features = model.get_image_features(**inputs)
+ ```
+ """
+ # Use Siglip2Model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ vision_outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values=pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ pooled_output = vision_outputs.pooler_output
+
+ return pooled_output
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_attention_mask: Optional[torch.Tensor] = None,
+ spatial_shapes: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ return_loss: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> Siglip2Output:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+ return_loss (`bool`, *optional*):
+ Whether or not to return the contrastive loss.
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> texts = ["a photo of 2 cats", "a photo of 2 dogs"]
+ >>> # important: we pass `padding=max_length` since the model was trained with this
+ >>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+
+ >>> logits_per_image = outputs.logits_per_image
+ >>> probs = torch.sigmoid(logits_per_image) # these are the probabilities
+ >>> print(f"{probs[0][0]:.1%} that image 0 is '{texts[0]}'")
+ 31.9% that image 0 is 'a photo of 2 cats'
+ ```
+ """
+ # Use Siglip2 model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ vision_outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values=pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ text_outputs: BaseModelOutputWithPooling = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ image_embeds = vision_outputs.pooler_output
+ text_embeds = text_outputs.pooler_output
+
+ # normalized features
+ image_embeds = image_embeds / image_embeds.norm(p=2, dim=-1, keepdim=True)
+ text_embeds = text_embeds / text_embeds.norm(p=2, dim=-1, keepdim=True)
+
+ # cosine similarity as logits
+ logits_per_text = torch.matmul(text_embeds, image_embeds.t().to(text_embeds.device))
+
+ logit_scale, logit_bias = self.logit_scale.to(text_embeds.device), self.logit_bias.to(text_embeds.device)
+ logits_per_text = logits_per_text * logit_scale.exp() + logit_bias
+
+ logits_per_image = logits_per_text.t()
+
+ loss = None
+ if return_loss:
+ # Adapted from https://github.com/google-research/big_vision/blob/01edb81a4716f93a48be43b3a4af14e29cdb3a7f/big_vision/trainers/proj/image_text/siglip2.py#L287
+ eye = torch.eye(logits_per_text.size(0), device=logits_per_text.device)
+ m1_diag1 = -torch.ones_like(logits_per_text) + 2 * eye
+ loglik = torch.nn.functional.logsigmoid(m1_diag1 * logits_per_text)
+ nll = -torch.sum(loglik, dim=-1)
+ loss = nll.mean()
+
+ return Siglip2Output(
+ loss=loss,
+ logits_per_image=logits_per_image,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ image_embeds=image_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Siglip2 vision encoder with an image classification head on top (a linear layer on top of the pooled final hidden states of
+ the patch tokens) e.g. for ImageNet.
+ """
+)
+class Siglip2ForImageClassification(Siglip2PreTrainedModel):
+ main_input_name = "pixel_values"
+
+ def __init__(self, config: Siglip2Config) -> None:
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+
+ # Create the vision model with proper attention
+ # and take only vision_model submodule (for backward compatibility)
+ vision_model = Siglip2VisionModel._from_config(config.vision_config)
+ self.vision_model = vision_model.vision_model
+
+ # Classifier head
+ self.classifier = (
+ nn.Linear(config.vision_config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity()
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ pixel_attention_mask: Optional[torch.Tensor] = None,
+ spatial_shapes: Optional[torch.LongTensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> ImageClassifierOutput:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, Siglip2ForImageClassification
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> # note: we are loading a `Siglip2Model` from the hub here,
+ >>> # so the head will be randomly initialized, hence the predictions will be random if seed is not set above.
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/siglip2-base-patch16-224")
+ >>> model = Siglip2ForImageClassification.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> logits = outputs.logits
+ >>> # model predicts one of the two classes
+ >>> predicted_class_idx = logits.argmax(-1).item()
+ >>> print("Predicted class:", model.config.id2label[predicted_class_idx])
+ Predicted class: LABEL_1
+ ```
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ sequence_output = outputs.last_hidden_state
+
+ # average pool the patch tokens
+ if pixel_attention_mask is not None:
+ pool_mask = pixel_attention_mask[..., None].to(sequence_output.device)
+ sequence_output = torch.sum(sequence_output * pool_mask, dim=1) / torch.sum(pool_mask, dim=1)
+ else:
+ sequence_output = torch.mean(sequence_output, dim=1)
+
+ # apply classifier
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "Siglip2Model",
+ "Siglip2PreTrainedModel",
+ "Siglip2TextModel",
+ "Siglip2VisionModel",
+ "Siglip2ForImageClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/modular_siglip2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/modular_siglip2.py
new file mode 100644
index 0000000000000000000000000000000000000000..2956187763c8388914573e1d480bcbfa849e1eb7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/modular_siglip2.py
@@ -0,0 +1,637 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import Optional
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from transformers.models.siglip.configuration_siglip import SiglipConfig, SiglipTextConfig, SiglipVisionConfig
+from transformers.models.siglip.modeling_siglip import (
+ BaseModelOutput,
+ BaseModelOutputWithPooling,
+ ImageClassifierOutput,
+ SiglipForImageClassification,
+ SiglipModel,
+ SiglipMultiheadAttentionPoolingHead,
+ SiglipOutput,
+ SiglipPreTrainedModel,
+ SiglipTextModel,
+ SiglipTextModelOutput,
+ SiglipVisionModel,
+ SiglipVisionModelOutput,
+ SiglipVisionTransformer,
+)
+
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+
+
+class Siglip2TextConfig(SiglipTextConfig):
+ pass
+
+
+class Siglip2VisionConfig(SiglipVisionConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Siglip2VisionModel`]. It is used to instantiate a
+ Siglip2 vision encoder according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the vision encoder of the Siglip2
+ [google/siglip2-base-patch16-naflex](https://huggingface.co/google/siglip2-base-patch16-naflex) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_channels (`int`, *optional*, defaults to 3):
+ Number of channels in the input images.
+ num_patches (`int`, *optional*, defaults to 256):
+ The number of patches in the image with the size of (`patch_size`, `patch_size`).
+ The image is resized to fill maximum of this number of patches, and to preserve
+ the aspect ratio. In case the resulted number of patches is lower, the image is
+ padded in "patch" dimension.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+
+ Example:
+
+ ```python
+ >>> from transformers import Siglip2VisionConfig, Siglip2VisionModel
+
+ >>> # Initializing a Siglip2VisionConfig with google/siglip2-base-patch16-naflex style configuration
+ >>> configuration = Siglip2VisionConfig()
+
+ >>> # Initializing a Siglip2VisionModel (with random weights) from the google/siglip2-base-patch16-naflex style configuration
+ >>> model = Siglip2VisionModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ def __init__(
+ self,
+ hidden_size=768,
+ intermediate_size=3072,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ num_channels=3,
+ num_patches=256,
+ patch_size=16,
+ hidden_act="gelu_pytorch_tanh",
+ layer_norm_eps=1e-6,
+ attention_dropout=0.0,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.num_patches = num_patches
+ del self.image_size
+
+
+class Siglip2Config(SiglipConfig):
+ pass
+
+
+class Siglip2VisionOutput(SiglipVisionModelOutput):
+ pass
+
+
+class Siglip2TextOutput(SiglipTextModelOutput):
+ pass
+
+
+class Siglip2Output(SiglipOutput):
+ pass
+
+
+class Siglip2VisionEmbeddings(nn.Module):
+ def __init__(self, config: Siglip2VisionConfig):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.patch_size = config.patch_size
+
+ self.patch_embedding = nn.Linear(
+ in_features=config.num_channels * self.patch_size * self.patch_size,
+ out_features=self.embed_dim,
+ )
+
+ self.num_patches = config.num_patches
+ self.position_embedding_size = int(self.num_patches**0.5)
+ self.position_embedding = nn.Embedding(self.num_patches, self.embed_dim)
+
+ @staticmethod
+ def resize_positional_embeddings(
+ positional_embeddings: torch.Tensor,
+ spatial_shapes: torch.LongTensor,
+ max_length: int,
+ ) -> torch.Tensor:
+ """
+ Resize positional embeddings to image-specific size and pad to a fixed size.
+
+ Args:
+ positional_embeddings (`torch.Tensor`):
+ Position embeddings of shape (height, width, embed_dim)
+ spatial_shapes (`torch.LongTensor`):
+ Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to
+ max_length (`int`):
+ Maximum length of the positional embeddings to pad resized positional embeddings to
+
+ Returns:
+ `torch.Tensor`: Embeddings of shape (batch_size, max_length, embed_dim)
+ """
+ batch_size = spatial_shapes.shape[0]
+ embed_dim = positional_embeddings.shape[-1]
+ source_dtype = positional_embeddings.dtype
+
+ resulted_positional_embeddings = torch.empty(
+ (batch_size, max_length, embed_dim),
+ device=positional_embeddings.device,
+ dtype=source_dtype,
+ )
+
+ # (height, width, embed_dim) -> (1, embed_dim, height, width) for interpolation
+ positional_embeddings = positional_embeddings.permute(2, 0, 1).unsqueeze(0)
+
+ # Upcast to float32 on CPU because antialias is not supported for bfloat16/float16 on CPU
+ if positional_embeddings.device.type == "cpu":
+ positional_embeddings = positional_embeddings.to(torch.float32)
+
+ for i in range(batch_size):
+ # (1, dim, height, width) -> (1, dim, target_height, target_width)
+ height, width = spatial_shapes[i]
+ resized_embeddings = F.interpolate(
+ positional_embeddings,
+ size=(height, width),
+ mode="bilinear",
+ align_corners=False,
+ antialias=True,
+ )
+
+ # (1, dim, target_height, target_width) -> (target_height * target_width, dim)
+ resized_embeddings = resized_embeddings.reshape(embed_dim, height * width).transpose(0, 1)
+
+ # Cast to original dtype
+ resized_embeddings = resized_embeddings.to(source_dtype)
+
+ resulted_positional_embeddings[i, : height * width] = resized_embeddings
+ resulted_positional_embeddings[i, height * width :] = resized_embeddings[0]
+
+ return resulted_positional_embeddings
+
+ def forward(self, pixel_values: torch.FloatTensor, spatial_shapes: torch.LongTensor) -> torch.Tensor:
+ """
+ Args:
+ pixel_values (`torch.FloatTensor`):
+ Pixel values of shape (batch_size, max_num_patches, num_channels * patch_size * patch_size)
+ spatial_shapes (`list[tuple[int, int]]`):
+ Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to
+ """
+
+ # Apply patch embeddings to already patchified pixel values
+ target_dtype = self.patch_embedding.weight.dtype
+ patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype))
+
+ # Get positional resized and padded positional embeddings
+ positional_embeddings = self.position_embedding.weight.reshape(
+ self.position_embedding_size, self.position_embedding_size, -1
+ )
+ resized_positional_embeddings = self.resize_positional_embeddings(
+ positional_embeddings, spatial_shapes, max_length=pixel_values.shape[1]
+ )
+
+ # Add positional embeddings to patch embeddings
+ embeddings = patch_embeds + resized_positional_embeddings
+ return embeddings
+
+
+class Siglip2VisionTransformer(SiglipVisionTransformer):
+ def __init__(self, config: Siglip2VisionConfig):
+ super().__init__(config)
+ self._use_flash_attention_2 = config._attn_implementation == "flash_attention_2"
+
+ # Update: add `spatial_shapes` and `attention_mask`
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ attention_mask: torch.Tensor,
+ spatial_shapes: torch.LongTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ hidden_states = self.embeddings(pixel_values, spatial_shapes)
+
+ if attention_mask is not None and not self._use_flash_attention_2:
+ # [batch_size, seq_len] -> [batch_size, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_states.dtype)
+ else:
+ encoder_attention_mask = attention_mask
+
+ encoder_outputs: BaseModelOutput = self.encoder(
+ inputs_embeds=hidden_states,
+ attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ last_hidden_state = encoder_outputs.last_hidden_state
+ last_hidden_state = self.post_layernorm(last_hidden_state)
+
+ pooler_output = self.head(last_hidden_state, attention_mask) if self.use_head else None
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooler_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class Siglip2PreTrainedModel(SiglipPreTrainedModel):
+ pass
+
+
+class Siglip2TextModel(SiglipTextModel):
+ pass
+
+
+class Siglip2MultiheadAttentionPoolingHead(SiglipMultiheadAttentionPoolingHead):
+ def __init__(self, config: Siglip2VisionConfig):
+ super().__init__(config)
+ self.num_heads = config.num_attention_heads
+
+ def forward(self, hidden_state: torch.Tensor, attention_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ batch_size = hidden_state.shape[0]
+ probe = self.probe.repeat(batch_size, 1, 1)
+
+ if attention_mask is not None:
+ target_len, source_len = probe.shape[1], hidden_state.shape[1]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_state.dtype, target_len)
+ attention_mask = attention_mask.repeat(1, self.num_heads, target_len, 1)
+ attention_mask = attention_mask.reshape(-1, target_len, source_len)
+
+ hidden_state = self.attention(probe, hidden_state, hidden_state, attn_mask=attention_mask)[0]
+
+ residual = hidden_state
+ hidden_state = self.layernorm(hidden_state)
+ hidden_state = residual + self.mlp(hidden_state)
+
+ return hidden_state[:, 0]
+
+
+class Siglip2VisionModel(SiglipVisionModel):
+ # Update: add `spatial_shapes` and `pixel_attention_mask`
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ pixel_attention_mask: torch.Tensor,
+ spatial_shapes: torch.LongTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, Siglip2VisionModel
+
+ >>> model = Siglip2VisionModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> last_hidden_state = outputs.last_hidden_state
+ >>> pooled_output = outputs.pooler_output # pooled features
+ ```"""
+ return self.vision_model(
+ pixel_values=pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+
+class Siglip2Model(SiglipModel):
+ # Update: add `spatial_shapes` and `pixel_attention_mask`
+ def get_image_features(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_attention_mask: Optional[torch.Tensor] = None,
+ spatial_shapes: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> torch.FloatTensor:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+
+ Returns:
+ image_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The image embeddings obtained by
+ applying the projection layer to the pooled output of [`Siglip2VisionModel`].
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... image_features = model.get_image_features(**inputs)
+ ```
+ """
+ # Use Siglip2Model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ vision_outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values=pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ pooled_output = vision_outputs.pooler_output
+
+ return pooled_output
+
+ # Update: add `spatial_shapes` and `pixel_attention_mask`
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_attention_mask: Optional[torch.Tensor] = None,
+ spatial_shapes: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ return_loss: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> Siglip2Output:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+ return_loss (`bool`, *optional*):
+ Whether or not to return the contrastive loss.
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> import torch
+
+ >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224")
+ >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> texts = ["a photo of 2 cats", "a photo of 2 dogs"]
+ >>> # important: we pass `padding=max_length` since the model was trained with this
+ >>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+
+ >>> logits_per_image = outputs.logits_per_image
+ >>> probs = torch.sigmoid(logits_per_image) # these are the probabilities
+ >>> print(f"{probs[0][0]:.1%} that image 0 is '{texts[0]}'")
+ 31.9% that image 0 is 'a photo of 2 cats'
+ ```
+ """
+ # Use Siglip2 model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ vision_outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values=pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ text_outputs: BaseModelOutputWithPooling = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ image_embeds = vision_outputs.pooler_output
+ text_embeds = text_outputs.pooler_output
+
+ # normalized features
+ image_embeds = image_embeds / image_embeds.norm(p=2, dim=-1, keepdim=True)
+ text_embeds = text_embeds / text_embeds.norm(p=2, dim=-1, keepdim=True)
+
+ # cosine similarity as logits
+ logits_per_text = torch.matmul(text_embeds, image_embeds.t().to(text_embeds.device))
+
+ logit_scale, logit_bias = self.logit_scale.to(text_embeds.device), self.logit_bias.to(text_embeds.device)
+ logits_per_text = logits_per_text * logit_scale.exp() + logit_bias
+
+ logits_per_image = logits_per_text.t()
+
+ loss = None
+ if return_loss:
+ # Adapted from https://github.com/google-research/big_vision/blob/01edb81a4716f93a48be43b3a4af14e29cdb3a7f/big_vision/trainers/proj/image_text/siglip2.py#L287
+ eye = torch.eye(logits_per_text.size(0), device=logits_per_text.device)
+ m1_diag1 = -torch.ones_like(logits_per_text) + 2 * eye
+ loglik = torch.nn.functional.logsigmoid(m1_diag1 * logits_per_text)
+ nll = -torch.sum(loglik, dim=-1)
+ loss = nll.mean()
+
+ return Siglip2Output(
+ loss=loss,
+ logits_per_image=logits_per_image,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ image_embeds=image_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ )
+
+
+class Siglip2ForImageClassification(SiglipForImageClassification):
+ # Update: add `spatial_shapes` and `pixel_attention_mask`
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ pixel_attention_mask: Optional[torch.Tensor] = None,
+ spatial_shapes: Optional[torch.LongTensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> ImageClassifierOutput:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
+ Tensor containing the spatial dimensions (height, width) of the input images.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, Siglip2ForImageClassification
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> # note: we are loading a `Siglip2Model` from the hub here,
+ >>> # so the head will be randomly initialized, hence the predictions will be random if seed is not set above.
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/siglip2-base-patch16-224")
+ >>> model = Siglip2ForImageClassification.from_pretrained("google/siglip2-base-patch16-224")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> logits = outputs.logits
+ >>> # model predicts one of the two classes
+ >>> predicted_class_idx = logits.argmax(-1).item()
+ >>> print("Predicted class:", model.config.id2label[predicted_class_idx])
+ Predicted class: LABEL_1
+ ```
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ outputs: BaseModelOutputWithPooling = self.vision_model(
+ pixel_values,
+ attention_mask=pixel_attention_mask,
+ spatial_shapes=spatial_shapes,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ sequence_output = outputs.last_hidden_state
+
+ # average pool the patch tokens
+ if pixel_attention_mask is not None:
+ pool_mask = pixel_attention_mask[..., None].to(sequence_output.device)
+ sequence_output = torch.sum(sequence_output * pool_mask, dim=1) / torch.sum(pool_mask, dim=1)
+ else:
+ sequence_output = torch.mean(sequence_output, dim=1)
+
+ # apply classifier
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "Siglip2Config",
+ "Siglip2TextConfig",
+ "Siglip2VisionConfig",
+ "Siglip2Model",
+ "Siglip2PreTrainedModel",
+ "Siglip2TextModel",
+ "Siglip2VisionModel",
+ "Siglip2ForImageClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/processing_siglip2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/processing_siglip2.py
new file mode 100644
index 0000000000000000000000000000000000000000..2b638027474a8e5492a76f04873197315ca19aaa
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/siglip2/processing_siglip2.py
@@ -0,0 +1,151 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Image/Text processor class for SigLIP2.
+"""
+
+from typing import Optional, Union
+
+from ...feature_extraction_utils import BatchFeature
+from ...image_utils import ImageInput
+from ...processing_utils import ImagesKwargs, ProcessingKwargs, ProcessorMixin, Unpack
+from ...tokenization_utils_base import PreTokenizedInput, TextInput
+
+
+class Siglip2ImagesKwargs(ImagesKwargs, total=False):
+ max_num_patches: Optional[int]
+ patch_size: Optional[int]
+
+
+class Siglip2ProcessorKwargs(ProcessingKwargs, total=False):
+ images_kwargs: Siglip2ImagesKwargs
+
+ _defaults = {
+ "text_kwargs": {
+ "padding": "max_length",
+ "truncation": True,
+ "max_length": 64,
+ },
+ "images_kwargs": {
+ "max_num_patches": 256,
+ "patch_size": 16,
+ },
+ }
+
+
+class Siglip2Processor(ProcessorMixin):
+ r"""
+ Constructs a Siglip2 processor which wraps a Siglip2 image processor and a Gemma tokenizer into a single processor.
+
+ [`Siglip2Processor`] offers all the functionalities of [`Siglip2ImageProcessor`] and [`GemmaTokenizerFast`]. See the
+ [`~Siglip2Processor.__call__`] and [`~Siglip2Processor.decode`] for more information.
+
+ Args:
+ image_processor ([`Siglip2ImageProcessor`]):
+ The image processor is a required input.
+ tokenizer ([`GemmaTokenizerFast`]):
+ The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+
+ image_processor_class = "AutoImageProcessor"
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(self, image_processor, tokenizer):
+ super().__init__(image_processor, tokenizer)
+
+ def __call__(
+ self,
+ images: Optional[Union[ImageInput, list[ImageInput], list[list[ImageInput]]]] = None,
+ text: Optional[Union[TextInput, "PreTokenizedInput", list[TextInput], list["PreTokenizedInput"]]] = None,
+ audio=None,
+ videos=None,
+ **kwargs: Unpack[Siglip2ProcessorKwargs],
+ ) -> BatchFeature:
+ """
+ Main method to prepare for the model one or several sequences(s) and image(s). This method forwards the `text`
+ and `kwargs` arguments to GemmaTokenizerFast's [`~GemmaTokenizerFast.__call__`] if `text` is not `None` to encode
+ the text. To prepare the image(s), this method forwards the `images` argument to
+ Siglip2ImageProcessor's [`~Siglip2ImageProcessor.__call__`] if `images` is not `None`. Please refer to the docstring
+ of the above two methods for more information.
+
+ Args:
+ images (`PIL.Image.Image`, `np.ndarray`, `torch.Tensor`, `list[PIL.Image.Image]`, `list[np.ndarray]`, `list[torch.Tensor]`):
+ The image or batch of images to be prepared. Each image can be a PIL image, NumPy array or PyTorch
+ tensor. Both channels-first and channels-last formats are supported.
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `max_length`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding
+ index) among:
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*, defaults to 64):
+ Maximum length of the returned list and optionally padding length (see above).
+ truncation (`bool`, *optional*, defaults to `True`):
+ Activates truncation to cut input sequences longer than `max_length` to `max_length`.
+ return_tensors (`str` or [`~utils.TensorType`], *optional*, defaults to `'pt'`):
+ If set, will return tensors of a particular framework. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+
+ Returns:
+ [`BatchFeature`]: A [`BatchFeature`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`.
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not
+ `None`).
+ - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is not `None`.
+ - **pixel_attention_mask** -- Attention mask for the pixel values. Returned when `images` is not `None`.
+ - **spatial_shapes** -- The number of horizontal and vertical patches per image.
+ Returned when `images` is not `None`.
+ """
+ output_kwargs = self._merge_kwargs(
+ Siglip2ProcessorKwargs,
+ tokenizer_init_kwargs=self.tokenizer.init_kwargs,
+ **kwargs,
+ )
+
+ if text is None and images is None:
+ raise ValueError("You have to specify either text or images. Both cannot be none.")
+
+ if text is not None:
+ encoding = self.tokenizer(text, **output_kwargs["text_kwargs"])
+
+ if images is not None:
+ image_features = self.image_processor(images, **output_kwargs["images_kwargs"])
+
+ if text is not None and images is not None:
+ encoding.update(image_features)
+ return encoding
+ elif text is not None:
+ return encoding
+ else:
+ return_tensors = output_kwargs["common_kwargs"]["return_tensors"]
+ return BatchFeature(data=dict(**image_features), tensor_type=return_tensors)
+
+
+__all__ = ["Siglip2Processor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..188d99ef78669b038c92223edb6b0caa4d2bb6be
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_smollm3 import *
+ from .modeling_smollm3 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/configuration_smollm3.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/configuration_smollm3.py
new file mode 100644
index 0000000000000000000000000000000000000000..fd1861a589f953b38982053235f79ceba7b9cc30
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/configuration_smollm3.py
@@ -0,0 +1,247 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/smollm3/modular_smollm3.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_smollm3.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from ...configuration_utils import PretrainedConfig, layer_type_validation
+from ...modeling_rope_utils import rope_config_validation
+
+
+class SmolLM3Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SmolLM3Model`]. It is used to instantiate a
+ SmolLM3 model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the SmolLM3 3B.
+ e.g. [HuggingFaceTB/SmolLM3-3B](https://huggingface.co/HuggingFaceTB/SmolLM3-3B)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 128256):
+ Vocabulary size of the SmolLM3 model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`SmolLM3Model`]
+ hidden_size (`int`, *optional*, defaults to 2048):
+ Dimension of the hidden representations.
+ intermediate_size (`int`, *optional*, defaults to 11008):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 36):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_key_value_heads (`int`, *optional*, defaults to 4):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details checkout [this
+ paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `16`.
+ hidden_act (`str` or `function`, *optional*, defaults to `"silu"`):
+ The non-linear activation function (function or string) in the decoder.
+ max_position_embeddings (`int`, *optional*, defaults to 32768):
+ The maximum sequence length that this model might ever be used with.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the rms normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ pad_token_id (`int`, *optional*, defaults to 128004):
+ The id of the padding token.
+ bos_token_id (`int`, *optional*, defaults to 128000):
+ The id of the beginning of sentence token.
+ eos_token_id (`int`, *optional*, defaults to 128001):
+ The id of the end of sentence token.
+ rope_theta (`float`, *optional*, defaults to 2000000.0):
+ The base period of the RoPE embeddings.
+ rope_scaling (`Dict`, *optional*):
+ Dictionary containing the scaling configuration for the RoPE embeddings. NOTE: if you apply new rope type
+ and you expect the model to work on longer `max_position_embeddings`, we recommend you to update this value
+ accordingly.
+ Expected contents:
+ `rope_type` (`str`):
+ The sub-variant of RoPE to use. Can be one of ['default', 'linear', 'dynamic', 'yarn', 'longrope',
+ 'llama3'], with 'default' being the original RoPE implementation.
+ `factor` (`float`, *optional*):
+ Used with all rope types except 'default'. The scaling factor to apply to the RoPE embeddings. In
+ most scaling types, a `factor` of x will enable the model to handle sequences of length x *
+ original maximum pre-trained length.
+ `original_max_position_embeddings` (`int`, *optional*):
+ Used with 'dynamic', 'longrope' and 'llama3'. The original max position embeddings used during
+ pretraining.
+ `attention_factor` (`float`, *optional*):
+ Used with 'yarn' and 'longrope'. The scaling factor to be applied on the attention
+ computation. If unspecified, it defaults to value recommended by the implementation, using the
+ `factor` field to infer the suggested value.
+ `beta_fast` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for extrapolation (only) in the linear
+ ramp function. If unspecified, it defaults to 32.
+ `beta_slow` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for interpolation (only) in the linear
+ ramp function. If unspecified, it defaults to 1.
+ `short_factor` (`List[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to short contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `long_factor` (`List[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to long contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `low_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to low frequency components of the RoPE
+ `high_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to high frequency components of the RoPE
+ use_sliding_window (`bool`, *optional*, defaults to `False`):
+ Whether to use sliding window attention.
+ sliding_window (`int`, *optional*):
+ Sliding window attention (SWA) window size. If not specified, will default to `None`.
+ no_rope_layers (`List[int]`, *optional*):
+ List with at least the same length as the number of layers in the model.
+ A `1` at an index position indicates that the corresponding layer will use RoPE,
+ while a `0` indicates that it's a NoPE layer.
+ no_rope_layer_interval (`int`, *optional*, defaults to 4):
+ If `no_rope_layers` is `None`, it will be created using a NoPE layer every
+ `no_rope_layer_interval` layers.
+ layer_types (`list`, *optional*):
+ Attention pattern for each layer. Automatically computed based on sliding window and NoPE settings.
+ attention_bias (`bool`, *optional*, defaults to `False`):
+ Whether to use a bias in the query, key, value and output projection layers during self-attention.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+
+ ```python
+ >>> from transformers import SmolLM3Model, SmolLM3Config
+
+ >>> # Initializing a SmolLM3 style configuration
+ >>> configuration = SmolLM3Config()
+
+ >>> # Initializing a model from the SmolLM3 style configuration
+ >>> model = SmolLM3Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "smollm3"
+ keys_to_ignore_at_inference = ["past_key_values"]
+
+ base_model_tp_plan = {
+ "layers.*.self_attn.q_proj": "colwise",
+ "layers.*.self_attn.k_proj": "colwise",
+ "layers.*.self_attn.v_proj": "colwise",
+ "layers.*.self_attn.o_proj": "rowwise",
+ "layers.*.mlp.gate_proj": "colwise",
+ "layers.*.mlp.up_proj": "colwise",
+ "layers.*.mlp.down_proj": "rowwise",
+ }
+ base_model_pp_plan = {
+ "embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "norm": (["hidden_states"], ["hidden_states"]),
+ }
+
+ def __init__(
+ self,
+ vocab_size=128256,
+ hidden_size=2048,
+ intermediate_size=11008,
+ num_hidden_layers=36,
+ num_attention_heads=16,
+ num_key_value_heads=4,
+ hidden_act="silu",
+ max_position_embeddings=32768,
+ initializer_range=0.02,
+ rms_norm_eps=1e-6,
+ use_cache=True,
+ pad_token_id=128004,
+ bos_token_id=128000,
+ eos_token_id=128001,
+ rope_theta=2000000.0,
+ rope_scaling=None,
+ use_sliding_window=False,
+ sliding_window=None,
+ no_rope_layers=None,
+ no_rope_layer_interval=4,
+ layer_types=None,
+ attention_bias=False,
+ attention_dropout=0.0,
+ mlp_bias=False,
+ **kwargs,
+ ):
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ **kwargs,
+ )
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.mlp_bias = mlp_bias
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.use_sliding_window = use_sliding_window
+ self.sliding_window = sliding_window
+
+ # for backward compatibility
+ if num_key_value_heads is None:
+ num_key_value_heads = num_attention_heads
+
+ self.num_key_value_heads = num_key_value_heads
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.rope_scaling = rope_scaling
+ self.attention_bias = attention_bias
+ self.attention_dropout = attention_dropout
+
+ if no_rope_layers is None:
+ self.no_rope_layers = [
+ int((layer_idx + 1) % no_rope_layer_interval != 0) for layer_idx in range(num_hidden_layers)
+ ]
+ else:
+ self.no_rope_layers = no_rope_layers
+
+ self.no_rope_layer_interval = no_rope_layer_interval
+
+ # Update layer_types based on sliding window and NoPE pattern
+ if layer_types is None:
+ layer_types = []
+ for layer_idx in range(num_hidden_layers):
+ has_rope = self.no_rope_layers[layer_idx]
+ if use_sliding_window and sliding_window is not None and not has_rope:
+ layer_types.append("sliding_attention")
+ else:
+ layer_types.append("full_attention")
+
+ self.layer_types = layer_types
+ layer_type_validation(self.layer_types)
+
+ # Validate the correctness of rotary position embeddings parameters
+ # BC: if there is a 'type' field, move it to 'rope_type'.
+ if self.rope_scaling is not None and "type" in self.rope_scaling:
+ self.rope_scaling["rope_type"] = self.rope_scaling["type"]
+ rope_config_validation(self)
+
+
+__all__ = ["SmolLM3Config"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/modeling_smollm3.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/modeling_smollm3.py
new file mode 100644
index 0000000000000000000000000000000000000000..1e08e288193b7d39ad30a61e4ed994c415840769
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/modeling_smollm3.py
@@ -0,0 +1,527 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/smollm3/modular_smollm3.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_smollm3.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Callable, Optional, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache
+from ...generation import GenerationMixin
+from ...integrations import use_kernel_forward_from_hub
+from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import (
+ GenericForQuestionAnswering,
+ GenericForSequenceClassification,
+ GenericForTokenClassification,
+ GradientCheckpointingLayer,
+)
+from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, auto_docstring, can_return_tuple
+from ...utils.deprecation import deprecate_kwarg
+from ...utils.generic import check_model_inputs
+from .configuration_smollm3 import SmolLM3Config
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs: Unpack[TransformersKwargs],
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class SmolLM3Attention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: SmolLM3Config, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = self.head_dim**-0.5
+ self.attention_dropout = config.attention_dropout
+ self.is_causal = True
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.k_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+
+ self.use_rope = config.no_rope_layers[layer_idx]
+ self.sliding_window = (
+ config.sliding_window
+ if config.use_sliding_window and config.layer_types[layer_idx] == "sliding_attention"
+ else None
+ )
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ if self.use_rope:
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ cache_kwargs = {"cache_position": cache_position}
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ sliding_window=self.sliding_window,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+@use_kernel_forward_from_hub("RMSNorm")
+class SmolLM3RMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ SmolLM3RMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+class SmolLM3MLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.mlp_bias)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ def forward(self, x):
+ down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x))
+ return down_proj
+
+
+class SmolLM3DecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: SmolLM3Config, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+
+ self.self_attn = SmolLM3Attention(config=config, layer_idx=layer_idx)
+
+ self.mlp = SmolLM3MLP(config)
+ self.input_layernorm = SmolLM3RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_attention_layernorm = SmolLM3RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.attention_type = config.layer_types[layer_idx]
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> torch.Tensor:
+ residual = hidden_states
+ hidden_states = self.input_layernorm(hidden_states)
+ # Self Attention
+ hidden_states, _ = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.post_attention_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+ return hidden_states
+
+
+@auto_docstring
+class SmolLM3PreTrainedModel(PreTrainedModel):
+ config: SmolLM3Config
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["SmolLM3DecoderLayer"]
+ _skip_keys_device_placement = ["past_key_values"]
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ _can_compile_fullgraph = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": SmolLM3DecoderLayer,
+ "attentions": SmolLM3Attention,
+ }
+
+
+class SmolLM3RotaryEmbedding(nn.Module):
+ inv_freq: torch.Tensor # fix linting for `register_buffer`
+
+ def __init__(self, config: SmolLM3Config, device=None):
+ super().__init__()
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and isinstance(config.rope_scaling, dict):
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ @torch.no_grad()
+ @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope)
+ def forward(self, x, position_ids):
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device)
+ position_ids_expanded = position_ids[:, None, :].float()
+
+ device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False): # Force float32
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos() * self.attention_scaling
+ sin = emb.sin() * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+@auto_docstring
+class SmolLM3Model(SmolLM3PreTrainedModel):
+ def __init__(self, config: SmolLM3Config):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.layers = nn.ModuleList(
+ [SmolLM3DecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = SmolLM3RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.rotary_emb = SmolLM3RotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+ self.has_sliding_layers = "sliding_attention" in self.config.layer_types
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPast:
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache(config=self.config)
+
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ # It may already have been prepared by e.g. `generate`
+ if not isinstance(causal_mask_mapping := attention_mask, dict):
+ # Prepare mask arguments
+ mask_kwargs = {
+ "config": self.config,
+ "input_embeds": inputs_embeds,
+ "attention_mask": attention_mask,
+ "cache_position": cache_position,
+ "past_key_values": past_key_values,
+ "position_ids": position_ids,
+ }
+ # Create the masks
+ causal_mask_mapping = {
+ "full_attention": create_causal_mask(**mask_kwargs),
+ }
+ # The sliding window alternating layers are not always activated depending on the config
+ if self.has_sliding_layers:
+ causal_mask_mapping["sliding_attention"] = create_sliding_window_causal_mask(**mask_kwargs)
+
+ hidden_states = inputs_embeds
+
+ # create position embeddings to be shared across the decoder layers
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ for decoder_layer in self.layers[: self.config.num_hidden_layers]:
+ hidden_states = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask_mapping[decoder_layer.attention_type],
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+
+ hidden_states = self.norm(hidden_states)
+ return BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ )
+
+
+@auto_docstring
+class SmolLM3ForCausalLM(SmolLM3PreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.weight"]
+ _tp_plan = {"lm_head": "colwise_rep"}
+ _pp_plan = {"lm_head": (["hidden_states"], ["logits"])}
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = SmolLM3Model(config)
+ self.vocab_size = config.vocab_size
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> CausalLMOutputWithPast:
+ r"""
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, SmolLM3ForCausalLM
+
+ >>> model = SmolLM3ForCausalLM.from_pretrained("meta-smollm3/SmolLM3-2-7b-hf")
+ >>> tokenizer = AutoTokenizer.from_pretrained("meta-smollm3/SmolLM3-2-7b-hf")
+
+ >>> prompt = "Hey, are you conscious? Can you talk to me?"
+ >>> inputs = tokenizer(prompt, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(inputs.input_ids, max_length=30)
+ >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+ "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you."
+ ```"""
+ outputs: BaseModelOutputWithPast = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ hidden_states = outputs.last_hidden_state
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs)
+
+ return CausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class SmolLM3ForSequenceClassification(GenericForSequenceClassification, SmolLM3PreTrainedModel):
+ pass
+
+
+class SmolLM3ForTokenClassification(GenericForTokenClassification, SmolLM3PreTrainedModel):
+ pass
+
+
+class SmolLM3ForQuestionAnswering(GenericForQuestionAnswering, SmolLM3PreTrainedModel):
+ base_model_prefix = "transformer" # For BC, where `transformer` was used instead of `model`
+
+
+__all__ = [
+ "SmolLM3PreTrainedModel",
+ "SmolLM3Model",
+ "SmolLM3ForCausalLM",
+ "SmolLM3ForSequenceClassification",
+ "SmolLM3ForTokenClassification",
+ "SmolLM3ForQuestionAnswering",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/modular_smollm3.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/modular_smollm3.py
new file mode 100644
index 0000000000000000000000000000000000000000..66d58f07a372df2f720f9940aba9902c23e74e66
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smollm3/modular_smollm3.py
@@ -0,0 +1,361 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Callable, Optional
+
+import torch
+
+from ...cache_utils import Cache
+from ...configuration_utils import PretrainedConfig, layer_type_validation
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_rope_utils import rope_config_validation
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS
+from ...processing_utils import Unpack
+from ...utils import logging
+from ...utils.deprecation import deprecate_kwarg
+from ..llama.modeling_llama import (
+ LlamaAttention,
+ LlamaDecoderLayer,
+ LlamaForCausalLM,
+ LlamaForQuestionAnswering,
+ LlamaForSequenceClassification,
+ LlamaForTokenClassification,
+ LlamaPreTrainedModel,
+ apply_rotary_pos_emb,
+ eager_attention_forward,
+)
+from ..qwen2.modeling_qwen2 import Qwen2Model
+
+
+logger = logging.get_logger(__name__)
+
+
+class SmolLM3Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SmolLM3Model`]. It is used to instantiate a
+ SmolLM3 model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the SmolLM3 3B.
+ e.g. [HuggingFaceTB/SmolLM3-3B](https://huggingface.co/HuggingFaceTB/SmolLM3-3B)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 128256):
+ Vocabulary size of the SmolLM3 model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`SmolLM3Model`]
+ hidden_size (`int`, *optional*, defaults to 2048):
+ Dimension of the hidden representations.
+ intermediate_size (`int`, *optional*, defaults to 11008):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 36):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_key_value_heads (`int`, *optional*, defaults to 4):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details checkout [this
+ paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `16`.
+ hidden_act (`str` or `function`, *optional*, defaults to `"silu"`):
+ The non-linear activation function (function or string) in the decoder.
+ max_position_embeddings (`int`, *optional*, defaults to 32768):
+ The maximum sequence length that this model might ever be used with.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the rms normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ pad_token_id (`int`, *optional*, defaults to 128004):
+ The id of the padding token.
+ bos_token_id (`int`, *optional*, defaults to 128000):
+ The id of the beginning of sentence token.
+ eos_token_id (`int`, *optional*, defaults to 128001):
+ The id of the end of sentence token.
+ rope_theta (`float`, *optional*, defaults to 2000000.0):
+ The base period of the RoPE embeddings.
+ rope_scaling (`Dict`, *optional*):
+ Dictionary containing the scaling configuration for the RoPE embeddings. NOTE: if you apply new rope type
+ and you expect the model to work on longer `max_position_embeddings`, we recommend you to update this value
+ accordingly.
+ Expected contents:
+ `rope_type` (`str`):
+ The sub-variant of RoPE to use. Can be one of ['default', 'linear', 'dynamic', 'yarn', 'longrope',
+ 'llama3'], with 'default' being the original RoPE implementation.
+ `factor` (`float`, *optional*):
+ Used with all rope types except 'default'. The scaling factor to apply to the RoPE embeddings. In
+ most scaling types, a `factor` of x will enable the model to handle sequences of length x *
+ original maximum pre-trained length.
+ `original_max_position_embeddings` (`int`, *optional*):
+ Used with 'dynamic', 'longrope' and 'llama3'. The original max position embeddings used during
+ pretraining.
+ `attention_factor` (`float`, *optional*):
+ Used with 'yarn' and 'longrope'. The scaling factor to be applied on the attention
+ computation. If unspecified, it defaults to value recommended by the implementation, using the
+ `factor` field to infer the suggested value.
+ `beta_fast` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for extrapolation (only) in the linear
+ ramp function. If unspecified, it defaults to 32.
+ `beta_slow` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for interpolation (only) in the linear
+ ramp function. If unspecified, it defaults to 1.
+ `short_factor` (`List[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to short contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `long_factor` (`List[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to long contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `low_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to low frequency components of the RoPE
+ `high_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to high frequency components of the RoPE
+ use_sliding_window (`bool`, *optional*, defaults to `False`):
+ Whether to use sliding window attention.
+ sliding_window (`int`, *optional*):
+ Sliding window attention (SWA) window size. If not specified, will default to `None`.
+ no_rope_layers (`List[int]`, *optional*):
+ List with at least the same length as the number of layers in the model.
+ A `1` at an index position indicates that the corresponding layer will use RoPE,
+ while a `0` indicates that it's a NoPE layer.
+ no_rope_layer_interval (`int`, *optional*, defaults to 4):
+ If `no_rope_layers` is `None`, it will be created using a NoPE layer every
+ `no_rope_layer_interval` layers.
+ layer_types (`list`, *optional*):
+ Attention pattern for each layer. Automatically computed based on sliding window and NoPE settings.
+ attention_bias (`bool`, *optional*, defaults to `False`):
+ Whether to use a bias in the query, key, value and output projection layers during self-attention.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+
+ ```python
+ >>> from transformers import SmolLM3Model, SmolLM3Config
+
+ >>> # Initializing a SmolLM3 style configuration
+ >>> configuration = SmolLM3Config()
+
+ >>> # Initializing a model from the SmolLM3 style configuration
+ >>> model = SmolLM3Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "smollm3"
+ keys_to_ignore_at_inference = ["past_key_values"]
+
+ base_model_tp_plan = {
+ "layers.*.self_attn.q_proj": "colwise",
+ "layers.*.self_attn.k_proj": "colwise",
+ "layers.*.self_attn.v_proj": "colwise",
+ "layers.*.self_attn.o_proj": "rowwise",
+ "layers.*.mlp.gate_proj": "colwise",
+ "layers.*.mlp.up_proj": "colwise",
+ "layers.*.mlp.down_proj": "rowwise",
+ }
+ base_model_pp_plan = {
+ "embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "norm": (["hidden_states"], ["hidden_states"]),
+ }
+
+ def __init__(
+ self,
+ vocab_size=128256,
+ hidden_size=2048,
+ intermediate_size=11008,
+ num_hidden_layers=36,
+ num_attention_heads=16,
+ num_key_value_heads=4,
+ hidden_act="silu",
+ max_position_embeddings=32768,
+ initializer_range=0.02,
+ rms_norm_eps=1e-6,
+ use_cache=True,
+ pad_token_id=128004,
+ bos_token_id=128000,
+ eos_token_id=128001,
+ rope_theta=2000000.0,
+ rope_scaling=None,
+ use_sliding_window=False,
+ sliding_window=None,
+ no_rope_layers=None,
+ no_rope_layer_interval=4,
+ layer_types=None,
+ attention_bias=False,
+ attention_dropout=0.0,
+ mlp_bias=False,
+ **kwargs,
+ ):
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ **kwargs,
+ )
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.mlp_bias = mlp_bias
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.use_sliding_window = use_sliding_window
+ self.sliding_window = sliding_window
+
+ # for backward compatibility
+ if num_key_value_heads is None:
+ num_key_value_heads = num_attention_heads
+
+ self.num_key_value_heads = num_key_value_heads
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.rope_scaling = rope_scaling
+ self.attention_bias = attention_bias
+ self.attention_dropout = attention_dropout
+
+ if no_rope_layers is None:
+ self.no_rope_layers = [
+ int((layer_idx + 1) % no_rope_layer_interval != 0) for layer_idx in range(num_hidden_layers)
+ ]
+ else:
+ self.no_rope_layers = no_rope_layers
+
+ self.no_rope_layer_interval = no_rope_layer_interval
+
+ # Update layer_types based on sliding window and NoPE pattern
+ if layer_types is None:
+ layer_types = []
+ for layer_idx in range(num_hidden_layers):
+ has_rope = self.no_rope_layers[layer_idx]
+ if use_sliding_window and sliding_window is not None and not has_rope:
+ layer_types.append("sliding_attention")
+ else:
+ layer_types.append("full_attention")
+
+ self.layer_types = layer_types
+ layer_type_validation(self.layer_types)
+
+ # Validate the correctness of rotary position embeddings parameters
+ # BC: if there is a 'type' field, move it to 'rope_type'.
+ if self.rope_scaling is not None and "type" in self.rope_scaling:
+ self.rope_scaling["rope_type"] = self.rope_scaling["type"]
+ rope_config_validation(self)
+
+
+class SmolLM3Attention(LlamaAttention):
+ def __init__(self, config: SmolLM3Config, layer_idx: int):
+ super().__init__(config, layer_idx)
+
+ self.use_rope = config.no_rope_layers[layer_idx]
+ self.sliding_window = (
+ config.sliding_window
+ if config.use_sliding_window and config.layer_types[layer_idx] == "sliding_attention"
+ else None
+ )
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ if self.use_rope:
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ cache_kwargs = {"cache_position": cache_position}
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ sliding_window=self.sliding_window,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class SmolLM3DecoderLayer(LlamaDecoderLayer):
+ def __init__(self, config: SmolLM3Config, layer_idx: int):
+ super().__init__(config, layer_idx)
+ self.attention_type = config.layer_types[layer_idx]
+
+
+class SmolLM3PreTrainedModel(LlamaPreTrainedModel):
+ pass
+
+
+class SmolLM3Model(Qwen2Model):
+ pass
+
+
+class SmolLM3ForCausalLM(LlamaForCausalLM):
+ pass
+
+
+class SmolLM3ForSequenceClassification(LlamaForSequenceClassification):
+ pass
+
+
+class SmolLM3ForTokenClassification(LlamaForTokenClassification):
+ pass
+
+
+class SmolLM3ForQuestionAnswering(LlamaForQuestionAnswering):
+ pass
+
+
+__all__ = [
+ "SmolLM3Config",
+ "SmolLM3PreTrainedModel",
+ "SmolLM3Model",
+ "SmolLM3ForCausalLM",
+ "SmolLM3ForSequenceClassification",
+ "SmolLM3ForTokenClassification",
+ "SmolLM3ForQuestionAnswering",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..5205a84b25c45f7f378d22808f1a307afb58c909
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_smolvlm import *
+ from .image_processing_smolvlm import *
+ from .image_processing_smolvlm_fast import *
+ from .modeling_smolvlm import *
+ from .processing_smolvlm import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/configuration_smolvlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/configuration_smolvlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..2dca4721c02b858f0883bd328bc98f9eb1a98094
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/configuration_smolvlm.py
@@ -0,0 +1,196 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_smolvlm.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 the HuggingFace Inc. team. All rights reserved.
+# Written by Orr Zohar
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ..auto import CONFIG_MAPPING, AutoConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class SmolVLMVisionConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SmolVLMVisionModel`]. It is used to instantiate a
+ SmolVLM vision encoder according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the SigLIP checkpoint
+ [google/siglip-so400m-patch14-384](https://huggingface.co/google/siglip-so400m-patch14-384) used in SmolVLM
+ [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct).
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 1152):
+ Dimensionality of the encoder layers and the pooler layer.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_channels (`int`, *optional*, defaults to 3):
+ Number of channels in the input images.
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 32):
+ The size (resolution) of each patch.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+
+ Example:
+
+ ```python
+ >>> from transformers.models.smolvlm.modeling_smolvlm import SmolVLMVisionTransformer
+ >>> from transformers.models.smolvlm.configuration_smolvlm import SmolVLMVisionConfig
+
+ >>> # Initializing a SmolVLMVisionConfig with google/siglip-so400m-patch14-384 style configuration
+ >>> configuration = SmolVLMVisionConfig()
+
+ >>> # Initializing a SmolVLMVisionTransformer (with random weights) from the google/siglip-so400m-patch14-384 style configuration
+ >>> model = SmolVLMVisionTransformer(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "smolvlm_vision"
+ base_config_key = "vision_config"
+
+ def __init__(
+ self,
+ hidden_size=1152,
+ intermediate_size=3072,
+ num_hidden_layers=12,
+ num_attention_heads=16,
+ num_channels=3,
+ image_size=224,
+ patch_size=32,
+ hidden_act="gelu_pytorch_tanh",
+ layer_norm_eps=1e-6,
+ attention_dropout=0.0,
+ initializer_range=0.02,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.num_channels = num_channels
+ self.patch_size = patch_size
+ self.image_size = image_size
+ self.attention_dropout = attention_dropout
+ self.layer_norm_eps = layer_norm_eps
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+
+
+class SmolVLMConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SmolVLMModel`]. It is used to instantiate a
+ SmolVLM model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the model of the SmolVLM
+ [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should cache the key/value pairs of the attention mechanism. Only
+ relevant if `config.is_decoder=True`.
+ image_token_id (`int`, *optional*, defaults to 128257):
+ The id of the "image" token.
+ tie_word_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether or not to tie the word embeddings with the token embeddings.
+ vision_config (`IdeficsVisionConfig` or `dict`, *optional*, defaults to `IdeficsVisionConfig`):
+ Custom vision config or dict for the vision tower
+ text_config (`PretrainedConfig` or `dict`, *optional*, defaults to `LlamaConfig`):
+ Custom text config or dict for the text model
+ scale_factor (`int`, *optional*, defaults to 2):
+ The scale factor for the image encoder.
+ pad_token_id (`int`, *optional*, defaults to 128002):
+ The id of the padding token.
+
+ Example:
+ ```python
+ >>> from transformers import SmolVLMModel, SmolVLMConfig
+ >>> # Initializing configuration
+ >>> configuration = SmolVLMConfig()
+ >>> # Initializing a model from the configuration
+ >>> model = SmolVLMModel(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "smolvlm"
+ sub_configs = {"text_config": AutoConfig, "vision_config": SmolVLMVisionConfig}
+
+ def __init__(
+ self,
+ use_cache=True,
+ image_token_id=128257,
+ tie_word_embeddings=False,
+ vision_config=None,
+ text_config=None,
+ scale_factor=2,
+ pad_token_id=128_002,
+ **kwargs,
+ ):
+ self.image_token_id = image_token_id
+ self.use_cache = use_cache
+ self.tie_word_embeddings = tie_word_embeddings
+
+ if vision_config is None:
+ self.vision_config = SmolVLMVisionConfig()
+ logger.info("vision_config is None, using default vision config")
+ elif isinstance(vision_config, dict):
+ self.vision_config = SmolVLMVisionConfig(**vision_config)
+ elif isinstance(vision_config, SmolVLMVisionConfig):
+ self.vision_config = vision_config
+
+ if isinstance(text_config, dict):
+ text_config["model_type"] = text_config.get("model_type", "llama")
+ text_config = CONFIG_MAPPING[text_config["model_type"]](**text_config)
+ elif text_config is None:
+ logger.info("text_config is None, using default text config")
+ text_config = CONFIG_MAPPING["llama"](
+ rms_norm_eps=1e-5,
+ pad_token_id=pad_token_id,
+ tie_word_embeddings=False,
+ )
+
+ self.text_config = text_config
+ self.scale_factor = scale_factor
+
+ super().__init__(**kwargs, pad_token_id=pad_token_id, tie_word_embeddings=tie_word_embeddings)
+
+
+__all__ = ["SmolVLMVisionConfig", "SmolVLMConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..d92d9a3385eb7ca289348589d09228a36be272e9
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm.py
@@ -0,0 +1,896 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_smolvlm.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 the HuggingFace Inc. team. All rights reserved.
+# Written by Orr Zohar
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import math
+from collections.abc import Iterable
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature
+from ...image_transforms import PaddingMode, pad, to_channel_dimension_format, to_pil_image
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ get_image_size,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_nested_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, is_vision_available, logging
+
+
+if is_vision_available():
+ import PIL
+ from PIL import Image
+
+
+logger = logging.get_logger(__name__)
+MAX_IMAGE_SIZE = 4096 # 4k resolution as absolute maximum
+
+
+def _resize_output_size_rescale_to_max_len(
+ height: int, width: int, min_len: Optional[int] = 1, max_len: Optional[int] = None
+) -> tuple[int, int]:
+ """
+ Get the output size of the image after resizing given a dictionary specifying the max and min sizes.
+ Args:
+ height (`int`):
+ Height of the input image.
+ width (`int`):
+ Width of the input image.
+ min_len (`int`, *optional*, defaults to 1):
+ Minimum size of the output image.
+ max_len (`int`, *optional*, defaults to the maximum size of the image):
+ Maximum size of the output image.
+ Returns:
+ The output size of the image after resizing.
+ """
+ max_len = max(height, width) if max_len is None else max_len
+ aspect_ratio = width / height
+
+ if width >= height:
+ width = max_len
+ height = int(width / aspect_ratio)
+ if height % 2 != 0:
+ height += 1
+ elif height > width:
+ height = max_len
+ width = int(height * aspect_ratio)
+ if width % 2 != 0:
+ width += 1
+
+ # Avoid resizing to a size smaller than min_len
+ height = max(height, min_len)
+ width = max(width, min_len)
+ return height, width
+
+
+def _resize_output_size_scale_below_upper_bound(
+ height: int, width: int, max_len: Optional[dict[str, int]] = None
+) -> tuple[int, int]:
+ """
+ Get the output size of the image after resizing given a dictionary specifying the max and min sizes.
+ Args:
+ height (`int`):
+ Height of the input image.
+ width (`int`):
+ Width of the input image.
+ max_len (`dict[str, int]`, *optional*, defaults to the maximum size of the image):
+ Defines the maximum dimensions of the image.
+ Returns:
+ The output size of the image after resizing.
+ """
+ max_len = max(height, width) if max_len is None else max_len
+
+ aspect_ratio = width / height
+ if width >= height and width > max_len:
+ width = max_len
+ height = int(width / aspect_ratio)
+ elif height > width and height > max_len:
+ height = max_len
+ width = int(height * aspect_ratio)
+
+ # Avoid resizing to a size smaller than 1
+ height = max(height, 1)
+ width = max(width, 1)
+ return height, width
+
+
+def get_resize_output_image_size(
+ image,
+ resolution_max_side: int,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> tuple[int, int]:
+ """
+ Get the output size of the image after resizing given a dictionary specifying the max and min sizes.
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ resolution_max_side (`int`):
+ The longest edge of the image will be resized to this value. The shortest edge will be resized to keep the
+ input aspect ratio.
+ input_data_format (`ChannelDimension` or `str`):
+ The channel dimension format of the input image.
+ Returns:
+ The output size of the image after resizing.
+ """
+ height, width = get_image_size(image, channel_dim=input_data_format)
+
+ # Find the output size, when rescaling the longest edge to max_len and preserving the aspect ratio
+ height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=resolution_max_side)
+ # Find the output size when scaling the image to be below the MAX_IMAGE_SIZE
+ height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=MAX_IMAGE_SIZE)
+ return height, width
+
+
+def get_max_height_width(
+ images_list: list[list[np.ndarray]], input_data_format: Optional[Union[str, ChannelDimension]] = None
+) -> list[int]:
+ """
+ Get the maximum height and width across all images in a batch.
+ """
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(images_list[0][0], num_channels=(1, 3, 4))
+
+ max_height = max_width = float("-inf")
+ for images in images_list:
+ for image in images:
+ height, width = get_image_size(image, channel_dim=input_data_format)
+ max_height = max(height, max_height)
+ max_width = max(width, max_width)
+ return (max_height, max_width)
+
+
+def make_pixel_mask(
+ image: np.ndarray, output_size: tuple[int, int], input_data_format: Optional[Union[str, ChannelDimension]] = None
+) -> np.ndarray:
+ """
+ Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding.
+ Args:
+ image (`np.ndarray`):
+ Image to make the pixel mask for.
+ output_size (`tuple[int, int]`):
+ Output size of the mask.
+ """
+ input_height, input_width = get_image_size(image, channel_dim=input_data_format)
+ mask = np.zeros(output_size, dtype=np.int64)
+ mask[:input_height, :input_width] = 1
+ return mask
+
+
+def convert_to_rgb(
+ image: np.ndarray,
+ palette: Optional[PIL.ImagePalette.ImagePalette] = None,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> ImageInput:
+ """
+ Converts an image to RGB format.
+ Args:
+ image (`np.ndarray`):
+ The image to convert.
+ palette (list[int], *optional*):
+ The palette to use if given.
+ data_format (ChannelDimension or str, *optional*):
+ The channel dimension format for the output image. If not provided, it will be the same as the input image.
+ input_data_format (ChannelDimension or str, *optional*):
+ The channel dimension format of the input image.
+ """
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(image, num_channels=(1, 3, 4))
+
+ # For all transformations, we want to keep the same data format as the input image unless otherwise specified.
+ # The resized image from PIL will always have channels last, so find the input format first.
+ data_format = input_data_format if data_format is None else data_format
+
+ mode = "P" if palette is not None else None
+ image = to_pil_image(image, image_mode=mode, input_data_format=input_data_format)
+ if image.mode == "P" and palette is not None:
+ image.putpalette(palette)
+
+ image_rgba = image.convert("RGBA")
+ background = Image.new("RGBA", image_rgba.size, (255, 255, 255))
+ alpha_composite = Image.alpha_composite(background, image_rgba)
+ alpha_composite = alpha_composite.convert("RGB")
+
+ output_array = np.array(alpha_composite)
+ # The image is always in channels last format after converting from a PIL image
+ output_array = to_channel_dimension_format(output_array, data_format, input_channel_dim=ChannelDimension.LAST)
+ return output_array
+
+
+# FIXME Amy: make a more general crop function that isn't just centre crop
+def _crop(
+ image: np.ndarray,
+ w1: int,
+ h1: int,
+ w2: int,
+ h2: int,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> np.ndarray:
+ if data_format is None:
+ data_format = infer_channel_dimension_format(image, num_channels=(1, 3, 4))
+
+ if data_format == ChannelDimension.FIRST:
+ image = image[:, h1:h2, w1:w2]
+ elif data_format == ChannelDimension.LAST:
+ image = image[h1:h2, w1:w2, :]
+ else:
+ raise ValueError("Invalid channel dimension format.")
+
+ return image
+
+
+class SmolVLMImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a SmolVLM image processor.
+ Args:
+ do_convert_rgb (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to RGB. This is useful if the input image is of a different format e.g. RGBA.
+ Only has an effect if the input image is in the PIL format.
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image. The longest edge of the image is resized to be <= `size["longest_edge"]`, with the
+ shortest edge resized to keep the input aspect ratio.
+ size (`Dict`, *optional*, defaults to `{"longest_edge": 4 * 364}`):
+ Controls the size of the output image. This is a dictionary containing the key "longest_edge".
+ The image will be resized such that the longest edge is <= `size["longest_edge"]` and the shortest edge is resized
+ to keep the input aspect ratio.
+ resample (`Resampling`, *optional*, defaults to `Resampling.LANCZOS`):
+ Resampling filter to use when resizing the image.
+ do_image_splitting (`bool`, *optional*, defaults to `True`):
+ Whether to split the image into sub-images concatenated with the original image. They are split into patches
+ such that each patch has a size of `max_image_size["height"]` x `max_image_size["width"]`.
+ max_image_size (`Dict`, *optional*, defaults to `{"longest_edge": 364}`):
+ Maximum resolution of the patches of images accepted by the model. This is a dictionary containing the key "longest_edge".
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image. If set to `True`, the image is rescaled to have pixel values between 0 and 1.
+ rescale_factor (`float`, *optional*, defaults to `1/255`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. If set to `True`, the image is normalized to have a mean of `image_mean` and
+ a standard deviation of `image_std`.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IDEFICS_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. Can be
+ overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IDEFICS_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether or not to pad the images to the largest height and width in the batch and number of images per
+ sample in the batch, such that the returned tensor is of shape (batch_size, max_num_images, num_channels, max_height, max_width).
+ """
+
+ model_input_names = ["pixel_values", "pixel_attention_mask"]
+
+ def __init__(
+ self,
+ do_convert_rgb: bool = True,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.LANCZOS,
+ do_image_splitting: bool = True,
+ max_image_size: Optional[dict[str, int]] = None,
+ do_rescale: bool = True,
+ rescale_factor: float = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_pad: bool = True,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ self.do_convert_rgb = do_convert_rgb
+ self.do_resize = do_resize
+ self.size = size if size is not None else {"longest_edge": 4 * 364}
+ self.resample = resample
+ self.do_image_splitting = do_image_splitting
+ self.max_image_size = max_image_size if max_image_size is not None else {"longest_edge": 364}
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+ self.do_pad = do_pad
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.LANCZOS,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image. The longest edge of the image is resized to size["longest_edge"], with the shortest edge
+ resized to keep the input aspect ratio. Can also be used with size["height"] and size["width"].
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Size of the output image.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.LANCZOS`):
+ Resampling filter to use when resizing the image.
+ data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the output image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(image, num_channels=(1, 3, 4))
+
+ # For all transformations, we want to keep the same data format as the input image unless otherwise specified.
+ # The resized image from PIL will always have channels last, so find the input format first.
+ data_format = input_data_format if data_format is None else data_format
+
+ if "longest_edge" in size:
+ size = get_resize_output_image_size(
+ image, resolution_max_side=size["longest_edge"], input_data_format=input_data_format
+ )
+ elif "height" in size and "width" in size:
+ size = (size["height"], size["width"])
+ else:
+ raise ValueError("size must be a dictionary with key 'longest_edge' or 'height' and 'width'.")
+
+ image_mode = None
+ if image.ndim == 2 or image.shape[-1] == 1:
+ image_mode = "P"
+ image = to_pil_image(image, image_mode=image_mode, input_data_format=input_data_format)
+
+ resized_image = image.resize((size[1], size[0]), resample=resample)
+ resized_image = np.array(resized_image)
+
+ # If the input image channel dimension was of size 1, then it is dropped when converting to a PIL image
+ # so we need to add it back if necessary.
+ resized_image = np.expand_dims(resized_image, axis=-1) if resized_image.ndim == 2 else resized_image
+ # The image is always in channels last format after converting from a PIL image
+ resized_image = to_channel_dimension_format(
+ resized_image, data_format, input_channel_dim=ChannelDimension.LAST
+ )
+ return resized_image
+
+ def split_image(
+ self,
+ image,
+ max_image_size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.LANCZOS,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ):
+ """
+ Split an image into squares of side max_image_size and the original image resized to max_image_size.
+ That means that a single image becomes a sequence of images.
+ This is a "trick" to spend more compute on each image with no changes in the vision encoder.
+ 1) If one side of the original image is larger than `max_image_size`, resize it to `max_image_size` while preserving the aspect ratio.
+ 2) Divide the resulting image into `ceil(height / max_image_size)` x `ceil(width / max_image_size)`
+ sub-images of the same size each (image_size, image_size). Typically, 364x364.
+ 3) Returns the list of the crops and the original image, in addition to the number of splits for the height and the width.
+ Args:
+ image (`np.ndarray`):
+ Images to split.
+ max_image_size (`dict[str, int]`):
+ Maximum size of the output image. If the image is larger than this size, it will be split into
+ patches of this size, and the original image will be concatenated with the patches, resized to max_size.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.LANCZOS`):
+ Resampling filter to use when resizing the image.
+ data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the output image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ height, width = get_image_size(image, channel_dim=input_data_format)
+ max_height = max_width = max_image_size["longest_edge"]
+
+ frames = []
+ if height > max_height or width > max_width:
+ # Calculate the number of splits
+ num_splits_h = math.ceil(height / max_height)
+ num_splits_w = math.ceil(width / max_width)
+ # Calculate the optimal width and height for the sub-images
+ optimal_height = math.ceil(height / num_splits_h)
+ optimal_width = math.ceil(width / num_splits_w)
+
+ # Iterate through each row and column
+ for r in range(num_splits_h):
+ for c in range(num_splits_w):
+ # Calculate the starting point of the crop
+ start_x = c * optimal_width
+ start_y = r * optimal_height
+
+ # Calculate the ending point of the crop
+ end_x = min(start_x + optimal_width, width)
+ end_y = min(start_y + optimal_height, height)
+
+ # Crop the image
+ cropped_image = _crop(
+ image,
+ start_x,
+ start_y,
+ end_x,
+ end_y,
+ data_format=data_format,
+ )
+ frames.append(cropped_image)
+
+ # For the global image at the end, we resize it to match the max_image_size, for cpu memory efficiency
+ global_image_height, global_image_width = max_height, max_width
+ if height != global_image_height or width != global_image_width:
+ image = self.resize(
+ image,
+ {"height": global_image_height, "width": global_image_width},
+ resample=resample,
+ input_data_format=data_format,
+ )
+ else:
+ num_splits_h, num_splits_w = 0, 0
+
+ frames.append(image)
+
+ return frames, num_splits_h, num_splits_w
+
+ def resize_for_vision_encoder(
+ self,
+ image: np.ndarray,
+ vision_encoder_max_size: int,
+ resample: PILImageResampling = PILImageResampling.LANCZOS,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ):
+ """
+ Resize images to be multiples of `vision_encoder_max_size` while preserving the aspect ratio.
+ Args:
+ image (`np.ndarray`):
+ Images to resize.
+ vision_encoder_max_size (`int`):
+ Maximum size of the output image. If the image is larger than this size, it will be split into
+ patches of this size, and the original image will be concatenated with the patches, resized to max_size.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.LANCZOS`):
+ Resampling filter to use when resizing the image.
+ data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the output image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred
+ """
+ height, width = get_image_size(image, channel_dim=input_data_format)
+
+ aspect_ratio = width / height
+ if width >= height:
+ width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size
+ height = int(width / aspect_ratio)
+ height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size
+ elif height > width:
+ height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size
+ width = int(height * aspect_ratio)
+ width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size
+ new_size = {"height": height, "width": width}
+ return self.resize(
+ image, size=new_size, resample=resample, input_data_format=input_data_format, data_format=data_format
+ )
+
+ def _pad_image(
+ self,
+ image: np.ndarray,
+ output_size: tuple[int, int],
+ constant_values: Union[float, Iterable[float]] = 0,
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ """
+ Pad an image with zeros to the given size.
+ """
+ input_height, input_width = get_image_size(image, channel_dim=input_data_format)
+ output_height, output_width = output_size
+
+ pad_bottom = output_height - input_height
+ pad_right = output_width - input_width
+ padding = ((0, pad_bottom), (0, pad_right))
+ padded_image = pad(
+ image,
+ padding,
+ mode=PaddingMode.CONSTANT,
+ constant_values=constant_values,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ return padded_image
+
+ def pad(
+ self,
+ images: list[np.ndarray],
+ constant_values: Union[float, Iterable[float]] = 0,
+ return_pixel_mask: bool = True,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> BatchFeature:
+ """
+ For a list of images, for each images, pads a batch of images to the bottom and right of the image with zeros to the size of largest height and width.
+ For each sample in the batch, pads the sample with empty images to the max_number of images per sample in the batch. Optionally returns a pixel mask.
+ Args:
+ images (`list[np.ndarray]`):
+ List of list of images to pad. Pads to the largest height and width in the batch.
+ constant_values (`float` or `Iterable[float]`, *optional*):
+ The value to use for the padding if `mode` is `"constant"`.
+ return_pixel_mask (`bool`, *optional*, defaults to `True`):
+ Whether to return a pixel mask.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ pad_size = get_max_height_width(images, input_data_format=input_data_format)
+
+ batch_size = len(images)
+ max_num_images = max(len(images_) for images_ in images)
+ input_data_format = (
+ infer_channel_dimension_format(images[0][0], num_channels=(1, 3, 4))
+ if input_data_format is None
+ else input_data_format
+ )
+ data_format = input_data_format if data_format is None else data_format
+
+ if input_data_format == ChannelDimension.FIRST:
+ n_channels = images[0][0].shape[0]
+ elif input_data_format == ChannelDimension.LAST:
+ n_channels = images[0][0].shape[-1]
+ else:
+ raise ValueError("Invalid channel dimension format.")
+
+ def empty_image(size, input_data_format):
+ if input_data_format == ChannelDimension.FIRST:
+ return np.zeros((n_channels, *size), dtype=np.uint8)
+ elif input_data_format == ChannelDimension.LAST:
+ return np.zeros((*size, n_channels), dtype=np.uint8)
+
+ padded_images_list = [
+ [empty_image(pad_size, data_format) for _ in range(max_num_images)] for _ in range(batch_size)
+ ]
+ padded_masks = [[np.zeros(pad_size, dtype=np.int64) for _ in range(max_num_images)] for _ in range(batch_size)]
+
+ for batch_idx in range(batch_size):
+ for sample_idx, image in enumerate(images[batch_idx]):
+ padded_images_list[batch_idx][sample_idx] = self._pad_image(
+ image,
+ pad_size,
+ constant_values=constant_values,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ padded_masks[batch_idx][sample_idx] = make_pixel_mask(
+ image, output_size=pad_size, input_data_format=input_data_format
+ )
+
+ padded_masks = padded_masks if return_pixel_mask else None
+ return padded_images_list, padded_masks
+
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_convert_rgb: Optional[bool] = None,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_image_splitting: Optional[bool] = None,
+ do_rescale: Optional[bool] = None,
+ max_image_size: Optional[dict[str, int]] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_pad: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_row_col_info: bool = False,
+ data_format: Optional[ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ):
+ """
+ Preprocess a batch of images.
+ Args:
+ images (`ImageInput`):
+ A list of images to preprocess.
+ do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`):
+ Whether to convert the image to RGB.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after resizing. With the longest edge resized to keep the input aspect ratio.
+ resample (`int`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only
+ has an effect if `do_resize` is set to `True`.
+ do_image_splitting (`bool`, *optional*, defaults to `self.do_image_splitting`):
+ Whether to split the image into sub-images concatenated with the original image. They are split into patches
+ such that each patch has a size of `max_image_size["height"]` x `max_image_size["width"]`.
+ max_image_size (`Dict`, *optional*, defaults to `self.max_image_size`):
+ Maximum resolution of the images. If the image is larger than this size, the image is split into patches.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image.
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to
+ `True`.
+ do_pad (`bool`, *optional*, defaults to `self.do_pad`):
+ Whether or not to pad the images to the largest height and width in the batch.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ return_row_col_info (`bool`, *optional*, default to `False`):
+ Whether to return the number of rows and columns of the split images. This is used for the
+ `SmolVLMProcessor` to generate prompt strings based on the number of rows and columns.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ size = size if size is not None else self.size
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_image_splitting = do_image_splitting if do_image_splitting is not None else self.do_image_splitting
+ max_image_size = max_image_size if max_image_size is not None else self.max_image_size
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb
+ do_pad = do_pad if do_pad is not None else self.do_pad
+
+ images = self.fetch_images(images)
+ images_list = make_nested_list_of_images(images)
+
+ if not valid_images(images_list[0]):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ # save the palettes for conversion to RGB
+ palettes_list = [
+ [im.getpalette() if isinstance(im, Image.Image) and im.mode == "P" else None for im in images]
+ for images in images_list
+ ]
+
+ # All transformations expect numpy arrays.
+ images_list = [[to_numpy_array(image) for image in images] for images in images_list]
+
+ # Extra channel dimension for grayscale images
+ if input_data_format in [ChannelDimension.LAST, None]:
+ images_list = [
+ [np.expand_dims(img, axis=-1) if img.ndim == 2 else img for img in images] for images in images_list
+ ]
+ elif input_data_format == ChannelDimension.FIRST:
+ images_list = [
+ [np.expand_dims(img, axis=0) if img.ndim == 2 else img for img in images] for images in images_list
+ ]
+
+ if do_rescale and is_scaled_image(images_list[0][0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ # We assume that all images have the same channel dimension format.
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(images_list[0][0], num_channels=(1, 3, 4))
+
+ if do_resize:
+ images_list = [
+ [
+ self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+ for image in images
+ ]
+ for images in images_list
+ ]
+
+ if do_image_splitting:
+ # We first resize both height and width of each image to the nearest max_image_size multiple, disregarding the aspect ratio
+ # for size=(10, max_image_size) -> rescaled_size=(max_image_size, max_image_size)
+ # for size=(11, max_image_size+1) -> rescaled_size=(max_image_size, max_image_size*2)
+ images_list = [
+ [
+ self.resize_for_vision_encoder(
+ image, max_image_size["longest_edge"], resample=resample, input_data_format=input_data_format
+ )
+ for image in images
+ ]
+ for images in images_list
+ ]
+ images_list_split_arrays = []
+ palettes_list_split_arrays = []
+ images_list_rows = []
+ images_list_cols = []
+ for images, palettes in zip(images_list, palettes_list):
+ split_image_arrays = []
+ split_palettes_arrays = []
+ image_rows = []
+ image_cols = []
+ for image, palette in zip(images, palettes):
+ split_image_array, rows, cols = self.split_image(
+ image,
+ max_image_size=max_image_size,
+ resample=resample,
+ input_data_format=input_data_format,
+ )
+ split_image_arrays.extend(split_image_array)
+ split_palettes_arrays.extend([palette] * len(split_image_array))
+ image_rows.append(rows)
+ image_cols.append(cols)
+ images_list_split_arrays.append(split_image_arrays)
+ palettes_list_split_arrays.append(split_palettes_arrays)
+ images_list_rows.append(image_rows)
+ images_list_cols.append(image_cols)
+ images_list = images_list_split_arrays
+ palettes_list = palettes_list_split_arrays
+ else:
+ # We square the images to max_image_size
+ images_list = [
+ [
+ self.resize(
+ image=image,
+ size={"height": max_image_size["longest_edge"], "width": max_image_size["longest_edge"]},
+ resample=resample,
+ input_data_format=input_data_format,
+ )
+ for image in images
+ ]
+ for images in images_list
+ ]
+ images_list_rows = [[0] * len(images) for images in images_list]
+ images_list_cols = [[0] * len(images) for images in images_list]
+
+ if do_convert_rgb:
+ images_list = [
+ [convert_to_rgb(img, palette) for img, palette in zip(images, palettes)]
+ for images, palettes in zip(images_list, palettes_list)
+ ]
+
+ if do_rescale:
+ images_list = [
+ [self.rescale(image, rescale_factor, input_data_format=input_data_format) for image in images]
+ for images in images_list
+ ]
+
+ if do_normalize:
+ images_list = [
+ [
+ self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+ for image in images
+ ]
+ for images in images_list
+ ]
+
+ pixel_attention_mask = None
+ if do_pad:
+ images_list, pixel_attention_mask = self.pad(
+ images_list, return_pixel_mask=True, return_tensors=return_tensors, input_data_format=input_data_format
+ )
+
+ if data_format is not None:
+ images_list = [
+ [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+ for image in images
+ ]
+ for images in images_list
+ ]
+
+ # Faster tensor conversion
+ data = {"pixel_values": np.array(images_list) if do_pad and return_tensors is not None else images_list}
+ if pixel_attention_mask is not None:
+ data["pixel_attention_mask"] = (
+ np.array(pixel_attention_mask) if do_pad and return_tensors is not None else pixel_attention_mask
+ )
+
+ encoding = BatchFeature(data=data, tensor_type=return_tensors)
+
+ # This is needed for generating correct text inputs in the processor - we don't pad to the max number of images
+ if return_row_col_info:
+ encoding["rows"] = images_list_rows
+ encoding["cols"] = images_list_cols
+
+ return encoding
+
+ def get_number_of_image_patches(self, height: int, width: int, images_kwargs=None):
+ """
+ A utility that returns number of image patches for a given image size.
+
+ Args:
+ height (`int`):
+ Height of the input image.
+ width (`int`):
+ Width of the input image.
+ images_kwargs (`dict`, *optional*)
+ Any kwargs to override defaults of the image processor.
+ Returns:
+ `int`: Number of patches per image.
+ """
+ do_image_splitting = images_kwargs.get("do_image_splitting", self.do_image_splitting)
+ max_image_size = images_kwargs.get("max_image_size", self.max_image_size)
+ size = images_kwargs.get("size", self.size)
+
+ num_patches = num_rows = num_cols = 1
+ if do_image_splitting:
+ height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=size["longest_edge"])
+ height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=4096)
+ aspect_ratio = width / height
+
+ if width >= height:
+ resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+ resized_height = int(width / aspect_ratio)
+ resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+ elif height > width:
+ resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+ resized_width = int(height * aspect_ratio)
+ resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+
+ max_height = max_width = max_image_size["longest_edge"]
+ if resized_height > max_height or resized_width > max_width:
+ # Calculate the number of splits
+ num_rows = math.ceil(resized_height / max_height)
+ num_cols = math.ceil(resized_width / max_width)
+ num_patches = num_rows * num_cols + 1
+
+ return num_patches, num_rows, num_cols
+
+
+__all__ = ["SmolVLMImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..a070cd87bf864f424da3516f978db42be40d543e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm_fast.py
@@ -0,0 +1,536 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_smolvlm.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 the HuggingFace Inc. team. All rights reserved.
+# Written by Orr Zohar
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import math
+from typing import Optional, Union
+
+import torch
+
+from ...image_processing_utils import BatchFeature
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ SizeDict,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ImageInput,
+ PILImageResampling,
+ make_nested_list_of_images,
+)
+from ...processing_utils import Unpack
+from ...utils import TensorType, auto_docstring, is_torchvision_available, logging
+
+
+if is_torchvision_available():
+ from torchvision.transforms import functional as F
+
+
+logger = logging.get_logger(__name__)
+
+
+class SmolVLMFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ """
+ do_pad (`bool`, *optional*):
+ Whether to pad the image. If `True`, will pad the patch dimension of the images in the batch to the largest
+ number of patches in the batch. Padding will be applied to the bottom and right with zeros.
+ do_image_splitting (`bool`, *optional*, defaults to `True`):
+ Whether to split the image into sub-images concatenated with the original image. They are split into patches
+ such that each patch has a size of `max_image_size["height"]` x `max_image_size["width"]`.
+ max_image_size (`Dict`, *optional*, defaults to `{"longest_edge": 364}`):
+ Maximum resolution of the patches of images accepted by the model. This is a dictionary containing the key "longest_edge".
+ return_row_col_info (`bool`, *optional*, defaults to `False`):
+ Whether to return the row and column information of the images.
+ """
+
+ do_pad: Optional[bool]
+ do_image_splitting: Optional[bool]
+ max_image_size: Optional[dict[str, int]]
+ return_row_col_info: Optional[bool]
+
+
+MAX_IMAGE_SIZE = 4096 # 4k resolution as absolute maximum
+
+
+def _resize_output_size_rescale_to_max_len(
+ height: int, width: int, min_len: Optional[int] = 1, max_len: Optional[int] = None
+) -> tuple[int, int]:
+ """
+ Get the output size of the image after resizing given a dictionary specifying the max and min sizes.
+ Args:
+ height (`int`):
+ Height of the input image.
+ width (`int`):
+ Width of the input image.
+ min_len (`int`, *optional*, defaults to 1):
+ Minimum size of the output image.
+ max_len (`int`, *optional*, defaults to the maximum size of the image):
+ Maximum size of the output image.
+ Returns:
+ The output size of the image after resizing.
+ """
+ max_len = max(height, width) if max_len is None else max_len
+ aspect_ratio = width / height
+
+ if width >= height:
+ width = max_len
+ height = int(width / aspect_ratio)
+ if height % 2 != 0:
+ height += 1
+ elif height > width:
+ height = max_len
+ width = int(height * aspect_ratio)
+ if width % 2 != 0:
+ width += 1
+
+ # Avoid resizing to a size smaller than min_len
+ height = max(height, min_len)
+ width = max(width, min_len)
+ return height, width
+
+
+def _resize_output_size_scale_below_upper_bound(
+ height: int, width: int, max_len: Optional[dict[str, int]] = None
+) -> tuple[int, int]:
+ """
+ Get the output size of the image after resizing given a dictionary specifying the max and min sizes.
+ Args:
+ height (`int`):
+ Height of the input image.
+ width (`int`):
+ Width of the input image.
+ max_len (`Dict[str, int]`, *optional*, defaults to the maximum size of the image):
+ Defines the maximum dimensions of the image.
+ Returns:
+ The output size of the image after resizing.
+ """
+ max_len = max(height, width) if max_len is None else max_len
+
+ aspect_ratio = width / height
+ if width >= height and width > max_len:
+ width = max_len
+ height = int(width / aspect_ratio)
+ elif height > width and height > max_len:
+ height = max_len
+ width = int(height * aspect_ratio)
+
+ # Avoid resizing to a size smaller than 1
+ height = max(height, 1)
+ width = max(width, 1)
+ return height, width
+
+
+def get_resize_output_image_size(
+ image,
+ resolution_max_side: int,
+) -> tuple[int, int]:
+ """
+ Get the output size of the image after resizing given a dictionary specifying the max and min sizes.
+ Args:
+ image (`torch.Tensor`):
+ Image to resize.
+ resolution_max_side (`int`):
+ The longest edge of the image will be resized to this value. The shortest edge will be resized to keep the
+ input aspect ratio.
+ Returns:
+ The output size of the image after resizing.
+ """
+ height, width = image.size()[-2:]
+
+ # Find the output size, when rescaling the longest edge to max_len and preserving the aspect ratio
+ height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=resolution_max_side)
+ # Find the output size when scaling the image to be below the MAX_IMAGE_SIZE
+ height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=MAX_IMAGE_SIZE)
+ return height, width
+
+
+def get_max_height_width(images_list: list[list["torch.Tensor"]]) -> tuple[int, int]:
+ """
+ Get the maximum height and width across all images in a batch.
+ """
+ image_sizes = []
+ for images in images_list:
+ for image in images:
+ image_sizes.append(image.size()[-2:])
+
+ max_height = max(size[0] for size in image_sizes)
+ max_width = max(size[1] for size in image_sizes)
+ return (max_height, max_width)
+
+
+@auto_docstring
+class SmolVLMImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.LANCZOS
+ image_mean = IMAGENET_STANDARD_MEAN
+ image_std = IMAGENET_STANDARD_STD
+ size = {"longest_edge": 4 * 364}
+ max_image_size = {"longest_edge": 364}
+ do_resize = True
+ do_rescale = True
+ do_normalize = True
+ do_convert_rgb = True
+ do_image_splitting = True
+ do_pad = True
+ return_row_col_info = False
+ valid_kwargs = SmolVLMFastImageProcessorKwargs
+
+ def _prepare_images_structure(self, images: ImageInput, expected_ndims: int = 3) -> ImageInput:
+ """
+ Prepare a nested images structure for processing.
+ """
+ return make_nested_list_of_images(images, expected_ndims=expected_ndims)
+
+ def resize(
+ self,
+ image: "torch.Tensor",
+ size: SizeDict,
+ interpolation: "F.InterpolationMode" = None,
+ antialias: bool = True,
+ **kwargs,
+ ) -> "torch.Tensor":
+ """
+ Resize an image. The longest edge of the image is resized to size.longest_edge, with the shortest edge
+ resized to keep the input aspect ratio. Can also be used with size.height and size.width.
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`Dict[str, int]`):
+ Size of the output image.
+ interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`):
+ `InterpolationMode` filter to use when resizing the image e.g. `InterpolationMode.BICUBIC`.
+ antialias (`bool`, *optional*, defaults to `True`):
+ Whether to use antialiasing when resizing the image.
+ """
+ interpolation = interpolation if interpolation is not None else F.InterpolationMode.BILINEAR
+ if interpolation == F.InterpolationMode.LANCZOS:
+ logger.warning_once(
+ "You have used fast image processor with LANCZOS resample which not yet supported for torch.Tensor. "
+ "BICUBIC resample will be used as an alternative. Please fall back to slow image processor if you "
+ "want full consistency with the original model."
+ )
+ interpolation = F.InterpolationMode.BICUBIC
+
+ if size.longest_edge:
+ size = get_resize_output_image_size(image, resolution_max_side=size.longest_edge)
+ elif size.height and size.width:
+ size = (size.height, size.width)
+ else:
+ raise ValueError("size must be a dictionary with key 'longest_edge' or 'height' and 'width'.")
+
+ return F.resize(image, size, interpolation=interpolation, antialias=antialias)
+
+ def split_images(
+ self,
+ images: torch.Tensor,
+ max_image_size: dict[str, int],
+ interpolation: "F.InterpolationMode" = None,
+ ):
+ """
+ Split an image into squares of side max_image_size and the original image resized to max_image_size.
+ That means that a single image becomes a sequence of images.
+ This is a "trick" to spend more compute on each image with no changes in the vision encoder.
+ 1) If one side of the original image is larger than `max_image_size`, resize it to `max_image_size` while preserving the aspect ratio.
+ 2) Divide the resulting image into `ceil(height / max_image_size)` x `ceil(width / max_image_size)`
+ sub-images of the same size each (image_size, image_size). Typically, 364x364.
+ 3) Returns the list of the crops and the original image, in addition to the number of splits for the height and the width.
+ Args:
+ images (`torch.Tensor`):
+ Images to split.
+ max_image_size (`Dict[str, int]`):
+ Maximum size of the output image. If the image is larger than this size, it will be split into
+ patches of this size, and the original image will be concatenated with the patches, resized to max_size.
+ interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`):
+ `InterpolationMode` filter to use when resizing the image e.g. `InterpolationMode.BICUBIC`.
+ """
+ batch_size, num_channels, height, width = images.size()
+ height_dim, width_dim = 2, 3
+
+ max_height = max_width = max_image_size["longest_edge"]
+
+ frames = []
+ if height > max_height or width > max_width:
+ # Calculate the number of splits
+ num_splits_h = math.ceil(height / max_height)
+ num_splits_w = math.ceil(width / max_width)
+
+ # Split the images by height, then by width
+ frames = (
+ images.unfold(height_dim, size=max_height, step=max_height)
+ .unfold(width_dim, size=max_width, step=max_width)
+ .contiguous()
+ .view(batch_size, num_channels, -1, max_height, max_width)
+ .permute(0, 2, 1, 3, 4)
+ ) # batch_size x n_frames x num_channels x height x width
+
+ # For the global image at the end, we resize it to match the max_image_size, for cpu memory efficiency
+ global_image_height, global_image_width = max_height, max_width
+ images = self.resize(
+ images, SizeDict(height=global_image_height, width=global_image_width), interpolation=interpolation
+ )
+
+ frames = torch.cat((frames, images.unsqueeze(1)), dim=1)
+ else:
+ num_splits_h, num_splits_w = 0, 0
+ frames = images.unsqueeze(1)
+
+ num_splits_h = [num_splits_h] * batch_size
+ num_splits_w = [num_splits_w] * batch_size
+
+ return frames, num_splits_h, num_splits_w
+
+ def resize_for_vision_encoder(
+ self,
+ image: torch.Tensor,
+ vision_encoder_max_size: int,
+ interpolation: "F.InterpolationMode" = None,
+ ):
+ """
+ Resize images to be multiples of `vision_encoder_max_size` while preserving the aspect ratio.
+ Args:
+ image (`torch.Tensor`):
+ Images to resize.
+ vision_encoder_max_size (`int`):
+ Maximum size of the output image. If the image is larger than this size, it will be split into
+ patches of this size, and the original image will be concatenated with the patches, resized to max_size.
+ interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`):
+ `InterpolationMode` filter to use when resizing the image e.g. `InterpolationMode.BICUBIC`.
+ """
+ height, width = image.size()[-2:]
+
+ aspect_ratio = width / height
+ if width >= height:
+ width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size
+ height = int(width / aspect_ratio)
+ height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size
+ elif height > width:
+ height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size
+ width = int(height * aspect_ratio)
+ width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size
+ new_size = SizeDict(height=height, width=width)
+ return self.resize(image, size=new_size, interpolation=interpolation)
+
+ def pad(
+ self,
+ image: torch.Tensor,
+ padded_size: tuple[int, int],
+ fill: int = 0,
+ return_pixel_mask: bool = True,
+ ):
+ original_size = image.shape[-2:]
+ padding_bottom = padded_size[0] - original_size[0]
+ padding_right = padded_size[1] - original_size[1]
+
+ if padding_bottom < 0 or padding_right < 0:
+ raise ValueError(
+ f"Padding dimensions are negative. Please make sure that the padded size is larger than the "
+ f"original size. Got padded size: {padded_size}, original size: {original_size}."
+ )
+
+ # Only pad if necessary
+ if original_size != padded_size:
+ padding = (0, 0, padding_right, padding_bottom)
+ image = F.pad(image, padding, fill=fill, padding_mode="constant")
+
+ # Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding.
+ pixel_mask = None
+ if return_pixel_mask:
+ pixel_mask = torch.zeros_like(image[..., 0, :, :], dtype=torch.int64)
+ pixel_mask[: original_size[0], : original_size[1]] = 1
+
+ return image, pixel_mask
+
+ @auto_docstring
+ def preprocess(self, images: ImageInput, **kwargs: Unpack[SmolVLMFastImageProcessorKwargs]) -> BatchFeature:
+ return super().preprocess(images, **kwargs)
+
+ def _preprocess(
+ self,
+ images: list[list["torch.Tensor"]],
+ do_resize: bool,
+ size: SizeDict,
+ interpolation: Optional["F.InterpolationMode"],
+ do_rescale: bool,
+ rescale_factor: float,
+ do_normalize: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ do_pad: Optional[bool],
+ do_image_splitting: Optional[bool],
+ max_image_size: Optional[dict[str, int]],
+ return_row_col_info: Optional[bool],
+ disable_grouping: Optional[bool],
+ return_tensors: Optional[Union[str, TensorType]],
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Process a batch of images for the model.
+ """
+
+ grouped_images, grouped_images_index = group_images_by_shape(
+ images, is_nested=True, disable_grouping=disable_grouping
+ )
+ resized_images_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ if do_resize:
+ stacked_images = self.resize(stacked_images, size, interpolation=interpolation)
+ resized_images_grouped[shape] = stacked_images
+ resized_images = reorder_images(resized_images_grouped, grouped_images_index, is_nested=True)
+
+ grouped_images, grouped_images_index = group_images_by_shape(
+ resized_images, is_nested=True, disable_grouping=disable_grouping
+ )
+ split_images_grouped = {}
+ if do_image_splitting:
+ rows_grouped = {}
+ cols_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ stacked_images = self.resize_for_vision_encoder(
+ stacked_images, max_image_size["longest_edge"], interpolation=interpolation
+ )
+ stacked_images, rows, cols = self.split_images(
+ stacked_images, max_image_size=max_image_size, interpolation=interpolation
+ )
+ split_images_grouped[shape] = stacked_images
+ rows_grouped[shape] = rows
+ cols_grouped[shape] = cols
+ processed_images = reorder_images(split_images_grouped, grouped_images_index, is_nested=True)
+ rows = reorder_images(rows_grouped, grouped_images_index, is_nested=True)
+ cols = reorder_images(cols_grouped, grouped_images_index, is_nested=True)
+ # flattenened the doubly nested list to a nested list
+ for i, group_images in enumerate(processed_images):
+ processed_images[i] = [image for sublist in group_images for image in sublist]
+ else:
+ for shape, stacked_images in grouped_images.items():
+ # We square the images to max_image_size
+ stacked_images = self.resize(
+ image=stacked_images,
+ size=SizeDict(height=max_image_size["longest_edge"], width=max_image_size["longest_edge"]),
+ interpolation=interpolation,
+ )
+ split_images_grouped[shape] = stacked_images
+ processed_images = reorder_images(split_images_grouped, grouped_images_index, is_nested=True)
+ rows = [[0] * len(images) for images in processed_images]
+ cols = [[0] * len(images) for images in processed_images]
+ # Group images by size for further processing
+ # Needed in case do_resize is False, or resize returns images with different sizes
+ grouped_images, grouped_images_index = group_images_by_shape(
+ processed_images, is_nested=True, disable_grouping=disable_grouping
+ )
+ processed_images_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ # Fused rescale and normalize
+ stacked_images = self.rescale_and_normalize(
+ stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std
+ )
+ processed_images_grouped[shape] = stacked_images
+ processed_images = reorder_images(processed_images_grouped, grouped_images_index, is_nested=True)
+ if do_pad:
+ # Get max images per batch
+ max_num_images = max(len(images_) for images_ in processed_images)
+ max_height, max_width = get_max_height_width(processed_images)
+
+ processed_images_padded = torch.zeros(
+ len(processed_images),
+ max_num_images,
+ *(processed_images[0][0].shape[0], max_height, max_width),
+ device=processed_images[0][0].device,
+ )
+ pixel_attention_masks = torch.zeros(
+ len(processed_images),
+ max_num_images,
+ *(max_height, max_width),
+ device=processed_images[0][0].device,
+ )
+ for i, images in enumerate(processed_images):
+ for j, image in enumerate(images):
+ processed_images_padded[i, j], pixel_attention_masks[i, j] = self.pad(
+ image, (max_height, max_width)
+ )
+ processed_images = processed_images_padded
+
+ if do_pad:
+ data = {"pixel_values": processed_images, "pixel_attention_mask": pixel_attention_masks}
+ elif return_tensors == "pt":
+ data = {"pixel_values": torch.stack([torch.stack(images) for images in processed_images])}
+ else:
+ data = {"pixel_values": processed_images}
+ # This is needed for generating correct text inputs in the processor - we don't pad to the max number of images
+ encoding = BatchFeature(data=data, tensor_type=return_tensors)
+
+ if return_row_col_info:
+ encoding["rows"] = rows
+ encoding["cols"] = cols
+
+ return encoding
+
+ def to_dict(self):
+ encoder_dict = super().to_dict()
+ encoder_dict.pop("_valid_processor_keys", None)
+ encoder_dict.pop("return_row_col_info", None)
+ return encoder_dict
+
+ def get_number_of_image_patches(self, height: int, width: int, images_kwargs=None):
+ """
+ A utility that returns number of image patches for a given image size.
+
+ Args:
+ height (`int`):
+ Height of the input image.
+ width (`int`):
+ Width of the input image.
+ images_kwargs (`dict`, *optional*)
+ Any kwargs to override defaults of the image processor.
+ Returns:
+ `int`: Number of patches per image.
+ """
+ do_image_splitting = images_kwargs.get("do_image_splitting", self.do_image_splitting)
+ max_image_size = images_kwargs.get("max_image_size", self.max_image_size)
+ size = images_kwargs.get("size", self.size)
+
+ num_patches = num_rows = num_cols = 1
+ if do_image_splitting:
+ height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=size["longest_edge"])
+ height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=MAX_IMAGE_SIZE)
+ aspect_ratio = width / height
+
+ if width >= height:
+ resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+ resized_height = int(width / aspect_ratio)
+ resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+ elif height > width:
+ resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+ resized_width = int(height * aspect_ratio)
+ resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"]
+
+ max_height = max_width = max_image_size["longest_edge"]
+ if resized_height > max_height or resized_width > max_width:
+ # Calculate the number of splits
+ num_rows = math.ceil(resized_height / max_height)
+ num_cols = math.ceil(resized_width / max_width)
+ num_patches = num_rows * num_cols + 1
+
+ return num_patches, num_rows, num_cols
+
+
+__all__ = ["SmolVLMImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/modeling_smolvlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/modeling_smolvlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..cde441cc672fdb64cd46e91ba014264f770db2da
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/modeling_smolvlm.py
@@ -0,0 +1,1028 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_smolvlm.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 the HuggingFace Inc. team. All rights reserved.
+# Written by Orr Zohar
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache
+from ...generation import GenerationConfig, GenerationMixin
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ModelOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import (
+ TransformersKwargs,
+ auto_docstring,
+ can_return_tuple,
+ logging,
+)
+from ..auto import AutoModel
+from .configuration_smolvlm import SmolVLMConfig, SmolVLMVisionConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class SmolVLMRMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ SmolVLMRMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+@auto_docstring
+class SmolVLMPreTrainedModel(PreTrainedModel):
+ config: SmolVLMConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["SmolVLMVisionAttention", "SmolVLMDecoderLayer"]
+ _skip_keys_device_placement = "past_key_values"
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ _supports_attention_backend = True
+
+ def _init_weights(self, module):
+ std = getattr(self.config, "initializer_range", self.config.get_text_config().initializer_range)
+
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.weight.data.fill_(1.0)
+ module.bias.data.zero_()
+ elif isinstance(module, SmolVLMRMSNorm):
+ module.weight.data.fill_(1.0)
+
+
+class SmolVLMVisionEmbeddings(nn.Module):
+ """
+ This is a modified version of `siglip.modelign_siglip.SiglipVisionEmbeddings` to enable images of variable
+ resolution.
+
+ The modifications are adapted from [Patch n' Pack: NaViT, a Vision Transformer for any Aspect Ratio and Resolution](https://huggingface.co/papers/2307.06304)
+ which allows treating images in their native aspect ratio and without the need to resize them to the same
+ fixed size. In particular, we start from the original pre-trained SigLIP model
+ (which uses images of fixed-size square images) and adapt it by training on images of variable resolutions.
+ """
+
+ def __init__(self, config: SmolVLMVisionConfig):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.image_size = config.image_size
+ self.patch_size = config.patch_size
+
+ self.patch_embedding = nn.Conv2d(
+ in_channels=config.num_channels,
+ out_channels=self.embed_dim,
+ kernel_size=self.patch_size,
+ stride=self.patch_size,
+ padding="valid",
+ )
+
+ self.num_patches_per_side = self.image_size // self.patch_size
+ self.num_patches = self.num_patches_per_side**2
+ self.num_positions = self.num_patches
+ self.position_embedding = nn.Embedding(self.num_positions, self.embed_dim)
+
+ def forward(self, pixel_values: torch.FloatTensor, patch_attention_mask: torch.BoolTensor) -> torch.Tensor:
+ batch_size, _, max_im_h, max_im_w = pixel_values.shape
+
+ patch_embeds = self.patch_embedding(pixel_values)
+ embeddings = patch_embeds.flatten(2).transpose(1, 2)
+
+ max_nb_patches_h, max_nb_patches_w = max_im_h // self.patch_size, max_im_w // self.patch_size
+ boundaries = torch.arange(
+ 1 / self.num_patches_per_side, 1.0, 1 / self.num_patches_per_side, device=pixel_values.device
+ )
+ position_ids = torch.full(
+ size=(batch_size, max_nb_patches_h * max_nb_patches_w), fill_value=0, device=pixel_values.device
+ )
+
+ for batch_idx, p_attn_mask in enumerate(patch_attention_mask):
+ nb_patches_h = p_attn_mask[:, 0].sum()
+ nb_patches_w = p_attn_mask[0].sum()
+
+ h_indices = torch.arange(nb_patches_h, device=position_ids.device, dtype=pixel_values.dtype)
+ w_indices = torch.arange(nb_patches_w, device=position_ids.device, dtype=pixel_values.dtype)
+
+ fractional_coords_h = h_indices / nb_patches_h * (1 - 1e-6)
+ fractional_coords_w = w_indices / nb_patches_w * (1 - 1e-6)
+
+ bucket_coords_h = torch.bucketize(fractional_coords_h, boundaries, right=True)
+ bucket_coords_w = torch.bucketize(fractional_coords_w, boundaries, right=True)
+
+ pos_ids = (bucket_coords_h[:, None] * self.num_patches_per_side + bucket_coords_w).flatten()
+ position_ids[batch_idx][p_attn_mask.view(-1)] = pos_ids
+
+ embeddings = embeddings + self.position_embedding(position_ids)
+ return embeddings
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class SmolVLMVisionAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ # Ignore copy
+ self.is_causal = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ batch_size, seq_length, embed_dim = hidden_states.shape
+
+ queries = self.q_proj(hidden_states)
+ keys = self.k_proj(hidden_states)
+ values = self.v_proj(hidden_states)
+
+ queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ queries,
+ keys,
+ values,
+ attention_mask,
+ is_causal=self.is_causal,
+ scaling=self.scale,
+ dropout=0.0 if not self.training else self.dropout,
+ )
+
+ attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+class SmolVLMVisionMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.activation_fn = ACT2FN[config.hidden_act]
+ self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.fc1(hidden_states)
+ hidden_states = self.activation_fn(hidden_states)
+ hidden_states = self.fc2(hidden_states)
+ return hidden_states
+
+
+class SmolVLMEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: SmolVLMVisionConfig):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.self_attn = SmolVLMVisionAttention(config)
+ self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.mlp = SmolVLMVisionMLP(config)
+ self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.FloatTensor]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`):
+ Input to the layer of shape `(batch, seq_len, embed_dim)`.
+ attention_mask (`torch.FloatTensor`):
+ Attention mask of shape `(batch, 1, q_len, k_v_seq_len)` where padding elements are indicated by very large negative values.
+ output_attentions (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class SmolVLMEncoder(nn.Module):
+ """
+ Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a
+ [`SmolVLMEncoderLayer`].
+
+ Args:
+ config: SmolVLMConfig
+ """
+
+ def __init__(self, config: SmolVLMConfig):
+ super().__init__()
+ self.config = config
+ self.layers = nn.ModuleList([SmolVLMEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ # Ignore copy
+ def forward(
+ self,
+ inputs_embeds,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ hidden_states = inputs_embeds
+ for encoder_layer in self.layers:
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The SmolVLM Vision Transformer Model outputting raw image embedding.
+ """
+)
+class SmolVLMVisionTransformer(SmolVLMPreTrainedModel):
+ config: SmolVLMVisionConfig
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+
+ def __init__(self, config: SmolVLMVisionConfig):
+ super().__init__(config)
+ embed_dim = config.hidden_size
+
+ self.embeddings = SmolVLMVisionEmbeddings(config)
+ self.encoder = SmolVLMEncoder(config)
+ self.patch_size = config.patch_size
+ self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self._use_flash_attention_2 = config._attn_implementation == "flash_attention_2"
+
+ def get_input_embeddings(self):
+ return self.embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings = value
+
+ def forward(
+ self,
+ pixel_values,
+ patch_attention_mask: Optional[torch.BoolTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ batch_size = pixel_values.size(0)
+ if patch_attention_mask is None:
+ patch_size = self.patch_size
+ patch_attention_mask = torch.ones(
+ (
+ batch_size,
+ pixel_values.size(2) // patch_size,
+ pixel_values.size(3) // patch_size,
+ )
+ )
+ patch_attention_mask = patch_attention_mask.to(dtype=torch.bool, device=pixel_values.device)
+
+ hidden_states = self.embeddings(pixel_values=pixel_values, patch_attention_mask=patch_attention_mask)
+
+ patch_attention_mask = patch_attention_mask.view(batch_size, -1)
+ # The call to `_upad_input` in `_flash_attention_forward` is expensive
+ # So when the `patch_attention_mask` is full of 1s (i.e. attending to the whole sequence),
+ # avoiding passing the attention_mask, which is equivalent to attending to the full sequence
+ if not self._use_flash_attention_2:
+ patch_attention_mask = _prepare_4d_attention_mask(patch_attention_mask, hidden_states.dtype)
+ elif not torch.any(~patch_attention_mask):
+ patch_attention_mask = None
+
+ encoder_outputs = self.encoder(
+ inputs_embeds=hidden_states,
+ attention_mask=patch_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_state = encoder_outputs[0]
+ last_hidden_state = self.post_layernorm(last_hidden_state)
+
+ if not return_dict:
+ return (last_hidden_state,) + encoder_outputs[1:]
+
+ return BaseModelOutput(
+ last_hidden_state=last_hidden_state,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for SmolVLM model's outputs that may also contain a past key/values (to speed up sequential decoding).
+ """
+)
+class SmolVLMBaseModelOutputWithPast(ModelOutput):
+ r"""
+ last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ If `past_key_values` is used only the last hidden-state of the sequences of shape `(batch_size, 1,
+ hidden_size)` is output.
+ past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and optionally if
+ `config.is_encoder_decoder=True` 2 additional tensors of shape `(batch_size, num_heads,
+ encoder_sequence_length, embed_size_per_head)`.
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and optionally if
+ `config.is_encoder_decoder=True` in the cross-attention blocks) that can be used (see `past_key_values`
+ input) to speed up sequential decoding.
+ image_hidden_states (`tuple(torch.FloatTensor)`, *optional*):
+ Tuple of `torch.FloatTensor` (one for the output of the image embeddings, `(batch_size, num_images,
+ sequence_length, hidden_size)`.
+ image_hidden_states of the model produced by the vision encoder
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ image_hidden_states: Optional[tuple[torch.FloatTensor]] = None
+
+
+class SmolVLMSimpleMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ input_size = config.vision_config.hidden_size * (config.scale_factor**2)
+ output_size = config.text_config.hidden_size
+ self.proj = nn.Linear(input_size, output_size, bias=False)
+
+ def forward(self, x):
+ return self.proj(x)
+
+
+class SmolVLMConnector(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.scale_factor = config.scale_factor
+ self.modality_projection = SmolVLMSimpleMLP(config)
+
+ def pixel_shuffle(self, x, scale_factor=2):
+ bsz, seq, embed_dim = x.size()
+ height = width = int(seq**0.5)
+ x = x.view(bsz, height, width, embed_dim)
+ x = x.view(bsz, height, int(width / scale_factor), embed_dim * scale_factor)
+ x = x.permute(0, 2, 1, 3)
+ x = x.reshape(bsz, int(width / scale_factor), int(height / scale_factor), embed_dim * (scale_factor**2))
+ x = x.permute(0, 2, 1, 3)
+ x = x.reshape(bsz, int(seq / (scale_factor**2)), embed_dim * (scale_factor**2))
+ return x
+
+ def forward(self, image_hidden_states):
+ image_hidden_states = self.pixel_shuffle(image_hidden_states, self.scale_factor)
+ image_hidden_states = self.modality_projection(image_hidden_states)
+ return image_hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ SmolVLM model consisting of a SIGLIP vision encoder and Llama3 language decoder
+ """
+)
+class SmolVLMModel(SmolVLMPreTrainedModel):
+ """
+ A subclass of Idefics3Model. We do *not* remove or block the call to inputs_merger
+ in forward. Instead, we override inputs_merger here with custom logic.
+ """
+
+ def __init__(self, config: SmolVLMConfig):
+ super().__init__(config)
+ self.padding_idx = self.config.text_config.pad_token_id
+ self.vocab_size = self.config.text_config.vocab_size
+
+ self.vision_model = SmolVLMVisionTransformer._from_config(config.vision_config)
+ self.connector = SmolVLMConnector(config)
+ self.text_model = AutoModel.from_config(config.text_config)
+
+ self.image_seq_len = int(
+ ((config.vision_config.image_size // config.vision_config.patch_size) ** 2) / (config.scale_factor**2)
+ )
+ self.image_token_id = self.config.image_token_id
+
+ self._use_flash_attention_2 = config.text_config._attn_implementation == "flash_attention_2"
+
+ self.post_init()
+
+ def enable_input_require_grads(self):
+ """
+ Enables the gradients for the input embeddings.
+
+ This is useful for lora when using gradient checkpointing.
+ c.f. https://github.com/huggingface/peft/issues/1402#issuecomment-1913675032
+
+ Override to set output.requires_grad = True for both the decoder's and vision model's embeddings.
+ """
+
+ def get_lowest_module(module):
+ if len(list(module.children())) == 0:
+ # If the module has no children, it is a leaf module (e.g., Linear, Conv2d, etc.)
+ return module
+ else:
+ # Recursively call the function on each child module
+ return get_lowest_module(list(module.children())[0])
+
+ def make_inputs_require_grads(module, input, output):
+ output.requires_grad_(True)
+
+ self._text_require_grads_hook = self.get_input_embeddings().register_forward_hook(make_inputs_require_grads)
+ self._vision_require_grads_hook = get_lowest_module(self.vision_model).register_forward_hook(
+ make_inputs_require_grads
+ )
+
+ def disable_input_require_grads(self):
+ self._text_require_grads_hook.remove()
+ self._vision_require_grads_hook.remove()
+
+ def get_input_embeddings(self):
+ return self.text_model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.text_model.set_input_embeddings(value)
+
+ def inputs_merger(
+ self, input_ids: torch.LongTensor, inputs_embeds: torch.Tensor, image_hidden_states: torch.Tensor
+ ):
+ """
+ This method aims at merging the token embeddings with the image hidden states into one single sequence of vectors that are fed to the transformer LM.
+ The merging happens as follows:
+ - The text token sequence is: `tok_1 tok_2 tok_3 ... tok_4`.
+ - We get the image hidden states for the image through the vision encoder and that hidden state, after a pixel shuffle operation, is then projected into the text embedding space.
+ We thus have a sequence of image hidden states of size (1, image_seq_len, hidden_dim), where 1 is for batch_size of 1 image and hidden_dim is the hidden_dim of the LM transformer.
+ - The merging happens so that we obtain the following sequence: `vector_tok_1 vector_tok_2 vector_tok_3 vector_fake_tok_around_image {sequence of image_seq_len image hidden states} vector_fake_toke_around_image vector_tok_4`. That sequence is fed to the LM.
+ - To fit the format of that sequence, `input_ids`, `input_embeds`, `attention_mask` are all 3 adapted to insert the image hidden states.
+ """
+ _, patch_size, _ = image_hidden_states.shape
+
+ if input_ids is None:
+ image_mask = inputs_embeds == self.get_input_embeddings()(
+ torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device)
+ )
+ image_mask = image_mask[..., 0] # slice off the hidden dim
+ else:
+ image_mask = input_ids == self.config.image_token_id
+
+ num_image_tokens = image_mask.sum(dim=1)
+ if not torch.all(num_image_tokens % patch_size == 0):
+ raise ValueError("At least one sample has tokens not divisible by patch_size.")
+
+ blocks_per_sample = num_image_tokens // patch_size
+
+ offsets = torch.nn.functional.pad(blocks_per_sample.cumsum(dim=0), (1, 0), value=0)
+ block_offset = offsets[:-1]
+ row_cum = image_mask.cumsum(dim=-1)
+ chunk_idx = (row_cum - 1) // patch_size
+ local_idx = (row_cum - 1) % patch_size
+ block_idx = block_offset.unsqueeze(1) + chunk_idx
+
+ image_embeds = torch.zeros_like(inputs_embeds)
+ image_embeds[image_mask] = image_hidden_states[block_idx[image_mask], local_idx[image_mask], :]
+
+ merged_embeds = torch.where(image_mask.unsqueeze(-1), image_embeds, inputs_embeds)
+ return merged_embeds
+
+ def get_image_features(self, pixel_values: torch.FloatTensor, pixel_attention_mask: torch.LongTensor = None):
+ """
+ Encodes images into continuous embeddings that can be forwarded to the language model.
+
+ Args:
+ pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`):
+ The tensors corresponding to the input images.
+ pixel_attention_mask (`torch.LongTensor`, *optional*):
+ The attention mask indicating padded regions in the image.
+ """
+ batch_size, num_images, num_channels, height, width = pixel_values.shape
+ pixel_values = pixel_values.to(dtype=self.dtype) # fp16 compatibility
+ pixel_values = pixel_values.view(batch_size * num_images, *pixel_values.shape[2:])
+
+ # Remove padding images - padding images are full 0.
+ nb_values_per_image = pixel_values.shape[1:].numel()
+ real_images_inds = (pixel_values == 0.0).sum(dim=(-1, -2, -3)) != nb_values_per_image
+
+ if not any(real_images_inds):
+ # no images, leave one empty image.
+ real_images_inds[0] = True
+
+ pixel_values = pixel_values[real_images_inds].contiguous()
+ # Handle the vision attention mask
+ if pixel_attention_mask is None:
+ pixel_attention_mask = torch.ones(
+ size=[pixel_values.shape[i] for i in (0, 2, 3)],
+ dtype=torch.bool,
+ device=pixel_values.device,
+ )
+ else:
+ # Remove padding images from the mask
+ pixel_attention_mask = pixel_attention_mask.view(batch_size * num_images, *pixel_attention_mask.shape[2:])
+ pixel_attention_mask = pixel_attention_mask[real_images_inds].contiguous()
+ patch_size = self.config.vision_config.patch_size
+ patches_subgrid = pixel_attention_mask.unfold(dimension=1, size=patch_size, step=patch_size)
+ patches_subgrid = patches_subgrid.unfold(dimension=2, size=patch_size, step=patch_size)
+ patch_attention_mask = (patches_subgrid.sum(dim=(-1, -2)) > 0).bool()
+
+ # Get sequence from the vision encoder
+ image_hidden_states = self.vision_model(pixel_values=pixel_values, patch_attention_mask=patch_attention_mask)
+ image_hidden_states = image_hidden_states.last_hidden_state
+
+ # Modality projection & resampling
+ image_hidden_states = self.connector(image_hidden_states)
+ return image_hidden_states
+
+ @can_return_tuple
+ @auto_docstring(
+ custom_intro="""
+ Inputs fed to the model can have an arbitrary number of images. To account for this, pixel_values fed to
+ the model have image padding -> (batch_size, max_num_images, 3, max_heights, max_widths) where
+ max_num_images is the maximum number of images among the batch_size samples in the batch.
+ Padding images are not needed beyond padding the pixel_values at the entrance of the model.
+ For efficiency, we only pass through the vision_model's forward the real images by
+ discarding the padding images i.e. pixel_values of size (image_batch_size, 3, height, width) where
+ image_batch_size would be 7 when num_images_per_sample=[1, 3, 1, 2] and max_num_images would be 3.
+ """
+ )
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_attention_mask: Optional[torch.BoolTensor] = None,
+ image_hidden_states: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Union[tuple, SmolVLMBaseModelOutputWithPast]:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ image_hidden_states (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`):
+ The hidden states of the image encoder after modality projection.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if self.training and self.text_model.gradient_checkpointing and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None:
+ batch_size, seq_length = input_ids.shape
+ elif inputs_embeds is not None:
+ batch_size, seq_length, _ = inputs_embeds.shape
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache(config=self.config)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.text_model.get_input_embeddings()(input_ids).to(input_ids.device)
+
+ # START VISUAL INPUTS INTEGRATION
+ if pixel_values is not None and image_hidden_states is not None:
+ raise ValueError("You cannot specify both pixel_values and image_hidden_states at the same time")
+
+ if pixel_values is not None:
+ image_hidden_states = self.get_image_features(pixel_values, pixel_attention_mask).to(inputs_embeds.device)
+ elif image_hidden_states is not None:
+ image_hidden_states = image_hidden_states.to(dtype=self.dtype, device=inputs_embeds.device)
+
+ if image_hidden_states is not None:
+ # When we generate, we don't want to replace the potential image_token_id that we generated by images
+ # that simply don't exist
+ inputs_embeds = self.inputs_merger(
+ input_ids=input_ids,
+ inputs_embeds=inputs_embeds,
+ image_hidden_states=image_hidden_states,
+ )
+
+ outputs = self.text_model(
+ inputs_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ return SmolVLMBaseModelOutputWithPast(
+ last_hidden_state=outputs.last_hidden_state,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=image_hidden_states,
+ )
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for Idefics causal language model (or autoregressive) outputs.
+ """
+)
+class SmolVLMCausalLMOutputWithPast(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Language modeling loss (for next-token prediction).
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+ past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`)
+ Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see
+ `past_key_values` input) to speed up sequential decoding.
+ image_hidden_states (`tuple(torch.FloatTensor)`, *optional*):
+ Tuple of `torch.FloatTensor` (one for the output of the image embeddings, `(batch_size, num_images,
+ sequence_length, hidden_size)`.
+ image_hidden_states of the model produced by the vision encoder
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ past_key_values: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ image_hidden_states: Optional[tuple[torch.FloatTensor]] = None
+
+
+@auto_docstring(
+ custom_intro="""
+ The SmolVLM Model with a language modeling head. It is made up a SigLIP vision encoder, with a language modeling head on top.
+ """
+)
+class SmolVLMForConditionalGeneration(SmolVLMPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = SmolVLMModel(config)
+ self.image_token_id = self.config.image_token_id
+ self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False)
+ self.vocab_size = config.text_config.vocab_size
+ self.model.text_model.generation_config = GenerationConfig.from_model_config(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def enable_input_require_grads(self):
+ """
+ Enables the gradients for the input embeddings. This is useful for fine-tuning adapter weights while keeping
+ the model weights fixed.
+ """
+
+ def make_inputs_require_grads(module, input, output):
+ output.requires_grad_(True)
+
+ self._text_require_grads_hook = self.get_input_embeddings().register_forward_hook(make_inputs_require_grads)
+ self._vision_require_grads_hook = self.model.vision_model.get_input_embeddings().register_forward_hook(
+ make_inputs_require_grads
+ )
+
+ def disable_input_require_grads(self):
+ self._text_require_grads_hook.remove()
+ self._vision_require_grads_hook.remove()
+
+ def get_input_embeddings(self):
+ return self.model.text_model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.text_model.set_input_embeddings(value)
+
+ def get_image_features(self, pixel_values: torch.FloatTensor, pixel_attention_mask: torch.LongTensor = None):
+ return self.model.get_image_features(pixel_values=pixel_values, pixel_attention_mask=pixel_attention_mask)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_attention_mask: Optional[torch.BoolTensor] = None,
+ image_hidden_states: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ return_dict: Optional[bool] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> Union[tuple, SmolVLMCausalLMOutputWithPast]:
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ image_hidden_states (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`):
+ The hidden states of the image encoder after modality projection.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or `model.image_token_id`. Tokens with indices set to `model.image_token_id` are
+ ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> import requests
+ >>> import torch
+ >>> from PIL import Image
+ >>> from io import BytesIO
+
+ >>> from transformers import AutoProcessor, AutoModelForImageTextToText
+ >>> from transformers.image_utils import load_image
+
+ >>> # Note that passing the image urls (instead of the actual pil images) to the processor is also possible
+ >>> image1 = load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg")
+ >>> image2 = load_image("https://cdn.britannica.com/59/94459-050-DBA42467/Skyline-Chicago.jpg")
+ >>> image3 = load_image("https://cdn.britannica.com/68/170868-050-8DDE8263/Golden-Gate-Bridge-San-Francisco.jpg")
+
+ >>> processor = AutoProcessor.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct")
+ >>> model = AutoModelForImageTextToText.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct", dtype=torch.bfloat16, device_map="auto")
+
+ >>> # Create inputs
+ >>> messages = [
+ ... {
+ ... "role": "user",
+ ... "content": [
+ ... {"type": "video", "path": path/to/video},
+ ... {"type": "text", "text": "What is happening in this video?"},
+ ... ]
+ ... }
+ ... ]
+
+ >>> inputs = processor.apply_chat_template([messages], add_generation_prompt=True)
+
+ >>> # Generate
+ >>> generated_ids = model.generate(**inputs, max_new_tokens=256)
+ >>> generated_texts = processor.batch_decode(generated_ids, skip_special_tokens=True)
+
+ >>> print(generated_texts)
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
+ outputs = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ pixel_values=pixel_values,
+ pixel_attention_mask=pixel_attention_mask,
+ image_hidden_states=image_hidden_states,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ cache_position=cache_position,
+ return_dict=True,
+ **kwargs,
+ )
+
+ hidden_states = outputs[0]
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(
+ logits=logits, labels=labels, vocab_size=self.config.text_config.vocab_size, **kwargs
+ )
+
+ return SmolVLMCausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=outputs.image_hidden_states,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ past_key_values=None,
+ attention_mask=None,
+ inputs_embeds=None,
+ cache_position=None,
+ pixel_values=None,
+ pixel_attention_mask=None,
+ image_hidden_states=None,
+ logits_to_keep=None,
+ **kwargs,
+ ):
+ # Overwritten -- there are mutually exclusive inputs (if the logic to make `image_hidden_states` take
+ # precedence is moved to the model, we can remove this fn)
+
+ model_inputs = super().prepare_inputs_for_generation(
+ input_ids,
+ past_key_values=past_key_values,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ cache_position=cache_position,
+ pixel_values=pixel_values,
+ pixel_attention_mask=pixel_attention_mask,
+ image_hidden_states=image_hidden_states,
+ logits_to_keep=logits_to_keep,
+ **kwargs,
+ )
+
+ if image_hidden_states is not None or cache_position[0] != 0:
+ model_inputs["pixel_values"] = None
+ model_inputs["pixel_attention_mask"] = None
+
+ return model_inputs
+
+
+__all__ = ["SmolVLMForConditionalGeneration", "SmolVLMPreTrainedModel", "SmolVLMModel", "SmolVLMVisionTransformer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/modular_smolvlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/modular_smolvlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..67bea742532a2827f40e699182a284cd055a005d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/modular_smolvlm.py
@@ -0,0 +1,410 @@
+# coding=utf-8
+# Copyright 2025 the HuggingFace Inc. team. All rights reserved.
+# Written by Orr Zohar
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...cache_utils import Cache, DynamicCache
+from ...generation import GenerationConfig
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...processing_utils import Unpack
+from ...utils import auto_docstring, can_return_tuple, logging
+from ..idefics3.configuration_idefics3 import Idefics3Config, Idefics3VisionConfig
+from ..idefics3.image_processing_idefics3 import Idefics3ImageProcessor
+from ..idefics3.image_processing_idefics3_fast import Idefics3ImageProcessorFast
+from ..idefics3.modeling_idefics3 import (
+ Idefics3BaseModelOutputWithPast,
+ Idefics3ForConditionalGeneration,
+ Idefics3Model,
+ Idefics3PreTrainedModel,
+ Idefics3VisionTransformer,
+)
+
+
+logger = logging.get_logger(__name__)
+
+
+class SmolVLMVisionConfig(Idefics3VisionConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SmolVLMVisionModel`]. It is used to instantiate a
+ SmolVLM vision encoder according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the SigLIP checkpoint
+ [google/siglip-so400m-patch14-384](https://huggingface.co/google/siglip-so400m-patch14-384) used in SmolVLM
+ [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct).
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 1152):
+ Dimensionality of the encoder layers and the pooler layer.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_channels (`int`, *optional*, defaults to 3):
+ Number of channels in the input images.
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 32):
+ The size (resolution) of each patch.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+
+ Example:
+
+ ```python
+ >>> from transformers.models.smolvlm.modeling_smolvlm import SmolVLMVisionTransformer
+ >>> from transformers.models.smolvlm.configuration_smolvlm import SmolVLMVisionConfig
+
+ >>> # Initializing a SmolVLMVisionConfig with google/siglip-so400m-patch14-384 style configuration
+ >>> configuration = SmolVLMVisionConfig()
+
+ >>> # Initializing a SmolVLMVisionTransformer (with random weights) from the google/siglip-so400m-patch14-384 style configuration
+ >>> model = SmolVLMVisionTransformer(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "smolvlm_vision"
+ pass
+
+
+class SmolVLMPreTrainedModel(Idefics3PreTrainedModel):
+ pass
+
+
+class SmolVLMVisionTransformer(Idefics3VisionTransformer):
+ pass
+
+
+class SmolVLMConfig(Idefics3Config):
+ r"""
+ This is the configuration class to store the configuration of a [`SmolVLMModel`]. It is used to instantiate a
+ SmolVLM model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the model of the SmolVLM
+ [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should cache the key/value pairs of the attention mechanism. Only
+ relevant if `config.is_decoder=True`.
+ image_token_id (`int`, *optional*, defaults to 128257):
+ The id of the "image" token.
+ tie_word_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether or not to tie the word embeddings with the token embeddings.
+ vision_config (`IdeficsVisionConfig` or `dict`, *optional*, defaults to `IdeficsVisionConfig`):
+ Custom vision config or dict for the vision tower
+ text_config (`PretrainedConfig` or `dict`, *optional*, defaults to `LlamaConfig`):
+ Custom text config or dict for the text model
+ scale_factor (`int`, *optional*, defaults to 2):
+ The scale factor for the image encoder.
+ pad_token_id (`int`, *optional*, defaults to 128002):
+ The id of the padding token.
+
+ Example:
+ ```python
+ >>> from transformers import SmolVLMModel, SmolVLMConfig
+ >>> # Initializing configuration
+ >>> configuration = SmolVLMConfig()
+ >>> # Initializing a model from the configuration
+ >>> model = SmolVLMModel(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "smolvlm"
+ pass
+
+
+class SmolVLMImageProcessor(Idefics3ImageProcessor):
+ pass
+
+
+class SmolVLMImageProcessorFast(Idefics3ImageProcessorFast):
+ pass
+
+
+class SmolVLMBaseModelOutputWithPast(Idefics3BaseModelOutputWithPast):
+ pass
+
+
+class SmolVLMModel(Idefics3Model):
+ """
+ A subclass of Idefics3Model. We do *not* remove or block the call to inputs_merger
+ in forward. Instead, we override inputs_merger here with custom logic.
+ """
+
+ def inputs_merger(
+ self, input_ids: torch.LongTensor, inputs_embeds: torch.Tensor, image_hidden_states: torch.Tensor
+ ):
+ _, patch_size, _ = image_hidden_states.shape
+
+ if input_ids is None:
+ image_mask = inputs_embeds == self.get_input_embeddings()(
+ torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device)
+ )
+ image_mask = image_mask[..., 0] # slice off the hidden dim
+ else:
+ image_mask = input_ids == self.config.image_token_id
+
+ num_image_tokens = image_mask.sum(dim=1)
+ if not torch.all(num_image_tokens % patch_size == 0):
+ raise ValueError("At least one sample has tokens not divisible by patch_size.")
+
+ blocks_per_sample = num_image_tokens // patch_size
+
+ offsets = torch.nn.functional.pad(blocks_per_sample.cumsum(dim=0), (1, 0), value=0)
+ block_offset = offsets[:-1]
+ row_cum = image_mask.cumsum(dim=-1)
+ chunk_idx = (row_cum - 1) // patch_size
+ local_idx = (row_cum - 1) % patch_size
+ block_idx = block_offset.unsqueeze(1) + chunk_idx
+
+ image_embeds = torch.zeros_like(inputs_embeds)
+ image_embeds[image_mask] = image_hidden_states[block_idx[image_mask], local_idx[image_mask], :]
+
+ merged_embeds = torch.where(image_mask.unsqueeze(-1), image_embeds, inputs_embeds)
+ return merged_embeds
+
+ def get_image_features(self, pixel_values: torch.FloatTensor, pixel_attention_mask: torch.LongTensor = None):
+ """
+ Encodes images into continuous embeddings that can be forwarded to the language model.
+
+ Args:
+ pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`):
+ The tensors corresponding to the input images.
+ pixel_attention_mask (`torch.LongTensor`, *optional*):
+ The attention mask indicating padded regions in the image.
+ """
+ batch_size, num_images, num_channels, height, width = pixel_values.shape
+ pixel_values = pixel_values.to(dtype=self.dtype) # fp16 compatibility
+ pixel_values = pixel_values.view(batch_size * num_images, *pixel_values.shape[2:])
+
+ # Remove padding images - padding images are full 0.
+ nb_values_per_image = pixel_values.shape[1:].numel()
+ real_images_inds = (pixel_values == 0.0).sum(dim=(-1, -2, -3)) != nb_values_per_image
+
+ if not any(real_images_inds):
+ # no images, leave one empty image.
+ real_images_inds[0] = True
+
+ pixel_values = pixel_values[real_images_inds].contiguous()
+ # Handle the vision attention mask
+ if pixel_attention_mask is None:
+ pixel_attention_mask = torch.ones(
+ size=[pixel_values.shape[i] for i in (0, 2, 3)],
+ dtype=torch.bool,
+ device=pixel_values.device,
+ )
+ else:
+ # Remove padding images from the mask
+ pixel_attention_mask = pixel_attention_mask.view(batch_size * num_images, *pixel_attention_mask.shape[2:])
+ pixel_attention_mask = pixel_attention_mask[real_images_inds].contiguous()
+ patch_size = self.config.vision_config.patch_size
+ patches_subgrid = pixel_attention_mask.unfold(dimension=1, size=patch_size, step=patch_size)
+ patches_subgrid = patches_subgrid.unfold(dimension=2, size=patch_size, step=patch_size)
+ patch_attention_mask = (patches_subgrid.sum(dim=(-1, -2)) > 0).bool()
+
+ # Get sequence from the vision encoder
+ image_hidden_states = self.vision_model(pixel_values=pixel_values, patch_attention_mask=patch_attention_mask)
+ image_hidden_states = image_hidden_states.last_hidden_state
+
+ # Modality projection & resampling
+ image_hidden_states = self.connector(image_hidden_states)
+ return image_hidden_states
+
+ @can_return_tuple
+ @auto_docstring(
+ custom_intro="""
+ Inputs fed to the model can have an arbitrary number of images. To account for this, pixel_values fed to
+ the model have image padding -> (batch_size, max_num_images, 3, max_heights, max_widths) where
+ max_num_images is the maximum number of images among the batch_size samples in the batch.
+ Padding images are not needed beyond padding the pixel_values at the entrance of the model.
+ For efficiency, we only pass through the vision_model's forward the real images by
+ discarding the padding images i.e. pixel_values of size (image_batch_size, 3, height, width) where
+ image_batch_size would be 7 when num_images_per_sample=[1, 3, 1, 2] and max_num_images would be 3.
+ """
+ )
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_attention_mask: Optional[torch.BoolTensor] = None,
+ image_hidden_states: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Union[tuple, SmolVLMBaseModelOutputWithPast]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if self.training and self.text_model.gradient_checkpointing and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None:
+ batch_size, seq_length = input_ids.shape
+ elif inputs_embeds is not None:
+ batch_size, seq_length, _ = inputs_embeds.shape
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache(config=self.config)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.text_model.get_input_embeddings()(input_ids).to(input_ids.device)
+
+ # START VISUAL INPUTS INTEGRATION
+ if pixel_values is not None and image_hidden_states is not None:
+ raise ValueError("You cannot specify both pixel_values and image_hidden_states at the same time")
+
+ if pixel_values is not None:
+ image_hidden_states = self.get_image_features(pixel_values, pixel_attention_mask).to(inputs_embeds.device)
+ elif image_hidden_states is not None:
+ image_hidden_states = image_hidden_states.to(dtype=self.dtype, device=inputs_embeds.device)
+
+ if image_hidden_states is not None:
+ # When we generate, we don't want to replace the potential image_token_id that we generated by images
+ # that simply don't exist
+ inputs_embeds = self.inputs_merger(
+ input_ids=input_ids,
+ inputs_embeds=inputs_embeds,
+ image_hidden_states=image_hidden_states,
+ )
+
+ outputs = self.text_model(
+ inputs_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ return SmolVLMBaseModelOutputWithPast(
+ last_hidden_state=outputs.last_hidden_state,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=image_hidden_states,
+ )
+
+
+class SmolVLMForConditionalGeneration(Idefics3ForConditionalGeneration):
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = SmolVLMModel(config)
+ self.model.text_model.generation_config = GenerationConfig.from_model_config(config)
+ self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False)
+ self.post_init()
+
+ def forward(self, **super_kwargs):
+ r"""
+ pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*):
+ Mask to avoid performing attention on padding pixel indices.
+ image_hidden_states (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`):
+ The hidden states of the image encoder after modality projection.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or `model.image_token_id`. Tokens with indices set to `model.image_token_id` are
+ ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> import requests
+ >>> import torch
+ >>> from PIL import Image
+ >>> from io import BytesIO
+
+ >>> from transformers import AutoProcessor, AutoModelForImageTextToText
+ >>> from transformers.image_utils import load_image
+
+ >>> # Note that passing the image urls (instead of the actual pil images) to the processor is also possible
+ >>> image1 = load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg")
+ >>> image2 = load_image("https://cdn.britannica.com/59/94459-050-DBA42467/Skyline-Chicago.jpg")
+ >>> image3 = load_image("https://cdn.britannica.com/68/170868-050-8DDE8263/Golden-Gate-Bridge-San-Francisco.jpg")
+
+ >>> processor = AutoProcessor.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct")
+ >>> model = AutoModelForImageTextToText.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct", dtype=torch.bfloat16, device_map="auto")
+
+ >>> # Create inputs
+ >>> messages = [
+ ... {
+ ... "role": "user",
+ ... "content": [
+ ... {"type": "video", "path": path/to/video},
+ ... {"type": "text", "text": "What is happening in this video?"},
+ ... ]
+ ... }
+ ... ]
+
+ >>> inputs = processor.apply_chat_template([messages], add_generation_prompt=True)
+
+ >>> # Generate
+ >>> generated_ids = model.generate(**inputs, max_new_tokens=256)
+ >>> generated_texts = processor.batch_decode(generated_ids, skip_special_tokens=True)
+
+ >>> print(generated_texts)
+ ```"""
+ super().forward(**super_kwargs)
+
+
+__all__ = [
+ "SmolVLMVisionConfig",
+ "SmolVLMConfig",
+ "SmolVLMImageProcessor",
+ "SmolVLMImageProcessorFast",
+ "SmolVLMForConditionalGeneration",
+ "SmolVLMPreTrainedModel",
+ "SmolVLMModel",
+ "SmolVLMVisionTransformer",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/processing_smolvlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/processing_smolvlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..59dc75114b9880a27924572eba78f2d4f9bfd494
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/processing_smolvlm.py
@@ -0,0 +1,423 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Processor class for SmolVLM.
+"""
+
+from datetime import timedelta
+from typing import TYPE_CHECKING, Optional, Union
+
+from ...feature_extraction_utils import BatchFeature
+from ...image_utils import ImageInput, make_nested_list_of_images
+from ...processing_utils import AllKwargsForChatTemplate, ImagesKwargs, ProcessingKwargs, ProcessorMixin, Unpack
+from ...tokenization_utils_base import BatchEncoding, TextInput
+from ...utils import is_num2words_available, is_vision_available, logging
+from ...video_utils import VideoInput
+
+
+if is_vision_available():
+ from .video_processing_smolvlm import (
+ DEFAULT_MEDIA_OUTTRO,
+ DEFAULT_VIDEO_INTRO,
+ FRAME_TIMESTAMP_MESSAGE,
+ )
+
+if is_vision_available():
+ from .video_processing_smolvlm import (
+ DEFAULT_MEDIA_OUTTRO,
+ DEFAULT_VIDEO_INTRO,
+ FRAME_TIMESTAMP_MESSAGE,
+ )
+
+if TYPE_CHECKING:
+ from ...tokenization_utils_base import PreTokenizedInput
+
+logger = logging.get_logger(__name__)
+
+
+if is_num2words_available():
+ from num2words import num2words
+else:
+ num2words = None
+
+
+# The correct chat template to be used for videos after #38105
+DEFAULT_CHAT_TEMPLATE = "<|im_start|>{% for message in messages %}{{message['role'] | capitalize}}{% if message['content'][0]['type'] == 'image' %}{{':'}}{% else %}{{': '}}{% endif %}{% for line in message['content'] %}{% if line['type'] == 'text' %}{{line['text']}}{% elif line['type'] == 'image' %}{{ '' }}{% elif line['type'] == 'video' %}{{ '' }}{% endif %}{% endfor %}\n{% endfor %}{% if add_generation_prompt %}{{ 'Assistant:' }}{% endif %}"
+
+
+def _prompt_split_image(
+ image_seq_len, image_rows, image_cols, fake_token_around_image, image_token, global_image_token
+):
+ """Prompt with expanded image tokens for when the image is split into patches."""
+ text_split_images = ""
+ for n_h in range(image_rows):
+ for n_w in range(image_cols):
+ text_split_images += (
+ f"{fake_token_around_image}" + f"" + f"{image_token}" * image_seq_len
+ )
+ text_split_images += "\n"
+
+ text_split_images += (
+ f"\n{fake_token_around_image}"
+ + f"{global_image_token}"
+ + f"{image_token}" * image_seq_len
+ + f"{fake_token_around_image}"
+ )
+ return text_split_images
+
+
+def _prompt_single_image(image_seq_len, fake_token_around_image, image_token, global_image_token):
+ """Prompt with expanded image tokens for a single image."""
+ return (
+ f"{fake_token_around_image}"
+ + f"{global_image_token}"
+ + f"{image_token}" * image_seq_len
+ + f"{fake_token_around_image}"
+ )
+
+
+def get_image_prompt_string(
+ image_rows, image_cols, image_seq_len, fake_token_around_image, image_token, global_image_token
+):
+ if image_rows == 0 and image_cols == 0:
+ return _prompt_single_image(
+ image_seq_len,
+ fake_token_around_image=fake_token_around_image,
+ image_token=image_token,
+ global_image_token=global_image_token,
+ )
+ return _prompt_split_image(
+ image_seq_len, image_rows, image_cols, fake_token_around_image, image_token, global_image_token
+ )
+
+
+class SmolVLMImagesKwargs(ImagesKwargs, total=False):
+ return_row_col_info: Optional[bool]
+ max_image_size: Optional[dict[str, int]]
+
+
+class SmolVLMProcessorKwargs(ProcessingKwargs, total=False):
+ images_kwargs: SmolVLMImagesKwargs
+
+ _defaults = {
+ "text_kwargs": {
+ "add_special_tokens": True,
+ "padding": False,
+ "is_split_into_words": False,
+ },
+ "images_kwargs": {
+ "return_row_col_info": True,
+ },
+ "videos_kwargs": {
+ "return_metadata": True,
+ },
+ }
+
+
+class SmolVLMProcessor(ProcessorMixin):
+ r"""
+ Constructs a SmolVLM processor which wraps a LLama tokenizer and SmolVLM image processor into a single processor.
+
+ [`SmolVLMProcessor`] offers all the functionalities of [`SmolVLMImageProcessor`] and [`SmolVLMTokenizerFast`]. See
+ the docstring of [`~IdeficsProcessor.__call__`] and [`~IdeficsProcessor.decode`] for more information.
+
+ Args:
+ image_processor (`SmolVLMImageProcessor`):
+ An instance of [`SmolVLMImageProcessor`]. The image processor is a required input.
+ tokenizer (`PreTrainedTokenizerBase`):
+ An instance of [`PreTrainedTokenizerBase`]. This should correspond with the model's text model. The tokenizer is a required input.
+ video_processor (`SmolVLMImageProcessor`):
+ n instance of [`SmolVLMImageProcessor`]. The video processor is a required input.
+ image_seq_len (`int`, *optional*, defaults to 169):
+ The length of the image sequence i.e. the number of tokens per image in the input.
+ This parameter is used to build the string from the input prompt and image tokens and should match the
+ value the model used. It is computed as: image_seq_len = int(((image_size // patch_size) ** 2) / (scale_factor**2))
+ chat_template (`str`, *optional*): A Jinja template which will be used to convert lists of messages
+ in a chat into a tokenizable string.
+ """
+
+ attributes = ["image_processor", "tokenizer", "video_processor"]
+ image_processor_class = "SmolVLMImageProcessor"
+ video_processor_class = "SmolVLMVideoProcessor" # NOTE: uses different interpolation than slow processors
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(
+ self,
+ image_processor,
+ tokenizer,
+ video_processor,
+ image_seq_len: int = 169,
+ chat_template: Optional[str] = None,
+ **kwargs,
+ ):
+ self.fake_image_token = getattr(tokenizer, "fake_image_token", "")
+ self.image_token = getattr(tokenizer, "image_token", "")
+ self.image_token_id = tokenizer.convert_tokens_to_ids(self.image_token)
+ self.end_of_utterance_token = getattr(tokenizer, "end_of_utterance_token", "")
+ self.global_image_token = getattr(tokenizer, "global_image_token", "")
+ self.image_seq_len = image_seq_len
+ self.video_token = getattr(tokenizer, "video_token", "")
+
+ if not num2words:
+ raise ImportError(
+ "Package `num2words` is required to run SmolVLM processor. Install it with `pip install num2words`."
+ )
+
+ super().__init__(image_processor, tokenizer, video_processor, chat_template=chat_template, **kwargs)
+
+ def expand_text_with_image_tokens(self, text, image_rows, image_cols):
+ prompt_strings = []
+ image_rows = image_rows if image_rows is not None else [[0] * len(text)]
+ image_cols = image_cols if image_cols is not None else [[0] * len(text)]
+ for sample, sample_rows, sample_cols in zip(text, image_rows, image_cols):
+ # Replace the image token with fake tokens around the expanded image token sequence of length `image_seq_len`
+ image_prompt_strings = []
+ for n_rows, n_cols in zip(sample_rows, sample_cols):
+ image_prompt_string = get_image_prompt_string(
+ n_rows,
+ n_cols,
+ self.image_seq_len,
+ image_token=self.image_token,
+ fake_token_around_image=self.fake_image_token,
+ global_image_token=self.global_image_token,
+ )
+ image_prompt_strings.append(image_prompt_string)
+
+ split_sample = sample.split(self.image_token)
+ if len(split_sample) == 0:
+ raise ValueError("The image token should be present in the text.")
+
+ # Place in the image prompt strings where the image tokens are
+ sample = split_sample[0]
+ for i, image_prompt_string in enumerate(image_prompt_strings):
+ sample += image_prompt_string + split_sample[i + 1]
+ prompt_strings.append(sample)
+
+ return prompt_strings
+
+ def expand_text_with_video_tokens(self, text, video_inputs):
+ num_frames = video_inputs["pixel_values"].shape[1]
+ video_metadata = iter(video_inputs["video_metadata"])
+
+ prompt_strings = []
+ for sample in text:
+ while self.video_token in sample:
+ metadata = next(video_metadata)
+ if metadata.fps is None:
+ logger.warning_once(
+ "SmolVLM requires frame timestamps to construct prompts, but the `fps` of the input video could not be inferred. "
+ "Probably `video_metadata` was missing from inputs and you passed pre-sampled frames. "
+ "Defaulting to `fps=24`. Please provide `video_metadata` for more accurate results."
+ )
+ metadata.fps = 24 # Set the default fps to 24 for BC, otherwise `timestamps` can't be inferred
+ timestamps = [(int(second // 60), int(second % 60)) for second in metadata.timestamps]
+ duration = int(metadata.duration) if metadata.duration is not None else int(metadata.timestamps[-1])
+ duration_td = timedelta(seconds=int(duration))
+ image_prompt_strings = DEFAULT_VIDEO_INTRO.format(
+ frame_count=num2words(num_frames), video_duration=str(duration_td)
+ )
+ for timestamp in timestamps:
+ image_prompt_string = _prompt_single_image(
+ self.image_seq_len,
+ image_token=self.image_token,
+ fake_token_around_image=self.fake_image_token,
+ global_image_token=self.global_image_token,
+ )
+ timestamp = f"{timestamp[0]:02d}:{timestamp[1]:02d}"
+ image_prompt_string = FRAME_TIMESTAMP_MESSAGE.format(timestamp=timestamp) + image_prompt_string
+ image_prompt_strings += image_prompt_string
+
+ image_prompt_strings += DEFAULT_MEDIA_OUTTRO
+ sample = sample.replace(self.video_token, image_prompt_strings, 1)
+ prompt_strings.append(sample)
+ return prompt_strings
+
+ def __call__(
+ self,
+ images: Union[ImageInput, list[ImageInput], list[list[ImageInput]]] = None,
+ text: Union[TextInput, "PreTokenizedInput", list[TextInput], list["PreTokenizedInput"]] = None,
+ audio=None,
+ videos: VideoInput = None,
+ **kwargs: Unpack[SmolVLMProcessorKwargs],
+ ) -> BatchEncoding:
+ """
+ Processes the input prompts and returns a BatchEncoding.
+
+ Example:
+
+ ```python
+ >>> import requests
+ >>> from transformers import SmolVLMProcessor
+ >>> from transformers.image_utils import load_image
+
+ >>> processor = SmolVLMProcessor.from_pretrained("HuggingFaceM4/SmolVLM2-256M-Video-Instruct")
+ >>> processor.image_processor.do_image_splitting = False # Force as False to simplify the example
+
+ >>> url1 = "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"
+ >>> url2 = "https://cdn.britannica.com/59/94459-050-DBA42467/Skyline-Chicago.jpg"
+
+ >>> image1, image2 = load_image(url1), load_image(url2)
+ >>> images = [[image1], [image2]]
+
+ >>> text = [
+ ... "In this image, we see",
+ ... "bla bla bla",
+ ... ]
+ >>> outputs = processor(images=images, text=text, return_tensors="pt", padding=True)
+ >>> input_ids = outputs.input_ids
+ >>> input_tokens = processor.tokenizer.batch_decode(input_ids)
+ >>> print(input_tokens)
+ ['<|begin_of_text|>(()*169) In this image, we see', '<|reserved_special_token_0|><|reserved_special_token_0|><|reserved_special_token_0|><|begin_of_text|>bla bla bla(()*169)']
+ ```
+
+ Args:
+ images (`PIL.Image.Image`, `np.ndarray`, `torch.Tensor`, `list[PIL.Image.Image]`, `list[np.ndarray]`, `list[torch.Tensor]`, *optional*):
+ The image or batch of images to be prepared. Each image can be a PIL image, NumPy array or PyTorch
+ tensor. If is of type `list[ImageInput]`, it's assumed that this is for a single prompt i.e. of batch size 1.
+ text (`Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]]`, *optional*):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ Wherever an image token, `` is encountered it is expanded to
+ `` + `` + `` * `image_seq_len` * `.
+ videos (`list[PIL.Image.Image]`, `np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, `list[torch.Tensor]`, *optional*):
+ The video or batch of videos to be prepared. Each video can be a list of PIL frames, NumPy array or PyTorch
+ tensor. If is of type `list[VideoInput]`, it's assumed that this is for a single prompt i.e. of batch size 1.
+ return_tensors (`Union[str, TensorType]`, *optional*):
+ If set, will return tensors of a particular framework. See [`PreTrainedTokenizerFast.__call__`] for more
+ information.
+ """
+ if text is None and images is None and videos is None:
+ raise ValueError("You must provide one of `text`, `images` or `videos'.")
+
+ if text is None and ((images is None) ^ (videos is not None)):
+ raise ValueError("You must specify exactly one of `images` or `videos`")
+
+ output_kwargs = self._merge_kwargs(
+ SmolVLMProcessorKwargs,
+ tokenizer_init_kwargs=self.tokenizer.init_kwargs,
+ **kwargs,
+ )
+
+ if text is not None:
+ if isinstance(text, str):
+ text = [text]
+ elif not isinstance(text, list) and not isinstance(text[0], str):
+ raise ValueError("Invalid input text. Please provide a string, or a list of strings")
+ n_images_in_text = sum([sample.count(self.image_token) for sample in text])
+ if n_images_in_text > 0 and (images is None and videos is None):
+ raise ValueError(f"We detected {n_images_in_text} tokens in the text but no images/videos were passed")
+
+ inputs = {}
+ # Images and videos are mutually exclusive, so process one which is present
+ if images is not None:
+ images = self.image_processor.fetch_images(images)
+ images = make_nested_list_of_images(images)
+ vision_inputs = self.image_processor(images, **output_kwargs["images_kwargs"])
+
+ image_rows = vision_inputs.pop("rows", None)
+ image_cols = vision_inputs.pop("cols", None)
+ inputs.update(vision_inputs)
+
+ if text is not None:
+ n_images_in_text = [sample.count(self.image_token) for sample in text]
+ n_images_in_images = [len(sublist) for sublist in images]
+ if n_images_in_images != n_images_in_text:
+ raise ValueError(
+ f"The number of images in the text {n_images_in_text} and images {n_images_in_images} should be the same."
+ )
+ text = self.expand_text_with_image_tokens(text, image_rows=image_rows, image_cols=image_cols)
+
+ elif videos is not None:
+ vision_inputs = self.video_processor(videos, **output_kwargs["videos_kwargs"])
+ if text is not None:
+ n_videos_in_text = [sample.count(self.video_token) for sample in text]
+ n_videos_in_videos = [len(sublist) for sublist in videos]
+ if n_videos_in_videos != n_videos_in_text:
+ raise ValueError(
+ f"The number of videos in the text {n_videos_in_text} and videos {n_videos_in_videos} should be the same."
+ )
+ text = self.expand_text_with_video_tokens(text, vision_inputs)
+
+ # If user has not requested video metadata, pop it. By default metadata
+ # is always returned to expand video tokens correctly
+ if "return_metadata" not in kwargs:
+ vision_inputs.pop("video_metadata")
+ inputs.update(vision_inputs)
+
+ return_tensors = output_kwargs["text_kwargs"].pop("return_tensors", None)
+
+ if text is not None:
+ text_inputs = self.tokenizer(text, **output_kwargs["text_kwargs"])
+ self._check_special_mm_tokens(text, text_inputs, modalities=["image"])
+ inputs.update(text_inputs)
+
+ return BatchFeature(inputs, tensor_type=return_tensors)
+
+ def apply_chat_template(
+ self,
+ conversation: Union[list[dict[str, str]], list[list[dict[str, str]]]],
+ chat_template: Optional[str] = None,
+ **kwargs: Unpack[AllKwargsForChatTemplate],
+ ) -> str:
+ """
+ Similar to the `apply_chat_template` method on tokenizers, this method applies a Jinja template to input
+ conversations to turn them into a single tokenizable string.
+
+ The input is expected to be in the following format, where each message content is a list consisting of text and
+ optionally image or video inputs. One can also provide an image, video, URL or local path which will be used to form
+ `pixel_values` when `return_dict=True`. If not provided, one will get only the formatted text, optionally tokenized text.
+
+ conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+ {"type": "text", "text": "Please describe this image in detail."},
+ ],
+ },
+ ]
+
+ Args:
+ conversation (`Union[list[Dict, [str, str]], list[list[dict[str, str]]]]`):
+ The conversation to format.
+ chat_template (`Optional[str]`, *optional*):
+ The Jinja template to use for formatting the conversation. If not provided, the tokenizer's
+ chat template is used.
+ """
+ if isinstance(conversation, (list, tuple)) and (
+ isinstance(conversation[0], (list, tuple)) or hasattr(conversation[0], "content")
+ ):
+ conversations = conversation
+ else:
+ conversations = [conversation]
+
+ has_video = any(
+ (isinstance(content, dict) and content["type"] == "video")
+ for conversation in conversations
+ for message in conversation
+ for content in message["content"]
+ )
+ if chat_template is None and has_video:
+ # re-assign to the correct default template for BC, if user is not requesting their own template
+ chat_template = DEFAULT_CHAT_TEMPLATE
+
+ kwargs.setdefault("num_frames", self.video_processor.num_frames)
+ kwargs.setdefault("fps", self.video_processor.fps)
+
+ return super().apply_chat_template(conversation, chat_template, **kwargs)
+
+
+__all__ = ["SmolVLMProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/video_processing_smolvlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/video_processing_smolvlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..020f2d4c8e93144b12952e60f8ab7b1f73933204
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/smolvlm/video_processing_smolvlm.py
@@ -0,0 +1,377 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import (
+ BatchFeature,
+ get_size_dict,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ SizeDict,
+)
+from ...processing_utils import Unpack, VideosKwargs
+from ...utils import (
+ TensorType,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+ is_vision_available,
+)
+from ...utils.import_utils import requires
+from ...video_processing_utils import (
+ BaseVideoProcessor,
+)
+from ...video_utils import VideoMetadata, group_videos_by_shape, reorder_videos
+
+
+if is_vision_available():
+ from ...image_utils import PILImageResampling
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+
+if is_torch_available():
+ import torch
+
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+DEFAULT_SYSTEM_MESSAGE = "You are a helpful language and vision assistant. You are able to understand the visual content that the user provides, and assist the user with a variety of tasks using natural language."
+DEFAULT_VIDEO_INTRO = (
+ "You are provided the following series of {frame_count} frames from a {video_duration} [H:MM:SS] video.\n"
+)
+DEFAULT_MEDIA_OUTTRO = "\n\n"
+FRAME_TIMESTAMP_MESSAGE = "\nFrame from {timestamp}:"
+MAX_IMAGE_SIZE = 4096 # 4k resolution as absolute maximum
+
+
+def get_max_height_width(videos: list["torch.Tensor"]) -> list[int]:
+ """
+ Get the maximum height and width across all videos in a batch.
+ """
+ max_height = max_width = float("-inf")
+ for video in videos:
+ height, width = video.size()[-2:]
+ max_height = max(height, max_height)
+ max_width = max(width, max_width)
+ return (max_height, max_width)
+
+
+def get_resize_output_image_size(
+ video,
+ resolution_max_side: int,
+) -> tuple[int, int]:
+ """
+ Get the output size of the video after resizing given a dictionary specifying the max and min sizes.
+ Args:
+ video (`np.ndarray`):
+ Video to resize.
+ resolution_max_side (`int`):
+ The longest edge of the video will be resized to this value. The shortest edge will be resized to keep the
+ input aspect ratio.
+ Returns:
+ The output size of the video after resizing.
+ """
+ height, width = video.size()[-2:]
+
+ # Find the output size, when rescaling the longest edge to max_len and preserving the aspect ratio
+ # The output size must be below the MAX_IMAGE_SIZE
+ resolution_max_side = min(MAX_IMAGE_SIZE, resolution_max_side)
+ resolution_max_side = max(height, width) if resolution_max_side is None else resolution_max_side
+ aspect_ratio = width / height
+
+ if width >= height:
+ width = resolution_max_side
+ height = int(width / aspect_ratio)
+ if height % 2 != 0:
+ height += 1
+ elif height > width:
+ height = resolution_max_side
+ width = int(height * aspect_ratio)
+ if width % 2 != 0:
+ width += 1
+
+ height = max(height, 1)
+ width = max(width, 1)
+
+ return height, width
+
+
+class SmolVLMVideoProcessorInitKwargs(VideosKwargs):
+ max_image_size: dict[str, int] = None
+
+
+@requires(backends=("torchvision",))
+class SmolVLMVideoProcessor(BaseVideoProcessor):
+ resample = PILImageResampling.LANCZOS
+ size = {"longest_edge": 4 * 364}
+ max_image_size = {"longest_edge": 364}
+ image_mean = IMAGENET_STANDARD_MEAN
+ image_std = IMAGENET_STANDARD_STD
+ do_resize = True
+ do_rescale = True
+ do_normalize = True
+ do_convert_rgb = True
+ do_pad = True
+ do_sample_frames = False # Set to False for BC, recommended to set `True` in new models
+ valid_kwargs = SmolVLMVideoProcessorInitKwargs
+ model_input_names = ["pixel_values", "pixel_attention_mask"]
+
+ def __init__(self, **kwargs: Unpack[SmolVLMVideoProcessorInitKwargs]):
+ super().__init__(**kwargs)
+ # For BC pop values from `config.video_sampling`. In official config `video_sampling` is guaranteed to be present
+ # We check for `Noneness` only for certain tests such as `test_init_without_params`
+ if "size" in kwargs and "video_sampling" in kwargs:
+ kwargs["video_sampling"]["video_size"] = kwargs["size"]
+
+ if "video_sampling" in kwargs:
+ self.num_frames = kwargs["video_sampling"]["max_frames"]
+ self.fps = kwargs["video_sampling"]["fps"]
+ self.size = get_size_dict(kwargs["video_sampling"]["video_size"], default_to_square=self.default_to_square)
+
+ def resize(
+ self,
+ video: "torch.Tensor",
+ size: SizeDict,
+ interpolation: "F.InterpolationMode" = None,
+ antialias: bool = True,
+ **kwargs,
+ ) -> "torch.Tensor":
+ """
+ Resize an video to `(size["height"], size["width"])`.
+ Args:
+ video (`torch.Tensor`):
+ Video to resize.
+ size (`SizeDict`):
+ Dictionary in the format `{"height": int, "width": int}` specifying the size of the output video.
+ resample (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`):
+ `InterpolationMode` filter to use when resizing the video e.g. `InterpolationMode.BICUBIC`.
+ Returns:
+ `torch.Tensor`: The resized video.
+ """
+ interpolation = interpolation if interpolation is not None else F.InterpolationMode.BILINEAR
+ if interpolation == F.InterpolationMode.LANCZOS:
+ logger.warning_once(
+ "You have used fast image processor with LANCZOS resample which not yet supported for torch.Tensor. "
+ "BICUBIC resample will be used as an alternative. Please fall back to image processor if you "
+ "want full consistency with the original model."
+ )
+ interpolation = F.InterpolationMode.BICUBIC
+
+ if size.longest_edge:
+ # Resize the image so that the shortest edge or the longest edge is of the given size
+ # while maintaining the aspect ratio of the original image.
+ new_size = get_resize_output_image_size(
+ video,
+ resolution_max_side=size.longest_edge,
+ )
+ elif size.height and size.width:
+ new_size = (size.height, size.width)
+ else:
+ raise ValueError(f"Size must contain 'height' and 'width' keys, or 'longest_edge' key. Got {size}.")
+
+ video = F.resize(video, new_size, interpolation=interpolation, antialias=antialias)
+
+ # Resize again to match image processor when `do_image_splitting=False`. Frames have to be squared to `max_image_size`
+ # NOTE: videos are always processoed without image splitting
+ max_size = self.max_image_size["longest_edge"], self.max_image_size["longest_edge"]
+ video = F.resize(video, max_size, interpolation=interpolation, antialias=antialias)
+ return video
+
+ def pad(
+ self,
+ video: "torch.Tensor",
+ padded_size: tuple[int, int],
+ max_num_frames: int,
+ fill: int = 0,
+ return_pixel_mask: bool = True,
+ ):
+ """Pads the sample with empty video to the padded_size
+ Args:
+ video (`torch.Tensor`):
+ Video to pad.
+ padded_size (`tuple[int, int]`):
+ Height and width to pad.
+ max_num_frames (`int`):
+ The maximum number of frames to which video will be padded.
+ fill (`int`, *optional*):
+ The value to use for the padding.
+ return_pixel_mask (`bool`, *optional*, defaults to `True`):
+ Whether to return a pixel mask.
+ """
+ original_size = video.size()[-2:]
+ padding_height = padded_size[0] - original_size[0]
+ padding_width = padded_size[1] - original_size[1]
+ padding_frame = max_num_frames - video.shape[0]
+ if padding_width < 0 or padding_height < 0:
+ raise ValueError(
+ f"Padding dimensions are negative. Please make sure that the padded size is larger than the "
+ f"original size. Got padded size: {padded_size}, original size: {original_size}."
+ )
+ if original_size != padded_size:
+ padding = [0, padding_width, 0, padding_height, 0, 0, 0, padding_frame]
+ video = F.pad(video, padding, fill=fill)
+
+ # Make a pixel mask for the video, where 1 indicates a valid pixel and 0 indicates padding.
+ # Mask shape is (num_frames, height, width) so we omit the channel dim
+ pixel_mask = None
+ if return_pixel_mask:
+ pixel_mask = torch.zeros_like(video[..., 0, :, :], dtype=torch.int64)
+ pixel_mask[..., : original_size[0], : original_size[1]] = 1
+
+ return video, pixel_mask
+
+ def sample_frames(
+ self,
+ metadata: VideoMetadata,
+ num_frames: Optional[int] = None,
+ fps: Optional[Union[int, float]] = None,
+ skip_secs: Optional[int] = 1,
+ **kwargs,
+ ):
+ """
+ Video sampling function which:
+ - Uses `num_frames` (if provided) or calculates it from `fps` and metadata.
+ - Applies a basic center-skip if fewer frames than available, otherwise
+ optionally skips `skip_secs` from both the start and end.
+ - Uniformly samples the desired number of frames between the start and end indices.
+
+ Args:
+ metadata (`VideoMetadata`):
+ Metadata of the video containing information about total duration, fps and total number of frames.
+ num_frames (`int`, *optional*):
+ Maximum number of frames to sample. Defaults to `self.num_frames`.
+ fps (`int` or `float`, *optional*):
+ Target frames to sample per second. Defaults to `self.fps`.
+ skip_secs (`float`, *optional*, defaults to `1`):
+ Number of seconds to skip from the start and end if the video is long enough.
+
+ Returns:
+ np.ndarray:
+ Indices to sample video frames.
+ """
+ if metadata is None or getattr(metadata, "fps", None) is None:
+ raise ValueError(
+ "Asked to sample frames per second but no video metadata was provided which is required when sampling in SmolVLM. "
+ "Please pass in `VideoMetadata` object or set `do_sample_frames=False`"
+ )
+
+ num_frames = num_frames if num_frames is not None else self.num_frames
+ fps = fps if fps is not None else self.fps
+ total_num_frames = metadata.total_num_frames
+
+ # Step 1) Estimate how many frames we'd sample at `target_fps`, fallback if target_fps <= 0
+ estimated_frames = int(round(fps * metadata["duration"]))
+
+ # Step 2) desired_frames
+ desired_frames = min(estimated_frames, num_frames)
+ if desired_frames < 1:
+ desired_frames = 1
+
+ # Step 3) center skip logic
+ start_idx = 0
+ end_idx = total_num_frames - 1
+
+ if skip_secs > 0 and (metadata["duration"] - 2 * skip_secs) > (num_frames * fps):
+ start_idx = int(skip_secs * metadata["fps"])
+ end_idx = int(total_num_frames - skip_secs * metadata["fps"])
+
+ start_idx = max(0, start_idx)
+ end_idx = min(end_idx, total_num_frames - 1)
+ if start_idx >= end_idx:
+ start_idx, end_idx = 0, total_num_frames - 1
+
+ indices = np.linspace(start_idx, end_idx, desired_frames, dtype=int)
+ indices = np.unique(indices)
+
+ return indices
+
+ def _preprocess(
+ self,
+ videos: list["torch.Tensor"],
+ do_convert_rgb: bool,
+ do_resize: bool,
+ size: SizeDict,
+ interpolation: Optional["F.InterpolationMode"],
+ do_rescale: bool,
+ rescale_factor: float,
+ do_normalize: bool,
+ do_pad: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ):
+ grouped_videos, grouped_videos_index = group_videos_by_shape(videos)
+ resized_videos_grouped = {}
+ for shape, stacked_videos in grouped_videos.items():
+ if do_convert_rgb:
+ stacked_videos = self.convert_to_rgb(stacked_videos)
+ if do_resize:
+ stacked_videos = self.resize(stacked_videos, size=size, interpolation=interpolation)
+ resized_videos_grouped[shape] = stacked_videos
+ resized_videos = reorder_videos(resized_videos_grouped, grouped_videos_index)
+
+ grouped_videos, grouped_videos_index = group_videos_by_shape(resized_videos)
+ processed_videos_grouped = {}
+ for shape, stacked_videos in grouped_videos.items():
+ stacked_videos = self.rescale_and_normalize(
+ stacked_videos, do_rescale, rescale_factor, do_normalize, image_mean, image_std
+ )
+ processed_videos_grouped[shape] = stacked_videos
+
+ processed_videos = reorder_videos(processed_videos_grouped, grouped_videos_index)
+
+ if do_pad:
+ pad_size = get_max_height_width(processed_videos)
+ max_num_frames = max(len(video) for video in processed_videos)
+ grouped_videos, grouped_videos_index = group_videos_by_shape(processed_videos)
+ processed_padded_mask_grouped = {}
+ processed_videos_grouped = {}
+
+ for shape, stacked_videos in grouped_videos.items():
+ stacked_videos, padded_masks = self.pad(
+ stacked_videos, padded_size=pad_size, max_num_frames=max_num_frames
+ )
+ processed_videos_grouped[shape] = stacked_videos
+ processed_padded_mask_grouped[shape] = padded_masks
+
+ processed_videos = reorder_videos(processed_videos_grouped, grouped_videos_index)
+ pixel_attention_mask = reorder_videos(processed_padded_mask_grouped, grouped_videos_index)
+
+ processed_videos = torch.stack(processed_videos, dim=0) if return_tensors else processed_videos
+ data = {"pixel_values": processed_videos}
+
+ if do_pad:
+ data["pixel_attention_mask"] = (
+ torch.stack(pixel_attention_mask, dim=0)
+ if do_pad and return_tensors is not None
+ else pixel_attention_mask
+ )
+ return BatchFeature(data, tensor_type=return_tensors)
+
+
+__all__ = ["SmolVLMVideoProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..4e07844d45c2d0f3c5bfba69b330c3beede0eab1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_speech_encoder_decoder import *
+ from .modeling_flax_speech_encoder_decoder import *
+ from .modeling_speech_encoder_decoder import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/configuration_speech_encoder_decoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/configuration_speech_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..63e161fcbe74775fcfd8ab6dee18f664ca694194
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/configuration_speech_encoder_decoder.py
@@ -0,0 +1,112 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ..auto.configuration_auto import AutoConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class SpeechEncoderDecoderConfig(PretrainedConfig):
+ r"""
+ [`SpeechEncoderDecoderConfig`] is the configuration class to store the configuration of a
+ [`SpeechEncoderDecoderModel`]. It is used to instantiate an Encoder Decoder model according to the specified
+ arguments, defining the encoder and decoder configs.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ kwargs (*optional*):
+ Dictionary of keyword arguments. Notably:
+
+ - **encoder** ([`PretrainedConfig`], *optional*) -- An instance of a configuration object that defines
+ the encoder config.
+ - **decoder** ([`PretrainedConfig`], *optional*) -- An instance of a configuration object that defines
+ the decoder config.
+
+ Examples:
+
+ ```python
+ >>> from transformers import BertConfig, Wav2Vec2Config, SpeechEncoderDecoderConfig, SpeechEncoderDecoderModel
+
+ >>> # Initializing a Wav2Vec2 & BERT style configuration
+ >>> config_encoder = Wav2Vec2Config()
+ >>> config_decoder = BertConfig()
+
+ >>> config = SpeechEncoderDecoderConfig.from_encoder_decoder_configs(config_encoder, config_decoder)
+
+ >>> # Initializing a Wav2Vec2Bert model from a Wav2Vec2 & google-bert/bert-base-uncased style configurations
+ >>> model = SpeechEncoderDecoderModel(config=config)
+
+ >>> # Accessing the model configuration
+ >>> config_encoder = model.config.encoder
+ >>> config_decoder = model.config.decoder
+ >>> # set decoder config to causal lm
+ >>> config_decoder.is_decoder = True
+ >>> config_decoder.add_cross_attention = True
+
+ >>> # Saving the model, including its configuration
+ >>> model.save_pretrained("my-model")
+
+ >>> # loading model and config from pretrained folder
+ >>> encoder_decoder_config = SpeechEncoderDecoderConfig.from_pretrained("my-model")
+ >>> model = SpeechEncoderDecoderModel.from_pretrained("my-model", config=encoder_decoder_config)
+ ```"""
+
+ model_type = "speech-encoder-decoder"
+ sub_configs = {"encoder": AutoConfig, "decoder": AutoConfig}
+ has_no_defaults_at_init = True
+
+ def __init__(self, **kwargs):
+ super().__init__(**kwargs)
+ if "encoder" not in kwargs or "decoder" not in kwargs:
+ raise ValueError(
+ f"A configuration of type {self.model_type} cannot be instantiated because not both `encoder` and"
+ f" `decoder` sub-configurations are passed, but only {kwargs}"
+ )
+
+ encoder_config = kwargs.pop("encoder")
+ encoder_model_type = encoder_config.pop("model_type")
+ decoder_config = kwargs.pop("decoder")
+ decoder_model_type = decoder_config.pop("model_type")
+
+ self.encoder = AutoConfig.for_model(encoder_model_type, **encoder_config)
+ self.decoder = AutoConfig.for_model(decoder_model_type, **decoder_config)
+ self.is_encoder_decoder = True
+
+ @classmethod
+ def from_encoder_decoder_configs(
+ cls, encoder_config: PretrainedConfig, decoder_config: PretrainedConfig, **kwargs
+ ) -> PretrainedConfig:
+ r"""
+ Instantiate a [`SpeechEncoderDecoderConfig`] (or a derived class) from a pre-trained encoder model
+ configuration and decoder model configuration.
+
+ Returns:
+ [`SpeechEncoderDecoderConfig`]: An instance of a configuration object
+ """
+ logger.info("Setting `config.is_decoder=True` and `config.add_cross_attention=True` for decoder_config")
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ return cls(encoder=encoder_config.to_dict(), decoder=decoder_config.to_dict(), **kwargs)
+
+
+__all__ = ["SpeechEncoderDecoderConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/modeling_flax_speech_encoder_decoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/modeling_flax_speech_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..3614c5d4981b4e010f9ba7732ad537865357046d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/modeling_flax_speech_encoder_decoder.py
@@ -0,0 +1,930 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Classes to support Flax Speech-Encoder-Decoder architectures"""
+
+import os
+from typing import Optional, Union
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.traverse_util import flatten_dict, unflatten_dict
+from jax import lax
+from jax.random import PRNGKey
+
+from ...modeling_flax_outputs import FlaxBaseModelOutput, FlaxCausalLMOutputWithCrossAttentions, FlaxSeq2SeqLMOutput
+from ...modeling_flax_utils import FlaxPreTrainedModel
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging, replace_return_docstrings
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_flax_auto import FlaxAutoModel, FlaxAutoModelForCausalLM
+from .configuration_speech_encoder_decoder import SpeechEncoderDecoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "SpeechEncoderDecoderConfig"
+
+SPEECH_ENCODER_DECODER_START_DOCSTRING = r"""
+ This class can be used to initialize a speech-sequence-to-text-sequence model with any pretrained speech
+ autoencoding model as the encoder and any pretrained text autoregressive model as the decoder. The encoder is
+ loaded via [`~AutoModel.from_pretrained`] function and the decoder is loaded via
+ [`~AutoModelForCausalLM.from_pretrained`] function. Cross-attention layers are automatically added to the decoder
+ and should be fine-tuned on a downstream generative task, like summarization.
+
+ The effectiveness of initializing sequence-to-sequence models with pretrained checkpoints for sequence generation
+ tasks was shown in [Leveraging Pre-trained Checkpoints for Sequence Generation
+ Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn. Michael Matena, Yanqi
+ Zhou, Wei Li, Peter J. Liu.
+
+ Additionally, in [Large-Scale Self- and Semi-Supervised Learning for Speech
+ Translation](https://huggingface.co/papers/2104.06678) it is shown how leveraging large pretrained speech models for speech
+ translation yields a significant performance improvement.
+
+ After such an Speech-Encoder Decoder model has been trained/fine-tuned, it can be saved/loaded just like any other
+ models (see the examples for more information).
+
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a Flax Linen
+ [flax.nn.Module](https://flax.readthedocs.io/en/latest/_autosummary/flax.nn.module.html) subclass. Use it as a
+ regular Flax Module and refer to the Flax documentation for all matter related to general usage and behavior.
+
+ Parameters:
+ config ([`SpeechEncoderDecoderConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs).
+
+ This can be used to enable mixed-precision training or half-precision inference on GPUs or TPUs. If
+ specified all the computation will be performed with the given `dtype`.
+
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.**
+
+ If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`] and
+ [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+SPEECH_ENCODER_DECODER_INPUTS_DOCSTRING = r"""
+ Args:
+ inputs (`jnp.ndarray` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, feature_dim)`, *optional*):
+ Float values of input raw speech waveform or speech features. Values can be obtained by loading a `.flac`
+ or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.*
+ via the torchcodec library (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `inputs`, either the [`Wav2Vec2Processor`] or
+ [`Speech2TextProcessor`] should be used for padding and conversion into a tensor of type
+ `torch.FloatTensor`.
+ attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ decoder_input_ids (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ For sequence to sequence training, `decoder_input_ids` should be provided. `decoder_input_ids` should be
+ created outside of the model by shifting the `labels` to the right, replacing -100 by the `pad_token_id`
+ and prepending them with the `decoder_start_token_id`.
+ decoder_attention_mask (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_position_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the
+ range `[0, config.decoder.max_position_embeddings - 1]`.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ If set to `True`, the model will return a [`~utils.FlaxSeq2SeqLMOutput`] instead of a plain tuple.
+"""
+
+SPEECH_ENCODER_DECODER_ENCODE_INPUTS_DOCSTRING = r"""
+ Args:
+ inputs (`jnp.ndarray` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, feature_dim)`, *optional*):
+ Float values of input raw speech waveform or speech features. Values can be obtained by loading a *.flac*
+ or *.wav* audio file into an array of type *list[float]* or a *numpy.ndarray*, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into *inputs*, either the [`Wav2Vec2Processor`] or [`Speech2TextProcessor`] should be used
+ for padding and conversion into a tensor of type *torch.FloatTensor*.
+ attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ If set to `True`, the model will return a [`~utils.FlaxBaseModelOutput`] instead of a plain tuple.
+"""
+
+SPEECH_ENCODER_DECODER_DECODE_INPUTS_DOCSTRING = r"""
+ Args:
+ decoder_input_ids (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ For sequence to sequence training, `decoder_input_ids` should be provided. `decoder_input_ids` should be
+ created outside of the model by shifting the `labels` to the right, replacing -100 by the `pad_token_id`
+ and prepending them with the `decoder_start_token_id`.
+ encoder_outputs (`tuple(tuple(jnp.ndarray)`):
+ Tuple consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*: `attentions`)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ encoder_attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ decoder_attention_mask (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_position_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the
+ range `[0, config.decoder.max_position_embeddings - 1]`.
+ past_key_values (`dict[str, np.ndarray]`, *optional*, returned by `init_cache` or when passing previous `past_key_values`):
+ Dictionary of pre-computed hidden-states (key and values in the attention blocks) that can be used for fast
+ auto-regressive decoding. Pre-computed key and value hidden-states are of shape *[batch_size, max_length]*.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ If set to `True`, the model will return a [`~utils.FlaxCausalLMOutputWithCrossAttentions`] instead of a
+ plain tuple.
+"""
+
+
+class FlaxSpeechEncoderDecoderModule(nn.Module):
+ config: SpeechEncoderDecoderConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ encoder_config = self.config.encoder
+ decoder_config = self.config.decoder
+
+ # Copied from `modeling_hybrid_clip.py` with modifications.
+ from ...models.auto.modeling_flax_auto import FLAX_MODEL_FOR_CAUSAL_LM_MAPPING, FLAX_MODEL_MAPPING
+
+ encoder_module = FLAX_MODEL_MAPPING[encoder_config.__class__].module_class
+ decoder_module = FLAX_MODEL_FOR_CAUSAL_LM_MAPPING[decoder_config.__class__].module_class
+
+ self.encoder = encoder_module(encoder_config, dtype=self.dtype)
+ self.decoder = decoder_module(decoder_config, dtype=self.dtype)
+
+ # encoder outputs might need to be projected to different dimension for decoder
+ if (
+ self.encoder.config.hidden_size != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ self.enc_to_dec_proj = nn.Dense(
+ self.decoder.config.hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.decoder.config.initializer_range),
+ dtype=self.dtype,
+ )
+ else:
+ self.enc_to_dec_proj = None
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[jnp.ndarray, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.encoder.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size, stride in zip(self.config.encoder.conv_kernel, self.config.encoder.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.encoder.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.encoder.adapter_stride)
+
+ return input_lengths
+
+ def _get_encoder_module(self):
+ return self.encoder
+
+ def _get_projection_module(self):
+ return self.enc_to_dec_proj
+
+ def _get_decoder_module(self):
+ return self.decoder
+
+ def __call__(
+ self,
+ inputs,
+ attention_mask,
+ decoder_input_ids,
+ decoder_attention_mask,
+ decoder_position_ids,
+ encoder_outputs=None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ freeze_feature_encoder: bool = False,
+ ):
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ inputs,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ freeze_feature_encoder=freeze_feature_encoder,
+ )
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ # optionally project encoder_hidden_states
+ if self.enc_to_dec_proj is not None:
+ encoder_hidden_states = self.enc_to_dec_proj(encoder_hidden_states)
+
+ # compute correct encoder attention mask
+ if attention_mask is not None:
+ encoder_attention_mask = self.encoder._get_feature_vector_attention_mask(
+ encoder_hidden_states.shape[1], attention_mask
+ )
+ else:
+ encoder_attention_mask = None
+
+ # flax script modeling_flax_wav2vec2.py
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return FlaxSeq2SeqLMOutput(
+ logits=decoder_outputs.logits,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_hidden_states,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@add_start_docstrings(SPEECH_ENCODER_DECODER_START_DOCSTRING)
+class FlaxSpeechEncoderDecoderModel(FlaxPreTrainedModel):
+ r"""
+ [`FlaxSpeechEncoderDecoderModel`] is a generic model class that will be instantiated as a transformer architecture
+ with the module (flax.nn.Module) of one of the base model classes of the library as encoder module and another one
+ as decoder module when created with the :meth*~transformers.FlaxAutoModel.from_pretrained* class method for the
+ encoder and :meth*~transformers.FlaxAutoModelForCausalLM.from_pretrained* class method for the decoder.
+ """
+
+ config_class = SpeechEncoderDecoderConfig
+ base_model_prefix: str = "speech_encoder_decoder"
+ module_class = FlaxSpeechEncoderDecoderModule
+
+ def __init__(
+ self,
+ config: SpeechEncoderDecoderConfig,
+ input_shape: Optional[tuple] = None,
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ **kwargs,
+ ):
+ if not _do_init:
+ raise ValueError(
+ "`FlaxSpeechEncoderDecoderModel` cannot be created without initializing, `_do_init` must be `True`."
+ )
+
+ if config.decoder.cross_attention_hidden_size is not None:
+ # Raise ValueError or option to project enc to dec hidden_size (eg EncAdapterLayer)
+ if config.decoder.cross_attention_hidden_size != config.encoder.hidden_size:
+ raise ValueError(
+ "If `cross_attention_hidden_size` is specified in the decoder's configuration, it has to be equal"
+ f" to the encoder's `hidden_size`. Got {config.decoder.cross_attention_hidden_size} for"
+ f" `config.decoder.cross_attention_hidden_size` and {config.encoder.hidden_size} for"
+ " `config.encoder.hidden_size`."
+ )
+
+ # make sure input & output embeddings are not tied
+ config.tie_word_embeddings = False
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+
+ if input_shape is None:
+ # speech encoders almost always downsample the sequence length dimension
+ encoder_input_length = 1024
+ decoder_input_length = module._get_feat_extract_output_lengths(encoder_input_length)
+ input_shape = ((1, encoder_input_length), (1, decoder_input_length))
+
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ encoder_input_shape, decoder_input_shape = input_shape
+
+ # init input DeviceArrays
+ inputs = jnp.zeros(encoder_input_shape, dtype="f4")
+ attention_mask = jnp.ones_like(inputs, dtype="i4")
+ decoder_input_ids = jnp.zeros(decoder_input_shape, dtype="i4")
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+
+ batch_size, sequence_length = inputs.shape
+
+ decoder_batch_size, decoder_sequence_length = decoder_input_ids.shape
+ if not decoder_batch_size == batch_size:
+ raise ValueError(
+ f"The inputs of encoder and decoder should have the same batch size, but got {batch_size} for encoder"
+ f" and {decoder_batch_size} for decoder."
+ )
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(decoder_sequence_length)[None, :], (decoder_batch_size, decoder_sequence_length)
+ )
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(
+ rngs,
+ inputs,
+ attention_mask,
+ decoder_input_ids,
+ decoder_attention_mask,
+ decoder_position_ids,
+ )["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ def init_cache(self, batch_size, max_length, encoder_outputs):
+ r"""
+ Args:
+ batch_size (`int`):
+ batch_size used for fast auto-regressive decoding. Defines the batch size of the initialized cache.
+ max_length (`int`):
+ maximum possible length for auto-regressive decoding. Defines the sequence length of the initialized
+ cache.
+ encoder_outputs (`Union[FlaxBaseModelOutput, tuple(tuple(jnp.ndarray)]`):
+ `encoder_outputs` consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*:
+ `attentions`). `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*)
+ is a sequence of hidden-states at the output of the last layer of the encoder. Used in the
+ cross-attention of the decoder.
+ """
+ # init input variables to retrieve cache
+ decoder_input_ids = jnp.ones((batch_size, max_length), dtype="i4")
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(jnp.atleast_2d(decoder_input_ids).shape[-1]), decoder_input_ids.shape
+ )
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, decoder_position_ids, **kwargs):
+ decoder_module = module._get_decoder_module()
+ return decoder_module(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ **kwargs,
+ )
+
+ init_variables = self.module.init(
+ jax.random.PRNGKey(0),
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_hidden_states=encoder_outputs[0],
+ init_cache=True,
+ method=_decoder_forward, # we only need to call the decoder to init the cache
+ )
+ return unfreeze(init_variables["cache"])
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[jnp.ndarray, int], add_adapter: Optional[bool] = None
+ ):
+ return self.module._get_feat_extract_output_lengths(input_lengths, add_adapter=add_adapter)
+
+ @add_start_docstrings(SPEECH_ENCODER_DECODER_ENCODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxBaseModelOutput, config_class=_CONFIG_FOR_DOC)
+ def encode(
+ self,
+ inputs: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ freeze_feature_encoder: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import FlaxSpeechEncoderDecoderModel
+
+ >>> # initialize a wav2vec2-2-bart from pretrained wav2vec2 and bart models. Note that the cross-attention layers will be randomly initialized
+ >>> model = FlaxSpeechEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "facebook/wav2vec2-large-lv60", "facebook/bart-large"
+ ... )
+
+ >>> inputs = jnp.ones((2, 5000), dtype=jnp.float32)
+ >>> encoder_outputs = model.encode(inputs)
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(inputs, dtype="i4")
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _encoder_forward(module, inputs, attention_mask, **kwargs):
+ encode_module = module._get_encoder_module()
+ return encode_module(inputs, attention_mask, **kwargs)
+
+ outputs = self.module.apply(
+ {"params": params or self.params},
+ inputs=jnp.array(inputs, dtype="f4"),
+ attention_mask=jnp.array(attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ freeze_feature_encoder=freeze_feature_encoder,
+ rngs=rngs,
+ method=_encoder_forward,
+ )
+
+ if return_dict:
+ outputs = FlaxBaseModelOutput(
+ last_hidden_state=outputs.last_hidden_state,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ return outputs
+
+ @add_start_docstrings(SPEECH_ENCODER_DECODER_DECODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxCausalLMOutputWithCrossAttentions, config_class=_CONFIG_FOR_DOC)
+ def decode(
+ self,
+ decoder_input_ids,
+ encoder_outputs,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_position_ids: Optional[jnp.ndarray] = None,
+ past_key_values: Optional[dict] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import FlaxSpeechEncoderDecoderModel
+ >>> import jax.numpy as jnp
+
+ >>> # initialize a wav2vec2-2-bart from pretrained wav2vec2 and bart models. Note that the cross-attention layers will be randomly initialized
+ >>> model = FlaxSpeechEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "facebook/wav2vec2-large-lv60", "facebook/bart-large"
+ ... )
+
+ >>> inputs = jnp.ones((2, 5000), dtype=jnp.float32)
+ >>> encoder_outputs = model.encode(inputs)
+
+ >>> decoder_start_token_id = model.config.decoder.bos_token_id
+ >>> decoder_input_ids = jnp.ones((inputs.shape[0], 1), dtype="i4") * decoder_start_token_id
+
+ >>> outputs = model.decode(decoder_input_ids, encoder_outputs)
+ >>> logits = outputs.logits
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ encoder_hidden_states = encoder_outputs[0]
+ if encoder_attention_mask is None:
+ batch_size, sequence_length = encoder_hidden_states.shape[:2]
+ encoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ batch_size, sequence_length = decoder_input_ids.shape
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ if decoder_position_ids is None:
+ if past_key_values is not None:
+ raise ValueError("Make sure to provide `decoder_position_ids` when passing `past_key_values`.")
+
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(sequence_length)[None, :], (batch_size, sequence_length)
+ )
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ params = {"params": params or self.params}
+
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be
+ # passed down to ensure cache is used. It has to be made sure that cache is marked as mutable so that
+ # it can be changed by FlaxBartAttention module
+ if past_key_values:
+ params["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ def _decoder_forward(
+ module, decoder_input_ids, decoder_attention_mask, decoder_position_ids, encoder_hidden_states, **kwargs
+ ):
+ projection_module = module._get_projection_module()
+ decoder_module = module._get_decoder_module()
+
+ # optionally project encoder_hidden_states
+ if projection_module is not None:
+ encoder_hidden_states = projection_module(encoder_hidden_states)
+
+ return decoder_module(
+ decoder_input_ids,
+ decoder_attention_mask,
+ decoder_position_ids,
+ encoder_hidden_states=encoder_hidden_states,
+ **kwargs,
+ )
+
+ outputs = self.module.apply(
+ params,
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ decoder_position_ids=jnp.array(decoder_position_ids, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=jnp.array(encoder_attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ mutable=mutable,
+ method=_decoder_forward,
+ )
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs, past = outputs
+ outputs["past_key_values"] = unfreeze(past["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs, past = outputs
+ outputs = outputs[:1] + (unfreeze(past["cache"]),) + outputs[1:]
+
+ return outputs
+
+ @add_start_docstrings_to_model_forward(SPEECH_ENCODER_DECODER_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+ def __call__(
+ self,
+ inputs: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ decoder_input_ids: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_position_ids: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ freeze_feature_encoder: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import FlaxSpeechEncoderDecoderModel, AutoTokenizer
+
+ >>> # load a fine-tuned wav2vec2-2-bart model
+ >>> model = FlaxSpeechEncoderDecoderModel.from_pretrained("patrickvonplaten/wav2vec2-2-bart-large")
+ >>> # load output tokenizer
+ >>> tokenizer_output = AutoTokenizer.from_pretrained("facebook/bart-large")
+
+ >>> inputs = jnp.ones((2, 5000), dtype=jnp.float32)
+
+ >>> # use bart's special bos, pad and eos tokens
+ >>> model.config.decoder_start_token_id = model.decoder.config.bos_token_id
+ >>> model.config.pad_token_id = model.decoder.config.pad_token_id
+ >>> model.config.eos_token_id = model.decoder.config.eos_token_id
+
+ >>> outputs = model.generate(inputs)
+ # Assert something? More interesting input? dtype correct?
+ ```
+ """
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # prepare encoder inputs
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(inputs, dtype="i4")
+
+ # prepare decoder inputs
+ if decoder_input_ids is None:
+ raise ValueError(
+ "`decoder_input_ids` cannot be `None`. For sequence to sequence training, `decoder_position_ids` must"
+ " be specified as an input argument."
+ )
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+ if decoder_position_ids is None:
+ batch_size, sequence_length = decoder_input_ids.shape
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(sequence_length)[None, :], (batch_size, sequence_length)
+ )
+
+ # Handle any PRNG if needed
+ rngs = {"dropout": dropout_rng} if dropout_rng is not None else {}
+
+ return self.module.apply(
+ {"params": params or self.params},
+ inputs=jnp.array(inputs, dtype="f4"),
+ attention_mask=jnp.array(attention_mask, dtype="i4"),
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ decoder_position_ids=jnp.array(decoder_position_ids, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ freeze_feature_encoder=freeze_feature_encoder,
+ rngs=rngs,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ decoder_input_ids,
+ max_length,
+ attention_mask: Optional[jax.Array] = None,
+ decoder_attention_mask: Optional[jax.Array] = None,
+ encoder_outputs=None,
+ **kwargs,
+ ):
+ # initializing the cache
+ batch_size, seq_length = decoder_input_ids.shape
+
+ past_key_values = self.init_cache(batch_size, max_length, encoder_outputs)
+ # Note that usually one would have to put 0's in the attention_mask for x > input.shape[-1] and x < cache_length.
+ # But since the decoder uses a causal mask, those positions are masked anyways.
+ # Thus we can create a single static attention_mask here, which is more efficient for compilation
+ extended_attention_mask = jnp.ones((batch_size, max_length), dtype="i4")
+ if decoder_attention_mask is not None:
+ decoder_position_ids = decoder_attention_mask.cumsum(axis=-1) - 1
+ extended_attention_mask = lax.dynamic_update_slice(extended_attention_mask, decoder_attention_mask, (0, 0))
+ else:
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(seq_length, dtype="i4")[None, :], (batch_size, seq_length)
+ )
+
+ return {
+ "past_key_values": past_key_values,
+ "encoder_outputs": encoder_outputs,
+ "encoder_attention_mask": attention_mask,
+ "decoder_attention_mask": extended_attention_mask,
+ "decoder_position_ids": decoder_position_ids,
+ }
+
+ def update_inputs_for_generation(self, model_outputs, model_kwargs):
+ model_kwargs["past_key_values"] = model_outputs.past_key_values
+ model_kwargs["decoder_position_ids"] = model_kwargs["decoder_position_ids"][:, -1:] + 1
+ return model_kwargs
+
+ @classmethod
+ def from_encoder_decoder_pretrained(
+ cls,
+ encoder_pretrained_model_name_or_path: Optional[Union[str, os.PathLike]] = None,
+ decoder_pretrained_model_name_or_path: Optional[Union[str, os.PathLike]] = None,
+ *model_args,
+ **kwargs,
+ ) -> FlaxPreTrainedModel:
+ r"""
+ Instantiate an encoder and a decoder from one or two base classes of the library from pretrained model
+ checkpoints.
+
+ Params:
+ encoder_pretrained_model_name_or_path (`Union[str, os.PathLike]`, *optional*):
+ Information necessary to initiate the encoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~FlaxPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+
+ decoder_pretrained_model_name_or_path (`Union[str, os.PathLike]`, *optional*, defaults to `None`):
+ Information necessary to initiate the decoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~FlaxPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the encoder configuration, use the prefix *encoder_* for each configuration parameter.
+ - To update the decoder configuration, use the prefix *decoder_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import FlaxSpeechEncoderDecoderModel
+
+ >>> # initialize a wav2vec2-2-bart from pretrained wav2vec2 and bart models. Note that the cross-attention layers will be randomly initialized
+ >>> model = FlaxSpeechEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "facebook/wav2vec2-large-lv60", "facebook/bart-large"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./wav2vec2-2-bart-large")
+ >>> # load fine-tuned model
+ >>> model = FlaxSpeechEncoderDecoderModel.from_pretrained("./wav2vec2-2-bart-large")
+ ```"""
+
+ kwargs_encoder = {
+ argument[len("encoder_") :]: value for argument, value in kwargs.items() if argument.startswith("encoder_")
+ }
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+
+ # remove encoder, decoder kwargs from kwargs
+ for key in kwargs_encoder:
+ del kwargs["encoder_" + key]
+ for key in kwargs_decoder:
+ del kwargs["decoder_" + key]
+
+ # Load and initialize the encoder and decoder
+ # The distinction between encoder and decoder at the model level is made
+ # by the value of the flag `is_decoder` that we need to set correctly.
+ encoder = kwargs_encoder.pop("model", None)
+ if encoder is None:
+ if encoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `encoder_model` is not defined as an argument, a `encoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_encoder:
+ encoder_config, kwargs_encoder = AutoConfig.from_pretrained(
+ encoder_pretrained_model_name_or_path, **kwargs_encoder, return_unused_kwargs=True
+ )
+ if encoder_config.is_decoder is True or encoder_config.add_cross_attention is True:
+ logger.info(
+ f"Initializing {encoder_pretrained_model_name_or_path} as a encoder model "
+ "from a decoder model. Cross-attention and causal mask are disabled."
+ )
+ encoder_config.is_decoder = False
+ encoder_config.add_cross_attention = False
+
+ kwargs_encoder["config"] = encoder_config
+
+ encoder = FlaxAutoModel.from_pretrained(
+ encoder_pretrained_model_name_or_path, *model_args, **kwargs_encoder
+ )
+
+ decoder = kwargs_decoder.pop("model", None)
+ if decoder is None:
+ if decoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `decoder_model` is not defined as an argument, a `decoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_decoder:
+ decoder_config, kwargs_decoder = AutoConfig.from_pretrained(
+ decoder_pretrained_model_name_or_path, **kwargs_decoder, return_unused_kwargs=True
+ )
+ if decoder_config.is_decoder is False or decoder_config.add_cross_attention is False:
+ logger.info(
+ f"Initializing {decoder_pretrained_model_name_or_path} as a decoder model. Cross attention"
+ f" layers are added to {decoder_pretrained_model_name_or_path} and randomly initialized if"
+ f" {decoder_pretrained_model_name_or_path}'s architecture allows for cross attention layers."
+ )
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ kwargs_decoder["config"] = decoder_config
+
+ if kwargs_decoder["config"].is_decoder is False or kwargs_decoder["config"].add_cross_attention is False:
+ logger.warning(
+ f"Decoder model {decoder_pretrained_model_name_or_path} is not initialized as a decoder. "
+ f"In order to initialize {decoder_pretrained_model_name_or_path} as a decoder, "
+ "make sure that the attributes `is_decoder` and `add_cross_attention` of `decoder_config` "
+ "passed to `.from_encoder_decoder_pretrained(...)` are set to `True` or do not pass a "
+ "`decoder_config` to `.from_encoder_decoder_pretrained(...)`"
+ )
+
+ decoder = FlaxAutoModelForCausalLM.from_pretrained(decoder_pretrained_model_name_or_path, **kwargs_decoder)
+
+ # instantiate config with corresponding kwargs
+ dtype = kwargs.pop("dtype", jnp.float32)
+ config = SpeechEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config, **kwargs)
+
+ # make sure input & output word embeddings are not tied
+ config.tie_word_embeddings = False
+
+ # init model
+ model = cls(config, dtype=dtype)
+ model.params["encoder"] = encoder.params
+ model.params["decoder"] = decoder.params
+
+ return model
+
+
+__all__ = ["FlaxSpeechEncoderDecoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/modeling_speech_encoder_decoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/modeling_speech_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..9a519cd9a5dcc63c75b7befabb57dad801f65a92
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_encoder_decoder/modeling_speech_encoder_decoder.py
@@ -0,0 +1,504 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Classes to support Speech-Encoder-Text-Decoder architectures"""
+
+from typing import Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...configuration_utils import PretrainedConfig
+from ...generation import GenerationMixin
+from ...modeling_outputs import BaseModelOutput, Seq2SeqLMOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_auto import AutoModel, AutoModelForCausalLM
+from .configuration_speech_encoder_decoder import SpeechEncoderDecoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.encoder_decoder.modeling_encoder_decoder.shift_tokens_right
+def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ """
+ Shift input ids one token to the right.
+ """
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[:, 1:] = input_ids[:, :-1].clone()
+ if decoder_start_token_id is None:
+ raise ValueError("Make sure to set the decoder_start_token_id attribute of the model's configuration.")
+ shifted_input_ids[:, 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("Make sure to set the pad_token_id attribute of the model's configuration.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+@auto_docstring
+class SpeechEncoderDecoderModel(PreTrainedModel, GenerationMixin):
+ r"""
+ [`SpeechEncoderDecoderModel`] is a generic model class that will be instantiated as a transformer architecture with
+ one of the base model classes of the library as encoder and another one as decoder when created with the
+ :meth*~transformers.AutoModel.from_pretrained* class method for the encoder and
+ :meth*~transformers.AutoModelForCausalLM.from_pretrained* class method for the decoder.
+ """
+
+ config: SpeechEncoderDecoderConfig
+ base_model_prefix = "speech_encoder_decoder"
+ main_input_name = "inputs"
+ supports_gradient_checkpointing = True
+ _supports_param_buffer_assignment = False
+ _supports_flash_attn = True
+ _supports_sdpa = True
+
+ def __init__(
+ self,
+ config: Optional[PretrainedConfig] = None,
+ encoder: Optional[PreTrainedModel] = None,
+ decoder: Optional[PreTrainedModel] = None,
+ ):
+ r"""
+ encoder (`PreTrainedModel`, *optional*):
+ The encoder model to use.
+ decoder (`PreTrainedModel`, *optional*):
+ The decoder model to use.
+ """
+ if config is None and (encoder is None or decoder is None):
+ raise ValueError("Either a configuration or an encoder and a decoder has to be provided.")
+ if config is None:
+ config = SpeechEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config)
+ else:
+ if not isinstance(config, self.config_class):
+ raise ValueError(f"Config: {config} has to be of type {self.config_class}")
+
+ if config.decoder.cross_attention_hidden_size is not None:
+ if config.decoder.cross_attention_hidden_size != config.encoder.hidden_size:
+ raise ValueError(
+ "If `cross_attention_hidden_size` is specified in the decoder's configuration, it has to be equal"
+ f" to the encoder's `hidden_size`. Got {config.decoder.cross_attention_hidden_size} for"
+ f" `config.decoder.cross_attention_hidden_size` and {config.encoder.hidden_size} for"
+ " `config.encoder.hidden_size`."
+ )
+
+ # initialize with config
+ # make sure input & output embeddings is not tied
+ config.tie_word_embeddings = False
+ super().__init__(config)
+
+ if encoder is None:
+ encoder = AutoModel.from_config(config.encoder)
+
+ if decoder is None:
+ decoder = AutoModelForCausalLM.from_config(config.decoder)
+
+ self.encoder = encoder
+ self.decoder = decoder
+
+ if self.encoder.config.to_dict() != self.config.encoder.to_dict():
+ logger.warning(
+ f"Config of the encoder: {self.encoder.__class__} is overwritten by shared encoder config:"
+ f" {self.config.encoder}"
+ )
+ if self.decoder.config.to_dict() != self.config.decoder.to_dict():
+ logger.warning(
+ f"Config of the decoder: {self.decoder.__class__} is overwritten by shared decoder config:"
+ f" {self.config.decoder}"
+ )
+
+ # make sure that the individual model's config refers to the shared config
+ # so that the updates to the config will be synced
+ self.config.encoder._attn_implementation = self.encoder.config._attn_implementation
+ self.config.decoder._attn_implementation = self.decoder.config._attn_implementation
+ self.encoder.config = self.config.encoder
+ self.decoder.config = self.config.decoder
+
+ # get encoder output hidden size
+ self.encoder_output_dim = getattr(config.encoder, "output_hidden_size", config.encoder.hidden_size)
+ if (
+ self.encoder_output_dim != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ # encoder outputs might need to be projected to different dimension for decoder
+ self.enc_to_dec_proj = nn.Linear(self.encoder.config.hidden_size, self.decoder.config.hidden_size)
+
+ if self.encoder.get_output_embeddings() is not None:
+ raise ValueError(
+ f"The encoder {self.encoder} should not have a LM Head. Please use a model without LM Head"
+ )
+
+ def get_encoder(self):
+ return self.encoder
+
+ def get_input_embeddings(self):
+ return self.decoder.get_input_embeddings()
+
+ def get_output_embeddings(self):
+ return self.decoder.get_output_embeddings()
+
+ def set_output_embeddings(self, new_embeddings):
+ return self.decoder.set_output_embeddings(new_embeddings)
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder of the speech encoder so
+ that its parameters will not be updated during training.
+ """
+ self.encoder.freeze_feature_encoder()
+
+ @classmethod
+ def from_encoder_decoder_pretrained(
+ cls,
+ encoder_pretrained_model_name_or_path: Optional[str] = None,
+ decoder_pretrained_model_name_or_path: Optional[str] = None,
+ *model_args,
+ **kwargs,
+ ) -> PreTrainedModel:
+ r"""
+ Instantiate an encoder and a decoder from one or two base classes of the library from pretrained model
+ checkpoints.
+
+
+ The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated). To train
+ the model, you need to first set it back in training mode with `model.train()`.
+
+ Params:
+ encoder_pretrained_model_name_or_path (`str`, *optional*):
+ Information necessary to initiate the encoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~PreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *tensorflow index checkpoint file* (e.g, `./tf_model/model.ckpt.index`). In
+ this case, `from_tf` should be set to `True` and a configuration object should be provided as
+ `config` argument. This loading path is slower than converting the TensorFlow checkpoint in a
+ PyTorch model using the provided conversion scripts and loading the PyTorch model afterwards.
+
+ decoder_pretrained_model_name_or_path (`str`, *optional*, defaults to `None`):
+ Information necessary to initiate the decoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~PreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *tensorflow index checkpoint file* (e.g, `./tf_model/model.ckpt.index`). In
+ this case, `from_tf` should be set to `True` and a configuration object should be provided as
+ `config` argument. This loading path is slower than converting the TensorFlow checkpoint in a
+ PyTorch model using the provided conversion scripts and loading the PyTorch model afterwards.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the encoder configuration, use the prefix *encoder_* for each configuration parameter.
+ - To update the decoder configuration, use the prefix *decoder_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import SpeechEncoderDecoderModel
+
+ >>> # initialize a wav2vec2bert from a pretrained Wav2Vec2 and a pretrained BERT model. Note that the cross-attention layers will be randomly initialized
+ >>> model = SpeechEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "facebook/wav2vec2-base-960h", "google-bert/bert-base-uncased"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./wav2vec2bert")
+ >>> # load fine-tuned model
+ >>> model = SpeechEncoderDecoderModel.from_pretrained("./wav2vec2bert")
+ ```"""
+
+ kwargs_encoder = {
+ argument[len("encoder_") :]: value for argument, value in kwargs.items() if argument.startswith("encoder_")
+ }
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+
+ # remove encoder, decoder kwargs from kwargs
+ for key in kwargs_encoder:
+ del kwargs["encoder_" + key]
+ for key in kwargs_decoder:
+ del kwargs["decoder_" + key]
+
+ # Load and initialize the encoder and decoder
+ # The distinction between encoder and decoder at the model level is made
+ # by the value of the flag `is_decoder` that we need to set correctly.
+ encoder = kwargs_encoder.pop("model", None)
+ if encoder is None:
+ if encoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `encoder_model` is not defined as an argument, a `encoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_encoder:
+ encoder_config, kwargs_encoder = AutoConfig.from_pretrained(
+ encoder_pretrained_model_name_or_path, **kwargs_encoder, return_unused_kwargs=True
+ )
+
+ if encoder_config.is_decoder is True or encoder_config.add_cross_attention is True:
+ logger.info(
+ f"Initializing {encoder_pretrained_model_name_or_path} as a encoder model "
+ "from a decoder model. Cross-attention and causal mask are disabled."
+ )
+ encoder_config.is_decoder = False
+ encoder_config.add_cross_attention = False
+
+ kwargs_encoder["config"] = encoder_config
+
+ encoder = AutoModel.from_pretrained(encoder_pretrained_model_name_or_path, *model_args, **kwargs_encoder)
+
+ decoder = kwargs_decoder.pop("model", None)
+ if decoder is None:
+ if decoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `decoder_model` is not defined as an argument, a `decoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_decoder:
+ decoder_config, kwargs_decoder = AutoConfig.from_pretrained(
+ decoder_pretrained_model_name_or_path, **kwargs_decoder, return_unused_kwargs=True
+ )
+
+ if decoder_config.is_decoder is False or decoder_config.add_cross_attention is False:
+ logger.info(
+ f"Initializing {decoder_pretrained_model_name_or_path} as a decoder model. Cross attention"
+ f" layers are added to {decoder_pretrained_model_name_or_path} and randomly initialized if"
+ f" {decoder_pretrained_model_name_or_path}'s architecture allows for cross attention layers."
+ )
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ kwargs_decoder["config"] = decoder_config
+
+ if kwargs_decoder["config"].is_decoder is False or kwargs_decoder["config"].add_cross_attention is False:
+ logger.warning(
+ f"Decoder model {decoder_pretrained_model_name_or_path} is not initialized as a decoder. "
+ f"In order to initialize {decoder_pretrained_model_name_or_path} as a decoder, "
+ "make sure that the attributes `is_decoder` and `add_cross_attention` of `decoder_config` "
+ "passed to `.from_encoder_decoder_pretrained(...)` are set to `True` or do not pass a "
+ "`decoder_config` to `.from_encoder_decoder_pretrained(...)`"
+ )
+
+ decoder = AutoModelForCausalLM.from_pretrained(decoder_pretrained_model_name_or_path, **kwargs_decoder)
+
+ # instantiate config with corresponding kwargs
+ config = SpeechEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config, **kwargs)
+
+ # make sure input & output embeddings is not tied
+ config.tie_word_embeddings = False
+ return cls(encoder=encoder, decoder=decoder, config=config)
+
+ @auto_docstring
+ def forward(
+ self,
+ inputs: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ encoder_outputs: Optional[tuple[torch.FloatTensor]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ input_values: Optional[torch.FloatTensor] = None,
+ input_features: Optional[torch.FloatTensor] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ inputs (`torch.FloatTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, feature_dim)`, *optional*):
+ Float values of input raw speech waveform or speech features. Values can be obtained by loading a `.flac`
+ or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.*
+ via the torchcodec library (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `inputs`, either the [`Wav2Vec2Processor`] or
+ [`Speech2TextProcessor`] should be used for padding and conversion into a tensor of type
+ `torch.FloatTensor`.
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ For training, `decoder_input_ids` are automatically created by the model by shifting the `labels` to the
+ right, replacing -100 by the `pad_token_id` and prepending them with the `decoder_start_token_id`.
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, target_sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `decoder_input_ids` you can choose to directly pass an embedded
+ representation. This is useful if you want more control over how to convert `decoder_input_ids` indices
+ into associated vectors than the model's internal embedding lookup matrix.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss for the decoder. Indices should be in `[-100, 0,
+ ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Float values of input raw speech waveform. Values can be obtained by loading a *.flac* or *.wav* audio file
+ into an array of type *list[float]* or a *numpy.ndarray*, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into *input_values*, the [`Wav2Vec2Processor`] should be used for padding and conversion
+ into a tensor of type *torch.FloatTensor*. See [`Wav2Vec2Processor.__call__`] for details.
+
+ Examples:
+
+ ```python
+ >>> from transformers import SpeechEncoderDecoderModel, AutoProcessor
+ >>> from datasets import load_dataset
+ >>> import torch
+
+ >>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-xls-r-300m-en-to-15")
+ >>> model = SpeechEncoderDecoderModel.from_pretrained("facebook/wav2vec2-xls-r-300m-en-to-15")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+ >>> input_values = processor(ds[0]["audio"]["array"], return_tensors="pt").input_values
+ >>> # Inference: Translate English speech to German
+ >>> generated = model.generate(input_values)
+ >>> decoded = processor.batch_decode(generated, skip_special_tokens=True)[0]
+ >>> decoded
+ 'Mr. Quilter ist der Apostel der Mittelschicht und wir freuen uns, sein Evangelium willkommen heißen zu können.'
+
+ >>> # Training: Train model on English transcription
+ >>> labels = processor(text=ds[0]["text"], return_tensors="pt").input_ids
+
+ >>> loss = model(input_values, labels=labels).loss
+ >>> loss.backward()
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ kwargs_encoder = {argument: value for argument, value in kwargs.items() if not argument.startswith("decoder_")}
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+ if "num_items_in_batch" in kwargs_encoder:
+ kwargs_decoder["num_items_in_batch"] = kwargs_encoder.pop("num_items_in_batch", None)
+
+ if encoder_outputs is None:
+ if inputs is None:
+ if input_values is not None and input_features is not None:
+ raise ValueError("You cannot specify both input_values and input_features at the same time")
+ elif input_values is not None:
+ inputs = input_values
+ elif input_features is not None:
+ inputs = input_features
+ else:
+ raise ValueError("You have to specify either input_values or input_features")
+
+ encoder_outputs = self.encoder(
+ inputs,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ **kwargs_encoder,
+ )
+ elif isinstance(encoder_outputs, tuple):
+ encoder_outputs = BaseModelOutput(*encoder_outputs)
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ # optionally project encoder_hidden_states
+ if (
+ self.encoder_output_dim != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ encoder_hidden_states = self.enc_to_dec_proj(encoder_hidden_states)
+
+ # compute correct encoder attention mask
+ if attention_mask is not None:
+ encoder_attention_mask = self.encoder._get_feature_vector_attention_mask(
+ encoder_hidden_states.shape[1], attention_mask
+ )
+ else:
+ encoder_attention_mask = None
+
+ if (labels is not None) and (decoder_input_ids is None and decoder_inputs_embeds is None):
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ use_cache=use_cache,
+ past_key_values=past_key_values,
+ return_dict=return_dict,
+ **kwargs_decoder,
+ )
+
+ # Compute loss independent from decoder (as some shift the logits inside them)
+ loss = None
+ if labels is not None:
+ logits = decoder_outputs.logits if return_dict else decoder_outputs[0]
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.reshape(-1, self.decoder.config.vocab_size), labels.reshape(-1))
+
+ if not return_dict:
+ if loss is not None:
+ return (loss,) + decoder_outputs + encoder_outputs
+ else:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=decoder_outputs.logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_hidden_states,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor):
+ return shift_tokens_right(labels, self.config.pad_token_id, self.config.decoder_start_token_id)
+
+ def resize_token_embeddings(self, *args, **kwargs):
+ raise NotImplementedError(
+ "Resizing the embedding layers via the SpeechEncoderDecoderModel directly is not supported. Please use the"
+ " respective methods of the wrapped decoder object (model.decoder.resize_token_embeddings(...))"
+ )
+
+
+__all__ = ["SpeechEncoderDecoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ec094769d4aea356895c219ee6a9b64f347890b8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/__init__.py
@@ -0,0 +1,31 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_speech_to_text import *
+ from .feature_extraction_speech_to_text import *
+ from .modeling_speech_to_text import *
+ from .modeling_tf_speech_to_text import *
+ from .processing_speech_to_text import *
+ from .tokenization_speech_to_text import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/configuration_speech_to_text.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/configuration_speech_to_text.py
new file mode 100644
index 0000000000000000000000000000000000000000..a08d4fddfd4f35a554e11384f64330a5ecea46d1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/configuration_speech_to_text.py
@@ -0,0 +1,199 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Speech2Text model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Speech2TextConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Speech2TextModel`]. It is used to instantiate a
+ Speech2Text model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the Speech2Text
+ [facebook/s2t-small-librispeech-asr](https://huggingface.co/facebook/s2t-small-librispeech-asr) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 10000):
+ Vocabulary size of the Speech2Text model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`Speech2TextModel`]
+ encoder_layers (`int`, *optional*, defaults to 12):
+ Number of encoder layers.
+ encoder_ffn_dim (`int`, *optional*, defaults to 2048):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in encoder.
+ encoder_attention_heads (`int`, *optional*, defaults to 4):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ decoder_layers (`int`, *optional*, defaults to 6):
+ Number of decoder layers.
+ decoder_ffn_dim (`int`, *optional*, defaults to 2048):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in decoder.
+ decoder_attention_heads (`int`, *optional*, defaults to 4):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ encoder_layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the encoder. See the [LayerDrop paper](https://huggingface.co/papers/1909.11556) for
+ more details.
+ decoder_layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the decoder. See the [LayerDrop paper](https://huggingface.co/papers/1909.11556) for
+ more details.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether the model should return the last key/values attentions (not used by all models).
+ is_encoder_decoder (`bool`, *optional*, defaults to `True`):
+ Whether the model is set up as an encoder-decoder architecture for sequence-to-sequence tasks.
+ activation_function (`str` or `function`, *optional*, defaults to `"relu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ d_model (`int`, *optional*, defaults to 256):
+ Dimensionality of the layers and the pooler layer.
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for activations inside the fully connected layer.
+ init_std (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ decoder_start_token_id (`int`, *optional*, defaults to 2):
+ The initial token ID of the decoder when decoding sequences.
+ scale_embedding (`bool`, *optional*, defaults to `True`):
+ Whether the embeddings are scaled by the square root of `d_model`.
+ pad_token_id (`int`, *optional*, defaults to 1):
+ Padding token id.
+ bos_token_id (`int`, *optional*, defaults to 0):
+ The id of the beginning-of-sequence token.
+ eos_token_id (`int`, *optional*, defaults to 2):
+ The id of the end-of-sequence token.
+ max_source_positions (`int`, *optional*, defaults to 6000):
+ The maximum sequence length of log-mel filter-bank features that this model might ever be used with.
+ max_target_positions (`int`, *optional*, defaults to 1024):
+ The maximum sequence length that this model might ever be used with. Typically, set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ num_conv_layers (`int`, *optional*, defaults to 2):
+ Number of 1D convolutional layers in the conv module.
+ conv_kernel_sizes (`tuple[int]`, *optional*, defaults to `(5, 5)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the conv module. The length
+ of `conv_kernel_sizes` has to match `num_conv_layers`.
+ conv_channels (`int`, *optional*, defaults to 1024):
+ An integer defining the number of output channels of each convolution layers except the final one in the
+ conv module.
+ input_feat_per_channel (`int`, *optional*, defaults to 80):
+ An integer specifying the size of feature vector. This is also the dimensions of log-mel filter-bank
+ features.
+ input_channels (`int`, *optional*, defaults to 1):
+ An integer specifying number of input channels of the input feature vector.
+
+ Example:
+
+ ```python
+ >>> from transformers import Speech2TextConfig, Speech2TextModel
+
+ >>> # Initializing a Speech2Text s2t_transformer_s style configuration
+ >>> configuration = Speech2TextConfig()
+
+ >>> # Initializing a model (with random weights) from the s2t_transformer_s style configuration
+ >>> model = Speech2TextModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "speech_to_text"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {"num_attention_heads": "encoder_attention_heads", "hidden_size": "d_model"}
+
+ def __init__(
+ self,
+ vocab_size=10000,
+ encoder_layers=12,
+ encoder_ffn_dim=2048,
+ encoder_attention_heads=4,
+ decoder_layers=6,
+ decoder_ffn_dim=2048,
+ decoder_attention_heads=4,
+ encoder_layerdrop=0.0,
+ decoder_layerdrop=0.0,
+ use_cache=True,
+ is_encoder_decoder=True,
+ activation_function="relu",
+ d_model=256,
+ dropout=0.1,
+ attention_dropout=0.0,
+ activation_dropout=0.0,
+ init_std=0.02,
+ decoder_start_token_id=2,
+ scale_embedding=True,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ max_source_positions=6000,
+ max_target_positions=1024,
+ num_conv_layers=2,
+ conv_kernel_sizes=(5, 5),
+ conv_channels=1024,
+ input_feat_per_channel=80,
+ input_channels=1,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.d_model = d_model
+ self.encoder_ffn_dim = encoder_ffn_dim
+ self.encoder_layers = encoder_layers
+ self.encoder_attention_heads = encoder_attention_heads
+ self.decoder_ffn_dim = decoder_ffn_dim
+ self.decoder_layers = decoder_layers
+ self.decoder_attention_heads = decoder_attention_heads
+ self.dropout = dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.activation_function = activation_function
+ self.init_std = init_std
+ self.encoder_layerdrop = encoder_layerdrop
+ self.decoder_layerdrop = decoder_layerdrop
+ self.use_cache = use_cache
+ self.num_hidden_layers = encoder_layers
+ self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True
+ self.max_source_positions = max_source_positions
+ self.max_target_positions = max_target_positions
+ self.num_conv_layers = num_conv_layers
+ self.conv_kernel_sizes = list(conv_kernel_sizes)
+ self.conv_channels = conv_channels
+ self.input_feat_per_channel = input_feat_per_channel
+ self.input_channels = input_channels
+
+ if len(self.conv_kernel_sizes) != self.num_conv_layers:
+ raise ValueError(
+ "Configuration for convolutional module is incorrect. "
+ "It is required that `len(config.conv_kernel_sizes)` == `config.num_conv_layers` "
+ f"but is `len(config.conv_kernel_sizes) = {len(self.conv_kernel_sizes)}`, "
+ f"`config.num_conv_layers = {self.num_conv_layers}`."
+ )
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ is_encoder_decoder=is_encoder_decoder,
+ decoder_start_token_id=decoder_start_token_id,
+ **kwargs,
+ )
+
+
+__all__ = ["Speech2TextConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/feature_extraction_speech_to_text.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/feature_extraction_speech_to_text.py
new file mode 100644
index 0000000000000000000000000000000000000000..64627033671ee00646c74f0a1d29d498cd602bef
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/feature_extraction_speech_to_text.py
@@ -0,0 +1,315 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Feature extractor class for Speech2Text
+"""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...audio_utils import mel_filter_bank, spectrogram, window_function
+from ...feature_extraction_sequence_utils import SequenceFeatureExtractor
+from ...feature_extraction_utils import BatchFeature
+from ...utils import PaddingStrategy, TensorType, is_speech_available, logging
+
+
+if is_speech_available():
+ import torch
+ import torchaudio.compliance.kaldi as ta_kaldi
+
+logger = logging.get_logger(__name__)
+
+
+class Speech2TextFeatureExtractor(SequenceFeatureExtractor):
+ r"""
+ Constructs a Speech2Text feature extractor.
+
+ This feature extractor inherits from [`Speech2TextFeatureExtractor`] which contains most of the main methods. Users
+ should refer to this superclass for more information regarding those methods.
+
+ This class extracts mel-filter bank features from raw speech using TorchAudio if installed or using numpy
+ otherwise, and applies utterance-level cepstral mean and variance normalization to the extracted features.
+
+ Args:
+ feature_size (`int`, *optional*, defaults to 80):
+ The feature dimension of the extracted features.
+ sampling_rate (`int`, *optional*, defaults to 16000):
+ The sampling rate at which the audio files should be digitalized expressed in hertz (Hz).
+ num_mel_bins (`int`, *optional*, defaults to 80):
+ Number of Mel-frequency bins.
+ padding_value (`float`, *optional*, defaults to 0.0):
+ The value that is used to fill the padding vectors.
+ dither (`float`, *optional*, defaults to 0.0):
+ Adds dithering. In other words, adds a small Gaussian noise to each frame.
+ E.g. use 4.0 to add dithering with a normal distribution centered
+ around 0.0 with standard deviation 4.0 (assuming [-32k,+32k] range of kaldi waveform).
+ The value 0.0 means no dithering.
+ Dithering has similar effect as `mel_floor`. It reduces the high log_mel_fbank
+ values for signals with hard-zero sections, when VAD cutoff is present in the signal.
+ do_ceptral_normalize (`bool`, *optional*, defaults to `True`):
+ Whether or not to apply utterance-level cepstral mean and variance normalization to extracted features.
+ normalize_means (`bool`, *optional*, defaults to `True`):
+ Whether or not to zero-mean normalize the extracted features.
+ normalize_vars (`bool`, *optional*, defaults to `True`):
+ Whether or not to unit-variance normalize the extracted features.
+ """
+
+ model_input_names = ["input_features", "attention_mask"]
+
+ def __init__(
+ self,
+ feature_size=80,
+ sampling_rate=16000,
+ num_mel_bins=80,
+ padding_value=0.0,
+ dither=0.0,
+ do_ceptral_normalize=True,
+ normalize_means=True,
+ normalize_vars=True,
+ **kwargs,
+ ):
+ super().__init__(feature_size=feature_size, sampling_rate=sampling_rate, padding_value=padding_value, **kwargs)
+ self.num_mel_bins = num_mel_bins
+ self.dither = dither
+ self.do_ceptral_normalize = do_ceptral_normalize
+ self.normalize_means = normalize_means
+ self.normalize_vars = normalize_vars
+ self.return_attention_mask = True
+
+ if not is_speech_available():
+ mel_filters = mel_filter_bank(
+ num_frequency_bins=257,
+ num_mel_filters=self.num_mel_bins,
+ min_frequency=20,
+ max_frequency=sampling_rate // 2,
+ sampling_rate=sampling_rate,
+ norm=None,
+ mel_scale="kaldi",
+ triangularize_in_mel_space=True,
+ )
+
+ self.mel_filters = mel_filters
+ self.window = window_function(400, "povey", periodic=False)
+
+ def _extract_fbank_features(
+ self,
+ waveform: np.ndarray,
+ ) -> np.ndarray:
+ """
+ Get mel-filter bank features using TorchAudio. Note that TorchAudio requires 16-bit signed integers as inputs
+ and hence the waveform should not be normalized before feature extraction.
+ """
+ waveform = waveform * (2**15) # Kaldi compliance: 16-bit signed integers
+ if is_speech_available():
+ waveform = torch.from_numpy(waveform).unsqueeze(0)
+ features = ta_kaldi.fbank(
+ waveform,
+ dither=self.dither,
+ num_mel_bins=self.num_mel_bins,
+ sample_frequency=self.sampling_rate,
+ )
+ features = features.numpy()
+ else:
+ waveform = np.squeeze(waveform)
+ features = spectrogram(
+ waveform,
+ self.window,
+ frame_length=400,
+ hop_length=160,
+ fft_length=512,
+ power=2.0,
+ center=False,
+ dither=self.dither,
+ preemphasis=0.97,
+ mel_filters=self.mel_filters,
+ log_mel="log",
+ mel_floor=1.192092955078125e-07,
+ remove_dc_offset=True,
+ ).T
+ return features
+
+ @staticmethod
+ def utterance_cmvn(
+ x: np.ndarray,
+ input_length: int,
+ normalize_means: Optional[bool] = True,
+ normalize_vars: Optional[bool] = True,
+ padding_value: float = 0.0,
+ ) -> np.ndarray:
+ # make sure we normalize float32 arrays
+ if normalize_means:
+ mean = x[:input_length].mean(axis=0)
+ x = np.subtract(x, mean)
+ if normalize_vars:
+ std = x[:input_length].std(axis=0)
+ x = np.divide(x, std)
+
+ if input_length < x.shape[0]:
+ x[input_length:] = padding_value
+
+ # make sure array is in float32
+ x = x.astype(np.float32)
+
+ return x
+
+ def normalize(
+ self, input_features: list[np.ndarray], attention_mask: Optional[np.ndarray] = None
+ ) -> list[np.ndarray]:
+ lengths = attention_mask.sum(-1) if attention_mask is not None else [x.shape[0] for x in input_features]
+ return [
+ self.utterance_cmvn(x, n, self.normalize_means, self.normalize_vars, self.padding_value)
+ for x, n in zip(input_features, lengths)
+ ]
+
+ def __call__(
+ self,
+ raw_speech: Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]],
+ padding: Union[bool, str, PaddingStrategy] = False,
+ max_length: Optional[int] = None,
+ truncation: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ sampling_rate: Optional[int] = None,
+ return_attention_mask: Optional[bool] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Main method to featurize and prepare for the model one or several sequence(s).
+
+ Args:
+ raw_speech (`np.ndarray`, `list[float]`, `list[np.ndarray]`, `list[list[float]]`):
+ The sequence or batch of sequences to be padded. Each sequence can be a numpy array, a list of float
+ values, a list of numpy arrays or a list of list of float values. Must be mono channel audio, not
+ stereo, i.e. single float per timestep.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `True`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding
+ index) among:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ truncation (`bool`):
+ Activates truncation to cut input sequences longer than *max_length* to *max_length*.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value.
+
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta), or on TPUs which benefit from having sequence lengths be a multiple of 128.
+ return_attention_mask (`bool`, *optional*):
+ Whether to return the attention mask. If left to the default, will return the attention mask according
+ to the specific feature_extractor's default.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+
+
+ For Speech2TextTransformer models, `attention_mask` should always be passed for batched inference, to
+ avoid subtle bugs.
+
+
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ sampling_rate (`int`, *optional*):
+ The sampling rate at which the `raw_speech` input was sampled. It is strongly recommended to pass
+ `sampling_rate` at the forward call to prevent silent errors.
+ padding_value (`float`, *optional*, defaults to 0.0):
+ The value that is used to fill the padding values / vectors.
+ """
+
+ if sampling_rate is not None:
+ if sampling_rate != self.sampling_rate:
+ raise ValueError(
+ f"The model corresponding to this feature extractor: {self} was trained using a sampling rate of"
+ f" {self.sampling_rate}. Please make sure that the provided `raw_speech` input was sampled with"
+ f" {self.sampling_rate} and not {sampling_rate}."
+ )
+ else:
+ logger.warning(
+ f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. "
+ "Failing to do so can result in silent errors that might be hard to debug."
+ )
+
+ is_batched_numpy = isinstance(raw_speech, np.ndarray) and len(raw_speech.shape) > 1
+ if is_batched_numpy and len(raw_speech.shape) > 2:
+ raise ValueError(f"Only mono-channel audio is supported for input to {self}")
+ is_batched = is_batched_numpy or (
+ isinstance(raw_speech, (list, tuple)) and (isinstance(raw_speech[0], (np.ndarray, tuple, list)))
+ )
+
+ if is_batched:
+ raw_speech = [np.asarray(speech, dtype=np.float32) for speech in raw_speech]
+ elif not is_batched and not isinstance(raw_speech, np.ndarray):
+ raw_speech = np.asarray(raw_speech, dtype=np.float32)
+ elif isinstance(raw_speech, np.ndarray) and raw_speech.dtype is np.dtype(np.float64):
+ raw_speech = raw_speech.astype(np.float32)
+
+ # always return batch
+ if not is_batched:
+ raw_speech = [raw_speech]
+
+ # extract fbank features
+ features = [self._extract_fbank_features(waveform) for waveform in raw_speech]
+
+ # convert into correct format for padding
+ encoded_inputs = BatchFeature({"input_features": features})
+
+ padded_inputs = self.pad(
+ encoded_inputs,
+ padding=padding,
+ max_length=max_length,
+ truncation=truncation,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_attention_mask=return_attention_mask,
+ **kwargs,
+ )
+
+ # make sure list is in array format
+ input_features = padded_inputs.get("input_features")
+ if isinstance(input_features[0], list):
+ padded_inputs["input_features"] = [np.asarray(feature, dtype=np.float32) for feature in input_features]
+
+ attention_mask = padded_inputs.get("attention_mask")
+ if attention_mask is not None:
+ padded_inputs["attention_mask"] = [np.asarray(array, dtype=np.int32) for array in attention_mask]
+
+ # Utterance-level cepstral mean and variance normalization
+ if self.do_ceptral_normalize:
+ attention_mask = (
+ np.array(attention_mask, dtype=np.int32)
+ if self._get_padding_strategies(padding, max_length=max_length) is not PaddingStrategy.DO_NOT_PAD
+ else None
+ )
+ padded_inputs["input_features"] = self.normalize(
+ padded_inputs["input_features"], attention_mask=attention_mask
+ )
+
+ if return_tensors is not None:
+ padded_inputs = padded_inputs.convert_to_tensors(return_tensors)
+
+ return padded_inputs
+
+
+__all__ = ["Speech2TextFeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/modeling_speech_to_text.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/modeling_speech_to_text.py
new file mode 100644
index 0000000000000000000000000000000000000000..f6f71b30a1ba35c86ea42ab6a22c2b08a83871f1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/modeling_speech_to_text.py
@@ -0,0 +1,1336 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Speech2Text model."""
+
+import math
+from typing import Callable, Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import (
+ _prepare_4d_attention_mask,
+ _prepare_4d_attention_mask_for_sdpa,
+ _prepare_4d_causal_attention_mask,
+ _prepare_4d_causal_attention_mask_for_sdpa,
+)
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import (
+ auto_docstring,
+ is_torch_flex_attn_available,
+ logging,
+)
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_speech_to_text import Speech2TextConfig
+
+
+if is_torch_flex_attn_available():
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.bart.modeling_bart.shift_tokens_right
+def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ """
+ Shift input ids one token to the right.
+ """
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[:, 1:] = input_ids[:, :-1].clone()
+ shifted_input_ids[:, 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.pad_token_id has to be defined.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+class Conv1dSubsampler(nn.Module):
+ """
+ Convolutional subsampler: a stack of 1D convolution (along temporal dimension) followed by non-linear activation
+ via gated linear units (https://huggingface.co/papers/1911.08460)
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.num_layers = config.num_conv_layers
+ self.in_channels = config.input_feat_per_channel * config.input_channels
+ self.mid_channels = config.conv_channels
+ self.out_channels = config.d_model
+ self.kernel_sizes = config.conv_kernel_sizes
+
+ self.conv_layers = nn.ModuleList(
+ nn.Conv1d(
+ self.in_channels if i == 0 else self.mid_channels // 2,
+ self.mid_channels if i < self.num_layers - 1 else self.out_channels * 2,
+ kernel_size=k,
+ stride=2,
+ padding=k // 2,
+ )
+ for i, k in enumerate(self.kernel_sizes)
+ )
+
+ def forward(self, input_features):
+ hidden_states = input_features.transpose(1, 2).contiguous() # -> B x (C x D) x T
+ for conv in self.conv_layers:
+ hidden_states = conv(hidden_states)
+ hidden_states = nn.functional.glu(hidden_states, dim=1)
+ hidden_states = hidden_states.transpose(1, 2).contiguous() # -> T x B x (C x D)
+ return hidden_states
+
+
+class Speech2TextSinusoidalPositionalEmbedding(nn.Module):
+ """This module produces sinusoidal positional embeddings of any length."""
+
+ def __init__(self, num_positions: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ super().__init__()
+ self.offset = 2
+ self.embedding_dim = embedding_dim
+ self.padding_idx = padding_idx
+ self.make_weights(num_positions + self.offset, embedding_dim, padding_idx)
+
+ def make_weights(self, num_embeddings: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ emb_weights = self.get_embedding(num_embeddings, embedding_dim, padding_idx)
+ if hasattr(self, "weights"):
+ # in forward put the weights on the correct dtype and device of the param
+ emb_weights = emb_weights.to(dtype=self.weights.dtype, device=self.weights.device)
+
+ self.register_buffer("weights", emb_weights, persistent=False)
+
+ @staticmethod
+ def get_embedding(num_embeddings: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ """
+ Build sinusoidal embeddings. This matches the implementation in tensor2tensor, but differs slightly from the
+ description in Section 3.5 of "Attention Is All You Need".
+ """
+ half_dim = embedding_dim // 2
+ emb = math.log(10000) / (half_dim - 1)
+ emb = torch.exp(torch.arange(half_dim, dtype=torch.int64).float() * -emb)
+ emb = torch.arange(num_embeddings, dtype=torch.int64).float().unsqueeze(1) * emb.unsqueeze(0)
+ emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1).view(num_embeddings, -1)
+ if embedding_dim % 2 == 1:
+ # zero pad
+ emb = torch.cat([emb, torch.zeros(num_embeddings, 1)], dim=1)
+ if padding_idx is not None:
+ emb[padding_idx, :] = 0
+ return emb.to(torch.get_default_dtype())
+
+ @torch.no_grad()
+ def forward(self, input_ids: torch.Tensor, past_key_values_length: int = 0):
+ bsz, seq_len = input_ids.size()
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = self.create_position_ids_from_input_ids(input_ids, self.padding_idx, past_key_values_length).to(
+ input_ids.device
+ )
+
+ # expand embeddings if needed
+ max_pos = self.padding_idx + 1 + seq_len
+ if max_pos > self.weights.size(0):
+ self.make_weights(max_pos + self.offset, self.embedding_dim, self.padding_idx)
+
+ return self.weights.index_select(0, position_ids.view(-1)).view(bsz, seq_len, -1).detach()
+
+ def create_position_ids_from_input_ids(
+ self, input_ids: torch.Tensor, padding_idx: int, past_key_values_length: Optional[int] = 0
+ ):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding
+ symbols are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ x: torch.Tensor x:
+ Returns: torch.Tensor
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = input_ids.ne(padding_idx).int()
+ incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask
+ return incremental_indices.long() + padding_idx
+
+
+# Copied from transformers.models.bart.modeling_bart.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: Optional[float] = None,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ if scaling is None:
+ scaling = query.size(-1) ** -0.5
+
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.musicgen.modeling_musicgen.MusicgenAttention with Musicgen->Speech2Text
+class Speech2TextAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: Optional[float] = 0.0,
+ is_decoder: Optional[bool] = False,
+ bias: Optional[bool] = True,
+ is_causal: Optional[bool] = False,
+ config: Optional[Speech2TextConfig] = None,
+ layer_idx: Optional[int] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ self.config = config
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.is_causal = is_causal
+ self.layer_idx = layer_idx
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ # TODO: we need a refactor so that the different attention modules can get their specific kwargs
+ # ATM, we have mixed things encoder, decoder, and encoder-decoder attn
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ # determine input shapes
+ bsz, tgt_len = hidden_states.shape[:-1]
+ src_len = key_value_states.shape[1] if is_cross_attention else tgt_len
+
+ q_input_shape = (bsz, tgt_len, -1, self.head_dim)
+ kv_input_shape = (bsz, src_len, -1, self.head_dim)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_layer from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+ value_states = self.v_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.dropout,
+ scaling=self.scaling,
+ output_attentions=output_attentions,
+ head_mask=layer_head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.mbart.modeling_mbart.MBartEncoderLayer with MBart->Speech2Text, MBART->SPEECH_TO_TEXT
+class Speech2TextEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: Speech2TextConfig):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = Speech2TextAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.encoder_attention_heads,
+ dropout=config.attention_dropout,
+ config=config,
+ )
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+ self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim)
+ self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ layer_head_mask: torch.Tensor,
+ output_attentions: bool = False,
+ ) -> torch.Tensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ return hidden_states, attn_weights
+
+
+# copied from transformers.models.mbart.modeling_mbart.MBartDecoderLayer with MBart->Speech2Text, MBART->SPEECH_TO_TEXT
+# TODO: change copy when applying cache class
+class Speech2TextDecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: Speech2TextConfig, layer_idx=None):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = Speech2TextAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ is_causal=True,
+ config=config,
+ layer_idx=layer_idx,
+ )
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.encoder_attn = Speech2TextAttention(
+ self.embed_dim,
+ config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ config=config,
+ layer_idx=layer_idx,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim)
+ self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ # Copied from transformers.models.musicgen.modeling_musicgen.MusicgenDecoderLayer.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_layer_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = True,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> torch.Tensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`torch.FloatTensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ cross_attn_layer_head_mask (`torch.FloatTensor`): mask for cross-attention heads in a given layer of
+ size `(decoder_attention_heads,)`.
+ past_key_values (`Tuple(torch.FloatTensor)`): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_values=past_key_values,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+@auto_docstring
+class Speech2TextPreTrainedModel(PreTrainedModel):
+ config: Speech2TextConfig
+ base_model_prefix = "model"
+ main_input_name = "input_features"
+ supports_gradient_checkpointing = True
+ # TODO: tests would need a rewrite to check for correct implementation
+ # Current tests always assume certain inputs to be passed
+ _supports_flash_attn = False
+ _supports_sdpa = False
+ _supports_flex_attn = False
+
+ def _init_weights(self, module):
+ std = self.config.init_std
+ if isinstance(module, (nn.Linear, nn.Conv1d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+ def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor):
+ """
+ Computes the output length of the convolutional layers
+ """
+ for i in range(self.config.num_conv_layers):
+ input_lengths = (input_lengths - 1) // 2 + 1
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(self, feature_vector_length, attention_mask):
+ # generate creates 3D attention mask, because of the shape of input_features
+ # convert it to 2D if that's the case
+ if len(attention_mask.shape) > 2:
+ attention_mask = attention_mask[:, :, -1]
+
+ subsampled_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1))
+ bsz = attention_mask.size()[0]
+ attention_mask = torch.zeros(
+ (bsz, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+
+ # these two operations makes sure that all values
+ # before the output lengths indices are attended to
+ attention_mask[(torch.arange(bsz, device=attention_mask.device), subsampled_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).long()
+ return attention_mask
+
+
+class Speech2TextEncoder(Speech2TextPreTrainedModel):
+ """
+ Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a
+ [`Speech2TextEncoderLayer`].
+
+ Args:
+ config: Speech2TextConfig
+ embed_tokens (nn.Embedding): output embedding
+ """
+
+ def __init__(self, config: Speech2TextConfig):
+ super().__init__(config)
+
+ self.dropout = config.dropout
+ self.layerdrop = config.encoder_layerdrop
+
+ embed_dim = config.d_model
+ self.padding_idx = config.pad_token_id
+ self.max_source_positions = config.max_source_positions
+ self.embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0
+
+ self.conv = Conv1dSubsampler(config)
+
+ self.embed_positions = Speech2TextSinusoidalPositionalEmbedding(
+ self.max_source_positions,
+ embed_dim,
+ self.padding_idx,
+ )
+ self.layers = nn.ModuleList([Speech2TextEncoderLayer(config) for _ in range(config.encoder_layers)])
+ self.layer_norm = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_features,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Args:
+ input_features (`torch.LongTensor` of shape `(batch_size, sequence_length, feature_size)`):
+ Float values of fbank features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a
+ `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library (`pip install torchcodec`) or
+ the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the fbank features,
+ padding and conversion into a tensor of type `torch.FloatTensor`. See
+ [`~Speech2TextFeatureExtractor.__call__`]
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing convolution and attention on padding token indices. Mask values selected in
+ `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`torch.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ inputs_embeds = self.conv(input_features)
+ inputs_embeds = self.embed_scale * inputs_embeds
+
+ # subsample attention mask if necessary
+ if attention_mask is not None:
+ attention_mask = self._get_feature_vector_attention_mask(inputs_embeds.shape[1], attention_mask)
+ padding_mask = attention_mask.ne(1).long()
+ else:
+ padding_mask = torch.zeros(inputs_embeds.shape[:2], dtype=torch.long, device=inputs_embeds.device)
+
+ embed_pos = self.embed_positions(padding_mask)
+
+ hidden_states = inputs_embeds + embed_pos
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ inputs_embeds,
+ )
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ # check if head_mask has a correct number of layers specified if desired
+ if head_mask is not None:
+ assert head_mask.size()[0] == (len(self.layers)), (
+ f"The head_mask should be specified for {len(self.layers)} layers, but it is for {head_mask.size()[0]}."
+ )
+
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ to_drop = False
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop: # skip the layer
+ to_drop = True
+
+ if to_drop:
+ layer_outputs = (None, None)
+ else:
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+ # Copied from transformers.models.bart.modeling_bart.BartPreTrainedModel._update_full_mask
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+
+class Speech2TextDecoder(Speech2TextPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`Speech2TextDecoderLayer`]
+
+ Args:
+ config: Speech2TextConfig
+ embed_tokens (nn.Embedding): output embedding
+ """
+
+ def __init__(self, config: Speech2TextConfig):
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.decoder_layerdrop
+ self.padding_idx = config.pad_token_id
+ self.max_target_positions = config.max_target_positions
+ self.embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.d_model, self.padding_idx)
+
+ self.embed_positions = Speech2TextSinusoidalPositionalEmbedding(
+ self.max_target_positions,
+ config.d_model,
+ self.padding_idx,
+ )
+
+ self.layers = nn.ModuleList(
+ [Speech2TextDecoderLayer(config, layer_idx=i) for i in range(config.decoder_layers)]
+ )
+
+ self.layer_norm = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ inputs_embeds=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ cache_position=None,
+ ):
+ r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you
+ provide it.
+
+ Indices can be obtained using [`Speech2TextTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in encoder to avoid performing cross-attention
+ on hidden heads. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of
+ shape `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and in the
+ cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those
+ that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of
+ all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids) * self.embed_scale
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache = True` is incompatible with gradient checkpointing. Setting `use_cache = False`..."
+ )
+ use_cache = False
+
+ if use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+ attention_mask = self._update_causal_mask(
+ attention_mask,
+ input_shape,
+ inputs_embeds,
+ past_key_values_length,
+ )
+ encoder_attention_mask = self._update_cross_attn_mask(
+ encoder_hidden_states,
+ encoder_attention_mask,
+ input_shape,
+ inputs_embeds,
+ )
+
+ # embed positions
+ positions = self.embed_positions(input_ids, past_key_values_length=past_key_values_length)
+
+ hidden_states = inputs_embeds + positions
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ # check if head_mask/cross_attn_head_mask has a correct number of layers specified if desired
+ for attn_mask, mask_name in zip([head_mask, cross_attn_head_mask], ["head_mask", "cross_attn_head_mask"]):
+ if attn_mask is not None:
+ assert attn_mask.size()[0] == (len(self.layers)), (
+ f"The `{mask_name}` should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop:
+ continue
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ hidden_states = self.layer_norm(hidden_states)
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+ # Copied from transformers.models.musicgen.modeling_musicgen.MusicgenDecoder._update_causal_mask
+ def _update_causal_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ input_shape: torch.Size,
+ inputs_embeds: torch.Tensor,
+ past_key_values_length: int,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ # 2d mask is passed through the layers
+ attention_mask = attention_mask if (attention_mask is not None and 0 in attention_mask) else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & cross_attn_head_mask can not be supported when using SDPA, and we fall back on
+ # the manual implementation that requires a 4D causal mask in all cases.
+ attention_mask = _prepare_4d_causal_attention_mask_for_sdpa(
+ attention_mask,
+ input_shape,
+ inputs_embeds,
+ past_key_values_length,
+ )
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask)
+ # Other attention flavors support in-built causal (when `mask is None`)
+ # while we need to create our specific block mask regardless
+ elif attention_mask is None:
+ attention_mask = make_flex_block_causal_mask(
+ torch.ones(
+ size=(input_shape),
+ device=inputs_embeds.device,
+ )
+ )
+ else:
+ # 4d mask is passed through the layers
+ attention_mask = _prepare_4d_causal_attention_mask(
+ attention_mask, input_shape, inputs_embeds, past_key_values_length
+ )
+
+ return attention_mask
+
+ # Copied from transformers.models.musicgen.modeling_musicgen.MusicgenDecoder._update_cross_attn_mask
+ def _update_cross_attn_mask(
+ self,
+ encoder_hidden_states: Union[torch.Tensor, None],
+ encoder_attention_mask: Union[torch.Tensor, None],
+ input_shape: torch.Size,
+ inputs_embeds: torch.Tensor,
+ ):
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ encoder_attention_mask = encoder_attention_mask if 0 in encoder_attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & cross_attn_head_mask can not be supported when using SDPA, and we fall back on
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ encoder_attention_mask,
+ inputs_embeds.dtype,
+ tgt_len=input_shape[-1],
+ )
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(encoder_attention_mask, torch.Tensor):
+ encoder_attention_mask = make_flex_block_causal_mask(
+ encoder_attention_mask,
+ query_length=input_shape[-1],
+ is_causal=False,
+ )
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(
+ encoder_attention_mask, inputs_embeds.dtype, tgt_len=input_shape[-1]
+ )
+
+ return encoder_attention_mask
+
+
+@auto_docstring
+class Speech2TextModel(Speech2TextPreTrainedModel):
+ def __init__(self, config: Speech2TextConfig):
+ super().__init__(config)
+
+ self.encoder = Speech2TextEncoder(config)
+ self.decoder = Speech2TextDecoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.decoder.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.decoder.embed_tokens = value
+
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`SpeechToTextTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ SpeechToText uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+
+ If you want to change padding behavior, you should read
+ [`modeling_speech_to_text._prepare_decoder_attention_mask`] and modify to your needs. See diagram 1 in [the
+ paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import Speech2TextModel, AutoFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = Speech2TextModel.from_pretrained("facebook/s2t-small-librispeech-asr")
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/s2t-small-librispeech-asr")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(
+ ... ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], return_tensors="pt"
+ ... )
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = torch.tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 256]
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_features,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ # downsample encoder attention mask
+ if attention_mask is not None:
+ encoder_attention_mask = self._get_feature_vector_attention_mask(
+ encoder_outputs[0].shape[1], attention_mask
+ )
+ else:
+ encoder_attention_mask = None
+
+ # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn)
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_outputs[0],
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The Speech2Text Model with a language modeling head. Can be used for summarization.
+ """
+)
+class Speech2TextForConditionalGeneration(Speech2TextPreTrainedModel, GenerationMixin):
+ base_model_prefix = "model"
+ _tied_weights_keys = ["lm_head.weight"]
+
+ def __init__(self, config: Speech2TextConfig):
+ super().__init__(config)
+ self.model = Speech2TextModel(config)
+ self.lm_head = nn.Linear(config.d_model, self.config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_encoder(self):
+ return self.model.get_encoder()
+
+ def get_decoder(self):
+ return self.model.get_decoder()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`SpeechToTextTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ SpeechToText uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+
+ If you want to change padding behavior, you should read
+ [`modeling_speech_to_text._prepare_decoder_attention_mask`] and modify to your needs. See diagram 1 in [the
+ paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the language modeling loss. Indices should either be in `[0, ..., config.vocab_size]`
+ or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored (masked), the loss is
+ only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import Speech2TextProcessor, Speech2TextForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> model = Speech2TextForConditionalGeneration.from_pretrained("facebook/s2t-small-librispeech-asr")
+ >>> processor = Speech2TextProcessor.from_pretrained("facebook/s2t-small-librispeech-asr")
+
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+ >>> inputs = processor(
+ ... ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], return_tensors="pt"
+ ... )
+ >>> input_features = inputs.input_features
+
+ >>> generated_ids = model.generate(inputs=input_features)
+
+ >>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+ >>> transcription
+ 'mister quilter is the apostle of the middle classes and we are glad to welcome his gospel'
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ outputs = self.model(
+ input_features,
+ attention_mask=attention_mask,
+ decoder_input_ids=decoder_input_ids,
+ encoder_outputs=encoder_outputs,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+ lm_logits = self.lm_head(outputs[0])
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (lm_logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=lm_logits,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+
+__all__ = ["Speech2TextForConditionalGeneration", "Speech2TextModel", "Speech2TextPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/modeling_tf_speech_to_text.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/modeling_tf_speech_to_text.py
new file mode 100644
index 0000000000000000000000000000000000000000..402c005b7be78e5368c787bd1cebea0e25a27c94
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/modeling_tf_speech_to_text.py
@@ -0,0 +1,1600 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TensorFlow Speech2Text model."""
+
+from __future__ import annotations
+
+import random
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation, glu
+from ...modeling_tf_outputs import (
+ TFBaseModelOutput,
+ TFBaseModelOutputWithPastAndCrossAttentions,
+ TFSeq2SeqLMOutput,
+ TFSeq2SeqModelOutput,
+)
+from ...modeling_tf_utils import (
+ TFCausalLanguageModelingLoss,
+ TFModelInputType,
+ TFPreTrainedModel,
+ TFSharedEmbeddings,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import (
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+ replace_return_docstrings,
+)
+from .configuration_speech_to_text import Speech2TextConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "Speech2TextConfig"
+_CHECKPOINT_FOR_DOC = "facebook/s2t-small-librispeech-asr"
+
+
+LARGE_NEGATIVE = -1e8
+
+
+# Copied from transformers.models.bart.modeling_tf_bart.shift_tokens_right
+def shift_tokens_right(input_ids: tf.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ pad_token_id = tf.cast(pad_token_id, input_ids.dtype)
+ decoder_start_token_id = tf.cast(decoder_start_token_id, input_ids.dtype)
+ start_tokens = tf.fill(
+ (shape_list(input_ids)[0], 1), tf.convert_to_tensor(decoder_start_token_id, input_ids.dtype)
+ )
+ shifted_input_ids = tf.concat([start_tokens, input_ids[:, :-1]], -1)
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids = tf.where(
+ shifted_input_ids == -100,
+ tf.fill(shape_list(shifted_input_ids), tf.convert_to_tensor(pad_token_id, input_ids.dtype)),
+ shifted_input_ids,
+ )
+
+ # "Verify that `labels` has only positive values and -100"
+ assert_gte0 = tf.debugging.assert_greater_equal(shifted_input_ids, tf.constant(0, dtype=input_ids.dtype))
+
+ # Make sure the assertion op is called by wrapping the result in an identity no-op
+ with tf.control_dependencies([assert_gte0]):
+ shifted_input_ids = tf.identity(shifted_input_ids)
+
+ return shifted_input_ids
+
+
+# Copied from transformers.models.bart.modeling_tf_bart._make_causal_mask
+def _make_causal_mask(input_ids_shape: tf.TensorShape, past_key_values_length: int = 0):
+ """
+ Make causal mask used for bi-directional self-attention.
+ """
+ bsz = input_ids_shape[0]
+ tgt_len = input_ids_shape[1]
+ mask = tf.ones((tgt_len, tgt_len)) * LARGE_NEGATIVE
+ mask_cond = tf.range(shape_list(mask)[-1])
+
+ mask = tf.where(mask_cond < tf.reshape(mask_cond + 1, (shape_list(mask)[-1], 1)), 0.0, mask)
+
+ if past_key_values_length > 0:
+ mask = tf.concat([tf.zeros((tgt_len, past_key_values_length)), mask], axis=-1)
+
+ return tf.tile(mask[None, None, :, :], (bsz, 1, 1, 1))
+
+
+# Copied from transformers.models.bart.modeling_tf_bart._expand_mask
+def _expand_mask(mask: tf.Tensor, tgt_len: int | None = None):
+ """
+ Expands attention_mask from `[bsz, seq_len]` to `[bsz, 1, tgt_seq_len, src_seq_len]`.
+ """
+ src_len = shape_list(mask)[1]
+ tgt_len = tgt_len if tgt_len is not None else src_len
+ one_cst = tf.constant(1.0)
+ mask = tf.cast(mask, dtype=one_cst.dtype)
+ expanded_mask = tf.tile(mask[:, None, None, :], (1, 1, tgt_len, 1))
+
+ return (one_cst - expanded_mask) * LARGE_NEGATIVE
+
+
+class TFConv1dSubsampler(keras.layers.Layer):
+ """
+ Convolutional subsampler: a stack of 1D convolution (along temporal dimension) followed by non-linear activation
+ via gated linear units (https://huggingface.co/papers/1911.08460)
+ """
+
+ def __init__(self, config: Speech2TextConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.num_layers = config.num_conv_layers
+ self.in_channels = config.input_feat_per_channel * config.input_channels
+ self.mid_channels = config.conv_channels
+ self.out_channels = config.d_model
+ self.kernel_sizes = config.conv_kernel_sizes
+
+ self.conv_layers = [
+ keras.layers.Conv1D(
+ filters=self.mid_channels if i < self.num_layers - 1 else self.out_channels * 2,
+ kernel_size=k,
+ strides=2,
+ name=f"conv_layers.{i}",
+ )
+ for i, k in enumerate(self.kernel_sizes)
+ ]
+
+ def call(self, input_features: tf.Tensor) -> tf.Tensor:
+ # TF Conv1D assumes Batch x Time x Channels, same as the input
+ hidden_states = tf.cast(input_features, tf.float32)
+ for i, conv in enumerate(self.conv_layers):
+ # equivalent to `padding=k // 2` on PT's `nn.Conv1d`
+ pad_len = self.kernel_sizes[i] // 2
+ hidden_shapes = shape_list(hidden_states)
+ hidden_states = tf.concat(
+ (
+ tf.zeros((hidden_shapes[0], pad_len, hidden_shapes[2])),
+ hidden_states,
+ tf.zeros((hidden_shapes[0], pad_len, hidden_shapes[2])),
+ ),
+ axis=1,
+ )
+
+ hidden_states = conv(hidden_states)
+ hidden_states = glu(hidden_states, axis=2) # GLU over the Channel dimension
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv_layers", None) is not None:
+ for i, layer in enumerate(self.conv_layers):
+ with tf.name_scope(layer.name):
+ layer.build([None, None, self.in_channels] if i == 0 else [None, None, self.mid_channels // 2])
+
+
+class TFSpeech2TextSinusoidalPositionalEmbedding(keras.layers.Layer):
+ """This module produces sinusoidal positional embeddings of any length."""
+
+ def __init__(self, num_positions: int, embedding_dim: int, padding_idx: int | None = None, **kwargs):
+ super().__init__(**kwargs)
+ self.offset = 2
+ self.embedding_dim = embedding_dim
+ self.padding_idx = padding_idx
+ self.embedding_weights = self._get_embedding(num_positions + self.offset, embedding_dim, padding_idx)
+
+ @staticmethod
+ def _get_embedding(num_embeddings: int, embedding_dim: int, padding_idx: int | None = None) -> tf.Tensor:
+ """
+ Build sinusoidal embeddings. This matches the implementation in tensor2tensor, but differs slightly from the
+ description in Section 3.5 of "Attention Is All You Need".
+ """
+ half_dim = embedding_dim // 2
+ emb = tf.math.log(10000.0) / (half_dim - 1)
+ emb = tf.math.exp(tf.range(half_dim, dtype=tf.float32) * -emb)
+ emb = tf.expand_dims(tf.range(num_embeddings, dtype=tf.float32), axis=1) * tf.expand_dims(emb, axis=0)
+ emb = tf.reshape(tf.concat([tf.math.sin(emb), tf.math.cos(emb)], axis=1), shape=[num_embeddings, -1])
+ if embedding_dim % 2 == 1:
+ # zero pad
+ emb = tf.concat([emb, tf.zeros(num_embeddings, 1)], axis=1)
+ if padding_idx is not None:
+ emb = tf.concat([emb[:padding_idx, :], tf.zeros((1, tf.shape(emb)[1])), emb[padding_idx + 1 :, :]], axis=0)
+ return emb
+
+ def call(self, input_ids: tf.Tensor, past_key_values_length: int = 0) -> tf.Tensor:
+ bsz, seq_len = shape_list(input_ids)
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = self.create_position_ids_from_input_ids(input_ids, self.padding_idx, past_key_values_length)
+
+ # Matt: The PyTorch code does a lot of work to cache the embeddings, setting the cached values as a
+ # model attribute in the forward pass. This is extremely forbidden in TF, which wants forward calls to be
+ # idempotent. TF doesn't need that caching anyway, since it can just store constants during compilation,
+ # so we just remove all of that code.
+ embeddings = self._get_embedding(
+ self.padding_idx + 1 + seq_len + self.offset + past_key_values_length, self.embedding_dim, self.padding_idx
+ )
+ return tf.reshape(tf.gather(embeddings, tf.reshape(position_ids, (-1,)), axis=0), (bsz, seq_len, -1))
+
+ @staticmethod
+ def create_position_ids_from_input_ids(
+ input_ids: tf.Tensor, padding_idx: int, past_key_values_length: int | None = 0
+ ) -> tf.Tensor:
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding
+ symbols are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ x: tf.Tensor x:
+ Returns: tf.Tensor
+ """
+ mask = tf.cast(tf.math.not_equal(input_ids, padding_idx), dtype=tf.int32)
+ incremental_indices = (tf.math.cumsum(mask, axis=1) + past_key_values_length) * mask
+ return tf.cast(incremental_indices, dtype=tf.int64) + padding_idx
+
+
+# Copied from transformers.models.bart.modeling_tf_bart.TFBartAttention with Bart->Speech2Text
+class TFSpeech2TextAttention(keras.layers.Layer):
+ """Multi-headed attention from "Attention Is All You Need"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.embed_dim = embed_dim
+
+ self.num_heads = num_heads
+ self.dropout = keras.layers.Dropout(dropout)
+ self.head_dim = embed_dim // num_heads
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+
+ self.k_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="k_proj")
+ self.q_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="q_proj")
+ self.v_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="v_proj")
+ self.out_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="out_proj")
+
+ def _shape(self, tensor: tf.Tensor, seq_len: int, bsz: int):
+ return tf.transpose(tf.reshape(tensor, (bsz, seq_len, self.num_heads, self.head_dim)), (0, 2, 1, 3))
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ key_value_states: tf.Tensor | None = None,
+ past_key_value: tuple[tuple[tf.Tensor]] | None = None,
+ attention_mask: tf.Tensor | None = None,
+ layer_head_mask: tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> tuple[tf.Tensor, tf.Tensor | None]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ bsz, tgt_len, embed_dim = shape_list(hidden_states)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+ # get key, value proj
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_states = past_key_value[0]
+ value_states = past_key_value[1]
+ elif is_cross_attention:
+ # cross_attentions
+ key_states = self._shape(self.k_proj(key_value_states), -1, bsz)
+ value_states = self._shape(self.v_proj(key_value_states), -1, bsz)
+ elif past_key_value is not None:
+ # reuse k, v, self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+ key_states = tf.concat([past_key_value[0], key_states], axis=2)
+ value_states = tf.concat([past_key_value[1], value_states], axis=2)
+ else:
+ # self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(tf.Tensor, tf.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(tf.Tensor, tf.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_states, value_states)
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = tf.reshape(self._shape(query_states, tgt_len, bsz), proj_shape)
+ key_states = tf.reshape(key_states, proj_shape)
+ value_states = tf.reshape(value_states, proj_shape)
+
+ src_len = shape_list(key_states)[1]
+ attn_weights = tf.matmul(query_states, key_states, transpose_b=True)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_weights),
+ [bsz * self.num_heads, tgt_len, src_len],
+ message=(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {shape_list(attn_weights)}"
+ ),
+ )
+
+ if attention_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(attention_mask),
+ [bsz, 1, tgt_len, src_len],
+ message=(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is"
+ f" {shape_list(attention_mask)}"
+ ),
+ )
+
+ attention_mask = tf.cast(attention_mask, dtype=attn_weights.dtype)
+ attn_weights = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len)) + attention_mask
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_weights = stable_softmax(attn_weights, axis=-1)
+
+ if layer_head_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(layer_head_mask),
+ [self.num_heads],
+ message=(
+ f"Head mask for a single layer should be of size {(self.num_heads)}, but is"
+ f" {shape_list(layer_head_mask)}"
+ ),
+ )
+
+ attn_weights = tf.reshape(layer_head_mask, (1, -1, 1, 1)) * tf.reshape(
+ attn_weights, (bsz, self.num_heads, tgt_len, src_len)
+ )
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_probs = self.dropout(attn_weights, training=training)
+ attn_output = tf.matmul(attn_probs, value_states)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_output),
+ [bsz * self.num_heads, tgt_len, self.head_dim],
+ message=(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {shape_list(attn_output)}"
+ ),
+ )
+
+ attn_output = tf.transpose(
+ tf.reshape(attn_output, (bsz, self.num_heads, tgt_len, self.head_dim)), (0, 2, 1, 3)
+ )
+ attn_output = tf.reshape(attn_output, (bsz, tgt_len, embed_dim))
+
+ attn_output = self.out_proj(attn_output)
+ attn_weights: tf.Tensor = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len))
+
+ return attn_output, attn_weights, past_key_value
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "k_proj", None) is not None:
+ with tf.name_scope(self.k_proj.name):
+ self.k_proj.build([None, None, self.embed_dim])
+ if getattr(self, "q_proj", None) is not None:
+ with tf.name_scope(self.q_proj.name):
+ self.q_proj.build([None, None, self.embed_dim])
+ if getattr(self, "v_proj", None) is not None:
+ with tf.name_scope(self.v_proj.name):
+ self.v_proj.build([None, None, self.embed_dim])
+ if getattr(self, "out_proj", None) is not None:
+ with tf.name_scope(self.out_proj.name):
+ self.out_proj.build([None, None, self.embed_dim])
+
+
+class TFSpeech2TextEncoderLayer(keras.layers.Layer):
+ def __init__(self, config: Speech2TextConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.embed_dim = config.d_model
+ self.self_attn = TFSpeech2TextAttention(
+ self.embed_dim, config.encoder_attention_heads, dropout=config.attention_dropout, name="self_attn"
+ )
+ self.self_attn_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="self_attn_layer_norm")
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.activation_fn = get_tf_activation(config.activation_function)
+ self.activation_dropout = keras.layers.Dropout(config.activation_dropout)
+ self.fc1 = keras.layers.Dense(config.encoder_ffn_dim, name="fc1")
+ self.fc2 = keras.layers.Dense(self.embed_dim, name="fc2")
+ self.final_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="final_layer_norm")
+ self.config = config
+
+ def call(
+ self, hidden_states: tf.Tensor, attention_mask: tf.Tensor, layer_head_mask: tf.Tensor, training: bool = False
+ ):
+ """
+ Args:
+ hidden_states (`tf.Tensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`tf.Tensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`tf.Tensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, self_attn_weights, _ = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ training=training,
+ )
+
+ tf.debugging.assert_equal(
+ shape_list(hidden_states),
+ shape_list(residual),
+ message=f"Self attn modified the shape of query {shape_list(residual)} to {shape_list(hidden_states)}",
+ )
+
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout(hidden_states, training=training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ return hidden_states, self_attn_weights
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attn", None) is not None:
+ with tf.name_scope(self.self_attn.name):
+ self.self_attn.build(None)
+ if getattr(self, "self_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.self_attn_layer_norm.name):
+ self.self_attn_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "fc1", None) is not None:
+ with tf.name_scope(self.fc1.name):
+ self.fc1.build([None, None, self.embed_dim])
+ if getattr(self, "fc2", None) is not None:
+ with tf.name_scope(self.fc2.name):
+ self.fc2.build([None, None, self.config.encoder_ffn_dim])
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build([None, None, self.embed_dim])
+
+
+class TFSpeech2TextDecoderLayer(keras.layers.Layer):
+ def __init__(self, config: Speech2TextConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.embed_dim = config.d_model
+
+ self.self_attn = TFSpeech2TextAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ name="self_attn",
+ is_decoder=True,
+ )
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.activation_fn = get_tf_activation(config.activation_function)
+ self.activation_dropout = keras.layers.Dropout(config.activation_dropout)
+
+ self.self_attn_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="self_attn_layer_norm")
+ self.encoder_attn = TFSpeech2TextAttention(
+ self.embed_dim,
+ config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ name="encoder_attn",
+ is_decoder=True,
+ )
+ self.encoder_attn_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="encoder_attn_layer_norm")
+ self.fc1 = keras.layers.Dense(config.decoder_ffn_dim, name="fc1")
+ self.fc2 = keras.layers.Dense(self.embed_dim, name="fc2")
+ self.final_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="final_layer_norm")
+ self.config = config
+
+ def call(
+ self,
+ hidden_states,
+ attention_mask: tf.Tensor | None = None,
+ encoder_hidden_states: tf.Tensor | None = None,
+ encoder_attention_mask: tf.Tensor | None = None,
+ layer_head_mask: tf.Tensor | None = None,
+ cross_attn_layer_head_mask: tf.Tensor | None = None,
+ past_key_value: tuple[tf.Tensor] | None = None,
+ training=False,
+ ) -> tuple[tf.Tensor, tf.Tensor, tuple[tuple[tf.Tensor]]]:
+ """
+ Args:
+ hidden_states (`tf.Tensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`tf.Tensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`tf.Tensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`tf.Tensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`tf.Tensor`): mask for attention heads in a given layer of size
+ `(decoder_attention_heads,)`
+ cross_attn_layer_head_mask (`tf.Tensor`): mask for heads of the cross-attention module.
+ `(decoder_attention_heads,)`
+ past_key_value (`Tuple(tf.Tensor)`): cached past key and value projection states
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ # decoder uni-directional self-attention cached key/values tuple is at positions 1,2
+ self_attn_past_key_value = past_key_value[:2] if past_key_value is not None else None
+ # add present self-attn cache to positions 1,2 of present_key_value tuple
+ hidden_states, self_attn_weights, present_key_value = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_value=self_attn_past_key_value,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ training=training,
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_present_key_value = None
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ # cross_attn cached key/values tuple is at positions 3,4 of present_key_value tuple
+ cross_attn_past_key_value = past_key_value[-2:] if past_key_value is not None else None
+ hidden_states, cross_attn_weights, cross_attn_present_key_value = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_value=cross_attn_past_key_value,
+ training=training,
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ # add cross-attn to positions 3,4 of present_key_value tuple
+ present_key_value = present_key_value + cross_attn_present_key_value
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout(hidden_states, training=training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ return (
+ hidden_states,
+ self_attn_weights,
+ cross_attn_weights,
+ present_key_value,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attn", None) is not None:
+ with tf.name_scope(self.self_attn.name):
+ self.self_attn.build(None)
+ if getattr(self, "self_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.self_attn_layer_norm.name):
+ self.self_attn_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "encoder_attn", None) is not None:
+ with tf.name_scope(self.encoder_attn.name):
+ self.encoder_attn.build(None)
+ if getattr(self, "encoder_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.encoder_attn_layer_norm.name):
+ self.encoder_attn_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "fc1", None) is not None:
+ with tf.name_scope(self.fc1.name):
+ self.fc1.build([None, None, self.embed_dim])
+ if getattr(self, "fc2", None) is not None:
+ with tf.name_scope(self.fc2.name):
+ self.fc2.build([None, None, self.config.decoder_ffn_dim])
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build([None, None, self.embed_dim])
+
+
+class TFSpeech2TextPreTrainedModel(TFPreTrainedModel):
+ config_class = Speech2TextConfig
+ base_model_prefix = "model"
+ main_input_name = "input_features"
+ _keys_to_ignore_on_load_unexpected = [r"encoder.embed_positions.weights"]
+
+ def _get_feat_extract_output_lengths(self, input_lengths: tf.Tensor):
+ """
+ Computes the output length of the convolutional layers
+ """
+ for _ in range(self.config.num_conv_layers):
+ input_lengths = (input_lengths - 1) // 2 + 1
+
+ return input_lengths
+
+ @property
+ def input_signature(self):
+ return {
+ "input_features": tf.TensorSpec(
+ (None, None, self.config.input_feat_per_channel * self.config.input_channels),
+ tf.float32,
+ name="input_features",
+ ),
+ "attention_mask": tf.TensorSpec((None, None), tf.int32, name="attention_mask"),
+ "decoder_input_ids": tf.TensorSpec((None, None), tf.int32, name="decoder_input_ids"),
+ "decoder_attention_mask": tf.TensorSpec((None, None), tf.int32, name="decoder_attention_mask"),
+ }
+
+
+SPEECH_TO_TEXT_START_DOCSTRING = r"""
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Parameters:
+ config ([`Speech2TextConfig`]):
+ Model configuration class with all the parameters of the model. Initializing with a config file does not
+ load the weights associated with the model, only the configuration. Check out the
+ [`~TFPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+
+SPEECH_TO_TEXT_INPUTS_DOCSTRING = r"""
+ Args:
+ input_features (`tf.Tensor` of shape `(batch_size, sequence_length, feature_size)`):
+ Float values of fbank features extracted from the raw speech waveform. Raw speech waveform can be obtained
+ by loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray or a
+ `torch.Tensor``, *e.g.* via the torchcodec library (`pip install torchcodec`) or the soundfile library
+ (`pip install soundfile`).
+ To prepare the arrayinto `input_features`, the [`AutoFeatureExtractor`] should be used for extracting
+ the fbank features, padding and conversion into a tensor of floats.
+ See [`~Speech2TextFeatureExtractor.__call__`]
+ attention_mask (`tf.Tensor` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ decoder_input_ids (`tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`Speech2TextTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ SpeechToText uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ For translation and summarization training, `decoder_input_ids` should be provided. If no
+ `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right
+ for denoising pre-training following the paper.
+ decoder_attention_mask (`tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ will be made by default and ignore pad tokens. It is not recommended to set this for most use cases.
+ head_mask (`tf.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in the encoder. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ decoder_head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in the decoder. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ encoder_outputs (`tf.FloatTensor`, *optional*):
+ hidden states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ of shape `(batch_size, sequence_length, hidden_size)` is a sequence of
+ past_key_values (`tuple[tuple[tf.Tensor]]` of length `config.n_layers`)
+ contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ decoder_inputs_embeds (`tf.FloatTensor` of shape `(batch_size, target_sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `decoder_input_ids` you can choose to directly pass an embedded
+ representation. If `past_key_values` is used, optionally only the last `decoder_inputs_embeds` have to be
+ input (see `past_key_values`). This is useful if you want more control over how to convert
+ `decoder_input_ids` indices into associated vectors than the model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+
+@keras_serializable
+class TFSpeech2TextEncoder(keras.layers.Layer):
+ config_class = Speech2TextConfig
+ """
+ Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a
+ [`TFSpeech2TextEncoderLayer`].
+
+ Args:
+ config: Speech2TextConfig
+ """
+
+ def __init__(self, config: Speech2TextConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.layerdrop = config.encoder_layerdrop
+
+ embed_dim = config.d_model
+ self.padding_idx = config.pad_token_id
+ self.max_source_positions = config.max_source_positions
+ self.embed_scale = tf.math.sqrt(float(embed_dim)) if config.scale_embedding else 1.0
+
+ self.conv = TFConv1dSubsampler(config, name="conv")
+
+ self.embed_positions = TFSpeech2TextSinusoidalPositionalEmbedding(
+ num_positions=config.max_source_positions,
+ embedding_dim=embed_dim,
+ padding_idx=self.padding_idx,
+ name="embed_positions",
+ )
+ self.layers = [TFSpeech2TextEncoderLayer(config, name=f"layers.{i}") for i in range(config.encoder_layers)]
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="layer_norm")
+
+ def _get_feat_extract_output_lengths(self, input_lengths: tf.Tensor):
+ """
+ Computes the output length of the convolutional layers
+ """
+ for _ in range(self.config.num_conv_layers):
+ input_lengths = (input_lengths - 1) // 2 + 1
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(self, feature_vector_length, attention_mask):
+ # generate creates 3D attention mask, because of the shape of input_features
+ # convert it to 2D if that's the case
+ if len(attention_mask.shape) > 2:
+ attention_mask = attention_mask[:, :, -1]
+
+ subsampled_lengths = self._get_feat_extract_output_lengths(tf.math.reduce_sum(attention_mask, -1))
+ bsz = shape_list(attention_mask)[0]
+ indices = tf.concat(
+ (
+ tf.expand_dims(tf.range(bsz, dtype=attention_mask.dtype), -1),
+ tf.expand_dims(subsampled_lengths - 1, -1),
+ ),
+ axis=-1,
+ )
+ attention_mask = tf.scatter_nd(indices=indices, updates=tf.ones(bsz), shape=[bsz, feature_vector_length])
+ attention_mask = tf.cast(tf.reverse(tf.math.cumsum(tf.reverse(attention_mask, [-1]), -1), [-1]), tf.int64)
+ return attention_mask
+
+ @unpack_inputs
+ def call(
+ self,
+ input_features=None,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ ):
+ """
+ Args:
+ input_features (`tf.Tensor` of shape `(batch_size, sequence_length, feature_size)`):
+ Float values of fbank features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a
+ `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library (`pip install torchcodec`) or
+ the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the fbank features,
+ padding and conversion into a tensor of floats. See [`~Speech2TextFeatureExtractor.__call__`]
+ attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`tf.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, `optional):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ if input_features is None:
+ raise ValueError("You have to specify input_features")
+
+ inputs_embeds = self.conv(input_features)
+ inputs_embeds = self.embed_scale * inputs_embeds
+
+ # subsample attention mask if necessary
+ if attention_mask is not None:
+ attention_mask = self._get_feature_vector_attention_mask(tf.shape(inputs_embeds)[1], attention_mask)
+ padding_mask = tf.cast(tf.math.not_equal(attention_mask, 1), tf.int64)
+ else:
+ padding_mask = tf.zeros(tf.shape(inputs_embeds)[:-1], dtype=tf.int64)
+
+ embed_pos = self.embed_positions(padding_mask)
+
+ hidden_states = inputs_embeds + embed_pos
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ # check attention mask and invert
+ if attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _expand_mask(attention_mask)
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ # check if head_mask has a correct number of layers specified if desired
+ if head_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(head_mask)[0],
+ len(self.layers),
+ message=(
+ f"The head_mask should be specified for {len(self.layers)} layers, but it is for"
+ f" {shape_list(head_mask)[0]}."
+ ),
+ )
+
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = random.uniform(0, 1)
+ if training and (dropout_probability < self.layerdrop): # skip the layer
+ continue
+
+ hidden_states, attn = encoder_layer(
+ hidden_states,
+ attention_mask,
+ head_mask[idx] if head_mask is not None else None,
+ training=training,
+ )
+
+ if output_attentions:
+ all_attentions += (attn,)
+
+ hidden_states = self.layer_norm(hidden_states)
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return TFBaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv", None) is not None:
+ with tf.name_scope(self.conv.name):
+ self.conv.build(None)
+ if getattr(self, "embed_positions", None) is not None:
+ with tf.name_scope(self.embed_positions.name):
+ self.embed_positions.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.d_model])
+ if getattr(self, "layers", None) is not None:
+ for layer in self.layers:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@keras_serializable
+class TFSpeech2TextDecoder(keras.layers.Layer):
+ config_class = Speech2TextConfig
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`TFSpeech2TextDecoderLayer`]
+
+ Args:
+ config: Speech2TextConfig
+ """
+
+ def __init__(self, config: Speech2TextConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.layerdrop = config.decoder_layerdrop
+ self.padding_idx = config.pad_token_id
+ self.max_target_positions = config.max_target_positions
+ self.embed_scale = tf.math.sqrt(float(config.d_model)) if config.scale_embedding else 1.0
+
+ self.embed_tokens = TFSharedEmbeddings(config.vocab_size, config.d_model, name="embed_tokens")
+
+ self.embed_positions = TFSpeech2TextSinusoidalPositionalEmbedding(
+ num_positions=config.max_target_positions,
+ embedding_dim=config.d_model,
+ padding_idx=self.padding_idx,
+ name="embed_positions",
+ )
+
+ self.layers = [TFSpeech2TextDecoderLayer(config, name=f"layers.{i}") for i in range(config.decoder_layers)]
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="layer_norm")
+
+ self.dropout = keras.layers.Dropout(config.dropout)
+
+ def get_embed_tokens(self):
+ return self.embed_tokens
+
+ def set_embed_tokens(self, embed_tokens):
+ self.embed_tokens = embed_tokens
+
+ @unpack_inputs
+ def call(
+ self,
+ input_ids=None,
+ inputs_embeds=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ ):
+ r"""
+ Args:
+ input_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you
+ provide it.
+
+ Indices can be obtained using [`Speech2TextTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ encoder_hidden_states (`tf.Tensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ encoder_attention_mask (`tf.Tensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`tuple[tuple[tf.Tensor]]` of length `config.n_layers` with each tuple having 2 tuples each of which has 2 tensors of shape `(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`):
+ Contains precomputed key and value hidden-states of the attention blocks. Can be used to speed up
+ decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those
+ that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of
+ all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = shape_list(input_ids)
+ elif inputs_embeds is not None:
+ input_shape = shape_list(inputs_embeds)[:-1]
+ else:
+ raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds")
+
+ # past_key_values_length
+ past_key_values_length = shape_list(past_key_values[0][0])[2] if past_key_values is not None else 0
+
+ if inputs_embeds is None:
+ check_embeddings_within_bounds(input_ids, self.embed_tokens.vocab_size)
+ inputs_embeds = self.embed_tokens(input_ids) * self.embed_scale
+ else:
+ inputs_embeds = inputs_embeds
+
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ if input_shape[-1] > 1:
+ combined_attention_mask = _make_causal_mask(input_shape, past_key_values_length=past_key_values_length)
+ else:
+ combined_attention_mask = _expand_mask(
+ tf.ones((input_shape[0], input_shape[1] + past_key_values_length)), tgt_len=input_shape[-1]
+ )
+
+ if attention_mask is not None:
+ combined_attention_mask = combined_attention_mask + _expand_mask(attention_mask, tgt_len=input_shape[-1])
+
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _expand_mask(encoder_attention_mask, tgt_len=input_shape[-1])
+
+ # embed positions
+ positions = self.embed_positions(input_ids, past_key_values_length=past_key_values_length)
+
+ hidden_states = inputs_embeds + positions
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attns = () if (output_attentions and encoder_hidden_states is not None) else None
+ next_decoder_cache = () if use_cache else None
+
+ # check if head_mask and cross_attn_head_mask have a correct number of layers specified if desired
+ for attn_mask_name, attn_mask in [("head_mask", head_mask), ("cross_attn_head_mask", cross_attn_head_mask)]:
+ if attn_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(attn_mask)[0],
+ len(self.layers),
+ message=(
+ f"The {attn_mask_name} should be specified for {len(self.layers)} layers, but it is for"
+ f" {shape_list(attn_mask)[0]}."
+ ),
+ )
+
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ dropout_probability = random.uniform(0, 1)
+ if training and (dropout_probability < self.layerdrop):
+ continue
+
+ past_key_value = past_key_values[idx] if past_key_values is not None else None
+ cross_attn_layer_head_mask = cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None
+
+ hidden_states, layer_self_attn, layer_cross_attn, present_key_value = decoder_layer(
+ hidden_states,
+ attention_mask=combined_attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ layer_head_mask=head_mask[idx] if head_mask is not None else None,
+ cross_attn_layer_head_mask=cross_attn_layer_head_mask,
+ past_key_value=past_key_value,
+ )
+
+ if use_cache:
+ next_decoder_cache += (present_key_value,)
+
+ if output_attentions:
+ all_self_attns += (layer_self_attn,)
+
+ if encoder_hidden_states is not None:
+ all_cross_attns += (layer_cross_attn,)
+
+ hidden_states = self.layer_norm(hidden_states)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ next_cache = next_decoder_cache if use_cache else None
+
+ if not return_dict:
+ return hidden_states, next_cache, all_hidden_states, all_self_attns, all_cross_attns
+ else:
+ return TFBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attns,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "embed_tokens", None) is not None:
+ with tf.name_scope(self.embed_tokens.name):
+ self.embed_tokens.build(None)
+ if getattr(self, "embed_positions", None) is not None:
+ with tf.name_scope(self.embed_positions.name):
+ self.embed_positions.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.d_model])
+ if getattr(self, "layers", None) is not None:
+ for layer in self.layers:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@keras_serializable
+class TFSpeech2TextMainLayer(keras.layers.Layer):
+ config_class = Speech2TextConfig
+
+ def __init__(self, config: Speech2TextConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+
+ self.encoder = TFSpeech2TextEncoder(config, name="encoder")
+ self.decoder = TFSpeech2TextDecoder(config, name="decoder")
+
+ def get_input_embeddings(self):
+ return self.decoder.embed_tokens
+
+ def set_input_embeddings(self, new_embeddings):
+ self.decoder.embed_tokens = new_embeddings
+
+ @unpack_inputs
+ def call(
+ self,
+ input_features=None,
+ attention_mask=None,
+ decoder_input_ids=None,
+ decoder_attention_mask=None,
+ head_mask=None,
+ decoder_head_mask=None,
+ cross_attn_head_mask=None,
+ encoder_outputs=None,
+ past_key_values=None,
+ decoder_inputs_embeds=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ **kwargs,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_features=input_features,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ # If the user passed a tuple for encoder_outputs, we wrap it in a TFBaseModelOutput when return_dict=True
+ elif return_dict and not isinstance(encoder_outputs, TFBaseModelOutput):
+ encoder_outputs = TFBaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+ # If the user passed a TFBaseModelOutput for encoder_outputs, we wrap it in a tuple when return_dict=False
+ elif not return_dict and not isinstance(encoder_outputs, tuple):
+ encoder_outputs = encoder_outputs.to_tuple()
+
+ # downsample encoder attention mask
+ if attention_mask is not None:
+ encoder_attention_mask = self.encoder._get_feature_vector_attention_mask(
+ tf.shape(encoder_outputs[0])[1], attention_mask
+ )
+ else:
+ encoder_attention_mask = None
+
+ # decoder outputs consists of (dec_features, past_key_value, dec_hidden, dec_attn)
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_outputs[0],
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return TFSeq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "decoder", None) is not None:
+ with tf.name_scope(self.decoder.name):
+ self.decoder.build(None)
+
+
+@add_start_docstrings(
+ "The bare Speech2Text Model outputting raw hidden-states without any specific head on top.",
+ SPEECH_TO_TEXT_START_DOCSTRING,
+)
+class TFSpeech2TextModel(TFSpeech2TextPreTrainedModel):
+ def __init__(self, config: Speech2TextConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.model = TFSpeech2TextMainLayer(config, name="model")
+
+ def get_encoder(self):
+ return self.model.encoder
+
+ def get_decoder(self):
+ return self.model.decoder
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(SPEECH_TO_TEXT_INPUTS_DOCSTRING)
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFSeq2SeqModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_features: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_input_ids: np.ndarray | tf.Tensor | None = None,
+ decoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_head_mask: np.ndarray | tf.Tensor | None = None,
+ cross_attn_head_mask: np.ndarray | tf.Tensor | None = None,
+ encoder_outputs: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ decoder_inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ **kwargs,
+ ) -> tuple | TFSeq2SeqModelOutput:
+ outputs = self.model(
+ input_features=input_features,
+ attention_mask=attention_mask,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def serving_output(self, output):
+ pkv = tf.tuple(output.past_key_values)[1] if self.config.use_cache else None
+ dec_hs = tf.convert_to_tensor(output.decoder_hidden_states) if self.config.output_hidden_states else None
+ dec_attns = tf.convert_to_tensor(output.decoder_attentions) if self.config.output_attentions else None
+ cross_attns = tf.convert_to_tensor(output.cross_attentions) if self.config.output_attentions else None
+ enc_hs = tf.convert_to_tensor(output.encoder_hidden_states) if self.config.output_hidden_states else None
+ enc_attns = tf.convert_to_tensor(output.encoder_attentions) if self.config.output_attentions else None
+
+ return TFSeq2SeqModelOutput(
+ last_hidden_state=output.last_hidden_state,
+ past_key_values=pkv,
+ decoder_hidden_states=dec_hs,
+ decoder_attentions=dec_attns,
+ cross_attentions=cross_attns,
+ encoder_last_hidden_state=output.encoder_last_hidden_state,
+ encoder_hidden_states=enc_hs,
+ encoder_attentions=enc_attns,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "model", None) is not None:
+ with tf.name_scope(self.model.name):
+ self.model.build(None)
+
+
+@add_start_docstrings(
+ "The Speech2Text Model with a language modeling head. Can be used for summarization.",
+ SPEECH_TO_TEXT_START_DOCSTRING,
+)
+class TFSpeech2TextForConditionalGeneration(TFSpeech2TextPreTrainedModel, TFCausalLanguageModelingLoss):
+ def __init__(self, config: Speech2TextConfig):
+ super().__init__(config)
+ self.model = TFSpeech2TextMainLayer(config, name="model")
+ self.lm_head = keras.layers.Dense(self.config.vocab_size, use_bias=False, name="lm_head")
+ # TODO (Joao): investigate why Speech2Text has numerical issues in XLA generate
+ self.supports_xla_generation = False
+ self.config = config
+
+ def get_encoder(self):
+ return self.model.encoder
+
+ def get_decoder(self):
+ return self.model.decoder
+
+ def resize_token_embeddings(self, new_num_tokens: int) -> tf.Variable:
+ new_embeddings = super().resize_token_embeddings(new_num_tokens)
+ return new_embeddings
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(SPEECH_TO_TEXT_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_features: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_input_ids: np.ndarray | tf.Tensor | None = None,
+ decoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_head_mask: np.ndarray | tf.Tensor | None = None,
+ cross_attn_head_mask: np.ndarray | tf.Tensor | None = None,
+ encoder_outputs: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ decoder_inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ **kwargs,
+ ) -> tuple | TFSeq2SeqLMOutput:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Returns:
+
+ Example:
+
+ ```python
+ >>> import tensorflow as tf
+ >>> from transformers import Speech2TextProcessor, TFSpeech2TextForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> model = TFSpeech2TextForConditionalGeneration.from_pretrained(
+ ... "facebook/s2t-small-librispeech-asr", from_pt=True
+ ... )
+ >>> processor = Speech2TextProcessor.from_pretrained("facebook/s2t-small-librispeech-asr")
+
+
+ >>> def map_to_array(example):
+ ... example["speech"] = example["audio"]["array"]
+ ... return example
+
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> ds = ds.map(map_to_array)
+ >>> ds.set_format(type="tf")
+
+ >>> input_features = processor(
+ ... ds["speech"][0], sampling_rate=16000, return_tensors="tf"
+ ... ).input_features # Batch size 1
+ >>> generated_ids = model.generate(input_features)
+
+ >>> transcription = processor.batch_decode(generated_ids)
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ outputs = self.model(
+ input_features=input_features,
+ attention_mask=attention_mask,
+ decoder_input_ids=decoder_input_ids,
+ encoder_outputs=encoder_outputs,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ lm_logits = self.lm_head(outputs[0])
+ masked_lm_loss = None if labels is None else self.hf_compute_loss(labels, lm_logits)
+
+ if not return_dict:
+ output = (lm_logits,) + outputs[1:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return TFSeq2SeqLMOutput(
+ loss=masked_lm_loss,
+ logits=lm_logits,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+ def serving_output(self, output):
+ pkv = tf.tuple(output.past_key_values)[1] if self.config.use_cache else None
+ dec_hs = tf.convert_to_tensor(output.decoder_hidden_states) if self.config.output_hidden_states else None
+ dec_attns = tf.convert_to_tensor(output.decoder_attentions) if self.config.output_attentions else None
+ cross_attns = tf.convert_to_tensor(output.cross_attentions) if self.config.output_attentions else None
+ enc_hs = tf.convert_to_tensor(output.encoder_hidden_states) if self.config.output_hidden_states else None
+ enc_attns = tf.convert_to_tensor(output.encoder_attentions) if self.config.output_attentions else None
+
+ return TFSeq2SeqLMOutput(
+ logits=output.logits,
+ past_key_values=pkv,
+ decoder_hidden_states=dec_hs,
+ decoder_attentions=dec_attns,
+ cross_attentions=cross_attns,
+ encoder_last_hidden_state=output.encoder_last_hidden_state,
+ encoder_hidden_states=enc_hs,
+ encoder_attentions=enc_attns,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ decoder_input_ids,
+ past_key_values=None,
+ attention_mask=None,
+ head_mask=None,
+ decoder_head_mask=None,
+ cross_attn_head_mask=None,
+ use_cache=None,
+ encoder_outputs=None,
+ **kwargs,
+ ):
+ # cut decoder_input_ids if past is used
+ if past_key_values is not None:
+ decoder_input_ids = decoder_input_ids[:, -1:]
+
+ return {
+ "input_features": None, # needs to be passed to make Keras.layer.__call__ happy
+ "encoder_outputs": encoder_outputs,
+ "past_key_values": past_key_values,
+ "decoder_input_ids": decoder_input_ids,
+ "attention_mask": attention_mask,
+ "head_mask": head_mask,
+ "decoder_head_mask": decoder_head_mask,
+ "cross_attn_head_mask": cross_attn_head_mask,
+ "use_cache": use_cache, # change this to avoid caching (presumably for debugging)
+ }
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "model", None) is not None:
+ with tf.name_scope(self.model.name):
+ self.model.build(None)
+ if getattr(self, "lm_head", None) is not None:
+ with tf.name_scope(self.lm_head.name):
+ self.lm_head.build([None, None, self.config.d_model])
+
+ def tf_to_pt_weight_rename(self, tf_weight):
+ if tf_weight == "lm_head.weight":
+ return tf_weight, "model.decoder.embed_tokens.weight"
+ else:
+ return (tf_weight,)
+
+
+__all__ = ["TFSpeech2TextForConditionalGeneration", "TFSpeech2TextModel", "TFSpeech2TextPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/processing_speech_to_text.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/processing_speech_to_text.py
new file mode 100644
index 0000000000000000000000000000000000000000..2df5808b9f66c0421471fd17b14eded19d36767b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/processing_speech_to_text.py
@@ -0,0 +1,106 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Speech processor class for Speech2Text
+"""
+
+import warnings
+from contextlib import contextmanager
+
+from ...processing_utils import ProcessorMixin
+
+
+class Speech2TextProcessor(ProcessorMixin):
+ r"""
+ Constructs a Speech2Text processor which wraps a Speech2Text feature extractor and a Speech2Text tokenizer into a
+ single processor.
+
+ [`Speech2TextProcessor`] offers all the functionalities of [`Speech2TextFeatureExtractor`] and
+ [`Speech2TextTokenizer`]. See the [`~Speech2TextProcessor.__call__`] and [`~Speech2TextProcessor.decode`] for more
+ information.
+
+ Args:
+ feature_extractor (`Speech2TextFeatureExtractor`):
+ An instance of [`Speech2TextFeatureExtractor`]. The feature extractor is a required input.
+ tokenizer (`Speech2TextTokenizer`):
+ An instance of [`Speech2TextTokenizer`]. The tokenizer is a required input.
+ """
+
+ feature_extractor_class = "Speech2TextFeatureExtractor"
+ tokenizer_class = "Speech2TextTokenizer"
+
+ def __init__(self, feature_extractor, tokenizer):
+ super().__init__(feature_extractor, tokenizer)
+ self.current_processor = self.feature_extractor
+ self._in_target_context_manager = False
+
+ def __call__(self, *args, **kwargs):
+ """
+ When used in normal mode, this method forwards all its arguments to Speech2TextFeatureExtractor's
+ [`~Speech2TextFeatureExtractor.__call__`] and returns its output. If used in the context
+ [`~Speech2TextProcessor.as_target_processor`] this method forwards all its arguments to Speech2TextTokenizer's
+ [`~Speech2TextTokenizer.__call__`]. Please refer to the docstring of the above two methods for more
+ information.
+ """
+ # For backward compatibility
+ if self._in_target_context_manager:
+ return self.current_processor(*args, **kwargs)
+
+ if "raw_speech" in kwargs:
+ warnings.warn("Using `raw_speech` as a keyword argument is deprecated. Use `audio` instead.")
+ audio = kwargs.pop("raw_speech")
+ else:
+ audio = kwargs.pop("audio", None)
+ sampling_rate = kwargs.pop("sampling_rate", None)
+ text = kwargs.pop("text", None)
+ if len(args) > 0:
+ audio = args[0]
+ args = args[1:]
+
+ if audio is None and text is None:
+ raise ValueError("You need to specify either an `audio` or `text` input to process.")
+
+ if audio is not None:
+ inputs = self.feature_extractor(audio, *args, sampling_rate=sampling_rate, **kwargs)
+ if text is not None:
+ encodings = self.tokenizer(text, **kwargs)
+
+ if text is None:
+ return inputs
+ elif audio is None:
+ return encodings
+ else:
+ inputs["labels"] = encodings["input_ids"]
+ return inputs
+
+ @contextmanager
+ def as_target_processor(self):
+ """
+ Temporarily sets the tokenizer for processing the input. Useful for encoding the labels when fine-tuning
+ Speech2Text.
+ """
+ warnings.warn(
+ "`as_target_processor` is deprecated and will be removed in v5 of Transformers. You can process your "
+ "labels by using the argument `text` of the regular `__call__` method (either in the same call as "
+ "your audio inputs, or in a separate call."
+ )
+ self._in_target_context_manager = True
+ self.current_processor = self.tokenizer
+ yield
+ self.current_processor = self.feature_extractor
+ self._in_target_context_manager = False
+
+
+__all__ = ["Speech2TextProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/tokenization_speech_to_text.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/tokenization_speech_to_text.py
new file mode 100644
index 0000000000000000000000000000000000000000..e1e694cb9583957ba353f286a8f279e306e20c76
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speech_to_text/tokenization_speech_to_text.py
@@ -0,0 +1,295 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for Speech2Text."""
+
+import json
+import os
+from pathlib import Path
+from shutil import copyfile
+from typing import Any, Optional, Union
+
+import sentencepiece
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...utils import logging
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+SPIECE_UNDERLINE = "▁"
+
+VOCAB_FILES_NAMES = {
+ "vocab_file": "vocab.json",
+ "spm_file": "sentencepiece.bpe.model",
+}
+
+
+MAX_MODEL_INPUT_SIZES = {
+ "facebook/s2t-small-librispeech-asr": 1024,
+}
+
+MUSTC_LANGS = ["pt", "fr", "ru", "nl", "ro", "it", "es", "de"]
+
+LANGUAGES = {"mustc": MUSTC_LANGS}
+
+
+@requires(backends=("sentencepiece",))
+class Speech2TextTokenizer(PreTrainedTokenizer):
+ """
+ Construct an Speech2Text tokenizer.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains some of the main methods. Users should refer to
+ the superclass for more information regarding such methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ spm_file (`str`):
+ Path to the [SentencePiece](https://github.com/google/sentencepiece) model file
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sentence token.
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sentence token.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ do_upper_case (`bool`, *optional*, defaults to `False`):
+ Whether or not to uppercase the output when decoding.
+ do_lower_case (`bool`, *optional*, defaults to `False`):
+ Whether or not to lowercase the input when tokenizing.
+ tgt_lang (`str`, *optional*):
+ A string representing the target language.
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+
+ **kwargs
+ Additional keyword arguments passed along to [`PreTrainedTokenizer`]
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ prefix_tokens: list[int] = []
+
+ def __init__(
+ self,
+ vocab_file,
+ spm_file,
+ bos_token="",
+ eos_token=" ",
+ pad_token="",
+ unk_token="",
+ do_upper_case=False,
+ do_lower_case=False,
+ tgt_lang=None,
+ lang_codes=None,
+ additional_special_tokens=None,
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ **kwargs,
+ ) -> None:
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+
+ self.do_upper_case = do_upper_case
+ self.do_lower_case = do_lower_case
+
+ self.encoder = load_json(vocab_file)
+ self.decoder = {v: k for k, v in self.encoder.items()}
+ self.spm_file = spm_file
+ self.sp_model = load_spm(spm_file, self.sp_model_kwargs)
+
+ if lang_codes is not None:
+ self.lang_codes = lang_codes
+ self.langs = LANGUAGES[lang_codes]
+ self.lang_tokens = [f"" for lang in self.langs]
+ self.lang_code_to_id = {lang: self.sp_model.PieceToId(f"") for lang in self.langs}
+ if additional_special_tokens is not None:
+ additional_special_tokens = self.lang_tokens + additional_special_tokens
+ else:
+ additional_special_tokens = self.lang_tokens
+ self._tgt_lang = tgt_lang if tgt_lang is not None else self.langs[0]
+
+ self.set_tgt_lang_special_tokens(self._tgt_lang)
+ else:
+ self.lang_code_to_id = {}
+
+ super().__init__(
+ bos_token=bos_token,
+ eos_token=eos_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ do_upper_case=do_upper_case,
+ do_lower_case=do_lower_case,
+ tgt_lang=tgt_lang,
+ lang_codes=lang_codes,
+ sp_model_kwargs=self.sp_model_kwargs,
+ additional_special_tokens=additional_special_tokens,
+ **kwargs,
+ )
+
+ @property
+ def vocab_size(self) -> int:
+ return len(self.encoder)
+
+ def get_vocab(self) -> dict:
+ vocab = self.encoder.copy()
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ @property
+ def tgt_lang(self) -> str:
+ return self._tgt_lang
+
+ @tgt_lang.setter
+ def tgt_lang(self, new_tgt_lang) -> None:
+ self._tgt_lang = new_tgt_lang
+ self.set_tgt_lang_special_tokens(new_tgt_lang)
+
+ def set_tgt_lang_special_tokens(self, tgt_lang: str) -> None:
+ """Reset the special tokens to the target language setting. prefix=[eos, tgt_lang_code] and suffix=[eos]."""
+ lang_code_id = self.lang_code_to_id[tgt_lang]
+ self.prefix_tokens = [lang_code_id]
+
+ def _tokenize(self, text: str) -> list[str]:
+ return self.sp_model.encode(text, out_type=str)
+
+ def _convert_token_to_id(self, token):
+ return self.encoder.get(token, self.encoder[self.unk_token])
+
+ def _convert_id_to_token(self, index: int) -> str:
+ """Converts an index (integer) in a token (str) using the decoder."""
+ return self.decoder.get(index, self.unk_token)
+
+ def convert_tokens_to_string(self, tokens: list[str]) -> str:
+ """Converts a sequence of tokens (strings for sub-words) in a single string."""
+ current_sub_tokens = []
+ out_string = ""
+ for token in tokens:
+ # make sure that special tokens are not decoded using sentencepiece model
+ if token in self.all_special_tokens:
+ decoded = self.sp_model.decode(current_sub_tokens)
+ out_string += (decoded.upper() if self.do_upper_case else decoded) + token + " "
+ current_sub_tokens = []
+ else:
+ current_sub_tokens.append(token)
+ decoded = self.sp_model.decode(current_sub_tokens)
+ out_string += decoded.upper() if self.do_upper_case else decoded
+ return out_string.strip()
+
+ def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None) -> list[int]:
+ """Build model inputs from a sequence by appending eos_token_id."""
+ if token_ids_1 is None:
+ return self.prefix_tokens + token_ids_0 + [self.eos_token_id]
+ # We don't expect to process pairs, but leave the pair logic for API consistency
+ return self.prefix_tokens + token_ids_0 + token_ids_1 + [self.eos_token_id]
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ prefix_ones = [1] * len(self.prefix_tokens)
+ suffix_ones = [1]
+ if token_ids_1 is None:
+ return prefix_ones + ([0] * len(token_ids_0)) + suffix_ones
+ return prefix_ones + ([0] * len(token_ids_0)) + ([0] * len(token_ids_1)) + suffix_ones
+
+ def __getstate__(self) -> dict:
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ return state
+
+ def __setstate__(self, d: dict) -> None:
+ self.__dict__ = d
+
+ # for backward compatibility
+ if not hasattr(self, "sp_model_kwargs"):
+ self.sp_model_kwargs = {}
+
+ self.sp_model = load_spm(self.spm_file, self.sp_model_kwargs)
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ save_dir = Path(save_directory)
+ assert save_dir.is_dir(), f"{save_directory} should be a directory"
+ vocab_save_path = save_dir / (
+ (filename_prefix + "-" if filename_prefix else "") + self.vocab_files_names["vocab_file"]
+ )
+ spm_save_path = save_dir / (
+ (filename_prefix + "-" if filename_prefix else "") + self.vocab_files_names["spm_file"]
+ )
+
+ save_json(self.encoder, vocab_save_path)
+
+ if os.path.abspath(self.spm_file) != os.path.abspath(spm_save_path) and os.path.isfile(self.spm_file):
+ copyfile(self.spm_file, spm_save_path)
+ elif not os.path.isfile(self.spm_file):
+ with open(spm_save_path, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (str(vocab_save_path), str(spm_save_path))
+
+
+def load_spm(path: str, sp_model_kwargs: dict[str, Any]) -> sentencepiece.SentencePieceProcessor:
+ spm = sentencepiece.SentencePieceProcessor(**sp_model_kwargs)
+ spm.Load(str(path))
+ return spm
+
+
+def load_json(path: str) -> Union[dict, list]:
+ with open(path, "r") as f:
+ return json.load(f)
+
+
+def save_json(data, path: str) -> None:
+ with open(path, "w") as f:
+ json.dump(data, f, indent=2)
+
+
+__all__ = ["Speech2TextTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..52fee59ae9b96d14361a771cbc58089d5e5811f2
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_speecht5 import *
+ from .feature_extraction_speecht5 import *
+ from .modeling_speecht5 import *
+ from .processing_speecht5 import *
+ from .tokenization_speecht5 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/configuration_speecht5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/configuration_speecht5.py
new file mode 100644
index 0000000000000000000000000000000000000000..b73471a29dc4cda3538b08c3da40b9b34d337b14
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/configuration_speecht5.py
@@ -0,0 +1,422 @@
+# coding=utf-8
+# Copyright 2023 The Fairseq Authors, Microsoft Research, and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""SpeechT5 model configuration"""
+
+import functools
+import operator
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class SpeechT5Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SpeechT5Model`]. It is used to instantiate a
+ SpeechT5 model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the SpeechT5
+ [microsoft/speecht5_asr](https://huggingface.co/microsoft/speecht5_asr) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 81):
+ Vocabulary size of the SpeechT5 model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed to the forward method of [`SpeechT5Model`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ encoder_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ encoder_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ encoder_ffn_dim (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ encoder_layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ decoder_layers (`int`, *optional*, defaults to 6):
+ Number of hidden layers in the Transformer decoder.
+ decoder_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ decoder_ffn_dim (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer decoder.
+ decoder_layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability for the decoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ positional_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the text position encoding layers.
+ hidden_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for activations inside the fully connected layer.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-5):
+ The epsilon used by the layer normalization layers.
+ scale_embedding (`bool`, *optional*, defaults to `False`):
+ Scale embeddings by diving by sqrt(d_model).
+ feat_extract_norm (`str`, *optional*, defaults to `"group"`):
+ The norm to be applied to 1D convolutional layers in the speech encoder pre-net. One of `"group"` for group
+ normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D
+ convolutional layers.
+ feat_proj_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for output of the speech encoder pre-net.
+ feat_extract_activation (`str, `optional`, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the 1D convolutional layers of the feature
+ extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 512, 512, 512)`):
+ A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the
+ speech encoder pre-net. The length of *conv_dim* defines the number of 1D convolutional layers.
+ conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 2, 2, 2, 2, 2)`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the speech encoder pre-net. The
+ length of *conv_stride* defines the number of convolutional layers and has to match the length of
+ *conv_dim*.
+ conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 3, 3, 3, 3, 3)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the speech encoder pre-net.
+ The length of *conv_kernel* defines the number of convolutional layers and has to match the length of
+ *conv_dim*.
+ conv_bias (`bool`, *optional*, defaults to `False`):
+ Whether the 1D convolutional layers have a bias.
+ num_conv_pos_embeddings (`int`, *optional*, defaults to 128):
+ Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional
+ embeddings layer.
+ num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16):
+ Number of groups of 1D convolutional positional embeddings layer.
+ apply_spec_augment (`bool`, *optional*, defaults to `True`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the speech encoder pre-net. For
+ reference see [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking
+ procedure generates ''mask_time_prob*len(time_axis)/mask_time_length'' independent masks over the axis. If
+ reasoning from the probability of each feature vector to be chosen as the start of the vector span to be
+ masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the
+ actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2),:
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks''
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The
+ masking procedure generates ''mask_feature_prob*len(feature_axis)/mask_time_length'' independent masks over
+ the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector
+ span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap
+ may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is
+ True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ mask_feature_min_masks (`int`, *optional*, defaults to 0),:
+ The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time
+ step, irrespectively of `mask_feature_prob`. Only relevant if
+ ''mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks''
+ num_mel_bins (`int`, *optional*, defaults to 80):
+ Number of mel features used per input features. Used by the speech decoder pre-net. Should correspond to
+ the value used in the [`SpeechT5Processor`] class.
+ speech_decoder_prenet_layers (`int`, *optional*, defaults to 2):
+ Number of layers in the speech decoder pre-net.
+ speech_decoder_prenet_units (`int`, *optional*, defaults to 256):
+ Dimensionality of the layers in the speech decoder pre-net.
+ speech_decoder_prenet_dropout (`float`, *optional*, defaults to 0.5):
+ The dropout probability for the speech decoder pre-net layers.
+ speaker_embedding_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of the *XVector* embedding vectors.
+ speech_decoder_postnet_layers (`int`, *optional*, defaults to 5):
+ Number of layers in the speech decoder post-net.
+ speech_decoder_postnet_units (`int`, *optional*, defaults to 256):
+ Dimensionality of the layers in the speech decoder post-net.
+ speech_decoder_postnet_kernel (`int`, *optional*, defaults to 5):
+ Number of convolutional filter channels in the speech decoder post-net.
+ speech_decoder_postnet_dropout (`float`, *optional*, defaults to 0.5):
+ The dropout probability for the speech decoder post-net layers.
+ reduction_factor (`int`, *optional*, defaults to 2):
+ Spectrogram length reduction factor for the speech decoder inputs.
+ max_speech_positions (`int`, *optional*, defaults to 4000):
+ The maximum sequence length of speech features that this model might ever be used with.
+ max_text_positions (`int`, *optional*, defaults to 450):
+ The maximum sequence length of text features that this model might ever be used with.
+ encoder_max_relative_position (`int`, *optional*, defaults to 160):
+ Maximum distance for relative position embedding in the encoder.
+ use_guided_attention_loss (`bool`, *optional*, defaults to `True`):
+ Whether to apply guided attention loss while training the TTS model.
+ guided_attention_loss_num_heads (`int`, *optional*, defaults to 2):
+ Number of attention heads the guided attention loss will be applied to. Use -1 to apply this loss to all
+ attention heads.
+ guided_attention_loss_sigma (`float`, *optional*, defaults to 0.4):
+ Standard deviation for guided attention loss.
+ guided_attention_loss_scale (`float`, *optional*, defaults to 10.0):
+ Scaling coefficient for guided attention loss (also known as lambda).
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+
+ Example:
+
+ ```python
+ >>> from transformers import SpeechT5Model, SpeechT5Config
+
+ >>> # Initializing a "microsoft/speecht5_asr" style configuration
+ >>> configuration = SpeechT5Config()
+
+ >>> # Initializing a model (with random weights) from the "microsoft/speecht5_asr" style configuration
+ >>> model = SpeechT5Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "speecht5"
+ attribute_map = {"num_attention_heads": "encoder_attention_heads", "num_hidden_layers": "encoder_layers"}
+
+ def __init__(
+ self,
+ vocab_size=81,
+ hidden_size=768,
+ encoder_layers=12,
+ encoder_attention_heads=12,
+ encoder_ffn_dim=3072,
+ encoder_layerdrop=0.1,
+ decoder_layers=6,
+ decoder_ffn_dim=3072,
+ decoder_attention_heads=12,
+ decoder_layerdrop=0.1,
+ hidden_act="gelu",
+ positional_dropout=0.1,
+ hidden_dropout=0.1,
+ attention_dropout=0.1,
+ activation_dropout=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ scale_embedding=False,
+ feat_extract_norm="group",
+ feat_proj_dropout=0.0,
+ feat_extract_activation="gelu",
+ conv_dim=(512, 512, 512, 512, 512, 512, 512),
+ conv_stride=(5, 2, 2, 2, 2, 2, 2),
+ conv_kernel=(10, 3, 3, 3, 3, 2, 2),
+ conv_bias=False,
+ num_conv_pos_embeddings=128,
+ num_conv_pos_embedding_groups=16,
+ apply_spec_augment=True,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ mask_feature_min_masks=0,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ decoder_start_token_id=2,
+ num_mel_bins=80,
+ speech_decoder_prenet_layers=2,
+ speech_decoder_prenet_units=256,
+ speech_decoder_prenet_dropout=0.5,
+ speaker_embedding_dim=512,
+ speech_decoder_postnet_layers=5,
+ speech_decoder_postnet_units=256,
+ speech_decoder_postnet_kernel=5,
+ speech_decoder_postnet_dropout=0.5,
+ reduction_factor=2,
+ max_speech_positions=4000,
+ max_text_positions=450,
+ encoder_max_relative_position=160,
+ use_guided_attention_loss=True,
+ guided_attention_loss_num_heads=2,
+ guided_attention_loss_sigma=0.4,
+ guided_attention_loss_scale=10.0,
+ use_cache=True,
+ is_encoder_decoder=True,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.encoder_layers = encoder_layers
+ self.encoder_ffn_dim = encoder_ffn_dim
+ self.encoder_attention_heads = encoder_attention_heads
+ self.encoder_layerdrop = encoder_layerdrop
+ self.decoder_layers = decoder_layers
+ self.decoder_ffn_dim = decoder_ffn_dim
+ self.decoder_attention_heads = decoder_attention_heads
+ self.decoder_layerdrop = decoder_layerdrop
+ self.hidden_act = hidden_act
+ self.positional_dropout = positional_dropout
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.scale_embedding = scale_embedding
+
+ self.feat_extract_norm = feat_extract_norm
+ self.feat_proj_dropout = feat_proj_dropout
+ self.feat_extract_activation = feat_extract_activation
+ self.conv_dim = list(conv_dim)
+ self.conv_stride = list(conv_stride)
+ self.conv_kernel = list(conv_kernel)
+ self.conv_bias = conv_bias
+ self.num_conv_pos_embeddings = num_conv_pos_embeddings
+ self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups
+ self.num_feat_extract_layers = len(self.conv_dim)
+
+ if (
+ (len(self.conv_stride) != self.num_feat_extract_layers)
+ or (len(self.conv_kernel) != self.num_feat_extract_layers)
+ or (len(self.conv_dim) != self.num_feat_extract_layers)
+ ):
+ raise ValueError(
+ "Configuration for convolutional layers is incorrect. It is required that `len(config.conv_dim)` =="
+ " `len(config.conv_stride)` == `len(config.conv_kernel)`, but is `len(config.conv_dim) ="
+ f" {len(self.conv_dim)}`, `len(config.conv_stride) = {len(self.conv_stride)}`,"
+ f" `len(config.conv_kernel) = {len(self.conv_kernel)}`."
+ )
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+ self.mask_feature_min_masks = mask_feature_min_masks
+
+ self.num_mel_bins = num_mel_bins
+ self.speech_decoder_prenet_layers = speech_decoder_prenet_layers
+ self.speech_decoder_prenet_units = speech_decoder_prenet_units
+ self.speech_decoder_prenet_dropout = speech_decoder_prenet_dropout
+ self.speaker_embedding_dim = speaker_embedding_dim
+
+ self.speech_decoder_postnet_layers = speech_decoder_postnet_layers
+ self.speech_decoder_postnet_units = speech_decoder_postnet_units
+ self.speech_decoder_postnet_kernel = speech_decoder_postnet_kernel
+ self.speech_decoder_postnet_dropout = speech_decoder_postnet_dropout
+ self.reduction_factor = reduction_factor
+
+ self.max_speech_positions = max_speech_positions
+ self.max_text_positions = max_text_positions
+ self.encoder_max_relative_position = encoder_max_relative_position
+
+ self.use_guided_attention_loss = use_guided_attention_loss
+ self.guided_attention_loss_num_heads = guided_attention_loss_num_heads
+ self.guided_attention_loss_sigma = guided_attention_loss_sigma
+ self.guided_attention_loss_scale = guided_attention_loss_scale
+
+ self.use_cache = use_cache
+ self.is_encoder_decoder = is_encoder_decoder
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ is_encoder_decoder=is_encoder_decoder,
+ decoder_start_token_id=decoder_start_token_id,
+ **kwargs,
+ )
+
+ def inputs_to_logits_ratio(self):
+ return functools.reduce(operator.mul, self.conv_stride, 1)
+
+
+class SpeechT5HifiGanConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SpeechT5HifiGanModel`]. It is used to instantiate
+ a SpeechT5 HiFi-GAN vocoder model according to the specified arguments, defining the model architecture.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the SpeechT5
+ [microsoft/speecht5_hifigan](https://huggingface.co/microsoft/speecht5_hifigan) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ model_in_dim (`int`, *optional*, defaults to 80):
+ The number of frequency bins in the input log-mel spectrogram.
+ sampling_rate (`int`, *optional*, defaults to 16000):
+ The sampling rate at which the output audio will be generated, expressed in hertz (Hz).
+ upsample_initial_channel (`int`, *optional*, defaults to 512):
+ The number of input channels into the upsampling network.
+ upsample_rates (`tuple[int]` or `list[int]`, *optional*, defaults to `[4, 4, 4, 4]`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the upsampling network. The
+ length of *upsample_rates* defines the number of convolutional layers and has to match the length of
+ *upsample_kernel_sizes*.
+ upsample_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[8, 8, 8, 8]`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the upsampling network. The
+ length of *upsample_kernel_sizes* defines the number of convolutional layers and has to match the length of
+ *upsample_rates*.
+ resblock_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[3, 7, 11]`):
+ A tuple of integers defining the kernel sizes of the 1D convolutional layers in the multi-receptive field
+ fusion (MRF) module.
+ resblock_dilation_sizes (`tuple[tuple[int]]` or `list[list[int]]`, *optional*, defaults to `[[1, 3, 5], [1, 3, 5], [1, 3, 5]]`):
+ A nested tuple of integers defining the dilation rates of the dilated 1D convolutional layers in the
+ multi-receptive field fusion (MRF) module.
+ initializer_range (`float`, *optional*, defaults to 0.01):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ leaky_relu_slope (`float`, *optional*, defaults to 0.1):
+ The angle of the negative slope used by the leaky ReLU activation.
+ normalize_before (`bool`, *optional*, defaults to `True`):
+ Whether or not to normalize the spectrogram before vocoding using the vocoder's learned mean and variance.
+
+ Example:
+
+ ```python
+ >>> from transformers import SpeechT5HifiGan, SpeechT5HifiGanConfig
+
+ >>> # Initializing a "microsoft/speecht5_hifigan" style configuration
+ >>> configuration = SpeechT5HifiGanConfig()
+
+ >>> # Initializing a model (with random weights) from the "microsoft/speecht5_hifigan" style configuration
+ >>> model = SpeechT5HifiGan(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "hifigan"
+
+ def __init__(
+ self,
+ model_in_dim=80,
+ sampling_rate=16000,
+ upsample_initial_channel=512,
+ upsample_rates=[4, 4, 4, 4],
+ upsample_kernel_sizes=[8, 8, 8, 8],
+ resblock_kernel_sizes=[3, 7, 11],
+ resblock_dilation_sizes=[[1, 3, 5], [1, 3, 5], [1, 3, 5]],
+ initializer_range=0.01,
+ leaky_relu_slope=0.1,
+ normalize_before=True,
+ **kwargs,
+ ):
+ self.model_in_dim = model_in_dim
+ self.sampling_rate = sampling_rate
+ self.upsample_initial_channel = upsample_initial_channel
+ self.upsample_rates = upsample_rates
+ self.upsample_kernel_sizes = upsample_kernel_sizes
+ self.resblock_kernel_sizes = resblock_kernel_sizes
+ self.resblock_dilation_sizes = resblock_dilation_sizes
+ self.initializer_range = initializer_range
+ self.leaky_relu_slope = leaky_relu_slope
+ self.normalize_before = normalize_before
+ super().__init__(**kwargs)
+
+
+__all__ = ["SpeechT5Config", "SpeechT5HifiGanConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/feature_extraction_speecht5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/feature_extraction_speecht5.py
new file mode 100644
index 0000000000000000000000000000000000000000..822ae01a88d7d9e8714d2ef42bf66aab73418a49
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/feature_extraction_speecht5.py
@@ -0,0 +1,396 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Feature extractor class for SpeechT5."""
+
+import warnings
+from typing import Any, Optional, Union
+
+import numpy as np
+
+from ...audio_utils import mel_filter_bank, optimal_fft_length, spectrogram, window_function
+from ...feature_extraction_sequence_utils import SequenceFeatureExtractor
+from ...feature_extraction_utils import BatchFeature
+from ...utils import PaddingStrategy, TensorType, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class SpeechT5FeatureExtractor(SequenceFeatureExtractor):
+ r"""
+ Constructs a SpeechT5 feature extractor.
+
+ This class can pre-process a raw speech signal by (optionally) normalizing to zero-mean unit-variance, for use by
+ the SpeechT5 speech encoder prenet.
+
+ This class can also extract log-mel filter bank features from raw speech, for use by the SpeechT5 speech decoder
+ prenet.
+
+ This feature extractor inherits from [`~feature_extraction_sequence_utils.SequenceFeatureExtractor`] which contains
+ most of the main methods. Users should refer to this superclass for more information regarding those methods.
+
+ Args:
+ feature_size (`int`, *optional*, defaults to 1):
+ The feature dimension of the extracted features.
+ sampling_rate (`int`, *optional*, defaults to 16000):
+ The sampling rate at which the audio files should be digitalized expressed in hertz (Hz).
+ padding_value (`float`, *optional*, defaults to 0.0):
+ The value that is used to fill the padding values.
+ do_normalize (`bool`, *optional*, defaults to `False`):
+ Whether or not to zero-mean unit-variance normalize the input. Normalizing can help to significantly
+ improve the performance for some models.
+ num_mel_bins (`int`, *optional*, defaults to 80):
+ The number of mel-frequency bins in the extracted spectrogram features.
+ hop_length (`int`, *optional*, defaults to 16):
+ Number of ms between windows. Otherwise referred to as "shift" in many papers.
+ win_length (`int`, *optional*, defaults to 64):
+ Number of ms per window.
+ win_function (`str`, *optional*, defaults to `"hann_window"`):
+ Name for the window function used for windowing, must be accessible via `torch.{win_function}`
+ frame_signal_scale (`float`, *optional*, defaults to 1.0):
+ Constant multiplied in creating the frames before applying DFT. This argument is deprecated.
+ fmin (`float`, *optional*, defaults to 80):
+ Minimum mel frequency in Hz.
+ fmax (`float`, *optional*, defaults to 7600):
+ Maximum mel frequency in Hz.
+ mel_floor (`float`, *optional*, defaults to 1e-10):
+ Minimum value of mel frequency banks.
+ reduction_factor (`int`, *optional*, defaults to 2):
+ Spectrogram length reduction factor. This argument is deprecated.
+ return_attention_mask (`bool`, *optional*, defaults to `True`):
+ Whether or not [`~SpeechT5FeatureExtractor.__call__`] should return `attention_mask`.
+ """
+
+ model_input_names = ["input_values", "attention_mask"]
+
+ def __init__(
+ self,
+ feature_size: int = 1,
+ sampling_rate: int = 16000,
+ padding_value: float = 0.0,
+ do_normalize: bool = False,
+ num_mel_bins: int = 80,
+ hop_length: int = 16,
+ win_length: int = 64,
+ win_function: str = "hann_window",
+ frame_signal_scale: float = 1.0,
+ fmin: float = 80,
+ fmax: float = 7600,
+ mel_floor: float = 1e-10,
+ reduction_factor: int = 2,
+ return_attention_mask: bool = True,
+ **kwargs,
+ ):
+ super().__init__(feature_size=feature_size, sampling_rate=sampling_rate, padding_value=padding_value, **kwargs)
+ self.do_normalize = do_normalize
+ self.return_attention_mask = return_attention_mask
+
+ self.num_mel_bins = num_mel_bins
+ self.hop_length = hop_length
+ self.win_length = win_length
+ self.win_function = win_function
+ self.frame_signal_scale = frame_signal_scale
+ self.fmin = fmin
+ self.fmax = fmax
+ self.mel_floor = mel_floor
+ self.reduction_factor = reduction_factor
+
+ self.sample_size = win_length * sampling_rate // 1000
+ self.sample_stride = hop_length * sampling_rate // 1000
+ self.n_fft = optimal_fft_length(self.sample_size)
+ self.n_freqs = (self.n_fft // 2) + 1
+
+ self.window = window_function(window_length=self.sample_size, name=self.win_function, periodic=True)
+
+ self.mel_filters = mel_filter_bank(
+ num_frequency_bins=self.n_freqs,
+ num_mel_filters=self.num_mel_bins,
+ min_frequency=self.fmin,
+ max_frequency=self.fmax,
+ sampling_rate=self.sampling_rate,
+ norm="slaney",
+ mel_scale="slaney",
+ )
+
+ if frame_signal_scale != 1.0:
+ warnings.warn(
+ "The argument `frame_signal_scale` is deprecated and will be removed in version 4.30.0 of Transformers",
+ FutureWarning,
+ )
+ if reduction_factor != 2.0:
+ warnings.warn(
+ "The argument `reduction_factor` is deprecated and will be removed in version 4.30.0 of Transformers",
+ FutureWarning,
+ )
+
+ @staticmethod
+ # Copied from transformers.models.wav2vec2.feature_extraction_wav2vec2.Wav2Vec2FeatureExtractor.zero_mean_unit_var_norm
+ def zero_mean_unit_var_norm(
+ input_values: list[np.ndarray], attention_mask: list[np.ndarray], padding_value: float = 0.0
+ ) -> list[np.ndarray]:
+ """
+ Every array in the list is normalized to have zero mean and unit variance
+ """
+ if attention_mask is not None:
+ attention_mask = np.array(attention_mask, np.int32)
+ normed_input_values = []
+
+ for vector, length in zip(input_values, attention_mask.sum(-1)):
+ normed_slice = (vector - vector[:length].mean()) / np.sqrt(vector[:length].var() + 1e-7)
+ if length < normed_slice.shape[0]:
+ normed_slice[length:] = padding_value
+
+ normed_input_values.append(normed_slice)
+ else:
+ normed_input_values = [(x - x.mean()) / np.sqrt(x.var() + 1e-7) for x in input_values]
+
+ return normed_input_values
+
+ def _extract_mel_features(
+ self,
+ one_waveform: np.ndarray,
+ ) -> np.ndarray:
+ """
+ Extracts log-mel filterbank features for one waveform array (unbatched).
+ """
+ log_mel_spec = spectrogram(
+ one_waveform,
+ window=self.window,
+ frame_length=self.sample_size,
+ hop_length=self.sample_stride,
+ fft_length=self.n_fft,
+ mel_filters=self.mel_filters,
+ mel_floor=self.mel_floor,
+ log_mel="log10",
+ )
+ return log_mel_spec.T
+
+ def __call__(
+ self,
+ audio: Optional[Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]]] = None,
+ audio_target: Optional[Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]]] = None,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ max_length: Optional[int] = None,
+ truncation: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ sampling_rate: Optional[int] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Main method to featurize and prepare for the model one or several sequence(s).
+
+ Pass in a value for `audio` to extract waveform features. Pass in a value for `audio_target` to extract log-mel
+ spectrogram features.
+
+ Args:
+ audio (`np.ndarray`, `list[float]`, `list[np.ndarray]`, `list[list[float]]`, *optional*):
+ The sequence or batch of sequences to be processed. Each sequence can be a numpy array, a list of float
+ values, a list of numpy arrays or a list of list of float values. This outputs waveform features. Must
+ be mono channel audio, not stereo, i.e. single float per timestep.
+ audio_target (`np.ndarray`, `list[float]`, `list[np.ndarray]`, `list[list[float]]`, *optional*):
+ The sequence or batch of sequences to be processed as targets. Each sequence can be a numpy array, a
+ list of float values, a list of numpy arrays or a list of list of float values. This outputs log-mel
+ spectrogram features.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding
+ index) among:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ truncation (`bool`):
+ Activates truncation to cut input sequences longer than *max_length* to *max_length*.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value.
+
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta), or on TPUs which benefit from having sequence lengths be a multiple of 128.
+ return_attention_mask (`bool`, *optional*):
+ Whether to return the attention mask. If left to the default, will return the attention mask according
+ to the specific feature_extractor's default.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ sampling_rate (`int`, *optional*):
+ The sampling rate at which the `audio` or `audio_target` input was sampled. It is strongly recommended
+ to pass `sampling_rate` at the forward call to prevent silent errors.
+ """
+ if audio is None and audio_target is None:
+ raise ValueError("You must provide either `audio` or `audio_target` values.")
+
+ if sampling_rate is not None:
+ if sampling_rate != self.sampling_rate:
+ raise ValueError(
+ f"The model corresponding to this feature extractor: {self} was trained using a sampling rate of"
+ f" {self.sampling_rate}. Please make sure that the provided audio input was sampled with"
+ f" {self.sampling_rate} and not {sampling_rate}."
+ )
+ else:
+ logger.warning(
+ f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. "
+ "Failing to do so can result in silent errors that might be hard to debug."
+ )
+
+ if audio is not None:
+ inputs = self._process_audio(
+ audio,
+ False,
+ padding,
+ max_length,
+ truncation,
+ pad_to_multiple_of,
+ return_attention_mask,
+ return_tensors,
+ **kwargs,
+ )
+ else:
+ inputs = None
+
+ if audio_target is not None:
+ inputs_target = self._process_audio(
+ audio_target,
+ True,
+ padding,
+ max_length,
+ truncation,
+ pad_to_multiple_of,
+ return_attention_mask,
+ return_tensors,
+ **kwargs,
+ )
+
+ if inputs is None:
+ return inputs_target
+ else:
+ inputs["labels"] = inputs_target["input_values"]
+ decoder_attention_mask = inputs_target.get("attention_mask")
+ if decoder_attention_mask is not None:
+ inputs["decoder_attention_mask"] = decoder_attention_mask
+
+ return inputs
+
+ def _process_audio(
+ self,
+ speech: Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]],
+ is_target: bool = False,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ max_length: Optional[int] = None,
+ truncation: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ is_batched_numpy = isinstance(speech, np.ndarray) and len(speech.shape) > 1
+ if is_batched_numpy and len(speech.shape) > 2:
+ raise ValueError(f"Only mono-channel audio is supported for input to {self}")
+ is_batched = is_batched_numpy or (
+ isinstance(speech, (list, tuple)) and (isinstance(speech[0], (np.ndarray, tuple, list)))
+ )
+
+ if is_batched:
+ speech = [np.asarray(speech, dtype=np.float32) for speech in speech]
+ elif not is_batched and not isinstance(speech, np.ndarray):
+ speech = np.asarray(speech, dtype=np.float32)
+ elif isinstance(speech, np.ndarray) and speech.dtype is np.dtype(np.float64):
+ speech = speech.astype(np.float32)
+
+ # always return batch
+ if not is_batched:
+ speech = [speech]
+
+ # needed to make pad() work on spectrogram inputs
+ feature_size_hack = self.feature_size
+
+ # convert into correct format for padding
+ if is_target:
+ features = [self._extract_mel_features(waveform) for waveform in speech]
+ encoded_inputs = BatchFeature({"input_values": features})
+ self.feature_size = self.num_mel_bins
+ else:
+ encoded_inputs = BatchFeature({"input_values": speech})
+
+ padded_inputs = self.pad(
+ encoded_inputs,
+ padding=padding,
+ max_length=max_length,
+ truncation=truncation,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_attention_mask=return_attention_mask,
+ **kwargs,
+ )
+
+ self.feature_size = feature_size_hack
+
+ # convert input values to correct format
+ input_values = padded_inputs["input_values"]
+ if not isinstance(input_values[0], np.ndarray):
+ padded_inputs["input_values"] = [np.asarray(array, dtype=np.float32) for array in input_values]
+ elif (
+ not isinstance(input_values, np.ndarray)
+ and isinstance(input_values[0], np.ndarray)
+ and input_values[0].dtype is np.dtype(np.float64)
+ ):
+ padded_inputs["input_values"] = [array.astype(np.float32) for array in input_values]
+ elif isinstance(input_values, np.ndarray) and input_values.dtype is np.dtype(np.float64):
+ padded_inputs["input_values"] = input_values.astype(np.float32)
+
+ # convert attention_mask to correct format
+ attention_mask = padded_inputs.get("attention_mask")
+ if attention_mask is not None:
+ padded_inputs["attention_mask"] = [np.asarray(array, dtype=np.int32) for array in attention_mask]
+
+ # zero-mean and unit-variance normalization
+ if not is_target and self.do_normalize:
+ attention_mask = (
+ attention_mask
+ if self._get_padding_strategies(padding, max_length=max_length) is not PaddingStrategy.DO_NOT_PAD
+ else None
+ )
+ padded_inputs["input_values"] = self.zero_mean_unit_var_norm(
+ padded_inputs["input_values"], attention_mask=attention_mask, padding_value=self.padding_value
+ )
+
+ if return_tensors is not None:
+ padded_inputs = padded_inputs.convert_to_tensors(return_tensors)
+
+ return padded_inputs
+
+ def to_dict(self) -> dict[str, Any]:
+ output = super().to_dict()
+
+ # Don't serialize these as they are derived from the other properties.
+ names = ["window", "mel_filters", "sample_size", "sample_stride", "n_fft", "n_freqs"]
+ for name in names:
+ if name in output:
+ del output[name]
+
+ return output
+
+
+__all__ = ["SpeechT5FeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/modeling_speecht5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/modeling_speecht5.py
new file mode 100644
index 0000000000000000000000000000000000000000..b9502dd6ea0713bd2f7aa7866f0078156f78e952
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/modeling_speecht5.py
@@ -0,0 +1,3244 @@
+# coding=utf-8
+# Copyright 2023 The Fairseq Authors, Microsoft Research, and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch SpeechT5 model."""
+
+import math
+from typing import Optional, Union
+
+import numpy as np
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, L1Loss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask, _prepare_4d_causal_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+ Seq2SeqSpectrogramOutput,
+)
+from ...modeling_utils import EmbeddingAccessMixin, PreTrainedModel
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_speecht5 import SpeechT5Config, SpeechT5HifiGanConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+_HIDDEN_STATES_START_POSITION = 1
+
+# General docstring
+
+
+# Copied from transformers.models.bart.modeling_bart.shift_tokens_right
+def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ """
+ Shift input ids one token to the right.
+ """
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[:, 1:] = input_ids[:, :-1].clone()
+ shifted_input_ids[:, 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.pad_token_id has to be defined.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+def shift_spectrograms_right(
+ input_values: torch.Tensor, reduction_factor: int = 1, attention_mask: Optional[torch.Tensor] = None
+):
+ """
+ Shift input spectrograms one timestep to the right. Also applies the reduction factor to the sequence length.
+ """
+ # thin out frames for reduction factor
+ if reduction_factor > 1:
+ input_values = input_values[:, reduction_factor - 1 :: reduction_factor]
+ if attention_mask is not None:
+ attention_mask = attention_mask[:, reduction_factor - 1 :: reduction_factor]
+
+ shifted_input_values = input_values.new_zeros(input_values.shape)
+ shifted_input_values[:, 1:] = input_values[:, :-1].clone()
+
+ # replace possible -100 values in labels by zeros
+ shifted_input_values.masked_fill_(shifted_input_values == -100.0, 0.0)
+
+ return shifted_input_values, attention_mask
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2._compute_mask_indices
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2NoLayerNormConvLayer with Wav2Vec2->SpeechT5
+class SpeechT5NoLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2LayerNormConvLayer with Wav2Vec2->SpeechT5
+class SpeechT5LayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+
+ hidden_states = hidden_states.transpose(-2, -1)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states.transpose(-2, -1)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2GroupNormConvLayer with Wav2Vec2->SpeechT5
+class SpeechT5GroupNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.speech_to_text.modeling_speech_to_text.Speech2TextSinusoidalPositionalEmbedding with Speech2Text->SpeechT5
+class SpeechT5SinusoidalPositionalEmbedding(nn.Module):
+ """This module produces sinusoidal positional embeddings of any length."""
+
+ def __init__(self, num_positions: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ super().__init__()
+ self.offset = 2
+ self.embedding_dim = embedding_dim
+ self.padding_idx = padding_idx
+ self.make_weights(num_positions + self.offset, embedding_dim, padding_idx)
+
+ def make_weights(self, num_embeddings: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ emb_weights = self.get_embedding(num_embeddings, embedding_dim, padding_idx)
+ if hasattr(self, "weights"):
+ # in forward put the weights on the correct dtype and device of the param
+ emb_weights = emb_weights.to(dtype=self.weights.dtype, device=self.weights.device)
+
+ self.register_buffer("weights", emb_weights, persistent=False)
+
+ @staticmethod
+ def get_embedding(num_embeddings: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ """
+ Build sinusoidal embeddings. This matches the implementation in tensor2tensor, but differs slightly from the
+ description in Section 3.5 of "Attention Is All You Need".
+ """
+ half_dim = embedding_dim // 2
+ emb = math.log(10000) / (half_dim - 1)
+ emb = torch.exp(torch.arange(half_dim, dtype=torch.int64).float() * -emb)
+ emb = torch.arange(num_embeddings, dtype=torch.int64).float().unsqueeze(1) * emb.unsqueeze(0)
+ emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1).view(num_embeddings, -1)
+ if embedding_dim % 2 == 1:
+ # zero pad
+ emb = torch.cat([emb, torch.zeros(num_embeddings, 1)], dim=1)
+ if padding_idx is not None:
+ emb[padding_idx, :] = 0
+ return emb.to(torch.get_default_dtype())
+
+ @torch.no_grad()
+ def forward(self, input_ids: torch.Tensor, past_key_values_length: int = 0):
+ bsz, seq_len = input_ids.size()
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = self.create_position_ids_from_input_ids(input_ids, self.padding_idx, past_key_values_length).to(
+ input_ids.device
+ )
+
+ # expand embeddings if needed
+ max_pos = self.padding_idx + 1 + seq_len
+ if max_pos > self.weights.size(0):
+ self.make_weights(max_pos + self.offset, self.embedding_dim, self.padding_idx)
+
+ return self.weights.index_select(0, position_ids.view(-1)).view(bsz, seq_len, -1).detach()
+
+ def create_position_ids_from_input_ids(
+ self, input_ids: torch.Tensor, padding_idx: int, past_key_values_length: Optional[int] = 0
+ ):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding
+ symbols are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ x: torch.Tensor x:
+ Returns: torch.Tensor
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = input_ids.ne(padding_idx).int()
+ incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask
+ return incremental_indices.long() + padding_idx
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2PositionalConvEmbedding with Wav2Vec2->SpeechT5
+class SpeechT5PositionalConvEmbedding(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=config.num_conv_pos_embeddings,
+ padding=config.num_conv_pos_embeddings // 2,
+ groups=config.num_conv_pos_embedding_groups,
+ )
+
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0):
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+ if hasattr(self.conv, "parametrizations"):
+ weight_g = self.conv.parametrizations.weight.original0
+ weight_v = self.conv.parametrizations.weight.original1
+ else:
+ weight_g = self.conv.weight_g
+ weight_v = self.conv.weight_v
+ deepspeed.zero.register_external_parameter(self, weight_v)
+ deepspeed.zero.register_external_parameter(self, weight_g)
+ else:
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+
+ self.padding = SpeechT5SamePadLayer(config.num_conv_pos_embeddings)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.padding(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class SpeechT5ScaledPositionalEncoding(nn.Module):
+ """
+ Scaled positional encoding, see §3.2 in https://huggingface.co/papers/1809.08895
+ """
+
+ def __init__(self, dropout, dim, max_len=5000):
+ pe = torch.zeros(max_len, dim)
+ position = torch.arange(0, max_len).unsqueeze(1)
+ div_term = torch.exp(torch.arange(0, dim, 2, dtype=torch.int64).float() * -(math.log(10000.0) / dim))
+ pe[:, 0::2] = torch.sin(position.float() * div_term)
+ pe[:, 1::2] = torch.cos(position.float() * div_term)
+ pe = pe.unsqueeze(0)
+ super().__init__()
+ self.register_buffer("pe", pe, persistent=False)
+ self.dropout = nn.Dropout(p=dropout)
+ self.dim = dim
+ self.alpha = nn.Parameter(torch.tensor(1.0))
+
+ def forward(self, emb):
+ emb = emb + self.alpha * self.pe[:, : emb.size(1)]
+ emb = self.dropout(emb)
+ return emb
+
+
+class SpeechT5RelativePositionalEncoding(torch.nn.Module):
+ def __init__(self, dim, max_length=1000):
+ super().__init__()
+ self.dim = dim
+ self.max_length = max_length
+ self.pe_k = torch.nn.Embedding(2 * max_length, dim)
+
+ def forward(self, hidden_states):
+ seq_len = hidden_states.shape[1]
+ pos_seq = torch.arange(0, seq_len).to(device=hidden_states.device, dtype=torch.long)
+ pos_seq = pos_seq[:, None] - pos_seq[None, :]
+
+ pos_seq[pos_seq < -self.max_length] = -self.max_length
+ pos_seq[pos_seq >= self.max_length] = self.max_length - 1
+ pos_seq = pos_seq + self.max_length
+
+ return self.pe_k(pos_seq)
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2SamePadLayer with Wav2Vec2->SpeechT5
+class SpeechT5SamePadLayer(nn.Module):
+ def __init__(self, num_conv_pos_embeddings):
+ super().__init__()
+ self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0
+
+ def forward(self, hidden_states):
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, :, : -self.num_pad_remove]
+ return hidden_states
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2FeatureEncoder with Wav2Vec2->SpeechT5
+class SpeechT5FeatureEncoder(nn.Module):
+ """Construct the features from raw audio waveform"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ if config.feat_extract_norm == "group":
+ conv_layers = [SpeechT5GroupNormConvLayer(config, layer_id=0)] + [
+ SpeechT5NoLayerNormConvLayer(config, layer_id=i + 1) for i in range(config.num_feat_extract_layers - 1)
+ ]
+ elif config.feat_extract_norm == "layer":
+ conv_layers = [
+ SpeechT5LayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)
+ ]
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']"
+ )
+ self.conv_layers = nn.ModuleList(conv_layers)
+ self.gradient_checkpointing = False
+ self._requires_grad = True
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def forward(self, input_values):
+ hidden_states = input_values[:, None]
+
+ # make sure hidden_states require grad for gradient_checkpointing
+ if self._requires_grad and self.training:
+ hidden_states.requires_grad = True
+
+ for conv_layer in self.conv_layers:
+ hidden_states = conv_layer(hidden_states)
+
+ return hidden_states
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2FeatureProjection with Wav2Vec2->SpeechT5
+class SpeechT5FeatureProjection(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps)
+ self.projection = nn.Linear(config.conv_dim[-1], config.hidden_size)
+ self.dropout = nn.Dropout(config.feat_proj_dropout)
+
+ def forward(self, hidden_states):
+ # non-projected hidden states are needed for quantization
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states, norm_hidden_states
+
+
+class SpeechT5SpeechEncoderPrenet(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.feature_encoder = SpeechT5FeatureEncoder(config)
+ self.feature_projection = SpeechT5FeatureProjection(config)
+
+ # model only needs masking vector if mask prob is > 0.0
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ self.pos_conv_embed = SpeechT5PositionalConvEmbedding(config)
+ self.pos_sinusoidal_embed = SpeechT5SinusoidalPositionalEmbedding(
+ config.max_speech_positions + config.pad_token_id + 1,
+ config.hidden_size,
+ config.pad_token_id,
+ )
+
+ def freeze_feature_encoder(self):
+ self.feature_encoder._freeze_parameters()
+
+ def forward(
+ self,
+ input_values: torch.Tensor,
+ attention_mask: Optional[torch.LongTensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ ):
+ extract_features = self.feature_encoder(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1],
+ attention_mask,
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ positional_conv_embedding = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + positional_conv_embedding
+
+ if attention_mask is not None:
+ padding_mask = attention_mask.ne(1).long()
+ else:
+ padding_mask = torch.zeros(hidden_states.shape[:2], dtype=torch.long, device=hidden_states.device)
+
+ positional_sinusoidal_embeddings = self.pos_sinusoidal_embed(padding_mask)
+ hidden_states = hidden_states + positional_sinusoidal_embeddings
+
+ return hidden_states, attention_mask
+
+ # Copied from transformers.models.unispeech.modeling_unispeech.UniSpeechPreTrainedModel._get_feature_vector_attention_mask
+ def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths).to(torch.long)
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+ # Copied from transformers.models.unispeech.modeling_unispeech.UniSpeechPreTrainedModel._get_feat_extract_output_lengths
+ def _get_feat_extract_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ return input_lengths
+
+ # Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2Model._mask_hidden_states
+ def _mask_hidden_states(
+ self,
+ hidden_states: torch.FloatTensor,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+ elif self.config.mask_time_prob > 0 and self.training:
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool)
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool)
+ mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1)
+ hidden_states[mask_feature_indices] = 0
+
+ return hidden_states
+
+
+class SpeechT5SpeechDecoderPrenet(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+
+ self.layers = nn.ModuleList(
+ [
+ nn.Linear(
+ config.num_mel_bins if i == 0 else config.speech_decoder_prenet_units,
+ config.speech_decoder_prenet_units,
+ )
+ for i in range(config.speech_decoder_prenet_layers)
+ ]
+ )
+
+ self.final_layer = nn.Linear(config.speech_decoder_prenet_units, config.hidden_size)
+ self.encode_positions = SpeechT5ScaledPositionalEncoding(
+ config.positional_dropout,
+ config.hidden_size,
+ config.max_speech_positions,
+ )
+ self.speaker_embeds_layer = nn.Linear(config.speaker_embedding_dim + config.hidden_size, config.hidden_size)
+
+ def _consistent_dropout(self, inputs_embeds, p):
+ mask = torch.bernoulli(inputs_embeds[0], p=p)
+ all_masks = mask.unsqueeze(0).repeat(inputs_embeds.size(0), 1, 1)
+ return torch.where(all_masks == 1, inputs_embeds, 0) * 1 / (1 - p)
+
+ def forward(
+ self,
+ input_values: torch.Tensor,
+ speaker_embeddings: Optional[torch.Tensor] = None,
+ ):
+ # Dropout is always applied, even when evaluating. See §2.2 in https://huggingface.co/papers/1712.05884.
+
+ inputs_embeds = input_values
+ for layer in self.layers:
+ inputs_embeds = nn.functional.relu(layer(inputs_embeds))
+ inputs_embeds = self._consistent_dropout(inputs_embeds, self.config.speech_decoder_prenet_dropout)
+
+ inputs_embeds = self.final_layer(inputs_embeds)
+ inputs_embeds = self.encode_positions(inputs_embeds)
+
+ if speaker_embeddings is not None:
+ speaker_embeddings = nn.functional.normalize(speaker_embeddings)
+ speaker_embeddings = speaker_embeddings.unsqueeze(1).expand(-1, inputs_embeds.size(1), -1)
+ inputs_embeds = torch.cat([inputs_embeds, speaker_embeddings], dim=-1)
+ inputs_embeds = nn.functional.relu(self.speaker_embeds_layer(inputs_embeds))
+
+ return inputs_embeds
+
+
+class SpeechT5BatchNormConvLayer(nn.Module):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+
+ if layer_id == 0:
+ in_conv_dim = config.num_mel_bins
+ else:
+ in_conv_dim = config.speech_decoder_postnet_units
+
+ if layer_id == config.speech_decoder_postnet_layers - 1:
+ out_conv_dim = config.num_mel_bins
+ else:
+ out_conv_dim = config.speech_decoder_postnet_units
+
+ self.conv = nn.Conv1d(
+ in_conv_dim,
+ out_conv_dim,
+ kernel_size=config.speech_decoder_postnet_kernel,
+ stride=1,
+ padding=(config.speech_decoder_postnet_kernel - 1) // 2,
+ bias=False,
+ )
+ self.batch_norm = nn.BatchNorm1d(out_conv_dim)
+
+ if layer_id < config.speech_decoder_postnet_layers - 1:
+ self.activation = nn.Tanh()
+ else:
+ self.activation = None
+
+ self.dropout = nn.Dropout(config.speech_decoder_postnet_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.batch_norm(hidden_states)
+ if self.activation is not None:
+ hidden_states = self.activation(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+class SpeechT5SpeechDecoderPostnet(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+
+ self.feat_out = nn.Linear(config.hidden_size, config.num_mel_bins * config.reduction_factor)
+ self.prob_out = nn.Linear(config.hidden_size, config.reduction_factor)
+
+ self.layers = nn.ModuleList(
+ [SpeechT5BatchNormConvLayer(config, i) for i in range(config.speech_decoder_postnet_layers)]
+ )
+
+ def forward(self, hidden_states: torch.Tensor):
+ outputs_before_postnet = self.feat_out(hidden_states).view(hidden_states.size(0), -1, self.config.num_mel_bins)
+ outputs_after_postnet = self.postnet(outputs_before_postnet)
+ logits = self.prob_out(hidden_states).view(hidden_states.size(0), -1)
+ return outputs_before_postnet, outputs_after_postnet, logits
+
+ def postnet(self, hidden_states: torch.Tensor):
+ layer_output = hidden_states.transpose(1, 2)
+ for layer in self.layers:
+ layer_output = layer(layer_output)
+ return hidden_states + layer_output.transpose(1, 2)
+
+
+class SpeechT5TextEncoderPrenet(nn.Module, EmbeddingAccessMixin):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id)
+ self.encode_positions = SpeechT5ScaledPositionalEncoding(
+ config.positional_dropout,
+ config.hidden_size,
+ config.max_text_positions,
+ )
+
+ def forward(self, input_ids: torch.Tensor):
+ inputs_embeds = self.embed_tokens(input_ids)
+ inputs_embeds = self.encode_positions(inputs_embeds)
+ return inputs_embeds
+
+
+class SpeechT5TextDecoderPrenet(nn.Module, EmbeddingAccessMixin):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.dropout = nn.Dropout(config.positional_dropout)
+ self.embed_scale = math.sqrt(config.hidden_size) if config.scale_embedding else 1.0
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id)
+
+ self.embed_positions = SpeechT5SinusoidalPositionalEmbedding(
+ config.max_text_positions + config.pad_token_id + 1,
+ config.hidden_size,
+ config.pad_token_id,
+ )
+
+ def forward(
+ self,
+ input_ids: torch.Tensor,
+ attention_mask: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ ):
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ else:
+ raise ValueError("You have to specify `decoder_input_ids`")
+
+ past_key_values_length = 0
+ if past_key_values is not None:
+ past_key_values_length = (
+ past_key_values[0][0].shape[-2]
+ if not isinstance(past_key_values, Cache)
+ else past_key_values.get_seq_length()
+ )
+
+ positions = self.embed_positions(input_ids, past_key_values_length)
+
+ inputs_embeds = self.embed_tokens(input_ids) * self.embed_scale
+ inputs_embeds += positions
+ inputs_embeds = self.dropout(inputs_embeds)
+
+ return inputs_embeds, attention_mask
+
+
+class SpeechT5TextDecoderPostnet(nn.Module, EmbeddingAccessMixin):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ def forward(self, hidden_states: torch.Tensor):
+ return self.lm_head(hidden_states)
+
+ def get_output_embeddings(self):
+ # Post-net has no token embeddings, but its lm_head must still be
+ # tied to the decoder weights when `tie_word_embeddings=True`.
+ return self.lm_head
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head = new_embeddings
+
+
+class SpeechT5Attention(nn.Module):
+ """
+ Multi-headed attention from 'Attention Is All You Need' paper with relative position bias (see
+ https://aclanthology.org/N18-2074.pdf)
+ """
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: Optional[float] = 0.0,
+ is_decoder: Optional[bool] = False,
+ bias: Optional[bool] = True,
+ layer_idx: Optional[bool] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.layer_idx = layer_idx
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ position_bias: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[Cache]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ bsz, tgt_len, _ = hidden_states.size()
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k_proj(current_states)
+ value_states = self.v_proj(current_states)
+ key_states = key_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = query_states.view(bsz, tgt_len, self.num_heads, self.head_dim).transpose(1, 2)
+ query_states = query_states.reshape(*proj_shape)
+ key_states = key_states.reshape(*proj_shape)
+ value_states = value_states.reshape(*proj_shape)
+
+ src_len = key_states.size(1)
+ attn_weights = torch.bmm(query_states, key_states.transpose(1, 2))
+
+ if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len):
+ raise ValueError(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ # relative attention bias
+ if position_bias is not None:
+ reshape_q = query_states.contiguous().view(bsz * self.num_heads, -1, self.head_dim).transpose(0, 1)
+ rel_pos_bias = torch.matmul(reshape_q, position_bias.transpose(-2, -1))
+ rel_pos_bias = rel_pos_bias.transpose(0, 1).view(
+ bsz * self.num_heads, position_bias.size(0), position_bias.size(1)
+ )
+ attn_weights += rel_pos_bias
+
+ if attention_mask is not None:
+ if attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is {attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attention_mask
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if layer_head_mask is not None:
+ if layer_head_mask.size() != (self.num_heads,):
+ raise ValueError(
+ f"Head mask for a single layer should be of size {(self.num_heads,)}, but is"
+ f" {layer_head_mask.size()}"
+ )
+ attn_weights = layer_head_mask.view(1, -1, 1, 1) * attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ if output_attentions:
+ # this operation is a bit awkward, but it's required to
+ # make sure that attn_weights keeps its gradient.
+ # In order to do so, attn_weights have to be reshaped
+ # twice and have to be reused in the following
+ attn_weights_reshaped = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights_reshaped.view(bsz * self.num_heads, tgt_len, src_len)
+ else:
+ attn_weights_reshaped = None
+
+ attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ attn_output = torch.bmm(attn_probs, value_states)
+
+ if attn_output.size() != (bsz * self.num_heads, tgt_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim)
+ attn_output = attn_output.transpose(1, 2)
+
+ # Use the `embed_dim` from the config (stored in the class) rather than `hidden_state` because `attn_output` can be
+ # partitioned aross GPUs when using tensor-parallelism.
+ attn_output = attn_output.reshape(bsz, tgt_len, self.embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights_reshaped
+
+
+class SpeechT5FeedForward(nn.Module):
+ def __init__(self, config, intermediate_size):
+ super().__init__()
+ self.intermediate_dropout = nn.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = nn.Linear(config.hidden_size, intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ self.output_dense = nn.Linear(intermediate_size, config.hidden_size)
+ self.output_dropout = nn.Dropout(config.hidden_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states)
+ return hidden_states
+
+
+class SpeechT5EncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: SpeechT5Config):
+ super().__init__()
+ self.attention = SpeechT5Attention(
+ embed_dim=config.hidden_size,
+ num_heads=config.encoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = SpeechT5FeedForward(config, config.encoder_ffn_dim)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ position_bias: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`):
+ input to the layer of shape `(batch, seq_len, hidden_size)`
+ attention_mask (`torch.FloatTensor`):
+ attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very
+ large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(config.encoder_attention_heads,)`.
+ position_bias (`torch.FloatTensor`):
+ relative position embeddings of size `(seq_len, seq_len, hidden_size // encoder_attention_heads)`
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states, attn_weights = self.attention(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = residual + hidden_states
+
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class SpeechT5DecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: SpeechT5Config, layer_idx=None):
+ super().__init__()
+ self.self_attn = SpeechT5Attention(
+ embed_dim=config.hidden_size,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ layer_idx=layer_idx,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.self_attn_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ self.encoder_attn = SpeechT5Attention(
+ config.hidden_size,
+ config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ layer_idx=layer_idx,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ self.feed_forward = SpeechT5FeedForward(config, config.decoder_ffn_dim)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_layer_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = True,
+ cache_position: Optional[torch.Tensor] = None,
+ ):
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, hidden_size)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`torch.FloatTensor`):
+ cross attention input to the layer of shape `(batch, seq_len, hidden_size)`
+ encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ cross_attn_layer_head_mask (`torch.FloatTensor`): mask for cross-attention heads in a given layer of
+ size `(decoder_attention_heads,)`.
+ past_key_values (`Tuple(torch.FloatTensor)`): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_values=past_key_values,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = residual + hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = residual + hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ # Fully Connected
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+@auto_docstring
+class SpeechT5PreTrainedModel(PreTrainedModel):
+ config: SpeechT5Config
+ base_model_prefix = "speecht5"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module: nn.Module):
+ """Initialize the weights"""
+ std = self.config.initializer_range
+ if isinstance(module, SpeechT5PositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, SpeechT5ScaledPositionalEncoding):
+ module.alpha.data.fill_(1.0)
+ elif isinstance(module, SpeechT5FeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm, nn.BatchNorm1d)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+ if hasattr(module, "masked_spec_embed"):
+ nn.init.uniform_(module.masked_spec_embed)
+
+
+class SpeechT5Encoder(SpeechT5PreTrainedModel):
+ """
+ Transformer encoder consisting of *config.encoder_layers* layers. Each layer is a [`SpeechT5EncoderLayer`].
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layerdrop = config.encoder_layerdrop
+
+ self.layers = nn.ModuleList([SpeechT5EncoderLayer(config) for _ in range(config.encoder_layers)])
+
+ self.embed_positions = SpeechT5RelativePositionalEncoding(
+ config.hidden_size // config.encoder_attention_heads, config.encoder_max_relative_position
+ )
+
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, feature_size)`):
+ Features extracted from the speech or text input by the encoder prenet.
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing convolution and attention on padding token indices. Mask values selected in
+ `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ head_mask (`torch.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # expand attention_mask
+ if attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_states.dtype)
+
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ position_bias = self.embed_positions(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ # check if head_mask has a correct number of layers specified if desired
+ if head_mask is not None:
+ if head_mask.size()[0] != len(self.layers):
+ raise ValueError(
+ f"The head_mask should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ skip_the_layer = False
+ if self.training:
+ dropout_probability = torch.rand([])
+ skip_the_layer = dropout_probability < self.layerdrop
+
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ output_attentions=output_attentions,
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class SpeechT5EncoderWithSpeechPrenet(SpeechT5PreTrainedModel):
+ """
+ Wrapper around SpeechT5Encoder that applies SpeechT5SpeechEncoderPrenet to convert the audio waveform data to
+ hidden features.
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.prenet = SpeechT5SpeechEncoderPrenet(config)
+ self.wrapped_encoder = SpeechT5Encoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_values: torch.FloatTensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ hidden_states, attention_mask = self.prenet(input_values, attention_mask)
+
+ outputs = self.wrapped_encoder(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ return outputs
+
+
+class SpeechT5EncoderWithTextPrenet(SpeechT5PreTrainedModel):
+ """
+ Wrapper around SpeechT5Encoder that applies SpeechT5TextEncoderPrenet to convert the input_ids to hidden features.
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.prenet = SpeechT5TextEncoderPrenet(config)
+ self.wrapped_encoder = SpeechT5Encoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.prenet.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.prenet.set_input_embeddings(value)
+
+ def forward(
+ self,
+ input_values: torch.FloatTensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ hidden_states = self.prenet(input_values)
+
+ outputs = self.wrapped_encoder(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ return outputs
+
+
+class SpeechT5EncoderWithoutPrenet(SpeechT5PreTrainedModel):
+ """
+ This wrapper class is a helper class to correctly load pretrained checkpoints when used in combination with
+ [`SpeechT5Model`].
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.wrapped_encoder = SpeechT5Encoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_values: torch.FloatTensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ return self.wrapped_encoder(
+ hidden_states=input_values,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+
+class SpeechT5Decoder(SpeechT5PreTrainedModel):
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`SpeechT5DecoderLayer`]
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.layerdrop = config.decoder_layerdrop
+
+ self.layers = nn.ModuleList([SpeechT5DecoderLayer(config, layer_idx=i) for i in range(config.decoder_layers)])
+
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ hidden_states: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPastAndCrossAttentions]:
+ r"""
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, feature_size)`):
+ Features extracted from the speech or text input by the decoder prenet.
+ attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder to avoid performing
+ cross-attention on hidden heads. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of
+ shape `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and in the
+ cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those
+ that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of
+ all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ input_shape = hidden_states.size()[:-1]
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ if use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+
+ attention_mask = _prepare_4d_causal_attention_mask(
+ attention_mask, input_shape, hidden_states, past_key_values_length
+ )
+
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(
+ encoder_attention_mask, hidden_states.dtype, tgt_len=input_shape[-1]
+ )
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ # check if head_mask/cross_attn_head_mask has a correct number of layers specified if desired
+ for attn_mask, mask_name in zip([head_mask, cross_attn_head_mask], ["head_mask", "cross_attn_head_mask"]):
+ if attn_mask is not None:
+ if attn_mask.size()[0] != (len(self.layers)):
+ raise ValueError(
+ f"The `{mask_name}` should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+
+ for idx, decoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ skip_the_layer = False
+ if self.training:
+ dropout_probability = torch.rand([])
+ skip_the_layer = dropout_probability < self.layerdrop
+ if skip_the_layer and not synced_gpus:
+ continue
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, past_key_values, all_hidden_states, all_self_attentions, all_cross_attentions]
+ if v is not None
+ )
+
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+class SpeechT5DecoderWithSpeechPrenet(SpeechT5PreTrainedModel):
+ """
+ Wrapper around SpeechT5Decoder that applies SpeechT5SpeechDecoderPrenet to convert log-mel filterbanks to hidden
+ features.
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.prenet = SpeechT5SpeechDecoderPrenet(config)
+ self.wrapped_decoder = SpeechT5Decoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.LongTensor] = None,
+ speaker_embeddings: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPastAndCrossAttentions]:
+ decoder_hidden_states = self.prenet(input_values, speaker_embeddings)
+
+ outputs = self.wrapped_decoder(
+ hidden_states=decoder_hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ return outputs
+
+
+class SpeechT5DecoderWithTextPrenet(SpeechT5PreTrainedModel):
+ """
+ Wrapper around SpeechT5Decoder that applies SpeechT5TextDecoderPrenet to convert input tokens to hidden features.
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.prenet = SpeechT5TextDecoderPrenet(config)
+ self.wrapped_decoder = SpeechT5Decoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.prenet.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.prenet.set_input_embeddings(value)
+
+ def forward(
+ self,
+ input_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPastAndCrossAttentions]:
+ decoder_hidden_states, attention_mask = self.prenet(input_values, attention_mask, past_key_values)
+
+ outputs = self.wrapped_decoder(
+ hidden_states=decoder_hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ return outputs
+
+
+class SpeechT5DecoderWithoutPrenet(SpeechT5PreTrainedModel):
+ """
+ This wrapper class is a helper class to correctly load pretrained checkpoints when used in combination with
+ [`SpeechT5Model`].
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+ self.wrapped_decoder = SpeechT5Decoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPastAndCrossAttentions]:
+ outputs = self.wrapped_decoder(
+ hidden_states=input_values,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+ return outputs
+
+
+class SpeechT5GuidedMultiheadAttentionLoss(nn.Module):
+ """
+ Guided attention loss from the paper [Efficiently Trainable Text-to-Speech System Based on Deep Convolutional
+ Networks with Guided Attention](https://huggingface.co/papers/1710.08969), adapted for multi-head attention.
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__()
+ self.sigma = config.guided_attention_loss_sigma
+ self.scale = config.guided_attention_loss_scale
+
+ def forward(
+ self, attentions: torch.FloatTensor, input_masks: torch.BoolTensor, output_masks: torch.BoolTensor
+ ) -> torch.Tensor:
+ """
+ Compute the attention loss.
+
+ Args:
+ attentions (`torch.FloatTensor` of shape `(batch_size, layers * heads, output_sequence_length, input_sequence_length)`):
+ Batch of multi-head attention weights
+ input_masks (`torch.BoolTensor` of shape `(batch_size, input_sequence_length)`):
+ Input attention mask as booleans.
+ output_masks (`torch.BoolTensor` of shape `(batch_size, output_sequence_length)`):
+ Target attention mask as booleans.
+
+ Returns:
+ `torch.Tensor` with the loss value
+ """
+ guided_attn_masks = self._make_guided_attention_masks(input_masks, output_masks, attentions.device)
+ masks = output_masks.unsqueeze(-1) & input_masks.unsqueeze(-2)
+ masks = masks.to(attentions.device).unsqueeze(1)
+
+ losses = guided_attn_masks * attentions
+ loss = torch.mean(losses.masked_select(masks))
+ return self.scale * loss
+
+ def _make_guided_attention_masks(self, input_masks, output_masks, device):
+ input_lengths = input_masks.sum(-1)
+ output_lengths = output_masks.sum(-1)
+
+ guided_attn_masks = torch.zeros((len(input_masks), output_masks.shape[1], input_masks.shape[1]), device=device)
+
+ for idx, (ilen, olen) in enumerate(zip(input_lengths, output_lengths)):
+ guided_attn_masks[idx, :olen, :ilen] = self._make_guided_attention_mask(ilen, olen, self.sigma, device)
+
+ return guided_attn_masks.unsqueeze(1)
+
+ @staticmethod
+ def _make_guided_attention_mask(input_length, output_length, sigma, device):
+ grid_y, grid_x = torch.meshgrid(
+ torch.arange(input_length, device=device),
+ torch.arange(output_length, device=device),
+ indexing="xy",
+ )
+ grid_x = grid_x.float() / output_length
+ grid_y = grid_y.float() / input_length
+ return 1.0 - torch.exp(-((grid_y - grid_x) ** 2) / (2 * (sigma**2)))
+
+
+class SpeechT5SpectrogramLoss(nn.Module):
+ """
+ Loss computation used by SpeechT5ForTextToSpeech.
+ """
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__()
+ self.use_guided_attention_loss = config.use_guided_attention_loss
+ self.guided_attention_loss_num_heads = config.guided_attention_loss_num_heads
+ self.reduction_factor = config.reduction_factor
+
+ self.l1_criterion = L1Loss()
+ self.bce_criterion = BCEWithLogitsLoss(pos_weight=torch.tensor(5.0))
+
+ if self.use_guided_attention_loss:
+ self.attn_criterion = SpeechT5GuidedMultiheadAttentionLoss(config)
+
+ def forward(
+ self,
+ attention_mask: torch.LongTensor,
+ outputs_before_postnet: torch.FloatTensor,
+ outputs_after_postnet: torch.FloatTensor,
+ logits: torch.FloatTensor,
+ labels: torch.FloatTensor,
+ cross_attentions: Optional[torch.FloatTensor] = None,
+ ) -> torch.Tensor:
+ padding_mask = labels != -100.0
+
+ # mask out the padded portions
+ labels = labels.masked_select(padding_mask)
+ outputs_before_postnet = outputs_before_postnet.masked_select(padding_mask)
+ outputs_after_postnet = outputs_after_postnet.masked_select(padding_mask)
+
+ # spectrogram loss
+ l1_loss = self.l1_criterion(outputs_after_postnet, labels) + self.l1_criterion(outputs_before_postnet, labels)
+
+ # construct stop labels from the padding mask
+ masks = padding_mask[:, :, 0]
+ stop_labels = torch.cat([~masks * 1.0, torch.ones(masks.size(0), 1).to(masks.device)], dim=1)
+ stop_labels = stop_labels[:, 1:].masked_select(masks)
+ logits = logits.masked_select(masks)
+
+ # stop token loss
+ bce_loss = self.bce_criterion(logits, stop_labels)
+
+ # combined loss
+ loss = l1_loss + bce_loss
+
+ # guided attention loss
+ if self.use_guided_attention_loss:
+ attn = torch.cat([x[:, : self.guided_attention_loss_num_heads] for x in cross_attentions], dim=1)
+ input_masks = attention_mask == 1
+ output_masks = padding_mask[:, :, 0]
+ if self.reduction_factor > 1:
+ output_masks = output_masks[:, self.reduction_factor - 1 :: self.reduction_factor]
+ attn_loss = self.attn_criterion(attn, input_masks, output_masks)
+ loss += attn_loss
+
+ return loss
+
+
+@auto_docstring(
+ custom_intro="""
+ The bare SpeechT5 Encoder-Decoder Model outputting raw hidden-states without any specific pre- or post-nets.
+ """
+)
+class SpeechT5Model(SpeechT5PreTrainedModel):
+ def __init__(
+ self,
+ config: SpeechT5Config,
+ encoder: Optional[nn.Module] = None,
+ decoder: Optional[nn.Module] = None,
+ ):
+ r"""
+ encoder (`PreTrainedModel`, *optional*):
+ The encoder model to use.
+ decoder (`PreTrainedModel`, *optional*):
+ The decoder model to use.
+ """
+ super().__init__(config)
+ self.config = config
+ self.encoder = SpeechT5EncoderWithoutPrenet(config) if encoder is None else encoder
+ self.decoder = SpeechT5DecoderWithoutPrenet(config) if decoder is None else decoder
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ if isinstance(self.encoder, SpeechT5EncoderWithTextPrenet):
+ return self.encoder.get_input_embeddings()
+ if isinstance(self.decoder, SpeechT5DecoderWithTextPrenet):
+ return self.decoder.get_input_embeddings()
+ raise NotImplementedError
+
+ def set_input_embeddings(self, value):
+ if isinstance(self.encoder, SpeechT5EncoderWithTextPrenet):
+ self.encoder.set_input_embeddings(value)
+ if isinstance(self.decoder, SpeechT5DecoderWithTextPrenet):
+ self.decoder.set_input_embeddings(value)
+
+ def get_encoder(self):
+ return self.encoder
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ if isinstance(self.encoder, SpeechT5EncoderWithSpeechPrenet):
+ self.encoder.prenet.freeze_feature_encoder()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ decoder_input_values: Optional[torch.Tensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ speaker_embeddings: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqModelOutput]:
+ r"""
+ input_values (`torch.Tensor` of shape `(batch_size, sequence_length)`):
+ Depending on which encoder is being used, the `input_values` are either: float values of the input raw
+ speech waveform, or indices of input sequence tokens in the vocabulary, or hidden states.
+ decoder_input_values (`torch.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Depending on which decoder is being used, the `decoder_input_values` are either: float values of log-mel
+ filterbank features extracted from the raw speech waveform, or indices of decoder input sequence tokens in
+ the vocabulary, or hidden states.
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_values`. Causal mask will
+ also be used by default.
+
+ If you want to change padding behavior, you should read [`SpeechT5Decoder._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://huggingface.co/papers/1910.13461) for more
+ information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ speaker_embeddings (`torch.FloatTensor` of shape `(batch_size, config.speaker_embedding_dim)`, *optional*):
+ Tensor containing the speaker embeddings.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_values=input_values,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ # downsample encoder attention mask (only for encoders with speech input)
+ if attention_mask is not None and isinstance(self.encoder, SpeechT5EncoderWithSpeechPrenet):
+ encoder_attention_mask = self.encoder.prenet._get_feature_vector_attention_mask(
+ encoder_outputs[0].shape[1], attention_mask
+ )
+ else:
+ encoder_attention_mask = attention_mask
+
+ if isinstance(self.decoder, SpeechT5DecoderWithSpeechPrenet):
+ decoder_args = {"speaker_embeddings": speaker_embeddings}
+ else:
+ decoder_args = {}
+
+ decoder_outputs = self.decoder(
+ input_values=decoder_input_values,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_outputs[0],
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ **decoder_args,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ SpeechT5 Model with a speech encoder and a text decoder.
+ """
+)
+class SpeechT5ForSpeechToText(SpeechT5PreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["text_decoder_postnet.lm_head.weight"]
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that does not define the"
+ " vocabulary size of the language model head. Please instantiate the model as follows:"
+ " `SpeechT5ForSpeechToText.from_pretrained(..., vocab_size=vocab_size)`. or define `vocab_size` of"
+ " your model's configuration."
+ )
+
+ speech_encoder = SpeechT5EncoderWithSpeechPrenet(config)
+ text_decoder = SpeechT5DecoderWithTextPrenet(config)
+ self.speecht5 = SpeechT5Model(config, speech_encoder, text_decoder)
+
+ self.text_decoder_postnet = SpeechT5TextDecoderPostnet(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_encoder(self):
+ return self.speecht5.get_encoder()
+
+ def get_decoder(self):
+ return self.speecht5.get_decoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.get_encoder().prenet.freeze_feature_encoder()
+
+ def get_output_embeddings(self):
+ return self.text_decoder_postnet.get_output_embeddings()
+
+ def set_output_embeddings(self, new_embeddings):
+ self.text_decoder_postnet.set_output_embeddings(new_embeddings)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.LongTensor] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, Seq2SeqLMOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a *.flac* or *.wav* audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`SpeechT5Processor`] should be used for padding
+ and conversion into a tensor of type `torch.FloatTensor`. See [`SpeechT5Processor.__call__`] for details.
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`SpeechT5Tokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ SpeechT5 uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_values`. Causal mask will
+ also be used by default.
+
+ If you want to change padding behavior, you should read [`SpeechT5Decoder._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://huggingface.co/papers/1910.13461) for more
+ information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the language modeling loss. Indices should either be in `[0, ..., config.vocab_size]`
+ or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored (masked), the loss is
+ only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Label indices can be obtained using [`SpeechT5Tokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ Example:
+
+ ```python
+ >>> from transformers import SpeechT5Processor, SpeechT5ForSpeechToText
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset(
+ ... "hf-internal-testing/librispeech_asr_demo", "clean", split="validation"
+ ... ) # doctest: +IGNORE_RESULT
+ >>> dataset = dataset.sort("id")
+ >>> sampling_rate = dataset.features["audio"].sampling_rate
+
+ >>> processor = SpeechT5Processor.from_pretrained("microsoft/speecht5_asr")
+ >>> model = SpeechT5ForSpeechToText.from_pretrained("microsoft/speecht5_asr")
+
+ >>> # audio file is decoded on the fly
+ >>> inputs = processor(audio=dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+ >>> predicted_ids = model.generate(**inputs, max_length=100)
+
+ >>> # transcribe speech
+ >>> transcription = processor.batch_decode(predicted_ids, skip_special_tokens=True)
+ >>> transcription[0]
+ 'mister quilter is the apostle of the middle classes and we are glad to welcome his gospel'
+ ```
+
+ ```python
+ >>> inputs["labels"] = processor(text_target=dataset[0]["text"], return_tensors="pt").input_ids
+
+ >>> # compute loss
+ >>> loss = model(**inputs).loss
+ >>> round(loss.item(), 2)
+ 19.68
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ if decoder_input_ids is None:
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ outputs = self.speecht5(
+ input_values=input_values,
+ attention_mask=attention_mask,
+ decoder_input_values=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ )
+
+ logits = self.text_decoder_postnet(outputs[0])
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+
+def _generate_speech(
+ model: SpeechT5PreTrainedModel,
+ input_values: torch.FloatTensor,
+ speaker_embeddings: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ threshold: float = 0.5,
+ minlenratio: float = 0.0,
+ maxlenratio: float = 20.0,
+ vocoder: Optional[nn.Module] = None,
+ output_cross_attentions: bool = False,
+ return_output_lengths: bool = False,
+) -> Union[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor]]:
+ if speaker_embeddings is None:
+ raise ValueError(
+ """`speaker_embeddings` must be specified. For example, you can use a speaker embeddings by following
+ the code snippet provided in this link:
+ https://huggingface.co/datasets/Matthijs/cmu-arctic-xvectors
+ """
+ )
+
+ if attention_mask is None:
+ encoder_attention_mask = 1 - (input_values == model.config.pad_token_id).int()
+ else:
+ encoder_attention_mask = attention_mask
+
+ bsz = input_values.size(0)
+
+ encoder_out = model.speecht5.encoder(
+ input_values=input_values,
+ attention_mask=encoder_attention_mask,
+ return_dict=True,
+ )
+
+ encoder_last_hidden_state = encoder_out.last_hidden_state
+
+ # downsample encoder attention mask
+ if isinstance(model.speecht5.encoder, SpeechT5EncoderWithSpeechPrenet):
+ encoder_attention_mask = model.speecht5.encoder.prenet._get_feature_vector_attention_mask(
+ encoder_out[0].shape[1], encoder_attention_mask
+ )
+
+ maxlen = int(encoder_last_hidden_state.size(1) * maxlenratio / model.config.reduction_factor)
+ minlen = int(encoder_last_hidden_state.size(1) * minlenratio / model.config.reduction_factor)
+
+ # Start the output sequence with a mel spectrum that is all zeros.
+ output_sequence = encoder_last_hidden_state.new_zeros(bsz, 1, model.config.num_mel_bins)
+
+ spectrogram = []
+ cross_attentions = []
+ past_key_values = None
+ idx = 0
+ result_spectrogram = {}
+
+ while True:
+ idx += 1
+
+ # Run the decoder prenet on the entire output sequence.
+ decoder_hidden_states = model.speecht5.decoder.prenet(output_sequence, speaker_embeddings)
+ # Run the decoder layers on the last element of the prenet output.
+ decoder_out = model.speecht5.decoder.wrapped_decoder(
+ hidden_states=decoder_hidden_states[:, -1:],
+ attention_mask=None,
+ encoder_hidden_states=encoder_last_hidden_state,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=True,
+ output_attentions=output_cross_attentions,
+ return_dict=True,
+ )
+
+ if output_cross_attentions:
+ cross_attentions.append(torch.cat(decoder_out.cross_attentions, dim=0))
+
+ last_decoder_output = decoder_out.last_hidden_state.squeeze(1)
+ past_key_values = decoder_out.past_key_values
+
+ # Predict the new mel spectrum for this step in the sequence.
+ spectrum = model.speech_decoder_postnet.feat_out(last_decoder_output)
+ spectrum = spectrum.view(bsz, model.config.reduction_factor, model.config.num_mel_bins)
+ spectrogram.append(spectrum)
+
+ # Extend the output sequence with the new mel spectrum.
+ new_spectrogram = spectrum[:, -1, :].view(bsz, 1, model.config.num_mel_bins)
+ output_sequence = torch.cat((output_sequence, new_spectrogram), dim=1)
+ # Predict the probability that this is the stop token.
+ prob = torch.sigmoid(model.speech_decoder_postnet.prob_out(last_decoder_output))
+
+ if idx < minlen:
+ continue
+ else:
+ # If the generation loop is less than maximum length time, check the ones in the batch that have met
+ # the prob threshold. Otherwise, assume all have met thresholds and fill other spectrograms for the batch.
+ if idx < maxlen:
+ meet_thresholds = torch.sum(prob, dim=-1) >= threshold
+ meet_indexes = torch.where(meet_thresholds)[0].tolist()
+ else:
+ meet_indexes = range(len(prob))
+ meet_indexes = [i for i in meet_indexes if i not in result_spectrogram]
+ if len(meet_indexes) > 0:
+ spectrograms = torch.stack(spectrogram)
+ spectrograms = spectrograms.transpose(0, 1).flatten(1, 2)
+ spectrograms = model.speech_decoder_postnet.postnet(spectrograms)
+ for meet_index in meet_indexes:
+ result_spectrogram[meet_index] = spectrograms[meet_index]
+ if len(result_spectrogram) >= bsz:
+ break
+ spectrograms = [result_spectrogram[i] for i in range(len(result_spectrogram))]
+ if not return_output_lengths:
+ spectrogram = spectrograms[0] if bsz == 1 else torch.nn.utils.rnn.pad_sequence(spectrograms, batch_first=True)
+ if vocoder is not None:
+ outputs = vocoder(spectrogram)
+ else:
+ outputs = spectrogram
+ if output_cross_attentions:
+ cross_attentions = torch.cat(cross_attentions, dim=2)
+ if bsz > 1:
+ cross_attentions = cross_attentions.view(
+ bsz, int(cross_attentions.size(0) / bsz), *cross_attentions.size()[-3:]
+ )
+ outputs = (outputs, cross_attentions)
+ else:
+ # batched return values should also include the spectrogram/waveform lengths
+ spectrogram_lengths = []
+ for i in range(bsz):
+ spectrogram_lengths.append(spectrograms[i].size(0))
+ if vocoder is None:
+ spectrograms = torch.nn.utils.rnn.pad_sequence(spectrograms, batch_first=True)
+ outputs = (spectrograms, spectrogram_lengths)
+ else:
+ waveforms = []
+ spectrograms = torch.nn.utils.rnn.pad_sequence(spectrograms, batch_first=True)
+ waveforms = vocoder(spectrograms)
+ waveform_lengths = [int(waveforms.size(1) / max(spectrogram_lengths)) * i for i in spectrogram_lengths]
+ outputs = (waveforms, waveform_lengths)
+ if output_cross_attentions:
+ cross_attentions = torch.cat(cross_attentions, dim=2)
+ cross_attentions = cross_attentions.view(
+ bsz, int(cross_attentions.size(0) / bsz), *cross_attentions.size()[-3:]
+ )
+ outputs = (*outputs, cross_attentions)
+ return outputs
+
+
+@auto_docstring(
+ custom_intro="""
+ SpeechT5 Model with a text encoder and a speech decoder.
+ """
+)
+class SpeechT5ForTextToSpeech(SpeechT5PreTrainedModel):
+ main_input_name = "input_ids"
+
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that does not define the"
+ " vocabulary size of the language model head. Please instantiate the model as follows:"
+ " `SpeechT5ForTextToSpeech.from_pretrained(..., vocab_size=vocab_size)`. or define `vocab_size` of"
+ " your model's configuration."
+ )
+
+ text_encoder = SpeechT5EncoderWithTextPrenet(config)
+ speech_decoder = SpeechT5DecoderWithSpeechPrenet(config)
+ self.speecht5 = SpeechT5Model(config, text_encoder, speech_decoder)
+
+ self.speech_decoder_postnet = SpeechT5SpeechDecoderPostnet(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @classmethod
+ def can_generate(cls) -> bool:
+ # Speecht5 has a unique model structure, where the external class (`SpeechT5ForTextToSpeech`) doesn't need to inherit from
+ # `GenerationMixin` (it has a non-standard generation method). This means that the base `can_generate()` will return `False`,
+ # but we need to override it so as to do `GenerationConfig` handling in multiple parts of the codebase.
+ return True
+
+ def get_encoder(self):
+ return self.speecht5.get_encoder()
+
+ def get_decoder(self):
+ return self.speecht5.get_decoder()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ decoder_input_values: Optional[torch.FloatTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ speaker_embeddings: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.FloatTensor] = None,
+ stop_labels: Optional[torch.Tensor] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, Seq2SeqSpectrogramOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`SpeechT5Tokenizer`]. See [`~PreTrainedTokenizer.encode`] and
+ [`~PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ decoder_input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_mel_bins)`):
+ Float values of input mel spectrogram.
+
+ SpeechT5 uses an all-zero spectrum as the starting token for `decoder_input_values` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_values` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_values`. Causal mask will
+ also be used by default.
+
+ If you want to change padding behavior, you should read [`SpeechT5Decoder._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://huggingface.co/papers/1910.13461) for more
+ information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ speaker_embeddings (`torch.FloatTensor` of shape `(batch_size, config.speaker_embedding_dim)`, *optional*):
+ Tensor containing the speaker embeddings.
+ labels (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_mel_bins)`, *optional*):
+ Float values of target mel spectrogram. Timesteps set to `-100.0` are ignored (masked) for the loss
+ computation. Spectrograms can be obtained using [`SpeechT5Processor`]. See [`SpeechT5Processor.__call__`]
+ for details.
+ stop_labels (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Binary tensor indicating the position of the stop token in the sequence.
+
+ Example:
+
+ ```python
+ >>> from transformers import SpeechT5Processor, SpeechT5ForTextToSpeech, SpeechT5HifiGan, set_seed
+ >>> import torch
+
+ >>> processor = SpeechT5Processor.from_pretrained("microsoft/speecht5_tts")
+ >>> model = SpeechT5ForTextToSpeech.from_pretrained("microsoft/speecht5_tts")
+ >>> vocoder = SpeechT5HifiGan.from_pretrained("microsoft/speecht5_hifigan")
+
+ >>> inputs = processor(text="Hello, my dog is cute", return_tensors="pt")
+ >>> speaker_embeddings = torch.zeros((1, 512)) # or load xvectors from a file
+
+ >>> set_seed(555) # make deterministic
+
+ >>> # generate speech
+ >>> speech = model.generate(inputs["input_ids"], speaker_embeddings=speaker_embeddings, vocoder=vocoder)
+ >>> speech.shape
+ torch.Size([15872])
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ if decoder_input_values is None:
+ decoder_input_values, decoder_attention_mask = shift_spectrograms_right(
+ labels, self.config.reduction_factor, decoder_attention_mask
+ )
+ if self.config.use_guided_attention_loss:
+ output_attentions = True
+
+ outputs = self.speecht5(
+ input_values=input_ids,
+ attention_mask=attention_mask,
+ decoder_input_values=decoder_input_values,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ speaker_embeddings=speaker_embeddings,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ )
+
+ outputs_before_postnet, outputs_after_postnet, logits = self.speech_decoder_postnet(outputs[0])
+
+ loss = None
+ if labels is not None:
+ criterion = SpeechT5SpectrogramLoss(self.config)
+ loss = criterion(
+ attention_mask,
+ outputs_before_postnet,
+ outputs_after_postnet,
+ logits,
+ labels,
+ outputs.cross_attentions,
+ )
+
+ if not return_dict:
+ output = (outputs_after_postnet,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqSpectrogramOutput(
+ loss=loss,
+ spectrogram=outputs_after_postnet,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+ @torch.no_grad()
+ def generate(
+ self,
+ input_ids: torch.LongTensor,
+ attention_mask: Optional[torch.LongTensor] = None,
+ speaker_embeddings: Optional[torch.FloatTensor] = None,
+ threshold: float = 0.5,
+ minlenratio: float = 0.0,
+ maxlenratio: float = 20.0,
+ vocoder: Optional[nn.Module] = None,
+ output_cross_attentions: bool = False,
+ return_output_lengths: bool = False,
+ **kwargs,
+ ) -> Union[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor]]:
+ r"""
+ Converts a sequence of input tokens into a sequence of mel spectrograms, which are subsequently turned into a
+ speech waveform using a vocoder.
+
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`SpeechT5Tokenizer`]. See [`~PreTrainedTokenizer.encode`] and
+ [`~PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Attention mask from the tokenizer, required for batched inference to signal to the model where to
+ ignore padded tokens from the input_ids.
+ speaker_embeddings (`torch.FloatTensor` of shape `(batch_size, config.speaker_embedding_dim)`, *optional*):
+ Tensor containing the speaker embeddings.
+ threshold (`float`, *optional*, defaults to 0.5):
+ The generated sequence ends when the predicted stop token probability exceeds this value.
+ minlenratio (`float`, *optional*, defaults to 0.0):
+ Used to calculate the minimum required length for the output sequence.
+ maxlenratio (`float`, *optional*, defaults to 20.0):
+ Used to calculate the maximum allowed length for the output sequence.
+ vocoder (`nn.Module`, *optional*):
+ The vocoder that converts the mel spectrogram into a speech waveform. If `None`, the output is the mel
+ spectrogram.
+ output_cross_attentions (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the attentions tensors of the decoder's cross-attention layers.
+ return_output_lengths (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the concrete spectrogram/waveform lengths.
+
+ Returns:
+ `tuple(torch.FloatTensor)` comprising various elements depending on the inputs:
+ - when `return_output_lengths` is False
+ - **spectrogram** (*optional*, returned when no `vocoder` is provided) `torch.FloatTensor` of shape
+ `(output_sequence_length, config.num_mel_bins)` -- The predicted log-mel spectrogram.
+ - **waveform** (*optional*, returned when a `vocoder` is provided) `torch.FloatTensor` of shape
+ `(num_frames,)` -- The predicted speech waveform.
+ - **cross_attentions** (*optional*, returned when `output_cross_attentions` is `True`)
+ `torch.FloatTensor` of shape `(config.decoder_layers, config.decoder_attention_heads,
+ output_sequence_length, input_sequence_length)` -- The outputs of the decoder's cross-attention layers.
+ - when `return_output_lengths` is True
+ - **spectrograms** (*optional*, returned when no `vocoder` is provided) `torch.FloatTensor` of shape
+ `(batch_size, output_sequence_length, config.num_mel_bins)` -- The predicted log-mel spectrograms that
+ are padded to the maximum length.
+ - **spectrogram_lengths** (*optional*, returned when no `vocoder` is provided) `list[Int]` -- A list of
+ all the concrete lengths for each spectrogram.
+ - **waveforms** (*optional*, returned when a `vocoder` is provided) `torch.FloatTensor` of shape
+ `(batch_size, num_frames)` -- The predicted speech waveforms that are padded to the maximum length.
+ - **waveform_lengths** (*optional*, returned when a `vocoder` is provided) `list[Int]` -- A list of all
+ the concrete lengths for each waveform.
+ - **cross_attentions** (*optional*, returned when `output_cross_attentions` is `True`)
+ `torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.decoder_attention_heads,
+ output_sequence_length, input_sequence_length)` -- The outputs of the decoder's cross-attention layers.
+ """
+ if speaker_embeddings is not None:
+ batch_size = input_ids.size(0)
+ if speaker_embeddings.size(0) != batch_size:
+ if speaker_embeddings.size(0) == 1:
+ speaker_embeddings = speaker_embeddings.repeat(batch_size, 1)
+ else:
+ raise ValueError(
+ "The first dimension of speaker_embeddings must be either 1 or the same as batch_size."
+ )
+
+ return _generate_speech(
+ self,
+ input_ids,
+ speaker_embeddings,
+ attention_mask,
+ threshold,
+ minlenratio,
+ maxlenratio,
+ vocoder,
+ output_cross_attentions,
+ return_output_lengths,
+ )
+
+ @torch.no_grad()
+ def generate_speech(
+ self,
+ input_ids: torch.LongTensor,
+ speaker_embeddings: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ threshold: float = 0.5,
+ minlenratio: float = 0.0,
+ maxlenratio: float = 20.0,
+ vocoder: Optional[nn.Module] = None,
+ output_cross_attentions: bool = False,
+ return_output_lengths: bool = False,
+ ) -> Union[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor]]:
+ r"""
+ Converts a sequence of input tokens into a sequence of mel spectrograms, which are subsequently turned into a
+ speech waveform using a vocoder.
+
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`SpeechT5Tokenizer`]. See [`~PreTrainedTokenizer.encode`] and
+ [`~PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ speaker_embeddings (`torch.FloatTensor` of shape `(batch_size, config.speaker_embedding_dim)`, *optional*):
+ Tensor containing the speaker embeddings.
+ attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing convolution and attention on padding token indices. Mask values selected in
+ `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ threshold (`float`, *optional*, defaults to 0.5):
+ The generated sequence ends when the predicted stop token probability exceeds this value.
+ minlenratio (`float`, *optional*, defaults to 0.0):
+ Used to calculate the minimum required length for the output sequence.
+ maxlenratio (`float`, *optional*, defaults to 20.0):
+ Used to calculate the maximum allowed length for the output sequence.
+ vocoder (`nn.Module`, *optional*, defaults to `None`):
+ The vocoder that converts the mel spectrogram into a speech waveform. If `None`, the output is the mel
+ spectrogram.
+ output_cross_attentions (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the attentions tensors of the decoder's cross-attention layers.
+ return_output_lengths (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the concrete spectrogram/waveform lengths.
+
+ Returns:
+ `tuple(torch.FloatTensor)` comprising various elements depending on the inputs:
+ - when `return_output_lengths` is False
+ - **spectrogram** (*optional*, returned when no `vocoder` is provided) `torch.FloatTensor` of shape
+ `(output_sequence_length, config.num_mel_bins)` -- The predicted log-mel spectrogram.
+ - **waveform** (*optional*, returned when a `vocoder` is provided) `torch.FloatTensor` of shape
+ `(num_frames,)` -- The predicted speech waveform.
+ - **cross_attentions** (*optional*, returned when `output_cross_attentions` is `True`)
+ `torch.FloatTensor` of shape `(config.decoder_layers, config.decoder_attention_heads,
+ output_sequence_length, input_sequence_length)` -- The outputs of the decoder's cross-attention layers.
+ - when `return_output_lengths` is True
+ - **spectrograms** (*optional*, returned when no `vocoder` is provided) `torch.FloatTensor` of shape
+ `(batch_size, output_sequence_length, config.num_mel_bins)` -- The predicted log-mel spectrograms that
+ are padded to the maximum length.
+ - **spectrogram_lengths** (*optional*, returned when no `vocoder` is provided) `list[Int]` -- A list of
+ all the concrete lengths for each spectrogram.
+ - **waveforms** (*optional*, returned when a `vocoder` is provided) `torch.FloatTensor` of shape
+ `(batch_size, num_frames)` -- The predicted speech waveforms that are padded to the maximum length.
+ - **waveform_lengths** (*optional*, returned when a `vocoder` is provided) `list[Int]` -- A list of all
+ the concrete lengths for each waveform.
+ - **cross_attentions** (*optional*, returned when `output_cross_attentions` is `True`)
+ `torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.decoder_attention_heads,
+ output_sequence_length, input_sequence_length)` -- The outputs of the decoder's cross-attention layers.
+ """
+ if speaker_embeddings is not None:
+ batch_size = input_ids.size(0)
+ if speaker_embeddings.size(0) != batch_size:
+ if speaker_embeddings.size(0) == 1:
+ speaker_embeddings = speaker_embeddings.repeat(batch_size, 1)
+ else:
+ raise ValueError(
+ "The first dimension of speaker_embeddings must be either 1 or the same as batch size."
+ )
+
+ return _generate_speech(
+ self,
+ input_ids,
+ speaker_embeddings,
+ attention_mask,
+ threshold,
+ minlenratio,
+ maxlenratio,
+ vocoder,
+ output_cross_attentions,
+ return_output_lengths,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ SpeechT5 Model with a speech encoder and a speech decoder.
+ """
+)
+class SpeechT5ForSpeechToSpeech(SpeechT5PreTrainedModel):
+ def __init__(self, config: SpeechT5Config):
+ super().__init__(config)
+
+ speech_encoder = SpeechT5EncoderWithSpeechPrenet(config)
+ speech_decoder = SpeechT5DecoderWithSpeechPrenet(config)
+ self.speecht5 = SpeechT5Model(config, speech_encoder, speech_decoder)
+
+ self.speech_decoder_postnet = SpeechT5SpeechDecoderPostnet(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_encoder(self):
+ return self.speecht5.get_encoder()
+
+ def get_decoder(self):
+ return self.speecht5.get_decoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.get_encoder().prenet.freeze_feature_encoder()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ decoder_input_values: Optional[torch.FloatTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ speaker_embeddings: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.FloatTensor] = None,
+ stop_labels: Optional[torch.Tensor] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, Seq2SeqSpectrogramOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a *.flac* or *.wav* audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`SpeechT5Processor`] should be used for padding and conversion into
+ a tensor of type `torch.FloatTensor`. See [`SpeechT5Processor.__call__`] for details.
+ decoder_input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_mel_bins)`):
+ Float values of input mel spectrogram.
+
+ SpeechT5 uses an all-zero spectrum as the starting token for `decoder_input_values` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_values` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_values`. Causal mask will
+ also be used by default.
+
+ If you want to change padding behavior, you should read [`SpeechT5Decoder._prepare_decoder_attention_mask`]
+ and modify to your needs. See diagram 1 in [the paper](https://huggingface.co/papers/1910.13461) for more
+ information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ speaker_embeddings (`torch.FloatTensor` of shape `(batch_size, config.speaker_embedding_dim)`, *optional*):
+ Tensor containing the speaker embeddings.
+ labels (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_mel_bins)`, *optional*):
+ Float values of target mel spectrogram. Spectrograms can be obtained using [`SpeechT5Processor`]. See
+ [`SpeechT5Processor.__call__`] for details.
+ stop_labels (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Binary tensor indicating the position of the stop token in the sequence.
+
+ Example:
+
+ ```python
+ >>> from transformers import SpeechT5Processor, SpeechT5ForSpeechToSpeech, SpeechT5HifiGan, set_seed
+ >>> from datasets import load_dataset
+ >>> import torch
+
+ >>> dataset = load_dataset(
+ ... "hf-internal-testing/librispeech_asr_demo", "clean", split="validation"
+ ... ) # doctest: +IGNORE_RESULT
+ >>> dataset = dataset.sort("id")
+ >>> sampling_rate = dataset.features["audio"].sampling_rate
+
+ >>> processor = SpeechT5Processor.from_pretrained("microsoft/speecht5_vc")
+ >>> model = SpeechT5ForSpeechToSpeech.from_pretrained("microsoft/speecht5_vc")
+ >>> vocoder = SpeechT5HifiGan.from_pretrained("microsoft/speecht5_hifigan")
+
+ >>> # audio file is decoded on the fly
+ >>> inputs = processor(audio=dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+
+ >>> speaker_embeddings = torch.zeros((1, 512)) # or load xvectors from a file
+
+ >>> set_seed(555) # make deterministic
+
+ >>> # generate speech
+ >>> speech = model.generate_speech(inputs["input_values"], speaker_embeddings, vocoder=vocoder)
+ >>> speech.shape
+ torch.Size([77824])
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ if decoder_input_values is None:
+ decoder_input_values, decoder_attention_mask = shift_spectrograms_right(
+ labels, self.config.reduction_factor, decoder_attention_mask
+ )
+
+ outputs = self.speecht5(
+ input_values=input_values,
+ attention_mask=attention_mask,
+ decoder_input_values=decoder_input_values,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ speaker_embeddings=speaker_embeddings,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ )
+
+ _, spectrogram, logits = self.speech_decoder_postnet(outputs[0])
+
+ loss = None
+
+ if not return_dict:
+ output = (spectrogram,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqSpectrogramOutput(
+ loss=loss,
+ spectrogram=spectrogram,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+ @torch.no_grad()
+ def generate_speech(
+ self,
+ input_values: torch.FloatTensor,
+ speaker_embeddings: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ threshold: float = 0.5,
+ minlenratio: float = 0.0,
+ maxlenratio: float = 20.0,
+ vocoder: Optional[nn.Module] = None,
+ output_cross_attentions: bool = False,
+ return_output_lengths: bool = False,
+ ) -> torch.FloatTensor:
+ r"""
+ Converts a raw speech waveform into a sequence of mel spectrograms, which are subsequently turned back into a
+ speech waveform using a vocoder.
+
+ Args:
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform.
+
+ Values can be obtained by loading a *.flac* or *.wav* audio file into an array of type `list[float]`,
+ a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library (`pip install torchcodec`)
+ or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`SpeechT5Processor`] should be used for padding and
+ conversion into a tensor of type `torch.FloatTensor`. See [`SpeechT5Processor.__call__`] for details.
+ speaker_embeddings (`torch.FloatTensor` of shape `(batch_size, config.speaker_embedding_dim)`, *optional*):
+ Tensor containing the speaker embeddings.
+ attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing convolution and attention on padding token indices. Mask values selected in
+ `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ threshold (`float`, *optional*, defaults to 0.5):
+ The generated sequence ends when the predicted stop token probability exceeds this value.
+ minlenratio (`float`, *optional*, defaults to 0.0):
+ Used to calculate the minimum required length for the output sequence.
+ maxlenratio (`float`, *optional*, defaults to 20.0):
+ Used to calculate the maximum allowed length for the output sequence.
+ vocoder (`nn.Module`, *optional*, defaults to `None`):
+ The vocoder that converts the mel spectrogram into a speech waveform. If `None`, the output is the mel
+ spectrogram.
+ output_cross_attentions (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the attentions tensors of the decoder's cross-attention layers.
+ return_output_lengths (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the concrete spectrogram/waveform lengths.
+
+ Returns:
+ `tuple(torch.FloatTensor)` comprising various elements depending on the inputs:
+ - when `return_output_lengths` is False
+ - **spectrogram** (*optional*, returned when no `vocoder` is provided) `torch.FloatTensor` of shape
+ `(output_sequence_length, config.num_mel_bins)` -- The predicted log-mel spectrogram.
+ - **waveform** (*optional*, returned when a `vocoder` is provided) `torch.FloatTensor` of shape
+ `(num_frames,)` -- The predicted speech waveform.
+ - **cross_attentions** (*optional*, returned when `output_cross_attentions` is `True`)
+ `torch.FloatTensor` of shape `(config.decoder_layers, config.decoder_attention_heads,
+ output_sequence_length, input_sequence_length)` -- The outputs of the decoder's cross-attention layers.
+ - when `return_output_lengths` is True
+ - **spectrograms** (*optional*, returned when no `vocoder` is provided) `torch.FloatTensor` of shape
+ `(batch_size, output_sequence_length, config.num_mel_bins)` -- The predicted log-mel spectrograms that
+ are padded to the maximum length.
+ - **spectrogram_lengths** (*optional*, returned when no `vocoder` is provided) `list[Int]` -- A list of
+ all the concrete lengths for each spectrogram.
+ - **waveforms** (*optional*, returned when a `vocoder` is provided) `torch.FloatTensor` of shape
+ `(batch_size, num_frames)` -- The predicted speech waveforms that are padded to the maximum length.
+ - **waveform_lengths** (*optional*, returned when a `vocoder` is provided) `list[Int]` -- A list of all
+ the concrete lengths for each waveform.
+ - **cross_attentions** (*optional*, returned when `output_cross_attentions` is `True`)
+ `torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.decoder_attention_heads,
+ output_sequence_length, input_sequence_length)` -- The outputs of the decoder's cross-attention layers.
+ """
+ if speaker_embeddings is None:
+ speaker_embeddings = torch.zeros((1, 512), device=input_values.device)
+
+ return _generate_speech(
+ self,
+ input_values,
+ speaker_embeddings,
+ attention_mask,
+ threshold,
+ minlenratio,
+ maxlenratio,
+ vocoder,
+ output_cross_attentions,
+ return_output_lengths,
+ )
+
+
+class HifiGanResidualBlock(nn.Module):
+ def __init__(self, channels, kernel_size=3, dilation=(1, 3, 5), leaky_relu_slope=0.1):
+ super().__init__()
+ self.leaky_relu_slope = leaky_relu_slope
+
+ self.convs1 = nn.ModuleList(
+ [
+ nn.Conv1d(
+ channels,
+ channels,
+ kernel_size,
+ stride=1,
+ dilation=dilation[i],
+ padding=self.get_padding(kernel_size, dilation[i]),
+ )
+ for i in range(len(dilation))
+ ]
+ )
+ self.convs2 = nn.ModuleList(
+ [
+ nn.Conv1d(
+ channels,
+ channels,
+ kernel_size,
+ stride=1,
+ dilation=1,
+ padding=self.get_padding(kernel_size, 1),
+ )
+ for _ in range(len(dilation))
+ ]
+ )
+
+ def get_padding(self, kernel_size, dilation=1):
+ return (kernel_size * dilation - dilation) // 2
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ for layer in self.convs1:
+ weight_norm(layer)
+ for layer in self.convs2:
+ weight_norm(layer)
+
+ def remove_weight_norm(self):
+ for layer in self.convs1:
+ nn.utils.remove_weight_norm(layer)
+ for layer in self.convs2:
+ nn.utils.remove_weight_norm(layer)
+
+ def forward(self, hidden_states):
+ for conv1, conv2 in zip(self.convs1, self.convs2):
+ residual = hidden_states
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = conv1(hidden_states)
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = conv2(hidden_states)
+ hidden_states = hidden_states + residual
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ HiFi-GAN vocoder.
+ """
+)
+class SpeechT5HifiGan(PreTrainedModel):
+ config: SpeechT5HifiGanConfig
+ main_input_name = "spectrogram"
+
+ def __init__(self, config: SpeechT5HifiGanConfig):
+ super().__init__(config)
+ self.num_kernels = len(config.resblock_kernel_sizes)
+ self.num_upsamples = len(config.upsample_rates)
+ self.conv_pre = nn.Conv1d(
+ config.model_in_dim,
+ config.upsample_initial_channel,
+ kernel_size=7,
+ stride=1,
+ padding=3,
+ )
+
+ self.upsampler = nn.ModuleList()
+ for i, (upsample_rate, kernel_size) in enumerate(zip(config.upsample_rates, config.upsample_kernel_sizes)):
+ self.upsampler.append(
+ nn.ConvTranspose1d(
+ config.upsample_initial_channel // (2**i),
+ config.upsample_initial_channel // (2 ** (i + 1)),
+ kernel_size=kernel_size,
+ stride=upsample_rate,
+ padding=(kernel_size - upsample_rate) // 2,
+ )
+ )
+
+ self.resblocks = nn.ModuleList()
+ for i in range(len(self.upsampler)):
+ channels = config.upsample_initial_channel // (2 ** (i + 1))
+ for kernel_size, dilation in zip(config.resblock_kernel_sizes, config.resblock_dilation_sizes):
+ self.resblocks.append(HifiGanResidualBlock(channels, kernel_size, dilation, config.leaky_relu_slope))
+
+ self.conv_post = nn.Conv1d(channels, 1, kernel_size=7, stride=1, padding=3)
+
+ self.register_buffer("mean", torch.zeros(config.model_in_dim))
+ self.register_buffer("scale", torch.ones(config.model_in_dim))
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _init_weights(self, module: nn.Module):
+ """Initialize the weights."""
+ if isinstance(module, (nn.Conv1d, nn.ConvTranspose1d)):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ weight_norm(self.conv_pre)
+ for layer in self.upsampler:
+ weight_norm(layer)
+ for layer in self.resblocks:
+ layer.apply_weight_norm()
+ weight_norm(self.conv_post)
+
+ def remove_weight_norm(self):
+ nn.utils.remove_weight_norm(self.conv_pre)
+ for layer in self.upsampler:
+ nn.utils.remove_weight_norm(layer)
+ for layer in self.resblocks:
+ layer.remove_weight_norm()
+ nn.utils.remove_weight_norm(self.conv_post)
+
+ @auto_docstring(
+ custom_intro="""
+ Converts a log-mel spectrogram into a speech waveform. Passing a batch of log-mel spectrograms returns a batch
+ of speech waveforms. Passing a single, un-batched log-mel spectrogram returns a single, un-batched speech
+ waveform.
+ """
+ )
+ def forward(self, spectrogram: torch.FloatTensor) -> torch.FloatTensor:
+ r"""
+ spectrogram (`torch.FloatTensor`):
+ Tensor containing the log-mel spectrograms. Can be batched and of shape `(batch_size, sequence_length,
+ config.model_in_dim)`, or un-batched and of shape `(sequence_length, config.model_in_dim)`.
+
+ Returns:
+ `torch.FloatTensor`: Tensor containing the speech waveform. If the input spectrogram is batched, will be of
+ shape `(batch_size, num_frames,)`. If un-batched, will be of shape `(num_frames,)`.
+ """
+ if self.config.normalize_before:
+ spectrogram = (spectrogram - self.mean) / self.scale
+
+ is_batched = spectrogram.dim() == 3
+ if not is_batched:
+ spectrogram = spectrogram.unsqueeze(0)
+
+ hidden_states = spectrogram.transpose(2, 1)
+
+ hidden_states = self.conv_pre(hidden_states)
+ for i in range(self.num_upsamples):
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.config.leaky_relu_slope)
+ hidden_states = self.upsampler[i](hidden_states)
+
+ res_state = self.resblocks[i * self.num_kernels](hidden_states)
+ for j in range(1, self.num_kernels):
+ res_state += self.resblocks[i * self.num_kernels + j](hidden_states)
+ hidden_states = res_state / self.num_kernels
+
+ hidden_states = nn.functional.leaky_relu(hidden_states)
+ hidden_states = self.conv_post(hidden_states)
+ hidden_states = torch.tanh(hidden_states)
+
+ if not is_batched:
+ # remove batch dim and collapse tensor to 1-d audio waveform
+ waveform = hidden_states.squeeze(0).transpose(1, 0).view(-1)
+ else:
+ # remove seq-len dim since this collapses to 1
+ waveform = hidden_states.squeeze(1)
+
+ return waveform
+
+
+__all__ = [
+ "SpeechT5ForSpeechToText",
+ "SpeechT5ForSpeechToSpeech",
+ "SpeechT5ForTextToSpeech",
+ "SpeechT5Model",
+ "SpeechT5PreTrainedModel",
+ "SpeechT5HifiGan",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/number_normalizer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/number_normalizer.py
new file mode 100644
index 0000000000000000000000000000000000000000..eb3314c24f24c1f8b9bc760c4ece69e0a2819888
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/number_normalizer.py
@@ -0,0 +1,192 @@
+# coding=utf-8
+# Copyright 2023 The Fairseq Authors, Microsoft Research, and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Number Normalizer class for SpeechT5."""
+
+import re
+
+
+class EnglishNumberNormalizer:
+ def __init__(self):
+ self.ones = ["", "one", "two", "three", "four", "five", "six", "seven", "eight", "nine"]
+ self.teens = [
+ "",
+ "eleven",
+ "twelve",
+ "thirteen",
+ "fourteen",
+ "fifteen",
+ "sixteen",
+ "seventeen",
+ "eighteen",
+ "nineteen",
+ ]
+ self.tens = ["", "ten", "twenty", "thirty", "forty", "fifty", "sixty", "seventy", "eighty", "ninety"]
+ self.thousands = [
+ "",
+ "thousand",
+ "million",
+ "billion",
+ "trillion",
+ "quadrillion",
+ "quintillion",
+ "sextillion",
+ "septillion",
+ "octillion",
+ "nonillion",
+ "decillion",
+ ]
+
+ # Define a dictionary to map currency symbols to their names
+ # Top most traded currencies according to
+ # https://en.wikipedia.org/wiki/Template:Most_traded_currencies
+ self.currency_symbols = {
+ "$": " dollars",
+ "€": " euros",
+ "£": " pounds",
+ "¢": " cents",
+ "¥": " japanese yen",
+ "﷼": " saudi riyal",
+ "₹": " indian rupees",
+ "₽": " russian rubles",
+ "฿": " thai baht",
+ "₺": " turkish liras",
+ "₴": " ukrainian hryvnia",
+ "₣": " swiss francs",
+ "₡": " costa rican colon",
+ "₱": " philippine peso",
+ "₪": " israeli shekels",
+ "₮": " mongolian tögrög",
+ "₩": " south korean won",
+ "₦": " nigerian naira",
+ "₫": " vietnamese Đồng",
+ }
+
+ def spell_number(self, num):
+ if num == 0:
+ return "zero"
+
+ parts = []
+ for i in range(0, len(self.thousands)):
+ if num % 1000 != 0:
+ part = ""
+ hundreds = num % 1000 // 100
+ tens_units = num % 100
+
+ if hundreds > 0:
+ part += self.ones[hundreds] + " hundred"
+ if tens_units > 0:
+ part += " and "
+
+ if tens_units > 10 and tens_units < 20:
+ part += self.teens[tens_units - 10]
+ else:
+ tens_digit = self.tens[tens_units // 10]
+ ones_digit = self.ones[tens_units % 10]
+ if tens_digit:
+ part += tens_digit
+ if ones_digit:
+ if tens_digit:
+ part += " "
+ part += ones_digit
+
+ parts.append(part)
+
+ num //= 1000
+
+ return " ".join(reversed(parts))
+
+ def convert(self, number):
+ """
+ Converts an individual number passed in string form to spelt-out form
+ """
+ if "." in number:
+ integer_part, decimal_part = number.split(".")
+ else:
+ integer_part, decimal_part = number, "00"
+
+ # Extract currency symbol if present
+ currency_symbol = ""
+ for symbol, name in self.currency_symbols.items():
+ if integer_part.startswith(symbol):
+ currency_symbol = name
+ integer_part = integer_part[len(symbol) :]
+ break
+
+ if integer_part.startswith("-"):
+ if integer_part[1:].startswith(symbol):
+ currency_symbol = name
+ integer_part = "-" + integer_part[len(symbol) + 1 :]
+ break
+
+ # Extract 'minus' prefix for negative numbers
+ minus_prefix = ""
+ if integer_part.startswith("-"):
+ minus_prefix = "minus "
+ integer_part = integer_part[1:]
+ elif integer_part.startswith("minus"):
+ minus_prefix = "minus "
+ integer_part = integer_part[len("minus") :]
+
+ percent_suffix = ""
+ if "%" in integer_part or "%" in decimal_part:
+ percent_suffix = " percent"
+ integer_part = integer_part.replace("%", "")
+ decimal_part = decimal_part.replace("%", "")
+
+ integer_part = integer_part.zfill(3 * ((len(integer_part) - 1) // 3 + 1))
+
+ parts = []
+ for i in range(0, len(integer_part), 3):
+ chunk = int(integer_part[i : i + 3])
+ if chunk > 0:
+ part = self.spell_number(chunk)
+ unit = self.thousands[len(integer_part[i:]) // 3 - 1]
+ if unit:
+ part += " " + unit
+ parts.append(part)
+
+ spelled_integer = " ".join(parts)
+
+ # Format the spelt-out number based on conditions, such as:
+ # If it has decimal parts, currency symbol, minus prefix, etc
+ if decimal_part == "00":
+ return (
+ f"{minus_prefix}{spelled_integer}{percent_suffix}{currency_symbol}"
+ if minus_prefix or currency_symbol
+ else f"{spelled_integer}{percent_suffix}"
+ )
+ else:
+ spelled_decimal = " ".join([self.spell_number(int(digit)) for digit in decimal_part])
+ return (
+ f"{minus_prefix}{spelled_integer} point {spelled_decimal}{percent_suffix}{currency_symbol}"
+ if minus_prefix or currency_symbol
+ else f"{minus_prefix}{spelled_integer} point {spelled_decimal}{percent_suffix}"
+ )
+
+ def __call__(self, text):
+ """
+ Convert numbers / number-like quantities in a string to their spelt-out counterparts
+ """
+ # Form part of the pattern for all currency symbols
+ pattern = r"(? 15000, etc)
+ text = re.sub(r"(\d+,\d+)", lambda match: match.group(1).replace(",", ""), text)
+
+ # Use regex to find and replace numbers in the text
+ converted_text = re.sub(pattern, lambda match: self.convert(match.group(1)), text)
+ converted_text = re.sub(" +", " ", converted_text)
+
+ return converted_text
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/processing_speecht5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/processing_speecht5.py
new file mode 100644
index 0000000000000000000000000000000000000000..6be19f8ae9ed1c1cde5c4579b39344221b970758
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/processing_speecht5.py
@@ -0,0 +1,172 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Speech processor class for SpeechT5."""
+
+from ...processing_utils import ProcessorMixin
+
+
+class SpeechT5Processor(ProcessorMixin):
+ r"""
+ Constructs a SpeechT5 processor which wraps a feature extractor and a tokenizer into a single processor.
+
+ [`SpeechT5Processor`] offers all the functionalities of [`SpeechT5FeatureExtractor`] and [`SpeechT5Tokenizer`]. See
+ the docstring of [`~SpeechT5Processor.__call__`] and [`~SpeechT5Processor.decode`] for more information.
+
+ Args:
+ feature_extractor (`SpeechT5FeatureExtractor`):
+ An instance of [`SpeechT5FeatureExtractor`]. The feature extractor is a required input.
+ tokenizer (`SpeechT5Tokenizer`):
+ An instance of [`SpeechT5Tokenizer`]. The tokenizer is a required input.
+ """
+
+ feature_extractor_class = "SpeechT5FeatureExtractor"
+ tokenizer_class = "SpeechT5Tokenizer"
+
+ def __init__(self, feature_extractor, tokenizer):
+ super().__init__(feature_extractor, tokenizer)
+
+ def __call__(self, *args, **kwargs):
+ """
+ Processes audio and text input, as well as audio and text targets.
+
+ You can process audio by using the argument `audio`, or process audio targets by using the argument
+ `audio_target`. This forwards the arguments to SpeechT5FeatureExtractor's
+ [`~SpeechT5FeatureExtractor.__call__`].
+
+ You can process text by using the argument `text`, or process text labels by using the argument `text_target`.
+ This forwards the arguments to SpeechT5Tokenizer's [`~SpeechT5Tokenizer.__call__`].
+
+ Valid input combinations are:
+
+ - `text` only
+ - `audio` only
+ - `text_target` only
+ - `audio_target` only
+ - `text` and `audio_target`
+ - `audio` and `audio_target`
+ - `text` and `text_target`
+ - `audio` and `text_target`
+
+ Please refer to the docstring of the above two methods for more information.
+ """
+ audio = kwargs.pop("audio", None)
+ text = kwargs.pop("text", None)
+ text_target = kwargs.pop("text_target", None)
+ audio_target = kwargs.pop("audio_target", None)
+ sampling_rate = kwargs.pop("sampling_rate", None)
+
+ if audio is not None and text is not None:
+ raise ValueError(
+ "Cannot process both `audio` and `text` inputs. Did you mean `audio_target` or `text_target`?"
+ )
+ if audio_target is not None and text_target is not None:
+ raise ValueError(
+ "Cannot process both `audio_target` and `text_target` inputs. Did you mean `audio` or `text`?"
+ )
+ if audio is None and audio_target is None and text is None and text_target is None:
+ raise ValueError(
+ "You need to specify either an `audio`, `audio_target`, `text`, or `text_target` input to process."
+ )
+
+ if audio is not None:
+ inputs = self.feature_extractor(audio, *args, sampling_rate=sampling_rate, **kwargs)
+ elif text is not None:
+ inputs = self.tokenizer(text, **kwargs)
+ else:
+ inputs = None
+
+ if audio_target is not None:
+ targets = self.feature_extractor(audio_target=audio_target, *args, sampling_rate=sampling_rate, **kwargs)
+ labels = targets["input_values"]
+ elif text_target is not None:
+ targets = self.tokenizer(text_target, **kwargs)
+ labels = targets["input_ids"]
+ else:
+ targets = None
+
+ if inputs is None:
+ return targets
+
+ if targets is not None:
+ inputs["labels"] = labels
+
+ decoder_attention_mask = targets.get("attention_mask")
+ if decoder_attention_mask is not None:
+ inputs["decoder_attention_mask"] = decoder_attention_mask
+
+ return inputs
+
+ def pad(self, *args, **kwargs):
+ """
+ Collates the audio and text inputs, as well as their targets, into a padded batch.
+
+ Audio inputs are padded by SpeechT5FeatureExtractor's [`~SpeechT5FeatureExtractor.pad`]. Text inputs are padded
+ by SpeechT5Tokenizer's [`~SpeechT5Tokenizer.pad`].
+
+ Valid input combinations are:
+
+ - `input_ids` only
+ - `input_values` only
+ - `labels` only, either log-mel spectrograms or text tokens
+ - `input_ids` and log-mel spectrogram `labels`
+ - `input_values` and text `labels`
+
+ Please refer to the docstring of the above two methods for more information.
+ """
+ input_values = kwargs.pop("input_values", None)
+ input_ids = kwargs.pop("input_ids", None)
+ labels = kwargs.pop("labels", None)
+
+ if input_values is not None and input_ids is not None:
+ raise ValueError("Cannot process both `input_values` and `input_ids` inputs.")
+ if input_values is None and input_ids is None and labels is None:
+ raise ValueError(
+ "You need to specify either an `input_values`, `input_ids`, or `labels` input to be padded."
+ )
+
+ if input_values is not None:
+ inputs = self.feature_extractor.pad(input_values, *args, **kwargs)
+ elif input_ids is not None:
+ inputs = self.tokenizer.pad(input_ids, **kwargs)
+ else:
+ inputs = None
+
+ if labels is not None:
+ if "input_ids" in labels or (isinstance(labels, list) and "input_ids" in labels[0]):
+ targets = self.tokenizer.pad(labels, **kwargs)
+ labels = targets["input_ids"]
+ else:
+ feature_size_hack = self.feature_extractor.feature_size
+ self.feature_extractor.feature_size = self.feature_extractor.num_mel_bins
+ targets = self.feature_extractor.pad(labels, *args, **kwargs)
+ self.feature_extractor.feature_size = feature_size_hack
+ labels = targets["input_values"]
+ else:
+ targets = None
+
+ if inputs is None:
+ return targets
+
+ if targets is not None:
+ inputs["labels"] = labels
+
+ decoder_attention_mask = targets.get("attention_mask")
+ if decoder_attention_mask is not None:
+ inputs["decoder_attention_mask"] = decoder_attention_mask
+
+ return inputs
+
+
+__all__ = ["SpeechT5Processor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/tokenization_speecht5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/tokenization_speecht5.py
new file mode 100644
index 0000000000000000000000000000000000000000..de19db8568e542b6b2506e0652d48c89850c0e40
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/speecht5/tokenization_speecht5.py
@@ -0,0 +1,223 @@
+# coding=utf-8
+# Copyright 2023 The Facebook Inc. and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for SpeechT5."""
+
+import os
+from shutil import copyfile
+from typing import Any, Optional
+
+import sentencepiece as spm
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...utils import logging
+from ...utils.import_utils import requires
+from .number_normalizer import EnglishNumberNormalizer
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "spm_char.model"}
+
+
+@requires(backends=("sentencepiece",))
+class SpeechT5Tokenizer(PreTrainedTokenizer):
+ """
+ Construct a SpeechT5 tokenizer. Based on [SentencePiece](https://github.com/google/sentencepiece).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ [SentencePiece](https://github.com/google/sentencepiece) file (generally has a *.spm* extension) that
+ contains the vocabulary necessary to instantiate a tokenizer.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The begin of sequence token.
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sequence token.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ normalize (`bool`, *optional*, defaults to `False`):
+ Whether to convert numeric quantities in the text to their spelt-out english counterparts.
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+
+ Attributes:
+ sp_model (`SentencePieceProcessor`):
+ The *SentencePiece* processor that is used for every conversion (string, tokens and IDs).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ bos_token="",
+ eos_token=" ",
+ unk_token="",
+ pad_token="",
+ normalize=False,
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ **kwargs,
+ ) -> None:
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+ self.vocab_file = vocab_file
+ self.normalize = normalize
+ self._normalizer = None
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(vocab_file)
+
+ super().__init__(
+ bos_token=bos_token,
+ eos_token=eos_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ normalize=normalize,
+ sp_model_kwargs=self.sp_model_kwargs,
+ **kwargs,
+ )
+
+ def prepare_for_tokenization(self, text, is_split_into_words=False, **kwargs):
+ normalize = kwargs.pop("normalize", self.normalize)
+ if is_split_into_words:
+ text = " " + text
+ if normalize:
+ text = self.normalizer(text)
+ return (text, kwargs)
+
+ @property
+ def vocab_size(self):
+ return self.sp_model.get_piece_size()
+
+ @property
+ def normalizer(self):
+ if self._normalizer is None:
+ self._normalizer = EnglishNumberNormalizer()
+ return self._normalizer
+
+ @normalizer.setter
+ def normalizer(self, value):
+ self._normalizer = value
+
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ return state
+
+ def __setstate__(self, d):
+ self.__dict__ = d
+
+ # for backward compatibility
+ if not hasattr(self, "sp_model_kwargs"):
+ self.sp_model_kwargs = {}
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(self.vocab_file)
+
+ def _tokenize(self, text: str) -> list[str]:
+ """Take as input a string and return a list of strings (tokens) for words/sub-words"""
+ return self.sp_model.encode(text, out_type=str)
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.sp_model.piece_to_id(token)
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ token = self.sp_model.IdToPiece(index)
+ return token
+
+ # Copied from transformers.models.albert.tokenization_albert.AlbertTokenizer.convert_tokens_to_string
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ current_sub_tokens = []
+ out_string = ""
+ prev_is_special = False
+ for token in tokens:
+ # make sure that special tokens are not decoded using sentencepiece model
+ if token in self.all_special_tokens:
+ if not prev_is_special:
+ out_string += " "
+ out_string += self.sp_model.decode(current_sub_tokens) + token
+ prev_is_special = True
+ current_sub_tokens = []
+ else:
+ current_sub_tokens.append(token)
+ prev_is_special = False
+ out_string += self.sp_model.decode(current_sub_tokens)
+ return out_string.strip()
+
+ def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None) -> list[int]:
+ """Build model inputs from a sequence by appending eos_token_id."""
+ if token_ids_1 is None:
+ return token_ids_0 + [self.eos_token_id]
+ # We don't expect to process pairs, but leave the pair logic for API consistency
+ return token_ids_0 + token_ids_1 + [self.eos_token_id]
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ suffix_ones = [1]
+ if token_ids_1 is None:
+ return ([0] * len(token_ids_0)) + suffix_ones
+ return ([0] * len(token_ids_0)) + ([0] * len(token_ids_1)) + suffix_ones
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ elif not os.path.isfile(self.vocab_file):
+ with open(out_vocab_file, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["SpeechT5Tokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..258d79a9c347991b6b10d66608c5cc2b3a9cecae
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_splinter import *
+ from .modeling_splinter import *
+ from .tokenization_splinter import *
+ from .tokenization_splinter_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/configuration_splinter.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/configuration_splinter.py
new file mode 100644
index 0000000000000000000000000000000000000000..533b067ed34f3118a9f85896120110103b7993f0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/configuration_splinter.py
@@ -0,0 +1,123 @@
+# coding=utf-8
+# Copyright 2021 Tel AViv University, AllenAI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Splinter model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class SplinterConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SplinterModel`]. It is used to instantiate an
+ Splinter model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the Splinter
+ [tau/splinter-base](https://huggingface.co/tau/splinter-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the Splinter model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`SplinterModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimension of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the `token_type_ids` passed when calling [`SplinterModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ question_token_id (`int`, *optional*, defaults to 104):
+ The id of the `[QUESTION]` token.
+
+ Example:
+
+ ```python
+ >>> from transformers import SplinterModel, SplinterConfig
+
+ >>> # Initializing a Splinter tau/splinter-base style configuration
+ >>> configuration = SplinterConfig()
+
+ >>> # Initializing a model from the tau/splinter-base style configuration
+ >>> model = SplinterModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "splinter"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=512,
+ type_vocab_size=2,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ use_cache=True,
+ pad_token_id=0,
+ question_token_id=104,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.type_vocab_size = type_vocab_size
+ self.layer_norm_eps = layer_norm_eps
+ self.use_cache = use_cache
+ self.question_token_id = question_token_id
+
+
+__all__ = ["SplinterConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/modeling_splinter.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/modeling_splinter.py
new file mode 100644
index 0000000000000000000000000000000000000000..905c7a27ad3d166df988d2d12787be06310d4e87
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/modeling_splinter.py
@@ -0,0 +1,863 @@
+# coding=utf-8
+# Copyright 2021 Tel AViv University, AllenAI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Splinter model."""
+
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ModelOutput, QuestionAnsweringModelOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import (
+ auto_docstring,
+ can_return_tuple,
+ logging,
+)
+from .configuration_splinter import SplinterConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class SplinterEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ ) -> tuple:
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+# Copied from transformers.models.align.modeling_align.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.align.modeling_align.AlignTextSelfAttention with AlignText->Splinter
+class SplinterSelfAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.attention_dropout = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ **kwargs,
+ ) -> tuple[torch.Tensor]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.attention_head_size)
+
+ query_states = self.query(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.key(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.value(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ head_mask=head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ outputs = (attn_output, attn_weights) if output_attentions else (attn_output,)
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertSelfOutput with Bert->Splinter
+class SplinterSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+# Copied from transformers.models.align.modeling_align.AlignTextAttention with AlignText->Splinter
+class SplinterAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.self = SplinterSelfAttention(config)
+ self.output = SplinterSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ **kwargs,
+ ) -> tuple[torch.Tensor]:
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ **kwargs,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertIntermediate with Bert->Splinter
+class SplinterIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertOutput with Bert->Splinter
+class SplinterOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+# Copied from transformers.models.align.modeling_align.AlignTextLayer with AlignText->Splinter
+class SplinterLayer(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = SplinterAttention(config)
+ self.intermediate = SplinterIntermediate(config)
+ self.output = SplinterOutput(config)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ **kwargs,
+ ) -> tuple[torch.Tensor]:
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ **kwargs,
+ )
+ attention_output = self_attention_outputs[0]
+
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+# Copied from transformers.models.align.modeling_align.AlignTextEncoder with AlignText->Splinter
+class SplinterEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([SplinterLayer(config) for i in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ @can_return_tuple
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ **kwargs,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutput]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ **kwargs,
+ )
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+@auto_docstring
+class SplinterPreTrainedModel(PreTrainedModel):
+ config: SplinterConfig
+ base_model_prefix = "splinter"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+@auto_docstring
+class SplinterModel(SplinterPreTrainedModel):
+ """
+ The model is an encoder (with only self-attention) following the architecture described in [Attention is all you
+ need](https://huggingface.co/papers/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones,
+ Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin.
+ """
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = SplinterEmbeddings(config)
+ self.encoder = SplinterEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `batch_size, sequence_length`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `batch_size, sequence_length`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(((batch_size, seq_length)), device=device)
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ )
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ )
+ sequence_output = encoder_outputs[0]
+
+ return BaseModelOutput(
+ last_hidden_state=sequence_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class SplinterFullyConnectedLayer(nn.Module):
+ def __init__(self, input_dim, output_dim, hidden_act="gelu"):
+ super().__init__()
+
+ self.input_dim = input_dim
+ self.output_dim = output_dim
+
+ self.dense = nn.Linear(self.input_dim, self.output_dim)
+ self.act_fn = ACT2FN[hidden_act]
+ self.LayerNorm = nn.LayerNorm(self.output_dim)
+
+ def forward(self, inputs: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(inputs)
+ hidden_states = self.act_fn(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states)
+ return hidden_states
+
+
+class QuestionAwareSpanSelectionHead(nn.Module):
+ """
+ Implementation of Question-Aware Span Selection (QASS) head, described in Splinter's paper:
+
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.query_start_transform = SplinterFullyConnectedLayer(config.hidden_size, config.hidden_size)
+ self.query_end_transform = SplinterFullyConnectedLayer(config.hidden_size, config.hidden_size)
+ self.start_transform = SplinterFullyConnectedLayer(config.hidden_size, config.hidden_size)
+ self.end_transform = SplinterFullyConnectedLayer(config.hidden_size, config.hidden_size)
+
+ self.start_classifier = nn.Linear(config.hidden_size, config.hidden_size, bias=False)
+ self.end_classifier = nn.Linear(config.hidden_size, config.hidden_size, bias=False)
+
+ def forward(self, inputs, positions):
+ _, _, dim = inputs.size()
+ index = positions.unsqueeze(-1).repeat(1, 1, dim) # [batch_size, num_positions, dim]
+ gathered_reps = torch.gather(inputs, dim=1, index=index) # [batch_size, num_positions, dim]
+
+ query_start_reps = self.query_start_transform(gathered_reps) # [batch_size, num_positions, dim]
+ query_end_reps = self.query_end_transform(gathered_reps) # [batch_size, num_positions, dim]
+ start_reps = self.start_transform(inputs) # [batch_size, seq_length, dim]
+ end_reps = self.end_transform(inputs) # [batch_size, seq_length, dim]
+
+ hidden_states = self.start_classifier(query_start_reps) # [batch_size, num_positions, dim]
+ start_reps = start_reps.permute(0, 2, 1) # [batch_size, dim, seq_length]
+ start_logits = torch.matmul(hidden_states, start_reps)
+
+ hidden_states = self.end_classifier(query_end_reps)
+ end_reps = end_reps.permute(0, 2, 1)
+ end_logits = torch.matmul(hidden_states, end_reps)
+
+ return start_logits, end_logits
+
+
+@auto_docstring
+class SplinterForQuestionAnswering(SplinterPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.splinter = SplinterModel(config)
+ self.splinter_qass = QuestionAwareSpanSelectionHead(config)
+ self.question_token_id = config.question_token_id
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ question_positions: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple, QuestionAnsweringModelOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `batch_size, sequence_length`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `batch_size, sequence_length`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ question_positions (`torch.LongTensor` of shape `(batch_size, num_questions)`, *optional*):
+ The positions of all question tokens. If given, start_logits and end_logits will be of shape `(batch_size,
+ num_questions, sequence_length)`. If None, the first question token in each sequence in the batch will be
+ the only one for which start_logits and end_logits are calculated and they will be of shape `(batch_size,
+ sequence_length)`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ question_positions_were_none = False
+ if question_positions is None:
+ if input_ids is not None:
+ question_position_for_each_example = torch.argmax(
+ (torch.eq(input_ids, self.question_token_id)).int(), dim=-1
+ )
+ else:
+ question_position_for_each_example = torch.zeros(
+ inputs_embeds.size(0), dtype=torch.long, layout=inputs_embeds.layout, device=inputs_embeds.device
+ )
+ question_positions = question_position_for_each_example.unsqueeze(-1)
+ question_positions_were_none = True
+
+ outputs = self.splinter(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ start_logits, end_logits = self.splinter_qass(sequence_output, question_positions)
+
+ if question_positions_were_none:
+ start_logits, end_logits = start_logits.squeeze(1), end_logits.squeeze(1)
+
+ if attention_mask is not None:
+ start_logits = start_logits + (1 - attention_mask) * torch.finfo(start_logits.dtype).min
+ end_logits = end_logits + (1 - attention_mask) * torch.finfo(end_logits.dtype).min
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions.clamp_(0, ignored_index)
+ end_positions.clamp_(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[1:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return QuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for outputs of Splinter as a span selection model.
+ """
+)
+class SplinterForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when start and end positions are provided):
+ Total span extraction loss is the sum of a Cross-Entropy for the start and end positions.
+ start_logits (`torch.FloatTensor` of shape `(batch_size, num_questions, sequence_length)`):
+ Span-start scores (before SoftMax).
+ end_logits (`torch.FloatTensor` of shape `(batch_size, num_questions, sequence_length)`):
+ Span-end scores (before SoftMax).
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ start_logits: Optional[torch.FloatTensor] = None
+ end_logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@auto_docstring(
+ custom_intro="""
+ Splinter Model for the recurring span selection task as done during the pretraining. The difference to the QA task
+ is that we do not have a question, but multiple question tokens that replace the occurrences of recurring spans
+ instead.
+ """
+)
+class SplinterForPreTraining(SplinterPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.splinter = SplinterModel(config)
+ self.splinter_qass = QuestionAwareSpanSelectionHead(config)
+ self.question_token_id = config.question_token_id
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ question_positions: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple, SplinterForPreTrainingOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_questions, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ token_type_ids (`torch.LongTensor` of shape `batch_size, num_questions, sequence_length`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `batch_size, num_questions, sequence_length`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_questions, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert *input_ids* indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ start_positions (`torch.LongTensor` of shape `(batch_size, num_questions)`, *optional*):
+ Labels for position (index) of the start of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ end_positions (`torch.LongTensor` of shape `(batch_size, num_questions)`, *optional*):
+ Labels for position (index) of the end of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ question_positions (`torch.LongTensor` of shape `(batch_size, num_questions)`, *optional*):
+ The positions of all question tokens. If given, start_logits and end_logits will be of shape `(batch_size,
+ num_questions, sequence_length)`. If None, the first question token in each sequence in the batch will be
+ the only one for which start_logits and end_logits are calculated and they will be of shape `(batch_size,
+ sequence_length)`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if question_positions is None and start_positions is not None and end_positions is not None:
+ raise TypeError("question_positions must be specified in order to calculate the loss")
+
+ elif question_positions is None and input_ids is None:
+ raise TypeError("question_positions must be specified when input_embeds is used")
+
+ elif question_positions is None:
+ question_positions = self._prepare_question_positions(input_ids)
+
+ outputs = self.splinter(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ batch_size, sequence_length, dim = sequence_output.size()
+ # [batch_size, num_questions, sequence_length]
+ start_logits, end_logits = self.splinter_qass(sequence_output, question_positions)
+
+ num_questions = question_positions.size(1)
+ if attention_mask is not None:
+ attention_mask_for_each_question = attention_mask.unsqueeze(1).expand(
+ batch_size, num_questions, sequence_length
+ )
+ start_logits = start_logits + (1 - attention_mask_for_each_question) * torch.finfo(start_logits.dtype).min
+ end_logits = end_logits + (1 - attention_mask_for_each_question) * torch.finfo(end_logits.dtype).min
+
+ total_loss = None
+ # [batch_size, num_questions, sequence_length]
+ if start_positions is not None and end_positions is not None:
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ start_positions.clamp_(0, max(0, sequence_length - 1))
+ end_positions.clamp_(0, max(0, sequence_length - 1))
+
+ # Ignore zero positions in the loss. Splinter never predicts zero
+ # during pretraining and zero is used for padding question
+ # tokens as well as for start and end positions of padded
+ # question tokens.
+ loss_fct = CrossEntropyLoss(ignore_index=self.config.pad_token_id)
+ start_loss = loss_fct(
+ start_logits.view(batch_size * num_questions, sequence_length),
+ start_positions.view(batch_size * num_questions),
+ )
+ end_loss = loss_fct(
+ end_logits.view(batch_size * num_questions, sequence_length),
+ end_positions.view(batch_size * num_questions),
+ )
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[1:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return SplinterForPreTrainingOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def _prepare_question_positions(self, input_ids: torch.Tensor) -> torch.Tensor:
+ rows, flat_positions = torch.where(input_ids == self.config.question_token_id)
+ num_questions = torch.bincount(rows)
+ positions = torch.full(
+ (input_ids.size(0), num_questions.max()),
+ self.config.pad_token_id,
+ dtype=torch.long,
+ device=input_ids.device,
+ )
+ cols = torch.cat([torch.arange(n) for n in num_questions])
+ positions[rows, cols] = flat_positions
+ return positions
+
+
+__all__ = [
+ "SplinterForQuestionAnswering",
+ "SplinterForPreTraining",
+ "SplinterLayer",
+ "SplinterModel",
+ "SplinterPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/tokenization_splinter.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/tokenization_splinter.py
new file mode 100644
index 0000000000000000000000000000000000000000..f2ccafe12d5a9cbdcf777e520401ec0ff863a0b7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/tokenization_splinter.py
@@ -0,0 +1,507 @@
+# coding=utf-8
+# Copyright 2021 Tel AViv University, AllenAI and The HuggingFace Inc. team. All rights reserved.
+# All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for Splinter."""
+
+import collections
+import os
+import unicodedata
+from typing import Optional
+
+from ...tokenization_utils import PreTrainedTokenizer, _is_control, _is_punctuation, _is_whitespace
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "vocab.txt"}
+
+
+def load_vocab(vocab_file):
+ """Loads a vocabulary file into a dictionary."""
+ vocab = collections.OrderedDict()
+ with open(vocab_file, "r", encoding="utf-8") as reader:
+ tokens = reader.readlines()
+ for index, token in enumerate(tokens):
+ token = token.rstrip("\n")
+ vocab[token] = index
+ return vocab
+
+
+def whitespace_tokenize(text):
+ """Runs basic whitespace cleaning and splitting on a piece of text."""
+ text = text.strip()
+ if not text:
+ return []
+ tokens = text.split()
+ return tokens
+
+
+class SplinterTokenizer(PreTrainedTokenizer):
+ r"""
+ Construct a Splinter tokenizer. Based on WordPiece.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ do_basic_tokenize (`bool`, *optional*, defaults to `True`):
+ Whether or not to do basic tokenization before WordPiece.
+ never_split (`Iterable`, *optional*):
+ Collection of tokens which will never be split during tokenization. Only has an effect when
+ `do_basic_tokenize=True`
+ unk_token (`str`, *optional*, defaults to `"[UNK]"`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ sep_token (`str`, *optional*, defaults to `"[SEP]"`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `"[PAD]"`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `"[CLS]"`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `"[MASK]"`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ question_token (`str`, *optional*, defaults to `"[QUESTION]"`):
+ The token used for constructing question representations.
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters.
+
+ This should likely be deactivated for Japanese (see this
+ [issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original BERT).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+
+ def __init__(
+ self,
+ vocab_file,
+ do_lower_case=True,
+ do_basic_tokenize=True,
+ never_split=None,
+ unk_token="[UNK]",
+ sep_token="[SEP]",
+ pad_token="[PAD]",
+ cls_token="[CLS]",
+ mask_token="[MASK]",
+ question_token="[QUESTION]",
+ tokenize_chinese_chars=True,
+ strip_accents=None,
+ **kwargs,
+ ):
+ if not os.path.isfile(vocab_file):
+ raise ValueError(
+ f"Can't find a vocabulary file at path '{vocab_file}'. To load the vocabulary from a Google pretrained"
+ " model use `tokenizer = BertTokenizer.from_pretrained(PRETRAINED_MODEL_NAME)`"
+ )
+ self.vocab = load_vocab(vocab_file)
+ self.ids_to_tokens = collections.OrderedDict([(ids, tok) for tok, ids in self.vocab.items()])
+ self.do_basic_tokenize = do_basic_tokenize
+ if do_basic_tokenize:
+ self.basic_tokenizer = BasicTokenizer(
+ do_lower_case=do_lower_case,
+ never_split=never_split,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ )
+ self.wordpiece_tokenizer = WordpieceTokenizer(vocab=self.vocab, unk_token=str(unk_token))
+ self.question_token = question_token
+ super().__init__(
+ do_lower_case=do_lower_case,
+ do_basic_tokenize=do_basic_tokenize,
+ never_split=never_split,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ question_token=question_token,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ **kwargs,
+ )
+
+ @property
+ def question_token_id(self):
+ """
+ `Optional[int]`: Id of the question token in the vocabulary, used to condition the answer on a question
+ representation.
+ """
+ return self.convert_tokens_to_ids(self.question_token)
+
+ @property
+ def do_lower_case(self):
+ return self.basic_tokenizer.do_lower_case
+
+ @property
+ def vocab_size(self):
+ return len(self.vocab)
+
+ def get_vocab(self):
+ return dict(self.vocab, **self.added_tokens_encoder)
+
+ def _tokenize(self, text):
+ split_tokens = []
+ if self.do_basic_tokenize:
+ for token in self.basic_tokenizer.tokenize(text, never_split=self.all_special_tokens):
+ # If the token is part of the never_split set
+ if token in self.basic_tokenizer.never_split:
+ split_tokens.append(token)
+ else:
+ split_tokens += self.wordpiece_tokenizer.tokenize(token)
+ else:
+ split_tokens = self.wordpiece_tokenizer.tokenize(text)
+ return split_tokens
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.vocab.get(token, self.vocab.get(self.unk_token))
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ return self.ids_to_tokens.get(index, self.unk_token)
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ out_string = " ".join(tokens).replace(" ##", "").strip()
+ return out_string
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a pair of sequence for question answering tasks by concatenating and adding special
+ tokens. A Splinter sequence has the following format:
+
+ - single sequence: `[CLS] X [SEP]`
+ - pair of sequences for question answering: `[CLS] question_tokens [QUESTION] . [SEP] context_tokens [SEP]`
+
+ Args:
+ token_ids_0 (`list[int]`):
+ The question token IDs if pad_on_right, else context tokens IDs
+ token_ids_1 (`list[int]`, *optional*):
+ The context token IDs if pad_on_right, else question token IDs
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ if token_ids_1 is None:
+ return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
+
+ cls = [self.cls_token_id]
+ sep = [self.sep_token_id]
+ question_suffix = [self.question_token_id] + [self.convert_tokens_to_ids(".")]
+ if self.padding_side == "right":
+ # Input is question-then-context
+ return cls + token_ids_0 + question_suffix + sep + token_ids_1 + sep
+ else:
+ # Input is context-then-question
+ return cls + token_ids_0 + sep + token_ids_1 + question_suffix + sep
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ if token_ids_1 is not None:
+ return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
+ return [1] + ([0] * len(token_ids_0)) + [1]
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create the token type IDs corresponding to the sequences passed. [What are token type
+ IDs?](../glossary#token-type-ids)
+
+ Should be overridden in a subclass if the model has a special way of building those.
+
+ Args:
+ token_ids_0 (`list[int]`): The first tokenized sequence.
+ token_ids_1 (`list[int]`, *optional*): The second tokenized sequence.
+
+ Returns:
+ `list[int]`: The token type ids.
+ """
+ sep = [self.sep_token_id]
+ cls = [self.cls_token_id]
+ question_suffix = [self.question_token_id] + [self.convert_tokens_to_ids(".")]
+ if token_ids_1 is None:
+ return len(cls + token_ids_0 + sep) * [0]
+
+ if self.padding_side == "right":
+ # Input is question-then-context
+ return len(cls + token_ids_0 + question_suffix + sep) * [0] + len(token_ids_1 + sep) * [1]
+ else:
+ # Input is context-then-question
+ return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + question_suffix + sep) * [1]
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ index = 0
+ if os.path.isdir(save_directory):
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+ else:
+ vocab_file = (filename_prefix + "-" if filename_prefix else "") + save_directory
+ with open(vocab_file, "w", encoding="utf-8") as writer:
+ for token, token_index in sorted(self.vocab.items(), key=lambda kv: kv[1]):
+ if index != token_index:
+ logger.warning(
+ f"Saving vocabulary to {vocab_file}: vocabulary indices are not consecutive."
+ " Please check that the vocabulary is not corrupted!"
+ )
+ index = token_index
+ writer.write(token + "\n")
+ index += 1
+ return (vocab_file,)
+
+
+class BasicTokenizer:
+ """
+ Constructs a BasicTokenizer that will run basic tokenization (punctuation splitting, lower casing, etc.).
+
+ Args:
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ never_split (`Iterable`, *optional*):
+ Collection of tokens which will never be split during tokenization. Only has an effect when
+ `do_basic_tokenize=True`
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters.
+
+ This should likely be deactivated for Japanese (see this
+ [issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original BERT).
+ """
+
+ def __init__(self, do_lower_case=True, never_split=None, tokenize_chinese_chars=True, strip_accents=None):
+ if never_split is None:
+ never_split = []
+ self.do_lower_case = do_lower_case
+ self.never_split = set(never_split)
+ self.tokenize_chinese_chars = tokenize_chinese_chars
+ self.strip_accents = strip_accents
+
+ def tokenize(self, text, never_split=None):
+ """
+ Basic Tokenization of a piece of text. Split on "white spaces" only, for sub-word tokenization, see
+ WordPieceTokenizer.
+
+ Args:
+ **never_split**: (*optional*) list of str
+ Kept for backward compatibility purposes. Now implemented directly at the base class level (see
+ [`PreTrainedTokenizer.tokenize`]) List of token not to split.
+ """
+ # union() returns a new set by concatenating the two sets.
+ never_split = self.never_split.union(set(never_split)) if never_split else self.never_split
+ text = self._clean_text(text)
+
+ # This was added on November 1st, 2018 for the multilingual and Chinese
+ # models. This is also applied to the English models now, but it doesn't
+ # matter since the English models were not trained on any Chinese data
+ # and generally don't have any Chinese data in them (there are Chinese
+ # characters in the vocabulary because Wikipedia does have some Chinese
+ # words in the English Wikipedia.).
+ if self.tokenize_chinese_chars:
+ text = self._tokenize_chinese_chars(text)
+ orig_tokens = whitespace_tokenize(text)
+ split_tokens = []
+ for token in orig_tokens:
+ if token not in never_split:
+ if self.do_lower_case:
+ token = token.lower()
+ if self.strip_accents is not False:
+ token = self._run_strip_accents(token)
+ elif self.strip_accents:
+ token = self._run_strip_accents(token)
+ split_tokens.extend(self._run_split_on_punc(token, never_split))
+
+ output_tokens = whitespace_tokenize(" ".join(split_tokens))
+ return output_tokens
+
+ def _run_strip_accents(self, text):
+ """Strips accents from a piece of text."""
+ text = unicodedata.normalize("NFD", text)
+ output = []
+ for char in text:
+ cat = unicodedata.category(char)
+ if cat == "Mn":
+ continue
+ output.append(char)
+ return "".join(output)
+
+ def _run_split_on_punc(self, text, never_split=None):
+ """Splits punctuation on a piece of text."""
+ if never_split is not None and text in never_split:
+ return [text]
+ chars = list(text)
+ i = 0
+ start_new_word = True
+ output = []
+ while i < len(chars):
+ char = chars[i]
+ if _is_punctuation(char):
+ output.append([char])
+ start_new_word = True
+ else:
+ if start_new_word:
+ output.append([])
+ start_new_word = False
+ output[-1].append(char)
+ i += 1
+
+ return ["".join(x) for x in output]
+
+ def _tokenize_chinese_chars(self, text):
+ """Adds whitespace around any CJK character."""
+ output = []
+ for char in text:
+ cp = ord(char)
+ if self._is_chinese_char(cp):
+ output.append(" ")
+ output.append(char)
+ output.append(" ")
+ else:
+ output.append(char)
+ return "".join(output)
+
+ def _is_chinese_char(self, cp):
+ """Checks whether CP is the codepoint of a CJK character."""
+ # This defines a "chinese character" as anything in the CJK Unicode block:
+ # https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block)
+ #
+ # Note that the CJK Unicode block is NOT all Japanese and Korean characters,
+ # despite its name. The modern Korean Hangul alphabet is a different block,
+ # as is Japanese Hiragana and Katakana. Those alphabets are used to write
+ # space-separated words, so they are not treated specially and handled
+ # like the all of the other languages.
+ if (
+ (cp >= 0x4E00 and cp <= 0x9FFF)
+ or (cp >= 0x3400 and cp <= 0x4DBF)
+ or (cp >= 0x20000 and cp <= 0x2A6DF)
+ or (cp >= 0x2A700 and cp <= 0x2B73F)
+ or (cp >= 0x2B740 and cp <= 0x2B81F)
+ or (cp >= 0x2B820 and cp <= 0x2CEAF)
+ or (cp >= 0xF900 and cp <= 0xFAFF)
+ or (cp >= 0x2F800 and cp <= 0x2FA1F)
+ ):
+ return True
+
+ return False
+
+ def _clean_text(self, text):
+ """Performs invalid character removal and whitespace cleanup on text."""
+ output = []
+ for char in text:
+ cp = ord(char)
+ if cp == 0 or cp == 0xFFFD or _is_control(char):
+ continue
+ if _is_whitespace(char):
+ output.append(" ")
+ else:
+ output.append(char)
+ return "".join(output)
+
+
+class WordpieceTokenizer:
+ """Runs WordPiece tokenization."""
+
+ def __init__(self, vocab, unk_token, max_input_chars_per_word=100):
+ self.vocab = vocab
+ self.unk_token = unk_token
+ self.max_input_chars_per_word = max_input_chars_per_word
+
+ def tokenize(self, text):
+ """
+ Tokenizes a piece of text into its word pieces. This uses a greedy longest-match-first algorithm to perform
+ tokenization using the given vocabulary.
+
+ For example, `input = "unaffable"` will return as output `["un", "##aff", "##able"]`.
+
+ Args:
+ text: A single token or whitespace separated tokens. This should have
+ already been passed through *BasicTokenizer*.
+
+ Returns:
+ A list of wordpiece tokens.
+ """
+
+ output_tokens = []
+ for token in whitespace_tokenize(text):
+ chars = list(token)
+ if len(chars) > self.max_input_chars_per_word:
+ output_tokens.append(self.unk_token)
+ continue
+
+ is_bad = False
+ start = 0
+ sub_tokens = []
+ while start < len(chars):
+ end = len(chars)
+ cur_substr = None
+ while start < end:
+ substr = "".join(chars[start:end])
+ if start > 0:
+ substr = "##" + substr
+ if substr in self.vocab:
+ cur_substr = substr
+ break
+ end -= 1
+ if cur_substr is None:
+ is_bad = True
+ break
+ sub_tokens.append(cur_substr)
+ start = end
+
+ if is_bad:
+ output_tokens.append(self.unk_token)
+ else:
+ output_tokens.extend(sub_tokens)
+ return output_tokens
+
+
+__all__ = ["SplinterTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/tokenization_splinter_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/tokenization_splinter_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..548d8e6c63b0dda90e66dc37be406fb45d68e2f8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/splinter/tokenization_splinter_fast.py
@@ -0,0 +1,193 @@
+# coding=utf-8
+# Copyright 2021 Tel AViv University, AllenAI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Tokenization classes for Splinter."""
+
+import json
+from typing import Optional
+
+from tokenizers import normalizers
+
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import logging
+from .tokenization_splinter import SplinterTokenizer
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "vocab.txt"}
+
+
+class SplinterTokenizerFast(PreTrainedTokenizerFast):
+ r"""
+ Construct a "fast" Splinter tokenizer (backed by HuggingFace's *tokenizers* library). Based on WordPiece.
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ unk_token (`str`, *optional*, defaults to `"[UNK]"`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ sep_token (`str`, *optional*, defaults to `"[SEP]"`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `"[PAD]"`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `"[CLS]"`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `"[MASK]"`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ question_token (`str`, *optional*, defaults to `"[QUESTION]"`):
+ The token used for constructing question representations.
+ clean_text (`bool`, *optional*, defaults to `True`):
+ Whether or not to clean the text before tokenization by removing any control characters and replacing all
+ whitespaces by the classic one.
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters. This should likely be deactivated for Japanese (see [this
+ issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original BERT).
+ wordpieces_prefix (`str`, *optional*, defaults to `"##"`):
+ The prefix for subwords.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ slow_tokenizer_class = SplinterTokenizer
+
+ def __init__(
+ self,
+ vocab_file=None,
+ tokenizer_file=None,
+ do_lower_case=True,
+ unk_token="[UNK]",
+ sep_token="[SEP]",
+ pad_token="[PAD]",
+ cls_token="[CLS]",
+ mask_token="[MASK]",
+ question_token="[QUESTION]",
+ tokenize_chinese_chars=True,
+ strip_accents=None,
+ **kwargs,
+ ):
+ super().__init__(
+ vocab_file,
+ tokenizer_file=tokenizer_file,
+ do_lower_case=do_lower_case,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ additional_special_tokens=(question_token,),
+ **kwargs,
+ )
+
+ pre_tok_state = json.loads(self.backend_tokenizer.normalizer.__getstate__())
+ if (
+ pre_tok_state.get("lowercase", do_lower_case) != do_lower_case
+ or pre_tok_state.get("strip_accents", strip_accents) != strip_accents
+ ):
+ pre_tok_class = getattr(normalizers, pre_tok_state.pop("type"))
+ pre_tok_state["lowercase"] = do_lower_case
+ pre_tok_state["strip_accents"] = strip_accents
+ self.backend_tokenizer.normalizer = pre_tok_class(**pre_tok_state)
+
+ self.do_lower_case = do_lower_case
+
+ @property
+ def question_token_id(self):
+ """
+ `Optional[int]`: Id of the question token in the vocabulary, used to condition the answer on a question
+ representation.
+ """
+ return self.convert_tokens_to_ids(self.question_token)
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a pair of sequence for question answering tasks by concatenating and adding special
+ tokens. A Splinter sequence has the following format:
+
+ - single sequence: `[CLS] X [SEP]`
+ - pair of sequences for question answering: `[CLS] question_tokens [QUESTION] . [SEP] context_tokens [SEP]`
+
+ Args:
+ token_ids_0 (`list[int]`):
+ The question token IDs if pad_on_right, else context tokens IDs
+ token_ids_1 (`list[int]`, *optional*):
+ The context token IDs if pad_on_right, else question token IDs
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ if token_ids_1 is None:
+ return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
+
+ cls = [self.cls_token_id]
+ sep = [self.sep_token_id]
+ question_suffix = [self.question_token_id] + [self.convert_tokens_to_ids(".")]
+ if self.padding_side == "right":
+ # Input is question-then-context
+ return cls + token_ids_0 + question_suffix + sep + token_ids_1 + sep
+ else:
+ # Input is context-then-question
+ return cls + token_ids_0 + sep + token_ids_1 + question_suffix + sep
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create the token type IDs corresponding to the sequences passed. [What are token type
+ IDs?](../glossary#token-type-ids)
+
+ Should be overridden in a subclass if the model has a special way of building those.
+
+ Args:
+ token_ids_0 (`list[int]`): The first tokenized sequence.
+ token_ids_1 (`list[int]`, *optional*): The second tokenized sequence.
+
+ Returns:
+ `list[int]`: The token type ids.
+ """
+ sep = [self.sep_token_id]
+ cls = [self.cls_token_id]
+ question_suffix = [self.question_token_id] + [self.convert_tokens_to_ids(".")]
+ if token_ids_1 is None:
+ return len(cls + token_ids_0 + sep) * [0]
+
+ if self.padding_side == "right":
+ # Input is question-then-context
+ return len(cls + token_ids_0 + question_suffix + sep) * [0] + len(token_ids_1 + sep) * [1]
+ else:
+ # Input is context-then-question
+ return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + question_suffix + sep) * [1]
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ files = self._tokenizer.model.save(save_directory, name=filename_prefix)
+ return tuple(files)
+
+
+__all__ = ["SplinterTokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e0a760d2b5cae36272850ddd2035976e476a6315
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_squeezebert import *
+ from .modeling_squeezebert import *
+ from .tokenization_squeezebert import *
+ from .tokenization_squeezebert_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/configuration_squeezebert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/configuration_squeezebert.py
new file mode 100644
index 0000000000000000000000000000000000000000..4b3c080a3d6ee7a9843ebfe95f64ee0d715a6688
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/configuration_squeezebert.py
@@ -0,0 +1,167 @@
+# coding=utf-8
+# Copyright 2020 The SqueezeBert authors and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""SqueezeBERT model configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class SqueezeBertConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SqueezeBertModel`]. It is used to instantiate a
+ SqueezeBERT model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the SqueezeBERT
+ [squeezebert/squeezebert-uncased](https://huggingface.co/squeezebert/squeezebert-uncased) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the SqueezeBERT model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`SqueezeBertModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the `token_type_ids` passed when calling [`BertModel`] or [`TFBertModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+
+ pad_token_id (`int`, *optional*, defaults to 0):
+ The ID of the token in the word embedding to use as padding.
+ embedding_size (`int`, *optional*, defaults to 768):
+ The dimension of the word embedding vectors.
+
+ q_groups (`int`, *optional*, defaults to 4):
+ The number of groups in Q layer.
+ k_groups (`int`, *optional*, defaults to 4):
+ The number of groups in K layer.
+ v_groups (`int`, *optional*, defaults to 4):
+ The number of groups in V layer.
+ post_attention_groups (`int`, *optional*, defaults to 1):
+ The number of groups in the first feed forward network layer.
+ intermediate_groups (`int`, *optional*, defaults to 4):
+ The number of groups in the second feed forward network layer.
+ output_groups (`int`, *optional*, defaults to 4):
+ The number of groups in the third feed forward network layer.
+
+ Examples:
+
+ ```python
+ >>> from transformers import SqueezeBertConfig, SqueezeBertModel
+
+ >>> # Initializing a SqueezeBERT configuration
+ >>> configuration = SqueezeBertConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration above
+ >>> model = SqueezeBertModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```
+ """
+
+ model_type = "squeezebert"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=512,
+ type_vocab_size=2,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ pad_token_id=0,
+ embedding_size=768,
+ q_groups=4,
+ k_groups=4,
+ v_groups=4,
+ post_attention_groups=1,
+ intermediate_groups=4,
+ output_groups=4,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.hidden_act = hidden_act
+ self.intermediate_size = intermediate_size
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.max_position_embeddings = max_position_embeddings
+ self.type_vocab_size = type_vocab_size
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.embedding_size = embedding_size
+ self.q_groups = q_groups
+ self.k_groups = k_groups
+ self.v_groups = v_groups
+ self.post_attention_groups = post_attention_groups
+ self.intermediate_groups = intermediate_groups
+ self.output_groups = output_groups
+
+
+# # Copied from transformers.models.bert.configuration_bert.BertOnxxConfig with Bert->SqueezeBert
+class SqueezeBertOnnxConfig(OnnxConfig):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ if self.task == "multiple-choice":
+ dynamic_axis = {0: "batch", 1: "choice", 2: "sequence"}
+ else:
+ dynamic_axis = {0: "batch", 1: "sequence"}
+ return OrderedDict(
+ [
+ ("input_ids", dynamic_axis),
+ ("attention_mask", dynamic_axis),
+ ("token_type_ids", dynamic_axis),
+ ]
+ )
+
+
+__all__ = ["SqueezeBertConfig", "SqueezeBertOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/modeling_squeezebert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/modeling_squeezebert.py
new file mode 100644
index 0000000000000000000000000000000000000000..a732e76bda6a082b5ff8ebf57c49d58b74f41a55
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/modeling_squeezebert.py
@@ -0,0 +1,962 @@
+# coding=utf-8
+# Copyright 2020 The SqueezeBert authors and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch SqueezeBert model."""
+
+import math
+from typing import Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPooling,
+ MaskedLMOutput,
+ MultipleChoiceModelOutput,
+ QuestionAnsweringModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...utils import (
+ auto_docstring,
+ logging,
+)
+from .configuration_squeezebert import SqueezeBertConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class SqueezeBertEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.embedding_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.embedding_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.embedding_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+
+ def forward(self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None):
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ position_embeddings = self.position_embeddings(position_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + position_embeddings + token_type_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class MatMulWrapper(nn.Module):
+ """
+ Wrapper for torch.matmul(). This makes flop-counting easier to implement. Note that if you directly call
+ torch.matmul() in your code, the flop counter will typically ignore the flops of the matmul.
+ """
+
+ def __init__(self):
+ super().__init__()
+
+ def forward(self, mat1, mat2):
+ """
+
+ :param inputs: two torch tensors :return: matmul of these tensors
+
+ Here are the typical dimensions found in BERT (the B is optional) mat1.shape: [B, , M, K]
+ mat2.shape: [B, , K, N] output shape: [B, , M, N]
+ """
+ return torch.matmul(mat1, mat2)
+
+
+class SqueezeBertLayerNorm(nn.LayerNorm):
+ """
+ This is a nn.LayerNorm subclass that accepts NCW data layout and performs normalization in the C dimension.
+
+ N = batch C = channels W = sequence length
+ """
+
+ def __init__(self, hidden_size, eps=1e-12):
+ nn.LayerNorm.__init__(self, normalized_shape=hidden_size, eps=eps) # instantiates self.{weight, bias, eps}
+
+ def forward(self, x):
+ x = x.permute(0, 2, 1)
+ x = nn.LayerNorm.forward(self, x)
+ return x.permute(0, 2, 1)
+
+
+class ConvDropoutLayerNorm(nn.Module):
+ """
+ ConvDropoutLayerNorm: Conv, Dropout, LayerNorm
+ """
+
+ def __init__(self, cin, cout, groups, dropout_prob):
+ super().__init__()
+
+ self.conv1d = nn.Conv1d(in_channels=cin, out_channels=cout, kernel_size=1, groups=groups)
+ self.layernorm = SqueezeBertLayerNorm(cout)
+ self.dropout = nn.Dropout(dropout_prob)
+
+ def forward(self, hidden_states, input_tensor):
+ x = self.conv1d(hidden_states)
+ x = self.dropout(x)
+ x = x + input_tensor
+ x = self.layernorm(x)
+ return x
+
+
+class ConvActivation(nn.Module):
+ """
+ ConvActivation: Conv, Activation
+ """
+
+ def __init__(self, cin, cout, groups, act):
+ super().__init__()
+ self.conv1d = nn.Conv1d(in_channels=cin, out_channels=cout, kernel_size=1, groups=groups)
+ self.act = ACT2FN[act]
+
+ def forward(self, x):
+ output = self.conv1d(x)
+ return self.act(output)
+
+
+class SqueezeBertSelfAttention(nn.Module):
+ def __init__(self, config, cin, q_groups=1, k_groups=1, v_groups=1):
+ """
+ config = used for some things; ignored for others (work in progress...) cin = input channels = output channels
+ groups = number of groups to use in conv1d layers
+ """
+ super().__init__()
+ if cin % config.num_attention_heads != 0:
+ raise ValueError(
+ f"cin ({cin}) is not a multiple of the number of attention heads ({config.num_attention_heads})"
+ )
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(cin / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Conv1d(in_channels=cin, out_channels=cin, kernel_size=1, groups=q_groups)
+ self.key = nn.Conv1d(in_channels=cin, out_channels=cin, kernel_size=1, groups=k_groups)
+ self.value = nn.Conv1d(in_channels=cin, out_channels=cin, kernel_size=1, groups=v_groups)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.softmax = nn.Softmax(dim=-1)
+
+ self.matmul_qk = MatMulWrapper()
+ self.matmul_qkv = MatMulWrapper()
+
+ def transpose_for_scores(self, x):
+ """
+ - input: [N, C, W]
+ - output: [N, C1, W, C2] where C1 is the head index, and C2 is one head's contents
+ """
+ new_x_shape = (x.size()[0], self.num_attention_heads, self.attention_head_size, x.size()[-1]) # [N, C1, C2, W]
+ x = x.view(*new_x_shape)
+ return x.permute(0, 1, 3, 2) # [N, C1, C2, W] --> [N, C1, W, C2]
+
+ def transpose_key_for_scores(self, x):
+ """
+ - input: [N, C, W]
+ - output: [N, C1, C2, W] where C1 is the head index, and C2 is one head's contents
+ """
+ new_x_shape = (x.size()[0], self.num_attention_heads, self.attention_head_size, x.size()[-1]) # [N, C1, C2, W]
+ x = x.view(*new_x_shape)
+ # no `permute` needed
+ return x
+
+ def transpose_output(self, x):
+ """
+ - input: [N, C1, W, C2]
+ - output: [N, C, W]
+ """
+ x = x.permute(0, 1, 3, 2).contiguous() # [N, C1, C2, W]
+ new_x_shape = (x.size()[0], self.all_head_size, x.size()[3]) # [N, C, W]
+ x = x.view(*new_x_shape)
+ return x
+
+ def forward(self, hidden_states, attention_mask, output_attentions):
+ """
+ expects hidden_states in [N, C, W] data layout.
+
+ The attention_mask data layout is [N, W], and it does not need to be transposed.
+ """
+ mixed_query_layer = self.query(hidden_states)
+ mixed_key_layer = self.key(hidden_states)
+ mixed_value_layer = self.value(hidden_states)
+
+ query_layer = self.transpose_for_scores(mixed_query_layer)
+ key_layer = self.transpose_key_for_scores(mixed_key_layer)
+ value_layer = self.transpose_for_scores(mixed_value_layer)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_score = self.matmul_qk(query_layer, key_layer)
+ attention_score = attention_score / math.sqrt(self.attention_head_size)
+ # Apply the attention mask is (precomputed for all layers in BertModel forward() function)
+ attention_score = attention_score + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = self.softmax(attention_score)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ context_layer = self.matmul_qkv(attention_probs, value_layer)
+ context_layer = self.transpose_output(context_layer)
+
+ result = {"context_layer": context_layer}
+ if output_attentions:
+ result["attention_score"] = attention_score
+ return result
+
+
+class SqueezeBertModule(nn.Module):
+ def __init__(self, config):
+ """
+ - hidden_size = input chans = output chans for Q, K, V (they are all the same ... for now) = output chans for
+ the module
+ - intermediate_size = output chans for intermediate layer
+ - groups = number of groups for all layers in the BertModule. (eventually we could change the interface to
+ allow different groups for different layers)
+ """
+ super().__init__()
+
+ c0 = config.hidden_size
+ c1 = config.hidden_size
+ c2 = config.intermediate_size
+ c3 = config.hidden_size
+
+ self.attention = SqueezeBertSelfAttention(
+ config=config, cin=c0, q_groups=config.q_groups, k_groups=config.k_groups, v_groups=config.v_groups
+ )
+ self.post_attention = ConvDropoutLayerNorm(
+ cin=c0, cout=c1, groups=config.post_attention_groups, dropout_prob=config.hidden_dropout_prob
+ )
+ self.intermediate = ConvActivation(cin=c1, cout=c2, groups=config.intermediate_groups, act=config.hidden_act)
+ self.output = ConvDropoutLayerNorm(
+ cin=c2, cout=c3, groups=config.output_groups, dropout_prob=config.hidden_dropout_prob
+ )
+
+ def forward(self, hidden_states, attention_mask, output_attentions):
+ att = self.attention(hidden_states, attention_mask, output_attentions)
+ attention_output = att["context_layer"]
+
+ post_attention_output = self.post_attention(attention_output, hidden_states)
+ intermediate_output = self.intermediate(post_attention_output)
+ layer_output = self.output(intermediate_output, post_attention_output)
+
+ output_dict = {"feature_map": layer_output}
+ if output_attentions:
+ output_dict["attention_score"] = att["attention_score"]
+
+ return output_dict
+
+
+class SqueezeBertEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+
+ assert config.embedding_size == config.hidden_size, (
+ "If you want embedding_size != intermediate hidden_size, "
+ "please insert a Conv1d layer to adjust the number of channels "
+ "before the first SqueezeBertModule."
+ )
+
+ self.layers = nn.ModuleList(SqueezeBertModule(config) for _ in range(config.num_hidden_layers))
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ if head_mask is None:
+ head_mask_is_all_none = True
+ elif head_mask.count(None) == len(head_mask):
+ head_mask_is_all_none = True
+ else:
+ head_mask_is_all_none = False
+ assert head_mask_is_all_none is True, "head_mask is not yet supported in the SqueezeBert implementation."
+
+ # [batch_size, sequence_length, hidden_size] --> [batch_size, hidden_size, sequence_length]
+ hidden_states = hidden_states.permute(0, 2, 1)
+
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ for layer in self.layers:
+ if output_hidden_states:
+ hidden_states = hidden_states.permute(0, 2, 1)
+ all_hidden_states += (hidden_states,)
+ hidden_states = hidden_states.permute(0, 2, 1)
+
+ layer_output = layer.forward(hidden_states, attention_mask, output_attentions)
+
+ hidden_states = layer_output["feature_map"]
+
+ if output_attentions:
+ all_attentions += (layer_output["attention_score"],)
+
+ # [batch_size, hidden_size, sequence_length] --> [batch_size, sequence_length, hidden_size]
+ hidden_states = hidden_states.permute(0, 2, 1)
+
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_attentions
+ )
+
+
+class SqueezeBertPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states):
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+class SqueezeBertPredictionHeadTransform(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ if isinstance(config.hidden_act, str):
+ self.transform_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.transform_act_fn = config.hidden_act
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.transform_act_fn(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states)
+ return hidden_states
+
+
+class SqueezeBertLMPredictionHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.transform = SqueezeBertPredictionHeadTransform(config)
+
+ # The output weights are the same as the input embeddings, but there is
+ # an output-only bias for each token.
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+
+ # Need a link between the two variables so that the bias is correctly resized with `resize_token_embeddings`
+ self.decoder.bias = self.bias
+
+ def _tie_weights(self) -> None:
+ self.decoder.bias = self.bias
+
+ def forward(self, hidden_states):
+ hidden_states = self.transform(hidden_states)
+ hidden_states = self.decoder(hidden_states)
+ return hidden_states
+
+
+class SqueezeBertOnlyMLMHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.predictions = SqueezeBertLMPredictionHead(config)
+
+ def forward(self, sequence_output):
+ prediction_scores = self.predictions(sequence_output)
+ return prediction_scores
+
+
+@auto_docstring
+class SqueezeBertPreTrainedModel(PreTrainedModel):
+ config: SqueezeBertConfig
+ base_model_prefix = "transformer"
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv1d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, SqueezeBertLMPredictionHead):
+ module.bias.data.zero_()
+
+
+@auto_docstring
+class SqueezeBertModel(SqueezeBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.embeddings = SqueezeBertEmbeddings(config)
+ self.encoder = SqueezeBertEncoder(config)
+ self.pooler = SqueezeBertPooler(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, new_embeddings):
+ self.embeddings.word_embeddings = new_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithPooling]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(input_shape, device=device)
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ extended_attention_mask = self.get_extended_attention_mask(attention_mask, input_shape)
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids, position_ids=position_ids, token_type_ids=token_type_ids, inputs_embeds=inputs_embeds
+ )
+ encoder_outputs = self.encoder(
+ hidden_states=embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output)
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring
+class SqueezeBertForMaskedLM(SqueezeBertPreTrainedModel):
+ _tied_weights_keys = ["cls.predictions.decoder.weight", "cls.predictions.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.transformer = SqueezeBertModel(config)
+ self.cls = SqueezeBertOnlyMLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.cls.predictions.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.cls.predictions.decoder = new_embeddings
+ self.cls.predictions.bias = new_embeddings.bias
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, MaskedLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ prediction_scores = self.cls(sequence_output)
+
+ masked_lm_loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss() # -100 index = padding token
+ masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return MaskedLMOutput(
+ loss=masked_lm_loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ SqueezeBERT Model transformer with a sequence classification/regression head on top (a linear layer on top of the
+ pooled output) e.g. for GLUE tasks.
+ """
+)
+class SqueezeBertForSequenceClassification(SqueezeBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.config = config
+
+ self.transformer = SqueezeBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, self.config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class SqueezeBertForMultipleChoice(SqueezeBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.transformer = SqueezeBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, MultipleChoiceModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ num_choices-1]` where *num_choices* is the size of the second dimension of the input tensors. (see
+ *input_ids* above)
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None
+ inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels)
+
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return MultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class SqueezeBertForTokenClassification(SqueezeBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.transformer = SqueezeBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ sequence_output = self.dropout(sequence_output)
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class SqueezeBertForQuestionAnswering(SqueezeBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.transformer = SqueezeBertModel(config)
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.Tensor] = None,
+ end_positions: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, QuestionAnsweringModelOutput]:
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[2:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return QuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "SqueezeBertForMaskedLM",
+ "SqueezeBertForMultipleChoice",
+ "SqueezeBertForQuestionAnswering",
+ "SqueezeBertForSequenceClassification",
+ "SqueezeBertForTokenClassification",
+ "SqueezeBertModel",
+ "SqueezeBertModule",
+ "SqueezeBertPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/tokenization_squeezebert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/tokenization_squeezebert.py
new file mode 100644
index 0000000000000000000000000000000000000000..4834f66816672aaa6784a4b3464ac7d090f88ead
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/tokenization_squeezebert.py
@@ -0,0 +1,482 @@
+# coding=utf-8
+# Copyright 2020 The SqueezeBert authors and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for SqueezeBERT."""
+
+import collections
+import os
+import unicodedata
+from typing import Optional
+
+from ...tokenization_utils import PreTrainedTokenizer, _is_control, _is_punctuation, _is_whitespace
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "vocab.txt"}
+
+
+# Copied from transformers.models.bert.tokenization_bert.load_vocab
+def load_vocab(vocab_file):
+ """Loads a vocabulary file into a dictionary."""
+ vocab = collections.OrderedDict()
+ with open(vocab_file, "r", encoding="utf-8") as reader:
+ tokens = reader.readlines()
+ for index, token in enumerate(tokens):
+ token = token.rstrip("\n")
+ vocab[token] = index
+ return vocab
+
+
+# Copied from transformers.models.bert.tokenization_bert.whitespace_tokenize
+def whitespace_tokenize(text):
+ """Runs basic whitespace cleaning and splitting on a piece of text."""
+ text = text.strip()
+ if not text:
+ return []
+ tokens = text.split()
+ return tokens
+
+
+# Copied from transformers.models.bert.tokenization_bert.BertTokenizer with Bert->SqueezeBert,BERT->SqueezeBERT
+class SqueezeBertTokenizer(PreTrainedTokenizer):
+ r"""
+ Construct a SqueezeBERT tokenizer. Based on WordPiece.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ do_basic_tokenize (`bool`, *optional*, defaults to `True`):
+ Whether or not to do basic tokenization before WordPiece.
+ never_split (`Iterable`, *optional*):
+ Collection of tokens which will never be split during tokenization. Only has an effect when
+ `do_basic_tokenize=True`
+ unk_token (`str`, *optional*, defaults to `"[UNK]"`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ sep_token (`str`, *optional*, defaults to `"[SEP]"`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `"[PAD]"`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `"[CLS]"`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `"[MASK]"`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters.
+
+ This should likely be deactivated for Japanese (see this
+ [issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original SqueezeBERT).
+ clean_up_tokenization_spaces (`bool`, *optional*, defaults to `True`):
+ Whether or not to cleanup spaces after decoding, cleanup consists in removing potential artifacts like
+ extra spaces.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+
+ def __init__(
+ self,
+ vocab_file,
+ do_lower_case=True,
+ do_basic_tokenize=True,
+ never_split=None,
+ unk_token="[UNK]",
+ sep_token="[SEP]",
+ pad_token="[PAD]",
+ cls_token="[CLS]",
+ mask_token="[MASK]",
+ tokenize_chinese_chars=True,
+ strip_accents=None,
+ clean_up_tokenization_spaces=True,
+ **kwargs,
+ ):
+ if not os.path.isfile(vocab_file):
+ raise ValueError(
+ f"Can't find a vocabulary file at path '{vocab_file}'. To load the vocabulary from a Google pretrained"
+ " model use `tokenizer = SqueezeBertTokenizer.from_pretrained(PRETRAINED_MODEL_NAME)`"
+ )
+ self.vocab = load_vocab(vocab_file)
+ self.ids_to_tokens = collections.OrderedDict([(ids, tok) for tok, ids in self.vocab.items()])
+ self.do_basic_tokenize = do_basic_tokenize
+ if do_basic_tokenize:
+ self.basic_tokenizer = BasicTokenizer(
+ do_lower_case=do_lower_case,
+ never_split=never_split,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ )
+
+ self.wordpiece_tokenizer = WordpieceTokenizer(vocab=self.vocab, unk_token=str(unk_token))
+
+ super().__init__(
+ do_lower_case=do_lower_case,
+ do_basic_tokenize=do_basic_tokenize,
+ never_split=never_split,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ **kwargs,
+ )
+
+ @property
+ def do_lower_case(self):
+ return self.basic_tokenizer.do_lower_case
+
+ @property
+ def vocab_size(self):
+ return len(self.vocab)
+
+ def get_vocab(self):
+ return dict(self.vocab, **self.added_tokens_encoder)
+
+ def _tokenize(self, text, split_special_tokens=False):
+ split_tokens = []
+ if self.do_basic_tokenize:
+ for token in self.basic_tokenizer.tokenize(
+ text, never_split=self.all_special_tokens if not split_special_tokens else None
+ ):
+ # If the token is part of the never_split set
+ if token in self.basic_tokenizer.never_split:
+ split_tokens.append(token)
+ else:
+ split_tokens += self.wordpiece_tokenizer.tokenize(token)
+ else:
+ split_tokens = self.wordpiece_tokenizer.tokenize(text)
+ return split_tokens
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.vocab.get(token, self.vocab.get(self.unk_token))
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ return self.ids_to_tokens.get(index, self.unk_token)
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ out_string = " ".join(tokens).replace(" ##", "").strip()
+ return out_string
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. A SqueezeBERT sequence has the following format:
+
+ - single sequence: `[CLS] X [SEP]`
+ - pair of sequences: `[CLS] A [SEP] B [SEP]`
+
+ Args:
+ token_ids_0 (`List[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`List[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `List[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ if token_ids_1 is None:
+ return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
+ cls = [self.cls_token_id]
+ sep = [self.sep_token_id]
+ return cls + token_ids_0 + sep + token_ids_1 + sep
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`List[int]`):
+ List of IDs.
+ token_ids_1 (`List[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `List[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ if token_ids_1 is not None:
+ return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
+ return [1] + ([0] * len(token_ids_0)) + [1]
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ index = 0
+ if os.path.isdir(save_directory):
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+ else:
+ vocab_file = (filename_prefix + "-" if filename_prefix else "") + save_directory
+ with open(vocab_file, "w", encoding="utf-8") as writer:
+ for token, token_index in sorted(self.vocab.items(), key=lambda kv: kv[1]):
+ if index != token_index:
+ logger.warning(
+ f"Saving vocabulary to {vocab_file}: vocabulary indices are not consecutive."
+ " Please check that the vocabulary is not corrupted!"
+ )
+ index = token_index
+ writer.write(token + "\n")
+ index += 1
+ return (vocab_file,)
+
+
+# Copied from transformers.models.bert.tokenization_bert.BasicTokenizer
+class BasicTokenizer:
+ """
+ Constructs a BasicTokenizer that will run basic tokenization (punctuation splitting, lower casing, etc.).
+
+ Args:
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ never_split (`Iterable`, *optional*):
+ Collection of tokens which will never be split during tokenization. Only has an effect when
+ `do_basic_tokenize=True`
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters.
+
+ This should likely be deactivated for Japanese (see this
+ [issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original BERT).
+ do_split_on_punc (`bool`, *optional*, defaults to `True`):
+ In some instances we want to skip the basic punctuation splitting so that later tokenization can capture
+ the full context of the words, such as contractions.
+ """
+
+ def __init__(
+ self,
+ do_lower_case=True,
+ never_split=None,
+ tokenize_chinese_chars=True,
+ strip_accents=None,
+ do_split_on_punc=True,
+ ):
+ if never_split is None:
+ never_split = []
+ self.do_lower_case = do_lower_case
+ self.never_split = set(never_split)
+ self.tokenize_chinese_chars = tokenize_chinese_chars
+ self.strip_accents = strip_accents
+ self.do_split_on_punc = do_split_on_punc
+
+ def tokenize(self, text, never_split=None):
+ """
+ Basic Tokenization of a piece of text. For sub-word tokenization, see WordPieceTokenizer.
+
+ Args:
+ never_split (`List[str]`, *optional*)
+ Kept for backward compatibility purposes. Now implemented directly at the base class level (see
+ [`PreTrainedTokenizer.tokenize`]) List of token not to split.
+ """
+ # union() returns a new set by concatenating the two sets.
+ never_split = self.never_split.union(set(never_split)) if never_split else self.never_split
+ text = self._clean_text(text)
+
+ # This was added on November 1st, 2018 for the multilingual and Chinese
+ # models. This is also applied to the English models now, but it doesn't
+ # matter since the English models were not trained on any Chinese data
+ # and generally don't have any Chinese data in them (there are Chinese
+ # characters in the vocabulary because Wikipedia does have some Chinese
+ # words in the English Wikipedia.).
+ if self.tokenize_chinese_chars:
+ text = self._tokenize_chinese_chars(text)
+ # prevents treating the same character with different unicode codepoints as different characters
+ unicode_normalized_text = unicodedata.normalize("NFC", text)
+ orig_tokens = whitespace_tokenize(unicode_normalized_text)
+ split_tokens = []
+ for token in orig_tokens:
+ if token not in never_split:
+ if self.do_lower_case:
+ token = token.lower()
+ if self.strip_accents is not False:
+ token = self._run_strip_accents(token)
+ elif self.strip_accents:
+ token = self._run_strip_accents(token)
+ split_tokens.extend(self._run_split_on_punc(token, never_split))
+
+ output_tokens = whitespace_tokenize(" ".join(split_tokens))
+ return output_tokens
+
+ def _run_strip_accents(self, text):
+ """Strips accents from a piece of text."""
+ text = unicodedata.normalize("NFD", text)
+ output = []
+ for char in text:
+ cat = unicodedata.category(char)
+ if cat == "Mn":
+ continue
+ output.append(char)
+ return "".join(output)
+
+ def _run_split_on_punc(self, text, never_split=None):
+ """Splits punctuation on a piece of text."""
+ if not self.do_split_on_punc or (never_split is not None and text in never_split):
+ return [text]
+ chars = list(text)
+ i = 0
+ start_new_word = True
+ output = []
+ while i < len(chars):
+ char = chars[i]
+ if _is_punctuation(char):
+ output.append([char])
+ start_new_word = True
+ else:
+ if start_new_word:
+ output.append([])
+ start_new_word = False
+ output[-1].append(char)
+ i += 1
+
+ return ["".join(x) for x in output]
+
+ def _tokenize_chinese_chars(self, text):
+ """Adds whitespace around any CJK character."""
+ output = []
+ for char in text:
+ cp = ord(char)
+ if self._is_chinese_char(cp):
+ output.append(" ")
+ output.append(char)
+ output.append(" ")
+ else:
+ output.append(char)
+ return "".join(output)
+
+ def _is_chinese_char(self, cp):
+ """Checks whether CP is the codepoint of a CJK character."""
+ # This defines a "chinese character" as anything in the CJK Unicode block:
+ # https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block)
+ #
+ # Note that the CJK Unicode block is NOT all Japanese and Korean characters,
+ # despite its name. The modern Korean Hangul alphabet is a different block,
+ # as is Japanese Hiragana and Katakana. Those alphabets are used to write
+ # space-separated words, so they are not treated specially and handled
+ # like the all of the other languages.
+ if (
+ (cp >= 0x4E00 and cp <= 0x9FFF)
+ or (cp >= 0x3400 and cp <= 0x4DBF)
+ or (cp >= 0x20000 and cp <= 0x2A6DF)
+ or (cp >= 0x2A700 and cp <= 0x2B73F)
+ or (cp >= 0x2B740 and cp <= 0x2B81F)
+ or (cp >= 0x2B820 and cp <= 0x2CEAF)
+ or (cp >= 0xF900 and cp <= 0xFAFF)
+ or (cp >= 0x2F800 and cp <= 0x2FA1F)
+ ):
+ return True
+
+ return False
+
+ def _clean_text(self, text):
+ """Performs invalid character removal and whitespace cleanup on text."""
+ output = []
+ for char in text:
+ cp = ord(char)
+ if cp == 0 or cp == 0xFFFD or _is_control(char):
+ continue
+ if _is_whitespace(char):
+ output.append(" ")
+ else:
+ output.append(char)
+ return "".join(output)
+
+
+class WordpieceTokenizer:
+ """Runs WordPiece tokenization."""
+
+ def __init__(self, vocab, unk_token, max_input_chars_per_word=100):
+ self.vocab = vocab
+ self.unk_token = unk_token
+ self.max_input_chars_per_word = max_input_chars_per_word
+
+ def tokenize(self, text):
+ """
+ Tokenizes a piece of text into its word pieces. This uses a greedy longest-match-first algorithm to perform
+ tokenization using the given vocabulary.
+
+ For example, `input = "unaffable"` will return as output `["un", "##aff", "##able"]`.
+
+ Args:
+ text: A single token or whitespace separated tokens. This should have
+ already been passed through *BasicTokenizer*.
+
+ Returns:
+ A list of wordpiece tokens.
+ """
+
+ output_tokens = []
+ for token in whitespace_tokenize(text):
+ chars = list(token)
+ if len(chars) > self.max_input_chars_per_word:
+ output_tokens.append(self.unk_token)
+ continue
+
+ is_bad = False
+ start = 0
+ sub_tokens = []
+ while start < len(chars):
+ end = len(chars)
+ cur_substr = None
+ while start < end:
+ substr = "".join(chars[start:end])
+ if start > 0:
+ substr = "##" + substr
+ if substr in self.vocab:
+ cur_substr = substr
+ break
+ end -= 1
+ if cur_substr is None:
+ is_bad = True
+ break
+ sub_tokens.append(cur_substr)
+ start = end
+
+ if is_bad:
+ output_tokens.append(self.unk_token)
+ else:
+ output_tokens.extend(sub_tokens)
+ return output_tokens
+
+
+__all__ = ["SqueezeBertTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/tokenization_squeezebert_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/tokenization_squeezebert_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..b6e460d43a6413a3971b22494af49ba8910730c6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/squeezebert/tokenization_squeezebert_fast.py
@@ -0,0 +1,147 @@
+# coding=utf-8
+# Copyright 2020 The SqueezeBert authors and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for SqueezeBERT."""
+
+import json
+from typing import Optional
+
+from tokenizers import normalizers
+
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import logging
+from .tokenization_squeezebert import SqueezeBertTokenizer
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "vocab.txt", "tokenizer_file": "tokenizer.json"}
+
+
+# Copied from transformers.models.bert.tokenization_bert_fast.BertTokenizerFast with Bert->SqueezeBert,BERT->SqueezeBERT
+class SqueezeBertTokenizerFast(PreTrainedTokenizerFast):
+ r"""
+ Construct a "fast" SqueezeBERT tokenizer (backed by HuggingFace's *tokenizers* library). Based on WordPiece.
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ unk_token (`str`, *optional*, defaults to `"[UNK]"`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ sep_token (`str`, *optional*, defaults to `"[SEP]"`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `"[PAD]"`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `"[CLS]"`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `"[MASK]"`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ clean_text (`bool`, *optional*, defaults to `True`):
+ Whether or not to clean the text before tokenization by removing any control characters and replacing all
+ whitespaces by the classic one.
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters. This should likely be deactivated for Japanese (see [this
+ issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original SqueezeBERT).
+ wordpieces_prefix (`str`, *optional*, defaults to `"##"`):
+ The prefix for subwords.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ slow_tokenizer_class = SqueezeBertTokenizer
+
+ def __init__(
+ self,
+ vocab_file=None,
+ tokenizer_file=None,
+ do_lower_case=True,
+ unk_token="[UNK]",
+ sep_token="[SEP]",
+ pad_token="[PAD]",
+ cls_token="[CLS]",
+ mask_token="[MASK]",
+ tokenize_chinese_chars=True,
+ strip_accents=None,
+ **kwargs,
+ ):
+ super().__init__(
+ vocab_file,
+ tokenizer_file=tokenizer_file,
+ do_lower_case=do_lower_case,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ **kwargs,
+ )
+
+ normalizer_state = json.loads(self.backend_tokenizer.normalizer.__getstate__())
+ if (
+ normalizer_state.get("lowercase", do_lower_case) != do_lower_case
+ or normalizer_state.get("strip_accents", strip_accents) != strip_accents
+ or normalizer_state.get("handle_chinese_chars", tokenize_chinese_chars) != tokenize_chinese_chars
+ ):
+ normalizer_class = getattr(normalizers, normalizer_state.pop("type"))
+ normalizer_state["lowercase"] = do_lower_case
+ normalizer_state["strip_accents"] = strip_accents
+ normalizer_state["handle_chinese_chars"] = tokenize_chinese_chars
+ self.backend_tokenizer.normalizer = normalizer_class(**normalizer_state)
+
+ self.do_lower_case = do_lower_case
+
+ def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. A SqueezeBERT sequence has the following format:
+
+ - single sequence: `[CLS] X [SEP]`
+ - pair of sequences: `[CLS] A [SEP] B [SEP]`
+
+ Args:
+ token_ids_0 (`List[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`List[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `List[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ output = [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
+
+ if token_ids_1 is not None:
+ output += token_ids_1 + [self.sep_token_id]
+
+ return output
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ files = self._tokenizer.model.save(save_directory, name=filename_prefix)
+ return tuple(files)
+
+
+__all__ = ["SqueezeBertTokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..004a82f49cd66857a6d10e614da2451046a1dcad
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_stablelm import *
+ from .modeling_stablelm import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/configuration_stablelm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/configuration_stablelm.py
new file mode 100644
index 0000000000000000000000000000000000000000..b919470c7f3d55c5f61b8f3ebea987e7a678fd53
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/configuration_stablelm.py
@@ -0,0 +1,202 @@
+# coding=utf-8
+# Copyright 2024 Stability AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""StableLM model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...modeling_rope_utils import rope_config_validation
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class StableLmConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`~StableLmModel`].
+ It is used to instantiate an StableLM model according to the specified arguments, defining the model
+ architecture. Instantiating a configuration with the defaults will yield a similar configuration to that of
+ the StableLM [stabilityai/stablelm-3b-4e1t](https://huggingface.co/stabilityai/stablelm-3b-4e1t) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used
+ to control the model outputs. Read the documentation from [`PretrainedConfig`]
+ for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 50304):
+ Vocabulary size of the StableLM model. Defines the number of different tokens that
+ can be represented by the `inputs_ids` passed when calling [`StableLmModel`].
+ intermediate_size (`int`, *optional*, defaults to 6912):
+ Dimension of the MLP representations.
+ hidden_size (`int`, *optional*, defaults to 2560):
+ Number of hidden layers in the Transformer decoder.
+ num_hidden_layers (`int`, *optional*, defaults to 32):
+ Number of hidden layers in the Transformer decoder.
+ num_attention_heads (`int`, *optional*, defaults to 32):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_key_value_heads (`int`, *optional*, defaults to 32):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details, check out [this
+ paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to
+ `num_attention_heads`.
+ hidden_act (`str` or `function`, *optional*, defaults to `"silu"`):
+ The non-linear activation function (function or string).
+ max_position_embeddings (`int`, *optional*, defaults to 4096):
+ The maximum sequence length that this model might ever be used with.
+ Typically set this to something large just in case (e.g., 512 or 1024 or 2048).
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing
+ all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions
+ (not used by all models). Only relevant if `config.is_decoder=True`.
+ tie_word_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether the model's input and output word embeddings should be tied.
+ rope_theta (`float`, *optional*, defaults to `10000.0`):
+ The base period of the RoPE embeddings.
+ rope_scaling (`Dict`, *optional*):
+ Dictionary containing the scaling configuration for the RoPE embeddings. NOTE: if you apply new rope type
+ and you expect the model to work on longer `max_position_embeddings`, we recommend you to update this value
+ accordingly.
+ Expected contents:
+ `rope_type` (`str`):
+ The sub-variant of RoPE to use. Can be one of ['default', 'linear', 'dynamic', 'yarn', 'longrope',
+ 'llama3'], with 'default' being the original RoPE implementation.
+ `factor` (`float`, *optional*):
+ Used with all rope types except 'default'. The scaling factor to apply to the RoPE embeddings. In
+ most scaling types, a `factor` of x will enable the model to handle sequences of length x *
+ original maximum pre-trained length.
+ `original_max_position_embeddings` (`int`, *optional*):
+ Used with 'dynamic', 'longrope' and 'llama3'. The original max position embeddings used during
+ pretraining.
+ `attention_factor` (`float`, *optional*):
+ Used with 'yarn' and 'longrope'. The scaling factor to be applied on the attention
+ computation. If unspecified, it defaults to value recommended by the implementation, using the
+ `factor` field to infer the suggested value.
+ `beta_fast` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for extrapolation (only) in the linear
+ ramp function. If unspecified, it defaults to 32.
+ `beta_slow` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for interpolation (only) in the linear
+ ramp function. If unspecified, it defaults to 1.
+ `short_factor` (`list[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to short contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `long_factor` (`list[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to long contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `low_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to low frequency components of the RoPE
+ `high_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to high frequency components of the RoPE
+ use_qkv_bias (`bool`, *optional*, defaults to `False`):
+ Whether or not the model should use bias for qkv layers.
+ qk_layernorm (`bool`, *optional*, defaults to `False`):
+ Whether or not to normalize, per head, the Queries and Keys after projecting the hidden states.
+ use_parallel_residual (`bool`, *optional*, defaults to `False`):
+ Whether to use a "parallel" formulation in each Transformer layer, which can provide a slight training
+ speedup at large scales.
+ hidden_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio after applying the MLP to the hidden states.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ partial_rotary_factor (`float`, *optional*, defaults to 0.25):
+ Percentage of the query and keys which will have rotary embedding.
+ bos_token_id (int, *optional*, defaults to 0):
+ The id of the `BOS` token in the vocabulary.
+ eos_token_id (int, *optional*, defaults to 0):
+ The id of the `EOS` token in the vocabulary.
+
+ Example:
+
+ ```python
+ >>> from transformers import StableLmModel, StableLmConfig
+
+ >>> # Initializing a StableLM stablelm-3b style configuration
+ >>> configuration = StableLmConfig()
+ ```"""
+
+ model_type = "stablelm"
+ keys_to_ignore_at_inference = ["past_key_values"]
+
+ def __init__(
+ self,
+ vocab_size=50304,
+ intermediate_size=6912,
+ hidden_size=2560,
+ num_hidden_layers=32,
+ num_attention_heads=32,
+ num_key_value_heads=32,
+ hidden_act="silu",
+ max_position_embeddings=4096,
+ initializer_range=0.02,
+ layer_norm_eps=1.0e-5,
+ use_cache=True,
+ tie_word_embeddings=False,
+ rope_theta=10_000,
+ rope_scaling=None,
+ use_qkv_bias=False,
+ qk_layernorm=False,
+ use_parallel_residual=False,
+ hidden_dropout=0.0,
+ attention_dropout=0.0,
+ partial_rotary_factor=0.25,
+ bos_token_id=0,
+ eos_token_id=0,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.num_key_value_heads = num_key_value_heads
+ self.hidden_act = hidden_act
+
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.rope_scaling = rope_scaling
+ self.use_qkv_bias = use_qkv_bias
+ self.qk_layernorm = qk_layernorm
+ self.use_parallel_residual = use_parallel_residual
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.partial_rotary_factor = partial_rotary_factor
+ # Validate the correctness of rotary position embeddings parameters
+ # BC: if there is a 'type' field, move it to 'rope_type'.
+ if self.rope_scaling is not None and "type" in self.rope_scaling:
+ self.rope_scaling["rope_type"] = self.rope_scaling["type"]
+ rope_config_validation(self)
+
+ super().__init__(
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ tie_word_embeddings=tie_word_embeddings,
+ **kwargs,
+ )
+
+
+__all__ = ["StableLmConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/modeling_stablelm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/modeling_stablelm.py
new file mode 100644
index 0000000000000000000000000000000000000000..69cf41bcfdd8e9f0990c48e58df4cf1f89d59157
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/stablelm/modeling_stablelm.py
@@ -0,0 +1,1001 @@
+# coding=utf-8
+# Copyright 2024 EleutherAI and the HuggingFace Inc. team. All rights reserved.
+#
+# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX
+# and OPT implementations in this library. It has been modified from its
+# original forms to accommodate minor architectural differences compared
+# to GPT-NeoX and OPT used by the Meta AI team that trained the model.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch StableLM model."""
+
+import math
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_flash_attention_utils import flash_attn_supports_top_left_mask, is_flash_attn_available
+from ...modeling_layers import (
+ GenericForSequenceClassification,
+ GenericForTokenClassification,
+ GradientCheckpointingLayer,
+)
+from ...modeling_outputs import (
+ BaseModelOutputWithPast,
+ CausalLMOutputWithPast,
+)
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, can_return_tuple, is_torch_flex_attn_available, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_stablelm import StableLmConfig
+
+
+if is_torch_flex_attn_available():
+ from torch.nn.attention.flex_attention import BlockMask
+
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+if is_flash_attn_available():
+ from ...modeling_flash_attention_utils import _flash_attention_forward
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.llama.modeling_llama.LlamaRotaryEmbedding with Llama->StableLm
+class StableLmRotaryEmbedding(nn.Module):
+ inv_freq: torch.Tensor # fix linting for `register_buffer`
+
+ def __init__(self, config: StableLmConfig, device=None):
+ super().__init__()
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and isinstance(config.rope_scaling, dict):
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ @torch.no_grad()
+ @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope)
+ def forward(self, x, position_ids):
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device)
+ position_ids_expanded = position_ids[:, None, :].float()
+
+ device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False): # Force float32
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos() * self.attention_scaling
+ sin = emb.sin() * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+# Copied from transformers.models.llama.modeling_llama.rotate_half
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+# Copied from transformers.models.llama.modeling_llama.apply_rotary_pos_emb
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+# Copied from transformers.models.mistral.modeling_mistral.MistralMLP with Mistral->StableLm
+class StableLmMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ def forward(self, x):
+ down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x))
+ return down_proj
+
+
+class StableLmLayerNormPerHead(nn.Module):
+ def __init__(self, dim, num_heads, eps=1e-5, bias=False):
+ super().__init__()
+ self.dim = dim
+ self.num_heads = num_heads
+ self.norms = nn.ModuleList([nn.LayerNorm(dim, eps=eps, bias=bias) for _ in range(self.num_heads)])
+
+ def forward(self, hidden_states: torch.Tensor):
+ # Split along the num_heads axis to get per-head inputs
+ # [batch_size, num_heads, seq_len, head_dim] -> [batch_size, 1, seq_len, head_dim] * num_heads
+ states_per_heads = torch.split(hidden_states, 1, dim=1)
+ # Normalize and merge the heads back together
+ return torch.cat([norm(hidden_states) for norm, hidden_states in zip(self.norms, states_per_heads)], dim=1)
+
+
+# Copied from transformers.models.llama.modeling_llama.repeat_kv
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+class StableLmAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: StableLmConfig, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ if layer_idx is None:
+ logger.warning_once(
+ f"Instantiating {self.__class__.__name__} without passing a `layer_idx` is not recommended and will "
+ "lead to errors during the forward call if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+
+ self.hidden_size = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.hidden_size // self.num_heads
+ self.num_key_value_heads = config.num_key_value_heads
+ self.num_key_value_groups = self.num_heads // self.num_key_value_heads
+ self.rope_theta = config.rope_theta
+ self.rotary_ndims = int(self.head_dim * config.partial_rotary_factor)
+ self.is_causal = True
+
+ if (self.head_dim * self.num_heads) != self.hidden_size:
+ raise ValueError(
+ f"hidden_size must be divisible by num_heads (got `hidden_size`: {self.hidden_size}"
+ f" and `num_heads`: {self.num_heads})."
+ )
+ self.q_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim, bias=config.use_qkv_bias)
+ self.k_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=config.use_qkv_bias)
+ self.v_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=config.use_qkv_bias)
+ self.o_proj = nn.Linear(self.hidden_size, self.hidden_size, bias=False)
+
+ self.qk_layernorm = config.qk_layernorm
+ if self.qk_layernorm:
+ self.q_layernorm = StableLmLayerNormPerHead(self.head_dim, self.num_heads, eps=config.layer_norm_eps)
+ self.k_layernorm = StableLmLayerNormPerHead(
+ self.head_dim, self.num_key_value_heads, eps=config.layer_norm_eps
+ )
+
+ self.attention_dropout = nn.Dropout(config.attention_dropout)
+ self.rotary_emb = StableLmRotaryEmbedding(config=self.config)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: bool = False,
+ use_cache: bool = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ bsz, q_len, _ = hidden_states.size()
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ query_states = query_states.view(bsz, q_len, self.num_heads, self.head_dim).transpose(1, 2)
+ key_states = key_states.view(bsz, q_len, self.num_key_value_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, q_len, self.num_key_value_heads, self.head_dim).transpose(1, 2)
+
+ if self.qk_layernorm:
+ query_states = self.q_layernorm(query_states)
+ key_states = self.k_layernorm(key_states)
+
+ cos, sin = position_embeddings
+
+ # Partial rotary embedding
+ query_rot, query_pass = (
+ query_states[..., : self.rotary_ndims],
+ query_states[..., self.rotary_ndims :],
+ )
+ key_rot, key_pass = (
+ key_states[..., : self.rotary_ndims],
+ key_states[..., self.rotary_ndims :],
+ )
+ # [batch_size, seq_length, num_heads, head_dim // config.partial_rotary_factor]
+ query_rot, key_rot = apply_rotary_pos_emb(query_rot, key_rot, cos, sin)
+
+ # [batch_size, seq_length, num_heads, head_dim]
+ query_states = torch.cat((query_rot, query_pass), dim=-1)
+ key_states = torch.cat((key_rot, key_pass), dim=-1)
+
+ if past_key_values is not None:
+ # Specific to RoPE models with partial rotation
+ cache_kwargs = {
+ "sin": sin,
+ "cos": cos,
+ "partial_rotation_size": self.rotary_ndims,
+ "cache_position": cache_position,
+ }
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ # Repeat k/v heads if n_kv_heads < n_heads
+ key_states = repeat_kv(key_states, self.num_key_value_groups)
+ value_states = repeat_kv(value_states, self.num_key_value_groups)
+
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim)
+
+ if attention_mask is not None: # no matter the length, we just slice it
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights += causal_mask
+
+ # upcast attention to fp32
+ attn_weights = nn.functional.softmax(attn_weights, dtype=torch.float32, dim=-1).to(query_states.dtype)
+ attn_weights = self.attention_dropout(attn_weights)
+
+ attn_output = torch.matmul(attn_weights, value_states)
+
+ if attn_output.size() != (bsz, self.num_heads, q_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, q_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ attn_output = attn_output.reshape(bsz, q_len, self.hidden_size)
+
+ attn_output = self.o_proj(attn_output)
+
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights
+
+
+class StableLmSdpaAttention(StableLmAttention):
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: bool = False,
+ use_cache: bool = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ if output_attentions:
+ # TODO: Improve this warning with e.g. `model.config.attn_implementation = "manual"` once this is implemented.
+ logger.warning_once(
+ "StableLmModel is using StableLmSdpaAttention, but `torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to the manual attention implementation, "
+ 'but specifying the manual implementation will be required from Transformers version v5.0.0 onwards. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ return super().forward(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ )
+
+ bsz, q_len, _ = hidden_states.size()
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ query_states = query_states.view(bsz, q_len, self.num_heads, self.head_dim).transpose(1, 2)
+ key_states = key_states.view(bsz, q_len, self.num_key_value_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, q_len, self.num_key_value_heads, self.head_dim).transpose(1, 2)
+
+ if self.qk_layernorm:
+ query_states = self.q_layernorm(query_states)
+ key_states = self.k_layernorm(key_states)
+
+ cos, sin = position_embeddings
+
+ # Partial rotary embedding
+ query_rot, query_pass = (
+ query_states[..., : self.rotary_ndims],
+ query_states[..., self.rotary_ndims :],
+ )
+ key_rot, key_pass = (
+ key_states[..., : self.rotary_ndims],
+ key_states[..., self.rotary_ndims :],
+ )
+ # [batch_size, seq_length, num_heads, head_dim // config.partial_rotary_factor]
+ query_rot, key_rot = apply_rotary_pos_emb(query_rot, key_rot, cos, sin)
+
+ # [batch_size, seq_length, num_heads, head_dim]
+ query_states = torch.cat((query_rot, query_pass), dim=-1)
+ key_states = torch.cat((key_rot, key_pass), dim=-1)
+
+ if past_key_values is not None:
+ # Specific to RoPE models with partial rotation
+ cache_kwargs = {
+ "sin": sin,
+ "cos": cos,
+ "partial_rotation_size": self.rotary_ndims,
+ "cache_position": cache_position,
+ }
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ # Repeat k/v heads if n_kv_heads < n_heads
+ key_states = repeat_kv(key_states, self.num_key_value_groups)
+ value_states = repeat_kv(value_states, self.num_key_value_groups)
+
+ causal_mask = attention_mask
+ if attention_mask is not None: # no matter the length, we just slice it
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+
+ # SDPA with memory-efficient backend is currently (torch==2.1.2) bugged with non-contiguous inputs with custom attn_mask,
+ # Reference: https://github.com/pytorch/pytorch/issues/112577.
+ if query_states.device.type == "cuda" and attention_mask is not None:
+ query_states = query_states.contiguous()
+ key_states = key_states.contiguous()
+ value_states = value_states.contiguous()
+
+ # We dispatch to SDPA's Flash Attention or Efficient kernels via this `is_causal` if statement instead of an inline conditional assignment
+ # in SDPA to support both torch.compile's dynamic shapes and full graph options. An inline conditional prevents dynamic shapes from compiling.
+ # The q_len > 1 is necessary to match with AttentionMaskConverter.to_causal_4d that does not create a causal mask in case q_len == 1.
+ is_causal = bool(causal_mask is None and q_len > 1)
+
+ attn_output = torch.nn.functional.scaled_dot_product_attention(
+ query_states,
+ key_states,
+ value_states,
+ attn_mask=causal_mask,
+ dropout_p=self.attention_dropout.p if self.training else 0.0,
+ is_causal=is_causal,
+ )
+
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ attn_output = attn_output.view(bsz, q_len, self.hidden_size)
+
+ attn_output = self.o_proj(attn_output)
+
+ return attn_output, None
+
+
+class StableLmFlashAttention2(StableLmAttention):
+ """
+ StableLM flash attention module. This module inherits from `StableLmAttention` as the weights of the module stays
+ untouched. The only required change would be on the forward pass where it needs to correctly call the public API of
+ flash attention and deal with padding tokens in case the input contains any of them.
+ """
+
+ def __init__(self, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+
+ # TODO: Should be removed once Flash Attention for RoCm is bumped to 2.1.
+ # flash_attn<2.1 generates top-left aligned causal mask, while what is needed here is bottom-right alignment, that was made default for flash_attn>=2.1. This attribute is used to handle this difference. Reference: https://github.com/Dao-AILab/flash-attention/releases/tag/v2.1.0.
+ # Beware that with flash_attn<2.1, using q_seqlen != k_seqlen (except for the case q_seqlen == 1) produces a wrong mask (top-left).
+ self._flash_attn_uses_top_left_mask = flash_attn_supports_top_left_mask()
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: bool = False,
+ use_cache: bool = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ **kwargs,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ # StableLmFlashAttention2 attention does not support output_attentions
+
+ output_attentions = False
+
+ bsz, q_len, _ = hidden_states.size()
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ # Flash attention requires the input to have the shape
+ # batch_size x seq_length x head_dim x hidden_dim
+ # therefore we just need to keep the original shape
+ query_states = query_states.view(bsz, q_len, self.num_heads, self.head_dim).transpose(1, 2)
+ key_states = key_states.view(bsz, q_len, self.num_key_value_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, q_len, self.num_key_value_heads, self.head_dim).transpose(1, 2)
+
+ if self.qk_layernorm:
+ query_states = self.q_layernorm(query_states)
+ key_states = self.k_layernorm(key_states)
+
+ cos, sin = position_embeddings
+
+ # Partial rotary embedding
+ query_rot, query_pass = (
+ query_states[..., : self.rotary_ndims],
+ query_states[..., self.rotary_ndims :],
+ )
+ key_rot, key_pass = (
+ key_states[..., : self.rotary_ndims],
+ key_states[..., self.rotary_ndims :],
+ )
+ query_rot, key_rot = apply_rotary_pos_emb(query_rot, key_rot, cos, sin)
+
+ # [batch_size, seq_length, num_heads, head_dim]
+ query_states = torch.cat((query_rot, query_pass), dim=-1)
+ key_states = torch.cat((key_rot, key_pass), dim=-1)
+
+ if past_key_values is not None:
+ cache_kwargs = {
+ "sin": sin,
+ "cos": cos,
+ "partial_rotation_size": self.rotary_ndims,
+ "cache_position": cache_position,
+ }
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ # TODO: These transpose are quite inefficient but Flash Attention requires the layout [batch_size, sequence_length, num_heads, head_dim]. We would need to refactor the KV cache
+ # to be able to avoid many of these transpose/reshape/view.
+ query_states = query_states.transpose(1, 2)
+ key_states = key_states.transpose(1, 2)
+ value_states = value_states.transpose(1, 2)
+
+ dropout_rate = self.attention_dropout.p if self.training else 0.0
+
+ attn_output = _flash_attention_forward(
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ q_len,
+ position_ids=position_ids,
+ dropout=dropout_rate,
+ use_top_left_mask=self._flash_attn_uses_top_left_mask,
+ is_causal=self.is_causal,
+ )
+
+ attn_output = attn_output.reshape(bsz, q_len, self.hidden_size).contiguous()
+ attn_output = self.o_proj(attn_output)
+
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights
+
+
+ATTENTION_CLASSES = {
+ "eager": StableLmAttention,
+ "sdpa": StableLmSdpaAttention,
+ "flash_attention_2": StableLmFlashAttention2,
+}
+
+
+class StableLmDecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: StableLmConfig, layer_idx: int):
+ super().__init__()
+ self.use_parallel_residual = config.use_parallel_residual
+ self.hidden_size = config.hidden_size
+ self.self_attn = ATTENTION_CLASSES[config._attn_implementation](config, layer_idx=layer_idx)
+ self.mlp = StableLmMLP(config)
+ self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.post_attention_layernorm = None
+ if not self.use_parallel_residual:
+ self.post_attention_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[tuple[torch.Tensor]] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ position_ids (`torch.LongTensor` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range
+ `[0, config.n_positions - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ past_key_values (`Tuple(torch.FloatTensor)`, *optional*):
+ cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence
+ position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*):
+ Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`,
+ with `head_dim` being the embedding dimension of each attention head.
+ """
+
+ residual = hidden_states
+
+ hidden_states = self.input_layernorm(hidden_states)
+
+ # Self Attention
+ self_attn_output, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ )
+
+ # copied from transformers.models.gpt_neox.modeling_gpt_neox.GPTNeoXLayer.forward
+ if self.use_parallel_residual:
+ # x = x + attn(ln1(x)) + mlp(ln1(x))
+ # Fully Connected
+ mlp_output = self.mlp(hidden_states)
+ mlp_output = self.dropout(mlp_output)
+ hidden_states = residual + self_attn_output + mlp_output
+ else:
+ # x = x + attn(ln1(x))
+ # x = x + mlp(ln2(x))
+ residual = residual + self_attn_output
+ # Fully Connected
+ mlp_output = self.mlp(self.post_attention_layernorm(residual))
+ mlp_output = self.dropout(mlp_output)
+ hidden_states = residual + mlp_output
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+@auto_docstring
+class StableLmPreTrainedModel(PreTrainedModel):
+ config: StableLmConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["StableLmDecoderLayer"]
+ _skip_keys_device_placement = "past_key_values"
+ _supports_flash_attn = True
+ _supports_sdpa = True
+
+ _can_compile_fullgraph = True
+
+ def _init_weights(self, module):
+ std = self.config.initializer_range
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.weight.data.fill_(1.0)
+ module.bias.data.zero_()
+
+
+@auto_docstring
+class StableLmModel(StableLmPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.num_hidden_layers* layers. Each layer is a [`StableLmDecoderLayer`]
+
+ Args:
+ config: StableLmConfig
+ """
+
+ def __init__(self, config: StableLmConfig):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.layers = nn.ModuleList(
+ [StableLmDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.rotary_emb = StableLmRotaryEmbedding(config=config)
+
+ self._attn_implementation = config._attn_implementation
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> BaseModelOutputWithPast:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ # TODO (joao): remove this exception in v4.56 -- it exists for users that try to pass a legacy cache
+ if not isinstance(past_key_values, (type(None), Cache)):
+ raise ValueError("The `past_key_values` should be either a `Cache` object or `None`.")
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache(config=self.config)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ causal_mask = self._update_causal_mask(
+ attention_mask, inputs_embeds, cache_position, past_key_values, output_attentions
+ )
+
+ hidden_states = inputs_embeds
+
+ # create position embeddings to be shared across the decoder layers
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+
+ for decoder_layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ hidden_states = self.norm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ return BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ )
+
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._update_causal_mask
+ def _update_causal_mask(
+ self,
+ attention_mask: Union[torch.Tensor, "BlockMask"],
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool = False,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+ if self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask)
+ return attention_mask
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_compilable_cache = past_key_values.is_compileable if past_key_values is not None else False
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_compilable_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype = input_tensor.dtype
+ sequence_length = input_tensor.shape[1]
+ if using_compilable_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type in ["cuda", "xpu", "npu"]
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._prepare_4d_causal_attention_mask_with_cache_position
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=cache_position.device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=cache_position.device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :].to(
+ causal_mask.device
+ )
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
+
+
+# Copied from transformers.models.persimmon.modeling_persimmon.PersimmonForCausalLM with PERSIMMON->STABLELM,Persimmon->StableLm
+class StableLmForCausalLM(StableLmPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.weight"]
+
+ # Copied from transformers.models.llama.modeling_llama.LlamaForCausalLM.__init__ with LLAMA->STABLELM,Llama->StableLm
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = StableLmModel(config)
+ self.vocab_size = config.vocab_size
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ # Ignore copy
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs,
+ ) -> CausalLMOutputWithPast:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, StableLmForCausalLM
+
+ >>> model = StableLmForCausalLM.from_pretrained("adept/persimmon-8b-base")
+ >>> tokenizer = AutoTokenizer.from_pretrained("adept/persimmon-8b-base")
+
+ >>> prompt = "human: Hey, what should I eat for dinner?"
+ >>> inputs = tokenizer(prompt, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(inputs.input_ids, max_length=30)
+ >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+ 'human: Hey, what should I eat for dinner?\n\ncat: 🐱\n\nhuman: 😐\n\n'
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
+ outputs: BaseModelOutputWithPast = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ cache_position=cache_position,
+ )
+
+ hidden_states = outputs.last_hidden_state
+ # No upscaling to float was ever done for StableLm
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(
+ logits,
+ labels,
+ vocab_size=self.config.vocab_size,
+ **kwargs,
+ )
+
+ return CausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class StableLmForSequenceClassification(GenericForSequenceClassification, StableLmPreTrainedModel): ...
+
+
+class StableLmForTokenClassification(GenericForTokenClassification, StableLmPreTrainedModel): ...
+
+
+__all__ = [
+ "StableLmForCausalLM",
+ "StableLmModel",
+ "StableLmPreTrainedModel",
+ "StableLmForSequenceClassification",
+ "StableLmForTokenClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..6349255ed3a4756aa7d449ff6af35847886dd136
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_starcoder2 import *
+ from .modeling_starcoder2 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/configuration_starcoder2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/configuration_starcoder2.py
new file mode 100644
index 0000000000000000000000000000000000000000..795fcb4696b8066f94d613fc8ccf77677408cea1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/configuration_starcoder2.py
@@ -0,0 +1,207 @@
+# coding=utf-8
+# Copyright 2024 BigCode and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Starcoder2 model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...modeling_rope_utils import rope_config_validation
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Starcoder2Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Starcoder2Model`]. It is used to instantiate a
+ Starcoder2 model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the [bigcode/starcoder2-7b](https://huggingface.co/bigcode/starcoder2-7b) model.
+
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 49152):
+ Vocabulary size of the Starcoder2 model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`Starcoder2Model`]
+ hidden_size (`int`, *optional*, defaults to 3072):
+ Dimension of the hidden representations.
+ intermediate_size (`int`, *optional*, defaults to 12288):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 30):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 24):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_key_value_heads (`int`, *optional*, defaults to 2):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details, check out [this
+ paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `8`.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The non-linear activation function (function or string) in the decoder.
+ max_position_embeddings (`int`, *optional*, defaults to 4096):
+ The maximum sequence length that this model might ever be used with. Starcoder2's sliding window attention
+ allows sequence of up to 4096*32 tokens.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ norm_epsilon (`float`, *optional*, defaults to 1e-05):
+ Epsilon value for the layer norm
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ bos_token_id (`int`, *optional*, defaults to 50256):
+ The id of the "beginning-of-sequence" token.
+ eos_token_id (`int`, *optional*, defaults to 50256):
+ The id of the "end-of-sequence" token.
+ rope_theta (`float`, *optional*, defaults to 10000.0):
+ The base period of the RoPE embeddings.
+ rope_scaling (`Dict`, *optional*):
+ Dictionary containing the scaling configuration for the RoPE embeddings. NOTE: if you apply new rope type
+ and you expect the model to work on longer `max_position_embeddings`, we recommend you to update this value
+ accordingly.
+ Expected contents:
+ `rope_type` (`str`):
+ The sub-variant of RoPE to use. Can be one of ['default', 'linear', 'dynamic', 'yarn', 'longrope',
+ 'llama3'], with 'default' being the original RoPE implementation.
+ `factor` (`float`, *optional*):
+ Used with all rope types except 'default'. The scaling factor to apply to the RoPE embeddings. In
+ most scaling types, a `factor` of x will enable the model to handle sequences of length x *
+ original maximum pre-trained length.
+ `original_max_position_embeddings` (`int`, *optional*):
+ Used with 'dynamic', 'longrope' and 'llama3'. The original max position embeddings used during
+ pretraining.
+ `attention_factor` (`float`, *optional*):
+ Used with 'yarn' and 'longrope'. The scaling factor to be applied on the attention
+ computation. If unspecified, it defaults to value recommended by the implementation, using the
+ `factor` field to infer the suggested value.
+ `beta_fast` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for extrapolation (only) in the linear
+ ramp function. If unspecified, it defaults to 32.
+ `beta_slow` (`float`, *optional*):
+ Only used with 'yarn'. Parameter to set the boundary for interpolation (only) in the linear
+ ramp function. If unspecified, it defaults to 1.
+ `short_factor` (`list[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to short contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `long_factor` (`list[float]`, *optional*):
+ Only used with 'longrope'. The scaling factor to be applied to long contexts (<
+ `original_max_position_embeddings`). Must be a list of numbers with the same length as the hidden
+ size divided by the number of attention heads divided by 2
+ `low_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to low frequency components of the RoPE
+ `high_freq_factor` (`float`, *optional*):
+ Only used with 'llama3'. Scaling factor applied to high frequency components of the RoPE
+ sliding_window (`int`, *optional*):
+ Sliding window attention window size. If not specified, will default to `None` (no sliding window).
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ residual_dropout (`float`, *optional*, defaults to 0.0):
+ Residual connection dropout value.
+ embedding_dropout (`float`, *optional*, defaults to 0.0):
+ Embedding dropout.
+ use_bias (`bool`, *optional*, defaults to `True`):
+ Whether to use bias term on linear layers of the model.
+
+
+ ```python
+ >>> from transformers import Starcoder2Model, Starcoder2Config
+
+ >>> # Initializing a Starcoder2 7B style configuration
+ >>> configuration = Starcoder2Config()
+
+ >>> # Initializing a model from the Starcoder2 7B style configuration
+ >>> model = Starcoder2Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "starcoder2"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ # Default tensor parallel plan for base model `Starcoder2`
+ base_model_tp_plan = {
+ "layers.*.self_attn.q_proj": "colwise",
+ "layers.*.self_attn.k_proj": "colwise",
+ "layers.*.self_attn.v_proj": "colwise",
+ "layers.*.self_attn.o_proj": "rowwise",
+ "layers.*.mlp.c_fc": "colwise",
+ "layers.*.mlp.c_proj": "colwise",
+ }
+ base_model_pp_plan = {
+ "embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "norm": (["hidden_states"], ["hidden_states"]),
+ }
+
+ def __init__(
+ self,
+ vocab_size=49152,
+ hidden_size=3072,
+ intermediate_size=12288,
+ num_hidden_layers=30,
+ num_attention_heads=24,
+ num_key_value_heads=2,
+ hidden_act="gelu_pytorch_tanh",
+ max_position_embeddings=4096,
+ initializer_range=0.018042,
+ norm_epsilon=1e-5,
+ use_cache=True,
+ bos_token_id=50256,
+ eos_token_id=50256,
+ rope_theta=10000.0,
+ rope_scaling=None,
+ sliding_window=None,
+ attention_dropout=0.0,
+ residual_dropout=0.0,
+ embedding_dropout=0.0,
+ use_bias=True,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.sliding_window = sliding_window
+ self.use_bias = use_bias
+ self.num_key_value_heads = num_key_value_heads
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.norm_epsilon = norm_epsilon
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.rope_scaling = rope_scaling
+ self.attention_dropout = attention_dropout
+ self.residual_dropout = residual_dropout
+ self.embedding_dropout = embedding_dropout
+ # Validate the correctness of rotary position embeddings parameters
+ # BC: if there is a 'type' field, move it to 'rope_type'.
+ if self.rope_scaling is not None and "type" in self.rope_scaling:
+ self.rope_scaling["rope_type"] = self.rope_scaling["type"]
+ rope_config_validation(self)
+
+ super().__init__(
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ **kwargs,
+ )
+
+
+__all__ = ["Starcoder2Config"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/modeling_starcoder2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/modeling_starcoder2.py
new file mode 100644
index 0000000000000000000000000000000000000000..dfdfec22ca99cf1f205dcaa103ca448afe8498dd
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/modeling_starcoder2.py
@@ -0,0 +1,485 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/starcoder2/modular_starcoder2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_starcoder2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2024 BigCode and the HuggingFace Inc. team. All rights reserved.
+#
+# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX
+# and OPT implementations in this library. It has been modified from its
+# original forms to accommodate minor architectural differences compared
+# to GPT-NeoX and OPT used by the Meta AI team that trained the model.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Callable, Optional, Union
+
+import torch
+from torch import nn
+
+from transformers.utils.generic import check_model_inputs
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache
+from ...generation import GenerationMixin
+from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import (
+ GenericForSequenceClassification,
+ GenericForTokenClassification,
+ GradientCheckpointingLayer,
+)
+from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, auto_docstring, can_return_tuple
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_starcoder2 import Starcoder2Config
+
+
+class Starcoder2MLP(nn.Module):
+ def __init__(self, config: Starcoder2Config):
+ super().__init__()
+ embed_dim = config.hidden_size
+ self.c_fc = nn.Linear(embed_dim, config.intermediate_size, bias=config.use_bias)
+ self.c_proj = nn.Linear(config.intermediate_size, embed_dim, bias=config.use_bias)
+ self.act = ACT2FN[config.hidden_act]
+ self.residual_dropout = config.residual_dropout
+
+ def forward(self, hidden_states: Optional[tuple[torch.FloatTensor]]) -> torch.FloatTensor:
+ hidden_states = self.c_fc(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.c_proj(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.residual_dropout, training=self.training)
+ return hidden_states
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs: Unpack[TransformersKwargs],
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class Starcoder2Attention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: Starcoder2Config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = self.head_dim**-0.5
+ self.attention_dropout = config.attention_dropout
+ self.is_causal = True
+ self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.use_bias)
+ self.k_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.use_bias)
+ self.v_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.use_bias)
+ self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.use_bias)
+ self.residual_dropout = config.residual_dropout
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ sliding_window=getattr(self.config, "sliding_window", None), # diff with Llama
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ attn_output = nn.functional.dropout(
+ attn_output, p=self.residual_dropout, training=self.training
+ ) # diff with Llama
+
+ return attn_output, attn_weights
+
+
+class Starcoder2DecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: Starcoder2Config, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+ self.self_attn = Starcoder2Attention(config=config, layer_idx=layer_idx)
+ self.mlp = Starcoder2MLP(config)
+ self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.norm_epsilon)
+ self.post_attention_layernorm = nn.LayerNorm(config.hidden_size, eps=config.norm_epsilon)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None, # necessary, but kept here for BC
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> torch.Tensor:
+ residual = hidden_states
+ hidden_states = self.input_layernorm(hidden_states)
+ # Self Attention
+ hidden_states, _ = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.post_attention_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+ return hidden_states
+
+
+class Starcoder2RotaryEmbedding(nn.Module):
+ inv_freq: torch.Tensor # fix linting for `register_buffer`
+
+ def __init__(self, config: Starcoder2Config, device=None):
+ super().__init__()
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and isinstance(config.rope_scaling, dict):
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ @torch.no_grad()
+ @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope)
+ def forward(self, x, position_ids):
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device)
+ position_ids_expanded = position_ids[:, None, :].float()
+
+ device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False): # Force float32
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos() * self.attention_scaling
+ sin = emb.sin() * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+@auto_docstring
+class Starcoder2PreTrainedModel(PreTrainedModel):
+ config: Starcoder2Config
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["Starcoder2DecoderLayer"]
+ _skip_keys_device_placement = ["past_key_values"]
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ _can_compile_fullgraph = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": Starcoder2DecoderLayer,
+ "attentions": Starcoder2Attention,
+ }
+
+
+@auto_docstring
+class Starcoder2Model(Starcoder2PreTrainedModel):
+ def __init__(self, config: Starcoder2Config):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.layers = nn.ModuleList(
+ [Starcoder2DecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = nn.LayerNorm(config.hidden_size, eps=config.norm_epsilon)
+ self.rotary_emb = Starcoder2RotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+ self.embedding_dropout = config.embedding_dropout
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, list[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPast:
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache(config=self.config)
+
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ mask_function = create_causal_mask if self.config.sliding_window is None else create_sliding_window_causal_mask
+ causal_mask = mask_function(
+ config=self.config,
+ input_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ cache_position=cache_position,
+ past_key_values=past_key_values,
+ position_ids=position_ids,
+ )
+
+ hidden_states = inputs_embeds
+ hidden_states = nn.functional.dropout(
+ hidden_states, p=self.embedding_dropout, training=self.training
+ ) # main diff with Llama
+
+ # create position embeddings to be shared across the decoder layers
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+ for decoder_layer in self.layers[: self.config.num_hidden_layers]:
+ hidden_states = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+
+ hidden_states = self.norm(hidden_states)
+
+ return BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ )
+
+
+@auto_docstring
+class Starcoder2ForCausalLM(Starcoder2PreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.weight"]
+ _tp_plan = {"lm_head": "colwise_rep"}
+ _pp_plan = {"lm_head": (["hidden_states"], ["logits"])}
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = Starcoder2Model(config)
+ self.vocab_size = config.vocab_size
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> CausalLMOutputWithPast:
+ r"""
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, Starcoder2ForCausalLM
+
+ >>> model = Starcoder2ForCausalLM.from_pretrained("meta-starcoder2/Starcoder2-2-7b-hf")
+ >>> tokenizer = AutoTokenizer.from_pretrained("meta-starcoder2/Starcoder2-2-7b-hf")
+
+ >>> prompt = "Hey, are you conscious? Can you talk to me?"
+ >>> inputs = tokenizer(prompt, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(inputs.input_ids, max_length=30)
+ >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+ "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you."
+ ```"""
+ outputs: BaseModelOutputWithPast = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ hidden_states = outputs.last_hidden_state
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs)
+
+ return CausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class Starcoder2ForSequenceClassification(GenericForSequenceClassification, Starcoder2PreTrainedModel):
+ pass
+
+
+class Starcoder2ForTokenClassification(GenericForTokenClassification, Starcoder2PreTrainedModel):
+ pass
+
+
+__all__ = [
+ "Starcoder2ForCausalLM",
+ "Starcoder2Model",
+ "Starcoder2PreTrainedModel",
+ "Starcoder2ForSequenceClassification",
+ "Starcoder2ForTokenClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/modular_starcoder2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/modular_starcoder2.py
new file mode 100644
index 0000000000000000000000000000000000000000..a1baf7de87670f914441ec50941c9f799b238eb6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/starcoder2/modular_starcoder2.py
@@ -0,0 +1,239 @@
+# coding=utf-8
+# Copyright 2024 BigCode and the HuggingFace Inc. team. All rights reserved.
+#
+# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX
+# and OPT implementations in this library. It has been modified from its
+# original forms to accommodate minor architectural differences compared
+# to GPT-NeoX and OPT used by the Meta AI team that trained the model.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Starcoder2 model."""
+
+from typing import Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from transformers.utils.generic import check_model_inputs
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache
+from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, logging
+from ...utils.deprecation import deprecate_kwarg
+from ..mistral.modeling_mistral import (
+ MistralAttention,
+ MistralDecoderLayer,
+ MistralForCausalLM,
+ MistralForSequenceClassification,
+ MistralForTokenClassification,
+ MistralModel,
+ MistralRotaryEmbedding,
+ apply_rotary_pos_emb,
+ eager_attention_forward,
+)
+from .configuration_starcoder2 import Starcoder2Config
+
+
+logger = logging.get_logger(__name__)
+
+
+class Starcoder2MLP(nn.Module):
+ def __init__(self, config: Starcoder2Config):
+ super().__init__()
+ embed_dim = config.hidden_size
+ self.c_fc = nn.Linear(embed_dim, config.intermediate_size, bias=config.use_bias)
+ self.c_proj = nn.Linear(config.intermediate_size, embed_dim, bias=config.use_bias)
+ self.act = ACT2FN[config.hidden_act]
+ self.residual_dropout = config.residual_dropout
+
+ def forward(self, hidden_states: Optional[tuple[torch.FloatTensor]]) -> torch.FloatTensor:
+ hidden_states = self.c_fc(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.c_proj(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.residual_dropout, training=self.training)
+ return hidden_states
+
+
+class Starcoder2Attention(MistralAttention):
+ def __init__(self, config: Starcoder2Config, layer_idx: Optional[int] = None):
+ super().__init__(config=config, layer_idx=layer_idx)
+ self.residual_dropout = config.residual_dropout
+ self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.use_bias)
+ self.k_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.use_bias)
+ self.v_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.use_bias)
+ self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.use_bias)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ sliding_window=getattr(self.config, "sliding_window", None), # diff with Llama
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ attn_output = nn.functional.dropout(
+ attn_output, p=self.residual_dropout, training=self.training
+ ) # diff with Llama
+
+ return attn_output, attn_weights
+
+
+class Starcoder2DecoderLayer(MistralDecoderLayer):
+ def __init__(self, config: Starcoder2Config, layer_idx: int):
+ super().__init__(config, layer_idx)
+ self.self_attn = Starcoder2Attention(config=config, layer_idx=layer_idx)
+ self.mlp = Starcoder2MLP(config)
+ self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.norm_epsilon)
+ self.post_attention_layernorm = nn.LayerNorm(config.hidden_size, eps=config.norm_epsilon)
+
+
+class Starcoder2RotaryEmbedding(MistralRotaryEmbedding):
+ pass
+
+
+class Starcoder2Model(MistralModel):
+ def __init__(self, config: Starcoder2Config):
+ super().__init__(config)
+ self.layers = nn.ModuleList(
+ [Starcoder2DecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.norm = nn.LayerNorm(config.hidden_size, eps=config.norm_epsilon)
+ self.embedding_dropout = config.embedding_dropout
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, list[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPast:
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if use_cache and past_key_values is None:
+ past_key_values = DynamicCache(config=self.config)
+
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ mask_function = create_causal_mask if self.config.sliding_window is None else create_sliding_window_causal_mask
+ causal_mask = mask_function(
+ config=self.config,
+ input_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ cache_position=cache_position,
+ past_key_values=past_key_values,
+ position_ids=position_ids,
+ )
+
+ hidden_states = inputs_embeds
+ hidden_states = nn.functional.dropout(
+ hidden_states, p=self.embedding_dropout, training=self.training
+ ) # main diff with Llama
+
+ # create position embeddings to be shared across the decoder layers
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+ for decoder_layer in self.layers[: self.config.num_hidden_layers]:
+ hidden_states = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+
+ hidden_states = self.norm(hidden_states)
+
+ return BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ )
+
+
+class Starcoder2ForCausalLM(MistralForCausalLM):
+ pass
+
+
+class Starcoder2ForSequenceClassification(MistralForSequenceClassification):
+ pass
+
+
+class Starcoder2ForTokenClassification(MistralForTokenClassification):
+ pass
+
+
+__all__ = [
+ "Starcoder2ForCausalLM",
+ "Starcoder2Model",
+ "Starcoder2PreTrainedModel", # noqa: F822
+ "Starcoder2ForSequenceClassification",
+ "Starcoder2ForTokenClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..666f44026eff6e9c5d908370f7d13f1adfd1d1cf
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_superglue import *
+ from .image_processing_superglue import *
+ from .modeling_superglue import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/configuration_superglue.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/configuration_superglue.py
new file mode 100644
index 0000000000000000000000000000000000000000..74bd991f95e70867d505e39d1826209fc8b3bf34
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/configuration_superglue.py
@@ -0,0 +1,122 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING, Optional
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ..auto import CONFIG_MAPPING
+
+
+if TYPE_CHECKING:
+ from ..superpoint import SuperPointConfig
+
+logger = logging.get_logger(__name__)
+
+
+class SuperGlueConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SuperGlueModel`]. It is used to instantiate a
+ SuperGlue model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the SuperGlue
+ [magic-leap-community/superglue_indoor](https://huggingface.co/magic-leap-community/superglue_indoor) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ keypoint_detector_config (`Union[AutoConfig, dict]`, *optional*, defaults to `SuperPointConfig`):
+ The config object or dictionary of the keypoint detector.
+ hidden_size (`int`, *optional*, defaults to 256):
+ The dimension of the descriptors.
+ keypoint_encoder_sizes (`list[int]`, *optional*, defaults to `[32, 64, 128, 256]`):
+ The sizes of the keypoint encoder layers.
+ gnn_layers_types (`list[str]`, *optional*, defaults to `['self', 'cross', 'self', 'cross', 'self', 'cross', 'self', 'cross', 'self', 'cross', 'self', 'cross', 'self', 'cross', 'self', 'cross', 'self', 'cross']`):
+ The types of the GNN layers. Must be either 'self' or 'cross'.
+ num_attention_heads (`int`, *optional*, defaults to 4):
+ The number of heads in the GNN layers.
+ sinkhorn_iterations (`int`, *optional*, defaults to 100):
+ The number of Sinkhorn iterations.
+ matching_threshold (`float`, *optional*, defaults to 0.0):
+ The matching threshold.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+
+ Examples:
+ ```python
+ >>> from transformers import SuperGlueConfig, SuperGlueModel
+
+ >>> # Initializing a SuperGlue superglue style configuration
+ >>> configuration = SuperGlueConfig()
+
+ >>> # Initializing a model from the superglue style configuration
+ >>> model = SuperGlueModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```
+ """
+
+ model_type = "superglue"
+
+ def __init__(
+ self,
+ keypoint_detector_config: "SuperPointConfig" = None,
+ hidden_size: int = 256,
+ keypoint_encoder_sizes: Optional[list[int]] = None,
+ gnn_layers_types: Optional[list[str]] = None,
+ num_attention_heads: int = 4,
+ sinkhorn_iterations: int = 100,
+ matching_threshold: float = 0.0,
+ initializer_range: float = 0.02,
+ **kwargs,
+ ):
+ self.gnn_layers_types = gnn_layers_types if gnn_layers_types is not None else ["self", "cross"] * 9
+ # Check whether all gnn_layers_types are either 'self' or 'cross'
+ if not all(layer_type in ["self", "cross"] for layer_type in self.gnn_layers_types):
+ raise ValueError("All gnn_layers_types must be either 'self' or 'cross'")
+
+ if hidden_size % num_attention_heads != 0:
+ raise ValueError("hidden_size % num_attention_heads is different from zero")
+
+ self.keypoint_encoder_sizes = (
+ keypoint_encoder_sizes if keypoint_encoder_sizes is not None else [32, 64, 128, 256]
+ )
+ self.hidden_size = hidden_size
+ self.keypoint_encoder_sizes = keypoint_encoder_sizes
+ self.gnn_layers_types = gnn_layers_types
+ self.num_attention_heads = num_attention_heads
+ self.sinkhorn_iterations = sinkhorn_iterations
+ self.matching_threshold = matching_threshold
+
+ if isinstance(keypoint_detector_config, dict):
+ keypoint_detector_config["model_type"] = keypoint_detector_config.get("model_type", "superpoint")
+ keypoint_detector_config = CONFIG_MAPPING[keypoint_detector_config["model_type"]](
+ **keypoint_detector_config
+ )
+ if keypoint_detector_config is None:
+ keypoint_detector_config = CONFIG_MAPPING["superpoint"]()
+
+ self.keypoint_detector_config = keypoint_detector_config
+ self.initializer_range = initializer_range
+ self.attention_probs_dropout_prob = 0
+ self.is_decoder = False
+
+ super().__init__(**kwargs)
+
+ @property
+ def sub_configs(self):
+ return {"keypoint_detector_config": type(self.keypoint_detector_config)}
+
+
+__all__ = ["SuperGlueConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/image_processing_superglue.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/image_processing_superglue.py
new file mode 100644
index 0000000000000000000000000000000000000000..f02e2a9f65c04402f2046e4514aec04ad8f58302
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/image_processing_superglue.py
@@ -0,0 +1,474 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for SuperPoint."""
+
+from typing import TYPE_CHECKING, Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import resize, to_channel_dimension_format
+from ...image_utils import (
+ ChannelDimension,
+ ImageInput,
+ ImageType,
+ PILImageResampling,
+ get_image_type,
+ infer_channel_dimension_format,
+ is_pil_image,
+ is_scaled_image,
+ is_torch_available,
+ is_valid_image,
+ is_vision_available,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, logging, requires_backends
+from ...utils.import_utils import requires
+
+
+if is_torch_available():
+ import torch
+
+if TYPE_CHECKING:
+ from .modeling_superglue import KeypointMatchingOutput
+
+if is_vision_available():
+ import PIL
+ from PIL import Image, ImageDraw
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.superpoint.image_processing_superpoint.is_grayscale
+def is_grayscale(
+ image: np.ndarray,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+):
+ if input_data_format == ChannelDimension.FIRST:
+ if image.shape[0] == 1:
+ return True
+ return np.all(image[0, ...] == image[1, ...]) and np.all(image[1, ...] == image[2, ...])
+ elif input_data_format == ChannelDimension.LAST:
+ if image.shape[-1] == 1:
+ return True
+ return np.all(image[..., 0] == image[..., 1]) and np.all(image[..., 1] == image[..., 2])
+
+
+# Copied from transformers.models.superpoint.image_processing_superpoint.convert_to_grayscale
+def convert_to_grayscale(
+ image: ImageInput,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> ImageInput:
+ """
+ Converts an image to grayscale format using the NTSC formula. Only support numpy and PIL Image. TODO support torch
+ and tensorflow grayscale conversion
+
+ This function is supposed to return a 1-channel image, but it returns a 3-channel image with the same value in each
+ channel, because of an issue that is discussed in :
+ https://github.com/huggingface/transformers/pull/25786#issuecomment-1730176446
+
+ Args:
+ image (Image):
+ The image to convert.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image.
+ """
+ requires_backends(convert_to_grayscale, ["vision"])
+
+ if isinstance(image, np.ndarray):
+ if is_grayscale(image, input_data_format=input_data_format):
+ return image
+ if input_data_format == ChannelDimension.FIRST:
+ gray_image = image[0, ...] * 0.2989 + image[1, ...] * 0.5870 + image[2, ...] * 0.1140
+ gray_image = np.stack([gray_image] * 3, axis=0)
+ elif input_data_format == ChannelDimension.LAST:
+ gray_image = image[..., 0] * 0.2989 + image[..., 1] * 0.5870 + image[..., 2] * 0.1140
+ gray_image = np.stack([gray_image] * 3, axis=-1)
+ return gray_image
+
+ if not isinstance(image, PIL.Image.Image):
+ return image
+
+ image = image.convert("L")
+ return image
+
+
+def validate_and_format_image_pairs(images: ImageInput):
+ error_message = (
+ "Input images must be a one of the following :",
+ " - A pair of PIL images.",
+ " - A pair of 3D arrays.",
+ " - A list of pairs of PIL images.",
+ " - A list of pairs of 3D arrays.",
+ )
+
+ def _is_valid_image(image):
+ """images is a PIL Image or a 3D array."""
+ return is_pil_image(image) or (
+ is_valid_image(image) and get_image_type(image) != ImageType.PIL and len(image.shape) == 3
+ )
+
+ if isinstance(images, list):
+ if len(images) == 2 and all((_is_valid_image(image)) for image in images):
+ return images
+ if all(
+ isinstance(image_pair, list)
+ and len(image_pair) == 2
+ and all(_is_valid_image(image) for image in image_pair)
+ for image_pair in images
+ ):
+ return [image for image_pair in images for image in image_pair]
+ raise ValueError(error_message)
+
+
+@requires(backends=("torch",))
+class SuperGlueImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a SuperGlue image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Controls whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden
+ by `do_resize` in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"height": 480, "width": 640}`):
+ Resolution of the output image after `resize` is applied. Only has an effect if `do_resize` is set to
+ `True`. Can be overridden by `size` in the `preprocess` method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in
+ the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess`
+ method.
+ do_grayscale (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to grayscale. Can be overridden by `do_grayscale` in the `preprocess` method.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_rescale: bool = True,
+ rescale_factor: float = 1 / 255,
+ do_grayscale: bool = True,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"height": 480, "width": 640}
+ size = get_size_dict(size, default_to_square=False)
+
+ self.do_resize = do_resize
+ self.size = size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_grayscale = do_grayscale
+
+ # Copied from transformers.models.superpoint.image_processing_superpoint.SuperPointImageProcessor.resize
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ):
+ """
+ Resize an image.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Dictionary of the form `{"height": int, "width": int}`, specifying the size of the output image.
+ data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the output image. If not provided, it will be inferred from the input
+ image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ size = get_size_dict(size, default_to_square=False)
+
+ return resize(
+ image,
+ size=(size["height"], size["width"]),
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ def preprocess(
+ self,
+ images,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_grayscale: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image pairs to preprocess. Expects either a list of 2 images or a list of list of 2 images list with
+ pixel values ranging from 0 to 255. If passing in images with pixel values between 0 and 1, set
+ `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the output image after `resize` has been applied. If `size["shortest_edge"]` >= 384, the image
+ is resized to `(size["shortest_edge"], size["shortest_edge"])`. Otherwise, the smaller edge of the
+ image will be matched to `int(size["shortest_edge"]/ crop_pct)`, after which the image is cropped to
+ `(size["shortest_edge"], size["shortest_edge"])`. Only has an effect if `do_resize` is set to `True`.
+ resample (`PILImageResampling`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of `PILImageResampling`, filters. Only
+ has an effect if `do_resize` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_grayscale (`bool`, *optional*, defaults to `self.do_grayscale`):
+ Whether to convert the image to grayscale.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_grayscale = do_grayscale if do_grayscale is not None else self.do_grayscale
+
+ size = size if size is not None else self.size
+ size = get_size_dict(size, default_to_square=False)
+
+ # Validate and convert the input images into a flattened list of images for all subsequent processing steps.
+ images = validate_and_format_image_pairs(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ validate_preprocess_arguments(
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ )
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if is_scaled_image(images[0]) and do_rescale:
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ all_images = []
+ for image in images:
+ if do_resize:
+ image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+
+ if do_grayscale:
+ image = convert_to_grayscale(image, input_data_format=input_data_format)
+
+ image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+ all_images.append(image)
+
+ # Convert back the flattened list of images into a list of pairs of images.
+ image_pairs = [all_images[i : i + 2] for i in range(0, len(all_images), 2)]
+
+ data = {"pixel_values": image_pairs}
+
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+ def post_process_keypoint_matching(
+ self,
+ outputs: "KeypointMatchingOutput",
+ target_sizes: Union[TensorType, list[tuple]],
+ threshold: float = 0.0,
+ ) -> list[dict[str, torch.Tensor]]:
+ """
+ Converts the raw output of [`KeypointMatchingOutput`] into lists of keypoints, scores and descriptors
+ with coordinates absolute to the original image sizes.
+ Args:
+ outputs ([`KeypointMatchingOutput`]):
+ Raw outputs of the model.
+ target_sizes (`torch.Tensor` or `list[tuple[tuple[int, int]]]`, *optional*):
+ Tensor of shape `(batch_size, 2, 2)` or list of tuples of tuples (`tuple[int, int]`) containing the
+ target size `(height, width)` of each image in the batch. This must be the original image size (before
+ any processing).
+ threshold (`float`, *optional*, defaults to 0.0):
+ Threshold to filter out the matches with low scores.
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the keypoints in the first and second image
+ of the pair, the matching scores and the matching indices.
+ """
+ if outputs.mask.shape[0] != len(target_sizes):
+ raise ValueError("Make sure that you pass in as many target sizes as the batch dimension of the mask")
+ if not all(len(target_size) == 2 for target_size in target_sizes):
+ raise ValueError("Each element of target_sizes must contain the size (h, w) of each image of the batch")
+
+ if isinstance(target_sizes, list):
+ image_pair_sizes = torch.tensor(target_sizes, device=outputs.mask.device)
+ else:
+ if target_sizes.shape[1] != 2 or target_sizes.shape[2] != 2:
+ raise ValueError(
+ "Each element of target_sizes must contain the size (h, w) of each image of the batch"
+ )
+ image_pair_sizes = target_sizes
+
+ keypoints = outputs.keypoints.clone()
+ keypoints = keypoints * image_pair_sizes.flip(-1).reshape(-1, 2, 1, 2)
+ keypoints = keypoints.to(torch.int32)
+
+ results = []
+ for mask_pair, keypoints_pair, matches, scores in zip(
+ outputs.mask, keypoints, outputs.matches[:, 0], outputs.matching_scores[:, 0]
+ ):
+ mask0 = mask_pair[0] > 0
+ mask1 = mask_pair[1] > 0
+ keypoints0 = keypoints_pair[0][mask0]
+ keypoints1 = keypoints_pair[1][mask1]
+ matches0 = matches[mask0]
+ scores0 = scores[mask0]
+
+ # Filter out matches with low scores
+ valid_matches = torch.logical_and(scores0 > threshold, matches0 > -1)
+
+ matched_keypoints0 = keypoints0[valid_matches]
+ matched_keypoints1 = keypoints1[matches0[valid_matches]]
+ matching_scores = scores0[valid_matches]
+
+ results.append(
+ {
+ "keypoints0": matched_keypoints0,
+ "keypoints1": matched_keypoints1,
+ "matching_scores": matching_scores,
+ }
+ )
+
+ return results
+
+ # Copied from transformers.models.efficientloftr.image_processing_efficientloftr.EfficientLoFTRImageProcessor.visualize_keypoint_matching with EfficientLoFTR->SuperGlue
+ def visualize_keypoint_matching(
+ self,
+ images: ImageInput,
+ keypoint_matching_output: list[dict[str, torch.Tensor]],
+ ) -> list["Image.Image"]:
+ """
+ Plots the image pairs side by side with the detected keypoints as well as the matching between them.
+
+ Args:
+ images (`ImageInput`):
+ Image pairs to plot. Same as `SuperGlueImageProcessor.preprocess`. Expects either a list of 2
+ images or a list of list of 2 images list with pixel values ranging from 0 to 255.
+ keypoint_matching_output (List[Dict[str, torch.Tensor]]]):
+ A post processed keypoint matching output
+
+ Returns:
+ `List[PIL.Image.Image]`: A list of PIL images, each containing the image pairs side by side with the detected
+ keypoints as well as the matching between them.
+ """
+ images = validate_and_format_image_pairs(images)
+ images = [to_numpy_array(image) for image in images]
+ image_pairs = [images[i : i + 2] for i in range(0, len(images), 2)]
+
+ results = []
+ for image_pair, pair_output in zip(image_pairs, keypoint_matching_output):
+ height0, width0 = image_pair[0].shape[:2]
+ height1, width1 = image_pair[1].shape[:2]
+ plot_image = np.zeros((max(height0, height1), width0 + width1, 3), dtype=np.uint8)
+ plot_image[:height0, :width0] = image_pair[0]
+ plot_image[:height1, width0:] = image_pair[1]
+
+ plot_image_pil = Image.fromarray(plot_image)
+ draw = ImageDraw.Draw(plot_image_pil)
+
+ keypoints0_x, keypoints0_y = pair_output["keypoints0"].unbind(1)
+ keypoints1_x, keypoints1_y = pair_output["keypoints1"].unbind(1)
+ for keypoint0_x, keypoint0_y, keypoint1_x, keypoint1_y, matching_score in zip(
+ keypoints0_x, keypoints0_y, keypoints1_x, keypoints1_y, pair_output["matching_scores"]
+ ):
+ color = self._get_color(matching_score)
+ draw.line(
+ (keypoint0_x, keypoint0_y, keypoint1_x + width0, keypoint1_y),
+ fill=color,
+ width=3,
+ )
+ draw.ellipse((keypoint0_x - 2, keypoint0_y - 2, keypoint0_x + 2, keypoint0_y + 2), fill="black")
+ draw.ellipse(
+ (keypoint1_x + width0 - 2, keypoint1_y - 2, keypoint1_x + width0 + 2, keypoint1_y + 2),
+ fill="black",
+ )
+
+ results.append(plot_image_pil)
+ return results
+
+ # Copied from transformers.models.efficientloftr.image_processing_efficientloftr.EfficientLoFTRImageProcessor._get_color
+ def _get_color(self, score):
+ """Maps a score to a color."""
+ r = int(255 * (1 - score))
+ g = int(255 * score)
+ b = 0
+ return (r, g, b)
+
+
+__all__ = ["SuperGlueImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/modeling_superglue.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/modeling_superglue.py
new file mode 100644
index 0000000000000000000000000000000000000000..61c52d06e6053dfef81533557a0fde3434519aee
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superglue/modeling_superglue.py
@@ -0,0 +1,811 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch SuperGlue model."""
+
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from transformers import PreTrainedModel
+from transformers.models.superglue.configuration_superglue import SuperGlueConfig
+
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import ModelOutput, auto_docstring, logging
+from ..auto import AutoModelForKeypointDetection
+
+
+logger = logging.get_logger(__name__)
+
+
+def concat_pairs(tensor_tuple0: tuple[torch.Tensor], tensor_tuple1: tuple[torch.Tensor]) -> tuple[torch.Tensor]:
+ """
+ Concatenate two tuples of tensors pairwise
+
+ Args:
+ tensor_tuple0 (`tuple[torch.Tensor]`):
+ Tuple of tensors.
+ tensor_tuple1 (`tuple[torch.Tensor]`):
+ Tuple of tensors.
+
+ Returns:
+ (`tuple[torch.Tensor]`): Tuple of concatenated tensors.
+ """
+ return tuple(torch.cat([tensor0, tensor1]) for tensor0, tensor1 in zip(tensor_tuple0, tensor_tuple1))
+
+
+def normalize_keypoints(keypoints: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ Normalize keypoints locations based on image image_shape
+
+ Args:
+ keypoints (`torch.Tensor` of shape `(batch_size, num_keypoints, 2)`):
+ Keypoints locations in (x, y) format.
+ height (`int`):
+ Image height.
+ width (`int`):
+ Image width.
+
+ Returns:
+ Normalized keypoints locations of shape (`torch.Tensor` of shape `(batch_size, num_keypoints, 2)`).
+ """
+ size = torch.tensor([width, height], device=keypoints.device, dtype=keypoints.dtype)[None]
+ center = size / 2
+ scaling = size.max(1, keepdim=True).values * 0.7
+ return (keypoints - center[:, None, :]) / scaling[:, None, :]
+
+
+def log_sinkhorn_iterations(
+ log_cost_matrix: torch.Tensor,
+ log_source_distribution: torch.Tensor,
+ log_target_distribution: torch.Tensor,
+ num_iterations: int,
+) -> torch.Tensor:
+ """
+ Perform Sinkhorn Normalization in Log-space for stability
+
+ Args:
+ log_cost_matrix (`torch.Tensor` of shape `(batch_size, num_rows, num_columns)`):
+ Logarithm of the cost matrix.
+ log_source_distribution (`torch.Tensor` of shape `(batch_size, num_rows)`):
+ Logarithm of the source distribution.
+ log_target_distribution (`torch.Tensor` of shape `(batch_size, num_columns)`):
+ Logarithm of the target distribution.
+
+ Returns:
+ log_cost_matrix (`torch.Tensor` of shape `(batch_size, num_rows, num_columns)`): Logarithm of the optimal
+ transport matrix.
+ """
+ log_u_scaling = torch.zeros_like(log_source_distribution)
+ log_v_scaling = torch.zeros_like(log_target_distribution)
+ for _ in range(num_iterations):
+ log_u_scaling = log_source_distribution - torch.logsumexp(log_cost_matrix + log_v_scaling.unsqueeze(1), dim=2)
+ log_v_scaling = log_target_distribution - torch.logsumexp(log_cost_matrix + log_u_scaling.unsqueeze(2), dim=1)
+ return log_cost_matrix + log_u_scaling.unsqueeze(2) + log_v_scaling.unsqueeze(1)
+
+
+def log_optimal_transport(scores: torch.Tensor, reg_param: torch.Tensor, iterations: int) -> torch.Tensor:
+ """
+ Perform Differentiable Optimal Transport in Log-space for stability
+
+ Args:
+ scores: (`torch.Tensor` of shape `(batch_size, num_rows, num_columns)`):
+ Cost matrix.
+ reg_param: (`torch.Tensor` of shape `(batch_size, 1, 1)`):
+ Regularization parameter.
+ iterations: (`int`):
+ Number of Sinkhorn iterations.
+
+ Returns:
+ log_optimal_transport_matrix: (`torch.Tensor` of shape `(batch_size, num_rows, num_columns)`): Logarithm of the
+ optimal transport matrix.
+ """
+ batch_size, num_rows, num_columns = scores.shape
+ one_tensor = scores.new_tensor(1)
+ num_rows_tensor, num_columns_tensor = (num_rows * one_tensor).to(scores), (num_columns * one_tensor).to(scores)
+
+ source_reg_param = reg_param.expand(batch_size, num_rows, 1)
+ target_reg_param = reg_param.expand(batch_size, 1, num_columns)
+ reg_param = reg_param.expand(batch_size, 1, 1)
+
+ couplings = torch.cat([torch.cat([scores, source_reg_param], -1), torch.cat([target_reg_param, reg_param], -1)], 1)
+
+ log_normalization = -(num_rows_tensor + num_columns_tensor).log()
+ log_source_distribution = torch.cat(
+ [log_normalization.expand(num_rows), num_columns_tensor.log()[None] + log_normalization]
+ )
+ log_target_distribution = torch.cat(
+ [log_normalization.expand(num_columns), num_rows_tensor.log()[None] + log_normalization]
+ )
+ log_source_distribution, log_target_distribution = (
+ log_source_distribution[None].expand(batch_size, -1),
+ log_target_distribution[None].expand(batch_size, -1),
+ )
+
+ log_optimal_transport_matrix = log_sinkhorn_iterations(
+ couplings, log_source_distribution, log_target_distribution, num_iterations=iterations
+ )
+ log_optimal_transport_matrix = log_optimal_transport_matrix - log_normalization # multiply probabilities by M+N
+ return log_optimal_transport_matrix
+
+
+def arange_like(x, dim: int) -> torch.Tensor:
+ return x.new_ones(x.shape[dim]).cumsum(0) - 1
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for outputs of keypoint matching models. Due to the nature of keypoint detection and matching, the number
+ of keypoints is not fixed and can vary from image to image, which makes batching non-trivial. In the batch of
+ images, the maximum number of matches is set as the dimension of the matches and matching scores. The mask tensor is
+ used to indicate which values in the keypoints, matches and matching_scores tensors are keypoint matching
+ information.
+ """
+)
+class KeypointMatchingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*):
+ Loss computed during training.
+ matches (`torch.FloatTensor` of shape `(batch_size, 2, num_matches)`):
+ Index of keypoint matched in the other image.
+ matching_scores (`torch.FloatTensor` of shape `(batch_size, 2, num_matches)`):
+ Scores of predicted matches.
+ keypoints (`torch.FloatTensor` of shape `(batch_size, num_keypoints, 2)`):
+ Absolute (x, y) coordinates of predicted keypoints in a given image.
+ mask (`torch.IntTensor` of shape `(batch_size, num_keypoints)`):
+ Mask indicating which values in matches and matching_scores are keypoint matching information.
+ hidden_states (`tuple[torch.FloatTensor, ...]`, *optional*):
+ Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(batch_size, 2, num_channels,
+ num_keypoints)`, returned when `output_hidden_states=True` is passed or when
+ `config.output_hidden_states=True`)
+ attentions (`tuple[torch.FloatTensor, ...]`, *optional*):
+ Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, 2, num_heads, num_keypoints,
+ num_keypoints)`, returned when `output_attentions=True` is passed or when `config.output_attentions=True`)
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ matches: Optional[torch.FloatTensor] = None
+ matching_scores: Optional[torch.FloatTensor] = None
+ keypoints: Optional[torch.FloatTensor] = None
+ mask: Optional[torch.IntTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+class SuperGlueMultiLayerPerceptron(nn.Module):
+ def __init__(self, config: SuperGlueConfig, in_channels: int, out_channels: int) -> None:
+ super().__init__()
+ self.linear = nn.Linear(in_channels, out_channels)
+ self.batch_norm = nn.BatchNorm1d(out_channels)
+ self.activation = nn.ReLU()
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ hidden_state = self.linear(hidden_state)
+ hidden_state = hidden_state.transpose(-1, -2)
+ hidden_state = self.batch_norm(hidden_state)
+ hidden_state = hidden_state.transpose(-1, -2)
+ hidden_state = self.activation(hidden_state)
+ return hidden_state
+
+
+class SuperGlueKeypointEncoder(nn.Module):
+ def __init__(self, config: SuperGlueConfig) -> None:
+ super().__init__()
+ layer_sizes = config.keypoint_encoder_sizes
+ hidden_size = config.hidden_size
+ # 3 here consists of 2 for the (x, y) coordinates and 1 for the score of the keypoint
+ encoder_channels = [3] + layer_sizes + [hidden_size]
+
+ layers = [
+ SuperGlueMultiLayerPerceptron(config, encoder_channels[i - 1], encoder_channels[i])
+ for i in range(1, len(encoder_channels) - 1)
+ ]
+ layers.append(nn.Linear(encoder_channels[-2], encoder_channels[-1]))
+ self.encoder = nn.ModuleList(layers)
+
+ def forward(
+ self,
+ keypoints: torch.Tensor,
+ scores: torch.Tensor,
+ output_hidden_states: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, Optional[tuple[torch.Tensor]]]:
+ scores = scores.unsqueeze(2)
+ hidden_state = torch.cat([keypoints, scores], dim=2)
+ all_hidden_states = () if output_hidden_states else None
+ for layer in self.encoder:
+ hidden_state = layer(hidden_state)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_state,)
+ return hidden_state, all_hidden_states
+
+
+class SuperGlueSelfAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.position_embedding_type = position_embedding_type or getattr(
+ config, "position_embedding_type", "absolute"
+ )
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ self.max_position_embeddings = config.max_position_embeddings
+ self.distance_embedding = nn.Embedding(2 * config.max_position_embeddings - 1, self.attention_head_size)
+
+ self.is_decoder = config.is_decoder
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ # If this is instantiated as a cross-attention module, the keys
+ # and values come from an encoder; the attention mask needs to be
+ # such that the encoder's padding tokens are not attended to.
+ is_cross_attention = encoder_hidden_states is not None
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ attention_mask = encoder_attention_mask if is_cross_attention else attention_mask
+
+ batch_size = hidden_states.shape[0]
+ key_layer = (
+ self.key(current_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(current_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ query_length, key_length = query_layer.shape[2], key_layer.shape[2]
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_l - position_ids_r
+
+ positional_embedding = self.distance_embedding(distance + self.max_position_embeddings - 1)
+ positional_embedding = positional_embedding.to(dtype=query_layer.dtype) # fp16 compatibility
+
+ if self.position_embedding_type == "relative_key":
+ relative_position_scores = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores
+ elif self.position_embedding_type == "relative_key_query":
+ relative_position_scores_query = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ relative_position_scores_key = torch.einsum("bhrd,lrd->bhlr", key_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores_query + relative_position_scores_key
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in SuperGlueModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ if self.is_decoder:
+ outputs = outputs + (None,)
+ return outputs
+
+
+class SuperGlueSelfOutput(nn.Module):
+ def __init__(self, config: SuperGlueConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor, *args) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ return hidden_states
+
+
+SUPERGLUE_SELF_ATTENTION_CLASSES = {
+ "eager": SuperGlueSelfAttention,
+}
+
+
+class SuperGlueAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ self.self = SUPERGLUE_SELF_ATTENTION_CLASSES[config._attn_implementation](
+ config,
+ position_embedding_type=position_embedding_type,
+ )
+ self.output = SuperGlueSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+class SuperGlueAttentionalPropagation(nn.Module):
+ def __init__(self, config: SuperGlueConfig) -> None:
+ super().__init__()
+ hidden_size = config.hidden_size
+ self.attention = SuperGlueAttention(config)
+ mlp_channels = [hidden_size * 2, hidden_size * 2, hidden_size]
+ layers = [
+ SuperGlueMultiLayerPerceptron(config, mlp_channels[i - 1], mlp_channels[i])
+ for i in range(1, len(mlp_channels) - 1)
+ ]
+ layers.append(nn.Linear(mlp_channels[-2], mlp_channels[-1]))
+ self.mlp = nn.ModuleList(layers)
+
+ def forward(
+ self,
+ descriptors: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ ) -> tuple[torch.Tensor, Optional[tuple[torch.Tensor]], Optional[tuple[torch.Tensor]]]:
+ attention_outputs = self.attention(
+ descriptors,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ )
+ output = attention_outputs[0]
+ attention = attention_outputs[1:]
+
+ hidden_state = torch.cat([descriptors, output], dim=2)
+
+ all_hidden_states = () if output_hidden_states else None
+ for layer in self.mlp:
+ hidden_state = layer(hidden_state)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_state,)
+
+ return hidden_state, all_hidden_states, attention
+
+
+class SuperGlueAttentionalGNN(nn.Module):
+ def __init__(self, config: SuperGlueConfig) -> None:
+ super().__init__()
+ self.hidden_size = config.hidden_size
+ self.layers_types = config.gnn_layers_types
+ self.layers = nn.ModuleList([SuperGlueAttentionalPropagation(config) for _ in range(len(self.layers_types))])
+
+ def forward(
+ self,
+ descriptors: torch.Tensor,
+ mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, Optional[tuple], Optional[tuple]]:
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ batch_size, num_keypoints, _ = descriptors.shape
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (descriptors,)
+
+ for gnn_layer, layer_type in zip(self.layers, self.layers_types):
+ encoder_hidden_states = None
+ encoder_attention_mask = None
+ if layer_type == "cross":
+ encoder_hidden_states = (
+ descriptors.reshape(-1, 2, num_keypoints, self.hidden_size)
+ .flip(1)
+ .reshape(batch_size, num_keypoints, self.hidden_size)
+ )
+ encoder_attention_mask = (
+ mask.reshape(-1, 2, 1, 1, num_keypoints).flip(1).reshape(batch_size, 1, 1, num_keypoints)
+ if mask is not None
+ else None
+ )
+
+ gnn_outputs = gnn_layer(
+ descriptors,
+ attention_mask=mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_hidden_states=output_hidden_states,
+ output_attentions=output_attentions,
+ )
+ delta = gnn_outputs[0]
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + gnn_outputs[1]
+ if output_attentions:
+ all_attentions = all_attentions + gnn_outputs[2]
+
+ descriptors = descriptors + delta
+ return descriptors, all_hidden_states, all_attentions
+
+
+class SuperGlueFinalProjection(nn.Module):
+ def __init__(self, config: SuperGlueConfig) -> None:
+ super().__init__()
+ hidden_size = config.hidden_size
+ self.final_proj = nn.Linear(hidden_size, hidden_size, bias=True)
+
+ def forward(self, descriptors: torch.Tensor) -> torch.Tensor:
+ return self.final_proj(descriptors)
+
+
+@auto_docstring
+class SuperGluePreTrainedModel(PreTrainedModel):
+ config: SuperGlueConfig
+ base_model_prefix = "superglue"
+ main_input_name = "pixel_values"
+
+ def _init_weights(self, module: nn.Module) -> None:
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.BatchNorm1d):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+ if hasattr(module, "bin_score"):
+ module.bin_score.data.fill_(1.0)
+
+
+@auto_docstring(
+ custom_intro="""
+ SuperGlue model taking images as inputs and outputting the matching of them.
+ """
+)
+class SuperGlueForKeypointMatching(SuperGluePreTrainedModel):
+ """SuperGlue feature matching middle-end
+
+ Given two sets of keypoints and locations, we determine the
+ correspondences by:
+ 1. Keypoint Encoding (normalization + visual feature and location fusion)
+ 2. Graph Neural Network with multiple self and cross-attention layers
+ 3. Final projection layer
+ 4. Optimal Transport Layer (a differentiable Hungarian matching algorithm)
+ 5. Thresholding matrix based on mutual exclusivity and a match_threshold
+
+ The correspondence ids use -1 to indicate non-matching points.
+
+ Paul-Edouard Sarlin, Daniel DeTone, Tomasz Malisiewicz, and Andrew
+ Rabinovich. SuperGlue: Learning Feature Matching with Graph Neural
+ Networks. In CVPR, 2020. https://huggingface.co/papers/1911.11763
+ """
+
+ def __init__(self, config: SuperGlueConfig) -> None:
+ super().__init__(config)
+
+ self.keypoint_detector = AutoModelForKeypointDetection.from_config(config.keypoint_detector_config)
+
+ self.keypoint_encoder = SuperGlueKeypointEncoder(config)
+ self.gnn = SuperGlueAttentionalGNN(config)
+ self.final_projection = SuperGlueFinalProjection(config)
+
+ bin_score = torch.nn.Parameter(torch.tensor(1.0))
+ self.register_parameter("bin_score", bin_score)
+
+ self.post_init()
+
+ def _match_image_pair(
+ self,
+ keypoints: torch.Tensor,
+ descriptors: torch.Tensor,
+ scores: torch.Tensor,
+ height: int,
+ width: int,
+ mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> tuple[torch.Tensor, torch.Tensor, tuple, tuple]:
+ """
+ Perform keypoint matching between two images.
+
+ Args:
+ keypoints (`torch.Tensor` of shape `(batch_size, 2, num_keypoints, 2)`):
+ Keypoints detected in the pair of image.
+ descriptors (`torch.Tensor` of shape `(batch_size, 2, descriptor_dim, num_keypoints)`):
+ Descriptors of the keypoints detected in the image pair.
+ scores (`torch.Tensor` of shape `(batch_size, 2, num_keypoints)`):
+ Confidence scores of the keypoints detected in the image pair.
+ height (`int`): Image height.
+ width (`int`): Image width.
+ mask (`torch.Tensor` of shape `(batch_size, 2, num_keypoints)`, *optional*):
+ Mask indicating which values in the keypoints, matches and matching_scores tensors are keypoint matching
+ information.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors. Default to `config.output_attentions`.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. Default to `config.output_hidden_states`.
+
+ Returns:
+ matches (`torch.Tensor` of shape `(batch_size, 2, num_keypoints)`):
+ For each image pair, for each keypoint in image0, the index of the keypoint in image1 that was matched
+ with. And for each keypoint in image1, the index of the keypoint in image0 that was matched with.
+ matching_scores (`torch.Tensor` of shape `(batch_size, 2, num_keypoints)`):
+ Scores of predicted matches for each image pair
+ all_hidden_states (`tuple(torch.FloatTensor)`, *optional*):
+ Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(1, 2, num_keypoints,
+ num_channels)`.
+ all_attentions (`tuple(torch.FloatTensor)`, *optional*):
+ Tuple of `torch.FloatTensor` (one for each layer) of shape `(1, 2, num_heads, num_keypoints,
+ num_keypoints)`.
+ """
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ if keypoints.shape[2] == 0: # no keypoints
+ shape = keypoints.shape[:-1]
+ return (
+ keypoints.new_full(shape, -1, dtype=torch.int),
+ keypoints.new_zeros(shape),
+ all_hidden_states,
+ all_attentions,
+ )
+
+ batch_size, _, num_keypoints, _ = keypoints.shape
+ # (batch_size, 2, num_keypoints, 2) -> (batch_size * 2, num_keypoints, 2)
+ keypoints = keypoints.reshape(batch_size * 2, num_keypoints, 2)
+ descriptors = descriptors.reshape(batch_size * 2, num_keypoints, self.config.hidden_size)
+ scores = scores.reshape(batch_size * 2, num_keypoints)
+ mask = mask.reshape(batch_size * 2, num_keypoints) if mask is not None else None
+
+ # Keypoint normalization
+ keypoints = normalize_keypoints(keypoints, height, width)
+
+ encoded_keypoints = self.keypoint_encoder(keypoints, scores, output_hidden_states=output_hidden_states)
+
+ last_hidden_state = encoded_keypoints[0]
+
+ # Keypoint MLP encoder.
+ descriptors = descriptors + last_hidden_state
+
+ if mask is not None:
+ input_shape = descriptors.size()
+ extended_attention_mask = self.get_extended_attention_mask(mask, input_shape)
+ else:
+ extended_attention_mask = torch.ones((batch_size, num_keypoints), device=keypoints.device)
+
+ # Multi-layer Transformer network.
+ gnn_outputs = self.gnn(
+ descriptors,
+ mask=extended_attention_mask,
+ output_hidden_states=output_hidden_states,
+ output_attentions=output_attentions,
+ )
+ descriptors = gnn_outputs[0]
+
+ # Final MLP projection.
+ projected_descriptors = self.final_projection(descriptors)
+
+ # (batch_size * 2, num_keypoints, descriptor_dim) -> (batch_size, 2, num_keypoints, descriptor_dim)
+ final_descriptors = projected_descriptors.reshape(batch_size, 2, num_keypoints, self.config.hidden_size)
+ final_descriptors0 = final_descriptors[:, 0]
+ final_descriptors1 = final_descriptors[:, 1]
+
+ # Compute matching descriptor distance.
+ scores = final_descriptors0 @ final_descriptors1.transpose(1, 2)
+ scores = scores / self.config.hidden_size**0.5
+
+ if mask is not None:
+ mask = mask.reshape(batch_size, 2, num_keypoints)
+ mask0 = mask[:, 0].unsqueeze(2)
+ mask1 = mask[:, 1].unsqueeze(1)
+ mask = torch.logical_and(mask0, mask1)
+ scores = scores.masked_fill(mask == 0, torch.finfo(scores.dtype).min)
+
+ # Run the optimal transport.
+ scores = log_optimal_transport(scores, self.bin_score, iterations=self.config.sinkhorn_iterations)
+
+ # Get the matches with score above "match_threshold".
+ max0 = scores[:, :-1, :-1].max(2)
+ max1 = scores[:, :-1, :-1].max(1)
+ indices0 = max0.indices
+ indices1 = max1.indices
+ mutual0 = arange_like(indices0, 1)[None] == indices1.gather(1, indices0)
+ mutual1 = arange_like(indices1, 1)[None] == indices0.gather(1, indices1)
+ zero = scores.new_tensor(0)
+ matching_scores0 = torch.where(mutual0, max0.values.exp(), zero)
+ matching_scores0 = torch.where(matching_scores0 > self.config.matching_threshold, matching_scores0, zero)
+ matching_scores1 = torch.where(mutual1, matching_scores0.gather(1, indices1), zero)
+ valid0 = mutual0 & (matching_scores0 > zero)
+ valid1 = mutual1 & valid0.gather(1, indices1)
+ matches0 = torch.where(valid0, indices0, indices0.new_tensor(-1))
+ matches1 = torch.where(valid1, indices1, indices1.new_tensor(-1))
+
+ matches = torch.cat([matches0, matches1], dim=1).reshape(batch_size, 2, -1)
+ matching_scores = torch.cat([matching_scores0, matching_scores1], dim=1).reshape(batch_size, 2, -1)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + encoded_keypoints[1]
+ all_hidden_states = all_hidden_states + gnn_outputs[1]
+ all_hidden_states = all_hidden_states + (projected_descriptors,)
+ all_hidden_states = tuple(
+ x.reshape(batch_size, 2, num_keypoints, -1).transpose(-1, -2) for x in all_hidden_states
+ )
+ if output_attentions:
+ all_attentions = all_attentions + gnn_outputs[2]
+ all_attentions = tuple(x.reshape(batch_size, 2, -1, num_keypoints, num_keypoints) for x in all_attentions)
+
+ return (
+ matches,
+ matching_scores,
+ all_hidden_states,
+ all_attentions,
+ )
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, KeypointMatchingOutput]:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, AutoModel
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "https://github.com/magicleap/SuperGluePretrainedNetwork/blob/master/assets/phototourism_sample_images/london_bridge_78916675_4568141288.jpg?raw=true"
+ >>> image1 = Image.open(requests.get(url, stream=True).raw)
+ >>> url = "https://github.com/magicleap/SuperGluePretrainedNetwork/blob/master/assets/phototourism_sample_images/london_bridge_19481797_2295892421.jpg?raw=true"
+ >>> image2 = Image.open(requests.get(url, stream=True).raw)
+ >>> images = [image1, image2]
+
+ >>> processor = AutoImageProcessor.from_pretrained("magic-leap-community/superglue_outdoor")
+ >>> model = AutoModel.from_pretrained("magic-leap-community/superglue_outdoor")
+
+ >>> with torch.no_grad():
+ >>> inputs = processor(images, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ ```"""
+ loss = None
+ if labels is not None:
+ raise ValueError("SuperGlue is not trainable, no labels should be provided.")
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values.ndim != 5 or pixel_values.size(1) != 2:
+ raise ValueError("Input must be a 5D tensor of shape (batch_size, 2, num_channels, height, width)")
+
+ batch_size, _, channels, height, width = pixel_values.shape
+ pixel_values = pixel_values.reshape(batch_size * 2, channels, height, width)
+ keypoint_detections = self.keypoint_detector(pixel_values)
+
+ keypoints, scores, descriptors, mask = keypoint_detections[:4]
+ keypoints = keypoints.reshape(batch_size, 2, -1, 2).to(pixel_values)
+ scores = scores.reshape(batch_size, 2, -1).to(pixel_values)
+ descriptors = descriptors.reshape(batch_size, 2, -1, self.config.hidden_size).to(pixel_values)
+ mask = mask.reshape(batch_size, 2, -1)
+
+ absolute_keypoints = keypoints.clone()
+ absolute_keypoints[:, :, :, 0] = absolute_keypoints[:, :, :, 0] * width
+ absolute_keypoints[:, :, :, 1] = absolute_keypoints[:, :, :, 1] * height
+
+ matches, matching_scores, hidden_states, attentions = self._match_image_pair(
+ absolute_keypoints,
+ descriptors,
+ scores,
+ height,
+ width,
+ mask=mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [loss, matches, matching_scores, keypoints, mask, hidden_states, attentions]
+ if v is not None
+ )
+
+ return KeypointMatchingOutput(
+ loss=loss,
+ matches=matches,
+ matching_scores=matching_scores,
+ keypoints=keypoints,
+ mask=mask,
+ hidden_states=hidden_states,
+ attentions=attentions,
+ )
+
+
+__all__ = ["SuperGluePreTrainedModel", "SuperGlueForKeypointMatching"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ccec260fa5e7d33818153d651d833d43226224e7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_superpoint import *
+ from .image_processing_superpoint import *
+ from .image_processing_superpoint_fast import *
+ from .modeling_superpoint import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/configuration_superpoint.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/configuration_superpoint.py
new file mode 100644
index 0000000000000000000000000000000000000000..1e4271960726fd34235e8377fd42d438bda1d35c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/configuration_superpoint.py
@@ -0,0 +1,89 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class SuperPointConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SuperPointForKeypointDetection`]. It is used to instantiate a
+ SuperPoint model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the SuperPoint
+ [magic-leap-community/superpoint](https://huggingface.co/magic-leap-community/superpoint) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ encoder_hidden_sizes (`List`, *optional*, defaults to `[64, 64, 128, 128]`):
+ The number of channels in each convolutional layer in the encoder.
+ decoder_hidden_size (`int`, *optional*, defaults to 256): The hidden size of the decoder.
+ keypoint_decoder_dim (`int`, *optional*, defaults to 65): The output dimension of the keypoint decoder.
+ descriptor_decoder_dim (`int`, *optional*, defaults to 256): The output dimension of the descriptor decoder.
+ keypoint_threshold (`float`, *optional*, defaults to 0.005):
+ The threshold to use for extracting keypoints.
+ max_keypoints (`int`, *optional*, defaults to -1):
+ The maximum number of keypoints to extract. If `-1`, will extract all keypoints.
+ nms_radius (`int`, *optional*, defaults to 4):
+ The radius for non-maximum suppression.
+ border_removal_distance (`int`, *optional*, defaults to 4):
+ The distance from the border to remove keypoints.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+
+ Example:
+ ```python
+ >>> from transformers import SuperPointConfig, SuperPointForKeypointDetection
+
+ >>> # Initializing a SuperPoint superpoint style configuration
+ >>> configuration = SuperPointConfig()
+ >>> # Initializing a model from the superpoint style configuration
+ >>> model = SuperPointForKeypointDetection(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "superpoint"
+
+ def __init__(
+ self,
+ encoder_hidden_sizes: list[int] = [64, 64, 128, 128],
+ decoder_hidden_size: int = 256,
+ keypoint_decoder_dim: int = 65,
+ descriptor_decoder_dim: int = 256,
+ keypoint_threshold: float = 0.005,
+ max_keypoints: int = -1,
+ nms_radius: int = 4,
+ border_removal_distance: int = 4,
+ initializer_range=0.02,
+ **kwargs,
+ ):
+ self.encoder_hidden_sizes = encoder_hidden_sizes
+ self.decoder_hidden_size = decoder_hidden_size
+ self.keypoint_decoder_dim = keypoint_decoder_dim
+ self.descriptor_decoder_dim = descriptor_decoder_dim
+ self.keypoint_threshold = keypoint_threshold
+ self.max_keypoints = max_keypoints
+ self.nms_radius = nms_radius
+ self.border_removal_distance = border_removal_distance
+ self.initializer_range = initializer_range
+
+ super().__init__(**kwargs)
+
+
+__all__ = ["SuperPointConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/image_processing_superpoint.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/image_processing_superpoint.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6167160c29dc800828ce8ed664b5aefae11e8ff
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/image_processing_superpoint.py
@@ -0,0 +1,352 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for SuperPoint."""
+
+from typing import TYPE_CHECKING, Optional, Union
+
+import numpy as np
+
+from ... import is_torch_available, is_vision_available
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import resize, to_channel_dimension_format
+from ...image_utils import (
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+)
+from ...utils import TensorType, logging, requires_backends
+
+
+if is_torch_available():
+ import torch
+
+if TYPE_CHECKING:
+ from .modeling_superpoint import SuperPointKeypointDescriptionOutput
+
+if is_vision_available():
+ import PIL
+
+logger = logging.get_logger(__name__)
+
+
+def is_grayscale(
+ image: np.ndarray,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+):
+ if input_data_format == ChannelDimension.FIRST:
+ if image.shape[0] == 1:
+ return True
+ return np.all(image[0, ...] == image[1, ...]) and np.all(image[1, ...] == image[2, ...])
+ elif input_data_format == ChannelDimension.LAST:
+ if image.shape[-1] == 1:
+ return True
+ return np.all(image[..., 0] == image[..., 1]) and np.all(image[..., 1] == image[..., 2])
+
+
+def convert_to_grayscale(
+ image: ImageInput,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> ImageInput:
+ """
+ Converts an image to grayscale format using the NTSC formula. Only support numpy and PIL Image. TODO support torch
+ and tensorflow grayscale conversion
+
+ This function is supposed to return a 1-channel image, but it returns a 3-channel image with the same value in each
+ channel, because of an issue that is discussed in :
+ https://github.com/huggingface/transformers/pull/25786#issuecomment-1730176446
+
+ Args:
+ image (Image):
+ The image to convert.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image.
+ """
+ requires_backends(convert_to_grayscale, ["vision"])
+
+ if isinstance(image, np.ndarray):
+ if is_grayscale(image, input_data_format=input_data_format):
+ return image
+ if input_data_format == ChannelDimension.FIRST:
+ gray_image = image[0, ...] * 0.2989 + image[1, ...] * 0.5870 + image[2, ...] * 0.1140
+ gray_image = np.stack([gray_image] * 3, axis=0)
+ elif input_data_format == ChannelDimension.LAST:
+ gray_image = image[..., 0] * 0.2989 + image[..., 1] * 0.5870 + image[..., 2] * 0.1140
+ gray_image = np.stack([gray_image] * 3, axis=-1)
+ return gray_image
+
+ if not isinstance(image, PIL.Image.Image):
+ return image
+
+ image = image.convert("L")
+ return image
+
+
+class SuperPointImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a SuperPoint image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Controls whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden
+ by `do_resize` in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"height": 480, "width": 640}`):
+ Resolution of the output image after `resize` is applied. Only has an effect if `do_resize` is set to
+ `True`. Can be overridden by `size` in the `preprocess` method.
+ resample (`Resampling`, *optional*, defaults to `2`):
+ Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in
+ the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess`
+ method.
+ do_grayscale (`bool`, *optional*, defaults to `False`):
+ Whether to convert the image to grayscale. Can be overridden by `do_grayscale` in the `preprocess` method.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_rescale: bool = True,
+ rescale_factor: float = 1 / 255,
+ do_grayscale: bool = False,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"height": 480, "width": 640}
+ size = get_size_dict(size, default_to_square=False)
+
+ self.do_resize = do_resize
+ self.size = size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_grayscale = do_grayscale
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ):
+ """
+ Resize an image.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Dictionary of the form `{"height": int, "width": int}`, specifying the size of the output image.
+ data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the output image. If not provided, it will be inferred from the input
+ image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ size = get_size_dict(size, default_to_square=False)
+
+ return resize(
+ image,
+ size=(size["height"], size["width"]),
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ def preprocess(
+ self,
+ images,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_grayscale: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the output image after `resize` has been applied. If `size["shortest_edge"]` >= 384, the image
+ is resized to `(size["shortest_edge"], size["shortest_edge"])`. Otherwise, the smaller edge of the
+ image will be matched to `int(size["shortest_edge"]/ crop_pct)`, after which the image is cropped to
+ `(size["shortest_edge"], size["shortest_edge"])`. Only has an effect if `do_resize` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_grayscale (`bool`, *optional*, defaults to `self.do_grayscale`):
+ Whether to convert the image to grayscale.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_grayscale = do_grayscale if do_grayscale is not None else self.do_grayscale
+
+ size = size if size is not None else self.size
+ size = get_size_dict(size, default_to_square=False)
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ if do_resize and size is None:
+ raise ValueError("Size must be specified if do_resize is True.")
+
+ if do_rescale and rescale_factor is None:
+ raise ValueError("Rescale factor must be specified if do_rescale is True.")
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_resize:
+ images = [
+ self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_grayscale:
+ images = [convert_to_grayscale(image, input_data_format=input_data_format) for image in images]
+
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images
+ ]
+
+ data = {"pixel_values": images}
+
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+ def post_process_keypoint_detection(
+ self, outputs: "SuperPointKeypointDescriptionOutput", target_sizes: Union[TensorType, list[tuple]]
+ ) -> list[dict[str, "torch.Tensor"]]:
+ """
+ Converts the raw output of [`SuperPointForKeypointDetection`] into lists of keypoints, scores and descriptors
+ with coordinates absolute to the original image sizes.
+
+ Args:
+ outputs ([`SuperPointKeypointDescriptionOutput`]):
+ Raw outputs of the model containing keypoints in a relative (x, y) format, with scores and descriptors.
+ target_sizes (`torch.Tensor` or `list[tuple[int, int]]`):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size
+ `(height, width)` of each image in the batch. This must be the original
+ image size (before any processing).
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the keypoints in absolute format according
+ to target_sizes, scores and descriptors for an image in the batch as predicted by the model.
+ """
+ if len(outputs.mask) != len(target_sizes):
+ raise ValueError("Make sure that you pass in as many target sizes as the batch dimension of the mask")
+
+ if isinstance(target_sizes, list):
+ image_sizes = torch.tensor(target_sizes, device=outputs.mask.device)
+ else:
+ if target_sizes.shape[1] != 2:
+ raise ValueError(
+ "Each element of target_sizes must contain the size (h, w) of each image of the batch"
+ )
+ image_sizes = target_sizes
+
+ # Flip the image sizes to (width, height) and convert keypoints to absolute coordinates
+ image_sizes = torch.flip(image_sizes, [1])
+ masked_keypoints = outputs.keypoints * image_sizes[:, None]
+
+ # Convert masked_keypoints to int
+ masked_keypoints = masked_keypoints.to(torch.int32)
+
+ results = []
+ for image_mask, keypoints, scores, descriptors in zip(
+ outputs.mask, masked_keypoints, outputs.scores, outputs.descriptors
+ ):
+ indices = torch.nonzero(image_mask).squeeze(1)
+ keypoints = keypoints[indices]
+ scores = scores[indices]
+ descriptors = descriptors[indices]
+ results.append({"keypoints": keypoints, "scores": scores, "descriptors": descriptors})
+
+ return results
+
+
+__all__ = ["SuperPointImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/image_processing_superpoint_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/image_processing_superpoint_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..e70bb397ff6a8a468f4dbb6f803f152d796f1f92
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/image_processing_superpoint_fast.py
@@ -0,0 +1,182 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for Superpoint."""
+
+from typing import TYPE_CHECKING, Optional, Union
+
+from ...image_processing_utils import BatchFeature
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import (
+ PILImageResampling,
+ SizeDict,
+)
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+)
+
+
+if is_torch_available():
+ import torch
+
+if TYPE_CHECKING:
+ from .modeling_superpoint import SuperPointKeypointDescriptionOutput
+
+if is_torchvision_v2_available():
+ import torchvision.transforms.v2.functional as F
+elif is_torchvision_available():
+ import torchvision.transforms.functional as F
+
+
+def is_grayscale(
+ image: "torch.Tensor",
+):
+ """Checks if an image is grayscale (all RGB channels are identical)."""
+ if image.ndim < 3 or image.shape[0 if image.ndim == 3 else 1] == 1:
+ return True
+ return torch.all(image[..., 0, :, :] == image[..., 1, :, :]) and torch.all(
+ image[..., 1, :, :] == image[..., 2, :, :]
+ )
+
+
+class SuperPointFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ r"""
+ do_grayscale (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to grayscale. Can be overridden by `do_grayscale` in the `preprocess` method.
+ """
+
+ do_grayscale: Optional[bool] = True
+
+
+def convert_to_grayscale(
+ image: "torch.Tensor",
+) -> "torch.Tensor":
+ """
+ Converts an image to grayscale format using the NTSC formula. Only support torch.Tensor.
+
+ This function is supposed to return a 1-channel image, but it returns a 3-channel image with the same value in each
+ channel, because of an issue that is discussed in :
+ https://github.com/huggingface/transformers/pull/25786#issuecomment-1730176446
+
+ Args:
+ image (torch.Tensor):
+ The image to convert.
+ """
+ if is_grayscale(image):
+ return image
+ return F.rgb_to_grayscale(image, num_output_channels=3)
+
+
+@auto_docstring
+class SuperPointImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BILINEAR
+ size = {"height": 480, "width": 640}
+ default_to_square = False
+ do_resize = True
+ do_rescale = True
+ rescale_factor = 1 / 255
+ do_normalize = None
+ valid_kwargs = SuperPointFastImageProcessorKwargs
+
+ def __init__(self, **kwargs: Unpack[SuperPointFastImageProcessorKwargs]):
+ super().__init__(**kwargs)
+
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ size: Union[dict[str, int], SizeDict],
+ rescale_factor: float,
+ do_rescale: bool,
+ do_resize: bool,
+ interpolation: Optional["F.InterpolationMode"],
+ do_grayscale: bool,
+ disable_grouping: bool,
+ return_tensors: Union[str, TensorType],
+ **kwargs,
+ ) -> BatchFeature:
+ grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping)
+ processed_images_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ if do_grayscale:
+ stacked_images = convert_to_grayscale(stacked_images)
+ if do_resize:
+ stacked_images = self.resize(stacked_images, size=size, interpolation=interpolation)
+ if do_rescale:
+ stacked_images = self.rescale(stacked_images, rescale_factor)
+ processed_images_grouped[shape] = stacked_images
+ processed_images = reorder_images(processed_images_grouped, grouped_images_index)
+ processed_images = torch.stack(processed_images, dim=0) if return_tensors else processed_images
+ return BatchFeature(data={"pixel_values": processed_images})
+
+ def post_process_keypoint_detection(
+ self, outputs: "SuperPointKeypointDescriptionOutput", target_sizes: Union[TensorType, list[tuple]]
+ ) -> list[dict[str, "torch.Tensor"]]:
+ """
+ Converts the raw output of [`SuperPointForKeypointDetection`] into lists of keypoints, scores and descriptors
+ with coordinates absolute to the original image sizes.
+
+ Args:
+ outputs ([`SuperPointKeypointDescriptionOutput`]):
+ Raw outputs of the model containing keypoints in a relative (x, y) format, with scores and descriptors.
+ target_sizes (`torch.Tensor` or `List[Tuple[int, int]]`):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`Tuple[int, int]`) containing the target size
+ `(height, width)` of each image in the batch. This must be the original
+ image size (before any processing).
+ Returns:
+ `List[Dict]`: A list of dictionaries, each dictionary containing the keypoints in absolute format according
+ to target_sizes, scores and descriptors for an image in the batch as predicted by the model.
+ """
+ if len(outputs.mask) != len(target_sizes):
+ raise ValueError("Make sure that you pass in as many target sizes as the batch dimension of the mask")
+
+ if isinstance(target_sizes, list):
+ image_sizes = torch.tensor(target_sizes, device=outputs.mask.device)
+ else:
+ if target_sizes.shape[1] != 2:
+ raise ValueError(
+ "Each element of target_sizes must contain the size (h, w) of each image of the batch"
+ )
+ image_sizes = target_sizes
+
+ # Flip the image sizes to (width, height) and convert keypoints to absolute coordinates
+ image_sizes = torch.flip(image_sizes, [1])
+ masked_keypoints = outputs.keypoints * image_sizes[:, None]
+
+ # Convert masked_keypoints to int
+ masked_keypoints = masked_keypoints.to(torch.int32)
+
+ results = []
+ for image_mask, keypoints, scores, descriptors in zip(
+ outputs.mask, masked_keypoints, outputs.scores, outputs.descriptors
+ ):
+ indices = torch.nonzero(image_mask).squeeze(1)
+ keypoints = keypoints[indices]
+ scores = scores[indices]
+ descriptors = descriptors[indices]
+ results.append({"keypoints": keypoints, "scores": scores, "descriptors": descriptors})
+
+ return results
+
+
+__all__ = ["SuperPointImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/modeling_superpoint.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/modeling_superpoint.py
new file mode 100644
index 0000000000000000000000000000000000000000..efd3113eb3b0f8518734a36ff451f347605737b2
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/superpoint/modeling_superpoint.py
@@ -0,0 +1,477 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch SuperPoint model."""
+
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from transformers import PreTrainedModel
+from transformers.modeling_outputs import (
+ BaseModelOutputWithNoAttention,
+)
+from transformers.models.superpoint.configuration_superpoint import SuperPointConfig
+
+from ...utils import (
+ ModelOutput,
+ auto_docstring,
+ logging,
+)
+
+
+logger = logging.get_logger(__name__)
+
+
+def remove_keypoints_from_borders(
+ keypoints: torch.Tensor, scores: torch.Tensor, border: int, height: int, width: int
+) -> tuple[torch.Tensor, torch.Tensor]:
+ """Removes keypoints (and their associated scores) that are too close to the border"""
+ mask_h = (keypoints[:, 0] >= border) & (keypoints[:, 0] < (height - border))
+ mask_w = (keypoints[:, 1] >= border) & (keypoints[:, 1] < (width - border))
+ mask = mask_h & mask_w
+ return keypoints[mask], scores[mask]
+
+
+def top_k_keypoints(keypoints: torch.Tensor, scores: torch.Tensor, k: int) -> tuple[torch.Tensor, torch.Tensor]:
+ """Keeps the k keypoints with highest score"""
+ if k >= len(keypoints):
+ return keypoints, scores
+ scores, indices = torch.topk(scores, k, dim=0)
+ return keypoints[indices], scores
+
+
+def simple_nms(scores: torch.Tensor, nms_radius: int) -> torch.Tensor:
+ """Applies non-maximum suppression on scores"""
+ if nms_radius < 0:
+ raise ValueError("Expected positive values for nms_radius")
+
+ def max_pool(x):
+ return nn.functional.max_pool2d(x, kernel_size=nms_radius * 2 + 1, stride=1, padding=nms_radius)
+
+ zeros = torch.zeros_like(scores)
+ max_mask = scores == max_pool(scores)
+ for _ in range(2):
+ supp_mask = max_pool(max_mask.float()) > 0
+ supp_scores = torch.where(supp_mask, zeros, scores)
+ new_max_mask = supp_scores == max_pool(supp_scores)
+ max_mask = max_mask | (new_max_mask & (~supp_mask))
+ return torch.where(max_mask, scores, zeros)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for outputs of image point description models. Due to the nature of keypoint detection, the number of
+ keypoints is not fixed and can vary from image to image, which makes batching non-trivial. In the batch of images,
+ the maximum number of keypoints is set as the dimension of the keypoints, scores and descriptors tensors. The mask
+ tensor is used to indicate which values in the keypoints, scores and descriptors tensors are keypoint information
+ and which are padding.
+ """
+)
+class SuperPointKeypointDescriptionOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*):
+ Loss computed during training.
+ keypoints (`torch.FloatTensor` of shape `(batch_size, num_keypoints, 2)`):
+ Relative (x, y) coordinates of predicted keypoints in a given image.
+ scores (`torch.FloatTensor` of shape `(batch_size, num_keypoints)`):
+ Scores of predicted keypoints.
+ descriptors (`torch.FloatTensor` of shape `(batch_size, num_keypoints, descriptor_size)`):
+ Descriptors of predicted keypoints.
+ mask (`torch.BoolTensor` of shape `(batch_size, num_keypoints)`):
+ Mask indicating which values in keypoints, scores and descriptors are keypoint information.
+ hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or
+ when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, +
+ one for the output of each stage) of shape `(batch_size, sequence_length, hidden_size)`. Hidden-states
+ (also called feature maps) of the model at the output of each stage.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ keypoints: Optional[torch.IntTensor] = None
+ scores: Optional[torch.FloatTensor] = None
+ descriptors: Optional[torch.FloatTensor] = None
+ mask: Optional[torch.BoolTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+
+
+class SuperPointConvBlock(nn.Module):
+ def __init__(
+ self, config: SuperPointConfig, in_channels: int, out_channels: int, add_pooling: bool = False
+ ) -> None:
+ super().__init__()
+ self.conv_a = nn.Conv2d(
+ in_channels,
+ out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ )
+ self.conv_b = nn.Conv2d(
+ out_channels,
+ out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ )
+ self.relu = nn.ReLU(inplace=True)
+ self.pool = nn.MaxPool2d(kernel_size=2, stride=2) if add_pooling else None
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.relu(self.conv_a(hidden_states))
+ hidden_states = self.relu(self.conv_b(hidden_states))
+ if self.pool is not None:
+ hidden_states = self.pool(hidden_states)
+ return hidden_states
+
+
+class SuperPointEncoder(nn.Module):
+ """
+ SuperPoint encoder module. It is made of 4 convolutional layers with ReLU activation and max pooling, reducing the
+ dimensionality of the image.
+ """
+
+ def __init__(self, config: SuperPointConfig) -> None:
+ super().__init__()
+ # SuperPoint uses 1 channel images
+ self.input_dim = 1
+
+ conv_blocks = []
+ conv_blocks.append(
+ SuperPointConvBlock(config, self.input_dim, config.encoder_hidden_sizes[0], add_pooling=True)
+ )
+ for i in range(1, len(config.encoder_hidden_sizes) - 1):
+ conv_blocks.append(
+ SuperPointConvBlock(
+ config, config.encoder_hidden_sizes[i - 1], config.encoder_hidden_sizes[i], add_pooling=True
+ )
+ )
+ conv_blocks.append(
+ SuperPointConvBlock(
+ config, config.encoder_hidden_sizes[-2], config.encoder_hidden_sizes[-1], add_pooling=False
+ )
+ )
+ self.conv_blocks = nn.ModuleList(conv_blocks)
+
+ def forward(
+ self,
+ input,
+ output_hidden_states: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ ) -> Union[tuple, BaseModelOutputWithNoAttention]:
+ all_hidden_states = () if output_hidden_states else None
+
+ for conv_block in self.conv_blocks:
+ input = conv_block(input)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (input,)
+ output = input
+ if not return_dict:
+ return tuple(v for v in [output, all_hidden_states] if v is not None)
+
+ return BaseModelOutputWithNoAttention(
+ last_hidden_state=output,
+ hidden_states=all_hidden_states,
+ )
+
+
+class SuperPointInterestPointDecoder(nn.Module):
+ """
+ The SuperPointInterestPointDecoder uses the output of the SuperPointEncoder to compute the keypoint with scores.
+ The scores are first computed by a convolutional layer, then a softmax is applied to get a probability distribution
+ over the 65 possible keypoint classes. The keypoints are then extracted from the scores by thresholding and
+ non-maximum suppression. Post-processing is then applied to remove keypoints too close to the image borders as well
+ as to keep only the k keypoints with highest score.
+ """
+
+ def __init__(self, config: SuperPointConfig) -> None:
+ super().__init__()
+ self.keypoint_threshold = config.keypoint_threshold
+ self.max_keypoints = config.max_keypoints
+ self.nms_radius = config.nms_radius
+ self.border_removal_distance = config.border_removal_distance
+
+ self.relu = nn.ReLU(inplace=True)
+ self.pool = nn.MaxPool2d(kernel_size=2, stride=2)
+ self.conv_score_a = nn.Conv2d(
+ config.encoder_hidden_sizes[-1],
+ config.decoder_hidden_size,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ )
+ self.conv_score_b = nn.Conv2d(
+ config.decoder_hidden_size, config.keypoint_decoder_dim, kernel_size=1, stride=1, padding=0
+ )
+
+ def forward(self, encoded: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
+ scores = self._get_pixel_scores(encoded)
+ keypoints, scores = self._extract_keypoints(scores)
+
+ return keypoints, scores
+
+ def _get_pixel_scores(self, encoded: torch.Tensor) -> torch.Tensor:
+ """Based on the encoder output, compute the scores for each pixel of the image"""
+ scores = self.relu(self.conv_score_a(encoded))
+ scores = self.conv_score_b(scores)
+ scores = nn.functional.softmax(scores, 1)[:, :-1]
+ batch_size, _, height, width = scores.shape
+ scores = scores.permute(0, 2, 3, 1).reshape(batch_size, height, width, 8, 8)
+ scores = scores.permute(0, 1, 3, 2, 4).reshape(batch_size, height * 8, width * 8)
+ scores = simple_nms(scores, self.nms_radius)
+ return scores
+
+ def _extract_keypoints(self, scores: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
+ """
+ Based on their scores, extract the pixels that represent the keypoints that will be used for descriptors computation.
+ The keypoints are in the form of relative (x, y) coordinates.
+ """
+ _, height, width = scores.shape
+
+ # Threshold keypoints by score value
+ keypoints = torch.nonzero(scores[0] > self.keypoint_threshold)
+ scores = scores[0][tuple(keypoints.t())]
+
+ # Discard keypoints near the image borders
+ keypoints, scores = remove_keypoints_from_borders(
+ keypoints, scores, self.border_removal_distance, height * 8, width * 8
+ )
+
+ # Keep the k keypoints with highest score
+ if self.max_keypoints >= 0:
+ keypoints, scores = top_k_keypoints(keypoints, scores, self.max_keypoints)
+
+ # Convert (y, x) to (x, y)
+ keypoints = torch.flip(keypoints, [1]).to(scores.dtype)
+
+ return keypoints, scores
+
+
+class SuperPointDescriptorDecoder(nn.Module):
+ """
+ The SuperPointDescriptorDecoder uses the outputs of both the SuperPointEncoder and the
+ SuperPointInterestPointDecoder to compute the descriptors at the keypoints locations.
+
+ The descriptors are first computed by a convolutional layer, then normalized to have a norm of 1. The descriptors
+ are then interpolated at the keypoints locations.
+ """
+
+ def __init__(self, config: SuperPointConfig) -> None:
+ super().__init__()
+
+ self.relu = nn.ReLU(inplace=True)
+ self.pool = nn.MaxPool2d(kernel_size=2, stride=2)
+ self.conv_descriptor_a = nn.Conv2d(
+ config.encoder_hidden_sizes[-1],
+ config.decoder_hidden_size,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ )
+ self.conv_descriptor_b = nn.Conv2d(
+ config.decoder_hidden_size,
+ config.descriptor_decoder_dim,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ )
+
+ def forward(self, encoded: torch.Tensor, keypoints: torch.Tensor) -> torch.Tensor:
+ """Based on the encoder output and the keypoints, compute the descriptors for each keypoint"""
+ descriptors = self.conv_descriptor_b(self.relu(self.conv_descriptor_a(encoded)))
+ descriptors = nn.functional.normalize(descriptors, p=2, dim=1)
+
+ descriptors = self._sample_descriptors(keypoints[None], descriptors[0][None], 8)[0]
+
+ # [descriptor_dim, num_keypoints] -> [num_keypoints, descriptor_dim]
+ descriptors = torch.transpose(descriptors, 0, 1)
+
+ return descriptors
+
+ @staticmethod
+ def _sample_descriptors(keypoints, descriptors, scale: int = 8) -> torch.Tensor:
+ """Interpolate descriptors at keypoint locations"""
+ batch_size, num_channels, height, width = descriptors.shape
+ keypoints = keypoints - scale / 2 + 0.5
+ divisor = torch.tensor([[(width * scale - scale / 2 - 0.5), (height * scale - scale / 2 - 0.5)]])
+ divisor = divisor.to(keypoints)
+ keypoints /= divisor
+ keypoints = keypoints * 2 - 1 # normalize to (-1, 1)
+ kwargs = {"align_corners": True}
+ # [batch_size, num_channels, num_keypoints, 2] -> [batch_size, num_channels, num_keypoints, 2]
+ keypoints = keypoints.view(batch_size, 1, -1, 2)
+ descriptors = nn.functional.grid_sample(descriptors, keypoints, mode="bilinear", **kwargs)
+ # [batch_size, descriptor_decoder_dim, num_channels, num_keypoints] -> [batch_size, descriptor_decoder_dim, num_keypoints]
+ descriptors = descriptors.reshape(batch_size, num_channels, -1)
+ descriptors = nn.functional.normalize(descriptors, p=2, dim=1)
+ return descriptors
+
+
+@auto_docstring
+class SuperPointPreTrainedModel(PreTrainedModel):
+ config: SuperPointConfig
+ base_model_prefix = "superpoint"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = False
+
+ def _init_weights(self, module: Union[nn.Linear, nn.Conv2d, nn.LayerNorm]) -> None:
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+ def extract_one_channel_pixel_values(self, pixel_values: torch.FloatTensor) -> torch.FloatTensor:
+ """
+ Assuming pixel_values has shape (batch_size, 3, height, width), and that all channels values are the same,
+ extract the first channel value to get a tensor of shape (batch_size, 1, height, width) for SuperPoint. This is
+ a workaround for the issue discussed in :
+ https://github.com/huggingface/transformers/pull/25786#issuecomment-1730176446
+
+ Args:
+ pixel_values: torch.FloatTensor of shape (batch_size, 3, height, width)
+
+ Returns:
+ pixel_values: torch.FloatTensor of shape (batch_size, 1, height, width)
+
+ """
+ return pixel_values[:, 0, :, :][:, None, :, :]
+
+
+@auto_docstring(
+ custom_intro="""
+ SuperPoint model outputting keypoints and descriptors.
+ """
+)
+class SuperPointForKeypointDetection(SuperPointPreTrainedModel):
+ """
+ SuperPoint model. It consists of a SuperPointEncoder, a SuperPointInterestPointDecoder and a
+ SuperPointDescriptorDecoder. SuperPoint was proposed in `SuperPoint: Self-Supervised Interest Point Detection and
+ Description `__ by Daniel DeTone, Tomasz Malisiewicz, and Andrew Rabinovich. It
+ is a fully convolutional neural network that extracts keypoints and descriptors from an image. It is trained in a
+ self-supervised manner, using a combination of a photometric loss and a loss based on the homographic adaptation of
+ keypoints. It is made of a convolutional encoder and two decoders: one for keypoints and one for descriptors.
+ """
+
+ def __init__(self, config: SuperPointConfig) -> None:
+ super().__init__(config)
+
+ self.config = config
+
+ self.encoder = SuperPointEncoder(config)
+ self.keypoint_decoder = SuperPointInterestPointDecoder(config)
+ self.descriptor_decoder = SuperPointDescriptorDecoder(config)
+
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ labels: Optional[torch.LongTensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SuperPointKeypointDescriptionOutput]:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+ >>> model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+
+ >>> inputs = processor(image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ ```"""
+ loss = None
+ if labels is not None:
+ raise ValueError("SuperPoint does not support training for now.")
+
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ pixel_values = self.extract_one_channel_pixel_values(pixel_values)
+
+ batch_size, _, height, width = pixel_values.shape
+
+ encoder_outputs = self.encoder(
+ pixel_values,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_state = encoder_outputs[0]
+
+ list_keypoints_scores = [
+ self.keypoint_decoder(last_hidden_state[None, ...]) for last_hidden_state in last_hidden_state
+ ]
+
+ list_keypoints = [keypoints_scores[0] for keypoints_scores in list_keypoints_scores]
+ list_scores = [keypoints_scores[1] for keypoints_scores in list_keypoints_scores]
+
+ list_descriptors = [
+ self.descriptor_decoder(last_hidden_state[None, ...], keypoints[None, ...])
+ for last_hidden_state, keypoints in zip(last_hidden_state, list_keypoints)
+ ]
+
+ maximum_num_keypoints = max(keypoints.shape[0] for keypoints in list_keypoints)
+
+ keypoints = torch.zeros((batch_size, maximum_num_keypoints, 2), device=pixel_values.device)
+ scores = torch.zeros((batch_size, maximum_num_keypoints), device=pixel_values.device)
+ descriptors = torch.zeros(
+ (batch_size, maximum_num_keypoints, self.config.descriptor_decoder_dim),
+ device=pixel_values.device,
+ )
+ mask = torch.zeros((batch_size, maximum_num_keypoints), device=pixel_values.device, dtype=torch.int)
+
+ for i, (_keypoints, _scores, _descriptors) in enumerate(zip(list_keypoints, list_scores, list_descriptors)):
+ keypoints[i, : _keypoints.shape[0]] = _keypoints
+ scores[i, : _scores.shape[0]] = _scores
+ descriptors[i, : _descriptors.shape[0]] = _descriptors
+ mask[i, : _scores.shape[0]] = 1
+
+ # Convert to relative coordinates
+ keypoints = keypoints / torch.tensor([width, height], device=keypoints.device)
+
+ hidden_states = encoder_outputs[1] if output_hidden_states else None
+ if not return_dict:
+ return tuple(v for v in [loss, keypoints, scores, descriptors, mask, hidden_states] if v is not None)
+
+ return SuperPointKeypointDescriptionOutput(
+ loss=loss,
+ keypoints=keypoints,
+ scores=scores,
+ descriptors=descriptors,
+ mask=mask,
+ hidden_states=hidden_states,
+ )
+
+
+__all__ = ["SuperPointForKeypointDetection", "SuperPointPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..370f6c71fadb5dad5ccae5609ea384700dbd97b9
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_swiftformer import *
+ from .modeling_swiftformer import *
+ from .modeling_tf_swiftformer import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/configuration_swiftformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/configuration_swiftformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..c0b4428a4322fcf930bcf772e2e2194b2b4a82f1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/configuration_swiftformer.py
@@ -0,0 +1,148 @@
+# coding=utf-8
+# Copyright 2023 MBZUAI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""SwiftFormer model configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from packaging import version
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class SwiftFormerConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SwiftFormerModel`]. It is used to instantiate an
+ SwiftFormer model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the SwiftFormer
+ [MBZUAI/swiftformer-xs](https://huggingface.co/MBZUAI/swiftformer-xs) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels
+ depths (`list[int]`, *optional*, defaults to `[3, 3, 6, 4]`):
+ Depth of each stage
+ embed_dims (`list[int]`, *optional*, defaults to `[48, 56, 112, 220]`):
+ The embedding dimension at each stage
+ mlp_ratio (`int`, *optional*, defaults to 4):
+ Ratio of size of the hidden dimensionality of an MLP to the dimensionality of its input.
+ downsamples (`list[bool]`, *optional*, defaults to `[True, True, True, True]`):
+ Whether or not to downsample inputs between two stages.
+ hidden_act (`str`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (string). `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ down_patch_size (`int`, *optional*, defaults to 3):
+ The size of patches in downsampling layers.
+ down_stride (`int`, *optional*, defaults to 2):
+ The stride of convolution kernels in downsampling layers.
+ down_pad (`int`, *optional*, defaults to 1):
+ Padding in downsampling layers.
+ drop_path_rate (`float`, *optional*, defaults to 0.0):
+ Rate at which to increase dropout probability in DropPath.
+ drop_mlp_rate (`float`, *optional*, defaults to 0.0):
+ Dropout rate for the MLP component of SwiftFormer.
+ drop_conv_encoder_rate (`float`, *optional*, defaults to 0.0):
+ Dropout rate for the ConvEncoder component of SwiftFormer.
+ use_layer_scale (`bool`, *optional*, defaults to `True`):
+ Whether to scale outputs from token mixers.
+ layer_scale_init_value (`float`, *optional*, defaults to 1e-05):
+ Factor by which outputs from token mixers are scaled.
+ batch_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the batch normalization layers.
+
+
+ Example:
+
+ ```python
+ >>> from transformers import SwiftFormerConfig, SwiftFormerModel
+
+ >>> # Initializing a SwiftFormer swiftformer-base-patch16-224 style configuration
+ >>> configuration = SwiftFormerConfig()
+
+ >>> # Initializing a model (with random weights) from the swiftformer-base-patch16-224 style configuration
+ >>> model = SwiftFormerModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "swiftformer"
+
+ def __init__(
+ self,
+ image_size=224,
+ num_channels=3,
+ depths=[3, 3, 6, 4],
+ embed_dims=[48, 56, 112, 220],
+ mlp_ratio=4,
+ downsamples=[True, True, True, True],
+ hidden_act="gelu",
+ down_patch_size=3,
+ down_stride=2,
+ down_pad=1,
+ drop_path_rate=0.0,
+ drop_mlp_rate=0.0,
+ drop_conv_encoder_rate=0.0,
+ use_layer_scale=True,
+ layer_scale_init_value=1e-5,
+ batch_norm_eps=1e-5,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.image_size = image_size
+ self.num_channels = num_channels
+ self.depths = depths
+ self.embed_dims = embed_dims
+ self.mlp_ratio = mlp_ratio
+ self.downsamples = downsamples
+ self.hidden_act = hidden_act
+ self.down_patch_size = down_patch_size
+ self.down_stride = down_stride
+ self.down_pad = down_pad
+ self.drop_path_rate = drop_path_rate
+ self.drop_mlp_rate = drop_mlp_rate
+ self.drop_conv_encoder_rate = drop_conv_encoder_rate
+ self.use_layer_scale = use_layer_scale
+ self.layer_scale_init_value = layer_scale_init_value
+ self.batch_norm_eps = batch_norm_eps
+
+
+class SwiftFormerOnnxConfig(OnnxConfig):
+ torch_onnx_minimum_version = version.parse("1.11")
+
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ return OrderedDict(
+ [
+ ("pixel_values", {0: "batch", 1: "num_channels", 2: "height", 3: "width"}),
+ ]
+ )
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 1e-4
+
+
+__all__ = ["SwiftFormerConfig", "SwiftFormerOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/modeling_swiftformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/modeling_swiftformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..4b6fac00a0240fecf59c10f0175f2255552079d3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/modeling_swiftformer.py
@@ -0,0 +1,544 @@
+# coding=utf-8
+# Copyright 2023 MBZUAI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch SwiftFormer model."""
+
+import collections.abc
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2CLS
+from ...modeling_outputs import BaseModelOutputWithNoAttention, ImageClassifierOutputWithNoAttention
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from .configuration_swiftformer import SwiftFormerConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class SwiftFormerPatchEmbedding(nn.Module):
+ """
+ Patch Embedding Layer constructed of two 2D convolutional layers.
+
+ Input: tensor of shape `[batch_size, in_channels, height, width]`
+
+ Output: tensor of shape `[batch_size, out_channels, height/4, width/4]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig):
+ super().__init__()
+
+ in_chs = config.num_channels
+ out_chs = config.embed_dims[0]
+ self.patch_embedding = nn.Sequential(
+ nn.Conv2d(in_chs, out_chs // 2, kernel_size=3, stride=2, padding=1),
+ nn.BatchNorm2d(out_chs // 2, eps=config.batch_norm_eps),
+ nn.ReLU(),
+ nn.Conv2d(out_chs // 2, out_chs, kernel_size=3, stride=2, padding=1),
+ nn.BatchNorm2d(out_chs, eps=config.batch_norm_eps),
+ nn.ReLU(),
+ )
+
+ def forward(self, x):
+ return self.patch_embedding(x)
+
+
+# Copied from transformers.models.beit.modeling_beit.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+class SwiftFormerDropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, config: SwiftFormerConfig) -> None:
+ super().__init__()
+ self.drop_prob = config.drop_path_rate
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+class SwiftFormerEmbeddings(nn.Module):
+ """
+ Embeddings layer consisting of a single 2D convolutional and batch normalization layer.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height/stride, width/stride]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, index: int):
+ super().__init__()
+
+ patch_size = config.down_patch_size
+ stride = config.down_stride
+ padding = config.down_pad
+ embed_dims = config.embed_dims
+
+ in_chans = embed_dims[index]
+ embed_dim = embed_dims[index + 1]
+
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ stride = stride if isinstance(stride, collections.abc.Iterable) else (stride, stride)
+ padding = padding if isinstance(padding, collections.abc.Iterable) else (padding, padding)
+
+ self.proj = nn.Conv2d(in_chans, embed_dim, kernel_size=patch_size, stride=stride, padding=padding)
+ self.norm = nn.BatchNorm2d(embed_dim, eps=config.batch_norm_eps)
+
+ def forward(self, x):
+ x = self.proj(x)
+ x = self.norm(x)
+ return x
+
+
+class SwiftFormerConvEncoder(nn.Module):
+ """
+ `SwiftFormerConvEncoder` with 3*3 and 1*1 convolutions.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int):
+ super().__init__()
+ hidden_dim = int(config.mlp_ratio * dim)
+
+ self.depth_wise_conv = nn.Conv2d(dim, dim, kernel_size=3, padding=1, groups=dim)
+ self.norm = nn.BatchNorm2d(dim, eps=config.batch_norm_eps)
+ self.point_wise_conv1 = nn.Conv2d(dim, hidden_dim, kernel_size=1)
+ self.act = nn.GELU()
+ self.point_wise_conv2 = nn.Conv2d(hidden_dim, dim, kernel_size=1)
+ self.drop_path = nn.Dropout(p=config.drop_conv_encoder_rate)
+ self.layer_scale = nn.Parameter(torch.ones(dim).unsqueeze(-1).unsqueeze(-1), requires_grad=True)
+
+ def forward(self, x):
+ input = x
+ x = self.depth_wise_conv(x)
+ x = self.norm(x)
+ x = self.point_wise_conv1(x)
+ x = self.act(x)
+ x = self.point_wise_conv2(x)
+ x = input + self.drop_path(self.layer_scale * x)
+ return x
+
+
+class SwiftFormerMlp(nn.Module):
+ """
+ MLP layer with 1*1 convolutions.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, in_features: int):
+ super().__init__()
+ hidden_features = int(in_features * config.mlp_ratio)
+ self.norm1 = nn.BatchNorm2d(in_features, eps=config.batch_norm_eps)
+ self.fc1 = nn.Conv2d(in_features, hidden_features, 1)
+ act_layer = ACT2CLS[config.hidden_act]
+ self.act = act_layer()
+ self.fc2 = nn.Conv2d(hidden_features, in_features, 1)
+ self.drop = nn.Dropout(p=config.drop_mlp_rate)
+
+ def forward(self, x):
+ x = self.norm1(x)
+ x = self.fc1(x)
+ x = self.act(x)
+ x = self.drop(x)
+ x = self.fc2(x)
+ x = self.drop(x)
+ return x
+
+
+class SwiftFormerEfficientAdditiveAttention(nn.Module):
+ """
+ Efficient Additive Attention module for SwiftFormer.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int = 512):
+ super().__init__()
+
+ self.to_query = nn.Linear(dim, dim)
+ self.to_key = nn.Linear(dim, dim)
+
+ self.w_g = nn.Parameter(torch.randn(dim, 1))
+ self.scale_factor = dim**-0.5
+ self.proj = nn.Linear(dim, dim)
+ self.final = nn.Linear(dim, dim)
+
+ def forward(self, x):
+ query = self.to_query(x)
+ key = self.to_key(x)
+
+ query = torch.nn.functional.normalize(query, dim=-1)
+ key = torch.nn.functional.normalize(key, dim=-1)
+
+ query_weight = query @ self.w_g
+ scaled_query_weight = query_weight * self.scale_factor
+ scaled_query_weight = scaled_query_weight.softmax(dim=-1)
+
+ global_queries = torch.sum(scaled_query_weight * query, dim=1)
+ global_queries = global_queries.unsqueeze(1).repeat(1, key.shape[1], 1)
+
+ out = self.proj(global_queries * key) + query
+ out = self.final(out)
+
+ return out
+
+
+class SwiftFormerLocalRepresentation(nn.Module):
+ """
+ Local Representation module for SwiftFormer that is implemented by 3*3 depth-wise and point-wise convolutions.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int):
+ super().__init__()
+
+ self.depth_wise_conv = nn.Conv2d(dim, dim, kernel_size=3, padding=1, groups=dim)
+ self.norm = nn.BatchNorm2d(dim, eps=config.batch_norm_eps)
+ self.point_wise_conv1 = nn.Conv2d(dim, dim, kernel_size=1)
+ self.act = nn.GELU()
+ self.point_wise_conv2 = nn.Conv2d(dim, dim, kernel_size=1)
+ self.drop_path = nn.Identity()
+ self.layer_scale = nn.Parameter(torch.ones(dim).unsqueeze(-1).unsqueeze(-1), requires_grad=True)
+
+ def forward(self, x):
+ input = x
+ x = self.depth_wise_conv(x)
+ x = self.norm(x)
+ x = self.point_wise_conv1(x)
+ x = self.act(x)
+ x = self.point_wise_conv2(x)
+ x = input + self.drop_path(self.layer_scale * x)
+ return x
+
+
+class SwiftFormerEncoderBlock(nn.Module):
+ """
+ SwiftFormer Encoder Block for SwiftFormer. It consists of (1) Local representation module, (2)
+ SwiftFormerEfficientAdditiveAttention, and (3) MLP block.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels,height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int, drop_path: float = 0.0) -> None:
+ super().__init__()
+
+ layer_scale_init_value = config.layer_scale_init_value
+ use_layer_scale = config.use_layer_scale
+
+ self.local_representation = SwiftFormerLocalRepresentation(config, dim=dim)
+ self.attn = SwiftFormerEfficientAdditiveAttention(config, dim=dim)
+ self.linear = SwiftFormerMlp(config, in_features=dim)
+ self.drop_path = SwiftFormerDropPath(config) if drop_path > 0.0 else nn.Identity()
+ self.use_layer_scale = use_layer_scale
+ if use_layer_scale:
+ self.layer_scale_1 = nn.Parameter(
+ layer_scale_init_value * torch.ones(dim).unsqueeze(-1).unsqueeze(-1), requires_grad=True
+ )
+ self.layer_scale_2 = nn.Parameter(
+ layer_scale_init_value * torch.ones(dim).unsqueeze(-1).unsqueeze(-1), requires_grad=True
+ )
+
+ def forward(self, x):
+ x = self.local_representation(x)
+ batch_size, channels, height, width = x.shape
+ res = self.attn(x.permute(0, 2, 3, 1).reshape(batch_size, height * width, channels))
+ res = res.reshape(batch_size, height, width, channels).permute(0, 3, 1, 2)
+ if self.use_layer_scale:
+ x = x + self.drop_path(self.layer_scale_1 * res)
+ x = x + self.drop_path(self.layer_scale_2 * self.linear(x))
+ else:
+ x = x + self.drop_path(res)
+ x = x + self.drop_path(self.linear(x))
+ return x
+
+
+class SwiftFormerStage(nn.Module):
+ """
+ A Swiftformer stage consisting of a series of `SwiftFormerConvEncoder` blocks and a final
+ `SwiftFormerEncoderBlock`.
+
+ Input: tensor in shape `[batch_size, channels, height, width]`
+
+ Output: tensor in shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, index: int) -> None:
+ super().__init__()
+
+ layer_depths = config.depths
+ dim = config.embed_dims[index]
+ depth = layer_depths[index]
+
+ blocks = []
+ for block_idx in range(depth):
+ block_dpr = config.drop_path_rate * (block_idx + sum(layer_depths[:index])) / (sum(layer_depths) - 1)
+
+ if depth - block_idx <= 1:
+ blocks.append(SwiftFormerEncoderBlock(config, dim=dim, drop_path=block_dpr))
+ else:
+ blocks.append(SwiftFormerConvEncoder(config, dim=dim))
+
+ self.blocks = nn.ModuleList(blocks)
+
+ def forward(self, input):
+ for block in self.blocks:
+ input = block(input)
+ return input
+
+
+class SwiftFormerEncoder(nn.Module):
+ def __init__(self, config: SwiftFormerConfig) -> None:
+ super().__init__()
+ self.config = config
+
+ embed_dims = config.embed_dims
+ downsamples = config.downsamples
+ layer_depths = config.depths
+
+ # Transformer model
+ network = []
+ for i in range(len(layer_depths)):
+ stage = SwiftFormerStage(config=config, index=i)
+ network.append(stage)
+ if i >= len(layer_depths) - 1:
+ break
+ if downsamples[i] or embed_dims[i] != embed_dims[i + 1]:
+ # downsampling between two stages
+ network.append(SwiftFormerEmbeddings(config, index=i))
+ self.network = nn.ModuleList(network)
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithNoAttention]:
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ all_hidden_states = (hidden_states,) if output_hidden_states else None
+
+ for block in self.network:
+ hidden_states = block(hidden_states)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states] if v is not None)
+
+ return BaseModelOutputWithNoAttention(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ )
+
+
+@auto_docstring
+class SwiftFormerPreTrainedModel(PreTrainedModel):
+ config: SwiftFormerConfig
+ base_model_prefix = "swiftformer"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["SwiftFormerEncoderBlock"]
+
+ def _init_weights(self, module: nn.Module) -> None:
+ """Initialize the weights"""
+ if isinstance(module, (nn.Conv2d, nn.Linear)):
+ nn.init.trunc_normal_(module.weight, std=0.02)
+ if module.bias is not None:
+ nn.init.constant_(module.bias, 0)
+ elif isinstance(module, (nn.LayerNorm, nn.BatchNorm2d)):
+ nn.init.constant_(module.bias, 0)
+ nn.init.constant_(module.weight, 1.0)
+ elif isinstance(module, (SwiftFormerConvEncoder, SwiftFormerLocalRepresentation)):
+ module.layer_scale.data.fill_(1.0)
+ elif isinstance(module, SwiftFormerEncoderBlock):
+ if self.config.use_layer_scale:
+ module.layer_scale_1.data.fill_(self.config.layer_scale_init_value)
+ module.layer_scale_2.data.fill_(self.config.layer_scale_init_value)
+ elif isinstance(module, SwiftFormerEfficientAdditiveAttention):
+ nn.init.normal_(module.w_g)
+
+
+@auto_docstring
+class SwiftFormerModel(SwiftFormerPreTrainedModel):
+ def __init__(self, config: SwiftFormerConfig):
+ super().__init__(config)
+ self.config = config
+
+ self.patch_embed = SwiftFormerPatchEmbedding(config)
+ self.encoder = SwiftFormerEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithNoAttention]:
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ embedding_output = self.patch_embed(pixel_values)
+ encoder_outputs = self.encoder(
+ embedding_output,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if not return_dict:
+ return tuple(v for v in encoder_outputs if v is not None)
+
+ return BaseModelOutputWithNoAttention(
+ last_hidden_state=encoder_outputs.last_hidden_state,
+ hidden_states=encoder_outputs.hidden_states,
+ )
+
+
+@auto_docstring
+class SwiftFormerForImageClassification(SwiftFormerPreTrainedModel):
+ def __init__(self, config: SwiftFormerConfig) -> None:
+ super().__init__(config)
+
+ embed_dims = config.embed_dims
+
+ self.num_labels = config.num_labels
+ self.swiftformer = SwiftFormerModel(config)
+
+ # Classifier head
+ self.norm = nn.BatchNorm2d(embed_dims[-1], eps=config.batch_norm_eps)
+ self.head = nn.Linear(embed_dims[-1], self.num_labels) if self.num_labels > 0 else nn.Identity()
+ self.dist_head = nn.Linear(embed_dims[-1], self.num_labels) if self.num_labels > 0 else nn.Identity()
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, ImageClassifierOutputWithNoAttention]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # run base model
+ outputs = self.swiftformer(
+ pixel_values,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs.last_hidden_state if return_dict else outputs[0]
+
+ # run classification head
+ sequence_output = self.norm(sequence_output)
+ sequence_output = sequence_output.flatten(2).mean(-1)
+ cls_out = self.head(sequence_output)
+ distillation_out = self.dist_head(sequence_output)
+ logits = (cls_out + distillation_out) / 2
+
+ # calculate loss
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return ImageClassifierOutputWithNoAttention(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ )
+
+
+__all__ = ["SwiftFormerForImageClassification", "SwiftFormerModel", "SwiftFormerPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/modeling_tf_swiftformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/modeling_tf_swiftformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..612c2406a1d03cf5cf473a6964a1cd7c0f50a663
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swiftformer/modeling_tf_swiftformer.py
@@ -0,0 +1,866 @@
+# coding=utf-8
+# Copyright 2024 MBZUAI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TensorFlow SwiftFormer model."""
+
+import collections.abc
+from typing import Optional, Union
+
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_outputs import (
+ TFBaseModelOutputWithNoAttention,
+ TFImageClassifierOutputWithNoAttention,
+)
+from ...modeling_tf_utils import TFPreTrainedModel, keras, keras_serializable, unpack_inputs
+from ...utils import (
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+)
+from .configuration_swiftformer import SwiftFormerConfig
+
+
+logger = logging.get_logger(__name__)
+
+# General docstring
+_CONFIG_FOR_DOC = "SwiftFormerConfig"
+
+# Base docstring
+_CHECKPOINT_FOR_DOC = "MBZUAI/swiftformer-xs"
+_EXPECTED_OUTPUT_SHAPE = [1, 220, 7, 7]
+
+# Image classification docstring
+_IMAGE_CLASS_CHECKPOINT = "MBZUAI/swiftformer-xs"
+_IMAGE_CLASS_EXPECTED_OUTPUT = "tabby, tabby cat"
+
+
+class TFSwiftFormerPatchEmbeddingSequential(keras.layers.Layer):
+ """
+ The sequential component of the patch embedding layer.
+
+ Input: tensor of shape `[batch_size, in_channels, height, width]`
+
+ Output: tensor of shape `[batch_size, out_channels, height/4, width/4]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.out_chs = config.embed_dims[0]
+
+ self.zero_padding = keras.layers.ZeroPadding2D(padding=(1, 1))
+ self.conv1 = keras.layers.Conv2D(self.out_chs // 2, kernel_size=3, strides=2, name="0")
+ self.batch_norm1 = keras.layers.BatchNormalization(epsilon=config.batch_norm_eps, momentum=0.9, name="1")
+ self.conv2 = keras.layers.Conv2D(self.out_chs, kernel_size=3, strides=2, name="3")
+ self.batch_norm2 = keras.layers.BatchNormalization(epsilon=config.batch_norm_eps, momentum=0.9, name="4")
+ self.config = config
+
+ def call(self, x: tf.Tensor, training: bool = False) -> tf.Tensor:
+ x = self.zero_padding(x)
+ x = self.conv1(x)
+ x = self.batch_norm1(x, training=training)
+ x = get_tf_activation("relu")(x)
+ x = self.zero_padding(x)
+ x = self.conv2(x)
+ x = self.batch_norm2(x, training=training)
+ x = get_tf_activation("relu")(x)
+ return x
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ if getattr(self, "conv1", None) is not None:
+ with tf.name_scope(self.conv1.name):
+ self.conv1.build(self.config.num_channels)
+ if getattr(self, "batch_norm1", None) is not None:
+ with tf.name_scope(self.batch_norm1.name):
+ self.batch_norm1.build((None, None, None, self.out_chs // 2))
+ if getattr(self, "conv2", None) is not None:
+ with tf.name_scope(self.conv2.name):
+ self.conv2.build((None, None, None, self.out_chs // 2))
+ if getattr(self, "batch_norm2", None) is not None:
+ with tf.name_scope(self.batch_norm2.name):
+ self.batch_norm2.build((None, None, None, self.out_chs))
+ self.built = True
+
+
+class TFSwiftFormerPatchEmbedding(keras.layers.Layer):
+ """
+ Patch Embedding Layer constructed of two 2D convolutional layers.
+
+ Input: tensor of shape `[batch_size, in_channels, height, width]`
+
+ Output: tensor of shape `[batch_size, out_channels, height/4, width/4]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.patch_embedding = TFSwiftFormerPatchEmbeddingSequential(config, name="patch_embedding")
+
+ def call(self, x: tf.Tensor, training: bool = False) -> tf.Tensor:
+ return self.patch_embedding(x, training=training)
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ if getattr(self, "patch_embedding", None) is not None:
+ with tf.name_scope(self.patch_embedding.name):
+ self.patch_embedding.build(None)
+ self.built = True
+
+
+class TFSwiftFormerDropPath(keras.layers.Layer):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, config: SwiftFormerConfig, **kwargs) -> None:
+ super().__init__(**kwargs)
+ raise NotImplementedError("Drop path is not implemented in TF port")
+
+ def call(self, hidden_states: tf.Tensor, training: bool = False) -> tf.Tensor:
+ raise NotImplementedError("Drop path is not implemented in TF port")
+
+
+class TFSwiftFormerEmbeddings(keras.layers.Layer):
+ """
+ Embeddings layer consisting of a single 2D convolutional and batch normalization layer.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height/stride, width/stride]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, index: int, **kwargs):
+ super().__init__(**kwargs)
+
+ patch_size = config.down_patch_size
+ stride = config.down_stride
+ padding = config.down_pad
+ embed_dims = config.embed_dims
+
+ self.in_chans = embed_dims[index]
+ self.embed_dim = embed_dims[index + 1]
+
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ stride = stride if isinstance(stride, collections.abc.Iterable) else (stride, stride)
+ padding = padding if isinstance(padding, collections.abc.Iterable) else (padding, padding)
+
+ self.pad = keras.layers.ZeroPadding2D(padding=padding)
+ self.proj = keras.layers.Conv2D(self.embed_dim, kernel_size=patch_size, strides=stride, name="proj")
+ self.norm = keras.layers.BatchNormalization(epsilon=config.batch_norm_eps, momentum=0.9, name="norm")
+
+ def call(self, x: tf.Tensor, training: bool = False) -> tf.Tensor:
+ x = self.pad(x)
+ x = self.proj(x)
+ x = self.norm(x, training=training)
+ return x
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ if getattr(self, "proj", None) is not None:
+ with tf.name_scope(self.proj.name):
+ self.proj.build(self.in_chans)
+ if getattr(self, "norm", None) is not None:
+ with tf.name_scope(self.norm.name):
+ self.norm.build((None, None, None, self.embed_dim))
+ self.built = True
+
+
+class TFSwiftFormerConvEncoder(keras.layers.Layer):
+ """
+ `SwiftFormerConvEncoder` with 3*3 and 1*1 convolutions.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int, **kwargs):
+ super().__init__(**kwargs)
+ hidden_dim = int(config.mlp_ratio * dim)
+
+ self.dim = dim
+ self.pad = keras.layers.ZeroPadding2D(padding=(1, 1))
+ self.depth_wise_conv = keras.layers.Conv2D(dim, kernel_size=3, groups=dim, name="depth_wise_conv")
+ self.norm = keras.layers.BatchNormalization(epsilon=config.batch_norm_eps, momentum=0.9, name="norm")
+ self.point_wise_conv1 = keras.layers.Conv2D(hidden_dim, kernel_size=1, name="point_wise_conv1")
+ self.act = get_tf_activation("gelu")
+ self.point_wise_conv2 = keras.layers.Conv2D(dim, kernel_size=1, name="point_wise_conv2")
+ self.drop_path = keras.layers.Dropout(name="drop_path", rate=config.drop_conv_encoder_rate)
+ self.hidden_dim = int(config.mlp_ratio * self.dim)
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.layer_scale = self.add_weight(
+ name="layer_scale",
+ shape=self.dim,
+ initializer="ones",
+ trainable=True,
+ )
+
+ if getattr(self, "depth_wise_conv", None) is not None:
+ with tf.name_scope(self.depth_wise_conv.name):
+ self.depth_wise_conv.build(self.dim)
+ if getattr(self, "norm", None) is not None:
+ with tf.name_scope(self.norm.name):
+ self.norm.build((None, None, None, self.dim))
+ if getattr(self, "point_wise_conv1", None) is not None:
+ with tf.name_scope(self.point_wise_conv1.name):
+ self.point_wise_conv1.build(self.dim)
+ if getattr(self, "point_wise_conv2", None) is not None:
+ with tf.name_scope(self.point_wise_conv2.name):
+ self.point_wise_conv2.build(self.hidden_dim)
+ if getattr(self, "drop_path", None) is not None:
+ with tf.name_scope(self.drop_path.name):
+ self.drop_path.build(None)
+ self.built = True
+
+ def call(self, x: tf.Tensor, training: bool = False) -> tf.Tensor:
+ input = x
+ x = self.pad(x)
+ x = self.depth_wise_conv(x)
+ x = self.norm(x, training=training)
+ x = self.point_wise_conv1(x)
+ x = self.act(x)
+ x = self.point_wise_conv2(x)
+ x = input + self.drop_path(self.layer_scale * x)
+ return x
+
+
+class TFSwiftFormerMlp(keras.layers.Layer):
+ """
+ MLP layer with 1*1 convolutions.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, in_features: int, **kwargs):
+ super().__init__(**kwargs)
+
+ hidden_features = int(in_features * config.mlp_ratio)
+ self.norm1 = keras.layers.BatchNormalization(epsilon=config.batch_norm_eps, momentum=0.9, name="norm1")
+ self.fc1 = keras.layers.Conv2D(hidden_features, 1, name="fc1")
+ act_layer = get_tf_activation(config.hidden_act)
+ self.act = act_layer
+ self.fc2 = keras.layers.Conv2D(in_features, 1, name="fc2")
+ self.drop = keras.layers.Dropout(rate=config.drop_mlp_rate)
+ self.hidden_features = hidden_features
+ self.in_features = in_features
+
+ def call(self, x: tf.Tensor, training: bool = False) -> tf.Tensor:
+ x = self.norm1(x, training=training)
+ x = self.fc1(x)
+ x = self.act(x)
+ x = self.drop(x, training=training)
+ x = self.fc2(x)
+ x = self.drop(x, training=training)
+ return x
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ if getattr(self, "norm1", None) is not None:
+ with tf.name_scope(self.norm1.name):
+ self.norm1.build((None, None, None, self.in_features))
+ if getattr(self, "fc1", None) is not None:
+ with tf.name_scope(self.fc1.name):
+ self.fc1.build((None, None, None, self.in_features))
+ if getattr(self, "fc2", None) is not None:
+ with tf.name_scope(self.fc2.name):
+ self.fc2.build((None, None, None, self.hidden_features))
+ self.built = True
+
+
+class TFSwiftFormerEfficientAdditiveAttention(keras.layers.Layer):
+ """
+ Efficient Additive Attention module for SwiftFormer.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int = 512, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dim = dim
+
+ self.to_query = keras.layers.Dense(dim, name="to_query")
+ self.to_key = keras.layers.Dense(dim, name="to_key")
+
+ self.scale_factor = dim**-0.5
+ self.proj = keras.layers.Dense(dim, name="proj")
+ self.final = keras.layers.Dense(dim, name="final")
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.w_g = self.add_weight(
+ name="w_g",
+ shape=(self.dim, 1),
+ initializer=keras.initializers.RandomNormal(mean=0, stddev=1),
+ trainable=True,
+ )
+
+ if getattr(self, "to_query", None) is not None:
+ with tf.name_scope(self.to_query.name):
+ self.to_query.build(self.dim)
+ if getattr(self, "to_key", None) is not None:
+ with tf.name_scope(self.to_key.name):
+ self.to_key.build(self.dim)
+ if getattr(self, "proj", None) is not None:
+ with tf.name_scope(self.proj.name):
+ self.proj.build(self.dim)
+ if getattr(self, "final", None) is not None:
+ with tf.name_scope(self.final.name):
+ self.final.build(self.dim)
+ self.built = True
+
+ def call(self, x: tf.Tensor) -> tf.Tensor:
+ query = self.to_query(x)
+ key = self.to_key(x)
+
+ query = tf.math.l2_normalize(query, dim=-1)
+ key = tf.math.l2_normalize(key, dim=-1)
+
+ query_weight = query @ self.w_g
+ scaled_query_weight = query_weight * self.scale_factor
+ scaled_query_weight = tf.nn.softmax(scaled_query_weight, axis=-1)
+
+ global_queries = tf.math.reduce_sum(scaled_query_weight * query, axis=1)
+ global_queries = tf.tile(tf.expand_dims(global_queries, 1), (1, key.shape[1], 1))
+
+ out = self.proj(global_queries * key) + query
+ out = self.final(out)
+
+ return out
+
+
+class TFSwiftFormerLocalRepresentation(keras.layers.Layer):
+ """
+ Local Representation module for SwiftFormer that is implemented by 3*3 depth-wise and point-wise convolutions.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dim = dim
+
+ self.pad = keras.layers.ZeroPadding2D(padding=(1, 1))
+ self.depth_wise_conv = keras.layers.Conv2D(dim, kernel_size=3, groups=dim, name="depth_wise_conv")
+ self.norm = keras.layers.BatchNormalization(epsilon=config.batch_norm_eps, momentum=0.9, name="norm")
+ self.point_wise_conv1 = keras.layers.Conv2D(dim, kernel_size=1, name="point_wise_conv1")
+ self.act = get_tf_activation("gelu")
+ self.point_wise_conv2 = keras.layers.Conv2D(dim, kernel_size=1, name="point_wise_conv2")
+ self.drop_path = keras.layers.Identity(name="drop_path")
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.layer_scale = self.add_weight(
+ name="layer_scale",
+ shape=(self.dim),
+ initializer="ones",
+ trainable=True,
+ )
+ if getattr(self, "depth_wise_conv", None) is not None:
+ with tf.name_scope(self.depth_wise_conv.name):
+ self.depth_wise_conv.build((None, None, None, self.dim))
+ if getattr(self, "norm", None) is not None:
+ with tf.name_scope(self.norm.name):
+ self.norm.build((None, None, None, self.dim))
+ if getattr(self, "point_wise_conv1", None) is not None:
+ with tf.name_scope(self.point_wise_conv1.name):
+ self.point_wise_conv1.build(self.dim)
+ if getattr(self, "point_wise_conv2", None) is not None:
+ with tf.name_scope(self.point_wise_conv2.name):
+ self.point_wise_conv2.build(self.dim)
+ if getattr(self, "drop_path", None) is not None:
+ with tf.name_scope(self.drop_path.name):
+ self.drop_path.build(None)
+ self.built = True
+
+ def call(self, x: tf.Tensor, training: bool = False) -> tf.Tensor:
+ input = x
+ x = self.pad(x)
+ x = self.depth_wise_conv(x)
+ x = self.norm(x, training=training)
+ x = self.point_wise_conv1(x)
+ x = self.act(x)
+ x = self.point_wise_conv2(x)
+ x = input + self.drop_path(self.layer_scale * x, training=training)
+ return x
+
+
+class TFSwiftFormerEncoderBlock(keras.layers.Layer):
+ """
+ SwiftFormer Encoder Block for SwiftFormer. It consists of (1) Local representation module, (2)
+ SwiftFormerEfficientAdditiveAttention, and (3) MLP block.
+
+ Input: tensor of shape `[batch_size, channels, height, width]`
+
+ Output: tensor of shape `[batch_size, channels,height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, dim: int, drop_path: float = 0.0, **kwargs):
+ super().__init__(**kwargs)
+
+ layer_scale_init_value = config.layer_scale_init_value
+ use_layer_scale = config.use_layer_scale
+
+ self.local_representation = TFSwiftFormerLocalRepresentation(config, dim=dim, name="local_representation")
+ self.attn = TFSwiftFormerEfficientAdditiveAttention(config, dim=dim, name="attn")
+ self.linear = TFSwiftFormerMlp(config, in_features=dim, name="linear")
+ self.drop_path = TFSwiftFormerDropPath(config) if drop_path > 0.0 else keras.layers.Identity()
+ self.use_layer_scale = use_layer_scale
+ if use_layer_scale:
+ self.dim = dim
+ self.layer_scale_init_value = layer_scale_init_value
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.layer_scale_1 = self.add_weight(
+ name="layer_scale_1",
+ shape=self.dim,
+ initializer=keras.initializers.constant(self.layer_scale_init_value),
+ trainable=True,
+ )
+ self.layer_scale_2 = self.add_weight(
+ name="layer_scale_2",
+ shape=self.dim,
+ initializer=keras.initializers.constant(self.layer_scale_init_value),
+ trainable=True,
+ )
+
+ if getattr(self, "local_representation", None) is not None:
+ with tf.name_scope(self.local_representation.name):
+ self.local_representation.build(None)
+ if getattr(self, "attn", None) is not None:
+ with tf.name_scope(self.attn.name):
+ self.attn.build(None)
+ if getattr(self, "linear", None) is not None:
+ with tf.name_scope(self.linear.name):
+ self.linear.build(None)
+ self.built = True
+
+ def call(self, x: tf.Tensor, training: bool = False):
+ x = self.local_representation(x, training=training)
+ batch_size, height, width, channels = x.shape
+
+ res = tf.reshape(x, [-1, height * width, channels])
+ res = self.attn(res)
+ res = tf.reshape(res, [-1, height, width, channels])
+ if self.use_layer_scale:
+ x = x + self.drop_path(self.layer_scale_1 * res, training=training)
+ x = x + self.drop_path(self.layer_scale_2 * self.linear(x), training=training)
+ else:
+ x = x + self.drop_path(res, training=training)
+ x = x + self.drop_path(self.linear(x), training=training)
+ return x
+
+
+class TFSwiftFormerStage(keras.layers.Layer):
+ """
+ A Swiftformer stage consisting of a series of `SwiftFormerConvEncoder` blocks and a final
+ `SwiftFormerEncoderBlock`.
+
+ Input: tensor in shape `[batch_size, channels, height, width]`
+
+ Output: tensor in shape `[batch_size, channels, height, width]`
+ """
+
+ def __init__(self, config: SwiftFormerConfig, index: int, **kwargs) -> None:
+ super().__init__(**kwargs)
+
+ layer_depths = config.depths
+ dim = config.embed_dims[index]
+ depth = layer_depths[index]
+
+ self.blocks = []
+ for block_idx in range(depth):
+ block_dpr = config.drop_path_rate * (block_idx + sum(layer_depths[:index])) / (sum(layer_depths) - 1)
+
+ if depth - block_idx <= 1:
+ self.blocks.append(
+ TFSwiftFormerEncoderBlock(config, dim=dim, drop_path=block_dpr, name=f"blocks_._{block_idx}")
+ )
+ else:
+ self.blocks.append(TFSwiftFormerConvEncoder(config, dim=dim, name=f"blocks_._{block_idx}"))
+
+ def call(self, input: tf.Tensor, training: bool = False) -> tf.Tensor:
+ for i, block in enumerate(self.blocks):
+ input = block(input, training=training)
+ return input
+
+ def build(self, input_shape=None):
+ for layer in self.blocks:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+class TFSwiftFormerEncoder(keras.layers.Layer):
+ def __init__(self, config: SwiftFormerConfig, **kwargs) -> None:
+ super().__init__(**kwargs)
+ self.config = config
+
+ embed_dims = config.embed_dims
+ downsamples = config.downsamples
+ layer_depths = config.depths
+
+ # Transformer model
+ self.network = []
+ name_i = 0
+ for i in range(len(layer_depths)):
+ stage = TFSwiftFormerStage(config, index=i, name=f"network_._{name_i}")
+ self.network.append(stage)
+ name_i += 1
+ if i >= len(layer_depths) - 1:
+ break
+ if downsamples[i] or embed_dims[i] != embed_dims[i + 1]:
+ # downsampling between two stages
+ self.network.append(TFSwiftFormerEmbeddings(config, index=i, name=f"network_._{name_i}"))
+ name_i += 1
+
+ self.gradient_checkpointing = False
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ training: bool = False,
+ ) -> Union[tuple, TFBaseModelOutputWithNoAttention]:
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ all_hidden_states = (hidden_states,) if output_hidden_states else None
+
+ for i, block in enumerate(self.network):
+ hidden_states = block(hidden_states, training=training)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ hidden_states = tf.transpose(hidden_states, perm=[0, 3, 1, 2])
+ if all_hidden_states:
+ all_hidden_states = tuple(tf.transpose(s, perm=[0, 3, 1, 2]) for s in all_hidden_states)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states] if v is not None)
+
+ return TFBaseModelOutputWithNoAttention(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ )
+
+ def build(self, input_shape=None):
+ for layer in self.network:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+class TFSwiftFormerPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = SwiftFormerConfig
+ base_model_prefix = "swiftformer"
+ main_input_name = "pixel_values"
+
+
+TFSWIFTFORMER_START_DOCSTRING = r"""
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TF 2.0 models accepts two formats as inputs:
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional arguments.
+ This second option is useful when using [`keras.Model.fit`] method which currently requires having all the
+ tensors in the first argument of the model call function: `model(inputs)`.
+ If you choose this second option, there are three possibilities you can use to gather all the input Tensors in the
+ first positional argument :
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+
+
+ Parameters:
+ config ([`SwiftFormerConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+TFSWIFTFORMER_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`tf.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`]
+ for details.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to run the model in training mode.
+"""
+
+
+@keras_serializable
+class TFSwiftFormerMainLayer(keras.layers.Layer):
+ config_class = SwiftFormerConfig
+
+ def __init__(self, config: SwiftFormerConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+
+ self.patch_embed = TFSwiftFormerPatchEmbedding(config, name="patch_embed")
+ self.encoder = TFSwiftFormerEncoder(config, name="encoder")
+
+ @unpack_inputs
+ def call(
+ self,
+ pixel_values: Optional[tf.Tensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ training: bool = False,
+ ) -> Union[tuple, TFBaseModelOutputWithNoAttention]:
+ r""" """
+
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # TF 2.0 image layers can't use NCHW format when running on CPU.
+ # We transpose to NHWC format and then transpose back after the full forward pass.
+ # (batch_size, num_channels, height, width) -> (batch_size, height, width, num_channels)
+ pixel_values = tf.transpose(pixel_values, perm=[0, 2, 3, 1])
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ embedding_output = self.patch_embed(pixel_values, training=training)
+ encoder_outputs = self.encoder(
+ embedding_output,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ if not return_dict:
+ return tuple(v for v in encoder_outputs if v is not None)
+
+ return TFBaseModelOutputWithNoAttention(
+ last_hidden_state=encoder_outputs.last_hidden_state,
+ hidden_states=encoder_outputs.hidden_states,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ if getattr(self, "patch_embed", None) is not None:
+ with tf.name_scope(self.patch_embed.name):
+ self.patch_embed.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ self.built = True
+
+
+@add_start_docstrings(
+ "The bare TFSwiftFormer Model transformer outputting raw hidden-states without any specific head on top.",
+ TFSWIFTFORMER_START_DOCSTRING,
+)
+class TFSwiftFormerModel(TFSwiftFormerPreTrainedModel):
+ def __init__(self, config: SwiftFormerConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.swiftformer = TFSwiftFormerMainLayer(config, name="swiftformer")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(TFSWIFTFORMER_INPUTS_DOCSTRING)
+ def call(
+ self,
+ pixel_values: Optional[tf.Tensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ training: bool = False,
+ ) -> Union[TFBaseModelOutputWithNoAttention, tuple[tf.Tensor]]:
+ outputs = self.swiftformer(
+ pixel_values=pixel_values,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ if getattr(self, "swiftformer", None) is not None:
+ with tf.name_scope(self.swiftformer.name):
+ self.swiftformer.build(None)
+ self.built = True
+
+
+@add_start_docstrings(
+ """
+ TFSwiftFormer Model transformer with an image classification head on top (e.g. for ImageNet).
+ """,
+ TFSWIFTFORMER_START_DOCSTRING,
+)
+class TFSwiftFormerForImageClassification(TFSwiftFormerPreTrainedModel):
+ def __init__(self, config: SwiftFormerConfig, **kwargs) -> None:
+ super().__init__(config, **kwargs)
+
+ self.num_labels = config.num_labels
+ self.swiftformer = TFSwiftFormerMainLayer(config, name="swiftformer")
+
+ # Classifier head
+ self.norm = keras.layers.BatchNormalization(epsilon=config.batch_norm_eps, momentum=0.9, name="norm")
+ self.head = (
+ keras.layers.Dense(self.num_labels, name="head")
+ if self.num_labels > 0
+ else keras.layers.Identity(name="head")
+ )
+ self.dist_head = (
+ keras.layers.Dense(self.num_labels, name="dist_head")
+ if self.num_labels > 0
+ else keras.layers.Identity(name="dist_head")
+ )
+
+ def hf_compute_loss(self, labels, logits):
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == tf.int64 or labels.dtype == tf.int32):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = keras.losses.MSE
+ if self.num_labels == 1:
+ loss = loss_fct(labels.squeeze(), logits.squeeze())
+ else:
+ loss = loss_fct(labels, logits)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = keras.losses.SparseCategoricalCrossentropy(
+ from_logits=True, reduction=keras.losses.Reduction.NONE
+ )
+ loss = loss_fct(labels, logits)
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = keras.losses.SparseCategoricalCrossentropy(
+ from_logits=True,
+ reduction=keras.losses.Reduction.NONE,
+ )
+ loss = loss_fct(labels, logits)
+ else:
+ loss = None
+
+ return loss
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(TFSWIFTFORMER_INPUTS_DOCSTRING)
+ def call(
+ self,
+ pixel_values: Optional[tf.Tensor] = None,
+ labels: Optional[tf.Tensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ training: bool = False,
+ ) -> Union[tuple, TFImageClassifierOutputWithNoAttention]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # run base model
+ outputs = self.swiftformer(
+ pixel_values,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = outputs.last_hidden_state if return_dict else outputs[0]
+ sequence_output = tf.transpose(sequence_output, perm=[0, 2, 3, 1])
+
+ # run classification head
+ sequence_output = self.norm(sequence_output, training=training)
+ sequence_output = tf.transpose(sequence_output, perm=[0, 3, 1, 2])
+ _, num_channels, height, width = sequence_output.shape
+ sequence_output = tf.reshape(sequence_output, [-1, num_channels, height * width])
+ sequence_output = tf.reduce_mean(sequence_output, axis=-1)
+ cls_out = self.head(sequence_output)
+ distillation_out = self.dist_head(sequence_output)
+ logits = (cls_out + distillation_out) / 2
+
+ # calculate loss
+ loss = None if labels is None else self.hf_compute_loss(labels=labels, logits=logits)
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFImageClassifierOutputWithNoAttention(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ if getattr(self, "swiftformer", None) is not None:
+ with tf.name_scope(self.swiftformer.name):
+ self.swiftformer.build(None)
+ if getattr(self, "norm", None) is not None:
+ with tf.name_scope(self.norm.name):
+ self.norm.build((None, None, None, self.config.embed_dims[-1]))
+ if getattr(self, "head", None) is not None:
+ with tf.name_scope(self.head.name):
+ self.head.build(self.config.embed_dims[-1])
+ if getattr(self, "dist_head", None) is not None:
+ with tf.name_scope(self.dist_head.name):
+ self.dist_head.build(self.config.embed_dims[-1])
+ self.built = True
+
+
+__all__ = ["TFSwiftFormerForImageClassification", "TFSwiftFormerModel", "TFSwiftFormerPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..3dc5871b0375e8a5553e30dce1e5dde807a1b493
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_swin import *
+ from .modeling_swin import *
+ from .modeling_tf_swin import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/configuration_swin.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/configuration_swin.py
new file mode 100644
index 0000000000000000000000000000000000000000..41462d51edbedbd098fcf7a97eec6e412516cd62
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/configuration_swin.py
@@ -0,0 +1,179 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Swin Transformer model configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from packaging import version
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+from ...utils.backbone_utils import BackboneConfigMixin, get_aligned_output_features_output_indices
+
+
+logger = logging.get_logger(__name__)
+
+
+class SwinConfig(BackboneConfigMixin, PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SwinModel`]. It is used to instantiate a Swin
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the Swin
+ [microsoft/swin-tiny-patch4-window7-224](https://huggingface.co/microsoft/swin-tiny-patch4-window7-224)
+ architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 4):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ embed_dim (`int`, *optional*, defaults to 96):
+ Dimensionality of patch embedding.
+ depths (`list(int)`, *optional*, defaults to `[2, 2, 6, 2]`):
+ Depth of each layer in the Transformer encoder.
+ num_heads (`list(int)`, *optional*, defaults to `[3, 6, 12, 24]`):
+ Number of attention heads in each layer of the Transformer encoder.
+ window_size (`int`, *optional*, defaults to 7):
+ Size of windows.
+ mlp_ratio (`float`, *optional*, defaults to 4.0):
+ Ratio of MLP hidden dimensionality to embedding dimensionality.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether or not a learnable bias should be added to the queries, keys and values.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings and encoder.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ drop_path_rate (`float`, *optional*, defaults to 0.1):
+ Stochastic depth rate.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder. If string, `"gelu"`, `"relu"`,
+ `"selu"` and `"gelu_new"` are supported.
+ use_absolute_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether or not to add absolute position embeddings to the patch embeddings.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the layer normalization layers.
+ encoder_stride (`int`, *optional*, defaults to 32):
+ Factor to increase the spatial resolution by in the decoder head for masked image modeling.
+ out_features (`list[str]`, *optional*):
+ If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc.
+ (depending on how many stages the model has). If unset and `out_indices` is set, will default to the
+ corresponding stages. If unset and `out_indices` is unset, will default to the last stage. Must be in the
+ same order as defined in the `stage_names` attribute.
+ out_indices (`list[int]`, *optional*):
+ If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how
+ many stages the model has). If unset and `out_features` is set, will default to the corresponding stages.
+ If unset and `out_features` is unset, will default to the last stage. Must be in the
+ same order as defined in the `stage_names` attribute.
+
+ Example:
+
+ ```python
+ >>> from transformers import SwinConfig, SwinModel
+
+ >>> # Initializing a Swin microsoft/swin-tiny-patch4-window7-224 style configuration
+ >>> configuration = SwinConfig()
+
+ >>> # Initializing a model (with random weights) from the microsoft/swin-tiny-patch4-window7-224 style configuration
+ >>> model = SwinModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "swin"
+
+ attribute_map = {
+ "num_attention_heads": "num_heads",
+ "num_hidden_layers": "num_layers",
+ }
+
+ def __init__(
+ self,
+ image_size=224,
+ patch_size=4,
+ num_channels=3,
+ embed_dim=96,
+ depths=[2, 2, 6, 2],
+ num_heads=[3, 6, 12, 24],
+ window_size=7,
+ mlp_ratio=4.0,
+ qkv_bias=True,
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ drop_path_rate=0.1,
+ hidden_act="gelu",
+ use_absolute_embeddings=False,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ encoder_stride=32,
+ out_features=None,
+ out_indices=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.embed_dim = embed_dim
+ self.depths = depths
+ self.num_layers = len(depths)
+ self.num_heads = num_heads
+ self.window_size = window_size
+ self.mlp_ratio = mlp_ratio
+ self.qkv_bias = qkv_bias
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.drop_path_rate = drop_path_rate
+ self.hidden_act = hidden_act
+ self.use_absolute_embeddings = use_absolute_embeddings
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.encoder_stride = encoder_stride
+ # we set the hidden_size attribute in order to make Swin work with VisionEncoderDecoderModel
+ # this indicates the channel dimension after the last stage of the model
+ self.hidden_size = int(embed_dim * 2 ** (len(depths) - 1))
+ self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, len(depths) + 1)]
+ self._out_features, self._out_indices = get_aligned_output_features_output_indices(
+ out_features=out_features, out_indices=out_indices, stage_names=self.stage_names
+ )
+
+
+class SwinOnnxConfig(OnnxConfig):
+ torch_onnx_minimum_version = version.parse("1.11")
+
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ return OrderedDict(
+ [
+ ("pixel_values", {0: "batch", 1: "num_channels", 2: "height", 3: "width"}),
+ ]
+ )
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 1e-4
+
+
+__all__ = ["SwinConfig", "SwinOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/modeling_swin.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/modeling_swin.py
new file mode 100644
index 0000000000000000000000000000000000000000..3287fe7933c782f86d9ff9782570223f146f4149
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/modeling_swin.py
@@ -0,0 +1,1279 @@
+# coding=utf-8
+# Copyright 2022 Microsoft Research and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Swin Transformer model."""
+
+import collections.abc
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BackboneOutput
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, meshgrid, prune_linear_layer
+from ...utils import ModelOutput, auto_docstring, logging, torch_int
+from ...utils.backbone_utils import BackboneMixin
+from .configuration_swin import SwinConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# drop_path, SwinPatchEmbeddings, SwinPatchMerging and SwinDropPath are from the timm library.
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swin encoder's outputs, with potential hidden states and attentions.
+ """
+)
+class SwinEncoderOutput(ModelOutput):
+ r"""
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swin model's outputs that also contains a pooling of the last hidden states.
+ """
+)
+class SwinModelOutput(ModelOutput):
+ r"""
+ pooler_output (`torch.FloatTensor` of shape `(batch_size, hidden_size)`, *optional*, returned when `add_pooling_layer=True` is passed):
+ Average pooling of the last layer hidden-state.
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ pooler_output: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swin masked image model outputs.
+ """
+)
+class SwinMaskedImageModelingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `bool_masked_pos` is provided):
+ Masked image modeling (MLM) loss.
+ reconstruction (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ Reconstructed pixel values.
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ reconstruction: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+ @property
+ def logits(self):
+ warnings.warn(
+ "logits attribute is deprecated and will be removed in version 5 of Transformers."
+ " Please use the reconstruction attribute to retrieve the final output instead.",
+ FutureWarning,
+ )
+ return self.reconstruction
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swin outputs for image classification.
+ """
+)
+class SwinImageClassifierOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+def window_partition(input_feature, window_size):
+ """
+ Partitions the given input into windows.
+ """
+ batch_size, height, width, num_channels = input_feature.shape
+ input_feature = input_feature.view(
+ batch_size, height // window_size, window_size, width // window_size, window_size, num_channels
+ )
+ windows = input_feature.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, window_size, window_size, num_channels)
+ return windows
+
+
+def window_reverse(windows, window_size, height, width):
+ """
+ Merges windows to produce higher resolution features.
+ """
+ num_channels = windows.shape[-1]
+ windows = windows.view(-1, height // window_size, width // window_size, window_size, window_size, num_channels)
+ windows = windows.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, height, width, num_channels)
+ return windows
+
+
+class SwinEmbeddings(nn.Module):
+ """
+ Construct the patch and position embeddings. Optionally, also the mask token.
+ """
+
+ def __init__(self, config, use_mask_token=False):
+ super().__init__()
+
+ self.patch_embeddings = SwinPatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+ self.patch_grid = self.patch_embeddings.grid_size
+ self.mask_token = nn.Parameter(torch.zeros(1, 1, config.embed_dim)) if use_mask_token else None
+
+ if config.use_absolute_embeddings:
+ self.position_embeddings = nn.Parameter(torch.zeros(1, num_patches + 1, config.embed_dim))
+ else:
+ self.position_embeddings = None
+
+ self.norm = nn.LayerNorm(config.embed_dim)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.patch_size = config.patch_size
+ self.config = config
+
+ # Copied from transformers.models.vit.modeling_vit.ViTEmbeddings.interpolate_pos_encoding
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ num_positions = self.position_embeddings.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embeddings
+
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor],
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> tuple[torch.Tensor]:
+ _, num_channels, height, width = pixel_values.shape
+ embeddings, output_dimensions = self.patch_embeddings(pixel_values)
+ embeddings = self.norm(embeddings)
+ batch_size, seq_len, _ = embeddings.size()
+
+ if bool_masked_pos is not None:
+ mask_tokens = self.mask_token.expand(batch_size, seq_len, -1)
+ # replace the masked visual tokens by mask_tokens
+ mask = bool_masked_pos.unsqueeze(-1).type_as(mask_tokens)
+ embeddings = embeddings * (1.0 - mask) + mask_tokens * mask
+
+ if self.position_embeddings is not None:
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings)
+
+ return embeddings, output_dimensions
+
+
+class SwinPatchEmbeddings(nn.Module):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.embed_dim
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+ self.grid_size = (image_size[0] // patch_size[0], image_size[1] // patch_size[1])
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def maybe_pad(self, pixel_values, height, width):
+ if width % self.patch_size[1] != 0:
+ pad_values = (0, self.patch_size[1] - width % self.patch_size[1])
+ pixel_values = nn.functional.pad(pixel_values, pad_values)
+ if height % self.patch_size[0] != 0:
+ pad_values = (0, 0, 0, self.patch_size[0] - height % self.patch_size[0])
+ pixel_values = nn.functional.pad(pixel_values, pad_values)
+ return pixel_values
+
+ def forward(self, pixel_values: Optional[torch.FloatTensor]) -> tuple[torch.Tensor, tuple[int]]:
+ _, num_channels, height, width = pixel_values.shape
+ # pad the input to be divisible by self.patch_size, if needed
+ pixel_values = self.maybe_pad(pixel_values, height, width)
+ embeddings = self.projection(pixel_values)
+ _, _, height, width = embeddings.shape
+ output_dimensions = (height, width)
+ embeddings = embeddings.flatten(2).transpose(1, 2)
+
+ return embeddings, output_dimensions
+
+
+class SwinPatchMerging(nn.Module):
+ """
+ Patch Merging Layer.
+
+ Args:
+ input_resolution (`tuple[int]`):
+ Resolution of input feature.
+ dim (`int`):
+ Number of input channels.
+ norm_layer (`nn.Module`, *optional*, defaults to `nn.LayerNorm`):
+ Normalization layer class.
+ """
+
+ def __init__(self, input_resolution: tuple[int], dim: int, norm_layer: nn.Module = nn.LayerNorm) -> None:
+ super().__init__()
+ self.input_resolution = input_resolution
+ self.dim = dim
+ self.reduction = nn.Linear(4 * dim, 2 * dim, bias=False)
+ self.norm = norm_layer(4 * dim)
+
+ def maybe_pad(self, input_feature, height, width):
+ should_pad = (height % 2 == 1) or (width % 2 == 1)
+ if should_pad:
+ pad_values = (0, 0, 0, width % 2, 0, height % 2)
+ input_feature = nn.functional.pad(input_feature, pad_values)
+
+ return input_feature
+
+ def forward(self, input_feature: torch.Tensor, input_dimensions: tuple[int, int]) -> torch.Tensor:
+ height, width = input_dimensions
+ # `dim` is height * width
+ batch_size, dim, num_channels = input_feature.shape
+
+ input_feature = input_feature.view(batch_size, height, width, num_channels)
+ # pad input to be divisible by width and height, if needed
+ input_feature = self.maybe_pad(input_feature, height, width)
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_0 = input_feature[:, 0::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_1 = input_feature[:, 1::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_2 = input_feature[:, 0::2, 1::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_3 = input_feature[:, 1::2, 1::2, :]
+ # batch_size height/2 width/2 4*num_channels
+ input_feature = torch.cat([input_feature_0, input_feature_1, input_feature_2, input_feature_3], -1)
+ input_feature = input_feature.view(batch_size, -1, 4 * num_channels) # batch_size height/2*width/2 4*C
+
+ input_feature = self.norm(input_feature)
+ input_feature = self.reduction(input_feature)
+
+ return input_feature
+
+
+# Copied from transformers.models.beit.modeling_beit.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+# Copied from transformers.models.beit.modeling_beit.BeitDropPath with Beit->Swin
+class SwinDropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: Optional[float] = None) -> None:
+ super().__init__()
+ self.drop_prob = drop_prob
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+class SwinSelfAttention(nn.Module):
+ def __init__(self, config, dim, num_heads, window_size):
+ super().__init__()
+ if dim % num_heads != 0:
+ raise ValueError(
+ f"The hidden size ({dim}) is not a multiple of the number of attention heads ({num_heads})"
+ )
+
+ self.num_attention_heads = num_heads
+ self.attention_head_size = int(dim / num_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.window_size = (
+ window_size if isinstance(window_size, collections.abc.Iterable) else (window_size, window_size)
+ )
+
+ self.relative_position_bias_table = nn.Parameter(
+ torch.zeros((2 * self.window_size[0] - 1) * (2 * self.window_size[1] - 1), num_heads)
+ )
+
+ # get pair-wise relative position index for each token inside the window
+ coords_h = torch.arange(self.window_size[0])
+ coords_w = torch.arange(self.window_size[1])
+ coords = torch.stack(meshgrid([coords_h, coords_w], indexing="ij"))
+ coords_flatten = torch.flatten(coords, 1)
+ relative_coords = coords_flatten[:, :, None] - coords_flatten[:, None, :]
+ relative_coords = relative_coords.permute(1, 2, 0).contiguous()
+ relative_coords[:, :, 0] += self.window_size[0] - 1
+ relative_coords[:, :, 1] += self.window_size[1] - 1
+ relative_coords[:, :, 0] *= 2 * self.window_size[1] - 1
+ relative_position_index = relative_coords.sum(-1)
+ self.register_buffer("relative_position_index", relative_position_index)
+
+ self.query = nn.Linear(self.all_head_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(self.all_head_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(self.all_head_size, self.all_head_size, bias=config.qkv_bias)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ batch_size, dim, num_channels = hidden_states.shape
+ hidden_shape = (batch_size, dim, -1, self.attention_head_size)
+
+ query_layer = self.query(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_layer = self.key(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_layer = self.value(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+
+ relative_position_bias = self.relative_position_bias_table[self.relative_position_index.view(-1)]
+ relative_position_bias = relative_position_bias.view(
+ self.window_size[0] * self.window_size[1], self.window_size[0] * self.window_size[1], -1
+ )
+
+ relative_position_bias = relative_position_bias.permute(2, 0, 1).contiguous()
+ attention_scores = attention_scores + relative_position_bias.unsqueeze(0)
+
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in SwinModel forward() function)
+ mask_shape = attention_mask.shape[0]
+ attention_scores = attention_scores.view(
+ batch_size // mask_shape, mask_shape, self.num_attention_heads, dim, dim
+ )
+ attention_scores = attention_scores + attention_mask.unsqueeze(1).unsqueeze(0)
+ attention_scores = attention_scores.view(-1, self.num_attention_heads, dim, dim)
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+class SwinSelfOutput(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(dim, dim)
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ return hidden_states
+
+
+class SwinAttention(nn.Module):
+ def __init__(self, config, dim, num_heads, window_size):
+ super().__init__()
+ self.self = SwinSelfAttention(config, dim, num_heads, window_size)
+ self.output = SwinSelfOutput(config, dim)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ self_outputs = self.self(hidden_states, attention_mask, head_mask, output_attentions)
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+class SwinIntermediate(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(dim, int(config.mlp_ratio * dim))
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+class SwinOutput(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(int(config.mlp_ratio * dim), dim)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+class SwinLayer(nn.Module):
+ def __init__(self, config, dim, input_resolution, num_heads, drop_path_rate=0.0, shift_size=0):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.shift_size = shift_size
+ self.window_size = config.window_size
+ self.input_resolution = input_resolution
+ self.layernorm_before = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+ self.attention = SwinAttention(config, dim, num_heads, window_size=self.window_size)
+ self.drop_path = SwinDropPath(drop_path_rate) if drop_path_rate > 0.0 else nn.Identity()
+ self.layernorm_after = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+ self.intermediate = SwinIntermediate(config, dim)
+ self.output = SwinOutput(config, dim)
+
+ def set_shift_and_window_size(self, input_resolution):
+ if min(input_resolution) <= self.window_size:
+ # if window size is larger than input resolution, we don't partition windows
+ self.shift_size = torch_int(0)
+ self.window_size = (
+ torch.min(torch.tensor(input_resolution)) if torch.jit.is_tracing() else min(input_resolution)
+ )
+
+ def get_attn_mask(self, height, width, dtype, device):
+ if self.shift_size > 0:
+ # calculate attention mask for SW-MSA
+ img_mask = torch.zeros((1, height, width, 1), dtype=dtype, device=device)
+ height_slices = (
+ slice(0, -self.window_size),
+ slice(-self.window_size, -self.shift_size),
+ slice(-self.shift_size, None),
+ )
+ width_slices = (
+ slice(0, -self.window_size),
+ slice(-self.window_size, -self.shift_size),
+ slice(-self.shift_size, None),
+ )
+ count = 0
+ for height_slice in height_slices:
+ for width_slice in width_slices:
+ img_mask[:, height_slice, width_slice, :] = count
+ count += 1
+
+ mask_windows = window_partition(img_mask, self.window_size)
+ mask_windows = mask_windows.view(-1, self.window_size * self.window_size)
+ attn_mask = mask_windows.unsqueeze(1) - mask_windows.unsqueeze(2)
+ attn_mask = attn_mask.masked_fill(attn_mask != 0, -100.0).masked_fill(attn_mask == 0, 0.0)
+ else:
+ attn_mask = None
+ return attn_mask
+
+ def maybe_pad(self, hidden_states, height, width):
+ pad_right = (self.window_size - width % self.window_size) % self.window_size
+ pad_bottom = (self.window_size - height % self.window_size) % self.window_size
+ pad_values = (0, 0, 0, pad_right, 0, pad_bottom)
+ hidden_states = nn.functional.pad(hidden_states, pad_values)
+ return hidden_states, pad_values
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ always_partition: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ if not always_partition:
+ self.set_shift_and_window_size(input_dimensions)
+ else:
+ pass
+ height, width = input_dimensions
+ batch_size, _, channels = hidden_states.size()
+ shortcut = hidden_states
+
+ hidden_states = self.layernorm_before(hidden_states)
+
+ hidden_states = hidden_states.view(batch_size, height, width, channels)
+
+ # pad hidden_states to multiples of window size
+ hidden_states, pad_values = self.maybe_pad(hidden_states, height, width)
+
+ _, height_pad, width_pad, _ = hidden_states.shape
+ # cyclic shift
+ if self.shift_size > 0:
+ shifted_hidden_states = torch.roll(hidden_states, shifts=(-self.shift_size, -self.shift_size), dims=(1, 2))
+ else:
+ shifted_hidden_states = hidden_states
+
+ # partition windows
+ hidden_states_windows = window_partition(shifted_hidden_states, self.window_size)
+ hidden_states_windows = hidden_states_windows.view(-1, self.window_size * self.window_size, channels)
+ attn_mask = self.get_attn_mask(
+ height_pad, width_pad, dtype=hidden_states.dtype, device=hidden_states_windows.device
+ )
+
+ attention_outputs = self.attention(
+ hidden_states_windows, attn_mask, head_mask, output_attentions=output_attentions
+ )
+
+ attention_output = attention_outputs[0]
+
+ attention_windows = attention_output.view(-1, self.window_size, self.window_size, channels)
+ shifted_windows = window_reverse(attention_windows, self.window_size, height_pad, width_pad)
+
+ # reverse cyclic shift
+ if self.shift_size > 0:
+ attention_windows = torch.roll(shifted_windows, shifts=(self.shift_size, self.shift_size), dims=(1, 2))
+ else:
+ attention_windows = shifted_windows
+
+ was_padded = pad_values[3] > 0 or pad_values[5] > 0
+ if was_padded:
+ attention_windows = attention_windows[:, :height, :width, :].contiguous()
+
+ attention_windows = attention_windows.view(batch_size, height * width, channels)
+
+ hidden_states = shortcut + self.drop_path(attention_windows)
+
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+ layer_output = hidden_states + self.output(layer_output)
+
+ layer_outputs = (layer_output, attention_outputs[1]) if output_attentions else (layer_output,)
+ return layer_outputs
+
+
+class SwinStage(GradientCheckpointingLayer):
+ def __init__(self, config, dim, input_resolution, depth, num_heads, drop_path, downsample):
+ super().__init__()
+ self.config = config
+ self.dim = dim
+ self.blocks = nn.ModuleList(
+ [
+ SwinLayer(
+ config=config,
+ dim=dim,
+ input_resolution=input_resolution,
+ num_heads=num_heads,
+ drop_path_rate=drop_path[i],
+ shift_size=0 if (i % 2 == 0) else config.window_size // 2,
+ )
+ for i in range(depth)
+ ]
+ )
+
+ # patch merging layer
+ if downsample is not None:
+ self.downsample = downsample(input_resolution, dim=dim, norm_layer=nn.LayerNorm)
+ else:
+ self.downsample = None
+
+ self.pointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ always_partition: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ height, width = input_dimensions
+ for i, layer_module in enumerate(self.blocks):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states, input_dimensions, layer_head_mask, output_attentions, always_partition
+ )
+
+ hidden_states = layer_outputs[0]
+
+ hidden_states_before_downsampling = hidden_states
+ if self.downsample is not None:
+ height_downsampled, width_downsampled = (height + 1) // 2, (width + 1) // 2
+ output_dimensions = (height, width, height_downsampled, width_downsampled)
+ hidden_states = self.downsample(hidden_states_before_downsampling, input_dimensions)
+ else:
+ output_dimensions = (height, width, height, width)
+
+ stage_outputs = (hidden_states, hidden_states_before_downsampling, output_dimensions)
+
+ if output_attentions:
+ stage_outputs += layer_outputs[1:]
+ return stage_outputs
+
+
+class SwinEncoder(nn.Module):
+ def __init__(self, config, grid_size):
+ super().__init__()
+ self.num_layers = len(config.depths)
+ self.config = config
+ dpr = [x.item() for x in torch.linspace(0, config.drop_path_rate, sum(config.depths), device="cpu")]
+ self.layers = nn.ModuleList(
+ [
+ SwinStage(
+ config=config,
+ dim=int(config.embed_dim * 2**i_layer),
+ input_resolution=(grid_size[0] // (2**i_layer), grid_size[1] // (2**i_layer)),
+ depth=config.depths[i_layer],
+ num_heads=config.num_heads[i_layer],
+ drop_path=dpr[sum(config.depths[:i_layer]) : sum(config.depths[: i_layer + 1])],
+ downsample=SwinPatchMerging if (i_layer < self.num_layers - 1) else None,
+ )
+ for i_layer in range(self.num_layers)
+ ]
+ )
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ output_hidden_states_before_downsampling: Optional[bool] = False,
+ always_partition: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ ) -> Union[tuple, SwinEncoderOutput]:
+ all_hidden_states = () if output_hidden_states else None
+ all_reshaped_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if output_hidden_states:
+ batch_size, _, hidden_size = hidden_states.shape
+ # rearrange b (h w) c -> b c h w
+ reshaped_hidden_state = hidden_states.view(batch_size, *input_dimensions, hidden_size)
+ reshaped_hidden_state = reshaped_hidden_state.permute(0, 3, 1, 2)
+ all_hidden_states += (hidden_states,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+
+ for i, layer_module in enumerate(self.layers):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states, input_dimensions, layer_head_mask, output_attentions, always_partition
+ )
+
+ hidden_states = layer_outputs[0]
+ hidden_states_before_downsampling = layer_outputs[1]
+ output_dimensions = layer_outputs[2]
+
+ input_dimensions = (output_dimensions[-2], output_dimensions[-1])
+
+ if output_hidden_states and output_hidden_states_before_downsampling:
+ batch_size, _, hidden_size = hidden_states_before_downsampling.shape
+ # rearrange b (h w) c -> b c h w
+ # here we use the original (not downsampled) height and width
+ reshaped_hidden_state = hidden_states_before_downsampling.view(
+ batch_size, *(output_dimensions[0], output_dimensions[1]), hidden_size
+ )
+ reshaped_hidden_state = reshaped_hidden_state.permute(0, 3, 1, 2)
+ all_hidden_states += (hidden_states_before_downsampling,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+ elif output_hidden_states and not output_hidden_states_before_downsampling:
+ batch_size, _, hidden_size = hidden_states.shape
+ # rearrange b (h w) c -> b c h w
+ reshaped_hidden_state = hidden_states.view(batch_size, *input_dimensions, hidden_size)
+ reshaped_hidden_state = reshaped_hidden_state.permute(0, 3, 1, 2)
+ all_hidden_states += (hidden_states,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+
+ if output_attentions:
+ all_self_attentions += layer_outputs[3:]
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+
+ return SwinEncoderOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ reshaped_hidden_states=all_reshaped_hidden_states,
+ )
+
+
+@auto_docstring
+class SwinPreTrainedModel(PreTrainedModel):
+ config: SwinConfig
+ base_model_prefix = "swin"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["SwinStage"]
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, SwinEmbeddings):
+ if module.mask_token is not None:
+ module.mask_token.data.zero_()
+ if module.position_embeddings is not None:
+ module.position_embeddings.data.zero_()
+ elif isinstance(module, SwinSelfAttention):
+ module.relative_position_bias_table.data.zero_()
+
+
+@auto_docstring
+class SwinModel(SwinPreTrainedModel):
+ def __init__(self, config, add_pooling_layer=True, use_mask_token=False):
+ r"""
+ add_pooling_layer (`bool`, *optional*, defaults to `True`):
+ Whether or not to apply pooling layer.
+ use_mask_token (`bool`, *optional*, defaults to `False`):
+ Whether or not to create and apply mask tokens in the embedding layer.
+ """
+ super().__init__(config)
+ self.config = config
+ self.num_layers = len(config.depths)
+ self.num_features = int(config.embed_dim * 2 ** (self.num_layers - 1))
+
+ self.embeddings = SwinEmbeddings(config, use_mask_token=use_mask_token)
+ self.encoder = SwinEncoder(config, self.embeddings.patch_grid)
+
+ self.layernorm = nn.LayerNorm(self.num_features, eps=config.layer_norm_eps)
+ self.pooler = nn.AdaptiveAvgPool1d(1) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SwinModelOutput]:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`, *optional*):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, len(self.config.depths))
+
+ embedding_output, input_dimensions = self.embeddings(
+ pixel_values, bool_masked_pos=bool_masked_pos, interpolate_pos_encoding=interpolate_pos_encoding
+ )
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ input_dimensions,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = encoder_outputs[0]
+ sequence_output = self.layernorm(sequence_output)
+
+ pooled_output = None
+ if self.pooler is not None:
+ pooled_output = self.pooler(sequence_output.transpose(1, 2))
+ pooled_output = torch.flatten(pooled_output, 1)
+
+ if not return_dict:
+ output = (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return output
+
+ return SwinModelOutput(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ reshaped_hidden_states=encoder_outputs.reshaped_hidden_states,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Swin Model with a decoder on top for masked image modeling, as proposed in [SimMIM](https://huggingface.co/papers/2111.09886).
+
+
+
+ Note that we provide a script to pre-train this model on custom data in our [examples
+ directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
+
+
+ """
+)
+class SwinForMaskedImageModeling(SwinPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.swin = SwinModel(config, add_pooling_layer=False, use_mask_token=True)
+
+ num_features = int(config.embed_dim * 2 ** (config.num_layers - 1))
+ self.decoder = nn.Sequential(
+ nn.Conv2d(
+ in_channels=num_features, out_channels=config.encoder_stride**2 * config.num_channels, kernel_size=1
+ ),
+ nn.PixelShuffle(config.encoder_stride),
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SwinMaskedImageModelingOutput]:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+
+ Examples:
+ ```python
+ >>> from transformers import AutoImageProcessor, SwinForMaskedImageModeling
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("microsoft/swin-base-simmim-window6-192")
+ >>> model = SwinForMaskedImageModeling.from_pretrained("microsoft/swin-base-simmim-window6-192")
+
+ >>> num_patches = (model.config.image_size // model.config.patch_size) ** 2
+ >>> pixel_values = image_processor(images=image, return_tensors="pt").pixel_values
+ >>> # create random boolean mask of shape (batch_size, num_patches)
+ >>> bool_masked_pos = torch.randint(low=0, high=2, size=(1, num_patches)).bool()
+
+ >>> outputs = model(pixel_values, bool_masked_pos=bool_masked_pos)
+ >>> loss, reconstructed_pixel_values = outputs.loss, outputs.reconstruction
+ >>> list(reconstructed_pixel_values.shape)
+ [1, 3, 192, 192]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.swin(
+ pixel_values,
+ bool_masked_pos=bool_masked_pos,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ # Reshape to (batch_size, num_channels, height, width)
+ sequence_output = sequence_output.transpose(1, 2)
+ batch_size, num_channels, sequence_length = sequence_output.shape
+ height = width = math.floor(sequence_length**0.5)
+ sequence_output = sequence_output.reshape(batch_size, num_channels, height, width)
+
+ # Reconstruct pixel values
+ reconstructed_pixel_values = self.decoder(sequence_output)
+
+ masked_im_loss = None
+ if bool_masked_pos is not None:
+ size = self.config.image_size // self.config.patch_size
+ bool_masked_pos = bool_masked_pos.reshape(-1, size, size)
+ mask = (
+ bool_masked_pos.repeat_interleave(self.config.patch_size, 1)
+ .repeat_interleave(self.config.patch_size, 2)
+ .unsqueeze(1)
+ .contiguous()
+ )
+ reconstruction_loss = nn.functional.l1_loss(pixel_values, reconstructed_pixel_values, reduction="none")
+ masked_im_loss = (reconstruction_loss * mask).sum() / (mask.sum() + 1e-5) / self.config.num_channels
+
+ if not return_dict:
+ output = (reconstructed_pixel_values,) + outputs[2:]
+ return ((masked_im_loss,) + output) if masked_im_loss is not None else output
+
+ return SwinMaskedImageModelingOutput(
+ loss=masked_im_loss,
+ reconstruction=reconstructed_pixel_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ reshaped_hidden_states=outputs.reshaped_hidden_states,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Swin Model transformer with an image classification head on top (a linear layer on top of the final hidden state of
+ the [CLS] token) e.g. for ImageNet.
+
+
+
+ Note that it's possible to fine-tune Swin on higher resolution images than the ones it has been trained on, by
+ setting `interpolate_pos_encoding` to `True` in the forward of the model. This will interpolate the pre-trained
+ position embeddings to the higher resolution.
+
+
+ """
+)
+class SwinForImageClassification(SwinPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.swin = SwinModel(config)
+
+ # Classifier head
+ self.classifier = (
+ nn.Linear(self.swin.num_features, config.num_labels) if config.num_labels > 0 else nn.Identity()
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SwinImageClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.swin(
+ pixel_values,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ return_dict=return_dict,
+ )
+
+ pooled_output = outputs[1]
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, pooled_logits=logits, config=self.config)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SwinImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ reshaped_hidden_states=outputs.reshaped_hidden_states,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Swin backbone, to be used with frameworks like DETR and MaskFormer.
+ """
+)
+class SwinBackbone(SwinPreTrainedModel, BackboneMixin):
+ def __init__(self, config: SwinConfig):
+ super().__init__(config)
+ super()._init_backbone(config)
+
+ self.num_features = [config.embed_dim] + [int(config.embed_dim * 2**i) for i in range(len(config.depths))]
+ self.embeddings = SwinEmbeddings(config)
+ self.encoder = SwinEncoder(config, self.embeddings.patch_grid)
+
+ # Add layer norms to hidden states of out_features
+ hidden_states_norms = {}
+ for stage, num_channels in zip(self._out_features, self.channels):
+ hidden_states_norms[stage] = nn.LayerNorm(num_channels)
+ self.hidden_states_norms = nn.ModuleDict(hidden_states_norms)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def forward(
+ self,
+ pixel_values: torch.Tensor,
+ output_hidden_states: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> BackboneOutput:
+ """
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, AutoBackbone
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> processor = AutoImageProcessor.from_pretrained("shi-labs/nat-mini-in1k-224")
+ >>> model = AutoBackbone.from_pretrained(
+ ... "microsoft/swin-tiny-patch4-window7-224", out_features=["stage1", "stage2", "stage3", "stage4"]
+ ... )
+
+ >>> inputs = processor(image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> feature_maps = outputs.feature_maps
+ >>> list(feature_maps[-1].shape)
+ [1, 768, 7, 7]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ embedding_output, input_dimensions = self.embeddings(pixel_values)
+
+ outputs = self.encoder(
+ embedding_output,
+ input_dimensions,
+ head_mask=None,
+ output_attentions=output_attentions,
+ output_hidden_states=True,
+ output_hidden_states_before_downsampling=True,
+ always_partition=True,
+ return_dict=True,
+ )
+
+ hidden_states = outputs.reshaped_hidden_states
+
+ feature_maps = ()
+ for stage, hidden_state in zip(self.stage_names, hidden_states):
+ if stage in self.out_features:
+ batch_size, num_channels, height, width = hidden_state.shape
+ hidden_state = hidden_state.permute(0, 2, 3, 1).contiguous()
+ hidden_state = hidden_state.view(batch_size, height * width, num_channels)
+ hidden_state = self.hidden_states_norms[stage](hidden_state)
+ hidden_state = hidden_state.view(batch_size, height, width, num_channels)
+ hidden_state = hidden_state.permute(0, 3, 1, 2).contiguous()
+ feature_maps += (hidden_state,)
+
+ if not return_dict:
+ output = (feature_maps,)
+ if output_hidden_states:
+ output += (outputs.hidden_states,)
+ return output
+
+ return BackboneOutput(
+ feature_maps=feature_maps,
+ hidden_states=outputs.hidden_states if output_hidden_states else None,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "SwinForImageClassification",
+ "SwinForMaskedImageModeling",
+ "SwinModel",
+ "SwinPreTrainedModel",
+ "SwinBackbone",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/modeling_tf_swin.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/modeling_tf_swin.py
new file mode 100644
index 0000000000000000000000000000000000000000..7fa54e958046cc2c8b9e40c69959775013755d68
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin/modeling_tf_swin.py
@@ -0,0 +1,1639 @@
+# coding=utf-8
+# Copyright 2022 Microsoft Research and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TF 2.0 Swin Transformer model."""
+
+from __future__ import annotations
+
+import collections.abc
+import math
+import warnings
+from collections.abc import Iterable
+from dataclasses import dataclass
+from functools import partial
+from typing import Any, Callable
+
+import tensorflow as tf
+
+from ...activations_tf import ACT2FN
+from ...modeling_tf_utils import (
+ TFPreTrainedModel,
+ TFSequenceClassificationLoss,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import shape_list
+from ...utils import (
+ ModelOutput,
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+ replace_return_docstrings,
+)
+from .configuration_swin import SwinConfig
+
+
+logger = logging.get_logger(__name__)
+
+# General docstring
+_CONFIG_FOR_DOC = "SwinConfig"
+
+# Base docstring
+_CHECKPOINT_FOR_DOC = "microsoft/swin-tiny-patch4-window7-224"
+_EXPECTED_OUTPUT_SHAPE = [1, 49, 768]
+
+# Image classification docstring
+_IMAGE_CLASS_CHECKPOINT = "microsoft/swin-tiny-patch4-window7-224"
+_IMAGE_CLASS_EXPECTED_OUTPUT = "tabby, tabby cat"
+
+
+# drop_path, TFSwinPatchEmbeddings, TFSwinPatchMerging and TFSwinDropPath are tensorflow
+# implementations of PyTorch functionalities in the timm library.
+
+
+@dataclass
+class TFSwinEncoderOutput(ModelOutput):
+ """
+ Swin encoder's outputs, with potential hidden states and attentions.
+
+ Args:
+ last_hidden_state (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each stage) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ reshaped_hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ last_hidden_state: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+ reshaped_hidden_states: tuple[tf.Tensor, ...] | None = None
+
+
+@dataclass
+class TFSwinModelOutput(ModelOutput):
+ """
+ Swin model's outputs that also contains a pooling of the last hidden states.
+
+ Args:
+ last_hidden_state (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ pooler_output (`tf.Tensor` of shape `(batch_size, hidden_size)`, *optional*, returned when `add_pooling_layer=True` is passed):
+ Average pooling of the last layer hidden-state.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each stage) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ reshaped_hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ last_hidden_state: tf.Tensor | None = None
+ pooler_output: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+ reshaped_hidden_states: tuple[tf.Tensor, ...] | None = None
+
+
+@dataclass
+class TFSwinMaskedImageModelingOutput(ModelOutput):
+ """
+ Swin masked image model outputs.
+
+ Args:
+ loss (`tf.Tensor` of shape `(1,)`, *optional*, returned when `bool_masked_pos` is provided):
+ Masked image modeling (MLM) loss.
+ reconstruction (`tf.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Reconstructed pixel values.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each stage) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ reshaped_hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ loss: tf.Tensor | None = None
+ reconstruction: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+ reshaped_hidden_states: tuple[tf.Tensor, ...] | None = None
+
+ @property
+ def logits(self):
+ warnings.warn(
+ "logits attribute is deprecated and will be removed in version 5 of Transformers."
+ " Please use the reconstruction attribute to retrieve the final output instead.",
+ FutureWarning,
+ )
+ return self.reconstruction
+
+
+@dataclass
+class TFSwinImageClassifierOutput(ModelOutput):
+ """
+ Swin outputs for image classification.
+
+ Args:
+ loss (`tf.Tensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (`tf.Tensor` of shape `(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each stage) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ reshaped_hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each stage) of shape
+ `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ loss: tf.Tensor | None = None
+ logits: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+ reshaped_hidden_states: tuple[tf.Tensor, ...] | None = None
+
+
+def window_partition(input_feature: tf.Tensor, window_size: int) -> tf.Tensor:
+ """
+ Partitions the given input into windows.
+ """
+ batch_size, height, width, num_channels = shape_list(input_feature)
+ input_feature = tf.reshape(
+ input_feature,
+ (batch_size, height // window_size, window_size, width // window_size, window_size, num_channels),
+ )
+ windows = tf.transpose(input_feature, (0, 1, 3, 2, 4, 5))
+ windows = tf.reshape(windows, (-1, window_size, window_size, num_channels))
+ return windows
+
+
+def window_reverse(windows: tf.Tensor, window_size: int, height: int, width: int) -> tf.Tensor:
+ """
+ Merges windows to produce higher resolution features.
+ """
+ x = tf.shape(windows)[0]
+ y = tf.cast(height * width / (window_size * window_size), tf.int32)
+ batch_size = tf.math.floordiv(x, y)
+ windows = tf.reshape(
+ windows, (batch_size, height // window_size, width // window_size, window_size, window_size, -1)
+ )
+ windows = tf.transpose(windows, (0, 1, 3, 2, 4, 5))
+ windows = tf.reshape(windows, (batch_size, height, width, -1))
+ return windows
+
+
+def drop_path(
+ input: tf.Tensor, drop_prob: float = 0.0, training: bool = False, scale_by_keep: bool = True
+) -> tf.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ input_shape = shape_list(input)
+ ndim = len(input_shape)
+ shape = [input_shape[0]] + [1] * (ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = tf.random.uniform(shape)
+ random_tensor = tf.where(random_tensor <= keep_prob, 1.0, 0.0)
+ if keep_prob > 0.0 and scale_by_keep:
+ random_tensor /= keep_prob
+ return input * random_tensor
+
+
+class TFSwinEmbeddings(keras.layers.Layer):
+ """
+ Construct the patch and position embeddings. Optionally, also the mask token.
+ """
+
+ def __init__(self, config: SwinConfig, use_mask_token: bool = False, **kwargs) -> None:
+ super().__init__(**kwargs)
+ self.patch_embeddings = TFSwinPatchEmbeddings(config, name="patch_embeddings")
+ self.num_patches = self.patch_embeddings.num_patches
+ self.patch_grid = self.patch_embeddings.grid_size
+ self.embed_dim = config.embed_dim
+ self.use_mask_token = use_mask_token
+ self.use_absolute_embeddings = config.use_absolute_embeddings
+
+ self.norm = keras.layers.LayerNormalization(name="norm", epsilon=1e-5)
+ self.dropout = keras.layers.Dropout(config.hidden_dropout_prob, name="dropout")
+ self.config = config
+
+ def build(self, input_shape: tf.TensorShape) -> None:
+ if self.use_mask_token:
+ self.mask_token = self.add_weight(shape=(1, 1, self.embed_dim), initializer="zeros", name="mask_token")
+ else:
+ self.mask_token = None
+
+ if self.use_absolute_embeddings:
+ self.position_embeddings = self.add_weight(
+ (1, self.num_patches + 1, self.embed_dim), initializer="zeros", name="positional_embeddings"
+ )
+ else:
+ self.position_embeddings = None
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "patch_embeddings", None) is not None:
+ with tf.name_scope(self.patch_embeddings.name):
+ self.patch_embeddings.build(None)
+ if getattr(self, "norm", None) is not None:
+ with tf.name_scope(self.norm.name):
+ self.norm.build([None, None, self.config.embed_dim])
+ if getattr(self, "dropout", None) is not None:
+ with tf.name_scope(self.dropout.name):
+ self.dropout.build(None)
+
+ def call(
+ self, pixel_values: tf.Tensor, bool_masked_pos: bool | None = None, training: bool = False
+ ) -> tuple[tf.Tensor, tuple[int, int]]:
+ embeddings, output_dimensions = self.patch_embeddings(pixel_values, training=training)
+ embeddings = self.norm(embeddings, training=training)
+ batch_size, seq_len, _ = shape_list(embeddings)
+
+ if bool_masked_pos is not None:
+ mask_tokens = tf.repeat(self.mask_token, batch_size, 0)
+ mask_tokens = tf.repeat(mask_tokens, seq_len, 1)
+ # replace the masked visual tokens by mask_tokens
+ mask = tf.expand_dims(bool_masked_pos, -1)
+ mask = tf.cast(mask, mask_tokens.dtype)
+
+ embeddings = embeddings * (1.0 - mask) + mask_tokens * mask
+
+ if self.position_embeddings is not None:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings, training=training)
+
+ return embeddings, output_dimensions
+
+
+class TFSwinPatchEmbeddings(keras.layers.Layer):
+ """
+ Image to Patch Embedding.
+ """
+
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.embed_dim
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+ self.grid_size = (image_size[0] // patch_size[0], image_size[1] // patch_size[1])
+
+ self.projection = keras.layers.Conv2D(
+ filters=hidden_size,
+ kernel_size=self.patch_size,
+ strides=self.patch_size,
+ padding="valid",
+ name="projection",
+ )
+
+ def maybe_pad(self, pixel_values: tf.Tensor, height: int, width: int) -> tf.Tensor:
+ if width % self.patch_size[1] != 0:
+ pad_values = ((0, 0), (0, 0), (0, 0), (0, self.patch_size[1] - width % self.patch_size[1]))
+ pixel_values = tf.pad(pixel_values, pad_values)
+ if height % self.patch_size[0] != 0:
+ pad_values = ((0, 0), (0, 0), (0, self.patch_size[0] - height % self.patch_size[0]), (0, 0))
+ pixel_values = tf.pad(pixel_values, pad_values)
+ return pixel_values
+
+ def call(self, pixel_values: tf.Tensor, training: bool = False) -> tuple[tf.Tensor, tuple[int, int]]:
+ _, num_channels, height, width = shape_list(pixel_values)
+ if tf.executing_eagerly() and num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ )
+ # pad the input to be divisible by self.patch_size, if needed
+ pixel_values = self.maybe_pad(pixel_values, height, width)
+
+ # B,C,H,W -> B,H,W,C
+ pixel_values = tf.transpose(pixel_values, (0, 2, 3, 1))
+
+ embeddings = self.projection(pixel_values, training=training)
+
+ # B,H,W,C -> B,C,H,W
+ embeddings = tf.transpose(embeddings, (0, 3, 1, 2))
+
+ batch_size, channels, height, width = shape_list(embeddings)
+ output_dimensions = (height, width)
+
+ embeddings = tf.reshape(embeddings, (batch_size, channels, -1))
+ embeddings = tf.transpose(embeddings, (0, 2, 1))
+ return embeddings, output_dimensions
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "projection", None) is not None:
+ with tf.name_scope(self.projection.name):
+ self.projection.build([None, None, None, self.num_channels])
+
+
+class TFSwinPatchMerging(keras.layers.Layer):
+ """
+ Patch Merging Layer.
+
+ Args:
+ input_resolution (`tuple[int]`):
+ Resolution of input feature.
+ dim (`int`):
+ Number of input channels.
+ norm_layer (`keras.layer.Layer`, *optional*, defaults to `keras.layers.LayerNormalization`):
+ Normalization layer class.
+ """
+
+ def __init__(
+ self, input_resolution: tuple[int, int], dim: int, norm_layer: Callable | None = None, **kwargs
+ ) -> None:
+ super().__init__(**kwargs)
+ self.input_resolution = input_resolution
+ self.dim = dim
+ self.reduction = keras.layers.Dense(2 * dim, use_bias=False, name="reduction")
+ if norm_layer is None:
+ # Use same default epsilon as PyTorch
+ self.norm = keras.layers.LayerNormalization(epsilon=1e-5, name="norm")
+ else:
+ self.norm = norm_layer(name="norm")
+
+ def maybe_pad(self, input_feature: tf.Tensor, height: int, width: int) -> tf.Tensor:
+ should_pad = (height % 2 == 1) or (width % 2 == 1)
+ if should_pad:
+ pad_values = ((0, 0), (0, height % 2), (0, width % 2), (0, 0))
+ input_feature = tf.pad(input_feature, pad_values)
+
+ return input_feature
+
+ def call(self, input_feature: tf.Tensor, input_dimensions: tuple[int, int], training: bool = False) -> tf.Tensor:
+ height, width = input_dimensions
+ # `dim` is height * width
+ batch_size, _, num_channels = shape_list(input_feature)
+
+ input_feature = tf.reshape(input_feature, (batch_size, height, width, num_channels))
+ # pad input to be divisible by width and height, if needed
+ input_feature = self.maybe_pad(input_feature, height, width)
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_0 = input_feature[:, 0::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_1 = input_feature[:, 1::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_2 = input_feature[:, 0::2, 1::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_3 = input_feature[:, 1::2, 1::2, :]
+ # batch_size height/2 width/2 4*num_channels
+ input_feature = tf.concat([input_feature_0, input_feature_1, input_feature_2, input_feature_3], -1)
+ input_feature = tf.reshape(
+ input_feature, (batch_size, -1, 4 * num_channels)
+ ) # batch_size height/2*width/2 4*C
+
+ input_feature = self.norm(input_feature, training=training)
+ input_feature = self.reduction(input_feature, training=training)
+
+ return input_feature
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "reduction", None) is not None:
+ with tf.name_scope(self.reduction.name):
+ self.reduction.build([None, None, 4 * self.dim])
+ if getattr(self, "norm", None) is not None:
+ with tf.name_scope(self.norm.name):
+ self.norm.build([None, None, 4 * self.dim])
+
+
+class TFSwinDropPath(keras.layers.Layer):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: float | None = None, scale_by_keep: bool = True, **kwargs) -> None:
+ super().__init__(**kwargs)
+ self.drop_prob = drop_prob
+ self.scale_by_keep = scale_by_keep
+
+ def call(self, input: tf.Tensor, training: bool = False) -> tf.Tensor:
+ return drop_path(input, self.drop_prob, training, self.scale_by_keep)
+
+
+class TFSwinSelfAttention(keras.layers.Layer):
+ def __init__(self, config: SwinConfig, dim: int, num_heads: int, **kwargs) -> None:
+ super().__init__(**kwargs)
+ if dim % num_heads != 0:
+ raise ValueError(
+ f"The hidden size ({dim}) is not a multiple of the number of attention heads ({num_heads})"
+ )
+
+ self.num_attention_heads = num_heads
+ self.attention_head_size = int(dim / num_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ window_size = config.window_size
+ self.window_size = (
+ window_size if isinstance(window_size, collections.abc.Iterable) else (window_size, window_size)
+ )
+
+ self.query = keras.layers.Dense(
+ self.all_head_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ use_bias=config.qkv_bias,
+ name="query",
+ )
+ self.key = keras.layers.Dense(
+ self.all_head_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ use_bias=config.qkv_bias,
+ name="key",
+ )
+ self.value = keras.layers.Dense(
+ self.all_head_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ use_bias=config.qkv_bias,
+ name="value",
+ )
+
+ self.dropout = keras.layers.Dropout(config.attention_probs_dropout_prob)
+
+ def build(self, input_shape: tf.TensorShape) -> None:
+ self.relative_position_bias_table = self.add_weight(
+ shape=(((2 * self.window_size[0] - 1) * (2 * self.window_size[1] - 1)), self.num_attention_heads),
+ initializer="zeros",
+ name="relative_position_bias_table",
+ )
+ self.relative_position_index = self.add_weight(
+ shape=(self.window_size[0] ** 2, self.window_size[1] ** 2),
+ trainable=False,
+ dtype=tf.int32,
+ name="relative_position_index",
+ )
+
+ # get pair-wise relative position index for each token inside the window
+ coords_h = tf.range(self.window_size[0])
+ coords_w = tf.range(self.window_size[1])
+ coords = tf.stack(tf.meshgrid(coords_h, coords_w, indexing="ij"))
+ coords_flatten = tf.reshape(coords, (shape_list(coords)[0], -1))
+ relative_coords = coords_flatten[:, :, None] - coords_flatten[:, None, :]
+ relative_coords = tf.transpose(relative_coords, (1, 2, 0))
+
+ stack_0, stack_1 = tf.unstack(relative_coords, axis=2)
+ stack_0 += self.window_size[0] - 1
+ stack_0 *= 2 * self.window_size[1] - 1
+ stack_1 += self.window_size[1] - 1
+ relative_coords = tf.stack([stack_0, stack_1], axis=2)
+
+ self.relative_position_index.assign(tf.cast(tf.reduce_sum(relative_coords, axis=-1), tf.int32))
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "query", None) is not None:
+ with tf.name_scope(self.query.name):
+ self.query.build([None, None, self.all_head_size])
+ if getattr(self, "key", None) is not None:
+ with tf.name_scope(self.key.name):
+ self.key.build([None, None, self.all_head_size])
+ if getattr(self, "value", None) is not None:
+ with tf.name_scope(self.value.name):
+ self.value.build([None, None, self.all_head_size])
+
+ def transpose_for_scores(self, x: tf.Tensor) -> tf.Tensor:
+ new_x_shape = shape_list(x)[:-1] + [self.num_attention_heads, self.attention_head_size]
+ x = tf.reshape(x, new_x_shape)
+ return tf.transpose(x, (0, 2, 1, 3))
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool = False,
+ training: bool = False,
+ ) -> tuple[tf.Tensor, ...]:
+ batch_size, dim, _ = shape_list(hidden_states)
+ mixed_query_layer = self.query(hidden_states)
+
+ key_layer = self.transpose_for_scores(self.key(hidden_states))
+ value_layer = self.transpose_for_scores(self.value(hidden_states))
+ query_layer = self.transpose_for_scores(mixed_query_layer)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = tf.matmul(query_layer, tf.transpose(key_layer, (0, 1, 3, 2)))
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ relative_position_bias = tf.gather(
+ self.relative_position_bias_table, tf.reshape(self.relative_position_index, (-1,))
+ )
+ relative_position_bias = tf.reshape(
+ relative_position_bias,
+ (self.window_size[0] * self.window_size[1], self.window_size[0] * self.window_size[1], -1),
+ )
+
+ relative_position_bias = tf.transpose(relative_position_bias, (2, 0, 1))
+ attention_scores = attention_scores + tf.expand_dims(relative_position_bias, 0)
+
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in SwinModel call() function)
+ mask_shape = shape_list(attention_mask)[0]
+ attention_scores = tf.reshape(
+ attention_scores, (batch_size // mask_shape, mask_shape, self.num_attention_heads, dim, dim)
+ )
+ attention_mask = tf.expand_dims(attention_mask, 1)
+ attention_mask = tf.expand_dims(attention_mask, 0)
+ attention_scores = attention_scores + attention_mask
+ attention_scores = tf.reshape(attention_scores, (-1, self.num_attention_heads, dim, dim))
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = tf.nn.softmax(attention_scores, axis=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs, training=training)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = tf.matmul(attention_probs, value_layer)
+ context_layer = tf.transpose(context_layer, (0, 2, 1, 3))
+ new_context_layer_shape = shape_list(context_layer)[:-2] + [
+ self.all_head_size,
+ ]
+ context_layer = tf.reshape(context_layer, new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+class TFSwinSelfOutput(keras.layers.Layer):
+ def __init__(self, config: SwinConfig, dim: int, **kwargs) -> None:
+ super().__init__(**kwargs)
+ self.dense = keras.layers.Dense(dim, name="dense")
+ self.dropout = keras.layers.Dropout(config.attention_probs_dropout_prob, name="dropout")
+ self.dim = dim
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.dim])
+ if getattr(self, "dropout", None) is not None:
+ with tf.name_scope(self.dropout.name):
+ self.dropout.build(None)
+
+
+class TFSwinAttention(keras.layers.Layer):
+ def __init__(self, config: SwinConfig, dim: int, num_heads: int, **kwargs) -> None:
+ super().__init__(**kwargs)
+ self.self = TFSwinSelfAttention(config, dim, num_heads, name="self")
+ self.self_output = TFSwinSelfOutput(config, dim, name="output")
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ """
+ Prunes heads of the model. See base class PreTrainedModel heads: dict of {layer_num: list of heads to prune in
+ this layer}
+ """
+ raise NotImplementedError
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool = False,
+ training: bool = False,
+ ) -> tf.Tensor:
+ self_outputs = self.self(hidden_states, attention_mask, head_mask, output_attentions, training=training)
+ attention_output = self.self_output(self_outputs[0], hidden_states, training=training)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self", None) is not None:
+ with tf.name_scope(self.self.name):
+ self.self.build(None)
+ if getattr(self, "self_output", None) is not None:
+ with tf.name_scope(self.self_output.name):
+ self.self_output.build(None)
+
+
+class TFSwinIntermediate(keras.layers.Layer):
+ def __init__(self, config: SwinConfig, dim: int, **kwargs) -> None:
+ super().__init__(**kwargs)
+ self.dense = keras.layers.Dense(int(config.mlp_ratio * dim), name="dense")
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+ self.dim = dim
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.dim])
+
+
+class TFSwinOutput(keras.layers.Layer):
+ def __init__(self, config: SwinConfig, dim: int, **kwargs) -> None:
+ super().__init__(**kwargs)
+ self.dense = keras.layers.Dense(dim, name="dense")
+ self.dropout = keras.layers.Dropout(config.hidden_dropout_prob, "dropout")
+ self.config = config
+ self.dim = dim
+
+ def call(self, hidden_states: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, int(self.config.mlp_ratio * self.dim)])
+
+
+class TFSwinLayer(keras.layers.Layer):
+ def __init__(
+ self,
+ config,
+ dim,
+ input_resolution: tuple[int, int],
+ num_heads: int,
+ drop_path_rate: float = 0.0,
+ shift_size: int = 0,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ min_res = tf.reduce_min(input_resolution)
+ self.window_size = min_res if min_res <= config.window_size else config.window_size
+ self.shift_size = 0 if min_res <= self.window_size else shift_size
+ self.input_resolution = input_resolution
+
+ self.layernorm_before = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm_before")
+ self.attention = TFSwinAttention(config, dim, num_heads, name="attention")
+ self.drop_path = (
+ TFSwinDropPath(drop_path_rate, name="drop_path")
+ if drop_path_rate > 0.0
+ else keras.layers.Activation("linear", name="drop_path")
+ )
+ self.layernorm_after = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm_after")
+ self.intermediate = TFSwinIntermediate(config, dim, name="intermediate")
+ self.swin_output = TFSwinOutput(config, dim, name="output")
+ self.dim = dim
+
+ def get_attn_mask(self, height: int, width: int, window_size: int, shift_size: int) -> tf.Tensor | None:
+ img_mask = tf.zeros((height, width))
+ height_slices = ((0, -window_size), (-window_size, -shift_size), (-shift_size, -1))
+ width_slices = ((0, -window_size), (-window_size, -shift_size), (-shift_size, -1))
+
+ # calculate attention mask for SW-MSA
+ if shift_size > 0:
+ count = 0
+ for height_slice in height_slices:
+ for width_slice in width_slices:
+ height_inds = tf.range(height_slice[0] % height, height_slice[1] % height + 1)
+ width_inds = tf.range(width_slice[0] % width, width_slice[1] % width + 1)
+ indices = tf.reshape(tf.stack(tf.meshgrid(height_inds, width_inds), axis=-1), (-1, 2))
+ if len(indices) >= 1:
+ updates = tf.ones((len(indices),), dtype=img_mask.dtype) * count
+ img_mask = tf.tensor_scatter_nd_update(img_mask, indices, updates)
+ count += 1
+
+ img_mask = tf.expand_dims(img_mask, -1)
+ img_mask = tf.expand_dims(img_mask, 0)
+
+ mask_windows = window_partition(img_mask, window_size)
+ mask_windows = tf.reshape(mask_windows, (-1, window_size * window_size))
+ attn_mask = tf.expand_dims(mask_windows, 1) - tf.expand_dims(mask_windows, 2)
+ attn_mask = tf.where(attn_mask != 0, -100.0, attn_mask)
+ attn_mask = tf.where(attn_mask == 0, 0.0, attn_mask)
+ return attn_mask
+
+ def maybe_pad(
+ self, hidden_states: tf.Tensor, window_size: int, height: int, width: int
+ ) -> tuple[tf.Tensor, tf.Tensor]:
+ pad_right = (window_size - width % window_size) % window_size
+ pad_bottom = (window_size - height % window_size) % window_size
+ pad_values = [[0, 0], [0, pad_bottom], [0, pad_right], [0, 0]]
+ hidden_states = tf.pad(hidden_states, pad_values)
+ pad_values = tf.reshape(pad_values, (-1,))
+ return hidden_states, pad_values
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool = False,
+ training: bool = False,
+ ) -> tf.Tensor:
+ # if window size is larger than input resolution, we don't partition windows
+ min_res = tf.reduce_min(input_dimensions)
+ shift_size = 0 if min_res <= self.window_size else self.shift_size
+ window_size = min_res if min_res <= self.window_size else self.window_size
+
+ height, width = input_dimensions
+ batch_size, _, channels = shape_list(hidden_states)
+ shortcut = hidden_states
+
+ hidden_states = self.layernorm_before(hidden_states, training=training)
+ hidden_states = tf.reshape(hidden_states, (batch_size, height, width, channels))
+ # pad hidden_states to multiples of window size
+ hidden_states, pad_values = self.maybe_pad(hidden_states, window_size, height, width)
+
+ _, height_pad, width_pad, _ = shape_list(hidden_states)
+ # cyclic shift
+ if shift_size > 0:
+ shifted_hidden_states = tf.roll(hidden_states, shift=(-shift_size, -shift_size), axis=(1, 2))
+ else:
+ shifted_hidden_states = hidden_states
+
+ # partition windows
+ hidden_states_windows = window_partition(shifted_hidden_states, window_size)
+ hidden_states_windows = tf.reshape(hidden_states_windows, (-1, window_size * window_size, channels))
+ attn_mask = self.get_attn_mask(
+ height=height_pad, width=width_pad, window_size=window_size, shift_size=shift_size
+ )
+
+ attention_outputs = self.attention(
+ hidden_states_windows, attn_mask, head_mask, output_attentions=output_attentions, training=training
+ )
+
+ attention_output = attention_outputs[0]
+
+ attention_windows = tf.reshape(attention_output, (-1, window_size, window_size, channels))
+ shifted_windows = window_reverse(attention_windows, window_size, height_pad, width_pad)
+
+ # reverse cyclic shift
+ if shift_size > 0:
+ attention_windows = tf.roll(shifted_windows, shift=(shift_size, shift_size), axis=(1, 2))
+ else:
+ attention_windows = shifted_windows
+
+ was_padded = pad_values[3] > 0 or pad_values[5] > 0
+ if was_padded:
+ attention_windows = attention_windows[:, :height, :width, :]
+
+ attention_windows = tf.reshape(attention_windows, (batch_size, height * width, channels))
+
+ hidden_states = shortcut + self.drop_path(attention_windows, training=training)
+
+ layer_output = self.layernorm_after(hidden_states, training=training)
+ layer_output = self.intermediate(layer_output)
+ layer_output = hidden_states + self.swin_output(layer_output, training=training)
+
+ layer_outputs = (layer_output, attention_outputs[1]) if output_attentions else (layer_output,)
+ return layer_outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layernorm_before", None) is not None:
+ with tf.name_scope(self.layernorm_before.name):
+ self.layernorm_before.build([None, None, self.dim])
+ if getattr(self, "attention", None) is not None:
+ with tf.name_scope(self.attention.name):
+ self.attention.build(None)
+ if getattr(self, "drop_path", None) is not None:
+ with tf.name_scope(self.drop_path.name):
+ self.drop_path.build(None)
+ if getattr(self, "layernorm_after", None) is not None:
+ with tf.name_scope(self.layernorm_after.name):
+ self.layernorm_after.build([None, None, self.dim])
+ if getattr(self, "intermediate", None) is not None:
+ with tf.name_scope(self.intermediate.name):
+ self.intermediate.build(None)
+ if getattr(self, "swin_output", None) is not None:
+ with tf.name_scope(self.swin_output.name):
+ self.swin_output.build(None)
+
+
+class TFSwinStage(keras.layers.Layer):
+ def __init__(
+ self,
+ config: SwinConfig,
+ dim: int,
+ input_resolution: tuple[int, int],
+ depth: int,
+ num_heads: int,
+ drop_path: list[float],
+ downsample: Callable | None,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ self.config = config
+ self.dim = dim
+ self.blocks = [
+ TFSwinLayer(
+ config=config,
+ dim=dim,
+ input_resolution=input_resolution,
+ num_heads=num_heads,
+ shift_size=0 if (i % 2 == 0) else config.window_size // 2,
+ drop_path_rate=drop_path[i],
+ name=f"blocks.{i}",
+ )
+ for i in range(depth)
+ ]
+
+ # patch merging layer
+ if downsample is not None:
+ self.downsample = downsample(
+ input_resolution,
+ dim=dim,
+ norm_layer=partial(keras.layers.LayerNormalization, epsilon=1e-5),
+ name="downsample",
+ )
+ else:
+ self.downsample = None
+
+ self.pointing = False
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = False,
+ training: bool = False,
+ ) -> tuple[tf.Tensor, ...]:
+ height, width = input_dimensions
+ for i, layer_module in enumerate(self.blocks):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states, input_dimensions, layer_head_mask, output_attentions, training=training
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if self.downsample is not None:
+ height_downsampled, width_downsampled = (height + 1) // 2, (width + 1) // 2
+ output_dimensions = (height, width, height_downsampled, width_downsampled)
+ hidden_states = self.downsample(layer_outputs[0], input_dimensions, training=training)
+ else:
+ output_dimensions = (height, width, height, width)
+
+ stage_outputs = (hidden_states, output_dimensions)
+
+ if output_attentions:
+ stage_outputs += layer_outputs[1:]
+ return stage_outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "downsample", None) is not None:
+ with tf.name_scope(self.downsample.name):
+ self.downsample.build(None)
+ if getattr(self, "blocks", None) is not None:
+ for layer in self.blocks:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+class TFSwinEncoder(keras.layers.Layer):
+ def __init__(self, config: SwinConfig, grid_size: tuple[int, int], **kwargs):
+ super().__init__(**kwargs)
+ self.num_layers = len(config.depths)
+ self.config = config
+ dpr = list((tf.linspace(0, 1, sum(config.depths)) * config.drop_path_rate).numpy())
+ self.layers = [
+ TFSwinStage(
+ config=config,
+ dim=int(config.embed_dim * 2**i_layer),
+ input_resolution=(grid_size[0] // (2**i_layer), grid_size[1] // (2**i_layer)),
+ depth=config.depths[i_layer],
+ num_heads=config.num_heads[i_layer],
+ drop_path=dpr[sum(config.depths[:i_layer]) : sum(config.depths[: i_layer + 1])],
+ downsample=TFSwinPatchMerging if (i_layer < self.num_layers - 1) else None,
+ name=f"layers.{i_layer}",
+ )
+ for i_layer in range(self.num_layers)
+ ]
+
+ self.gradient_checkpointing = False
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ training: bool = False,
+ ) -> tuple[tf.Tensor, ...] | TFSwinEncoderOutput:
+ all_input_dimensions = ()
+ all_hidden_states = () if output_hidden_states else None
+ all_reshaped_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if output_hidden_states:
+ batch_size, _, hidden_size = shape_list(hidden_states)
+ # rearrange b (h w) c -> b c h w
+ reshaped_hidden_state = tf.reshape(hidden_states, (batch_size, *input_dimensions, hidden_size))
+ reshaped_hidden_state = tf.transpose(reshaped_hidden_state, (0, 3, 1, 2))
+ all_hidden_states += (hidden_states,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+
+ for i, layer_module in enumerate(self.layers):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states, input_dimensions, layer_head_mask, output_attentions, training=training
+ )
+
+ hidden_states = layer_outputs[0]
+ output_dimensions = layer_outputs[1]
+
+ input_dimensions = (output_dimensions[-2], output_dimensions[-1])
+ all_input_dimensions += (input_dimensions,)
+
+ if output_hidden_states:
+ batch_size, _, hidden_size = shape_list(hidden_states)
+ # rearrange b (h w) c -> b c h w
+ reshaped_hidden_state = tf.reshape(hidden_states, (batch_size, *input_dimensions, hidden_size))
+ reshaped_hidden_state = tf.transpose(reshaped_hidden_state, (0, 3, 1, 2))
+ all_hidden_states += (hidden_states,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+
+ if output_attentions:
+ all_self_attentions += layer_outputs[2:]
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+
+ return TFSwinEncoderOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ reshaped_hidden_states=all_reshaped_hidden_states,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layers", None) is not None:
+ for layer in self.layers:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+class TFSwinPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = SwinConfig
+ base_model_prefix = "swin"
+ main_input_name = "pixel_values"
+
+
+SWIN_START_DOCSTRING = r"""
+ This model is a Tensorflow
+ [keras.layers.Layer](https://www.tensorflow.org/api_docs/python/tf/keras/layers/Layer) sub-class. Use it as a
+ regular Tensorflow Module and refer to the Tensorflow documentation for all matter related to general usage and
+ behavior.
+
+ Parameters:
+ config ([`SwinConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+SWIN_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`tf.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`]
+ for details.
+ head_mask (`tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+def normalize_data_format(value: str) -> str:
+ """
+ From tensorflow addons
+ https://github.com/tensorflow/addons/blob/8cec33fcaaf1cf90aec7bdd55a0fcdbb251ce5c2/tensorflow_addons/utils/keras_utils.py#L71
+ """
+ if value is None:
+ value = keras.backend.image_data_format()
+ data_format = value.lower()
+ if data_format not in {"channels_first", "channels_last"}:
+ raise ValueError(
+ 'The `data_format` argument must be one of "channels_first", "channels_last". Received: ' + str(value)
+ )
+ return data_format
+
+
+class AdaptiveAveragePooling1D(keras.layers.Layer):
+ """
+ Args:
+ Average 1D Pooling with adaptive kernel size.
+ output_size: An integer or tuple/list of a single integer, specifying pooled_features.
+ The new size of output channels.
+ data_format: A string,
+ one of `channels_last` (default) or `channels_first`. The ordering of the dimensions in the inputs.
+ `channels_last` corresponds to inputs with shape `(batch, steps, channels)` while `channels_first` corresponds
+ to inputs with shape `(batch, channels, steps)`.
+ Input shape:
+ - If `data_format='channels_last'`: 3D tensor with shape `(batch, steps, channels)`.
+ - If `data_format='channels_first'`: 3D tensor with shape `(batch, channels, steps)`.
+ Output shape:
+ - If `data_format='channels_last'`: 3D tensor with shape `(batch_size, pooled_steps, channels)`.
+ - If `data_format='channels_first'`: 3D tensor with shape `(batch_size, channels, pooled_steps)`.
+
+ Adapted from [tensorflow-addon's adaptive pooling.py](
+ https://github.com/tensorflow/addons/blob/8cec33fcaaf1cf90aec7bdd55a0fcdbb251ce5c2/tensorflow_addons/layers/adaptive_pooling.py#L90-L120
+ )
+ """
+
+ def __init__(
+ self,
+ output_size: int | Iterable[int],
+ reduce_function: Callable = tf.reduce_mean,
+ data_format: str | None = None,
+ **kwargs,
+ ) -> None:
+ self.data_format = normalize_data_format(data_format)
+ self.reduce_function = reduce_function
+ self.output_size = (output_size,) if isinstance(output_size, int) else tuple(output_size)
+ super().__init__(**kwargs)
+
+ def call(self, inputs: tf.Tensor, *args) -> None:
+ bins = self.output_size[0]
+ if self.data_format == "channels_last":
+ splits = tf.split(inputs, bins, axis=1)
+ splits = tf.stack(splits, axis=1)
+ out_vect = self.reduce_function(splits, axis=2)
+ else:
+ splits = tf.split(inputs, bins, axis=2)
+ splits = tf.stack(splits, axis=2)
+ out_vect = self.reduce_function(splits, axis=3)
+ return out_vect
+
+ def compute_output_shape(self, input_shape: Iterable[int]) -> tf.TensorShape:
+ input_shape = tf.TensorShape(input_shape).as_list()
+ if self.data_format == "channels_last":
+ shape = tf.TensorShape([input_shape[0], self.output_size[0], input_shape[2]])
+ else:
+ shape = tf.TensorShape([input_shape[0], input_shape[1], self.output_size[0]])
+ return shape
+
+ def get_config(self) -> dict[str, Any]:
+ config = {
+ "output_size": self.output_size,
+ "data_format": self.data_format,
+ }
+ base_config = super().get_config()
+ return {**base_config, **config}
+
+
+@keras_serializable
+class TFSwinMainLayer(keras.layers.Layer):
+ config_class = SwinConfig
+
+ def __init__(
+ self, config: SwinConfig, add_pooling_layer: bool = True, use_mask_token: bool = False, **kwargs
+ ) -> None:
+ super().__init__(**kwargs)
+ self.config = config
+ self.num_layers = len(config.depths)
+ self.num_features = int(config.embed_dim * 2 ** (self.num_layers - 1))
+
+ self.embeddings = TFSwinEmbeddings(config, use_mask_token=use_mask_token, name="embeddings")
+ self.encoder = TFSwinEncoder(config, self.embeddings.patch_grid, name="encoder")
+
+ self.layernorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm")
+ self.pooler = AdaptiveAveragePooling1D(output_size=(1,)) if add_pooling_layer else None
+
+ def get_input_embeddings(self) -> TFSwinPatchEmbeddings:
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune: dict[int, list]):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ def get_head_mask(self, head_mask: Any | None) -> list:
+ if head_mask is not None:
+ raise NotImplementedError
+ return [None] * len(self.config.depths)
+
+ @unpack_inputs
+ def call(
+ self,
+ pixel_values: tf.Tensor | None = None,
+ bool_masked_pos: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFSwinModelOutput | tuple[tf.Tensor, ...]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask)
+ embedding_output, input_dimensions = self.embeddings(
+ pixel_values, bool_masked_pos=bool_masked_pos, training=training
+ )
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ input_dimensions,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = encoder_outputs[0]
+ sequence_output = self.layernorm(sequence_output, training=training)
+
+ pooled_output = None
+ if self.pooler is not None:
+ batch_size, _, num_features = shape_list(sequence_output)
+ pooled_output = self.pooler(sequence_output)
+ pooled_output = tf.reshape(pooled_output, (batch_size, num_features))
+
+ if not return_dict:
+ output = (sequence_output, pooled_output) + encoder_outputs[1:]
+ return output
+
+ return TFSwinModelOutput(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ reshaped_hidden_states=encoder_outputs.reshaped_hidden_states,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "embeddings", None) is not None:
+ with tf.name_scope(self.embeddings.name):
+ self.embeddings.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "layernorm", None) is not None:
+ with tf.name_scope(self.layernorm.name):
+ self.layernorm.build([None, None, self.num_features])
+
+
+@add_start_docstrings(
+ "The bare Swin Model transformer outputting raw hidden-states without any specific head on top.",
+ SWIN_START_DOCSTRING,
+)
+class TFSwinModel(TFSwinPreTrainedModel):
+ def __init__(
+ self, config: SwinConfig, add_pooling_layer: bool = True, use_mask_token: bool = False, **kwargs
+ ) -> None:
+ super().__init__(config, **kwargs)
+ self.config = config
+ self.swin = TFSwinMainLayer(config, name="swin")
+
+ @add_start_docstrings_to_model_forward(SWIN_INPUTS_DOCSTRING)
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFSwinModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ modality="vision",
+ expected_output=_EXPECTED_OUTPUT_SHAPE,
+ )
+ @unpack_inputs
+ def call(
+ self,
+ pixel_values: tf.Tensor | None = None,
+ bool_masked_pos: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFSwinModelOutput | tuple[tf.Tensor, ...]:
+ r"""
+ bool_masked_pos (`tf.Tensor` of shape `(batch_size, num_patches)`, *optional*):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ swin_outputs = self.swin(
+ pixel_values=pixel_values,
+ bool_masked_pos=bool_masked_pos,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return swin_outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "swin", None) is not None:
+ with tf.name_scope(self.swin.name):
+ self.swin.build(None)
+
+
+class TFSwinPixelShuffle(keras.layers.Layer):
+ """TF layer implementation of torch.nn.PixelShuffle"""
+
+ def __init__(self, upscale_factor: int, **kwargs) -> None:
+ super().__init__(**kwargs)
+ if not isinstance(upscale_factor, int) or upscale_factor < 2:
+ raise ValueError(f"upscale_factor must be an integer value >= 2 got {upscale_factor}")
+ self.upscale_factor = upscale_factor
+
+ def call(self, x: tf.Tensor) -> tf.Tensor:
+ hidden_states = x
+ batch_size, _, _, num_input_channels = shape_list(hidden_states)
+ block_size_squared = self.upscale_factor**2
+ output_depth = int(num_input_channels / block_size_squared)
+ # When the number of output channels >= 2, PyTorch's PixelShuffle and
+ # TF's depth_to_space differ in their output as the order of channels selected for combining
+ # is a permutation of the other c.f.
+ # https://stackoverflow.com/questions/68272502/tf-depth-to-space-not-same-as-torchs-pixelshuffle-when-output-channels-1
+ permutation = tf.constant(
+ [[i + j * block_size_squared for i in range(block_size_squared) for j in range(output_depth)]]
+ )
+ hidden_states = tf.gather(params=hidden_states, indices=tf.tile(permutation, [batch_size, 1]), batch_dims=-1)
+ hidden_states = tf.nn.depth_to_space(hidden_states, block_size=self.upscale_factor, data_format="NHWC")
+ return hidden_states
+
+
+class TFSwinDecoder(keras.layers.Layer):
+ def __init__(self, config: SwinConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.conv2d = keras.layers.Conv2D(
+ filters=config.encoder_stride**2 * config.num_channels, kernel_size=1, strides=1, name="0"
+ )
+ self.pixel_shuffle = TFSwinPixelShuffle(config.encoder_stride, name="1")
+ self.config = config
+
+ def call(self, x: tf.Tensor) -> tf.Tensor:
+ hidden_states = x
+ # B,C,H,W -> B,H,W,C
+ hidden_states = tf.transpose(hidden_states, (0, 2, 3, 1))
+ hidden_states = self.conv2d(hidden_states)
+ hidden_states = self.pixel_shuffle(hidden_states)
+ # B,H,W,C -> B,C,H,W
+ hidden_states = tf.transpose(hidden_states, (0, 3, 1, 2))
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv2d", None) is not None:
+ with tf.name_scope(self.conv2d.name):
+ self.conv2d.build([None, None, None, self.config.hidden_size])
+ if getattr(self, "pixel_shuffle", None) is not None:
+ with tf.name_scope(self.pixel_shuffle.name):
+ self.pixel_shuffle.build(None)
+
+
+@add_start_docstrings(
+ "Swin Model with a decoder on top for masked image modeling, as proposed in"
+ " [SimMIM](https://huggingface.co/papers/2111.09886).",
+ SWIN_START_DOCSTRING,
+)
+class TFSwinForMaskedImageModeling(TFSwinPreTrainedModel):
+ def __init__(self, config: SwinConfig):
+ super().__init__(config)
+
+ self.swin = TFSwinMainLayer(config, add_pooling_layer=False, use_mask_token=True, name="swin")
+
+ self.decoder = TFSwinDecoder(config, name="decoder")
+
+ @add_start_docstrings_to_model_forward(SWIN_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFSwinMaskedImageModelingOutput, config_class=_CONFIG_FOR_DOC)
+ @unpack_inputs
+ def call(
+ self,
+ pixel_values: tf.Tensor | None = None,
+ bool_masked_pos: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> tuple | TFSwinMaskedImageModelingOutput:
+ r"""
+ bool_masked_pos (`tf.Tensor` of shape `(batch_size, num_patches)`):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+
+ Returns:
+
+ Examples:
+ ```python
+ >>> from transformers import AutoImageProcessor, TFSwinForMaskedImageModeling
+ >>> import tensorflow as tf
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("microsoft/swin-tiny-patch4-window7-224")
+ >>> model = TFSwinForMaskedImageModeling.from_pretrained("microsoft/swin-tiny-patch4-window7-224")
+
+ >>> num_patches = (model.config.image_size // model.config.patch_size) ** 2
+ >>> pixel_values = image_processor(images=image, return_tensors="tf").pixel_values
+ >>> # create random boolean mask of shape (batch_size, num_patches)
+ >>> bool_masked_pos = tf.random.uniform((1, num_patches)) >= 0.5
+
+ >>> outputs = model(pixel_values, bool_masked_pos=bool_masked_pos)
+ >>> loss, reconstructed_pixel_values = outputs.loss, outputs.reconstruction
+ >>> list(reconstructed_pixel_values.shape)
+ [1, 3, 224, 224]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.swin(
+ pixel_values,
+ bool_masked_pos=bool_masked_pos,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = outputs[0]
+ # Reshape to (batch_size, num_channels, height, width)
+ sequence_output = tf.transpose(sequence_output, (0, 2, 1))
+ batch_size, num_channels, sequence_length = shape_list(sequence_output)
+ height = width = int(sequence_length**0.5)
+ sequence_output = tf.reshape(sequence_output, (batch_size, num_channels, height, width))
+
+ # Reconstruct pixel values
+ reconstructed_pixel_values = self.decoder(sequence_output)
+
+ masked_im_loss = None
+ if bool_masked_pos is not None:
+ size = self.config.image_size // self.config.patch_size
+ bool_masked_pos = tf.reshape(bool_masked_pos, (-1, size, size))
+ mask = tf.repeat(bool_masked_pos, self.config.patch_size, 1)
+ mask = tf.repeat(mask, self.config.patch_size, 2)
+ mask = tf.expand_dims(mask, 1)
+ mask = tf.cast(mask, tf.float32)
+
+ reconstruction_loss = keras.losses.mean_absolute_error(
+ # Swap axes as metric calculation reduces over the final dimension
+ tf.transpose(pixel_values, (1, 2, 3, 0)),
+ tf.transpose(reconstructed_pixel_values, (1, 2, 3, 0)),
+ )
+ reconstruction_loss = tf.expand_dims(reconstruction_loss, 0)
+ total_loss = tf.reduce_sum(reconstruction_loss * mask)
+ num_masked_pixels = (tf.reduce_sum(mask) + 1e-5) * self.config.num_channels
+ masked_im_loss = total_loss / num_masked_pixels
+ masked_im_loss = tf.reshape(masked_im_loss, (1,))
+
+ if not return_dict:
+ output = (reconstructed_pixel_values,) + outputs[2:]
+ return ((masked_im_loss,) + output) if masked_im_loss is not None else output
+
+ return TFSwinMaskedImageModelingOutput(
+ loss=masked_im_loss,
+ reconstruction=reconstructed_pixel_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ reshaped_hidden_states=outputs.reshaped_hidden_states,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "swin", None) is not None:
+ with tf.name_scope(self.swin.name):
+ self.swin.build(None)
+ if getattr(self, "decoder", None) is not None:
+ with tf.name_scope(self.decoder.name):
+ self.decoder.build(None)
+
+
+@add_start_docstrings(
+ """
+ Swin Model transformer with an image classification head on top (a linear layer on top of the final hidden state of
+ the [CLS] token) e.g. for ImageNet.
+ """,
+ SWIN_START_DOCSTRING,
+)
+class TFSwinForImageClassification(TFSwinPreTrainedModel, TFSequenceClassificationLoss):
+ def __init__(self, config: SwinConfig):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.swin = TFSwinMainLayer(config, name="swin")
+
+ # Classifier head
+ self.classifier = (
+ keras.layers.Dense(config.num_labels, name="classifier")
+ if config.num_labels > 0
+ else keras.layers.Activation("linear", name="classifier")
+ )
+
+ @add_start_docstrings_to_model_forward(SWIN_INPUTS_DOCSTRING)
+ @add_code_sample_docstrings(
+ checkpoint=_IMAGE_CLASS_CHECKPOINT,
+ output_type=TFSwinImageClassifierOutput,
+ config_class=_CONFIG_FOR_DOC,
+ expected_output=_IMAGE_CLASS_EXPECTED_OUTPUT,
+ )
+ @unpack_inputs
+ def call(
+ self,
+ pixel_values: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ labels: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> tuple[tf.Tensor, ...] | TFSwinImageClassifierOutput:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.swin(
+ pixel_values,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ pooled_output = outputs[1]
+
+ logits = self.classifier(pooled_output, training=training)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFSwinImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ reshaped_hidden_states=outputs.reshaped_hidden_states,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "swin", None) is not None:
+ with tf.name_scope(self.swin.name):
+ self.swin.build(None)
+ if getattr(self, "classifier", None) is not None:
+ if hasattr(self.classifier, "name"):
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.swin.num_features])
+
+
+__all__ = ["TFSwinForImageClassification", "TFSwinForMaskedImageModeling", "TFSwinModel", "TFSwinPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..082570230cc84b99e76aa5b4943c2f9013efc7b0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_swin2sr import *
+ from .image_processing_swin2sr import *
+ from .image_processing_swin2sr_fast import *
+ from .modeling_swin2sr import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/configuration_swin2sr.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/configuration_swin2sr.py
new file mode 100644
index 0000000000000000000000000000000000000000..a507d9d625136c1710f72924f62edd563d803d2d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/configuration_swin2sr.py
@@ -0,0 +1,154 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Swin2SR Transformer model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Swin2SRConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Swin2SRModel`]. It is used to instantiate a Swin
+ Transformer v2 model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the Swin Transformer v2
+ [caidas/swin2sr-classicalsr-x2-64](https://huggingface.co/caidas/swin2sr-classicalsr-x2-64) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ image_size (`int`, *optional*, defaults to 64):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 1):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ num_channels_out (`int`, *optional*, defaults to `num_channels`):
+ The number of output channels. If not set, it will be set to `num_channels`.
+ embed_dim (`int`, *optional*, defaults to 180):
+ Dimensionality of patch embedding.
+ depths (`list(int)`, *optional*, defaults to `[6, 6, 6, 6, 6, 6]`):
+ Depth of each layer in the Transformer encoder.
+ num_heads (`list(int)`, *optional*, defaults to `[6, 6, 6, 6, 6, 6]`):
+ Number of attention heads in each layer of the Transformer encoder.
+ window_size (`int`, *optional*, defaults to 8):
+ Size of windows.
+ mlp_ratio (`float`, *optional*, defaults to 2.0):
+ Ratio of MLP hidden dimensionality to embedding dimensionality.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether or not a learnable bias should be added to the queries, keys and values.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings and encoder.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ drop_path_rate (`float`, *optional*, defaults to 0.1):
+ Stochastic depth rate.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder. If string, `"gelu"`, `"relu"`,
+ `"selu"` and `"gelu_new"` are supported.
+ use_absolute_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether or not to add absolute position embeddings to the patch embeddings.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the layer normalization layers.
+ upscale (`int`, *optional*, defaults to 2):
+ The upscale factor for the image. 2/3/4/8 for image super resolution, 1 for denoising and compress artifact
+ reduction
+ img_range (`float`, *optional*, defaults to 1.0):
+ The range of the values of the input image.
+ resi_connection (`str`, *optional*, defaults to `"1conv"`):
+ The convolutional block to use before the residual connection in each stage.
+ upsampler (`str`, *optional*, defaults to `"pixelshuffle"`):
+ The reconstruction reconstruction module. Can be 'pixelshuffle'/'pixelshuffledirect'/'nearest+conv'/None.
+
+ Example:
+
+ ```python
+ >>> from transformers import Swin2SRConfig, Swin2SRModel
+
+ >>> # Initializing a Swin2SR caidas/swin2sr-classicalsr-x2-64 style configuration
+ >>> configuration = Swin2SRConfig()
+
+ >>> # Initializing a model (with random weights) from the caidas/swin2sr-classicalsr-x2-64 style configuration
+ >>> model = Swin2SRModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "swin2sr"
+
+ attribute_map = {
+ "hidden_size": "embed_dim",
+ "num_attention_heads": "num_heads",
+ "num_hidden_layers": "num_layers",
+ }
+
+ def __init__(
+ self,
+ image_size=64,
+ patch_size=1,
+ num_channels=3,
+ num_channels_out=None,
+ embed_dim=180,
+ depths=[6, 6, 6, 6, 6, 6],
+ num_heads=[6, 6, 6, 6, 6, 6],
+ window_size=8,
+ mlp_ratio=2.0,
+ qkv_bias=True,
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ drop_path_rate=0.1,
+ hidden_act="gelu",
+ use_absolute_embeddings=False,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ upscale=2,
+ img_range=1.0,
+ resi_connection="1conv",
+ upsampler="pixelshuffle",
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_channels_out = num_channels if num_channels_out is None else num_channels_out
+ self.embed_dim = embed_dim
+ self.depths = depths
+ self.num_layers = len(depths)
+ self.num_heads = num_heads
+ self.window_size = window_size
+ self.mlp_ratio = mlp_ratio
+ self.qkv_bias = qkv_bias
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.drop_path_rate = drop_path_rate
+ self.hidden_act = hidden_act
+ self.use_absolute_embeddings = use_absolute_embeddings
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.upscale = upscale
+ self.img_range = img_range
+ self.resi_connection = resi_connection
+ self.upsampler = upsampler
+
+
+__all__ = ["Swin2SRConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/image_processing_swin2sr.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/image_processing_swin2sr.py
new file mode 100644
index 0000000000000000000000000000000000000000..8257ca9d8eaa432a876e6689afcd6c9b0295347b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/image_processing_swin2sr.py
@@ -0,0 +1,206 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for Swin2SR."""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature
+from ...image_transforms import get_image_size, pad, to_channel_dimension_format
+from ...image_utils import (
+ ChannelDimension,
+ ImageInput,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Swin2SRImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a Swin2SR image processor.
+
+ Args:
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale`
+ parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the
+ `preprocess` method.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_pad: bool = True,
+ pad_size: int = 8,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_pad = do_pad
+ self.pad_size = pad_size
+
+ def pad(
+ self,
+ image: np.ndarray,
+ size: int,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ):
+ """
+ Pad an image to make the height and width divisible by `size`.
+
+ Args:
+ image (`np.ndarray`):
+ Image to pad.
+ size (`int`):
+ The size to make the height and width divisible by.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format for the output image. If unset, the channel dimension format of the input
+ image is used. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+
+ Returns:
+ `np.ndarray`: The padded image.
+ """
+ old_height, old_width = get_image_size(image, input_data_format)
+ pad_height = (old_height // size + 1) * size - old_height
+ pad_width = (old_width // size + 1) * size - old_width
+
+ return pad(
+ image,
+ ((0, pad_height), (0, pad_width)),
+ mode="symmetric",
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_pad: Optional[bool] = None,
+ pad_size: Optional[int] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Union[str, ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ):
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image to make the height and width divisible by `window_size`.
+ pad_size (`int`, *optional*, defaults to 32):
+ The size of the sliding window for the local attention.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of typ, input_data_format=input_data_format
+ `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_pad = do_pad if do_pad is not None else self.do_pad
+ pad_size = pad_size if pad_size is not None else self.pad_size
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_pad=do_pad,
+ size_divisibility=pad_size, # Here the pad function simply requires pad_size.
+ )
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_pad:
+ images = [self.pad(image, size=pad_size, input_data_format=input_data_format) for image in images]
+
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images
+ ]
+
+ data = {"pixel_values": images}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["Swin2SRImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/image_processing_swin2sr_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/image_processing_swin2sr_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..cc8235f1141ebc281372029224086d0a9899c1dc
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/image_processing_swin2sr_fast.py
@@ -0,0 +1,121 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for Swin2SR."""
+
+from typing import Optional, Union
+
+from ...image_processing_utils import BatchFeature, ChannelDimension, get_image_size
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import ImageInput
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+)
+
+
+if is_torch_available():
+ import torch
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+
+class Swin2SRFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ """
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image to make the height and width divisible by `window_size`.
+ pad_size (`int`, *optional*, defaults to `8`):
+ The size of the sliding window for the local attention.
+ """
+
+ do_pad: Optional[bool]
+ pad_size: Optional[int]
+
+
+@auto_docstring
+class Swin2SRImageProcessorFast(BaseImageProcessorFast):
+ do_rescale = True
+ rescale_factor = 1 / 255
+ do_pad = True
+ pad_size = 8
+ valid_kwargs = Swin2SRFastImageProcessorKwargs
+
+ def __init__(self, **kwargs: Unpack[Swin2SRFastImageProcessorKwargs]):
+ super().__init__(**kwargs)
+
+ def preprocess(self, images: ImageInput, **kwargs: Unpack[Swin2SRFastImageProcessorKwargs]) -> BatchFeature:
+ return super().preprocess(images, **kwargs)
+
+ def pad(self, images: "torch.Tensor", size: int) -> "torch.Tensor":
+ """
+ Pad an image to make the height and width divisible by `size`.
+
+ Args:
+ images (`torch.Tensor`):
+ Images to pad.
+ size (`int`):
+ The size to make the height and width divisible by.
+
+ Returns:
+ `torch.Tensor`: The padded images.
+ """
+ height, width = get_image_size(images, ChannelDimension.FIRST)
+ pad_height = (height // size + 1) * size - height
+ pad_width = (width // size + 1) * size - width
+
+ return F.pad(
+ images,
+ (0, 0, pad_width, pad_height),
+ padding_mode="symmetric",
+ )
+
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ do_rescale: bool,
+ rescale_factor: float,
+ do_pad: bool,
+ pad_size: int,
+ disable_grouping: Optional[bool],
+ return_tensors: Optional[Union[str, TensorType]],
+ **kwargs,
+ ) -> BatchFeature:
+ grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping)
+ processed_image_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ if do_rescale:
+ stacked_images = self.rescale(stacked_images, scale=rescale_factor)
+ if do_pad:
+ stacked_images = self.pad(stacked_images, size=pad_size)
+ processed_image_grouped[shape] = stacked_images
+ processed_images = reorder_images(processed_image_grouped, grouped_images_index)
+ processed_images = torch.stack(processed_images, dim=0) if return_tensors else processed_images
+
+ return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors)
+
+
+__all__ = ["Swin2SRImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/modeling_swin2sr.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/modeling_swin2sr.py
new file mode 100644
index 0000000000000000000000000000000000000000..c2d12e8d78aea6038b2d76777459602e60512cdd
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swin2sr/modeling_swin2sr.py
@@ -0,0 +1,1105 @@
+# coding=utf-8
+# Copyright 2022 Microsoft Research and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Swin2SR Transformer model."""
+
+import collections.abc
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ImageSuperResolutionOutput
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, meshgrid, prune_linear_layer
+from ...utils import ModelOutput, auto_docstring, logging
+from .configuration_swin2sr import Swin2SRConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swin2SR encoder's outputs, with potential hidden states and attentions.
+ """
+)
+class Swin2SREncoderOutput(ModelOutput):
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+# Copied from transformers.models.swin.modeling_swin.window_partition
+def window_partition(input_feature, window_size):
+ """
+ Partitions the given input into windows.
+ """
+ batch_size, height, width, num_channels = input_feature.shape
+ input_feature = input_feature.view(
+ batch_size, height // window_size, window_size, width // window_size, window_size, num_channels
+ )
+ windows = input_feature.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, window_size, window_size, num_channels)
+ return windows
+
+
+# Copied from transformers.models.swin.modeling_swin.window_reverse
+def window_reverse(windows, window_size, height, width):
+ """
+ Merges windows to produce higher resolution features.
+ """
+ num_channels = windows.shape[-1]
+ windows = windows.view(-1, height // window_size, width // window_size, window_size, window_size, num_channels)
+ windows = windows.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, height, width, num_channels)
+ return windows
+
+
+# Copied from transformers.models.beit.modeling_beit.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinDropPath with Swin->Swin2SR
+class Swin2SRDropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: Optional[float] = None) -> None:
+ super().__init__()
+ self.drop_prob = drop_prob
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+class Swin2SREmbeddings(nn.Module):
+ """
+ Construct the patch and optional position embeddings.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.patch_embeddings = Swin2SRPatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+
+ if config.use_absolute_embeddings:
+ self.position_embeddings = nn.Parameter(torch.zeros(1, num_patches + 1, config.embed_dim))
+ else:
+ self.position_embeddings = None
+
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.window_size = config.window_size
+
+ def forward(self, pixel_values: Optional[torch.FloatTensor]) -> tuple[torch.Tensor]:
+ embeddings, output_dimensions = self.patch_embeddings(pixel_values)
+
+ if self.position_embeddings is not None:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings)
+
+ return embeddings, output_dimensions
+
+
+class Swin2SRPatchEmbeddings(nn.Module):
+ def __init__(self, config, normalize_patches=True):
+ super().__init__()
+ num_channels = config.embed_dim
+ image_size, patch_size = config.image_size, config.patch_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ patches_resolution = [image_size[0] // patch_size[0], image_size[1] // patch_size[1]]
+ self.patches_resolution = patches_resolution
+ self.num_patches = patches_resolution[0] * patches_resolution[1]
+
+ self.projection = nn.Conv2d(num_channels, config.embed_dim, kernel_size=patch_size, stride=patch_size)
+ self.layernorm = nn.LayerNorm(config.embed_dim) if normalize_patches else None
+
+ def forward(self, embeddings: Optional[torch.FloatTensor]) -> tuple[torch.Tensor, tuple[int]]:
+ embeddings = self.projection(embeddings)
+ _, _, height, width = embeddings.shape
+ output_dimensions = (height, width)
+ embeddings = embeddings.flatten(2).transpose(1, 2)
+
+ if self.layernorm is not None:
+ embeddings = self.layernorm(embeddings)
+
+ return embeddings, output_dimensions
+
+
+class Swin2SRPatchUnEmbeddings(nn.Module):
+ r"""Image to Patch Unembedding"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.embed_dim = config.embed_dim
+
+ def forward(self, embeddings, x_size):
+ batch_size, height_width, num_channels = embeddings.shape
+ embeddings = embeddings.transpose(1, 2).view(batch_size, self.embed_dim, x_size[0], x_size[1]) # B Ph*Pw C
+ return embeddings
+
+
+# Copied from transformers.models.swinv2.modeling_swinv2.Swinv2PatchMerging with Swinv2->Swin2SR
+class Swin2SRPatchMerging(nn.Module):
+ """
+ Patch Merging Layer.
+
+ Args:
+ input_resolution (`tuple[int]`):
+ Resolution of input feature.
+ dim (`int`):
+ Number of input channels.
+ norm_layer (`nn.Module`, *optional*, defaults to `nn.LayerNorm`):
+ Normalization layer class.
+ """
+
+ def __init__(self, input_resolution: tuple[int], dim: int, norm_layer: nn.Module = nn.LayerNorm) -> None:
+ super().__init__()
+ self.input_resolution = input_resolution
+ self.dim = dim
+ self.reduction = nn.Linear(4 * dim, 2 * dim, bias=False)
+ self.norm = norm_layer(2 * dim)
+
+ def maybe_pad(self, input_feature, height, width):
+ should_pad = (height % 2 == 1) or (width % 2 == 1)
+ if should_pad:
+ pad_values = (0, 0, 0, width % 2, 0, height % 2)
+ input_feature = nn.functional.pad(input_feature, pad_values)
+
+ return input_feature
+
+ def forward(self, input_feature: torch.Tensor, input_dimensions: tuple[int, int]) -> torch.Tensor:
+ height, width = input_dimensions
+ # `dim` is height * width
+ batch_size, dim, num_channels = input_feature.shape
+
+ input_feature = input_feature.view(batch_size, height, width, num_channels)
+ # pad input to be divisible by width and height, if needed
+ input_feature = self.maybe_pad(input_feature, height, width)
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_0 = input_feature[:, 0::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_1 = input_feature[:, 1::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_2 = input_feature[:, 0::2, 1::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_3 = input_feature[:, 1::2, 1::2, :]
+ # [batch_size, height/2 * width/2, 4*num_channels]
+ input_feature = torch.cat([input_feature_0, input_feature_1, input_feature_2, input_feature_3], -1)
+ input_feature = input_feature.view(batch_size, -1, 4 * num_channels) # [batch_size, height/2 * width/2, 4*C]
+
+ input_feature = self.reduction(input_feature)
+ input_feature = self.norm(input_feature)
+
+ return input_feature
+
+
+# Copied from transformers.models.swinv2.modeling_swinv2.Swinv2SelfAttention with Swinv2->Swin2SR
+class Swin2SRSelfAttention(nn.Module):
+ def __init__(self, config, dim, num_heads, window_size, pretrained_window_size=[0, 0]):
+ super().__init__()
+ if dim % num_heads != 0:
+ raise ValueError(
+ f"The hidden size ({dim}) is not a multiple of the number of attention heads ({num_heads})"
+ )
+
+ self.num_attention_heads = num_heads
+ self.attention_head_size = int(dim / num_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.window_size = (
+ window_size if isinstance(window_size, collections.abc.Iterable) else (window_size, window_size)
+ )
+ self.pretrained_window_size = pretrained_window_size
+ self.logit_scale = nn.Parameter(torch.log(10 * torch.ones((num_heads, 1, 1))))
+ # mlp to generate continuous relative position bias
+ self.continuous_position_bias_mlp = nn.Sequential(
+ nn.Linear(2, 512, bias=True), nn.ReLU(inplace=True), nn.Linear(512, num_heads, bias=False)
+ )
+
+ # get relative_coords_table
+ relative_coords_h = torch.arange(-(self.window_size[0] - 1), self.window_size[0], dtype=torch.int64).float()
+ relative_coords_w = torch.arange(-(self.window_size[1] - 1), self.window_size[1], dtype=torch.int64).float()
+ relative_coords_table = (
+ torch.stack(meshgrid([relative_coords_h, relative_coords_w], indexing="ij"))
+ .permute(1, 2, 0)
+ .contiguous()
+ .unsqueeze(0)
+ ) # [1, 2*window_height - 1, 2*window_width - 1, 2]
+ if pretrained_window_size[0] > 0:
+ relative_coords_table[:, :, :, 0] /= pretrained_window_size[0] - 1
+ relative_coords_table[:, :, :, 1] /= pretrained_window_size[1] - 1
+ elif window_size > 1:
+ relative_coords_table[:, :, :, 0] /= self.window_size[0] - 1
+ relative_coords_table[:, :, :, 1] /= self.window_size[1] - 1
+ relative_coords_table *= 8 # normalize to -8, 8
+ relative_coords_table = (
+ torch.sign(relative_coords_table) * torch.log2(torch.abs(relative_coords_table) + 1.0) / math.log2(8)
+ )
+ # set to same dtype as mlp weight
+ relative_coords_table = relative_coords_table.to(next(self.continuous_position_bias_mlp.parameters()).dtype)
+ self.register_buffer("relative_coords_table", relative_coords_table, persistent=False)
+
+ # get pair-wise relative position index for each token inside the window
+ coords_h = torch.arange(self.window_size[0])
+ coords_w = torch.arange(self.window_size[1])
+ coords = torch.stack(meshgrid([coords_h, coords_w], indexing="ij"))
+ coords_flatten = torch.flatten(coords, 1)
+ relative_coords = coords_flatten[:, :, None] - coords_flatten[:, None, :]
+ relative_coords = relative_coords.permute(1, 2, 0).contiguous()
+ relative_coords[:, :, 0] += self.window_size[0] - 1
+ relative_coords[:, :, 1] += self.window_size[1] - 1
+ relative_coords[:, :, 0] *= 2 * self.window_size[1] - 1
+ relative_position_index = relative_coords.sum(-1)
+ self.register_buffer("relative_position_index", relative_position_index, persistent=False)
+
+ self.query = nn.Linear(self.all_head_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(self.all_head_size, self.all_head_size, bias=False)
+ self.value = nn.Linear(self.all_head_size, self.all_head_size, bias=config.qkv_bias)
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ batch_size, dim, num_channels = hidden_states.shape
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ key_layer = (
+ self.key(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ # cosine attention
+ attention_scores = nn.functional.normalize(query_layer, dim=-1) @ nn.functional.normalize(
+ key_layer, dim=-1
+ ).transpose(-2, -1)
+ logit_scale = torch.clamp(self.logit_scale, max=math.log(1.0 / 0.01)).exp()
+ attention_scores = attention_scores * logit_scale
+ relative_position_bias_table = self.continuous_position_bias_mlp(self.relative_coords_table).view(
+ -1, self.num_attention_heads
+ )
+ # [window_height*window_width,window_height*window_width,num_attention_heads]
+ relative_position_bias = relative_position_bias_table[self.relative_position_index.view(-1)].view(
+ self.window_size[0] * self.window_size[1], self.window_size[0] * self.window_size[1], -1
+ )
+ # [num_attention_heads,window_height*window_width,window_height*window_width]
+ relative_position_bias = relative_position_bias.permute(2, 0, 1).contiguous() # nH, Wh*Ww, Wh*Ww
+ relative_position_bias = 16 * torch.sigmoid(relative_position_bias)
+ attention_scores = attention_scores + relative_position_bias.unsqueeze(0)
+
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in Swin2SRModel forward() function)
+ mask_shape = attention_mask.shape[0]
+ attention_scores = attention_scores.view(
+ batch_size // mask_shape, mask_shape, self.num_attention_heads, dim, dim
+ ) + attention_mask.unsqueeze(1).unsqueeze(0)
+ attention_scores = attention_scores + attention_mask.unsqueeze(1).unsqueeze(0)
+ attention_scores = attention_scores.view(-1, self.num_attention_heads, dim, dim)
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinSelfOutput with Swin->Swin2SR
+class Swin2SRSelfOutput(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(dim, dim)
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ return hidden_states
+
+
+# Copied from transformers.models.swinv2.modeling_swinv2.Swinv2Attention with Swinv2->Swin2SR
+class Swin2SRAttention(nn.Module):
+ def __init__(self, config, dim, num_heads, window_size, pretrained_window_size=0):
+ super().__init__()
+ self.self = Swin2SRSelfAttention(
+ config=config,
+ dim=dim,
+ num_heads=num_heads,
+ window_size=window_size,
+ pretrained_window_size=pretrained_window_size
+ if isinstance(pretrained_window_size, collections.abc.Iterable)
+ else (pretrained_window_size, pretrained_window_size),
+ )
+ self.output = Swin2SRSelfOutput(config, dim)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ self_outputs = self.self(hidden_states, attention_mask, head_mask, output_attentions)
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinIntermediate with Swin->Swin2SR
+class Swin2SRIntermediate(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(dim, int(config.mlp_ratio * dim))
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinOutput with Swin->Swin2SR
+class Swin2SROutput(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(int(config.mlp_ratio * dim), dim)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.swinv2.modeling_swinv2.Swinv2Layer with Swinv2->Swin2SR
+class Swin2SRLayer(nn.Module):
+ def __init__(
+ self, config, dim, input_resolution, num_heads, drop_path_rate=0.0, shift_size=0, pretrained_window_size=0
+ ):
+ super().__init__()
+ self.input_resolution = input_resolution
+ window_size, shift_size = self._compute_window_shift(
+ (config.window_size, config.window_size), (shift_size, shift_size)
+ )
+ self.window_size = window_size[0]
+ self.shift_size = shift_size[0]
+ self.attention = Swin2SRAttention(
+ config=config,
+ dim=dim,
+ num_heads=num_heads,
+ window_size=self.window_size,
+ pretrained_window_size=pretrained_window_size
+ if isinstance(pretrained_window_size, collections.abc.Iterable)
+ else (pretrained_window_size, pretrained_window_size),
+ )
+ self.layernorm_before = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+ self.drop_path = Swin2SRDropPath(drop_path_rate) if drop_path_rate > 0.0 else nn.Identity()
+ self.intermediate = Swin2SRIntermediate(config, dim)
+ self.output = Swin2SROutput(config, dim)
+ self.layernorm_after = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+
+ def _compute_window_shift(self, target_window_size, target_shift_size) -> tuple[tuple[int, int], tuple[int, int]]:
+ window_size = [r if r <= w else w for r, w in zip(self.input_resolution, target_window_size)]
+ shift_size = [0 if r <= w else s for r, w, s in zip(self.input_resolution, window_size, target_shift_size)]
+ return window_size, shift_size
+
+ def get_attn_mask(self, height, width, dtype):
+ if self.shift_size > 0:
+ # calculate attention mask for shifted window multihead self attention
+ img_mask = torch.zeros((1, height, width, 1), dtype=dtype)
+ height_slices = (
+ slice(0, -self.window_size),
+ slice(-self.window_size, -self.shift_size),
+ slice(-self.shift_size, None),
+ )
+ width_slices = (
+ slice(0, -self.window_size),
+ slice(-self.window_size, -self.shift_size),
+ slice(-self.shift_size, None),
+ )
+ count = 0
+ for height_slice in height_slices:
+ for width_slice in width_slices:
+ img_mask[:, height_slice, width_slice, :] = count
+ count += 1
+
+ mask_windows = window_partition(img_mask, self.window_size)
+ mask_windows = mask_windows.view(-1, self.window_size * self.window_size)
+ attn_mask = mask_windows.unsqueeze(1) - mask_windows.unsqueeze(2)
+ attn_mask = attn_mask.masked_fill(attn_mask != 0, -100.0).masked_fill(attn_mask == 0, 0.0)
+ else:
+ attn_mask = None
+ return attn_mask
+
+ def maybe_pad(self, hidden_states, height, width):
+ pad_right = (self.window_size - width % self.window_size) % self.window_size
+ pad_bottom = (self.window_size - height % self.window_size) % self.window_size
+ pad_values = (0, 0, 0, pad_right, 0, pad_bottom)
+ hidden_states = nn.functional.pad(hidden_states, pad_values)
+ return hidden_states, pad_values
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ height, width = input_dimensions
+ batch_size, _, channels = hidden_states.size()
+ shortcut = hidden_states
+
+ # pad hidden_states to multiples of window size
+ hidden_states = hidden_states.view(batch_size, height, width, channels)
+ hidden_states, pad_values = self.maybe_pad(hidden_states, height, width)
+ _, height_pad, width_pad, _ = hidden_states.shape
+ # cyclic shift
+ if self.shift_size > 0:
+ shifted_hidden_states = torch.roll(hidden_states, shifts=(-self.shift_size, -self.shift_size), dims=(1, 2))
+ else:
+ shifted_hidden_states = hidden_states
+
+ # partition windows
+ hidden_states_windows = window_partition(shifted_hidden_states, self.window_size)
+ hidden_states_windows = hidden_states_windows.view(-1, self.window_size * self.window_size, channels)
+ attn_mask = self.get_attn_mask(height_pad, width_pad, dtype=hidden_states.dtype)
+ if attn_mask is not None:
+ attn_mask = attn_mask.to(hidden_states_windows.device)
+
+ attention_outputs = self.attention(
+ hidden_states_windows, attn_mask, head_mask, output_attentions=output_attentions
+ )
+
+ attention_output = attention_outputs[0]
+
+ attention_windows = attention_output.view(-1, self.window_size, self.window_size, channels)
+ shifted_windows = window_reverse(attention_windows, self.window_size, height_pad, width_pad)
+
+ # reverse cyclic shift
+ if self.shift_size > 0:
+ attention_windows = torch.roll(shifted_windows, shifts=(self.shift_size, self.shift_size), dims=(1, 2))
+ else:
+ attention_windows = shifted_windows
+
+ was_padded = pad_values[3] > 0 or pad_values[5] > 0
+ if was_padded:
+ attention_windows = attention_windows[:, :height, :width, :].contiguous()
+
+ attention_windows = attention_windows.view(batch_size, height * width, channels)
+ hidden_states = self.layernorm_before(attention_windows)
+ hidden_states = shortcut + self.drop_path(hidden_states)
+
+ layer_output = self.intermediate(hidden_states)
+ layer_output = self.output(layer_output)
+ layer_output = hidden_states + self.drop_path(self.layernorm_after(layer_output))
+
+ layer_outputs = (layer_output, attention_outputs[1]) if output_attentions else (layer_output,)
+ return layer_outputs
+
+
+class Swin2SRStage(GradientCheckpointingLayer):
+ """
+ This corresponds to the Residual Swin Transformer Block (RSTB) in the original implementation.
+ """
+
+ def __init__(self, config, dim, input_resolution, depth, num_heads, drop_path, pretrained_window_size=0):
+ super().__init__()
+ self.config = config
+ self.dim = dim
+ self.layers = nn.ModuleList(
+ [
+ Swin2SRLayer(
+ config=config,
+ dim=dim,
+ input_resolution=input_resolution,
+ num_heads=num_heads,
+ shift_size=0 if (i % 2 == 0) else config.window_size // 2,
+ pretrained_window_size=pretrained_window_size,
+ )
+ for i in range(depth)
+ ]
+ )
+
+ if config.resi_connection == "1conv":
+ self.conv = nn.Conv2d(dim, dim, 3, 1, 1)
+ elif config.resi_connection == "3conv":
+ # to save parameters and memory
+ self.conv = nn.Sequential(
+ nn.Conv2d(dim, dim // 4, 3, 1, 1),
+ nn.LeakyReLU(negative_slope=0.2, inplace=True),
+ nn.Conv2d(dim // 4, dim // 4, 1, 1, 0),
+ nn.LeakyReLU(negative_slope=0.2, inplace=True),
+ nn.Conv2d(dim // 4, dim, 3, 1, 1),
+ )
+
+ self.patch_embed = Swin2SRPatchEmbeddings(config, normalize_patches=False)
+
+ self.patch_unembed = Swin2SRPatchUnEmbeddings(config)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ residual = hidden_states
+
+ height, width = input_dimensions
+ for i, layer_module in enumerate(self.layers):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(hidden_states, input_dimensions, layer_head_mask, output_attentions)
+
+ hidden_states = layer_outputs[0]
+
+ output_dimensions = (height, width, height, width)
+
+ hidden_states = self.patch_unembed(hidden_states, input_dimensions)
+ hidden_states = self.conv(hidden_states)
+ hidden_states, _ = self.patch_embed(hidden_states)
+
+ hidden_states = hidden_states + residual
+
+ stage_outputs = (hidden_states, output_dimensions)
+
+ if output_attentions:
+ stage_outputs += layer_outputs[1:]
+ return stage_outputs
+
+
+class Swin2SREncoder(nn.Module):
+ def __init__(self, config, grid_size):
+ super().__init__()
+ self.num_stages = len(config.depths)
+ self.config = config
+ dpr = [x.item() for x in torch.linspace(0, config.drop_path_rate, sum(config.depths), device="cpu")]
+ self.stages = nn.ModuleList(
+ [
+ Swin2SRStage(
+ config=config,
+ dim=config.embed_dim,
+ input_resolution=(grid_size[0], grid_size[1]),
+ depth=config.depths[stage_idx],
+ num_heads=config.num_heads[stage_idx],
+ drop_path=dpr[sum(config.depths[:stage_idx]) : sum(config.depths[: stage_idx + 1])],
+ pretrained_window_size=0,
+ )
+ for stage_idx in range(self.num_stages)
+ ]
+ )
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ ) -> Union[tuple, Swin2SREncoderOutput]:
+ all_input_dimensions = ()
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ for i, stage_module in enumerate(self.stages):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = stage_module(hidden_states, input_dimensions, layer_head_mask, output_attentions)
+
+ hidden_states = layer_outputs[0]
+ output_dimensions = layer_outputs[1]
+
+ input_dimensions = (output_dimensions[-2], output_dimensions[-1])
+ all_input_dimensions += (input_dimensions,)
+
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if output_attentions:
+ all_self_attentions += layer_outputs[2:]
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+
+ return Swin2SREncoderOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+@auto_docstring
+class Swin2SRPreTrainedModel(PreTrainedModel):
+ config: Swin2SRConfig
+ base_model_prefix = "swin2sr"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ torch.nn.init.trunc_normal_(module.weight.data, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+@auto_docstring
+class Swin2SRModel(Swin2SRPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ if config.num_channels == 3 and config.num_channels_out == 3:
+ mean = torch.tensor([0.4488, 0.4371, 0.4040]).view(1, 3, 1, 1)
+ else:
+ mean = torch.zeros(1, 1, 1, 1)
+ self.register_buffer("mean", mean, persistent=False)
+
+ self.img_range = config.img_range
+
+ self.first_convolution = nn.Conv2d(config.num_channels, config.embed_dim, 3, 1, 1)
+ self.embeddings = Swin2SREmbeddings(config)
+ self.encoder = Swin2SREncoder(config, grid_size=self.embeddings.patch_embeddings.patches_resolution)
+
+ self.layernorm = nn.LayerNorm(config.embed_dim, eps=config.layer_norm_eps)
+ self.patch_unembed = Swin2SRPatchUnEmbeddings(config)
+ self.conv_after_body = nn.Conv2d(config.embed_dim, config.embed_dim, 3, 1, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ def pad_and_normalize(self, pixel_values):
+ _, _, height, width = pixel_values.size()
+
+ # 1. pad
+ window_size = self.config.window_size
+ modulo_pad_height = (window_size - height % window_size) % window_size
+ modulo_pad_width = (window_size - width % window_size) % window_size
+ pixel_values = nn.functional.pad(pixel_values, (0, modulo_pad_width, 0, modulo_pad_height), "reflect")
+
+ # 2. normalize
+ mean = self.mean.type_as(pixel_values)
+ pixel_values = (pixel_values - mean) * self.img_range
+
+ return pixel_values
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, len(self.config.depths))
+
+ _, _, height, width = pixel_values.shape
+
+ # some preprocessing: padding + normalization
+ pixel_values = self.pad_and_normalize(pixel_values)
+
+ embeddings = self.first_convolution(pixel_values)
+ embedding_output, input_dimensions = self.embeddings(embeddings)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ input_dimensions,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = encoder_outputs[0]
+ sequence_output = self.layernorm(sequence_output)
+
+ sequence_output = self.patch_unembed(sequence_output, (height, width))
+ sequence_output = self.conv_after_body(sequence_output) + embeddings
+
+ if not return_dict:
+ output = (sequence_output,) + encoder_outputs[1:]
+
+ return output
+
+ return BaseModelOutput(
+ last_hidden_state=sequence_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class Upsample(nn.Module):
+ """Upsample module.
+
+ Args:
+ scale (`int`):
+ Scale factor. Supported scales: 2^n and 3.
+ num_features (`int`):
+ Channel number of intermediate features.
+ """
+
+ def __init__(self, scale, num_features):
+ super().__init__()
+
+ self.scale = scale
+ if (scale & (scale - 1)) == 0:
+ # scale = 2^n
+ for i in range(int(math.log(scale, 2))):
+ self.add_module(f"convolution_{i}", nn.Conv2d(num_features, 4 * num_features, 3, 1, 1))
+ self.add_module(f"pixelshuffle_{i}", nn.PixelShuffle(2))
+ elif scale == 3:
+ self.convolution = nn.Conv2d(num_features, 9 * num_features, 3, 1, 1)
+ self.pixelshuffle = nn.PixelShuffle(3)
+ else:
+ raise ValueError(f"Scale {scale} is not supported. Supported scales: 2^n and 3.")
+
+ def forward(self, hidden_state):
+ if (self.scale & (self.scale - 1)) == 0:
+ for i in range(int(math.log(self.scale, 2))):
+ hidden_state = self.__getattr__(f"convolution_{i}")(hidden_state)
+ hidden_state = self.__getattr__(f"pixelshuffle_{i}")(hidden_state)
+
+ elif self.scale == 3:
+ hidden_state = self.convolution(hidden_state)
+ hidden_state = self.pixelshuffle(hidden_state)
+
+ return hidden_state
+
+
+class UpsampleOneStep(nn.Module):
+ """UpsampleOneStep module (the difference with Upsample is that it always only has 1conv + 1pixelshuffle)
+
+ Used in lightweight SR to save parameters.
+
+ Args:
+ scale (int):
+ Scale factor. Supported scales: 2^n and 3.
+ in_channels (int):
+ Channel number of intermediate features.
+ out_channels (int):
+ Channel number of output features.
+ """
+
+ def __init__(self, scale, in_channels, out_channels):
+ super().__init__()
+
+ self.conv = nn.Conv2d(in_channels, (scale**2) * out_channels, 3, 1, 1)
+ self.pixel_shuffle = nn.PixelShuffle(scale)
+
+ def forward(self, x):
+ x = self.conv(x)
+ x = self.pixel_shuffle(x)
+
+ return x
+
+
+class PixelShuffleUpsampler(nn.Module):
+ def __init__(self, config, num_features):
+ super().__init__()
+ self.conv_before_upsample = nn.Conv2d(config.embed_dim, num_features, 3, 1, 1)
+ self.activation = nn.LeakyReLU(inplace=True)
+ self.upsample = Upsample(config.upscale, num_features)
+ self.final_convolution = nn.Conv2d(num_features, config.num_channels_out, 3, 1, 1)
+
+ def forward(self, sequence_output):
+ x = self.conv_before_upsample(sequence_output)
+ x = self.activation(x)
+ x = self.upsample(x)
+ x = self.final_convolution(x)
+
+ return x
+
+
+class NearestConvUpsampler(nn.Module):
+ def __init__(self, config, num_features):
+ super().__init__()
+ if config.upscale != 4:
+ raise ValueError("The nearest+conv upsampler only supports an upscale factor of 4 at the moment.")
+
+ self.conv_before_upsample = nn.Conv2d(config.embed_dim, num_features, 3, 1, 1)
+ self.activation = nn.LeakyReLU(inplace=True)
+ self.conv_up1 = nn.Conv2d(num_features, num_features, 3, 1, 1)
+ self.conv_up2 = nn.Conv2d(num_features, num_features, 3, 1, 1)
+ self.conv_hr = nn.Conv2d(num_features, num_features, 3, 1, 1)
+ self.final_convolution = nn.Conv2d(num_features, config.num_channels_out, 3, 1, 1)
+ self.lrelu = nn.LeakyReLU(negative_slope=0.2, inplace=True)
+
+ def forward(self, sequence_output):
+ sequence_output = self.conv_before_upsample(sequence_output)
+ sequence_output = self.activation(sequence_output)
+ sequence_output = self.lrelu(
+ self.conv_up1(torch.nn.functional.interpolate(sequence_output, scale_factor=2, mode="nearest"))
+ )
+ sequence_output = self.lrelu(
+ self.conv_up2(torch.nn.functional.interpolate(sequence_output, scale_factor=2, mode="nearest"))
+ )
+ reconstruction = self.final_convolution(self.lrelu(self.conv_hr(sequence_output)))
+ return reconstruction
+
+
+class PixelShuffleAuxUpsampler(nn.Module):
+ def __init__(self, config, num_features):
+ super().__init__()
+
+ self.upscale = config.upscale
+ self.conv_bicubic = nn.Conv2d(config.num_channels, num_features, 3, 1, 1)
+ self.conv_before_upsample = nn.Conv2d(config.embed_dim, num_features, 3, 1, 1)
+ self.activation = nn.LeakyReLU(inplace=True)
+ self.conv_aux = nn.Conv2d(num_features, config.num_channels, 3, 1, 1)
+ self.conv_after_aux = nn.Sequential(nn.Conv2d(3, num_features, 3, 1, 1), nn.LeakyReLU(inplace=True))
+ self.upsample = Upsample(config.upscale, num_features)
+ self.final_convolution = nn.Conv2d(num_features, config.num_channels_out, 3, 1, 1)
+
+ def forward(self, sequence_output, bicubic, height, width):
+ bicubic = self.conv_bicubic(bicubic)
+ sequence_output = self.conv_before_upsample(sequence_output)
+ sequence_output = self.activation(sequence_output)
+ aux = self.conv_aux(sequence_output)
+ sequence_output = self.conv_after_aux(aux)
+ sequence_output = (
+ self.upsample(sequence_output)[:, :, : height * self.upscale, : width * self.upscale]
+ + bicubic[:, :, : height * self.upscale, : width * self.upscale]
+ )
+ reconstruction = self.final_convolution(sequence_output)
+
+ return reconstruction, aux
+
+
+@auto_docstring(
+ custom_intro="""
+ Swin2SR Model transformer with an upsampler head on top for image super resolution and restoration.
+ """
+)
+class Swin2SRForImageSuperResolution(Swin2SRPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.swin2sr = Swin2SRModel(config)
+ self.upsampler = config.upsampler
+ self.upscale = config.upscale
+
+ # Upsampler
+ num_features = 64
+ if self.upsampler == "pixelshuffle":
+ self.upsample = PixelShuffleUpsampler(config, num_features)
+ elif self.upsampler == "pixelshuffle_aux":
+ self.upsample = PixelShuffleAuxUpsampler(config, num_features)
+ elif self.upsampler == "pixelshuffledirect":
+ # for lightweight SR (to save parameters)
+ self.upsample = UpsampleOneStep(config.upscale, config.embed_dim, config.num_channels_out)
+ elif self.upsampler == "nearest+conv":
+ # for real-world SR (less artifacts)
+ self.upsample = NearestConvUpsampler(config, num_features)
+ else:
+ # for image denoising and JPEG compression artifact reduction
+ self.final_convolution = nn.Conv2d(config.embed_dim, config.num_channels_out, 3, 1, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, ImageSuperResolutionOutput]:
+ r"""
+ Example:
+ ```python
+ >>> import torch
+ >>> import numpy as np
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> from transformers import AutoImageProcessor, Swin2SRForImageSuperResolution
+
+ >>> processor = AutoImageProcessor.from_pretrained("caidas/swin2SR-classical-sr-x2-64")
+ >>> model = Swin2SRForImageSuperResolution.from_pretrained("caidas/swin2SR-classical-sr-x2-64")
+
+ >>> url = "https://huggingface.co/spaces/jjourney1125/swin2sr/resolve/main/samples/butterfly.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+ >>> # prepare image for the model
+ >>> inputs = processor(image, return_tensors="pt")
+
+ >>> # forward pass
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+
+ >>> output = outputs.reconstruction.data.squeeze().float().cpu().clamp_(0, 1).numpy()
+ >>> output = np.moveaxis(output, source=0, destination=-1)
+ >>> output = (output * 255.0).round().astype(np.uint8) # float32 to uint8
+ >>> # you can visualize `output` with `Image.fromarray`
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ loss = None
+ if labels is not None:
+ raise NotImplementedError("Training is not supported at the moment")
+
+ height, width = pixel_values.shape[2:]
+
+ if self.config.upsampler == "pixelshuffle_aux":
+ bicubic = nn.functional.interpolate(
+ pixel_values,
+ size=(height * self.upscale, width * self.upscale),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ outputs = self.swin2sr(
+ pixel_values,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ if self.upsampler in ["pixelshuffle", "pixelshuffledirect", "nearest+conv"]:
+ reconstruction = self.upsample(sequence_output)
+ elif self.upsampler == "pixelshuffle_aux":
+ reconstruction, aux = self.upsample(sequence_output, bicubic, height, width)
+ aux = aux / self.swin2sr.img_range + self.swin2sr.mean
+ else:
+ reconstruction = pixel_values + self.final_convolution(sequence_output)
+
+ reconstruction = reconstruction / self.swin2sr.img_range + self.swin2sr.mean
+ reconstruction = reconstruction[:, :, : height * self.upscale, : width * self.upscale]
+
+ if not return_dict:
+ output = (reconstruction,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return ImageSuperResolutionOutput(
+ loss=loss,
+ reconstruction=reconstruction,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["Swin2SRForImageSuperResolution", "Swin2SRModel", "Swin2SRPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..172f1573f1eb1bca4893b2495879346c0b044b9c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_swinv2 import *
+ from .modeling_swinv2 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/configuration_swinv2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/configuration_swinv2.py
new file mode 100644
index 0000000000000000000000000000000000000000..8fe493259082bd8596a480afb6ae52bf10a49dee
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/configuration_swinv2.py
@@ -0,0 +1,159 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Swinv2 Transformer model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ...utils.backbone_utils import BackboneConfigMixin, get_aligned_output_features_output_indices
+
+
+logger = logging.get_logger(__name__)
+
+
+class Swinv2Config(BackboneConfigMixin, PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Swinv2Model`]. It is used to instantiate a Swin
+ Transformer v2 model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the Swin Transformer v2
+ [microsoft/swinv2-tiny-patch4-window8-256](https://huggingface.co/microsoft/swinv2-tiny-patch4-window8-256)
+ architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 4):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ embed_dim (`int`, *optional*, defaults to 96):
+ Dimensionality of patch embedding.
+ depths (`list(int)`, *optional*, defaults to `[2, 2, 6, 2]`):
+ Depth of each layer in the Transformer encoder.
+ num_heads (`list(int)`, *optional*, defaults to `[3, 6, 12, 24]`):
+ Number of attention heads in each layer of the Transformer encoder.
+ window_size (`int`, *optional*, defaults to 7):
+ Size of windows.
+ pretrained_window_sizes (`list(int)`, *optional*, defaults to `[0, 0, 0, 0]`):
+ Size of windows during pretraining.
+ mlp_ratio (`float`, *optional*, defaults to 4.0):
+ Ratio of MLP hidden dimensionality to embedding dimensionality.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether or not a learnable bias should be added to the queries, keys and values.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings and encoder.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ drop_path_rate (`float`, *optional*, defaults to 0.1):
+ Stochastic depth rate.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder. If string, `"gelu"`, `"relu"`,
+ `"selu"` and `"gelu_new"` are supported.
+ use_absolute_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether or not to add absolute position embeddings to the patch embeddings.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the layer normalization layers.
+ encoder_stride (`int`, *optional*, defaults to 32):
+ Factor to increase the spatial resolution by in the decoder head for masked image modeling.
+ out_features (`list[str]`, *optional*):
+ If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc.
+ (depending on how many stages the model has). If unset and `out_indices` is set, will default to the
+ corresponding stages. If unset and `out_indices` is unset, will default to the last stage.
+ out_indices (`list[int]`, *optional*):
+ If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how
+ many stages the model has). If unset and `out_features` is set, will default to the corresponding stages.
+ If unset and `out_features` is unset, will default to the last stage.
+
+ Example:
+
+ ```python
+ >>> from transformers import Swinv2Config, Swinv2Model
+
+ >>> # Initializing a Swinv2 microsoft/swinv2-tiny-patch4-window8-256 style configuration
+ >>> configuration = Swinv2Config()
+
+ >>> # Initializing a model (with random weights) from the microsoft/swinv2-tiny-patch4-window8-256 style configuration
+ >>> model = Swinv2Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "swinv2"
+
+ attribute_map = {
+ "num_attention_heads": "num_heads",
+ "num_hidden_layers": "num_layers",
+ }
+
+ def __init__(
+ self,
+ image_size=224,
+ patch_size=4,
+ num_channels=3,
+ embed_dim=96,
+ depths=[2, 2, 6, 2],
+ num_heads=[3, 6, 12, 24],
+ window_size=7,
+ pretrained_window_sizes=[0, 0, 0, 0],
+ mlp_ratio=4.0,
+ qkv_bias=True,
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ drop_path_rate=0.1,
+ hidden_act="gelu",
+ use_absolute_embeddings=False,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ encoder_stride=32,
+ out_features=None,
+ out_indices=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.embed_dim = embed_dim
+ self.depths = depths
+ self.num_layers = len(depths)
+ self.num_heads = num_heads
+ self.window_size = window_size
+ self.pretrained_window_sizes = pretrained_window_sizes
+ self.mlp_ratio = mlp_ratio
+ self.qkv_bias = qkv_bias
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.drop_path_rate = drop_path_rate
+ self.hidden_act = hidden_act
+ self.use_absolute_embeddings = use_absolute_embeddings
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.encoder_stride = encoder_stride
+ self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, len(depths) + 1)]
+ self._out_features, self._out_indices = get_aligned_output_features_output_indices(
+ out_features=out_features, out_indices=out_indices, stage_names=self.stage_names
+ )
+ # we set the hidden_size attribute in order to make Swinv2 work with VisionEncoderDecoderModel
+ # this indicates the channel dimension after the last stage of the model
+ self.hidden_size = int(embed_dim * 2 ** (len(depths) - 1))
+
+
+__all__ = ["Swinv2Config"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/modeling_swinv2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/modeling_swinv2.py
new file mode 100644
index 0000000000000000000000000000000000000000..57731192d769e7a5d69e1c561c4f0c77d6b2c536
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/swinv2/modeling_swinv2.py
@@ -0,0 +1,1343 @@
+# coding=utf-8
+# Copyright 2022 Microsoft Research and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Swinv2 Transformer model."""
+
+import collections.abc
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import Tensor, nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BackboneOutput
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, meshgrid, prune_linear_layer
+from ...utils import ModelOutput, auto_docstring, logging, torch_int
+from ...utils.backbone_utils import BackboneMixin
+from .configuration_swinv2 import Swinv2Config
+
+
+logger = logging.get_logger(__name__)
+
+
+# drop_path, Swinv2PatchEmbeddings, Swinv2PatchMerging and Swinv2DropPath are from https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/swin_transformer_v2.py.
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swinv2 encoder's outputs, with potential hidden states and attentions.
+ """
+)
+# Copied from transformers.models.swin.modeling_swin.SwinEncoderOutput with Swin->Swinv2
+class Swinv2EncoderOutput(ModelOutput):
+ r"""
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swinv2 model's outputs that also contains a pooling of the last hidden states.
+ """
+)
+# Copied from transformers.models.swin.modeling_swin.SwinModelOutput with Swin->Swinv2
+class Swinv2ModelOutput(ModelOutput):
+ r"""
+ pooler_output (`torch.FloatTensor` of shape `(batch_size, hidden_size)`, *optional*, returned when `add_pooling_layer=True` is passed):
+ Average pooling of the last layer hidden-state.
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ pooler_output: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swinv2 masked image model outputs.
+ """
+)
+# Copied from transformers.models.swin.modeling_swin.SwinMaskedImageModelingOutput with Swin->Swinv2
+class Swinv2MaskedImageModelingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `bool_masked_pos` is provided):
+ Masked image modeling (MLM) loss.
+ reconstruction (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ Reconstructed pixel values.
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ reconstruction: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+ @property
+ def logits(self):
+ warnings.warn(
+ "logits attribute is deprecated and will be removed in version 5 of Transformers."
+ " Please use the reconstruction attribute to retrieve the final output instead.",
+ FutureWarning,
+ )
+ return self.reconstruction
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Swinv2 outputs for image classification.
+ """
+)
+# Copied from transformers.models.swin.modeling_swin.SwinImageClassifierOutput with Swin->Swinv2
+class Swinv2ImageClassifierOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ reshaped_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each stage) of
+ shape `(batch_size, hidden_size, height, width)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs reshaped to
+ include the spatial dimensions.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ reshaped_hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+# Copied from transformers.models.swin.modeling_swin.window_partition
+def window_partition(input_feature, window_size):
+ """
+ Partitions the given input into windows.
+ """
+ batch_size, height, width, num_channels = input_feature.shape
+ input_feature = input_feature.view(
+ batch_size, height // window_size, window_size, width // window_size, window_size, num_channels
+ )
+ windows = input_feature.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, window_size, window_size, num_channels)
+ return windows
+
+
+# Copied from transformers.models.swin.modeling_swin.window_reverse
+def window_reverse(windows, window_size, height, width):
+ """
+ Merges windows to produce higher resolution features.
+ """
+ num_channels = windows.shape[-1]
+ windows = windows.view(-1, height // window_size, width // window_size, window_size, window_size, num_channels)
+ windows = windows.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, height, width, num_channels)
+ return windows
+
+
+# Copied from transformers.models.swin.modeling_swin.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinDropPath with Swin->Swinv2
+class Swinv2DropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: Optional[float] = None) -> None:
+ super().__init__()
+ self.drop_prob = drop_prob
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinEmbeddings with Swin->Swinv2
+class Swinv2Embeddings(nn.Module):
+ """
+ Construct the patch and position embeddings. Optionally, also the mask token.
+ """
+
+ def __init__(self, config, use_mask_token=False):
+ super().__init__()
+
+ self.patch_embeddings = Swinv2PatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+ self.patch_grid = self.patch_embeddings.grid_size
+ self.mask_token = nn.Parameter(torch.zeros(1, 1, config.embed_dim)) if use_mask_token else None
+
+ if config.use_absolute_embeddings:
+ self.position_embeddings = nn.Parameter(torch.zeros(1, num_patches + 1, config.embed_dim))
+ else:
+ self.position_embeddings = None
+
+ self.norm = nn.LayerNorm(config.embed_dim)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.patch_size = config.patch_size
+ self.config = config
+
+ # Copied from transformers.models.vit.modeling_vit.ViTEmbeddings.interpolate_pos_encoding
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ num_positions = self.position_embeddings.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embeddings
+
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor],
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> tuple[torch.Tensor]:
+ _, num_channels, height, width = pixel_values.shape
+ embeddings, output_dimensions = self.patch_embeddings(pixel_values)
+ embeddings = self.norm(embeddings)
+ batch_size, seq_len, _ = embeddings.size()
+
+ if bool_masked_pos is not None:
+ mask_tokens = self.mask_token.expand(batch_size, seq_len, -1)
+ # replace the masked visual tokens by mask_tokens
+ mask = bool_masked_pos.unsqueeze(-1).type_as(mask_tokens)
+ embeddings = embeddings * (1.0 - mask) + mask_tokens * mask
+
+ if self.position_embeddings is not None:
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings)
+
+ return embeddings, output_dimensions
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinPatchEmbeddings with Swin->Swinv2
+class Swinv2PatchEmbeddings(nn.Module):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.embed_dim
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+ self.grid_size = (image_size[0] // patch_size[0], image_size[1] // patch_size[1])
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def maybe_pad(self, pixel_values, height, width):
+ if width % self.patch_size[1] != 0:
+ pad_values = (0, self.patch_size[1] - width % self.patch_size[1])
+ pixel_values = nn.functional.pad(pixel_values, pad_values)
+ if height % self.patch_size[0] != 0:
+ pad_values = (0, 0, 0, self.patch_size[0] - height % self.patch_size[0])
+ pixel_values = nn.functional.pad(pixel_values, pad_values)
+ return pixel_values
+
+ def forward(self, pixel_values: Optional[torch.FloatTensor]) -> tuple[torch.Tensor, tuple[int]]:
+ _, num_channels, height, width = pixel_values.shape
+ # pad the input to be divisible by self.patch_size, if needed
+ pixel_values = self.maybe_pad(pixel_values, height, width)
+ embeddings = self.projection(pixel_values)
+ _, _, height, width = embeddings.shape
+ output_dimensions = (height, width)
+ embeddings = embeddings.flatten(2).transpose(1, 2)
+
+ return embeddings, output_dimensions
+
+
+class Swinv2PatchMerging(nn.Module):
+ """
+ Patch Merging Layer.
+
+ Args:
+ input_resolution (`tuple[int]`):
+ Resolution of input feature.
+ dim (`int`):
+ Number of input channels.
+ norm_layer (`nn.Module`, *optional*, defaults to `nn.LayerNorm`):
+ Normalization layer class.
+ """
+
+ def __init__(self, input_resolution: tuple[int], dim: int, norm_layer: nn.Module = nn.LayerNorm) -> None:
+ super().__init__()
+ self.input_resolution = input_resolution
+ self.dim = dim
+ self.reduction = nn.Linear(4 * dim, 2 * dim, bias=False)
+ self.norm = norm_layer(2 * dim)
+
+ def maybe_pad(self, input_feature, height, width):
+ should_pad = (height % 2 == 1) or (width % 2 == 1)
+ if should_pad:
+ pad_values = (0, 0, 0, width % 2, 0, height % 2)
+ input_feature = nn.functional.pad(input_feature, pad_values)
+
+ return input_feature
+
+ def forward(self, input_feature: torch.Tensor, input_dimensions: tuple[int, int]) -> torch.Tensor:
+ height, width = input_dimensions
+ # `dim` is height * width
+ batch_size, dim, num_channels = input_feature.shape
+
+ input_feature = input_feature.view(batch_size, height, width, num_channels)
+ # pad input to be divisible by width and height, if needed
+ input_feature = self.maybe_pad(input_feature, height, width)
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_0 = input_feature[:, 0::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_1 = input_feature[:, 1::2, 0::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_2 = input_feature[:, 0::2, 1::2, :]
+ # [batch_size, height/2, width/2, num_channels]
+ input_feature_3 = input_feature[:, 1::2, 1::2, :]
+ # [batch_size, height/2 * width/2, 4*num_channels]
+ input_feature = torch.cat([input_feature_0, input_feature_1, input_feature_2, input_feature_3], -1)
+ input_feature = input_feature.view(batch_size, -1, 4 * num_channels) # [batch_size, height/2 * width/2, 4*C]
+
+ input_feature = self.reduction(input_feature)
+ input_feature = self.norm(input_feature)
+
+ return input_feature
+
+
+class Swinv2SelfAttention(nn.Module):
+ def __init__(self, config, dim, num_heads, window_size, pretrained_window_size=[0, 0]):
+ super().__init__()
+ if dim % num_heads != 0:
+ raise ValueError(
+ f"The hidden size ({dim}) is not a multiple of the number of attention heads ({num_heads})"
+ )
+
+ self.num_attention_heads = num_heads
+ self.attention_head_size = int(dim / num_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.window_size = (
+ window_size if isinstance(window_size, collections.abc.Iterable) else (window_size, window_size)
+ )
+ self.pretrained_window_size = pretrained_window_size
+ self.logit_scale = nn.Parameter(torch.log(10 * torch.ones((num_heads, 1, 1))))
+ # mlp to generate continuous relative position bias
+ self.continuous_position_bias_mlp = nn.Sequential(
+ nn.Linear(2, 512, bias=True), nn.ReLU(inplace=True), nn.Linear(512, num_heads, bias=False)
+ )
+
+ # get relative_coords_table
+ relative_coords_h = torch.arange(-(self.window_size[0] - 1), self.window_size[0], dtype=torch.int64).float()
+ relative_coords_w = torch.arange(-(self.window_size[1] - 1), self.window_size[1], dtype=torch.int64).float()
+ relative_coords_table = (
+ torch.stack(meshgrid([relative_coords_h, relative_coords_w], indexing="ij"))
+ .permute(1, 2, 0)
+ .contiguous()
+ .unsqueeze(0)
+ ) # [1, 2*window_height - 1, 2*window_width - 1, 2]
+ if pretrained_window_size[0] > 0:
+ relative_coords_table[:, :, :, 0] /= pretrained_window_size[0] - 1
+ relative_coords_table[:, :, :, 1] /= pretrained_window_size[1] - 1
+ elif window_size > 1:
+ relative_coords_table[:, :, :, 0] /= self.window_size[0] - 1
+ relative_coords_table[:, :, :, 1] /= self.window_size[1] - 1
+ relative_coords_table *= 8 # normalize to -8, 8
+ relative_coords_table = (
+ torch.sign(relative_coords_table) * torch.log2(torch.abs(relative_coords_table) + 1.0) / math.log2(8)
+ )
+ # set to same dtype as mlp weight
+ relative_coords_table = relative_coords_table.to(next(self.continuous_position_bias_mlp.parameters()).dtype)
+ self.register_buffer("relative_coords_table", relative_coords_table, persistent=False)
+
+ # get pair-wise relative position index for each token inside the window
+ coords_h = torch.arange(self.window_size[0])
+ coords_w = torch.arange(self.window_size[1])
+ coords = torch.stack(meshgrid([coords_h, coords_w], indexing="ij"))
+ coords_flatten = torch.flatten(coords, 1)
+ relative_coords = coords_flatten[:, :, None] - coords_flatten[:, None, :]
+ relative_coords = relative_coords.permute(1, 2, 0).contiguous()
+ relative_coords[:, :, 0] += self.window_size[0] - 1
+ relative_coords[:, :, 1] += self.window_size[1] - 1
+ relative_coords[:, :, 0] *= 2 * self.window_size[1] - 1
+ relative_position_index = relative_coords.sum(-1)
+ self.register_buffer("relative_position_index", relative_position_index, persistent=False)
+
+ self.query = nn.Linear(self.all_head_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(self.all_head_size, self.all_head_size, bias=False)
+ self.value = nn.Linear(self.all_head_size, self.all_head_size, bias=config.qkv_bias)
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ batch_size, dim, num_channels = hidden_states.shape
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ key_layer = (
+ self.key(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ # cosine attention
+ attention_scores = nn.functional.normalize(query_layer, dim=-1) @ nn.functional.normalize(
+ key_layer, dim=-1
+ ).transpose(-2, -1)
+ logit_scale = torch.clamp(self.logit_scale, max=math.log(1.0 / 0.01)).exp()
+ attention_scores = attention_scores * logit_scale
+ relative_position_bias_table = self.continuous_position_bias_mlp(self.relative_coords_table).view(
+ -1, self.num_attention_heads
+ )
+ # [window_height*window_width,window_height*window_width,num_attention_heads]
+ relative_position_bias = relative_position_bias_table[self.relative_position_index.view(-1)].view(
+ self.window_size[0] * self.window_size[1], self.window_size[0] * self.window_size[1], -1
+ )
+ # [num_attention_heads,window_height*window_width,window_height*window_width]
+ relative_position_bias = relative_position_bias.permute(2, 0, 1).contiguous() # nH, Wh*Ww, Wh*Ww
+ relative_position_bias = 16 * torch.sigmoid(relative_position_bias)
+ attention_scores = attention_scores + relative_position_bias.unsqueeze(0)
+
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in Swinv2Model forward() function)
+ mask_shape = attention_mask.shape[0]
+ attention_scores = attention_scores.view(
+ batch_size // mask_shape, mask_shape, self.num_attention_heads, dim, dim
+ ) + attention_mask.unsqueeze(1).unsqueeze(0)
+ attention_scores = attention_scores + attention_mask.unsqueeze(1).unsqueeze(0)
+ attention_scores = attention_scores.view(-1, self.num_attention_heads, dim, dim)
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinSelfOutput with Swin->Swinv2
+class Swinv2SelfOutput(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(dim, dim)
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ return hidden_states
+
+
+class Swinv2Attention(nn.Module):
+ def __init__(self, config, dim, num_heads, window_size, pretrained_window_size=0):
+ super().__init__()
+ self.self = Swinv2SelfAttention(
+ config=config,
+ dim=dim,
+ num_heads=num_heads,
+ window_size=window_size,
+ pretrained_window_size=pretrained_window_size
+ if isinstance(pretrained_window_size, collections.abc.Iterable)
+ else (pretrained_window_size, pretrained_window_size),
+ )
+ self.output = Swinv2SelfOutput(config, dim)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ self_outputs = self.self(hidden_states, attention_mask, head_mask, output_attentions)
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinIntermediate with Swin->Swinv2
+class Swinv2Intermediate(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(dim, int(config.mlp_ratio * dim))
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.swin.modeling_swin.SwinOutput with Swin->Swinv2
+class Swinv2Output(nn.Module):
+ def __init__(self, config, dim):
+ super().__init__()
+ self.dense = nn.Linear(int(config.mlp_ratio * dim), dim)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+class Swinv2Layer(nn.Module):
+ def __init__(
+ self, config, dim, input_resolution, num_heads, drop_path_rate=0.0, shift_size=0, pretrained_window_size=0
+ ):
+ super().__init__()
+ self.input_resolution = input_resolution
+ window_size, shift_size = self._compute_window_shift(
+ (config.window_size, config.window_size), (shift_size, shift_size)
+ )
+ self.window_size = window_size[0]
+ self.shift_size = shift_size[0]
+ self.attention = Swinv2Attention(
+ config=config,
+ dim=dim,
+ num_heads=num_heads,
+ window_size=self.window_size,
+ pretrained_window_size=pretrained_window_size
+ if isinstance(pretrained_window_size, collections.abc.Iterable)
+ else (pretrained_window_size, pretrained_window_size),
+ )
+ self.layernorm_before = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+ self.drop_path = Swinv2DropPath(drop_path_rate) if drop_path_rate > 0.0 else nn.Identity()
+ self.intermediate = Swinv2Intermediate(config, dim)
+ self.output = Swinv2Output(config, dim)
+ self.layernorm_after = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+
+ def _compute_window_shift(self, target_window_size, target_shift_size) -> tuple[tuple[int, int], tuple[int, int]]:
+ window_size = [r if r <= w else w for r, w in zip(self.input_resolution, target_window_size)]
+ shift_size = [0 if r <= w else s for r, w, s in zip(self.input_resolution, window_size, target_shift_size)]
+ return window_size, shift_size
+
+ def get_attn_mask(self, height, width, dtype):
+ if self.shift_size > 0:
+ # calculate attention mask for shifted window multihead self attention
+ img_mask = torch.zeros((1, height, width, 1), dtype=dtype)
+ height_slices = (
+ slice(0, -self.window_size),
+ slice(-self.window_size, -self.shift_size),
+ slice(-self.shift_size, None),
+ )
+ width_slices = (
+ slice(0, -self.window_size),
+ slice(-self.window_size, -self.shift_size),
+ slice(-self.shift_size, None),
+ )
+ count = 0
+ for height_slice in height_slices:
+ for width_slice in width_slices:
+ img_mask[:, height_slice, width_slice, :] = count
+ count += 1
+
+ mask_windows = window_partition(img_mask, self.window_size)
+ mask_windows = mask_windows.view(-1, self.window_size * self.window_size)
+ attn_mask = mask_windows.unsqueeze(1) - mask_windows.unsqueeze(2)
+ attn_mask = attn_mask.masked_fill(attn_mask != 0, -100.0).masked_fill(attn_mask == 0, 0.0)
+ else:
+ attn_mask = None
+ return attn_mask
+
+ def maybe_pad(self, hidden_states, height, width):
+ pad_right = (self.window_size - width % self.window_size) % self.window_size
+ pad_bottom = (self.window_size - height % self.window_size) % self.window_size
+ pad_values = (0, 0, 0, pad_right, 0, pad_bottom)
+ hidden_states = nn.functional.pad(hidden_states, pad_values)
+ return hidden_states, pad_values
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ height, width = input_dimensions
+ batch_size, _, channels = hidden_states.size()
+ shortcut = hidden_states
+
+ # pad hidden_states to multiples of window size
+ hidden_states = hidden_states.view(batch_size, height, width, channels)
+ hidden_states, pad_values = self.maybe_pad(hidden_states, height, width)
+ _, height_pad, width_pad, _ = hidden_states.shape
+ # cyclic shift
+ if self.shift_size > 0:
+ shifted_hidden_states = torch.roll(hidden_states, shifts=(-self.shift_size, -self.shift_size), dims=(1, 2))
+ else:
+ shifted_hidden_states = hidden_states
+
+ # partition windows
+ hidden_states_windows = window_partition(shifted_hidden_states, self.window_size)
+ hidden_states_windows = hidden_states_windows.view(-1, self.window_size * self.window_size, channels)
+ attn_mask = self.get_attn_mask(height_pad, width_pad, dtype=hidden_states.dtype)
+ if attn_mask is not None:
+ attn_mask = attn_mask.to(hidden_states_windows.device)
+
+ attention_outputs = self.attention(
+ hidden_states_windows, attn_mask, head_mask, output_attentions=output_attentions
+ )
+
+ attention_output = attention_outputs[0]
+
+ attention_windows = attention_output.view(-1, self.window_size, self.window_size, channels)
+ shifted_windows = window_reverse(attention_windows, self.window_size, height_pad, width_pad)
+
+ # reverse cyclic shift
+ if self.shift_size > 0:
+ attention_windows = torch.roll(shifted_windows, shifts=(self.shift_size, self.shift_size), dims=(1, 2))
+ else:
+ attention_windows = shifted_windows
+
+ was_padded = pad_values[3] > 0 or pad_values[5] > 0
+ if was_padded:
+ attention_windows = attention_windows[:, :height, :width, :].contiguous()
+
+ attention_windows = attention_windows.view(batch_size, height * width, channels)
+ hidden_states = self.layernorm_before(attention_windows)
+ hidden_states = shortcut + self.drop_path(hidden_states)
+
+ layer_output = self.intermediate(hidden_states)
+ layer_output = self.output(layer_output)
+ layer_output = hidden_states + self.drop_path(self.layernorm_after(layer_output))
+
+ layer_outputs = (layer_output, attention_outputs[1]) if output_attentions else (layer_output,)
+ return layer_outputs
+
+
+class Swinv2Stage(GradientCheckpointingLayer):
+ def __init__(
+ self, config, dim, input_resolution, depth, num_heads, drop_path, downsample, pretrained_window_size=0
+ ):
+ super().__init__()
+ self.config = config
+ self.dim = dim
+ blocks = []
+ for i in range(depth):
+ block = Swinv2Layer(
+ config=config,
+ dim=dim,
+ input_resolution=input_resolution,
+ num_heads=num_heads,
+ drop_path_rate=drop_path[i],
+ shift_size=0 if (i % 2 == 0) else config.window_size // 2,
+ pretrained_window_size=pretrained_window_size,
+ )
+ blocks.append(block)
+ self.blocks = nn.ModuleList(blocks)
+
+ # patch merging layer
+ if downsample is not None:
+ self.downsample = downsample(input_resolution, dim=dim, norm_layer=nn.LayerNorm)
+ else:
+ self.downsample = None
+
+ self.pointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ height, width = input_dimensions
+ for i, layer_module in enumerate(self.blocks):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states,
+ input_dimensions,
+ layer_head_mask,
+ output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ hidden_states_before_downsampling = hidden_states
+ if self.downsample is not None:
+ height_downsampled, width_downsampled = (height + 1) // 2, (width + 1) // 2
+ output_dimensions = (height, width, height_downsampled, width_downsampled)
+ hidden_states = self.downsample(hidden_states_before_downsampling, input_dimensions)
+ else:
+ output_dimensions = (height, width, height, width)
+
+ stage_outputs = (hidden_states, hidden_states_before_downsampling, output_dimensions)
+
+ if output_attentions:
+ stage_outputs += layer_outputs[1:]
+ return stage_outputs
+
+
+class Swinv2Encoder(nn.Module):
+ def __init__(self, config, grid_size, pretrained_window_sizes=(0, 0, 0, 0)):
+ super().__init__()
+ self.num_layers = len(config.depths)
+ self.config = config
+ if self.config.pretrained_window_sizes is not None:
+ pretrained_window_sizes = config.pretrained_window_sizes
+ dpr = [x.item() for x in torch.linspace(0, config.drop_path_rate, sum(config.depths), device="cpu")]
+
+ layers = []
+ for i_layer in range(self.num_layers):
+ stage = Swinv2Stage(
+ config=config,
+ dim=int(config.embed_dim * 2**i_layer),
+ input_resolution=(grid_size[0] // (2**i_layer), grid_size[1] // (2**i_layer)),
+ depth=config.depths[i_layer],
+ num_heads=config.num_heads[i_layer],
+ drop_path=dpr[sum(config.depths[:i_layer]) : sum(config.depths[: i_layer + 1])],
+ downsample=Swinv2PatchMerging if (i_layer < self.num_layers - 1) else None,
+ pretrained_window_size=pretrained_window_sizes[i_layer],
+ )
+ layers.append(stage)
+ self.layers = nn.ModuleList(layers)
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ input_dimensions: tuple[int, int],
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ output_hidden_states_before_downsampling: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ ) -> Union[tuple, Swinv2EncoderOutput]:
+ all_hidden_states = () if output_hidden_states else None
+ all_reshaped_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if output_hidden_states:
+ batch_size, _, hidden_size = hidden_states.shape
+ # rearrange b (h w) c -> b c h w
+ reshaped_hidden_state = hidden_states.view(batch_size, *input_dimensions, hidden_size)
+ reshaped_hidden_state = reshaped_hidden_state.permute(0, 3, 1, 2)
+ all_hidden_states += (hidden_states,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+
+ for i, layer_module in enumerate(self.layers):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states,
+ input_dimensions,
+ layer_head_mask,
+ output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+ hidden_states_before_downsampling = layer_outputs[1]
+ output_dimensions = layer_outputs[2]
+
+ input_dimensions = (output_dimensions[-2], output_dimensions[-1])
+
+ if output_hidden_states and output_hidden_states_before_downsampling:
+ batch_size, _, hidden_size = hidden_states_before_downsampling.shape
+ # rearrange b (h w) c -> b c h w
+ # here we use the original (not downsampled) height and width
+ reshaped_hidden_state = hidden_states_before_downsampling.view(
+ batch_size, *(output_dimensions[0], output_dimensions[1]), hidden_size
+ )
+ reshaped_hidden_state = reshaped_hidden_state.permute(0, 3, 1, 2)
+ all_hidden_states += (hidden_states_before_downsampling,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+ elif output_hidden_states and not output_hidden_states_before_downsampling:
+ batch_size, _, hidden_size = hidden_states.shape
+ # rearrange b (h w) c -> b c h w
+ reshaped_hidden_state = hidden_states.view(batch_size, *input_dimensions, hidden_size)
+ reshaped_hidden_state = reshaped_hidden_state.permute(0, 3, 1, 2)
+ all_hidden_states += (hidden_states,)
+ all_reshaped_hidden_states += (reshaped_hidden_state,)
+
+ if output_attentions:
+ all_self_attentions += layer_outputs[3:]
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, all_hidden_states, all_self_attentions, all_reshaped_hidden_states]
+ if v is not None
+ )
+
+ return Swinv2EncoderOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ reshaped_hidden_states=all_reshaped_hidden_states,
+ )
+
+
+@auto_docstring
+class Swinv2PreTrainedModel(PreTrainedModel):
+ config: Swinv2Config
+ base_model_prefix = "swinv2"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["Swinv2Stage"]
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, Swinv2Embeddings):
+ if module.mask_token is not None:
+ module.mask_token.data.zero_()
+ if module.position_embeddings is not None:
+ module.position_embeddings.data.zero_()
+ elif isinstance(module, Swinv2SelfAttention):
+ module.logit_scale.data.fill_(math.log(10))
+
+
+@auto_docstring
+# Copied from transformers.models.swin.modeling_swin.SwinModel with SWIN->SWINV2,Swin->Swinv2
+class Swinv2Model(Swinv2PreTrainedModel):
+ def __init__(self, config, add_pooling_layer=True, use_mask_token=False):
+ r"""
+ add_pooling_layer (`bool`, *optional*, defaults to `True`):
+ Whether or not to apply pooling layer.
+ use_mask_token (`bool`, *optional*, defaults to `False`):
+ Whether or not to create and apply mask tokens in the embedding layer.
+ """
+ super().__init__(config)
+ self.config = config
+ self.num_layers = len(config.depths)
+ self.num_features = int(config.embed_dim * 2 ** (self.num_layers - 1))
+
+ self.embeddings = Swinv2Embeddings(config, use_mask_token=use_mask_token)
+ self.encoder = Swinv2Encoder(config, self.embeddings.patch_grid)
+
+ self.layernorm = nn.LayerNorm(self.num_features, eps=config.layer_norm_eps)
+ self.pooler = nn.AdaptiveAvgPool1d(1) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Swinv2ModelOutput]:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`, *optional*):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, len(self.config.depths))
+
+ embedding_output, input_dimensions = self.embeddings(
+ pixel_values, bool_masked_pos=bool_masked_pos, interpolate_pos_encoding=interpolate_pos_encoding
+ )
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ input_dimensions,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = encoder_outputs[0]
+ sequence_output = self.layernorm(sequence_output)
+
+ pooled_output = None
+ if self.pooler is not None:
+ pooled_output = self.pooler(sequence_output.transpose(1, 2))
+ pooled_output = torch.flatten(pooled_output, 1)
+
+ if not return_dict:
+ output = (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return output
+
+ return Swinv2ModelOutput(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ reshaped_hidden_states=encoder_outputs.reshaped_hidden_states,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Swinv2 Model with a decoder on top for masked image modeling, as proposed in
+ [SimMIM](https://huggingface.co/papers/2111.09886).
+
+
+
+ Note that we provide a script to pre-train this model on custom data in our [examples
+ directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
+
+
+ """
+)
+# Copied from transformers.models.swin.modeling_swin.SwinForMaskedImageModeling with swin->swinv2, base-simmim-window6-192->tiny-patch4-window8-256,SWIN->SWINV2,Swin->Swinv2,192->256
+class Swinv2ForMaskedImageModeling(Swinv2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.swinv2 = Swinv2Model(config, add_pooling_layer=False, use_mask_token=True)
+
+ num_features = int(config.embed_dim * 2 ** (config.num_layers - 1))
+ self.decoder = nn.Sequential(
+ nn.Conv2d(
+ in_channels=num_features, out_channels=config.encoder_stride**2 * config.num_channels, kernel_size=1
+ ),
+ nn.PixelShuffle(config.encoder_stride),
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Swinv2MaskedImageModelingOutput]:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+
+ Examples:
+ ```python
+ >>> from transformers import AutoImageProcessor, Swinv2ForMaskedImageModeling
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("microsoft/swinv2-tiny-patch4-window8-256")
+ >>> model = Swinv2ForMaskedImageModeling.from_pretrained("microsoft/swinv2-tiny-patch4-window8-256")
+
+ >>> num_patches = (model.config.image_size // model.config.patch_size) ** 2
+ >>> pixel_values = image_processor(images=image, return_tensors="pt").pixel_values
+ >>> # create random boolean mask of shape (batch_size, num_patches)
+ >>> bool_masked_pos = torch.randint(low=0, high=2, size=(1, num_patches)).bool()
+
+ >>> outputs = model(pixel_values, bool_masked_pos=bool_masked_pos)
+ >>> loss, reconstructed_pixel_values = outputs.loss, outputs.reconstruction
+ >>> list(reconstructed_pixel_values.shape)
+ [1, 3, 256, 256]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.swinv2(
+ pixel_values,
+ bool_masked_pos=bool_masked_pos,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ # Reshape to (batch_size, num_channels, height, width)
+ sequence_output = sequence_output.transpose(1, 2)
+ batch_size, num_channels, sequence_length = sequence_output.shape
+ height = width = math.floor(sequence_length**0.5)
+ sequence_output = sequence_output.reshape(batch_size, num_channels, height, width)
+
+ # Reconstruct pixel values
+ reconstructed_pixel_values = self.decoder(sequence_output)
+
+ masked_im_loss = None
+ if bool_masked_pos is not None:
+ size = self.config.image_size // self.config.patch_size
+ bool_masked_pos = bool_masked_pos.reshape(-1, size, size)
+ mask = (
+ bool_masked_pos.repeat_interleave(self.config.patch_size, 1)
+ .repeat_interleave(self.config.patch_size, 2)
+ .unsqueeze(1)
+ .contiguous()
+ )
+ reconstruction_loss = nn.functional.l1_loss(pixel_values, reconstructed_pixel_values, reduction="none")
+ masked_im_loss = (reconstruction_loss * mask).sum() / (mask.sum() + 1e-5) / self.config.num_channels
+
+ if not return_dict:
+ output = (reconstructed_pixel_values,) + outputs[2:]
+ return ((masked_im_loss,) + output) if masked_im_loss is not None else output
+
+ return Swinv2MaskedImageModelingOutput(
+ loss=masked_im_loss,
+ reconstruction=reconstructed_pixel_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ reshaped_hidden_states=outputs.reshaped_hidden_states,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Swinv2 Model transformer with an image classification head on top (a linear layer on top of the final hidden state
+ of the [CLS] token) e.g. for ImageNet.
+
+
+
+ Note that it's possible to fine-tune SwinV2 on higher resolution images than the ones it has been trained on, by
+ setting `interpolate_pos_encoding` to `True` in the forward of the model. This will interpolate the pre-trained
+ position embeddings to the higher resolution.
+
+
+ """
+)
+# Copied from transformers.models.swin.modeling_swin.SwinForImageClassification with SWIN->SWINV2,Swin->Swinv2,swin->swinv2
+class Swinv2ForImageClassification(Swinv2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.swinv2 = Swinv2Model(config)
+
+ # Classifier head
+ self.classifier = (
+ nn.Linear(self.swinv2.num_features, config.num_labels) if config.num_labels > 0 else nn.Identity()
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Swinv2ImageClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.swinv2(
+ pixel_values,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ return_dict=return_dict,
+ )
+
+ pooled_output = outputs[1]
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, pooled_logits=logits, config=self.config)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Swinv2ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ reshaped_hidden_states=outputs.reshaped_hidden_states,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Swinv2 backbone, to be used with frameworks like DETR and MaskFormer.
+ """
+)
+class Swinv2Backbone(Swinv2PreTrainedModel, BackboneMixin):
+ def __init__(self, config):
+ super().__init__(config)
+ super()._init_backbone(config)
+
+ self.num_features = [config.embed_dim] + [int(config.embed_dim * 2**i) for i in range(len(config.depths))]
+ self.embeddings = Swinv2Embeddings(config)
+ self.encoder = Swinv2Encoder(config, self.embeddings.patch_grid)
+
+ # initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Tensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> BackboneOutput:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, AutoBackbone
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> processor = AutoImageProcessor.from_pretrained("microsoft/swinv2-tiny-patch4-window8-256")
+ >>> model = AutoBackbone.from_pretrained(
+ ... "microsoft/swinv2-tiny-patch4-window8-256", out_features=["stage1", "stage2", "stage3", "stage4"]
+ ... )
+
+ >>> inputs = processor(image, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> feature_maps = outputs.feature_maps
+ >>> list(feature_maps[-1].shape)
+ [1, 2048, 7, 7]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ embedding_output, input_dimensions = self.embeddings(pixel_values)
+
+ outputs = self.encoder(
+ embedding_output,
+ input_dimensions,
+ head_mask=None,
+ output_attentions=output_attentions,
+ output_hidden_states=True,
+ output_hidden_states_before_downsampling=True,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs.reshaped_hidden_states if return_dict else outputs[-1]
+
+ feature_maps = ()
+ for stage, hidden_state in zip(self.stage_names, hidden_states):
+ if stage in self.out_features:
+ feature_maps += (hidden_state,)
+
+ if not return_dict:
+ output = (feature_maps,)
+ if output_hidden_states:
+ output += (outputs[1],)
+ if output_attentions:
+ output += (outputs[2],)
+ return output
+
+ return BackboneOutput(
+ feature_maps=feature_maps,
+ hidden_states=outputs.hidden_states if output_hidden_states else None,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "Swinv2ForImageClassification",
+ "Swinv2ForMaskedImageModeling",
+ "Swinv2Model",
+ "Swinv2PreTrainedModel",
+ "Swinv2Backbone",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..70afa7006d73dd2ecf9c421edd78e230cae4c731
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_switch_transformers import *
+ from .modeling_switch_transformers import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/configuration_switch_transformers.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/configuration_switch_transformers.py
new file mode 100644
index 0000000000000000000000000000000000000000..1b8d42e1d608bc8fecadd495cfc5d0ea9f6c5ec5
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/configuration_switch_transformers.py
@@ -0,0 +1,185 @@
+# coding=utf-8
+# Copyright 2022, Google and HuggingFace Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Switch Transformers model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class SwitchTransformersConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`SwitchTransformersModel`]. It is used to
+ instantiate a SwitchTransformers model according to the specified arguments, defining the model architecture.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the
+ SwitchTransformers [google/switch-base-8](https://huggingface.co/google/switch-base-8) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Arguments:
+ vocab_size (`int`, *optional*, defaults to 32128):
+ Vocabulary size of the SwitchTransformers model. Defines the number of different tokens that can be
+ represented by the `inputs_ids` passed when calling [`SwitchTransformersModel`].
+ d_model (`int`, *optional*, defaults to 768):
+ Size of the encoder layers and the pooler layer.
+ d_kv (`int`, *optional*, defaults to 64):
+ Size of the key, query, value projections per attention head. `d_kv` has to be equal to `d_model //
+ num_heads`.
+ d_ff (`int`, *optional*, defaults to 2048):
+ Size of the intermediate feed forward layer in each `SwitchTransformersBlock`.
+ expert_capacity (`int`, *optional*, defaults to 64):
+ Number of tokens that can be stored in each expert. If set to 1, the model will behave like a regular
+ Transformer.
+ num_layers (`int`, *optional*, defaults to 12):
+ Number of dense hidden layers in the Transformer encoder layer.
+ num_sparse_encoder_layers (`int`, *optional*, defaults to 3):
+ Number of sparse (MoE) dense hidden layers in the Transformer encoder layer.
+ num_decoder_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer decoder. Will use the same value as `num_layers` if not set.
+ num_sparse_decoder_layers (`int`, *optional*, defaults to 3):
+ Number of sparse (MoE) dense hidden layers in the Transformer decoder layer.
+ num_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ num_experts (`int`, *optional*, defaults to 8):
+ Number of experts for each SwitchTransformer layer.
+ router_bias (`bool`, *optional*, defaults to `False`):
+ Whether to add a bias to the router.
+ router_jitter_noise (`float`, *optional*, defaults to 0.01):
+ Amount of noise to add to the router.
+ router_dtype (`str`, *optional*, default to `"float32"`):
+ The `dtype` used for the routers. It is preferable to keep the `dtype` to `"float32"` as specified in the
+ *selective precision* discussion in [the paper](https://huggingface.co/papers/2101.03961).
+ router_ignore_padding_tokens (`bool`, *optional*, defaults to `False`):
+ Whether to ignore padding tokens when routing.
+ relative_attention_num_buckets (`int`, *optional*, defaults to 32):
+ The number of buckets to use for each attention layer.
+ relative_attention_max_distance (`int`, *optional*, defaults to 128):
+ The maximum distance of the longer sequences for the bucket separation.
+ dropout_rate (`float`, *optional*, defaults to 0.1):
+ The ratio for all dropout layers.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-6):
+ The epsilon used by the layer normalization layers.
+ router_z_loss_coef (`float`, *optional*, defaults to 0.001):
+ The z loss factor for the total loss.
+ router_aux_loss_coef (`float`, *optional*, defaults to 0.001):
+ The aux loss factor for the total loss.
+ initializer_factor (`float`, *optional*, defaults to 1.0):
+ A factor for initializing all weight matrices (should be kept to 1, used internally for initialization
+ testing).
+ dense_act_fn (`string`, *optional*, defaults to `"relu"`):
+ Type of feed forward layer to be used. Should be one of `"relu"` or `"gated-gelu"`. SwitchTransformersv1.1
+ uses the `"gated-gelu"` feed forward projection. Original SwitchTransformers uses `"relu"`.
+ add_router_probs (`bool`, *optional*, defaults to `False`):
+ Whether to output router probabilities to compute router auxiliary loss.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+ """
+
+ model_type = "switch_transformers"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {"hidden_size": "d_model", "num_attention_heads": "num_heads", "num_hidden_layers": "num_layers"}
+
+ def __init__(
+ self,
+ vocab_size=32128,
+ d_model=768,
+ d_kv=64,
+ d_ff=2048,
+ expert_capacity=64,
+ num_layers=12,
+ num_sparse_encoder_layers=3,
+ num_decoder_layers=12,
+ num_sparse_decoder_layers=3,
+ num_heads=12,
+ num_experts=8,
+ router_bias=False,
+ router_jitter_noise=0.01,
+ router_dtype="float32",
+ router_ignore_padding_tokens=False,
+ relative_attention_num_buckets=32,
+ relative_attention_max_distance=128,
+ dropout_rate=0.1,
+ layer_norm_epsilon=1e-6,
+ router_z_loss_coef=0.001,
+ router_aux_loss_coef=0.001,
+ initializer_factor=1.0,
+ dense_act_fn="relu",
+ is_encoder_decoder=True,
+ add_router_probs=False,
+ use_cache=True,
+ pad_token_id=0,
+ eos_token_id=1,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.d_model = d_model
+ self.d_kv = d_kv
+ self.d_ff = d_ff
+
+ self.num_sparse_encoder_layers = num_sparse_encoder_layers
+
+ self.num_layers = num_layers
+ self.num_decoder_layers = (
+ num_decoder_layers if num_decoder_layers is not None else self.num_layers
+ ) # default = symmetry
+ self.num_sparse_decoder_layers = num_sparse_decoder_layers
+
+ # This tells us, each how many encoder layer we'll have to set a sparse layer.
+ if self.num_sparse_encoder_layers > 0:
+ self.encoder_sparse_step = self.num_layers // self.num_sparse_encoder_layers
+ else:
+ self.encoder_sparse_step = self.num_layers # HACK: this will create 0 sparse layers
+
+ # This tells us, each how many encoder layer we'll have to set a sparse layer.
+ if self.num_sparse_decoder_layers > 0:
+ self.decoder_sparse_step = self.num_decoder_layers // self.num_sparse_decoder_layers
+ else:
+ self.decoder_sparse_step = self.num_decoder_layers # HACK: this will create 0 sparse layers
+
+ self.num_heads = num_heads
+ self.num_experts = num_experts
+ self.expert_capacity = expert_capacity
+ self.router_bias = router_bias
+ self.router_jitter_noise = router_jitter_noise
+ if router_dtype not in ["float32", "float16", "bfloat16"]:
+ raise ValueError(f"`router_dtype` must be one of 'float32', 'float16' or 'bfloat16', got {router_dtype}")
+ self.router_dtype = router_dtype
+
+ self.router_ignore_padding_tokens = router_ignore_padding_tokens
+ self.relative_attention_num_buckets = relative_attention_num_buckets
+ self.relative_attention_max_distance = relative_attention_max_distance
+
+ self.dropout_rate = dropout_rate
+ self.layer_norm_epsilon = layer_norm_epsilon
+ self.initializer_factor = initializer_factor
+ self.use_cache = use_cache
+ self.add_router_probs = add_router_probs
+
+ self.router_z_loss_coef = router_z_loss_coef
+ self.router_aux_loss_coef = router_aux_loss_coef
+ self.dense_act_fn = dense_act_fn
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ eos_token_id=eos_token_id,
+ is_encoder_decoder=is_encoder_decoder,
+ **kwargs,
+ )
+
+
+__all__ = ["SwitchTransformersConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/modeling_switch_transformers.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/modeling_switch_transformers.py
new file mode 100644
index 0000000000000000000000000000000000000000..2bf97ba8317ad34da33945f1a14db4959584a7e5
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/switch_transformers/modeling_switch_transformers.py
@@ -0,0 +1,1819 @@
+# coding=utf-8
+# Copyright 2022 SwitchTransformers Authors and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch SwitchTransformers model."""
+
+import copy
+import math
+import warnings
+from typing import Optional, Union
+
+import torch
+import torch.nn as nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ MoEModelOutput,
+ MoEModelOutputWithPastAndCrossAttentions,
+ Seq2SeqMoEModelOutput,
+ Seq2SeqMoEOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import (
+ DUMMY_INPUTS,
+ DUMMY_MASK,
+ auto_docstring,
+ is_torch_flex_attn_available,
+ is_torch_fx_proxy,
+ is_torchdynamo_compiling,
+ logging,
+)
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_switch_transformers import SwitchTransformersConfig
+
+
+if is_torch_flex_attn_available():
+ from torch.nn.attention.flex_attention import BlockMask
+
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.get_logger(__name__)
+
+
+####################################################
+# This dict contains ids and associated url
+# for the pretrained weights provided with the models
+####################################################
+
+
+def router_z_loss_func(router_logits: torch.Tensor) -> float:
+ r"""
+ Compute the router z-loss implemented in PyTorch.
+
+ The router z-loss was introduced in [Designing Effective Sparse Expert Models](https://huggingface.co/papers/2202.08906).
+ It encourages router logits to remain small in an effort to improve stability.
+
+ Args:
+ router_logits (`float`):
+ Input logits of shape [batch_size, sequence_length, num_experts]
+
+ Returns:
+ Scalar router z-loss.
+ """
+ num_groups, tokens_per_group, _ = router_logits.shape
+ log_z = torch.logsumexp(router_logits, dim=-1)
+ z_loss = log_z**2
+ return torch.sum(z_loss) / (num_groups * tokens_per_group)
+
+
+def load_balancing_loss_func(router_probs: torch.Tensor, expert_indices: torch.Tensor) -> float:
+ r"""
+ Computes auxiliary load balancing loss as in Switch Transformer - implemented in Pytorch.
+
+ See Switch Transformer (https://huggingface.co/papers/2101.03961) for more details. This function implements the loss
+ function presented in equations (4) - (6) of the paper. It aims at penalizing cases where the routing between
+ experts is too unbalanced.
+
+ Args:
+ router_probs (`torch.Tensor`):
+ Probability assigned to each expert per token. Shape: [batch_size, seqeunce_length, num_experts].
+ expert_indices (`torch.Tensor`):
+ Indices tensor of shape [batch_size, seqeunce_length] identifying the selected expert for a given token.
+
+ Returns:
+ The auxiliary loss.
+ """
+ num_experts = router_probs.shape[-1]
+
+ # cast the expert indices to int64, otherwise one-hot encoding will fail
+ if expert_indices.dtype != torch.int64:
+ expert_indices = expert_indices.to(torch.int64)
+
+ if len(expert_indices.shape) == 2:
+ expert_indices = expert_indices.unsqueeze(2)
+
+ expert_mask = torch.nn.functional.one_hot(expert_indices, num_experts)
+
+ # For a given token, determine if it was routed to a given expert.
+ expert_mask = torch.max(expert_mask, axis=-2).values
+
+ # cast to float32 otherwise mean will fail
+ expert_mask = expert_mask.to(torch.float32)
+ tokens_per_group_and_expert = torch.mean(expert_mask, axis=-2)
+
+ router_prob_per_group_and_expert = torch.mean(router_probs, axis=-2)
+ return torch.mean(tokens_per_group_and_expert * router_prob_per_group_and_expert) * (num_experts**2)
+
+
+class SwitchTransformersTop1Router(nn.Module):
+ """
+ Router using tokens choose top-1 experts assignment.
+
+ This router uses the same mechanism as in Switch Transformer (https://huggingface.co/papers/2101.03961) and V-MoE
+ (https://huggingface.co/papers/2106.05974): tokens choose their top experts. Items are sorted by router_probs and then
+ routed to their choice of expert until the expert's expert_capacity is reached. **There is no guarantee that each
+ token is processed by an expert**, or that each expert receives at least one token.
+
+ """
+
+ def __init__(self, config: SwitchTransformersConfig):
+ super().__init__()
+ self.num_experts = config.num_experts
+ self.expert_capacity = config.expert_capacity
+ self.classifier = nn.Linear(config.hidden_size, self.num_experts, bias=config.router_bias)
+ self.jitter_noise = config.router_jitter_noise
+ self.ignore_padding_tokens = config.router_ignore_padding_tokens
+ self.dtype = getattr(torch, config.router_dtype)
+
+ def _compute_router_probabilities(self, hidden_states: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
+ r"""
+ Computes router probabilities from input hidden states.
+
+ Args:
+ hidden_states (`torch.Tensor`):
+ (batch_size, sequence_length, hidden_dim) from which router probabilities are computed.
+ Returns:
+ router_probabilities (`torch.Tensor`):
+ Tensor of shape (batch_size, sequence_length, num_experts) corresponding to the probabilities for each
+ token and expert. Used for routing tokens to experts.
+ router_logits (`torch.Tensor`):
+ Logits tensor of shape (batch_size, sequence_length, num_experts) corresponding to raw router logits.
+ This is used later for computing router z-loss.
+ """
+ # float32 is used to ensure stability. See the discussion of "selective precision" in
+ # https://huggingface.co/papers/2101.03961.
+ # We also store the previous dtype to cast back the output to the previous dtype
+ self.input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(self.dtype)
+
+ if self.training and self.jitter_noise > 0:
+ # Multiply the token inputs by the uniform distribution - adding some noise
+ hidden_states *= torch.empty_like(hidden_states).uniform_(1.0 - self.jitter_noise, 1.0 + self.jitter_noise)
+
+ # Shape: [num_groups, tokens_per_group, num_experts]
+ self._cast_classifier()
+ router_logits = self.classifier(hidden_states)
+
+ # Apply Softmax and cast back to the original `dtype`
+ router_probabilities = nn.functional.softmax(router_logits, dim=-1, dtype=self.dtype).to(self.input_dtype)
+ return router_probabilities, router_logits
+
+ def _cast_classifier(self):
+ r"""
+ `bitsandbytes` `Linear8bitLt` layers does not support manual casting Therefore we need to check if they are an
+ instance of the `Linear8bitLt` class by checking special attributes.
+ """
+ if not (hasattr(self.classifier, "SCB") or hasattr(self.classifier, "CB")):
+ self.classifier = self.classifier.to(self.dtype)
+
+ def forward(self, hidden_states: torch.Tensor) -> tuple:
+ r"""
+ Generic forward function for every Router class. Each Router expects to have the same input hidden states
+ (`hidden_states`) corresponding to the hidden states for each token, the `expert_capacity` corresponding to the
+ number of tokens the Router will send to each expert, some Routers can send up to few tokens to each expert.
+
+ Each Router works as the following: it expects the hidden states for each token, gets the `router_probs` and
+ `router_logits` from the `router_weights`. This will assign for each token, the raw probability to be assigned
+ to an expert. Then each Router class will have to define its own `_compute_routing_instructions`.
+
+ Args:
+ hidden_states (`torch.Tensor`) :
+ [num_groups, tokens_per_group, hidden_dim] inputs to send to experts.
+ Returns:
+ tuple[`torch.Tensor`, `torch.Tensor`, `torch.Tensor`] Tuple containing the expert index, the router probs
+ and the router logits. The router probabilities and logits are required to compute the loss.
+ """
+ router_probs, router_logits = self._compute_router_probabilities(hidden_states)
+
+ expert_index = torch.argmax(router_probs, dim=-1)
+ expert_index = torch.nn.functional.one_hot(expert_index, num_classes=self.num_experts)
+
+ # Mask tokens outside expert capacity. Sum over each sequence
+ token_priority = torch.cumsum(expert_index, dim=-2)
+ # mask if the token routed to to the expert will overflow
+ expert_capacity_mask = token_priority <= self.expert_capacity
+ expert_index = expert_index * expert_capacity_mask
+
+ router_probs = torch.max(router_probs, dim=-1).values.unsqueeze(-1)
+ return expert_index, router_probs, router_logits
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerNorm with T5->SwitchTransformers
+class SwitchTransformersLayerNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ Construct a layernorm module in the SwitchTransformers style. No bias and no subtraction of mean.
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ # SwitchTransformers uses a layer_norm which only scales and doesn't shift, which is also known as Root Mean
+ # Square Layer Normalization https://huggingface.co/papers/1910.07467 thus variance is calculated
+ # w/o mean and there is no bias. Additionally we want to make sure that the accumulation for
+ # half-precision inputs is done in fp32
+
+ variance = hidden_states.to(torch.float32).pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+
+ # convert into half-precision if necessary
+ if self.weight.dtype in [torch.float16, torch.bfloat16]:
+ hidden_states = hidden_states.to(self.weight.dtype)
+
+ return self.weight * hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5DenseActDense with T5->SwitchTransformers
+class SwitchTransformersDenseActDense(nn.Module):
+ def __init__(self, config: SwitchTransformersConfig):
+ super().__init__()
+ self.wi = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.act = ACT2FN[config.dense_act_fn]
+
+ def forward(self, hidden_states):
+ hidden_states = self.wi(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ if (
+ isinstance(self.wo.weight, torch.Tensor)
+ and hidden_states.dtype != self.wo.weight.dtype
+ and self.wo.weight.dtype != torch.int8
+ ):
+ hidden_states = hidden_states.to(self.wo.weight.dtype)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+class SwitchTransformersSparseMLP(nn.Module):
+ r"""
+ Implementation of the Switch Transformers Sparse MLP module.
+ """
+
+ def __init__(self, config: SwitchTransformersConfig, expert_class: nn.Module = SwitchTransformersDenseActDense):
+ super().__init__()
+ # Step 1: Get the correct router according to its class
+ self.router = SwitchTransformersTop1Router(config)
+
+ # Step 2: Get the experts
+ self.experts = nn.ModuleDict()
+ for idx in range(config.num_experts):
+ self.experts[f"expert_{idx}"] = expert_class(config)
+
+ def forward(self, hidden_states):
+ r"""
+ Hold on, this will be slightly tricky to understand In the correct order, a MoE layer does the following:
+
+ 1- Gets the `router_mask` from the router. The shape of the mask is `(batch_size, sequence_length, num_expert)`
+ and corresponds to the argmax of the `router_probs`. The probabilities are needed in the computation of the
+ hidden states : they are broadcasted to the hidden states values (can be interpreted as a scaling factor).
+
+ 2- Dispatch the tokens to its associated experts. We do a classic for loop over the experts and assign for each
+ expert the corresponding hidden states.
+
+ """
+ # Step 1: Get the router_mask from the router as well as the probabilities
+ router_mask, router_probs, router_logits = self.router(hidden_states)
+ expert_index = torch.argmax(router_mask, dim=-1)
+
+ # If a token gets dropped, we just set it to zero such that it does not get updated.
+ next_states = torch.zeros(hidden_states.shape, device=hidden_states.device, dtype=hidden_states.dtype)
+
+ router_mask = router_mask.bool()
+ batch_size, seq_len, num_experts = router_mask.shape
+ idx_mask = router_mask.reshape(batch_size * seq_len, num_experts).sum(dim=0)
+ idx_mask = torch.nonzero(idx_mask, as_tuple=True)[
+ 0
+ ].tolist() # length: number of "activated" expert / value: index
+ for idx in idx_mask:
+ next_states[router_mask[:, :, idx]] = getattr(self.experts, f"expert_{idx}")(
+ hidden_states[router_mask[:, :, idx]]
+ )
+
+ hidden_states = router_probs * next_states
+ return hidden_states, (router_logits, expert_index)
+
+
+class SwitchTransformersLayerFF(nn.Module):
+ r"""
+ Switch Transformers Feed Forward layer module. This is a wrapper around the Mixture of Experts module.
+
+ Parameters:
+ config : ([`SwitchTransformersConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+ is_sparse (`bool`):
+ Whether the MLP layer is a `Sparse` layer (contains a Mixture of Experts) or not
+ """
+
+ def __init__(self, config: SwitchTransformersConfig, is_sparse=False):
+ super().__init__()
+ self.is_sparse = is_sparse
+
+ # Check if it is a sparse layer, if not then it is a dense layer
+ if not self.is_sparse:
+ self.mlp = SwitchTransformersDenseActDense(config)
+ else:
+ self.mlp = SwitchTransformersSparseMLP(config)
+
+ self.layer_norm = SwitchTransformersLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(self, hidden_states, output_router_logits):
+ forwarded_states = self.layer_norm(hidden_states)
+ forwarded_states = self.mlp(forwarded_states)
+
+ if isinstance(forwarded_states, tuple):
+ forwarded_states, router_tuple = forwarded_states
+ else:
+ router_tuple = None
+
+ output = hidden_states + self.dropout(forwarded_states)
+
+ if output_router_logits and router_tuple is not None:
+ output = (output, router_tuple)
+
+ return output
+
+
+# Copied from transformers.models.t5.modeling_t5.T5Attention with T5->SwitchTransformers
+class SwitchTransformersAttention(nn.Module):
+ def __init__(
+ self,
+ config: SwitchTransformersConfig,
+ has_relative_attention_bias=False,
+ layer_idx: Optional[int] = None,
+ ):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.has_relative_attention_bias = has_relative_attention_bias
+ self.relative_attention_num_buckets = config.relative_attention_num_buckets
+ self.relative_attention_max_distance = config.relative_attention_max_distance
+ self.d_model = config.d_model
+ self.key_value_proj_dim = config.d_kv
+ self.n_heads = config.num_heads
+ self.dropout = config.dropout_rate
+ self.inner_dim = self.n_heads * self.key_value_proj_dim
+ self.layer_idx = layer_idx
+ if layer_idx is None and self.is_decoder:
+ logger.warning_once(
+ f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and "
+ "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+
+ # Mesh TensorFlow initialization to avoid scaling before softmax
+ self.q = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.k = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.v = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.o = nn.Linear(self.inner_dim, self.d_model, bias=False)
+
+ if self.has_relative_attention_bias:
+ self.relative_attention_bias = nn.Embedding(self.relative_attention_num_buckets, self.n_heads)
+ self.pruned_heads = set()
+ self.gradient_checkpointing = False
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.n_heads, self.key_value_proj_dim, self.pruned_heads
+ )
+ # Prune linear layers
+ self.q = prune_linear_layer(self.q, index)
+ self.k = prune_linear_layer(self.k, index)
+ self.v = prune_linear_layer(self.v, index)
+ self.o = prune_linear_layer(self.o, index, dim=1)
+ # Update hyper params
+ self.n_heads = self.n_heads - len(heads)
+ self.inner_dim = self.key_value_proj_dim * self.n_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ @staticmethod
+ def _relative_position_bucket(relative_position, bidirectional=True, num_buckets=32, max_distance=128):
+ """
+ Adapted from Mesh Tensorflow:
+ https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593
+
+ Translate relative position to a bucket number for relative attention. The relative position is defined as
+ memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to
+ position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for
+ small absolute relative_position and larger buckets for larger absolute relative_positions. All relative
+ positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket.
+ This should allow for more graceful generalization to longer sequences than the model has been trained on
+
+ Args:
+ relative_position: an int32 Tensor
+ bidirectional: a boolean - whether the attention is bidirectional
+ num_buckets: an integer
+ max_distance: an integer
+
+ Returns:
+ a Tensor with the same shape as relative_position, containing int32 values in the range [0, num_buckets)
+ """
+ relative_buckets = 0
+ if bidirectional:
+ num_buckets //= 2
+ relative_buckets += (relative_position > 0).to(torch.long) * num_buckets
+ relative_position = torch.abs(relative_position)
+ else:
+ relative_position = -torch.min(relative_position, torch.zeros_like(relative_position))
+ # now relative_position is in the range [0, inf)
+
+ # half of the buckets are for exact increments in positions
+ max_exact = num_buckets // 2
+ is_small = relative_position < max_exact
+
+ # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance
+ relative_position_if_large = max_exact + (
+ torch.log(relative_position.float() / max_exact)
+ / math.log(max_distance / max_exact)
+ * (num_buckets - max_exact)
+ ).to(torch.long)
+ relative_position_if_large = torch.min(
+ relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1)
+ )
+
+ relative_buckets += torch.where(is_small, relative_position, relative_position_if_large)
+ return relative_buckets
+
+ def compute_bias(self, query_length, key_length, device=None, cache_position=None):
+ """Compute binned relative position bias"""
+ if device is None:
+ device = self.relative_attention_bias.weight.device
+ if cache_position is None:
+ context_position = torch.arange(query_length, dtype=torch.long, device=device)[:, None]
+ else:
+ context_position = cache_position[:, None].to(device)
+ memory_position = torch.arange(key_length, dtype=torch.long, device=device)[None, :]
+ relative_position = memory_position - context_position # shape (query_length, key_length)
+ relative_position_bucket = self._relative_position_bucket(
+ relative_position, # shape (query_length, key_length)
+ bidirectional=(not self.is_decoder),
+ num_buckets=self.relative_attention_num_buckets,
+ max_distance=self.relative_attention_max_distance,
+ )
+ values = self.relative_attention_bias(relative_position_bucket) # shape (query_length, key_length, num_heads)
+ values = values.permute([2, 0, 1]).unsqueeze(0) # shape (1, num_heads, query_length, key_length)
+ return values
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ mask=None,
+ key_value_states=None,
+ position_bias=None,
+ past_key_values=None,
+ layer_head_mask=None,
+ query_length=None,
+ use_cache=False,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ """
+ Self-attention (if key_value_states is None) or attention over source sentence (provided by key_value_states).
+ """
+ # Input is (batch_size, seq_length, dim)
+ # Mask is (batch_size, 1, 1, key_length) (non-causal encoder) or (batch_size, 1, seq_length, key_length) (causal decoder)
+ batch_size, seq_length = hidden_states.shape[:2]
+
+ # if key_value_states are provided this layer is used as a cross-attention layer for the decoder
+ is_cross_attention = key_value_states is not None
+
+ query_states = self.q(hidden_states)
+ query_states = query_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ # Check is encoder-decoder model is being used. Otherwise we'll get `DynamicCache`
+ if past_key_values is not None and isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k(current_states)
+ value_states = self.v(current_states)
+ key_states = key_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+ value_states = value_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # compute scores, equivalent of torch.einsum("bnqd,bnkd->bnqk", query_states, key_states), compatible with onnx op>9
+ scores = torch.matmul(query_states, key_states.transpose(3, 2))
+
+ if position_bias is None:
+ key_length = key_states.shape[-2]
+ # cache position is 0-indexed so we add 1 to get the real length of queries (aka with past)
+ real_seq_length = query_length if query_length is not None else cache_position[-1] + 1
+ if not self.has_relative_attention_bias:
+ position_bias = torch.zeros(
+ (1, self.n_heads, seq_length, key_length), device=scores.device, dtype=scores.dtype
+ )
+ if self.gradient_checkpointing and self.training:
+ position_bias.requires_grad = True
+ else:
+ position_bias = self.compute_bias(
+ real_seq_length, key_length, device=scores.device, cache_position=cache_position
+ )
+ position_bias = position_bias[:, :, -seq_length:, :]
+
+ if mask is not None:
+ causal_mask = mask[:, :, :, : key_states.shape[-2]]
+ position_bias = position_bias + causal_mask
+
+ if self.pruned_heads:
+ mask = torch.ones(position_bias.shape[1])
+ mask[list(self.pruned_heads)] = 0
+ position_bias_masked = position_bias[:, mask.bool()]
+ else:
+ position_bias_masked = position_bias
+
+ scores += position_bias_masked
+
+ # (batch_size, n_heads, seq_length, key_length)
+ attn_weights = nn.functional.softmax(scores.float(), dim=-1).type_as(scores)
+ attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ # Mask heads if we want to
+ if layer_head_mask is not None:
+ attn_weights = attn_weights * layer_head_mask
+
+ attn_output = torch.matmul(attn_weights, value_states)
+
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ attn_output = attn_output.view(batch_size, -1, self.inner_dim)
+ attn_output = self.o(attn_output)
+
+ outputs = (attn_output, position_bias)
+
+ if output_attentions:
+ outputs = outputs + (attn_weights,)
+ return outputs
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerSelfAttention with T5->SwitchTransformers
+class SwitchTransformersLayerSelfAttention(nn.Module):
+ def __init__(self, config, has_relative_attention_bias=False, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.SelfAttention = SwitchTransformersAttention(
+ config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx
+ )
+ self.layer_norm = SwitchTransformersLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.SelfAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0])
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerCrossAttention with T5->SwitchTransformers
+class SwitchTransformersLayerCrossAttention(nn.Module):
+ def __init__(self, config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.EncDecAttention = SwitchTransformersAttention(
+ config, has_relative_attention_bias=False, layer_idx=layer_idx
+ )
+ self.layer_norm = SwitchTransformersLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ key_value_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ query_length=None,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.EncDecAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ key_value_states=key_value_states,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ query_length=query_length,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ layer_output = hidden_states + self.dropout(attention_output[0])
+ outputs = (layer_output,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+class SwitchTransformersBlock(GradientCheckpointingLayer):
+ def __init__(self, config, has_relative_attention_bias=False, is_sparse=False, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.is_sparse = is_sparse
+ self.layer = nn.ModuleList()
+ self.layer.append(
+ SwitchTransformersLayerSelfAttention(
+ config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx
+ )
+ )
+ if self.is_decoder:
+ self.layer.append(SwitchTransformersLayerCrossAttention(config, layer_idx=layer_idx))
+
+ self.layer.append(SwitchTransformersLayerFF(config, is_sparse=self.is_sparse))
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ encoder_decoder_position_bias=None,
+ layer_head_mask=None,
+ cross_attn_layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=False,
+ output_router_logits=True,
+ return_dict=True,
+ cache_position=None,
+ ):
+ self_attention_outputs = self.layer[0](
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = self_attention_outputs[0]
+ attention_outputs = self_attention_outputs[1:] # Keep self-attention outputs and relative position weights
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16 and torch.isinf(hidden_states).any():
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ do_cross_attention = self.is_decoder and encoder_hidden_states is not None
+ if do_cross_attention:
+ cross_attention_outputs = self.layer[1](
+ hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ position_bias=encoder_decoder_position_bias,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ query_length=cache_position[-1] + 1,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = cross_attention_outputs[0]
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16 and torch.isinf(hidden_states).any():
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ # Keep cross-attention outputs and relative position weights
+ attention_outputs = attention_outputs + cross_attention_outputs[1:]
+
+ # Apply Feed Forward layer
+ hidden_states = self.layer[-1](hidden_states, output_router_logits)
+
+ if isinstance(hidden_states, tuple):
+ hidden_states, router_tuple = hidden_states
+ else:
+ router_tuple = (torch.zeros((1,), device=hidden_states.device, dtype=torch.int64),)
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16 and torch.isinf(hidden_states).any():
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ outputs = (hidden_states,)
+
+ return (
+ outputs + attention_outputs + (router_tuple,)
+ ) # hidden-states, (self-attention position bias), (self-attention weights), (cross-attention position bias), (cross-attention weights), (router_tuple)
+
+
+@auto_docstring
+class SwitchTransformersPreTrainedModel(PreTrainedModel):
+ config: SwitchTransformersConfig
+ base_model_prefix = "switch_transformers"
+ supports_gradient_checkpointing = True
+
+ _can_compile_fullgraph = False
+ _no_split_modules = ["SwitchTransformersBlock"]
+
+ @property
+ def dummy_inputs(self):
+ input_ids = torch.tensor(DUMMY_INPUTS)
+ input_mask = torch.tensor(DUMMY_MASK)
+ dummy_inputs = {
+ "decoder_input_ids": input_ids,
+ "input_ids": input_ids,
+ "decoder_attention_mask": input_mask,
+ }
+ return dummy_inputs
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ factor = self.config.initializer_factor # Used for testing weights initialization
+ if isinstance(module, SwitchTransformersLayerNorm):
+ module.weight.data.fill_(factor * 1.0)
+ elif isinstance(
+ module,
+ (SwitchTransformersModel, SwitchTransformersForConditionalGeneration, SwitchTransformersEncoderModel),
+ ):
+ # Mesh TensorFlow embeddings initialization
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L1624
+ module.shared.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ if hasattr(module, "lm_head") and not self.config.tie_word_embeddings:
+ module.lm_head.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ elif isinstance(module, SwitchTransformersDenseActDense):
+ # Mesh TensorFlow FF initialization
+ # See https://github.com/tensorflow/mesh/blob/master/mesh_tensorflow/transformer/transformer_layers.py#L56
+ # and https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L89
+ module.wi.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi, "bias") and module.wi.bias is not None:
+ module.wi.bias.data.zero_()
+ module.wo.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_ff) ** -0.5))
+ if hasattr(module.wo, "bias") and module.wo.bias is not None:
+ module.wo.bias.data.zero_()
+ elif isinstance(module, SwitchTransformersAttention):
+ # Mesh TensorFlow attention initialization to avoid scaling before softmax
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/attention.py#L136
+ d_model = self.config.d_model
+ key_value_proj_dim = self.config.d_kv
+ n_heads = self.config.num_heads
+ module.q.weight.data.normal_(mean=0.0, std=factor * ((d_model * key_value_proj_dim) ** -0.5))
+ module.k.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.v.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.o.weight.data.normal_(mean=0.0, std=factor * ((n_heads * key_value_proj_dim) ** -0.5))
+ if module.has_relative_attention_bias:
+ module.relative_attention_bias.weight.data.normal_(mean=0.0, std=factor * ((d_model) ** -0.5))
+ elif isinstance(module, SwitchTransformersSparseMLP):
+ # Mesh TensorFlow attention initialization to avoid scaling before softmax
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/attention.py#L136
+ d_model = self.config.d_model
+ key_value_proj_dim = self.config.d_kv
+ n_heads = self.config.num_heads
+ module.router.classifier.weight.data.normal_(mean=0.0, std=factor * 1)
+ for idx in range(self.config.num_experts):
+ module.experts[f"expert_{idx}"].wi.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.experts[f"expert_{idx}"].wo.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+
+ def _shift_right(self, input_ids):
+ decoder_start_token_id = self.config.decoder_start_token_id
+ pad_token_id = self.config.pad_token_id
+
+ if decoder_start_token_id is None:
+ raise ValueError(
+ "self.model.config.decoder_start_token_id has to be defined. In SwitchTransformers it is usually set"
+ " to the pad_token_id. See SwitchTransformers docs for more information"
+ )
+
+ # shift inputs to the right
+ if is_torch_fx_proxy(input_ids):
+ # Item assignment is not supported natively for proxies.
+ shifted_input_ids = torch.full(input_ids.shape[:-1] + (1,), decoder_start_token_id)
+ shifted_input_ids = torch.cat([shifted_input_ids, input_ids[..., :-1]], dim=-1)
+ else:
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
+ shifted_input_ids[..., 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.pad_token_id has to be defined.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+class SwitchTransformersStack(SwitchTransformersPreTrainedModel):
+ def __init__(self, config, embed_tokens=None):
+ super().__init__(config)
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.d_model)
+
+ if embed_tokens is not None:
+ self.embed_tokens.weight = embed_tokens.weight
+
+ self.is_decoder = config.is_decoder
+
+ sparse_step = config.decoder_sparse_step if self.is_decoder else config.encoder_sparse_step
+ config.num_layers = config.num_decoder_layers if self.is_decoder else config.num_layers
+ self.block = nn.ModuleList()
+ for i in range(config.num_layers):
+ is_sparse = (i % sparse_step == 1 or sparse_step == 1) if sparse_step > 0 else False
+
+ self.block.append(
+ SwitchTransformersBlock(
+ config, has_relative_attention_bias=bool(i == 0), is_sparse=is_sparse, layer_idx=i
+ )
+ )
+
+ self.final_layer_norm = SwitchTransformersLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ self.device_map = None
+ self.gradient_checkpointing = False
+
+ def set_input_embeddings(self, new_embeddings):
+ self.embed_tokens = new_embeddings
+
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ inputs_embeds=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ output_router_logits=True,
+ return_dict=None,
+ cache_position=None,
+ ):
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(
+ f"You cannot specify both {err_msg_prefix}input_ids and {err_msg_prefix}inputs_embeds at the same time"
+ )
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(f"You have to specify either {err_msg_prefix}input_ids or {err_msg_prefix}inputs_embeds")
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ if self.embed_tokens is None:
+ raise ValueError("You have to initialize the model with valid token embeddings")
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ batch_size, seq_length = input_shape
+
+ if use_cache is True:
+ if not self.is_decoder:
+ raise ValueError(f"`use_cache` can only be set to `True` if {self} is used as a decoder")
+
+ if self.is_decoder:
+ if use_cache and past_key_values is None:
+ if self.config.is_encoder_decoder:
+ past_key_values = EncoderDecoderCache(
+ DynamicCache(config=self.config), DynamicCache(config=self.config)
+ )
+ else:
+ past_key_values = DynamicCache(config=self.config)
+ elif not self.is_decoder:
+ # do not pass cache object down the line for encoder stack
+ # it messes indexing later in decoder-stack because cache object is modified in-place
+ past_key_values = None
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+ if cache_position is None:
+ cache_position = torch.arange(
+ past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device
+ )
+
+ if attention_mask is None and not is_torchdynamo_compiling():
+ # required mask seq length can be calculated via length of past cache
+ mask_seq_length = past_key_values_length + seq_length
+ attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device)
+
+ if self.config.is_decoder:
+ causal_mask = self._update_causal_mask(
+ attention_mask,
+ inputs_embeds,
+ cache_position,
+ past_key_values.self_attention_cache
+ if isinstance(past_key_values, EncoderDecoderCache)
+ else past_key_values,
+ output_attentions,
+ )
+ else:
+ causal_mask = attention_mask[:, None, None, :]
+ causal_mask = causal_mask.to(dtype=inputs_embeds.dtype)
+ causal_mask = (1.0 - causal_mask) * torch.finfo(inputs_embeds.dtype).min
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=inputs_embeds.device)
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ head_mask = self.get_head_mask(head_mask, self.config.num_layers)
+ cross_attn_head_mask = self.get_head_mask(cross_attn_head_mask, self.config.num_layers)
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_router_probs = () if output_router_logits else None
+ all_cross_attentions = () if (output_attentions and self.is_decoder) else None
+ position_bias = None
+ encoder_decoder_position_bias = None
+
+ hidden_states = self.dropout(inputs_embeds)
+
+ for i, layer_module in enumerate(self.block):
+ layer_head_mask = head_mask[i]
+ cross_attn_layer_head_mask = cross_attn_head_mask[i]
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states,
+ causal_mask,
+ position_bias,
+ encoder_hidden_states,
+ encoder_extended_attention_mask,
+ encoder_decoder_position_bias,
+ layer_head_mask=layer_head_mask,
+ cross_attn_layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_router_logits=output_router_logits,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ router_probs = layer_outputs[-1]
+ layer_outputs = layer_outputs[:-1]
+
+ hidden_states = layer_outputs[0]
+
+ # We share the position biases between the layers - the first layer store them
+ # layer_outputs = hidden-states, key-value-states (self-attention position bias), (self-attention weights),
+ # (cross-attention position bias), (cross-attention weights)
+ position_bias = layer_outputs[1]
+ if self.is_decoder and encoder_hidden_states is not None:
+ encoder_decoder_position_bias = layer_outputs[3 if output_attentions else 2]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[2],)
+ if self.is_decoder:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[4],)
+
+ if output_router_logits:
+ all_router_probs = all_router_probs + (router_probs,)
+
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ past_key_values,
+ all_hidden_states,
+ all_attentions,
+ all_cross_attentions,
+ all_router_probs,
+ ]
+ if v is not None
+ )
+ return MoEModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ router_probs=all_router_probs,
+ )
+
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._update_causal_mask
+ def _update_causal_mask(
+ self,
+ attention_mask: Union[torch.Tensor, "BlockMask"],
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool = False,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+ if self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask)
+ return attention_mask
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_compilable_cache = past_key_values.is_compileable if past_key_values is not None else False
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_compilable_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype = input_tensor.dtype
+ sequence_length = input_tensor.shape[1]
+ if using_compilable_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type in ["cuda", "xpu", "npu"]
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._prepare_4d_causal_attention_mask_with_cache_position
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=cache_position.device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=cache_position.device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :].to(
+ causal_mask.device
+ )
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
+
+
+# Warning message for FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+__HEAD_MASK_WARNING_MSG = """
+The input argument `head_mask` was split into two arguments `head_mask` and `decoder_head_mask`. Currently,
+`decoder_head_mask` is set to copy `head_mask`, but this feature is deprecated and will be removed in future versions.
+If you do not want to use any `decoder_head_mask` now, please set `decoder_head_mask = torch.ones(num_layers,
+num_heads)`.
+"""
+
+
+@auto_docstring
+class SwitchTransformersModel(SwitchTransformersPreTrainedModel):
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight"]
+
+ def __init__(self, config: SwitchTransformersConfig):
+ super().__init__(config)
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = SwitchTransformersStack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ self.decoder = SwitchTransformersStack(decoder_config, self.shared)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Model parallel
+ self.device_map = None
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ def get_encoder(self):
+ return self.encoder
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ decoder_inputs_embeds: Optional[torch.Tensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ output_router_logits: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqMoEModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. SWITCH_TRANSFORMERS is a model with relative position
+ embeddings so you should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [SWITCH_TRANSFORMERS
+ Training](./switch_transformers#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ SWITCH_TRANSFORMERS uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [SWITCH_TRANSFORMERS
+ Training](./switch_transformers#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, SwitchTransformersModel
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/switch-base-8")
+ >>> model = SwitchTransformersModel.from_pretrained("google/switch-base-8")
+
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> decoder_input_ids = tokenizer("Studies show that", return_tensors="pt").input_ids # Batch size 1
+
+ >>> # preprocess: Prepend decoder_input_ids with start token which is pad token for SwitchTransformersModel.
+ >>> # This is not needed for torch's SwitchTransformersForConditionalGeneration as it does this internally using labels arg.
+ >>> decoder_input_ids = model._shift_right(decoder_input_ids)
+
+ >>> # forward pass
+ >>> outputs = model(input_ids=input_ids, decoder_input_ids=decoder_input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+ if head_mask is not None and decoder_head_mask is None:
+ if self.config.num_layers == self.config.num_decoder_layers:
+ warnings.warn(__HEAD_MASK_WARNING_MSG, FutureWarning)
+ decoder_head_mask = head_mask
+
+ if (
+ output_router_logits
+ and self.config.num_sparse_encoder_layers == 0
+ and self.config.num_sparse_encoder_layers == 0
+ ):
+ raise ValueError(
+ "You asked to return `output_router_logits` but the transformer in dense, and does "
+ " not contain any sparse MLP Layers. Set `output_router_logits = False` and restart"
+ )
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ output_router_logits=output_router_logits,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, MoEModelOutput):
+ encoder_outputs = MoEModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ router_probs=encoder_outputs[3] if len(encoder_outputs) > 3 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ output_router_logits=output_router_logits,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqMoEModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ decoder_router_logits=decoder_outputs.router_probs,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ encoder_router_logits=encoder_outputs.router_probs,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ SWITCH_TRANSFORMERS Model with a `language modeling` head on top.
+ """
+)
+class SwitchTransformersForConditionalGeneration(SwitchTransformersPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight", "lm_head.weight"]
+
+ def __init__(self, config: SwitchTransformersConfig):
+ super().__init__(config)
+ self.model_dim = config.d_model
+
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = SwitchTransformersStack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = SwitchTransformersStack(decoder_config, self.shared)
+
+ self.lm_head = nn.Linear(config.d_model, config.vocab_size, bias=False)
+
+ self.router_z_loss_coef = config.router_z_loss_coef
+ self.router_aux_loss_coef = config.router_aux_loss_coef
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Model parallel
+ self.device_map = None
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.Tensor]]] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ output_router_logits: Optional[bool] = True,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqMoEOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. SWITCH_TRANSFORMERS is a model with relative position
+ embeddings so you should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [SWITCH_TRANSFORMERS
+ Training](./switch_transformers#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ SWITCH_TRANSFORMERS uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [SWITCH_TRANSFORMERS
+ Training](./switch_transformers#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size - 1]`. All labels set to `-100` are ignored (masked), the loss is only computed for
+ labels in `[0, ..., config.vocab_size]`
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, SwitchTransformersForConditionalGeneration
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/switch-base-8")
+ >>> model = SwitchTransformersForConditionalGeneration.from_pretrained("google/switch-base-8")
+
+ >>> # training
+ >>> input_ids = tokenizer("The walks in park", return_tensors="pt").input_ids
+ >>> labels = tokenizer(" cute dog the ", return_tensors="pt").input_ids
+ >>> outputs = model(input_ids=input_ids, labels=labels)
+ >>> loss = outputs.loss
+ >>> logits = outputs.logits
+
+ >>> # inference
+ >>> input_ids = tokenizer(
+ ... "summarize: studies have shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> outputs = model.generate(input_ids)
+ >>> # . To, let’s say you have a dog. To summarize:
+ >>> # Since the model has been trained on MLM, this will output gibberish
+ ```"""
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+ if head_mask is not None and decoder_head_mask is None:
+ if self.config.num_layers == self.config.num_decoder_layers:
+ warnings.warn(__HEAD_MASK_WARNING_MSG, FutureWarning)
+ decoder_head_mask = head_mask
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ # Convert encoder inputs in embeddings if needed
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ output_router_logits=output_router_logits,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, MoEModelOutput):
+ encoder_outputs = MoEModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ router_probs=encoder_outputs[3] if len(encoder_outputs) > 3 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None:
+ # get decoder inputs from shifting lm labels to the right
+ decoder_input_ids = self._shift_right(labels)
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ output_router_logits=output_router_logits,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ if self.config.tie_word_embeddings:
+ # Rescale output before projecting on vocab
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/transformer.py#L586
+ sequence_output = sequence_output * (self.model_dim**-0.5)
+
+ lm_logits = self.lm_head(sequence_output)
+
+ loss = None
+ encoder_z_loss = None
+ encoder_aux_loss = None
+ decoder_z_loss = None
+ decoder_aux_loss = None
+
+ if output_router_logits:
+ # Compute the router loss (z_loss + auxiliary loss) for each router in the encoder and decoder
+ if self.encoder.config.encoder_sparse_step > 1:
+ encoder_router_logits, encoder_expert_indexes = self._unpack_router_logits(encoder_outputs[-1])
+ encoder_z_loss = router_z_loss_func(encoder_router_logits)
+ encoder_router_probs = nn.Softmax(dim=-1)(encoder_router_logits)
+ encoder_aux_loss = load_balancing_loss_func(encoder_router_probs, encoder_expert_indexes)
+ else:
+ encoder_z_loss = 0
+ encoder_aux_loss = 0
+
+ if self.decoder.config.decoder_sparse_step > 1:
+ decoder_router_logits, decoder_expert_indexes = self._unpack_router_logits(decoder_outputs[-1])
+ decoder_z_loss = router_z_loss_func(decoder_router_logits)
+ decoder_router_probs = nn.Softmax(dim=-1)(decoder_router_logits)
+ decoder_aux_loss = load_balancing_loss_func(decoder_router_probs, decoder_expert_indexes)
+ else:
+ decoder_z_loss = 0
+ decoder_aux_loss = 0
+
+ if labels is not None:
+ loss_fct = CrossEntropyLoss(ignore_index=-100)
+ # move labels to correct device to enable PP
+ labels = labels.to(lm_logits.device)
+ loss = loss_fct(lm_logits.view(-1, lm_logits.size(-1)), labels.view(-1))
+
+ if output_router_logits:
+ z_loss = self.router_z_loss_coef * (encoder_z_loss + decoder_z_loss)
+ aux_loss = self.router_aux_loss_coef * (encoder_aux_loss + decoder_aux_loss)
+ loss = loss + z_loss + aux_loss
+
+ if not return_dict:
+ output = (lm_logits,)
+ if output_router_logits:
+ output += (encoder_z_loss, encoder_aux_loss, decoder_z_loss, decoder_aux_loss)
+ output += (*decoder_outputs[1:], *encoder_outputs)
+
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqMoEOutput(
+ loss=loss,
+ logits=lm_logits,
+ encoder_z_loss=encoder_z_loss,
+ encoder_aux_loss=encoder_aux_loss,
+ decoder_z_loss=decoder_z_loss,
+ decoder_aux_loss=decoder_aux_loss,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ decoder_router_logits=decoder_outputs.router_probs,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ encoder_router_logits=encoder_outputs.router_probs,
+ )
+
+ def _unpack_router_logits(self, router_outputs):
+ total_router_logits = []
+ total_expert_indexes = []
+ for router_output in router_outputs:
+ if len(router_output[0].shape) > 1:
+ router_logits, expert_indexes = router_output
+ total_router_logits.append(router_logits)
+ total_expert_indexes.append(expert_indexes)
+ return torch.cat(total_router_logits, dim=1), torch.cat(total_expert_indexes, dim=1)
+
+ def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor):
+ return self._shift_right(labels)
+
+
+@auto_docstring(
+ custom_intro="""
+ The bare SWITCH_TRANSFORMERS Model transformer outputting encoder's raw hidden-states without any specific head
+ """
+)
+class SwitchTransformersEncoderModel(SwitchTransformersPreTrainedModel):
+ _tied_weights_keys = ["encoder.embed_tokens.weight"]
+
+ def __init__(self, config: SwitchTransformersConfig):
+ super().__init__(config)
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.use_cache = False
+ encoder_config.is_encoder_decoder = False
+ self.encoder = SwitchTransformersStack(encoder_config, self.shared)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Model parallel
+ self.device_map = None
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+
+ def get_encoder(self):
+ return self.encoder
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.block[layer].layer[0].SelfAttention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ output_router_logits: Optional[bool] = True,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], MoEModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. SWITCH_TRANSFORMERS is a model with relative position
+ embeddings so you should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [SWITCH_TRANSFORMERS
+ Training](./switch_transformers#training).
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, SwitchTransformersEncoderModel
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/switch-base-8")
+ >>> model = SwitchTransformersEncoderModel.from_pretrained("google/switch-base-8")
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> outputs = model(input_ids=input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ output_router_logits=output_router_logits,
+ return_dict=return_dict,
+ )
+
+ return encoder_outputs
+
+
+__all__ = [
+ "SwitchTransformersEncoderModel",
+ "SwitchTransformersForConditionalGeneration",
+ "SwitchTransformersModel",
+ "SwitchTransformersPreTrainedModel",
+ "SwitchTransformersTop1Router",
+ "SwitchTransformersSparseMLP",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..366eab10826b19cd75e87b013f58f55976969abe
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/__init__.py
@@ -0,0 +1,31 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_t5 import *
+ from .modeling_flax_t5 import *
+ from .modeling_t5 import *
+ from .modeling_tf_t5 import *
+ from .tokenization_t5 import *
+ from .tokenization_t5_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/configuration_t5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/configuration_t5.py
new file mode 100644
index 0000000000000000000000000000000000000000..21d2552008719e47946886fa5c20b79ef98bde9f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/configuration_t5.py
@@ -0,0 +1,171 @@
+# coding=utf-8
+# Copyright 2020, The T5 Authors and HuggingFace Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""T5 model configuration"""
+
+from collections.abc import Mapping
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxSeq2SeqConfigWithPast
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class T5Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`T5Model`] or a [`TFT5Model`]. It is used to
+ instantiate a T5 model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the T5
+ [google-t5/t5-small](https://huggingface.co/google-t5/t5-small) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Arguments:
+ vocab_size (`int`, *optional*, defaults to 32128):
+ Vocabulary size of the T5 model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`T5Model`] or [`TFT5Model`].
+ d_model (`int`, *optional*, defaults to 512):
+ Size of the encoder layers and the pooler layer.
+ d_kv (`int`, *optional*, defaults to 64):
+ Size of the key, query, value projections per attention head. The `inner_dim` of the projection layer will
+ be defined as `num_heads * d_kv`.
+ d_ff (`int`, *optional*, defaults to 2048):
+ Size of the intermediate feed forward layer in each `T5Block`.
+ num_layers (`int`, *optional*, defaults to 6):
+ Number of hidden layers in the Transformer encoder.
+ num_decoder_layers (`int`, *optional*):
+ Number of hidden layers in the Transformer decoder. Will use the same value as `num_layers` if not set.
+ num_heads (`int`, *optional*, defaults to 8):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ relative_attention_num_buckets (`int`, *optional*, defaults to 32):
+ The number of buckets to use for each attention layer.
+ relative_attention_max_distance (`int`, *optional*, defaults to 128):
+ The maximum distance of the longer sequences for the bucket separation.
+ dropout_rate (`float`, *optional*, defaults to 0.1):
+ The ratio for all dropout layers.
+ classifier_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for classifier.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-6):
+ The epsilon used by the layer normalization layers.
+ initializer_factor (`float`, *optional*, defaults to 1):
+ A factor for initializing all weight matrices (should be kept to 1, used internally for initialization
+ testing).
+ feed_forward_proj (`string`, *optional*, defaults to `"relu"`):
+ Type of feed forward layer to be used. Should be one of `"relu"` or `"gated-gelu"`. T5v1.1 uses the
+ `"gated-gelu"` feed forward projection. Original T5 uses `"relu"`.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+ """
+
+ model_type = "t5"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {
+ "hidden_size": "d_model",
+ "num_attention_heads": "num_heads",
+ "num_hidden_layers": "num_layers",
+ "head_dim": "d_kv",
+ }
+
+ def __init__(
+ self,
+ vocab_size=32128,
+ d_model=512,
+ d_kv=64,
+ d_ff=2048,
+ num_layers=6,
+ num_decoder_layers=None,
+ num_heads=8,
+ relative_attention_num_buckets=32,
+ relative_attention_max_distance=128,
+ dropout_rate=0.1,
+ layer_norm_epsilon=1e-6,
+ initializer_factor=1.0,
+ feed_forward_proj="relu",
+ is_encoder_decoder=True,
+ use_cache=True,
+ pad_token_id=0,
+ eos_token_id=1,
+ classifier_dropout=0.0,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.d_model = d_model
+ self.d_kv = d_kv
+ self.d_ff = d_ff
+ self.num_layers = num_layers
+ self.num_decoder_layers = (
+ num_decoder_layers if num_decoder_layers is not None else self.num_layers
+ ) # default = symmetry
+ self.num_heads = num_heads
+ self.relative_attention_num_buckets = relative_attention_num_buckets
+ self.relative_attention_max_distance = relative_attention_max_distance
+ self.dropout_rate = dropout_rate
+ self.classifier_dropout = classifier_dropout
+ self.layer_norm_epsilon = layer_norm_epsilon
+ self.initializer_factor = initializer_factor
+ self.feed_forward_proj = feed_forward_proj
+ self.use_cache = use_cache
+
+ act_info = self.feed_forward_proj.split("-")
+ self.dense_act_fn = act_info[-1]
+ self.is_gated_act = act_info[0] == "gated"
+
+ if len(act_info) > 1 and act_info[0] != "gated" or len(act_info) > 2:
+ raise ValueError(
+ f"`feed_forward_proj`: {feed_forward_proj} is not a valid activation function of the dense layer. "
+ "Please make sure `feed_forward_proj` is of the format `gated-{ACT_FN}` or `{ACT_FN}`, e.g. "
+ "'gated-gelu' or 'relu'"
+ )
+
+ # for backwards compatibility
+ if feed_forward_proj == "gated-gelu":
+ self.dense_act_fn = "gelu_new"
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ eos_token_id=eos_token_id,
+ is_encoder_decoder=is_encoder_decoder,
+ **kwargs,
+ )
+
+
+class T5OnnxConfig(OnnxSeq2SeqConfigWithPast):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ common_inputs = {
+ "input_ids": {0: "batch", 1: "encoder_sequence"},
+ "attention_mask": {0: "batch", 1: "encoder_sequence"},
+ }
+ if self.use_past:
+ common_inputs["attention_mask"][1] = "past_encoder_sequence + sequence"
+ common_inputs["decoder_input_ids"] = {0: "batch"}
+ common_inputs["decoder_attention_mask"] = {0: "batch", 1: "past_decoder_sequence + sequence"}
+ else:
+ common_inputs["decoder_input_ids"] = {0: "batch", 1: "decoder_sequence"}
+ common_inputs["decoder_attention_mask"] = {0: "batch", 1: "decoder_sequence"}
+
+ if self.use_past:
+ self.fill_with_past_key_values_(common_inputs, direction="inputs")
+
+ return common_inputs
+
+ @property
+ def default_onnx_opset(self) -> int:
+ return 13
+
+
+__all__ = ["T5Config", "T5OnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_flax_t5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_flax_t5.py
new file mode 100644
index 0000000000000000000000000000000000000000..c829a084e4d96e15efd28cad90dd52f02be2d6dd
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_flax_t5.py
@@ -0,0 +1,1801 @@
+# coding=utf-8
+# Copyright 2021 T5 Authors and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Flax T5 model."""
+
+import copy
+from typing import Callable, Optional
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+import numpy as np
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.linen import combine_masks, make_causal_mask
+from flax.linen import partitioning as nn_partitioning
+from flax.linen.attention import dot_product_attention_weights
+from flax.traverse_util import flatten_dict, unflatten_dict
+from jax.random import PRNGKey
+
+from ...modeling_flax_outputs import (
+ FlaxBaseModelOutput,
+ FlaxBaseModelOutputWithPastAndCrossAttentions,
+ FlaxCausalLMOutputWithCrossAttentions,
+ FlaxSeq2SeqLMOutput,
+ FlaxSeq2SeqModelOutput,
+)
+from ...modeling_flax_utils import (
+ ACT2FN,
+ FlaxPreTrainedModel,
+ append_call_sample_docstring,
+ append_replace_return_docstrings,
+ overwrite_call_docstring,
+)
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging, replace_return_docstrings
+from .configuration_t5 import T5Config
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "google-t5/t5-small"
+_CONFIG_FOR_DOC = "T5Config"
+
+remat = nn_partitioning.remat
+
+
+# Copied from transformers.models.bart.modeling_flax_bart.shift_tokens_right
+def shift_tokens_right(input_ids: jnp.ndarray, pad_token_id: int, decoder_start_token_id: int) -> jnp.ndarray:
+ """
+ Shift input ids one token to the right.
+ """
+ shifted_input_ids = jnp.zeros_like(input_ids)
+ shifted_input_ids = shifted_input_ids.at[:, 1:].set(input_ids[:, :-1])
+ shifted_input_ids = shifted_input_ids.at[:, 0].set(decoder_start_token_id)
+
+ shifted_input_ids = jnp.where(shifted_input_ids == -100, pad_token_id, shifted_input_ids)
+ return shifted_input_ids
+
+
+class FlaxT5LayerNorm(nn.Module):
+ hidden_size: int
+ dtype: jnp.dtype = jnp.float32
+ eps: float = 1e-6
+ weight_init: Callable[..., np.ndarray] = jax.nn.initializers.ones
+
+ def setup(self):
+ self.weight = self.param("weight", self.weight_init, (self.hidden_size,))
+
+ def __call__(self, hidden_states):
+ """
+ Construct a layernorm module in the T5 style; No bias and no subtraction of mean.
+ """
+ # layer norm should always be calculated in float32
+ variance = jnp.power(hidden_states.astype("f4"), 2).mean(axis=-1, keepdims=True)
+ hidden_states = hidden_states / jnp.sqrt(variance + self.eps)
+
+ return self.weight * hidden_states
+
+
+class FlaxT5DenseActDense(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ wi_init_std = self.config.initializer_factor * (self.config.d_model**-0.5)
+ wo_init_std = self.config.initializer_factor * (self.config.d_ff**-0.5)
+
+ self.wi = nn.Dense(
+ self.config.d_ff,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(wi_init_std),
+ dtype=self.dtype,
+ )
+ self.wo = nn.Dense(
+ self.config.d_model,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(wo_init_std),
+ dtype=self.dtype,
+ )
+ self.dropout = nn.Dropout(self.config.dropout_rate)
+ self.act = ACT2FN[self.config.dense_act_fn]
+
+ def __call__(self, hidden_states, deterministic=True):
+ hidden_states = self.wi(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+class FlaxT5DenseGatedActDense(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ wi_init_std = self.config.initializer_factor * (self.config.d_model**-0.5)
+ wo_init_std = self.config.initializer_factor * (self.config.d_ff**-0.5)
+
+ self.wi_0 = nn.Dense(
+ self.config.d_ff,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(wi_init_std),
+ dtype=self.dtype,
+ )
+ self.wi_1 = nn.Dense(
+ self.config.d_ff,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(wi_init_std),
+ dtype=self.dtype,
+ )
+ self.wo = nn.Dense(
+ self.config.d_model,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(wo_init_std),
+ dtype=self.dtype,
+ )
+ self.dropout = nn.Dropout(self.config.dropout_rate)
+ self.act = ACT2FN[self.config.dense_act_fn]
+
+ def __call__(self, hidden_states, deterministic):
+ hidden_gelu = self.act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+class FlaxT5LayerFF(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ if self.config.is_gated_act:
+ self.DenseReluDense = FlaxT5DenseGatedActDense(self.config, dtype=self.dtype)
+ else:
+ self.DenseReluDense = FlaxT5DenseActDense(self.config, dtype=self.dtype)
+
+ self.layer_norm = FlaxT5LayerNorm(self.config.d_model, eps=self.config.layer_norm_epsilon, dtype=self.dtype)
+ self.dropout = nn.Dropout(self.config.dropout_rate)
+
+ def __call__(self, hidden_states, deterministic=True):
+ forwarded_states = self.layer_norm(hidden_states)
+ forwarded_states = self.DenseReluDense(forwarded_states, deterministic=deterministic)
+ hidden_states = hidden_states + self.dropout(forwarded_states, deterministic=deterministic)
+ return hidden_states
+
+
+class FlaxT5Attention(nn.Module):
+ config: T5Config
+ has_relative_attention_bias: bool = False
+ causal: bool = False
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.relative_attention_num_buckets = self.config.relative_attention_num_buckets
+ self.relative_attention_max_distance = self.config.relative_attention_max_distance
+ self.d_model = self.config.d_model
+ self.key_value_proj_dim = self.config.d_kv
+ self.n_heads = self.config.num_heads
+ self.dropout = self.config.dropout_rate
+ self.inner_dim = self.n_heads * self.key_value_proj_dim
+
+ q_init_std = self.config.initializer_factor * ((self.inner_dim * self.key_value_proj_dim) ** -0.5)
+ kv_init_std = self.config.initializer_factor * (self.inner_dim**-0.5)
+ o_init_std = self.config.initializer_factor * (self.inner_dim**-0.5)
+
+ self.q = nn.Dense(
+ self.inner_dim,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(q_init_std),
+ dtype=self.dtype,
+ )
+ self.k = nn.Dense(
+ self.inner_dim,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(kv_init_std),
+ dtype=self.dtype,
+ )
+ self.v = nn.Dense(
+ self.inner_dim,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(kv_init_std),
+ dtype=self.dtype,
+ )
+ self.o = nn.Dense(
+ self.d_model,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(o_init_std),
+ dtype=self.dtype,
+ )
+
+ if self.has_relative_attention_bias:
+ self.relative_attention_bias = nn.Embed(
+ self.relative_attention_num_buckets,
+ self.n_heads,
+ embedding_init=jax.nn.initializers.normal(kv_init_std),
+ dtype=self.dtype,
+ )
+
+ @staticmethod
+ def _relative_position_bucket(relative_position, bidirectional=True, num_buckets=32, max_distance=128):
+ """
+ Adapted from Mesh Tensorflow:
+ https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593
+
+ Translate relative position to a bucket number for relative attention. The relative position is defined as
+ memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to
+ position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for
+ small absolute relative_position and larger buckets for larger absolute relative_positions. All relative
+ positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket.
+ This should allow for more graceful generalization to longer sequences than the model has been trained on
+ """
+ relative_buckets = 0
+ if bidirectional:
+ num_buckets //= 2
+ relative_buckets += (relative_position > 0) * num_buckets
+ relative_position = jnp.abs(relative_position)
+ else:
+ relative_position = -jnp.clip(relative_position, a_max=0)
+ # now relative_position is in the range [0, inf)
+
+ # half of the buckets are for exact increments in positions
+ max_exact = num_buckets // 2
+ is_small = relative_position < max_exact
+
+ # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance
+ relative_position_if_large = max_exact + (
+ jnp.log(relative_position / max_exact) / jnp.log(max_distance / max_exact) * (num_buckets - max_exact)
+ )
+ relative_position_if_large = jnp.clip(relative_position_if_large, a_max=num_buckets - 1)
+
+ relative_buckets += jnp.where(is_small, relative_position, relative_position_if_large)
+
+ return relative_buckets.astype("i4")
+
+ def compute_bias(self, query_length, key_length):
+ """Compute binned relative position bias"""
+ context_position = jnp.arange(query_length, dtype="i4")[:, None]
+ memory_position = jnp.arange(key_length, dtype="i4")[None, :]
+
+ relative_position = memory_position - context_position
+ relative_position_bucket = self._relative_position_bucket(
+ relative_position,
+ bidirectional=(not self.causal),
+ num_buckets=self.relative_attention_num_buckets,
+ max_distance=self.relative_attention_max_distance,
+ )
+
+ values = self.relative_attention_bias(relative_position_bucket)
+ values = values.transpose((2, 0, 1))[None, :, :, :]
+ return values
+
+ def _split_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.n_heads, self.key_value_proj_dim))
+
+ def _merge_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.inner_dim,))
+
+ @nn.compact
+ def _concatenate_to_cache(self, key, value, query, attention_mask):
+ """
+ This function takes projected key, value states from a single input token and concatenates the states to cached
+ states from previous steps. This function is slightly adapted from the official Flax repository:
+ https://github.com/google/flax/blob/491ce18759622506588784b4fca0e4bf05f8c8cd/flax/linen/attention.py#L252
+ """
+ # detect if we're initializing by absence of existing cache data.
+ is_initialized = self.has_variable("cache", "cached_key")
+ cached_key = self.variable("cache", "cached_key", jnp.zeros, key.shape, key.dtype)
+ cached_value = self.variable("cache", "cached_value", jnp.zeros, value.shape, value.dtype)
+ cache_index = self.variable("cache", "cache_index", lambda: jnp.array(0, dtype=jnp.int32))
+
+ if is_initialized:
+ *batch_dims, max_length, num_heads, depth_per_head = cached_key.value.shape
+ # update key, value caches with our new 1d spatial slices
+ cur_index = cache_index.value
+ indices = (0,) * len(batch_dims) + (cur_index, 0, 0)
+ key = jax.lax.dynamic_update_slice(cached_key.value, key, indices)
+ value = jax.lax.dynamic_update_slice(cached_value.value, value, indices)
+ cached_key.value = key
+ cached_value.value = value
+ num_updated_cache_vectors = query.shape[1]
+ cache_index.value = cache_index.value + num_updated_cache_vectors
+ # causal mask for cached decoder self-attention: our single query position should only attend to those key positions
+ # that have already been generated and cached, not the remaining zero elements.
+ pad_mask = jnp.broadcast_to(
+ jnp.arange(max_length) < cur_index + num_updated_cache_vectors,
+ tuple(batch_dims) + (1, num_updated_cache_vectors, max_length),
+ )
+ attention_mask = combine_masks(pad_mask, attention_mask)
+ return key, value, attention_mask
+
+ def _create_position_bias(
+ self, key_states, query_states, attention_mask, init_cache, seq_length, causal_attention_mask_shift
+ ):
+ cache_is_filled = self.causal and self.has_variable("cache", "cached_key") and (not init_cache)
+ key_length = key_states.shape[1]
+ query_length = key_length if cache_is_filled else query_states.shape[1]
+
+ if self.has_relative_attention_bias:
+ position_bias = self.compute_bias(query_length, key_length)
+ elif attention_mask is not None:
+ position_bias = jnp.zeros_like(attention_mask)
+ else:
+ position_bias = jnp.zeros((1, self.n_heads, query_length, key_length), dtype=self.dtype)
+
+ # if key and values are already calculated, only the last query position bias should be taken
+ if cache_is_filled:
+ max_decoder_length = self.variables["cache"]["cached_key"].shape[1]
+ position_bias = jax.lax.dynamic_slice(
+ position_bias,
+ (0, 0, causal_attention_mask_shift, 0),
+ (1, self.n_heads, seq_length, max_decoder_length),
+ )
+ return position_bias
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask=None,
+ key_value_states=None,
+ position_bias=None,
+ use_cache=False,
+ output_attentions=False,
+ deterministic=True,
+ init_cache=False,
+ ):
+ """
+ Self-attention (if key_value_states is None) or attention over source sentence (provided by key_value_states).
+ """
+ batch_size, seq_length = hidden_states.shape[:2]
+
+ # q, k, v projections
+ query_states = self.q(hidden_states) # (batch_size, n_heads, seq_length, dim_per_head)
+ key_states = self.k(hidden_states) if key_value_states is None else self.k(key_value_states)
+ value_states = self.v(hidden_states) if key_value_states is None else self.v(key_value_states)
+
+ # reshape to (batch_size, seq_length, n_heads, head_dim)
+ query_states = self._split_heads(query_states)
+ key_states = self._split_heads(key_states)
+ value_states = self._split_heads(value_states)
+
+ # counter-act scaling in dot_product_attention_weights function
+ query_states *= jnp.sqrt(query_states.shape[-1])
+
+ # for fast decoding causal attention mask should be shifted
+ causal_attention_mask_shift = (
+ self.variables["cache"]["cache_index"] if (self.has_variable("cache", "cached_key") and self.causal) else 0
+ )
+ # create causal attention_mask; attention_mask has to be defined when model is causal
+ if self.causal:
+ causal_attention_mask = make_causal_mask(attention_mask, dtype="bool")
+
+ # fast decoding for generate requires special attention_mask
+ if self.has_variable("cache", "cached_key"):
+ max_decoder_length = self.variables["cache"]["cached_key"].shape[1]
+ causal_attention_mask = jax.lax.dynamic_slice(
+ causal_attention_mask,
+ (0, 0, causal_attention_mask_shift, 0),
+ (1, 1, seq_length, max_decoder_length),
+ )
+
+ # broadcast causal attention mask & attention mask to fit for merge
+ causal_attention_mask = jnp.broadcast_to(
+ causal_attention_mask, (batch_size,) + causal_attention_mask.shape[1:]
+ )
+ attention_mask = jnp.broadcast_to(
+ jnp.expand_dims(attention_mask, axis=(-3, -2)), causal_attention_mask.shape
+ )
+ attention_mask = combine_masks(attention_mask, causal_attention_mask)
+ elif attention_mask is not None:
+ attention_mask = jnp.expand_dims(attention_mask, axis=(-3, -2))
+
+ # During fast autoregressive decoding, we feed one position at a time,
+ # and cache the keys and values step by step.
+ if self.causal and (self.has_variable("cache", "cached_key") or init_cache):
+ key_states, value_states, attention_mask = self._concatenate_to_cache(
+ key_states, value_states, query_states, attention_mask
+ )
+
+ # replace masked positions with -10_000
+ if attention_mask is not None:
+ mask_value = jnp.finfo(self.dtype).min
+ attention_mask = jax.lax.select(
+ attention_mask > 0,
+ jnp.full(attention_mask.shape, 0.0).astype(self.dtype),
+ jnp.full(attention_mask.shape, mask_value).astype(self.dtype),
+ )
+
+ if position_bias is None:
+ # compute position bias (only for first layer)
+ position_bias = self._create_position_bias(
+ key_states, query_states, attention_mask, init_cache, seq_length, causal_attention_mask_shift
+ )
+
+ if attention_mask is not None:
+ position_bias = position_bias + attention_mask
+
+ # create dropout rng
+ dropout_rng = None
+ if not deterministic and self.dropout > 0.0:
+ dropout_rng = self.make_rng("dropout")
+
+ # Softmax(QK^T)
+ attn_weights = dot_product_attention_weights(
+ query_states,
+ key_states,
+ bias=position_bias,
+ dropout_rng=dropout_rng,
+ dropout_rate=self.dropout,
+ broadcast_dropout=True,
+ deterministic=deterministic,
+ dtype=self.dtype,
+ )
+
+ # multiply with value states
+ attn_output = jnp.einsum("...hqk,...khd->...qhd", attn_weights, value_states)
+
+ # bring back to (batch_size, seq_length, d_model)
+ attn_output = self._merge_heads(attn_output)
+
+ # apply output matrix
+ attn_output = self.o(attn_output)
+
+ outputs = (attn_output, position_bias)
+
+ if output_attentions:
+ outputs = outputs + (attn_weights,)
+
+ return outputs
+
+
+class FlaxT5LayerSelfAttention(nn.Module):
+ config: T5Config
+ has_relative_attention_bias: bool = False
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.SelfAttention = FlaxT5Attention(
+ self.config,
+ has_relative_attention_bias=self.has_relative_attention_bias,
+ causal=self.config.causal,
+ dtype=self.dtype,
+ )
+ self.layer_norm = FlaxT5LayerNorm(self.config.d_model, eps=self.config.layer_norm_epsilon, dtype=self.dtype)
+ self.dropout = nn.Dropout(self.config.dropout_rate)
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ output_attentions=False,
+ deterministic=True,
+ init_cache=False,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.SelfAttention(
+ normed_hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ deterministic=deterministic,
+ init_cache=init_cache,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0], deterministic=deterministic)
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+class FlaxT5LayerCrossAttention(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.EncDecAttention = FlaxT5Attention(
+ self.config, has_relative_attention_bias=False, causal=False, dtype=self.dtype
+ )
+ self.layer_norm = FlaxT5LayerNorm(self.config.d_model, eps=self.config.layer_norm_epsilon, dtype=self.dtype)
+ self.dropout = nn.Dropout(self.config.dropout_rate)
+
+ def __call__(
+ self,
+ hidden_states,
+ key_value_states,
+ attention_mask=None,
+ position_bias=None,
+ output_attentions=False,
+ deterministic=True,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.EncDecAttention(
+ normed_hidden_states,
+ attention_mask=attention_mask,
+ key_value_states=key_value_states,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0], deterministic=deterministic)
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+class FlaxT5Block(nn.Module):
+ config: T5Config
+ has_relative_attention_bias: bool = False
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.causal = self.config.causal
+ self.layer = (
+ FlaxT5LayerSelfAttention(
+ self.config,
+ has_relative_attention_bias=self.has_relative_attention_bias,
+ name=str(0),
+ dtype=self.dtype,
+ ),
+ )
+ feed_forward_index = 1
+ if self.causal:
+ self.layer += (FlaxT5LayerCrossAttention(self.config, name=str(1), dtype=self.dtype),)
+ feed_forward_index += 1
+
+ self.layer += (FlaxT5LayerFF(self.config, name=str(feed_forward_index), dtype=self.dtype),)
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ encoder_decoder_position_bias=None,
+ output_attentions=False,
+ return_dict=True,
+ deterministic=True,
+ init_cache=False,
+ ):
+ self_attention_outputs = self.layer[0](
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ deterministic=deterministic,
+ init_cache=init_cache,
+ )
+ hidden_states = self_attention_outputs[0]
+ attention_outputs = self_attention_outputs[1:] # Keep self-attention outputs and relative position weights
+
+ do_cross_attention = self.causal and encoder_hidden_states is not None
+ if do_cross_attention:
+ cross_attention_outputs = self.layer[1](
+ hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ position_bias=encoder_decoder_position_bias,
+ output_attentions=output_attentions,
+ deterministic=deterministic,
+ )
+ hidden_states = cross_attention_outputs[0]
+
+ # Keep cross-attention outputs and relative position weights
+ attention_outputs = attention_outputs + cross_attention_outputs[1:]
+
+ # Apply Feed Forward layer
+ hidden_states = self.layer[-1](hidden_states, deterministic=deterministic)
+
+ outputs = (hidden_states,)
+
+ outputs = outputs + attention_outputs
+
+ # returns hidden-states, present_key_value_states, (self-attention position bias), (self-attention weights),
+ # (cross-attention position bias), (cross-attention weights)
+ return outputs
+
+
+class FlaxT5LayerCollection(nn.Module):
+ config: T5Config
+ has_relative_attention_bias: bool
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.layer = FlaxT5Block(
+ self.config, has_relative_attention_bias=self.has_relative_attention_bias, dtype=self.dtype
+ )
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ encoder_decoder_position_bias=None,
+ output_attentions=False,
+ deterministic=True,
+ init_cache=False,
+ ):
+ return self.layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ encoder_decoder_position_bias=encoder_decoder_position_bias,
+ output_attentions=output_attentions,
+ deterministic=deterministic,
+ init_cache=init_cache,
+ )
+
+
+class FlaxT5BlockCollection(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.causal = self.config.causal
+ if self.gradient_checkpointing:
+ FlaxT5CheckpointLayer = remat(FlaxT5LayerCollection, static_argnums=(6, 7, 8))
+ self.blocks = [
+ FlaxT5CheckpointLayer(
+ self.config,
+ has_relative_attention_bias=(i == 0),
+ dtype=self.dtype,
+ name=str(i),
+ )
+ for i in range(self.config.num_layers)
+ ]
+ else:
+ self.blocks = [
+ FlaxT5LayerCollection(
+ self.config,
+ has_relative_attention_bias=(i == 0),
+ dtype=self.dtype,
+ name=str(i),
+ )
+ for i in range(self.config.num_layers)
+ ]
+
+ def __call__(
+ self,
+ hidden_states=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ deterministic: bool = True,
+ init_cache: bool = False,
+ ):
+ # Prepare head mask if needed
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and self.causal) else None
+ position_bias = None
+ encoder_decoder_position_bias = None
+
+ for i, layer_module in enumerate(self.blocks):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states,
+ attention_mask,
+ position_bias,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ encoder_decoder_position_bias,
+ output_attentions,
+ deterministic,
+ init_cache,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ # We share the position biases between the layers - the first layer store them
+ # layer_outputs = hidden-states, key-value-states (self-attention position bias), (self-attention weights),
+ # (cross-attention position bias), (cross-attention weights)
+ position_bias = layer_outputs[1]
+
+ if self.causal and encoder_hidden_states is not None:
+ encoder_decoder_position_bias = layer_outputs[3 if output_attentions else 2]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[2],)
+ if self.causal:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[4],)
+
+ return FlaxBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+class FlaxT5Stack(nn.Module):
+ config: T5Config
+ embed_tokens: nn.Embed
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.causal = self.config.causal
+
+ self.block = FlaxT5BlockCollection(
+ self.config, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+ self.final_layer_norm = FlaxT5LayerNorm(
+ self.config.d_model, eps=self.config.layer_norm_epsilon, dtype=self.dtype
+ )
+ self.dropout = nn.Dropout(self.config.dropout_rate)
+
+ def __call__(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ init_cache: bool = False,
+ ):
+ hidden_states = self.embed_tokens(input_ids)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+
+ outputs = self.block(
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ deterministic=deterministic,
+ init_cache=init_cache,
+ )
+
+ hidden_states = outputs[0]
+
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+
+ # Add last layer
+ all_hidden_states = None
+
+ if output_hidden_states:
+ all_hidden_states = outputs.hidden_states
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ if output_hidden_states:
+ return (
+ hidden_states,
+ all_hidden_states,
+ ) + outputs[2:]
+ return (hidden_states,) + outputs[1:]
+
+ return FlaxBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+T5_ENCODE_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`jnp.ndarray` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+T5_DECODE_INPUTS_DOCSTRING = r"""
+ Args:
+ decoder_input_ids (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ For training, `decoder_input_ids` should be provided.
+ encoder_outputs (`tuple(tuple(jnp.ndarray)`):
+ Tuple consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*: `attentions`)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ encoder_attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ decoder_attention_mask (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+
+ If you want to change padding behavior, you should modify to your needs. See diagram 1 in [the
+ paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ past_key_values (`Dict[str, np.ndarray]`, *optional*, returned by `init_cache` or when passing previous `past_key_values`):
+ Dictionary of pre-computed hidden-states (key and values in the attention blocks) that can be used for fast
+ auto-regressive decoding. Pre-computed key and value hidden-states are of shape *[batch_size, max_length]*.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+T5_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`jnp.ndarray` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ decoder_input_ids (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ T5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [T5
+ Training](./t5#training).
+ decoder_attention_mask (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ encoder_outputs (`tuple(tuple(jnp.ndarray)`, *optional*):
+ Tuple consists of (`last_hidden_state`, `optional`: *hidden_states*, `optional`: *attentions*)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)` is a sequence of hidden states at
+ the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ past_key_values (`tuple(tuple(jnp.ndarray))` of length `config.n_layers` with each tuple having 4 tensors of shape `(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`):
+ Contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+class FlaxT5PreTrainedModel(FlaxPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = T5Config
+ base_model_prefix = "transformer"
+ module_class: nn.Module = None
+
+ def __init__(
+ self,
+ config: T5Config,
+ input_shape: tuple[int] = (1, 1),
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ gradient_checkpointing: bool = False,
+ **kwargs,
+ ):
+ module = self.module_class(config=config, dtype=dtype, gradient_checkpointing=gradient_checkpointing, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ def enable_gradient_checkpointing(self):
+ self._module = self.module_class(
+ config=self.config,
+ dtype=self.dtype,
+ gradient_checkpointing=True,
+ )
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensors
+ input_ids = jnp.zeros(input_shape, dtype="i4")
+
+ attention_mask = jnp.ones_like(input_ids)
+ args = [input_ids, attention_mask]
+ if self.module_class not in [FlaxT5EncoderModule]:
+ decoder_input_ids = jnp.ones_like(input_ids)
+ decoder_attention_mask = jnp.ones_like(input_ids)
+ args.extend([decoder_input_ids, decoder_attention_mask])
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(
+ rngs,
+ *args,
+ )["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ @add_start_docstrings_to_model_forward(T5_INPUTS_DOCSTRING)
+ def __call__(
+ self,
+ input_ids: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ decoder_input_ids: jnp.ndarray = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ if decoder_input_ids is None:
+ raise ValueError(
+ "Make sure to provide both `input_ids` and `decoder_input_ids`. `decoder_input_ids` is not passed"
+ " here."
+ )
+
+ # prepare encoder inputs
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ # prepare decoder inputs
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {"dropout": dropout_rng} if dropout_rng is not None else {}
+
+ return self.module.apply(
+ {"params": params or self.params},
+ input_ids=jnp.array(input_ids, dtype="i4"),
+ attention_mask=jnp.array(attention_mask, dtype="i4"),
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ )
+
+ def init_cache(self, batch_size, max_length, encoder_outputs):
+ r"""
+ Args:
+ batch_size (`int`):
+ batch_size used for fast auto-regressive decoding. Defines the batch size of the initialized cache.
+ max_length (`int`):
+ maximum possible length for auto-regressive decoding. Defines the sequence length of the initialized
+ cache.
+ encoder_outputs (`Union[FlaxBaseModelOutput, tuple(tuple(jnp.ndarray)]`):
+ `encoder_outputs` consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*:
+ `attentions`). `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*)
+ is a sequence of hidden-states at the output of the last layer of the encoder. Used in the
+ cross-attention of the decoder.
+ """
+ # init input variables to retrieve cache
+ decoder_input_ids = jnp.ones((batch_size, max_length), dtype="i4")
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, **kwargs):
+ decoder_module = module._get_decoder_module()
+ return decoder_module(
+ decoder_input_ids,
+ decoder_attention_mask,
+ **kwargs,
+ )
+
+ init_variables = self.module.init(
+ jax.random.PRNGKey(0),
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_outputs[0],
+ init_cache=True,
+ method=_decoder_forward, # we only need to call the decoder to init the cache
+ )
+ return unfreeze(init_variables["cache"])
+
+ @add_start_docstrings(T5_ENCODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxBaseModelOutput, config_class=T5Config)
+ def encode(
+ self,
+ input_ids: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, FlaxT5ForConditionalGeneration
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = FlaxT5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+ >>> text = "My friends are cool but they eat too many carbs."
+ >>> inputs = tokenizer(text, return_tensors="np")
+ >>> encoder_outputs = model.encode(**inputs)
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _encoder_forward(module, input_ids, attention_mask, **kwargs):
+ encode_module = module._get_encoder_module()
+ return encode_module(input_ids, attention_mask, **kwargs)
+
+ return self.module.apply(
+ {"params": params or self.params},
+ input_ids=jnp.array(input_ids, dtype="i4"),
+ attention_mask=jnp.array(attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ method=_encoder_forward,
+ )
+
+ @add_start_docstrings(T5_DECODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxBaseModelOutputWithPastAndCrossAttentions, config_class=T5Config)
+ def decode(
+ self,
+ decoder_input_ids,
+ encoder_outputs,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ past_key_values: Optional[dict] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, FlaxT5ForConditionalGeneration
+ >>> import jax.numpy as jnp
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = FlaxT5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+ >>> text = "My friends are cool but they eat too many carbs."
+ >>> inputs = tokenizer(text, return_tensors="np")
+ >>> encoder_outputs = model.encode(**inputs)
+
+ >>> decoder_start_token_id = model.config.decoder_start_token_id
+ >>> decoder_input_ids = jnp.ones((inputs.input_ids.shape[0], 1), dtype="i4") * decoder_start_token_id
+
+ >>> outputs = model.decode(decoder_input_ids, encoder_outputs)
+ >>> logits = outputs.logits
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ encoder_hidden_states = encoder_outputs[0]
+ if encoder_attention_mask is None:
+ batch_size, sequence_length = encoder_hidden_states.shape[:2]
+ encoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ batch_size, sequence_length = decoder_input_ids.shape
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ inputs = {"params": params or self.params}
+
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be
+ # passed down to ensure cache is used. It has to be made sure that cache is marked as mutable so that
+ # it can be changed by FlaxT5Attention module
+ if past_key_values:
+ inputs["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, **kwargs):
+ decoder_module = module._get_decoder_module()
+ return decoder_module(
+ decoder_input_ids,
+ decoder_attention_mask,
+ **kwargs,
+ )
+
+ outputs = self.module.apply(
+ inputs,
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=jnp.array(encoder_attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ mutable=mutable,
+ method=_decoder_forward,
+ )
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs, past = outputs
+ outputs["past_key_values"] = unfreeze(past["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs, past = outputs
+ outputs = outputs[:1] + (unfreeze(past["cache"]),) + outputs[1:]
+
+ return outputs
+
+
+T5_START_DOCSTRING = r"""
+ The T5 model was proposed in [Exploring the Limits of Transfer Learning with a Unified Text-to-Text
+ Transformer](https://huggingface.co/papers/1910.10683) by Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan
+ Narang, Michael Matena, Yanqi Zhou, Wei Li, Peter J. Liu. It's an encoder decoder transformer pre-trained in a
+ text-to-text denoising generative setting.
+
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a Flax Linen
+ [flax.nn.Module](https://flax.readthedocs.io/en/latest/_autosummary/flax.nn.module.html) subclass. Use it as a
+ regular Flax Module and refer to the Flax documentation for all matter related to general usage and behavior.
+
+ Finally, this model supports inherent JAX features such as:
+
+ - [Just-In-Time (JIT) compilation](https://jax.readthedocs.io/en/latest/jax.html#just-in-time-compilation-jit)
+ - [Automatic Differentiation](https://jax.readthedocs.io/en/latest/jax.html#automatic-differentiation)
+ - [Vectorization](https://jax.readthedocs.io/en/latest/jax.html#vectorization-vmap)
+ - [Parallelization](https://jax.readthedocs.io/en/latest/jax.html#parallelization-pmap)
+
+ Parameters:
+ config ([`T5Config`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs).
+
+ This can be used to enable mixed-precision training or half-precision inference on GPUs or TPUs. If
+ specified all the computation will be performed with the given `dtype`.
+
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.**
+
+ If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`] and
+ [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+
+@add_start_docstrings(
+ "The bare T5 Model transformer outputting raw hidden-stateswithout any specific head on top.",
+ T5_START_DOCSTRING,
+)
+class FlaxT5Module(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def _get_encoder_module(self):
+ return self.encoder
+
+ def _get_decoder_module(self):
+ return self.decoder
+
+ def setup(self):
+ self.shared = nn.Embed(
+ self.config.vocab_size,
+ self.config.d_model,
+ embedding_init=jax.nn.initializers.normal(self.config.initializer_factor * 1.0),
+ dtype=self.dtype,
+ )
+
+ encoder_config = copy.deepcopy(self.config)
+ encoder_config.causal = False
+ self.encoder = FlaxT5Stack(
+ encoder_config,
+ embed_tokens=self.shared,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+
+ decoder_config = copy.deepcopy(self.config)
+ decoder_config.causal = True
+ decoder_config.num_layers = self.config.num_decoder_layers
+ self.decoder = FlaxT5Stack(
+ decoder_config,
+ embed_tokens=self.shared,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+
+ def __call__(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ decoder_input_ids=None,
+ decoder_attention_mask=None,
+ encoder_outputs=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ deterministic: bool = True,
+ ):
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Encode if needed (training, first prediction pass)
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_outputs[0],
+ encoder_attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return FlaxSeq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+class FlaxT5Model(FlaxT5PreTrainedModel):
+ module_class = FlaxT5Module
+
+
+append_call_sample_docstring(FlaxT5Model, _CHECKPOINT_FOR_DOC, FlaxSeq2SeqModelOutput, _CONFIG_FOR_DOC)
+
+FLAX_T5_MODEL_DOCSTRING = """
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, FlaxT5Model
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = FlaxT5Model.from_pretrained("google-t5/t5-small")
+
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="np"
+ ... ).input_ids
+ >>> decoder_input_ids = tokenizer("Studies show that", return_tensors="np").input_ids
+
+ >>> # preprocess: Prepend decoder_input_ids with start token which is pad token for T5Model.
+ >>> # This is not needed for torch's T5ForConditionalGeneration as it does this internally using labels arg.
+ >>> decoder_input_ids = model._shift_right(decoder_input_ids)
+
+ >>> # forward pass
+ >>> outputs = model(input_ids=input_ids, decoder_input_ids=decoder_input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```
+"""
+
+
+overwrite_call_docstring(FlaxT5Model, T5_INPUTS_DOCSTRING + FLAX_T5_MODEL_DOCSTRING)
+append_replace_return_docstrings(FlaxT5Model, output_type=FlaxSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+
+
+@add_start_docstrings(
+ "The bare T5 Model transformer outputting encoder's raw hidden-states without any specific head on top.",
+ T5_START_DOCSTRING,
+)
+class FlaxT5EncoderModule(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.shared = nn.Embed(
+ self.config.vocab_size,
+ self.config.d_model,
+ embedding_init=jax.nn.initializers.normal(self.config.initializer_factor * 1.0),
+ dtype=self.dtype,
+ )
+
+ encoder_config = copy.deepcopy(self.config)
+ encoder_config.is_decoder = False
+ encoder_config.is_encoder_decoder = False
+ encoder_config.causal = False
+ self.encoder = FlaxT5Stack(
+ encoder_config,
+ embed_tokens=self.shared,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+
+ def __call__(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ):
+ # Encode if needed (training, first prediction pass)
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ return encoder_outputs
+
+
+class FlaxT5EncoderModel(FlaxT5PreTrainedModel):
+ module_class = FlaxT5EncoderModule
+
+ @add_start_docstrings_to_model_forward(T5_ENCODE_INPUTS_DOCSTRING)
+ def __call__(
+ self,
+ input_ids: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # prepare encoder inputs
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {"dropout": dropout_rng} if dropout_rng is not None else {}
+
+ return self.module.apply(
+ {"params": params or self.params},
+ input_ids=jnp.array(input_ids, dtype="i4"),
+ attention_mask=jnp.array(attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ )
+
+
+@add_start_docstrings("""T5 Model with a `language modeling` head on top.""", T5_START_DOCSTRING)
+class FlaxT5ForConditionalGenerationModule(nn.Module):
+ config: T5Config
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def _get_encoder_module(self):
+ return self.encoder
+
+ def _get_decoder_module(self):
+ return self.decoder
+
+ def setup(self):
+ self.model_dim = self.config.d_model
+
+ self.shared = nn.Embed(
+ self.config.vocab_size,
+ self.config.d_model,
+ embedding_init=jax.nn.initializers.normal(self.config.initializer_factor),
+ dtype=self.dtype,
+ )
+
+ encoder_config = copy.deepcopy(self.config)
+ encoder_config.causal = False
+ encoder_config.use_cache = False
+ encoder_config.is_encoder_decoder = False
+ self.encoder = FlaxT5Stack(
+ encoder_config, self.shared, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+
+ decoder_config = copy.deepcopy(self.config)
+ decoder_config.causal = True
+ decoder_config.is_encoder_decoder = False
+ decoder_config.num_layers = self.config.num_decoder_layers
+ self.decoder = FlaxT5Stack(
+ decoder_config, self.shared, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+
+ self.lm_head = nn.Dense(
+ self.config.vocab_size,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_factor),
+ dtype=self.dtype,
+ )
+
+ def __call__(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ decoder_input_ids=None,
+ decoder_attention_mask=None,
+ encoder_outputs=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ deterministic: bool = True,
+ ):
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Encode
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ if self.config.tie_word_embeddings:
+ # Rescale output before projecting on vocab
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/transformer.py#L586
+ sequence_output = sequence_output * (self.model_dim**-0.5)
+
+ if self.config.tie_word_embeddings:
+ shared_embedding = self.shared.variables["params"]["embedding"]
+ lm_logits = self.lm_head.apply({"params": {"kernel": shared_embedding.T}}, sequence_output)
+ else:
+ lm_logits = self.lm_head(sequence_output)
+
+ if not return_dict:
+ return (lm_logits,) + decoder_outputs[1:] + encoder_outputs
+
+ return FlaxSeq2SeqLMOutput(
+ logits=lm_logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+class FlaxT5ForConditionalGeneration(FlaxT5PreTrainedModel):
+ module_class = FlaxT5ForConditionalGenerationModule
+
+ @add_start_docstrings(T5_DECODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxCausalLMOutputWithCrossAttentions, config_class=T5Config)
+ def decode(
+ self,
+ decoder_input_ids,
+ encoder_outputs,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ past_key_values: Optional[dict] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, FlaxT5ForConditionalGeneration
+ >>> import jax.numpy as jnp
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = FlaxT5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+ >>> text = "summarize: My friends are cool but they eat too many carbs."
+ >>> inputs = tokenizer(text, return_tensors="np")
+ >>> encoder_outputs = model.encode(**inputs)
+
+ >>> decoder_start_token_id = model.config.decoder_start_token_id
+ >>> decoder_input_ids = jnp.ones((inputs.input_ids.shape[0], 1), dtype="i4") * decoder_start_token_id
+
+ >>> outputs = model.decode(decoder_input_ids, encoder_outputs)
+ >>> logits = outputs.logits
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ encoder_hidden_states = encoder_outputs[0]
+ if encoder_attention_mask is None:
+ batch_size, sequence_length = encoder_hidden_states.shape[:2]
+ encoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ batch_size, sequence_length = decoder_input_ids.shape
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ inputs = {"params": params or self.params}
+
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be
+ # passed down to ensure cache is used. It has to be made sure that cache is marked as mutable so that
+ # it can be changed by FlaxT5Attention module
+ if past_key_values:
+ inputs["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, **kwargs):
+ decoder_module = module._get_decoder_module()
+ decoder_outputs = decoder_module(
+ decoder_input_ids,
+ decoder_attention_mask,
+ **kwargs,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ if self.config.tie_word_embeddings:
+ # Rescale output before projecting on vocab
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/transformer.py#L586
+ sequence_output = sequence_output * (self.config.d_model**-0.5)
+
+ if self.config.tie_word_embeddings:
+ shared_embedding = module.shared.variables["params"]["embedding"]
+ lm_logits = module.lm_head.apply({"params": {"kernel": shared_embedding.T}}, sequence_output)
+ else:
+ lm_logits = module.lm_head(sequence_output)
+
+ return lm_logits, decoder_outputs
+
+ outputs = self.module.apply(
+ inputs,
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=jnp.array(encoder_attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ mutable=mutable,
+ method=_decoder_forward,
+ )
+
+ if past_key_values is None:
+ lm_logits, decoder_outputs = outputs
+ else:
+ (lm_logits, decoder_outputs), past = outputs
+
+ if return_dict:
+ outputs = FlaxCausalLMOutputWithCrossAttentions(
+ logits=lm_logits,
+ hidden_states=decoder_outputs.hidden_states,
+ attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ )
+ else:
+ outputs = (lm_logits,) + decoder_outputs[1:]
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs["past_key_values"] = unfreeze(past["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs = outputs[:1] + (unfreeze(past["cache"]),) + outputs[1:]
+
+ return outputs
+
+ def prepare_inputs_for_generation(
+ self,
+ decoder_input_ids,
+ max_length,
+ attention_mask: Optional[jax.Array] = None,
+ decoder_attention_mask: Optional[jax.Array] = None,
+ encoder_outputs=None,
+ **kwargs,
+ ):
+ # initializing the cache
+ batch_size, seq_length = decoder_input_ids.shape
+
+ past_key_values = self.init_cache(batch_size, max_length, encoder_outputs)
+ # Note that usually one would have to put 0's in the attention_mask for x > input_ids.shape[-1] and x < cache_length.
+ # But since the decoder uses a causal mask, those positions are masked anyways.
+ # Thus we can create a single static attention_mask here, which is more efficient for compilation
+ extended_attention_mask = jnp.ones((batch_size, max_length), dtype="i4")
+ if decoder_attention_mask is not None:
+ extended_attention_mask = jax.lax.dynamic_update_slice(
+ extended_attention_mask, decoder_attention_mask, (0, 0)
+ )
+
+ return {
+ "past_key_values": past_key_values,
+ "encoder_outputs": encoder_outputs,
+ "encoder_attention_mask": attention_mask,
+ "decoder_attention_mask": extended_attention_mask,
+ }
+
+ def update_inputs_for_generation(self, model_outputs, model_kwargs):
+ model_kwargs["past_key_values"] = model_outputs.past_key_values
+ return model_kwargs
+
+
+FLAX_T5_CONDITIONAL_GENERATION_DOCSTRING = """
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, FlaxT5ForConditionalGeneration
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = FlaxT5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+ >>> ARTICLE_TO_SUMMARIZE = "summarize: My friends are cool but they eat too many carbs."
+ >>> inputs = tokenizer([ARTICLE_TO_SUMMARIZE], return_tensors="np")
+
+ >>> # Generate Summary
+ >>> summary_ids = model.generate(inputs["input_ids"]).sequences
+ >>> print(tokenizer.decode(summary_ids[0], skip_special_tokens=True, clean_up_tokenization_spaces=False))
+ ```
+"""
+
+
+overwrite_call_docstring(
+ FlaxT5ForConditionalGeneration, T5_INPUTS_DOCSTRING + FLAX_T5_CONDITIONAL_GENERATION_DOCSTRING
+)
+append_replace_return_docstrings(
+ FlaxT5ForConditionalGeneration, output_type=FlaxSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC
+)
+
+
+__all__ = ["FlaxT5EncoderModel", "FlaxT5ForConditionalGeneration", "FlaxT5Model", "FlaxT5PreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_t5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_t5.py
new file mode 100644
index 0000000000000000000000000000000000000000..35290bad16c639306131d6a75fe323633d9fd49b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_t5.py
@@ -0,0 +1,2406 @@
+# coding=utf-8
+# Copyright 2018 Mesh TensorFlow authors, T5 Authors and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch T5 model."""
+
+import copy
+import math
+import os
+import warnings
+from typing import Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+ Seq2SeqQuestionAnsweringModelOutput,
+ Seq2SeqSequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import (
+ DUMMY_INPUTS,
+ DUMMY_MASK,
+ add_start_docstrings,
+ auto_docstring,
+ is_torch_flex_attn_available,
+ is_torch_fx_proxy,
+ is_torchdynamo_compiling,
+ logging,
+)
+from ...utils.deprecation import deprecate_kwarg
+from ...utils.model_parallel_utils import assert_device_map, get_device_map
+from .configuration_t5 import T5Config
+
+
+if is_torch_flex_attn_available():
+ from torch.nn.attention.flex_attention import BlockMask
+
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.get_logger(__name__)
+
+
+####################################################
+# This dict contains ids and associated url
+# for the pretrained weights provided with the models
+####################################################
+
+
+####################################################
+# This is a conversion method from TF 1.0 to PyTorch
+# More details: https://medium.com/huggingface/from-tensorflow-to-pytorch-265f40ef2a28
+####################################################
+def load_tf_weights_in_t5(model, config, tf_checkpoint_path):
+ """Load tf checkpoints in a pytorch model."""
+ try:
+ import re
+
+ import numpy as np
+ import tensorflow as tf
+ except ImportError:
+ logger.error(
+ "Loading a TensorFlow model in PyTorch, requires TensorFlow to be installed. Please see "
+ "https://www.tensorflow.org/install/ for installation instructions."
+ )
+ raise
+ tf_path = os.path.abspath(tf_checkpoint_path)
+ logger.info(f"Converting TensorFlow checkpoint from {tf_path}")
+ # Load weights from TF model
+ init_vars = tf.train.list_variables(tf_path)
+ names = []
+ tf_weights = {}
+ for name, shape in init_vars:
+ logger.info(f"Loading TF weight {name} with shape {shape}")
+ array = tf.train.load_variable(tf_path, name)
+ names.append(name)
+ tf_weights[name] = array
+
+ for txt_name in names:
+ name = txt_name.split("/")
+ # adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
+ # which are not required for using pretrained model
+ if any(
+ n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
+ for n in name
+ ):
+ logger.info(f"Skipping {'/'.join(name)}")
+ tf_weights.pop(txt_name, None)
+ continue
+ if "_slot_" in name[-1]:
+ logger.info(f"Skipping {'/'.join(name)}")
+ tf_weights.pop(txt_name, None)
+ continue
+ pointer = model
+ array = tf_weights[txt_name]
+
+ for m_name in name:
+ if re.fullmatch(r"[A-Za-z]+_\d+", m_name):
+ scope_names = re.split(r"_(\d+)", m_name)
+ else:
+ scope_names = [m_name]
+ if scope_names[0] in ["kernel", "scale", "embedding"]:
+ pointer = getattr(pointer, "weight")
+ elif scope_names[0] == "self_attention":
+ pointer = getattr(pointer, "layer")
+ pointer = pointer[0]
+ elif scope_names[0] == "enc_dec_attention":
+ pointer = getattr(pointer, "layer")
+ pointer = pointer[1]
+ elif scope_names[0] == "dense_relu_dense":
+ pointer = getattr(pointer, "layer")
+ pointer = pointer[2]
+ elif scope_names[0] == "rms_norm":
+ if hasattr(pointer, "layer_norm"):
+ pointer = getattr(pointer, "layer_norm")
+ elif hasattr(pointer, "final_layer_norm"):
+ pointer = getattr(pointer, "final_layer_norm")
+ elif scope_names[0] == "scale":
+ pointer = getattr(pointer, "weight")
+ elif scope_names[0] == "output_bias" or scope_names[0] == "beta":
+ pointer = getattr(pointer, "bias")
+ elif scope_names[0] == "squad":
+ pointer = getattr(pointer, "classifier")
+ elif scope_names[0] == "decoder" and name[1] == "logits":
+ continue
+ elif scope_names[0] == "logits":
+ pointer = getattr(pointer, "lm_head")
+ elif scope_names[0] == "wi" and len(scope_names) > 1 and scope_names[1].isdigit():
+ pointer = getattr(pointer, f"wi_{scope_names[1]}")
+ continue
+ else:
+ try:
+ pointer = getattr(pointer, scope_names[0])
+ except AttributeError:
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ if len(scope_names) >= 2:
+ num = int(scope_names[1])
+ pointer = pointer[num]
+ if scope_names[0] not in ["kernel", "scale", "embedding"]:
+ pointer = getattr(pointer, "weight")
+ if scope_names[0] != "embedding":
+ logger.info(f"Transposing numpy weight of shape {array.shape} for {name}")
+ array = np.transpose(array)
+ try:
+ if pointer.shape != array.shape:
+ raise ValueError(f"Pointer shape {pointer.shape} and array shape {array.shape} mismatched")
+ except AssertionError as e:
+ e.args += (pointer.shape, array.shape)
+ raise
+ logger.info(f"Initialize PyTorch weight {name}")
+ pointer.data = torch.from_numpy(array.astype(np.float32))
+ tf_weights.pop(txt_name, None)
+
+ logger.info(f"Weights not copied to PyTorch model: {', '.join(tf_weights.keys())}.")
+ return model
+
+
+####################################################
+# PyTorch Models are constructed by sub-classing
+# - torch.nn.Module for the layers and
+# - PreTrainedModel for the models (it-self a sub-class of nn.Module)
+####################################################
+PARALLELIZE_DOCSTRING = r"""
+ This is an experimental feature and is a subject to change at a moment's notice.
+
+ Uses a device map to distribute attention modules of the model across several devices. If no device map is given,
+ it will evenly distribute blocks across all devices.
+
+ Args:
+ device_map (`dict[int, list]`, *optional*):
+ A dictionary that maps attention modules to devices. Note that the embedding module and LMHead are always
+ automatically mapped to the first device (for esoteric reasons). That means that the first device should
+ have fewer attention modules mapped to it than other devices. For reference, the t5 models have the
+ following number of attention modules:
+
+ - google-t5/t5-small: 6
+ - google-t5/t5-base: 12
+ - google-t5/t5-large: 24
+ - google-t5/t5-3b: 24
+ - google-t5/t5-11b: 24
+
+ Example:
+
+ ```python
+ # Here is an example of a device map on a machine with 4 GPUs using google-t5/t5-3b, which has a total of 24 attention modules:
+ model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-3b")
+ device_map = {
+ 0: [0, 1, 2],
+ 1: [3, 4, 5, 6, 7, 8, 9],
+ 2: [10, 11, 12, 13, 14, 15, 16],
+ 3: [17, 18, 19, 20, 21, 22, 23],
+ }
+ model.parallelize(device_map)
+ ```
+"""
+DEPARALLELIZE_DOCSTRING = r"""
+ Moves the model to cpu from a model parallel state.
+
+ Example:
+
+ ```python
+ # On a 4 GPU machine with google-t5/t5-3b:
+ model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-3b")
+ device_map = {
+ 0: [0, 1, 2],
+ 1: [3, 4, 5, 6, 7, 8, 9],
+ 2: [10, 11, 12, 13, 14, 15, 16],
+ 3: [17, 18, 19, 20, 21, 22, 23],
+ }
+ model.parallelize(device_map) # Splits the model across several devices
+ model.deparallelize() # Put the model back on cpu and cleans memory by calling torch.cuda.empty_cache()
+ ```
+"""
+
+
+class T5LayerNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ Construct a layernorm module in the T5 style. No bias and no subtraction of mean.
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ # T5 uses a layer_norm which only scales and doesn't shift, which is also known as Root Mean
+ # Square Layer Normalization https://huggingface.co/papers/1910.07467 thus variance is calculated
+ # w/o mean and there is no bias. Additionally we want to make sure that the accumulation for
+ # half-precision inputs is done in fp32
+
+ variance = hidden_states.to(torch.float32).pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+
+ # convert into half-precision if necessary
+ if self.weight.dtype in [torch.float16, torch.bfloat16]:
+ hidden_states = hidden_states.to(self.weight.dtype)
+
+ return self.weight * hidden_states
+
+
+try:
+ from apex.normalization import FusedRMSNorm
+
+ T5LayerNorm = FusedRMSNorm # noqa
+
+ logger.info("Discovered apex.normalization.FusedRMSNorm - will use it instead of T5LayerNorm")
+except ImportError:
+ # using the normal T5LayerNorm
+ pass
+except Exception:
+ logger.warning("discovered apex but it failed to load, falling back to T5LayerNorm")
+ pass
+
+
+class T5DenseActDense(nn.Module):
+ def __init__(self, config: T5Config):
+ super().__init__()
+ self.wi = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.act = ACT2FN[config.dense_act_fn]
+
+ def forward(self, hidden_states):
+ hidden_states = self.wi(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ if (
+ isinstance(self.wo.weight, torch.Tensor)
+ and hidden_states.dtype != self.wo.weight.dtype
+ and self.wo.weight.dtype != torch.int8
+ ):
+ hidden_states = hidden_states.to(self.wo.weight.dtype)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+class T5DenseGatedActDense(nn.Module):
+ def __init__(self, config: T5Config):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.act = ACT2FN[config.dense_act_fn]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+
+ # To make 8bit quantization work for google/flan-t5-xxl, self.wo is kept in float32.
+ # See https://github.com/huggingface/transformers/issues/20287
+ # we also make sure the weights are not in `int8` in case users will force `_keep_in_fp32_modules` to be `None``
+ if (
+ isinstance(self.wo.weight, torch.Tensor)
+ and hidden_states.dtype != self.wo.weight.dtype
+ and self.wo.weight.dtype != torch.int8
+ ):
+ hidden_states = hidden_states.to(self.wo.weight.dtype)
+
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+class T5LayerFF(nn.Module):
+ def __init__(self, config: T5Config):
+ super().__init__()
+ if config.is_gated_act:
+ self.DenseReluDense = T5DenseGatedActDense(config)
+ else:
+ self.DenseReluDense = T5DenseActDense(config)
+
+ self.layer_norm = T5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ hidden_states = hidden_states + self.dropout(forwarded_states)
+ return hidden_states
+
+
+class T5Attention(nn.Module):
+ def __init__(
+ self,
+ config: T5Config,
+ has_relative_attention_bias=False,
+ layer_idx: Optional[int] = None,
+ ):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.has_relative_attention_bias = has_relative_attention_bias
+ self.relative_attention_num_buckets = config.relative_attention_num_buckets
+ self.relative_attention_max_distance = config.relative_attention_max_distance
+ self.d_model = config.d_model
+ self.key_value_proj_dim = config.d_kv
+ self.n_heads = config.num_heads
+ self.dropout = config.dropout_rate
+ self.inner_dim = self.n_heads * self.key_value_proj_dim
+ self.layer_idx = layer_idx
+ if layer_idx is None and self.is_decoder:
+ logger.warning_once(
+ f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and "
+ "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+
+ # Mesh TensorFlow initialization to avoid scaling before softmax
+ self.q = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.k = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.v = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.o = nn.Linear(self.inner_dim, self.d_model, bias=False)
+
+ if self.has_relative_attention_bias:
+ self.relative_attention_bias = nn.Embedding(self.relative_attention_num_buckets, self.n_heads)
+ self.pruned_heads = set()
+ self.gradient_checkpointing = False
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.n_heads, self.key_value_proj_dim, self.pruned_heads
+ )
+ # Prune linear layers
+ self.q = prune_linear_layer(self.q, index)
+ self.k = prune_linear_layer(self.k, index)
+ self.v = prune_linear_layer(self.v, index)
+ self.o = prune_linear_layer(self.o, index, dim=1)
+ # Update hyper params
+ self.n_heads = self.n_heads - len(heads)
+ self.inner_dim = self.key_value_proj_dim * self.n_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ @staticmethod
+ def _relative_position_bucket(relative_position, bidirectional=True, num_buckets=32, max_distance=128):
+ """
+ Adapted from Mesh Tensorflow:
+ https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593
+
+ Translate relative position to a bucket number for relative attention. The relative position is defined as
+ memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to
+ position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for
+ small absolute relative_position and larger buckets for larger absolute relative_positions. All relative
+ positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket.
+ This should allow for more graceful generalization to longer sequences than the model has been trained on
+
+ Args:
+ relative_position: an int32 Tensor
+ bidirectional: a boolean - whether the attention is bidirectional
+ num_buckets: an integer
+ max_distance: an integer
+
+ Returns:
+ a Tensor with the same shape as relative_position, containing int32 values in the range [0, num_buckets)
+ """
+ relative_buckets = 0
+ if bidirectional:
+ num_buckets //= 2
+ relative_buckets += (relative_position > 0).to(torch.long) * num_buckets
+ relative_position = torch.abs(relative_position)
+ else:
+ relative_position = -torch.min(relative_position, torch.zeros_like(relative_position))
+ # now relative_position is in the range [0, inf)
+
+ # half of the buckets are for exact increments in positions
+ max_exact = num_buckets // 2
+ is_small = relative_position < max_exact
+
+ # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance
+ relative_position_if_large = max_exact + (
+ torch.log(relative_position.float() / max_exact)
+ / math.log(max_distance / max_exact)
+ * (num_buckets - max_exact)
+ ).to(torch.long)
+ relative_position_if_large = torch.min(
+ relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1)
+ )
+
+ relative_buckets += torch.where(is_small, relative_position, relative_position_if_large)
+ return relative_buckets
+
+ def compute_bias(self, query_length, key_length, device=None, cache_position=None):
+ """Compute binned relative position bias"""
+ if device is None:
+ device = self.relative_attention_bias.weight.device
+ if cache_position is None:
+ context_position = torch.arange(query_length, dtype=torch.long, device=device)[:, None]
+ else:
+ context_position = cache_position[:, None].to(device)
+ memory_position = torch.arange(key_length, dtype=torch.long, device=device)[None, :]
+ relative_position = memory_position - context_position # shape (query_length, key_length)
+ relative_position_bucket = self._relative_position_bucket(
+ relative_position, # shape (query_length, key_length)
+ bidirectional=(not self.is_decoder),
+ num_buckets=self.relative_attention_num_buckets,
+ max_distance=self.relative_attention_max_distance,
+ )
+ values = self.relative_attention_bias(relative_position_bucket) # shape (query_length, key_length, num_heads)
+ values = values.permute([2, 0, 1]).unsqueeze(0) # shape (1, num_heads, query_length, key_length)
+ return values
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ mask=None,
+ key_value_states=None,
+ position_bias=None,
+ past_key_values=None,
+ layer_head_mask=None,
+ query_length=None,
+ use_cache=False,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ """
+ Self-attention (if key_value_states is None) or attention over source sentence (provided by key_value_states).
+ """
+ # Input is (batch_size, seq_length, dim)
+ # Mask is (batch_size, 1, 1, key_length) (non-causal encoder) or (batch_size, 1, seq_length, key_length) (causal decoder)
+ batch_size, seq_length = hidden_states.shape[:2]
+
+ # if key_value_states are provided this layer is used as a cross-attention layer for the decoder
+ is_cross_attention = key_value_states is not None
+
+ query_states = self.q(hidden_states)
+ query_states = query_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ # Check is encoder-decoder model is being used. Otherwise we'll get `DynamicCache`
+ if past_key_values is not None and isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k(current_states)
+ value_states = self.v(current_states)
+ key_states = key_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+ value_states = value_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # compute scores, equivalent of torch.einsum("bnqd,bnkd->bnqk", query_states, key_states), compatible with onnx op>9
+ scores = torch.matmul(query_states, key_states.transpose(3, 2))
+
+ if position_bias is None:
+ key_length = key_states.shape[-2]
+ # cache position is 0-indexed so we add 1 to get the real length of queries (aka with past)
+ real_seq_length = query_length if query_length is not None else cache_position[-1] + 1
+ if not self.has_relative_attention_bias:
+ position_bias = torch.zeros(
+ (1, self.n_heads, seq_length, key_length), device=scores.device, dtype=scores.dtype
+ )
+ if self.gradient_checkpointing and self.training:
+ position_bias.requires_grad = True
+ else:
+ position_bias = self.compute_bias(
+ real_seq_length, key_length, device=scores.device, cache_position=cache_position
+ )
+ position_bias = position_bias[:, :, -seq_length:, :]
+
+ if mask is not None:
+ causal_mask = mask[:, :, :, : key_states.shape[-2]]
+ position_bias = position_bias + causal_mask
+
+ if self.pruned_heads:
+ mask = torch.ones(position_bias.shape[1])
+ mask[list(self.pruned_heads)] = 0
+ position_bias_masked = position_bias[:, mask.bool()]
+ else:
+ position_bias_masked = position_bias
+
+ scores += position_bias_masked
+
+ # (batch_size, n_heads, seq_length, key_length)
+ attn_weights = nn.functional.softmax(scores.float(), dim=-1).type_as(scores)
+ attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ # Mask heads if we want to
+ if layer_head_mask is not None:
+ attn_weights = attn_weights * layer_head_mask
+
+ attn_output = torch.matmul(attn_weights, value_states)
+
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ attn_output = attn_output.view(batch_size, -1, self.inner_dim)
+ attn_output = self.o(attn_output)
+
+ outputs = (attn_output, position_bias)
+
+ if output_attentions:
+ outputs = outputs + (attn_weights,)
+ return outputs
+
+
+class T5LayerSelfAttention(nn.Module):
+ def __init__(self, config, has_relative_attention_bias=False, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.SelfAttention = T5Attention(
+ config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx
+ )
+ self.layer_norm = T5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.SelfAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0])
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+class T5LayerCrossAttention(nn.Module):
+ def __init__(self, config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.EncDecAttention = T5Attention(config, has_relative_attention_bias=False, layer_idx=layer_idx)
+ self.layer_norm = T5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ key_value_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ query_length=None,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.EncDecAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ key_value_states=key_value_states,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ query_length=query_length,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ layer_output = hidden_states + self.dropout(attention_output[0])
+ outputs = (layer_output,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+class T5Block(GradientCheckpointingLayer):
+ def __init__(self, config, has_relative_attention_bias=False, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.layer = nn.ModuleList()
+ self.layer.append(
+ T5LayerSelfAttention(config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx)
+ )
+ if self.is_decoder:
+ self.layer.append(T5LayerCrossAttention(config, layer_idx=layer_idx))
+
+ self.layer.append(T5LayerFF(config))
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ encoder_decoder_position_bias=None,
+ layer_head_mask=None,
+ cross_attn_layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=False,
+ return_dict=True,
+ cache_position=None,
+ ):
+ self_attention_outputs = self.layer[0](
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = self_attention_outputs[0]
+ attention_outputs = self_attention_outputs[1:] # Keep self-attention outputs and relative position weights
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.where(
+ torch.isinf(hidden_states).any(),
+ torch.finfo(hidden_states.dtype).max - 1000,
+ torch.finfo(hidden_states.dtype).max,
+ )
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ do_cross_attention = self.is_decoder and encoder_hidden_states is not None
+ if do_cross_attention:
+ cross_attention_outputs = self.layer[1](
+ hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ position_bias=encoder_decoder_position_bias,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ query_length=cache_position[-1] + 1,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ )
+ hidden_states = cross_attention_outputs[0]
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.where(
+ torch.isinf(hidden_states).any(),
+ torch.finfo(hidden_states.dtype).max - 1000,
+ torch.finfo(hidden_states.dtype).max,
+ )
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ # Keep cross-attention outputs and relative position weights
+ attention_outputs = attention_outputs + cross_attention_outputs[1:]
+
+ # Apply Feed Forward layer
+ hidden_states = self.layer[-1](hidden_states)
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.where(
+ torch.isinf(hidden_states).any(),
+ torch.finfo(hidden_states.dtype).max - 1000,
+ torch.finfo(hidden_states.dtype).max,
+ )
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ outputs = (hidden_states,)
+
+ return (
+ outputs + attention_outputs
+ ) # hidden-states, (self-attention position bias), (self-attention weights), (cross-attention position bias), (cross-attention weights)
+
+
+class T5ClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, config: T5Config):
+ super().__init__()
+ self.dense = nn.Linear(config.d_model, config.d_model)
+ self.dropout = nn.Dropout(p=config.classifier_dropout)
+ self.out_proj = nn.Linear(config.d_model, config.num_labels)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.dense(hidden_states)
+ hidden_states = torch.tanh(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.out_proj(hidden_states)
+ return hidden_states
+
+
+@auto_docstring
+class T5PreTrainedModel(PreTrainedModel):
+ config: T5Config
+ load_tf_weights = load_tf_weights_in_t5
+ base_model_prefix = "transformer"
+ is_parallelizable = True
+ supports_gradient_checkpointing = True
+ _can_compile_fullgraph = True
+
+ _no_split_modules = ["T5Block"]
+ _keep_in_fp32_modules = ["wo"]
+
+ @property
+ def dummy_inputs(self):
+ input_ids = torch.tensor(DUMMY_INPUTS)
+ input_mask = torch.tensor(DUMMY_MASK)
+ dummy_inputs = {
+ "decoder_input_ids": input_ids,
+ "input_ids": input_ids,
+ "decoder_attention_mask": input_mask,
+ }
+ return dummy_inputs
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ factor = self.config.initializer_factor # Used for testing weights initialization
+ if isinstance(module, T5LayerNorm):
+ module.weight.data.fill_(factor * 1.0)
+ elif isinstance(
+ module,
+ (T5Model, T5ForConditionalGeneration, T5EncoderModel, T5ForQuestionAnswering),
+ ):
+ # Mesh TensorFlow embeddings initialization
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L1624
+ module.shared.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ if hasattr(module, "lm_head") and not self.config.tie_word_embeddings:
+ module.lm_head.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ if hasattr(module, "qa_outputs"):
+ module.qa_outputs.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ module.qa_outputs.bias.data.zero_()
+ elif isinstance(module, T5ForTokenClassification):
+ if hasattr(module, "classifier"):
+ module.classifier.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ module.classifier.bias.data.zero_()
+ elif isinstance(module, T5ClassificationHead):
+ module.dense.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.dense, "bias") and module.dense.bias is not None:
+ module.dense.bias.data.zero_()
+ module.out_proj.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.out_proj, "bias") and module.out_proj.bias is not None:
+ module.out_proj.bias.data.zero_()
+ elif isinstance(module, T5DenseActDense):
+ # Mesh TensorFlow FF initialization
+ # See https://github.com/tensorflow/mesh/blob/master/mesh_tensorflow/transformer/transformer_layers.py#L56
+ # and https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L89
+ module.wi.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi, "bias") and module.wi.bias is not None:
+ module.wi.bias.data.zero_()
+ module.wo.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_ff) ** -0.5))
+ if hasattr(module.wo, "bias") and module.wo.bias is not None:
+ module.wo.bias.data.zero_()
+ elif isinstance(module, T5DenseGatedActDense):
+ module.wi_0.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi_0, "bias") and module.wi_0.bias is not None:
+ module.wi_0.bias.data.zero_()
+ module.wi_1.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi_1, "bias") and module.wi_1.bias is not None:
+ module.wi_1.bias.data.zero_()
+ module.wo.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_ff) ** -0.5))
+ if hasattr(module.wo, "bias") and module.wo.bias is not None:
+ module.wo.bias.data.zero_()
+ elif isinstance(module, T5Attention):
+ # Mesh TensorFlow attention initialization to avoid scaling before softmax
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/attention.py#L136
+ d_model = self.config.d_model
+ key_value_proj_dim = self.config.d_kv
+ n_heads = self.config.num_heads
+ module.q.weight.data.normal_(mean=0.0, std=factor * ((d_model * key_value_proj_dim) ** -0.5))
+ module.k.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.v.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.o.weight.data.normal_(mean=0.0, std=factor * ((n_heads * key_value_proj_dim) ** -0.5))
+ if module.has_relative_attention_bias:
+ module.relative_attention_bias.weight.data.normal_(mean=0.0, std=factor * ((d_model) ** -0.5))
+
+ def _shift_right(self, input_ids):
+ decoder_start_token_id = self.config.decoder_start_token_id
+ pad_token_id = self.config.pad_token_id
+
+ if decoder_start_token_id is None:
+ raise ValueError(
+ "self.model.config.decoder_start_token_id has to be defined. In T5 it is usually set to the pad_token_id. "
+ "See T5 docs for more information."
+ )
+
+ # shift inputs to the right
+ if is_torch_fx_proxy(input_ids):
+ # Item assignment is not supported natively for proxies.
+ shifted_input_ids = torch.full(input_ids.shape[:-1] + (1,), decoder_start_token_id)
+ shifted_input_ids = torch.cat([shifted_input_ids, input_ids[..., :-1]], dim=-1)
+ else:
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
+ shifted_input_ids[..., 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.pad_token_id has to be defined.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+class T5Stack(T5PreTrainedModel):
+ def __init__(self, config, embed_tokens=None):
+ super().__init__(config)
+
+ self.embed_tokens = embed_tokens
+ self.is_decoder = config.is_decoder
+
+ self.block = nn.ModuleList(
+ [T5Block(config, has_relative_attention_bias=bool(i == 0), layer_idx=i) for i in range(config.num_layers)]
+ )
+ self.final_layer_norm = T5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+ # Model parallel
+ self.model_parallel = False
+ self.device_map = None
+ self.gradient_checkpointing = False
+
+ @add_start_docstrings(PARALLELIZE_DOCSTRING)
+ def parallelize(self, device_map=None):
+ warnings.warn(
+ "`T5Stack.parallelize` is deprecated and will be removed in v5 of Transformers, you should load your model"
+ " with `device_map='balanced'` in the call to `from_pretrained`. You can also provide your own"
+ " `device_map` but it needs to be a dictionary module_name to device, so for instance {'block.0': 0,"
+ " 'block.1': 1, ...}",
+ FutureWarning,
+ )
+ # Check validity of device_map
+ self.device_map = (
+ get_device_map(len(self.block), range(torch.cuda.device_count())) if device_map is None else device_map
+ )
+ assert_device_map(self.device_map, len(self.block))
+ self.model_parallel = True
+ self.first_device = "cpu" if "cpu" in self.device_map else "cuda:" + str(min(self.device_map.keys()))
+ self.last_device = "cuda:" + str(max(self.device_map.keys()))
+ # Load onto devices
+ for k, v in self.device_map.items():
+ for layer in v:
+ cuda_device = "cuda:" + str(k)
+ self.block[layer] = self.block[layer].to(cuda_device)
+
+ # Set embed_tokens to first layer
+ self.embed_tokens = self.embed_tokens.to(self.first_device)
+ # Set final layer norm to last device
+ self.final_layer_norm = self.final_layer_norm.to(self.last_device)
+
+ @add_start_docstrings(DEPARALLELIZE_DOCSTRING)
+ def deparallelize(self):
+ warnings.warn(
+ "Like `parallelize`, `deparallelize` is deprecated and will be removed in v5 of Transformers.",
+ FutureWarning,
+ )
+ self.model_parallel = False
+ self.device_map = None
+ self.first_device = "cpu"
+ self.last_device = "cpu"
+ for i in range(len(self.block)):
+ self.block[i] = self.block[i].to("cpu")
+ self.embed_tokens = self.embed_tokens.to("cpu")
+ self.final_layer_norm = self.final_layer_norm.to("cpu")
+ torch.cuda.empty_cache()
+
+ def set_input_embeddings(self, new_embeddings):
+ self.embed_tokens = new_embeddings
+
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ inputs_embeds=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ cache_position=None,
+ ):
+ # Model parallel
+ if self.model_parallel:
+ torch.cuda.set_device(self.first_device)
+ self.embed_tokens = self.embed_tokens.to(self.first_device)
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(
+ f"You cannot specify both {err_msg_prefix}input_ids and {err_msg_prefix}inputs_embeds at the same time"
+ )
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(f"You have to specify either {err_msg_prefix}input_ids or {err_msg_prefix}inputs_embeds")
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ if self.embed_tokens is None:
+ raise ValueError("You have to initialize the model with valid token embeddings")
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ batch_size, seq_length = input_shape
+
+ if use_cache is True:
+ if not self.is_decoder:
+ raise ValueError(f"`use_cache` can only be set to `True` if {self} is used as a decoder")
+
+ if self.is_decoder:
+ if use_cache and past_key_values is None:
+ if self.config.is_encoder_decoder:
+ past_key_values = EncoderDecoderCache(
+ DynamicCache(config=self.config), DynamicCache(config=self.config)
+ )
+ else:
+ past_key_values = DynamicCache(config=self.config)
+ elif not self.is_decoder:
+ # do not pass cache object down the line for encoder stack
+ # it messes indexing later in decoder-stack because cache object is modified in-place
+ past_key_values = None
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+ if cache_position is None:
+ cache_position = torch.arange(
+ past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device
+ )
+
+ if attention_mask is None and not is_torchdynamo_compiling():
+ # required mask seq length can be calculated via length of past cache
+ mask_seq_length = past_key_values_length + seq_length
+ attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device)
+
+ if self.config.is_decoder:
+ causal_mask = self._update_causal_mask(
+ attention_mask,
+ inputs_embeds,
+ cache_position,
+ past_key_values.self_attention_cache
+ if isinstance(past_key_values, EncoderDecoderCache)
+ else past_key_values,
+ output_attentions,
+ )
+ elif attention_mask is not None:
+ causal_mask = attention_mask[:, None, None, :]
+ causal_mask = causal_mask.to(dtype=inputs_embeds.dtype)
+ causal_mask = (1.0 - causal_mask) * torch.finfo(inputs_embeds.dtype).min
+ else:
+ causal_mask = None
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(
+ encoder_hidden_shape, device=inputs_embeds.device, dtype=torch.long
+ )
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ head_mask = self.get_head_mask(head_mask, self.config.num_layers)
+ cross_attn_head_mask = self.get_head_mask(cross_attn_head_mask, self.config.num_layers)
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and self.is_decoder) else None
+ position_bias = None
+ encoder_decoder_position_bias = None
+
+ hidden_states = self.dropout(inputs_embeds)
+
+ for i, layer_module in enumerate(self.block):
+ layer_head_mask = head_mask[i]
+ cross_attn_layer_head_mask = cross_attn_head_mask[i]
+ # Model parallel
+ if self.model_parallel:
+ torch.cuda.set_device(hidden_states.device)
+ # Ensure that attention_mask is always on the same device as hidden_states
+ if causal_mask is not None:
+ causal_mask = causal_mask.to(hidden_states.device)
+ if position_bias is not None:
+ position_bias = position_bias.to(hidden_states.device)
+ if encoder_hidden_states is not None:
+ encoder_hidden_states = encoder_hidden_states.to(hidden_states.device)
+ if encoder_extended_attention_mask is not None:
+ encoder_extended_attention_mask = encoder_extended_attention_mask.to(hidden_states.device)
+ if encoder_decoder_position_bias is not None:
+ encoder_decoder_position_bias = encoder_decoder_position_bias.to(hidden_states.device)
+ if layer_head_mask is not None:
+ layer_head_mask = layer_head_mask.to(hidden_states.device)
+ if cross_attn_layer_head_mask is not None:
+ cross_attn_layer_head_mask = cross_attn_layer_head_mask.to(hidden_states.device)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states,
+ causal_mask,
+ position_bias,
+ encoder_hidden_states,
+ encoder_extended_attention_mask,
+ encoder_decoder_position_bias, # as a positional argument for gradient checkpointing
+ layer_head_mask=layer_head_mask,
+ cross_attn_layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ # We share the position biases between the layers - the first layer store them
+ # layer_outputs = hidden-states, key-value-states (self-attention position bias), (self-attention weights),
+ # (cross-attention position bias), (cross-attention weights)
+ position_bias = layer_outputs[1]
+ if self.is_decoder and encoder_hidden_states is not None:
+ encoder_decoder_position_bias = layer_outputs[3 if output_attentions else 2]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[2],)
+ if self.is_decoder:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[4],)
+
+ # Model Parallel: If it's the last layer for that device, put things on the next device
+ if self.model_parallel:
+ for k, v in self.device_map.items():
+ if i == v[-1] and "cuda:" + str(k) != self.last_device:
+ hidden_states = hidden_states.to("cuda:" + str(k + 1))
+
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ past_key_values,
+ all_hidden_states,
+ all_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._update_causal_mask
+ def _update_causal_mask(
+ self,
+ attention_mask: Union[torch.Tensor, "BlockMask"],
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool = False,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+ if self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask)
+ return attention_mask
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_compilable_cache = past_key_values.is_compileable if past_key_values is not None else False
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_compilable_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype = input_tensor.dtype
+ sequence_length = input_tensor.shape[1]
+ if using_compilable_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type in ["cuda", "xpu", "npu"]
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._prepare_4d_causal_attention_mask_with_cache_position
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=cache_position.device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=cache_position.device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :].to(
+ causal_mask.device
+ )
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
+
+
+# Warning message for FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+__HEAD_MASK_WARNING_MSG = """
+The input argument `head_mask` was split into two arguments `head_mask` and `decoder_head_mask`. Currently,
+`decoder_head_mask` is set to copy `head_mask`, but this feature is deprecated and will be removed in future versions.
+If you do not want to use any `decoder_head_mask` now, please set `decoder_head_mask = torch.ones(num_layers,
+num_heads)`.
+"""
+
+
+@auto_docstring
+class T5Model(T5PreTrainedModel):
+ _keys_to_ignore_on_load_unexpected = [
+ "decoder.block.0.layer.1.EncDecAttention.relative_attention_bias.weight",
+ ]
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight"]
+
+ def __init__(self, config: T5Config):
+ super().__init__(config)
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = T5Stack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = T5Stack(decoder_config, self.shared)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Model parallel
+ self.model_parallel = False
+ self.device_map = None
+
+ @add_start_docstrings(PARALLELIZE_DOCSTRING)
+ def parallelize(self, device_map=None):
+ warnings.warn(
+ "`T5Model.parallelize` is deprecated and will be removed in v5 of Transformers, you should load your model"
+ " with `device_map='balanced'` in the call to `from_pretrained`. You can also provide your own"
+ " `device_map` but it needs to be a dictionary module_name to device, so for instance {'encoder.block.0':"
+ " 0, 'encoder.block.1': 1, ...}",
+ FutureWarning,
+ )
+ self.device_map = (
+ get_device_map(len(self.encoder.block), range(torch.cuda.device_count()))
+ if device_map is None
+ else device_map
+ )
+ assert_device_map(self.device_map, len(self.encoder.block))
+ self.encoder.parallelize(self.device_map)
+ self.decoder.parallelize(self.device_map)
+ self.model_parallel = True
+
+ @add_start_docstrings(DEPARALLELIZE_DOCSTRING)
+ def deparallelize(self):
+ warnings.warn(
+ "Like `parallelize`, `deparallelize` is deprecated and will be removed in v5 of Transformers.",
+ FutureWarning,
+ )
+ self.encoder.deparallelize()
+ self.decoder.deparallelize()
+ self.encoder = self.encoder.to("cpu")
+ self.decoder = self.decoder.to("cpu")
+ self.model_parallel = False
+ self.device_map = None
+ torch.cuda.empty_cache()
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ def get_encoder(self):
+ return self.encoder
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ decoder_inputs_embeds: Optional[torch.Tensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ T5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [T5
+ Training](./t5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, T5Model
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = T5Model.from_pretrained("google-t5/t5-small")
+
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> decoder_input_ids = tokenizer("Studies show that", return_tensors="pt").input_ids # Batch size 1
+
+ >>> # preprocess: Prepend decoder_input_ids with start token which is pad token for T5Model.
+ >>> # This is not needed for torch's T5ForConditionalGeneration as it does this internally using labels arg.
+ >>> decoder_input_ids = model._shift_right(decoder_input_ids)
+
+ >>> # forward pass
+ >>> outputs = model(input_ids=input_ids, decoder_input_ids=decoder_input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+ if head_mask is not None and decoder_head_mask is None:
+ if self.config.num_layers == self.config.num_decoder_layers:
+ warnings.warn(__HEAD_MASK_WARNING_MSG, FutureWarning)
+ decoder_head_mask = head_mask
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ # Set device for model parallelism
+ if self.model_parallel:
+ torch.cuda.set_device(self.decoder.first_device)
+ hidden_states = hidden_states.to(self.decoder.first_device)
+ if decoder_input_ids is not None:
+ decoder_input_ids = decoder_input_ids.to(self.decoder.first_device)
+ if attention_mask is not None:
+ attention_mask = attention_mask.to(self.decoder.first_device)
+ if decoder_attention_mask is not None:
+ decoder_attention_mask = decoder_attention_mask.to(self.decoder.first_device)
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ T5 Model with a `language modeling` head on top.
+ """
+)
+class T5ForConditionalGeneration(T5PreTrainedModel, GenerationMixin):
+ _keys_to_ignore_on_load_unexpected = [
+ "decoder.block.0.layer.1.EncDecAttention.relative_attention_bias.weight",
+ ]
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight", "lm_head.weight"]
+
+ def __init__(self, config: T5Config):
+ super().__init__(config)
+ self.model_dim = config.d_model
+
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = T5Stack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = T5Stack(decoder_config, self.shared)
+
+ self.lm_head = nn.Linear(config.d_model, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Model parallel
+ self.model_parallel = False
+ self.device_map = None
+
+ @add_start_docstrings(PARALLELIZE_DOCSTRING)
+ def parallelize(self, device_map=None):
+ warnings.warn(
+ "`T5ForConditionalGeneration.parallelize` is deprecated and will be removed in v5 of Transformers, you"
+ " should load your model with `device_map='balanced'` in the call to `from_pretrained`. You can also"
+ " provide your own `device_map` but it needs to be a dictionary module_name to device, so for instance"
+ " {'encoder.block.0': 0, 'encoder.block.1': 1, ...}",
+ FutureWarning,
+ )
+ self.device_map = (
+ get_device_map(len(self.encoder.block), range(torch.cuda.device_count()))
+ if device_map is None
+ else device_map
+ )
+ assert_device_map(self.device_map, len(self.encoder.block))
+ self.encoder.parallelize(self.device_map)
+ self.decoder.parallelize(self.device_map)
+ self.lm_head = self.lm_head.to(self.decoder.first_device)
+ self.model_parallel = True
+
+ @add_start_docstrings(DEPARALLELIZE_DOCSTRING)
+ def deparallelize(self):
+ warnings.warn(
+ "Like `parallelize`, `deparallelize` is deprecated and will be removed in v5 of Transformers.",
+ FutureWarning,
+ )
+ self.encoder.deparallelize()
+ self.decoder.deparallelize()
+ self.encoder = self.encoder.to("cpu")
+ self.decoder = self.decoder.to("cpu")
+ self.lm_head = self.lm_head.to("cpu")
+ self.model_parallel = False
+ self.device_map = None
+ torch.cuda.empty_cache()
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.Tensor]]] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ T5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [T5
+ Training](./t5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size - 1]`. All labels set to `-100` are ignored (masked), the loss is only computed for
+ labels in `[0, ..., config.vocab_size]`
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, T5ForConditionalGeneration
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = T5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+ >>> # training
+ >>> input_ids = tokenizer("The walks in park", return_tensors="pt").input_ids
+ >>> labels = tokenizer(" cute dog the ", return_tensors="pt").input_ids
+ >>> outputs = model(input_ids=input_ids, labels=labels)
+ >>> loss = outputs.loss
+ >>> logits = outputs.logits
+
+ >>> # inference
+ >>> input_ids = tokenizer(
+ ... "summarize: studies have shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> outputs = model.generate(input_ids)
+ >>> print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+ >>> # studies have shown that owning a dog is good for you.
+ ```"""
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+ if head_mask is not None and decoder_head_mask is None:
+ if self.config.num_layers == self.config.num_decoder_layers:
+ warnings.warn(__HEAD_MASK_WARNING_MSG, FutureWarning)
+ decoder_head_mask = head_mask
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ # Convert encoder inputs in embeddings if needed
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.model_parallel:
+ torch.cuda.set_device(self.decoder.first_device)
+
+ if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None:
+ # get decoder inputs from shifting lm labels to the right
+ decoder_input_ids = self._shift_right(labels)
+
+ # Set device for model parallelism
+ if self.model_parallel:
+ torch.cuda.set_device(self.decoder.first_device)
+ hidden_states = hidden_states.to(self.decoder.first_device)
+ if decoder_input_ids is not None:
+ decoder_input_ids = decoder_input_ids.to(self.decoder.first_device)
+ if attention_mask is not None:
+ attention_mask = attention_mask.to(self.decoder.first_device)
+ if decoder_attention_mask is not None:
+ decoder_attention_mask = decoder_attention_mask.to(self.decoder.first_device)
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ # Set device for model parallelism
+ if self.model_parallel:
+ torch.cuda.set_device(self.encoder.first_device)
+ self.lm_head = self.lm_head.to(self.encoder.first_device)
+ sequence_output = sequence_output.to(self.lm_head.weight.device)
+
+ if self.config.tie_word_embeddings:
+ # Rescale output before projecting on vocab
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/transformer.py#L586
+ sequence_output = sequence_output * (self.model_dim**-0.5)
+
+ lm_logits = self.lm_head(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss(ignore_index=-100)
+ # move labels to correct device to enable PP
+ labels = labels.to(lm_logits.device)
+ loss = loss_fct(lm_logits.view(-1, lm_logits.size(-1)), labels.view(-1))
+ # TODO(thom): Add z_loss https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L666
+
+ if not return_dict:
+ output = (lm_logits,) + decoder_outputs[1:] + encoder_outputs
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=lm_logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor):
+ return self._shift_right(labels)
+
+
+@auto_docstring
+class T5EncoderModel(T5PreTrainedModel):
+ _tied_weights_keys = ["encoder.embed_tokens.weight"]
+ _keys_to_ignore_on_load_unexpected = [r"decoder"]
+
+ def __init__(self, config: T5Config):
+ super().__init__(config)
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = config
+ encoder_config.use_cache = False
+ encoder_config.is_encoder_decoder = False
+ self.encoder = T5Stack(encoder_config, self.shared)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Model parallel
+ self.model_parallel = False
+ self.device_map = None
+
+ @add_start_docstrings(PARALLELIZE_DOCSTRING)
+ def parallelize(self, device_map=None):
+ warnings.warn(
+ "`T5EncoderModel.parallelize` is deprecated and will be removed in v5 of Transformers, you should load"
+ " your model with `device_map='balanced'` in the call to `from_pretrained`. You can also provide your own"
+ " `device_map` but it needs to be a dictionary module_name to device, so for instance {'block.0': 0,"
+ " 'block.1': 1, ...}",
+ FutureWarning,
+ )
+ self.device_map = (
+ get_device_map(len(self.encoder.block), range(torch.cuda.device_count()))
+ if device_map is None
+ else device_map
+ )
+ assert_device_map(self.device_map, len(self.encoder.block))
+ self.encoder.parallelize(self.device_map)
+ self.model_parallel = True
+
+ @add_start_docstrings(DEPARALLELIZE_DOCSTRING)
+ def deparallelize(self):
+ warnings.warn(
+ "Like `parallelize`, `deparallelize` is deprecated and will be removed in v5 of Transformers.",
+ FutureWarning,
+ )
+ self.encoder.deparallelize()
+ self.encoder = self.encoder.to("cpu")
+ self.model_parallel = False
+ self.device_map = None
+ torch.cuda.empty_cache()
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+
+ def get_encoder(self):
+ return self.encoder
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.block[layer].layer[0].SelfAttention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], BaseModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, T5EncoderModel
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = T5EncoderModel.from_pretrained("google-t5/t5-small")
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> outputs = model(input_ids=input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ return encoder_outputs
+
+
+@auto_docstring(
+ custom_intro="""
+ T5 model with a sequence classification/head on top (a linear layer on top of the pooled output) e.g. for GLUE
+ tasks.
+ """
+)
+class T5ForSequenceClassification(T5PreTrainedModel):
+ _keys_to_ignore_on_load_unexpected = ["decoder.block.0.layer.1.EncDecAttention.relative_attention_bias.weight"]
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight"]
+
+ def __init__(self, config: T5Config):
+ super().__init__(config)
+ self.transformer = T5Model(config)
+ self.classification_head = T5ClassificationHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ self.model_parallel = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[list[torch.FloatTensor]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Seq2SeqSequenceClassifierOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ T5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [T5
+ Training](./t5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ if labels is not None:
+ use_cache = False
+
+ if input_ids is None and inputs_embeds is not None:
+ raise NotImplementedError(
+ f"Passing input embeddings is currently not supported for {self.__class__.__name__}"
+ )
+
+ # Copied from models.bart.modeling_bart.BartModel.forward different to other models, T5 automatically creates
+ # decoder_input_ids from input_ids if no decoder_input_ids are provided
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+
+ eos_mask = input_ids.eq(self.config.eos_token_id).to(sequence_output.device)
+
+ if len(torch.unique_consecutive(eos_mask.sum(1))) > 1:
+ raise ValueError("All examples must have the same number of tokens.")
+ batch_size, _, hidden_size = sequence_output.shape
+ sentence_representation = sequence_output[eos_mask, :].view(batch_size, -1, hidden_size)[:, -1, :]
+ logits = self.classification_head(sentence_representation)
+
+ loss = None
+ if labels is not None:
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.config.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.config.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.config.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqSequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+
+@auto_docstring
+class T5ForTokenClassification(T5PreTrainedModel):
+ _tied_weights_keys = ["transformer.encoder.embed_tokens.weight"]
+
+ def __init__(self, config: T5Config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.transformer = T5EncoderModel(config)
+ self.dropout = nn.Dropout(config.classifier_dropout)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], TokenClassifierOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits, outputs[2:-1])
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class T5ForQuestionAnswering(T5PreTrainedModel):
+ _keys_to_ignore_on_load_unexpected = ["decoder.block.0.layer.1.EncDecAttention.relative_attention_bias.weight"]
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight"]
+
+ def __init__(self, config: T5Config):
+ super().__init__(config)
+ self.model_dim = config.d_model
+
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = T5Stack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = T5Stack(decoder_config, self.shared)
+
+ self.num_labels = config.num_labels
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ self.model_parallel = False
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.Tensor]]] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqQuestionAnsweringModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ T5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [T5
+ Training](./t5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ if start_positions is not None and end_positions is not None:
+ use_cache = False
+
+ # Copied from models.bart.modeling_bart.BartModel.forward
+ # different to other models, T5 automatically creates decoder_input_ids from
+ # input_ids if no decoder_input_ids are provided
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+ if head_mask is not None and decoder_head_mask is None:
+ if self.config.num_layers == self.config.num_decoder_layers:
+ warnings.warn(__HEAD_MASK_WARNING_MSG, FutureWarning)
+ decoder_head_mask = head_mask
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=None,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1).to(start_logits.device)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1).to(end_logits.device)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + decoder_outputs[1:] + encoder_outputs
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return Seq2SeqQuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+__all__ = [
+ "T5EncoderModel",
+ "T5ForConditionalGeneration",
+ "T5Model",
+ "T5PreTrainedModel",
+ "load_tf_weights_in_t5",
+ "T5ForQuestionAnswering",
+ "T5ForSequenceClassification",
+ "T5ForTokenClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_tf_t5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_tf_t5.py
new file mode 100644
index 0000000000000000000000000000000000000000..142a0f73115e2adc2a057cdc4911d20fa131e501
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/modeling_tf_t5.py
@@ -0,0 +1,1676 @@
+# coding=utf-8
+# Copyright 2020 T5 Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TF 2.0 T5 model."""
+
+from __future__ import annotations
+
+import copy
+import itertools
+import math
+import warnings
+
+import numpy as np
+import tensorflow as tf
+from tensorflow.compiler.tf2xla.python.xla import dynamic_slice
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_outputs import (
+ TFBaseModelOutput,
+ TFBaseModelOutputWithPastAndCrossAttentions,
+ TFSeq2SeqLMOutput,
+ TFSeq2SeqModelOutput,
+)
+from ...modeling_tf_utils import (
+ TFCausalLanguageModelingLoss,
+ TFModelInputType,
+ TFPreTrainedModel,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import (
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+ replace_return_docstrings,
+)
+from .configuration_t5 import T5Config
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "T5Config"
+
+
+####################################################
+# TF 2.0 Models are constructed using Keras imperative API by sub-classing
+# - keras.layers.Layer for the layers and
+# - TFPreTrainedModel for the models (it-self a sub-class of keras.Model)
+####################################################
+
+
+class TFT5LayerNorm(keras.layers.Layer):
+ def __init__(self, hidden_size, epsilon=1e-6, **kwargs):
+ """
+ Construct a layernorm module in the T5 style No bias and no subtraction of mean.
+ """
+ super().__init__(**kwargs)
+ self.variance_epsilon = epsilon
+ self.hidden_size = hidden_size
+
+ def build(self, input_shape):
+ """Build shared word embedding layer"""
+ self.weight = self.add_weight("weight", shape=(self.hidden_size,), initializer="ones")
+ super().build(input_shape)
+
+ def call(self, hidden_states):
+ variance = tf.math.reduce_mean(tf.math.square(hidden_states), axis=-1, keepdims=True)
+ hidden_states = hidden_states * tf.math.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states
+
+
+class TFT5DenseActDense(keras.layers.Layer):
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ wi_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (config.d_model**-0.5)
+ )
+ wo_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (config.d_ff**-0.5)
+ )
+ self.wi = keras.layers.Dense(
+ config.d_ff, use_bias=False, name="wi", kernel_initializer=wi_initializer
+ ) # Update init weights as in flax
+ self.wo = keras.layers.Dense(
+ config.d_model, use_bias=False, name="wo", kernel_initializer=wo_initializer
+ ) # Update init weights as in flax
+ self.dropout = keras.layers.Dropout(config.dropout_rate)
+ self.act = get_tf_activation(config.dense_act_fn)
+ self.config = config
+
+ def call(self, hidden_states, training=False):
+ hidden_states = self.wi(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "wi", None) is not None:
+ with tf.name_scope(self.wi.name):
+ self.wi.build([None, None, self.config.d_model])
+ if getattr(self, "wo", None) is not None:
+ with tf.name_scope(self.wo.name):
+ self.wo.build([None, None, self.config.d_ff])
+
+
+class TFT5DenseGatedActDense(keras.layers.Layer):
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ wi_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (config.d_model**-0.5)
+ )
+ wo_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (config.d_ff**-0.5)
+ )
+ self.wi_0 = keras.layers.Dense(
+ config.d_ff, use_bias=False, name="wi_0", kernel_initializer=wi_initializer
+ ) # Update init weights as in flax
+ self.wi_1 = keras.layers.Dense(
+ config.d_ff, use_bias=False, name="wi_1", kernel_initializer=wi_initializer
+ ) # Update init weights as in flax
+ self.wo = keras.layers.Dense(
+ config.d_model, use_bias=False, name="wo", kernel_initializer=wo_initializer
+ ) # Update init weights as in flax
+ self.dropout = keras.layers.Dropout(config.dropout_rate)
+ self.act = get_tf_activation(config.dense_act_fn)
+ self.config = config
+
+ def call(self, hidden_states, training=False):
+ hidden_gelu = self.act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "wi_0", None) is not None:
+ with tf.name_scope(self.wi_0.name):
+ self.wi_0.build([None, None, self.config.d_model])
+ if getattr(self, "wi_1", None) is not None:
+ with tf.name_scope(self.wi_1.name):
+ self.wi_1.build([None, None, self.config.d_model])
+ if getattr(self, "wo", None) is not None:
+ with tf.name_scope(self.wo.name):
+ self.wo.build([None, None, self.config.d_ff])
+
+
+class TFT5LayerFF(keras.layers.Layer):
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ if config.is_gated_act:
+ self.DenseReluDense = TFT5DenseGatedActDense(config, name="DenseReluDense")
+ else:
+ self.DenseReluDense = TFT5DenseActDense(config, name="DenseReluDense")
+
+ self.layer_norm = TFT5LayerNorm(config.d_model, epsilon=config.layer_norm_epsilon, name="layer_norm")
+ self.dropout = keras.layers.Dropout(config.dropout_rate)
+
+ def call(self, hidden_states, training=False):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ dense_output = self.DenseReluDense(normed_hidden_states, training=training)
+ hidden_states = hidden_states + self.dropout(dense_output, training=training)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build(None)
+ if getattr(self, "DenseReluDense", None) is not None:
+ with tf.name_scope(self.DenseReluDense.name):
+ self.DenseReluDense.build(None)
+
+
+class TFT5Attention(keras.layers.Layer):
+ NEW_ID = itertools.count()
+
+ def __init__(self, config, has_relative_attention_bias=False, **kwargs):
+ super().__init__(**kwargs)
+ self.layer_id = next(TFT5Attention.NEW_ID)
+ self.is_decoder = config.is_decoder
+ self.use_cache = config.use_cache
+ self.has_relative_attention_bias = has_relative_attention_bias
+ self.output_attentions = config.output_attentions
+
+ self.relative_attention_num_buckets = config.relative_attention_num_buckets
+ self.relative_attention_max_distance = config.relative_attention_max_distance
+ self.d_model = config.d_model
+ self.key_value_proj_dim = config.d_kv
+ self.n_heads = config.num_heads
+ self.inner_dim = self.n_heads * self.key_value_proj_dim
+
+ # Mesh TensorFlow initialization to avoid scaling before softmax
+ q_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * ((self.inner_dim * self.key_value_proj_dim) ** -0.5)
+ )
+ k_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (self.inner_dim**-0.5)
+ )
+ v_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (self.inner_dim**-0.5)
+ )
+ o_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (self.inner_dim**-0.5)
+ )
+ self.relative_attention_bias_initializer = keras.initializers.RandomNormal(
+ mean=0, stddev=config.initializer_factor * (self.inner_dim**-0.5)
+ )
+
+ self.q = keras.layers.Dense(
+ self.inner_dim, use_bias=False, name="q", kernel_initializer=q_initializer
+ ) # Update init weights as in flax
+ self.k = keras.layers.Dense(
+ self.inner_dim, use_bias=False, name="k", kernel_initializer=k_initializer
+ ) # Update init weights as in flax
+ self.v = keras.layers.Dense(
+ self.inner_dim, use_bias=False, name="v", kernel_initializer=v_initializer
+ ) # Update init weights as in flax
+ self.o = keras.layers.Dense(
+ self.d_model, use_bias=False, name="o", kernel_initializer=o_initializer
+ ) # Update init weights as in flax
+ self.dropout = keras.layers.Dropout(config.dropout_rate)
+
+ self.pruned_heads = set()
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if self.has_relative_attention_bias:
+ with tf.name_scope("relative_attention_bias"):
+ self.relative_attention_bias = self.add_weight(
+ name="embeddings",
+ shape=[self.relative_attention_num_buckets, self.n_heads],
+ initializer=self.relative_attention_bias_initializer, # Add initializer
+ )
+ if getattr(self, "q", None) is not None:
+ with tf.name_scope(self.q.name):
+ self.q.build([None, None, self.d_model])
+ if getattr(self, "k", None) is not None:
+ with tf.name_scope(self.k.name):
+ self.k.build([None, None, self.d_model])
+ if getattr(self, "v", None) is not None:
+ with tf.name_scope(self.v.name):
+ self.v.build([None, None, self.d_model])
+ if getattr(self, "o", None) is not None:
+ with tf.name_scope(self.o.name):
+ self.o.build([None, None, self.inner_dim])
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ @staticmethod
+ def _relative_position_bucket(relative_position, bidirectional=True, num_buckets=32, max_distance=128):
+ """
+ Adapted from Mesh Tensorflow:
+ https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593
+
+ Translate relative position to a bucket number for relative attention. The relative position is defined as
+ memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to
+ position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for
+ small absolute relative_position and larger buckets for larger absolute relative_positions. All relative
+ positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket.
+ This should allow for more graceful generalization to longer sequences than the model has been trained on
+
+ Args:
+ relative_position: an int32 Tensor
+ bidirectional: a boolean - whether the attention is bidirectional
+ num_buckets: an integer
+ max_distance: an integer
+
+ Returns:
+ a Tensor with the same shape as relative_position, containing int32 values in the range [0, num_buckets)
+ """
+ relative_buckets = 0
+ # n = -relative_position
+ if bidirectional:
+ num_buckets //= 2
+ relative_buckets += (
+ tf.cast(tf.math.greater(relative_position, 0), dtype=relative_position.dtype) * num_buckets
+ )
+ relative_position = tf.math.abs(relative_position)
+ else:
+ relative_position = -tf.math.minimum(relative_position, 0)
+ # now n is in the range [0, inf)
+ max_exact = num_buckets // 2
+ is_small = tf.math.less(relative_position, max_exact)
+ relative_position_if_large = max_exact + tf.cast(
+ tf.math.log(tf.cast(relative_position, tf.float32) / tf.cast(max_exact, tf.float32))
+ / math.log(max_distance / max_exact)
+ * (num_buckets - max_exact),
+ dtype=relative_position.dtype,
+ )
+ relative_position_if_large = tf.math.minimum(relative_position_if_large, num_buckets - 1)
+ relative_buckets += tf.where(is_small, relative_position, relative_position_if_large)
+ return relative_buckets
+
+ def compute_bias(self, query_length, key_length):
+ """Compute binned relative position bias"""
+ context_position = tf.range(query_length)[:, None]
+ memory_position = tf.range(key_length)[None, :]
+ relative_position = memory_position - context_position # shape (query_length, key_length)
+ relative_position_bucket = self._relative_position_bucket(
+ relative_position,
+ bidirectional=(not self.is_decoder),
+ num_buckets=self.relative_attention_num_buckets,
+ max_distance=self.relative_attention_max_distance,
+ )
+ values = tf.gather(
+ self.relative_attention_bias, relative_position_bucket
+ ) # shape (query_length, key_length, num_heads)
+ values = tf.expand_dims(
+ tf.transpose(values, [2, 0, 1]), axis=0
+ ) # shape (1, num_heads, query_length, key_length)
+ return values
+
+ def call(
+ self,
+ hidden_states,
+ mask=None,
+ key_value_states=None,
+ position_bias=None,
+ past_key_value=None,
+ layer_head_mask=None,
+ query_length=None,
+ use_cache=False,
+ training=False,
+ output_attentions=False,
+ ):
+ """
+ Self-attention (if key_value_states is None) or attention over source sentence (provided by key_value_states).
+ """
+ # Input is (batch_size, query_length, dim)
+ # Mask is (batch_size, key_length) (non-causal) or (batch_size, key_length, key_length)
+ # past_key_value[0] is (batch_size, n_heads, q_len - 1, dim_per_head)
+ batch_size, seq_length = shape_list(hidden_states)[:2]
+
+ real_seq_length = seq_length
+
+ if past_key_value is not None:
+ assert len(past_key_value) == 2, (
+ f"past_key_value should have 2 past states: keys and values. Got {len(past_key_value)} past states"
+ )
+ real_seq_length += shape_list(past_key_value[0])[2] if query_length is None else query_length
+
+ key_length = real_seq_length if key_value_states is None else shape_list(key_value_states)[1]
+
+ def shape(hidden_states):
+ """projection"""
+ return tf.transpose(
+ tf.reshape(hidden_states, (batch_size, -1, self.n_heads, self.key_value_proj_dim)), perm=(0, 2, 1, 3)
+ )
+
+ def unshape(hidden_states):
+ """compute context"""
+ return tf.reshape(tf.transpose(hidden_states, perm=(0, 2, 1, 3)), (batch_size, -1, self.inner_dim))
+
+ def project(hidden_states, proj_layer, key_value_states, past_key_value):
+ """projects hidden states correctly to key/query states"""
+ if key_value_states is None:
+ # self-attn
+ # (batch_size, n_heads, seq_length, dim_per_head)
+ hidden_states = shape(proj_layer(hidden_states))
+ elif past_key_value is None:
+ # cross-attn
+ # (batch_size, n_heads, seq_length, dim_per_head)
+ hidden_states = shape(proj_layer(key_value_states))
+
+ if past_key_value is not None:
+ if key_value_states is None:
+ # self-attn
+ # (batch_size, n_heads, key_length, dim_per_head)
+ hidden_states = tf.concat([past_key_value, hidden_states], axis=2)
+ else:
+ # cross-attn
+ hidden_states = past_key_value
+ return hidden_states
+
+ # get query
+ query_states = shape(self.q(hidden_states)) # (batch_size, n_heads, query_length, dim_per_head)
+
+ # get key/value
+ key_states = project(
+ hidden_states, self.k, key_value_states, past_key_value[0] if past_key_value is not None else None
+ )
+ value_states = project(
+ hidden_states, self.v, key_value_states, past_key_value[1] if past_key_value is not None else None
+ )
+
+ # to cope with keras serialization
+ if self.is_decoder and use_cache:
+ present_key_value_state = (key_states, value_states)
+ else:
+ present_key_value_state = None
+
+ scores = tf.einsum(
+ "bnqd,bnkd->bnqk", query_states, key_states
+ ) # (batch_size, n_heads, query_length, key_length)
+
+ if position_bias is None:
+ if not self.has_relative_attention_bias:
+ position_bias = tf.zeros((1, self.n_heads, real_seq_length, key_length))
+ else:
+ position_bias = self.compute_bias(real_seq_length, key_length)
+
+ # if key and values are already calculated we want only the last query position bias
+ if past_key_value is not None:
+ if not self.has_relative_attention_bias:
+ position_bias = position_bias[:, :, -seq_length:, :]
+ else:
+ # we might have a padded past structure, in which case we want to fetch the position bias slice
+ # right after the most recently filled past index
+ most_recently_filled_past_index = tf.reduce_max(tf.where(past_key_value[0][0, 0, :, 0] != 0.0))
+ position_bias = dynamic_slice(
+ position_bias,
+ (0, 0, most_recently_filled_past_index + 1, 0),
+ (1, self.n_heads, seq_length, real_seq_length),
+ )
+
+ if mask is not None:
+ position_bias = tf.cast(position_bias, dtype=mask.dtype)
+ position_bias = position_bias + mask # (batch_size, n_heads, query_length, key_length)
+
+ scores += position_bias
+ weights = stable_softmax(scores, axis=-1) # (batch_size, n_heads, query_length, key_length)
+ weights = self.dropout(weights, training=training) # (batch_size, n_heads, query_length, key_length)
+
+ # Mask heads if we want to
+ if layer_head_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(layer_head_mask),
+ [self.n_heads],
+ message=(
+ f"Head mask for a single layer should be of size {(self.n_heads)}, but is"
+ f" {shape_list(layer_head_mask)}"
+ ),
+ )
+ weights = tf.reshape(layer_head_mask, (1, -1, 1, 1)) * weights
+
+ attn_output = tf.matmul(weights, value_states) # (batch_size, n_heads, query_length, dim_per_head)
+
+ attn_output = self.o(unshape(attn_output))
+
+ outputs = (attn_output,) + (present_key_value_state,) + (position_bias,)
+
+ if output_attentions:
+ outputs = outputs + (weights,)
+
+ return outputs
+
+
+class TFT5LayerSelfAttention(keras.layers.Layer):
+ def __init__(self, config, has_relative_attention_bias=False, **kwargs):
+ super().__init__(**kwargs)
+ self.SelfAttention = TFT5Attention(
+ config,
+ has_relative_attention_bias=has_relative_attention_bias,
+ name="SelfAttention",
+ )
+ self.layer_norm = TFT5LayerNorm(config.d_model, epsilon=config.layer_norm_epsilon, name="layer_norm")
+ self.dropout = keras.layers.Dropout(config.dropout_rate)
+
+ def call(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_value=None,
+ use_cache=False,
+ output_attentions=False,
+ training=False,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.SelfAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_value=past_key_value,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0], training=training)
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "SelfAttention", None) is not None:
+ with tf.name_scope(self.SelfAttention.name):
+ self.SelfAttention.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build(None)
+
+
+class TFT5LayerCrossAttention(keras.layers.Layer):
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ self.EncDecAttention = TFT5Attention(
+ config,
+ has_relative_attention_bias=False,
+ name="EncDecAttention",
+ )
+ self.layer_norm = TFT5LayerNorm(config.d_model, epsilon=config.layer_norm_epsilon, name="layer_norm")
+ self.dropout = keras.layers.Dropout(config.dropout_rate)
+
+ def call(
+ self,
+ hidden_states,
+ key_value_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_value=None,
+ query_length=None,
+ use_cache=False,
+ output_attentions=False,
+ training=False,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.EncDecAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ key_value_states=key_value_states,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_value=past_key_value,
+ query_length=query_length,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0], training=training)
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "EncDecAttention", None) is not None:
+ with tf.name_scope(self.EncDecAttention.name):
+ self.EncDecAttention.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build(None)
+
+
+class TFT5Block(keras.layers.Layer):
+ def __init__(self, config, has_relative_attention_bias=False, **kwargs):
+ super().__init__(**kwargs)
+ self.is_decoder = config.is_decoder
+ self.layer = []
+ self.layer.append(
+ TFT5LayerSelfAttention(
+ config,
+ has_relative_attention_bias=has_relative_attention_bias,
+ name="layer_._0",
+ )
+ )
+ if self.is_decoder:
+ self.layer.append(
+ TFT5LayerCrossAttention(
+ config,
+ name="layer_._1",
+ )
+ )
+
+ self.layer.append(TFT5LayerFF(config, name=f"layer_._{len(self.layer)}"))
+
+ def call(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ encoder_decoder_position_bias=None,
+ layer_head_mask=None,
+ encoder_layer_head_mask=None,
+ past_key_value=None,
+ use_cache=False,
+ output_attentions=False,
+ training=False,
+ ):
+ if past_key_value is not None:
+ assert self.is_decoder, "Only decoder can use `past_key_values`"
+ expected_num_past_key_values = 2 if encoder_hidden_states is None else 4
+
+ if len(past_key_value) != expected_num_past_key_values:
+ raise ValueError(
+ f"There should be {expected_num_past_key_values} past states. "
+ f"{'2 (key / value) for cross attention' if expected_num_past_key_values == 4 else ''}. "
+ f"Got {len(past_key_value)} past key / value states"
+ )
+
+ self_attn_past_key_value = past_key_value[:2]
+ cross_attn_past_key_value = past_key_value[2:]
+ else:
+ self_attn_past_key_value, cross_attn_past_key_value = None, None
+
+ self_attention_outputs = self.layer[0](
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_value=self_attn_past_key_value,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states, present_key_value_state = self_attention_outputs[:2]
+ attention_outputs = self_attention_outputs[2:] # Keep self-attention outputs and relative position weights
+
+ if self.is_decoder and encoder_hidden_states is not None:
+ # the actual query length is unknown for cross attention
+ # if using past key value states. Need to inject it here
+ if present_key_value_state is not None:
+ query_length = shape_list(present_key_value_state[0])[2]
+ else:
+ query_length = None
+
+ cross_attention_outputs = self.layer[1](
+ hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ position_bias=encoder_decoder_position_bias,
+ layer_head_mask=encoder_layer_head_mask,
+ past_key_value=cross_attn_past_key_value,
+ query_length=query_length,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = cross_attention_outputs[0]
+ # Combine self attn and cross attn key value states
+ if present_key_value_state is not None:
+ present_key_value_state = present_key_value_state + cross_attention_outputs[1]
+
+ # Keep cross-attention outputs and relative position weights
+ attention_outputs = attention_outputs + cross_attention_outputs[2:]
+
+ # Apply Feed Forward layer
+ hidden_states = self.layer[-1](hidden_states, training=training)
+ outputs = (hidden_states,)
+
+ # Add attentions if we output them
+ outputs = outputs + (present_key_value_state,) + attention_outputs
+ return outputs # hidden-states, present_key_value_states, (self-attention weights), (self-attention position bias), (cross-attention weights), (cross-attention position bias)
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ for layer_module in self.layer:
+ if hasattr(layer_module, "name"):
+ with tf.name_scope(layer_module.name):
+ layer_module.build(None)
+
+
+####################################################
+# The full model without a specific pretrained or finetuning head is
+# provided as a keras.layers.Layer usually called "TFT5MainLayer"
+####################################################
+@keras_serializable
+class TFT5MainLayer(keras.layers.Layer):
+ config_class = T5Config
+
+ def __init__(self, config, embed_tokens=None, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+ self.output_hidden_states = config.output_hidden_states
+ self.output_attentions = config.output_attentions
+ self.use_cache = config.use_cache
+
+ self.embed_tokens = embed_tokens
+ self.is_decoder = config.is_decoder
+
+ self.config = config
+ self.num_hidden_layers = config.num_layers
+
+ self.block = [
+ TFT5Block(config, has_relative_attention_bias=bool(i == 0), name=f"block_._{i}")
+ for i in range(config.num_layers)
+ ]
+ self.final_layer_norm = TFT5LayerNorm(
+ config.d_model, epsilon=config.layer_norm_epsilon, name="final_layer_norm"
+ )
+ self.dropout = keras.layers.Dropout(config.dropout_rate)
+
+ def _prune_heads(self, heads_to_prune):
+ raise NotImplementedError # Not implemented yet in the library fr TF 2.0 models
+
+ @unpack_inputs
+ def call(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ inputs_embeds=None,
+ head_mask=None,
+ encoder_head_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ ) -> tuple:
+ if input_ids is not None and inputs_embeds is not None:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(
+ f"You cannot specify both {err_msg_prefix}input_ids and {err_msg_prefix}inputs_embeds at the same time"
+ )
+ elif input_ids is not None:
+ input_shape = shape_list(input_ids)
+ input_ids = tf.reshape(input_ids, (-1, input_shape[-1]))
+ elif inputs_embeds is not None:
+ input_shape = shape_list(inputs_embeds)[:-1]
+ else:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(f"You have to specify either {err_msg_prefix}input_ids or {err_msg_prefix}inputs_embeds")
+
+ if inputs_embeds is None:
+ assert self.embed_tokens is not None, "You have to initialize the model with valid token embeddings"
+ check_embeddings_within_bounds(input_ids, self.embed_tokens.input_dim)
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ batch_size, seq_length = input_shape
+
+ # required mask seq length can be calculated via length of past
+ mask_seq_length = (
+ shape_list(past_key_values[0][0])[2] + seq_length if past_key_values is not None else seq_length
+ )
+
+ if attention_mask is None:
+ attention_mask = tf.fill((batch_size, mask_seq_length), 1)
+ if self.is_decoder and encoder_attention_mask is None and encoder_hidden_states is not None:
+ encoder_seq_length = shape_list(encoder_hidden_states)[1]
+ encoder_attention_mask = tf.fill((batch_size, encoder_seq_length), 1)
+
+ # initialize past_key_values with `None` if past does not exist
+ if past_key_values is None:
+ past_key_values = [None] * len(self.block)
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ attention_mask = tf.cast(attention_mask, dtype=inputs_embeds.dtype)
+ num_dims_attention_mask = len(shape_list(attention_mask))
+ if num_dims_attention_mask == 3:
+ extended_attention_mask = attention_mask[:, None, :, :]
+ elif num_dims_attention_mask == 2:
+ # Provided a padding mask of dimensions [batch_size, mask_seq_length]
+ # - if the model is a decoder, apply a causal mask in addition to the padding mask
+ # - if the model is an encoder, make the mask broadcastable to [batch_size, num_heads, mask_seq_length, mask_seq_length]
+ if self.is_decoder:
+ seq_ids = tf.range(mask_seq_length)
+ causal_mask = tf.less_equal(
+ tf.tile(seq_ids[None, None, :], (batch_size, mask_seq_length, 1)),
+ seq_ids[None, :, None],
+ )
+ causal_mask = tf.cast(causal_mask, dtype=attention_mask.dtype)
+ extended_attention_mask = causal_mask[:, None, :, :] * attention_mask[:, None, None, :]
+ if past_key_values[0] is not None:
+ extended_attention_mask = extended_attention_mask[:, :, -seq_length:, :]
+ else:
+ extended_attention_mask = attention_mask[:, None, None, :]
+
+ # Since attention_mask is 1.0 for positions we want to attend and 0.0 for
+ # masked positions, this operation will create a tensor which is 0.0 for
+ # positions we want to attend and -1e9 for masked positions.
+ # Since we are adding it to the raw scores before the softmax, this is
+ # effectively the same as removing these entirely.
+
+ # T5 has a mask that can compare sequence ids, we can simulate this here with this transposition
+ # Cf. https://github.com/tensorflow/mesh/blob/8d2465e9bc93129b913b5ccc6a59aa97abd96ec6/mesh_tensorflow/transformer/transformer_layers.py#L270
+ # extended_attention_mask = tf.math.equal(extended_attention_mask,
+ # tf.transpose(extended_attention_mask, perm=(-1, -2)))
+
+ extended_attention_mask = (1.0 - extended_attention_mask) * -1e9
+
+ if self.is_decoder and encoder_attention_mask is not None:
+ # If a 2D ou 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, mask_seq_length, mask_seq_length]
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ encoder_attention_mask = tf.cast(encoder_attention_mask, dtype=extended_attention_mask.dtype)
+ num_dims_encoder_attention_mask = len(shape_list(encoder_attention_mask))
+ if num_dims_encoder_attention_mask == 3:
+ encoder_extended_attention_mask = encoder_attention_mask[:, None, :, :]
+ if num_dims_encoder_attention_mask == 2:
+ encoder_extended_attention_mask = encoder_attention_mask[:, None, None, :]
+
+ # T5 has a mask that can compare sequence ids, we can simulate this here with this transposition
+ # Cf. https://github.com/tensorflow/mesh/blob/8d2465e9bc93129b913b5ccc6a59aa97abd96ec6/mesh_tensorflow/transformer/transformer_layers.py#L270
+ # encoder_extended_attention_mask = tf.math.equal(encoder_extended_attention_mask,
+ # tf.transpose(encoder_extended_attention_mask, perm=(-1, -2)))
+
+ encoder_extended_attention_mask = (1.0 - encoder_extended_attention_mask) * -1e9
+ else:
+ encoder_extended_attention_mask = None
+
+ present_key_value_states = () if use_cache and self.is_decoder else None
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and self.is_decoder) else None
+ position_bias = None
+ encoder_decoder_position_bias = None
+
+ hidden_states = self.dropout(inputs_embeds, training=training)
+
+ for idx, (layer_module, past_key_value) in enumerate(zip(self.block, past_key_values)):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+ layer_outputs = layer_module(
+ hidden_states,
+ attention_mask=extended_attention_mask,
+ position_bias=position_bias,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ encoder_decoder_position_bias=encoder_decoder_position_bias,
+ layer_head_mask=head_mask[idx] if head_mask is not None else None,
+ encoder_layer_head_mask=encoder_head_mask[idx] if encoder_head_mask is not None else None,
+ past_key_value=past_key_value,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ training=training,
+ )
+
+ # layer_outputs is a tuple with:
+ # hidden-states, key-value-states, (self-attention weights), (self-attention position bias), (cross-attention weights), (cross-attention position bias)
+ hidden_states, present_key_value_state = layer_outputs[:2]
+
+ # We share the position biases between the layers - the first layer store them
+ # layer_outputs = hidden-states, past_key_values, (self-attention weights),
+ # (self-attention position bias), (cross-attention position bias), (cross-attention weights),
+ position_bias = layer_outputs[2]
+
+ if self.is_decoder and encoder_hidden_states is not None:
+ encoder_decoder_position_bias = layer_outputs[4 if output_attentions else 3]
+
+ # append next layer key value states
+ if present_key_value_state is not None and use_cache and self.is_decoder:
+ present_key_value_states = present_key_value_states + (present_key_value_state,)
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[3],)
+ if self.is_decoder:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[5],)
+
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ outputs = (hidden_states,)
+ # need to check if is decoder here as well for special cases when using keras compile
+ if use_cache and self.is_decoder:
+ outputs = outputs + (present_key_value_states,)
+ if output_hidden_states:
+ outputs = outputs + (all_hidden_states,)
+ if output_attentions:
+ outputs = outputs + (all_attentions,)
+ if self.is_decoder:
+ outputs + (all_cross_attentions,)
+ return outputs # last-layer hidden state, (past_key_values), (all hidden states), (all attentions), (all_cross_attentions)
+
+ if self.is_decoder:
+ return TFBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=present_key_value_states,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+ else:
+ return TFBaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build(None)
+ if getattr(self, "block", None) is not None:
+ for layer in self.block:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+####################################################
+# TFT5PreTrainedModel is a sub-class of keras.Model
+# which take care of loading and saving pretrained weights
+# and various common utilities.
+# Here you just need to specify a few (self-explanatory)
+# pointers for your model.
+####################################################
+class TFT5PreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = T5Config
+ base_model_prefix = "transformer"
+ # names with a '.' represents the authorized unexpected/missing layers when a TF model is loaded from a PT model
+ _keys_to_ignore_on_load_unexpected = [r"decoder\Wblock[\W_0]+layer[\W_1]+EncDecAttention\Wrelative_attention_bias"]
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, value):
+ self.shared = value
+ self.encoder.embed_tokens = self.shared
+ if hasattr(self, "decoder"):
+ self.decoder.embed_tokens = self.shared
+
+ def _shift_right(self, input_ids):
+ decoder_start_token_id = self.config.decoder_start_token_id
+ pad_token_id = self.config.pad_token_id
+
+ assert decoder_start_token_id is not None, (
+ "self.model.config.decoder_start_token_id has to be defined. In TF T5 it is usually set to the"
+ " pad_token_id. See T5 docs for more information"
+ )
+
+ start_tokens = tf.fill((shape_list(input_ids)[0], 1), decoder_start_token_id)
+ start_tokens = tf.cast(start_tokens, input_ids.dtype) # Ensure compatible dtypes for concatenation
+ shifted_input_ids = tf.concat([start_tokens, input_ids[:, :-1]], -1)
+
+ assert pad_token_id is not None, "self.model.config.pad_token_id has to be defined."
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids = tf.where(
+ shifted_input_ids == -100,
+ tf.cast(tf.fill(shape_list(shifted_input_ids), pad_token_id), shifted_input_ids.dtype),
+ shifted_input_ids,
+ )
+
+ # "Verify that `labels` has only positive values and -100"
+ assert_gte0 = tf.debugging.assert_greater_equal(
+ shifted_input_ids, tf.constant(0, dtype=shifted_input_ids.dtype)
+ )
+
+ # Make sure the assertion op is called by wrapping the result in an identity no-op
+ with tf.control_dependencies([assert_gte0]):
+ shifted_input_ids = tf.identity(shifted_input_ids)
+
+ return shifted_input_ids
+
+
+T5_START_DOCSTRING = r"""
+
+ The T5 model was proposed in [Exploring the Limits of Transfer Learning with a Unified Text-to-Text
+ Transformer](https://huggingface.co/papers/1910.10683) by Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan
+ Narang, Michael Matena, Yanqi Zhou, Wei Li, Peter J. Liu. It's an encoder decoder transformer pre-trained in a
+ text-to-text denoising generative setting.
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Parameters:
+ config ([`T5Config`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+T5_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on the right or the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.__call__`] and
+ [`PreTrainedTokenizer.encode`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `inputs` for pretraining take a look at [T5 Training](./t5#training).
+ decoder_input_ids (`tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Provide for sequence to sequence training. T5 uses the `pad_token_id` as the starting token for
+ `decoder_input_ids` generation. If `past_key_values` is used, optionally only the last `decoder_input_ids`
+ have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [T5
+ Training](./t5#training).
+ attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ decoder_attention_mask (`tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ head_mask (`tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the encoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ decoder_head_mask (`tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ encoder_outputs (`tuple(tuple(tf.FloatTensor)`, *optional*):
+ Tuple consists of (`last_hidden_state`, `optional`: *hidden_states*, `optional`: *attentions*)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)` is a sequence of hidden states at
+ the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ past_key_values (`tuple(tuple(tf.Tensor))` of length `config.n_layers` with each tuple having 4 tensors of shape `(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`):
+ contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ decoder_inputs_embeds (`tf.Tensor` of shape `(batch_size, target_sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `decoder_input_ids` you can choose to directly pass an embedded
+ representation. If `past_key_values` is used, optionally only the last `decoder_inputs_embeds` have to be
+ input (see `past_key_values`). This is useful if you want more control over how to convert
+ `decoder_input_ids` indices into associated vectors than the model's internal embedding lookup matrix.
+
+ If `decoder_input_ids` and `decoder_inputs_embeds` are both unset, `decoder_inputs_embeds` takes the value
+ of `inputs_embeds`.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+T5_ENCODER_INPUTS_DOCSTRING = r"""
+ Args:
+ inputs (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on the right or the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.__call__`] and
+ [`PreTrainedTokenizer.encode`] for details.
+
+ To know more on how to prepare `inputs` for pre-training take a look at [T5 Training](./t5#training).
+ attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ inputs_embeds (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ head_mask (`tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+_HEAD_MASK_WARNING_MSG = """
+The input argument `head_mask` was split into two arguments `head_mask` and `decoder_head_mask`. Currently,
+`decoder_head_mask` is set to copy `head_mask`, but this feature is deprecated and will be removed in future versions.
+If you do not want to use any `decoder_head_mask` now, please set `decoder_head_mask = tf.ones((num_layers,
+num_heads))`.
+"""
+
+
+@add_start_docstrings(
+ "The bare T5 Model transformer outputting raw hidden-stateswithout any specific head on top.",
+ T5_START_DOCSTRING,
+)
+class TFT5Model(TFT5PreTrainedModel):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.shared = keras.layers.Embedding(
+ input_dim=config.vocab_size,
+ output_dim=config.d_model,
+ embeddings_initializer=keras.initializers.TruncatedNormal(self.config.initializer_factor),
+ name="shared",
+ )
+ # Additional attribute to specify the expected name scope of the layer (for loading/storing weights)
+ self.shared.load_weight_prefix = "shared"
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.use_cache = False
+ self.encoder = TFT5MainLayer(encoder_config, self.shared, name="encoder")
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = TFT5MainLayer(decoder_config, self.shared, name="decoder")
+
+ def get_encoder(self):
+ return self.encoder
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(T5_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFSeq2SeqModelOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_input_ids: np.ndarray | tf.Tensor | None = None,
+ decoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_head_mask: np.ndarray | tf.Tensor | None = None,
+ encoder_outputs: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ decoder_inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ ) -> tuple | TFSeq2SeqModelOutput:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TFT5Model
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = TFT5Model.from_pretrained("google-t5/t5-small")
+
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="tf"
+ ... ).input_ids # Batch size 1
+ >>> decoder_input_ids = tokenizer("Studies show that", return_tensors="tf").input_ids # Batch size 1
+
+ >>> # preprocess: Prepend decoder_input_ids with start token which is pad token for T5Model.
+ >>> # This is not needed for torch's T5ForConditionalGeneration as it does this internally using labels arg.
+ >>> decoder_input_ids = model._shift_right(decoder_input_ids)
+
+ >>> # forward pass
+ >>> outputs = model(input_ids, decoder_input_ids=decoder_input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ # FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+ if head_mask is not None and decoder_head_mask is None:
+ warnings.warn(_HEAD_MASK_WARNING_MSG, FutureWarning)
+ decoder_head_mask = head_mask
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids,
+ attention_mask=attention_mask,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ head_mask=decoder_head_mask,
+ encoder_head_mask=head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ past = decoder_outputs[1] if use_cache else None
+
+ if not return_dict:
+ if past_key_values is not None:
+ decoder_outputs = decoder_outputs[:1] + (past,) + decoder_outputs[2:]
+ return decoder_outputs + encoder_outputs
+
+ return TFSeq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=past,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ # The shared/tied weights expect to be in the model base namespace
+ # Adding "/" to the end (not the start!) of a tf.name_scope puts it in the root namespace rather than
+ # the current one.
+ with tf.name_scope(self.shared.load_weight_prefix + "/" + self.shared.name + "/"):
+ self.shared.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "decoder", None) is not None:
+ with tf.name_scope(self.decoder.name):
+ self.decoder.build(None)
+
+
+@add_start_docstrings("""T5 Model with a `language modeling` head on top.""", T5_START_DOCSTRING)
+class TFT5ForConditionalGeneration(TFT5PreTrainedModel, TFCausalLanguageModelingLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.model_dim = config.d_model
+ self.shared = keras.layers.Embedding(
+ config.vocab_size,
+ config.d_model,
+ name="shared",
+ embeddings_initializer=get_initializer(self.config.initializer_factor),
+ )
+ # Additional attribute to specify the expected name scope of the layer (for loading/storing weights)
+ self.shared.load_weight_prefix = "shared"
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.use_cache = False
+ self.encoder = TFT5MainLayer(encoder_config, self.shared, name="encoder")
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = TFT5MainLayer(decoder_config, self.shared, name="decoder")
+
+ if not config.tie_word_embeddings:
+ lm_head_initializer = keras.initializers.RandomNormal(mean=0, stddev=config.initializer_factor)
+ self.lm_head = keras.layers.Dense(
+ config.vocab_size, use_bias=False, name="lm_head", kernel_initializer=lm_head_initializer
+ ) # Update init weights as in flax
+ self.config = config
+
+ def get_output_embeddings(self):
+ if self.config.tie_word_embeddings:
+ return self.get_input_embeddings()
+ else:
+ # in a dense layer the kernel has a shape (last_dim, units), for us (dim, num_tokens)
+ # value has a shape (num_tokens, dim) then needs to be transposed
+ return tf.transpose(self.lm_head.kernel)
+
+ def set_output_embeddings(self, value):
+ if self.config.tie_word_embeddings:
+ self.set_input_embeddings(value)
+ else:
+ lm_head_initializer = keras.initializers.RandomNormal(mean=0, stddev=self.config.initializer_factor)
+ self.lm_head = keras.layers.Dense(
+ shape_list(value)[0], use_bias=False, name="lm_head", kernel_initializer=lm_head_initializer
+ ) # Update init weights as in flax
+ # in a dense layer the kernel has a shape (last_dim, units), for us (dim, num_tokens)
+ # value has a shape (num_tokens, dim) then needs to be transposed
+ transposed_value = tf.transpose(value)
+ self.lm_head.kernel = transposed_value
+
+ def get_encoder(self):
+ return self.encoder
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(T5_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_input_ids: np.ndarray | tf.Tensor | None = None,
+ decoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_head_mask: np.ndarray | tf.Tensor | None = None,
+ encoder_outputs: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ decoder_inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ ) -> tuple | TFSeq2SeqLMOutput:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the cross entropy classification loss. Indices should be in `[0, ...,
+ config.vocab_size - 1]`.
+
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TFT5ForConditionalGeneration
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = TFT5ForConditionalGeneration.from_pretrained("google-t5/t5-small")
+
+ >>> # training
+ >>> inputs = tokenizer("The walks in park", return_tensors="tf").input_ids
+ >>> labels = tokenizer(" cute dog the ", return_tensors="tf").input_ids
+ >>> outputs = model(inputs, labels=labels)
+ >>> loss = outputs.loss
+ >>> logits = outputs.logits
+
+ >>> # inference
+ >>> inputs = tokenizer(
+ ... "summarize: studies have shown that owning a dog is good for you", return_tensors="tf"
+ ... ).input_ids # Batch size 1
+ >>> outputs = model.generate(inputs)
+ >>> print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+ >>> # studies have shown that owning a dog is good for you
+ ```"""
+ # FutureWarning: head_mask was separated into two input args - head_mask, decoder_head_mask
+ if head_mask is not None and decoder_head_mask is None:
+ warnings.warn(_HEAD_MASK_WARNING_MSG, FutureWarning)
+ decoder_head_mask = head_mask
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None:
+ # get decoder inputs from shifting lm labels to the right
+ decoder_input_ids = self._shift_right(labels)
+
+ # Decode
+ decoder_outputs = self.decoder(
+ decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ head_mask=decoder_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ # T5v1.1 does not tie output word embeddings and thus does not require downscaling
+ if self.config.tie_word_embeddings:
+ sequence_output = sequence_output * (self.model_dim**-0.5)
+ logits = tf.matmul(sequence_output, self.shared.weights, transpose_b=True)
+ else:
+ logits = self.lm_head(sequence_output)
+
+ logits = tf.cast(logits, tf.float32)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ past = decoder_outputs[1] if use_cache else None
+ if not return_dict:
+ if past_key_values is not None:
+ decoder_outputs = decoder_outputs[:1] + (past,) + decoder_outputs[2:]
+ output = (logits,) + decoder_outputs[1:] + encoder_outputs
+ return ((loss,) + output) if loss is not None else output
+
+ # If the user passed a tuple for encoder_outputs, we wrap it in a TFBaseModelOutput when return_dict=True
+ elif isinstance(encoder_outputs, tuple):
+ last_hidden_state = encoder_outputs[0]
+ hidden_states = None
+ attentions = None
+ idx = 0
+ if output_hidden_states:
+ idx += 1
+ hidden_states = encoder_outputs[idx]
+ if output_attentions:
+ idx += 1
+ attentions = encoder_outputs[idx]
+
+ encoder_outputs = TFBaseModelOutput(
+ last_hidden_state=last_hidden_state,
+ hidden_states=hidden_states,
+ attentions=attentions,
+ )
+
+ return TFSeq2SeqLMOutput(
+ loss=loss,
+ logits=logits,
+ past_key_values=past,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def serving_output(self, output):
+ pkv = tf.convert_to_tensor(output.past_key_values[1:]) if self.config.use_cache else None
+ dec_hs = tf.convert_to_tensor(output.decoder_hidden_states) if self.config.output_hidden_states else None
+ dec_attns = tf.convert_to_tensor(output.decoder_attentions) if self.config.output_attentions else None
+ cross_attns = tf.convert_to_tensor(output.cross_attentions) if self.config.output_attentions else None
+ enc_hs = tf.convert_to_tensor(output.encoder_hidden_states) if self.config.output_hidden_states else None
+ enc_attns = tf.convert_to_tensor(output.encoder_attentions) if self.config.output_attentions else None
+
+ return TFSeq2SeqLMOutput(
+ logits=output.logits,
+ past_key_values=pkv,
+ decoder_hidden_states=dec_hs,
+ decoder_attentions=dec_attns,
+ cross_attentions=cross_attns,
+ encoder_last_hidden_state=output.encoder_last_hidden_state,
+ encoder_hidden_states=enc_hs,
+ encoder_attentions=enc_attns,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ past_key_values=None,
+ attention_mask=None,
+ decoder_attention_mask=None,
+ head_mask=None,
+ decoder_head_mask=None,
+ use_cache=None,
+ encoder_outputs=None,
+ **kwargs,
+ ):
+ # cut decoder_input_ids if past is used
+ if past_key_values is not None:
+ input_ids = input_ids[:, -1:]
+
+ return {
+ "input_ids": None, # needs to be passed to make Keras.layer.__call__ happy
+ "decoder_input_ids": input_ids,
+ "past_key_values": past_key_values,
+ "encoder_outputs": encoder_outputs,
+ "attention_mask": attention_mask,
+ "decoder_attention_mask": decoder_attention_mask,
+ "head_mask": head_mask,
+ "decoder_head_mask": decoder_head_mask,
+ "use_cache": use_cache,
+ }
+
+ def prepare_decoder_input_ids_from_labels(self, labels: tf.Tensor):
+ return self._shift_right(labels)
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ # The shared/tied weights expect to be in the model base namespace
+ # Adding "/" to the end (not the start!) of a tf.name_scope puts it in the root namespace rather than
+ # the current one.
+ with tf.name_scope(self.shared.load_weight_prefix + "/" + self.shared.name + "/"):
+ self.shared.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "decoder", None) is not None:
+ with tf.name_scope(self.decoder.name):
+ self.decoder.build(None)
+ if getattr(self, "lm_head", None) is not None:
+ with tf.name_scope(self.lm_head.name):
+ self.lm_head.build([None, None, self.config.d_model])
+
+
+@add_start_docstrings(
+ "The bare T5 Model transformer outputting encoder's raw hidden-stateswithout any specific head on top.",
+ T5_START_DOCSTRING,
+)
+class TFT5EncoderModel(TFT5PreTrainedModel):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.shared = keras.layers.Embedding(
+ config.vocab_size,
+ config.d_model,
+ name="shared",
+ embeddings_initializer=get_initializer(self.config.initializer_factor),
+ )
+ # Additional attribute to specify the expected name scope of the layer (for loading/storing weights)
+ self.shared.load_weight_prefix = "shared"
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.use_cache = False
+ self.encoder = TFT5MainLayer(encoder_config, self.shared, name="encoder")
+
+ def get_encoder(self):
+ return self.encoder
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(T5_ENCODER_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFBaseModelOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ ) -> tuple | TFBaseModelOutput:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TFT5EncoderModel
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+ >>> model = TFT5EncoderModel.from_pretrained("google-t5/t5-small")
+
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="tf"
+ ... ).input_ids # Batch size 1
+ >>> outputs = model(input_ids)
+ ```"""
+
+ encoder_outputs = self.encoder(
+ input_ids,
+ attention_mask=attention_mask,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ if not return_dict:
+ return encoder_outputs
+
+ return TFBaseModelOutput(
+ last_hidden_state=encoder_outputs.last_hidden_state,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ # The shared/tied weights expect to be in the model base namespace
+ # Adding "/" to the end (not the start!) of a tf.name_scope puts it in the root namespace rather than
+ # the current one.
+ with tf.name_scope(self.shared.load_weight_prefix + "/" + self.shared.name + "/"):
+ self.shared.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+
+
+__all__ = ["TFT5EncoderModel", "TFT5ForConditionalGeneration", "TFT5Model", "TFT5PreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/tokenization_t5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/tokenization_t5.py
new file mode 100644
index 0000000000000000000000000000000000000000..0a25271345cfa3a2fc9139c06ec9eb7b59aeef23
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/tokenization_t5.py
@@ -0,0 +1,448 @@
+# coding=utf-8
+# Copyright 2018 T5 Authors and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for model T5."""
+
+import os
+import re
+import warnings
+from shutil import copyfile
+from typing import TYPE_CHECKING, Any, Optional
+
+import sentencepiece as spm
+
+from ...convert_slow_tokenizer import import_protobuf
+from ...tokenization_utils import PreTrainedTokenizer
+from ...tokenization_utils_base import AddedToken
+
+
+if TYPE_CHECKING:
+ from ...tokenization_utils_base import TextInput
+from ...utils import logging
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "spiece.model"}
+
+
+SPIECE_UNDERLINE = "▁"
+
+
+@requires(backends=("sentencepiece",))
+class T5Tokenizer(PreTrainedTokenizer):
+ """
+ Construct a T5 tokenizer. Based on [SentencePiece](https://github.com/google/sentencepiece).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ [SentencePiece](https://github.com/google/sentencepiece) file (generally has a *.spm* extension) that
+ contains the vocabulary necessary to instantiate a tokenizer.
+ eos_token (`str`, *optional*, defaults to `""`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ extra_ids (`int`, *optional*, defaults to 100):
+ Add a number of extra ids added to the vocabulary for use as sentinels. These tokens are
+ accessible as "" where "{%d}" is a number between 0 and extra_ids-1. These tokens can be
+ retrieved by calling get_sentinel_tokens method and token ids can be by calling get_sentinel_token_ids
+ method
+ additional_special_tokens (`list[str]`, *optional*):
+ Additional special tokens used by the tokenizer.
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+ legacy (`bool`, *optional*):
+ Whether or not the `legacy` behaviour of the tokenizer should be used. Legacy is before the merge of #24622
+ and #25224 which includes fixes to properly handle tokens that appear after special tokens. A simple
+ example:
+
+ - `legacy=True`:
+ ```python
+ >>> from transformers import T5Tokenizer
+
+ >>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-base", legacy=True)
+ >>> tokenizer.encode("Hello .")
+ [8774, 32099, 3, 5, 1]
+ ```
+ - `legacy=False`:
+ ```python
+ >>> from transformers import T5Tokenizer
+
+ >>> tokenizer = T5Tokenizer.from_pretrained("google-t5/t5-base", legacy=False)
+ >>> tokenizer.encode("Hello .") # the extra space `[3]` is no longer here
+ [8774, 32099, 5, 1]
+ ```
+ Checkout the [pull request](https://github.com/huggingface/transformers/pull/24565) for more details.
+ add_prefix_space (`bool`, *optional*, defaults to `False`):
+ Whether or not to add an initial space to the input. This allows to treat the leading word just as any
+ other word.
+
+ Attributes:
+ sp_model (`SentencePieceProcessor`):
+ The *SentencePiece* processor that is used for every conversion (string, tokens and IDs).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ eos_token="",
+ unk_token="",
+ pad_token="",
+ extra_ids=100,
+ additional_special_tokens=None,
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ legacy=None,
+ add_prefix_space=True,
+ **kwargs,
+ ) -> None:
+ pad_token = AddedToken(pad_token, special=True) if isinstance(pad_token, str) else pad_token
+ unk_token = AddedToken(unk_token, special=True) if isinstance(unk_token, str) else unk_token
+ eos_token = AddedToken(eos_token, special=True) if isinstance(eos_token, str) else eos_token
+
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+
+ self.vocab_file = vocab_file
+ self._extra_ids = extra_ids
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(vocab_file)
+
+ if additional_special_tokens is not None:
+ extra_tokens = [x for x in additional_special_tokens if "" for i in range(extra_ids)]
+ elif extra_ids > 0 and extra_ids != len(extra_tokens):
+ raise ValueError(
+ f"Both extra_ids ({extra_ids}) and additional_special_tokens ({additional_special_tokens}) are"
+ " provided to T5Tokenizer. In this case the additional_special_tokens must include the extra_ids"
+ " tokens"
+ )
+ else:
+ extra_tokens = [f"" for i in range(extra_ids)]
+ additional_special_tokens = extra_tokens
+
+ # for legacy purpose, we keep this. Will be removed and tests updated. (when `added_tokens_decoder` is not passed as kwargs)
+ self._added_tokens_decoder = {}
+ for i in range(len(extra_tokens)):
+ self._added_tokens_decoder[len(self.sp_model) - 1 + extra_ids - i] = AddedToken(
+ f"", single_word=False, lstrip=True, rstrip=True, special=True, normalized=False
+ )
+
+ if legacy is None:
+ logger.warning_once(
+ f"You are using the default legacy behaviour of the {self.__class__}. This is"
+ " expected, and simply means that the `legacy` (previous) behavior will be used so nothing changes for you."
+ " If you want to use the new behaviour, set `legacy=False`. This should only be set if you understand what it"
+ " means, and thoroughly read the reason why this was added as explained in"
+ " https://github.com/huggingface/transformers/pull/24565"
+ )
+ legacy = True
+
+ self.legacy = legacy
+ self.sp_model = self.get_spm_processor(kwargs.pop("from_slow", False))
+ self.add_prefix_space = add_prefix_space
+
+ super().__init__(
+ eos_token=eos_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ extra_ids=extra_ids,
+ additional_special_tokens=additional_special_tokens,
+ sp_model_kwargs=self.sp_model_kwargs,
+ legacy=legacy,
+ add_prefix_space=add_prefix_space,
+ **kwargs,
+ )
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.get_spm_processor
+ def get_spm_processor(self, from_slow=False):
+ tokenizer = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ if self.legacy or from_slow: # no dependency on protobuf
+ tokenizer.Load(self.vocab_file)
+ return tokenizer
+
+ with open(self.vocab_file, "rb") as f:
+ sp_model = f.read()
+ model_pb2 = import_protobuf(f"The new behaviour of {self.__class__.__name__} (with `self.legacy = False`)")
+ model = model_pb2.ModelProto.FromString(sp_model)
+ normalizer_spec = model_pb2.NormalizerSpec()
+ normalizer_spec.add_dummy_prefix = False
+ model.normalizer_spec.MergeFrom(normalizer_spec)
+ sp_model = model.SerializeToString()
+ tokenizer.LoadFromSerializedProto(sp_model)
+ return tokenizer
+
+ @staticmethod
+ def _eventually_correct_t5_max_length(pretrained_model_name_or_path, max_model_length, init_max_model_length):
+ if pretrained_model_name_or_path in T5Tokenizer.max_model_input_sizes:
+ deprecated_max_model_length = T5Tokenizer.max_model_input_sizes[pretrained_model_name_or_path]
+ if init_max_model_length is not None and init_max_model_length != max_model_length:
+ return init_max_model_length
+ elif init_max_model_length is None:
+ warnings.warn(
+ "This tokenizer was incorrectly instantiated with a model max length of"
+ f" {deprecated_max_model_length} which will be corrected in Transformers v5.\nFor now, this"
+ " behavior is kept to avoid breaking backwards compatibility when padding/encoding with"
+ " `truncation is True`.\n- Be aware that you SHOULD NOT rely on"
+ f" {pretrained_model_name_or_path} automatically truncating your input to"
+ f" {deprecated_max_model_length} when padding/encoding.\n- If you want to encode/pad to sequences"
+ f" longer than {deprecated_max_model_length} you can either instantiate this tokenizer with"
+ " `model_max_length` or pass `max_length` when encoding/padding.\n- To avoid this warning, please"
+ " instantiate this tokenizer with `model_max_length` set to your preferred value.",
+ FutureWarning,
+ )
+
+ return max_model_length
+
+ @property
+ def vocab_size(self):
+ return self.sp_model.get_piece_size()
+
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ # normal case: some special tokens
+ if token_ids_1 is None:
+ return ([0] * len(token_ids_0)) + [1]
+ return ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
+
+ def get_sentinel_tokens(self):
+ return list(
+ set(filter(lambda x: bool(re.search(r"", x)) is not None, self.additional_special_tokens))
+ )
+
+ def get_sentinel_token_ids(self):
+ return [self.convert_tokens_to_ids(token) for token in self.get_sentinel_tokens()]
+
+ def _add_eos_if_not_present(self, token_ids: list[int]) -> list[int]:
+ """Do not add eos again if user already added it."""
+ if len(token_ids) > 0 and token_ids[-1] == self.eos_token_id:
+ warnings.warn(
+ f"This sequence already has {self.eos_token}. In future versions this behavior may lead to duplicated"
+ " eos tokens being added."
+ )
+ return token_ids
+ else:
+ return token_ids + [self.eos_token_id]
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. T5 does not make
+ use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+ """
+ eos = [self.eos_token_id]
+
+ if token_ids_1 is None:
+ return len(token_ids_0 + eos) * [0]
+ return len(token_ids_0 + eos + token_ids_1 + eos) * [0]
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. A sequence has the following format:
+
+ - single sequence: `X `
+ - pair of sequences: `A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ token_ids_0 = self._add_eos_if_not_present(token_ids_0)
+ if token_ids_1 is None:
+ return token_ids_0
+ else:
+ token_ids_1 = self._add_eos_if_not_present(token_ids_1)
+ return token_ids_0 + token_ids_1
+
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ return state
+
+ def __setstate__(self, d):
+ self.__dict__ = d
+
+ # for backward compatibility
+ if not hasattr(self, "sp_model_kwargs"):
+ self.sp_model_kwargs = {}
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(self.vocab_file)
+
+ def tokenize(self, text: "TextInput", **kwargs) -> list[str]:
+ """
+ Converts a string to a list of tokens. If `self.legacy` is set to `False`, a prefix token is added unless the
+ first token is special.
+ """
+ if self.legacy or len(text) == 0:
+ return super().tokenize(text, **kwargs)
+
+ text = text.replace(SPIECE_UNDERLINE, " ")
+ if self.add_prefix_space:
+ text = SPIECE_UNDERLINE + text
+
+ tokens = super().tokenize(text, **kwargs)
+
+ if len(tokens) > 1 and tokens[0] == SPIECE_UNDERLINE and tokens[1] in self.all_special_tokens:
+ tokens = tokens[1:]
+ return tokens
+
+ @property
+ def unk_token_length(self):
+ return len(self.sp_model.encode(str(self.unk_token)))
+
+ def _tokenize(self, text, **kwargs):
+ """
+ Returns a tokenized string.
+
+ We de-activated the `add_dummy_prefix` option, thus the sentencepiece internals will always strip any
+ SPIECE_UNDERLINE. For example: `self.sp_model.encode(f"{SPIECE_UNDERLINE}Hey", out_type = str)` will give
+ `['H', 'e', 'y']` instead of `['▁He', 'y']`. Thus we always encode `f"{unk_token}text"` and strip the
+ `unk_token`. Here is an example with `unk_token = ""` and `unk_token_length = 4`.
+ `self.tokenizer.sp_model.encode(" Hey", out_type = str)[4:]`.
+ """
+ if self.legacy or not text.startswith((SPIECE_UNDERLINE, " ")):
+ return self.sp_model.encode(text, out_type=str)
+
+ # 1. Encode string + prefix ex: " Hey"
+ tokens = self.sp_model.encode(self.unk_token + text, out_type=str)
+ # 2. Remove self.unk_token from ['<','unk','>', '▁Hey']
+ return tokens[self.unk_token_length :] if len(tokens) >= self.unk_token_length else tokens
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.sp_model.piece_to_id(token)
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ token = self.sp_model.IdToPiece(index)
+ return token
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ # since we manually add the prefix space, we have to remove it when decoding
+ if tokens[0].startswith(SPIECE_UNDERLINE) and self.add_prefix_space:
+ tokens[0] = tokens[0][1:]
+
+ current_sub_tokens = []
+ out_string = ""
+ prev_is_special = False
+ for token in tokens:
+ # make sure that special tokens are not decoded using sentencepiece model
+ if token in self.all_special_tokens:
+ if not prev_is_special:
+ out_string += " "
+ out_string += self.sp_model.decode(current_sub_tokens) + token
+ prev_is_special = True
+ current_sub_tokens = []
+ else:
+ current_sub_tokens.append(token)
+ prev_is_special = False
+ out_string += self.sp_model.decode(current_sub_tokens)
+ return out_string.strip()
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ elif not os.path.isfile(self.vocab_file):
+ with open(out_vocab_file, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["T5Tokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/tokenization_t5_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/tokenization_t5_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..bdba1a7928c8a9ef240aa6a6f694ca44e66e8c4a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5/tokenization_t5_fast.py
@@ -0,0 +1,233 @@
+# coding=utf-8
+# Copyright 2018 T5 Authors and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for model T5."""
+
+import os
+import re
+import warnings
+from shutil import copyfile
+from typing import Optional
+
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import is_sentencepiece_available, logging
+
+
+if is_sentencepiece_available():
+ from .tokenization_t5 import T5Tokenizer
+else:
+ T5Tokenizer = None
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "spiece.model", "tokenizer_file": "tokenizer.json"}
+
+
+# TODO(PVP) - this should be removed in Transformers v5
+
+
+class T5TokenizerFast(PreTrainedTokenizerFast):
+ """
+ Construct a "fast" T5 tokenizer (backed by HuggingFace's *tokenizers* library). Based on
+ [Unigram](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=unigram#models).
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ [SentencePiece](https://github.com/google/sentencepiece) file (generally has a *.spm* extension) that
+ contains the vocabulary necessary to instantiate a tokenizer.
+ eos_token (`str`, *optional*, defaults to `""`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ extra_ids (`int`, *optional*, defaults to 100):
+ Add a number of extra ids added to the vocabulary for use as sentinels. These tokens are accessible as
+ "" where "{%d}" is a number between 0 and extra_ids-1. These tokens can be retrieved by
+ calling get_sentinel_tokens method and token ids can be by calling get_sentinel_token_ids method
+ additional_special_tokens (`list[str]`, *optional*):
+ Additional special tokens used by the tokenizer.
+ add_prefix_space (`bool`, *optional*):
+ Whether or not the tokenizer should automatically add a prefix space
+ from_slow (`book`, *optional*, defaults to `False`):
+ Whether or not the tokenizer should be converted from a slow one. If `add_prefix_space` is set, this will be set to `True`.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+ slow_tokenizer_class = T5Tokenizer
+
+ prefix_tokens: list[int] = []
+
+ def __init__(
+ self,
+ vocab_file=None,
+ tokenizer_file=None,
+ eos_token="",
+ unk_token="",
+ pad_token="",
+ extra_ids=100,
+ additional_special_tokens=None,
+ add_prefix_space=None,
+ **kwargs,
+ ):
+ # Add extra_ids to the special token list
+ if additional_special_tokens is not None:
+ extra_tokens = [x for x in additional_special_tokens if "" for i in range(extra_ids)]
+ elif extra_ids > 0 and extra_ids != len(extra_tokens):
+ raise ValueError(
+ f"Both extra_ids ({extra_ids}) and additional_special_tokens ({additional_special_tokens}) are"
+ " provided to T5Tokenizer. In this case the additional_special_tokens must include the extra_ids"
+ " tokens"
+ )
+ else:
+ extra_tokens = [f"" for i in range(extra_ids)]
+ additional_special_tokens = extra_tokens
+
+ if add_prefix_space is not None:
+ logger.warning_once(
+ "You set `add_prefix_space`. The tokenizer needs to be converted from the slow tokenizers"
+ )
+ kwargs["from_slow"] = True
+
+ super().__init__(
+ vocab_file=vocab_file,
+ tokenizer_file=tokenizer_file,
+ eos_token=eos_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ extra_ids=extra_ids,
+ additional_special_tokens=additional_special_tokens,
+ add_prefix_space=add_prefix_space,
+ **kwargs,
+ )
+
+ self.vocab_file = vocab_file
+ self._extra_ids = extra_ids
+
+ @staticmethod
+ def _eventually_correct_t5_max_length(pretrained_model_name_or_path, max_model_length, init_max_model_length):
+ if pretrained_model_name_or_path in T5TokenizerFast.max_model_input_sizes:
+ deprecated_max_model_length = T5TokenizerFast.max_model_input_sizes[pretrained_model_name_or_path]
+ if init_max_model_length is not None and init_max_model_length != max_model_length:
+ return init_max_model_length
+ elif init_max_model_length is None:
+ warnings.warn(
+ "This tokenizer was incorrectly instantiated with a model max length of"
+ f" {deprecated_max_model_length} which will be corrected in Transformers v5.\nFor now, this"
+ " behavior is kept to avoid breaking backwards compatibility when padding/encoding with"
+ " `truncation is True`.\n- Be aware that you SHOULD NOT rely on"
+ f" {pretrained_model_name_or_path} automatically truncating your input to"
+ f" {deprecated_max_model_length} when padding/encoding.\n- If you want to encode/pad to sequences"
+ f" longer than {deprecated_max_model_length} you can either instantiate this tokenizer with"
+ " `model_max_length` or pass `max_length` when encoding/padding.\n- To avoid this warning, please"
+ " instantiate this tokenizer with `model_max_length` set to your preferred value.",
+ FutureWarning,
+ )
+
+ return max_model_length
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not self.can_save_slow_tokenizer:
+ raise ValueError(
+ "Your fast tokenizer does not have the necessary information to save the vocabulary for a slow "
+ "tokenizer."
+ )
+
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ logger.info(f"Copy vocab file to {out_vocab_file}")
+
+ return (out_vocab_file,)
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. A sequence has the following format:
+
+ - single sequence: `X `
+ - pair of sequences: `A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ token_ids_0 = token_ids_0 + [self.eos_token_id]
+ if token_ids_1 is None:
+ return self.prefix_tokens + token_ids_0
+ else:
+ token_ids_1 = token_ids_1 + [self.eos_token_id]
+ return self.prefix_tokens + token_ids_0 + token_ids_1
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. T5 does not make
+ use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+ """
+ eos = [self.eos_token_id]
+
+ if token_ids_1 is None:
+ return len(token_ids_0 + eos) * [0]
+ return len(token_ids_0 + eos + token_ids_1 + eos) * [0]
+
+ def get_sentinel_tokens(self):
+ return list(
+ set(filter(lambda x: bool(re.search(r"", x)) is not None, self.additional_special_tokens))
+ )
+
+ def get_sentinel_token_ids(self):
+ return [self.convert_tokens_to_ids(token) for token in self.get_sentinel_tokens()]
+
+
+__all__ = ["T5TokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..aa8099e267826725cd4e6abcbb5098e4f37cc96e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_encdecgemma2 import *
+ from .modeling_encdecgemma2 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/configuration_t5gemma.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/configuration_t5gemma.py
new file mode 100644
index 0000000000000000000000000000000000000000..86e367413aceeb86207777f26074fa341d7fb717
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/configuration_t5gemma.py
@@ -0,0 +1,331 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/t5gemma/modular_t5gemma.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_t5gemma.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved.
+#
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import Any, Optional, Union
+
+from ...configuration_utils import PretrainedConfig, layer_type_validation
+
+
+class T5GemmaModuleConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`T5GemmaModuleModel`]. It is used to instantiate an T5GemmaModule
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the T5GemmaModule-7B.
+ e.g. [google/t5_gemma_module-7b](https://huggingface.co/google/t5_gemma_module-7b)
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+ Args:
+ vocab_size (`int`, *optional*, defaults to 256000):
+ Vocabulary size of the T5GemmaModule model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`T5GemmaModuleModel`]
+ hidden_size (`int`, *optional*, defaults to 2304):
+ Dimension of the hidden representations.
+ intermediate_size (`int`, *optional*, defaults to 9216):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 26):
+ Number of hidden layers in the Transformer decoder.
+ num_attention_heads (`int`, *optional*, defaults to 8):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ num_key_value_heads (`int`, *optional*, defaults to 4):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details, check out [this
+ paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to
+ `num_attention_heads`.
+ head_dim (`int`, *optional*, defaults to 256):
+ The attention head dimension.
+ hidden_activation (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`):
+ The non-linear activation function (function or string) in the decoder. Will default to `"gelu_pytorch_tanh"`
+ if not specified. `"gelu_pytorch_tanh"` uses an approximation of the `"gelu"` activation function.
+ max_position_embeddings (`int`, *optional*, defaults to 8192):
+ The maximum sequence length that this model might ever be used with.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the rms normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ pad_token_id (`int`, *optional*, defaults to 0):
+ Padding token id.
+ eos_token_id (`int`, *optional*, defaults to 1):
+ End of stream token id.
+ bos_token_id (`int`, *optional*, defaults to 2):
+ Beginning of stream token id.
+ tie_word_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether to tie weight embeddings
+ rope_theta (`float`, *optional*, defaults to 10000.0):
+ The base period of the RoPE embeddings.
+ attention_bias (`bool`, defaults to `False`, *optional*, defaults to `False`):
+ Whether to use a bias in the query, key, value and output projection layers during self-attention.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ query_pre_attn_scalar (`float`, *optional*, defaults to 256):
+ scaling factor used on the attention scores
+ sliding_window (`int`, *optional*, defaults to 4096):
+ in T5GemmaModule, every other layer uses sliding window attention. This is the size of the sliding window.
+ layer_types (`list`, *optional*):
+ Attention pattern for each layer.
+ final_logit_softcapping (`float`, *optional*, defaults to 30.0):
+ scaling factor when applying tanh softcapping on the logits.
+ attn_logit_softcapping (`float`, *optional*, defaults to 50.0):
+ scaling factor when applying tanh softcapping on the attention scores.
+
+ ```python
+ >>> from transformers import T5GemmaModuleModel, T5GemmaModuleConfig
+ >>> # Initializing a T5GemmaModule t5_gemma_module-7b style configuration
+ >>> configuration = T5GemmaModuleConfig()
+ >>> # Initializing a model from the t5_gemma_module-7b style configuration
+ >>> model = T5GemmaModuleModel(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "t5_gemma_module"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ base_model_tp_plan = {
+ "layers.*.self_attn.q_proj": "colwise",
+ "layers.*.self_attn.k_proj": "colwise",
+ "layers.*.self_attn.v_proj": "colwise",
+ "layers.*.self_attn.o_proj": "rowwise",
+ "layers.*.mlp.gate_proj": "colwise",
+ "layers.*.mlp.up_proj": "colwise",
+ "layers.*.mlp.down_proj": "rowwise",
+ }
+ base_model_pp_plan = {
+ "embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "norm": (["hidden_states"], ["hidden_states"]),
+ }
+
+ def __init__(
+ self,
+ vocab_size=256000,
+ hidden_size=2304,
+ intermediate_size=9216,
+ num_hidden_layers=26,
+ num_attention_heads=8,
+ num_key_value_heads=4,
+ head_dim=256,
+ hidden_activation="gelu_pytorch_tanh",
+ max_position_embeddings=8192,
+ initializer_range=0.02,
+ rms_norm_eps=1e-6,
+ use_cache=True,
+ pad_token_id=0,
+ eos_token_id=1,
+ bos_token_id=2,
+ tie_word_embeddings=True,
+ rope_theta=10000.0,
+ attention_bias=False,
+ attention_dropout=0.0,
+ query_pre_attn_scalar=256,
+ sliding_window=4096,
+ layer_types=None,
+ final_logit_softcapping=30.0,
+ attn_logit_softcapping=50.0,
+ **kwargs,
+ ):
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ tie_word_embeddings=tie_word_embeddings,
+ **kwargs,
+ )
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.head_dim = head_dim
+ self.num_key_value_heads = num_key_value_heads
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+ self.use_cache = use_cache
+ self.rope_theta = rope_theta
+ self.attention_bias = attention_bias
+ self.attention_dropout = attention_dropout
+ self.hidden_activation = hidden_activation
+ self.query_pre_attn_scalar = query_pre_attn_scalar
+ self.sliding_window = sliding_window
+ self.final_logit_softcapping = final_logit_softcapping
+ self.attn_logit_softcapping = attn_logit_softcapping
+ self.layer_types = layer_types
+
+ if self.layer_types is None:
+ self.layer_types = [
+ "sliding_attention" if bool((i + 1) % 2) else "full_attention" for i in range(self.num_hidden_layers)
+ ]
+ layer_type_validation(self.layer_types)
+
+
+class T5GemmaConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`T5GemmaModel`]. It is used to instantiate an T5Gemma
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to a hypothetical balanced Gemma2 encoder-decoder model.
+ e.g. [google/t5gemma-2b-2b-prefixlm-it](https://huggingface.co/google/t5gemma-2b-2b-prefixlm-it)
+ ```python
+ >>> from transformers import T5GemmaConfig, T5GemmaModel
+ >>> t5gemma_config = T5GemmaConfig.from_pretrained("google/t5gemma-2b-2b-prefixlm-it")
+ >>> model = T5GemmaModel(t5gemma_config)
+ ```
+ Configuration objects inherit from [PretrainedConfig] and can be used to control the model outputs. Read the
+ documentation from [PretrainedConfig] for more information.
+ Args:
+ encoder (`Union[T5GemmaModuleConfig, dict]`, optional, *optional*):
+ Configuration for the encoder.
+ decoder (`Union[T5GemmaModuleConfig, dict]`, optional, *optional*):
+ Configuration for the decoder.
+ is_encoder_decoder (bool, optional, *optional*, defaults to `True`):
+ Whether the model is used as an encoder/decoder or not.
+ dropout_rate (`float`, *optional*, defaults to 0.0):
+ The ratio for all dropout layers (following T5).
+ classifier_dropout_rate (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for classifier (following T5).
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for attention.
+ tie_word_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether tie input and output embeddings.
+ vocab_size (`int`, *optional*, defaults to 256000):
+ Vocabulary size of the T5Gemma model (the same as Gemma 2).
+ kwargs (additional keyword arguments, optional, *optional*):
+ Will be passed to the PretrainedConfig base class.
+ """
+
+ model_type = "t5gemma"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ base_model_tp_plan = {
+ # encoder
+ "encoder.layers.*.self_attn.q_proj": "colwise",
+ "encoder.layers.*.self_attn.k_proj": "colwise",
+ "encoder.layers.*.self_attn.v_proj": "colwise",
+ "encoder.layers.*.self_attn.o_proj": "rowwise",
+ "encoder.layers.*.mlp.gate_proj": "colwise",
+ "encoder.layers.*.mlp.up_proj": "colwise",
+ "encoder.layers.*.mlp.down_proj": "rowwise",
+ # decoder
+ "decoder.layers.*.self_attn.q_proj": "colwise",
+ "decoder.layers.*.self_attn.k_proj": "colwise",
+ "decoder.layers.*.self_attn.v_proj": "colwise",
+ "decoder.layers.*.self_attn.o_proj": "rowwise",
+ "decoder.layers.*.cross_attn.q_proj": "colwise",
+ "decoder.layers.*.cross_attn.k_proj": "colwise",
+ "decoder.layers.*.cross_attn.v_proj": "colwise",
+ "decoder.layers.*.cross_attn.o_proj": "rowwise",
+ "decoder.layers.*.mlp.gate_proj": "colwise",
+ "decoder.layers.*.mlp.up_proj": "colwise",
+ "decoder.layers.*.mlp.down_proj": "rowwise",
+ }
+ base_model_pp_plan = {
+ # encoder
+ "encoder.embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "encoder.layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "encoder.norm": (["hidden_states"], ["hidden_states"]),
+ # decoder
+ "decoder.embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "decoder.layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "decoder.norm": (["hidden_states"], ["hidden_states"]),
+ }
+
+ def __init__(
+ self,
+ encoder: Optional[Union[T5GemmaModuleConfig, dict[Any, Any]]] = None,
+ decoder: Optional[Union[T5GemmaModuleConfig, dict[Any, Any]]] = None,
+ is_encoder_decoder: bool = True,
+ dropout_rate: float = 0.0,
+ classifier_dropout_rate: float = 0.0,
+ attention_dropout: float = 0.0,
+ tie_word_embeddings: bool = True,
+ vocab_size: int = 256000,
+ **kwargs,
+ ):
+ if isinstance(encoder, dict):
+ encoder = T5GemmaModuleConfig(**encoder)
+ elif encoder is None:
+ encoder = T5GemmaModuleConfig()
+ else:
+ assert isinstance(encoder, T5GemmaModuleConfig), f"{type(encoder)} is not supported."
+
+ if isinstance(decoder, dict):
+ decoder = T5GemmaModuleConfig(**decoder)
+ elif decoder is None:
+ decoder = encoder
+ else:
+ assert isinstance(decoder, T5GemmaModuleConfig), f"{type(decoder)} is not supported."
+
+ encoder = T5GemmaModuleConfig(**encoder.to_dict())
+ decoder = T5GemmaModuleConfig(**decoder.to_dict())
+
+ encoder.is_decoder = False
+ encoder.dropout_rate = dropout_rate
+ encoder.attention_dropout = attention_dropout
+ self.encoder = encoder
+
+ decoder.is_decoder = True
+ decoder.use_cache = True
+ decoder.dropout_rate = dropout_rate
+ decoder.attention_dropout = attention_dropout
+ decoder.cross_attention_hidden_size = encoder.hidden_size
+ self.decoder = decoder
+
+ for special_token_key in ["bos_token_id", "pad_token_id", "eos_token_id"]:
+ if special_token_key not in kwargs:
+ kwargs[special_token_key] = getattr(decoder, special_token_key)
+
+ super().__init__(**kwargs)
+
+ self.is_encoder_decoder = is_encoder_decoder
+ self.use_cache = kwargs.get("use_cache", decoder.use_cache)
+ self.initializer_range = kwargs.get("initializer_range", decoder.initializer_range)
+ self.dropout_rate = dropout_rate
+ self.attention_dropout = attention_dropout
+ self.classifier_dropout_rate = classifier_dropout_rate
+ self.tie_word_embeddings = tie_word_embeddings
+
+ # Used in pipeline generation.
+ self.vocab_size = vocab_size
+
+ def __setattr__(self, key, value):
+ shared_attr_with_submodules = [
+ "output_hidden_states",
+ "output_attentions",
+ "_attn_implementation",
+ "dropout_rate",
+ "attention_dropout",
+ "vocab_size",
+ ]
+
+ if key in shared_attr_with_submodules:
+ setattr(self.encoder, key, value)
+ setattr(self.decoder, key, value)
+ super().__setattr__(key, value)
+
+ def get_text_config(self, *args, **kwargs):
+ # Always return self, regardless of the decoder option.
+ return self
+
+
+__all__ = ["T5GemmaConfig", "T5GemmaModuleConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/modeling_t5gemma.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/modeling_t5gemma.py
new file mode 100644
index 0000000000000000000000000000000000000000..422083fc914c28e9444e4d6f523e4b1bbb156705
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/modeling_t5gemma.py
@@ -0,0 +1,1391 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/t5gemma/modular_t5gemma.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_t5gemma.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved.
+#
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import Callable, Optional, Union
+
+import torch
+import torch.nn as nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, auto_docstring, can_return_tuple, is_torchdynamo_compiling, logging
+from ...utils.deprecation import deprecate_kwarg
+from ...utils.generic import OutputRecorder, check_model_inputs
+from .configuration_t5gemma import T5GemmaConfig, T5GemmaModuleConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class T5GemmaRMSNorm(nn.Module):
+ def __init__(self, dim: int, eps: float = 1e-6):
+ super().__init__()
+ self.eps = eps
+ self.weight = nn.Parameter(torch.zeros(dim))
+
+ def _norm(self, x):
+ return x * torch.rsqrt(x.pow(2).mean(-1, keepdim=True) + self.eps)
+
+ def forward(self, x):
+ output = self._norm(x.float())
+ # Llama does x.to(float16) * w whilst T5Gemma is (x * w).to(float16)
+ # See https://github.com/huggingface/transformers/pull/29402
+ output = output * (1.0 + self.weight.float())
+ return output.type_as(x)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.eps}"
+
+
+class T5GemmaMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False)
+ self.act_fn = ACT2FN[config.hidden_activation]
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(self, x):
+ hidden_states = self.act_fn(self.gate_proj(x)) * self.up_proj(x)
+ hidden_states = self.dropout(hidden_states)
+ down_proj = self.down_proj(hidden_states)
+ return down_proj
+
+
+class T5GemmaRotaryEmbedding(nn.Module):
+ inv_freq: torch.Tensor # fix linting for `register_buffer`
+
+ def __init__(self, config, device=None):
+ super().__init__()
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and isinstance(config.rope_scaling, dict):
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ @torch.no_grad()
+ @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope)
+ def forward(self, x, position_ids):
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device)
+ position_ids_expanded = position_ids[:, None, :].float()
+
+ device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False): # Force float32
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos() * self.attention_scaling
+ sin = emb.sin() * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ dropout: float = 0.0,
+ scaling: Optional[float] = None,
+ softcap: Optional[float] = None,
+ **kwargs,
+) -> tuple[torch.Tensor, torch.Tensor]:
+ if scaling is None:
+ scaling = module.head_dim**-0.5
+
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+
+ if softcap is not None:
+ attn_weights = attn_weights / softcap
+ attn_weights = torch.tanh(attn_weights)
+ attn_weights = attn_weights * softcap
+ if attention_mask is not None: # no matter the length, we just slice it
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ # upcast attention to fp32
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ return attn_output, attn_weights
+
+
+class T5GemmaSelfAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: T5GemmaModuleConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = config.query_pre_attn_scalar**-0.5
+ self.attention_dropout = self.config.attention_dropout
+ # Requied by flash attention: encoder selfattention is non-causal
+ self.is_causal = config.is_decoder
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.k_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+ self.attn_logit_softcapping = self.config.attn_logit_softcapping
+ self.sliding_window = config.sliding_window if config.layer_types[layer_idx] == "sliding_attention" else None
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=self.attention_dropout if self.training else 0.0,
+ scaling=self.scaling,
+ sliding_window=self.sliding_window,
+ softcap=self.attn_logit_softcapping,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class T5GemmaCrossAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: T5GemmaModuleConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = config.query_pre_attn_scalar**-0.5
+ self.attention_dropout = self.config.attention_dropout
+ self.is_causal = False
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+
+ self.k_proj = nn.Linear(
+ config.cross_attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.cross_attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+ self.attn_logit_softcapping = self.config.attn_logit_softcapping
+
+ if config.cross_attention_hidden_size is None:
+ raise ValueError("Cross-attention needs cross_attention_hidden_size to be specified.")
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ encoder_hidden_states: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ if encoder_hidden_states is None:
+ raise ValueError("Encoder hidden state is required for cross attention.")
+
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ curr_past_key_value = past_key_values.cross_attention_cache
+
+ if past_key_values is None or not is_updated:
+ encoder_input_shape = encoder_hidden_states.shape[:-1]
+ encoder_hidden_shape = (*encoder_input_shape, -1, self.head_dim)
+ key_states = self.k_proj(encoder_hidden_states).view(encoder_hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(encoder_hidden_states).view(encoder_hidden_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ key_states, value_states = curr_past_key_value.update(key_states, value_states, self.layer_idx)
+ past_key_values.is_updated[self.layer_idx] = True
+ else:
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=self.attention_dropout if self.training else 0.0,
+ scaling=self.scaling,
+ sliding_window=None,
+ softcap=self.attn_logit_softcapping,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class T5GemmaEncoderLayer(GradientCheckpointingLayer):
+ """Encoder sub-layer."""
+
+ def __init__(self, config, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+ self.config = config
+ self.layer_idx = layer_idx
+ self.attention_type = config.layer_types[layer_idx]
+
+ self.self_attn = T5GemmaSelfAttention(
+ config=config,
+ layer_idx=layer_idx,
+ )
+ self.pre_self_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_self_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ self.mlp = T5GemmaMLP(config)
+ self.pre_feedforward_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_feedforward_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ **kwargs,
+ ) -> tuple[torch.FloatTensor,]:
+ residual = hidden_states
+ hidden_states = self.pre_self_attn_layernorm(hidden_states)
+ hidden_states, _ = self.self_attn(
+ hidden_states=hidden_states,
+ position_embeddings=position_embeddings,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=None,
+ **kwargs,
+ )
+ hidden_states = self.post_self_attn_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.pre_feedforward_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = self.post_feedforward_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+ return hidden_states
+
+
+class T5GemmaDecoderLayer(T5GemmaEncoderLayer):
+ """Decoder sub-layer: an extra cross-attention layer."""
+
+ def __init__(self, config, layer_idx: int):
+ super().__init__(config, layer_idx)
+ self.cross_attn = T5GemmaCrossAttention(config=config, layer_idx=layer_idx)
+ self.pre_cross_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_cross_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> torch.FloatTensor:
+ residual = hidden_states
+ hidden_states = self.pre_self_attn_layernorm(hidden_states)
+ hidden_states, _ = self.self_attn(
+ hidden_states=hidden_states,
+ position_embeddings=position_embeddings,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values.self_attention_cache if past_key_values is not None else None,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+ hidden_states = self.post_self_attn_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.pre_cross_attn_layernorm(hidden_states)
+ hidden_states, _ = self.cross_attn(
+ hidden_states=hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ **kwargs,
+ )
+ hidden_states = self.post_cross_attn_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.pre_feedforward_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = self.post_feedforward_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+ return hidden_states
+
+
+class T5GemmaClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, hidden_size: int, num_labels: int, classifier_dropout_rate: float = 0.0):
+ super().__init__()
+ self.dropout = nn.Dropout(p=classifier_dropout_rate)
+ self.out_proj = nn.Linear(hidden_size, num_labels)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.out_proj(hidden_states)
+ return hidden_states
+
+
+class T5GemmaLMHead(nn.Module):
+ """Head for language modeling (generation) tasks."""
+
+ def __init__(self, hidden_size: int, vocab_size: int, bias: bool = False):
+ super().__init__()
+ self.out_proj = nn.Linear(hidden_size, vocab_size, bias=bias)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ logits = self.out_proj(hidden_states)
+ return logits
+
+
+class T5GemmaAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: T5GemmaConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads)
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.scaling = config.query_pre_attn_scalar**-0.5
+ self.attention_dropout = self.config.attention_dropout
+ self.is_causal = True
+
+ self.q_proj = nn.Linear(
+ config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.k_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.o_proj = nn.Linear(
+ config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias
+ )
+ self.attn_logit_softcapping = self.config.attn_logit_softcapping
+ self.sliding_window = config.sliding_window if config.layer_types[layer_idx] == "sliding_attention" else None
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ # sin and cos are specific to RoPE models; cache_position needed for the static cache
+ cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
+ key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=self.attention_dropout if self.training else 0.0,
+ scaling=self.scaling,
+ sliding_window=self.sliding_window,
+ softcap=self.attn_logit_softcapping,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+@auto_docstring
+class T5GemmaPreTrainedModel(PreTrainedModel):
+ config: T5GemmaConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["T5GemmaBlock"]
+ _skip_keys_device_placement = ["past_key_values"]
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ _can_compile_fullgraph = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": T5GemmaDecoderLayer,
+ "attentions": T5GemmaAttention,
+ }
+
+ def _init_weights(self, module):
+ # TODO: support intialization for encoders and decoders separately(?)
+ super()._init_weights(module)
+ std = self.config.initializer_range
+ if isinstance(module, T5GemmaClassificationHead):
+ scale = module.out_proj.weight.shape[0] ** -0.5
+ module.out_proj.weight.data.normal_(mean=0.0, std=std * scale)
+ if hasattr(module.out_proj, "bias") and module.out_proj.bias is not None:
+ module.out_proj.bias.data.zero_()
+ elif isinstance(module, T5GemmaLMHead):
+ if not self.config.tie_word_embeddings:
+ scale = module.out_proj.weight.shape[0] ** -0.5
+ module.out_proj.weight.data.normal_(mean=0.0, std=std * scale)
+
+ def _shift_right(self, input_ids):
+ """
+ Shifts input_ids to the right, prepends the decoder_start_token_id, and handles
+ pad_token_id replacement for labels that were -100.
+ This is a common preparation step for decoder inputs in sequence-to-sequence models.
+ """
+ decoder_start_token_id = self.config.decoder.bos_token_id
+ pad_token_id = self.config.decoder.pad_token_id
+
+ if decoder_start_token_id is None:
+ raise ValueError("self.model.config.decoder.bos_token_id has to be defined. ")
+
+ # shift inputs to the right
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
+ shifted_input_ids[..., 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.decoder.pad_token_id has to be defined.")
+
+ # Is this T5 specific?
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+def bidirectional_mask_function(attention_mask: Optional[torch.Tensor]) -> Callable:
+ """
+ This creates bidirectional attention mask.
+ """
+
+ def inner_mask(batch_idx: int, head_idx: int, q_idx: int, kv_idx: int) -> bool:
+ if attention_mask is None:
+ return torch.ones((), dtype=torch.bool)
+ return attention_mask[batch_idx, kv_idx].to(torch.bool)
+
+ return inner_mask
+
+
+def sliding_window_bidirectional_mask_function(sliding_window: int) -> Callable:
+ """
+ This creates bidirectional attention mask with sliding window.
+ """
+
+ def inner_mask(batch_idx: int, head_idx: int, q_idx: int, kv_idx: int) -> bool:
+ return (q_idx - sliding_window < kv_idx) & (kv_idx < q_idx + sliding_window)
+
+ return inner_mask
+
+
+def make_default_2d_attention_mask(
+ token_ids: Optional[torch.LongTensor],
+ hidden_states: torch.Tensor,
+ pad_token_id: Optional[int],
+) -> torch.Tensor:
+ """Construct the default attention mask."""
+ if token_ids is not None:
+ if pad_token_id is None:
+ raise ValueError("`pad_token_id` is required for padding information.")
+ attention_mask = (token_ids != pad_token_id).to(hidden_states.device, torch.long)
+ else:
+ attention_mask = torch.ones(
+ (hidden_states.shape[0], hidden_states.shape[1]), device=hidden_states.device, dtype=torch.long
+ )
+ return attention_mask
+
+
+class T5GemmaEncoder(T5GemmaPreTrainedModel):
+ _can_record_outputs = {
+ "attentions": T5GemmaSelfAttention,
+ "hidden_states": T5GemmaEncoderLayer,
+ }
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.norm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.rotary_emb = T5GemmaRotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+
+ self.layers = nn.ModuleList(
+ [T5GemmaEncoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutput:
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ # As we want to pass `past_key_values=None` explicitly everywhere, we need to pop them from kwargs if present
+ kwargs.pop("past_key_values", None)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ cache_position = torch.arange(0, inputs_embeds.shape[1], device=inputs_embeds.device)
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ if attention_mask is None:
+ attention_mask = make_default_2d_attention_mask(input_ids, inputs_embeds, self.config.pad_token_id)
+
+ if not isinstance(self_attn_mask_mapping := attention_mask, dict):
+ mask_kwargs = {
+ "config": self.config,
+ "input_embeds": inputs_embeds,
+ "attention_mask": attention_mask,
+ "cache_position": cache_position,
+ "past_key_values": None,
+ "position_ids": position_ids,
+ }
+ self_attn_mask_mapping = {
+ "full_attention": create_causal_mask(
+ **mask_kwargs,
+ or_mask_function=bidirectional_mask_function(attention_mask),
+ ),
+ "sliding_attention": create_sliding_window_causal_mask(
+ **mask_kwargs,
+ or_mask_function=sliding_window_bidirectional_mask_function(self.config.sliding_window),
+ and_mask_function=bidirectional_mask_function(attention_mask),
+ ),
+ }
+
+ hidden_states = inputs_embeds
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ normalizer = torch.tensor(self.config.hidden_size**0.5, dtype=hidden_states.dtype)
+ hidden_states = hidden_states * normalizer
+ hidden_states = self.dropout(hidden_states)
+
+ for layer_module in self.layers[: self.config.num_hidden_layers]:
+ hidden_states = layer_module(
+ hidden_states,
+ position_embeddings,
+ self_attn_mask_mapping[layer_module.attention_type],
+ position_ids,
+ **kwargs,
+ )
+ hidden_states = self.norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ )
+
+
+class T5GemmaDecoder(T5GemmaEncoder):
+ _can_record_outputs = {
+ "attentions": OutputRecorder(T5GemmaSelfAttention, index=1),
+ "cross_attentions": OutputRecorder(T5GemmaCrossAttention, index=1),
+ "hidden_states": T5GemmaDecoderLayer,
+ }
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.layers = nn.ModuleList(
+ [T5GemmaDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+
+ self.post_init()
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPastAndCrossAttentions:
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+ if encoder_hidden_states is None:
+ raise ValueError("`encoder_hidden_states` must be given in decoder")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if not self.training and use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ if attention_mask is None and past_key_values is None:
+ attention_mask = make_default_2d_attention_mask(input_ids, inputs_embeds, self.config.pad_token_id)
+
+ if not isinstance(self_attn_mask_mapping := attention_mask, dict):
+ mask_kwargs = {
+ "config": self.config,
+ "input_embeds": inputs_embeds,
+ "attention_mask": attention_mask,
+ "cache_position": cache_position,
+ "past_key_values": past_key_values.self_attention_cache if past_key_values is not None else None,
+ "position_ids": position_ids,
+ }
+ self_attn_mask_mapping = {
+ "full_attention": create_causal_mask(**mask_kwargs),
+ "sliding_attention": create_sliding_window_causal_mask(**mask_kwargs),
+ }
+
+ if not isinstance(cross_attn_mask_mapping := encoder_attention_mask, dict):
+ mask_kwargs = {
+ "config": self.config,
+ "input_embeds": encoder_hidden_states,
+ "attention_mask": encoder_attention_mask,
+ "cache_position": cache_position,
+ "past_key_values": None,
+ "position_ids": None,
+ }
+ cross_attn_mask_mapping = {
+ "full_attention": create_causal_mask(
+ **mask_kwargs,
+ or_mask_function=bidirectional_mask_function(encoder_attention_mask),
+ ),
+ }
+
+ hidden_states = inputs_embeds
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ normalizer = torch.tensor(self.config.hidden_size**0.5, dtype=hidden_states.dtype)
+ hidden_states = hidden_states * normalizer
+ hidden_states = self.dropout(hidden_states)
+
+ for layer_module in self.layers[: self.config.num_hidden_layers]:
+ hidden_states = layer_module(
+ hidden_states,
+ position_embeddings,
+ self_attn_mask_mapping[layer_module.attention_type],
+ position_ids,
+ past_key_values,
+ use_cache,
+ cache_position,
+ encoder_hidden_states,
+ cross_attn_mask_mapping["full_attention"],
+ **kwargs,
+ )
+ hidden_states = self.norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ )
+
+
+@auto_docstring
+class T5GemmaModel(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig):
+ super().__init__(config)
+
+ if not config.is_encoder_decoder:
+ raise ValueError("T5GemmaModel only support encoder-decoder modeling. Use `T5GemmaEncoderModel` instead.")
+
+ self.encoder = T5GemmaEncoder(config.encoder)
+ self.decoder = T5GemmaDecoder(config.decoder)
+
+ self.post_init()
+
+ def get_encoder(self):
+ return self.encoder
+
+ def get_input_embeddings(self):
+ return self.encoder.get_input_embeddings()
+
+ def set_input_embeddings(self, new_embeddings):
+ return self.encoder.set_input_embeddings(new_embeddings)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ decoder_inputs_embeds: Optional[torch.Tensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> Seq2SeqModelOutput:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ """
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+
+ encoder_hidden_states = encoder_outputs.last_hidden_state
+
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=attention_mask,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states
+ if kwargs.get("output_hidden_states", False)
+ else (decoder_outputs.last_hidden_state,),
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring
+class T5GemmaEncoderModel(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig):
+ super().__init__(config)
+
+ if config.is_encoder_decoder:
+ raise ValueError("T5GemmaEncoderModel only supports encoder-only model. Use `T5GemmaModel` instead.")
+
+ self.encoder = T5GemmaEncoder(config.encoder)
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.encoder.get_input_embeddings()
+
+ def set_input_embeddings(self, new_embeddings):
+ return self.encoder.set_input_embeddings(new_embeddings)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutput:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+ return encoder_outputs
+
+
+class T5GemmaForConditionalGeneration(T5GemmaPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["model.decoder.embed_tokens.weight", "lm_head.out_proj.weight"]
+ _tp_plan = {"lm_head.out_proj": "colwise_rep"}
+ _pp_plan = {"lm_head.out_proj": (["hidden_states"], ["logits"])}
+
+ def __init__(self, config: T5GemmaConfig):
+ config.is_encoder_decoder = True
+ super().__init__(config)
+
+ self.model = T5GemmaModel(config)
+ self.vocab_size = config.decoder.vocab_size
+ self.lm_head = T5GemmaLMHead(config.decoder.hidden_size, self.vocab_size)
+ self.loss_type = "ForMaskedLM"
+
+ self.post_init()
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.out_proj = new_embeddings
+
+ def get_output_embeddings(self):
+ return self.lm_head.out_proj
+
+ def _tie_weights(self):
+ # Decoder input and output embeddings are tied.
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.lm_head.out_proj, self.get_decoder().get_input_embeddings())
+
+ def get_encoder(self):
+ return self.model.encoder
+
+ def get_decoder(self):
+ return self.model.decoder
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+ """
+ if self.training and self.config._attn_implementation != "eager":
+ msg = (
+ "It is strongly recommended to train T5Gemma models with the `eager` attention implementation "
+ f"instead of `{self.config._attn_implementation}`. Use `eager` with `AutoModelForCausalLM.from_pretrained('', attn_implementation='eager')`."
+ )
+ if is_torchdynamo_compiling():
+ raise ValueError(msg)
+ else:
+ logger.warning_once(msg)
+
+ if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None:
+ # get decoder inputs from shifting lm labels to the right
+ decoder_input_ids = self._shift_right(labels)
+
+ decoder_outputs: Seq2SeqModelOutput = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ hidden_states = decoder_outputs.last_hidden_state
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+ decoder_config = self.get_decoder().config
+ if decoder_config.final_logit_softcapping is not None:
+ logits = logits / decoder_config.final_logit_softcapping
+ logits = torch.tanh(logits)
+ logits = logits * decoder_config.final_logit_softcapping
+
+ loss = None
+ if labels is not None:
+ # Input has right-shifted so we directly perform masked lm loss
+ loss = self.loss_function(logits, labels, self.vocab_size, **kwargs)
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.decoder_hidden_states,
+ decoder_attentions=decoder_outputs.decoder_attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=decoder_outputs.encoder_last_hidden_state,
+ encoder_hidden_states=decoder_outputs.encoder_hidden_states,
+ encoder_attentions=decoder_outputs.encoder_attentions,
+ )
+
+ def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor):
+ return self._shift_right(labels)
+
+
+@auto_docstring
+class T5GemmaForSequenceClassification(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig, is_encoder_decoder: Optional[bool] = None):
+ r"""
+ is_encoder_decoder (`Optional`, *optional*):
+ Whether use encoder_decoder for sequence classification. When set to False, only encoder is used.
+ """
+ if is_encoder_decoder is not None:
+ config.is_encoder_decoder = is_encoder_decoder
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ if config.is_encoder_decoder:
+ self.model = T5GemmaModel(config)
+ else:
+ self.model = T5GemmaEncoderModel(config)
+
+ hidden_size = config.encoder.hidden_size
+ if config.is_encoder_decoder:
+ hidden_size = config.decoder.hidden_size
+
+ classifier_dropout = getattr(config, "classifier_dropout_rate", 0.1)
+ self.score = T5GemmaClassificationHead(hidden_size, self.num_labels, classifier_dropout)
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.set_input_embeddings(value)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.Tensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> SequenceClassifierOutput:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ if self.config.is_encoder_decoder and (input_ids is None and inputs_embeds is not None):
+ raise NotImplementedError(
+ f"Passing input embeddings is currently not supported for {self.__class__.__name__} in encoder-decoder mode."
+ )
+
+ # Following T5, we automatically creates decoder_input_ids from input_ids if no decoder_input_ids are provided
+ if self.config.is_encoder_decoder and (decoder_input_ids is None and decoder_inputs_embeds is None):
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ if self.config.is_encoder_decoder:
+ outputs: Seq2SeqModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_outputs=encoder_outputs,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=False,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.decoder_hidden_states
+ attentions = outputs.decoder_attentions
+ else:
+ outputs: BaseModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.hidden_states
+ attentions = outputs.attentions
+
+ logits = self.score(last_hidden_state)
+
+ if input_ids is not None:
+ batch_size = input_ids.shape[0]
+ else:
+ batch_size = inputs_embeds.shape[0]
+
+ if self.config.pad_token_id is None and batch_size != 1:
+ raise ValueError("Cannot handle batch sizes > 1 if no padding token is defined.")
+ if self.config.pad_token_id is None:
+ last_non_pad_token = -1
+ elif input_ids is not None:
+ # To handle both left- and right- padding, we take the rightmost token that is not equal to pad_token_id
+ non_pad_mask = (input_ids != self.config.pad_token_id).to(logits.device, torch.int32)
+ token_indices = torch.arange(input_ids.shape[-1], device=logits.device, dtype=torch.int32)
+ last_non_pad_token = (token_indices * non_pad_mask).argmax(-1)
+
+ if self.config.is_encoder_decoder:
+ last_non_pad_token += 1 # due to the right shift.
+ last_non_pad_token = torch.clamp(last_non_pad_token, max=decoder_input_ids.shape[-1] - 1)
+ else:
+ last_non_pad_token = -1
+ logger.warning_once(
+ f"{self.__class__.__name__} will not detect padding tokens in `inputs_embeds`. Results may be "
+ "unexpected if using padding tokens in conjunction with `inputs_embeds.`"
+ )
+
+ pooled_logits = logits[torch.arange(batch_size, device=logits.device), last_non_pad_token]
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, pooled_logits=pooled_logits, config=self.config)
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=pooled_logits,
+ hidden_states=hidden_states,
+ attentions=attentions,
+ )
+
+
+@auto_docstring
+class T5GemmaForTokenClassification(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig, is_encoder_decoder: Optional[bool] = None):
+ r"""
+ is_encoder_decoder (`Optional`, *optional*):
+ Whether use encoder_decoder for token classification. When set to False, only encoder is used.
+ """
+ if is_encoder_decoder is not None:
+ config.is_encoder_decoder = is_encoder_decoder
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ if config.is_encoder_decoder:
+ self.model = T5GemmaModel(config)
+ else:
+ self.model = T5GemmaEncoderModel(config)
+
+ hidden_size = config.encoder.hidden_size
+ if config.is_encoder_decoder:
+ hidden_size = config.decoder.hidden_size
+
+ classifier_dropout = getattr(config, "classifier_dropout_rate", 0.1)
+ self.score = T5GemmaClassificationHead(hidden_size, self.num_labels, classifier_dropout)
+
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.set_input_embeddings(value)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.Tensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> TokenClassifierOutput:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ if self.config.is_encoder_decoder and (input_ids is None and inputs_embeds is not None):
+ raise NotImplementedError(
+ f"Passing input embeddings is currently not supported for {self.__class__.__name__} in encoder-decoder mode."
+ )
+
+ if self.config.is_encoder_decoder and (decoder_input_ids is None and decoder_inputs_embeds is None):
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ if self.config.is_encoder_decoder:
+ outputs: Seq2SeqModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_outputs=encoder_outputs,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=False,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.decoder_hidden_states
+ attentions = outputs.decoder_attentions
+ else:
+ outputs: BaseModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.hidden_states
+ attentions = outputs.attentions
+
+ logits = self.score(last_hidden_state)
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits, labels, self.config)
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=hidden_states,
+ attentions=attentions,
+ )
+
+
+__all__ = [
+ "T5GemmaForConditionalGeneration",
+ "T5GemmaModel",
+ "T5GemmaEncoderModel",
+ "T5GemmaPreTrainedModel",
+ "T5GemmaForSequenceClassification",
+ "T5GemmaForTokenClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/modular_t5gemma.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/modular_t5gemma.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef35bb1609e14fe6970d6daf4de56de62c752edc
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/t5gemma/modular_t5gemma.py
@@ -0,0 +1,1250 @@
+# coding=utf-8
+# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved.
+#
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import Any, Callable, Optional, Union
+
+import torch
+import torch.nn as nn
+
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...configuration_utils import PretrainedConfig
+from ...generation import GenerationMixin
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import (
+ TransformersKwargs,
+ auto_docstring,
+ can_return_tuple,
+ is_torchdynamo_compiling,
+ logging,
+)
+from ...utils.deprecation import deprecate_kwarg
+from ...utils.generic import OutputRecorder, check_model_inputs
+from ..gemma2.configuration_gemma2 import Gemma2Config
+from ..gemma2.modeling_gemma2 import (
+ Gemma2Attention,
+ Gemma2MLP,
+ Gemma2PreTrainedModel,
+ Gemma2RMSNorm,
+ Gemma2RotaryEmbedding,
+ create_causal_mask,
+ create_sliding_window_causal_mask,
+ eager_attention_forward,
+)
+
+
+_CHECKPOINT_FOR_DOC = "google/t5gemma-2b-2b-prefixlm-it"
+
+
+logger = logging.get_logger(__name__)
+
+
+class T5GemmaModuleConfig(Gemma2Config):
+ pass
+
+
+class T5GemmaConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`T5GemmaModel`]. It is used to instantiate an T5Gemma
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to a hypothetical balanced Gemma2 encoder-decoder model.
+ e.g. [google/t5gemma-2b-2b-prefixlm-it](https://huggingface.co/google/t5gemma-2b-2b-prefixlm-it)
+ ```python
+ >>> from transformers import T5GemmaConfig, T5GemmaModel
+ >>> t5gemma_config = T5GemmaConfig.from_pretrained("google/t5gemma-2b-2b-prefixlm-it")
+ >>> model = T5GemmaModel(t5gemma_config)
+ ```
+ Configuration objects inherit from [PretrainedConfig] and can be used to control the model outputs. Read the
+ documentation from [PretrainedConfig] for more information.
+ Args:
+ encoder (`Union[T5GemmaModuleConfig, dict]`, optional, *optional*):
+ Configuration for the encoder.
+ decoder (`Union[T5GemmaModuleConfig, dict]`, optional, *optional*):
+ Configuration for the decoder.
+ is_encoder_decoder (bool, optional, *optional*, defaults to `True`):
+ Whether the model is used as an encoder/decoder or not.
+ dropout_rate (`float`, *optional*, defaults to 0.0):
+ The ratio for all dropout layers (following T5).
+ classifier_dropout_rate (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for classifier (following T5).
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for attention.
+ tie_word_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether tie input and output embeddings.
+ vocab_size (`int`, *optional*, defaults to 256000):
+ Vocabulary size of the T5Gemma model (the same as Gemma 2).
+ kwargs (additional keyword arguments, optional, *optional*):
+ Will be passed to the PretrainedConfig base class.
+ """
+
+ model_type = "t5gemma"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ base_model_tp_plan = {
+ # encoder
+ "encoder.layers.*.self_attn.q_proj": "colwise",
+ "encoder.layers.*.self_attn.k_proj": "colwise",
+ "encoder.layers.*.self_attn.v_proj": "colwise",
+ "encoder.layers.*.self_attn.o_proj": "rowwise",
+ "encoder.layers.*.mlp.gate_proj": "colwise",
+ "encoder.layers.*.mlp.up_proj": "colwise",
+ "encoder.layers.*.mlp.down_proj": "rowwise",
+ # decoder
+ "decoder.layers.*.self_attn.q_proj": "colwise",
+ "decoder.layers.*.self_attn.k_proj": "colwise",
+ "decoder.layers.*.self_attn.v_proj": "colwise",
+ "decoder.layers.*.self_attn.o_proj": "rowwise",
+ "decoder.layers.*.cross_attn.q_proj": "colwise",
+ "decoder.layers.*.cross_attn.k_proj": "colwise",
+ "decoder.layers.*.cross_attn.v_proj": "colwise",
+ "decoder.layers.*.cross_attn.o_proj": "rowwise",
+ "decoder.layers.*.mlp.gate_proj": "colwise",
+ "decoder.layers.*.mlp.up_proj": "colwise",
+ "decoder.layers.*.mlp.down_proj": "rowwise",
+ }
+ base_model_pp_plan = {
+ # encoder
+ "encoder.embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "encoder.layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "encoder.norm": (["hidden_states"], ["hidden_states"]),
+ # decoder
+ "decoder.embed_tokens": (["input_ids"], ["inputs_embeds"]),
+ "decoder.layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
+ "decoder.norm": (["hidden_states"], ["hidden_states"]),
+ }
+
+ def __init__(
+ self,
+ encoder: Optional[Union[T5GemmaModuleConfig, dict[Any, Any]]] = None,
+ decoder: Optional[Union[T5GemmaModuleConfig, dict[Any, Any]]] = None,
+ is_encoder_decoder: bool = True,
+ dropout_rate: float = 0.0,
+ classifier_dropout_rate: float = 0.0,
+ attention_dropout: float = 0.0,
+ tie_word_embeddings: bool = True,
+ vocab_size: int = 256000,
+ **kwargs,
+ ):
+ if isinstance(encoder, dict):
+ encoder = T5GemmaModuleConfig(**encoder)
+ elif encoder is None:
+ encoder = T5GemmaModuleConfig()
+ else:
+ assert isinstance(encoder, T5GemmaModuleConfig), f"{type(encoder)} is not supported."
+
+ if isinstance(decoder, dict):
+ decoder = T5GemmaModuleConfig(**decoder)
+ elif decoder is None:
+ decoder = encoder
+ else:
+ assert isinstance(decoder, T5GemmaModuleConfig), f"{type(decoder)} is not supported."
+
+ encoder = T5GemmaModuleConfig(**encoder.to_dict())
+ decoder = T5GemmaModuleConfig(**decoder.to_dict())
+
+ encoder.is_decoder = False
+ encoder.dropout_rate = dropout_rate
+ encoder.attention_dropout = attention_dropout
+ self.encoder = encoder
+
+ decoder.is_decoder = True
+ decoder.use_cache = True
+ decoder.dropout_rate = dropout_rate
+ decoder.attention_dropout = attention_dropout
+ decoder.cross_attention_hidden_size = encoder.hidden_size
+ self.decoder = decoder
+
+ for special_token_key in ["bos_token_id", "pad_token_id", "eos_token_id"]:
+ if special_token_key not in kwargs:
+ kwargs[special_token_key] = getattr(decoder, special_token_key)
+
+ super().__init__(**kwargs)
+
+ self.is_encoder_decoder = is_encoder_decoder
+ self.use_cache = kwargs.get("use_cache", decoder.use_cache)
+ self.initializer_range = kwargs.get("initializer_range", decoder.initializer_range)
+ self.dropout_rate = dropout_rate
+ self.attention_dropout = attention_dropout
+ self.classifier_dropout_rate = classifier_dropout_rate
+ self.tie_word_embeddings = tie_word_embeddings
+
+ # Used in pipeline generation.
+ self.vocab_size = vocab_size
+
+ def __setattr__(self, key, value):
+ shared_attr_with_submodules = [
+ "output_hidden_states",
+ "output_attentions",
+ "_attn_implementation",
+ "dropout_rate",
+ "attention_dropout",
+ "vocab_size",
+ ]
+
+ if key in shared_attr_with_submodules:
+ setattr(self.encoder, key, value)
+ setattr(self.decoder, key, value)
+ super().__setattr__(key, value)
+
+ def get_text_config(self, *args, **kwargs):
+ # Always return self, regardless of the decoder option.
+ return self
+
+
+class T5GemmaRMSNorm(Gemma2RMSNorm):
+ pass
+
+
+class T5GemmaMLP(Gemma2MLP):
+ def __init__(self, config):
+ super().__init__(config)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(self, x):
+ hidden_states = self.act_fn(self.gate_proj(x)) * self.up_proj(x)
+ hidden_states = self.dropout(hidden_states)
+ down_proj = self.down_proj(hidden_states)
+ return down_proj
+
+
+class T5GemmaRotaryEmbedding(Gemma2RotaryEmbedding):
+ def __init__(self, config, device=None):
+ super().__init__(config, device)
+
+
+class T5GemmaSelfAttention(Gemma2Attention):
+ def __init__(self, config: T5GemmaModuleConfig, layer_idx: int):
+ super().__init__(config, layer_idx)
+ # Requied by flash attention: encoder selfattention is non-causal
+ self.is_causal = config.is_decoder
+
+
+class T5GemmaCrossAttention(Gemma2Attention):
+ def __init__(self, config: T5GemmaModuleConfig, layer_idx: int):
+ super().__init__(config, layer_idx)
+ del self.sliding_window
+ self.is_causal = False
+
+ if config.cross_attention_hidden_size is None:
+ raise ValueError("Cross-attention needs cross_attention_hidden_size to be specified.")
+
+ self.k_proj = nn.Linear(
+ config.cross_attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+ self.v_proj = nn.Linear(
+ config.cross_attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias
+ )
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ encoder_hidden_states: Optional[torch.Tensor],
+ past_key_values: Optional[Cache] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ if encoder_hidden_states is None:
+ raise ValueError("Encoder hidden state is required for cross attention.")
+
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ curr_past_key_value = past_key_values.cross_attention_cache
+
+ if past_key_values is None or not is_updated:
+ encoder_input_shape = encoder_hidden_states.shape[:-1]
+ encoder_hidden_shape = (*encoder_input_shape, -1, self.head_dim)
+ key_states = self.k_proj(encoder_hidden_states).view(encoder_hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(encoder_hidden_states).view(encoder_hidden_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ key_states, value_states = curr_past_key_value.update(key_states, value_states, self.layer_idx)
+ past_key_values.is_updated[self.layer_idx] = True
+ else:
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=self.attention_dropout if self.training else 0.0,
+ scaling=self.scaling,
+ sliding_window=None,
+ softcap=self.attn_logit_softcapping,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+def bidirectional_mask_function(attention_mask: Optional[torch.Tensor]) -> Callable:
+ """
+ This creates bidirectional attention mask.
+ """
+
+ def inner_mask(batch_idx: int, head_idx: int, q_idx: int, kv_idx: int) -> bool:
+ if attention_mask is None:
+ return torch.ones((), dtype=torch.bool)
+ return attention_mask[batch_idx, kv_idx].to(torch.bool)
+
+ return inner_mask
+
+
+def sliding_window_bidirectional_mask_function(sliding_window: int) -> Callable:
+ """
+ This creates bidirectional attention mask with sliding window.
+ """
+
+ def inner_mask(batch_idx: int, head_idx: int, q_idx: int, kv_idx: int) -> bool:
+ return (q_idx - sliding_window < kv_idx) & (kv_idx < q_idx + sliding_window)
+
+ return inner_mask
+
+
+class T5GemmaEncoderLayer(GradientCheckpointingLayer):
+ """Encoder sub-layer."""
+
+ def __init__(self, config, layer_idx: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+ self.config = config
+ self.layer_idx = layer_idx
+ self.attention_type = config.layer_types[layer_idx]
+
+ self.self_attn = T5GemmaSelfAttention(
+ config=config,
+ layer_idx=layer_idx,
+ )
+ self.pre_self_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_self_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ self.mlp = T5GemmaMLP(config)
+ self.pre_feedforward_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_feedforward_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ **kwargs,
+ ) -> tuple[torch.FloatTensor,]:
+ residual = hidden_states
+ hidden_states = self.pre_self_attn_layernorm(hidden_states)
+ hidden_states, _ = self.self_attn(
+ hidden_states=hidden_states,
+ position_embeddings=position_embeddings,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=None,
+ **kwargs,
+ )
+ hidden_states = self.post_self_attn_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.pre_feedforward_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = self.post_feedforward_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+ return hidden_states
+
+
+class T5GemmaDecoderLayer(T5GemmaEncoderLayer):
+ """Decoder sub-layer: an extra cross-attention layer."""
+
+ def __init__(self, config, layer_idx: int):
+ super().__init__(config, layer_idx)
+ self.cross_attn = T5GemmaCrossAttention(config=config, layer_idx=layer_idx)
+ self.pre_cross_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.post_cross_attn_layernorm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_embeddings: tuple[torch.Tensor, torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> torch.FloatTensor:
+ residual = hidden_states
+ hidden_states = self.pre_self_attn_layernorm(hidden_states)
+ hidden_states, _ = self.self_attn(
+ hidden_states=hidden_states,
+ position_embeddings=position_embeddings,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values.self_attention_cache if past_key_values is not None else None,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+ hidden_states = self.post_self_attn_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.pre_cross_attn_layernorm(hidden_states)
+ hidden_states, _ = self.cross_attn(
+ hidden_states=hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ **kwargs,
+ )
+ hidden_states = self.post_cross_attn_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.pre_feedforward_layernorm(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = self.post_feedforward_layernorm(hidden_states)
+ hidden_states = residual + self.dropout(hidden_states)
+ return hidden_states
+
+
+class T5GemmaClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, hidden_size: int, num_labels: int, classifier_dropout_rate: float = 0.0):
+ super().__init__()
+ self.dropout = nn.Dropout(p=classifier_dropout_rate)
+ self.out_proj = nn.Linear(hidden_size, num_labels)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.out_proj(hidden_states)
+ return hidden_states
+
+
+class T5GemmaLMHead(nn.Module):
+ """Head for language modeling (generation) tasks."""
+
+ def __init__(self, hidden_size: int, vocab_size: int, bias: bool = False):
+ super().__init__()
+ self.out_proj = nn.Linear(hidden_size, vocab_size, bias=bias)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ logits = self.out_proj(hidden_states)
+ return logits
+
+
+@auto_docstring
+class T5GemmaPreTrainedModel(Gemma2PreTrainedModel):
+ config: T5GemmaConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["T5GemmaBlock"]
+
+ def _init_weights(self, module):
+ # TODO: support intialization for encoders and decoders separately(?)
+ PreTrainedModel._init_weights(self, module)
+ std = self.config.initializer_range
+ if isinstance(module, T5GemmaClassificationHead):
+ scale = module.out_proj.weight.shape[0] ** -0.5
+ module.out_proj.weight.data.normal_(mean=0.0, std=std * scale)
+ if hasattr(module.out_proj, "bias") and module.out_proj.bias is not None:
+ module.out_proj.bias.data.zero_()
+ elif isinstance(module, T5GemmaLMHead):
+ if not self.config.tie_word_embeddings:
+ scale = module.out_proj.weight.shape[0] ** -0.5
+ module.out_proj.weight.data.normal_(mean=0.0, std=std * scale)
+
+ def _shift_right(self, input_ids):
+ """
+ Shifts input_ids to the right, prepends the decoder_start_token_id, and handles
+ pad_token_id replacement for labels that were -100.
+ This is a common preparation step for decoder inputs in sequence-to-sequence models.
+ """
+ decoder_start_token_id = self.config.decoder.bos_token_id
+ pad_token_id = self.config.decoder.pad_token_id
+
+ if decoder_start_token_id is None:
+ raise ValueError("self.model.config.decoder.bos_token_id has to be defined. ")
+
+ # shift inputs to the right
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
+ shifted_input_ids[..., 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.decoder.pad_token_id has to be defined.")
+
+ # Is this T5 specific?
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+def make_default_2d_attention_mask(
+ token_ids: Optional[torch.LongTensor],
+ hidden_states: torch.Tensor,
+ pad_token_id: Optional[int],
+) -> torch.Tensor:
+ """Construct the default attention mask."""
+ if token_ids is not None:
+ if pad_token_id is None:
+ raise ValueError("`pad_token_id` is required for padding information.")
+ attention_mask = (token_ids != pad_token_id).to(hidden_states.device, torch.long)
+ else:
+ attention_mask = torch.ones(
+ (hidden_states.shape[0], hidden_states.shape[1]), device=hidden_states.device, dtype=torch.long
+ )
+ return attention_mask
+
+
+class T5GemmaEncoder(T5GemmaPreTrainedModel):
+ _can_record_outputs = {
+ "attentions": T5GemmaSelfAttention,
+ "hidden_states": T5GemmaEncoderLayer,
+ }
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ self.norm = T5GemmaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.rotary_emb = T5GemmaRotaryEmbedding(config=config)
+ self.gradient_checkpointing = False
+
+ self.layers = nn.ModuleList(
+ [T5GemmaEncoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutput:
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ # As we want to pass `past_key_values=None` explicitly everywhere, we need to pop them from kwargs if present
+ kwargs.pop("past_key_values", None)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ cache_position = torch.arange(0, inputs_embeds.shape[1], device=inputs_embeds.device)
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ if attention_mask is None:
+ attention_mask = make_default_2d_attention_mask(input_ids, inputs_embeds, self.config.pad_token_id)
+
+ if not isinstance(self_attn_mask_mapping := attention_mask, dict):
+ mask_kwargs = {
+ "config": self.config,
+ "input_embeds": inputs_embeds,
+ "attention_mask": attention_mask,
+ "cache_position": cache_position,
+ "past_key_values": None,
+ "position_ids": position_ids,
+ }
+ self_attn_mask_mapping = {
+ "full_attention": create_causal_mask(
+ **mask_kwargs,
+ or_mask_function=bidirectional_mask_function(attention_mask),
+ ),
+ "sliding_attention": create_sliding_window_causal_mask(
+ **mask_kwargs,
+ or_mask_function=sliding_window_bidirectional_mask_function(self.config.sliding_window),
+ and_mask_function=bidirectional_mask_function(attention_mask),
+ ),
+ }
+
+ hidden_states = inputs_embeds
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ normalizer = torch.tensor(self.config.hidden_size**0.5, dtype=hidden_states.dtype)
+ hidden_states = hidden_states * normalizer
+ hidden_states = self.dropout(hidden_states)
+
+ for layer_module in self.layers[: self.config.num_hidden_layers]:
+ hidden_states = layer_module(
+ hidden_states,
+ position_embeddings,
+ self_attn_mask_mapping[layer_module.attention_type],
+ position_ids,
+ **kwargs,
+ )
+ hidden_states = self.norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ )
+
+
+class T5GemmaDecoder(T5GemmaEncoder):
+ _can_record_outputs = {
+ "attentions": OutputRecorder(T5GemmaSelfAttention, index=1),
+ "cross_attentions": OutputRecorder(T5GemmaCrossAttention, index=1),
+ "hidden_states": T5GemmaDecoderLayer,
+ }
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.layers = nn.ModuleList(
+ [T5GemmaDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+
+ self.post_init()
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPastAndCrossAttentions:
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+ if encoder_hidden_states is None:
+ raise ValueError("`encoder_hidden_states` must be given in decoder")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if not self.training and use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if cache_position is None:
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ if attention_mask is None and past_key_values is None:
+ attention_mask = make_default_2d_attention_mask(input_ids, inputs_embeds, self.config.pad_token_id)
+
+ if not isinstance(self_attn_mask_mapping := attention_mask, dict):
+ mask_kwargs = {
+ "config": self.config,
+ "input_embeds": inputs_embeds,
+ "attention_mask": attention_mask,
+ "cache_position": cache_position,
+ "past_key_values": past_key_values.self_attention_cache if past_key_values is not None else None,
+ "position_ids": position_ids,
+ }
+ self_attn_mask_mapping = {
+ "full_attention": create_causal_mask(**mask_kwargs),
+ "sliding_attention": create_sliding_window_causal_mask(**mask_kwargs),
+ }
+
+ if not isinstance(cross_attn_mask_mapping := encoder_attention_mask, dict):
+ mask_kwargs = {
+ "config": self.config,
+ "input_embeds": encoder_hidden_states,
+ "attention_mask": encoder_attention_mask,
+ "cache_position": cache_position,
+ "past_key_values": None,
+ "position_ids": None,
+ }
+ cross_attn_mask_mapping = {
+ "full_attention": create_causal_mask(
+ **mask_kwargs,
+ or_mask_function=bidirectional_mask_function(encoder_attention_mask),
+ ),
+ }
+
+ hidden_states = inputs_embeds
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+
+ normalizer = torch.tensor(self.config.hidden_size**0.5, dtype=hidden_states.dtype)
+ hidden_states = hidden_states * normalizer
+ hidden_states = self.dropout(hidden_states)
+
+ for layer_module in self.layers[: self.config.num_hidden_layers]:
+ hidden_states = layer_module(
+ hidden_states,
+ position_embeddings,
+ self_attn_mask_mapping[layer_module.attention_type],
+ position_ids,
+ past_key_values,
+ use_cache,
+ cache_position,
+ encoder_hidden_states,
+ cross_attn_mask_mapping["full_attention"],
+ **kwargs,
+ )
+ hidden_states = self.norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ )
+
+
+@auto_docstring
+class T5GemmaModel(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig):
+ super().__init__(config)
+
+ if not config.is_encoder_decoder:
+ raise ValueError("T5GemmaModel only support encoder-decoder modeling. Use `T5GemmaEncoderModel` instead.")
+
+ self.encoder = T5GemmaEncoder(config.encoder)
+ self.decoder = T5GemmaDecoder(config.decoder)
+
+ self.post_init()
+
+ def get_encoder(self):
+ return self.encoder
+
+ def get_input_embeddings(self):
+ return self.encoder.get_input_embeddings()
+
+ def set_input_embeddings(self, new_embeddings):
+ return self.encoder.set_input_embeddings(new_embeddings)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ decoder_inputs_embeds: Optional[torch.Tensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> Seq2SeqModelOutput:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ """
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+
+ encoder_hidden_states = encoder_outputs.last_hidden_state
+
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=attention_mask,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states
+ if kwargs.get("output_hidden_states", False)
+ else (decoder_outputs.last_hidden_state,),
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring
+class T5GemmaEncoderModel(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig):
+ super().__init__(config)
+
+ if config.is_encoder_decoder:
+ raise ValueError("T5GemmaEncoderModel only supports encoder-only model. Use `T5GemmaModel` instead.")
+
+ self.encoder = T5GemmaEncoder(config.encoder)
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.encoder.get_input_embeddings()
+
+ def set_input_embeddings(self, new_embeddings):
+ return self.encoder.set_input_embeddings(new_embeddings)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutput:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+ return encoder_outputs
+
+
+class T5GemmaForConditionalGeneration(T5GemmaPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["model.decoder.embed_tokens.weight", "lm_head.out_proj.weight"]
+ _tp_plan = {"lm_head.out_proj": "colwise_rep"}
+ _pp_plan = {"lm_head.out_proj": (["hidden_states"], ["logits"])}
+
+ def __init__(self, config: T5GemmaConfig):
+ config.is_encoder_decoder = True
+ super().__init__(config)
+
+ self.model = T5GemmaModel(config)
+ self.vocab_size = config.decoder.vocab_size
+ self.lm_head = T5GemmaLMHead(config.decoder.hidden_size, self.vocab_size)
+ self.loss_type = "ForMaskedLM"
+
+ self.post_init()
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.out_proj = new_embeddings
+
+ def get_output_embeddings(self):
+ return self.lm_head.out_proj
+
+ def _tie_weights(self):
+ # Decoder input and output embeddings are tied.
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.lm_head.out_proj, self.get_decoder().get_input_embeddings())
+
+ def get_encoder(self):
+ return self.model.encoder
+
+ def get_decoder(self):
+ return self.model.decoder
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+ """
+ if self.training and self.config._attn_implementation != "eager":
+ msg = (
+ "It is strongly recommended to train T5Gemma models with the `eager` attention implementation "
+ f"instead of `{self.config._attn_implementation}`. Use `eager` with `AutoModelForCausalLM.from_pretrained('', attn_implementation='eager')`."
+ )
+ if is_torchdynamo_compiling():
+ raise ValueError(msg)
+ else:
+ logger.warning_once(msg)
+
+ if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None:
+ # get decoder inputs from shifting lm labels to the right
+ decoder_input_ids = self._shift_right(labels)
+
+ decoder_outputs: Seq2SeqModelOutput = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ hidden_states = decoder_outputs.last_hidden_state
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+ decoder_config = self.get_decoder().config
+ if decoder_config.final_logit_softcapping is not None:
+ logits = logits / decoder_config.final_logit_softcapping
+ logits = torch.tanh(logits)
+ logits = logits * decoder_config.final_logit_softcapping
+
+ loss = None
+ if labels is not None:
+ # Input has right-shifted so we directly perform masked lm loss
+ loss = self.loss_function(logits, labels, self.vocab_size, **kwargs)
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.decoder_hidden_states,
+ decoder_attentions=decoder_outputs.decoder_attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=decoder_outputs.encoder_last_hidden_state,
+ encoder_hidden_states=decoder_outputs.encoder_hidden_states,
+ encoder_attentions=decoder_outputs.encoder_attentions,
+ )
+
+ def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor):
+ return self._shift_right(labels)
+
+
+@auto_docstring
+class T5GemmaForSequenceClassification(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig, is_encoder_decoder: Optional[bool] = None):
+ r"""
+ is_encoder_decoder (`Optional`, *optional*):
+ Whether use encoder_decoder for sequence classification. When set to False, only encoder is used.
+ """
+ if is_encoder_decoder is not None:
+ config.is_encoder_decoder = is_encoder_decoder
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ if config.is_encoder_decoder:
+ self.model = T5GemmaModel(config)
+ else:
+ self.model = T5GemmaEncoderModel(config)
+
+ hidden_size = config.encoder.hidden_size
+ if config.is_encoder_decoder:
+ hidden_size = config.decoder.hidden_size
+
+ classifier_dropout = getattr(config, "classifier_dropout_rate", 0.1)
+ self.score = T5GemmaClassificationHead(hidden_size, self.num_labels, classifier_dropout)
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.set_input_embeddings(value)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.Tensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> SequenceClassifierOutput:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ if self.config.is_encoder_decoder and (input_ids is None and inputs_embeds is not None):
+ raise NotImplementedError(
+ f"Passing input embeddings is currently not supported for {self.__class__.__name__} in encoder-decoder mode."
+ )
+
+ # Following T5, we automatically creates decoder_input_ids from input_ids if no decoder_input_ids are provided
+ if self.config.is_encoder_decoder and (decoder_input_ids is None and decoder_inputs_embeds is None):
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ if self.config.is_encoder_decoder:
+ outputs: Seq2SeqModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_outputs=encoder_outputs,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=False,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.decoder_hidden_states
+ attentions = outputs.decoder_attentions
+ else:
+ outputs: BaseModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.hidden_states
+ attentions = outputs.attentions
+
+ logits = self.score(last_hidden_state)
+
+ if input_ids is not None:
+ batch_size = input_ids.shape[0]
+ else:
+ batch_size = inputs_embeds.shape[0]
+
+ if self.config.pad_token_id is None and batch_size != 1:
+ raise ValueError("Cannot handle batch sizes > 1 if no padding token is defined.")
+ if self.config.pad_token_id is None:
+ last_non_pad_token = -1
+ elif input_ids is not None:
+ # To handle both left- and right- padding, we take the rightmost token that is not equal to pad_token_id
+ non_pad_mask = (input_ids != self.config.pad_token_id).to(logits.device, torch.int32)
+ token_indices = torch.arange(input_ids.shape[-1], device=logits.device, dtype=torch.int32)
+ last_non_pad_token = (token_indices * non_pad_mask).argmax(-1)
+
+ if self.config.is_encoder_decoder:
+ last_non_pad_token += 1 # due to the right shift.
+ last_non_pad_token = torch.clamp(last_non_pad_token, max=decoder_input_ids.shape[-1] - 1)
+ else:
+ last_non_pad_token = -1
+ logger.warning_once(
+ f"{self.__class__.__name__} will not detect padding tokens in `inputs_embeds`. Results may be "
+ "unexpected if using padding tokens in conjunction with `inputs_embeds.`"
+ )
+
+ pooled_logits = logits[torch.arange(batch_size, device=logits.device), last_non_pad_token]
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, pooled_logits=pooled_logits, config=self.config)
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=pooled_logits,
+ hidden_states=hidden_states,
+ attentions=attentions,
+ )
+
+
+@auto_docstring
+class T5GemmaForTokenClassification(T5GemmaPreTrainedModel):
+ def __init__(self, config: T5GemmaConfig, is_encoder_decoder: Optional[bool] = None):
+ r"""
+ is_encoder_decoder (`Optional`, *optional*):
+ Whether use encoder_decoder for token classification. When set to False, only encoder is used.
+ """
+ if is_encoder_decoder is not None:
+ config.is_encoder_decoder = is_encoder_decoder
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ if config.is_encoder_decoder:
+ self.model = T5GemmaModel(config)
+ else:
+ self.model = T5GemmaEncoderModel(config)
+
+ hidden_size = config.encoder.hidden_size
+ if config.is_encoder_decoder:
+ hidden_size = config.decoder.hidden_size
+
+ classifier_dropout = getattr(config, "classifier_dropout_rate", 0.1)
+ self.score = T5GemmaClassificationHead(hidden_size, self.num_labels, classifier_dropout)
+
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.set_input_embeddings(value)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.Tensor] = None,
+ decoder_position_ids: Optional[torch.LongTensor] = None,
+ encoder_outputs: Optional[BaseModelOutput] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> TokenClassifierOutput:
+ r"""
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, decoder_sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.decoder.n_positions - 1]`. [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ if self.config.is_encoder_decoder and (input_ids is None and inputs_embeds is not None):
+ raise NotImplementedError(
+ f"Passing input embeddings is currently not supported for {self.__class__.__name__} in encoder-decoder mode."
+ )
+
+ if self.config.is_encoder_decoder and (decoder_input_ids is None and decoder_inputs_embeds is None):
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ if self.config.is_encoder_decoder:
+ outputs: Seq2SeqModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_outputs=encoder_outputs,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=False,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.decoder_hidden_states
+ attentions = outputs.decoder_attentions
+ else:
+ outputs: BaseModelOutput = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ inputs_embeds=inputs_embeds,
+ **kwargs,
+ )
+ last_hidden_state = outputs.last_hidden_state
+ hidden_states = outputs.hidden_states
+ attentions = outputs.attentions
+
+ logits = self.score(last_hidden_state)
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits, labels, self.config)
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=hidden_states,
+ attentions=attentions,
+ )
+
+
+__all__ = [
+ "T5GemmaConfig",
+ "T5GemmaModuleConfig",
+ "T5GemmaForConditionalGeneration",
+ "T5GemmaModel",
+ "T5GemmaEncoderModel",
+ "T5GemmaPreTrainedModel", # noqa: F822
+ "T5GemmaForSequenceClassification",
+ "T5GemmaForTokenClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..8ebd1da6fdaeea49c47590e03c86474733265baa
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_table_transformer import *
+ from .modeling_table_transformer import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/configuration_table_transformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/configuration_table_transformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..32eed6ce0df168c0f6a71c0bd30d19f42d47729d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/configuration_table_transformer.py
@@ -0,0 +1,287 @@
+# coding=utf-8
+# Copyright The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Table Transformer model configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from packaging import version
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+from ...utils.backbone_utils import verify_backbone_config_arguments
+from ..auto import CONFIG_MAPPING
+
+
+logger = logging.get_logger(__name__)
+
+
+class TableTransformerConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TableTransformerModel`]. It is used to
+ instantiate a Table Transformer model according to the specified arguments, defining the model architecture.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the Table Transformer
+ [microsoft/table-transformer-detection](https://huggingface.co/microsoft/table-transformer-detection) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ use_timm_backbone (`bool`, *optional*, defaults to `True`):
+ Whether or not to use the `timm` library for the backbone. If set to `False`, will use the [`AutoBackbone`]
+ API.
+ backbone_config (`PretrainedConfig` or `dict`, *optional*):
+ The configuration of the backbone model. Only used in case `use_timm_backbone` is set to `False` in which
+ case it will default to `ResNetConfig()`.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ num_queries (`int`, *optional*, defaults to 100):
+ Number of object queries, i.e. detection slots. This is the maximal number of objects
+ [`TableTransformerModel`] can detect in a single image. For COCO, we recommend 100 queries.
+ d_model (`int`, *optional*, defaults to 256):
+ Dimension of the layers.
+ encoder_layers (`int`, *optional*, defaults to 6):
+ Number of encoder layers.
+ decoder_layers (`int`, *optional*, defaults to 6):
+ Number of decoder layers.
+ encoder_attention_heads (`int`, *optional*, defaults to 8):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ decoder_attention_heads (`int`, *optional*, defaults to 8):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ decoder_ffn_dim (`int`, *optional*, defaults to 2048):
+ Dimension of the "intermediate" (often named feed-forward) layer in decoder.
+ encoder_ffn_dim (`int`, *optional*, defaults to 2048):
+ Dimension of the "intermediate" (often named feed-forward) layer in decoder.
+ activation_function (`str` or `function`, *optional*, defaults to `"relu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for activations inside the fully connected layer.
+ init_std (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ init_xavier_std (`float`, *optional*, defaults to 1):
+ The scaling factor used for the Xavier initialization gain in the HM Attention map module.
+ encoder_layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ decoder_layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the decoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ auxiliary_loss (`bool`, *optional*, defaults to `False`):
+ Whether auxiliary decoding losses (loss at each decoder layer) are to be used.
+ position_embedding_type (`str`, *optional*, defaults to `"sine"`):
+ Type of position embeddings to be used on top of the image features. One of `"sine"` or `"learned"`.
+ backbone (`str`, *optional*):
+ Name of backbone to use when `backbone_config` is `None`. If `use_pretrained_backbone` is `True`, this
+ will load the corresponding pretrained weights from the timm or transformers library. If `use_pretrained_backbone`
+ is `False`, this loads the backbone's config and uses that to initialize the backbone with random weights.
+ use_pretrained_backbone (`bool`, *optional*, `True`):
+ Whether to use pretrained weights for the backbone.
+ backbone_kwargs (`dict`, *optional*):
+ Keyword arguments to be passed to AutoBackbone when loading from a checkpoint
+ e.g. `{'out_indices': (0, 1, 2, 3)}`. Cannot be specified if `backbone_config` is set.
+ dilation (`bool`, *optional*, defaults to `False`):
+ Whether to replace stride with dilation in the last convolutional block (DC5). Only supported when
+ `use_timm_backbone` = `True`.
+ class_cost (`float`, *optional*, defaults to 1):
+ Relative weight of the classification error in the Hungarian matching cost.
+ bbox_cost (`float`, *optional*, defaults to 5):
+ Relative weight of the L1 error of the bounding box coordinates in the Hungarian matching cost.
+ giou_cost (`float`, *optional*, defaults to 2):
+ Relative weight of the generalized IoU loss of the bounding box in the Hungarian matching cost.
+ mask_loss_coefficient (`float`, *optional*, defaults to 1):
+ Relative weight of the Focal loss in the panoptic segmentation loss.
+ dice_loss_coefficient (`float`, *optional*, defaults to 1):
+ Relative weight of the DICE/F-1 loss in the panoptic segmentation loss.
+ bbox_loss_coefficient (`float`, *optional*, defaults to 5):
+ Relative weight of the L1 bounding box loss in the object detection loss.
+ giou_loss_coefficient (`float`, *optional*, defaults to 2):
+ Relative weight of the generalized IoU loss in the object detection loss.
+ eos_coefficient (`float`, *optional*, defaults to 0.1):
+ Relative classification weight of the 'no-object' class in the object detection loss.
+
+ Examples:
+
+ ```python
+ >>> from transformers import TableTransformerModel, TableTransformerConfig
+
+ >>> # Initializing a Table Transformer microsoft/table-transformer-detection style configuration
+ >>> configuration = TableTransformerConfig()
+
+ >>> # Initializing a model from the microsoft/table-transformer-detection style configuration
+ >>> model = TableTransformerModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "table-transformer"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {
+ "hidden_size": "d_model",
+ "num_attention_heads": "encoder_attention_heads",
+ }
+
+ # Copied from transformers.models.detr.configuration_detr.DetrConfig.__init__
+ def __init__(
+ self,
+ use_timm_backbone=True,
+ backbone_config=None,
+ num_channels=3,
+ num_queries=100,
+ encoder_layers=6,
+ encoder_ffn_dim=2048,
+ encoder_attention_heads=8,
+ decoder_layers=6,
+ decoder_ffn_dim=2048,
+ decoder_attention_heads=8,
+ encoder_layerdrop=0.0,
+ decoder_layerdrop=0.0,
+ is_encoder_decoder=True,
+ activation_function="relu",
+ d_model=256,
+ dropout=0.1,
+ attention_dropout=0.0,
+ activation_dropout=0.0,
+ init_std=0.02,
+ init_xavier_std=1.0,
+ auxiliary_loss=False,
+ position_embedding_type="sine",
+ backbone="resnet50",
+ use_pretrained_backbone=True,
+ backbone_kwargs=None,
+ dilation=False,
+ class_cost=1,
+ bbox_cost=5,
+ giou_cost=2,
+ mask_loss_coefficient=1,
+ dice_loss_coefficient=1,
+ bbox_loss_coefficient=5,
+ giou_loss_coefficient=2,
+ eos_coefficient=0.1,
+ **kwargs,
+ ):
+ # We default to values which were previously hard-coded in the model. This enables configurability of the config
+ # while keeping the default behavior the same.
+ if use_timm_backbone and backbone_kwargs is None:
+ backbone_kwargs = {}
+ if dilation:
+ backbone_kwargs["output_stride"] = 16
+ backbone_kwargs["out_indices"] = [1, 2, 3, 4]
+ backbone_kwargs["in_chans"] = num_channels
+ # Backwards compatibility
+ elif not use_timm_backbone and backbone in (None, "resnet50"):
+ if backbone_config is None:
+ logger.info("`backbone_config` is `None`. Initializing the config with the default `ResNet` backbone.")
+ backbone_config = CONFIG_MAPPING["resnet"](out_features=["stage4"])
+ elif isinstance(backbone_config, dict):
+ backbone_model_type = backbone_config.get("model_type")
+ config_class = CONFIG_MAPPING[backbone_model_type]
+ backbone_config = config_class.from_dict(backbone_config)
+ backbone = None
+ # set timm attributes to None
+ dilation = None
+
+ verify_backbone_config_arguments(
+ use_timm_backbone=use_timm_backbone,
+ use_pretrained_backbone=use_pretrained_backbone,
+ backbone=backbone,
+ backbone_config=backbone_config,
+ backbone_kwargs=backbone_kwargs,
+ )
+
+ self.use_timm_backbone = use_timm_backbone
+ self.backbone_config = backbone_config
+ self.num_channels = num_channels
+ self.num_queries = num_queries
+ self.d_model = d_model
+ self.encoder_ffn_dim = encoder_ffn_dim
+ self.encoder_layers = encoder_layers
+ self.encoder_attention_heads = encoder_attention_heads
+ self.decoder_ffn_dim = decoder_ffn_dim
+ self.decoder_layers = decoder_layers
+ self.decoder_attention_heads = decoder_attention_heads
+ self.dropout = dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.activation_function = activation_function
+ self.init_std = init_std
+ self.init_xavier_std = init_xavier_std
+ self.encoder_layerdrop = encoder_layerdrop
+ self.decoder_layerdrop = decoder_layerdrop
+ self.num_hidden_layers = encoder_layers
+ self.auxiliary_loss = auxiliary_loss
+ self.position_embedding_type = position_embedding_type
+ self.backbone = backbone
+ self.use_pretrained_backbone = use_pretrained_backbone
+ self.backbone_kwargs = backbone_kwargs
+ self.dilation = dilation
+ # Hungarian matcher
+ self.class_cost = class_cost
+ self.bbox_cost = bbox_cost
+ self.giou_cost = giou_cost
+ # Loss coefficients
+ self.mask_loss_coefficient = mask_loss_coefficient
+ self.dice_loss_coefficient = dice_loss_coefficient
+ self.bbox_loss_coefficient = bbox_loss_coefficient
+ self.giou_loss_coefficient = giou_loss_coefficient
+ self.eos_coefficient = eos_coefficient
+ super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs)
+
+ @property
+ def num_attention_heads(self) -> int:
+ return self.encoder_attention_heads
+
+ @property
+ def hidden_size(self) -> int:
+ return self.d_model
+
+ @property
+ def sub_configs(self):
+ return (
+ {"backbone_config": type(self.backbone_config)}
+ if getattr(self, "backbone_config", None) is not None
+ else {}
+ )
+
+
+# Copied from transformers.models.detr.configuration_detr.DetrOnnxConfig
+class TableTransformerOnnxConfig(OnnxConfig):
+ torch_onnx_minimum_version = version.parse("1.11")
+
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ return OrderedDict(
+ [
+ ("pixel_values", {0: "batch", 1: "num_channels", 2: "height", 3: "width"}),
+ ("pixel_mask", {0: "batch"}),
+ ]
+ )
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 1e-5
+
+ @property
+ def default_onnx_opset(self) -> int:
+ return 12
+
+
+__all__ = ["TableTransformerConfig", "TableTransformerOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/modeling_table_transformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/modeling_table_transformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..d55ea67400755faec5ad051b4950eb1189eb596b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/table_transformer/modeling_table_transformer.py
@@ -0,0 +1,1330 @@
+# coding=utf-8
+# Copyright 2022 Microsoft Research and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Table Transformer model."""
+
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+from torch import Tensor, nn
+
+from ...activations import ACT2FN
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithCrossAttentions, Seq2SeqModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import (
+ ModelOutput,
+ auto_docstring,
+ is_timm_available,
+ logging,
+ requires_backends,
+)
+from ...utils.backbone_utils import load_backbone
+from .configuration_table_transformer import TableTransformerConfig
+
+
+if is_timm_available():
+ from timm import create_model
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for outputs of the TABLE_TRANSFORMER decoder. This class adds one attribute to BaseModelOutputWithCrossAttentions,
+ namely an optional stack of intermediate decoder activations, i.e. the output of each decoder layer, each of them
+ gone through a layernorm. This is useful when training the model with auxiliary decoding losses.
+ """
+)
+# Copied from transformers.models.detr.modeling_detr.DetrDecoderOutput with DETR->TABLE_TRANSFORMER,Detr->TableTransformer
+class TableTransformerDecoderOutput(BaseModelOutputWithCrossAttentions):
+ r"""
+ cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`):
+ Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax,
+ used to compute the weighted average in the cross-attention heads.
+ intermediate_hidden_states (`torch.FloatTensor` of shape `(config.decoder_layers, batch_size, num_queries, hidden_size)`, *optional*, returned when `config.auxiliary_loss=True`):
+ Intermediate decoder activations, i.e. the output of each decoder layer, each of them gone through a
+ layernorm.
+ """
+
+ intermediate_hidden_states: Optional[torch.FloatTensor] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for outputs of the TABLE_TRANSFORMER encoder-decoder model. This class adds one attribute to Seq2SeqModelOutput,
+ namely an optional stack of intermediate decoder activations, i.e. the output of each decoder layer, each of them
+ gone through a layernorm. This is useful when training the model with auxiliary decoding losses.
+ """
+)
+# Copied from transformers.models.detr.modeling_detr.DetrModelOutput with DETR->TABLE_TRANSFORMER,Detr->TableTransformer
+class TableTransformerModelOutput(Seq2SeqModelOutput):
+ r"""
+ last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the decoder of the model.
+ intermediate_hidden_states (`torch.FloatTensor` of shape `(config.decoder_layers, batch_size, sequence_length, hidden_size)`, *optional*, returned when `config.auxiliary_loss=True`):
+ Intermediate decoder activations, i.e. the output of each decoder layer, each of them gone through a
+ layernorm.
+ """
+
+ intermediate_hidden_states: Optional[torch.FloatTensor] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`TableTransformerForObjectDetection`].
+ """
+)
+# Copied from transformers.models.detr.modeling_detr.DetrObjectDetectionOutput with Detr->TableTransformer,DetrImageProcessor->DetrImageProcessor
+class TableTransformerObjectDetectionOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` are provided)):
+ Total loss as a linear combination of a negative log-likehood (cross-entropy) for class prediction and a
+ bounding box loss. The latter is defined as a linear combination of the L1 loss and the generalized
+ scale-invariant IoU loss.
+ loss_dict (`Dict`, *optional*):
+ A dictionary containing the individual losses. Useful for logging.
+ logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`):
+ Classification logits (including no-object) for all queries.
+ pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`):
+ Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These
+ values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding
+ possible padding). You can use [`~TableTransformerImageProcessor.post_process_object_detection`] to retrieve the
+ unnormalized bounding boxes.
+ auxiliary_outputs (`list[Dict]`, *optional*):
+ Optional, only returned when auxiliary losses are activated (i.e. `config.auxiliary_loss` is set to `True`)
+ and labels are provided. It is a list of dictionaries containing the two above keys (`logits` and
+ `pred_boxes`) for each decoder layer.
+ last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the decoder of the model.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ loss_dict: Optional[dict] = None
+ logits: Optional[torch.FloatTensor] = None
+ pred_boxes: Optional[torch.FloatTensor] = None
+ auxiliary_outputs: Optional[list[dict]] = None
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ decoder_hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ decoder_attentions: Optional[tuple[torch.FloatTensor]] = None
+ cross_attentions: Optional[tuple[torch.FloatTensor]] = None
+ encoder_last_hidden_state: Optional[torch.FloatTensor] = None
+ encoder_hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ encoder_attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrFrozenBatchNorm2d with Detr->TableTransformer
+class TableTransformerFrozenBatchNorm2d(nn.Module):
+ """
+ BatchNorm2d where the batch statistics and the affine parameters are fixed.
+
+ Copy-paste from torchvision.misc.ops with added eps before rqsrt, without which any other models than
+ torchvision.models.resnet[18,34,50,101] produce nans.
+ """
+
+ def __init__(self, n):
+ super().__init__()
+ self.register_buffer("weight", torch.ones(n))
+ self.register_buffer("bias", torch.zeros(n))
+ self.register_buffer("running_mean", torch.zeros(n))
+ self.register_buffer("running_var", torch.ones(n))
+
+ def _load_from_state_dict(
+ self, state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs
+ ):
+ num_batches_tracked_key = prefix + "num_batches_tracked"
+ if num_batches_tracked_key in state_dict:
+ del state_dict[num_batches_tracked_key]
+
+ super()._load_from_state_dict(
+ state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs
+ )
+
+ def forward(self, x):
+ # move reshapes to the beginning
+ # to make it user-friendly
+ weight = self.weight.reshape(1, -1, 1, 1)
+ bias = self.bias.reshape(1, -1, 1, 1)
+ running_var = self.running_var.reshape(1, -1, 1, 1)
+ running_mean = self.running_mean.reshape(1, -1, 1, 1)
+ epsilon = 1e-5
+ scale = weight * (running_var + epsilon).rsqrt()
+ bias = bias - running_mean * scale
+ return x * scale + bias
+
+
+# Copied from transformers.models.detr.modeling_detr.replace_batch_norm with Detr->TableTransformer
+def replace_batch_norm(model):
+ r"""
+ Recursively replace all `torch.nn.BatchNorm2d` with `TableTransformerFrozenBatchNorm2d`.
+
+ Args:
+ model (torch.nn.Module):
+ input model
+ """
+ for name, module in model.named_children():
+ if isinstance(module, nn.BatchNorm2d):
+ new_module = TableTransformerFrozenBatchNorm2d(module.num_features)
+
+ if module.weight.device != torch.device("meta"):
+ new_module.weight.data.copy_(module.weight)
+ new_module.bias.data.copy_(module.bias)
+ new_module.running_mean.data.copy_(module.running_mean)
+ new_module.running_var.data.copy_(module.running_var)
+
+ model._modules[name] = new_module
+
+ if len(list(module.children())) > 0:
+ replace_batch_norm(module)
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrConvEncoder with Detr->TableTransformer
+class TableTransformerConvEncoder(nn.Module):
+ """
+ Convolutional backbone, using either the AutoBackbone API or one from the timm library.
+
+ nn.BatchNorm2d layers are replaced by TableTransformerFrozenBatchNorm2d as defined above.
+
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.config = config
+
+ # For backwards compatibility we have to use the timm library directly instead of the AutoBackbone API
+ if config.use_timm_backbone:
+ # We default to values which were previously hard-coded. This enables configurability from the config
+ # using backbone arguments, while keeping the default behavior the same.
+ requires_backends(self, ["timm"])
+ kwargs = getattr(config, "backbone_kwargs", {})
+ kwargs = {} if kwargs is None else kwargs.copy()
+ out_indices = kwargs.pop("out_indices", (1, 2, 3, 4))
+ num_channels = kwargs.pop("in_chans", config.num_channels)
+ if config.dilation:
+ kwargs["output_stride"] = kwargs.get("output_stride", 16)
+ backbone = create_model(
+ config.backbone,
+ pretrained=config.use_pretrained_backbone,
+ features_only=True,
+ out_indices=out_indices,
+ in_chans=num_channels,
+ **kwargs,
+ )
+ else:
+ backbone = load_backbone(config)
+
+ # replace batch norm by frozen batch norm
+ with torch.no_grad():
+ replace_batch_norm(backbone)
+ self.model = backbone
+ self.intermediate_channel_sizes = (
+ self.model.feature_info.channels() if config.use_timm_backbone else self.model.channels
+ )
+
+ backbone_model_type = None
+ if config.backbone is not None:
+ backbone_model_type = config.backbone
+ elif config.backbone_config is not None:
+ backbone_model_type = config.backbone_config.model_type
+ else:
+ raise ValueError("Either `backbone` or `backbone_config` should be provided in the config")
+
+ if "resnet" in backbone_model_type:
+ for name, parameter in self.model.named_parameters():
+ if config.use_timm_backbone:
+ if "layer2" not in name and "layer3" not in name and "layer4" not in name:
+ parameter.requires_grad_(False)
+ else:
+ if "stage.1" not in name and "stage.2" not in name and "stage.3" not in name:
+ parameter.requires_grad_(False)
+
+ def forward(self, pixel_values: torch.Tensor, pixel_mask: torch.Tensor):
+ # send pixel_values through the model to get list of feature maps
+ features = self.model(pixel_values) if self.config.use_timm_backbone else self.model(pixel_values).feature_maps
+
+ out = []
+ for feature_map in features:
+ # downsample pixel_mask to match shape of corresponding feature_map
+ mask = nn.functional.interpolate(pixel_mask[None].float(), size=feature_map.shape[-2:]).to(torch.bool)[0]
+ out.append((feature_map, mask))
+ return out
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrConvModel with Detr->TableTransformer
+class TableTransformerConvModel(nn.Module):
+ """
+ This module adds 2D position embeddings to all intermediate feature maps of the convolutional encoder.
+ """
+
+ def __init__(self, conv_encoder, position_embedding):
+ super().__init__()
+ self.conv_encoder = conv_encoder
+ self.position_embedding = position_embedding
+
+ def forward(self, pixel_values, pixel_mask):
+ # send pixel_values and pixel_mask through backbone to get list of (feature_map, pixel_mask) tuples
+ out = self.conv_encoder(pixel_values, pixel_mask)
+ pos = []
+ for feature_map, mask in out:
+ # position encoding
+ pos.append(self.position_embedding(feature_map, mask).to(feature_map.dtype))
+
+ return out, pos
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrSinePositionEmbedding with Detr->TableTransformer
+class TableTransformerSinePositionEmbedding(nn.Module):
+ """
+ This is a more standard version of the position embedding, very similar to the one used by the Attention is all you
+ need paper, generalized to work on images.
+ """
+
+ def __init__(self, embedding_dim=64, temperature=10000, normalize=False, scale=None):
+ super().__init__()
+ self.embedding_dim = embedding_dim
+ self.temperature = temperature
+ self.normalize = normalize
+ if scale is not None and normalize is False:
+ raise ValueError("normalize should be True if scale is passed")
+ if scale is None:
+ scale = 2 * math.pi
+ self.scale = scale
+
+ def forward(self, pixel_values, pixel_mask):
+ if pixel_mask is None:
+ raise ValueError("No pixel mask provided")
+ y_embed = pixel_mask.cumsum(1, dtype=torch.float32)
+ x_embed = pixel_mask.cumsum(2, dtype=torch.float32)
+ if self.normalize:
+ y_embed = y_embed / (y_embed[:, -1:, :] + 1e-6) * self.scale
+ x_embed = x_embed / (x_embed[:, :, -1:] + 1e-6) * self.scale
+
+ dim_t = torch.arange(self.embedding_dim, dtype=torch.int64, device=pixel_values.device).float()
+ dim_t = self.temperature ** (2 * torch.div(dim_t, 2, rounding_mode="floor") / self.embedding_dim)
+
+ pos_x = x_embed[:, :, :, None] / dim_t
+ pos_y = y_embed[:, :, :, None] / dim_t
+ pos_x = torch.stack((pos_x[:, :, :, 0::2].sin(), pos_x[:, :, :, 1::2].cos()), dim=4).flatten(3)
+ pos_y = torch.stack((pos_y[:, :, :, 0::2].sin(), pos_y[:, :, :, 1::2].cos()), dim=4).flatten(3)
+ pos = torch.cat((pos_y, pos_x), dim=3).permute(0, 3, 1, 2)
+ return pos
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrLearnedPositionEmbedding with Detr->TableTransformer
+class TableTransformerLearnedPositionEmbedding(nn.Module):
+ """
+ This module learns positional embeddings up to a fixed maximum size.
+ """
+
+ def __init__(self, embedding_dim=256):
+ super().__init__()
+ self.row_embeddings = nn.Embedding(50, embedding_dim)
+ self.column_embeddings = nn.Embedding(50, embedding_dim)
+
+ def forward(self, pixel_values, pixel_mask=None):
+ height, width = pixel_values.shape[-2:]
+ width_values = torch.arange(width, device=pixel_values.device)
+ height_values = torch.arange(height, device=pixel_values.device)
+ x_emb = self.column_embeddings(width_values)
+ y_emb = self.row_embeddings(height_values)
+ pos = torch.cat([x_emb.unsqueeze(0).repeat(height, 1, 1), y_emb.unsqueeze(1).repeat(1, width, 1)], dim=-1)
+ pos = pos.permute(2, 0, 1)
+ pos = pos.unsqueeze(0)
+ pos = pos.repeat(pixel_values.shape[0], 1, 1, 1)
+ return pos
+
+
+# Copied from transformers.models.detr.modeling_detr.build_position_encoding with Detr->TableTransformer
+def build_position_encoding(config):
+ n_steps = config.d_model // 2
+ if config.position_embedding_type == "sine":
+ # TODO find a better way of exposing other arguments
+ position_embedding = TableTransformerSinePositionEmbedding(n_steps, normalize=True)
+ elif config.position_embedding_type == "learned":
+ position_embedding = TableTransformerLearnedPositionEmbedding(n_steps)
+ else:
+ raise ValueError(f"Not supported {config.position_embedding_type}")
+
+ return position_embedding
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrAttention with DETR->TABLE_TRANSFORMER,Detr->TableTransformer
+class TableTransformerAttention(nn.Module):
+ """
+ Multi-headed attention from 'Attention Is All You Need' paper.
+
+ Here, we add position embeddings to the queries and keys (as explained in the TABLE_TRANSFORMER paper).
+ """
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ bias: bool = True,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ if self.head_dim * num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ def _shape(self, tensor: torch.Tensor, seq_len: int, batch_size: int):
+ return tensor.view(batch_size, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
+
+ def with_pos_embed(self, tensor: torch.Tensor, object_queries: Optional[Tensor]):
+ return tensor if object_queries is None else tensor + object_queries
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ object_queries: Optional[torch.Tensor] = None,
+ key_value_states: Optional[torch.Tensor] = None,
+ spatial_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ batch_size, target_len, embed_dim = hidden_states.size()
+
+ # add position embeddings to the hidden states before projecting to queries and keys
+ if object_queries is not None:
+ hidden_states_original = hidden_states
+ hidden_states = self.with_pos_embed(hidden_states, object_queries)
+
+ # add key-value position embeddings to the key value states
+ if spatial_position_embeddings is not None:
+ key_value_states_original = key_value_states
+ key_value_states = self.with_pos_embed(key_value_states, spatial_position_embeddings)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+ # get key, value proj
+ if is_cross_attention:
+ # cross_attentions
+ key_states = self._shape(self.k_proj(key_value_states), -1, batch_size)
+ value_states = self._shape(self.v_proj(key_value_states_original), -1, batch_size)
+ else:
+ # self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, batch_size)
+ value_states = self._shape(self.v_proj(hidden_states_original), -1, batch_size)
+
+ proj_shape = (batch_size * self.num_heads, -1, self.head_dim)
+ query_states = self._shape(query_states, target_len, batch_size).view(*proj_shape)
+ key_states = key_states.view(*proj_shape)
+ value_states = value_states.view(*proj_shape)
+
+ source_len = key_states.size(1)
+
+ attn_weights = torch.bmm(query_states, key_states.transpose(1, 2))
+
+ if attn_weights.size() != (batch_size * self.num_heads, target_len, source_len):
+ raise ValueError(
+ f"Attention weights should be of size {(batch_size * self.num_heads, target_len, source_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ if attention_mask is not None:
+ if attention_mask.size() != (batch_size, 1, target_len, source_len):
+ raise ValueError(
+ f"Attention mask should be of size {(batch_size, 1, target_len, source_len)}, but is"
+ f" {attention_mask.size()}"
+ )
+ if attention_mask.dtype == torch.bool:
+ attention_mask = torch.zeros_like(attention_mask, dtype=attn_weights.dtype).masked_fill_(
+ attention_mask, -torch.inf
+ )
+ attn_weights = attn_weights.view(batch_size, self.num_heads, target_len, source_len) + attention_mask
+ attn_weights = attn_weights.view(batch_size * self.num_heads, target_len, source_len)
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if output_attentions:
+ # this operation is a bit awkward, but it's required to
+ # make sure that attn_weights keeps its gradient.
+ # In order to do so, attn_weights have to reshaped
+ # twice and have to be reused in the following
+ attn_weights_reshaped = attn_weights.view(batch_size, self.num_heads, target_len, source_len)
+ attn_weights = attn_weights_reshaped.view(batch_size * self.num_heads, target_len, source_len)
+ else:
+ attn_weights_reshaped = None
+
+ attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ attn_output = torch.bmm(attn_probs, value_states)
+
+ if attn_output.size() != (batch_size * self.num_heads, target_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(batch_size, self.num_heads, target_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.view(batch_size, self.num_heads, target_len, self.head_dim)
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(batch_size, target_len, embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights_reshaped
+
+
+class TableTransformerEncoderLayer(nn.Module):
+ # Copied from transformers.models.detr.modeling_detr.DetrEncoderLayer.__init__ with Detr->TableTransformer
+ def __init__(self, config: TableTransformerConfig):
+ super().__init__()
+ self.embed_dim = config.d_model
+ self.self_attn = TableTransformerAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.encoder_attention_heads,
+ dropout=config.attention_dropout,
+ )
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+ self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim)
+ self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ object_queries: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative
+ values.
+ object_queries (`torch.FloatTensor`, *optional*): object queries, to be added to hidden_states.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ object_queries=object_queries,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ hidden_states = residual + hidden_states
+
+ if self.training:
+ if torch.isinf(hidden_states).any() or torch.isnan(hidden_states).any():
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class TableTransformerDecoderLayer(GradientCheckpointingLayer):
+ # Copied from transformers.models.detr.modeling_detr.DetrDecoderLayer.__init__ with Detr->TableTransformer
+ def __init__(self, config: TableTransformerConfig):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = TableTransformerAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ )
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.encoder_attn = TableTransformerAttention(
+ self.embed_dim,
+ config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim)
+ self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ object_queries: Optional[torch.Tensor] = None,
+ query_position_embeddings: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ):
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative
+ values.
+ object_queries (`torch.FloatTensor`, *optional*):
+ object queries that are added to the queries and keys
+ in the cross-attention layer.
+ query_position_embeddings (`torch.FloatTensor`, *optional*):
+ object queries that are added to the queries and keys
+ in the self-attention layer.
+ encoder_hidden_states (`torch.FloatTensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size
+ `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative
+ values.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ object_queries=query_position_embeddings,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ object_queries=query_position_embeddings,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ spatial_position_embeddings=object_queries,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ # Fully Connected
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+@auto_docstring
+class TableTransformerPreTrainedModel(PreTrainedModel):
+ config: TableTransformerConfig
+ base_model_prefix = "model"
+ main_input_name = "pixel_values"
+ _no_split_modules = [
+ r"TableTransformerConvEncoder",
+ r"TableTransformerEncoderLayer",
+ r"TableTransformerDecoderLayer",
+ ]
+
+ def _init_weights(self, module):
+ std = self.config.init_std
+
+ if isinstance(module, TableTransformerLearnedPositionEmbedding):
+ nn.init.uniform_(module.row_embeddings.weight)
+ nn.init.uniform_(module.column_embeddings.weight)
+ if isinstance(module, (nn.Linear, nn.Conv2d, nn.BatchNorm2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+class TableTransformerEncoder(TableTransformerPreTrainedModel):
+ """
+ Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a
+ [`TableTransformerEncoderLayer`].
+
+ The encoder updates the flattened feature map through multiple self-attention layers.
+
+ Small tweak for Table Transformer:
+
+ - object_queries are added to the forward pass.
+
+ Args:
+ config: TableTransformerConfig
+ """
+
+ def __init__(self, config: TableTransformerConfig):
+ super().__init__(config)
+
+ self.dropout = config.dropout
+ self.layerdrop = config.encoder_layerdrop
+
+ self.layers = nn.ModuleList([TableTransformerEncoderLayer(config) for _ in range(config.encoder_layers)])
+
+ self.layernorm = nn.LayerNorm(config.d_model)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ inputs_embeds=None,
+ attention_mask=None,
+ object_queries=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Flattened feature map (output of the backbone + projection layer) that is passed to the encoder.
+
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding pixel features. Mask values selected in `[0, 1]`:
+
+ - 1 for pixel features that are real (i.e. **not masked**),
+ - 0 for pixel features that are padding (i.e. **masked**).
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ object_queries (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Position embeddings that are added to the queries and keys in each self-attention layer.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ hidden_states = inputs_embeds
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ # expand attention_mask
+ if attention_mask is not None:
+ # [batch_size, seq_len] -> [batch_size, 1, target_seq_len, source_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ for encoder_layer in self.layers:
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ to_drop = False
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop: # skip the layer
+ to_drop = True
+
+ if to_drop:
+ layer_outputs = (None, None)
+ else:
+ # we add object_queries as extra input to the encoder_layer
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ object_queries=object_queries,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ hidden_states = self.layernorm(hidden_states)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrDecoder with DETR->TABLE_TRANSFORMER,Detr->TableTransformer
+class TableTransformerDecoder(TableTransformerPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`TableTransformerDecoderLayer`].
+
+ The decoder updates the query embeddings through multiple self-attention and cross-attention layers.
+
+ Some small tweaks for TABLE_TRANSFORMER:
+
+ - object_queries and query_position_embeddings are added to the forward pass.
+ - if self.config.auxiliary_loss is set to True, also returns a stack of activations from all decoding layers.
+
+ Args:
+ config: TableTransformerConfig
+ """
+
+ def __init__(self, config: TableTransformerConfig):
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.decoder_layerdrop
+
+ self.layers = nn.ModuleList([TableTransformerDecoderLayer(config) for _ in range(config.decoder_layers)])
+ # in TABLE_TRANSFORMER, the decoder uses layernorm after the last decoder layer output
+ self.layernorm = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ inputs_embeds=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ object_queries=None,
+ query_position_embeddings=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ The query embeddings that are passed into the decoder.
+
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on certain queries. Mask values selected in `[0, 1]`:
+
+ - 1 for queries that are **not masked**,
+ - 0 for queries that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding pixel_values of the encoder. Mask values selected
+ in `[0, 1]`:
+
+ - 1 for pixels that are real (i.e. **not masked**),
+ - 0 for pixels that are padding (i.e. **masked**).
+
+ object_queries (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Object queries that are added to the queries and keys in each cross-attention layer.
+ query_position_embeddings (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`):
+ , *optional*): Position embeddings that are added to the values and keys in each self-attention layer.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if inputs_embeds is not None:
+ hidden_states = inputs_embeds
+ input_shape = inputs_embeds.size()[:-1]
+
+ combined_attention_mask = None
+
+ if attention_mask is not None and combined_attention_mask is not None:
+ # [batch_size, seq_len] -> [batch_size, 1, target_seq_len, source_seq_len]
+ combined_attention_mask = combined_attention_mask + _prepare_4d_attention_mask(
+ attention_mask, inputs_embeds.dtype, tgt_len=input_shape[-1]
+ )
+
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ # [batch_size, seq_len] -> [batch_size, 1, target_seq_len, source_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(
+ encoder_attention_mask, inputs_embeds.dtype, tgt_len=input_shape[-1]
+ )
+
+ # optional intermediate hidden states
+ intermediate = () if self.config.auxiliary_loss else None
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop:
+ continue
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ combined_attention_mask,
+ object_queries,
+ query_position_embeddings,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if self.config.auxiliary_loss:
+ hidden_states = self.layernorm(hidden_states)
+ intermediate += (hidden_states,)
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ # finally, apply layernorm
+ hidden_states = self.layernorm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ # stack intermediate decoder activations
+ if self.config.auxiliary_loss:
+ intermediate = torch.stack(intermediate)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, all_hidden_states, all_self_attns, all_cross_attentions, intermediate]
+ if v is not None
+ )
+ return TableTransformerDecoderOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ intermediate_hidden_states=intermediate,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The bare Table Transformer Model (consisting of a backbone and encoder-decoder Transformer) outputting raw
+ hidden-states without any specific head on top.
+ """
+)
+class TableTransformerModel(TableTransformerPreTrainedModel):
+ # Copied from transformers.models.detr.modeling_detr.DetrModel.__init__ with Detr->TableTransformer
+ def __init__(self, config: TableTransformerConfig):
+ super().__init__(config)
+
+ # Create backbone + positional encoding
+ backbone = TableTransformerConvEncoder(config)
+ object_queries = build_position_encoding(config)
+ self.backbone = TableTransformerConvModel(backbone, object_queries)
+
+ # Create projection layer
+ self.input_projection = nn.Conv2d(backbone.intermediate_channel_sizes[-1], config.d_model, kernel_size=1)
+
+ self.query_position_embeddings = nn.Embedding(config.num_queries, config.d_model)
+
+ self.encoder = TableTransformerEncoder(config)
+ self.decoder = TableTransformerDecoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_encoder(self):
+ return self.encoder
+
+ def freeze_backbone(self):
+ for name, param in self.backbone.conv_encoder.model.named_parameters():
+ param.requires_grad_(False)
+
+ def unfreeze_backbone(self):
+ for name, param in self.backbone.conv_encoder.model.named_parameters():
+ param.requires_grad_(True)
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ pixel_mask: Optional[torch.FloatTensor] = None,
+ decoder_attention_mask: Optional[torch.FloatTensor] = None,
+ encoder_outputs: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], TableTransformerModelOutput]:
+ r"""
+ decoder_attention_mask (`torch.FloatTensor` of shape `(batch_size, num_queries)`, *optional*):
+ Not used by default. Can be used to mask object queries.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you
+ can choose to directly pass a flattened representation of an image.
+ decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*):
+ Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an
+ embedded representation.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, TableTransformerModel
+ >>> from huggingface_hub import hf_hub_download
+ >>> from PIL import Image
+
+ >>> file_path = hf_hub_download(repo_id="nielsr/example-pdf", repo_type="dataset", filename="example_pdf.png")
+ >>> image = Image.open(file_path).convert("RGB")
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("microsoft/table-transformer-detection")
+ >>> model = TableTransformerModel.from_pretrained("microsoft/table-transformer-detection")
+
+ >>> # prepare image for the model
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+
+ >>> # forward pass
+ >>> outputs = model(**inputs)
+
+ >>> # the last hidden states are the final query embeddings of the Transformer decoder
+ >>> # these are of shape (batch_size, num_queries, hidden_size)
+ >>> last_hidden_states = outputs.last_hidden_state
+ >>> list(last_hidden_states.shape)
+ [1, 15, 256]
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ batch_size, num_channels, height, width = pixel_values.shape
+ device = pixel_values.device
+
+ if pixel_mask is None:
+ pixel_mask = torch.ones(((batch_size, height, width)), device=device)
+
+ # First, sent pixel_values + pixel_mask through Backbone to obtain the features
+ # pixel_values should be of shape (batch_size, num_channels, height, width)
+ # pixel_mask should be of shape (batch_size, height, width)
+ features, position_embeddings_list = self.backbone(pixel_values, pixel_mask)
+
+ # get final feature map and downsampled mask
+ feature_map, mask = features[-1]
+
+ if mask is None:
+ raise ValueError("Backbone does not return downsampled pixel mask")
+
+ # Second, apply 1x1 convolution to reduce the channel dimension to d_model (256 by default)
+ projected_feature_map = self.input_projection(feature_map)
+
+ # Third, flatten the feature map + object queries of shape NxCxHxW to NxCxHW, and permute it to NxHWxC
+ # In other words, turn their shape into (batch_size, sequence_length, hidden_size)
+ flattened_features = projected_feature_map.flatten(2).permute(0, 2, 1)
+ object_queries = position_embeddings_list[-1].flatten(2).permute(0, 2, 1)
+
+ flattened_mask = mask.flatten(1)
+
+ # Fourth, sent flattened_features + flattened_mask + object queries through encoder
+ # flattened_features is a Tensor of shape (batch_size, height*width, hidden_size)
+ # flattened_mask is a Tensor of shape (batch_size, height*width)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ inputs_embeds=flattened_features,
+ attention_mask=flattened_mask,
+ object_queries=object_queries,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ # Fifth, sent query embeddings + object queries through the decoder (which is conditioned on the encoder output)
+ query_position_embeddings = self.query_position_embeddings.weight.unsqueeze(0).repeat(batch_size, 1, 1)
+ queries = torch.zeros_like(query_position_embeddings)
+
+ # decoder outputs consists of (dec_features, dec_hidden, dec_attn)
+ decoder_outputs = self.decoder(
+ inputs_embeds=queries,
+ attention_mask=None,
+ object_queries=object_queries,
+ query_position_embeddings=query_position_embeddings,
+ encoder_hidden_states=encoder_outputs[0],
+ encoder_attention_mask=flattened_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return TableTransformerModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ intermediate_hidden_states=decoder_outputs.intermediate_hidden_states,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Table Transformer Model (consisting of a backbone and encoder-decoder Transformer) with object detection heads on
+ top, for tasks such as COCO detection.
+ """
+)
+class TableTransformerForObjectDetection(TableTransformerPreTrainedModel):
+ # Copied from transformers.models.detr.modeling_detr.DetrForObjectDetection.__init__ with Detr->TableTransformer
+ def __init__(self, config: TableTransformerConfig):
+ super().__init__(config)
+
+ # DETR encoder-decoder model
+ self.model = TableTransformerModel(config)
+
+ # Object detection heads
+ self.class_labels_classifier = nn.Linear(
+ config.d_model, config.num_labels + 1
+ ) # We add one for the "no object" class
+ self.bbox_predictor = TableTransformerMLPPredictionHead(
+ input_dim=config.d_model, hidden_dim=config.d_model, output_dim=4, num_layers=3
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ pixel_mask: Optional[torch.FloatTensor] = None,
+ decoder_attention_mask: Optional[torch.FloatTensor] = None,
+ encoder_outputs: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[list[dict]] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], TableTransformerObjectDetectionOutput]:
+ r"""
+ decoder_attention_mask (`torch.FloatTensor` of shape `(batch_size, num_queries)`, *optional*):
+ Not used by default. Can be used to mask object queries.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you
+ can choose to directly pass a flattened representation of an image.
+ decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*):
+ Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an
+ embedded representation.
+ labels (`list[Dict]` of len `(batch_size,)`, *optional*):
+ Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the
+ following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch
+ respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes
+ in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`.
+
+ Examples:
+
+ ```python
+ >>> from huggingface_hub import hf_hub_download
+ >>> from transformers import AutoImageProcessor, TableTransformerForObjectDetection
+ >>> import torch
+ >>> from PIL import Image
+
+ >>> file_path = hf_hub_download(repo_id="nielsr/example-pdf", repo_type="dataset", filename="example_pdf.png")
+ >>> image = Image.open(file_path).convert("RGB")
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("microsoft/table-transformer-detection")
+ >>> model = TableTransformerForObjectDetection.from_pretrained("microsoft/table-transformer-detection")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+
+ >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+ >>> target_sizes = torch.tensor([image.size[::-1]])
+ >>> results = image_processor.post_process_object_detection(outputs, threshold=0.9, target_sizes=target_sizes)[
+ ... 0
+ ... ]
+
+ >>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+ ... box = [round(i, 2) for i in box.tolist()]
+ ... print(
+ ... f"Detected {model.config.id2label[label.item()]} with confidence "
+ ... f"{round(score.item(), 3)} at location {box}"
+ ... )
+ Detected table with confidence 1.0 at location [202.1, 210.59, 1119.22, 385.09]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # First, sent images through TABLE_TRANSFORMER base model to obtain encoder + decoder outputs
+ outputs = self.model(
+ pixel_values,
+ pixel_mask=pixel_mask,
+ decoder_attention_mask=decoder_attention_mask,
+ encoder_outputs=encoder_outputs,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ # class logits + predicted bounding boxes
+ logits = self.class_labels_classifier(sequence_output)
+ pred_boxes = self.bbox_predictor(sequence_output).sigmoid()
+
+ loss, loss_dict, auxiliary_outputs = None, None, None
+ if labels is not None:
+ outputs_class, outputs_coord = None, None
+ if self.config.auxiliary_loss:
+ intermediate = outputs.intermediate_hidden_states if return_dict else outputs[4]
+ outputs_class = self.class_labels_classifier(intermediate)
+ outputs_coord = self.bbox_predictor(intermediate).sigmoid()
+ loss, loss_dict, auxiliary_outputs = self.loss_function(
+ logits, labels, self.device, pred_boxes, self.config, outputs_class, outputs_coord
+ )
+
+ if not return_dict:
+ if auxiliary_outputs is not None:
+ output = (logits, pred_boxes) + auxiliary_outputs + outputs
+ else:
+ output = (logits, pred_boxes) + outputs
+ return ((loss, loss_dict) + output) if loss is not None else output
+
+ return TableTransformerObjectDetectionOutput(
+ loss=loss,
+ loss_dict=loss_dict,
+ logits=logits,
+ pred_boxes=pred_boxes,
+ auxiliary_outputs=auxiliary_outputs,
+ last_hidden_state=outputs.last_hidden_state,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrMLPPredictionHead with Detr->TableTransformer,detr->table_transformer
+class TableTransformerMLPPredictionHead(nn.Module):
+ """
+ Very simple multi-layer perceptron (MLP, also called FFN), used to predict the normalized center coordinates,
+ height and width of a bounding box w.r.t. an image.
+
+ Copied from https://github.com/facebookresearch/table_transformer/blob/master/models/table_transformer.py
+
+ """
+
+ def __init__(self, input_dim, hidden_dim, output_dim, num_layers):
+ super().__init__()
+ self.num_layers = num_layers
+ h = [hidden_dim] * (num_layers - 1)
+ self.layers = nn.ModuleList(nn.Linear(n, k) for n, k in zip([input_dim] + h, h + [output_dim]))
+
+ def forward(self, x):
+ for i, layer in enumerate(self.layers):
+ x = nn.functional.relu(layer(x)) if i < self.num_layers - 1 else layer(x)
+ return x
+
+
+__all__ = ["TableTransformerForObjectDetection", "TableTransformerModel", "TableTransformerPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..7df7e765f60e84f181a7bc6ac3668f35e796b8c7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_tapas import *
+ from .modeling_tapas import *
+ from .modeling_tf_tapas import *
+ from .tokenization_tapas import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/configuration_tapas.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/configuration_tapas.py
new file mode 100644
index 0000000000000000000000000000000000000000..a40d4ba63931f48ad2209dc70ff5181d78dcd14f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/configuration_tapas.py
@@ -0,0 +1,229 @@
+# coding=utf-8
+# Copyright 2020 Google Research and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+TAPAS configuration. Based on the BERT configuration with added parameters.
+
+Hyperparameters are taken from run_task_main.py and hparam_utils.py of the original implementation. URLS:
+
+- https://github.com/google-research/tapas/blob/master/tapas/run_task_main.py
+- https://github.com/google-research/tapas/blob/master/tapas/utils/hparam_utils.py
+
+"""
+
+from ...configuration_utils import PretrainedConfig
+
+
+class TapasConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TapasModel`]. It is used to instantiate a TAPAS
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the TAPAS
+ [google/tapas-base-finetuned-sqa](https://huggingface.co/google/tapas-base-finetuned-sqa) architecture.
+
+ Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Hyperparameters additional to BERT are taken from run_task_main.py and hparam_utils.py of the original
+ implementation. Original implementation available at https://github.com/google-research/tapas/tree/master.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the TAPAS model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`TapasModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"swish"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 1024):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_sizes (`list[int]`, *optional*, defaults to `[3, 256, 256, 2, 256, 256, 10]`):
+ The vocabulary sizes of the `token_type_ids` passed when calling [`TapasModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ positive_label_weight (`float`, *optional*, defaults to 10.0):
+ Weight for positive labels.
+ num_aggregation_labels (`int`, *optional*, defaults to 0):
+ The number of aggregation operators to predict.
+ aggregation_loss_weight (`float`, *optional*, defaults to 1.0):
+ Importance weight for the aggregation loss.
+ use_answer_as_supervision (`bool`, *optional*):
+ Whether to use the answer as the only supervision for aggregation examples.
+ answer_loss_importance (`float`, *optional*, defaults to 1.0):
+ Importance weight for the regression loss.
+ use_normalized_answer_loss (`bool`, *optional*, defaults to `False`):
+ Whether to normalize the answer loss by the maximum of the predicted and expected value.
+ huber_loss_delta (`float`, *optional*):
+ Delta parameter used to calculate the regression loss.
+ temperature (`float`, *optional*, defaults to 1.0):
+ Value used to control (OR change) the skewness of cell logits probabilities.
+ aggregation_temperature (`float`, *optional*, defaults to 1.0):
+ Scales aggregation logits to control the skewness of probabilities.
+ use_gumbel_for_cells (`bool`, *optional*, defaults to `False`):
+ Whether to apply Gumbel-Softmax to cell selection.
+ use_gumbel_for_aggregation (`bool`, *optional*, defaults to `False`):
+ Whether to apply Gumbel-Softmax to aggregation selection.
+ average_approximation_function (`string`, *optional*, defaults to `"ratio"`):
+ Method to calculate the expected average of cells in the weak supervision case. One of `"ratio"`,
+ `"first_order"` or `"second_order"`.
+ cell_selection_preference (`float`, *optional*):
+ Preference for cell selection in ambiguous cases. Only applicable in case of weak supervision for
+ aggregation (WTQ, WikiSQL). If the total mass of the aggregation probabilities (excluding the "NONE"
+ operator) is higher than this hyperparameter, then aggregation is predicted for an example.
+ answer_loss_cutoff (`float`, *optional*):
+ Ignore examples with answer loss larger than cutoff.
+ max_num_rows (`int`, *optional*, defaults to 64):
+ Maximum number of rows.
+ max_num_columns (`int`, *optional*, defaults to 32):
+ Maximum number of columns.
+ average_logits_per_cell (`bool`, *optional*, defaults to `False`):
+ Whether to average logits per cell.
+ select_one_column (`bool`, *optional*, defaults to `True`):
+ Whether to constrain the model to only select cells from a single column.
+ allow_empty_column_selection (`bool`, *optional*, defaults to `False`):
+ Whether to allow not to select any column.
+ init_cell_selection_weights_to_zero (`bool`, *optional*, defaults to `False`):
+ Whether to initialize cell selection weights to 0 so that the initial probabilities are 50%.
+ reset_position_index_per_cell (`bool`, *optional*, defaults to `True`):
+ Whether to restart position indexes at every cell (i.e. use relative position embeddings).
+ disable_per_token_loss (`bool`, *optional*, defaults to `False`):
+ Whether to disable any (strong or weak) supervision on cells.
+ aggregation_labels (`dict[int, label]`, *optional*):
+ The aggregation labels used to aggregate the results. For example, the WTQ models have the following
+ aggregation labels: `{0: "NONE", 1: "SUM", 2: "AVERAGE", 3: "COUNT"}`
+ no_aggregation_label_index (`int`, *optional*):
+ If the aggregation labels are defined and one of these labels represents "No aggregation", this should be
+ set to its index. For example, the WTQ models have the "NONE" aggregation label at index 0, so that value
+ should be set to 0 for these models.
+
+
+ Example:
+
+ ```python
+ >>> from transformers import TapasModel, TapasConfig
+
+ >>> # Initializing a default (SQA) Tapas configuration
+ >>> configuration = TapasConfig()
+ >>> # Initializing a model from the configuration
+ >>> model = TapasModel(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "tapas"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=1024,
+ type_vocab_sizes=[3, 256, 256, 2, 256, 256, 10],
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ pad_token_id=0,
+ positive_label_weight=10.0,
+ num_aggregation_labels=0,
+ aggregation_loss_weight=1.0,
+ use_answer_as_supervision=None,
+ answer_loss_importance=1.0,
+ use_normalized_answer_loss=False,
+ huber_loss_delta=None,
+ temperature=1.0,
+ aggregation_temperature=1.0,
+ use_gumbel_for_cells=False,
+ use_gumbel_for_aggregation=False,
+ average_approximation_function="ratio",
+ cell_selection_preference=None,
+ answer_loss_cutoff=None,
+ max_num_rows=64,
+ max_num_columns=32,
+ average_logits_per_cell=False,
+ select_one_column=True,
+ allow_empty_column_selection=False,
+ init_cell_selection_weights_to_zero=False,
+ reset_position_index_per_cell=True,
+ disable_per_token_loss=False,
+ aggregation_labels=None,
+ no_aggregation_label_index=None,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, **kwargs)
+
+ # BERT hyperparameters (with updated max_position_embeddings and type_vocab_sizes)
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.hidden_act = hidden_act
+ self.intermediate_size = intermediate_size
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.max_position_embeddings = max_position_embeddings
+ self.type_vocab_sizes = type_vocab_sizes
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+
+ # Fine-tuning task hyperparameters
+ self.positive_label_weight = positive_label_weight
+ self.num_aggregation_labels = num_aggregation_labels
+ self.aggregation_loss_weight = aggregation_loss_weight
+ self.use_answer_as_supervision = use_answer_as_supervision
+ self.answer_loss_importance = answer_loss_importance
+ self.use_normalized_answer_loss = use_normalized_answer_loss
+ self.huber_loss_delta = huber_loss_delta
+ self.temperature = temperature
+ self.aggregation_temperature = aggregation_temperature
+ self.use_gumbel_for_cells = use_gumbel_for_cells
+ self.use_gumbel_for_aggregation = use_gumbel_for_aggregation
+ self.average_approximation_function = average_approximation_function
+ self.cell_selection_preference = cell_selection_preference
+ self.answer_loss_cutoff = answer_loss_cutoff
+ self.max_num_rows = max_num_rows
+ self.max_num_columns = max_num_columns
+ self.average_logits_per_cell = average_logits_per_cell
+ self.select_one_column = select_one_column
+ self.allow_empty_column_selection = allow_empty_column_selection
+ self.init_cell_selection_weights_to_zero = init_cell_selection_weights_to_zero
+ self.reset_position_index_per_cell = reset_position_index_per_cell
+ self.disable_per_token_loss = disable_per_token_loss
+
+ # Aggregation hyperparameters
+ self.aggregation_labels = aggregation_labels
+ self.no_aggregation_label_index = no_aggregation_label_index
+
+ if isinstance(self.aggregation_labels, dict):
+ self.aggregation_labels = {int(k): v for k, v in aggregation_labels.items()}
+
+
+__all__ = ["TapasConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/modeling_tapas.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/modeling_tapas.py
new file mode 100644
index 0000000000000000000000000000000000000000..903a2c56b1babd361783f0f1ff70f18267ce3186
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/modeling_tapas.py
@@ -0,0 +1,2347 @@
+# coding=utf-8
+# Copyright 2020 Google Research and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch TAPAS model."""
+
+import enum
+import math
+import os
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, MaskedLMOutput, SequenceClassifierOutput
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import ModelOutput, auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_tapas import TapasConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+EPSILON_ZERO_DIVISION = 1e-10
+CLOSE_ENOUGH_TO_LOG_ZERO = -10000.0
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`TapasForQuestionAnswering`].
+ """
+)
+class TableQuestionAnsweringOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` (and possibly `answer`, `aggregation_labels`, `numeric_values` and `numeric_values_scale` are provided)):
+ Total loss as the sum of the hierarchical cell selection log-likelihood loss and (optionally) the
+ semi-supervised regression loss and (optionally) supervised loss for aggregations.
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Prediction scores of the cell selection head, for every token.
+ logits_aggregation (`torch.FloatTensor`, *optional*, of shape `(batch_size, num_aggregation_labels)`):
+ Prediction scores of the aggregation head, for every aggregation operator.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ logits_aggregation: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+def load_tf_weights_in_tapas(model, config, tf_checkpoint_path):
+ """
+ Load tf checkpoints in a PyTorch model. This is an adaptation from load_tf_weights_in_bert
+
+ - add cell selection and aggregation heads
+ - take into account additional token type embedding layers
+ """
+ try:
+ import re
+
+ import numpy as np
+ import tensorflow as tf
+ except ImportError:
+ logger.error(
+ "Loading a TensorFlow model in PyTorch, requires TensorFlow to be installed. Please see "
+ "https://www.tensorflow.org/install/ for installation instructions."
+ )
+ raise
+ tf_path = os.path.abspath(tf_checkpoint_path)
+ logger.info(f"Converting TensorFlow checkpoint from {tf_path}")
+ # Load weights from TF model
+ init_vars = tf.train.list_variables(tf_path)
+ names = []
+ arrays = []
+ for name, shape in init_vars:
+ logger.info(f"Loading TF weight {name} with shape {shape}")
+ array = tf.train.load_variable(tf_path, name)
+ names.append(name)
+ arrays.append(array)
+
+ for name, array in zip(names, arrays):
+ name = name.split("/")
+ # adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculate m and v
+ # which are not required for using pretrained model
+ if any(
+ n
+ in [
+ "adam_v",
+ "adam_m",
+ "AdamWeightDecayOptimizer",
+ "AdamWeightDecayOptimizer_1",
+ "global_step",
+ "seq_relationship",
+ ]
+ for n in name
+ ):
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ # in case the model is TapasForSequenceClassification, we skip output_bias and output_weights
+ # since these are not used for classification
+ if isinstance(model, TapasForSequenceClassification):
+ if any(n in ["output_bias", "output_weights"] for n in name):
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ # in case the model is TapasModel, we skip output_bias, output_weights, output_bias_cls and output_weights_cls
+ # since this model does not have MLM and NSP heads
+ if isinstance(model, TapasModel):
+ if any(n in ["output_bias", "output_weights", "output_bias_cls", "output_weights_cls"] for n in name):
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ # in case the model is TapasForMaskedLM, we skip the pooler
+ if isinstance(model, TapasForMaskedLM):
+ if any(n in ["pooler"] for n in name):
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ # if first scope name starts with "bert", change it to "tapas"
+ if name[0] == "bert":
+ name[0] = "tapas"
+ pointer = model
+ for m_name in name:
+ if re.fullmatch(r"[A-Za-z]+_\d+", m_name):
+ scope_names = re.split(r"_(\d+)", m_name)
+ else:
+ scope_names = [m_name]
+ if scope_names[0] == "kernel" or scope_names[0] == "gamma":
+ pointer = getattr(pointer, "weight")
+ elif scope_names[0] == "beta":
+ pointer = getattr(pointer, "bias")
+ # cell selection heads
+ elif scope_names[0] == "output_bias":
+ if not isinstance(model, TapasForMaskedLM):
+ pointer = getattr(pointer, "output_bias")
+ else:
+ pointer = getattr(pointer, "bias")
+ elif scope_names[0] == "output_weights":
+ pointer = getattr(pointer, "output_weights")
+ elif scope_names[0] == "column_output_bias":
+ pointer = getattr(pointer, "column_output_bias")
+ elif scope_names[0] == "column_output_weights":
+ pointer = getattr(pointer, "column_output_weights")
+ # aggregation head
+ elif scope_names[0] == "output_bias_agg":
+ pointer = getattr(pointer, "aggregation_classifier")
+ pointer = getattr(pointer, "bias")
+ elif scope_names[0] == "output_weights_agg":
+ pointer = getattr(pointer, "aggregation_classifier")
+ pointer = getattr(pointer, "weight")
+ # classification head
+ elif scope_names[0] == "output_bias_cls":
+ pointer = getattr(pointer, "classifier")
+ pointer = getattr(pointer, "bias")
+ elif scope_names[0] == "output_weights_cls":
+ pointer = getattr(pointer, "classifier")
+ pointer = getattr(pointer, "weight")
+ else:
+ try:
+ pointer = getattr(pointer, scope_names[0])
+ except AttributeError:
+ logger.info(f"Skipping {'/'.join(name)}")
+ continue
+ if len(scope_names) >= 2:
+ num = int(scope_names[1])
+ pointer = pointer[num]
+ if m_name[-11:] == "_embeddings":
+ pointer = getattr(pointer, "weight")
+ elif m_name[-13:] in [f"_embeddings_{i}" for i in range(7)]:
+ pointer = getattr(pointer, "weight")
+ elif m_name == "kernel":
+ array = np.transpose(array)
+ try:
+ if pointer.shape != array.shape:
+ raise ValueError(f"Pointer shape {pointer.shape} and array shape {array.shape} mismatched")
+ except AssertionError as e:
+ e.args += (pointer.shape, array.shape)
+ raise
+ logger.info(f"Initialize PyTorch weight {name}")
+ # Added a check to see whether the array is a scalar (because bias terms in Tapas checkpoints can be
+ # scalar => should first be converted to numpy arrays)
+ if np.isscalar(array):
+ array = np.array(array)
+ pointer.data = torch.from_numpy(array)
+ return model
+
+
+class TapasEmbeddings(nn.Module):
+ """
+ Construct the embeddings from word, position and token_type embeddings. Same as BertEmbeddings but with a number of
+ additional token type embeddings to encode tabular structure.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ # we do not include config.disabled_features and config.disable_position_embeddings from the original implementation
+ # word embeddings
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ # position embeddings
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ # token type embeddings
+ for i, type_vocab_sizes in enumerate(config.type_vocab_sizes):
+ name = f"token_type_embeddings_{i}"
+ setattr(self, name, nn.Embedding(type_vocab_sizes, config.hidden_size))
+
+ self.number_of_token_type_embeddings = len(config.type_vocab_sizes)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ self.config = config
+
+ def forward(self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None):
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if position_ids is None:
+ # create absolute position embeddings
+ position_ids = torch.arange(seq_length, dtype=torch.long, device=device)
+ position_ids = position_ids.unsqueeze(0).expand(input_shape)
+ # when self.config.reset_position_index_per_cell is set to True, create relative position embeddings
+ if self.config.reset_position_index_per_cell:
+ # shape (batch_size, seq_len)
+ col_index = IndexMap(token_type_ids[:, :, 1], self.config.type_vocab_sizes[1], batch_dims=1)
+ # shape (batch_size, seq_len)
+ row_index = IndexMap(token_type_ids[:, :, 2], self.config.type_vocab_sizes[2], batch_dims=1)
+ # shape (batch_size, seq_len)
+ full_index = ProductIndexMap(col_index, row_index)
+ # shape (max_rows * max_columns,). First absolute position for every cell
+ first_position_per_segment = reduce_min(position_ids, full_index)[0]
+ # ? shape (batch_size, seq_len). First absolute position of the cell for every token
+ first_position = gather(first_position_per_segment, full_index)
+ # shape (1, seq_len)
+ position = torch.arange(seq_length, dtype=torch.long, device=device).unsqueeze(0)
+ position_ids = torch.min(
+ torch.as_tensor(self.config.max_position_embeddings - 1, device=device), position - first_position
+ )
+
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(
+ (input_shape + self.number_of_token_type_embeddings), dtype=torch.long, device=device
+ )
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+
+ position_embeddings = self.position_embeddings(position_ids)
+
+ embeddings = inputs_embeds + position_embeddings
+
+ for i in range(self.number_of_token_type_embeddings):
+ name = f"token_type_embeddings_{i}"
+ embeddings += getattr(self, name)(token_type_ids[:, :, i])
+
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class TapasSelfAttention(nn.Module):
+ def __init__(self, config, layer_idx=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.is_decoder = config.is_decoder
+ self.layer_idx = layer_idx
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ encoder_hidden_states=None,
+ past_key_values=None,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ is_cross_attention = encoder_hidden_states is not None
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_layer from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_layer = curr_past_key_value.layers[self.layer_idx].keys
+ value_layer = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_layer = (
+ self.key(current_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(current_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ if past_key_values is not None:
+ # save all key/value_layer to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_layer, value_layer = curr_past_key_value.update(
+ key_layer, value_layer, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in TapasModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(*new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+ if self.is_decoder:
+ outputs = outputs + (past_key_values,)
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertSelfOutput
+class TapasSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class TapasAttention(nn.Module):
+ def __init__(self, config, layer_idx=None):
+ super().__init__()
+ self.self = TapasSelfAttention(config, layer_idx=layer_idx)
+ self.output = TapasSelfOutput(config)
+ self.pruned_heads = set()
+
+ # Copied from transformers.models.bert.modeling_bert.BertAttention.prune_heads
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ # Copied from transformers.models.bert.modeling_bert.BertAttention.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertIntermediate
+class TapasIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertOutput
+class TapasOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class TapasLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_idx=None):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = TapasAttention(config, layer_idx=layer_idx)
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = TapasAttention(config, layer_idx=layer_idx)
+ self.intermediate = TapasIntermediate(config)
+ self.output = TapasOutput(config)
+
+ # Copied from transformers.models.bert.modeling_bert.BertLayer.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+ attention_output = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ cross_attention_outputs = self.crossattention(
+ attention_output,
+ attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:] # add cross attentions if we output attention weights
+
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+ # Copied from transformers.models.bert.modeling_bert.BertLayer.feed_forward_chunk
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+class TapasEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([TapasLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ cache_position=None,
+ ):
+ if use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_attentions
+ )
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPooler
+class TapasPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPredictionHeadTransform with Bert->Tapas
+class TapasPredictionHeadTransform(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ if isinstance(config.hidden_act, str):
+ self.transform_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.transform_act_fn = config.hidden_act
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.transform_act_fn(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertLMPredictionHead with Bert->Tapas
+class TapasLMPredictionHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.transform = TapasPredictionHeadTransform(config)
+
+ # The output weights are the same as the input embeddings, but there is
+ # an output-only bias for each token.
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+
+ # Need a link between the two variables so that the bias is correctly resized with `resize_token_embeddings`
+ self.decoder.bias = self.bias
+
+ def _tie_weights(self):
+ self.decoder.bias = self.bias
+
+ def forward(self, hidden_states):
+ hidden_states = self.transform(hidden_states)
+ hidden_states = self.decoder(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertOnlyMLMHead with Bert->Tapas
+class TapasOnlyMLMHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.predictions = TapasLMPredictionHead(config)
+
+ def forward(self, sequence_output: torch.Tensor) -> torch.Tensor:
+ prediction_scores = self.predictions(sequence_output)
+ return prediction_scores
+
+
+@auto_docstring
+class TapasPreTrainedModel(PreTrainedModel):
+ config: TapasConfig
+ base_model_prefix = "tapas"
+ supports_gradient_checkpointing = True
+ _supports_param_buffer_assignment = False
+
+ # Copied from transformers.models.bert.modeling_bert.BertPreTrainedModel._init_weights with Bert->Tapas
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, TapasLMPredictionHead):
+ module.bias.data.zero_()
+
+
+@auto_docstring
+class TapasModel(TapasPreTrainedModel):
+ """
+ This class is a small change compared to [`BertModel`], taking into account the additional token type ids.
+
+ The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of
+ cross-attention is added between the self-attention layers, following the architecture described in [Attention is
+ all you need](https://huggingface.co/papers/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit,
+ Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin.
+
+ """
+
+ def __init__(self, config, add_pooling_layer=True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = TapasEmbeddings(config)
+ self.encoder = TapasEncoder(config)
+
+ self.pooler = TapasPooler(config) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithPooling]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length, 7)`, *optional*):
+ Token indices that encode tabular structure. Indices can be obtained using [`AutoTokenizer`]. See this
+ class for more info.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. If
+ `reset_position_index_per_cell` of [`TapasConfig`] is set to `True`, relative position embeddings will be
+ used. Selected in the range `[0, config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasModel
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base")
+ >>> model = TapasModel.from_pretrained("google/tapas-base")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+ >>> queries = ["How many movies has George Clooney played in?", "How old is Brad Pitt?"]
+
+ >>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="pt")
+ >>> outputs = model(**inputs)
+
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(input_shape, device=device)
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(
+ (*input_shape, len(self.config.type_vocab_sizes)), dtype=torch.long, device=device
+ )
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ # If a 2D ou 3D attention mask is provided for the cross-attention
+ # we need to make broadcastabe to [batch_size, num_heads, seq_length, seq_length]
+ if self.config.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids, position_ids=position_ids, token_type_ids=token_type_ids, inputs_embeds=inputs_embeds
+ )
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring
+class TapasForMaskedLM(TapasPreTrainedModel):
+ _tied_weights_keys = ["cls.predictions.decoder.weight", "cls.predictions.decoder.bias"]
+ config: TapasConfig
+ base_model_prefix = "tapas"
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.tapas = TapasModel(config, add_pooling_layer=False)
+ self.cls = TapasOnlyMLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.cls.predictions.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.cls.predictions.decoder = new_embeddings
+ self.cls.predictions.bias = new_embeddings.bias
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[tuple, MaskedLMOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length, 7)`, *optional*):
+ Token indices that encode tabular structure. Indices can be obtained using [`AutoTokenizer`]. See this
+ class for more info.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. If
+ `reset_position_index_per_cell` of [`TapasConfig`] is set to `True`, relative position embeddings will be
+ used. Selected in the range `[0, config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasForMaskedLM
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base")
+ >>> model = TapasForMaskedLM.from_pretrained("google/tapas-base")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+
+ >>> inputs = tokenizer(
+ ... table=table, queries="How many [MASK] has George [MASK] played in?", return_tensors="pt"
+ ... )
+ >>> labels = tokenizer(
+ ... table=table, queries="How many movies has George Clooney played in?", return_tensors="pt"
+ ... )["input_ids"]
+
+ >>> outputs = model(**inputs, labels=labels)
+ >>> logits = outputs.logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.tapas(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ prediction_scores = self.cls(sequence_output)
+
+ masked_lm_loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss() # -100 index = padding token
+ masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return MaskedLMOutput(
+ loss=masked_lm_loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Tapas Model with a cell selection head and optional aggregation head on top for question-answering tasks on tables
+ (linear layers on top of the hidden-states output to compute `logits` and optional `logits_aggregation`), e.g. for
+ SQA, WTQ or WikiSQL-supervised tasks.
+ """
+)
+class TapasForQuestionAnswering(TapasPreTrainedModel):
+ def __init__(self, config: TapasConfig):
+ super().__init__(config)
+
+ # base model
+ self.tapas = TapasModel(config)
+
+ # dropout (only used when training)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ # cell selection heads
+ if config.init_cell_selection_weights_to_zero:
+ # init_cell_selection_weights_to_zero: Whether the initial weights should be
+ # set to 0. This ensures that all tokens have the same prior probability.
+ self.output_weights = nn.Parameter(torch.zeros(config.hidden_size))
+ self.column_output_weights = nn.Parameter(torch.zeros(config.hidden_size))
+ else:
+ self.output_weights = nn.Parameter(torch.empty(config.hidden_size))
+ nn.init.normal_(
+ self.output_weights, std=config.initializer_range
+ ) # here, a truncated normal is used in the original implementation
+ self.column_output_weights = nn.Parameter(torch.empty(config.hidden_size))
+ nn.init.normal_(
+ self.column_output_weights, std=config.initializer_range
+ ) # here, a truncated normal is used in the original implementation
+ self.output_bias = nn.Parameter(torch.zeros([]))
+ self.column_output_bias = nn.Parameter(torch.zeros([]))
+
+ # aggregation head
+ if config.num_aggregation_labels > 0:
+ self.aggregation_classifier = nn.Linear(config.hidden_size, config.num_aggregation_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ table_mask: Optional[torch.LongTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ aggregation_labels: Optional[torch.LongTensor] = None,
+ float_answer: Optional[torch.FloatTensor] = None,
+ numeric_values: Optional[torch.FloatTensor] = None,
+ numeric_values_scale: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TableQuestionAnsweringOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length, 7)`, *optional*):
+ Token indices that encode tabular structure. Indices can be obtained using [`AutoTokenizer`]. See this
+ class for more info.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. If
+ `reset_position_index_per_cell` of [`TapasConfig`] is set to `True`, relative position embeddings will be
+ used. Selected in the range `[0, config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ table_mask (`torch.LongTensor` of shape `(batch_size, seq_length)`, *optional*):
+ Mask for the table. Indicates which tokens belong to the table (1). Question tokens, table headers and
+ padding are 0.
+ labels (`torch.LongTensor` of shape `(batch_size, seq_length)`, *optional*):
+ Labels per token for computing the hierarchical cell selection loss. This encodes the positions of the
+ answer appearing in the table. Can be obtained using [`AutoTokenizer`].
+
+ - 1 for tokens that are **part of the answer**,
+ - 0 for tokens that are **not part of the answer**.
+ aggregation_labels (`torch.LongTensor` of shape `(batch_size, )`, *optional*):
+ Aggregation function index for every example in the batch for computing the aggregation loss. Indices
+ should be in `[0, ..., config.num_aggregation_labels - 1]`. Only required in case of strong supervision for
+ aggregation (WikiSQL-supervised).
+ float_answer (`torch.FloatTensor` of shape `(batch_size, )`, *optional*):
+ Float answer for every example in the batch. Set to *float('nan')* for cell selection questions. Only
+ required in case of weak supervision (WTQ) to calculate the aggregate mask and regression loss.
+ numeric_values (`torch.FloatTensor` of shape `(batch_size, seq_length)`, *optional*):
+ Numeric values of every token, NaN for tokens which are not numeric values. Can be obtained using
+ [`AutoTokenizer`]. Only required in case of weak supervision for aggregation (WTQ) to calculate the
+ regression loss.
+ numeric_values_scale (`torch.FloatTensor` of shape `(batch_size, seq_length)`, *optional*):
+ Scale of the numeric values of every token. Can be obtained using [`AutoTokenizer`]. Only required in case
+ of weak supervision for aggregation (WTQ) to calculate the regression loss.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasForQuestionAnswering
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base-finetuned-wtq")
+ >>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base-finetuned-wtq")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+ >>> queries = ["How many movies has George Clooney played in?", "How old is Brad Pitt?"]
+
+ >>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="pt")
+ >>> outputs = model(**inputs)
+
+ >>> logits = outputs.logits
+ >>> logits_aggregation = outputs.logits_aggregation
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.tapas(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ pooled_output = outputs[1]
+
+ sequence_output = self.dropout(sequence_output)
+
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ # Construct indices for the table.
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(
+ (*input_shape, len(self.config.type_vocab_sizes)), dtype=torch.long, device=device
+ )
+
+ token_types = [
+ "segment_ids",
+ "column_ids",
+ "row_ids",
+ "prev_labels",
+ "column_ranks",
+ "inv_column_ranks",
+ "numeric_relations",
+ ]
+
+ row_ids = token_type_ids[:, :, token_types.index("row_ids")]
+ column_ids = token_type_ids[:, :, token_types.index("column_ids")]
+
+ row_index = IndexMap(
+ indices=torch.min(row_ids, torch.as_tensor(self.config.max_num_rows - 1, device=row_ids.device)),
+ num_segments=self.config.max_num_rows,
+ batch_dims=1,
+ )
+ col_index = IndexMap(
+ indices=torch.min(column_ids, torch.as_tensor(self.config.max_num_columns - 1, device=column_ids.device)),
+ num_segments=self.config.max_num_columns,
+ batch_dims=1,
+ )
+ cell_index = ProductIndexMap(row_index, col_index)
+
+ # Masks.
+ input_shape = input_ids.size() if input_ids is not None else inputs_embeds.size()[:-1]
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+ if attention_mask is None:
+ attention_mask = torch.ones(input_shape, device=device)
+ # Table cells only, without question tokens and table headers.
+ if table_mask is None:
+ table_mask = torch.where(row_ids > 0, torch.ones_like(row_ids), torch.zeros_like(row_ids))
+ # torch.FloatTensor[batch_size, seq_length]
+ input_mask_float = attention_mask.to(device=device, dtype=torch.float)
+ table_mask_float = table_mask.to(device=device, dtype=torch.float)
+ # Mask for cells that exist in the table (i.e. that are not padding).
+ cell_mask, _ = reduce_mean(input_mask_float, cell_index)
+
+ # Compute logits per token. These are used to select individual cells.
+ logits = compute_token_logits(sequence_output, self.config.temperature, self.output_weights, self.output_bias)
+
+ # Compute logits per column. These are used to select a column.
+ column_logits = None
+ if self.config.select_one_column:
+ column_logits = compute_column_logits(
+ sequence_output,
+ self.column_output_weights,
+ self.column_output_bias,
+ cell_index,
+ cell_mask,
+ self.config.allow_empty_column_selection,
+ )
+
+ # Aggregation logits
+ logits_aggregation = None
+ if self.config.num_aggregation_labels > 0:
+ logits_aggregation = self.aggregation_classifier(pooled_output)
+
+ # Total loss calculation
+ total_loss = 0.0
+ calculate_loss = False
+ if labels is not None:
+ calculate_loss = True
+ is_supervised = not self.config.num_aggregation_labels > 0 or not self.config.use_answer_as_supervision
+
+ # Semi-supervised cell selection in case of no aggregation:
+ # If the answer (the denotation) appears directly in the table we might
+ # select the answer without applying any aggregation function. There are
+ # some ambiguous cases, see utils._calculate_aggregate_mask for more info.
+ # `aggregate_mask` is 1 for examples where we chose to aggregate and 0
+ # for examples where we chose to select the answer directly.
+ # `labels` encodes the positions of the answer appearing in the table.
+ if is_supervised:
+ aggregate_mask = None
+ else:
+ if float_answer is not None:
+ assert labels.shape[0] == float_answer.shape[0], (
+ "Make sure the answers are a FloatTensor of shape (batch_size,)"
+ )
+ # [batch_size]
+ aggregate_mask = _calculate_aggregate_mask(
+ float_answer,
+ pooled_output,
+ self.config.cell_selection_preference,
+ labels,
+ self.aggregation_classifier,
+ )
+ else:
+ raise ValueError("You have to specify float answers in order to calculate the aggregate mask")
+
+ # Cell selection log-likelihood
+ if self.config.average_logits_per_cell:
+ logits_per_cell, _ = reduce_mean(logits, cell_index)
+ logits = gather(logits_per_cell, cell_index)
+ dist_per_token = torch.distributions.Bernoulli(logits=logits)
+
+ # Compute cell selection loss per example.
+ selection_loss_per_example = None
+ if not self.config.select_one_column:
+ weight = torch.where(
+ labels == 0,
+ torch.ones_like(labels, dtype=torch.float32),
+ self.config.positive_label_weight * torch.ones_like(labels, dtype=torch.float32),
+ )
+ selection_loss_per_token = -dist_per_token.log_prob(labels) * weight
+ selection_loss_per_example = torch.sum(selection_loss_per_token * input_mask_float, dim=1) / (
+ torch.sum(input_mask_float, dim=1) + EPSILON_ZERO_DIVISION
+ )
+ else:
+ selection_loss_per_example, logits = _single_column_cell_selection_loss(
+ logits, column_logits, labels, cell_index, col_index, cell_mask
+ )
+ dist_per_token = torch.distributions.Bernoulli(logits=logits)
+
+ # Supervised cell selection
+ if self.config.disable_per_token_loss:
+ pass
+ elif is_supervised:
+ total_loss += torch.mean(selection_loss_per_example)
+ else:
+ # For the not supervised case, do not assign loss for cell selection
+ total_loss += torch.mean(selection_loss_per_example * (1.0 - aggregate_mask))
+
+ # Semi-supervised regression loss and supervised loss for aggregations
+ if self.config.num_aggregation_labels > 0:
+ if is_supervised:
+ # Note that `aggregate_mask` is None if the setting is supervised.
+ if aggregation_labels is not None:
+ assert labels.shape[0] == aggregation_labels.shape[0], (
+ "Make sure the aggregation labels are a LongTensor of shape (batch_size,)"
+ )
+ per_example_additional_loss = _calculate_aggregation_loss(
+ logits_aggregation,
+ aggregate_mask,
+ aggregation_labels,
+ self.config.use_answer_as_supervision,
+ self.config.num_aggregation_labels,
+ self.config.aggregation_loss_weight,
+ )
+ else:
+ raise ValueError(
+ "You have to specify aggregation labels in order to calculate the aggregation loss"
+ )
+ else:
+ # Set aggregation labels to zeros
+ aggregation_labels = torch.zeros(labels.shape[0], dtype=torch.long, device=labels.device)
+ per_example_additional_loss = _calculate_aggregation_loss(
+ logits_aggregation,
+ aggregate_mask,
+ aggregation_labels,
+ self.config.use_answer_as_supervision,
+ self.config.num_aggregation_labels,
+ self.config.aggregation_loss_weight,
+ )
+
+ if self.config.use_answer_as_supervision:
+ if numeric_values is not None and numeric_values_scale is not None:
+ assert numeric_values.shape == numeric_values_scale.shape
+ # Add regression loss for numeric answers which require aggregation.
+ answer_loss, large_answer_loss_mask = _calculate_regression_loss(
+ float_answer,
+ aggregate_mask,
+ dist_per_token,
+ numeric_values,
+ numeric_values_scale,
+ table_mask_float,
+ logits_aggregation,
+ self.config,
+ )
+ per_example_additional_loss += answer_loss
+ # Zero loss for examples with answer_loss > cutoff.
+ per_example_additional_loss *= large_answer_loss_mask
+ else:
+ raise ValueError(
+ "You have to specify numeric values and numeric values scale in order to calculate the"
+ " regression loss"
+ )
+
+ total_loss += torch.mean(per_example_additional_loss)
+
+ else:
+ # if no label ids are provided, set them to zeros in order to properly compute logits
+ labels = torch.zeros_like(logits)
+ _, logits = _single_column_cell_selection_loss(
+ logits, column_logits, labels, cell_index, col_index, cell_mask
+ )
+ if not return_dict:
+ output = (logits, logits_aggregation) + outputs[2:]
+ return ((total_loss,) + output) if calculate_loss else output
+
+ return TableQuestionAnsweringOutput(
+ loss=total_loss if calculate_loss else None,
+ logits=logits,
+ logits_aggregation=logits_aggregation,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Tapas Model with a sequence classification head on top (a linear layer on top of the pooled output), e.g. for table
+ entailment tasks, such as TabFact (Chen et al., 2020).
+ """
+)
+class TapasForSequenceClassification(TapasPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.tapas = TapasModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], SequenceClassifierOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length, 7)`, *optional*):
+ Token indices that encode tabular structure. Indices can be obtained using [`AutoTokenizer`]. See this
+ class for more info.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. If
+ `reset_position_index_per_cell` of [`TapasConfig`] is set to `True`, relative position embeddings will be
+ used. Selected in the range `[0, config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy). Note: this is called
+ "classification_class_index" in the original implementation.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasForSequenceClassification
+ >>> import torch
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base-finetuned-tabfact")
+ >>> model = TapasForSequenceClassification.from_pretrained("google/tapas-base-finetuned-tabfact")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+ >>> queries = [
+ ... "There is only one actor who is 45 years old",
+ ... "There are 3 actors which played in more than 60 movies",
+ ... ]
+
+ >>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="pt")
+ >>> labels = torch.tensor([1, 0]) # 1 means entailed, 0 means refuted
+
+ >>> outputs = model(**inputs, labels=labels)
+ >>> loss = outputs.loss
+ >>> logits = outputs.logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.tapas(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+""" TAPAS utilities."""
+
+
+class AverageApproximationFunction(str, enum.Enum):
+ RATIO = "ratio"
+ FIRST_ORDER = "first_order"
+ SECOND_ORDER = "second_order"
+
+
+# Beginning of everything related to segmented tensors
+
+
+class IndexMap:
+ """Index grouping entries within a tensor."""
+
+ def __init__(self, indices, num_segments, batch_dims=0):
+ """
+ Creates an index
+
+ Args:
+ indices (`torch.LongTensor`, same shape as a *values* Tensor to which the indices refer):
+ Tensor containing the indices.
+ num_segments (`torch.LongTensor`):
+ Scalar tensor, the number of segments. All elements in a batched segmented tensor must have the same
+ number of segments (although many segments can be empty).
+ batch_dims (`int`, *optional*, defaults to 0):
+ The number of batch dimensions. The first *batch_dims* dimensions of a SegmentedTensor are treated as
+ batch dimensions. Segments in different batch elements are always distinct even if they have the same
+ index.
+ """
+ self.indices = torch.as_tensor(indices, device=indices.device)
+ self.num_segments = torch.as_tensor(num_segments, device=indices.device)
+ self.batch_dims = batch_dims
+
+ def batch_shape(self):
+ return self.indices.size()[: self.batch_dims] # returns a torch.Size object
+
+
+class ProductIndexMap(IndexMap):
+ """The product of two indices."""
+
+ def __init__(self, outer_index, inner_index):
+ """
+ Combines indices i and j into pairs (i, j). The result is an index where each segment (i, j) is the
+ intersection of segments i and j. For example if the inputs represent table cells indexed by respectively rows
+ and columns the output will be a table indexed by (row, column) pairs, i.e. by cell. The implementation
+ combines indices {0, .., n - 1} and {0, .., m - 1} into {0, .., nm - 1}. The output has *num_segments* equal to
+ *outer_index.num_segments* * *inner_index.num_segments*
+
+ Args:
+ outer_index (`IndexMap`):
+ IndexMap.
+ inner_index (`IndexMap`):
+ IndexMap, must have the same shape as *outer_index*.
+ """
+ if outer_index.batch_dims != inner_index.batch_dims:
+ raise ValueError("outer_index.batch_dims and inner_index.batch_dims must be the same.")
+
+ super().__init__(
+ indices=(inner_index.indices + outer_index.indices * inner_index.num_segments),
+ num_segments=inner_index.num_segments * outer_index.num_segments,
+ batch_dims=inner_index.batch_dims,
+ )
+ self.outer_index = outer_index
+ self.inner_index = inner_index
+
+ def project_outer(self, index):
+ """Projects an index with the same index set onto the outer components."""
+ indices = torch.div(index.indices, self.inner_index.num_segments, rounding_mode="floor").type(torch.long)
+ return IndexMap(indices=indices, num_segments=self.outer_index.num_segments, batch_dims=index.batch_dims)
+
+ def project_inner(self, index):
+ """Projects an index with the same index set onto the inner components."""
+ return IndexMap(
+ indices=torch.fmod(index.indices, self.inner_index.num_segments)
+ .type(torch.float)
+ .floor()
+ .type(torch.long),
+ num_segments=self.inner_index.num_segments,
+ batch_dims=index.batch_dims,
+ )
+
+
+def gather(values, index, name="segmented_gather"):
+ """
+ Gathers from *values* using the index map. For each element in the domain of the index map this operation looks up
+ a value for that index in *values*. Two elements from the same segment always get assigned the same value.
+
+ Args:
+ values (`torch.Tensor` of shape (B1, ..., Bn, num_segments, V1, ...)):
+ Tensor with segment values.
+ index (`IndexMap` of shape (B1, ..., Bn, I1, ..., Ik)):
+ IndexMap.
+ name (`str`, *optional*, defaults to 'segmented_gather'):
+ Name for the operation. Currently not used
+
+ Returns:
+ `tuple(torch.Tensor)`: Tensor of shape (B1, ..., Bn, I1, ..., Ik, V1, ...) with the gathered values.
+ """
+ indices = index.indices
+ # first, check whether the indices of the index represent scalar values (i.e. not vectorized)
+ if len(values.shape[index.batch_dims :]) < 2:
+ return torch.gather(
+ values,
+ index.batch_dims,
+ indices.view(
+ values.size()[0], -1
+ ), # torch.gather expects index to have the same number of dimensions as values
+ ).view(indices.size())
+ else:
+ # this means we have a vectorized version
+ # we have to adjust the index
+ indices = indices.unsqueeze(-1).expand(values.shape)
+ return torch.gather(values, index.batch_dims, indices)
+
+
+def flatten(index, name="segmented_flatten"):
+ """
+ Flattens a batched index map (which is typically of shape batch_size, seq_length) to a 1d index map. This operation
+ relabels the segments to keep batch elements distinct. The k-th batch element will have indices shifted by
+ *num_segments* * (k - 1). The result is a tensor with *num_segments* multiplied by the number of elements in the
+ batch.
+
+ Args:
+ index (`IndexMap`):
+ IndexMap to flatten.
+ name (`str`, *optional*, defaults to 'segmented_flatten'):
+ Name for the operation. Currently not used
+
+ Returns:
+ (`IndexMap`): The flattened IndexMap.
+ """
+ # first, get batch_size as scalar tensor
+ batch_size = torch.prod(torch.tensor(list(index.batch_shape())))
+ # next, create offset as 1-D tensor of length batch_size,
+ # and multiply element-wise by num segments (to offset different elements in the batch) e.g. if batch size is 2: [0, 64]
+ offset = torch.arange(start=0, end=batch_size, device=index.num_segments.device) * index.num_segments
+ offset = offset.view(index.batch_shape())
+ for _ in range(index.batch_dims, len(index.indices.size())): # typically range(1,2)
+ offset = offset.unsqueeze(-1)
+
+ indices = offset + index.indices
+ return IndexMap(indices=indices.view(-1), num_segments=index.num_segments * batch_size, batch_dims=0)
+
+
+def range_index_map(batch_shape, num_segments, name="range_index_map"):
+ """
+ Constructs an index map equal to range(num_segments).
+
+ Args:
+ batch_shape (`torch.Size`):
+ Batch shape
+ num_segments (`int`):
+ Number of segments
+ name (`str`, *optional*, defaults to 'range_index_map'):
+ Name for the operation. Currently not used
+
+ Returns:
+ (`IndexMap`): IndexMap of shape batch_shape with elements equal to range(num_segments).
+ """
+ device = num_segments.device if torch.is_tensor(num_segments) else "cpu"
+ batch_shape = torch.as_tensor(
+ batch_shape, dtype=torch.long, device=device
+ ) # create a rank 1 tensor vector containing batch_shape (e.g. [2])
+ assert len(batch_shape.size()) == 1
+ num_segments = torch.as_tensor(
+ num_segments, device=device
+ ) # create a rank 0 tensor (scalar) containing num_segments (e.g. 64)
+ assert len(num_segments.size()) == 0
+
+ indices = torch.arange(
+ start=0, end=num_segments, device=num_segments.device
+ ) # create a rank 1 vector with num_segments elements
+ new_tensor = torch.cat(
+ [torch.ones_like(batch_shape, dtype=torch.long, device=num_segments.device), num_segments.unsqueeze(dim=0)],
+ dim=0,
+ )
+ # new_tensor is just a vector of [1 64] for example (assuming only 1 batch dimension)
+ new_shape = [int(x) for x in new_tensor.tolist()]
+ indices = indices.view(new_shape)
+
+ multiples = torch.cat([batch_shape, torch.as_tensor([1], device=device)], dim=0)
+ indices = indices.repeat(multiples.tolist())
+ # equivalent (in Numpy:)
+ # indices = torch.as_tensor(np.tile(indices.numpy(), multiples.tolist()))
+
+ return IndexMap(indices=indices, num_segments=num_segments, batch_dims=list(batch_shape.size())[0])
+
+
+def _segment_reduce(values, index, segment_reduce_fn, name):
+ """
+ Applies a segment reduction segment-wise.
+
+ Args:
+ values (`torch.Tensor`):
+ Tensor with segment values.
+ index (`IndexMap`):
+ IndexMap.
+ segment_reduce_fn (`str`):
+ Name for the reduce operation. One of "sum", "mean", "max" or "min".
+ name (`str`):
+ Name for the operation. Currently not used
+
+ Returns:
+ (`IndexMap`): IndexMap of shape batch_shape with elements equal to range(num_segments).
+ """
+ # Flatten the batch dimensions, as segments ops (scatter) do not support batching.
+ # However if `values` has extra dimensions to the right keep them
+ # unflattened. Segmented ops support vector-valued operations.
+ flat_index = flatten(index)
+ vector_shape = values.size()[len(index.indices.size()) :] # torch.Size object
+ flattened_shape = torch.cat(
+ [torch.as_tensor([-1], dtype=torch.long), torch.as_tensor(vector_shape, dtype=torch.long)], dim=0
+ )
+ # changed "view" by "reshape" in the following line
+ flat_values = values.reshape(flattened_shape.tolist())
+
+ out = torch.zeros(int(flat_index.num_segments), dtype=torch.float, device=flat_values.device)
+ segment_means = out.scatter_reduce(
+ dim=0, index=flat_index.indices.long(), src=flat_values.float(), reduce=segment_reduce_fn, include_self=False
+ )
+
+ device = index.num_segments.device
+ # Unflatten the values.
+ new_shape = torch.cat(
+ [
+ torch.as_tensor(index.batch_shape(), dtype=torch.long, device=device),
+ torch.as_tensor([index.num_segments], dtype=torch.long, device=device),
+ torch.as_tensor(vector_shape, dtype=torch.long, device=device),
+ ],
+ dim=0,
+ )
+
+ output_values = segment_means.clone().view(new_shape.tolist()).to(values.dtype)
+ output_index = range_index_map(index.batch_shape(), index.num_segments)
+ return output_values, output_index
+
+
+def reduce_sum(values, index, name="segmented_reduce_sum"):
+ """
+ Sums a tensor over its segments.
+
+ Outputs 0 for empty segments.
+
+ This operations computes the sum over segments, with support for:
+
+ - Batching using the first dimensions [B1, B2, ..., Bn]. Each element in a batch can have different indices.
+ - Vectorization using the last dimension [V1, V2, ...]. If they are present, the output will be a sum of
+ vectors rather than scalars. Only the middle dimensions [I1, ..., Ik] are reduced by the operation.
+
+ Args:
+ values (`torch.Tensor` of shape [B1, B2, ..., Bn, I1, .., Ik, V1, V2, ..]):
+ Tensor containing the values of which the sum must be taken segment-wise.
+ index (`IndexMap`, indices are of shape [B1, B2, ..., Bn, I1, .., Ik].):
+ Index defining the segments.
+ name (`str`, *optional*, defaults to 'segmented_reduce_sum'):
+ Name for the operation. Currently not used
+
+ Returns:
+ output_values (`torch.Tensor`of shape [B1, B2, ..., Bn, num_segments, V1, V2, ..]): Tensor containing the
+ output values. output_index (`IndexMap`): IndexMap with shape [B1, B2, ..., Bn, num_segments]. .
+ """
+ return _segment_reduce(values, index, "sum", name)
+
+
+def reduce_mean(values, index, name="segmented_reduce_mean"):
+ """
+ Averages a tensor over its segments.
+
+ Outputs 0 for empty segments.
+
+ This operations computes the mean over segments, with support for:
+
+ - Batching using the first dimensions [B1, B2, ..., Bn]. Each element in a batch can have different indices.
+ - Vectorization using the last dimension [V1, V2, ...]. If they are present, the output will be a mean of
+ vectors rather than scalars.
+
+ Only the middle dimensions [I1, ..., Ik] are reduced by the operation.
+
+ Args:
+ values (`torch.Tensor` of shape [B1, B2, ..., Bn, I1, .., Ik, V1, V2, ..]):
+ Tensor containing the values of which the mean must be taken segment-wise.
+ index (`IndexMap`, indices are of shape [B1, B2, ..., Bn, I1, .., Ik].):
+ Index defining the segments.
+ name (`str`, *optional*, defaults to 'segmented_reduce_sum'):
+ Name for the operation. Currently not used
+
+ Returns:
+ output_values (`torch.Tensor`of shape [B1, B2, ..., Bn, num_segments, V1, V2, ..]): Tensor containing the
+ output values. output_index (`IndexMap`): IndexMap with shape [B1, B2, ..., Bn, num_segments].
+ """
+ return _segment_reduce(values, index, "mean", name)
+
+
+def reduce_max(values, index, name="segmented_reduce_max"):
+ """
+ Computes the maximum over segments.
+
+ This operation computes the maximum over segments, with support for:
+
+ - Batching using the first dimensions [B1, B2, ..., Bn]. Each element in a batch can have different indices.
+ - Vectorization using the last dimension [V1, V2, ...]. If they are present, the output will be an element-wise
+ maximum of vectors rather than scalars.
+
+ Only the middle dimensions [I1, ..., Ik] are reduced by the operation.
+
+ Args:
+ values (`torch.Tensor` of shape [B1, B2, ..., Bn, I1, .., Ik, V1, V2, ..]):
+ Tensor containing the values of which the max must be taken segment-wise.
+ index (`IndexMap`, indices are of shape [B1, B2, ..., Bn, I1, .., Ik].):
+ Index defining the segments.
+ name (`str`, *optional*, defaults to 'segmented_reduce_sum'):
+ Name for the operation. Currently not used
+
+ Returns:
+ output_values (`torch.Tensor`of shape [B1, B2, ..., Bn, num_segments, V1, V2, ..]): Tensor containing the
+ output values. output_index (`IndexMap`): IndexMap with shape [B1, B2, ..., Bn, num_segments].
+ """
+ return _segment_reduce(values, index, "amax", name)
+
+
+def reduce_min(values, index, name="segmented_reduce_min"):
+ """
+ Computes the minimum over segments.
+
+ This operations computes the minimum over segments, with support for:
+
+ - Batching using the first dimensions [B1, B2, ..., Bn]. Each element in a batch can have different indices.
+ - Vectorization using the last dimension [V1, V2, ...]. If they are present, the output will be an element-wise
+ minimum of vectors rather than scalars.
+
+ Only the middle dimensions [I1, ..., Ik] are reduced by the operation.
+
+ Args:
+ values (`torch.Tensor` of shape [B1, B2, ..., Bn, I1, .., Ik, V1, V2, ..]):
+ Tensor containing the values of which the min must be taken segment-wise.
+ index (`IndexMap`, indices are of shape [B1, B2, ..., Bn, I1, .., Ik].):
+ Index defining the segments.
+ name (`str`, *optional*, defaults to 'segmented_reduce_sum'):
+ Name for the operation. Currently not used
+
+ Returns:
+ output_values (`torch.Tensor`of shape [B1, B2, ..., Bn, num_segments, V1, V2, ..]): Tensor containing the
+ output values. output_index (`IndexMap`): IndexMap with shape [B1, B2, ..., Bn, num_segments].
+ """
+ return _segment_reduce(values, index, "amin", name)
+
+
+# End of everything related to segmented tensors
+
+
+def compute_column_logits(
+ sequence_output, column_output_weights, column_output_bias, cell_index, cell_mask, allow_empty_column_selection
+):
+ """
+ Computes the column logits.
+
+ Args:
+ sequence_output (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Also known as last_hidden_state. Sequence of hidden-states at the output of the last layer of the model.
+ column_output_weights (`torch.FloatTensor` of shape `(hidden_size)`):
+ Weights of the linear layer for column selection.
+ column_output_bias (`torch.FloatTensor` of shape `()`):
+ Bias of the linear layer for column selection.
+ cell_index (`ProductIndexMap`):
+ Index that groups tokens into cells.
+ cell_mask (`torch.FloatTensor` of shape `(batch_size, max_num_rows * max_num_cols)`):
+ Mask for cells that exist in the table (i.e. that are not padding).
+ allow_empty_column_selection (`bool`):
+ Whether to allow not to select any column
+
+ Returns:
+ column_logits (`torch.FloatTensor`of shape `(batch_size, max_num_cols)`): Tensor containing the column logits
+ for every example in the batch.
+ """
+
+ # First, compute the token logits (batch_size, seq_len) - without temperature
+ token_logits = torch.einsum("bsj,j->bs", sequence_output, column_output_weights) + column_output_bias
+
+ # Next, average the logits per cell (batch_size, max_num_cols*max_num_rows)
+ cell_logits, cell_logits_index = reduce_mean(token_logits, cell_index)
+
+ # Finally, average the logits per column (batch_size, max_num_cols)
+ column_index = cell_index.project_inner(cell_logits_index)
+ column_logits, out_index = reduce_sum(cell_logits * cell_mask, column_index)
+
+ cell_count, _ = reduce_sum(cell_mask, column_index)
+ column_logits /= cell_count + EPSILON_ZERO_DIVISION
+
+ # Mask columns that do not appear in the example.
+ is_padding = torch.logical_and(cell_count < 0.5, ~torch.eq(out_index.indices, 0))
+ column_logits += CLOSE_ENOUGH_TO_LOG_ZERO * torch.as_tensor(
+ is_padding, dtype=torch.float32, device=is_padding.device
+ )
+
+ if not allow_empty_column_selection:
+ column_logits += CLOSE_ENOUGH_TO_LOG_ZERO * torch.as_tensor(
+ torch.eq(out_index.indices, 0), dtype=torch.float32, device=out_index.indices.device
+ )
+
+ return column_logits
+
+
+def _single_column_cell_selection_loss(token_logits, column_logits, labels, cell_index, col_index, cell_mask):
+ """
+ Computes the loss for cell selection constrained to a single column. The loss is a hierarchical log-likelihood. The
+ model first predicts a column and then selects cells within that column (conditioned on the column). Cells outside
+ the selected column are never selected.
+
+ Args:
+ token_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Tensor containing the logits per token.
+ column_logits (`torch.FloatTensor` of shape `(batch_size, max_num_cols)`):
+ Tensor containing the logits per column.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Labels per token.
+ cell_index (`ProductIndexMap`):
+ Index that groups tokens into cells.
+ col_index (`IndexMap`):
+ Index that groups tokens into columns.
+ cell_mask (`torch.FloatTensor` of shape `(batch_size, max_num_rows * max_num_cols)`):
+ Mask for cells that exist in the table (i.e. that are not padding).
+
+ Returns:
+ selection_loss_per_example (`torch.FloatTensor` of shape `(batch_size,)`): Loss for each example. logits
+ (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): New logits which are only allowed to select
+ cells in a single column. Logits outside of the most likely column according to *column_logits* will be set to
+ a very low value (such that the probabilities are 0).
+ """
+ # Part 1: column loss
+
+ # First find the column we should select. We use the column with maximum number of selected cells.
+ labels_per_column, _ = reduce_sum(torch.as_tensor(labels, dtype=torch.float32, device=labels.device), col_index)
+ # shape of labels_per_column is (batch_size, max_num_cols). It contains the number of label ids for every column, for every example
+ column_label = torch.argmax(labels_per_column, dim=-1) # shape (batch_size,)
+ # Check if there are no selected cells in the column. In that case the model
+ # should predict the special column id 0, which means "select nothing".
+ no_cell_selected = torch.eq(
+ torch.max(labels_per_column, dim=-1)[0], 0
+ ) # no_cell_selected is of shape (batch_size,) and equals True
+ # if an example of the batch has no cells selected (i.e. if there are no labels set to 1 for that example)
+ column_label = torch.where(
+ no_cell_selected.view(column_label.size()), torch.zeros_like(column_label), column_label
+ )
+
+ column_dist = torch.distributions.Categorical(logits=column_logits) # shape (batch_size, max_num_cols)
+ column_loss_per_example = -column_dist.log_prob(column_label)
+
+ # Part 2: cell loss
+
+ # Reduce the labels and logits to per-cell from per-token.
+ # logits_per_cell: shape (batch_size, max_num_rows*max_num_cols) i.e. (batch_size, 64*32)
+ logits_per_cell, _ = reduce_mean(token_logits, cell_index)
+ # labels_per_cell: shape (batch_size, 64*32), indicating whether each cell should be selected (1) or not (0)
+ labels_per_cell, labels_index = reduce_max(
+ torch.as_tensor(labels, dtype=torch.long, device=labels.device), cell_index
+ )
+
+ # Mask for the selected column.
+ # column_id_for_cells: shape (batch_size, 64*32), indicating to which column each cell belongs
+ column_id_for_cells = cell_index.project_inner(labels_index).indices
+ # column_mask: shape (batch_size, 64*32), equal to 1 if cell belongs to column to be selected
+ column_mask = torch.as_tensor(
+ torch.eq(column_id_for_cells, torch.unsqueeze(column_label, dim=-1)),
+ dtype=torch.float32,
+ device=cell_mask.device,
+ )
+
+ # Compute the log-likelihood for cells, but only for the selected column.
+ cell_dist = torch.distributions.Bernoulli(logits=logits_per_cell) # shape (batch_size, 64*32)
+ cell_log_prob = cell_dist.log_prob(labels_per_cell.type(torch.float32)) # shape(batch_size, 64*32)
+
+ cell_loss = -torch.sum(cell_log_prob * column_mask * cell_mask, dim=1)
+
+ # We need to normalize the loss by the number of cells in the column.
+ cell_loss /= torch.sum(column_mask * cell_mask, dim=1) + EPSILON_ZERO_DIVISION
+
+ selection_loss_per_example = column_loss_per_example
+ selection_loss_per_example += torch.where(
+ no_cell_selected.view(selection_loss_per_example.size()),
+ torch.zeros_like(selection_loss_per_example),
+ cell_loss,
+ )
+
+ # Set the probs outside the selected column (selected by the *model*)
+ # to 0. This ensures backwards compatibility with models that select
+ # cells from multiple columns.
+ selected_column_id = torch.as_tensor(
+ torch.argmax(column_logits, dim=-1), dtype=torch.long, device=column_logits.device
+ ) # shape (batch_size,)
+
+ # selected_column_mask: shape (batch_size, 64*32), equal to 1 if cell belongs to column selected by the model
+ selected_column_mask = torch.as_tensor(
+ torch.eq(column_id_for_cells, torch.unsqueeze(selected_column_id, dim=-1)),
+ dtype=torch.float32,
+ device=selected_column_id.device,
+ )
+
+ # Never select cells with the special column id 0.
+ selected_column_mask = torch.where(
+ torch.eq(column_id_for_cells, 0).view(selected_column_mask.size()),
+ torch.zeros_like(selected_column_mask),
+ selected_column_mask,
+ )
+ new_logits_per_cell = logits_per_cell + CLOSE_ENOUGH_TO_LOG_ZERO * (1.0 - cell_mask * selected_column_mask)
+ logits = gather(new_logits_per_cell, cell_index)
+
+ return selection_loss_per_example, logits
+
+
+def compute_token_logits(sequence_output, temperature, output_weights, output_bias):
+ """
+ Computes logits per token
+
+ Args:
+ sequence_output (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Also known as last_hidden_state. Sequence of hidden-states at the output of the last layer of the model.
+ temperature (`float`):
+ Temperature for the Bernoulli distribution.
+ output_weights (`torch.FloatTensor` of shape `(hidden_size,)`):
+ Weights of the linear layer for cell selection.
+ output_bias (`torch.FloatTensor` of shape `()`):
+ Bias of the linear layer for cell selection
+
+ Returns:
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): Logits per token.
+ """
+ logits = (torch.einsum("bsj,j->bs", sequence_output, output_weights) + output_bias) / temperature
+
+ return logits
+
+
+def _calculate_aggregate_mask(answer, pooled_output, cell_selection_preference, labels, aggregation_classifier):
+ """
+ Finds examples where the model should select cells with no aggregation.
+
+ Returns a mask that determines for which examples should the model select answers directly from the table, without
+ any aggregation function. If the answer is a piece of text the case is unambiguous as aggregation functions only
+ apply to numbers. If the answer is a number but does not appear in the table then we must use some aggregation
+ case. The ambiguous case is when the answer is a number that also appears in the table. In this case we use the
+ aggregation function probabilities predicted by the model to decide whether to select or aggregate. The threshold
+ for this is a hyperparameter *cell_selection_preference*
+
+ Args:
+ answer (`torch.FloatTensor` of shape `(batch_size, )`):
+ Answer for every example in the batch. Nan if there is no scalar answer.
+ pooled_output (`torch.FloatTensor` of shape `(batch_size, hidden_size)`):
+ Output of the pooler (BertPooler) on top of the encoder layer.
+ cell_selection_preference (`float`):
+ Preference for cell selection in ambiguous cases.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Labels per token. aggregation_classifier (`torch.nn.Linear`): Aggregation head
+
+ Returns:
+ aggregate_mask (`torch.FloatTensor` of shape `(batch_size,)`): A mask set to 1 for examples that should use
+ aggregation functions.
+ """
+ # torch.FloatTensor(batch_size,)
+ aggregate_mask_init = torch.logical_not(torch.isnan(answer)).type(torch.FloatTensor).to(answer.device)
+ logits_aggregation = aggregation_classifier(pooled_output)
+ dist_aggregation = torch.distributions.categorical.Categorical(logits=logits_aggregation)
+ # Index 0 corresponds to "no aggregation".
+ aggregation_ops_total_mass = torch.sum(dist_aggregation.probs[:, 1:], dim=1)
+
+ # Cell selection examples according to current model.
+ is_pred_cell_selection = aggregation_ops_total_mass <= cell_selection_preference
+
+ # Examples with non-empty cell selection supervision.
+ is_cell_supervision_available = torch.sum(labels, dim=1) > 0
+
+ # torch.where is not equivalent to tf.where (in tensorflow 1)
+ # hence the added .view on the condition to match the shape of the first tensor
+ aggregate_mask = torch.where(
+ torch.logical_and(is_pred_cell_selection, is_cell_supervision_available).view(aggregate_mask_init.size()),
+ torch.zeros_like(aggregate_mask_init, dtype=torch.float32),
+ aggregate_mask_init,
+ )
+
+ aggregate_mask = aggregate_mask.detach()
+
+ return aggregate_mask
+
+
+def _calculate_aggregation_loss_known(
+ logits_aggregation, aggregate_mask, aggregation_labels, use_answer_as_supervision, num_aggregation_labels
+):
+ """
+ Calculates aggregation loss when its type is known during training.
+
+ In the weakly supervised setting, the only known information is that for cell selection examples, "no aggregation"
+ should be predicted. For other examples (those that require aggregation), no loss is accumulated. In the setting
+ where aggregation type is always known, standard cross entropy loss is accumulated for all examples
+
+ Args:
+ logits_aggregation (`torch.FloatTensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ aggregate_mask (`torch.FloatTensor` of shape `(batch_size, )`):
+ A mask set to 1 for examples that should use aggregation functions.
+ aggregation_labels (`torch.LongTensor` of shape `(batch_size, )`):
+ Aggregation function id for every example in the batch.
+ use_answer_as_supervision (`bool`, *optional*):
+ Whether to use the answer as the only supervision for aggregation examples.
+ num_aggregation_labels (`int`, *optional*, defaults to 0):
+ The number of aggregation operators to predict.
+
+ Returns:
+ aggregation_loss_known (`torch.FloatTensor` of shape `(batch_size,)`): Aggregation loss (when its type is known
+ during training) per example.
+ """
+ if use_answer_as_supervision:
+ # Prepare "no aggregation" targets for cell selection examples.
+ target_aggregation = torch.zeros_like(aggregate_mask, dtype=torch.long)
+ else:
+ # Use aggregation supervision as the target.
+ target_aggregation = aggregation_labels
+
+ one_hot_labels = nn.functional.one_hot(target_aggregation, num_classes=num_aggregation_labels).type(torch.float32)
+ log_probs = nn.functional.log_softmax(logits_aggregation, dim=-1)
+
+ # torch.FloatTensor[batch_size]
+ per_example_aggregation_intermediate = -torch.sum(one_hot_labels * log_probs, dim=-1)
+ if use_answer_as_supervision:
+ # Accumulate loss only for examples requiring cell selection
+ # (no aggregation).
+ return per_example_aggregation_intermediate * (1 - aggregate_mask)
+ else:
+ return per_example_aggregation_intermediate
+
+
+def _calculate_aggregation_loss_unknown(logits_aggregation, aggregate_mask):
+ """
+ Calculates aggregation loss in the case of answer supervision.
+
+ Args:
+ logits_aggregation (`torch.FloatTensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ aggregate_mask (`torch.FloatTensor` of shape `(batch_size, )`):
+ A mask set to 1 for examples that should use aggregation functions
+
+ Returns:
+ aggregation_loss_unknown (`torch.FloatTensor` of shape `(batch_size,)`): Aggregation loss (in case of answer
+ supervision) per example.
+ """
+ dist_aggregation = torch.distributions.categorical.Categorical(logits=logits_aggregation)
+ # Index 0 corresponds to "no aggregation".
+ aggregation_ops_total_mass = torch.sum(dist_aggregation.probs[:, 1:], dim=1)
+ # Predict some aggregation in case of an answer that needs aggregation.
+ # This increases the probability of all aggregation functions, in a way
+ # similar to MML, but without considering whether the function gives the
+ # correct answer.
+ return -torch.log(aggregation_ops_total_mass) * aggregate_mask
+
+
+def _calculate_aggregation_loss(
+ logits_aggregation,
+ aggregate_mask,
+ aggregation_labels,
+ use_answer_as_supervision,
+ num_aggregation_labels,
+ aggregation_loss_weight,
+):
+ """
+ Calculates the aggregation loss per example.
+
+ Args:
+ logits_aggregation (`torch.FloatTensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ aggregate_mask (`torch.FloatTensor` of shape `(batch_size, )`):
+ A mask set to 1 for examples that should use aggregation functions.
+ aggregation_labels (`torch.LongTensor` of shape `(batch_size, )`):
+ Aggregation function id for every example in the batch.
+ use_answer_as_supervision (`bool`, *optional*):
+ Whether to use the answer as the only supervision for aggregation examples.
+ num_aggregation_labels (`int`, *optional*, defaults to 0):
+ The number of aggregation operators to predict.
+ aggregation_loss_weight (`float`, *optional*, defaults to 1.0):
+ Importance weight for the aggregation loss.
+
+ Returns:
+ aggregation_loss (`torch.FloatTensor` of shape `(batch_size,)`): Aggregation loss per example.
+ """
+ per_example_aggregation_loss = _calculate_aggregation_loss_known(
+ logits_aggregation, aggregate_mask, aggregation_labels, use_answer_as_supervision, num_aggregation_labels
+ )
+
+ if use_answer_as_supervision:
+ # Add aggregation loss for numeric answers that need aggregation.
+ per_example_aggregation_loss += _calculate_aggregation_loss_unknown(logits_aggregation, aggregate_mask)
+ return aggregation_loss_weight * per_example_aggregation_loss
+
+
+def _calculate_expected_result(
+ dist_per_cell, numeric_values, numeric_values_scale, input_mask_float, logits_aggregation, config
+):
+ """
+ Calculates the expected result given cell and aggregation probabilities.
+
+ Args:
+ dist_per_cell (`torch.distributions.Bernoulli`):
+ Cell selection distribution for each cell.
+ numeric_values (`torch.FloatTensor` of shape `(batch_size, seq_length)`):
+ Numeric values of every token. Nan for tokens which are not numeric values.
+ numeric_values_scale (`torch.FloatTensor` of shape `(batch_size, seq_length)`):
+ Scale of the numeric values of every token.
+ input_mask_float (`torch.FloatTensor` of shape `(batch_size, seq_length)`):
+ Mask for the table, without question tokens and table headers.
+ logits_aggregation (`torch.FloatTensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ config ([`TapasConfig`]):
+ Model configuration class with all the hyperparameters of the model
+
+ Returns:
+ expected_result (`torch.FloatTensor` of shape `(batch_size,)`): The expected result per example.
+ """
+ if config.use_gumbel_for_cells:
+ gumbel_dist = torch.distributions.RelaxedBernoulli(
+ # The token logits where already divided by the temperature and used for
+ # computing cell selection errors so we need to multiply it again here
+ temperature=config.temperature,
+ logits=dist_per_cell.logits * config.temperature,
+ )
+ scaled_probability_per_cell = gumbel_dist.sample()
+ else:
+ scaled_probability_per_cell = dist_per_cell.probs
+
+ # [batch_size, seq_length]
+ scaled_probability_per_cell = (scaled_probability_per_cell / numeric_values_scale) * input_mask_float
+ count_result = torch.sum(scaled_probability_per_cell, dim=1)
+ numeric_values_masked = torch.where(
+ torch.isnan(numeric_values), torch.zeros_like(numeric_values), numeric_values
+ ) # Mask non-numeric table values to zero.
+ sum_result = torch.sum(scaled_probability_per_cell * numeric_values_masked, dim=1)
+ avg_approximation = config.average_approximation_function
+ if avg_approximation == AverageApproximationFunction.RATIO:
+ average_result = sum_result / (count_result + EPSILON_ZERO_DIVISION)
+ elif avg_approximation == AverageApproximationFunction.FIRST_ORDER:
+ # The sum of all probabilities except that correspond to other cells
+ # Ex here stands for expectation, more explicitly the expectation of the sum of N-1 Bernoulli random variables plus
+ # the constant 1, which is computed as adding all N expected values and subtracting the extra one. It corresponds to X_c
+ # in Appendix D of the original TAPAS paper which is trying to approximate the average of a random set.
+ ex = torch.sum(scaled_probability_per_cell, dim=1, keepdim=True) - scaled_probability_per_cell + 1
+ average_result = torch.sum(numeric_values_masked * scaled_probability_per_cell / ex, dim=1)
+ elif avg_approximation == AverageApproximationFunction.SECOND_ORDER:
+ # The sum of all probabilities except that correspond to other cells
+ ex = torch.sum(scaled_probability_per_cell, dim=1, keepdim=True) - scaled_probability_per_cell + 1
+ pointwise_var = scaled_probability_per_cell * (1 - scaled_probability_per_cell)
+ var = torch.sum(pointwise_var, dim=1, keepdim=True) - pointwise_var
+
+ multiplier = (var / torch.square(ex) + 1) / ex
+ average_result = torch.sum(numeric_values_masked * scaled_probability_per_cell * multiplier, dim=1)
+ else:
+ raise ValueError(f"Invalid average_approximation_function: {config.average_approximation_function}")
+
+ if config.use_gumbel_for_aggregation:
+ gumbel_dist = torch.distributions.RelaxedOneHotCategorical(
+ config.aggregation_temperature, logits=logits_aggregation[:, 1:]
+ )
+ # [batch_size, num_aggregation_labels - 1]
+ aggregation_op_only_probs = gumbel_dist.sample()
+ else:
+ # [batch_size, num_aggregation_labels - 1]
+ aggregation_op_only_probs = nn.functional.softmax(
+ logits_aggregation[:, 1:] / config.aggregation_temperature, dim=-1
+ )
+
+ all_results = torch.cat(
+ [
+ torch.unsqueeze(sum_result, dim=1),
+ torch.unsqueeze(average_result, dim=1),
+ torch.unsqueeze(count_result, dim=1),
+ ],
+ dim=1,
+ )
+
+ expected_result = torch.sum(all_results * aggregation_op_only_probs, dim=1)
+ return expected_result
+
+
+# PyTorch does not currently support Huber loss with custom delta so we define it ourself
+def huber_loss(input, target, delta: float = 1.0):
+ errors = torch.abs(input - target) # shape (batch_size,)
+ return torch.where(errors < delta, 0.5 * errors**2, errors * delta - (0.5 * delta**2))
+
+
+def _calculate_regression_loss(
+ answer,
+ aggregate_mask,
+ dist_per_cell,
+ numeric_values,
+ numeric_values_scale,
+ input_mask_float,
+ logits_aggregation,
+ config,
+):
+ """
+ Calculates the regression loss per example.
+
+ Args:
+ answer (`torch.FloatTensor` of shape `(batch_size,)`):
+ Answer for every example in the batch. Nan if there is no scalar answer.
+ aggregate_mask (`torch.FloatTensor` of shape `(batch_size,)`):
+ A mask set to 1 for examples that should use aggregation functions.
+ dist_per_cell (`torch.distributions.Bernoulli`):
+ Cell selection distribution for each cell.
+ numeric_values (`torch.FloatTensor` of shape `(batch_size, seq_length)`):
+ Numeric values of every token. Nan for tokens which are not numeric values.
+ numeric_values_scale (`torch.FloatTensor` of shape `(batch_size, seq_length)`):
+ Scale of the numeric values of every token.
+ input_mask_float (`torch.FloatTensor` of shape `(batch_size, seq_length)`):
+ Mask for the table, without question tokens and table headers.
+ logits_aggregation (`torch.FloatTensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ config ([`TapasConfig`]):
+ Model configuration class with all the parameters of the model
+
+ Returns:
+ per_example_answer_loss_scaled (`torch.FloatTensor` of shape `(batch_size,)`): Scales answer loss for each
+ example in the batch. large_answer_loss_mask (`torch.FloatTensor` of shape `(batch_size,)`): A mask which is 1
+ for examples for which their answer loss is larger than the answer_loss_cutoff.
+ """
+ # float32 (batch_size,)
+ expected_result = _calculate_expected_result(
+ dist_per_cell, numeric_values, numeric_values_scale, input_mask_float, logits_aggregation, config
+ )
+
+ # float32 (batch_size,)
+ answer_masked = torch.where(torch.isnan(answer), torch.zeros_like(answer), answer)
+
+ if config.use_normalized_answer_loss:
+ normalizer = (torch.max(torch.abs(expected_result), torch.abs(answer_masked)) + EPSILON_ZERO_DIVISION).detach()
+
+ normalized_answer_masked = answer_masked / normalizer
+ normalized_expected_result = expected_result / normalizer
+ per_example_answer_loss = huber_loss(
+ normalized_expected_result * aggregate_mask, normalized_answer_masked * aggregate_mask
+ )
+ else:
+ per_example_answer_loss = huber_loss(
+ expected_result * aggregate_mask, answer_masked * aggregate_mask, delta=config.huber_loss_delta
+ )
+
+ if config.answer_loss_cutoff is None:
+ large_answer_loss_mask = torch.ones_like(per_example_answer_loss, dtype=torch.float32)
+
+ else:
+ large_answer_loss_mask = torch.where(
+ per_example_answer_loss > config.answer_loss_cutoff,
+ torch.zeros_like(per_example_answer_loss, dtype=torch.float32),
+ torch.ones_like(per_example_answer_loss, dtype=torch.float32),
+ )
+ per_example_answer_loss_scaled = config.answer_loss_importance * (per_example_answer_loss * aggregate_mask)
+
+ return per_example_answer_loss_scaled, large_answer_loss_mask
+
+
+__all__ = [
+ "TapasForMaskedLM",
+ "TapasForQuestionAnswering",
+ "TapasForSequenceClassification",
+ "TapasModel",
+ "TapasPreTrainedModel",
+ "load_tf_weights_in_tapas",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/modeling_tf_tapas.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/modeling_tf_tapas.py
new file mode 100644
index 0000000000000000000000000000000000000000..624df1fba1766f16b32b0138b01930eec502a788
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/modeling_tf_tapas.py
@@ -0,0 +1,2461 @@
+# coding=utf-8
+# Copyright 2021 Google Research and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TF 2.0 TAPAS model."""
+
+from __future__ import annotations
+
+import enum
+import math
+from dataclasses import dataclass
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_outputs import (
+ TFBaseModelOutputWithPastAndCrossAttentions,
+ TFBaseModelOutputWithPooling,
+ TFMaskedLMOutput,
+ TFSequenceClassifierOutput,
+)
+from ...modeling_tf_utils import (
+ TFMaskedLanguageModelingLoss,
+ TFModelInputType,
+ TFPreTrainedModel,
+ TFSequenceClassificationLoss,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import (
+ ModelOutput,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ is_tensorflow_probability_available,
+ logging,
+ replace_return_docstrings,
+)
+from .configuration_tapas import TapasConfig
+
+
+logger = logging.get_logger(__name__)
+
+# soft dependency
+if is_tensorflow_probability_available():
+ try:
+ import tensorflow_probability as tfp
+
+ # On the first call, check whether a compatible version of TensorFlow is installed
+ # TensorFlow Probability depends on a recent stable release of TensorFlow
+ n = tfp.distributions.Normal(loc=0.0, scale=1.0)
+ except ImportError:
+ logger.error(
+ "TAPAS models are not usable since `tensorflow_probability` can't be loaded. "
+ "It seems you have `tensorflow_probability` installed with the wrong tensorflow version. "
+ "Please try to reinstall it following the instructions here: https://github.com/tensorflow/probability."
+ )
+else:
+ try:
+ import tensorflow_probability as tfp
+
+ # On the first call, check whether a compatible version of TensorFlow is installed
+ # TensorFlow Probability depends on a recent stable release of TensorFlow
+ _ = tfp.distributions.Normal(loc=0.0, scale=1.0)
+ except ImportError:
+ pass
+
+_CONFIG_FOR_DOC = "TapasConfig"
+_CHECKPOINT_FOR_DOC = "google/tapas-base"
+
+
+EPSILON_ZERO_DIVISION = 1e-10
+CLOSE_ENOUGH_TO_LOG_ZERO = -10000.0
+
+
+@dataclass
+class TFTableQuestionAnsweringOutput(ModelOutput):
+ """
+ Output type of [`TFTapasForQuestionAnswering`].
+
+ Args:
+ loss (`tf.Tensor` of shape `(1,)`, *optional*, returned when `labels` (and possibly `answer`, `aggregation_labels`, `numeric_values` and `numeric_values_scale` are provided)):
+ Total loss as the sum of the hierarchical cell selection log-likelihood loss and (optionally) the
+ semi-supervised regression loss and (optionally) supervised loss for aggregations.
+ logits (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Prediction scores of the cell selection head, for every token.
+ logits_aggregation (`tf.Tensor`, *optional*, of shape `(batch_size, num_aggregation_labels)`):
+ Prediction scores of the aggregation head, for every aggregation operator.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`. Hidden-states of the model at the output of each layer plus
+ the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in
+ the self-attention heads.
+ """
+
+ loss: tf.Tensor | None = None
+ logits: tf.Tensor | None = None
+ logits_aggregation: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor] | None = None
+ attentions: tuple[tf.Tensor] | None = None
+
+
+class TFTapasEmbeddings(keras.layers.Layer):
+ """
+ Construct the embeddings from word, position and token_type embeddings. Same as BertEmbeddings but with a number of
+ additional token type embeddings to encode tabular structure.
+ """
+
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+ self.number_of_token_type_embeddings = len(config.type_vocab_sizes)
+ self.reset_position_index_per_cell = config.reset_position_index_per_cell
+ self.hidden_size = config.hidden_size
+ self.max_position_embeddings = config.max_position_embeddings
+ self.initializer_range = config.initializer_range
+ self.LayerNorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="LayerNorm")
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+
+ def build(self, input_shape=None):
+ with tf.name_scope("word_embeddings"):
+ self.weight = self.add_weight(
+ name="weight",
+ shape=[self.config.vocab_size, self.hidden_size],
+ initializer=get_initializer(self.initializer_range),
+ )
+
+ with tf.name_scope("position_embeddings"):
+ self.position_embeddings = self.add_weight(
+ name="embeddings",
+ shape=[self.max_position_embeddings, self.hidden_size],
+ initializer=get_initializer(self.initializer_range),
+ )
+ for i, type_vocab_size in enumerate(self.config.type_vocab_sizes):
+ with tf.name_scope(f"token_type_embeddings_{i}"):
+ setattr(
+ self,
+ f"token_type_embeddings_{i}",
+ self.add_weight(
+ name="embeddings",
+ shape=[type_vocab_size, self.hidden_size],
+ initializer=get_initializer(self.initializer_range),
+ ),
+ )
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "LayerNorm", None) is not None:
+ with tf.name_scope(self.LayerNorm.name):
+ self.LayerNorm.build([None, None, self.config.hidden_size])
+
+ def call(
+ self,
+ input_ids: tf.Tensor | None = None,
+ position_ids: tf.Tensor | None = None,
+ token_type_ids: tf.Tensor | None = None,
+ inputs_embeds: tf.Tensor | None = None,
+ training: bool = False,
+ ) -> tf.Tensor:
+ """
+ Applies embedding based on inputs tensor.
+
+ Returns:
+ final_embeddings (`tf.Tensor`): output embedding tensor.
+ """
+ assert not (input_ids is None and inputs_embeds is None)
+ if input_ids is not None:
+ input_shape = shape_list(input_ids)
+ else:
+ input_shape = shape_list(inputs_embeds)[:-1]
+
+ seq_length = input_shape[1]
+
+ if token_type_ids is None:
+ token_type_ids = tf.fill(dims=input_shape + [self.number_of_token_type_embeddings], value=0)
+
+ if position_ids is None:
+ # create absolute position embeddings
+ position_ids = tf.expand_dims(tf.range(start=0, limit=seq_length), axis=0)
+ position_ids = tf.broadcast_to(position_ids, shape=input_shape)
+ # when self.config.reset_position_index_per_cell is set to True, create relative position embeddings
+ if self.reset_position_index_per_cell:
+ # shape (batch_size, seq_len)
+ col_index = IndexMap(token_type_ids[:, :, 1], self.config.type_vocab_sizes[1], batch_dims=1)
+ # shape (batch_size, seq_len)
+ row_index = IndexMap(token_type_ids[:, :, 2], self.config.type_vocab_sizes[2], batch_dims=1)
+ # shape (batch_size, seq_len)
+ full_index = ProductIndexMap(col_index, row_index)
+ # shape (max_rows * max_columns,). First absolute position for every cell
+ first_position_per_segment = reduce_min(position_ids, full_index)[0]
+ # ? shape (batch_size, seq_len). First absolute position of the cell for every token
+ first_position = gather(first_position_per_segment, full_index)
+ # shape (1, seq_len)
+ position = tf.expand_dims(tf.range(start=0, limit=seq_length), axis=0)
+ position_ids = tf.math.minimum(self.max_position_embeddings - 1, position - first_position)
+
+ if input_ids is not None:
+ check_embeddings_within_bounds(input_ids, self.config.vocab_size)
+ inputs_embeds = tf.gather(params=self.weight, indices=input_ids)
+
+ position_embeddings = tf.gather(self.position_embeddings, indices=position_ids)
+
+ final_embeddings = inputs_embeds + position_embeddings
+
+ for i in range(self.number_of_token_type_embeddings):
+ name = f"token_type_embeddings_{i}"
+ final_embeddings += tf.gather(params=getattr(self, name), indices=token_type_ids[:, :, i])
+
+ final_embeddings = self.LayerNorm(inputs=final_embeddings)
+ final_embeddings = self.dropout(inputs=final_embeddings, training=training)
+
+ return final_embeddings
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertSelfAttention with Bert->Tapas
+class TFTapasSelfAttention(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ if config.hidden_size % config.num_attention_heads != 0:
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number "
+ f"of attention heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.sqrt_att_head_size = math.sqrt(self.attention_head_size)
+
+ self.query = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="query"
+ )
+ self.key = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="key"
+ )
+ self.value = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="value"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.attention_probs_dropout_prob)
+
+ self.is_decoder = config.is_decoder
+ self.config = config
+
+ def transpose_for_scores(self, tensor: tf.Tensor, batch_size: int) -> tf.Tensor:
+ # Reshape from [batch_size, seq_length, all_head_size] to [batch_size, seq_length, num_attention_heads, attention_head_size]
+ tensor = tf.reshape(tensor=tensor, shape=(batch_size, -1, self.num_attention_heads, self.attention_head_size))
+
+ # Transpose the tensor from [batch_size, seq_length, num_attention_heads, attention_head_size] to [batch_size, num_attention_heads, seq_length, attention_head_size]
+ return tf.transpose(tensor, perm=[0, 2, 1, 3])
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor,
+ encoder_attention_mask: tf.Tensor,
+ past_key_value: tuple[tf.Tensor],
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ batch_size = shape_list(hidden_states)[0]
+ mixed_query_layer = self.query(inputs=hidden_states)
+
+ # If this is instantiated as a cross-attention module, the keys
+ # and values come from an encoder; the attention mask needs to be
+ # such that the encoder's padding tokens are not attended to.
+ is_cross_attention = encoder_hidden_states is not None
+
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_layer = past_key_value[0]
+ value_layer = past_key_value[1]
+ attention_mask = encoder_attention_mask
+ elif is_cross_attention:
+ key_layer = self.transpose_for_scores(self.key(inputs=encoder_hidden_states), batch_size)
+ value_layer = self.transpose_for_scores(self.value(inputs=encoder_hidden_states), batch_size)
+ attention_mask = encoder_attention_mask
+ elif past_key_value is not None:
+ key_layer = self.transpose_for_scores(self.key(inputs=hidden_states), batch_size)
+ value_layer = self.transpose_for_scores(self.value(inputs=hidden_states), batch_size)
+ key_layer = tf.concat([past_key_value[0], key_layer], axis=2)
+ value_layer = tf.concat([past_key_value[1], value_layer], axis=2)
+ else:
+ key_layer = self.transpose_for_scores(self.key(inputs=hidden_states), batch_size)
+ value_layer = self.transpose_for_scores(self.value(inputs=hidden_states), batch_size)
+
+ query_layer = self.transpose_for_scores(mixed_query_layer, batch_size)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(tf.Tensor, tf.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(tf.Tensor, tf.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_layer, value_layer)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ # (batch size, num_heads, seq_len_q, seq_len_k)
+ attention_scores = tf.matmul(query_layer, key_layer, transpose_b=True)
+ dk = tf.cast(self.sqrt_att_head_size, dtype=attention_scores.dtype)
+ attention_scores = tf.divide(attention_scores, dk)
+
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in TFTapasModel call() function)
+ attention_scores = tf.add(attention_scores, attention_mask)
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = stable_softmax(logits=attention_scores, axis=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(inputs=attention_probs, training=training)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = tf.multiply(attention_probs, head_mask)
+
+ attention_output = tf.matmul(attention_probs, value_layer)
+ attention_output = tf.transpose(attention_output, perm=[0, 2, 1, 3])
+
+ # (batch_size, seq_len_q, all_head_size)
+ attention_output = tf.reshape(tensor=attention_output, shape=(batch_size, -1, self.all_head_size))
+ outputs = (attention_output, attention_probs) if output_attentions else (attention_output,)
+
+ if self.is_decoder:
+ outputs = outputs + (past_key_value,)
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "query", None) is not None:
+ with tf.name_scope(self.query.name):
+ self.query.build([None, None, self.config.hidden_size])
+ if getattr(self, "key", None) is not None:
+ with tf.name_scope(self.key.name):
+ self.key.build([None, None, self.config.hidden_size])
+ if getattr(self, "value", None) is not None:
+ with tf.name_scope(self.value.name):
+ self.value.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertSelfOutput with Bert->Tapas
+class TFTapasSelfOutput(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.LayerNorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="LayerNorm")
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+ hidden_states = self.LayerNorm(inputs=hidden_states + input_tensor)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+ if getattr(self, "LayerNorm", None) is not None:
+ with tf.name_scope(self.LayerNorm.name):
+ self.LayerNorm.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertAttention with Bert->Tapas
+class TFTapasAttention(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.self_attention = TFTapasSelfAttention(config, name="self")
+ self.dense_output = TFTapasSelfOutput(config, name="output")
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ def call(
+ self,
+ input_tensor: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor,
+ encoder_attention_mask: tf.Tensor,
+ past_key_value: tuple[tf.Tensor],
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ self_outputs = self.self_attention(
+ hidden_states=input_tensor,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = self.dense_output(
+ hidden_states=self_outputs[0], input_tensor=input_tensor, training=training
+ )
+ # add attentions (possibly with past_key_value) if we output them
+ outputs = (attention_output,) + self_outputs[1:]
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attention", None) is not None:
+ with tf.name_scope(self.self_attention.name):
+ self.self_attention.build(None)
+ if getattr(self, "dense_output", None) is not None:
+ with tf.name_scope(self.dense_output.name):
+ self.dense_output.build(None)
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertIntermediate with Bert->Tapas
+class TFTapasIntermediate(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.intermediate_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = get_tf_activation(config.hidden_act)
+ else:
+ self.intermediate_act_fn = config.hidden_act
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertOutput with Bert->Tapas
+class TFTapasOutput(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.LayerNorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="LayerNorm")
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+ hidden_states = self.LayerNorm(inputs=hidden_states + input_tensor)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.intermediate_size])
+ if getattr(self, "LayerNorm", None) is not None:
+ with tf.name_scope(self.LayerNorm.name):
+ self.LayerNorm.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertLayer with Bert->Tapas
+class TFTapasLayer(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.attention = TFTapasAttention(config, name="attention")
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = TFTapasAttention(config, name="crossattention")
+ self.intermediate = TFTapasIntermediate(config, name="intermediate")
+ self.bert_output = TFTapasOutput(config, name="output")
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor | None,
+ encoder_attention_mask: tf.Tensor | None,
+ past_key_value: tuple[tf.Tensor] | None,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ # decoder uni-directional self-attention cached key/values tuple is at positions 1,2
+ self_attn_past_key_value = past_key_value[:2] if past_key_value is not None else None
+ self_attention_outputs = self.attention(
+ input_tensor=hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ past_key_value=self_attn_past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = self_attention_outputs[0]
+
+ # if decoder, the last output is tuple of self-attn cache
+ if self.is_decoder:
+ outputs = self_attention_outputs[1:-1]
+ present_key_value = self_attention_outputs[-1]
+ else:
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ cross_attn_present_key_value = None
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ # cross_attn cached key/values tuple is at positions 3,4 of past_key_value tuple
+ cross_attn_past_key_value = past_key_value[-2:] if past_key_value is not None else None
+ cross_attention_outputs = self.crossattention(
+ input_tensor=attention_output,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_value=cross_attn_past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:-1] # add cross attentions if we output attention weights
+
+ # add cross-attn cache to positions 3,4 of present_key_value tuple
+ cross_attn_present_key_value = cross_attention_outputs[-1]
+ present_key_value = present_key_value + cross_attn_present_key_value
+
+ intermediate_output = self.intermediate(hidden_states=attention_output)
+ layer_output = self.bert_output(
+ hidden_states=intermediate_output, input_tensor=attention_output, training=training
+ )
+ outputs = (layer_output,) + outputs # add attentions if we output them
+
+ # if decoder, return the attn key/values as the last output
+ if self.is_decoder:
+ outputs = outputs + (present_key_value,)
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "attention", None) is not None:
+ with tf.name_scope(self.attention.name):
+ self.attention.build(None)
+ if getattr(self, "intermediate", None) is not None:
+ with tf.name_scope(self.intermediate.name):
+ self.intermediate.build(None)
+ if getattr(self, "bert_output", None) is not None:
+ with tf.name_scope(self.bert_output.name):
+ self.bert_output.build(None)
+ if getattr(self, "crossattention", None) is not None:
+ with tf.name_scope(self.crossattention.name):
+ self.crossattention.build(None)
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertEncoder with Bert->Tapas
+class TFTapasEncoder(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.layer = [TFTapasLayer(config, name=f"layer_._{i}") for i in range(config.num_hidden_layers)]
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor | None,
+ encoder_attention_mask: tf.Tensor | None,
+ past_key_values: tuple[tuple[tf.Tensor]] | None,
+ use_cache: bool | None,
+ output_attentions: bool,
+ output_hidden_states: bool,
+ return_dict: bool,
+ training: bool = False,
+ ) -> TFBaseModelOutputWithPastAndCrossAttentions | tuple[tf.Tensor]:
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None
+
+ next_decoder_cache = () if use_cache else None
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ past_key_value = past_key_values[i] if past_key_values is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask[i],
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = layer_outputs[0]
+
+ if use_cache:
+ next_decoder_cache += (layer_outputs[-1],)
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+ if self.config.add_cross_attention and encoder_hidden_states is not None:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v for v in [hidden_states, all_hidden_states, all_attentions, all_cross_attentions] if v is not None
+ )
+
+ return TFBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_decoder_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer", None) is not None:
+ for layer in self.layer:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertPooler with Bert->Tapas
+class TFTapasPooler(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ activation="tanh",
+ name="dense",
+ )
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(inputs=first_token_tensor)
+
+ return pooled_output
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertPredictionHeadTransform with Bert->Tapas
+class TFTapasPredictionHeadTransform(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ name="dense",
+ )
+
+ if isinstance(config.hidden_act, str):
+ self.transform_act_fn = get_tf_activation(config.hidden_act)
+ else:
+ self.transform_act_fn = config.hidden_act
+
+ self.LayerNorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="LayerNorm")
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.transform_act_fn(hidden_states)
+ hidden_states = self.LayerNorm(inputs=hidden_states)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+ if getattr(self, "LayerNorm", None) is not None:
+ with tf.name_scope(self.LayerNorm.name):
+ self.LayerNorm.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertLMPredictionHead with Bert->Tapas
+class TFTapasLMPredictionHead(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, input_embeddings: keras.layers.Layer, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+ self.hidden_size = config.hidden_size
+
+ self.transform = TFTapasPredictionHeadTransform(config, name="transform")
+
+ # The output weights are the same as the input embeddings, but there is
+ # an output-only bias for each token.
+ self.input_embeddings = input_embeddings
+
+ def build(self, input_shape=None):
+ self.bias = self.add_weight(shape=(self.config.vocab_size,), initializer="zeros", trainable=True, name="bias")
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transform", None) is not None:
+ with tf.name_scope(self.transform.name):
+ self.transform.build(None)
+
+ def get_output_embeddings(self) -> keras.layers.Layer:
+ return self.input_embeddings
+
+ def set_output_embeddings(self, value: tf.Variable):
+ self.input_embeddings.weight = value
+ self.input_embeddings.vocab_size = shape_list(value)[0]
+
+ def get_bias(self) -> dict[str, tf.Variable]:
+ return {"bias": self.bias}
+
+ def set_bias(self, value: tf.Variable):
+ self.bias = value["bias"]
+ self.config.vocab_size = shape_list(value["bias"])[0]
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.transform(hidden_states=hidden_states)
+ seq_length = shape_list(hidden_states)[1]
+ hidden_states = tf.reshape(tensor=hidden_states, shape=[-1, self.hidden_size])
+ hidden_states = tf.matmul(a=hidden_states, b=self.input_embeddings.weight, transpose_b=True)
+ hidden_states = tf.reshape(tensor=hidden_states, shape=[-1, seq_length, self.config.vocab_size])
+ hidden_states = tf.nn.bias_add(value=hidden_states, bias=self.bias)
+
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertMLMHead with Bert->Tapas
+class TFTapasMLMHead(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, input_embeddings: keras.layers.Layer, **kwargs):
+ super().__init__(**kwargs)
+
+ self.predictions = TFTapasLMPredictionHead(config, input_embeddings, name="predictions")
+
+ def call(self, sequence_output: tf.Tensor) -> tf.Tensor:
+ prediction_scores = self.predictions(hidden_states=sequence_output)
+
+ return prediction_scores
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "predictions", None) is not None:
+ with tf.name_scope(self.predictions.name):
+ self.predictions.build(None)
+
+
+@keras_serializable
+class TFTapasMainLayer(keras.layers.Layer):
+ config_class = TapasConfig
+
+ def __init__(self, config: TapasConfig, add_pooling_layer: bool = True, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+
+ self.embeddings = TFTapasEmbeddings(config, name="embeddings")
+ self.encoder = TFTapasEncoder(config, name="encoder")
+ self.pooler = TFTapasPooler(config, name="pooler") if add_pooling_layer else None
+
+ def get_input_embeddings(self) -> keras.layers.Layer:
+ return self.embeddings
+
+ def set_input_embeddings(self, value: tf.Variable):
+ self.embeddings.weight = value
+ self.embeddings.vocab_size = shape_list(value)[0]
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ raise NotImplementedError
+
+ @unpack_inputs
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFBaseModelOutputWithPooling | tuple[tf.Tensor]:
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = shape_list(input_ids)
+ elif inputs_embeds is not None:
+ input_shape = shape_list(inputs_embeds)[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ if attention_mask is None:
+ attention_mask = tf.fill(dims=input_shape, value=1)
+
+ if token_type_ids is None:
+ token_type_ids = tf.fill(dims=input_shape + [len(self.config.type_vocab_sizes)], value=0)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ training=training,
+ )
+
+ # We create a 3D attention mask from a 2D tensor mask.
+ # Sizes are [batch_size, 1, 1, to_seq_length]
+ # So we can broadcast to [batch_size, num_heads, from_seq_length, to_seq_length]
+ # this attention mask is more simple than the triangular masking of causal attention
+ # used in OpenAI GPT, we just need to prepare the broadcast dimension here.
+ extended_attention_mask = tf.reshape(attention_mask, (input_shape[0], 1, 1, input_shape[1]))
+
+ # Since attention_mask is 1.0 for positions we want to attend and 0.0 for
+ # masked positions, this operation will create a tensor which is 0.0 for
+ # positions we want to attend and -10000.0 for masked positions.
+ # Since we are adding it to the raw scores before the softmax, this is
+ # effectively the same as removing these entirely.
+ extended_attention_mask = tf.cast(extended_attention_mask, dtype=embedding_output.dtype)
+ one_cst = tf.constant(1.0, dtype=embedding_output.dtype)
+ ten_thousand_cst = tf.constant(-10000.0, dtype=embedding_output.dtype)
+ extended_attention_mask = tf.multiply(tf.subtract(one_cst, extended_attention_mask), ten_thousand_cst)
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ if head_mask is not None:
+ raise NotImplementedError
+ else:
+ head_mask = [None] * self.config.num_hidden_layers
+
+ encoder_outputs = self.encoder(
+ hidden_states=embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(hidden_states=sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (
+ sequence_output,
+ pooled_output,
+ ) + encoder_outputs[1:]
+
+ return TFBaseModelOutputWithPooling(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "embeddings", None) is not None:
+ with tf.name_scope(self.embeddings.name):
+ self.embeddings.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "pooler", None) is not None:
+ with tf.name_scope(self.pooler.name):
+ self.pooler.build(None)
+
+
+class TFTapasPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = TapasConfig
+ base_model_prefix = "tapas"
+
+ @property
+ def input_signature(self):
+ return {
+ "input_ids": tf.TensorSpec((None, None), tf.int32, name="input_ids"),
+ "attention_mask": tf.TensorSpec((None, None), tf.float32, name="attention_mask"),
+ "token_type_ids": tf.TensorSpec((None, None, 7), tf.int32, name="token_type_ids"),
+ }
+
+
+TAPAS_START_DOCSTRING = r"""
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Parameters:
+ config ([`TapasConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+TAPAS_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`np.ndarray`, `tf.Tensor`, `list[tf.Tensor]` ``dict[str, tf.Tensor]` or `dict[str, np.ndarray]` and each example must have the shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.__call__`] and
+ [`PreTrainedTokenizer.encode`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`np.ndarray` or `tf.Tensor` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ token_type_ids (`np.ndarray` or `tf.Tensor` of shape `({0}, 7)`, *optional*):
+ Token indices that encode tabular structure. Indices can be obtained using [`AutoTokenizer`]. See this
+ class for more info.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`np.ndarray` or `tf.Tensor` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. If
+ `reset_position_index_per_cell` of [`TapasConfig`] is set to `True`, relative position embeddings will be
+ used. Selected in the range `[0, config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ head_mask (`np.ndarray` or `tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ inputs_embeds (`np.ndarray` or `tf.Tensor` of shape `({0}, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False``):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+
+@add_start_docstrings(
+ "The bare Tapas Model transformer outputting raw hidden-states without any specific head on top.",
+ TAPAS_START_DOCSTRING,
+)
+class TFTapasModel(TFTapasPreTrainedModel):
+ def __init__(self, config: TapasConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.tapas = TFTapasMainLayer(config, name="tapas")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(TAPAS_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @replace_return_docstrings(output_type=TFBaseModelOutputWithPooling, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ ) -> TFBaseModelOutputWithPooling | tuple[tf.Tensor]:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasModel
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base")
+ >>> model = TapasModel.from_pretrained("google/tapas-base")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+ >>> queries = ["How many movies has George Clooney played in?", "How old is Brad Pitt?"]
+
+ >>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="tf")
+ >>> outputs = model(**inputs)
+
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ outputs = self.tapas(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "tapas", None) is not None:
+ with tf.name_scope(self.tapas.name):
+ self.tapas.build(None)
+
+
+@add_start_docstrings("""Tapas Model with a `language modeling` head on top.""", TAPAS_START_DOCSTRING)
+class TFTapasForMaskedLM(TFTapasPreTrainedModel, TFMaskedLanguageModelingLoss):
+ def __init__(self, config: TapasConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ if config.is_decoder:
+ logger.warning(
+ "If you want to use `TFTapasForMaskedLM` make sure `config.is_decoder=False` for "
+ "bi-directional self-attention."
+ )
+
+ self.tapas = TFTapasMainLayer(config, add_pooling_layer=False, name="tapas")
+ self.lm_head = TFTapasMLMHead(config, input_embeddings=self.tapas.embeddings, name="cls")
+
+ def get_lm_head(self) -> keras.layers.Layer:
+ return self.lm_head.predictions
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(TAPAS_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @replace_return_docstrings(output_type=TFMaskedLMOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFMaskedLMOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` or `np.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasForMaskedLM
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base")
+ >>> model = TapasForMaskedLM.from_pretrained("google/tapas-base")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+
+ >>> inputs = tokenizer(
+ ... table=table, queries="How many [MASK] has George [MASK] played in?", return_tensors="tf"
+ ... )
+ >>> labels = tokenizer(
+ ... table=table, queries="How many movies has George Clooney played in?", return_tensors="tf"
+ ... )["input_ids"]
+
+ >>> outputs = model(**inputs, labels=labels)
+ >>> logits = outputs.logits
+ ```"""
+ outputs = self.tapas(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+ loss = None if labels is None else self.hf_compute_loss(labels=labels, logits=prediction_scores)
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFMaskedLMOutput(
+ loss=loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "tapas", None) is not None:
+ with tf.name_scope(self.tapas.name):
+ self.tapas.build(None)
+ if getattr(self, "lm_head", None) is not None:
+ with tf.name_scope(self.lm_head.name):
+ self.lm_head.build(None)
+
+
+class TFTapasComputeTokenLogits(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.temperature = config.temperature
+ # cell selection heads
+ with tf.name_scope("output"):
+ self.output_weights = self.add_weight(
+ name="output_weights",
+ shape=(config.hidden_size,),
+ dtype=tf.float32,
+ trainable=True,
+ initializer=tf.zeros_initializer()
+ if config.init_cell_selection_weights_to_zero
+ else keras.initializers.TruncatedNormal(stddev=config.initializer_range),
+ )
+ self.output_bias = self.add_weight(
+ name="output_bias", shape=(), trainable=True, initializer=tf.zeros_initializer()
+ )
+
+ def call(self, sequence_output: tf.Tensor) -> tf.Tensor:
+ """
+ Computes logits per token
+
+ Args:
+ sequence_output (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Also known as last_hidden_state. Sequence of hidden-states at the output of the last layer of the
+ model.
+
+ Returns:
+ logits (`tf.Tensor` of shape `(batch_size, sequence_length)`): Logits per token.
+ """
+ logits = (tf.einsum("bsj,j->bs", sequence_output, self.output_weights) + self.output_bias) / self.temperature
+ return logits
+
+
+class TFTapasComputeColumnLogits(keras.layers.Layer):
+ def __init__(self, config: TapasConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ with tf.name_scope("column_output"):
+ self.column_output_weights = self.add_weight(
+ name="column_output_weights",
+ shape=[config.hidden_size],
+ dtype=tf.float32,
+ trainable=True,
+ initializer=tf.zeros_initializer()
+ if config.init_cell_selection_weights_to_zero
+ else keras.initializers.TruncatedNormal(stddev=config.initializer_range),
+ )
+ self.column_output_bias = self.add_weight(
+ name="column_output_bias", shape=(), trainable=True, initializer=tf.zeros_initializer()
+ )
+
+ def call(self, sequence_output, cell_index, cell_mask, allow_empty_column_selection) -> tf.Tensor:
+ """
+ Computes the column logits.
+
+ Args:
+ sequence_output (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Also known as last_hidden_state. Sequence of hidden-states at the output of the last layer of the
+ model.
+ cell_index (`ProductIndexMap`):
+ Index that groups tokens into cells.
+ cell_mask (`tf.Tensor` of shape `(batch_size, max_num_rows * max_num_cols)`):
+ Mask for cells that exist in the table (i.e. that are not padding).
+ allow_empty_column_selection (`bool`):
+ Whether to allow not to select any column
+
+ Returns:
+ column_logits (`tf.Tensor`of shape `(batch_size, max_num_cols)`): Tensor containing the column logits for
+ every example in the batch.
+ """
+
+ # First, compute the token logits (batch_size, seq_len) - without temperature
+ token_logits = tf.einsum("bsj,j->bs", sequence_output, self.column_output_weights) + self.column_output_bias
+
+ # Next, average the logits per cell (batch_size, max_num_cols*max_num_rows)
+ cell_logits, cell_logits_index = reduce_mean(token_logits, cell_index)
+
+ # Finally, average the logits per column (batch_size, max_num_cols)
+ column_index = cell_index.project_inner(cell_logits_index)
+ column_logits, out_index = reduce_sum(cell_logits * cell_mask, column_index)
+
+ cell_count, _ = reduce_sum(cell_mask, column_index)
+ column_logits /= cell_count + EPSILON_ZERO_DIVISION
+
+ # Mask columns that do not appear in the example.
+ is_padding = tf.logical_and(cell_count < 0.5, tf.not_equal(out_index.indices, 0))
+ column_logits += CLOSE_ENOUGH_TO_LOG_ZERO * tf.cast(is_padding, tf.float32)
+
+ if not allow_empty_column_selection:
+ column_logits += CLOSE_ENOUGH_TO_LOG_ZERO * tf.cast(tf.equal(out_index.indices, 0), tf.float32)
+
+ return column_logits
+
+
+@add_start_docstrings(
+ """
+ Tapas Model with a cell selection head and optional aggregation head on top for question-answering tasks on tables
+ (linear layers on top of the hidden-states output to compute `logits` and optional `logits_aggregation`), e.g. for
+ SQA, WTQ or WikiSQL-supervised tasks.
+ """,
+ TAPAS_START_DOCSTRING,
+)
+class TFTapasForQuestionAnswering(TFTapasPreTrainedModel):
+ def __init__(self, config: TapasConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ # base model
+ self.tapas = TFTapasMainLayer(config, name="tapas")
+
+ # dropout
+ self.dropout = keras.layers.Dropout(config.hidden_dropout_prob)
+
+ self.compute_token_logits = TFTapasComputeTokenLogits(config, name="compute_token_logits")
+
+ self.compute_column_logits = TFTapasComputeColumnLogits(config, name="compute_column_logits")
+
+ if config.num_aggregation_labels > 0:
+ self.aggregation_classifier = keras.layers.Dense(
+ config.num_aggregation_labels,
+ kernel_initializer=get_initializer(config.initializer_range),
+ name="aggregation_classifier",
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(TAPAS_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @replace_return_docstrings(output_type=TFTableQuestionAnsweringOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ table_mask: np.ndarray | tf.Tensor | None = None,
+ aggregation_labels: np.ndarray | tf.Tensor | None = None,
+ float_answer: np.ndarray | tf.Tensor | None = None,
+ numeric_values: np.ndarray | tf.Tensor | None = None,
+ numeric_values_scale: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFTableQuestionAnsweringOutput | tuple[tf.Tensor]:
+ r"""
+ table_mask (`tf.Tensor` of shape `(batch_size, seq_length)`, *optional*):
+ Mask for the table. Indicates which tokens belong to the table (1). Question tokens, table headers and
+ padding are 0.
+ labels (`tf.Tensor` of shape `(batch_size, seq_length)`, *optional*):
+ Labels per token for computing the hierarchical cell selection loss. This encodes the positions of the
+ answer appearing in the table. Can be obtained using [`AutoTokenizer`].
+
+ - 1 for tokens that are **part of the answer**,
+ - 0 for tokens that are **not part of the answer**.
+
+ aggregation_labels (`tf.Tensor` of shape `(batch_size, )`, *optional*):
+ Aggregation function index for every example in the batch for computing the aggregation loss. Indices
+ should be in `[0, ..., config.num_aggregation_labels - 1]`. Only required in case of strong supervision for
+ aggregation (WikiSQL-supervised).
+ float_answer (`tf.Tensor` of shape `(batch_size, )`, *optional*):
+ Float answer for every example in the batch. Set to *float('nan')* for cell selection questions. Only
+ required in case of weak supervision (WTQ) to calculate the aggregate mask and regression loss.
+ numeric_values (`tf.Tensor` of shape `(batch_size, seq_length)`, *optional*):
+ Numeric values of every token, NaN for tokens which are not numeric values. Can be obtained using
+ [`AutoTokenizer`]. Only required in case of weak supervision for aggregation (WTQ) to calculate the
+ regression loss.
+ numeric_values_scale (`tf.Tensor` of shape `(batch_size, seq_length)`, *optional*):
+ Scale of the numeric values of every token. Can be obtained using [`AutoTokenizer`]. Only required in case
+ of weak supervision for aggregation (WTQ) to calculate the regression loss.
+
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasForQuestionAnswering
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base-finetuned-wtq")
+ >>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base-finetuned-wtq")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+ >>> queries = ["How many movies has George Clooney played in?", "How old is Brad Pitt?"]
+
+ >>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="tf")
+ >>> outputs = model(**inputs)
+
+ >>> logits = outputs.logits
+ >>> logits_aggregation = outputs.logits_aggregation
+ ```"""
+
+ outputs = self.tapas(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = outputs[0]
+ pooled_output = outputs[1]
+
+ sequence_output = self.dropout(sequence_output)
+
+ if input_ids is not None:
+ input_shape = shape_list(input_ids)
+ else:
+ input_shape = shape_list(inputs_embeds)[:-1]
+
+ # Construct indices for the table.
+ if token_type_ids is None:
+ token_type_ids = tf.fill(input_shape + [len(self.config.type_vocab_sizes)], 0)
+
+ token_types = [
+ "segment_ids",
+ "column_ids",
+ "row_ids",
+ "prev_labels",
+ "column_ranks",
+ "inv_column_ranks",
+ "numeric_relations",
+ ]
+
+ row_ids = token_type_ids[:, :, token_types.index("row_ids")]
+ column_ids = token_type_ids[:, :, token_types.index("column_ids")]
+
+ # Construct indices for the table.
+ row_index = IndexMap(
+ indices=tf.minimum(tf.cast(row_ids, tf.int32), self.config.max_num_rows - 1),
+ num_segments=self.config.max_num_rows,
+ batch_dims=1,
+ )
+ col_index = IndexMap(
+ indices=tf.minimum(tf.cast(column_ids, tf.int32), self.config.max_num_columns - 1),
+ num_segments=self.config.max_num_columns,
+ batch_dims=1,
+ )
+ cell_index = ProductIndexMap(row_index, col_index)
+
+ # Masks.
+ input_shape = shape_list(input_ids) if input_ids is not None else shape_list(inputs_embeds)[:-1]
+ if attention_mask is None:
+ attention_mask = tf.ones(input_shape)
+ # Table cells only, without question tokens and table headers.
+ if table_mask is None:
+ table_mask = tf.where(row_ids > 0, tf.ones_like(row_ids), tf.zeros_like(row_ids))
+ # [batch_size, seq_length]
+ input_mask_float = tf.cast(attention_mask, tf.float32)
+ table_mask_float = tf.cast(table_mask, tf.float32)
+
+ # Mask for cells that exist in the table (i.e. that are not padding).
+ cell_mask, _ = reduce_mean(input_mask_float, cell_index)
+
+ # Compute logits per token. These are used to select individual cells.
+ logits = self.compute_token_logits(sequence_output)
+
+ # Compute logits per column. These are used to select a column.
+ column_logits = None
+ if self.config.select_one_column:
+ column_logits = self.compute_column_logits(
+ sequence_output, cell_index, cell_mask, self.config.allow_empty_column_selection
+ )
+
+ # Aggregate logits.
+ logits_aggregation = None
+ if self.config.num_aggregation_labels > 0:
+ logits_aggregation = self.aggregation_classifier(pooled_output)
+
+ # Total loss calculation
+ total_loss = tf.zeros(shape=(1,), dtype=tf.float32)
+ calculate_loss = False
+ if labels is not None:
+ calculate_loss = True
+ is_supervised = not self.config.num_aggregation_labels > 0 or not self.config.use_answer_as_supervision
+
+ # Semi-supervised cell selection in case of no aggregation:
+ # If the answer (the denotation) appears directly in the table we might
+ # select the answer without applying any aggregation function. There are
+ # some ambiguous cases, see utils._calculate_aggregate_mask for more info.
+ # `aggregate_mask` is 1 for examples where we chose to aggregate and 0
+ # for examples where we chose to select the answer directly.
+ # `labels` encodes the positions of the answer appearing in the table.
+ if is_supervised:
+ aggregate_mask = None
+ else:
+ if float_answer is not None:
+ assert shape_list(labels)[0] == shape_list(float_answer)[0], (
+ "Make sure the answers are a FloatTensor of shape (batch_size,)"
+ )
+ # [batch_size]
+ aggregate_mask = _calculate_aggregate_mask(
+ float_answer,
+ pooled_output,
+ self.config.cell_selection_preference,
+ labels,
+ self.aggregation_classifier,
+ )
+ else:
+ aggregate_mask = None
+ raise ValueError("You have to specify float answers in order to calculate the aggregate mask")
+
+ # Cell selection log-likelihood
+ if self.config.average_logits_per_cell:
+ logits_per_cell, _ = reduce_mean(logits, cell_index)
+ logits = gather(logits_per_cell, cell_index)
+ dist_per_token = tfp.distributions.Bernoulli(logits=logits)
+
+ # Compute cell selection loss per example.
+ selection_loss_per_example = None
+ if not self.config.select_one_column:
+ weight = tf.where(
+ labels == 0,
+ tf.ones_like(labels, dtype=tf.float32),
+ self.config.positive_label_weight * tf.ones_like(labels, dtype=tf.float32),
+ )
+ selection_loss_per_token = -dist_per_token.log_prob(labels) * weight
+ selection_loss_per_example = tf.reduce_sum(selection_loss_per_token * input_mask_float, axis=1) / (
+ tf.reduce_sum(input_mask_float, axis=1) + EPSILON_ZERO_DIVISION
+ )
+ else:
+ selection_loss_per_example, logits = _single_column_cell_selection_loss(
+ logits, column_logits, labels, cell_index, col_index, cell_mask
+ )
+ dist_per_token = tfp.distributions.Bernoulli(logits=logits)
+
+ # Supervised cell selection
+ if self.config.disable_per_token_loss:
+ pass
+ elif is_supervised:
+ total_loss += tf.reduce_mean(selection_loss_per_example)
+ else:
+ # For the not supervised case, do not assign loss for cell selection
+ total_loss += tf.reduce_mean(selection_loss_per_example * (1.0 - aggregate_mask))
+
+ # Semi-supervised regression loss and supervised loss for aggregations
+ if self.config.num_aggregation_labels > 0:
+ if is_supervised:
+ # Note that `aggregate_mask` is None if the setting is supervised.
+ if aggregation_labels is not None:
+ assert shape_list(labels)[0] == shape_list(aggregation_labels)[0], (
+ "Make sure the aggregation labels are a LongTensor of shape (batch_size,)"
+ )
+ per_example_additional_loss = _calculate_aggregation_loss(
+ logits_aggregation,
+ aggregate_mask,
+ aggregation_labels,
+ self.config.use_answer_as_supervision,
+ self.config.num_aggregation_labels,
+ self.config.aggregation_loss_weight,
+ )
+ else:
+ raise ValueError(
+ "You have to specify aggregation labels in order to calculate the aggregation loss"
+ )
+ else:
+ aggregation_labels = tf.zeros(shape_list(labels)[0], dtype=tf.int32)
+ per_example_additional_loss = _calculate_aggregation_loss(
+ logits_aggregation,
+ aggregate_mask,
+ aggregation_labels,
+ self.config.use_answer_as_supervision,
+ self.config.num_aggregation_labels,
+ self.config.aggregation_loss_weight,
+ )
+
+ if self.config.use_answer_as_supervision:
+ if numeric_values is not None and numeric_values_scale is not None:
+ assert shape_list(numeric_values) == shape_list(numeric_values_scale)
+ # Add regression loss for numeric answers which require aggregation.
+ answer_loss, large_answer_loss_mask = _calculate_regression_loss(
+ float_answer,
+ aggregate_mask,
+ dist_per_token,
+ numeric_values,
+ numeric_values_scale,
+ table_mask_float,
+ logits_aggregation,
+ self.config,
+ )
+ per_example_additional_loss += answer_loss
+ # Zero loss for examples with answer_loss > cutoff.
+ per_example_additional_loss *= large_answer_loss_mask
+ else:
+ raise ValueError(
+ "You have to specify numeric values and numeric values scale in order to calculate the"
+ " regression loss"
+ )
+ total_loss += tf.reduce_mean(per_example_additional_loss)
+
+ else:
+ # if no label ids are provided, set them to zeros in order to properly compute logits
+ labels = tf.zeros_like(logits)
+ _, logits = _single_column_cell_selection_loss(
+ logits, column_logits, labels, cell_index, col_index, cell_mask
+ )
+ if not return_dict:
+ output = (logits, logits_aggregation) + outputs[2:]
+ return ((total_loss,) + output) if calculate_loss else output
+
+ return TFTableQuestionAnsweringOutput(
+ loss=total_loss if calculate_loss else None,
+ logits=logits,
+ logits_aggregation=logits_aggregation,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "tapas", None) is not None:
+ with tf.name_scope(self.tapas.name):
+ self.tapas.build(None)
+ if getattr(self, "compute_token_logits", None) is not None:
+ with tf.name_scope(self.compute_token_logits.name):
+ self.compute_token_logits.build(None)
+ if getattr(self, "compute_column_logits", None) is not None:
+ with tf.name_scope(self.compute_column_logits.name):
+ self.compute_column_logits.build(None)
+ if getattr(self, "aggregation_classifier", None) is not None:
+ with tf.name_scope(self.aggregation_classifier.name):
+ self.aggregation_classifier.build([None, None, self.config.hidden_size])
+
+
+@add_start_docstrings(
+ """
+ Tapas Model with a sequence classification head on top (a linear layer on top of the pooled output), e.g. for table
+ entailment tasks, such as TabFact (Chen et al., 2020).
+ """,
+ TAPAS_START_DOCSTRING,
+)
+class TFTapasForSequenceClassification(TFTapasPreTrainedModel, TFSequenceClassificationLoss):
+ def __init__(self, config: TapasConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.tapas = TFTapasMainLayer(config, name="tapas")
+ self.dropout = keras.layers.Dropout(config.hidden_dropout_prob, name="dropout")
+ self.classifier = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="classifier"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(TAPAS_INPUTS_DOCSTRING.format("batch_size, num_choices, sequence_length"))
+ @replace_return_docstrings(output_type=TFSequenceClassifierOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFSequenceClassifierOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy). Note: this is called
+ "classification_class_index" in the original implementation.
+
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, TapasForSequenceClassification
+ >>> import tensorflow as tf
+ >>> import pandas as pd
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/tapas-base-finetuned-tabfact")
+ >>> model = TapasForSequenceClassification.from_pretrained("google/tapas-base-finetuned-tabfact")
+
+ >>> data = {
+ ... "Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"],
+ ... "Age": ["56", "45", "59"],
+ ... "Number of movies": ["87", "53", "69"],
+ ... }
+ >>> table = pd.DataFrame.from_dict(data)
+ >>> queries = [
+ ... "There is only one actor who is 45 years old",
+ ... "There are 3 actors which played in more than 60 movies",
+ ... ]
+
+ >>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="tf")
+ >>> labels = tf.convert_to_tensor([1, 0]) # 1 means entailed, 0 means refuted
+
+ >>> outputs = model(**inputs, labels=labels)
+ >>> loss = outputs.loss
+ >>> logits = outputs.logits
+ ```"""
+
+ outputs = self.tapas(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ pooled_output = outputs[1]
+ pooled_output = self.dropout(inputs=pooled_output, training=training)
+ logits = self.classifier(inputs=pooled_output)
+ loss = None if labels is None else self.hf_compute_loss(labels=labels, logits=logits)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFSequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "tapas", None) is not None:
+ with tf.name_scope(self.tapas.name):
+ self.tapas.build(None)
+ if getattr(self, "dropout", None) is not None:
+ with tf.name_scope(self.dropout.name):
+ self.dropout.build(None)
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.config.hidden_size])
+
+
+""" TAPAS utilities."""
+
+
+class AverageApproximationFunction(str, enum.Enum):
+ RATIO = "ratio"
+ FIRST_ORDER = "first_order"
+ SECOND_ORDER = "second_order"
+
+
+# Beginning of everything related to segmented tensors
+
+
+class IndexMap:
+ """Index grouping entries within a tensor."""
+
+ def __init__(self, indices, num_segments, batch_dims=0):
+ """
+ Creates an index.
+
+ Args:
+ indices: Tensor of indices, same shape as `values`.
+ num_segments: Scalar tensor, the number of segments. All elements
+ in a batched segmented tensor must have the same number of segments (although many segments can be empty).
+ batch_dims: Python integer, the number of batch dimensions. The first
+ `batch_dims` dimensions of a SegmentedTensor are treated as batch dimensions. Segments in different batch
+ elements are always distinct even if they have the same index.
+ """
+ self.indices = tf.convert_to_tensor(indices)
+ self.num_segments = tf.convert_to_tensor(num_segments)
+ self.batch_dims = batch_dims
+
+ def batch_shape(self):
+ return tf.shape(self.indices)[: self.batch_dims]
+
+
+class ProductIndexMap(IndexMap):
+ """The product of two indices."""
+
+ def __init__(self, outer_index, inner_index):
+ """
+ Combines indices i and j into pairs (i, j). The result is an index where each segment (i, j) is the
+ intersection of segments i and j. For example if the inputs represent table cells indexed by respectively rows
+ and columns the output will be a table indexed by (row, column) pairs, i.e. by cell. The implementation
+ combines indices {0, .., n - 1} and {0, .., m - 1} into {0, .., nm - 1}. The output has `num_segments` equal to
+ `outer_index.num_segements` * `inner_index.num_segments`.
+
+ Args:
+ outer_index: IndexMap.
+ inner_index: IndexMap, must have the same shape as `outer_index`.
+ """
+ if outer_index.batch_dims != inner_index.batch_dims:
+ raise ValueError("outer_index.batch_dims and inner_index.batch_dims must be the same.")
+
+ super().__init__(
+ indices=(
+ inner_index.indices
+ + outer_index.indices * tf.cast(inner_index.num_segments, inner_index.indices.dtype)
+ ),
+ num_segments=inner_index.num_segments * outer_index.num_segments,
+ batch_dims=inner_index.batch_dims,
+ )
+ self.outer_index = outer_index
+ self.inner_index = inner_index
+
+ def project_outer(self, index):
+ """Projects an index with the same index set onto the outer components."""
+ return IndexMap(
+ indices=tf.math.floordiv(index.indices, self.inner_index.num_segments),
+ num_segments=self.outer_index.num_segments,
+ batch_dims=index.batch_dims,
+ )
+
+ def project_inner(self, index):
+ """Projects an index with the same index set onto the inner components."""
+ return IndexMap(
+ indices=tf.math.floormod(index.indices, self.inner_index.num_segments),
+ num_segments=self.inner_index.num_segments,
+ batch_dims=index.batch_dims,
+ )
+
+
+def gather(values, index, name="segmented_gather"):
+ """
+ Gathers from `values` using the index map. For each element in the domain of the index map this operation looks up
+ a value for that index in `values`. Two elements from the same segment always get assigned the same value.
+
+ Args:
+ values: [B1, ..., Bn, num_segments, V1, ...] Tensor with segment values.
+ index: [B1, ..., Bn, I1, ..., Ik] IndexMap.
+ name: Name for the TensorFlow operation.
+
+ Returns:
+ [B1, ..., Bn, I1, ..., Ik, V1, ...] Tensor with the gathered values.
+ """
+ return tf.gather(values, index.indices, batch_dims=index.batch_dims, name=name)
+
+
+def flatten(index, name="segmented_flatten"):
+ """
+ Flattens a batched index map to a 1d index map. This operation relabels the segments to keep batch elements
+ distinct. The k-th batch element will have indices shifted by `num_segments` * (k - 1). The result is a tensor with
+ `num_segments` multiplied by the number of elements in the batch.
+
+ Args:
+ index: IndexMap to flatten.
+ name: Name for the TensorFlow operation.
+
+ Returns:
+ The flattened IndexMap.
+ """
+ batch_size = tf.reduce_prod(index.batch_shape())
+ offset = tf.range(batch_size) * index.num_segments
+ offset = tf.reshape(offset, index.batch_shape())
+ for _ in range(index.batch_dims, index.indices.shape.rank):
+ offset = tf.expand_dims(offset, -1)
+
+ indices = tf.cast(offset, index.indices.dtype) + index.indices
+ return IndexMap(indices=tf.reshape(indices, [-1]), num_segments=index.num_segments * batch_size, batch_dims=0)
+
+
+def range_index_map(batch_shape, num_segments, name="range_index_map"):
+ """
+ Constructs an index map equal to range(num_segments).
+
+ Args:
+ batch_shape (`tf.Tensor`):
+ Batch shape
+ num_segments (`int`):
+ Number of segments
+ name (`str`, *optional*, defaults to 'range_index_map'):
+ Name for the operation. Currently not used
+
+ Returns:
+ (`IndexMap`): IndexMap of shape batch_shape with elements equal to range(num_segments).
+ """
+ batch_shape = tf.convert_to_tensor(batch_shape)
+ batch_shape.shape.assert_has_rank(1)
+ num_segments = tf.convert_to_tensor(num_segments)
+ num_segments.shape.assert_has_rank(0)
+
+ indices = tf.range(num_segments)
+ shape = tf.concat([tf.ones_like(batch_shape, dtype=tf.int32), tf.expand_dims(num_segments, axis=0)], axis=0)
+ indices = tf.reshape(indices, shape)
+ multiples = tf.concat([batch_shape, [1]], axis=0)
+ indices = tf.tile(indices, multiples)
+ return IndexMap(indices=indices, num_segments=num_segments, batch_dims=batch_shape.shape.as_list()[0])
+
+
+def _segment_reduce(values, index, segment_reduce_fn, name):
+ """
+ Applies a segment reduction segment-wise.
+
+ Args:
+ values (`tf.Tensor`):
+ Tensor with segment values.
+ index (`IndexMap`):
+ IndexMap.
+ segment_reduce_fn (`str`):
+ Name for the reduce operation. One of "sum", "mean", "max" or "min".
+ name (`str`):
+ Name for the operation. Currently not used
+
+ Returns:
+ (`IndexMap`): IndexMap of shape batch_shape with elements equal to range(num_segments).
+ """
+ # Flatten the batch dimensions, as segments ops do not support batching.
+ # However if `values` has extra dimensions to the right keep them
+ # unflattened. Segmented ops support vector-valued operations.
+ flat_index = flatten(index)
+ vector_shape = tf.shape(values)[index.indices.shape.rank :]
+ flattened_shape = tf.concat([[-1], vector_shape], axis=0)
+ flat_values = tf.reshape(values, flattened_shape)
+ segment_means = segment_reduce_fn(
+ data=flat_values, segment_ids=flat_index.indices, num_segments=flat_index.num_segments
+ )
+
+ # Unflatten the values.
+ new_shape = tf.concat([index.batch_shape(), [index.num_segments], vector_shape], axis=0)
+ output_values = tf.reshape(segment_means, new_shape)
+ output_index = range_index_map(index.batch_shape(), index.num_segments)
+ return output_values, output_index
+
+
+def reduce_mean(values, index, name="segmented_reduce_mean"):
+ """
+ Averages a tensor over its segments. Outputs 0 for empty segments. This operations computes the mean over segments,
+ with support for:
+
+ - Batching using the first dimensions [B1, B2, ..., Bn]. Each element in a batch can have different indices.
+ - Vectorization using the last dimension [V1, V2, ...]. If they are present the output will be a mean of vectors
+ rather than scalars.
+ Only the middle dimensions [I1, ..., Ik] are reduced by the operation.
+
+ Args:
+ values: [B1, B2, ..., Bn, I1, .., Ik, V1, V2, ..] tensor of values to be
+ averaged.
+ index: IndexMap [B1, B2, ..., Bn, I1, .., Ik] index defining the segments.
+ name: Name for the TensorFlow ops.
+
+ Returns:
+ A pair (output_values, output_index) where `output_values` is a tensor of shape [B1, B2, ..., Bn, num_segments,
+ V1, V2, ..] and `index` is an IndexMap with shape [B1, B2, ..., Bn, num_segments].
+ """
+ return _segment_reduce(values, index, tf.math.unsorted_segment_mean, name)
+
+
+def reduce_sum(values, index, name="segmented_reduce_sum"):
+ """
+ Sums a tensor over its segments. Outputs 0 for empty segments. This operations computes the sum over segments, with
+ support for:
+
+ - Batching using the first dimensions [B1, B2, ..., Bn]. Each element in a batch can have different indices.
+ - Vectorization using the last dimension [V1, V2, ...]. If they are present the output will be a sum of vectors
+ rather than scalars.
+ Only the middle dimensions [I1, ..., Ik] are reduced by the operation.
+
+ Args:
+ values: [B1, B2, ..., Bn, I1, .., Ik, V1, V2, ..] tensor of values to be
+ averaged.
+ index: IndexMap [B1, B2, ..., Bn, I1, .., Ik] index defining the segments.
+ name: Name for the TensorFlow ops.
+
+ Returns:
+ A pair (output_values, output_index) where `output_values` is a tensor of shape [B1, B2, ..., Bn, num_segments,
+ V1, V2, ..] and `index` is an IndexMap with shape [B1, B2, ..., Bn, num_segments].
+ """
+ return _segment_reduce(values, index, tf.math.unsorted_segment_sum, name)
+
+
+def reduce_max(values, index, name="segmented_reduce_max"):
+ """
+ Computes the maximum over segments. This operations computes the maximum over segments, with support for:
+
+ - Batching using the first dimensions [B1, B2, ..., Bn]. Each element in a batch can have different indices.
+ - Vectorization using the last dimension [V1, V2, ...]. If they are present the output will be an element-wise
+ maximum of vectors rather than scalars.
+ Only the middle dimensions [I1, ..., Ik] are reduced by the operation.
+
+ Args:
+ values: [B1, B2, ..., Bn, I1, .., Ik, V1, V2, ..] tensor of values to be
+ averaged.
+ index: IndexMap [B1, B2, ..., Bn, I1, .., Ik] index defining the segments.
+ name: Name for the TensorFlow ops.
+
+ Returns:
+ A pair (output_values, output_index) where `output_values` is a tensor of shape [B1, B2, ..., Bn, num_segments,
+ V1, V2, ..] and `index` is an IndexMap with shape [B1, B2, ..., Bn, num_segments].
+ """
+ return _segment_reduce(values, index, tf.math.unsorted_segment_max, name)
+
+
+def reduce_min(values, index, name="segmented_reduce_min"):
+ """Computes the minimum over segments."""
+ return _segment_reduce(values, index, tf.math.unsorted_segment_min, name)
+
+
+def _single_column_cell_selection_loss(token_logits, column_logits, labels, cell_index, col_index, cell_mask):
+ """
+ Computes the loss for cell selection constrained to a single column. The loss is a hierarchical log-likelihood. The
+ model first predicts a column and then selects cells within that column (conditioned on the column). Cells outside
+ the selected column are never selected.
+
+ Args:
+ token_logits (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Tensor containing the logits per token.
+ column_logits (`tf.Tensor` of shape `(batch_size, max_num_cols)`):
+ Tensor containing the logits per column.
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Labels per token.
+ cell_index (`ProductIndexMap`):
+ Index that groups tokens into cells.
+ col_index (`IndexMap`):
+ Index that groups tokens into columns.
+ cell_mask (`tf.Tensor` of shape `(batch_size, max_num_rows * max_num_cols)`):
+ Mask for cells that exist in the table (i.e. that are not padding).
+
+ Returns:
+ selection_loss_per_example (`tf.Tensor` of shape `(batch_size,)`): Loss for each example. logits (`tf.Tensor`
+ of shape `(batch_size, sequence_length)`): New logits which are only allowed to select cells in a single
+ column. Logits outside of the most likely column according to *column_logits* will be set to a very low value
+ (such that the probabilities are 0).
+ """
+ # First find the column we should select. We use the column with maximum
+ # number of selected cells.
+ labels_per_column, _ = reduce_sum(tf.cast(labels, tf.float32), col_index)
+ column_label = tf.argmax(labels_per_column, axis=-1, output_type=tf.int32)
+ # Check if there are no selected cells in the column. In that case the model
+ # should predict the special column id 0, which means "select nothing".
+ no_cell_selected = tf.equal(tf.reduce_max(labels_per_column, axis=-1), 0)
+ column_label = tf.where(no_cell_selected, tf.zeros_like(column_label), column_label)
+
+ column_dist = tfp.distributions.Categorical(logits=column_logits)
+ column_loss_per_example = -column_dist.log_prob(column_label)
+
+ # Reduce the labels and logits to per-cell from per-token.
+ logits_per_cell, _ = reduce_mean(token_logits, cell_index)
+ labels_per_cell, labels_index = reduce_max(tf.cast(labels, tf.int32), cell_index)
+
+ # Mask for the selected column.
+ column_id_for_cells = cell_index.project_inner(labels_index).indices
+ column_mask = tf.cast(tf.equal(column_id_for_cells, tf.expand_dims(column_label, axis=1)), tf.float32)
+
+ # Compute the log-likelihood for cells, but only for the selected column.
+ cell_dist = tfp.distributions.Bernoulli(logits=logits_per_cell)
+ cell_log_prob = cell_dist.log_prob(labels_per_cell)
+ cell_loss = -tf.reduce_sum(cell_log_prob * column_mask * cell_mask, axis=1)
+ # We need to normalize the loss by the number of cells in the column.
+ cell_loss /= tf.reduce_sum(column_mask * cell_mask, axis=1) + EPSILON_ZERO_DIVISION
+
+ selection_loss_per_example = column_loss_per_example
+ selection_loss_per_example += tf.where(no_cell_selected, tf.zeros_like(selection_loss_per_example), cell_loss)
+
+ # Set the probs outside the selected column (selected by the *model*)
+ # to 0. This ensures backwards compatibility with models that select
+ # cells from multiple columns.
+ selected_column_id = tf.argmax(column_logits, axis=-1, output_type=tf.int32)
+ selected_column_mask = tf.cast(
+ tf.equal(column_id_for_cells, tf.expand_dims(selected_column_id, axis=-1)), tf.float32
+ )
+ # Never select cells with the special column id 0.
+ selected_column_mask = tf.where(
+ tf.equal(column_id_for_cells, 0), tf.zeros_like(selected_column_mask), selected_column_mask
+ )
+ logits_per_cell += CLOSE_ENOUGH_TO_LOG_ZERO * (1.0 - cell_mask * selected_column_mask)
+ logits = gather(logits_per_cell, cell_index)
+
+ return selection_loss_per_example, logits
+
+
+def _calculate_aggregate_mask(answer, pooled_output, cell_selection_preference, labels, aggregation_classifier):
+ """
+ Finds examples where the model should select cells with no aggregation.
+
+ Returns a mask that determines for which examples should the model select answers directly from the table, without
+ any aggregation function. If the answer is a piece of text the case is unambiguous as aggregation functions only
+ apply to numbers. If the answer is a number but does not appear in the table then we must use some aggregation
+ case. The ambiguous case is when the answer is a number that also appears in the table. In this case we use the
+ aggregation function probabilities predicted by the model to decide whether to select or aggregate. The threshold
+ for this is a hyperparameter *cell_selection_preference*
+
+ Args:
+ answer (`tf.Tensor` of shape `(batch_size, )`):
+ Answer for every example in the batch. Nan if there is no scalar answer.
+ pooled_output (`tf.Tensor` of shape `(batch_size, hidden_size)`):
+ Output of the pooler (BertPooler) on top of the encoder layer.
+ cell_selection_preference (`float`):
+ Preference for cell selection in ambiguous cases.
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Labels per token. aggregation_classifier (`torch.nn.Linear`): Aggregation head
+
+ Returns:
+ aggregate_mask (`tf.Tensor` of shape `(batch_size,)`): A mask set to 1 for examples that should use aggregation
+ functions.
+ """
+ # tf.Tensor(batch_size,)
+ aggregate_mask_init = tf.cast(tf.logical_not(tf.math.is_nan(answer)), tf.float32)
+ logits_aggregation = aggregation_classifier(pooled_output)
+ dist_aggregation = tfp.distributions.Categorical(logits=logits_aggregation)
+ # Index 0 corresponds to "no aggregation".
+ aggregation_ops_total_mass = tf.reduce_sum(dist_aggregation.probs_parameter()[:, 1:], axis=1)
+ # Cell selection examples according to current model.
+ is_pred_cell_selection = aggregation_ops_total_mass <= cell_selection_preference
+ # Examples with non-empty cell selection supervision.
+ is_cell_supervision_available = tf.reduce_sum(labels, axis=1) > 0
+ aggregate_mask = tf.where(
+ tf.logical_and(is_pred_cell_selection, is_cell_supervision_available),
+ tf.zeros_like(aggregate_mask_init, dtype=tf.float32),
+ aggregate_mask_init,
+ )
+ aggregate_mask = tf.stop_gradient(aggregate_mask)
+ return aggregate_mask
+
+
+def _calculate_aggregation_loss_known(
+ logits_aggregation, aggregate_mask, aggregation_labels, use_answer_as_supervision, num_aggregation_labels
+):
+ """
+ Calculates aggregation loss when its type is known during training.
+
+ In the weakly supervised setting, the only known information is that for cell selection examples, "no aggregation"
+ should be predicted. For other examples (those that require aggregation), no loss is accumulated. In the setting
+ where aggregation type is always known, standard cross entropy loss is accumulated for all examples
+
+ Args:
+ logits_aggregation (`tf.Tensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ aggregate_mask (`tf.Tensor` of shape `(batch_size, )`):
+ A mask set to 1 for examples that should use aggregation functions.
+ aggregation_labels (`tf.Tensor` of shape `(batch_size, )`):
+ Aggregation function id for every example in the batch.
+ use_answer_as_supervision (`bool`, *optional*):
+ Whether to use the answer as the only supervision for aggregation examples.
+ num_aggregation_labels (`int`, *optional*, defaults to 0):
+ The number of aggregation operators to predict.
+
+ Returns:
+ aggregation_loss_known (`tf.Tensor` of shape `(batch_size,)`): Aggregation loss (when its type is known during
+ training) per example.
+ """
+ if use_answer_as_supervision:
+ # Prepare "no aggregation" targets for cell selection examples.
+ target_aggregation = tf.zeros_like(aggregate_mask, dtype=tf.int32)
+ else:
+ # Use aggregation supervision as the target.
+ target_aggregation = aggregation_labels
+
+ one_hot_labels = tf.one_hot(target_aggregation, depth=num_aggregation_labels, dtype=tf.float32)
+ log_probs = tf.nn.log_softmax(logits_aggregation, axis=-1)
+
+ # [batch_size]
+ per_example_aggregation_intermediate = -tf.reduce_sum(one_hot_labels * log_probs, axis=-1)
+ if use_answer_as_supervision:
+ # Accumulate loss only for examples requiring cell selection
+ # (no aggregation).
+ return per_example_aggregation_intermediate * (1 - aggregate_mask)
+ else:
+ return per_example_aggregation_intermediate
+
+
+def _calculate_aggregation_loss_unknown(logits_aggregation, aggregate_mask):
+ """
+ Calculates aggregation loss in the case of answer supervision.
+
+ Args:
+ logits_aggregation (`tf.Tensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ aggregate_mask (`tf.Tensor` of shape `(batch_size, )`):
+ A mask set to 1 for examples that should use aggregation functions
+
+ Returns:
+ aggregation_loss_unknown (`tf.Tensor` of shape `(batch_size,)`): Aggregation loss (in case of answer
+ supervision) per example.
+ """
+ dist_aggregation = tfp.distributions.Categorical(logits=logits_aggregation)
+ # Index 0 corresponds to "no aggregation".
+ aggregation_ops_total_mass = tf.reduce_sum(dist_aggregation.probs_parameter()[:, 1:], axis=1)
+ # Predict some aggregation in case of an answer that needs aggregation.
+ # This increases the probability of all aggregation functions, in a way
+ # similar to MML, but without considering whether the function gives the
+ # correct answer.
+ return -tf.math.log(aggregation_ops_total_mass) * aggregate_mask
+
+
+def _calculate_aggregation_loss(
+ logits_aggregation,
+ aggregate_mask,
+ aggregation_labels,
+ use_answer_as_supervision,
+ num_aggregation_labels,
+ aggregation_loss_weight,
+):
+ """
+ Calculates the aggregation loss per example.
+
+ Args:
+ logits_aggregation (`tf.Tensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ aggregate_mask (`tf.Tensor` of shape `(batch_size, )`):
+ A mask set to 1 for examples that should use aggregation functions.
+ aggregation_labels (`tf.Tensor` of shape `(batch_size, )`):
+ Aggregation function id for every example in the batch.
+ use_answer_as_supervision (`bool`, *optional*):
+ Whether to use the answer as the only supervision for aggregation examples.
+ num_aggregation_labels (`int`, *optional*, defaults to 0):
+ The number of aggregation operators to predict.
+ aggregation_loss_weight (`float`, *optional*, defaults to 1.0):
+ Importance weight for the aggregation loss.
+
+ Returns:
+ aggregation_loss (`tf.Tensor` of shape `(batch_size,)`): Aggregation loss per example.
+ """
+ per_example_aggregation_loss = _calculate_aggregation_loss_known(
+ logits_aggregation, aggregate_mask, aggregation_labels, use_answer_as_supervision, num_aggregation_labels
+ )
+
+ if use_answer_as_supervision:
+ # Add aggregation loss for numeric answers that need aggregation.
+ per_example_aggregation_loss += _calculate_aggregation_loss_unknown(logits_aggregation, aggregate_mask)
+ return aggregation_loss_weight * per_example_aggregation_loss
+
+
+def _calculate_expected_result(
+ dist_per_cell, numeric_values, numeric_values_scale, input_mask_float, logits_aggregation, config
+):
+ """
+ Calculates the expected result given cell and aggregation probabilities.
+
+ Args:
+ dist_per_cell (`tfp.distributions.Bernoulli`):
+ Cell selection distribution for each cell.
+ numeric_values (`tf.Tensor` of shape `(batch_size, seq_length)`):
+ Numeric values of every token. Nan for tokens which are not numeric values.
+ numeric_values_scale (`tf.Tensor` of shape `(batch_size, seq_length)`):
+ Scale of the numeric values of every token.
+ input_mask_float (`tf.Tensor` of shape `(batch_size, seq_length)`):
+ Mask for the table, without question tokens and table headers.
+ logits_aggregation (`tf.Tensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ config ([`TapasConfig`]):
+ Model configuration class with all the hyperparameters of the model
+
+ Returns:
+ expected_result (`tf.Tensor` of shape `(batch_size,)`): The expected result per example.
+ """
+ if config.use_gumbel_for_cells:
+ gumbel_dist = tfp.distributions.RelaxedBernoulli(
+ # The token logits where already divided by the temperature and used for
+ # computing cell selection errors so we need to multiply it again here
+ config.temperature,
+ logits=dist_per_cell.logits_parameter() * config.temperature,
+ )
+ scaled_probability_per_cell = gumbel_dist.sample()
+ else:
+ scaled_probability_per_cell = dist_per_cell.probs_parameter()
+
+ # [batch_size, seq_length]
+ scaled_probability_per_cell = (scaled_probability_per_cell / numeric_values_scale) * input_mask_float
+ count_result = tf.reduce_sum(scaled_probability_per_cell, axis=1)
+ numeric_values_masked = tf.where(
+ tf.math.is_nan(numeric_values), tf.zeros_like(numeric_values), numeric_values
+ ) # Mask non-numeric table values to zero.
+ sum_result = tf.reduce_sum(scaled_probability_per_cell * numeric_values_masked, axis=1)
+ avg_approximation = config.average_approximation_function
+ if avg_approximation == AverageApproximationFunction.RATIO:
+ average_result = sum_result / (count_result + EPSILON_ZERO_DIVISION)
+ elif avg_approximation == AverageApproximationFunction.FIRST_ORDER:
+ # The sum of all probabilities except that correspond to other cells
+ ex = tf.reduce_sum(scaled_probability_per_cell, axis=1, keepdims=True) - scaled_probability_per_cell + 1
+ average_result = tf.reduce_sum(numeric_values_masked * scaled_probability_per_cell / ex, axis=1)
+ elif avg_approximation == AverageApproximationFunction.SECOND_ORDER:
+ # The sum of all probabilities except that correspond to other cells
+ ex = tf.reduce_sum(scaled_probability_per_cell, axis=1, keepdims=True) - scaled_probability_per_cell + 1
+ pointwise_var = scaled_probability_per_cell * (1 - scaled_probability_per_cell)
+ var = tf.reduce_sum(pointwise_var, axis=1, keepdims=True) - pointwise_var
+ multiplier = (var / tf.math.square(ex) + 1) / ex
+ average_result = tf.reduce_sum(numeric_values_masked * scaled_probability_per_cell * multiplier, axis=1)
+ else:
+ raise ValueError("Invalid average_approximation_function: %s", config.average_approximation_function)
+
+ if config.use_gumbel_for_aggregation:
+ gumbel_dist = tfp.distributions.RelaxedOneHotCategorical(
+ config.aggregation_temperature, logits=logits_aggregation[:, 1:]
+ )
+ # [batch_size, num_aggregation_labels - 1]
+ aggregation_op_only_probs = gumbel_dist.sample()
+ else:
+ # [batch_size, num_aggregation_labels - 1]
+ aggregation_op_only_probs = stable_softmax(logits_aggregation[:, 1:] / config.aggregation_temperature, axis=-1)
+ all_results = tf.concat(
+ [
+ tf.expand_dims(sum_result, axis=1),
+ tf.expand_dims(average_result, axis=1),
+ tf.expand_dims(count_result, axis=1),
+ ],
+ axis=1,
+ )
+ expected_result = tf.reduce_sum(all_results * aggregation_op_only_probs, axis=1)
+ return expected_result
+
+
+def _calculate_regression_loss(
+ answer,
+ aggregate_mask,
+ dist_per_cell,
+ numeric_values,
+ numeric_values_scale,
+ input_mask_float,
+ logits_aggregation,
+ config,
+):
+ """
+ Calculates the regression loss per example.
+
+ Args:
+ answer (`tf.Tensor` of shape `(batch_size,)`):
+ Answer for every example in the batch. Nan if there is no scalar answer.
+ aggregate_mask (`tf.Tensor` of shape `(batch_size,)`):
+ A mask set to 1 for examples that should use aggregation functions.
+ dist_per_cell (`torch.distributions.Bernoulli`):
+ Cell selection distribution for each cell.
+ numeric_values (`tf.Tensor` of shape `(batch_size, seq_length)`):
+ Numeric values of every token. Nan for tokens which are not numeric values.
+ numeric_values_scale (`tf.Tensor` of shape `(batch_size, seq_length)`):
+ Scale of the numeric values of every token.
+ input_mask_float (`tf.Tensor` of shape `(batch_size, seq_length)`):
+ Mask for the table, without question tokens and table headers.
+ logits_aggregation (`tf.Tensor` of shape `(batch_size, num_aggregation_labels)`):
+ Logits per aggregation operation.
+ config ([`TapasConfig`]):
+ Model configuration class with all the parameters of the model
+
+ Returns:
+ per_example_answer_loss_scaled (`tf.Tensor` of shape `(batch_size,)`): Scales answer loss for each example in
+ the batch. large_answer_loss_mask (`tf.Tensor` of shape `(batch_size,)`): A mask which is 1 for examples for
+ which their answer loss is larger than the answer_loss_cutoff.
+ """
+ # float32 (batch_size,)
+ expected_result = _calculate_expected_result(
+ dist_per_cell, numeric_values, numeric_values_scale, input_mask_float, logits_aggregation, config
+ )
+
+ # [batch_size]
+ answer_masked = tf.where(tf.math.is_nan(answer), tf.zeros_like(answer), answer)
+
+ if config.use_normalized_answer_loss:
+ normalizer = tf.stop_gradient(
+ tf.math.maximum(tf.math.abs(expected_result), tf.math.abs(answer_masked)) + EPSILON_ZERO_DIVISION
+ )
+ normalized_answer_masked = answer_masked / normalizer
+ normalized_expected_result = expected_result / normalizer
+ per_example_answer_loss = tf.compat.v1.losses.huber_loss(
+ normalized_answer_masked * aggregate_mask,
+ normalized_expected_result * aggregate_mask,
+ delta=tf.cast(1.0, tf.float32),
+ reduction=tf.losses.Reduction.NONE,
+ )
+ else:
+ per_example_answer_loss = tf.compat.v1.losses.huber_loss(
+ answer_masked * aggregate_mask,
+ expected_result * aggregate_mask,
+ delta=tf.cast(config.huber_loss_delta, tf.float32),
+ reduction=tf.losses.Reduction.NONE,
+ )
+ if config.answer_loss_cutoff is None:
+ large_answer_loss_mask = tf.ones_like(per_example_answer_loss, dtype=tf.float32)
+ else:
+ large_answer_loss_mask = tf.where(
+ per_example_answer_loss > config.answer_loss_cutoff,
+ tf.zeros_like(per_example_answer_loss, dtype=tf.float32),
+ tf.ones_like(per_example_answer_loss, dtype=tf.float32),
+ )
+ per_example_answer_loss_scaled = config.answer_loss_importance * (per_example_answer_loss * aggregate_mask)
+ return per_example_answer_loss_scaled, large_answer_loss_mask
+
+
+__all__ = [
+ "TFTapasForMaskedLM",
+ "TFTapasForQuestionAnswering",
+ "TFTapasForSequenceClassification",
+ "TFTapasModel",
+ "TFTapasPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/tokenization_tapas.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/tokenization_tapas.py
new file mode 100644
index 0000000000000000000000000000000000000000..4d91a1add94411d3b2a854327176b19e148ab4da
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tapas/tokenization_tapas.py
@@ -0,0 +1,2793 @@
+# coding=utf-8
+# Copyright 2020 Google Research and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for TAPAS model."""
+
+import collections
+import datetime
+import enum
+import itertools
+import math
+import os
+import re
+import unicodedata
+from collections.abc import Generator
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import numpy as np
+
+from ...tokenization_utils import PreTrainedTokenizer, _is_control, _is_punctuation, _is_whitespace
+from ...tokenization_utils_base import (
+ ENCODE_KWARGS_DOCSTRING,
+ VERY_LARGE_INTEGER,
+ BatchEncoding,
+ EncodedInput,
+ PreTokenizedInput,
+ TextInput,
+)
+from ...utils import ExplicitEnum, PaddingStrategy, TensorType, add_end_docstrings, is_pandas_available, logging
+
+
+if is_pandas_available():
+ import pandas as pd
+
+logger = logging.get_logger(__name__)
+
+
+VOCAB_FILES_NAMES = {"vocab_file": "vocab.txt"}
+
+
+class TapasTruncationStrategy(ExplicitEnum):
+ """
+ Possible values for the `truncation` argument in [`~TapasTokenizer.__call__`]. Useful for tab-completion in an IDE.
+ """
+
+ DROP_ROWS_TO_FIT = "drop_rows_to_fit"
+ DO_NOT_TRUNCATE = "do_not_truncate"
+
+
+TableValue = collections.namedtuple("TokenValue", ["token", "column_id", "row_id"])
+
+
+@dataclass(frozen=True)
+class TokenCoordinates:
+ column_index: int
+ row_index: int
+ token_index: int
+
+
+@dataclass
+class TokenizedTable:
+ rows: list[list[list[str]]]
+ selected_tokens: list[TokenCoordinates]
+
+
+@dataclass(frozen=True)
+class SerializedExample:
+ tokens: list[str]
+ column_ids: list[int]
+ row_ids: list[int]
+ segment_ids: list[int]
+
+
+def _is_inner_wordpiece(token: str):
+ return token.startswith("##")
+
+
+def load_vocab(vocab_file):
+ """Loads a vocabulary file into a dictionary."""
+ vocab = collections.OrderedDict()
+ with open(vocab_file, "r", encoding="utf-8") as reader:
+ tokens = reader.readlines()
+ for index, token in enumerate(tokens):
+ token = token.rstrip("\n")
+ vocab[token] = index
+ return vocab
+
+
+def whitespace_tokenize(text):
+ """Runs basic whitespace cleaning and splitting on a piece of text."""
+ text = text.strip()
+ if not text:
+ return []
+ tokens = text.split()
+ return tokens
+
+
+TAPAS_ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING = r"""
+ add_special_tokens (`bool`, *optional*, defaults to `True`):
+ Whether or not to encode the sequences with the special tokens relative to their model.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Activates and controls padding. Accepts the following values:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ truncation (`bool`, `str` or [`TapasTruncationStrategy`], *optional*, defaults to `False`):
+ Activates and controls truncation. Accepts the following values:
+
+ - `True` or `'drop_rows_to_fit'`: Truncate to a maximum length specified with the argument `max_length`
+ or to the maximum acceptable input length for the model if that argument is not provided. This will
+ truncate row by row, removing rows from the table.
+ - `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths
+ greater than the model maximum admissible input size).
+ max_length (`int`, *optional*):
+ Controls the maximum length to use by one of the truncation/padding parameters.
+
+ If left unset or set to `None`, this will use the predefined model maximum length if a maximum length
+ is required by one of the truncation/padding parameters. If the model has no specific maximum input
+ length (like XLNet) truncation/padding to a maximum length will be deactivated.
+ is_split_into_words (`bool`, *optional*, defaults to `False`):
+ Whether or not the input is already pre-tokenized (e.g., split into words). If set to `True`, the
+ tokenizer assumes the input is already split into words (for instance, by splitting it on whitespace)
+ which it will tokenize. This is useful for NER or token classification.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value. This is especially useful to enable
+ the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta).
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+"""
+
+
+class TapasTokenizer(PreTrainedTokenizer):
+ r"""
+ Construct a TAPAS tokenizer. Based on WordPiece. Flattens a table and one or more related sentences to be used by
+ TAPAS models.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods. [`TapasTokenizer`] creates several token type ids to
+ encode tabular structure. To be more precise, it adds 7 token type ids, in the following order: `segment_ids`,
+ `column_ids`, `row_ids`, `prev_labels`, `column_ranks`, `inv_column_ranks` and `numeric_relations`:
+
+ - segment_ids: indicate whether a token belongs to the question (0) or the table (1). 0 for special tokens and
+ padding.
+ - column_ids: indicate to which column of the table a token belongs (starting from 1). Is 0 for all question
+ tokens, special tokens and padding.
+ - row_ids: indicate to which row of the table a token belongs (starting from 1). Is 0 for all question tokens,
+ special tokens and padding. Tokens of column headers are also 0.
+ - prev_labels: indicate whether a token was (part of) an answer to the previous question (1) or not (0). Useful in
+ a conversational setup (such as SQA).
+ - column_ranks: indicate the rank of a table token relative to a column, if applicable. For example, if you have a
+ column "number of movies" with values 87, 53 and 69, then the column ranks of these tokens are 3, 1 and 2
+ respectively. 0 for all question tokens, special tokens and padding.
+ - inv_column_ranks: indicate the inverse rank of a table token relative to a column, if applicable. For example, if
+ you have a column "number of movies" with values 87, 53 and 69, then the inverse column ranks of these tokens are
+ 1, 3 and 2 respectively. 0 for all question tokens, special tokens and padding.
+ - numeric_relations: indicate numeric relations between the question and the tokens of the table. 0 for all
+ question tokens, special tokens and padding.
+
+ [`TapasTokenizer`] runs end-to-end tokenization on a table and associated sentences: punctuation splitting and
+ wordpiece.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ do_basic_tokenize (`bool`, *optional*, defaults to `True`):
+ Whether or not to do basic tokenization before WordPiece.
+ never_split (`Iterable`, *optional*):
+ Collection of tokens which will never be split during tokenization. Only has an effect when
+ `do_basic_tokenize=True`
+ unk_token (`str`, *optional*, defaults to `"[UNK]"`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ sep_token (`str`, *optional*, defaults to `"[SEP]"`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `"[PAD]"`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `"[CLS]"`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `"[MASK]"`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ empty_token (`str`, *optional*, defaults to `"[EMPTY]"`):
+ The token used for empty cell values in a table. Empty cell values include "", "n/a", "nan" and "?".
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters. This should likely be deactivated for Japanese (see this
+ [issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original BERT).
+ cell_trim_length (`int`, *optional*, defaults to -1):
+ If > 0: Trim cells so that the length is <= this value. Also disables further cell trimming, should thus be
+ used with `truncation` set to `True`.
+ max_column_id (`int`, *optional*):
+ Max column id to extract.
+ max_row_id (`int`, *optional*):
+ Max row id to extract.
+ strip_column_names (`bool`, *optional*, defaults to `False`):
+ Whether to add empty strings instead of column names.
+ update_answer_coordinates (`bool`, *optional*, defaults to `False`):
+ Whether to recompute the answer coordinates from the answer text.
+ min_question_length (`int`, *optional*):
+ Minimum length of each question in terms of tokens (will be skipped otherwise).
+ max_question_length (`int`, *optional*):
+ Maximum length of each question in terms of tokens (will be skipped otherwise).
+ clean_up_tokenization_spaces (`bool`, *optional*, defaults to `True`):
+ Whether or not to cleanup spaces after decoding, cleanup consists in removing potential artifacts like
+ extra spaces.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+
+ def __init__(
+ self,
+ vocab_file,
+ do_lower_case=True,
+ do_basic_tokenize=True,
+ never_split=None,
+ unk_token="[UNK]",
+ sep_token="[SEP]",
+ pad_token="[PAD]",
+ cls_token="[CLS]",
+ mask_token="[MASK]",
+ empty_token="[EMPTY]",
+ tokenize_chinese_chars=True,
+ strip_accents=None,
+ cell_trim_length: int = -1,
+ max_column_id: Optional[int] = None,
+ max_row_id: Optional[int] = None,
+ strip_column_names: bool = False,
+ update_answer_coordinates: bool = False,
+ min_question_length=None,
+ max_question_length=None,
+ model_max_length: int = 512,
+ additional_special_tokens: Optional[list[str]] = None,
+ clean_up_tokenization_spaces=True,
+ **kwargs,
+ ):
+ if not is_pandas_available():
+ raise ImportError("Pandas is required for the TAPAS tokenizer.")
+
+ if additional_special_tokens is not None:
+ if empty_token not in additional_special_tokens:
+ additional_special_tokens.append(empty_token)
+ else:
+ additional_special_tokens = [empty_token]
+
+ if not os.path.isfile(vocab_file):
+ raise ValueError(
+ f"Can't find a vocabulary file at path '{vocab_file}'. To load the vocabulary from a Google pretrained"
+ " model use `tokenizer = BertTokenizer.from_pretrained(PRETRAINED_MODEL_NAME)`"
+ )
+ self.vocab = load_vocab(vocab_file)
+ self.ids_to_tokens = collections.OrderedDict([(ids, tok) for tok, ids in self.vocab.items()])
+ self.do_basic_tokenize = do_basic_tokenize
+ if do_basic_tokenize:
+ self.basic_tokenizer = BasicTokenizer(
+ do_lower_case=do_lower_case,
+ never_split=never_split,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ )
+ self.wordpiece_tokenizer = WordpieceTokenizer(vocab=self.vocab, unk_token=str(unk_token))
+
+ # Additional properties
+ self.cell_trim_length = cell_trim_length
+ self.max_column_id = (
+ max_column_id
+ if max_column_id is not None
+ else model_max_length
+ if model_max_length is not None
+ else VERY_LARGE_INTEGER
+ )
+ self.max_row_id = (
+ max_row_id
+ if max_row_id is not None
+ else model_max_length
+ if model_max_length is not None
+ else VERY_LARGE_INTEGER
+ )
+ self.strip_column_names = strip_column_names
+ self.update_answer_coordinates = update_answer_coordinates
+ self.min_question_length = min_question_length
+ self.max_question_length = max_question_length
+
+ super().__init__(
+ do_lower_case=do_lower_case,
+ do_basic_tokenize=do_basic_tokenize,
+ never_split=never_split,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ empty_token=empty_token,
+ tokenize_chinese_chars=tokenize_chinese_chars,
+ strip_accents=strip_accents,
+ cell_trim_length=cell_trim_length,
+ max_column_id=max_column_id,
+ max_row_id=max_row_id,
+ strip_column_names=strip_column_names,
+ update_answer_coordinates=update_answer_coordinates,
+ min_question_length=min_question_length,
+ max_question_length=max_question_length,
+ model_max_length=model_max_length,
+ additional_special_tokens=additional_special_tokens,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ **kwargs,
+ )
+
+ @property
+ def do_lower_case(self):
+ return self.basic_tokenizer.do_lower_case
+
+ @property
+ def vocab_size(self):
+ return len(self.vocab)
+
+ def get_vocab(self):
+ return dict(self.vocab, **self.added_tokens_encoder)
+
+ def _tokenize(self, text):
+ if format_text(text) == EMPTY_TEXT:
+ return [self.additional_special_tokens[0]]
+ split_tokens = []
+ if self.do_basic_tokenize:
+ for token in self.basic_tokenizer.tokenize(text, never_split=self.all_special_tokens):
+ # If the token is part of the never_split set
+ if token in self.basic_tokenizer.never_split:
+ split_tokens.append(token)
+ else:
+ split_tokens += self.wordpiece_tokenizer.tokenize(token)
+ else:
+ split_tokens = self.wordpiece_tokenizer.tokenize(text)
+ return split_tokens
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.vocab.get(token, self.vocab.get(self.unk_token))
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ return self.ids_to_tokens.get(index, self.unk_token)
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ out_string = " ".join(tokens).replace(" ##", "").strip()
+ return out_string
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ index = 0
+ if os.path.isdir(save_directory):
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+ else:
+ vocab_file = (filename_prefix + "-" if filename_prefix else "") + save_directory
+ with open(vocab_file, "w", encoding="utf-8") as writer:
+ for token, token_index in sorted(self.vocab.items(), key=lambda kv: kv[1]):
+ if index != token_index:
+ logger.warning(
+ f"Saving vocabulary to {vocab_file}: vocabulary indices are not consecutive."
+ " Please check that the vocabulary is not corrupted!"
+ )
+ index = token_index
+ writer.write(token + "\n")
+ index += 1
+ return (vocab_file,)
+
+ def create_attention_mask_from_sequences(self, query_ids: list[int], table_values: list[TableValue]) -> list[int]:
+ """
+ Creates the attention mask according to the query token IDs and a list of table values.
+
+ Args:
+ query_ids (`list[int]`): list of token IDs corresponding to the ID.
+ table_values (`list[TableValue]`): lift of table values, which are named tuples containing the
+ token value, the column ID and the row ID of said token.
+
+ Returns:
+ `list[int]`: List of ints containing the attention mask values.
+ """
+ return [1] * (1 + len(query_ids) + 1 + len(table_values))
+
+ def create_segment_token_type_ids_from_sequences(
+ self, query_ids: list[int], table_values: list[TableValue]
+ ) -> list[int]:
+ """
+ Creates the segment token type IDs according to the query token IDs and a list of table values.
+
+ Args:
+ query_ids (`list[int]`): list of token IDs corresponding to the ID.
+ table_values (`list[TableValue]`): lift of table values, which are named tuples containing the
+ token value, the column ID and the row ID of said token.
+
+ Returns:
+ `list[int]`: List of ints containing the segment token type IDs values.
+ """
+ table_ids = list(zip(*table_values))[0] if table_values else []
+ return [0] * (1 + len(query_ids) + 1) + [1] * len(table_ids)
+
+ def create_column_token_type_ids_from_sequences(
+ self, query_ids: list[int], table_values: list[TableValue]
+ ) -> list[int]:
+ """
+ Creates the column token type IDs according to the query token IDs and a list of table values.
+
+ Args:
+ query_ids (`list[int]`): list of token IDs corresponding to the ID.
+ table_values (`list[TableValue]`): lift of table values, which are named tuples containing the
+ token value, the column ID and the row ID of said token.
+
+ Returns:
+ `list[int]`: List of ints containing the column token type IDs values.
+ """
+ table_column_ids = list(zip(*table_values))[1] if table_values else []
+ return [0] * (1 + len(query_ids) + 1) + list(table_column_ids)
+
+ def create_row_token_type_ids_from_sequences(
+ self, query_ids: list[int], table_values: list[TableValue]
+ ) -> list[int]:
+ """
+ Creates the row token type IDs according to the query token IDs and a list of table values.
+
+ Args:
+ query_ids (`list[int]`): list of token IDs corresponding to the ID.
+ table_values (`list[TableValue]`): lift of table values, which are named tuples containing the
+ token value, the column ID and the row ID of said token.
+
+ Returns:
+ `list[int]`: List of ints containing the row token type IDs values.
+ """
+ table_row_ids = list(zip(*table_values))[2] if table_values else []
+ return [0] * (1 + len(query_ids) + 1) + list(table_row_ids)
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a question and flattened table for question answering or sequence classification tasks
+ by concatenating and adding special tokens.
+
+ Args:
+ token_ids_0 (`list[int]`): The ids of the question.
+ token_ids_1 (`list[int]`, *optional*): The ids of the flattened table.
+
+ Returns:
+ `list[int]`: The model input with special tokens.
+ """
+ if token_ids_1 is None:
+ raise ValueError("With TAPAS, you must provide both question IDs and table IDs.")
+
+ return [self.cls_token_id] + token_ids_0 + [self.sep_token_id] + token_ids_1
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of question IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ List of flattened table IDs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ if token_ids_1 is not None:
+ return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1))
+ return [1] + ([0] * len(token_ids_0)) + [1]
+
+ @add_end_docstrings(TAPAS_ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING)
+ def __call__(
+ self,
+ table: "pd.DataFrame",
+ queries: Optional[
+ Union[
+ TextInput,
+ PreTokenizedInput,
+ EncodedInput,
+ list[TextInput],
+ list[PreTokenizedInput],
+ list[EncodedInput],
+ ]
+ ] = None,
+ answer_coordinates: Optional[Union[list[tuple], list[list[tuple]]]] = None,
+ answer_text: Optional[Union[list[TextInput], list[list[TextInput]]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Main method to tokenize and prepare for the model one or several sequence(s) related to a table.
+
+ Args:
+ table (`pd.DataFrame`):
+ Table containing tabular data. Note that all cell values must be text. Use *.astype(str)* on a Pandas
+ dataframe to convert it to string.
+ queries (`str` or `list[str]`):
+ Question or batch of questions related to a table to be encoded. Note that in case of a batch, all
+ questions must refer to the **same** table.
+ answer_coordinates (`list[Tuple]` or `list[list[Tuple]]`, *optional*):
+ Answer coordinates of each table-question pair in the batch. In case only a single table-question pair
+ is provided, then the answer_coordinates must be a single list of one or more tuples. Each tuple must
+ be a (row_index, column_index) pair. The first data row (not the column header row) has index 0. The
+ first column has index 0. In case a batch of table-question pairs is provided, then the
+ answer_coordinates must be a list of lists of tuples (each list corresponding to a single
+ table-question pair).
+ answer_text (`list[str]` or `list[list[str]]`, *optional*):
+ Answer text of each table-question pair in the batch. In case only a single table-question pair is
+ provided, then the answer_text must be a single list of one or more strings. Each string must be the
+ answer text of a corresponding answer coordinate. In case a batch of table-question pairs is provided,
+ then the answer_coordinates must be a list of lists of strings (each list corresponding to a single
+ table-question pair).
+ """
+ assert isinstance(table, pd.DataFrame), "Table must be of type pd.DataFrame"
+
+ # Input type checking for clearer error
+ valid_query = False
+
+ # Check that query has a valid type
+ if queries is None or isinstance(queries, str):
+ valid_query = True
+ elif isinstance(queries, (list, tuple)):
+ if len(queries) == 0 or isinstance(queries[0], str):
+ valid_query = True
+
+ if not valid_query:
+ raise ValueError(
+ "queries input must of type `str` (single example), `list[str]` (batch or single pretokenized"
+ " example). "
+ )
+ is_batched = isinstance(queries, (list, tuple))
+
+ if is_batched:
+ return self.batch_encode_plus(
+ table=table,
+ queries=queries,
+ answer_coordinates=answer_coordinates,
+ answer_text=answer_text,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+ else:
+ return self.encode_plus(
+ table=table,
+ query=queries,
+ answer_coordinates=answer_coordinates,
+ answer_text=answer_text,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ @add_end_docstrings(ENCODE_KWARGS_DOCSTRING, TAPAS_ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING)
+ def batch_encode_plus(
+ self,
+ table: "pd.DataFrame",
+ queries: Optional[
+ Union[
+ list[TextInput],
+ list[PreTokenizedInput],
+ list[EncodedInput],
+ ]
+ ] = None,
+ answer_coordinates: Optional[list[list[tuple]]] = None,
+ answer_text: Optional[list[list[TextInput]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Prepare a table and a list of strings for the model.
+
+
+
+ This method is deprecated, `__call__` should be used instead.
+
+
+
+ Args:
+ table (`pd.DataFrame`):
+ Table containing tabular data. Note that all cell values must be text. Use *.astype(str)* on a Pandas
+ dataframe to convert it to string.
+ queries (`list[str]`):
+ Batch of questions related to a table to be encoded. Note that all questions must refer to the **same**
+ table.
+ answer_coordinates (`list[Tuple]` or `list[list[Tuple]]`, *optional*):
+ Answer coordinates of each table-question pair in the batch. Each tuple must be a (row_index,
+ column_index) pair. The first data row (not the column header row) has index 0. The first column has
+ index 0. The answer_coordinates must be a list of lists of tuples (each list corresponding to a single
+ table-question pair).
+ answer_text (`list[str]` or `list[list[str]]`, *optional*):
+ Answer text of each table-question pair in the batch. In case a batch of table-question pairs is
+ provided, then the answer_coordinates must be a list of lists of strings (each list corresponding to a
+ single table-question pair). Each string must be the answer text of a corresponding answer coordinate.
+ """
+ if return_token_type_ids is not None and not add_special_tokens:
+ raise ValueError(
+ "Asking to return token_type_ids while setting add_special_tokens to False "
+ "results in an undefined behavior. Please set add_special_tokens to True or "
+ "set return_token_type_ids to None."
+ )
+
+ if (answer_coordinates and not answer_text) or (not answer_coordinates and answer_text):
+ raise ValueError("In case you provide answers, both answer_coordinates and answer_text should be provided")
+ elif answer_coordinates is None and answer_text is None:
+ answer_coordinates = answer_text = [None] * len(queries)
+
+ if "is_split_into_words" in kwargs:
+ raise NotImplementedError("Currently TapasTokenizer only supports questions as strings.")
+
+ if return_offsets_mapping:
+ raise NotImplementedError(
+ "return_offset_mapping is not available when using Python tokenizers. "
+ "To use this feature, change your tokenizer to one deriving from "
+ "transformers.PreTrainedTokenizerFast."
+ )
+
+ return self._batch_encode_plus(
+ table=table,
+ queries=queries,
+ answer_coordinates=answer_coordinates,
+ answer_text=answer_text,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ def _get_question_tokens(self, query):
+ """Tokenizes the query, taking into account the max and min question length."""
+
+ query_tokens = self.tokenize(query)
+ if self.max_question_length is not None and len(query_tokens) > self.max_question_length:
+ logger.warning("Skipping query as its tokens are longer than the max question length")
+ return "", []
+ if self.min_question_length is not None and len(query_tokens) < self.min_question_length:
+ logger.warning("Skipping query as its tokens are shorter than the min question length")
+ return "", []
+
+ return query, query_tokens
+
+ def _batch_encode_plus(
+ self,
+ table,
+ queries: Union[
+ list[TextInput],
+ list[PreTokenizedInput],
+ list[EncodedInput],
+ ],
+ answer_coordinates: Optional[list[list[tuple]]] = None,
+ answer_text: Optional[list[list[TextInput]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = True,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ table_tokens = self._tokenize_table(table)
+
+ queries_tokens = []
+ for idx, query in enumerate(queries):
+ query, query_tokens = self._get_question_tokens(query)
+ queries[idx] = query
+ queries_tokens.append(query_tokens)
+
+ batch_outputs = self._batch_prepare_for_model(
+ table,
+ queries,
+ tokenized_table=table_tokens,
+ queries_tokens=queries_tokens,
+ answer_coordinates=answer_coordinates,
+ padding=padding,
+ truncation=truncation,
+ answer_text=answer_text,
+ add_special_tokens=add_special_tokens,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ prepend_batch_axis=True,
+ return_attention_mask=return_attention_mask,
+ return_token_type_ids=return_token_type_ids,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_length=return_length,
+ verbose=verbose,
+ )
+
+ return BatchEncoding(batch_outputs)
+
+ def _batch_prepare_for_model(
+ self,
+ raw_table: "pd.DataFrame",
+ raw_queries: Union[
+ list[TextInput],
+ list[PreTokenizedInput],
+ list[EncodedInput],
+ ],
+ tokenized_table: Optional[TokenizedTable] = None,
+ queries_tokens: Optional[list[list[str]]] = None,
+ answer_coordinates: Optional[list[list[tuple]]] = None,
+ answer_text: Optional[list[list[TextInput]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = True,
+ return_attention_mask: Optional[bool] = True,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ prepend_batch_axis: bool = False,
+ **kwargs,
+ ) -> BatchEncoding:
+ batch_outputs = {}
+
+ for index, example in enumerate(zip(raw_queries, queries_tokens, answer_coordinates, answer_text)):
+ raw_query, query_tokens, answer_coords, answer_txt = example
+ outputs = self.prepare_for_model(
+ raw_table,
+ raw_query,
+ tokenized_table=tokenized_table,
+ query_tokens=query_tokens,
+ answer_coordinates=answer_coords,
+ answer_text=answer_txt,
+ add_special_tokens=add_special_tokens,
+ padding=PaddingStrategy.DO_NOT_PAD.value, # we pad in batch afterwards
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=None, # we pad in batch afterwards
+ padding_side=None, # we pad in batch afterward
+ return_attention_mask=False, # we pad in batch afterwards
+ return_token_type_ids=return_token_type_ids,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_length=return_length,
+ return_tensors=None, # We convert the whole batch to tensors at the end
+ prepend_batch_axis=False,
+ verbose=verbose,
+ prev_answer_coordinates=answer_coordinates[index - 1] if index != 0 else None,
+ prev_answer_text=answer_text[index - 1] if index != 0 else None,
+ )
+
+ for key, value in outputs.items():
+ if key not in batch_outputs:
+ batch_outputs[key] = []
+ batch_outputs[key].append(value)
+
+ batch_outputs = self.pad(
+ batch_outputs,
+ padding=padding,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_attention_mask=return_attention_mask,
+ )
+
+ batch_outputs = BatchEncoding(batch_outputs, tensor_type=return_tensors)
+
+ return batch_outputs
+
+ @add_end_docstrings(ENCODE_KWARGS_DOCSTRING)
+ def encode(
+ self,
+ table: "pd.DataFrame",
+ query: Optional[
+ Union[
+ TextInput,
+ PreTokenizedInput,
+ EncodedInput,
+ ]
+ ] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ) -> list[int]:
+ """
+ Prepare a table and a string for the model. This method does not return token type IDs, attention masks, etc.
+ which are necessary for the model to work correctly. Use that method if you want to build your processing on
+ your own, otherwise refer to `__call__`.
+
+ Args:
+ table (`pd.DataFrame`):
+ Table containing tabular data. Note that all cell values must be text. Use *.astype(str)* on a Pandas
+ dataframe to convert it to string.
+ query (`str` or `list[str]`):
+ Question related to a table to be encoded.
+ """
+ encoded_inputs = self.encode_plus(
+ table,
+ query=query,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ return_tensors=return_tensors,
+ **kwargs,
+ )
+
+ return encoded_inputs["input_ids"]
+
+ @add_end_docstrings(ENCODE_KWARGS_DOCSTRING, TAPAS_ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING)
+ def encode_plus(
+ self,
+ table: "pd.DataFrame",
+ query: Optional[
+ Union[
+ TextInput,
+ PreTokenizedInput,
+ EncodedInput,
+ ]
+ ] = None,
+ answer_coordinates: Optional[list[tuple]] = None,
+ answer_text: Optional[list[TextInput]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Prepare a table and a string for the model.
+
+ Args:
+ table (`pd.DataFrame`):
+ Table containing tabular data. Note that all cell values must be text. Use *.astype(str)* on a Pandas
+ dataframe to convert it to string.
+ query (`str` or `list[str]`):
+ Question related to a table to be encoded.
+ answer_coordinates (`list[Tuple]` or `list[list[Tuple]]`, *optional*):
+ Answer coordinates of each table-question pair in the batch. The answer_coordinates must be a single
+ list of one or more tuples. Each tuple must be a (row_index, column_index) pair. The first data row
+ (not the column header row) has index 0. The first column has index 0.
+ answer_text (`list[str]` or `list[list[str]]`, *optional*):
+ Answer text of each table-question pair in the batch. The answer_text must be a single list of one or
+ more strings. Each string must be the answer text of a corresponding answer coordinate.
+ """
+ if return_token_type_ids is not None and not add_special_tokens:
+ raise ValueError(
+ "Asking to return token_type_ids while setting add_special_tokens to False "
+ "results in an undefined behavior. Please set add_special_tokens to True or "
+ "set return_token_type_ids to None."
+ )
+
+ if (answer_coordinates and not answer_text) or (not answer_coordinates and answer_text):
+ raise ValueError("In case you provide answers, both answer_coordinates and answer_text should be provided")
+
+ if "is_split_into_words" in kwargs:
+ raise NotImplementedError("Currently TapasTokenizer only supports questions as strings.")
+
+ if return_offsets_mapping:
+ raise NotImplementedError(
+ "return_offset_mapping is not available when using Python tokenizers. "
+ "To use this feature, change your tokenizer to one deriving from "
+ "transformers.PreTrainedTokenizerFast."
+ )
+
+ return self._encode_plus(
+ table=table,
+ query=query,
+ answer_coordinates=answer_coordinates,
+ answer_text=answer_text,
+ add_special_tokens=add_special_tokens,
+ truncation=truncation,
+ padding=padding,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ def _encode_plus(
+ self,
+ table: "pd.DataFrame",
+ query: Union[
+ TextInput,
+ PreTokenizedInput,
+ EncodedInput,
+ ],
+ answer_coordinates: Optional[list[tuple]] = None,
+ answer_text: Optional[list[TextInput]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = True,
+ return_attention_mask: Optional[bool] = True,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ):
+ if query is None:
+ query = ""
+ logger.warning(
+ "TAPAS is a question answering model but you have not passed a query. Please be aware that the "
+ "model will probably not behave correctly."
+ )
+
+ table_tokens = self._tokenize_table(table)
+ query, query_tokens = self._get_question_tokens(query)
+
+ return self.prepare_for_model(
+ table,
+ query,
+ tokenized_table=table_tokens,
+ query_tokens=query_tokens,
+ answer_coordinates=answer_coordinates,
+ answer_text=answer_text,
+ add_special_tokens=add_special_tokens,
+ truncation=truncation,
+ padding=padding,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ prepend_batch_axis=True,
+ return_attention_mask=return_attention_mask,
+ return_token_type_ids=return_token_type_ids,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_length=return_length,
+ verbose=verbose,
+ )
+
+ @add_end_docstrings(ENCODE_KWARGS_DOCSTRING, TAPAS_ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING)
+ def prepare_for_model(
+ self,
+ raw_table: "pd.DataFrame",
+ raw_query: Union[
+ TextInput,
+ PreTokenizedInput,
+ EncodedInput,
+ ],
+ tokenized_table: Optional[TokenizedTable] = None,
+ query_tokens: Optional[TokenizedTable] = None,
+ answer_coordinates: Optional[list[tuple]] = None,
+ answer_text: Optional[list[TextInput]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TapasTruncationStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = True,
+ return_attention_mask: Optional[bool] = True,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ prepend_batch_axis: bool = False,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Prepares a sequence of input id so that it can be used by the model. It adds special tokens, truncates
+ sequences if overflowing while taking into account the special tokens.
+
+ Args:
+ raw_table (`pd.DataFrame`):
+ The original table before any transformation (like tokenization) was applied to it.
+ raw_query (`TextInput` or `PreTokenizedInput` or `EncodedInput`):
+ The original query before any transformation (like tokenization) was applied to it.
+ tokenized_table (`TokenizedTable`):
+ The table after tokenization.
+ query_tokens (`list[str]`):
+ The query after tokenization.
+ answer_coordinates (`list[Tuple]` or `list[list[Tuple]]`, *optional*):
+ Answer coordinates of each table-question pair in the batch. The answer_coordinates must be a single
+ list of one or more tuples. Each tuple must be a (row_index, column_index) pair. The first data row
+ (not the column header row) has index 0. The first column has index 0.
+ answer_text (`list[str]` or `list[list[str]]`, *optional*):
+ Answer text of each table-question pair in the batch. The answer_text must be a single list of one or
+ more strings. Each string must be the answer text of a corresponding answer coordinate.
+ """
+ if isinstance(padding, bool):
+ if padding and (max_length is not None or pad_to_multiple_of is not None):
+ padding = PaddingStrategy.MAX_LENGTH
+ else:
+ padding = PaddingStrategy.DO_NOT_PAD
+ elif not isinstance(padding, PaddingStrategy):
+ padding = PaddingStrategy(padding)
+
+ if isinstance(truncation, bool):
+ if truncation:
+ truncation = TapasTruncationStrategy.DROP_ROWS_TO_FIT
+ else:
+ truncation = TapasTruncationStrategy.DO_NOT_TRUNCATE
+ elif not isinstance(truncation, TapasTruncationStrategy):
+ truncation = TapasTruncationStrategy(truncation)
+
+ encoded_inputs = {}
+
+ is_part_of_batch = False
+ prev_answer_coordinates, prev_answer_text = None, None
+ if "prev_answer_coordinates" in kwargs and "prev_answer_text" in kwargs:
+ is_part_of_batch = True
+ prev_answer_coordinates = kwargs["prev_answer_coordinates"]
+ prev_answer_text = kwargs["prev_answer_text"]
+
+ num_rows = self._get_num_rows(raw_table, truncation != TapasTruncationStrategy.DO_NOT_TRUNCATE)
+ num_columns = self._get_num_columns(raw_table)
+ _, _, num_tokens = self._get_table_boundaries(tokenized_table)
+
+ if truncation != TapasTruncationStrategy.DO_NOT_TRUNCATE:
+ num_rows, num_tokens = self._get_truncated_table_rows(
+ query_tokens, tokenized_table, num_rows, num_columns, max_length, truncation_strategy=truncation
+ )
+ table_data = list(self._get_table_values(tokenized_table, num_columns, num_rows, num_tokens))
+
+ query_ids = self.convert_tokens_to_ids(query_tokens)
+ table_ids = list(zip(*table_data))[0] if len(table_data) > 0 else list(zip(*table_data))
+ table_ids = self.convert_tokens_to_ids(list(table_ids))
+
+ if "return_overflowing_tokens" in kwargs and kwargs["return_overflowing_tokens"]:
+ raise ValueError("TAPAS does not return overflowing tokens as it works on tables.")
+
+ if add_special_tokens:
+ input_ids = self.build_inputs_with_special_tokens(query_ids, table_ids)
+ else:
+ input_ids = query_ids + table_ids
+
+ if max_length is not None and len(input_ids) > max_length:
+ raise ValueError(
+ "Could not encode the query and table header given the maximum length. Encoding the query and table "
+ f"header results in a length of {len(input_ids)} which is higher than the max_length of {max_length}"
+ )
+
+ encoded_inputs["input_ids"] = input_ids
+
+ segment_ids = self.create_segment_token_type_ids_from_sequences(query_ids, table_data)
+ column_ids = self.create_column_token_type_ids_from_sequences(query_ids, table_data)
+ row_ids = self.create_row_token_type_ids_from_sequences(query_ids, table_data)
+ if not is_part_of_batch or (prev_answer_coordinates is None and prev_answer_text is None):
+ # simply set the prev_labels to zeros
+ prev_labels = [0] * len(row_ids)
+ else:
+ prev_labels = self.get_answer_ids(
+ column_ids, row_ids, table_data, prev_answer_text, prev_answer_coordinates
+ )
+
+ # FIRST: parse both the table and question in terms of numeric values
+
+ raw_table = add_numeric_table_values(raw_table)
+ raw_query = add_numeric_values_to_question(raw_query)
+
+ # SECOND: add numeric-related features (and not parse them in these functions):
+
+ column_ranks, inv_column_ranks = self._get_numeric_column_ranks(column_ids, row_ids, raw_table)
+ numeric_relations = self._get_numeric_relations(raw_query, column_ids, row_ids, raw_table)
+
+ # Load from model defaults
+ if return_token_type_ids is None:
+ return_token_type_ids = "token_type_ids" in self.model_input_names
+ if return_attention_mask is None:
+ return_attention_mask = "attention_mask" in self.model_input_names
+
+ if return_attention_mask:
+ attention_mask = self.create_attention_mask_from_sequences(query_ids, table_data)
+ encoded_inputs["attention_mask"] = attention_mask
+
+ if answer_coordinates is not None and answer_text is not None:
+ labels = self.get_answer_ids(column_ids, row_ids, table_data, answer_text, answer_coordinates)
+ numeric_values = self._get_numeric_values(raw_table, column_ids, row_ids)
+ numeric_values_scale = self._get_numeric_values_scale(raw_table, column_ids, row_ids)
+
+ encoded_inputs["labels"] = labels
+ encoded_inputs["numeric_values"] = numeric_values
+ encoded_inputs["numeric_values_scale"] = numeric_values_scale
+
+ if return_token_type_ids:
+ token_type_ids = [
+ segment_ids,
+ column_ids,
+ row_ids,
+ prev_labels,
+ column_ranks,
+ inv_column_ranks,
+ numeric_relations,
+ ]
+
+ token_type_ids = [list(ids) for ids in list(zip(*token_type_ids))]
+ encoded_inputs["token_type_ids"] = token_type_ids
+
+ if return_special_tokens_mask:
+ if add_special_tokens:
+ encoded_inputs["special_tokens_mask"] = self.get_special_tokens_mask(query_ids, table_ids)
+ else:
+ encoded_inputs["special_tokens_mask"] = [0] * len(input_ids)
+
+ # Check lengths
+ if max_length is None and len(encoded_inputs["input_ids"]) > self.model_max_length and verbose:
+ if not self.deprecation_warnings.get("sequence-length-is-longer-than-the-specified-maximum", False):
+ logger.warning(
+ "Token indices sequence length is longer than the specified maximum sequence length "
+ f"for this model ({len(encoded_inputs['input_ids'])} > {self.model_max_length}). Running this "
+ "sequence through the model will result in indexing errors."
+ )
+ self.deprecation_warnings["sequence-length-is-longer-than-the-specified-maximum"] = True
+
+ # Padding
+ if padding != PaddingStrategy.DO_NOT_PAD or return_attention_mask:
+ encoded_inputs = self.pad(
+ encoded_inputs,
+ max_length=max_length,
+ padding=padding.value,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_attention_mask=return_attention_mask,
+ )
+
+ if return_length:
+ encoded_inputs["length"] = len(encoded_inputs["input_ids"])
+
+ batch_outputs = BatchEncoding(
+ encoded_inputs, tensor_type=return_tensors, prepend_batch_axis=prepend_batch_axis
+ )
+
+ return batch_outputs
+
+ def _get_truncated_table_rows(
+ self,
+ query_tokens: list[str],
+ tokenized_table: TokenizedTable,
+ num_rows: int,
+ num_columns: int,
+ max_length: int,
+ truncation_strategy: Union[str, TapasTruncationStrategy],
+ ) -> tuple[int, int]:
+ """
+ Truncates a sequence pair in-place following the strategy.
+
+ Args:
+ query_tokens (`list[str]`):
+ List of strings corresponding to the tokenized query.
+ tokenized_table (`TokenizedTable`):
+ Tokenized table
+ num_rows (`int`):
+ Total number of table rows
+ num_columns (`int`):
+ Total number of table columns
+ max_length (`int`):
+ Total maximum length.
+ truncation_strategy (`str` or [`TapasTruncationStrategy]`):
+ Truncation strategy to use. Seeing as this method should only be called when truncating, the only
+ available strategy is the `"drop_rows_to_fit"` strategy.
+
+ Returns:
+ `Tuple(int, int)`: tuple containing the number of rows after truncation, and the number of tokens available
+ for each table element.
+ """
+ if not isinstance(truncation_strategy, TapasTruncationStrategy):
+ truncation_strategy = TapasTruncationStrategy(truncation_strategy)
+
+ if max_length is None:
+ max_length = self.model_max_length
+
+ if truncation_strategy == TapasTruncationStrategy.DROP_ROWS_TO_FIT:
+ while True:
+ num_tokens = self._get_max_num_tokens(
+ query_tokens, tokenized_table, num_rows=num_rows, num_columns=num_columns, max_length=max_length
+ )
+
+ if num_tokens is not None:
+ # We could fit the table.
+ break
+
+ # Try to drop a row to fit the table.
+ num_rows -= 1
+
+ if num_rows < 1:
+ break
+ elif truncation_strategy != TapasTruncationStrategy.DO_NOT_TRUNCATE:
+ raise ValueError(f"Unknown truncation strategy {truncation_strategy}.")
+
+ return num_rows, num_tokens or 1
+
+ def _tokenize_table(
+ self,
+ table=None,
+ ):
+ """
+ Tokenizes column headers and cell texts of a table.
+
+ Args:
+ table (`pd.Dataframe`):
+ Table. Returns: `TokenizedTable`: TokenizedTable object.
+ """
+ tokenized_rows = []
+ tokenized_row = []
+ # tokenize column headers
+ for column in table:
+ if self.strip_column_names:
+ tokenized_row.append(self.tokenize(""))
+ else:
+ tokenized_row.append(self.tokenize(column))
+ tokenized_rows.append(tokenized_row)
+
+ # tokenize cell values
+ for idx, row in table.iterrows():
+ tokenized_row = []
+ for cell in row:
+ tokenized_row.append(self.tokenize(cell))
+ tokenized_rows.append(tokenized_row)
+
+ token_coordinates = []
+ for row_index, row in enumerate(tokenized_rows):
+ for column_index, cell in enumerate(row):
+ for token_index, _ in enumerate(cell):
+ token_coordinates.append(
+ TokenCoordinates(
+ row_index=row_index,
+ column_index=column_index,
+ token_index=token_index,
+ )
+ )
+
+ return TokenizedTable(
+ rows=tokenized_rows,
+ selected_tokens=token_coordinates,
+ )
+
+ def _question_encoding_cost(self, question_tokens):
+ # Two extra spots of SEP and CLS.
+ return len(question_tokens) + 2
+
+ def _get_token_budget(self, question_tokens, max_length=None):
+ """
+ Computes the number of tokens left for the table after tokenizing a question, taking into account the max
+ sequence length of the model.
+
+ Args:
+ question_tokens (`list[String]`):
+ List of question tokens. Returns: `int`: the number of tokens left for the table, given the model max
+ length.
+ """
+ return (max_length if max_length is not None else self.model_max_length) - self._question_encoding_cost(
+ question_tokens
+ )
+
+ def _get_table_values(self, table, num_columns, num_rows, num_tokens) -> Generator[TableValue, None, None]:
+ """Iterates over partial table and returns token, column and row indexes."""
+ for tc in table.selected_tokens:
+ # First row is header row.
+ if tc.row_index >= num_rows + 1:
+ continue
+ if tc.column_index >= num_columns:
+ continue
+ cell = table.rows[tc.row_index][tc.column_index]
+ token = cell[tc.token_index]
+ word_begin_index = tc.token_index
+ # Don't add partial words. Find the starting word piece and check if it
+ # fits in the token budget.
+ while word_begin_index >= 0 and _is_inner_wordpiece(cell[word_begin_index]):
+ word_begin_index -= 1
+ if word_begin_index >= num_tokens:
+ continue
+ yield TableValue(token, tc.column_index + 1, tc.row_index)
+
+ def _get_table_boundaries(self, table):
+ """Return maximal number of rows, columns and tokens."""
+ max_num_tokens = 0
+ max_num_columns = 0
+ max_num_rows = 0
+ for tc in table.selected_tokens:
+ max_num_columns = max(max_num_columns, tc.column_index + 1)
+ max_num_rows = max(max_num_rows, tc.row_index + 1)
+ max_num_tokens = max(max_num_tokens, tc.token_index + 1)
+ max_num_columns = min(self.max_column_id, max_num_columns)
+ max_num_rows = min(self.max_row_id, max_num_rows)
+ return max_num_rows, max_num_columns, max_num_tokens
+
+ def _get_table_cost(self, table, num_columns, num_rows, num_tokens):
+ return sum(1 for _ in self._get_table_values(table, num_columns, num_rows, num_tokens))
+
+ def _get_max_num_tokens(self, question_tokens, tokenized_table, num_columns, num_rows, max_length):
+ """Computes max number of tokens that can be squeezed into the budget."""
+ token_budget = self._get_token_budget(question_tokens, max_length)
+ _, _, max_num_tokens = self._get_table_boundaries(tokenized_table)
+ if self.cell_trim_length >= 0 and max_num_tokens > self.cell_trim_length:
+ max_num_tokens = self.cell_trim_length
+ num_tokens = 0
+ for num_tokens in range(max_num_tokens + 1):
+ cost = self._get_table_cost(tokenized_table, num_columns, num_rows, num_tokens + 1)
+ if cost > token_budget:
+ break
+ if num_tokens < max_num_tokens:
+ if self.cell_trim_length >= 0:
+ # We don't allow dynamic trimming if a cell_trim_length is set.
+ return None
+ if num_tokens == 0:
+ return None
+ return num_tokens
+
+ def _get_num_columns(self, table):
+ num_columns = table.shape[1]
+ if num_columns >= self.max_column_id:
+ raise ValueError("Too many columns")
+ return num_columns
+
+ def _get_num_rows(self, table, drop_rows_to_fit):
+ num_rows = table.shape[0]
+ if num_rows >= self.max_row_id:
+ if drop_rows_to_fit:
+ num_rows = self.max_row_id - 1
+ else:
+ raise ValueError("Too many rows")
+ return num_rows
+
+ def _serialize_text(self, question_tokens):
+ """Serializes texts in index arrays."""
+ tokens = []
+ segment_ids = []
+ column_ids = []
+ row_ids = []
+
+ # add [CLS] token at the beginning
+ tokens.append(self.cls_token)
+ segment_ids.append(0)
+ column_ids.append(0)
+ row_ids.append(0)
+
+ for token in question_tokens:
+ tokens.append(token)
+ segment_ids.append(0)
+ column_ids.append(0)
+ row_ids.append(0)
+
+ return tokens, segment_ids, column_ids, row_ids
+
+ def _serialize(
+ self,
+ question_tokens,
+ table,
+ num_columns,
+ num_rows,
+ num_tokens,
+ ):
+ """Serializes table and text."""
+ tokens, segment_ids, column_ids, row_ids = self._serialize_text(question_tokens)
+
+ # add [SEP] token between question and table tokens
+ tokens.append(self.sep_token)
+ segment_ids.append(0)
+ column_ids.append(0)
+ row_ids.append(0)
+
+ for token, column_id, row_id in self._get_table_values(table, num_columns, num_rows, num_tokens):
+ tokens.append(token)
+ segment_ids.append(1)
+ column_ids.append(column_id)
+ row_ids.append(row_id)
+
+ return SerializedExample(
+ tokens=tokens,
+ segment_ids=segment_ids,
+ column_ids=column_ids,
+ row_ids=row_ids,
+ )
+
+ def _get_column_values(self, table, col_index):
+ table_numeric_values = {}
+ for row_index, row in table.iterrows():
+ cell = row[col_index]
+ if cell.numeric_value is not None:
+ table_numeric_values[row_index] = cell.numeric_value
+ return table_numeric_values
+
+ def _get_cell_token_indexes(self, column_ids, row_ids, column_id, row_id):
+ for index in range(len(column_ids)):
+ if column_ids[index] - 1 == column_id and row_ids[index] - 1 == row_id:
+ yield index
+
+ def _get_numeric_column_ranks(self, column_ids, row_ids, table):
+ """Returns column ranks for all numeric columns."""
+
+ ranks = [0] * len(column_ids)
+ inv_ranks = [0] * len(column_ids)
+
+ # original code from tf_example_utils.py of the original implementation
+ if table is not None:
+ for col_index in range(len(table.columns)):
+ table_numeric_values = self._get_column_values(table, col_index)
+
+ if not table_numeric_values:
+ continue
+
+ try:
+ key_fn = get_numeric_sort_key_fn(table_numeric_values.values())
+ except ValueError:
+ continue
+
+ table_numeric_values = {row_index: key_fn(value) for row_index, value in table_numeric_values.items()}
+
+ table_numeric_values_inv = collections.defaultdict(list)
+ for row_index, value in table_numeric_values.items():
+ table_numeric_values_inv[value].append(row_index)
+
+ unique_values = sorted(table_numeric_values_inv.keys())
+
+ for rank, value in enumerate(unique_values):
+ for row_index in table_numeric_values_inv[value]:
+ for index in self._get_cell_token_indexes(column_ids, row_ids, col_index, row_index):
+ ranks[index] = rank + 1
+ inv_ranks[index] = len(unique_values) - rank
+
+ return ranks, inv_ranks
+
+ def _get_numeric_sort_key_fn(self, table_numeric_values, value):
+ """
+ Returns the sort key function for comparing value to table values. The function returned will be a suitable
+ input for the key param of the sort(). See number_annotation_utils._get_numeric_sort_key_fn for details
+
+ Args:
+ table_numeric_values: Numeric values of a column
+ value: Numeric value in the question
+
+ Returns:
+ A function key function to compare column and question values.
+ """
+ if not table_numeric_values:
+ return None
+ all_values = list(table_numeric_values.values())
+ all_values.append(value)
+ try:
+ return get_numeric_sort_key_fn(all_values)
+ except ValueError:
+ return None
+
+ def _get_numeric_relations(self, question, column_ids, row_ids, table):
+ """
+ Returns numeric relations embeddings
+
+ Args:
+ question: Question object.
+ column_ids: Maps word piece position to column id.
+ row_ids: Maps word piece position to row id.
+ table: The table containing the numeric cell values.
+ """
+
+ numeric_relations = [0] * len(column_ids)
+
+ # first, we add any numeric value spans to the question:
+ # Create a dictionary that maps a table cell to the set of all relations
+ # this cell has with any value in the question.
+ cell_indices_to_relations = collections.defaultdict(set)
+ if question is not None and table is not None:
+ for numeric_value_span in question.numeric_spans:
+ for value in numeric_value_span.values:
+ for column_index in range(len(table.columns)):
+ table_numeric_values = self._get_column_values(table, column_index)
+ sort_key_fn = self._get_numeric_sort_key_fn(table_numeric_values, value)
+ if sort_key_fn is None:
+ continue
+ for row_index, cell_value in table_numeric_values.items():
+ relation = get_numeric_relation(value, cell_value, sort_key_fn)
+ if relation is not None:
+ cell_indices_to_relations[column_index, row_index].add(relation)
+
+ # For each cell add a special feature for all its word pieces.
+ for (column_index, row_index), relations in cell_indices_to_relations.items():
+ relation_set_index = 0
+ for relation in relations:
+ assert relation.value >= Relation.EQ.value
+ relation_set_index += 2 ** (relation.value - Relation.EQ.value)
+ for cell_token_index in self._get_cell_token_indexes(column_ids, row_ids, column_index, row_index):
+ numeric_relations[cell_token_index] = relation_set_index
+
+ return numeric_relations
+
+ def _get_numeric_values(self, table, column_ids, row_ids):
+ """Returns numeric values for computation of answer loss."""
+
+ numeric_values = [float("nan")] * len(column_ids)
+
+ if table is not None:
+ num_rows = table.shape[0]
+ num_columns = table.shape[1]
+
+ for col_index in range(num_columns):
+ for row_index in range(num_rows):
+ numeric_value = table.iloc[row_index, col_index].numeric_value
+ if numeric_value is not None:
+ if numeric_value.float_value is None:
+ continue
+ float_value = numeric_value.float_value
+ if float_value == float("inf"):
+ continue
+ for index in self._get_cell_token_indexes(column_ids, row_ids, col_index, row_index):
+ numeric_values[index] = float_value
+
+ return numeric_values
+
+ def _get_numeric_values_scale(self, table, column_ids, row_ids):
+ """Returns a scale to each token to down weigh the value of long words."""
+
+ numeric_values_scale = [1.0] * len(column_ids)
+
+ if table is None:
+ return numeric_values_scale
+
+ num_rows = table.shape[0]
+ num_columns = table.shape[1]
+
+ for col_index in range(num_columns):
+ for row_index in range(num_rows):
+ indices = list(self._get_cell_token_indexes(column_ids, row_ids, col_index, row_index))
+ num_indices = len(indices)
+ if num_indices > 1:
+ for index in indices:
+ numeric_values_scale[index] = float(num_indices)
+
+ return numeric_values_scale
+
+ def _pad_to_seq_length(self, inputs):
+ while len(inputs) > self.model_max_length:
+ inputs.pop()
+ while len(inputs) < self.model_max_length:
+ inputs.append(0)
+
+ def _get_all_answer_ids_from_coordinates(
+ self,
+ column_ids,
+ row_ids,
+ answers_list,
+ ):
+ """Maps lists of answer coordinates to token indexes."""
+ answer_ids = [0] * len(column_ids)
+ found_answers = set()
+ all_answers = set()
+ for answers in answers_list:
+ column_index, row_index = answers
+ all_answers.add((column_index, row_index))
+ for index in self._get_cell_token_indexes(column_ids, row_ids, column_index, row_index):
+ found_answers.add((column_index, row_index))
+ answer_ids[index] = 1
+
+ missing_count = len(all_answers) - len(found_answers)
+ return answer_ids, missing_count
+
+ def _get_all_answer_ids(self, column_ids, row_ids, answer_coordinates):
+ """
+ Maps answer coordinates of a question to token indexes.
+
+ In the SQA format (TSV), the coordinates are given as (row, column) tuples. Here, we first swap them to
+ (column, row) format before calling _get_all_answer_ids_from_coordinates.
+ """
+
+ def _to_coordinates(answer_coordinates_question):
+ return [(coords[1], coords[0]) for coords in answer_coordinates_question]
+
+ return self._get_all_answer_ids_from_coordinates(
+ column_ids, row_ids, answers_list=(_to_coordinates(answer_coordinates))
+ )
+
+ def _find_tokens(self, text, segment):
+ """Return start index of segment in text or None."""
+ logging.info(f"text: {text} {segment}")
+ for index in range(1 + len(text) - len(segment)):
+ for seg_index, seg_token in enumerate(segment):
+ if text[index + seg_index].piece != seg_token.piece:
+ break
+ else:
+ return index
+ return None
+
+ def _find_answer_coordinates_from_answer_text(
+ self,
+ tokenized_table,
+ answer_text,
+ ):
+ """Returns all occurrences of answer_text in the table."""
+ logging.info(f"answer text: {answer_text}")
+ for row_index, row in enumerate(tokenized_table.rows):
+ if row_index == 0:
+ # We don't search for answers in the header.
+ continue
+ for col_index, cell in enumerate(row):
+ token_index = self._find_tokens(cell, answer_text)
+ if token_index is not None:
+ yield TokenCoordinates(
+ row_index=row_index,
+ column_index=col_index,
+ token_index=token_index,
+ )
+
+ def _find_answer_ids_from_answer_texts(
+ self,
+ column_ids,
+ row_ids,
+ tokenized_table,
+ answer_texts,
+ ):
+ """Maps question with answer texts to the first matching token indexes."""
+ answer_ids = [0] * len(column_ids)
+ for answer_text in answer_texts:
+ for coordinates in self._find_answer_coordinates_from_answer_text(
+ tokenized_table,
+ answer_text,
+ ):
+ # Maps answer coordinates to indexes this can fail if tokens / rows have
+ # been pruned.
+ indexes = list(
+ self._get_cell_token_indexes(
+ column_ids,
+ row_ids,
+ column_id=coordinates.column_index,
+ row_id=coordinates.row_index - 1,
+ )
+ )
+ indexes.sort()
+ coordinate_answer_ids = []
+ if indexes:
+ begin_index = coordinates.token_index + indexes[0]
+ end_index = begin_index + len(answer_text)
+ for index in indexes:
+ if index >= begin_index and index < end_index:
+ coordinate_answer_ids.append(index)
+ if len(coordinate_answer_ids) == len(answer_text):
+ for index in coordinate_answer_ids:
+ answer_ids[index] = 1
+ break
+ return answer_ids
+
+ def _get_answer_ids(self, column_ids, row_ids, answer_coordinates):
+ """Maps answer coordinates of a question to token indexes."""
+ answer_ids, missing_count = self._get_all_answer_ids(column_ids, row_ids, answer_coordinates)
+
+ if missing_count:
+ raise ValueError("Couldn't find all answers")
+ return answer_ids
+
+ def get_answer_ids(self, column_ids, row_ids, tokenized_table, answer_texts_question, answer_coordinates_question):
+ if self.update_answer_coordinates:
+ return self._find_answer_ids_from_answer_texts(
+ column_ids,
+ row_ids,
+ tokenized_table,
+ answer_texts=[self.tokenize(at) for at in answer_texts_question],
+ )
+ return self._get_answer_ids(column_ids, row_ids, answer_coordinates_question)
+
+ def _pad(
+ self,
+ encoded_inputs: Union[dict[str, EncodedInput], BatchEncoding],
+ max_length: Optional[int] = None,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_attention_mask: Optional[bool] = None,
+ ) -> dict:
+ """
+ Pad encoded inputs (on left/right and up to predefined length or max length in the batch)
+
+ Args:
+ encoded_inputs:
+ Dictionary of tokenized inputs (`list[int]`) or batch of tokenized inputs (`list[list[int]]`).
+ max_length: maximum length of the returned list and optionally padding length (see below).
+ Will truncate by taking into account the special tokens.
+ padding_strategy: PaddingStrategy to use for padding.
+
+ - PaddingStrategy.LONGEST Pad to the longest sequence in the batch
+ - PaddingStrategy.MAX_LENGTH: Pad to the max length (default)
+ - PaddingStrategy.DO_NOT_PAD: Do not pad
+ The tokenizer padding sides are defined in self.padding_side:
+
+ - 'left': pads on the left of the sequences
+ - 'right': pads on the right of the sequences
+ pad_to_multiple_of: (optional) Integer if set will pad the sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Core on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta).
+ padding_side:
+ The side on which the model should have padding applied. Should be selected between ['right', 'left'].
+ Default value is picked from the class attribute of the same name.
+ return_attention_mask:
+ (optional) Set to False to avoid returning attention mask (default: set to model specifics)
+ """
+ # Load from model defaults
+ if return_attention_mask is None:
+ return_attention_mask = "attention_mask" in self.model_input_names
+
+ if padding_strategy == PaddingStrategy.LONGEST:
+ max_length = len(encoded_inputs["input_ids"])
+
+ if max_length is not None and pad_to_multiple_of is not None and (max_length % pad_to_multiple_of != 0):
+ max_length = ((max_length // pad_to_multiple_of) + 1) * pad_to_multiple_of
+
+ needs_to_be_padded = (
+ padding_strategy != PaddingStrategy.DO_NOT_PAD and len(encoded_inputs["input_ids"]) != max_length
+ )
+
+ # Initialize attention mask if not present.
+ if return_attention_mask and "attention_mask" not in encoded_inputs:
+ encoded_inputs["attention_mask"] = [1] * len(encoded_inputs["input_ids"])
+
+ if needs_to_be_padded:
+ difference = max_length - len(encoded_inputs["input_ids"])
+ padding_side = padding_side if padding_side is not None else self.padding_side
+ if padding_side == "right":
+ if return_attention_mask:
+ encoded_inputs["attention_mask"] = encoded_inputs["attention_mask"] + [0] * difference
+ if "token_type_ids" in encoded_inputs:
+ encoded_inputs["token_type_ids"] = (
+ encoded_inputs["token_type_ids"] + [[self.pad_token_type_id] * 7] * difference
+ )
+ if "labels" in encoded_inputs:
+ encoded_inputs["labels"] = encoded_inputs["labels"] + [0] * difference
+ if "numeric_values" in encoded_inputs:
+ encoded_inputs["numeric_values"] = encoded_inputs["numeric_values"] + [float("nan")] * difference
+ if "numeric_values_scale" in encoded_inputs:
+ encoded_inputs["numeric_values_scale"] = (
+ encoded_inputs["numeric_values_scale"] + [1.0] * difference
+ )
+ if "special_tokens_mask" in encoded_inputs:
+ encoded_inputs["special_tokens_mask"] = encoded_inputs["special_tokens_mask"] + [1] * difference
+ encoded_inputs["input_ids"] = encoded_inputs["input_ids"] + [self.pad_token_id] * difference
+ elif padding_side == "left":
+ if return_attention_mask:
+ encoded_inputs["attention_mask"] = [0] * difference + encoded_inputs["attention_mask"]
+ if "token_type_ids" in encoded_inputs:
+ encoded_inputs["token_type_ids"] = [[self.pad_token_type_id] * 7] * difference + encoded_inputs[
+ "token_type_ids"
+ ]
+ if "labels" in encoded_inputs:
+ encoded_inputs["labels"] = [0] * difference + encoded_inputs["labels"]
+ if "numeric_values" in encoded_inputs:
+ encoded_inputs["numeric_values"] = [float("nan")] * difference + encoded_inputs["numeric_values"]
+ if "numeric_values_scale" in encoded_inputs:
+ encoded_inputs["numeric_values_scale"] = [1.0] * difference + encoded_inputs[
+ "numeric_values_scale"
+ ]
+ if "special_tokens_mask" in encoded_inputs:
+ encoded_inputs["special_tokens_mask"] = [1] * difference + encoded_inputs["special_tokens_mask"]
+ encoded_inputs["input_ids"] = [self.pad_token_id] * difference + encoded_inputs["input_ids"]
+ else:
+ raise ValueError("Invalid padding strategy:" + str(padding_side))
+
+ return encoded_inputs
+
+ # Everything related to converting logits to predictions
+
+ def _get_cell_token_probs(self, probabilities, segment_ids, row_ids, column_ids):
+ for i, p in enumerate(probabilities):
+ segment_id = segment_ids[i]
+ col = column_ids[i] - 1
+ row = row_ids[i] - 1
+ if col >= 0 and row >= 0 and segment_id == 1:
+ yield i, p
+
+ def _get_mean_cell_probs(self, probabilities, segment_ids, row_ids, column_ids):
+ """Computes average probability per cell, aggregating over tokens."""
+ coords_to_probs = collections.defaultdict(list)
+ for i, prob in self._get_cell_token_probs(probabilities, segment_ids, row_ids, column_ids):
+ col = column_ids[i] - 1
+ row = row_ids[i] - 1
+ coords_to_probs[(col, row)].append(prob)
+ return {coords: np.array(cell_probs).mean() for coords, cell_probs in coords_to_probs.items()}
+
+ def convert_logits_to_predictions(self, data, logits, logits_agg=None, cell_classification_threshold=0.5):
+ """
+ Converts logits of [`TapasForQuestionAnswering`] to actual predicted answer coordinates and optional
+ aggregation indices.
+
+ The original implementation, on which this function is based, can be found
+ [here](https://github.com/google-research/tapas/blob/4908213eb4df7aa988573350278b44c4dbe3f71b/tapas/experiments/prediction_utils.py#L288).
+
+ Args:
+ data (`dict`):
+ Dictionary mapping features to actual values. Should be created using [`TapasTokenizer`].
+ logits (`torch.Tensor` or `tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Tensor containing the logits at the token level.
+ logits_agg (`torch.Tensor` or `tf.Tensor` of shape `(batch_size, num_aggregation_labels)`, *optional*):
+ Tensor containing the aggregation logits.
+ cell_classification_threshold (`float`, *optional*, defaults to 0.5):
+ Threshold to be used for cell selection. All table cells for which their probability is larger than
+ this threshold will be selected.
+
+ Returns:
+ `tuple` comprising various elements depending on the inputs:
+
+ - predicted_answer_coordinates (`list[list[[tuple]]` of length `batch_size`): Predicted answer coordinates
+ as a list of lists of tuples. Each element in the list contains the predicted answer coordinates of a
+ single example in the batch, as a list of tuples. Each tuple is a cell, i.e. (row index, column index).
+ - predicted_aggregation_indices (`list[int]`of length `batch_size`, *optional*, returned when
+ `logits_aggregation` is provided): Predicted aggregation operator indices of the aggregation head.
+ """
+ # converting to numpy arrays to work with PT/TF
+ logits = logits.numpy()
+ if logits_agg is not None:
+ logits_agg = logits_agg.numpy()
+ data = {key: value.numpy() for key, value in data.items() if key != "training"}
+ # input data is of type float32
+ # np.log(np.finfo(np.float32).max) = 88.72284
+ # Any value over 88.72284 will overflow when passed through the exponential, sending a warning
+ # We disable this warning by truncating the logits.
+ logits[logits < -88.7] = -88.7
+
+ # Compute probabilities from token logits
+ probabilities = 1 / (1 + np.exp(-logits)) * data["attention_mask"]
+ token_types = [
+ "segment_ids",
+ "column_ids",
+ "row_ids",
+ "prev_labels",
+ "column_ranks",
+ "inv_column_ranks",
+ "numeric_relations",
+ ]
+
+ # collect input_ids, segment ids, row ids and column ids of batch. Shape (batch_size, seq_len)
+ input_ids = data["input_ids"]
+ segment_ids = data["token_type_ids"][:, :, token_types.index("segment_ids")]
+ row_ids = data["token_type_ids"][:, :, token_types.index("row_ids")]
+ column_ids = data["token_type_ids"][:, :, token_types.index("column_ids")]
+
+ # next, get answer coordinates for every example in the batch
+ num_batch = input_ids.shape[0]
+ predicted_answer_coordinates = []
+ for i in range(num_batch):
+ probabilities_example = probabilities[i].tolist()
+ segment_ids_example = segment_ids[i]
+ row_ids_example = row_ids[i]
+ column_ids_example = column_ids[i]
+
+ max_width = column_ids_example.max()
+ max_height = row_ids_example.max()
+
+ if max_width == 0 and max_height == 0:
+ continue
+
+ cell_coords_to_prob = self._get_mean_cell_probs(
+ probabilities_example,
+ segment_ids_example.tolist(),
+ row_ids_example.tolist(),
+ column_ids_example.tolist(),
+ )
+
+ # Select the answers above the classification threshold.
+ answer_coordinates = []
+ for col in range(max_width):
+ for row in range(max_height):
+ cell_prob = cell_coords_to_prob.get((col, row), None)
+ if cell_prob is not None:
+ if cell_prob > cell_classification_threshold:
+ answer_coordinates.append((row, col))
+ answer_coordinates = sorted(answer_coordinates)
+ predicted_answer_coordinates.append(answer_coordinates)
+
+ output = (predicted_answer_coordinates,)
+
+ if logits_agg is not None:
+ predicted_aggregation_indices = logits_agg.argmax(axis=-1)
+ output = (predicted_answer_coordinates, predicted_aggregation_indices.tolist())
+
+ return output
+
+ # End of everything related to converting logits to predictions
+
+
+# Copied from transformers.models.bert.tokenization_bert.BasicTokenizer
+class BasicTokenizer:
+ """
+ Constructs a BasicTokenizer that will run basic tokenization (punctuation splitting, lower casing, etc.).
+
+ Args:
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether or not to lowercase the input when tokenizing.
+ never_split (`Iterable`, *optional*):
+ Collection of tokens which will never be split during tokenization. Only has an effect when
+ `do_basic_tokenize=True`
+ tokenize_chinese_chars (`bool`, *optional*, defaults to `True`):
+ Whether or not to tokenize Chinese characters.
+
+ This should likely be deactivated for Japanese (see this
+ [issue](https://github.com/huggingface/transformers/issues/328)).
+ strip_accents (`bool`, *optional*):
+ Whether or not to strip all accents. If this option is not specified, then it will be determined by the
+ value for `lowercase` (as in the original BERT).
+ do_split_on_punc (`bool`, *optional*, defaults to `True`):
+ In some instances we want to skip the basic punctuation splitting so that later tokenization can capture
+ the full context of the words, such as contractions.
+ """
+
+ def __init__(
+ self,
+ do_lower_case=True,
+ never_split=None,
+ tokenize_chinese_chars=True,
+ strip_accents=None,
+ do_split_on_punc=True,
+ ):
+ if never_split is None:
+ never_split = []
+ self.do_lower_case = do_lower_case
+ self.never_split = set(never_split)
+ self.tokenize_chinese_chars = tokenize_chinese_chars
+ self.strip_accents = strip_accents
+ self.do_split_on_punc = do_split_on_punc
+
+ def tokenize(self, text, never_split=None):
+ """
+ Basic Tokenization of a piece of text. For sub-word tokenization, see WordPieceTokenizer.
+
+ Args:
+ never_split (`List[str]`, *optional*)
+ Kept for backward compatibility purposes. Now implemented directly at the base class level (see
+ [`PreTrainedTokenizer.tokenize`]) List of token not to split.
+ """
+ # union() returns a new set by concatenating the two sets.
+ never_split = self.never_split.union(set(never_split)) if never_split else self.never_split
+ text = self._clean_text(text)
+
+ # This was added on November 1st, 2018 for the multilingual and Chinese
+ # models. This is also applied to the English models now, but it doesn't
+ # matter since the English models were not trained on any Chinese data
+ # and generally don't have any Chinese data in them (there are Chinese
+ # characters in the vocabulary because Wikipedia does have some Chinese
+ # words in the English Wikipedia.).
+ if self.tokenize_chinese_chars:
+ text = self._tokenize_chinese_chars(text)
+ # prevents treating the same character with different unicode codepoints as different characters
+ unicode_normalized_text = unicodedata.normalize("NFC", text)
+ orig_tokens = whitespace_tokenize(unicode_normalized_text)
+ split_tokens = []
+ for token in orig_tokens:
+ if token not in never_split:
+ if self.do_lower_case:
+ token = token.lower()
+ if self.strip_accents is not False:
+ token = self._run_strip_accents(token)
+ elif self.strip_accents:
+ token = self._run_strip_accents(token)
+ split_tokens.extend(self._run_split_on_punc(token, never_split))
+
+ output_tokens = whitespace_tokenize(" ".join(split_tokens))
+ return output_tokens
+
+ def _run_strip_accents(self, text):
+ """Strips accents from a piece of text."""
+ text = unicodedata.normalize("NFD", text)
+ output = []
+ for char in text:
+ cat = unicodedata.category(char)
+ if cat == "Mn":
+ continue
+ output.append(char)
+ return "".join(output)
+
+ def _run_split_on_punc(self, text, never_split=None):
+ """Splits punctuation on a piece of text."""
+ if not self.do_split_on_punc or (never_split is not None and text in never_split):
+ return [text]
+ chars = list(text)
+ i = 0
+ start_new_word = True
+ output = []
+ while i < len(chars):
+ char = chars[i]
+ if _is_punctuation(char):
+ output.append([char])
+ start_new_word = True
+ else:
+ if start_new_word:
+ output.append([])
+ start_new_word = False
+ output[-1].append(char)
+ i += 1
+
+ return ["".join(x) for x in output]
+
+ def _tokenize_chinese_chars(self, text):
+ """Adds whitespace around any CJK character."""
+ output = []
+ for char in text:
+ cp = ord(char)
+ if self._is_chinese_char(cp):
+ output.append(" ")
+ output.append(char)
+ output.append(" ")
+ else:
+ output.append(char)
+ return "".join(output)
+
+ def _is_chinese_char(self, cp):
+ """Checks whether CP is the codepoint of a CJK character."""
+ # This defines a "chinese character" as anything in the CJK Unicode block:
+ # https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block)
+ #
+ # Note that the CJK Unicode block is NOT all Japanese and Korean characters,
+ # despite its name. The modern Korean Hangul alphabet is a different block,
+ # as is Japanese Hiragana and Katakana. Those alphabets are used to write
+ # space-separated words, so they are not treated specially and handled
+ # like the all of the other languages.
+ if (
+ (cp >= 0x4E00 and cp <= 0x9FFF)
+ or (cp >= 0x3400 and cp <= 0x4DBF)
+ or (cp >= 0x20000 and cp <= 0x2A6DF)
+ or (cp >= 0x2A700 and cp <= 0x2B73F)
+ or (cp >= 0x2B740 and cp <= 0x2B81F)
+ or (cp >= 0x2B820 and cp <= 0x2CEAF)
+ or (cp >= 0xF900 and cp <= 0xFAFF)
+ or (cp >= 0x2F800 and cp <= 0x2FA1F)
+ ):
+ return True
+
+ return False
+
+ def _clean_text(self, text):
+ """Performs invalid character removal and whitespace cleanup on text."""
+ output = []
+ for char in text:
+ cp = ord(char)
+ if cp == 0 or cp == 0xFFFD or _is_control(char):
+ continue
+ if _is_whitespace(char):
+ output.append(" ")
+ else:
+ output.append(char)
+ return "".join(output)
+
+
+# Copied from transformers.models.bert.tokenization_bert.WordpieceTokenizer
+class WordpieceTokenizer:
+ """Runs WordPiece tokenization."""
+
+ def __init__(self, vocab, unk_token, max_input_chars_per_word=100):
+ self.vocab = vocab
+ self.unk_token = unk_token
+ self.max_input_chars_per_word = max_input_chars_per_word
+
+ def tokenize(self, text):
+ """
+ Tokenizes a piece of text into its word pieces. This uses a greedy longest-match-first algorithm to perform
+ tokenization using the given vocabulary.
+
+ For example, `input = "unaffable"` will return as output `["un", "##aff", "##able"]`.
+
+ Args:
+ text: A single token or whitespace separated tokens. This should have
+ already been passed through *BasicTokenizer*.
+
+ Returns:
+ A list of wordpiece tokens.
+ """
+
+ output_tokens = []
+ for token in whitespace_tokenize(text):
+ chars = list(token)
+ if len(chars) > self.max_input_chars_per_word:
+ output_tokens.append(self.unk_token)
+ continue
+
+ is_bad = False
+ start = 0
+ sub_tokens = []
+ while start < len(chars):
+ end = len(chars)
+ cur_substr = None
+ while start < end:
+ substr = "".join(chars[start:end])
+ if start > 0:
+ substr = "##" + substr
+ if substr in self.vocab:
+ cur_substr = substr
+ break
+ end -= 1
+ if cur_substr is None:
+ is_bad = True
+ break
+ sub_tokens.append(cur_substr)
+ start = end
+
+ if is_bad:
+ output_tokens.append(self.unk_token)
+ else:
+ output_tokens.extend(sub_tokens)
+ return output_tokens
+
+
+# Below: utilities for TAPAS tokenizer (independent from PyTorch/Tensorflow).
+# This includes functions to parse numeric values (dates and numbers) from both the table and questions in order
+# to create the column_ranks, inv_column_ranks, numeric_values, numeric values_scale and numeric_relations in
+# prepare_for_model of TapasTokenizer.
+# These are meant to be used in an academic setup, for production use cases Gold mine or Aqua should be used.
+
+
+# taken from constants.py of the original implementation
+# URL: https://github.com/google-research/tapas/blob/master/tapas/utils/constants.py
+class Relation(enum.Enum):
+ HEADER_TO_CELL = 1 # Connects header to cell.
+ CELL_TO_HEADER = 2 # Connects cell to header.
+ QUERY_TO_HEADER = 3 # Connects query to headers.
+ QUERY_TO_CELL = 4 # Connects query to cells.
+ ROW_TO_CELL = 5 # Connects row to cells.
+ CELL_TO_ROW = 6 # Connects cells to row.
+ EQ = 7 # Annotation value is same as cell value
+ LT = 8 # Annotation value is less than cell value
+ GT = 9 # Annotation value is greater than cell value
+
+
+@dataclass
+class Date:
+ year: Optional[int] = None
+ month: Optional[int] = None
+ day: Optional[int] = None
+
+
+@dataclass
+class NumericValue:
+ float_value: Optional[float] = None
+ date: Optional[Date] = None
+
+
+@dataclass
+class NumericValueSpan:
+ begin_index: Optional[int] = None
+ end_index: Optional[int] = None
+ values: list[NumericValue] = None
+
+
+@dataclass
+class Cell:
+ text: str
+ numeric_value: Optional[NumericValue] = None
+
+
+@dataclass
+class Question:
+ original_text: str # The original raw question string.
+ text: str # The question string after normalization.
+ numeric_spans: Optional[list[NumericValueSpan]] = None
+
+
+# Below: all functions from number_utils.py as well as 2 functions (namely get_all_spans and normalize_for_match)
+# from text_utils.py of the original implementation. URL's:
+# - https://github.com/google-research/tapas/blob/master/tapas/utils/number_utils.py
+# - https://github.com/google-research/tapas/blob/master/tapas/utils/text_utils.py
+
+
+# Constants for parsing date expressions.
+# Masks that specify (by a bool) which of (year, month, day) will be populated.
+_DateMask = collections.namedtuple("_DateMask", ["year", "month", "day"])
+
+_YEAR = _DateMask(True, False, False)
+_YEAR_MONTH = _DateMask(True, True, False)
+_YEAR_MONTH_DAY = _DateMask(True, True, True)
+_MONTH = _DateMask(False, True, False)
+_MONTH_DAY = _DateMask(False, True, True)
+
+# Pairs of patterns to pass to 'datetime.strptime' and masks specifying which
+# fields will be set by the corresponding pattern.
+_DATE_PATTERNS = (
+ ("%B", _MONTH),
+ ("%Y", _YEAR),
+ ("%Ys", _YEAR),
+ ("%b %Y", _YEAR_MONTH),
+ ("%B %Y", _YEAR_MONTH),
+ ("%B %d", _MONTH_DAY),
+ ("%b %d", _MONTH_DAY),
+ ("%d %b", _MONTH_DAY),
+ ("%d %B", _MONTH_DAY),
+ ("%B %d, %Y", _YEAR_MONTH_DAY),
+ ("%d %B %Y", _YEAR_MONTH_DAY),
+ ("%m-%d-%Y", _YEAR_MONTH_DAY),
+ ("%Y-%m-%d", _YEAR_MONTH_DAY),
+ ("%Y-%m", _YEAR_MONTH),
+ ("%B %Y", _YEAR_MONTH),
+ ("%d %b %Y", _YEAR_MONTH_DAY),
+ ("%Y-%m-%d", _YEAR_MONTH_DAY),
+ ("%b %d, %Y", _YEAR_MONTH_DAY),
+ ("%d.%m.%Y", _YEAR_MONTH_DAY),
+ ("%A, %b %d", _MONTH_DAY),
+ ("%A, %B %d", _MONTH_DAY),
+)
+
+# This mapping is used to convert date patterns to regex patterns.
+_FIELD_TO_REGEX = (
+ ("%A", r"\w+"), # Weekday as locale’s full name.
+ ("%B", r"\w+"), # Month as locale’s full name.
+ ("%Y", r"\d{4}"), # Year with century as a decimal number.
+ ("%b", r"\w{3}"), # Month as locale’s abbreviated name.
+ ("%d", r"\d{1,2}"), # Day of the month as a zero-padded decimal number.
+ ("%m", r"\d{1,2}"), # Month as a zero-padded decimal number.
+)
+
+
+def _process_date_pattern(dp):
+ """Compute a regex for each date pattern to use as a prefilter."""
+ pattern, mask = dp
+ regex = pattern
+ regex = regex.replace(".", re.escape("."))
+ regex = regex.replace("-", re.escape("-"))
+ regex = regex.replace(" ", r"\s+")
+ for field, field_regex in _FIELD_TO_REGEX:
+ regex = regex.replace(field, field_regex)
+ # Make sure we didn't miss any of the fields.
+ assert "%" not in regex, regex
+ return pattern, mask, re.compile("^" + regex + "$")
+
+
+def _process_date_patterns():
+ return tuple(_process_date_pattern(dp) for dp in _DATE_PATTERNS)
+
+
+_PROCESSED_DATE_PATTERNS = _process_date_patterns()
+
+_MAX_DATE_NGRAM_SIZE = 5
+
+# Following DynSp:
+# https://github.com/Microsoft/DynSP/blob/master/util.py#L414.
+_NUMBER_WORDS = [
+ "zero",
+ "one",
+ "two",
+ "three",
+ "four",
+ "five",
+ "six",
+ "seven",
+ "eight",
+ "nine",
+ "ten",
+ "eleven",
+ "twelve",
+]
+
+_ORDINAL_WORDS = [
+ "zeroth",
+ "first",
+ "second",
+ "third",
+ "fourth",
+ "fifth",
+ "sixth",
+ "seventh",
+ "eighth",
+ "ninth",
+ "tenth",
+ "eleventh",
+ "twelfth",
+]
+
+_ORDINAL_SUFFIXES = ["st", "nd", "rd", "th"]
+
+_NUMBER_PATTERN = re.compile(r"((^|\s)[+-])?((\.\d+)|(\d+(,\d\d\d)*(\.\d*)?))")
+
+# Following DynSp:
+# https://github.com/Microsoft/DynSP/blob/master/util.py#L293.
+_MIN_YEAR = 1700
+_MAX_YEAR = 2016
+
+_INF = float("INF")
+
+
+def _get_numeric_value_from_date(date, mask):
+ """Converts date (datetime Python object) to a NumericValue object with a Date object value."""
+ if date.year < _MIN_YEAR or date.year > _MAX_YEAR:
+ raise ValueError(f"Invalid year: {date.year}")
+
+ new_date = Date()
+ if mask.year:
+ new_date.year = date.year
+ if mask.month:
+ new_date.month = date.month
+ if mask.day:
+ new_date.day = date.day
+ return NumericValue(date=new_date)
+
+
+def _get_span_length_key(span):
+ """Sorts span by decreasing length first and increasing first index second."""
+ return span[1] - span[0], -span[0]
+
+
+def _get_numeric_value_from_float(value):
+ """Converts float (Python) to a NumericValue object with a float value."""
+ return NumericValue(float_value=value)
+
+
+# Doesn't parse ordinal expressions such as '18th of february 1655'.
+def _parse_date(text):
+ """Attempts to format a text as a standard date string (yyyy-mm-dd)."""
+ text = re.sub(r"Sept\b", "Sep", text)
+ for in_pattern, mask, regex in _PROCESSED_DATE_PATTERNS:
+ if not regex.match(text):
+ continue
+ try:
+ date = datetime.datetime.strptime(text, in_pattern).date()
+ except ValueError:
+ continue
+ try:
+ return _get_numeric_value_from_date(date, mask)
+ except ValueError:
+ continue
+ return None
+
+
+def _parse_number(text):
+ """Parses simple cardinal and ordinals numbers."""
+ for suffix in _ORDINAL_SUFFIXES:
+ if text.endswith(suffix):
+ text = text[: -len(suffix)]
+ break
+ text = text.replace(",", "")
+ try:
+ value = float(text)
+ except ValueError:
+ return None
+ if math.isnan(value):
+ return None
+ if value == _INF:
+ return None
+ return value
+
+
+def get_all_spans(text, max_ngram_length):
+ """
+ Split a text into all possible ngrams up to 'max_ngram_length'. Split points are white space and punctuation.
+
+ Args:
+ text: Text to split.
+ max_ngram_length: maximal ngram length.
+ Yields:
+ Spans, tuples of begin-end index.
+ """
+ start_indexes = []
+ for index, char in enumerate(text):
+ if not char.isalnum():
+ continue
+ if index == 0 or not text[index - 1].isalnum():
+ start_indexes.append(index)
+ if index + 1 == len(text) or not text[index + 1].isalnum():
+ for start_index in start_indexes[-max_ngram_length:]:
+ yield start_index, index + 1
+
+
+def normalize_for_match(text):
+ return " ".join(text.lower().split())
+
+
+def format_text(text):
+ """Lowercases and strips punctuation."""
+ text = text.lower().strip()
+ if text == "n/a" or text == "?" or text == "nan":
+ text = EMPTY_TEXT
+
+ text = re.sub(r"[^\w\d]+", " ", text).replace("_", " ")
+ text = " ".join(text.split())
+ text = text.strip()
+ if text:
+ return text
+ return EMPTY_TEXT
+
+
+def parse_text(text):
+ """
+ Extracts longest number and date spans.
+
+ Args:
+ text: text to annotate
+
+ Returns:
+ List of longest numeric value spans.
+ """
+ span_dict = collections.defaultdict(list)
+ for match in _NUMBER_PATTERN.finditer(text):
+ span_text = text[match.start() : match.end()]
+ number = _parse_number(span_text)
+ if number is not None:
+ span_dict[match.span()].append(_get_numeric_value_from_float(number))
+
+ for begin_index, end_index in get_all_spans(text, max_ngram_length=1):
+ if (begin_index, end_index) in span_dict:
+ continue
+ span_text = text[begin_index:end_index]
+
+ number = _parse_number(span_text)
+ if number is not None:
+ span_dict[begin_index, end_index].append(_get_numeric_value_from_float(number))
+ for number, word in enumerate(_NUMBER_WORDS):
+ if span_text == word:
+ span_dict[begin_index, end_index].append(_get_numeric_value_from_float(float(number)))
+ break
+ for number, word in enumerate(_ORDINAL_WORDS):
+ if span_text == word:
+ span_dict[begin_index, end_index].append(_get_numeric_value_from_float(float(number)))
+ break
+
+ for begin_index, end_index in get_all_spans(text, max_ngram_length=_MAX_DATE_NGRAM_SIZE):
+ span_text = text[begin_index:end_index]
+ date = _parse_date(span_text)
+ if date is not None:
+ span_dict[begin_index, end_index].append(date)
+
+ spans = sorted(span_dict.items(), key=lambda span_value: _get_span_length_key(span_value[0]), reverse=True)
+ selected_spans = []
+ for span, value in spans:
+ for selected_span, _ in selected_spans:
+ if selected_span[0] <= span[0] and span[1] <= selected_span[1]:
+ break
+ else:
+ selected_spans.append((span, value))
+
+ selected_spans.sort(key=lambda span_value: span_value[0][0])
+
+ numeric_value_spans = []
+ for span, values in selected_spans:
+ numeric_value_spans.append(NumericValueSpan(begin_index=span[0], end_index=span[1], values=values))
+ return numeric_value_spans
+
+
+# Below: all functions from number_annotation_utils.py and 2 functions (namely filter_invalid_unicode
+# and filter_invalid_unicode_from_table) from text_utils.py of the original implementation. URL's:
+# - https://github.com/google-research/tapas/blob/master/tapas/utils/number_annotation_utils.py
+# - https://github.com/google-research/tapas/blob/master/tapas/utils/text_utils.py
+
+
+_PrimitiveNumericValue = Union[float, tuple[Optional[float], Optional[float], Optional[float]]]
+_SortKeyFn = Callable[[NumericValue], tuple[float, Ellipsis]]
+
+_DATE_TUPLE_SIZE = 3
+
+EMPTY_TEXT = "EMPTY"
+
+NUMBER_TYPE = "number"
+DATE_TYPE = "date"
+
+
+def _get_value_type(numeric_value):
+ if numeric_value.float_value is not None:
+ return NUMBER_TYPE
+ elif numeric_value.date is not None:
+ return DATE_TYPE
+ raise ValueError(f"Unknown type: {numeric_value}")
+
+
+def _get_value_as_primitive_value(numeric_value):
+ """Maps a NumericValue proto to a float or tuple of float."""
+ if numeric_value.float_value is not None:
+ return numeric_value.float_value
+ if numeric_value.date is not None:
+ date = numeric_value.date
+ value_tuple = [None, None, None]
+ # All dates fields are cased to float to produce a simple primitive value.
+ if date.year is not None:
+ value_tuple[0] = float(date.year)
+ if date.month is not None:
+ value_tuple[1] = float(date.month)
+ if date.day is not None:
+ value_tuple[2] = float(date.day)
+ return tuple(value_tuple)
+ raise ValueError(f"Unknown type: {numeric_value}")
+
+
+def _get_all_types(numeric_values):
+ return {_get_value_type(value) for value in numeric_values}
+
+
+def get_numeric_sort_key_fn(numeric_values):
+ """
+ Creates a function that can be used as a sort key or to compare the values. Maps to primitive types and finds the
+ biggest common subset. Consider the values "05/05/2010" and "August 2007". With the corresponding primitive values
+ (2010.,5.,5.) and (2007.,8., None). These values can be compared by year and date so we map to the sequence (2010.,
+ 5.), (2007., 8.). If we added a third value "2006" with primitive value (2006., None, None), we could only compare
+ by the year so we would map to (2010.,), (2007.,) and (2006.,).
+
+ Args:
+ numeric_values: Values to compare
+
+ Returns:
+ A function that can be used as a sort key function (mapping numeric values to a comparable tuple)
+
+ Raises:
+ ValueError if values don't have a common type or are not comparable.
+ """
+ value_types = _get_all_types(numeric_values)
+ if len(value_types) != 1:
+ raise ValueError(f"No common value type in {numeric_values}")
+
+ value_type = next(iter(value_types))
+ if value_type == NUMBER_TYPE:
+ # Primitive values are simple floats, nothing to do here.
+ return _get_value_as_primitive_value
+
+ # The type can only be Date at this point which means the primitive type
+ # is a float triple.
+ valid_indexes = set(range(_DATE_TUPLE_SIZE))
+
+ for numeric_value in numeric_values:
+ value = _get_value_as_primitive_value(numeric_value)
+ assert isinstance(value, tuple)
+ for tuple_index, inner_value in enumerate(value):
+ if inner_value is None:
+ valid_indexes.discard(tuple_index)
+
+ if not valid_indexes:
+ raise ValueError(f"No common value in {numeric_values}")
+
+ def _sort_key_fn(numeric_value):
+ value = _get_value_as_primitive_value(numeric_value)
+ return tuple(value[index] for index in valid_indexes)
+
+ return _sort_key_fn
+
+
+def _consolidate_numeric_values(row_index_to_values, min_consolidation_fraction, debug_info):
+ """
+ Finds the most common numeric values in a column and returns them
+
+ Args:
+ row_index_to_values:
+ For each row index all the values in that cell.
+ min_consolidation_fraction:
+ Fraction of cells that need to have consolidated value.
+ debug_info:
+ Additional information only used for logging
+
+ Returns:
+ For each row index the first value that matches the most common value. Rows that don't have a matching value
+ are dropped. Empty list if values can't be consolidated.
+ """
+ type_counts = collections.Counter()
+ for numeric_values in row_index_to_values.values():
+ type_counts.update(_get_all_types(numeric_values))
+ if not type_counts:
+ return {}
+ max_count = max(type_counts.values())
+ if max_count < len(row_index_to_values) * min_consolidation_fraction:
+ # logging.log_every_n(logging.INFO, f'Can\'t consolidate types: {debug_info} {row_index_to_values} {max_count}', 100)
+ return {}
+
+ valid_types = set()
+ for value_type, count in type_counts.items():
+ if count == max_count:
+ valid_types.add(value_type)
+ if len(valid_types) > 1:
+ assert DATE_TYPE in valid_types
+ max_type = DATE_TYPE
+ else:
+ max_type = next(iter(valid_types))
+
+ new_row_index_to_value = {}
+ for index, values in row_index_to_values.items():
+ # Extract the first matching value.
+ for value in values:
+ if _get_value_type(value) == max_type:
+ new_row_index_to_value[index] = value
+ break
+
+ return new_row_index_to_value
+
+
+def _get_numeric_values(text):
+ """Parses text and returns numeric values."""
+ numeric_spans = parse_text(text)
+ return itertools.chain(*(span.values for span in numeric_spans))
+
+
+def _get_column_values(table, col_index):
+ """
+ Parses text in column and returns a dict mapping row_index to values. This is the _get_column_values function from
+ number_annotation_utils.py of the original implementation
+
+ Args:
+ table: Pandas dataframe
+ col_index: integer, indicating the index of the column to get the numeric values of
+ """
+ index_to_values = {}
+ for row_index, row in table.iterrows():
+ text = normalize_for_match(row[col_index].text)
+ index_to_values[row_index] = list(_get_numeric_values(text))
+ return index_to_values
+
+
+def get_numeric_relation(value, other_value, sort_key_fn):
+ """Compares two values and returns their relation or None."""
+ value = sort_key_fn(value)
+ other_value = sort_key_fn(other_value)
+ if value == other_value:
+ return Relation.EQ
+ if value < other_value:
+ return Relation.LT
+ if value > other_value:
+ return Relation.GT
+ return None
+
+
+def add_numeric_values_to_question(question):
+ """Adds numeric value spans to a question."""
+ original_text = question
+ question = normalize_for_match(question)
+ numeric_spans = parse_text(question)
+ return Question(original_text=original_text, text=question, numeric_spans=numeric_spans)
+
+
+def filter_invalid_unicode(text):
+ """Return an empty string and True if 'text' is in invalid unicode."""
+ return ("", True) if isinstance(text, bytes) else (text, False)
+
+
+def filter_invalid_unicode_from_table(table):
+ """
+ Removes invalid unicode from table. Checks whether a table cell text contains an invalid unicode encoding. If yes,
+ reset the table cell text to an empty str and log a warning for each invalid cell
+
+ Args:
+ table: table to clean.
+ """
+ # to do: add table id support
+ if not hasattr(table, "table_id"):
+ table.table_id = 0
+
+ for row_index, row in table.iterrows():
+ for col_index, cell in enumerate(row):
+ cell, is_invalid = filter_invalid_unicode(cell)
+ if is_invalid:
+ logging.warning(
+ f"Scrub an invalid table body @ table_id: {table.table_id}, row_index: {row_index}, "
+ f"col_index: {col_index}",
+ )
+ for col_index, column in enumerate(table.columns):
+ column, is_invalid = filter_invalid_unicode(column)
+ if is_invalid:
+ logging.warning(f"Scrub an invalid table header @ table_id: {table.table_id}, col_index: {col_index}")
+
+
+def add_numeric_table_values(table, min_consolidation_fraction=0.7, debug_info=None):
+ """
+ Parses text in table column-wise and adds the consolidated values. Consolidation refers to finding values with a
+ common types (date or number)
+
+ Args:
+ table:
+ Table to annotate.
+ min_consolidation_fraction:
+ Fraction of cells in a column that need to have consolidated value.
+ debug_info:
+ Additional information used for logging.
+ """
+ table = table.copy()
+ # First, filter table on invalid unicode
+ filter_invalid_unicode_from_table(table)
+
+ # Second, replace cell values by Cell objects
+ for row_index, row in table.iterrows():
+ for col_index, cell in enumerate(row):
+ table.iloc[row_index, col_index] = Cell(text=cell)
+
+ # Third, add numeric_value attributes to these Cell objects
+ for col_index, column in enumerate(table.columns):
+ column_values = _consolidate_numeric_values(
+ _get_column_values(table, col_index),
+ min_consolidation_fraction=min_consolidation_fraction,
+ debug_info=(debug_info, column),
+ )
+
+ for row_index, numeric_value in column_values.items():
+ table.iloc[row_index, col_index].numeric_value = numeric_value
+
+ return table
+
+
+__all__ = ["TapasTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..0785102f9e209fa4d9f11ef82dd825daff5f7f25
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_textnet import *
+ from .image_processing_textnet import *
+ from .image_processing_textnet_fast import *
+ from .modeling_textnet import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/configuration_textnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/configuration_textnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..90f73f54164e1720deb7f9445f610f1eabdc3df9
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/configuration_textnet.py
@@ -0,0 +1,135 @@
+# coding=utf-8
+# Copyright 2024 the Fast authors and HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TextNet model configuration"""
+
+from transformers import PretrainedConfig
+from transformers.utils import logging
+from transformers.utils.backbone_utils import BackboneConfigMixin, get_aligned_output_features_output_indices
+
+
+logger = logging.get_logger(__name__)
+
+
+class TextNetConfig(BackboneConfigMixin, PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TextNextModel`]. It is used to instantiate a
+ TextNext model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the
+ [czczup/textnet-base](https://huggingface.co/czczup/textnet-base). Configuration objects inherit from
+ [`PretrainedConfig`] and can be used to control the model outputs.Read the documentation from [`PretrainedConfig`]
+ for more information.
+
+ Args:
+ stem_kernel_size (`int`, *optional*, defaults to 3):
+ The kernel size for the initial convolution layer.
+ stem_stride (`int`, *optional*, defaults to 2):
+ The stride for the initial convolution layer.
+ stem_num_channels (`int`, *optional*, defaults to 3):
+ The num of channels in input for the initial convolution layer.
+ stem_out_channels (`int`, *optional*, defaults to 64):
+ The num of channels in out for the initial convolution layer.
+ stem_act_func (`str`, *optional*, defaults to `"relu"`):
+ The activation function for the initial convolution layer.
+ image_size (`tuple[int, int]`, *optional*, defaults to `[640, 640]`):
+ The size (resolution) of each image.
+ conv_layer_kernel_sizes (`list[list[list[int]]]`, *optional*):
+ A list of stage-wise kernel sizes. If `None`, defaults to:
+ `[[[3, 3], [3, 3], [3, 3]], [[3, 3], [1, 3], [3, 3], [3, 1]], [[3, 3], [3, 3], [3, 1], [1, 3]], [[3, 3], [3, 1], [1, 3], [3, 3]]]`.
+ conv_layer_strides (`list[list[int]]`, *optional*):
+ A list of stage-wise strides. If `None`, defaults to:
+ `[[1, 2, 1], [2, 1, 1, 1], [2, 1, 1, 1], [2, 1, 1, 1]]`.
+ hidden_sizes (`list[int]`, *optional*, defaults to `[64, 64, 128, 256, 512]`):
+ Dimensionality (hidden size) at each stage.
+ batch_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the batch normalization layers.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ out_features (`list[str]`, *optional*):
+ If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc.
+ (depending on how many stages the model has). If unset and `out_indices` is set, will default to the
+ corresponding stages. If unset and `out_indices` is unset, will default to the last stage.
+ out_indices (`list[int]`, *optional*):
+ If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how
+ many stages the model has). If unset and `out_features` is set, will default to the corresponding stages.
+ If unset and `out_features` is unset, will default to the last stage.
+
+ Examples:
+
+ ```python
+ >>> from transformers import TextNetConfig, TextNetBackbone
+
+ >>> # Initializing a TextNetConfig
+ >>> configuration = TextNetConfig()
+
+ >>> # Initializing a model (with random weights)
+ >>> model = TextNetBackbone(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "textnet"
+
+ def __init__(
+ self,
+ stem_kernel_size=3,
+ stem_stride=2,
+ stem_num_channels=3,
+ stem_out_channels=64,
+ stem_act_func="relu",
+ image_size=[640, 640],
+ conv_layer_kernel_sizes=None,
+ conv_layer_strides=None,
+ hidden_sizes=[64, 64, 128, 256, 512],
+ batch_norm_eps=1e-5,
+ initializer_range=0.02,
+ out_features=None,
+ out_indices=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ if conv_layer_kernel_sizes is None:
+ conv_layer_kernel_sizes = [
+ [[3, 3], [3, 3], [3, 3]],
+ [[3, 3], [1, 3], [3, 3], [3, 1]],
+ [[3, 3], [3, 3], [3, 1], [1, 3]],
+ [[3, 3], [3, 1], [1, 3], [3, 3]],
+ ]
+ if conv_layer_strides is None:
+ conv_layer_strides = [[1, 2, 1], [2, 1, 1, 1], [2, 1, 1, 1], [2, 1, 1, 1]]
+
+ self.stem_kernel_size = stem_kernel_size
+ self.stem_stride = stem_stride
+ self.stem_num_channels = stem_num_channels
+ self.stem_out_channels = stem_out_channels
+ self.stem_act_func = stem_act_func
+
+ self.image_size = image_size
+ self.conv_layer_kernel_sizes = conv_layer_kernel_sizes
+ self.conv_layer_strides = conv_layer_strides
+
+ self.initializer_range = initializer_range
+ self.hidden_sizes = hidden_sizes
+ self.batch_norm_eps = batch_norm_eps
+
+ self.depths = [len(layer) for layer in self.conv_layer_kernel_sizes]
+ self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, 5)]
+ self._out_features, self._out_indices = get_aligned_output_features_output_indices(
+ out_features=out_features, out_indices=out_indices, stage_names=self.stage_names
+ )
+
+
+__all__ = ["TextNetConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/image_processing_textnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/image_processing_textnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..f274c6a6a7464a14b08fe0c3daa6aee96920805d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/image_processing_textnet.py
@@ -0,0 +1,355 @@
+# coding=utf-8
+# Copyright 2024 the Fast authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for TextNet."""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import (
+ convert_to_rgb,
+ get_resize_output_image_size,
+ resize,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ IMAGENET_DEFAULT_MEAN,
+ IMAGENET_DEFAULT_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_kwargs,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, is_vision_available, logging
+
+
+logger = logging.get_logger(__name__)
+
+if is_vision_available():
+ import PIL
+
+
+class TextNetImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a TextNet image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by
+ `do_resize` in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"shortest_edge": 640}`):
+ Size of the image after resizing. The shortest edge of the image is resized to size["shortest_edge"], with
+ the longest edge resized to keep the input aspect ratio. Can be overridden by `size` in the `preprocess`
+ method.
+ size_divisor (`int`, *optional*, defaults to 32):
+ Ensures height and width are rounded to a multiple of this value after resizing.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method.
+ do_center_crop (`bool`, *optional*, defaults to `False`):
+ Whether to center crop the image to the specified `crop_size`. Can be overridden by `do_center_crop` in the
+ `preprocess` method.
+ crop_size (`dict[str, int]` *optional*, defaults to 224):
+ Size of the output image after applying `center_crop`. Can be overridden by `crop_size` in the `preprocess`
+ method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in
+ the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess`
+ method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by `do_normalize` in the `preprocess` method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `[0.485, 0.456, 0.406]`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `[0.229, 0.224, 0.225]`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_convert_rgb (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to RGB.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ size_divisor: int = 32,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_center_crop: bool = False,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = IMAGENET_DEFAULT_MEAN,
+ image_std: Optional[Union[float, list[float]]] = IMAGENET_DEFAULT_STD,
+ do_convert_rgb: bool = True,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"shortest_edge": 640}
+ size = get_size_dict(size, default_to_square=False)
+ crop_size = crop_size if crop_size is not None else {"height": 224, "width": 224}
+ crop_size = get_size_dict(crop_size, param_name="crop_size")
+
+ self.do_resize = do_resize
+ self.size = size
+ self.size_divisor = size_divisor
+ self.resample = resample
+ self.do_center_crop = do_center_crop
+ self.crop_size = crop_size
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD
+ self.do_convert_rgb = do_convert_rgb
+
+ self._valid_processor_keys = [
+ "images",
+ "do_resize",
+ "size",
+ "size_divisor",
+ "resample",
+ "do_center_crop",
+ "crop_size",
+ "do_rescale",
+ "rescale_factor",
+ "do_normalize",
+ "image_mean",
+ "image_std",
+ "do_convert_rgb",
+ "return_tensors",
+ "data_format",
+ "input_data_format",
+ ]
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image. The shortest edge of the image is resized to size["shortest_edge"] , with the longest edge
+ resized to keep the input aspect ratio. Both the height and width are resized to be divisible by 32.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Size of the output image.
+ size_divisor (`int`, *optional*, defaults to `32`):
+ Ensures height and width are rounded to a multiple of this value after resizing.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ Resampling filter to use when resiizing the image.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ default_to_square (`bool`, *optional*, defaults to `False`):
+ The value to be passed to `get_size_dict` as `default_to_square` when computing the image size. If the
+ `size` argument in `get_size_dict` is an `int`, it determines whether to default to a square image or
+ not.Note that this attribute is not used in computing `crop_size` via calling `get_size_dict`.
+ """
+ if "shortest_edge" in size:
+ size = size["shortest_edge"]
+ elif "height" in size and "width" in size:
+ size = (size["height"], size["width"])
+ else:
+ raise ValueError("Size must contain either 'shortest_edge' or 'height' and 'width'.")
+
+ height, width = get_resize_output_image_size(
+ image, size=size, input_data_format=input_data_format, default_to_square=False
+ )
+ if height % self.size_divisor != 0:
+ height += self.size_divisor - (height % self.size_divisor)
+ if width % self.size_divisor != 0:
+ width += self.size_divisor - (width % self.size_divisor)
+
+ return resize(
+ image,
+ size=(height, width),
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ size_divisor: Optional[int] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[int] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Optional[ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after resizing. Shortest edge of the image is resized to size["shortest_edge"], with
+ the longest edge resized to keep the input aspect ratio.
+ size_divisor (`int`, *optional*, defaults to `32`):
+ Ensures height and width are rounded to a multiple of this value after resizing.
+ resample (`int`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only
+ has an effect if `do_resize` is set to `True`.
+ do_center_crop (`bool`, *optional*, defaults to `self.do_center_crop`):
+ Whether to center crop the image.
+ crop_size (`dict[str, int]`, *optional*, defaults to `self.crop_size`):
+ Size of the center crop. Only has an effect if `do_center_crop` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image.
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to
+ `True`.
+ do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`):
+ Whether to convert the image to RGB.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ size = size if size is not None else self.size
+ size = get_size_dict(size, param_name="size", default_to_square=False)
+ size_divisor = size_divisor if size_divisor is not None else self.size_divisor
+ resample = resample if resample is not None else self.resample
+ do_center_crop = do_center_crop if do_center_crop is not None else self.do_center_crop
+ crop_size = crop_size if crop_size is not None else self.crop_size
+ crop_size = get_size_dict(crop_size, param_name="crop_size", default_to_square=True)
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb
+
+ validate_kwargs(captured_kwargs=kwargs.keys(), valid_processor_keys=self._valid_processor_keys)
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ if do_convert_rgb:
+ images = [convert_to_rgb(image) for image in images]
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if is_scaled_image(images[0]) and do_rescale:
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ all_images = []
+ for image in images:
+ if do_resize:
+ image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+
+ if do_center_crop:
+ image = self.center_crop(image=image, size=crop_size, input_data_format=input_data_format)
+
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+
+ if do_normalize:
+ image = self.normalize(
+ image=image, mean=image_mean, std=image_std, input_data_format=input_data_format
+ )
+
+ all_images.append(image)
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+ for image in all_images
+ ]
+
+ data = {"pixel_values": images}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["TextNetImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/image_processing_textnet_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/image_processing_textnet_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..f6a163c4268738d694f75a4595a28e65b7f680f5
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/image_processing_textnet_fast.py
@@ -0,0 +1,163 @@
+# coding=utf-8
+# Copyright 2025 the Fast authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for TextNet."""
+
+from typing import Optional, Union
+
+from ...image_processing_utils import BatchFeature
+from ...image_processing_utils_fast import BaseImageProcessorFast, DefaultFastImageProcessorKwargs
+from ...image_transforms import (
+ get_resize_output_image_size,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import (
+ IMAGENET_DEFAULT_MEAN,
+ IMAGENET_DEFAULT_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ SizeDict,
+)
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+)
+
+
+if is_torch_available():
+ import torch
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+
+class TextNetFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ """
+ size_divisor (`int`, *optional*, defaults to 32):
+ Ensures height and width are rounded to a multiple of this value after resizing.
+ """
+
+ size_divisor: Optional[int]
+
+
+@auto_docstring
+class TextNetImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BILINEAR
+ image_mean = IMAGENET_DEFAULT_MEAN
+ image_std = IMAGENET_DEFAULT_STD
+ size = {"shortest_edge": 640}
+ default_to_square = False
+ crop_size = {"height": 224, "width": 224}
+ do_resize = True
+ do_center_crop = False
+ do_rescale = True
+ do_normalize = True
+ do_convert_rgb = True
+ size_divisor = 32
+ valid_kwargs = TextNetFastImageProcessorKwargs
+
+ def __init__(self, **kwargs: Unpack[TextNetFastImageProcessorKwargs]) -> None:
+ super().__init__(**kwargs)
+
+ @auto_docstring
+ def preprocess(self, images: ImageInput, **kwargs: Unpack[TextNetFastImageProcessorKwargs]) -> BatchFeature:
+ return super().preprocess(images, **kwargs)
+
+ def resize(
+ self,
+ image: "torch.Tensor",
+ size: SizeDict,
+ interpolation: "F.InterpolationMode" = None,
+ antialias: bool = True,
+ size_divisor: int = 32,
+ **kwargs,
+ ) -> "torch.Tensor":
+ if size.shortest_edge:
+ new_size = get_resize_output_image_size(
+ image,
+ size=size.shortest_edge,
+ default_to_square=False,
+ input_data_format=ChannelDimension.FIRST,
+ )
+ else:
+ raise ValueError(f"Size must contain 'shortest_edge' key. Got {size}.")
+ # ensure height and width are divisible by size_divisor
+ height, width = new_size
+ if height % size_divisor != 0:
+ height += size_divisor - (height % size_divisor)
+ if width % size_divisor != 0:
+ width += size_divisor - (width % size_divisor)
+
+ return super().resize(
+ image, SizeDict(height=height, width=width), interpolation=interpolation, antialias=antialias
+ )
+
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ do_resize: bool,
+ size: SizeDict,
+ size_divisor: int,
+ interpolation: Optional["F.InterpolationMode"],
+ do_center_crop: bool,
+ crop_size: SizeDict,
+ do_rescale: bool,
+ rescale_factor: float,
+ do_normalize: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ disable_grouping: Optional[bool],
+ return_tensors: Optional[Union[str, TensorType]],
+ **kwargs,
+ ) -> BatchFeature:
+ # Group images by size for batched resizing
+ grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping)
+ resized_images_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ if do_resize:
+ stacked_images = self.resize(
+ image=stacked_images, size=size, interpolation=interpolation, size_divisor=size_divisor
+ )
+ resized_images_grouped[shape] = stacked_images
+ resized_images = reorder_images(resized_images_grouped, grouped_images_index)
+
+ # Group images by size for further processing
+ # Needed in case do_resize is False, or resize returns images with different sizes
+ grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping)
+ processed_images_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ if do_center_crop:
+ stacked_images = self.center_crop(stacked_images, crop_size)
+ # Fused rescale and normalize
+ stacked_images = self.rescale_and_normalize(
+ stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std
+ )
+ processed_images_grouped[shape] = stacked_images
+
+ processed_images = reorder_images(processed_images_grouped, grouped_images_index)
+ processed_images = torch.stack(processed_images, dim=0) if return_tensors else processed_images
+
+ return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors)
+
+
+__all__ = ["TextNetImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/modeling_textnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/modeling_textnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..aa66587ea2dc14b0afc3d7092ffeba183447a301
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/textnet/modeling_textnet.py
@@ -0,0 +1,434 @@
+# coding=utf-8
+# Copyright 2024 the Fast authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch TextNet model."""
+
+from typing import Any, Optional, Union
+
+import torch
+import torch.nn as nn
+from torch import Tensor
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from transformers import PreTrainedModel
+from transformers.activations import ACT2CLS
+from transformers.modeling_outputs import (
+ BackboneOutput,
+ BaseModelOutputWithNoAttention,
+ BaseModelOutputWithPoolingAndNoAttention,
+ ImageClassifierOutputWithNoAttention,
+)
+from transformers.models.textnet.configuration_textnet import TextNetConfig
+from transformers.utils import logging
+from transformers.utils.backbone_utils import BackboneMixin
+
+from ...utils import auto_docstring
+
+
+logger = logging.get_logger(__name__)
+
+
+class TextNetConvLayer(nn.Module):
+ def __init__(self, config: TextNetConfig):
+ super().__init__()
+
+ self.kernel_size = config.stem_kernel_size
+ self.stride = config.stem_stride
+ self.activation_function = config.stem_act_func
+
+ padding = (
+ (config.kernel_size[0] // 2, config.kernel_size[1] // 2)
+ if isinstance(config.stem_kernel_size, tuple)
+ else config.stem_kernel_size // 2
+ )
+
+ self.conv = nn.Conv2d(
+ config.stem_num_channels,
+ config.stem_out_channels,
+ kernel_size=config.stem_kernel_size,
+ stride=config.stem_stride,
+ padding=padding,
+ bias=False,
+ )
+ self.batch_norm = nn.BatchNorm2d(config.stem_out_channels, config.batch_norm_eps)
+
+ self.activation = nn.Identity()
+ if self.activation_function is not None:
+ self.activation = ACT2CLS[self.activation_function]()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.batch_norm(hidden_states)
+ return self.activation(hidden_states)
+
+
+class TextNetRepConvLayer(nn.Module):
+ r"""
+ This layer supports re-parameterization by combining multiple convolutional branches
+ (e.g., main convolution, vertical, horizontal, and identity branches) during training.
+ At inference time, these branches can be collapsed into a single convolution for
+ efficiency, as per the re-parameterization paradigm.
+
+ The "Rep" in the name stands for "re-parameterization" (introduced by RepVGG).
+ """
+
+ def __init__(self, config: TextNetConfig, in_channels: int, out_channels: int, kernel_size: int, stride: int):
+ super().__init__()
+
+ self.num_channels = in_channels
+ self.out_channels = out_channels
+ self.kernel_size = kernel_size
+ self.stride = stride
+
+ padding = ((kernel_size[0] - 1) // 2, (kernel_size[1] - 1) // 2)
+
+ self.activation_function = nn.ReLU()
+
+ self.main_conv = nn.Conv2d(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=kernel_size,
+ stride=stride,
+ padding=padding,
+ bias=False,
+ )
+ self.main_batch_norm = nn.BatchNorm2d(num_features=out_channels, eps=config.batch_norm_eps)
+
+ vertical_padding = ((kernel_size[0] - 1) // 2, 0)
+ horizontal_padding = (0, (kernel_size[1] - 1) // 2)
+
+ if kernel_size[1] != 1:
+ self.vertical_conv = nn.Conv2d(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=(kernel_size[0], 1),
+ stride=stride,
+ padding=vertical_padding,
+ bias=False,
+ )
+ self.vertical_batch_norm = nn.BatchNorm2d(num_features=out_channels, eps=config.batch_norm_eps)
+ else:
+ self.vertical_conv, self.vertical_batch_norm = None, None
+
+ if kernel_size[0] != 1:
+ self.horizontal_conv = nn.Conv2d(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=(1, kernel_size[1]),
+ stride=stride,
+ padding=horizontal_padding,
+ bias=False,
+ )
+ self.horizontal_batch_norm = nn.BatchNorm2d(num_features=out_channels, eps=config.batch_norm_eps)
+ else:
+ self.horizontal_conv, self.horizontal_batch_norm = None, None
+
+ self.rbr_identity = (
+ nn.BatchNorm2d(num_features=in_channels, eps=config.batch_norm_eps)
+ if out_channels == in_channels and stride == 1
+ else None
+ )
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ main_outputs = self.main_conv(hidden_states)
+ main_outputs = self.main_batch_norm(main_outputs)
+
+ # applies a convolution with a vertical kernel
+ if self.vertical_conv is not None:
+ vertical_outputs = self.vertical_conv(hidden_states)
+ vertical_outputs = self.vertical_batch_norm(vertical_outputs)
+ main_outputs = main_outputs + vertical_outputs
+
+ # applies a convolution with a horizontal kernel
+ if self.horizontal_conv is not None:
+ horizontal_outputs = self.horizontal_conv(hidden_states)
+ horizontal_outputs = self.horizontal_batch_norm(horizontal_outputs)
+ main_outputs = main_outputs + horizontal_outputs
+
+ if self.rbr_identity is not None:
+ id_out = self.rbr_identity(hidden_states)
+ main_outputs = main_outputs + id_out
+
+ return self.activation_function(main_outputs)
+
+
+class TextNetStage(nn.Module):
+ def __init__(self, config: TextNetConfig, depth: int):
+ super().__init__()
+ kernel_size = config.conv_layer_kernel_sizes[depth]
+ stride = config.conv_layer_strides[depth]
+
+ num_layers = len(kernel_size)
+ stage_in_channel_size = config.hidden_sizes[depth]
+ stage_out_channel_size = config.hidden_sizes[depth + 1]
+
+ in_channels = [stage_in_channel_size] + [stage_out_channel_size] * (num_layers - 1)
+ out_channels = [stage_out_channel_size] * num_layers
+
+ stage = []
+ for stage_config in zip(in_channels, out_channels, kernel_size, stride):
+ stage.append(TextNetRepConvLayer(config, *stage_config))
+ self.stage = nn.ModuleList(stage)
+
+ def forward(self, hidden_state):
+ for block in self.stage:
+ hidden_state = block(hidden_state)
+ return hidden_state
+
+
+class TextNetEncoder(nn.Module):
+ def __init__(self, config: TextNetConfig):
+ super().__init__()
+
+ stages = []
+ num_stages = len(config.conv_layer_kernel_sizes)
+ for stage_ix in range(num_stages):
+ stages.append(TextNetStage(config, stage_ix))
+
+ self.stages = nn.ModuleList(stages)
+
+ def forward(
+ self,
+ hidden_state: torch.Tensor,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> BaseModelOutputWithNoAttention:
+ hidden_states = [hidden_state]
+ for stage in self.stages:
+ hidden_state = stage(hidden_state)
+ hidden_states.append(hidden_state)
+
+ if not return_dict:
+ output = (hidden_state,)
+ return output + (hidden_states,) if output_hidden_states else output
+
+ return BaseModelOutputWithNoAttention(last_hidden_state=hidden_state, hidden_states=hidden_states)
+
+
+@auto_docstring
+class TextNetPreTrainedModel(PreTrainedModel):
+ config: TextNetConfig
+ base_model_prefix = "textnet"
+ main_input_name = "pixel_values"
+
+ def _init_weights(self, module):
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.BatchNorm2d):
+ module.weight.data.fill_(1.0)
+ if module.bias is not None:
+ module.bias.data.zero_()
+
+
+@auto_docstring
+class TextNetModel(TextNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.stem = TextNetConvLayer(config)
+ self.encoder = TextNetEncoder(config)
+ self.pooler = nn.AdaptiveAvgPool2d((2, 2))
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self, pixel_values: Tensor, output_hidden_states: Optional[bool] = None, return_dict: Optional[bool] = None
+ ) -> Union[tuple[Any, list[Any]], tuple[Any], BaseModelOutputWithPoolingAndNoAttention]:
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ hidden_state = self.stem(pixel_values)
+
+ encoder_outputs = self.encoder(
+ hidden_state, output_hidden_states=output_hidden_states, return_dict=return_dict
+ )
+
+ last_hidden_state = encoder_outputs[0]
+ pooled_output = self.pooler(last_hidden_state)
+
+ if not return_dict:
+ output = (last_hidden_state, pooled_output)
+ return output + (encoder_outputs[1],) if output_hidden_states else output
+
+ return BaseModelOutputWithPoolingAndNoAttention(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs[1] if output_hidden_states else None,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ TextNet Model with an image classification head on top (a linear layer on top of the pooled features), e.g. for
+ ImageNet.
+ """
+)
+class TextNetForImageClassification(TextNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.textnet = TextNetModel(config)
+ self.avg_pool = nn.AdaptiveAvgPool2d((1, 1))
+ self.flatten = nn.Flatten()
+ self.fc = nn.Linear(config.hidden_sizes[-1], config.num_labels) if config.num_labels > 0 else nn.Identity()
+
+ # classification head
+ self.classifier = nn.ModuleList([self.avg_pool, self.flatten])
+
+ # initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> ImageClassifierOutputWithNoAttention:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+ ```python
+ >>> import torch
+ >>> import requests
+ >>> from transformers import TextNetForImageClassification, TextNetImageProcessor
+ >>> from PIL import Image
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> processor = TextNetImageProcessor.from_pretrained("czczup/textnet-base")
+ >>> model = TextNetForImageClassification.from_pretrained("czczup/textnet-base")
+
+ >>> inputs = processor(images=image, return_tensors="pt")
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+ >>> outputs.logits.shape
+ torch.Size([1, 2])
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.textnet(pixel_values, output_hidden_states=output_hidden_states, return_dict=return_dict)
+ last_hidden_state = outputs[0]
+ for layer in self.classifier:
+ last_hidden_state = layer(last_hidden_state)
+ logits = self.fc(last_hidden_state)
+ loss = None
+
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return (loss,) + output if loss is not None else output
+
+ return ImageClassifierOutputWithNoAttention(loss=loss, logits=logits, hidden_states=outputs.hidden_states)
+
+
+@auto_docstring(
+ custom_intro="""
+ TextNet backbone, to be used with frameworks like DETR and MaskFormer.
+ """
+)
+class TextNetBackbone(TextNetPreTrainedModel, BackboneMixin):
+ has_attentions = False
+
+ def __init__(self, config):
+ super().__init__(config)
+ super()._init_backbone(config)
+
+ self.textnet = TextNetModel(config)
+ self.num_features = config.hidden_sizes
+
+ # initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self, pixel_values: Tensor, output_hidden_states: Optional[bool] = None, return_dict: Optional[bool] = None
+ ) -> Union[tuple[tuple], BackboneOutput]:
+ r"""
+ Examples:
+
+ ```python
+ >>> import torch
+ >>> import requests
+ >>> from PIL import Image
+ >>> from transformers import AutoImageProcessor, AutoBackbone
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> processor = AutoImageProcessor.from_pretrained("czczup/textnet-base")
+ >>> model = AutoBackbone.from_pretrained("czczup/textnet-base")
+
+ >>> inputs = processor(image, return_tensors="pt")
+ >>> with torch.no_grad():
+ >>> outputs = model(**inputs)
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ outputs = self.textnet(pixel_values, output_hidden_states=True, return_dict=return_dict)
+
+ hidden_states = outputs.hidden_states if return_dict else outputs[2]
+
+ feature_maps = ()
+ for idx, stage in enumerate(self.stage_names):
+ if stage in self.out_features:
+ feature_maps += (hidden_states[idx],)
+
+ if not return_dict:
+ output = (feature_maps,)
+ if output_hidden_states:
+ hidden_states = outputs.hidden_states if return_dict else outputs[2]
+ output += (hidden_states,)
+ return output
+
+ return BackboneOutput(
+ feature_maps=feature_maps,
+ hidden_states=outputs.hidden_states if output_hidden_states else None,
+ attentions=None,
+ )
+
+
+__all__ = ["TextNetBackbone", "TextNetModel", "TextNetPreTrainedModel", "TextNetForImageClassification"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e36c36bcfccb32d5299b30ab6c48283f93e35e7a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_time_series_transformer import *
+ from .modeling_time_series_transformer import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/configuration_time_series_transformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/configuration_time_series_transformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..a42e95ccc5db3fff5e4d90204cff6c855c0c5b56
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/configuration_time_series_transformer.py
@@ -0,0 +1,229 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Time Series Transformer model configuration"""
+
+from typing import Optional, Union
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class TimeSeriesTransformerConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TimeSeriesTransformerModel`]. It is used to
+ instantiate a Time Series Transformer model according to the specified arguments, defining the model architecture.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the Time Series
+ Transformer
+ [huggingface/time-series-transformer-tourism-monthly](https://huggingface.co/huggingface/time-series-transformer-tourism-monthly)
+ architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ prediction_length (`int`):
+ The prediction length for the decoder. In other words, the prediction horizon of the model. This value is
+ typically dictated by the dataset and we recommend to set it appropriately.
+ context_length (`int`, *optional*, defaults to `prediction_length`):
+ The context length for the encoder. If `None`, the context length will be the same as the
+ `prediction_length`.
+ distribution_output (`string`, *optional*, defaults to `"student_t"`):
+ The distribution emission head for the model. Could be either "student_t", "normal" or "negative_binomial".
+ loss (`string`, *optional*, defaults to `"nll"`):
+ The loss function for the model corresponding to the `distribution_output` head. For parametric
+ distributions it is the negative log likelihood (nll) - which currently is the only supported one.
+ input_size (`int`, *optional*, defaults to 1):
+ The size of the target variable which by default is 1 for univariate targets. Would be > 1 in case of
+ multivariate targets.
+ scaling (`string` or `bool`, *optional* defaults to `"mean"`):
+ Whether to scale the input targets via "mean" scaler, "std" scaler or no scaler if `None`. If `True`, the
+ scaler is set to "mean".
+ lags_sequence (`list[int]`, *optional*, defaults to `[1, 2, 3, 4, 5, 6, 7]`):
+ The lags of the input time series as covariates often dictated by the frequency of the data. Default is
+ `[1, 2, 3, 4, 5, 6, 7]` but we recommend to change it based on the dataset appropriately.
+ num_time_features (`int`, *optional*, defaults to 0):
+ The number of time features in the input time series.
+ num_dynamic_real_features (`int`, *optional*, defaults to 0):
+ The number of dynamic real valued features.
+ num_static_categorical_features (`int`, *optional*, defaults to 0):
+ The number of static categorical features.
+ num_static_real_features (`int`, *optional*, defaults to 0):
+ The number of static real valued features.
+ cardinality (`list[int]`, *optional*):
+ The cardinality (number of different values) for each of the static categorical features. Should be a list
+ of integers, having the same length as `num_static_categorical_features`. Cannot be `None` if
+ `num_static_categorical_features` is > 0.
+ embedding_dimension (`list[int]`, *optional*):
+ The dimension of the embedding for each of the static categorical features. Should be a list of integers,
+ having the same length as `num_static_categorical_features`. Cannot be `None` if
+ `num_static_categorical_features` is > 0.
+ d_model (`int`, *optional*, defaults to 64):
+ Dimensionality of the transformer layers.
+ encoder_layers (`int`, *optional*, defaults to 2):
+ Number of encoder layers.
+ decoder_layers (`int`, *optional*, defaults to 2):
+ Number of decoder layers.
+ encoder_attention_heads (`int`, *optional*, defaults to 2):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ decoder_attention_heads (`int`, *optional*, defaults to 2):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ encoder_ffn_dim (`int`, *optional*, defaults to 32):
+ Dimension of the "intermediate" (often named feed-forward) layer in encoder.
+ decoder_ffn_dim (`int`, *optional*, defaults to 32):
+ Dimension of the "intermediate" (often named feed-forward) layer in decoder.
+ activation_function (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and decoder. If string, `"gelu"` and
+ `"relu"` are supported.
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the encoder, and decoder.
+ encoder_layerdrop (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the attention and fully connected layers for each encoder layer.
+ decoder_layerdrop (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the attention and fully connected layers for each decoder layer.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability used between the two layers of the feed-forward networks.
+ num_parallel_samples (`int`, *optional*, defaults to 100):
+ The number of samples to generate in parallel for each time step of inference.
+ init_std (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated normal weight initialization distribution.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether to use the past key/values attentions (if applicable to the model) to speed up decoding.
+
+ Example:
+
+ ```python
+ >>> from transformers import TimeSeriesTransformerConfig, TimeSeriesTransformerModel
+
+ >>> # Initializing a Time Series Transformer configuration with 12 time steps for prediction
+ >>> configuration = TimeSeriesTransformerConfig(prediction_length=12)
+
+ >>> # Randomly initializing a model (with random weights) from the configuration
+ >>> model = TimeSeriesTransformerModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "time_series_transformer"
+ attribute_map = {
+ "hidden_size": "d_model",
+ "num_attention_heads": "encoder_attention_heads",
+ "num_hidden_layers": "encoder_layers",
+ }
+
+ def __init__(
+ self,
+ prediction_length: Optional[int] = None,
+ context_length: Optional[int] = None,
+ distribution_output: str = "student_t",
+ loss: str = "nll",
+ input_size: int = 1,
+ lags_sequence: list[int] = [1, 2, 3, 4, 5, 6, 7],
+ scaling: Optional[Union[str, bool]] = "mean",
+ num_dynamic_real_features: int = 0,
+ num_static_categorical_features: int = 0,
+ num_static_real_features: int = 0,
+ num_time_features: int = 0,
+ cardinality: Optional[list[int]] = None,
+ embedding_dimension: Optional[list[int]] = None,
+ encoder_ffn_dim: int = 32,
+ decoder_ffn_dim: int = 32,
+ encoder_attention_heads: int = 2,
+ decoder_attention_heads: int = 2,
+ encoder_layers: int = 2,
+ decoder_layers: int = 2,
+ is_encoder_decoder: bool = True,
+ activation_function: str = "gelu",
+ d_model: int = 64,
+ dropout: float = 0.1,
+ encoder_layerdrop: float = 0.1,
+ decoder_layerdrop: float = 0.1,
+ attention_dropout: float = 0.1,
+ activation_dropout: float = 0.1,
+ num_parallel_samples: int = 100,
+ init_std: float = 0.02,
+ use_cache=True,
+ **kwargs,
+ ):
+ # time series specific configuration
+ self.prediction_length = prediction_length
+ self.context_length = context_length or prediction_length
+ self.distribution_output = distribution_output
+ self.loss = loss
+ self.input_size = input_size
+ self.num_time_features = num_time_features
+ self.lags_sequence = lags_sequence
+ self.scaling = scaling
+ self.num_dynamic_real_features = num_dynamic_real_features
+ self.num_static_real_features = num_static_real_features
+ self.num_static_categorical_features = num_static_categorical_features
+ if cardinality and num_static_categorical_features > 0:
+ if len(cardinality) != num_static_categorical_features:
+ raise ValueError(
+ "The cardinality should be a list of the same length as `num_static_categorical_features`"
+ )
+ self.cardinality = cardinality
+ else:
+ self.cardinality = [0]
+ if embedding_dimension and num_static_categorical_features > 0:
+ if len(embedding_dimension) != num_static_categorical_features:
+ raise ValueError(
+ "The embedding dimension should be a list of the same length as `num_static_categorical_features`"
+ )
+ self.embedding_dimension = embedding_dimension
+ else:
+ self.embedding_dimension = [min(50, (cat + 1) // 2) for cat in self.cardinality]
+ self.num_parallel_samples = num_parallel_samples
+
+ # Transformer architecture configuration
+ self.feature_size = input_size * len(lags_sequence) + self._number_of_features
+ self.d_model = d_model
+ self.encoder_attention_heads = encoder_attention_heads
+ self.decoder_attention_heads = decoder_attention_heads
+ self.encoder_ffn_dim = encoder_ffn_dim
+ self.decoder_ffn_dim = decoder_ffn_dim
+ self.encoder_layers = encoder_layers
+ self.decoder_layers = decoder_layers
+
+ self.dropout = dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.encoder_layerdrop = encoder_layerdrop
+ self.decoder_layerdrop = decoder_layerdrop
+
+ self.activation_function = activation_function
+ self.init_std = init_std
+
+ self.use_cache = use_cache
+
+ super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs)
+
+ @property
+ def _number_of_features(self) -> int:
+ return (
+ sum(self.embedding_dimension)
+ + self.num_dynamic_real_features
+ + self.num_time_features
+ + self.num_static_real_features
+ + self.input_size * 2 # the log1p(abs(loc)) and log(scale) features
+ )
+
+
+__all__ = ["TimeSeriesTransformerConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/modeling_time_series_transformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/modeling_time_series_transformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..f46b2611d1b8b11dcce7ec024729c179aebe3f87
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/time_series_transformer/modeling_time_series_transformer.py
@@ -0,0 +1,1905 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+# Copyright 2018 Amazon.com, Inc. or its affiliates. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Time Series Transformer model."""
+
+from typing import Callable, Optional, Union
+
+import numpy as np
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...modeling_attn_mask_utils import (
+ _prepare_4d_attention_mask,
+ _prepare_4d_attention_mask_for_sdpa,
+ _prepare_4d_causal_attention_mask,
+ _prepare_4d_causal_attention_mask_for_sdpa,
+)
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ SampleTSPredictionOutput,
+ Seq2SeqTSModelOutput,
+ Seq2SeqTSPredictionOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...time_series_utils import NegativeBinomialOutput, NormalOutput, StudentTOutput
+from ...utils import auto_docstring, is_torch_flex_attn_available, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_time_series_transformer import TimeSeriesTransformerConfig
+
+
+if is_torch_flex_attn_available():
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.get_logger(__name__)
+
+
+class TimeSeriesFeatureEmbedder(nn.Module):
+ """
+ Embed a sequence of categorical features.
+
+ Args:
+ cardinalities (`list[int]`):
+ List of cardinalities of the categorical features.
+ embedding_dims (`list[int]`):
+ List of embedding dimensions of the categorical features.
+ """
+
+ def __init__(self, cardinalities: list[int], embedding_dims: list[int]) -> None:
+ super().__init__()
+
+ self.num_features = len(cardinalities)
+ self.embedders = nn.ModuleList([nn.Embedding(c, d) for c, d in zip(cardinalities, embedding_dims)])
+
+ def forward(self, features: torch.Tensor) -> torch.Tensor:
+ if self.num_features > 1:
+ # we slice the last dimension, giving an array of length
+ # self.num_features with shape (N,T) or (N)
+ cat_feature_slices = torch.chunk(features, self.num_features, dim=-1)
+ else:
+ cat_feature_slices = [features]
+
+ return torch.cat(
+ [
+ embed(cat_feature_slice.squeeze(-1))
+ for embed, cat_feature_slice in zip(self.embedders, cat_feature_slices)
+ ],
+ dim=-1,
+ )
+
+
+class TimeSeriesStdScaler(nn.Module):
+ """
+ Standardize features by calculating the mean and scaling along the first dimension, and then normalizes it by
+ subtracting from the mean and dividing by the standard deviation.
+ """
+
+ def __init__(self, config: TimeSeriesTransformerConfig):
+ super().__init__()
+ self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1
+ self.keepdim = config.keepdim if hasattr(config, "keepdim") else True
+ self.minimum_scale = config.minimum_scale if hasattr(config, "minimum_scale") else 1e-5
+
+ def forward(
+ self, data: torch.Tensor, observed_indicator: torch.Tensor
+ ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
+ """
+ Parameters:
+ data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`):
+ input for Batch norm calculation
+ observed_indicator (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`):
+ Calculating the scale on the observed indicator.
+ Returns:
+ tuple of `torch.Tensor` of shapes
+ (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`,
+ `(batch_size, 1, num_input_channels)`)
+ """
+ denominator = observed_indicator.sum(self.dim, keepdim=self.keepdim)
+ denominator = denominator.clamp_min(1.0)
+ loc = (data * observed_indicator).sum(self.dim, keepdim=self.keepdim) / denominator
+
+ variance = (((data - loc) * observed_indicator) ** 2).sum(self.dim, keepdim=self.keepdim) / denominator
+ scale = torch.sqrt(variance + self.minimum_scale)
+ return (data - loc) / scale, loc, scale
+
+
+class TimeSeriesMeanScaler(nn.Module):
+ """
+ Computes a scaling factor as the weighted average absolute value along the first dimension, and scales the data
+ accordingly.
+ """
+
+ def __init__(self, config: TimeSeriesTransformerConfig):
+ super().__init__()
+ self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1
+ self.keepdim = config.keepdim if hasattr(config, "keepdim") else True
+ self.minimum_scale = config.minimum_scale if hasattr(config, "minimum_scale") else 1e-10
+ self.default_scale = config.default_scale if hasattr(config, "default_scale") else None
+
+ def forward(
+ self, data: torch.Tensor, observed_indicator: torch.Tensor
+ ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
+ """
+ Parameters:
+ data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`):
+ input for Batch norm calculation
+ observed_indicator (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`):
+ Calculating the scale on the observed indicator.
+ Returns:
+ tuple of `torch.Tensor` of shapes
+ (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`,
+ `(batch_size, 1, num_input_channels)`)
+ """
+ ts_sum = (data * observed_indicator).abs().sum(self.dim, keepdim=True)
+ num_observed = observed_indicator.sum(self.dim, keepdim=True)
+
+ scale = ts_sum / torch.clamp(num_observed, min=1)
+
+ # If `default_scale` is provided, we use it, otherwise we use the scale
+ # of the batch.
+ if self.default_scale is None:
+ batch_sum = ts_sum.sum(dim=0)
+ batch_observations = torch.clamp(num_observed.sum(0), min=1)
+ default_scale = torch.squeeze(batch_sum / batch_observations)
+ else:
+ default_scale = self.default_scale * torch.ones_like(scale)
+
+ # apply default scale where there are no observations
+ scale = torch.where(num_observed > 0, scale, default_scale)
+
+ # ensure the scale is at least `self.minimum_scale`
+ scale = torch.clamp(scale, min=self.minimum_scale)
+ scaled_data = data / scale
+
+ if not self.keepdim:
+ scale = scale.squeeze(dim=self.dim)
+
+ return scaled_data, torch.zeros_like(scale), scale
+
+
+class TimeSeriesNOPScaler(nn.Module):
+ """
+ Assigns a scaling factor equal to 1 along the first dimension, and therefore applies no scaling to the input data.
+ """
+
+ def __init__(self, config: TimeSeriesTransformerConfig):
+ super().__init__()
+ self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1
+ self.keepdim = config.keepdim if hasattr(config, "keepdim") else True
+
+ def forward(
+ self, data: torch.Tensor, observed_indicator: Optional[torch.Tensor] = None
+ ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
+ """
+ Parameters:
+ data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`):
+ input for Batch norm calculation
+ Returns:
+ tuple of `torch.Tensor` of shapes
+ (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`,
+ `(batch_size, 1, num_input_channels)`)
+ """
+ scale = torch.ones_like(data, requires_grad=False).mean(dim=self.dim, keepdim=self.keepdim)
+ loc = torch.zeros_like(data, requires_grad=False).mean(dim=self.dim, keepdim=self.keepdim)
+ return data, loc, scale
+
+
+def nll(input: torch.distributions.Distribution, target: torch.Tensor) -> torch.Tensor:
+ """
+ Computes the negative log likelihood loss from input distribution with respect to target.
+ """
+ return -input.log_prob(target)
+
+
+def weighted_average(input_tensor: torch.Tensor, weights: Optional[torch.Tensor] = None, dim=None) -> torch.Tensor:
+ """
+ Computes the weighted average of a given tensor across a given `dim`, masking values associated with weight zero,
+ meaning instead of `nan * 0 = nan` you will get `0 * 0 = 0`.
+
+ Args:
+ input_tensor (`torch.FloatTensor`):
+ Input tensor, of which the average must be computed.
+ weights (`torch.FloatTensor`, *optional*):
+ Weights tensor, of the same shape as `input_tensor`.
+ dim (`int`, *optional*):
+ The dim along which to average `input_tensor`.
+
+ Returns:
+ `torch.FloatTensor`: The tensor with values averaged along the specified `dim`.
+ """
+ if weights is not None:
+ weighted_tensor = torch.where(weights != 0, input_tensor * weights, torch.zeros_like(input_tensor))
+ sum_weights = torch.clamp(weights.sum(dim=dim) if dim else weights.sum(), min=1.0)
+ return (weighted_tensor.sum(dim=dim) if dim else weighted_tensor.sum()) / sum_weights
+ else:
+ return input_tensor.mean(dim=dim)
+
+
+# Copied from transformers.models.marian.modeling_marian.MarianSinusoidalPositionalEmbedding with Marian->TimeSeries
+class TimeSeriesSinusoidalPositionalEmbedding(nn.Embedding):
+ """This module produces sinusoidal positional embeddings of any length."""
+
+ def __init__(self, num_positions: int, embedding_dim: int, padding_idx: Optional[int] = None) -> None:
+ super().__init__(num_positions, embedding_dim)
+
+ def _init_weight(self):
+ """
+ Identical to the XLM create_sinusoidal_embeddings except features are not interleaved. The cos features are in
+ the 2nd half of the vector. [dim // 2:]
+ """
+ n_pos, dim = self.weight.shape
+ position_enc = np.array(
+ [[pos / np.power(10000, 2 * (j // 2) / dim) for j in range(dim)] for pos in range(n_pos)]
+ )
+ out = torch.empty(n_pos, dim, dtype=self.weight.dtype, requires_grad=False)
+ sentinel = dim // 2 if dim % 2 == 0 else (dim // 2) + 1
+ out[:, 0:sentinel] = torch.FloatTensor(np.sin(position_enc[:, 0::2]))
+ out[:, sentinel:] = torch.FloatTensor(np.cos(position_enc[:, 1::2]))
+ self.weight = nn.Parameter(out, requires_grad=False)
+
+ @torch.no_grad()
+ def forward(
+ self, input_ids_shape: torch.Size, past_key_values_length: int = 0, position_ids: Optional[torch.Tensor] = None
+ ) -> torch.Tensor:
+ """`input_ids_shape` is expected to be [bsz x seqlen]."""
+ if position_ids is None:
+ bsz, seq_len = input_ids_shape[:2]
+ position_ids = torch.arange(
+ past_key_values_length, past_key_values_length + seq_len, dtype=torch.long, device=self.weight.device
+ )
+ return super().forward(position_ids)
+
+
+class TimeSeriesValueEmbedding(nn.Module):
+ def __init__(self, feature_size, d_model):
+ super().__init__()
+ self.value_projection = nn.Linear(in_features=feature_size, out_features=d_model, bias=False)
+
+ def forward(self, x):
+ return self.value_projection(x)
+
+
+# Copied from transformers.models.bart.modeling_bart.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: Optional[float] = None,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ if scaling is None:
+ scaling = query.size(-1) ** -0.5
+
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.bart.modeling_bart.BartAttention with Bart->TimeSeriesTransformer
+class TimeSeriesTransformerAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ is_causal: bool = False,
+ config: Optional[TimeSeriesTransformerConfig] = None,
+ layer_idx: Optional[int] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ self.config = config
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.is_causal = is_causal
+ self.layer_idx = layer_idx
+ if layer_idx is None and self.is_decoder:
+ logger.warning_once(
+ f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and "
+ "will lead to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ cache_position: Optional[torch.Tensor] = None,
+ # TODO: we need a refactor so that the different attention modules can get their specific kwargs
+ # ATM, we have mixed things encoder, decoder, and encoder-decoder attn
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ # determine input shapes
+ bsz, tgt_len = hidden_states.shape[:-1]
+ src_len = key_value_states.shape[1] if is_cross_attention else tgt_len
+
+ q_input_shape = (bsz, tgt_len, -1, self.head_dim)
+ kv_input_shape = (bsz, src_len, -1, self.head_dim)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k_proj(current_states)
+ value_states = self.v_proj(current_states)
+ key_states = key_states.view(*kv_input_shape).transpose(1, 2)
+ value_states = value_states.view(*kv_input_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.dropout,
+ scaling=self.scaling,
+ output_attentions=output_attentions,
+ head_mask=layer_head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.bart.modeling_bart.BartEncoderLayer with Bart->TimeSeriesTransformer, BART->TIME_SERIES_TRANSFORMER
+class TimeSeriesTransformerEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: TimeSeriesTransformerConfig, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = TimeSeriesTransformerAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.encoder_attention_heads,
+ dropout=config.attention_dropout,
+ config=config,
+ layer_idx=layer_idx,
+ )
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+ self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim)
+ self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ attention_mask: torch.FloatTensor,
+ layer_head_mask: torch.FloatTensor,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.FloatTensor, Optional[torch.FloatTensor]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ if hidden_states.dtype == torch.float16 and (
+ torch.isinf(hidden_states).any() or torch.isnan(hidden_states).any()
+ ):
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+# Copied from transformers.models.bart.modeling_bart.BartDecoderLayer with Bart->TimeSeriesTransformer, with BART->TIME_SERIES_TRANSFORMER
+class TimeSeriesTransformerDecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: TimeSeriesTransformerConfig, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = TimeSeriesTransformerAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ is_causal=True,
+ config=config,
+ layer_idx=layer_idx,
+ )
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.encoder_attn = TimeSeriesTransformerAttention(
+ self.embed_dim,
+ config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ config=config,
+ layer_idx=layer_idx,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim)
+ self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_layer_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = True,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`torch.FloatTensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ cross_attn_layer_head_mask (`torch.FloatTensor`): mask for cross-attention heads in a given layer of
+ size `(decoder_attention_heads,)`.
+ past_key_values (`Tuple(torch.FloatTensor)`): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. It is used to update the
+ cache in the correct position and to infer the complete sequence length.
+ """
+ residual = hidden_states
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_values=past_key_values,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+@auto_docstring
+class TimeSeriesTransformerPreTrainedModel(PreTrainedModel):
+ config: TimeSeriesTransformerConfig
+ base_model_prefix = "model"
+ main_input_name = "past_values"
+ supports_gradient_checkpointing = True
+ # TODO: tests would need a rewrite to check for correct implementation
+ # Current tests always assume certain inputs to be passed
+ _supports_flash_attn = False
+ _supports_sdpa = False
+ _supports_flex_attn = False
+
+ def _init_weights(self, module):
+ std = self.config.init_std
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, TimeSeriesSinusoidalPositionalEmbedding):
+ module._init_weight()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+ # Copied from transformers.models.bart.modeling_bart.BartPreTrainedModel._update_full_mask
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+ # Copied from transformers.models.musicgen.modeling_musicgen.MusicgenDecoder._update_causal_mask
+ def _update_causal_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ input_shape: torch.Size,
+ inputs_embeds: torch.Tensor,
+ past_key_values_length: int,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ # 2d mask is passed through the layers
+ attention_mask = attention_mask if (attention_mask is not None and 0 in attention_mask) else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & cross_attn_head_mask can not be supported when using SDPA, and we fall back on
+ # the manual implementation that requires a 4D causal mask in all cases.
+ attention_mask = _prepare_4d_causal_attention_mask_for_sdpa(
+ attention_mask,
+ input_shape,
+ inputs_embeds,
+ past_key_values_length,
+ )
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask)
+ # Other attention flavors support in-built causal (when `mask is None`)
+ # while we need to create our specific block mask regardless
+ elif attention_mask is None:
+ attention_mask = make_flex_block_causal_mask(
+ torch.ones(
+ size=(input_shape),
+ device=inputs_embeds.device,
+ )
+ )
+ else:
+ # 4d mask is passed through the layers
+ attention_mask = _prepare_4d_causal_attention_mask(
+ attention_mask, input_shape, inputs_embeds, past_key_values_length
+ )
+
+ return attention_mask
+
+ # Copied from transformers.models.musicgen.modeling_musicgen.MusicgenDecoder._update_cross_attn_mask
+ def _update_cross_attn_mask(
+ self,
+ encoder_hidden_states: Union[torch.Tensor, None],
+ encoder_attention_mask: Union[torch.Tensor, None],
+ input_shape: torch.Size,
+ inputs_embeds: torch.Tensor,
+ ):
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ encoder_attention_mask = encoder_attention_mask if 0 in encoder_attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & cross_attn_head_mask can not be supported when using SDPA, and we fall back on
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ encoder_attention_mask,
+ inputs_embeds.dtype,
+ tgt_len=input_shape[-1],
+ )
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(encoder_attention_mask, torch.Tensor):
+ encoder_attention_mask = make_flex_block_causal_mask(
+ encoder_attention_mask,
+ query_length=input_shape[-1],
+ is_causal=False,
+ )
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(
+ encoder_attention_mask, inputs_embeds.dtype, tgt_len=input_shape[-1]
+ )
+
+ return encoder_attention_mask
+
+
+class TimeSeriesTransformerEncoder(TimeSeriesTransformerPreTrainedModel):
+ """
+ Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a
+ [`TimeSeriesTransformerEncoderLayer`].
+
+ Args:
+ config: TimeSeriesTransformerConfig
+ """
+
+ def __init__(self, config: TimeSeriesTransformerConfig):
+ super().__init__(config)
+
+ self.dropout = config.dropout
+ self.layerdrop = config.encoder_layerdrop
+ if config.prediction_length is None:
+ raise ValueError("The `prediction_length` config needs to be specified.")
+
+ self.value_embedding = TimeSeriesValueEmbedding(feature_size=config.feature_size, d_model=config.d_model)
+ self.embed_positions = TimeSeriesSinusoidalPositionalEmbedding(
+ config.context_length + config.prediction_length, config.d_model
+ )
+ self.layers = nn.ModuleList([TimeSeriesTransformerEncoderLayer(config) for _ in range(config.encoder_layers)])
+ self.layernorm_embedding = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ r"""
+ Args:
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`torch.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ hidden_states = self.value_embedding(inputs_embeds)
+ embed_pos = self.embed_positions(inputs_embeds.size())
+
+ hidden_states = self.layernorm_embedding(hidden_states + embed_pos)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ inputs_embeds,
+ )
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ # check if head_mask has a correct number of layers specified if desired
+ if head_mask is not None:
+ if head_mask.size()[0] != (len(self.layers)):
+ raise ValueError(
+ f"The head_mask should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ to_drop = False
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop: # skip the layer
+ to_drop = True
+
+ if to_drop:
+ layer_outputs = (None, None)
+ else:
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+
+class TimeSeriesTransformerDecoder(TimeSeriesTransformerPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a
+ [`TimeSeriesTransformerDecoderLayer`]
+
+ Args:
+ config: TimeSeriesTransformerConfig
+ """
+
+ def __init__(self, config: TimeSeriesTransformerConfig):
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.decoder_layerdrop
+ if config.prediction_length is None:
+ raise ValueError("The `prediction_length` config needs to be specified.")
+
+ self.value_embedding = TimeSeriesValueEmbedding(feature_size=config.feature_size, d_model=config.d_model)
+ self.embed_positions = TimeSeriesSinusoidalPositionalEmbedding(
+ config.context_length + config.prediction_length, config.d_model
+ )
+ self.layers = nn.ModuleList(
+ [TimeSeriesTransformerDecoderLayer(config, layer_idx=i) for i in range(config.decoder_layers)]
+ )
+ self.layernorm_embedding = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPastAndCrossAttentions]:
+ r"""
+ Args:
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder to avoid performing
+ cross-attention on hidden heads. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of
+ shape `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and in the
+ cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those
+ that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of
+ all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. It is used to update the
+ cache in the correct position and to infer the complete sequence length.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ input_shape = inputs_embeds.size()[:-1]
+ # initialize `past_key_values`
+ if use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+ if cache_position is None:
+ cache_position = torch.arange(
+ past_key_values_length, past_key_values_length + input_shape[1], device=inputs_embeds.device
+ )
+
+ attention_mask = self._update_causal_mask(
+ attention_mask,
+ input_shape,
+ inputs_embeds,
+ past_key_values_length,
+ )
+ encoder_attention_mask = self._update_cross_attn_mask(
+ encoder_hidden_states,
+ encoder_attention_mask,
+ input_shape,
+ inputs_embeds,
+ )
+
+ hidden_states = self.value_embedding(inputs_embeds)
+ embed_pos = self.embed_positions(inputs_embeds.size(), past_key_values_length=self.config.context_length)
+ hidden_states = self.layernorm_embedding(hidden_states + embed_pos)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ # check if head_mask/cross_attn_head_mask has a correct number of layers specified if desired
+ for attn_mask, mask_name in zip([head_mask, cross_attn_head_mask], ["head_mask", "cross_attn_head_mask"]):
+ if attn_mask is not None:
+ if attn_mask.size()[0] != (len(self.layers)):
+ raise ValueError(
+ f"The `{mask_name}` should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop:
+ continue
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+@auto_docstring
+class TimeSeriesTransformerModel(TimeSeriesTransformerPreTrainedModel):
+ def __init__(self, config: TimeSeriesTransformerConfig):
+ super().__init__(config)
+
+ if config.scaling == "mean" or config.scaling is True:
+ self.scaler = TimeSeriesMeanScaler(config)
+ elif config.scaling == "std":
+ self.scaler = TimeSeriesStdScaler(config)
+ else:
+ self.scaler = TimeSeriesNOPScaler(config)
+
+ if config.num_static_categorical_features > 0:
+ self.embedder = TimeSeriesFeatureEmbedder(
+ cardinalities=config.cardinality,
+ embedding_dims=config.embedding_dimension,
+ )
+
+ # transformer encoder-decoder and mask initializer
+ self.encoder = TimeSeriesTransformerEncoder(config)
+ self.decoder = TimeSeriesTransformerDecoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @property
+ def _past_length(self) -> int:
+ return self.config.context_length + max(self.config.lags_sequence)
+
+ def get_lagged_subsequences(
+ self, sequence: torch.Tensor, subsequences_length: int, shift: int = 0
+ ) -> torch.Tensor:
+ """
+ Returns lagged subsequences of a given sequence. Returns a tensor of shape (N, S, C, I),
+ where S = subsequences_length and I = len(indices), containing lagged subsequences. Specifically, lagged[i,
+ j, :, k] = sequence[i, -indices[k]-S+j, :].
+
+ Args:
+ sequence: Tensor
+ The sequence from which lagged subsequences should be extracted. Shape: (N, T, C).
+ subsequences_length : int
+ Length of the subsequences to be extracted.
+ shift: int
+ Shift the lags by this amount back.
+ """
+ sequence_length = sequence.shape[1]
+ indices = [lag - shift for lag in self.config.lags_sequence]
+
+ if max(indices) + subsequences_length > sequence_length:
+ raise ValueError(
+ f"lags cannot go further than history length, found lag {max(indices)} "
+ f"while history length is only {sequence_length}"
+ )
+
+ lagged_values = []
+ for lag_index in indices:
+ begin_index = -lag_index - subsequences_length
+ end_index = -lag_index if lag_index > 0 else None
+ lagged_values.append(sequence[:, begin_index:end_index, ...])
+ return torch.stack(lagged_values, dim=-1)
+
+ def create_network_inputs(
+ self,
+ past_values: torch.Tensor,
+ past_time_features: torch.Tensor,
+ static_categorical_features: Optional[torch.Tensor] = None,
+ static_real_features: Optional[torch.Tensor] = None,
+ past_observed_mask: Optional[torch.Tensor] = None,
+ future_values: Optional[torch.Tensor] = None,
+ future_time_features: Optional[torch.Tensor] = None,
+ ):
+ # time feature
+ time_feat = (
+ torch.cat(
+ (
+ past_time_features[:, self._past_length - self.config.context_length :, ...],
+ future_time_features,
+ ),
+ dim=1,
+ )
+ if future_values is not None
+ else past_time_features[:, self._past_length - self.config.context_length :, ...]
+ )
+
+ # target
+ if past_observed_mask is None:
+ past_observed_mask = torch.ones_like(past_values)
+
+ context = past_values[:, -self.config.context_length :]
+ observed_context = past_observed_mask[:, -self.config.context_length :]
+ _, loc, scale = self.scaler(context, observed_context)
+
+ inputs = (
+ (torch.cat((past_values, future_values), dim=1) - loc) / scale
+ if future_values is not None
+ else (past_values - loc) / scale
+ )
+
+ # static features
+ if loc.ndim == 3:
+ squeezed_loc = loc.squeeze(1)
+ squeezed_scale = scale.squeeze(1)
+ else:
+ squeezed_loc = loc
+ squeezed_scale = scale
+ log_abs_loc = squeezed_loc.abs().log1p()
+ log_scale = squeezed_scale.log()
+ static_feat = torch.cat((log_abs_loc, log_scale), dim=1)
+
+ if static_real_features is not None:
+ static_feat = torch.cat((static_real_features, static_feat), dim=1)
+ if static_categorical_features is not None:
+ embedded_cat = self.embedder(static_categorical_features)
+ static_feat = torch.cat((embedded_cat, static_feat), dim=1)
+ expanded_static_feat = static_feat.unsqueeze(1).expand(-1, time_feat.shape[1], -1)
+
+ # all features
+ features = torch.cat((expanded_static_feat, time_feat), dim=-1)
+
+ # lagged features
+ subsequences_length = (
+ self.config.context_length + self.config.prediction_length
+ if future_values is not None
+ else self.config.context_length
+ )
+ lagged_sequence = self.get_lagged_subsequences(sequence=inputs, subsequences_length=subsequences_length)
+ lags_shape = lagged_sequence.shape
+ reshaped_lagged_sequence = lagged_sequence.reshape(lags_shape[0], lags_shape[1], -1)
+
+ if reshaped_lagged_sequence.shape[1] != time_feat.shape[1]:
+ raise ValueError(
+ f"input length {reshaped_lagged_sequence.shape[1]} and time feature lengths {time_feat.shape[1]} does not match"
+ )
+
+ # transformer inputs
+ transformer_inputs = torch.cat((reshaped_lagged_sequence, features), dim=-1)
+
+ return transformer_inputs, loc, scale, static_feat
+
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ past_values: torch.Tensor,
+ past_time_features: torch.Tensor,
+ past_observed_mask: torch.Tensor,
+ static_categorical_features: Optional[torch.Tensor] = None,
+ static_real_features: Optional[torch.Tensor] = None,
+ future_values: Optional[torch.Tensor] = None,
+ future_time_features: Optional[torch.Tensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[list[torch.FloatTensor]] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ output_hidden_states: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ use_cache: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[Seq2SeqTSModelOutput, tuple]:
+ r"""
+ past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, input_size)`):
+ Past values of the time series, that serve as context in order to predict the future. The sequence size of
+ this tensor must be larger than the `context_length` of the model, since the model will use the larger size
+ to construct lag features, i.e. additional values from the past which are added in order to serve as "extra
+ context".
+
+ The `sequence_length` here is equal to `config.context_length` + `max(config.lags_sequence)`, which if no
+ `lags_sequence` is configured, is equal to `config.context_length` + 7 (as by default, the largest
+ look-back index in `config.lags_sequence` is 7). The property `_past_length` returns the actual length of
+ the past.
+
+ The `past_values` is what the Transformer encoder gets as input (with optional additional features, such as
+ `static_categorical_features`, `static_real_features`, `past_time_features` and lags).
+
+ Optionally, missing values need to be replaced with zeros and indicated via the `past_observed_mask`.
+
+ For multivariate time series, the `input_size` > 1 dimension is required and corresponds to the number of
+ variates in the time series per time step.
+ past_time_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_features)`):
+ Required time features, which the model internally will add to `past_values`. These could be things like
+ "month of year", "day of the month", etc. encoded as vectors (for instance as Fourier features). These
+ could also be so-called "age" features, which basically help the model know "at which point in life" a
+ time-series is. Age features have small values for distant past time steps and increase monotonically the
+ more we approach the current time step. Holiday features are also a good example of time features.
+
+ These features serve as the "positional encodings" of the inputs. So contrary to a model like BERT, where
+ the position encodings are learned from scratch internally as parameters of the model, the Time Series
+ Transformer requires to provide additional time features. The Time Series Transformer only learns
+ additional embeddings for `static_categorical_features`.
+
+ Additional dynamic real covariates can be concatenated to this tensor, with the caveat that these features
+ must but known at prediction time.
+
+ The `num_features` here is equal to `config.`num_time_features` + `config.num_dynamic_real_features`.
+ past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, input_size)`, *optional*):
+ Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected in
+ `[0, 1]`:
+
+ - 1 for values that are **observed**,
+ - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros).
+ static_categorical_features (`torch.LongTensor` of shape `(batch_size, number of static categorical features)`, *optional*):
+ Optional static categorical features for which the model will learn an embedding, which it will add to the
+ values of the time series.
+
+ Static categorical features are features which have the same value for all time steps (static over time).
+
+ A typical example of a static categorical feature is a time series ID.
+ static_real_features (`torch.FloatTensor` of shape `(batch_size, number of static real features)`, *optional*):
+ Optional static real features which the model will add to the values of the time series.
+
+ Static real features are features which have the same value for all time steps (static over time).
+
+ A typical example of a static real feature is promotion information.
+ future_values (`torch.FloatTensor` of shape `(batch_size, prediction_length)` or `(batch_size, prediction_length, input_size)`, *optional*):
+ Future values of the time series, that serve as labels for the model. The `future_values` is what the
+ Transformer needs during training to learn to output, given the `past_values`.
+
+ The sequence length here is equal to `prediction_length`.
+
+ See the demo notebook and code snippets for details.
+
+ Optionally, during training any missing values need to be replaced with zeros and indicated via the
+ `future_observed_mask`.
+
+ For multivariate time series, the `input_size` > 1 dimension is required and corresponds to the number of
+ variates in the time series per time step.
+ future_time_features (`torch.FloatTensor` of shape `(batch_size, prediction_length, num_features)`):
+ Required time features for the prediction window, which the model internally will add to `future_values`.
+ These could be things like "month of year", "day of the month", etc. encoded as vectors (for instance as
+ Fourier features). These could also be so-called "age" features, which basically help the model know "at
+ which point in life" a time-series is. Age features have small values for distant past time steps and
+ increase monotonically the more we approach the current time step. Holiday features are also a good example
+ of time features.
+
+ These features serve as the "positional encodings" of the inputs. So contrary to a model like BERT, where
+ the position encodings are learned from scratch internally as parameters of the model, the Time Series
+ Transformer requires to provide additional time features. The Time Series Transformer only learns
+ additional embeddings for `static_categorical_features`.
+
+ Additional dynamic real covariates can be concatenated to this tensor, with the caveat that these features
+ must but known at prediction time.
+
+ The `num_features` here is equal to `config.`num_time_features` + `config.num_dynamic_real_features`.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ encoder_outputs (`tuple(tuple(torch.FloatTensor)`, *optional*):
+ Tuple consists of `last_hidden_state`, `hidden_states` (*optional*) and `attentions` (*optional*)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)` (*optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+
+ Examples:
+
+ ```python
+ >>> from huggingface_hub import hf_hub_download
+ >>> import torch
+ >>> from transformers import TimeSeriesTransformerModel
+
+ >>> file = hf_hub_download(
+ ... repo_id="hf-internal-testing/tourism-monthly-batch", filename="train-batch.pt", repo_type="dataset"
+ ... )
+ >>> batch = torch.load(file)
+
+ >>> model = TimeSeriesTransformerModel.from_pretrained("huggingface/time-series-transformer-tourism-monthly")
+
+ >>> # during training, one provides both past and future values
+ >>> # as well as possible additional features
+ >>> outputs = model(
+ ... past_values=batch["past_values"],
+ ... past_time_features=batch["past_time_features"],
+ ... past_observed_mask=batch["past_observed_mask"],
+ ... static_categorical_features=batch["static_categorical_features"],
+ ... static_real_features=batch["static_real_features"],
+ ... future_values=batch["future_values"],
+ ... future_time_features=batch["future_time_features"],
+ ... )
+
+ >>> last_hidden_state = outputs.last_hidden_state
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_inputs, loc, scale, static_feat = self.create_network_inputs(
+ past_values=past_values,
+ past_time_features=past_time_features,
+ past_observed_mask=past_observed_mask,
+ static_categorical_features=static_categorical_features,
+ static_real_features=static_real_features,
+ future_values=future_values,
+ future_time_features=future_time_features,
+ )
+
+ if encoder_outputs is None:
+ enc_input = transformer_inputs[:, : self.config.context_length, ...]
+ encoder_outputs = self.encoder(
+ inputs_embeds=enc_input,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ # Avoid empty tensors and instead create a zeroes tensor which
+ # will be treated the same in torch, i.e. matmul with empty == all 0s
+ if self.config.context_length >= transformer_inputs.shape[1]:
+ bsz, _, dim = transformer_inputs.shape
+ dec_input = torch.zeros(
+ size=(bsz, 1, dim), device=transformer_inputs.device, dtype=transformer_inputs.dtype
+ )
+ else:
+ dec_input = transformer_inputs[:, self.config.context_length :, ...]
+
+ decoder_outputs = self.decoder(
+ inputs_embeds=dec_input,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_outputs[0],
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs + (loc, scale, static_feat)
+
+ return Seq2SeqTSModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ loc=loc,
+ scale=scale,
+ static_features=static_feat,
+ )
+
+
+@auto_docstring
+class TimeSeriesTransformerForPrediction(TimeSeriesTransformerPreTrainedModel):
+ def __init__(self, config: TimeSeriesTransformerConfig):
+ super().__init__(config)
+ self.model = TimeSeriesTransformerModel(config)
+ if config.distribution_output == "student_t":
+ self.distribution_output = StudentTOutput(dim=config.input_size)
+ elif config.distribution_output == "normal":
+ self.distribution_output = NormalOutput(dim=config.input_size)
+ elif config.distribution_output == "negative_binomial":
+ self.distribution_output = NegativeBinomialOutput(dim=config.input_size)
+ else:
+ raise ValueError(f"Unknown distribution output {config.distribution_output}")
+
+ self.parameter_projection = self.distribution_output.get_parameter_projection(self.model.config.d_model)
+ self.target_shape = self.distribution_output.event_shape
+
+ if config.loss == "nll":
+ self.loss = nll
+ else:
+ raise ValueError(f"Unknown loss function {config.loss}")
+
+ # Initialize weights of distribution_output and apply final processing
+ self.post_init()
+
+ def output_params(self, dec_output):
+ return self.parameter_projection(dec_output)
+
+ def get_encoder(self):
+ return self.model.get_encoder()
+
+ def get_decoder(self):
+ return self.model.get_decoder()
+
+ @torch.jit.ignore
+ def output_distribution(self, params, loc=None, scale=None, trailing_n=None) -> torch.distributions.Distribution:
+ sliced_params = params
+ if trailing_n is not None:
+ sliced_params = [p[:, -trailing_n:] for p in params]
+ return self.distribution_output.distribution(sliced_params, loc=loc, scale=scale)
+
+ @auto_docstring
+ def forward(
+ self,
+ past_values: torch.Tensor,
+ past_time_features: torch.Tensor,
+ past_observed_mask: torch.Tensor,
+ static_categorical_features: Optional[torch.Tensor] = None,
+ static_real_features: Optional[torch.Tensor] = None,
+ future_values: Optional[torch.Tensor] = None,
+ future_time_features: Optional[torch.Tensor] = None,
+ future_observed_mask: Optional[torch.Tensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[list[torch.FloatTensor]] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ output_hidden_states: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ use_cache: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[Seq2SeqTSModelOutput, tuple]:
+ r"""
+ past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, input_size)`):
+ Past values of the time series, that serve as context in order to predict the future. The sequence size of
+ this tensor must be larger than the `context_length` of the model, since the model will use the larger size
+ to construct lag features, i.e. additional values from the past which are added in order to serve as "extra
+ context".
+
+ The `sequence_length` here is equal to `config.context_length` + `max(config.lags_sequence)`, which if no
+ `lags_sequence` is configured, is equal to `config.context_length` + 7 (as by default, the largest
+ look-back index in `config.lags_sequence` is 7). The property `_past_length` returns the actual length of
+ the past.
+
+ The `past_values` is what the Transformer encoder gets as input (with optional additional features, such as
+ `static_categorical_features`, `static_real_features`, `past_time_features` and lags).
+
+ Optionally, missing values need to be replaced with zeros and indicated via the `past_observed_mask`.
+
+ For multivariate time series, the `input_size` > 1 dimension is required and corresponds to the number of
+ variates in the time series per time step.
+ past_time_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_features)`):
+ Required time features, which the model internally will add to `past_values`. These could be things like
+ "month of year", "day of the month", etc. encoded as vectors (for instance as Fourier features). These
+ could also be so-called "age" features, which basically help the model know "at which point in life" a
+ time-series is. Age features have small values for distant past time steps and increase monotonically the
+ more we approach the current time step. Holiday features are also a good example of time features.
+
+ These features serve as the "positional encodings" of the inputs. So contrary to a model like BERT, where
+ the position encodings are learned from scratch internally as parameters of the model, the Time Series
+ Transformer requires to provide additional time features. The Time Series Transformer only learns
+ additional embeddings for `static_categorical_features`.
+
+ Additional dynamic real covariates can be concatenated to this tensor, with the caveat that these features
+ must but known at prediction time.
+
+ The `num_features` here is equal to `config.`num_time_features` + `config.num_dynamic_real_features`.
+ past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, input_size)`, *optional*):
+ Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected in
+ `[0, 1]`:
+
+ - 1 for values that are **observed**,
+ - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros).
+ static_categorical_features (`torch.LongTensor` of shape `(batch_size, number of static categorical features)`, *optional*):
+ Optional static categorical features for which the model will learn an embedding, which it will add to the
+ values of the time series.
+
+ Static categorical features are features which have the same value for all time steps (static over time).
+
+ A typical example of a static categorical feature is a time series ID.
+ static_real_features (`torch.FloatTensor` of shape `(batch_size, number of static real features)`, *optional*):
+ Optional static real features which the model will add to the values of the time series.
+
+ Static real features are features which have the same value for all time steps (static over time).
+
+ A typical example of a static real feature is promotion information.
+ future_values (`torch.FloatTensor` of shape `(batch_size, prediction_length)` or `(batch_size, prediction_length, input_size)`, *optional*):
+ Future values of the time series, that serve as labels for the model. The `future_values` is what the
+ Transformer needs during training to learn to output, given the `past_values`.
+
+ The sequence length here is equal to `prediction_length`.
+
+ See the demo notebook and code snippets for details.
+
+ Optionally, during training any missing values need to be replaced with zeros and indicated via the
+ `future_observed_mask`.
+
+ For multivariate time series, the `input_size` > 1 dimension is required and corresponds to the number of
+ variates in the time series per time step.
+ future_time_features (`torch.FloatTensor` of shape `(batch_size, prediction_length, num_features)`):
+ Required time features for the prediction window, which the model internally will add to `future_values`.
+ These could be things like "month of year", "day of the month", etc. encoded as vectors (for instance as
+ Fourier features). These could also be so-called "age" features, which basically help the model know "at
+ which point in life" a time-series is. Age features have small values for distant past time steps and
+ increase monotonically the more we approach the current time step. Holiday features are also a good example
+ of time features.
+
+ These features serve as the "positional encodings" of the inputs. So contrary to a model like BERT, where
+ the position encodings are learned from scratch internally as parameters of the model, the Time Series
+ Transformer requires to provide additional time features. The Time Series Transformer only learns
+ additional embeddings for `static_categorical_features`.
+
+ Additional dynamic real covariates can be concatenated to this tensor, with the caveat that these features
+ must but known at prediction time.
+
+ The `num_features` here is equal to `config.`num_time_features` + `config.num_dynamic_real_features`.
+ future_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, input_size)`, *optional*):
+ Boolean mask to indicate which `future_values` were observed and which were missing. Mask values selected
+ in `[0, 1]`:
+
+ - 1 for values that are **observed**,
+ - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros).
+
+ This mask is used to filter out missing values for the final loss calculation.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ encoder_outputs (`tuple(tuple(torch.FloatTensor)`, *optional*):
+ Tuple consists of `last_hidden_state`, `hidden_states` (*optional*) and `attentions` (*optional*)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)` (*optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+
+ Examples:
+
+ ```python
+ >>> from huggingface_hub import hf_hub_download
+ >>> import torch
+ >>> from transformers import TimeSeriesTransformerForPrediction
+
+ >>> file = hf_hub_download(
+ ... repo_id="hf-internal-testing/tourism-monthly-batch", filename="train-batch.pt", repo_type="dataset"
+ ... )
+ >>> batch = torch.load(file)
+
+ >>> model = TimeSeriesTransformerForPrediction.from_pretrained(
+ ... "huggingface/time-series-transformer-tourism-monthly"
+ ... )
+
+ >>> # during training, one provides both past and future values
+ >>> # as well as possible additional features
+ >>> outputs = model(
+ ... past_values=batch["past_values"],
+ ... past_time_features=batch["past_time_features"],
+ ... past_observed_mask=batch["past_observed_mask"],
+ ... static_categorical_features=batch["static_categorical_features"],
+ ... static_real_features=batch["static_real_features"],
+ ... future_values=batch["future_values"],
+ ... future_time_features=batch["future_time_features"],
+ ... )
+
+ >>> loss = outputs.loss
+ >>> loss.backward()
+
+ >>> # during inference, one only provides past values
+ >>> # as well as possible additional features
+ >>> # the model autoregressively generates future values
+ >>> outputs = model.generate(
+ ... past_values=batch["past_values"],
+ ... past_time_features=batch["past_time_features"],
+ ... past_observed_mask=batch["past_observed_mask"],
+ ... static_categorical_features=batch["static_categorical_features"],
+ ... static_real_features=batch["static_real_features"],
+ ... future_time_features=batch["future_time_features"],
+ ... )
+
+ >>> mean_prediction = outputs.sequences.mean(dim=1)
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ if future_values is not None:
+ use_cache = False
+
+ outputs = self.model(
+ past_values=past_values,
+ past_time_features=past_time_features,
+ past_observed_mask=past_observed_mask,
+ static_categorical_features=static_categorical_features,
+ static_real_features=static_real_features,
+ future_values=future_values,
+ future_time_features=future_time_features,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ output_hidden_states=output_hidden_states,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ prediction_loss = None
+ params = None
+ if future_values is not None:
+ params = self.output_params(outputs[0]) # outputs.last_hidden_state
+ # loc is 3rd last and scale is 2nd last output
+ distribution = self.output_distribution(params, loc=outputs[-3], scale=outputs[-2])
+
+ loss = self.loss(distribution, future_values)
+
+ if future_observed_mask is None:
+ future_observed_mask = torch.ones_like(future_values)
+
+ if len(self.target_shape) == 0:
+ loss_weights = future_observed_mask
+ else:
+ loss_weights, _ = future_observed_mask.min(dim=-1, keepdim=False)
+
+ prediction_loss = weighted_average(loss, weights=loss_weights)
+
+ if not return_dict:
+ outputs = ((params,) + outputs[1:]) if params is not None else outputs[1:]
+ return ((prediction_loss,) + outputs) if prediction_loss is not None else outputs
+
+ return Seq2SeqTSPredictionOutput(
+ loss=prediction_loss,
+ params=params,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ loc=outputs.loc,
+ scale=outputs.scale,
+ static_features=outputs.static_features,
+ )
+
+ @torch.no_grad()
+ def generate(
+ self,
+ past_values: torch.Tensor,
+ past_time_features: torch.Tensor,
+ future_time_features: torch.Tensor,
+ past_observed_mask: Optional[torch.Tensor] = None,
+ static_categorical_features: Optional[torch.Tensor] = None,
+ static_real_features: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> SampleTSPredictionOutput:
+ r"""
+ Greedily generate sequences of sample predictions from a model with a probability distribution head.
+
+ Parameters:
+ past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, input_size)`):
+ Past values of the time series, that serve as context in order to predict the future. The sequence size
+ of this tensor must be larger than the `context_length` of the model, since the model will use the
+ larger size to construct lag features, i.e. additional values from the past which are added in order to
+ serve as "extra context".
+
+ The `sequence_length` here is equal to `config.context_length` + `max(config.lags_sequence)`, which if
+ no `lags_sequence` is configured, is equal to `config.context_length` + 7 (as by default, the largest
+ look-back index in `config.lags_sequence` is 7). The property `_past_length` returns the actual length
+ of the past.
+
+ The `past_values` is what the Transformer encoder gets as input (with optional additional features,
+ such as `static_categorical_features`, `static_real_features`, `past_time_features` and lags).
+
+ Optionally, missing values need to be replaced with zeros and indicated via the `past_observed_mask`.
+
+ For multivariate time series, the `input_size` > 1 dimension is required and corresponds to the number
+ of variates in the time series per time step.
+ past_time_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_features)`):
+ Required time features, which the model internally will add to `past_values`. These could be things
+ like "month of year", "day of the month", etc. encoded as vectors (for instance as Fourier features).
+ These could also be so-called "age" features, which basically help the model know "at which point in
+ life" a time-series is. Age features have small values for distant past time steps and increase
+ monotonically the more we approach the current time step. Holiday features are also a good example of
+ time features.
+
+ These features serve as the "positional encodings" of the inputs. So contrary to a model like BERT,
+ where the position encodings are learned from scratch internally as parameters of the model, the Time
+ Series Transformer requires to provide additional time features. The Time Series Transformer only
+ learns additional embeddings for `static_categorical_features`.
+
+ Additional dynamic real covariates can be concatenated to this tensor, with the caveat that these
+ features must but known at prediction time.
+
+ The `num_features` here is equal to `config.`num_time_features` + `config.num_dynamic_real_features`.
+ future_time_features (`torch.FloatTensor` of shape `(batch_size, prediction_length, num_features)`):
+ Required time features for the prediction window, which the model internally will add to sampled
+ predictions. These could be things like "month of year", "day of the month", etc. encoded as vectors
+ (for instance as Fourier features). These could also be so-called "age" features, which basically help
+ the model know "at which point in life" a time-series is. Age features have small values for distant
+ past time steps and increase monotonically the more we approach the current time step. Holiday features
+ are also a good example of time features.
+
+ These features serve as the "positional encodings" of the inputs. So contrary to a model like BERT,
+ where the position encodings are learned from scratch internally as parameters of the model, the Time
+ Series Transformer requires to provide additional time features. The Time Series Transformer only
+ learns additional embeddings for `static_categorical_features`.
+
+ Additional dynamic real covariates can be concatenated to this tensor, with the caveat that these
+ features must but known at prediction time.
+
+ The `num_features` here is equal to `config.`num_time_features` + `config.num_dynamic_real_features`.
+ past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length)` or `(batch_size, sequence_length, input_size)`, *optional*):
+ Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected
+ in `[0, 1]`:
+
+ - 1 for values that are **observed**,
+ - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros).
+
+ static_categorical_features (`torch.LongTensor` of shape `(batch_size, number of static categorical features)`, *optional*):
+ Optional static categorical features for which the model will learn an embedding, which it will add to
+ the values of the time series.
+
+ Static categorical features are features which have the same value for all time steps (static over
+ time).
+
+ A typical example of a static categorical feature is a time series ID.
+ static_real_features (`torch.FloatTensor` of shape `(batch_size, number of static real features)`, *optional*):
+ Optional static real features which the model will add to the values of the time series.
+
+ Static real features are features which have the same value for all time steps (static over time).
+
+ A typical example of a static real feature is promotion information.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers.
+
+ Return:
+ [`SampleTSPredictionOutput`] where the outputs `sequences` tensor will have shape `(batch_size, number of
+ samples, prediction_length)` or `(batch_size, number of samples, prediction_length, input_size)` for
+ multivariate predictions.
+ """
+ outputs = self(
+ static_categorical_features=static_categorical_features,
+ static_real_features=static_real_features,
+ past_time_features=past_time_features,
+ past_values=past_values,
+ past_observed_mask=past_observed_mask,
+ future_time_features=future_time_features,
+ future_values=None,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ use_cache=True,
+ )
+
+ decoder = self.model.get_decoder()
+ enc_last_hidden = outputs.encoder_last_hidden_state
+ loc = outputs.loc
+ scale = outputs.scale
+ static_feat = outputs.static_features
+
+ num_parallel_samples = self.config.num_parallel_samples
+ repeated_loc = loc.repeat_interleave(repeats=num_parallel_samples, dim=0)
+ repeated_scale = scale.repeat_interleave(repeats=num_parallel_samples, dim=0)
+
+ repeated_past_values = (
+ past_values.repeat_interleave(repeats=num_parallel_samples, dim=0) - repeated_loc
+ ) / repeated_scale
+
+ expanded_static_feat = static_feat.unsqueeze(1).expand(-1, future_time_features.shape[1], -1)
+ features = torch.cat((expanded_static_feat, future_time_features), dim=-1)
+ repeated_features = features.repeat_interleave(repeats=num_parallel_samples, dim=0)
+
+ repeated_enc_last_hidden = enc_last_hidden.repeat_interleave(repeats=num_parallel_samples, dim=0)
+
+ future_samples = []
+
+ # greedy decoding
+ for k in range(self.config.prediction_length):
+ lagged_sequence = self.model.get_lagged_subsequences(
+ sequence=repeated_past_values,
+ subsequences_length=1 + k,
+ shift=1,
+ )
+
+ lags_shape = lagged_sequence.shape
+ reshaped_lagged_sequence = lagged_sequence.reshape(lags_shape[0], lags_shape[1], -1)
+
+ decoder_input = torch.cat((reshaped_lagged_sequence, repeated_features[:, : k + 1]), dim=-1)
+
+ dec_output = decoder(inputs_embeds=decoder_input, encoder_hidden_states=repeated_enc_last_hidden)
+ dec_last_hidden = dec_output.last_hidden_state
+
+ params = self.parameter_projection(dec_last_hidden[:, -1:])
+ distr = self.output_distribution(params, loc=repeated_loc, scale=repeated_scale)
+ next_sample = distr.sample()
+
+ repeated_past_values = torch.cat(
+ (repeated_past_values, (next_sample - repeated_loc) / repeated_scale), dim=1
+ )
+ future_samples.append(next_sample)
+
+ concat_future_samples = torch.cat(future_samples, dim=1)
+
+ return SampleTSPredictionOutput(
+ sequences=concat_future_samples.reshape(
+ (-1, num_parallel_samples, self.config.prediction_length) + self.target_shape,
+ )
+ )
+
+
+__all__ = ["TimeSeriesTransformerForPrediction", "TimeSeriesTransformerModel", "TimeSeriesTransformerPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..12f1541b9c549256b67b3a304cc482091842e94e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_timesfm import *
+ from .modeling_timesfm import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/configuration_timesfm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/configuration_timesfm.py
new file mode 100644
index 0000000000000000000000000000000000000000..04566ab34ab090fe9bb453196b04ee83f73b411d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/configuration_timesfm.py
@@ -0,0 +1,127 @@
+# coding=utf-8
+# Copyright 2025 Google LLC and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TimesFM model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class TimesFmConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TimesFmModelForPrediction`] or a [`TFTimesFmModel`]. It is used to
+ instantiate a TimesFM model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the TimesFM
+ [google/timesfm-2.0-500m-pytorch](https://huggingface.co/google/timesfm-2.0-500m-pytorch) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Arguments:
+ patch_length (`int`, *optional*, defaults to 32):
+ The length of one patch in the input sequence.
+ context_length (`int`, *optional*, defaults to 512):
+ The length of the input context.
+ horizon_length (`int`, *optional*, defaults to 128):
+ The length of the prediction horizon.
+ freq_size (`int`, *optional*, defaults to 3):
+ The number of frequency embeddings.
+ num_hidden_layers (`int`, *optional*, defaults to 50):
+ Number of Transformer layers.
+ hidden_size (`int`, *optional*, defaults to 1280):
+ Size of the hidden layers in the feed-forward networks.
+ intermediate_size (`int`, *optional*, defaults to 1280):
+ Dimension of the MLP representations.
+ head_dim (`int`, *optional*, defaults to 80):
+ Size of the key, query, value projections per attention head. The `inner_dim` of the projection layer will
+ be defined as `num_attention_heads * head_dim`.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ tolerance (`float`, *optional*, defaults to 1e-06):
+ The tolerance for the quantile loss.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the RMS normalization layers.
+ quantiles (`list[float]`, *optional*, defaults to `[0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8, 0.9]`):
+ The quantiles to predict.
+ pad_val (`float`, *optional*, defaults to 1123581321.0):
+ The value used to pad the predictions.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the attention scores.
+ use_positional_embedding (`bool`, *optional*, defaults to `False`):
+ Whether to add positional embeddings.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ min_timescale (`int`, *optional*, defaults to 1):
+ The start of the geometric positional index. Determines the periodicity of
+ the added signal.
+ max_timescale (`int`, *optional*, defaults to 10000):
+ The end of the geometric positional index. Determines the frequency of the
+ added signal.
+ """
+
+ model_type = "timesfm"
+ keys_to_ignore_at_inference = []
+ is_encoder_decoder = False
+
+ def __init__(
+ self,
+ patch_length: int = 32,
+ context_length: int = 512,
+ horizon_length: int = 128,
+ freq_size: int = 3,
+ num_hidden_layers: int = 50,
+ hidden_size: int = 1280,
+ intermediate_size: int = 1280,
+ head_dim: int = 80,
+ num_attention_heads: int = 16,
+ tolerance: float = 1e-6,
+ rms_norm_eps: float = 1e-6,
+ quantiles: list[float] = [0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8, 0.9],
+ pad_val: float = 1123581321.0,
+ attention_dropout: float = 0.0,
+ use_positional_embedding: bool = False,
+ initializer_range: float = 0.02,
+ min_timescale: int = 1,
+ max_timescale: int = 10_000,
+ **kwargs,
+ ):
+ self.patch_length = patch_length
+ self.context_length = context_length
+ self.horizon_length = horizon_length
+ self.quantiles = quantiles
+ self.pad_val = pad_val
+ self.freq_size = freq_size
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.head_dim = head_dim
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.tolerance = tolerance
+ self.rms_norm_eps = rms_norm_eps
+ self.attention_dropout = attention_dropout
+ self.use_positional_embedding = use_positional_embedding
+ self.initializer_range = initializer_range
+ self.min_timescale = min_timescale
+ self.max_timescale = max_timescale
+
+ super().__init__(
+ is_encoder_decoder=self.is_encoder_decoder,
+ **kwargs,
+ )
+
+
+__all__ = ["TimesFmConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/modeling_timesfm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/modeling_timesfm.py
new file mode 100644
index 0000000000000000000000000000000000000000..dd6f352376ffe817a1112ef0a60880612f667f1c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/modeling_timesfm.py
@@ -0,0 +1,845 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/timesfm/modular_timesfm.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_timesfm.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 Google LLC and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import math
+from collections.abc import Sequence
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ...integrations import use_kernel_forward_from_hub
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, auto_docstring, can_return_tuple, logging
+from .configuration_timesfm import TimesFmConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring
+class TimesFmOutput(BaseModelOutput):
+ r"""
+ loc (`torch.Tensor` of shape `(batch_size, )`):
+ The mean of the time series inputs.
+ scale (`torch.Tensor` of shape `(batch_size,)`):
+ The scale of the time series inputs.
+ """
+
+ loc: Optional[torch.Tensor] = None
+ scale: Optional[torch.Tensor] = None
+
+
+@dataclass
+@auto_docstring
+class TimesFmOutputForPrediction(BaseModelOutput):
+ r"""
+ mean_predictions (`torch.Tensor` of shape `(batch_size, sequence_length)`):
+ The mean predictions of the time series.
+ full_predictions (`torch.Tensor` of shape `(batch_size, sequence_length)`):
+ The full predictions of the time series including the mean and the quantiles.
+ loss (`torch.Tensor` of shape `(1,)`, *optional*, returned when `future_values` is provided):
+ The loss of the TimesFM model.
+ """
+
+ mean_predictions: Optional[torch.Tensor] = None
+ full_predictions: Optional[torch.Tensor] = None
+ loss: Optional[Union[torch.Tensor, float]] = None
+
+
+class TimesFmMLP(nn.Module):
+ """Pax MLP in pytorch."""
+
+ def __init__(self, config: TimesFmConfig):
+ super().__init__()
+ hidden_size = config.hidden_size
+ intermediate_size = config.intermediate_size
+
+ self.gate_proj = nn.Linear(hidden_size, intermediate_size)
+ self.down_proj = nn.Linear(intermediate_size, hidden_size)
+ self.layer_norm = nn.LayerNorm(normalized_shape=hidden_size, eps=1e-6)
+
+ def forward(self, x, paddings=None):
+ gate_inp = self.layer_norm(x)
+ gate = self.gate_proj(gate_inp)
+ gate = F.relu(gate)
+ outputs = self.down_proj(gate)
+ if paddings is not None:
+ outputs = outputs * (1.0 - paddings[:, :, None])
+ return outputs + x
+
+
+class TimesFmResidualBlock(nn.Module):
+ """TimesFM residual block."""
+
+ def __init__(self, input_dims, hidden_dims, output_dims):
+ super().__init__()
+ self.input_dims = input_dims
+ self.hidden_dims = hidden_dims
+ self.output_dims = output_dims
+
+ self.input_layer = nn.Linear(input_dims, hidden_dims)
+ self.activation = nn.SiLU()
+ self.output_layer = nn.Linear(hidden_dims, output_dims)
+ self.residual_layer = nn.Linear(input_dims, output_dims)
+
+ def forward(self, x):
+ hidden = self.input_layer(x)
+ hidden = self.activation(hidden)
+ output = self.output_layer(hidden)
+ residual = self.residual_layer(x)
+ return output + residual
+
+
+@use_kernel_forward_from_hub("RMSNorm")
+class TimesFmRMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ TimesFmRMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+class TimesFmPositionalEmbedding(nn.Module):
+ """Generates position embedding for a given 1-d sequence."""
+
+ def __init__(self, config: TimesFmConfig):
+ super().__init__()
+ min_timescale = config.min_timescale
+ max_timescale = config.max_timescale
+ self.embedding_dims = config.hidden_size
+
+ num_timescales = self.embedding_dims // 2
+ log_timescale_increment = math.log(float(max_timescale) / float(min_timescale)) / max(num_timescales - 1, 1)
+ self.register_buffer(
+ "inv_timescales",
+ min_timescale * torch.exp(torch.arange(num_timescales, dtype=torch.float32) * -log_timescale_increment),
+ )
+
+ def forward(self, seq_length=None, position=None):
+ """Generates a Tensor of sinusoids with different frequencies.
+
+ Args:
+ seq_length: an optional Python int defining the output sequence length.
+ if the `position` argument is specified.
+ position: [B, seq_length], optional position for each token in the
+ sequence, only required when the sequence is packed.
+
+ Returns:
+ [B, seqlen, D] if `position` is specified, else [1, seqlen, D]
+ """
+ if position is None and seq_length is None:
+ raise ValueError("Either position or seq_length must be provided")
+
+ if position is None:
+ # [1, seqlen]
+ position = torch.arange(seq_length, dtype=torch.float32, device=self.inv_timescales.device).unsqueeze(0)
+ elif position.ndim != 2:
+ raise ValueError(f"position must be 2-dimensional, got shape {position.shape}")
+
+ scaled_time = position.view(*position.shape, 1) * self.inv_timescales.view(1, 1, -1)
+ signal = torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], dim=2)
+
+ # Padding to ensure correct embedding dimension
+ signal = F.pad(signal, (0, 0, 0, self.embedding_dims % 2))
+ return signal
+
+
+def simple_eager_attention_forward(
+ module: nn.Module,
+ query_states: torch.Tensor,
+ key_states: torch.Tensor,
+ value_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs: Unpack[TransformersKwargs],
+):
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query_states.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class TimesFmAttention(nn.Module):
+ """Implements the attention used in TimesFM. One key difference is that there is _per_dim_scaling of the query."""
+
+ def __init__(self, config: TimesFmConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.is_causal = True
+ self.attention_dropout = config.attention_dropout
+ self.layer_idx = layer_idx
+
+ self.num_heads = config.num_attention_heads
+ self.hidden_size = config.hidden_size
+ self.head_dim = config.head_dim
+
+ self.q_size = self.num_heads * self.head_dim
+ self.kv_size = self.num_heads * self.head_dim
+ self.scaling = nn.Parameter(torch.empty((self.head_dim,)))
+
+ self.q_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim)
+ self.k_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim)
+ self.v_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim)
+ self.o_proj = nn.Linear(self.num_heads * self.head_dim, self.hidden_size)
+
+ def _scale_query(self, query: torch.Tensor) -> torch.Tensor:
+ scale = F.softplus(self.scaling).mul(1.442695041 / math.sqrt(self.head_dim))
+ return query * scale[None, None, None, :]
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ query_states = self._scale_query(query_states)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ attention_interface: Callable = simple_eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=1.0,
+ **kwargs,
+ )
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class TimesFmDecoderLayer(nn.Module):
+ """Transformer layer."""
+
+ def __init__(self, config: TimesFmConfig, layer_idx: int):
+ super().__init__()
+
+ self.self_attn = TimesFmAttention(config, layer_idx=layer_idx)
+ self.mlp = TimesFmMLP(config)
+ self.input_layernorm = TimesFmRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ paddings: torch.Tensor,
+ output_attentions: bool = False,
+ ) -> tuple[Optional[torch.Tensor], torch.Tensor]:
+ # Self Attention
+ residual = hidden_states
+ hidden_states = self.input_layernorm(hidden_states)
+ hidden_states, scores = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ # MLP
+ hidden_states = self.mlp(hidden_states, paddings=paddings)
+
+ return scores, hidden_states
+
+
+@auto_docstring
+class TimesFmPreTrainedModel(PreTrainedModel):
+ config: TimesFmConfig
+ base_model_prefix = "timesfm"
+ _no_split_modules = ["TimesFmDecoderLayer"]
+ main_input_name = "past_values"
+ _supports_sdpa = True
+
+ def _init_weights(self, module):
+ super()._init_weights(module)
+ if isinstance(module, TimesFmAttention):
+ # Initialize scaling parameter
+ nn.init.ones_(module.scaling)
+
+
+@auto_docstring
+class TimesFmModel(TimesFmPreTrainedModel):
+ def __init__(self, config: TimesFmConfig):
+ super().__init__(config)
+
+ self.config = config
+ self.input_ff_layer = TimesFmResidualBlock(
+ input_dims=2 * config.patch_length,
+ output_dims=config.hidden_size,
+ hidden_dims=config.intermediate_size,
+ )
+ self.freq_emb = nn.Embedding(num_embeddings=config.freq_size, embedding_dim=config.hidden_size)
+ self.layers = nn.ModuleList(
+ [TimesFmDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ if self.config.use_positional_embedding:
+ self.position_emb = TimesFmPositionalEmbedding(config=config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _forward_transform(
+ self, inputs: torch.Tensor, patched_pads: torch.Tensor
+ ) -> tuple[torch.Tensor, tuple[torch.Tensor, torch.Tensor]]:
+ """Input is of shape [B, N, P]."""
+ mu, sigma = self._timesfm_masked_mean_std(inputs, patched_pads)
+ sigma = torch.where(
+ sigma < self.config.tolerance,
+ torch.tensor(1.0, dtype=sigma.dtype, device=sigma.device),
+ sigma,
+ )
+
+ # Normalize each patch
+ outputs = (inputs - mu[:, None, None]) / sigma[:, None, None]
+ outputs = torch.where(
+ torch.abs(inputs - self.config.pad_val) < self.config.tolerance,
+ torch.tensor(self.config.pad_val, dtype=outputs.dtype, device=outputs.device),
+ outputs,
+ )
+ return outputs, (mu, sigma)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ past_values: torch.Tensor,
+ past_values_padding: torch.LongTensor,
+ freq: torch.Tensor,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ ) -> TimesFmOutput:
+ r"""
+ past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Past values of the time series that serves as input to the model.
+ past_values_padding (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ The padding indicator of the time series.
+ freq (`torch.LongTensor` of shape `(batch_size,)`):
+ Frequency indices for the time series data.
+ """
+ # Reshape into patches (using view for efficiency)
+ bsize = past_values.shape[0]
+ patched_inputs = past_values.view(bsize, -1, self.config.patch_length)
+ patched_pads = past_values_padding.view(bsize, -1, self.config.patch_length)
+
+ patched_inputs = torch.where(
+ torch.abs(patched_pads - 1.0) < self.config.tolerance,
+ torch.tensor(0.0, dtype=patched_inputs.dtype, device=patched_inputs.device),
+ patched_inputs,
+ )
+ patched_pads = torch.where(
+ torch.abs(patched_inputs - self.config.pad_val) < self.config.tolerance,
+ torch.tensor(1.0, dtype=patched_pads.dtype, device=patched_pads.device),
+ patched_pads,
+ )
+ patched_inputs, stats = self._forward_transform(patched_inputs, patched_pads)
+
+ # B x N x D
+ patched_inputs = patched_inputs * (1.0 - patched_pads)
+ concat_inputs = torch.cat([patched_inputs, patched_pads], dim=-1)
+ model_input = self.input_ff_layer(concat_inputs)
+
+ # A patch should not be padded even if there is at least one zero.
+ patched_padding = torch.min(patched_pads, dim=-1)[0] # Get the values from the min result
+ if self.config.use_positional_embedding:
+ pos_emb = self.position_emb(model_input.shape[1])
+ pos_emb = torch.concat([pos_emb] * model_input.shape[0], dim=0)
+ pos_emb = self._timesfm_shift_padded_seq(patched_padding, pos_emb)
+ model_input += pos_emb
+
+ f_emb = self.freq_emb(freq) # B x 1 x D
+ model_input += f_emb
+
+ # Convert paddings to attention mask and combine with causal mask
+ hidden_states = model_input
+ attention_mask = self._prepare_4d_attention_mask(
+ attention_mask=patched_padding,
+ sequence_length=hidden_states.shape[1],
+ dtype=hidden_states.dtype,
+ device=hidden_states.device,
+ is_causal=True,
+ )
+
+ all_attentions = []
+ all_hidden_states = []
+
+ for layer in self.layers[: self.config.num_hidden_layers]:
+ scores, hidden_states = layer(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ paddings=patched_padding,
+ output_attentions=output_attentions,
+ )
+ if output_attentions:
+ all_attentions.append(scores)
+ if output_hidden_states:
+ all_hidden_states.append(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = [model_input] + all_hidden_states
+ else:
+ all_hidden_states = None
+
+ return TimesFmOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions if output_attentions else None,
+ loc=stats[0],
+ scale=stats[1],
+ )
+
+ @staticmethod
+ def _prepare_4d_attention_mask(
+ attention_mask: Optional[torch.Tensor],
+ sequence_length: int,
+ dtype: torch.dtype,
+ device: torch.device,
+ is_causal: bool = True,
+ ) -> Optional[torch.Tensor]:
+ """
+ Creates 4D attention mask and combines causal and padding masks if needed.
+
+ Args:
+ attention_mask: Optional tensor of shape (batch_size, seq_length) containing padding mask
+ sequence_length: Length of the sequence
+ dtype: Data type of the mask
+ device: Device of the mask
+ is_causal: Whether to apply causal masking
+
+ Returns:
+ 4D attention mask of shape (batch_size, 1, seq_length, seq_length)
+ """
+ # Get minimum value for the dtype
+ min_value = torch.finfo(dtype).min if dtype.is_floating_point else torch.iinfo(dtype).min
+
+ # Handle padding mask
+ if attention_mask is not None:
+ # Convert 2D padding mask to 4D attention mask
+ attention_mask = attention_mask.view(attention_mask.shape[0], 1, 1, -1)
+ attention_mask = attention_mask * min_value
+
+ # Create causal mask if needed
+ if is_causal:
+ causal_mask = torch.triu(
+ torch.ones((sequence_length, sequence_length), dtype=dtype, device=device) * min_value,
+ diagonal=1,
+ )
+ causal_mask = causal_mask.view(1, 1, sequence_length, sequence_length)
+
+ # Combine with padding mask if it exists
+ if attention_mask is not None:
+ attention_mask = torch.minimum(attention_mask, causal_mask)
+ else:
+ attention_mask = causal_mask
+
+ return attention_mask
+
+ @staticmethod
+ def _timesfm_masked_mean_std(inputs: torch.Tensor, padding: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
+ """Calculates mean and standard deviation of `inputs` across axis 1.
+
+ It excludes values where `padding` is 1.
+
+ Args:
+ inputs: A PyTorch tensor of shape [b, n, p].
+ padding: A PyTorch tensor of shape [b, n, p] with values 0 or 1.
+
+ Returns:
+ A tuple containing the mean and standard deviation.
+ We return the statistics of the first patch with more than three non-padded values.
+ """
+
+ # Selecting the first patch with more than 3 unpadded values.
+ def _get_patch_index(arr: torch.Tensor):
+ indices = torch.argmax((arr >= 3).to(torch.int32), dim=1)
+ row_sum = (arr >= 3).to(torch.int32).sum(dim=1)
+ return torch.where(row_sum == 0, arr.shape[1] - 1, indices)
+
+ pad_sum = torch.sum(1 - padding, dim=2)
+ patch_indices = _get_patch_index(pad_sum)
+ bidxs = torch.arange(inputs.shape[0])
+
+ arr = inputs[bidxs, patch_indices, :]
+ pad = padding[bidxs, patch_indices, :]
+
+ # Create a mask where padding is 0
+ mask = 1 - pad
+
+ # Calculate the number of valid elements
+ num_valid_elements = torch.sum(mask, dim=1)
+ num_valid_elements = torch.where(
+ num_valid_elements == 0,
+ torch.tensor(1, dtype=num_valid_elements.dtype, device=num_valid_elements.device),
+ num_valid_elements,
+ )
+
+ # Calculate the masked sum and squared sum
+ masked_sum = torch.sum(arr * mask, dim=1)
+ masked_squared_sum = torch.sum((arr * mask) ** 2, dim=1)
+
+ # Calculate the masked mean and standard deviation
+ masked_mean = masked_sum / num_valid_elements
+ masked_var = masked_squared_sum / num_valid_elements - masked_mean**2
+ masked_var = torch.where(
+ masked_var < 0.0,
+ torch.tensor(0.0, dtype=masked_var.dtype, device=masked_var.device),
+ masked_var,
+ )
+ masked_std = torch.sqrt(masked_var)
+
+ return masked_mean, masked_std
+
+ @staticmethod
+ def _timesfm_shift_padded_seq(mask: torch.Tensor, seq: torch.Tensor) -> torch.Tensor:
+ """Shifts rows of seq based on the first 0 in each row of the mask.
+
+ Args:
+ mask: mask tensor of shape [B, N]
+ seq: seq tensor of shape [B, N, P]
+
+ Returns:
+ The shifted sequence.
+ """
+ batch_size, num_seq, feature_dim = seq.shape
+
+ new_mask: torch.BoolTensor = mask == 0
+
+ # Use argmax to find the first True value in each row
+ indices = new_mask.to(torch.int32).argmax(dim=1)
+
+ # Handle rows with all zeros
+ indices[~new_mask.any(dim=1)] = -1
+
+ # Create index ranges for each sequence in the batch
+ idx_range = torch.arange(num_seq, device=seq.device).view(1, -1, 1).expand(batch_size, -1, feature_dim)
+
+ # Calculate shifted indices for each element in each sequence
+ shifted_idx = (idx_range - indices[:, None, None]) % num_seq
+
+ # Gather values from seq using shifted indices
+ shifted_seq = seq.gather(1, shifted_idx)
+
+ return shifted_seq
+
+
+class TimesFmModelForPrediction(TimesFmPreTrainedModel):
+ """TimesFM model for quantile and mean prediction."""
+
+ def __init__(self, config: TimesFmConfig):
+ super().__init__(config)
+
+ self.config = config
+ self.context_len = config.context_length
+ self.horizon_len = config.horizon_length
+
+ self.decoder = TimesFmModel(config)
+
+ # quantile and mean output
+ self.horizon_ff_layer = TimesFmResidualBlock(
+ input_dims=config.hidden_size,
+ output_dims=config.horizon_length * (1 + len(config.quantiles)),
+ hidden_dims=config.intermediate_size,
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _preprocess(
+ self, inputs: Sequence[torch.Tensor], freq: Sequence[int]
+ ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
+ """Formats and pads raw inputs to feed into the model.
+
+ This function both pads each time series to match the context length, and
+ pads the inputs to meet the SPMD shape requirement.
+
+ Args:
+ inputs: A list of 1d Tensors. Each Tensor is the context time series of
+ a single forecast task.
+ freq: list of frequencies
+
+ Returns:
+ A tuple of:
+ - the padded input time series to meet the model required context.
+ - the padding indicator.
+ - the number of padded examples for SPMD so that each core has the same
+ number (a multiple of `batch_size`) of examples.
+ """
+ input_ts, input_padding, inp_freq = [], [], []
+
+ for i, ts in enumerate(inputs):
+ input_len = ts.shape[0]
+ padding = torch.zeros(input_len + self.horizon_len, dtype=ts.dtype, device=ts.device)
+ if input_len < self.context_len:
+ num_front_pad = self.context_len - input_len
+ ts = torch.cat([torch.zeros(num_front_pad, dtype=ts.dtype, device=ts.device), ts], dim=0)
+ padding = torch.cat([torch.ones(num_front_pad, dtype=ts.dtype, device=padding.device), padding], dim=0)
+ elif input_len > self.context_len:
+ ts = ts[-self.context_len :]
+ padding = padding[-(self.context_len + self.horizon_len) :]
+
+ input_ts.append(ts)
+ input_padding.append(padding)
+ inp_freq.append(freq[i])
+
+ return (
+ torch.stack(input_ts, dim=0),
+ torch.stack(input_padding, dim=0),
+ torch.tensor(inp_freq, dtype=torch.int32).reshape(-1, 1),
+ )
+
+ def _postprocess_output(
+ self, model_output: torch.Tensor, stats: tuple[torch.Tensor, torch.Tensor]
+ ) -> torch.Tensor:
+ """Postprocess output of stacked transformer."""
+
+ # B x N x (H.Q)
+ output_ts = self.horizon_ff_layer(model_output)
+
+ # Reshape using view
+ b, n, _ = output_ts.shape
+ output_ts = output_ts.view(b, n, self.config.horizon_length, len(self.config.quantiles) + 1)
+
+ mu, sigma = stats
+ return output_ts * sigma[:, None, None, None] + mu[:, None, None, None]
+
+ def _quantile_loss(self, predictions: torch.Tensor, targets: torch.Tensor) -> torch.Tensor:
+ losses = []
+ for i, q in enumerate(self.config.quantiles):
+ errors = targets - predictions[..., i]
+ loss = torch.max((q - 1) * errors, q * errors)
+ losses.append(loss.mean())
+ return torch.stack(losses).mean()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ past_values: Sequence[torch.Tensor],
+ freq: Optional[Sequence[Union[torch.Tensor, int]]] = None,
+ window_size: Optional[int] = None,
+ future_values: Optional[torch.Tensor] = None,
+ forecast_context_len: Optional[int] = None,
+ return_forecast_on_context: bool = False,
+ truncate_negative: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> TimesFmOutputForPrediction:
+ r"""
+ past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Past values of the time series that serves as input to the model.
+ freq (`torch.LongTensor` of shape `(batch_size,)`):
+ Frequency indices for the time series data.
+ window_size (`int`, *optional*):
+ Window size of trend + residual decomposition. If None then we do not do decomposition.
+ future_values (`torch.Tensor`, *optional*):
+ Optional future time series values to be used for loss computation.
+ forecast_context_len (`int`, *optional*):
+ Optional max context length.
+ return_forecast_on_context (`bool`, *optional*):
+ True to return the forecast on the context when available, i.e. after the first input patch.
+ truncate_negative (`bool`, *optional*):
+ Truncate to only non-negative values if any of the contexts have non-negative values,
+ otherwise do nothing.
+ output_attentions (`bool`, *optional*):
+ Whether to output the attentions.
+ output_hidden_states (`bool`, *optional*):
+ Whether to output the hidden states.
+
+ Example:
+
+ ```python
+ >>> from transformers import TimesFmModelForPrediction
+
+ >>> model = TimesFmModelForPrediction.from_pretrained("google/timesfm-2.0-500m-pytorch")
+
+ >>> forecast_input = [torch.linspace(0, 20, 100).sin(), torch.linspace(0, 20, 200).sin(), torch.linspace(0, 20, 400).sin()]
+ >>> frequency_input = torch.tensor([0, 1, 2], dtype=torch.long)
+
+ >>> # Generate
+ >>> with torch.no_grad():
+ >>> outputs = model(past_values=forecast_input, freq=frequency_input, return_dict=True)
+ >>> point_forecast_conv = outputs.mean_predictions
+ >>> quantile_forecast_conv = outputs.full_predictions
+ ```
+ """
+ if forecast_context_len is None:
+ fcontext_len = self.context_len
+ else:
+ fcontext_len = forecast_context_len
+
+ # Get device from first input tensor
+ device = past_values[0].device
+
+ # Truncate inputs to forecast_context_len
+ inputs = [ts[-fcontext_len:] for ts in past_values]
+ inp_min = torch.min(torch.stack([torch.min(ts) for ts in inputs]))
+
+ if window_size is not None:
+ new_inputs = []
+ new_freqs = []
+ for i, ts in enumerate(inputs):
+ new_inputs.extend(self._timesfm_moving_average(ts, window_size))
+ if freq is not None:
+ new_freqs.extend([freq[i]] * 2)
+ inputs = new_inputs
+ if freq is not None:
+ freq = new_freqs
+
+ if freq is None:
+ logger.info("No frequency provided via `freq`. Default to high (0).")
+ freq = [0] * len(inputs)
+
+ if output_attentions is None:
+ output_attentions = self.config.output_attentions
+ if output_hidden_states is None:
+ output_hidden_states = self.config.output_hidden_states
+
+ input_ts, input_padding, inp_freq = self._preprocess(inputs, freq)
+ # Move tensors to the same device as input
+ input_ts = input_ts.to(device)
+ input_padding = input_padding.to(device)
+ inp_freq = inp_freq.to(device)
+
+ final_out = input_ts
+ context_len = final_out.shape[1]
+ full_outputs = []
+
+ if input_padding.shape[1] != final_out.shape[1] + self.horizon_len:
+ raise ValueError(
+ "Length of paddings must match length of input + horizon_len:"
+ f" {input_padding.shape[1]} != {final_out.shape[1]} + {self.horizon_len}"
+ )
+ output_patch_len = self.config.horizon_length
+
+ num_decode_patches = (self.horizon_len + output_patch_len - 1) // output_patch_len
+ for step_index in range(num_decode_patches):
+ current_padding = input_padding[:, 0 : final_out.shape[1]]
+ input_ts = final_out[:, -fcontext_len:]
+ input_padding = current_padding[:, -fcontext_len:]
+ decoder_output = self.decoder(
+ past_values=input_ts,
+ past_values_padding=input_padding,
+ freq=inp_freq,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+ fprop_outputs = self._postprocess_output(
+ decoder_output.last_hidden_state,
+ (decoder_output.loc, decoder_output.scale),
+ )
+
+ if return_forecast_on_context and step_index == 0:
+ # For the first decodings step, collect the model forecast on the
+ # context except the unavailable first input batch forecast.
+ new_full_ts = fprop_outputs[:, :-1, : self.config.patch_length, :]
+ # We have to use reshape and not view for non-contiguous memory
+ new_full_ts = new_full_ts.reshape(new_full_ts.size(0), -1, new_full_ts.size(3))
+
+ full_outputs.append(new_full_ts)
+
+ # (full batch, last patch, output_patch_len, index of mean forecast = 0)
+ new_ts = fprop_outputs[:, -1, :output_patch_len, 0]
+ new_full_ts = fprop_outputs[:, -1, :output_patch_len, :]
+ # (full batch, last patch, output_patch_len, all output indices)
+ full_outputs.append(new_full_ts)
+ final_out = torch.concatenate([final_out, new_ts], axis=-1)
+
+ if return_forecast_on_context:
+ # `full_outputs` indexing starts at after the first input patch.
+ full_outputs = torch.concatenate(full_outputs, axis=1)[
+ :, : (context_len - self.config.patch_length + self.horizon_len), :
+ ]
+ else:
+ # `full_outputs` indexing starts at the forecast horizon.
+ full_outputs = torch.concatenate(full_outputs, axis=1)[:, 0 : self.horizon_len, :]
+
+ mean_outputs = full_outputs[:, :, 0]
+ if window_size is not None:
+ mean_outputs = mean_outputs[0::2, ...] + mean_outputs[1::2, ...]
+ full_outputs = full_outputs[0::2, ...] + full_outputs[1::2, ...]
+ if inp_min >= 0 and truncate_negative:
+ mean_outputs = torch.maximum(mean_outputs, 0.0)
+ full_outputs = torch.maximum(full_outputs, 0.0)
+
+ loss = None
+ if future_values is not None:
+ mse_loss = F.mse_loss(mean_outputs, future_values)
+ quantile_loss = self._quantile_loss(full_outputs[:, :, 1:], future_values)
+ loss = mse_loss + quantile_loss
+
+ return TimesFmOutputForPrediction(
+ last_hidden_state=decoder_output.last_hidden_state,
+ attentions=decoder_output.attentions if output_attentions else None,
+ hidden_states=decoder_output.hidden_states if output_hidden_states else None,
+ mean_predictions=mean_outputs,
+ full_predictions=full_outputs,
+ loss=loss,
+ )
+
+ @staticmethod
+ def _timesfm_moving_average(arr: torch.Tensor, window_size: int) -> list[torch.Tensor]:
+ """Calculates the moving average using PyTorch's convolution function."""
+ # Pad with zeros to handle initial window positions
+ arr_padded = F.pad(arr, (window_size - 1, 0), "constant", 0)
+ # Create a convolution kernel
+ kernel = torch.ones(window_size, dtype=arr.dtype, device=arr.device) / window_size
+ # Apply convolution to calculate the moving average
+ smoothed_arr = F.conv1d(arr_padded.view(1, 1, -1), kernel.view(1, 1, -1)).squeeze()
+ return [smoothed_arr, arr - smoothed_arr]
+
+
+__all__ = ["TimesFmModelForPrediction", "TimesFmPreTrainedModel", "TimesFmModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/modular_timesfm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/modular_timesfm.py
new file mode 100644
index 0000000000000000000000000000000000000000..b82816e7c737364bd1d5d256d6d37174a9d9965e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesfm/modular_timesfm.py
@@ -0,0 +1,801 @@
+# coding=utf-8
+# Copyright 2025 Google LLC and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch TimesFM model."""
+
+import math
+from collections.abc import Sequence
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import auto_docstring, can_return_tuple, logging
+from ..llama.modeling_llama import LlamaRMSNorm
+from ..phi4_multimodal.modeling_phi4_multimodal import simple_eager_attention_forward
+from .configuration_timesfm import TimesFmConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring
+class TimesFmOutput(BaseModelOutput):
+ r"""
+ loc (`torch.Tensor` of shape `(batch_size, )`):
+ The mean of the time series inputs.
+ scale (`torch.Tensor` of shape `(batch_size,)`):
+ The scale of the time series inputs.
+ """
+
+ loc: Optional[torch.Tensor] = None
+ scale: Optional[torch.Tensor] = None
+
+
+@dataclass
+@auto_docstring
+class TimesFmOutputForPrediction(BaseModelOutput):
+ r"""
+ mean_predictions (`torch.Tensor` of shape `(batch_size, sequence_length)`):
+ The mean predictions of the time series.
+ full_predictions (`torch.Tensor` of shape `(batch_size, sequence_length)`):
+ The full predictions of the time series including the mean and the quantiles.
+ loss (`torch.Tensor` of shape `(1,)`, *optional*, returned when `future_values` is provided):
+ The loss of the TimesFM model.
+ """
+
+ mean_predictions: Optional[torch.Tensor] = None
+ full_predictions: Optional[torch.Tensor] = None
+ loss: Optional[Union[torch.Tensor, float]] = None
+
+
+class TimesFmMLP(nn.Module):
+ """Pax MLP in pytorch."""
+
+ def __init__(self, config: TimesFmConfig):
+ super().__init__()
+ hidden_size = config.hidden_size
+ intermediate_size = config.intermediate_size
+
+ self.gate_proj = nn.Linear(hidden_size, intermediate_size)
+ self.down_proj = nn.Linear(intermediate_size, hidden_size)
+ self.layer_norm = nn.LayerNorm(normalized_shape=hidden_size, eps=1e-6)
+
+ def forward(self, x, paddings=None):
+ gate_inp = self.layer_norm(x)
+ gate = self.gate_proj(gate_inp)
+ gate = F.relu(gate)
+ outputs = self.down_proj(gate)
+ if paddings is not None:
+ outputs = outputs * (1.0 - paddings[:, :, None])
+ return outputs + x
+
+
+class TimesFmResidualBlock(nn.Module):
+ """TimesFM residual block."""
+
+ def __init__(self, input_dims, hidden_dims, output_dims):
+ super().__init__()
+ self.input_dims = input_dims
+ self.hidden_dims = hidden_dims
+ self.output_dims = output_dims
+
+ self.input_layer = nn.Linear(input_dims, hidden_dims)
+ self.activation = nn.SiLU()
+ self.output_layer = nn.Linear(hidden_dims, output_dims)
+ self.residual_layer = nn.Linear(input_dims, output_dims)
+
+ def forward(self, x):
+ hidden = self.input_layer(x)
+ hidden = self.activation(hidden)
+ output = self.output_layer(hidden)
+ residual = self.residual_layer(x)
+ return output + residual
+
+
+class TimesFmRMSNorm(LlamaRMSNorm):
+ pass
+
+
+class TimesFmPositionalEmbedding(nn.Module):
+ """Generates position embedding for a given 1-d sequence."""
+
+ def __init__(self, config: TimesFmConfig):
+ super().__init__()
+ min_timescale = config.min_timescale
+ max_timescale = config.max_timescale
+ self.embedding_dims = config.hidden_size
+
+ num_timescales = self.embedding_dims // 2
+ log_timescale_increment = math.log(float(max_timescale) / float(min_timescale)) / max(num_timescales - 1, 1)
+ self.register_buffer(
+ "inv_timescales",
+ min_timescale * torch.exp(torch.arange(num_timescales, dtype=torch.float32) * -log_timescale_increment),
+ )
+
+ def forward(self, seq_length=None, position=None):
+ """Generates a Tensor of sinusoids with different frequencies.
+
+ Args:
+ seq_length: an optional Python int defining the output sequence length.
+ if the `position` argument is specified.
+ position: [B, seq_length], optional position for each token in the
+ sequence, only required when the sequence is packed.
+
+ Returns:
+ [B, seqlen, D] if `position` is specified, else [1, seqlen, D]
+ """
+ if position is None and seq_length is None:
+ raise ValueError("Either position or seq_length must be provided")
+
+ if position is None:
+ # [1, seqlen]
+ position = torch.arange(seq_length, dtype=torch.float32, device=self.inv_timescales.device).unsqueeze(0)
+ elif position.ndim != 2:
+ raise ValueError(f"position must be 2-dimensional, got shape {position.shape}")
+
+ scaled_time = position.view(*position.shape, 1) * self.inv_timescales.view(1, 1, -1)
+ signal = torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], dim=2)
+
+ # Padding to ensure correct embedding dimension
+ signal = F.pad(signal, (0, 0, 0, self.embedding_dims % 2))
+ return signal
+
+
+class TimesFmAttention(nn.Module):
+ """Implements the attention used in TimesFM. One key difference is that there is _per_dim_scaling of the query."""
+
+ def __init__(self, config: TimesFmConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.is_causal = True
+ self.attention_dropout = config.attention_dropout
+ self.layer_idx = layer_idx
+
+ self.num_heads = config.num_attention_heads
+ self.hidden_size = config.hidden_size
+ self.head_dim = config.head_dim
+
+ self.q_size = self.num_heads * self.head_dim
+ self.kv_size = self.num_heads * self.head_dim
+ self.scaling = nn.Parameter(torch.empty((self.head_dim,)))
+
+ self.q_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim)
+ self.k_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim)
+ self.v_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim)
+ self.o_proj = nn.Linear(self.num_heads * self.head_dim, self.hidden_size)
+
+ def _scale_query(self, query: torch.Tensor) -> torch.Tensor:
+ scale = F.softplus(self.scaling).mul(1.442695041 / math.sqrt(self.head_dim))
+ return query * scale[None, None, None, :]
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ query_states = self._scale_query(query_states)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ attention_interface: Callable = simple_eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=1.0,
+ **kwargs,
+ )
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class TimesFmDecoderLayer(nn.Module):
+ """Transformer layer."""
+
+ def __init__(self, config: TimesFmConfig, layer_idx: int):
+ super().__init__()
+
+ self.self_attn = TimesFmAttention(config, layer_idx=layer_idx)
+ self.mlp = TimesFmMLP(config)
+ self.input_layernorm = TimesFmRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ paddings: torch.Tensor,
+ output_attentions: bool = False,
+ ) -> tuple[Optional[torch.Tensor], torch.Tensor]:
+ # Self Attention
+ residual = hidden_states
+ hidden_states = self.input_layernorm(hidden_states)
+ hidden_states, scores = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ # MLP
+ hidden_states = self.mlp(hidden_states, paddings=paddings)
+
+ return scores, hidden_states
+
+
+@auto_docstring
+class TimesFmPreTrainedModel(PreTrainedModel):
+ config: TimesFmConfig
+ base_model_prefix = "timesfm"
+ _no_split_modules = ["TimesFmDecoderLayer"]
+ main_input_name = "past_values"
+ _supports_sdpa = True
+
+ def _init_weights(self, module):
+ super()._init_weights(module)
+ if isinstance(module, TimesFmAttention):
+ # Initialize scaling parameter
+ nn.init.ones_(module.scaling)
+
+
+@auto_docstring
+class TimesFmModel(TimesFmPreTrainedModel):
+ def __init__(self, config: TimesFmConfig):
+ super().__init__(config)
+
+ self.config = config
+ self.input_ff_layer = TimesFmResidualBlock(
+ input_dims=2 * config.patch_length,
+ output_dims=config.hidden_size,
+ hidden_dims=config.intermediate_size,
+ )
+ self.freq_emb = nn.Embedding(num_embeddings=config.freq_size, embedding_dim=config.hidden_size)
+ self.layers = nn.ModuleList(
+ [TimesFmDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)]
+ )
+ if self.config.use_positional_embedding:
+ self.position_emb = TimesFmPositionalEmbedding(config=config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _forward_transform(
+ self, inputs: torch.Tensor, patched_pads: torch.Tensor
+ ) -> tuple[torch.Tensor, tuple[torch.Tensor, torch.Tensor]]:
+ """Input is of shape [B, N, P]."""
+ mu, sigma = self._timesfm_masked_mean_std(inputs, patched_pads)
+ sigma = torch.where(
+ sigma < self.config.tolerance,
+ torch.tensor(1.0, dtype=sigma.dtype, device=sigma.device),
+ sigma,
+ )
+
+ # Normalize each patch
+ outputs = (inputs - mu[:, None, None]) / sigma[:, None, None]
+ outputs = torch.where(
+ torch.abs(inputs - self.config.pad_val) < self.config.tolerance,
+ torch.tensor(self.config.pad_val, dtype=outputs.dtype, device=outputs.device),
+ outputs,
+ )
+ return outputs, (mu, sigma)
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ past_values: torch.Tensor,
+ past_values_padding: torch.LongTensor,
+ freq: torch.Tensor,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ ) -> TimesFmOutput:
+ r"""
+ past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Past values of the time series that serves as input to the model.
+ past_values_padding (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ The padding indicator of the time series.
+ freq (`torch.LongTensor` of shape `(batch_size,)`):
+ Frequency indices for the time series data.
+ """
+ # Reshape into patches (using view for efficiency)
+ bsize = past_values.shape[0]
+ patched_inputs = past_values.view(bsize, -1, self.config.patch_length)
+ patched_pads = past_values_padding.view(bsize, -1, self.config.patch_length)
+
+ patched_inputs = torch.where(
+ torch.abs(patched_pads - 1.0) < self.config.tolerance,
+ torch.tensor(0.0, dtype=patched_inputs.dtype, device=patched_inputs.device),
+ patched_inputs,
+ )
+ patched_pads = torch.where(
+ torch.abs(patched_inputs - self.config.pad_val) < self.config.tolerance,
+ torch.tensor(1.0, dtype=patched_pads.dtype, device=patched_pads.device),
+ patched_pads,
+ )
+ patched_inputs, stats = self._forward_transform(patched_inputs, patched_pads)
+
+ # B x N x D
+ patched_inputs = patched_inputs * (1.0 - patched_pads)
+ concat_inputs = torch.cat([patched_inputs, patched_pads], dim=-1)
+ model_input = self.input_ff_layer(concat_inputs)
+
+ # A patch should not be padded even if there is at least one zero.
+ patched_padding = torch.min(patched_pads, dim=-1)[0] # Get the values from the min result
+ if self.config.use_positional_embedding:
+ pos_emb = self.position_emb(model_input.shape[1])
+ pos_emb = torch.concat([pos_emb] * model_input.shape[0], dim=0)
+ pos_emb = self._timesfm_shift_padded_seq(patched_padding, pos_emb)
+ model_input += pos_emb
+
+ f_emb = self.freq_emb(freq) # B x 1 x D
+ model_input += f_emb
+
+ # Convert paddings to attention mask and combine with causal mask
+ hidden_states = model_input
+ attention_mask = self._prepare_4d_attention_mask(
+ attention_mask=patched_padding,
+ sequence_length=hidden_states.shape[1],
+ dtype=hidden_states.dtype,
+ device=hidden_states.device,
+ is_causal=True,
+ )
+
+ all_attentions = []
+ all_hidden_states = []
+
+ for layer in self.layers[: self.config.num_hidden_layers]:
+ scores, hidden_states = layer(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ paddings=patched_padding,
+ output_attentions=output_attentions,
+ )
+ if output_attentions:
+ all_attentions.append(scores)
+ if output_hidden_states:
+ all_hidden_states.append(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = [model_input] + all_hidden_states
+ else:
+ all_hidden_states = None
+
+ return TimesFmOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions if output_attentions else None,
+ loc=stats[0],
+ scale=stats[1],
+ )
+
+ @staticmethod
+ def _prepare_4d_attention_mask(
+ attention_mask: Optional[torch.Tensor],
+ sequence_length: int,
+ dtype: torch.dtype,
+ device: torch.device,
+ is_causal: bool = True,
+ ) -> Optional[torch.Tensor]:
+ """
+ Creates 4D attention mask and combines causal and padding masks if needed.
+
+ Args:
+ attention_mask: Optional tensor of shape (batch_size, seq_length) containing padding mask
+ sequence_length: Length of the sequence
+ dtype: Data type of the mask
+ device: Device of the mask
+ is_causal: Whether to apply causal masking
+
+ Returns:
+ 4D attention mask of shape (batch_size, 1, seq_length, seq_length)
+ """
+ # Get minimum value for the dtype
+ min_value = torch.finfo(dtype).min if dtype.is_floating_point else torch.iinfo(dtype).min
+
+ # Handle padding mask
+ if attention_mask is not None:
+ # Convert 2D padding mask to 4D attention mask
+ attention_mask = attention_mask.view(attention_mask.shape[0], 1, 1, -1)
+ attention_mask = attention_mask * min_value
+
+ # Create causal mask if needed
+ if is_causal:
+ causal_mask = torch.triu(
+ torch.ones((sequence_length, sequence_length), dtype=dtype, device=device) * min_value,
+ diagonal=1,
+ )
+ causal_mask = causal_mask.view(1, 1, sequence_length, sequence_length)
+
+ # Combine with padding mask if it exists
+ if attention_mask is not None:
+ attention_mask = torch.minimum(attention_mask, causal_mask)
+ else:
+ attention_mask = causal_mask
+
+ return attention_mask
+
+ @staticmethod
+ def _timesfm_masked_mean_std(inputs: torch.Tensor, padding: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
+ """Calculates mean and standard deviation of `inputs` across axis 1.
+
+ It excludes values where `padding` is 1.
+
+ Args:
+ inputs: A PyTorch tensor of shape [b, n, p].
+ padding: A PyTorch tensor of shape [b, n, p] with values 0 or 1.
+
+ Returns:
+ A tuple containing the mean and standard deviation.
+ We return the statistics of the first patch with more than three non-padded values.
+ """
+
+ # Selecting the first patch with more than 3 unpadded values.
+ def _get_patch_index(arr: torch.Tensor):
+ indices = torch.argmax((arr >= 3).to(torch.int32), dim=1)
+ row_sum = (arr >= 3).to(torch.int32).sum(dim=1)
+ return torch.where(row_sum == 0, arr.shape[1] - 1, indices)
+
+ pad_sum = torch.sum(1 - padding, dim=2)
+ patch_indices = _get_patch_index(pad_sum)
+ bidxs = torch.arange(inputs.shape[0])
+
+ arr = inputs[bidxs, patch_indices, :]
+ pad = padding[bidxs, patch_indices, :]
+
+ # Create a mask where padding is 0
+ mask = 1 - pad
+
+ # Calculate the number of valid elements
+ num_valid_elements = torch.sum(mask, dim=1)
+ num_valid_elements = torch.where(
+ num_valid_elements == 0,
+ torch.tensor(1, dtype=num_valid_elements.dtype, device=num_valid_elements.device),
+ num_valid_elements,
+ )
+
+ # Calculate the masked sum and squared sum
+ masked_sum = torch.sum(arr * mask, dim=1)
+ masked_squared_sum = torch.sum((arr * mask) ** 2, dim=1)
+
+ # Calculate the masked mean and standard deviation
+ masked_mean = masked_sum / num_valid_elements
+ masked_var = masked_squared_sum / num_valid_elements - masked_mean**2
+ masked_var = torch.where(
+ masked_var < 0.0,
+ torch.tensor(0.0, dtype=masked_var.dtype, device=masked_var.device),
+ masked_var,
+ )
+ masked_std = torch.sqrt(masked_var)
+
+ return masked_mean, masked_std
+
+ @staticmethod
+ def _timesfm_shift_padded_seq(mask: torch.Tensor, seq: torch.Tensor) -> torch.Tensor:
+ """Shifts rows of seq based on the first 0 in each row of the mask.
+
+ Args:
+ mask: mask tensor of shape [B, N]
+ seq: seq tensor of shape [B, N, P]
+
+ Returns:
+ The shifted sequence.
+ """
+ batch_size, num_seq, feature_dim = seq.shape
+
+ new_mask: torch.BoolTensor = mask == 0
+
+ # Use argmax to find the first True value in each row
+ indices = new_mask.to(torch.int32).argmax(dim=1)
+
+ # Handle rows with all zeros
+ indices[~new_mask.any(dim=1)] = -1
+
+ # Create index ranges for each sequence in the batch
+ idx_range = torch.arange(num_seq, device=seq.device).view(1, -1, 1).expand(batch_size, -1, feature_dim)
+
+ # Calculate shifted indices for each element in each sequence
+ shifted_idx = (idx_range - indices[:, None, None]) % num_seq
+
+ # Gather values from seq using shifted indices
+ shifted_seq = seq.gather(1, shifted_idx)
+
+ return shifted_seq
+
+
+class TimesFmModelForPrediction(TimesFmPreTrainedModel):
+ """TimesFM model for quantile and mean prediction."""
+
+ def __init__(self, config: TimesFmConfig):
+ super().__init__(config)
+
+ self.config = config
+ self.context_len = config.context_length
+ self.horizon_len = config.horizon_length
+
+ self.decoder = TimesFmModel(config)
+
+ # quantile and mean output
+ self.horizon_ff_layer = TimesFmResidualBlock(
+ input_dims=config.hidden_size,
+ output_dims=config.horizon_length * (1 + len(config.quantiles)),
+ hidden_dims=config.intermediate_size,
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _preprocess(
+ self, inputs: Sequence[torch.Tensor], freq: Sequence[int]
+ ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
+ """Formats and pads raw inputs to feed into the model.
+
+ This function both pads each time series to match the context length, and
+ pads the inputs to meet the SPMD shape requirement.
+
+ Args:
+ inputs: A list of 1d Tensors. Each Tensor is the context time series of
+ a single forecast task.
+ freq: list of frequencies
+
+ Returns:
+ A tuple of:
+ - the padded input time series to meet the model required context.
+ - the padding indicator.
+ - the number of padded examples for SPMD so that each core has the same
+ number (a multiple of `batch_size`) of examples.
+ """
+ input_ts, input_padding, inp_freq = [], [], []
+
+ for i, ts in enumerate(inputs):
+ input_len = ts.shape[0]
+ padding = torch.zeros(input_len + self.horizon_len, dtype=ts.dtype, device=ts.device)
+ if input_len < self.context_len:
+ num_front_pad = self.context_len - input_len
+ ts = torch.cat([torch.zeros(num_front_pad, dtype=ts.dtype, device=ts.device), ts], dim=0)
+ padding = torch.cat([torch.ones(num_front_pad, dtype=ts.dtype, device=padding.device), padding], dim=0)
+ elif input_len > self.context_len:
+ ts = ts[-self.context_len :]
+ padding = padding[-(self.context_len + self.horizon_len) :]
+
+ input_ts.append(ts)
+ input_padding.append(padding)
+ inp_freq.append(freq[i])
+
+ return (
+ torch.stack(input_ts, dim=0),
+ torch.stack(input_padding, dim=0),
+ torch.tensor(inp_freq, dtype=torch.int32).reshape(-1, 1),
+ )
+
+ def _postprocess_output(
+ self, model_output: torch.Tensor, stats: tuple[torch.Tensor, torch.Tensor]
+ ) -> torch.Tensor:
+ """Postprocess output of stacked transformer."""
+
+ # B x N x (H.Q)
+ output_ts = self.horizon_ff_layer(model_output)
+
+ # Reshape using view
+ b, n, _ = output_ts.shape
+ output_ts = output_ts.view(b, n, self.config.horizon_length, len(self.config.quantiles) + 1)
+
+ mu, sigma = stats
+ return output_ts * sigma[:, None, None, None] + mu[:, None, None, None]
+
+ def _quantile_loss(self, predictions: torch.Tensor, targets: torch.Tensor) -> torch.Tensor:
+ losses = []
+ for i, q in enumerate(self.config.quantiles):
+ errors = targets - predictions[..., i]
+ loss = torch.max((q - 1) * errors, q * errors)
+ losses.append(loss.mean())
+ return torch.stack(losses).mean()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ past_values: Sequence[torch.Tensor],
+ freq: Optional[Sequence[Union[torch.Tensor, int]]] = None,
+ window_size: Optional[int] = None,
+ future_values: Optional[torch.Tensor] = None,
+ forecast_context_len: Optional[int] = None,
+ return_forecast_on_context: bool = False,
+ truncate_negative: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> TimesFmOutputForPrediction:
+ r"""
+ past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Past values of the time series that serves as input to the model.
+ freq (`torch.LongTensor` of shape `(batch_size,)`):
+ Frequency indices for the time series data.
+ window_size (`int`, *optional*):
+ Window size of trend + residual decomposition. If None then we do not do decomposition.
+ future_values (`torch.Tensor`, *optional*):
+ Optional future time series values to be used for loss computation.
+ forecast_context_len (`int`, *optional*):
+ Optional max context length.
+ return_forecast_on_context (`bool`, *optional*):
+ True to return the forecast on the context when available, i.e. after the first input patch.
+ truncate_negative (`bool`, *optional*):
+ Truncate to only non-negative values if any of the contexts have non-negative values,
+ otherwise do nothing.
+ output_attentions (`bool`, *optional*):
+ Whether to output the attentions.
+ output_hidden_states (`bool`, *optional*):
+ Whether to output the hidden states.
+
+ Example:
+
+ ```python
+ >>> from transformers import TimesFmModelForPrediction
+
+ >>> model = TimesFmModelForPrediction.from_pretrained("google/timesfm-2.0-500m-pytorch")
+
+ >>> forecast_input = [torch.linspace(0, 20, 100).sin(), torch.linspace(0, 20, 200).sin(), torch.linspace(0, 20, 400).sin()]
+ >>> frequency_input = torch.tensor([0, 1, 2], dtype=torch.long)
+
+ >>> # Generate
+ >>> with torch.no_grad():
+ >>> outputs = model(past_values=forecast_input, freq=frequency_input, return_dict=True)
+ >>> point_forecast_conv = outputs.mean_predictions
+ >>> quantile_forecast_conv = outputs.full_predictions
+ ```
+ """
+ if forecast_context_len is None:
+ fcontext_len = self.context_len
+ else:
+ fcontext_len = forecast_context_len
+
+ # Get device from first input tensor
+ device = past_values[0].device
+
+ # Truncate inputs to forecast_context_len
+ inputs = [ts[-fcontext_len:] for ts in past_values]
+ inp_min = torch.min(torch.stack([torch.min(ts) for ts in inputs]))
+
+ if window_size is not None:
+ new_inputs = []
+ new_freqs = []
+ for i, ts in enumerate(inputs):
+ new_inputs.extend(self._timesfm_moving_average(ts, window_size))
+ if freq is not None:
+ new_freqs.extend([freq[i]] * 2)
+ inputs = new_inputs
+ if freq is not None:
+ freq = new_freqs
+
+ if freq is None:
+ logger.info("No frequency provided via `freq`. Default to high (0).")
+ freq = [0] * len(inputs)
+
+ if output_attentions is None:
+ output_attentions = self.config.output_attentions
+ if output_hidden_states is None:
+ output_hidden_states = self.config.output_hidden_states
+
+ input_ts, input_padding, inp_freq = self._preprocess(inputs, freq)
+ # Move tensors to the same device as input
+ input_ts = input_ts.to(device)
+ input_padding = input_padding.to(device)
+ inp_freq = inp_freq.to(device)
+
+ final_out = input_ts
+ context_len = final_out.shape[1]
+ full_outputs = []
+
+ if input_padding.shape[1] != final_out.shape[1] + self.horizon_len:
+ raise ValueError(
+ "Length of paddings must match length of input + horizon_len:"
+ f" {input_padding.shape[1]} != {final_out.shape[1]} + {self.horizon_len}"
+ )
+ output_patch_len = self.config.horizon_length
+
+ num_decode_patches = (self.horizon_len + output_patch_len - 1) // output_patch_len
+ for step_index in range(num_decode_patches):
+ current_padding = input_padding[:, 0 : final_out.shape[1]]
+ input_ts = final_out[:, -fcontext_len:]
+ input_padding = current_padding[:, -fcontext_len:]
+ decoder_output = self.decoder(
+ past_values=input_ts,
+ past_values_padding=input_padding,
+ freq=inp_freq,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+ fprop_outputs = self._postprocess_output(
+ decoder_output.last_hidden_state,
+ (decoder_output.loc, decoder_output.scale),
+ )
+
+ if return_forecast_on_context and step_index == 0:
+ # For the first decodings step, collect the model forecast on the
+ # context except the unavailable first input batch forecast.
+ new_full_ts = fprop_outputs[:, :-1, : self.config.patch_length, :]
+ # We have to use reshape and not view for non-contiguous memory
+ new_full_ts = new_full_ts.reshape(new_full_ts.size(0), -1, new_full_ts.size(3))
+
+ full_outputs.append(new_full_ts)
+
+ # (full batch, last patch, output_patch_len, index of mean forecast = 0)
+ new_ts = fprop_outputs[:, -1, :output_patch_len, 0]
+ new_full_ts = fprop_outputs[:, -1, :output_patch_len, :]
+ # (full batch, last patch, output_patch_len, all output indices)
+ full_outputs.append(new_full_ts)
+ final_out = torch.concatenate([final_out, new_ts], axis=-1)
+
+ if return_forecast_on_context:
+ # `full_outputs` indexing starts at after the first input patch.
+ full_outputs = torch.concatenate(full_outputs, axis=1)[
+ :, : (context_len - self.config.patch_length + self.horizon_len), :
+ ]
+ else:
+ # `full_outputs` indexing starts at the forecast horizon.
+ full_outputs = torch.concatenate(full_outputs, axis=1)[:, 0 : self.horizon_len, :]
+
+ mean_outputs = full_outputs[:, :, 0]
+ if window_size is not None:
+ mean_outputs = mean_outputs[0::2, ...] + mean_outputs[1::2, ...]
+ full_outputs = full_outputs[0::2, ...] + full_outputs[1::2, ...]
+ if inp_min >= 0 and truncate_negative:
+ mean_outputs = torch.maximum(mean_outputs, 0.0)
+ full_outputs = torch.maximum(full_outputs, 0.0)
+
+ loss = None
+ if future_values is not None:
+ mse_loss = F.mse_loss(mean_outputs, future_values)
+ quantile_loss = self._quantile_loss(full_outputs[:, :, 1:], future_values)
+ loss = mse_loss + quantile_loss
+
+ return TimesFmOutputForPrediction(
+ last_hidden_state=decoder_output.last_hidden_state,
+ attentions=decoder_output.attentions if output_attentions else None,
+ hidden_states=decoder_output.hidden_states if output_hidden_states else None,
+ mean_predictions=mean_outputs,
+ full_predictions=full_outputs,
+ loss=loss,
+ )
+
+ @staticmethod
+ def _timesfm_moving_average(arr: torch.Tensor, window_size: int) -> list[torch.Tensor]:
+ """Calculates the moving average using PyTorch's convolution function."""
+ # Pad with zeros to handle initial window positions
+ arr_padded = F.pad(arr, (window_size - 1, 0), "constant", 0)
+ # Create a convolution kernel
+ kernel = torch.ones(window_size, dtype=arr.dtype, device=arr.device) / window_size
+ # Apply convolution to calculate the moving average
+ smoothed_arr = F.conv1d(arr_padded.view(1, 1, -1), kernel.view(1, 1, -1)).squeeze()
+ return [smoothed_arr, arr - smoothed_arr]
+
+
+__all__ = ["TimesFmModelForPrediction", "TimesFmPreTrainedModel", "TimesFmModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..c0cc9d3d6a68569b0e0e94c94573d7191b153a68
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_timesformer import *
+ from .modeling_timesformer import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/configuration_timesformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/configuration_timesformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..edb69af230f901c1d8c237c24354a8fde9c5c909
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/configuration_timesformer.py
@@ -0,0 +1,129 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TimeSformer model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class TimesformerConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TimesformerModel`]. It is used to instantiate a
+ TimeSformer model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the TimeSformer
+ [facebook/timesformer-base-finetuned-k600](https://huggingface.co/facebook/timesformer-base-finetuned-k600)
+ architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ num_frames (`int`, *optional*, defaults to 8):
+ The number of frames in each video.
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ attention_type (`str`, *optional*, defaults to `"divided_space_time"`):
+ The attention type to use. Must be one of `"divided_space_time"`, `"space_only"`, `"joint_space_time"`.
+ drop_path_rate (`float`, *optional*, defaults to 0):
+ The dropout ratio for stochastic depth.
+
+ Example:
+
+ ```python
+ >>> from transformers import TimesformerConfig, TimesformerModel
+
+ >>> # Initializing a TimeSformer timesformer-base style configuration
+ >>> configuration = TimesformerConfig()
+
+ >>> # Initializing a model from the configuration
+ >>> model = TimesformerModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "timesformer"
+
+ def __init__(
+ self,
+ image_size=224,
+ patch_size=16,
+ num_channels=3,
+ num_frames=8,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-6,
+ qkv_bias=True,
+ attention_type="divided_space_time",
+ drop_path_rate=0,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_frames = num_frames
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.qkv_bias = qkv_bias
+
+ self.attention_type = attention_type
+ self.drop_path_rate = drop_path_rate
+
+
+__all__ = ["TimesformerConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/modeling_timesformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/modeling_timesformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..c0110b379aac860ac6ea82c79b1781d32853e408
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timesformer/modeling_timesformer.py
@@ -0,0 +1,770 @@
+# coding=utf-8
+# Copyright 2022 Meta and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch TimeSformer model."""
+
+import collections
+from typing import Optional, Union
+
+import torch
+import torch.nn.functional
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ImageClassifierOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import (
+ auto_docstring,
+ logging,
+)
+from .configuration_timesformer import TimesformerConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# Adapted from https://github.com/facebookresearch/TimeSformer/blob/a5ef29a7b7264baff199a30b3306ac27de901133/timesformer/models/vit.py#L155
+class TimesformerPatchEmbeddings(nn.Module):
+ """Image to Patch Embedding"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ image_size = config.image_size
+ patch_size = config.patch_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_patches = num_patches
+
+ self.projection = nn.Conv2d(config.num_channels, config.hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def forward(self, pixel_values):
+ batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ pixel_values = pixel_values.reshape(batch_size * num_frames, num_channels, height, width)
+
+ embeddings = self.projection(pixel_values)
+ patch_width = embeddings.size(-1)
+ embeddings = embeddings.flatten(2).transpose(1, 2)
+ return embeddings, num_frames, patch_width
+
+
+class TimesformerEmbeddings(nn.Module):
+ """
+ Construct the patch and position embeddings.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ embed_dim = config.hidden_size
+ num_frames = config.num_frames
+ drop_rate = config.hidden_dropout_prob
+ attention_type = config.attention_type
+
+ self.attention_type = attention_type
+ self.patch_embeddings = TimesformerPatchEmbeddings(config)
+ self.num_patches = self.patch_embeddings.num_patches
+
+ # Positional Embeddings
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, embed_dim))
+ self.position_embeddings = nn.Parameter(torch.zeros(1, self.num_patches + 1, embed_dim))
+ self.pos_drop = nn.Dropout(p=drop_rate)
+ if attention_type != "space_only":
+ self.time_embeddings = nn.Parameter(torch.zeros(1, num_frames, embed_dim))
+ self.time_drop = nn.Dropout(p=drop_rate)
+
+ def forward(self, pixel_values):
+ batch_size = pixel_values.shape[0]
+
+ # create patch embeddings
+ embeddings, num_frames, patch_width = self.patch_embeddings(pixel_values)
+
+ cls_tokens = self.cls_token.expand(embeddings.size(0), -1, -1)
+ embeddings = torch.cat((cls_tokens, embeddings), dim=1)
+
+ # resizing the positional embeddings in case they don't match the input at inference
+ if embeddings.size(1) != self.position_embeddings.size(1):
+ position_embeddings = self.position_embeddings
+ cls_pos_embed = position_embeddings[0, 0, :].unsqueeze(0).unsqueeze(1)
+ other_pos_embed = position_embeddings[0, 1:, :].unsqueeze(0).transpose(1, 2)
+ patch_num = int(other_pos_embed.size(2) ** 0.5)
+ patch_height = embeddings.size(1) // patch_width
+ other_pos_embed = other_pos_embed.reshape(1, embeddings.size(2), patch_num, patch_num)
+ new_pos_embed = nn.functional.interpolate(
+ other_pos_embed, size=(patch_height, patch_width), mode="nearest"
+ )
+ new_pos_embed = new_pos_embed.flatten(2)
+ new_pos_embed = new_pos_embed.transpose(1, 2)
+ new_pos_embed = torch.cat((cls_pos_embed, new_pos_embed), 1)
+ embeddings = embeddings + new_pos_embed
+ else:
+ embeddings = embeddings + self.position_embeddings
+ embeddings = self.pos_drop(embeddings)
+
+ # Time Embeddings
+ if self.attention_type != "space_only":
+ cls_tokens = embeddings[:batch_size, 0, :].unsqueeze(1)
+ embeddings = embeddings[:, 1:]
+ _, patch_height, patch_width = embeddings.shape
+ embeddings = (
+ embeddings.reshape(batch_size, num_frames, patch_height, patch_width)
+ .permute(0, 2, 1, 3)
+ .reshape(batch_size * patch_height, num_frames, patch_width)
+ )
+ # Resizing time embeddings in case they don't match
+ if num_frames != self.time_embeddings.size(1):
+ time_embeddings = self.time_embeddings.transpose(1, 2)
+ new_time_embeddings = nn.functional.interpolate(time_embeddings, size=(num_frames), mode="nearest")
+ new_time_embeddings = new_time_embeddings.transpose(1, 2)
+ embeddings = embeddings + new_time_embeddings
+ else:
+ embeddings = embeddings + self.time_embeddings
+ embeddings = self.time_drop(embeddings)
+ embeddings = embeddings.view(batch_size, patch_height, num_frames, patch_width).reshape(
+ batch_size, patch_height * num_frames, patch_width
+ )
+ embeddings = torch.cat((cls_tokens, embeddings), dim=1)
+
+ return embeddings
+
+
+# Copied from transformers.models.beit.modeling_beit.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+# Copied from transformers.models.beit.modeling_beit.BeitDropPath with Beit->TimeSformer
+class TimeSformerDropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: Optional[float] = None) -> None:
+ super().__init__()
+ self.drop_prob = drop_prob
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+# Adapted from https://github.com/facebookresearch/TimeSformer/blob/a5ef29a7b7264baff199a30b3306ac27de901133/timesformer/models/vit.py#L57
+class TimesformerSelfAttention(nn.Module):
+ def __init__(self, config: TimesformerConfig):
+ super().__init__()
+
+ num_heads = config.num_attention_heads
+ qkv_bias = config.qkv_bias
+ attention_dropout_prob = config.attention_probs_dropout_prob
+
+ self.num_heads = num_heads
+ head_dim = config.hidden_size // num_heads
+ self.scale = head_dim**-0.5
+ self.qkv = nn.Linear(config.hidden_size, config.hidden_size * 3, bias=qkv_bias)
+ self.attn_drop = nn.Dropout(attention_dropout_prob)
+
+ def forward(self, hidden_states, output_attentions: bool = False):
+ batch_size, hidden_size, num_channels = hidden_states.shape
+ qkv = (
+ self.qkv(hidden_states)
+ .reshape(batch_size, hidden_size, 3, self.num_heads, num_channels // self.num_heads)
+ .permute(2, 0, 3, 1, 4)
+ )
+ query, key, value = qkv[0], qkv[1], qkv[2]
+
+ attention_probs = (query @ key.transpose(-2, -1)) * self.scale
+ attention_probs = attention_probs.softmax(dim=-1)
+ attention_probs = self.attn_drop(attention_probs)
+
+ context_layer = (attention_probs @ value).transpose(1, 2).reshape(batch_size, hidden_size, num_channels)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+class TimesformerSelfOutput(nn.Module):
+ """
+ The residual connection is defined in TimesformerLayer instead of here (as is the case with other models), due to
+ the layernorm applied before each block.
+ """
+
+ def __init__(self, config: TimesformerConfig) -> None:
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ return hidden_states
+
+
+class TimeSformerAttention(nn.Module):
+ def __init__(self, config: TimesformerConfig) -> None:
+ super().__init__()
+ self.attention = TimesformerSelfAttention(config)
+ self.output = TimesformerSelfOutput(config)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ output_attentions: bool = False,
+ ) -> Union[tuple[torch.Tensor, torch.Tensor], tuple[torch.Tensor]]:
+ self_outputs = self.attention(hidden_states, output_attentions)
+
+ attention_output = self.output(self_outputs[0])
+
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Adapted from https://github.com/facebookresearch/TimeSformer/blob/a5ef29a7b7264baff199a30b3306ac27de901133/timesformer/models/vit.py#L39
+class TimesformerIntermediate(nn.Module):
+ def __init__(self, config: TimesformerConfig) -> None:
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ return hidden_states
+
+
+class TimesformerOutput(nn.Module):
+ def __init__(self, config: TimesformerConfig) -> None:
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ return hidden_states
+
+
+# Adapted from https://github.com/facebookresearch/TimeSformer/blob/a5ef29a7b7264baff199a30b3306ac27de901133/timesformer/models/vit.py#L89
+class TimesformerLayer(GradientCheckpointingLayer):
+ def __init__(self, config: TimesformerConfig, layer_index: int) -> None:
+ super().__init__()
+
+ attention_type = config.attention_type
+
+ drop_path_rates = [
+ x.item() for x in torch.linspace(0, config.drop_path_rate, config.num_hidden_layers, device="cpu")
+ ] # stochastic depth decay rule
+ drop_path_rate = drop_path_rates[layer_index]
+
+ self.drop_path = TimeSformerDropPath(drop_path_rate) if drop_path_rate > 0.0 else nn.Identity()
+ self.attention = TimeSformerAttention(config)
+ self.intermediate = TimesformerIntermediate(config)
+ self.output = TimesformerOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ self.config = config
+ self.attention_type = attention_type
+ if attention_type not in ["divided_space_time", "space_only", "joint_space_time"]:
+ raise ValueError(f"Unknown attention type: {attention_type}")
+
+ # Temporal Attention Parameters
+ if self.attention_type == "divided_space_time":
+ self.temporal_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.temporal_attention = TimeSformerAttention(config)
+ self.temporal_dense = nn.Linear(config.hidden_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor, output_attentions: bool = False):
+ num_frames = self.config.num_frames
+ num_patch_width = self.config.image_size // self.config.patch_size
+ batch_size = hidden_states.shape[0]
+ num_spatial_tokens = (hidden_states.size(1) - 1) // num_frames
+ num_patch_height = num_spatial_tokens // num_patch_width
+
+ if self.attention_type in ["space_only", "joint_space_time"]:
+ self_attention_outputs = self.attention(
+ self.layernorm_before(hidden_states), output_attentions=output_attentions
+ )
+ attention_output = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ hidden_states = hidden_states + self.drop_path(attention_output)
+
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+ layer_output = self.output(layer_output)
+ layer_output = hidden_states + self.drop_path(layer_output)
+
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+ elif self.attention_type == "divided_space_time":
+ # Temporal
+ temporal_embedding = hidden_states[:, 1:, :]
+ temporal_embedding = temporal_embedding.reshape(
+ batch_size, num_patch_height, num_patch_width, num_frames, temporal_embedding.shape[2]
+ ).reshape(batch_size * num_patch_height * num_patch_width, num_frames, temporal_embedding.shape[2])
+
+ temporal_attention_outputs = self.temporal_attention(
+ self.temporal_layernorm(temporal_embedding),
+ )
+ attention_output = temporal_attention_outputs[0]
+
+ residual_temporal = self.drop_path(attention_output)
+
+ residual_temporal = residual_temporal.reshape(
+ batch_size, num_patch_height, num_patch_width, num_frames, residual_temporal.shape[2]
+ ).reshape(batch_size, num_patch_height * num_patch_width * num_frames, residual_temporal.shape[2])
+ residual_temporal = self.temporal_dense(residual_temporal)
+ temporal_embedding = hidden_states[:, 1:, :] + residual_temporal
+
+ # Spatial
+ init_cls_token = hidden_states[:, 0, :].unsqueeze(1)
+ cls_token = init_cls_token.repeat(1, num_frames, 1)
+ cls_token = cls_token.reshape(batch_size * num_frames, 1, cls_token.shape[2])
+ spatial_embedding = temporal_embedding
+ spatial_embedding = (
+ spatial_embedding.reshape(
+ batch_size, num_patch_height, num_patch_width, num_frames, spatial_embedding.shape[2]
+ )
+ .permute(0, 3, 1, 2, 4)
+ .reshape(batch_size * num_frames, num_patch_height * num_patch_width, spatial_embedding.shape[2])
+ )
+ spatial_embedding = torch.cat((cls_token, spatial_embedding), 1)
+
+ spatial_attention_outputs = self.attention(
+ self.layernorm_before(spatial_embedding), output_attentions=output_attentions
+ )
+ attention_output = spatial_attention_outputs[0]
+ outputs = spatial_attention_outputs[1:] # add self attentions if we output attention weights
+
+ residual_spatial = self.drop_path(attention_output)
+
+ # Taking care of CLS token
+ cls_token = residual_spatial[:, 0, :]
+ cls_token = cls_token.reshape(batch_size, num_frames, cls_token.shape[1])
+ cls_token = torch.mean(cls_token, 1, True) # averaging for every frame
+ residual_spatial = residual_spatial[:, 1:, :]
+ residual_spatial = (
+ residual_spatial.reshape(
+ batch_size, num_frames, num_patch_height, num_patch_width, residual_spatial.shape[2]
+ )
+ .permute(0, 2, 3, 1, 4)
+ .reshape(batch_size, num_patch_height * num_patch_width * num_frames, residual_spatial.shape[2])
+ )
+ residual = residual_spatial
+ hidden_states = temporal_embedding
+
+ # Mlp
+ hidden_states = torch.cat((init_cls_token, hidden_states), 1) + torch.cat((cls_token, residual), 1)
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+ layer_output = self.output(layer_output)
+ layer_output = hidden_states + self.drop_path(layer_output)
+
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+
+class TimesformerEncoder(nn.Module):
+ def __init__(self, config: TimesformerConfig) -> None:
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([TimesformerLayer(config, ind) for ind in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ) -> Union[tuple, BaseModelOutput]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(hidden_states, output_attentions)
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+@auto_docstring
+class TimesformerPreTrainedModel(PreTrainedModel):
+ config: TimesformerConfig
+ base_model_prefix = "timesformer"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["TimesformerLayer"]
+
+ def _init_weights(self, module):
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ nn.init.trunc_normal_(module.weight, std=self.config.initializer_range)
+ if module.bias is not None:
+ nn.init.constant_(module.bias, 0)
+ elif isinstance(module, nn.LayerNorm):
+ nn.init.constant_(module.bias, 0)
+ nn.init.constant_(module.weight, 1.0)
+ elif isinstance(module, TimesformerEmbeddings):
+ nn.init.trunc_normal_(module.cls_token, std=self.config.initializer_range)
+ nn.init.trunc_normal_(module.position_embeddings, std=self.config.initializer_range)
+ module.patch_embeddings.apply(self._init_weights)
+
+
+@auto_docstring
+class TimesformerModel(TimesformerPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = TimesformerEmbeddings(config)
+ self.encoder = TimesformerEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], BaseModelOutput]:
+ r"""
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import numpy as np
+
+ >>> from transformers import AutoImageProcessor, TimesformerModel
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 8 frames
+ >>> indices = sample_frame_indices(clip_len=8, frame_sample_rate=4, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container, indices)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("MCG-NJU/videomae-base")
+ >>> model = TimesformerModel.from_pretrained("facebook/timesformer-base-finetuned-k400")
+
+ >>> # prepare video for the model
+ >>> inputs = image_processor(list(video), return_tensors="pt")
+
+ >>> # forward pass
+ >>> outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ >>> list(last_hidden_states.shape)
+ [1, 1569, 768]
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ embedding_output = self.embeddings(pixel_values)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+ if self.layernorm is not None:
+ sequence_output = self.layernorm(sequence_output)
+
+ if not return_dict:
+ return (sequence_output,) + encoder_outputs[1:]
+
+ return BaseModelOutput(
+ last_hidden_state=sequence_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ TimeSformer Model transformer with a video classification head on top (a linear layer on top of the final hidden state
+ of the [CLS] token) e.g. for ImageNet.
+ """
+)
+class TimesformerForVideoClassification(TimesformerPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.timesformer = TimesformerModel(config)
+
+ # Classifier head
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity()
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, ImageClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import torch
+ >>> import numpy as np
+
+ >>> from transformers import AutoImageProcessor, TimesformerForVideoClassification
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 8 frames
+ >>> indices = sample_frame_indices(clip_len=8, frame_sample_rate=1, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container, indices)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("MCG-NJU/videomae-base-finetuned-kinetics")
+ >>> model = TimesformerForVideoClassification.from_pretrained("facebook/timesformer-base-finetuned-k400")
+
+ >>> inputs = image_processor(list(video), return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+ ... logits = outputs.logits
+
+ >>> # model predicts one of the 400 Kinetics-400 classes
+ >>> predicted_label = logits.argmax(-1).item()
+ >>> print(model.config.id2label[predicted_label])
+ eating spaghetti
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.timesformer(
+ pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0][:, 0]
+
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["TimesformerModel", "TimesformerForVideoClassification", "TimesformerPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..4a58f096b1e48227518b04a11250d66635c65701
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_timm_backbone import *
+ from .modeling_timm_backbone import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/configuration_timm_backbone.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/configuration_timm_backbone.py
new file mode 100644
index 0000000000000000000000000000000000000000..7f8c1c22e9f9fb182eb55c04b6bf11aef04a34cb
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/configuration_timm_backbone.py
@@ -0,0 +1,86 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Configuration for Backbone models"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class TimmBackboneConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration for a timm backbone [`TimmBackbone`].
+
+ It is used to instantiate a timm backbone model according to the specified arguments, defining the model.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ backbone (`str`, *optional*):
+ The timm checkpoint to load.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ features_only (`bool`, *optional*, defaults to `True`):
+ Whether to output only the features or also the logits.
+ use_pretrained_backbone (`bool`, *optional*, defaults to `True`):
+ Whether to use a pretrained backbone.
+ out_indices (`list[int]`, *optional*):
+ If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how
+ many stages the model has). Will default to the last stage if unset.
+ freeze_batch_norm_2d (`bool`, *optional*, defaults to `False`):
+ Converts all `BatchNorm2d` and `SyncBatchNorm` layers of provided module into `FrozenBatchNorm2d`.
+
+ Example:
+ ```python
+ >>> from transformers import TimmBackboneConfig, TimmBackbone
+
+ >>> # Initializing a timm backbone
+ >>> configuration = TimmBackboneConfig("resnet50")
+
+ >>> # Initializing a model from the configuration
+ >>> model = TimmBackbone(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```
+ """
+
+ model_type = "timm_backbone"
+
+ def __init__(
+ self,
+ backbone=None,
+ num_channels=3,
+ features_only=True,
+ use_pretrained_backbone=True,
+ out_indices=None,
+ freeze_batch_norm_2d=False,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.backbone = backbone
+ self.num_channels = num_channels
+ self.features_only = features_only
+ self.use_pretrained_backbone = use_pretrained_backbone
+ self.use_timm_backbone = True
+ self.out_indices = out_indices if out_indices is not None else [-1]
+ self.freeze_batch_norm_2d = freeze_batch_norm_2d
+
+
+__all__ = ["TimmBackboneConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/modeling_timm_backbone.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/modeling_timm_backbone.py
new file mode 100644
index 0000000000000000000000000000000000000000..4959f76d588a090ba02baff23b4bd29773117c0d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_backbone/modeling_timm_backbone.py
@@ -0,0 +1,161 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Optional, Union
+
+import torch
+
+from ...modeling_outputs import BackboneOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import is_timm_available, is_torch_available, requires_backends
+from ...utils.backbone_utils import BackboneMixin
+from .configuration_timm_backbone import TimmBackboneConfig
+
+
+if is_timm_available():
+ import timm
+
+
+if is_torch_available():
+ from torch import Tensor
+
+
+class TimmBackbone(PreTrainedModel, BackboneMixin):
+ """
+ Wrapper class for timm models to be used as backbones. This enables using the timm models interchangeably with the
+ other models in the library keeping the same API.
+ """
+
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = False
+ config: TimmBackboneConfig
+
+ def __init__(self, config, **kwargs):
+ requires_backends(self, "timm")
+ super().__init__(config)
+ self.config = config
+
+ if config.backbone is None:
+ raise ValueError("backbone is not set in the config. Please set it to a timm model name.")
+
+ if hasattr(config, "out_features") and config.out_features is not None:
+ raise ValueError("out_features is not supported by TimmBackbone. Please use out_indices instead.")
+
+ pretrained = getattr(config, "use_pretrained_backbone", None)
+ if pretrained is None:
+ raise ValueError("use_pretrained_backbone is not set in the config. Please set it to True or False.")
+
+ # We just take the final layer by default. This matches the default for the transformers models.
+ out_indices = config.out_indices if getattr(config, "out_indices", None) is not None else (-1,)
+
+ in_chans = kwargs.pop("in_chans", config.num_channels)
+ self._backbone = timm.create_model(
+ config.backbone,
+ pretrained=pretrained,
+ # This is currently not possible for transformer architectures.
+ features_only=config.features_only,
+ in_chans=in_chans,
+ out_indices=out_indices,
+ **kwargs,
+ )
+
+ # Converts all `BatchNorm2d` and `SyncBatchNorm` or `BatchNormAct2d` and `SyncBatchNormAct2d` layers of provided module into `FrozenBatchNorm2d` or `FrozenBatchNormAct2d` respectively
+ if getattr(config, "freeze_batch_norm_2d", False):
+ self.freeze_batch_norm_2d()
+
+ # These are used to control the output of the model when called. If output_hidden_states is True, then
+ # return_layers is modified to include all layers.
+ self._return_layers = {
+ layer["module"]: str(layer["index"]) for layer in self._backbone.feature_info.get_dicts()
+ }
+ self._all_layers = {layer["module"]: str(i) for i, layer in enumerate(self._backbone.feature_info.info)}
+ super()._init_backbone(config)
+
+ @classmethod
+ def from_pretrained(cls, pretrained_model_name_or_path, *model_args, **kwargs):
+ requires_backends(cls, ["vision", "timm"])
+ from ...models.timm_backbone import TimmBackboneConfig
+
+ config = kwargs.pop("config", TimmBackboneConfig())
+
+ use_timm = kwargs.pop("use_timm_backbone", True)
+ if not use_timm:
+ raise ValueError("use_timm_backbone must be True for timm backbones")
+
+ num_channels = kwargs.pop("num_channels", config.num_channels)
+ features_only = kwargs.pop("features_only", config.features_only)
+ use_pretrained_backbone = kwargs.pop("use_pretrained_backbone", config.use_pretrained_backbone)
+ out_indices = kwargs.pop("out_indices", config.out_indices)
+ config = TimmBackboneConfig(
+ backbone=pretrained_model_name_or_path,
+ num_channels=num_channels,
+ features_only=features_only,
+ use_pretrained_backbone=use_pretrained_backbone,
+ out_indices=out_indices,
+ )
+ return super()._from_config(config, **kwargs)
+
+ def freeze_batch_norm_2d(self):
+ timm.utils.model.freeze_batch_norm_2d(self._backbone)
+
+ def unfreeze_batch_norm_2d(self):
+ timm.utils.model.unfreeze_batch_norm_2d(self._backbone)
+
+ def _init_weights(self, module):
+ """
+ Empty init weights function to ensure compatibility of the class in the library.
+ """
+ pass
+
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[BackboneOutput, tuple[Tensor, ...]]:
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ if output_attentions:
+ raise ValueError("Cannot output attentions for timm backbones at the moment")
+
+ if output_hidden_states:
+ # We modify the return layers to include all the stages of the backbone
+ self._backbone.return_layers = self._all_layers
+ hidden_states = self._backbone(pixel_values, **kwargs)
+ self._backbone.return_layers = self._return_layers
+ feature_maps = tuple(hidden_states[i] for i in self.out_indices)
+ else:
+ feature_maps = self._backbone(pixel_values, **kwargs)
+ hidden_states = None
+
+ feature_maps = tuple(feature_maps)
+ hidden_states = tuple(hidden_states) if hidden_states is not None else None
+
+ if not return_dict:
+ output = (feature_maps,)
+ if output_hidden_states:
+ output = output + (hidden_states,)
+ return output
+
+ return BackboneOutput(feature_maps=feature_maps, hidden_states=hidden_states, attentions=None)
+
+
+__all__ = ["TimmBackbone"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..9fbc4150412a73ec6d77a09db13c105e95e50c06
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_timm_wrapper import *
+ from .modeling_timm_wrapper import *
+ from .processing_timm_wrapper import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/configuration_timm_wrapper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/configuration_timm_wrapper.py
new file mode 100644
index 0000000000000000000000000000000000000000..5fa115a05431f4546386c7b0ca2424e4c85eac27
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/configuration_timm_wrapper.py
@@ -0,0 +1,127 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Configuration for TimmWrapper models"""
+
+from typing import Any, Optional
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import is_timm_available, logging, requires_backends
+
+
+if is_timm_available():
+ from timm.data import ImageNetInfo, infer_imagenet_subset
+
+
+logger = logging.get_logger(__name__)
+
+
+class TimmWrapperConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration for a timm backbone [`TimmWrapper`].
+
+ It is used to instantiate a timm model according to the specified arguments, defining the model.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Config loads imagenet label descriptions and stores them in `id2label` attribute, `label2id` attribute for default
+ imagenet models is set to `None` due to occlusions in the label descriptions.
+
+ Args:
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ do_pooling (`bool`, *optional*, defaults to `True`):
+ Whether to do pooling for the last_hidden_state in `TimmWrapperModel` or not.
+ model_args (`dict[str, Any]`, *optional*):
+ Additional keyword arguments to pass to the `timm.create_model` function. e.g. `model_args={"depth": 3}`
+ for `timm/vit_base_patch32_clip_448.laion2b_ft_in12k_in1k` to create a model with 3 blocks. Defaults to `None`.
+
+ Example:
+ ```python
+ >>> from transformers import TimmWrapperModel
+
+ >>> # Initializing a timm model
+ >>> model = TimmWrapperModel.from_pretrained("timm/resnet18.a1_in1k")
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```
+ """
+
+ model_type = "timm_wrapper"
+
+ def __init__(
+ self,
+ initializer_range: float = 0.02,
+ do_pooling: bool = True,
+ model_args: Optional[dict[str, Any]] = None,
+ **kwargs,
+ ):
+ self.initializer_range = initializer_range
+ self.do_pooling = do_pooling
+ self.model_args = model_args # named "model_args" for BC with timm
+ super().__init__(**kwargs)
+
+ @classmethod
+ def from_dict(cls, config_dict: dict[str, Any], **kwargs):
+ label_names = config_dict.get("label_names")
+ is_custom_model = "num_labels" in kwargs or "id2label" in kwargs
+
+ # if no labels added to config, use imagenet labeller in timm
+ if label_names is None and not is_custom_model:
+ requires_backends(cls, ["timm"])
+ imagenet_subset = infer_imagenet_subset(config_dict)
+ if imagenet_subset:
+ dataset_info = ImageNetInfo(imagenet_subset)
+ synsets = dataset_info.label_names()
+ label_descriptions = dataset_info.label_descriptions(as_dict=True)
+ label_names = [label_descriptions[synset] for synset in synsets]
+
+ if label_names is not None and not is_custom_model:
+ kwargs["id2label"] = dict(enumerate(label_names))
+
+ # if all label names are unique, create label2id mapping as well
+ if len(set(label_names)) == len(label_names):
+ kwargs["label2id"] = {name: i for i, name in enumerate(label_names)}
+ else:
+ kwargs["label2id"] = None
+
+ # timm config stores the `num_classes` attribute in both the root of config and in the "pretrained_cfg" dict.
+ # We are removing these attributes in order to have the native `transformers` num_labels attribute in config
+ # and to avoid duplicate attributes
+ num_labels_in_kwargs = kwargs.pop("num_labels", None)
+ num_labels_in_dict = config_dict.pop("num_classes", None)
+
+ # passed num_labels has priority over num_classes in config_dict
+ kwargs["num_labels"] = num_labels_in_kwargs or num_labels_in_dict
+
+ # pop num_classes from "pretrained_cfg",
+ # it is not necessary to have it, only root one is used in timm
+ if "pretrained_cfg" in config_dict and "num_classes" in config_dict["pretrained_cfg"]:
+ config_dict["pretrained_cfg"].pop("num_classes", None)
+
+ return super().from_dict(config_dict, **kwargs)
+
+ def to_dict(self) -> dict[str, Any]:
+ output = super().to_dict()
+ output["num_classes"] = self.num_labels
+ output["label_names"] = list(self.id2label.values())
+ output.pop("id2label", None)
+ output.pop("label2id", None)
+ return output
+
+
+__all__ = ["TimmWrapperConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/image_processing_timm_wrapper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/image_processing_timm_wrapper.py
new file mode 100644
index 0000000000000000000000000000000000000000..94ca3efedb1745a5ce8089d31b1f1122f4300d78
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/image_processing_timm_wrapper.py
@@ -0,0 +1,139 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+from typing import Any, Optional, Union
+
+import torch
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature
+from ...image_transforms import to_pil_image
+from ...image_utils import ImageInput, make_list_of_images
+from ...utils import TensorType, logging, requires_backends
+from ...utils.import_utils import is_timm_available, is_torch_available, requires
+
+
+if is_timm_available():
+ import timm
+
+if is_torch_available():
+ import torch
+
+
+logger = logging.get_logger(__name__)
+
+
+@requires(backends=("torch", "timm", "torchvision"))
+class TimmWrapperImageProcessor(BaseImageProcessor):
+ """
+ Wrapper class for timm models to be used within transformers.
+
+ Args:
+ pretrained_cfg (`dict[str, Any]`):
+ The configuration of the pretrained model used to resolve evaluation and
+ training transforms.
+ architecture (`Optional[str]`, *optional*):
+ Name of the architecture of the model.
+ """
+
+ main_input_name = "pixel_values"
+
+ def __init__(
+ self,
+ pretrained_cfg: dict[str, Any],
+ architecture: Optional[str] = None,
+ **kwargs,
+ ):
+ requires_backends(self, "timm")
+ super().__init__(architecture=architecture)
+
+ self.data_config = timm.data.resolve_data_config(pretrained_cfg, model=None, verbose=False)
+ self.val_transforms = timm.data.create_transform(**self.data_config, is_training=False)
+
+ # useful for training, see examples/pytorch/image-classification/run_image_classification.py
+ self.train_transforms = timm.data.create_transform(**self.data_config, is_training=True)
+
+ # If `ToTensor` is in the transforms, then the input should be numpy array or PIL image.
+ # Otherwise, the input can be a tensor. In later timm versions, `MaybeToTensor` is used
+ # which can handle both numpy arrays / PIL images and tensors.
+ self._not_supports_tensor_input = any(
+ transform.__class__.__name__ == "ToTensor" for transform in self.val_transforms.transforms
+ )
+
+ def to_dict(self) -> dict[str, Any]:
+ """
+ Serializes this instance to a Python dictionary.
+ """
+ output = super().to_dict()
+ output.pop("train_transforms", None)
+ output.pop("val_transforms", None)
+ output.pop("_not_supports_tensor_input", None)
+ return output
+
+ @classmethod
+ def get_image_processor_dict(
+ cls, pretrained_model_name_or_path: Union[str, os.PathLike], **kwargs
+ ) -> tuple[dict[str, Any], dict[str, Any]]:
+ """
+ Get the image processor dict for the model.
+ """
+ image_processor_filename = kwargs.pop("image_processor_filename", "config.json")
+ return super().get_image_processor_dict(
+ pretrained_model_name_or_path, image_processor_filename=image_processor_filename, **kwargs
+ )
+
+ def preprocess(
+ self,
+ images: ImageInput,
+ return_tensors: Optional[Union[str, TensorType]] = "pt",
+ ) -> BatchFeature:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return.
+ """
+ if return_tensors != "pt":
+ raise ValueError(f"return_tensors for TimmWrapperImageProcessor must be 'pt', but got {return_tensors}")
+
+ if self._not_supports_tensor_input and isinstance(images, torch.Tensor):
+ images = images.cpu().numpy()
+
+ # If the input is a torch tensor, then no conversion is needed
+ # Otherwise, we need to pass in a list of PIL images
+ if isinstance(images, torch.Tensor):
+ images = self.val_transforms(images)
+ # Add batch dimension if a single image
+ images = images.unsqueeze(0) if images.ndim == 3 else images
+ else:
+ images = make_list_of_images(images)
+ images = [to_pil_image(image) for image in images]
+ images = torch.stack([self.val_transforms(image) for image in images])
+
+ return BatchFeature({"pixel_values": images}, tensor_type=return_tensors)
+
+ def save_pretrained(self, *args, **kwargs):
+ # disable it to make checkpoint the same as in `timm` library.
+ logger.warning_once(
+ "The `save_pretrained` method is disabled for TimmWrapperImageProcessor. "
+ "The image processor configuration is saved directly in `config.json` when "
+ "`save_pretrained` is called for saving the model."
+ )
+
+
+__all__ = ["TimmWrapperImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/modeling_timm_wrapper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/modeling_timm_wrapper.py
new file mode 100644
index 0000000000000000000000000000000000000000..d6d844af479497bbe39950552ccbffb7031089ec
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/timm_wrapper/modeling_timm_wrapper.py
@@ -0,0 +1,379 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+from torch import Tensor, nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...modeling_outputs import ImageClassifierOutput, ModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, is_timm_available, requires_backends
+from .configuration_timm_wrapper import TimmWrapperConfig
+
+
+if is_timm_available():
+ import timm
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output class for models TimmWrapperModel, containing the last hidden states, an optional pooled output,
+ and optional hidden states.
+ """
+)
+class TimmWrapperModelOutput(ModelOutput):
+ r"""
+ last_hidden_state (`torch.FloatTensor`):
+ The last hidden state of the model, output before applying the classification head.
+ pooler_output (`torch.FloatTensor`, *optional*):
+ The pooled output derived from the last hidden state, if applicable.
+ hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned if `output_hidden_states=True` is set or if `config.output_hidden_states=True`):
+ A tuple containing the intermediate hidden states of the model at the output of each layer or specified layers.
+ attentions (`tuple(torch.FloatTensor)`, *optional*, returned if `output_attentions=True` is set or if `config.output_attentions=True`.):
+ A tuple containing the intermediate attention weights of the model at the output of each layer.
+ Note: Currently, Timm models do not support attentions output.
+ """
+
+ last_hidden_state: torch.FloatTensor
+ pooler_output: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@auto_docstring
+class TimmWrapperPreTrainedModel(PreTrainedModel):
+ main_input_name = "pixel_values"
+ config: TimmWrapperConfig
+ _no_split_modules = []
+ model_tags = ["timm"]
+
+ # used in Trainer to avoid passing `loss_kwargs` to model forward
+ accepts_loss_kwargs = False
+
+ def __init__(self, *args, **kwargs):
+ requires_backends(self, ["vision", "timm"])
+ super().__init__(*args, **kwargs)
+
+ def post_init(self):
+ self.supports_gradient_checkpointing = self._timm_model_supports_gradient_checkpointing()
+ super().post_init()
+
+ @staticmethod
+ def _fix_state_dict_key_on_load(key) -> tuple[str, bool]:
+ """
+ Overrides original method that renames `gamma` and `beta` to `weight` and `bias`.
+ We don't want this behavior for timm wrapped models. Instead, this method adds a
+ "timm_model." prefix to enable loading official timm Hub checkpoints.
+ """
+ if "timm_model." not in key:
+ return f"timm_model.{key}", True
+ return key, False
+
+ def _fix_state_dict_key_on_save(self, key):
+ """
+ Overrides original method to remove "timm_model." prefix from state_dict keys.
+ Makes the saved checkpoint compatible with the `timm` library.
+ """
+ return key.replace("timm_model.", ""), True
+
+ def load_state_dict(self, state_dict, *args, **kwargs):
+ """
+ Override original method to fix state_dict keys on load for cases when weights are loaded
+ without using the `from_pretrained` method (e.g., in Trainer to resume from checkpoint).
+ """
+ state_dict = {self._fix_state_dict_key_on_load(k)[0]: v for k, v in state_dict.items()}
+ return super().load_state_dict(state_dict, *args, **kwargs)
+
+ def _init_weights(self, module):
+ """
+ Initialize weights function to properly initialize Linear layer weights.
+ Since model architectures may vary, we assume only the classifier requires
+ initialization, while all other weights should be loaded from the checkpoint.
+ """
+ if isinstance(module, (nn.Linear)):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+
+ def _timm_model_supports_gradient_checkpointing(self):
+ """
+ Check if the timm model supports gradient checkpointing by checking if the `set_grad_checkpointing` method is available.
+ Some timm models will have the method but will raise an AssertionError when called so in this case we return False.
+ """
+ if not hasattr(self.timm_model, "set_grad_checkpointing"):
+ return False
+
+ try:
+ self.timm_model.set_grad_checkpointing(enable=True)
+ self.timm_model.set_grad_checkpointing(enable=False)
+ return True
+ except Exception:
+ return False
+
+ def _set_gradient_checkpointing(self, enable: bool = True, *args, **kwargs):
+ self.timm_model.set_grad_checkpointing(enable)
+
+
+class TimmWrapperModel(TimmWrapperPreTrainedModel):
+ """
+ Wrapper class for timm models to be used in transformers.
+ """
+
+ def __init__(self, config: TimmWrapperConfig):
+ super().__init__(config)
+ # using num_classes=0 to avoid creating classification head
+ extra_init_kwargs = config.model_args or {}
+ self.timm_model = timm.create_model(config.architecture, pretrained=False, num_classes=0, **extra_init_kwargs)
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[Union[bool, list[int]]] = None,
+ return_dict: Optional[bool] = None,
+ do_pooling: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[TimmWrapperModelOutput, tuple[Tensor, ...]]:
+ r"""
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. Not compatible with timm wrapped models.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. Not compatible with timm wrapped models.
+ do_pooling (`bool`, *optional*):
+ Whether to do pooling for the last_hidden_state in `TimmWrapperModel` or not. If `None` is passed, the
+ `do_pooling` value from the config is used.
+
+ Examples:
+ ```python
+ >>> import torch
+ >>> from PIL import Image
+ >>> from urllib.request import urlopen
+ >>> from transformers import AutoModel, AutoImageProcessor
+
+ >>> # Load image
+ >>> image = Image.open(urlopen(
+ ... 'https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/beignets-task-guide.png'
+ ... ))
+
+ >>> # Load model and image processor
+ >>> checkpoint = "timm/resnet50.a1_in1k"
+ >>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+ >>> model = AutoModel.from_pretrained(checkpoint).eval()
+
+ >>> # Preprocess image
+ >>> inputs = image_processor(image)
+
+ >>> # Forward pass
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+
+ >>> # Get pooled output
+ >>> pooled_output = outputs.pooler_output
+
+ >>> # Get last hidden state
+ >>> last_hidden_state = outputs.last_hidden_state
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ do_pooling = do_pooling if do_pooling is not None else self.config.do_pooling
+
+ if output_attentions:
+ raise ValueError("Cannot set `output_attentions` for timm models.")
+
+ if output_hidden_states and not hasattr(self.timm_model, "forward_intermediates"):
+ raise ValueError(
+ "The 'output_hidden_states' option cannot be set for this timm model. "
+ "To enable this feature, the 'forward_intermediates' method must be implemented "
+ "in the timm model (available in timm versions > 1.*). Please consider using a "
+ "different architecture or updating the timm package to a compatible version."
+ )
+
+ pixel_values = pixel_values.to(self.device, self.dtype)
+
+ if output_hidden_states:
+ # to enable hidden states selection
+ if isinstance(output_hidden_states, (list, tuple)):
+ kwargs["indices"] = output_hidden_states
+ last_hidden_state, hidden_states = self.timm_model.forward_intermediates(pixel_values, **kwargs)
+ else:
+ last_hidden_state = self.timm_model.forward_features(pixel_values, **kwargs)
+ hidden_states = None
+
+ if do_pooling:
+ # classification head is not created, applying pooling only
+ pooler_output = self.timm_model.forward_head(last_hidden_state)
+ else:
+ pooler_output = None
+
+ if not return_dict:
+ outputs = (last_hidden_state, pooler_output, hidden_states)
+ outputs = tuple(output for output in outputs if output is not None)
+ return outputs
+
+ return TimmWrapperModelOutput(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooler_output,
+ hidden_states=hidden_states,
+ )
+
+
+class TimmWrapperForImageClassification(TimmWrapperPreTrainedModel):
+ """
+ Wrapper class for timm models to be used in transformers for image classification.
+ """
+
+ def __init__(self, config: TimmWrapperConfig):
+ super().__init__(config)
+
+ if config.num_labels == 0:
+ raise ValueError(
+ "You are trying to load weights into `TimmWrapperForImageClassification` from a checkpoint with no classifier head. "
+ "Please specify the number of classes, e.g. `model = TimmWrapperForImageClassification.from_pretrained(..., num_labels=10)`, "
+ "or use `TimmWrapperModel` for feature extraction."
+ )
+
+ extra_init_kwargs = config.model_args or {}
+ self.timm_model = timm.create_model(
+ config.architecture, pretrained=False, num_classes=config.num_labels, **extra_init_kwargs
+ )
+ self.num_labels = config.num_labels
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[Union[bool, list[int]]] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[ImageClassifierOutput, tuple[Tensor, ...]]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. Not compatible with timm wrapped models.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. Not compatible with timm wrapped models.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ **kwargs:
+ Additional keyword arguments passed along to the `timm` model forward.
+
+ Examples:
+ ```python
+ >>> import torch
+ >>> from PIL import Image
+ >>> from urllib.request import urlopen
+ >>> from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+ >>> # Load image
+ >>> image = Image.open(urlopen(
+ ... 'https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/beignets-task-guide.png'
+ ... ))
+
+ >>> # Load model and image processor
+ >>> checkpoint = "timm/resnet50.a1_in1k"
+ >>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+ >>> model = AutoModelForImageClassification.from_pretrained(checkpoint).eval()
+
+ >>> # Preprocess image
+ >>> inputs = image_processor(image)
+
+ >>> # Forward pass
+ >>> with torch.no_grad():
+ ... logits = model(**inputs).logits
+
+ >>> # Get top 5 predictions
+ >>> top5_probabilities, top5_class_indices = torch.topk(logits.softmax(dim=1) * 100, k=5)
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ if output_attentions:
+ raise ValueError("Cannot set `output_attentions` for timm models.")
+
+ if output_hidden_states and not hasattr(self.timm_model, "forward_intermediates"):
+ raise ValueError(
+ "The 'output_hidden_states' option cannot be set for this timm model. "
+ "To enable this feature, the 'forward_intermediates' method must be implemented "
+ "in the timm model (available in timm versions > 1.*). Please consider using a "
+ "different architecture or updating the timm package to a compatible version."
+ )
+
+ pixel_values = pixel_values.to(self.device, self.dtype)
+
+ if output_hidden_states:
+ # to enable hidden states selection
+ if isinstance(output_hidden_states, (list, tuple)):
+ kwargs["indices"] = output_hidden_states
+ last_hidden_state, hidden_states = self.timm_model.forward_intermediates(pixel_values, **kwargs)
+ logits = self.timm_model.forward_head(last_hidden_state)
+ else:
+ logits = self.timm_model(pixel_values, **kwargs)
+ hidden_states = None
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ outputs = (loss, logits, hidden_states)
+ outputs = tuple(output for output in outputs if output is not None)
+ return outputs
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=hidden_states,
+ )
+
+
+__all__ = ["TimmWrapperPreTrainedModel", "TimmWrapperModel", "TimmWrapperForImageClassification"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..96ae1927c1b56002e6d3cf20f1fea145854f53f3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_trocr import *
+ from .modeling_trocr import *
+ from .processing_trocr import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/configuration_trocr.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/configuration_trocr.py
new file mode 100644
index 0000000000000000000000000000000000000000..c7d1e316b10e3a8806450a30979b7b179468ad30
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/configuration_trocr.py
@@ -0,0 +1,146 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TrOCR model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class TrOCRConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TrOCRForCausalLM`]. It is used to instantiate an
+ TrOCR model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the TrOCR
+ [microsoft/trocr-base-handwritten](https://huggingface.co/microsoft/trocr-base-handwritten) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 50265):
+ Vocabulary size of the TrOCR model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`TrOCRForCausalLM`].
+ d_model (`int`, *optional*, defaults to 1024):
+ Dimensionality of the layers and the pooler layer.
+ decoder_layers (`int`, *optional*, defaults to 12):
+ Number of decoder layers.
+ decoder_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ decoder_ffn_dim (`int`, *optional*, defaults to 4096):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in decoder.
+ activation_function (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the pooler. If string, `"gelu"`, `"relu"`,
+ `"silu"` and `"gelu_new"` are supported.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, and pooler.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for activations inside the fully connected layer.
+ init_std (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ decoder_layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the decoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+ scale_embedding (`bool`, *optional*, defaults to `False`):
+ Whether or not to scale the word embeddings by sqrt(d_model).
+ use_learned_position_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether or not to use learned position embeddings. If not, sinusoidal position embeddings will be used.
+ layernorm_embedding (`bool`, *optional*, defaults to `True`):
+ Whether or not to use a layernorm after the word + position embeddings.
+
+ Example:
+
+ ```python
+ >>> from transformers import TrOCRConfig, TrOCRForCausalLM
+
+ >>> # Initializing a TrOCR-base style configuration
+ >>> configuration = TrOCRConfig()
+
+ >>> # Initializing a model (with random weights) from the TrOCR-base style configuration
+ >>> model = TrOCRForCausalLM(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "trocr"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {
+ "num_attention_heads": "decoder_attention_heads",
+ "hidden_size": "d_model",
+ "num_hidden_layers": "decoder_layers",
+ }
+
+ def __init__(
+ self,
+ vocab_size=50265,
+ d_model=1024,
+ decoder_layers=12,
+ decoder_attention_heads=16,
+ decoder_ffn_dim=4096,
+ activation_function="gelu",
+ max_position_embeddings=512,
+ dropout=0.1,
+ attention_dropout=0.0,
+ activation_dropout=0.0,
+ decoder_start_token_id=2,
+ init_std=0.02,
+ decoder_layerdrop=0.0,
+ use_cache=True,
+ scale_embedding=False,
+ use_learned_position_embeddings=True,
+ layernorm_embedding=True,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.d_model = d_model
+ self.decoder_layers = decoder_layers
+ self.decoder_attention_heads = decoder_attention_heads
+ self.decoder_ffn_dim = decoder_ffn_dim
+ self.activation_function = activation_function
+ self.max_position_embeddings = max_position_embeddings
+ self.dropout = dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.init_std = init_std
+ self.decoder_layerdrop = decoder_layerdrop
+ self.use_cache = use_cache
+ self.scale_embedding = scale_embedding
+ self.use_learned_position_embeddings = use_learned_position_embeddings
+ self.layernorm_embedding = layernorm_embedding
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ decoder_start_token_id=decoder_start_token_id,
+ **kwargs,
+ )
+
+
+__all__ = ["TrOCRConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/modeling_trocr.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/modeling_trocr.py
new file mode 100644
index 0000000000000000000000000000000000000000..298c3fd2cb62433122e6515a09fe9cd8a15c2277
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/modeling_trocr.py
@@ -0,0 +1,864 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch TrOCR decoder model (based on RoBERTa)."""
+
+import math
+from typing import Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import (
+ _prepare_4d_attention_mask,
+ _prepare_4d_causal_attention_mask,
+)
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutputWithPastAndCrossAttentions, CausalLMOutputWithCrossAttentions
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_trocr import TrOCRConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.bart.modeling_bart.BartLearnedPositionalEmbedding with Bart->TrOCR
+class TrOCRLearnedPositionalEmbedding(nn.Embedding):
+ """
+ This module learns positional embeddings up to a fixed maximum size.
+ """
+
+ def __init__(self, num_embeddings: int, embedding_dim: int):
+ # TrOCR is set up so that if padding_idx is specified then offset the embedding ids by 2
+ # and adjust num_embeddings appropriately. Other models don't have this hack
+ self.offset = 2
+ super().__init__(num_embeddings + self.offset, embedding_dim)
+
+ def forward(self, input_ids: torch.Tensor, past_key_values_length: int = 0, position_ids: torch.Tensor = None):
+ """`input_ids' shape is expected to be [bsz x seqlen]."""
+
+ if position_ids is None:
+ bsz, seq_len = input_ids.shape[:2]
+ position_ids = torch.arange(
+ past_key_values_length, past_key_values_length + seq_len, dtype=torch.long, device=self.weight.device
+ ).expand(bsz, -1)
+ else:
+ position_ids = position_ids.unsqueeze(0)
+
+ return super().forward(position_ids + self.offset)
+
+
+# Copied from transformers.models.bart.modeling_bart.BartScaledWordEmbedding with Bart->TrOCR
+class TrOCRScaledWordEmbedding(nn.Embedding):
+ """
+ This module overrides nn.Embeddings' forward by multiplying with embeddings scale.
+ """
+
+ def __init__(self, num_embeddings: int, embedding_dim: int, padding_idx: int, embed_scale: Optional[float] = 1.0):
+ super().__init__(num_embeddings, embedding_dim, padding_idx)
+ self.embed_scale = embed_scale
+
+ def forward(self, input_ids: torch.Tensor):
+ return super().forward(input_ids) * self.embed_scale
+
+
+class TrOCRSinusoidalPositionalEmbedding(nn.Module):
+ """This module produces sinusoidal positional embeddings of any length."""
+
+ def __init__(self, num_positions: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ super().__init__()
+ self.offset = 2
+ self.embedding_dim = embedding_dim
+ self.padding_idx = padding_idx
+ self.weights = self.get_embedding(num_positions, embedding_dim, padding_idx)
+ self.register_buffer("_float_tensor", torch.FloatTensor(1))
+
+ @staticmethod
+ def get_embedding(num_embeddings: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ """
+ Build sinusoidal embeddings. This matches the implementation in tensor2tensor, but differs slightly from the
+ description in Section 3.5 of "Attention Is All You Need".
+ """
+ half_dim = embedding_dim // 2
+ emb = math.log(10000) / (half_dim - 1)
+ emb = torch.exp(torch.arange(half_dim, dtype=torch.int64).float() * -emb)
+ emb = torch.arange(num_embeddings, dtype=torch.int64).float().unsqueeze(1) * emb.unsqueeze(0)
+ emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1).view(num_embeddings, -1)
+ if embedding_dim % 2 == 1:
+ # zero pad
+ emb = torch.cat([emb, torch.zeros(num_embeddings, 1)], dim=1)
+ if padding_idx is not None:
+ emb[padding_idx, :] = 0
+
+ return emb.to(torch.get_default_dtype())
+
+ @torch.no_grad()
+ def forward(self, input_ids: torch.Tensor, past_key_values_length: int = 0):
+ bsz, seq_len = input_ids.size()
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = self.create_position_ids_from_input_ids(input_ids, self.padding_idx, past_key_values_length).to(
+ input_ids.device
+ )
+
+ # expand embeddings if needed
+ max_pos = self.padding_idx + 1 + seq_len
+ if self.weights is None or max_pos > self.weights.size(0):
+ # recompute/expand embeddings if needed
+ self.weights = self.get_embedding(max_pos, self.embedding_dim, self.padding_idx)
+ self.weights = self.weights.to(self._float_tensor)
+
+ x = self.weights.index_select(0, position_ids.view(-1)).view(bsz, seq_len, -1).detach()
+
+ return x
+
+ def create_position_ids_from_input_ids(
+ self, input_ids: torch.Tensor, padding_idx: int, past_key_values_length: Optional[int] = 0
+ ):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding
+ symbols are ignored. This is modified from fairseq's `utils.make_positions`.
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = input_ids.ne(padding_idx).int()
+ incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask
+ return incremental_indices.long() + padding_idx
+
+
+class TrOCRAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper."""
+
+ def __init__(
+ self,
+ config,
+ embed_dim: int,
+ num_heads: int,
+ kdim: Optional[int] = None,
+ vdim: Optional[int] = None,
+ dropout: Optional[float] = 0.0,
+ is_decoder: Optional[bool] = False,
+ bias: Optional[bool] = True,
+ is_cross_attention: Optional[bool] = False,
+ layer_idx: Optional[bool] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.kdim = kdim if kdim is not None else embed_dim
+ self.vdim = vdim if vdim is not None else embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ if not (self.head_dim * num_heads == self.embed_dim):
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.layer_idx = layer_idx
+
+ self.k_proj = nn.Linear(self.kdim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(self.vdim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ bsz, tgt_len, embed_dim = hidden_states.size()
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k_proj(current_states)
+ value_states = self.v_proj(current_states)
+ key_states = key_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = query_states.view(bsz, tgt_len, self.num_heads, self.head_dim).transpose(1, 2)
+ query_states = query_states.reshape(*proj_shape)
+ key_states = key_states.reshape(*proj_shape)
+ value_states = value_states.reshape(*proj_shape)
+
+ src_len = key_states.size(1)
+ attn_weights = torch.bmm(query_states, key_states.transpose(1, 2))
+
+ if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len):
+ raise ValueError(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ if attention_mask is not None:
+ if attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is {attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attention_mask
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if layer_head_mask is not None:
+ if layer_head_mask.size() != (self.num_heads,):
+ raise ValueError(
+ f"Head mask for a single layer should be of size {(self.num_heads,)}, but is"
+ f" {layer_head_mask.size()}"
+ )
+ attn_weights = layer_head_mask.view(1, -1, 1, 1) * attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ if output_attentions:
+ # this operation is a bit awkward, but it's required to
+ # make sure that attn_weights keeps its gradient.
+ # In order to do so, attn_weights have to be reshaped
+ # twice and have to be reused in the following
+ attn_weights_reshaped = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights_reshaped.view(bsz * self.num_heads, tgt_len, src_len)
+ else:
+ attn_weights_reshaped = None
+
+ attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ attn_output = torch.bmm(attn_probs, value_states)
+
+ if attn_output.size() != (bsz * self.num_heads, tgt_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim)
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights_reshaped
+
+
+class TrOCRDecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: TrOCRConfig, layer_idx=None):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+
+ self.self_attn = TrOCRAttention(
+ config,
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ layer_idx=layer_idx,
+ )
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ if config.is_decoder:
+ self.encoder_attn = TrOCRAttention(
+ config,
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ kdim=config.cross_attention_hidden_size,
+ vdim=config.cross_attention_hidden_size,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ is_cross_attention=True,
+ layer_idx=layer_idx,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim)
+ self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_layer_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = True,
+ cache_position: Optional[torch.Tensor] = None,
+ ):
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`torch.FloatTensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ cross_attn_layer_head_mask (`torch.FloatTensor`): mask for cross-attention heads in a given layer of
+ size *(decoder_attention_heads,)*.
+ past_key_values (`Tuple(torch.FloatTensor)`): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_values=past_key_values,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+@auto_docstring
+class TrOCRPreTrainedModel(PreTrainedModel):
+ config: TrOCRConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["TrOCRDecoderLayer"]
+
+ def _init_weights(self, module):
+ std = self.config.init_std
+ if isinstance(module, (nn.Linear, nn.Conv1d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+class TrOCRDecoder(TrOCRPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`TrOCRDecoderLayer`]
+
+ Args:
+ config: TrOCRConfig
+ """
+
+ def __init__(self, config: TrOCRConfig):
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.decoder_layerdrop
+ self.padding_idx = config.pad_token_id
+ embed_scale = math.sqrt(config.hidden_size) if config.scale_embedding else 1.0
+
+ self.embed_tokens = TrOCRScaledWordEmbedding(
+ config.vocab_size, config.hidden_size, self.padding_idx, embed_scale=embed_scale
+ )
+
+ if config.use_learned_position_embeddings:
+ self.embed_positions = TrOCRLearnedPositionalEmbedding(config.max_position_embeddings, config.hidden_size)
+ else:
+ self.embed_positions = TrOCRSinusoidalPositionalEmbedding(
+ config.max_position_embeddings + self.padding_idx + 1,
+ config.hidden_size,
+ self.padding_idx,
+ )
+
+ if config.layernorm_embedding:
+ self.layernorm_embedding = nn.LayerNorm(config.hidden_size)
+ else:
+ self.layernorm_embedding = None
+
+ self.layers = nn.ModuleList([TrOCRDecoderLayer(config, layer_idx=i) for i in range(config.decoder_layers)])
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ inputs_embeds=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ cache_position=None,
+ ):
+ r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you
+ provide it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in encoder to avoid performing cross-attention
+ on hidden heads. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of
+ shape `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and in the
+ cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those
+ that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of
+ all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time")
+ elif input_ids is not None:
+ input = input_ids
+ input_ids = input_ids.view(-1, input.shape[-1])
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ input = inputs_embeds[:, :, -1]
+ else:
+ raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds")
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache = True` is incompatible with gradient checkpointing. Setting `use_cache = False`..."
+ )
+ use_cache = False
+
+ if use_cache and past_key_values is None:
+ past_key_values = (
+ EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if encoder_hidden_states is not None
+ else DynamicCache(config=self.config)
+ )
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if self.config.use_learned_position_embeddings:
+ embed_pos = self.embed_positions(input, past_key_values_length=past_key_values_length)
+ else:
+ embed_pos = self.embed_positions(input_ids, past_key_values_length=past_key_values_length)
+
+ hidden_states = inputs_embeds + embed_pos
+
+ if self.layernorm_embedding is not None:
+ hidden_states = self.layernorm_embedding(hidden_states)
+
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ input_shape = input.shape
+
+ attention_mask = _prepare_4d_causal_attention_mask(
+ attention_mask, input_shape, inputs_embeds, past_key_values_length
+ )
+
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(
+ encoder_attention_mask, inputs_embeds.dtype, tgt_len=input_shape[-1]
+ )
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ # check if head_mask/cross_attn_head_mask has a correct number of layers specified if desired
+ for attn_mask, mask_name in zip([head_mask, cross_attn_head_mask], ["head_mask", "cross_attn_head_mask"]):
+ if attn_mask is not None:
+ if attn_mask.size()[0] != (len(self.layers)):
+ raise ValueError(
+ f"The `{mask_name}` should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop:
+ continue
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The TrOCR Model with a language modeling head. Can be used for summarization.
+ This wrapper class is a helper class to correctly load pretrained checkpoints when the causal language model is
+ used in combination with the [`EncoderDecoderModel`] framework.
+ """
+)
+class TrOCRDecoderWrapper(TrOCRPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.decoder = TrOCRDecoder(config)
+
+ def forward(self, *args, **kwargs):
+ return self.decoder(*args, **kwargs)
+
+
+@auto_docstring(
+ custom_intro="""
+ The TrOCR Decoder with a language modeling head. Can be used as the decoder part of [`EncoderDecoderModel`] and
+ """
+)
+class TrOCRForCausalLM(TrOCRPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["output_projection.weight"]
+
+ def __init__(self, config):
+ config.is_decoder = True
+ config.is_encoder_decoder = False
+ super().__init__(config)
+ self.model = TrOCRDecoderWrapper(config)
+
+ self.output_projection = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.decoder.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.model.decoder.embed_tokens = value
+
+ def get_output_embeddings(self):
+ return self.output_projection
+
+ def set_output_embeddings(self, new_embeddings):
+ self.output_projection = new_embeddings
+
+ def set_decoder(self, decoder):
+ self.model.decoder = decoder
+
+ def get_decoder(self):
+ return self.model.decoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutputWithCrossAttentions]:
+ r"""
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> from transformers import (
+ ... TrOCRConfig,
+ ... TrOCRProcessor,
+ ... TrOCRForCausalLM,
+ ... ViTConfig,
+ ... ViTModel,
+ ... VisionEncoderDecoderModel,
+ ... )
+ >>> import requests
+ >>> from PIL import Image
+
+ >>> # TrOCR is a decoder model and should be used within a VisionEncoderDecoderModel
+ >>> # init vision2text model with random weights
+ >>> encoder = ViTModel(ViTConfig())
+ >>> decoder = TrOCRForCausalLM(TrOCRConfig())
+ >>> model = VisionEncoderDecoderModel(encoder=encoder, decoder=decoder)
+
+ >>> # If you want to start from the pretrained model, load the checkpoint with `VisionEncoderDecoderModel`
+ >>> processor = TrOCRProcessor.from_pretrained("microsoft/trocr-base-handwritten")
+ >>> model = VisionEncoderDecoderModel.from_pretrained("microsoft/trocr-base-handwritten")
+
+ >>> # load image from the IAM dataset
+ >>> url = "https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+ >>> pixel_values = processor(image, return_tensors="pt").pixel_values
+ >>> text = "industry, ' Mr. Brown commented icily. ' Let us have a"
+
+ >>> # training
+ >>> model.config.decoder_start_token_id = processor.tokenizer.eos_token_id
+ >>> model.config.pad_token_id = processor.tokenizer.pad_token_id
+ >>> model.config.vocab_size = model.config.decoder.vocab_size
+
+ >>> labels = processor.tokenizer(text, return_tensors="pt").input_ids
+ >>> outputs = model(pixel_values, labels=labels)
+ >>> loss = outputs.loss
+ >>> round(loss.item(), 2)
+ 5.30
+
+ >>> # inference
+ >>> generated_ids = model.generate(pixel_values)
+ >>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+ >>> generated_text
+ 'industry, " Mr. Brown commented icily. " Let us have a'
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
+ outputs = self.model.decoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ logits = self.output_projection(outputs[0])
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return (loss,) + output if loss is not None else output
+
+ return CausalLMOutputWithCrossAttentions(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+__all__ = ["TrOCRForCausalLM", "TrOCRPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/processing_trocr.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/processing_trocr.py
new file mode 100644
index 0000000000000000000000000000000000000000..52cd1dc041db7f45346db8668266d92d9dfbd614
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/trocr/processing_trocr.py
@@ -0,0 +1,150 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Processor class for TrOCR.
+"""
+
+import warnings
+from contextlib import contextmanager
+from typing import Union
+
+from ...image_processing_utils import BatchFeature
+from ...image_utils import ImageInput
+from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack
+from ...tokenization_utils_base import PreTokenizedInput, TextInput
+
+
+class TrOCRProcessorKwargs(ProcessingKwargs, total=False):
+ _defaults = {}
+
+
+class TrOCRProcessor(ProcessorMixin):
+ r"""
+ Constructs a TrOCR processor which wraps a vision image processor and a TrOCR tokenizer into a single processor.
+
+ [`TrOCRProcessor`] offers all the functionalities of [`ViTImageProcessor`/`DeiTImageProcessor`] and
+ [`RobertaTokenizer`/`XLMRobertaTokenizer`]. See the [`~TrOCRProcessor.__call__`] and [`~TrOCRProcessor.decode`] for
+ more information.
+
+ Args:
+ image_processor ([`ViTImageProcessor`/`DeiTImageProcessor`], *optional*):
+ An instance of [`ViTImageProcessor`/`DeiTImageProcessor`]. The image processor is a required input.
+ tokenizer ([`RobertaTokenizer`/`XLMRobertaTokenizer`], *optional*):
+ An instance of [`RobertaTokenizer`/`XLMRobertaTokenizer`]. The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+ image_processor_class = "AutoImageProcessor"
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(self, image_processor=None, tokenizer=None, **kwargs):
+ feature_extractor = None
+ if "feature_extractor" in kwargs:
+ warnings.warn(
+ "The `feature_extractor` argument is deprecated and will be removed in v5, use `image_processor`"
+ " instead.",
+ FutureWarning,
+ )
+ feature_extractor = kwargs.pop("feature_extractor")
+
+ image_processor = image_processor if image_processor is not None else feature_extractor
+ if image_processor is None:
+ raise ValueError("You need to specify an `image_processor`.")
+ if tokenizer is None:
+ raise ValueError("You need to specify a `tokenizer`.")
+
+ super().__init__(image_processor, tokenizer)
+ self.current_processor = self.image_processor
+ self._in_target_context_manager = False
+
+ def __call__(
+ self,
+ images: ImageInput = None,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ audio=None,
+ videos=None,
+ **kwargs: Unpack[TrOCRProcessorKwargs],
+ ) -> BatchFeature:
+ """
+ When used in normal mode, this method forwards all its arguments to AutoImageProcessor's
+ [`~AutoImageProcessor.__call__`] and returns its output. If used in the context
+ [`~TrOCRProcessor.as_target_processor`] this method forwards all its arguments to TrOCRTokenizer's
+ [`~TrOCRTokenizer.__call__`]. Please refer to the docstring of the above two methods for more information.
+ """
+ # For backward compatibility
+ if self._in_target_context_manager:
+ return self.current_processor(images, **kwargs)
+
+ if images is None and text is None:
+ raise ValueError("You need to specify either an `images` or `text` input to process.")
+
+ output_kwargs = self._merge_kwargs(
+ TrOCRProcessorKwargs,
+ tokenizer_init_kwargs=self.tokenizer.init_kwargs,
+ **kwargs,
+ )
+
+ if images is not None:
+ inputs = self.image_processor(images, **output_kwargs["images_kwargs"])
+ if text is not None:
+ encodings = self.tokenizer(text, **output_kwargs["text_kwargs"])
+
+ if text is None:
+ return inputs
+ elif images is None:
+ return encodings
+ else:
+ inputs["labels"] = encodings["input_ids"]
+ return inputs
+
+ @property
+ def model_input_names(self):
+ image_processor_input_names = self.image_processor.model_input_names
+ return image_processor_input_names + ["labels"]
+
+ @contextmanager
+ def as_target_processor(self):
+ """
+ Temporarily sets the tokenizer for processing the input. Useful for encoding the labels when fine-tuning TrOCR.
+ """
+ warnings.warn(
+ "`as_target_processor` is deprecated and will be removed in v5 of Transformers. You can process your "
+ "labels by using the argument `text` of the regular `__call__` method (either in the same call as "
+ "your images inputs, or in a separate call."
+ )
+ self._in_target_context_manager = True
+ self.current_processor = self.tokenizer
+ yield
+ self.current_processor = self.image_processor
+ self._in_target_context_manager = False
+
+ @property
+ def feature_extractor_class(self):
+ warnings.warn(
+ "`feature_extractor_class` is deprecated and will be removed in v5. Use `image_processor_class` instead.",
+ FutureWarning,
+ )
+ return self.image_processor_class
+
+ @property
+ def feature_extractor(self):
+ warnings.warn(
+ "`feature_extractor` is deprecated and will be removed in v5. Use `image_processor` instead.",
+ FutureWarning,
+ )
+ return self.image_processor
+
+
+__all__ = ["TrOCRProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..7033f7a2e7f332115bd93eadba2761c269747709
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_tvp import *
+ from .image_processing_tvp import *
+ from .image_processing_tvp_fast import *
+ from .modeling_tvp import *
+ from .processing_tvp import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/configuration_tvp.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/configuration_tvp.py
new file mode 100644
index 0000000000000000000000000000000000000000..be7c785084d17c4e35720ee353bb1b217eff95f7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/configuration_tvp.py
@@ -0,0 +1,209 @@
+# coding=utf-8
+# Copyright 2023 The Intel AIA Team Authors, and HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License=, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing=, software
+# distributed under the License is distributed on an "AS IS" BASIS=,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND=, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TVP model configuration"""
+
+import copy
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ...utils.backbone_utils import verify_backbone_config_arguments
+from ..auto import CONFIG_MAPPING
+
+
+logger = logging.get_logger(__name__)
+
+
+class TvpConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`TvpModel`]. It is used to instantiate an Tvp
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the Tvp
+ [Intel/tvp-base](https://huggingface.co/Intel/tvp-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ backbone_config (`PretrainedConfig` or `dict`, *optional*):
+ The configuration of the backbone model.
+ backbone (`str`, *optional*):
+ Name of backbone to use when `backbone_config` is `None`. If `use_pretrained_backbone` is `True`, this
+ will load the corresponding pretrained weights from the timm or transformers library. If `use_pretrained_backbone`
+ is `False`, this loads the backbone's config and uses that to initialize the backbone with random weights.
+ use_pretrained_backbone (`bool`, *optional*, defaults to `False`):
+ Whether to use pretrained weights for the backbone.
+ use_timm_backbone (`bool`, *optional*, defaults to `False`):
+ Whether to load `backbone` from the timm library. If `False`, the backbone is loaded from the transformers
+ library.
+ backbone_kwargs (`dict`, *optional*):
+ Keyword arguments to be passed to AutoBackbone when loading from a checkpoint
+ e.g. `{'out_indices': (0, 1, 2, 3)}`. Cannot be specified if `backbone_config` is set.
+ distance_loss_weight (`float`, *optional*, defaults to 1.0):
+ The weight of distance loss.
+ duration_loss_weight (`float`, *optional*, defaults to 0.1):
+ The weight of duration loss.
+ visual_prompter_type (`str`, *optional*, defaults to `"framepad"`):
+ Visual prompt type. The type of padding. Framepad means padding on each frame. Should be one of "framepad"
+ or "framedownpad"
+ visual_prompter_apply (`str`, *optional*, defaults to `"replace"`):
+ The way of applying visual prompt. Replace means use the value of prompt to change the original value in
+ visual inputs. Should be one of "replace", or "add", or "remove".
+ visual_prompt_size (`int`, *optional*, defaults to 96):
+ The size of visual prompt.
+ max_img_size (`int`, *optional*, defaults to 448):
+ The maximum size of frame.
+ num_frames (`int`, *optional*, defaults to 48):
+ The number of frames extracted from a video.
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the Tvp text model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`TvpModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ max_grid_col_position_embeddings (`int`, *optional*, defaults to 100):
+ The largest number of horizontal patches from a video frame.
+ max_grid_row_position_embeddings (`int`, *optional*, defaults to 100):
+ The largest number of vertical patches from a video frame.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability of hidden layers.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability of attention layers.
+ """
+
+ model_type = "tvp"
+
+ def __init__(
+ self,
+ backbone_config=None,
+ backbone=None,
+ use_pretrained_backbone=False,
+ use_timm_backbone=False,
+ backbone_kwargs=None,
+ distance_loss_weight=1.0,
+ duration_loss_weight=0.1,
+ visual_prompter_type="framepad",
+ visual_prompter_apply="replace",
+ visual_prompt_size=96,
+ max_img_size=448,
+ num_frames=48,
+ vocab_size=30522,
+ hidden_size=768,
+ intermediate_size=3072,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ max_position_embeddings=512,
+ max_grid_col_position_embeddings=100,
+ max_grid_row_position_embeddings=100,
+ hidden_dropout_prob=0.1,
+ hidden_act="gelu",
+ layer_norm_eps=1e-12,
+ initializer_range=0.02,
+ attention_probs_dropout_prob=0.1,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ if backbone_config is None and backbone is None:
+ logger.info("`backbone_config` is `None`. Initializing the config with the default `ResNet` backbone.")
+ backbone_config = CONFIG_MAPPING["resnet"](out_features=["stage4"])
+ elif isinstance(backbone_config, dict):
+ backbone_model_type = backbone_config.get("model_type")
+ config_class = CONFIG_MAPPING[backbone_model_type]
+ backbone_config = config_class.from_dict(backbone_config)
+
+ verify_backbone_config_arguments(
+ use_timm_backbone=use_timm_backbone,
+ use_pretrained_backbone=use_pretrained_backbone,
+ backbone=backbone,
+ backbone_config=backbone_config,
+ backbone_kwargs=backbone_kwargs,
+ )
+
+ self.backbone_config = backbone_config
+ self.backbone = backbone
+ self.use_pretrained_backbone = use_pretrained_backbone
+ self.use_timm_backbone = use_timm_backbone
+ self.backbone_kwargs = backbone_kwargs
+ self.distance_loss_weight = distance_loss_weight
+ self.duration_loss_weight = duration_loss_weight
+ self.visual_prompter_type = visual_prompter_type
+ self.visual_prompter_apply = visual_prompter_apply
+ self.visual_prompt_size = visual_prompt_size
+ self.max_img_size = max_img_size
+ self.num_frames = num_frames
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.max_position_embeddings = max_position_embeddings
+ self.max_grid_col_position_embeddings = max_grid_col_position_embeddings
+ self.max_grid_row_position_embeddings = max_grid_row_position_embeddings
+ self.layer_norm_eps = layer_norm_eps
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+
+ @property
+ def sub_configs(self):
+ return (
+ {"backbone_config": type(self.backbone_config)}
+ if getattr(self, "backbone_config", None) is not None
+ else {}
+ )
+
+ @classmethod
+ def from_backbone_config(cls, backbone_config: PretrainedConfig, **kwargs):
+ """Instantiate a [`TvpConfig`] (or a derived class) from a pre-trained backbone model configuration.
+
+ Args:
+ backbone_config ([`PretrainedConfig`]):
+ The backbone configuration.
+ Returns:
+ [`TvpConfig`]: An instance of a configuration object
+ """
+ return cls(backbone_config=backbone_config, **kwargs)
+
+ def to_dict(self):
+ """
+ Serializes this instance to a Python dictionary. Override the default [`~PretrainedConfig.to_dict`].
+
+ Returns:
+ `dict[str, any]`: Dictionary of all the attributes that make up this configuration instance,
+ """
+ output = copy.deepcopy(self.__dict__)
+ if output["backbone_config"] is not None:
+ output["backbone_config"] = self.backbone_config.to_dict()
+ output["model_type"] = self.__class__.model_type
+ return output
+
+
+__all__ = ["TvpConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/image_processing_tvp.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/image_processing_tvp.py
new file mode 100644
index 0000000000000000000000000000000000000000..d906c5e6bc708064e24d9b1e08db3bc06ba1e185
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/image_processing_tvp.py
@@ -0,0 +1,482 @@
+# coding=utf-8
+# Copyright 2023 The Intel AIA Team Authors, and HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License=, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing=, software
+# distributed under the License is distributed on an "AS IS" BASIS=,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND=, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for TVP."""
+
+from collections.abc import Iterable
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import (
+ PaddingMode,
+ flip_channel_order,
+ pad,
+ resize,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ get_image_size,
+ is_valid_image,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging
+
+
+if is_vision_available():
+ import PIL
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.vivit.image_processing_vivit.make_batched
+def make_batched(videos) -> list[list[ImageInput]]:
+ if isinstance(videos, (list, tuple)) and isinstance(videos[0], (list, tuple)) and is_valid_image(videos[0][0]):
+ return videos
+
+ elif isinstance(videos, (list, tuple)) and is_valid_image(videos[0]):
+ return [videos]
+
+ elif is_valid_image(videos):
+ return [[videos]]
+
+ raise ValueError(f"Could not make batched video from {videos}")
+
+
+def get_resize_output_image_size(
+ input_image: np.ndarray,
+ max_size: int = 448,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> tuple[int, int]:
+ height, width = get_image_size(input_image, input_data_format)
+ if height >= width:
+ ratio = width * 1.0 / height
+ new_height = max_size
+ new_width = new_height * ratio
+ else:
+ ratio = height * 1.0 / width
+ new_width = max_size
+ new_height = new_width * ratio
+ size = (int(new_height), int(new_width))
+
+ return size
+
+
+class TvpImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a Tvp image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by the
+ `do_resize` parameter in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"longest_edge": 448}`):
+ Size of the output image after resizing. The longest edge of the image will be resized to
+ `size["longest_edge"]` while maintaining the aspect ratio of the original image. Can be overridden by
+ `size` in the `preprocess` method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the
+ `preprocess` method.
+ do_center_crop (`bool`, *optional*, defaults to `True`):
+ Whether to center crop the image to the specified `crop_size`. Can be overridden by the `do_center_crop`
+ parameter in the `preprocess` method.
+ crop_size (`dict[str, int]`, *optional*, defaults to `{"height": 448, "width": 448}`):
+ Size of the image after applying the center crop. Can be overridden by the `crop_size` parameter in the
+ `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale`
+ parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Defines the scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter
+ in the `preprocess` method.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image. Can be overridden by the `do_pad` parameter in the `preprocess` method.
+ pad_size (`dict[str, int]`, *optional*, defaults to `{"height": 448, "width": 448}`):
+ Size of the image after applying the padding. Can be overridden by the `pad_size` parameter in the
+ `preprocess` method.
+ constant_values (`Union[float, Iterable[float]]`, *optional*, defaults to 0):
+ The fill value to use when padding the image.
+ pad_mode (`PaddingMode`, *optional*, defaults to `PaddingMode.CONSTANT`):
+ Use what kind of mode in padding.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method.
+ do_flip_channel_order (`bool`, *optional*, defaults to `True`):
+ Whether to flip the color channels from RGB to BGR. Can be overridden by the `do_flip_channel_order`
+ parameter in the `preprocess` method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_center_crop: bool = True,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_pad: bool = True,
+ pad_size: Optional[dict[str, int]] = None,
+ constant_values: Union[float, Iterable[float]] = 0,
+ pad_mode: PaddingMode = PaddingMode.CONSTANT,
+ do_normalize: bool = True,
+ do_flip_channel_order: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"longest_edge": 448}
+ crop_size = crop_size if crop_size is not None else {"height": 448, "width": 448}
+ pad_size = pad_size if pad_size is not None else {"height": 448, "width": 448}
+
+ self.do_resize = do_resize
+ self.size = size
+ self.do_center_crop = do_center_crop
+ self.crop_size = crop_size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_pad = do_pad
+ self.pad_size = pad_size
+ self.constant_values = constant_values
+ self.pad_mode = pad_mode
+ self.do_normalize = do_normalize
+ self.do_flip_channel_order = do_flip_channel_order
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Size of the output image. If `size` is of the form `{"height": h, "width": w}`, the output image will
+ have the size `(h, w)`. If `size` is of the form `{"longest_edge": s}`, the output image will have its
+ longest edge of length `s` while keeping the aspect ratio of the original image.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ Resampling filter to use when resiizing the image.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ size = get_size_dict(size, default_to_square=False)
+ if "height" in size and "width" in size:
+ output_size = (size["height"], size["width"])
+ elif "longest_edge" in size:
+ output_size = get_resize_output_image_size(image, size["longest_edge"], input_data_format)
+ else:
+ raise ValueError(f"Size must have 'height' and 'width' or 'longest_edge' as keys. Got {size.keys()}")
+
+ return resize(
+ image,
+ size=output_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ def pad_image(
+ self,
+ image: np.ndarray,
+ pad_size: Optional[dict[str, int]] = None,
+ constant_values: Union[float, Iterable[float]] = 0,
+ pad_mode: PaddingMode = PaddingMode.CONSTANT,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ):
+ """
+ Pad an image with zeros to the given size.
+
+ Args:
+ image (`np.ndarray`):
+ Image to pad.
+ pad_size (`dict[str, int]`)
+ Size of the output image with pad.
+ constant_values (`Union[float, Iterable[float]]`)
+ The fill value to use when padding the image.
+ pad_mode (`PaddingMode`)
+ The pad mode, default to PaddingMode.CONSTANT
+ data_format (`ChannelDimension` or `str`, *optional*)
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ height, width = get_image_size(image, channel_dim=input_data_format)
+ max_height = pad_size.get("height", height)
+ max_width = pad_size.get("width", width)
+
+ pad_right, pad_bottom = max_width - width, max_height - height
+ if pad_right < 0 or pad_bottom < 0:
+ raise ValueError("The padding size must be greater than image size")
+
+ padding = ((0, pad_bottom), (0, pad_right))
+ padded_image = pad(
+ image,
+ padding,
+ mode=pad_mode,
+ constant_values=constant_values,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+
+ return padded_image
+
+ def _preprocess_image(
+ self,
+ image: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_pad: bool = True,
+ pad_size: Optional[dict[str, int]] = None,
+ constant_values: Optional[Union[float, Iterable[float]]] = None,
+ pad_mode: PaddingMode = None,
+ do_normalize: Optional[bool] = None,
+ do_flip_channel_order: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ data_format: Optional[ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """Preprocesses a single image."""
+
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_pad=do_pad,
+ size_divisibility=pad_size, # here the pad() method simply requires the pad_size argument.
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ # All transformations expect numpy arrays.
+ image = to_numpy_array(image)
+
+ if do_resize:
+ image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+
+ if do_center_crop:
+ image = self.center_crop(image, size=crop_size, input_data_format=input_data_format)
+
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+
+ if do_normalize:
+ image = self.normalize(
+ image=image.astype(np.float32), mean=image_mean, std=image_std, input_data_format=input_data_format
+ )
+
+ if do_pad:
+ image = self.pad_image(
+ image=image,
+ pad_size=pad_size,
+ constant_values=constant_values,
+ pad_mode=pad_mode,
+ input_data_format=input_data_format,
+ )
+
+ # the pretrained checkpoints assume images are BGR, not RGB
+ if do_flip_channel_order:
+ image = flip_channel_order(image=image, input_data_format=input_data_format)
+
+ image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+
+ return image
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ videos: Union[ImageInput, list[ImageInput], list[list[ImageInput]]],
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_pad: Optional[bool] = None,
+ pad_size: Optional[dict[str, int]] = None,
+ constant_values: Optional[Union[float, Iterable[float]]] = None,
+ pad_mode: PaddingMode = None,
+ do_normalize: Optional[bool] = None,
+ do_flip_channel_order: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ videos (`ImageInput` or `list[ImageInput]` or `list[list[ImageInput]]`):
+ Frames to preprocess.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after applying resize.
+ resample (`PILImageResampling`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only
+ has an effect if `do_resize` is set to `True`.
+ do_center_crop (`bool`, *optional*, defaults to `self.do_centre_crop`):
+ Whether to centre crop the image.
+ crop_size (`dict[str, int]`, *optional*, defaults to `self.crop_size`):
+ Size of the image after applying the centre crop.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image. Can be overridden by the `do_pad` parameter in the `preprocess` method.
+ pad_size (`dict[str, int]`, *optional*, defaults to `{"height": 448, "width": 448}`):
+ Size of the image after applying the padding. Can be overridden by the `pad_size` parameter in the
+ `preprocess` method.
+ constant_values (`Union[float, Iterable[float]]`, *optional*, defaults to 0):
+ The fill value to use when padding the image.
+ pad_mode (`PaddingMode`, *optional*, defaults to "PaddingMode.CONSTANT"):
+ Use what kind of mode in padding.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ do_flip_channel_order (`bool`, *optional*, defaults to `self.do_flip_channel_order`):
+ Whether to flip the channel order of the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the inferred channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ resample = resample if resample is not None else self.resample
+ do_center_crop = do_center_crop if do_center_crop is not None else self.do_center_crop
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_pad = do_pad if do_pad is not None else self.do_pad
+ pad_size = pad_size if pad_size is not None else self.pad_size
+ constant_values = constant_values if constant_values is not None else self.constant_values
+ pad_mode = pad_mode if pad_mode else self.pad_mode
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ do_flip_channel_order = (
+ do_flip_channel_order if do_flip_channel_order is not None else self.do_flip_channel_order
+ )
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+
+ size = size if size is not None else self.size
+ size = get_size_dict(size, default_to_square=False)
+ crop_size = crop_size if crop_size is not None else self.crop_size
+ crop_size = get_size_dict(crop_size, param_name="crop_size")
+
+ if not valid_images(videos):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ videos = make_batched(videos)
+
+ videos = [
+ np.array(
+ [
+ self._preprocess_image(
+ image=img,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_pad=do_pad,
+ pad_size=pad_size,
+ constant_values=constant_values,
+ pad_mode=pad_mode,
+ do_normalize=do_normalize,
+ do_flip_channel_order=do_flip_channel_order,
+ image_mean=image_mean,
+ image_std=image_std,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ for img in video
+ ]
+ )
+ for video in videos
+ ]
+
+ data = {"pixel_values": videos}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["TvpImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/image_processing_tvp_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/image_processing_tvp_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..3eec7e2d9c3dbb831e6cc6b4e4cb84af54f64974
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/image_processing_tvp_fast.py
@@ -0,0 +1,297 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for TVP."""
+
+from typing import Optional, Union
+
+from ...image_processing_utils import BatchFeature, get_size_dict
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ImageInput,
+ PILImageResampling,
+ SizeDict,
+ make_nested_list_of_images,
+)
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+)
+
+
+if is_torch_available():
+ import torch
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+
+class TvpFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ r"""
+ do_flip_channel_order (`bool`, *optional*):
+ Whether to flip the channel order of the image from RGB to BGR.
+ do_pad (`bool`, *optional*):
+ Whether to pad the image.
+ pad_size (`Dict[str, int]` or `SizeDict`, *optional*):
+ Size dictionary specifying the desired height and width for padding.
+ constant_values (`float` or `List[float]`, *optional*):
+ Value used to fill the padding area when `pad_mode` is `'constant'`.
+ pad_mode (`str`, *optional*):
+ Padding mode to use — `'constant'`, `'edge'`, `'reflect'`, or `'symmetric'`.
+ """
+
+ do_flip_channel_order: Optional[bool]
+ do_pad: Optional[bool]
+ pad_size: Optional[SizeDict]
+ constant_values: Optional[Union[float, list[float]]]
+ pad_mode: Optional[str]
+
+
+@auto_docstring
+class TvpImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BILINEAR
+ image_mean = IMAGENET_STANDARD_MEAN
+ image_std = IMAGENET_STANDARD_STD
+ size = {"longest_edge": 448}
+ default_to_square = False
+ crop_size = {"height": 448, "width": 448}
+ do_resize = True
+ do_center_crop = True
+ do_rescale = True
+ rescale_factor = 1 / 255
+ do_pad = True
+ pad_size = {"height": 448, "width": 448}
+ constant_values = 0
+ pad_mode = "constant"
+ do_normalize = True
+ do_flip_channel_order = True
+ valid_kwargs = TvpFastImageProcessorKwargs
+
+ def __init__(self, **kwargs: Unpack[TvpFastImageProcessorKwargs]):
+ super().__init__(**kwargs)
+
+ @auto_docstring
+ def preprocess(
+ self,
+ videos: Union[ImageInput, list[ImageInput], list[list[ImageInput]]],
+ **kwargs: Unpack[TvpFastImageProcessorKwargs],
+ ) -> BatchFeature:
+ """
+ Preprocess videos using the fast image processor.
+ """
+ return super().preprocess(videos, **kwargs)
+
+ def _further_process_kwargs(
+ self,
+ pad_size: Optional[SizeDict] = None,
+ **kwargs,
+ ) -> dict:
+ """
+ Update kwargs that need further processing before being validated
+ Can be overridden by subclasses to customize the processing of kwargs.
+ """
+ if pad_size is not None:
+ pad_size = SizeDict(**get_size_dict(pad_size, param_name="pad_size"))
+ kwargs["pad_size"] = pad_size
+
+ return super()._further_process_kwargs(**kwargs)
+
+ def _prepare_images_structure(
+ self,
+ images: ImageInput,
+ **kwargs,
+ ) -> ImageInput:
+ """
+ Prepare the images structure for processing.
+
+ Args:
+ images (`ImageInput`):
+ The input images to process.
+
+ Returns:
+ `ImageInput`: The images with a valid nesting.
+ """
+ return make_nested_list_of_images(images, **kwargs)
+
+ def _pad_frames(
+ self,
+ frames: "torch.Tensor",
+ pad_size: Union[SizeDict, dict],
+ constant_values: Union[float, list[float]],
+ pad_mode: str,
+ ) -> "torch.Tensor":
+ """Pad frames to the specified size."""
+ height, width = pad_size.height, pad_size.width
+
+ if frames.shape[-2:] == (height, width):
+ return frames
+
+ # Calculate padding
+ current_height, current_width = frames.shape[-2:]
+ pad_bottom = height - current_height
+ pad_right = width - current_width
+
+ if pad_bottom < 0 or pad_right < 0:
+ raise ValueError("The padding size must be greater than frame size")
+
+ # Apply padding
+ padding = [0, 0, pad_right, pad_bottom] # [left, top, right, bottom]
+ return F.pad(frames, padding, fill=constant_values, padding_mode=pad_mode)
+
+ def resize(
+ self,
+ image: "torch.Tensor",
+ size: SizeDict,
+ interpolation: "F.InterpolationMode" = None,
+ antialias: bool = True,
+ **kwargs,
+ ) -> "torch.Tensor":
+ """
+ Resize an image to the specified size.
+
+ Args:
+ image (`torch.Tensor`):
+ Image to resize.
+ size (`SizeDict` or `dict`):
+ Size dictionary. If `size` has `longest_edge`, resize the longest edge to that value
+ while maintaining aspect ratio. Otherwise, use the base class resize method.
+ interpolation (`F.InterpolationMode`, *optional*):
+ Interpolation method to use.
+ antialias (`bool`, *optional*, defaults to `True`):
+ Whether to use antialiasing.
+
+ Returns:
+ `torch.Tensor`: The resized image.
+ """
+ interpolation = interpolation if interpolation is not None else F.InterpolationMode.BILINEAR
+
+ # Handle longest_edge case (TVP-specific)
+ if size.longest_edge:
+ # Get current dimensions
+ current_height, current_width = image.shape[-2:]
+
+ # Calculate new dimensions maintaining aspect ratio
+ if current_height >= current_width:
+ ratio = current_width * 1.0 / current_height
+ new_height = size.longest_edge
+ new_width = int(new_height * ratio)
+ else:
+ ratio = current_height * 1.0 / current_width
+ new_width = size.longest_edge
+ new_height = int(new_width * ratio)
+
+ return super().resize(
+ image, SizeDict(height=new_height, width=new_width), interpolation=interpolation, antialias=antialias
+ )
+
+ # Use base class resize method for other cases
+ return super().resize(image, size, interpolation, antialias, **kwargs)
+
+ def _flip_channel_order(self, frames: "torch.Tensor") -> "torch.Tensor":
+ """
+ Flip channel order from RGB to BGR.
+
+ The slow processor puts the red channel at the end (BGR format),
+ but the channel order is different. We need to match the exact
+ channel order of the slow processor:
+
+ Slow processor:
+ - Channel 0: Blue (originally Red)
+ - Channel 1: Green
+ - Channel 2: Red (originally Blue)
+ """
+ # Assuming frames are in channels_first format (..., C, H, W)
+ frames = frames.flip(-3)
+
+ return frames
+
+ def _preprocess(
+ self,
+ images: list[list["torch.Tensor"]],
+ do_resize: bool,
+ size: Union[SizeDict, dict],
+ interpolation: Optional["F.InterpolationMode"],
+ do_center_crop: bool,
+ crop_size: Union[SizeDict, dict],
+ do_rescale: bool,
+ rescale_factor: float,
+ do_pad: bool,
+ pad_size: Union[SizeDict, dict],
+ constant_values: Union[float, list[float]],
+ pad_mode: str,
+ do_normalize: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ do_flip_channel_order: bool,
+ return_tensors: Optional[Union[str, TensorType]],
+ disable_grouping: Optional[bool],
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Preprocess videos using the fast image processor.
+
+ This method processes each video frame through the same pipeline as the original
+ TVP image processor but uses torchvision operations for better performance.
+ """
+ grouped_images, grouped_images_index = group_images_by_shape(
+ images, disable_grouping=disable_grouping, is_nested=True
+ )
+ processed_images_grouped = {}
+ for shape, stacked_frames in grouped_images.items():
+ # Resize if needed
+ if do_resize:
+ stacked_frames = self.resize(stacked_frames, size, interpolation)
+
+ # Center crop if needed
+ if do_center_crop:
+ stacked_frames = self.center_crop(stacked_frames, crop_size)
+
+ # Rescale and normalize using fused method for consistency
+ stacked_frames = self.rescale_and_normalize(
+ stacked_frames, do_rescale, rescale_factor, do_normalize, image_mean, image_std
+ )
+
+ # Pad if needed
+ if do_pad:
+ stacked_frames = self._pad_frames(stacked_frames, pad_size, constant_values, pad_mode)
+
+ # Flip channel order if needed (RGB to BGR)
+ if do_flip_channel_order:
+ stacked_frames = self._flip_channel_order(stacked_frames)
+
+ processed_images_grouped[shape] = stacked_frames
+
+ processed_images = reorder_images(processed_images_grouped, grouped_images_index, is_nested=True)
+ if return_tensors == "pt":
+ processed_images = [torch.stack(images, dim=0) for images in processed_images]
+ processed_images = torch.stack(processed_images, dim=0)
+
+ return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors)
+
+
+__all__ = ["TvpImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/modeling_tvp.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/modeling_tvp.py
new file mode 100644
index 0000000000000000000000000000000000000000..77d74bffe0ee48955deefdfdb36c06cd976373ac
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/modeling_tvp.py
@@ -0,0 +1,924 @@
+# coding=utf-8
+# Copyright 2023 The Intel AIA Team Authors, and HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License=, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing=, software
+# distributed under the License is distributed on an "AS IS" BASIS=,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND=, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch TVP Model"""
+
+import math
+from dataclasses import dataclass
+from typing import Optional
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, ModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import prune_linear_layer
+from ...utils import auto_docstring, logging
+from ...utils.backbone_utils import load_backbone
+from .configuration_tvp import TvpConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring
+class TvpVideoGroundingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `return_loss` is `True`):
+ Temporal-Distance IoU loss for video grounding.
+ logits (`torch.FloatTensor` of shape `(batch_size, 2)`):
+ Contains start_time/duration and end_time/duration. It is the time slot of the videos corresponding to the
+ input texts.
+ attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+class TvpLoss(nn.Module):
+ """
+ This class computes the losses for `TvpForVideoGrounding`. The process happens in two steps: 1) we compute
+ hungarian assignment between ground truth boxes and the outputs of the model 2) we supervise each pair of matched
+ ground-truth / prediction (supervise class and box).
+
+ Args:
+ losses (`list[str]`):
+ List of all the losses to be applied.
+ """
+
+ def __init__(self, losses):
+ super().__init__()
+ self.loss_map = {
+ "iou": self.loss_iou,
+ "distance": self.loss_distance,
+ "duration": self.loss_duration,
+ }
+ for loss in losses:
+ if loss not in self.loss_map:
+ raise ValueError(f"Loss {loss} not supported")
+
+ self.losses = losses
+
+ def loss_iou(self, start_time, end_time, candidates_start_time, candidates_end_time, duration):
+ """
+ Measure the intersection over union.
+ """
+ inter = torch.min(candidates_end_time, end_time) - torch.max(candidates_start_time, start_time)
+ union = torch.max(candidates_end_time, end_time) - torch.min(candidates_start_time, start_time)
+ iou = 1 - inter.clamp(min=0) / union
+
+ return iou
+
+ def loss_distance(self, start_time, end_time, candidates_start_time, candidates_end_time, duration):
+ """
+ Measure the distance of mid points.
+ """
+ mid_candidates = torch.div(torch.add(candidates_start_time, candidates_end_time), 2.0)
+ mid_groundtruth = torch.div(torch.add(start_time, end_time), 2.0)
+ distance_diff = torch.div(
+ torch.max(mid_candidates, mid_groundtruth) - torch.min(mid_candidates, mid_groundtruth), duration
+ ).clamp(min=0.2)
+
+ return distance_diff
+
+ def loss_duration(self, start_time, end_time, candidates_start_time, candidates_end_time, duration):
+ """
+ Measure the difference of duration.
+ """
+ duration_candidates = torch.sub(candidates_end_time, candidates_start_time)
+ duration_groundtruth = torch.sub(end_time, start_time)
+ duration_diff = torch.square(torch.div(torch.sub(duration_candidates, duration_groundtruth), duration))
+ duration_diff = duration_diff.clamp(min=0.4)
+
+ return duration_diff
+
+ def forward(self, logits, labels):
+ """
+ This performs the loss computation.
+
+ Args:
+ logits (`torch.FloatTensor`):
+ The output logits of head module.
+ labels (`list[torch.FloatTensor]`):
+ List of tensors ([start, end, duration]), which contains start time, end time of the video corresponding to the text, and also the duration.
+ """
+ duration, start_time, end_time = labels
+ candidates = torch.mul(logits, duration)
+ candidates_start_time, candidates_end_time = candidates[:, 0].float(), candidates[:, 1].float()
+
+ losses_dict = {}
+ for loss in self.losses:
+ losses_dict.update(
+ {loss: self.loss_map[loss](start_time, end_time, candidates_start_time, candidates_end_time, duration)}
+ )
+
+ return losses_dict
+
+
+class TvpVisionModel(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.backbone = load_backbone(config)
+
+ if config.backbone_config is not None:
+ in_channels = config.backbone_config.hidden_sizes[-1]
+ elif hasattr(self.backbone, "config") and hasattr(self.backbone.config, "hidden_sizes"):
+ in_channels = self.backbone.config.hidden_sizes[-1]
+ elif hasattr(self.backbone, "config") and hasattr(self.backbone.config, "hidden_size"):
+ in_channels = self.backbone.config.hidden_size
+ else:
+ raise ValueError("Backbone config not found")
+
+ self.grid_encoder_conv = nn.Conv2d(
+ in_channels,
+ config.hidden_size,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ groups=1,
+ bias=False,
+ )
+
+ def forward(self, pixel_values):
+ batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ # (batch_size * num_frames, num_channels, height, width)
+ pixel_values = pixel_values.view(batch_size * num_frames, num_channels, height, width)
+ grid_feat_outputs = self.backbone(pixel_values)["feature_maps"][0]
+ grid = self.grid_encoder_conv(grid_feat_outputs)
+ grid = nn.functional.max_pool2d(grid, kernel_size=2, stride=2)
+ grid = nn.functional.relu(grid, inplace=True)
+ new_channel, new_height, new_width = grid.shape[-3:]
+ # (batch_size, num_frames, num_channels, height, width)
+ grid = grid.view(batch_size, num_frames, new_channel, new_height, new_width)
+ # (batch_size, num_frames, height, width, num_channels)
+ grid = grid.permute(0, 1, 3, 4, 2)
+ return grid
+
+
+class TvpVisualInputEmbedding(nn.Module):
+ """
+ Takes input of both image and video (multi-frame)
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ # sequence embedding
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.row_position_embeddings = nn.Embedding(config.max_grid_row_position_embeddings, config.hidden_size)
+ self.col_position_embeddings = nn.Embedding(config.max_grid_col_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(1, config.hidden_size)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.max_grid_row_position_embeddings = config.max_grid_row_position_embeddings
+ self.max_grid_col_position_embeddings = config.max_grid_col_position_embeddings
+
+ def interpolate_pos_encoding(self, embedding: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained pad weights , to be able to use the model on collection of high
+ resolution images (high resolution videos).
+
+ """
+ h0 = w0 = 1
+ # if height dimension is to be interpolated
+ if height > self.max_grid_row_position_embeddings:
+ h0 = height / self.max_grid_row_position_embeddings
+ # if width dimension is to be interpolated
+ if width > self.max_grid_col_position_embeddings:
+ w0 = width / self.max_grid_col_position_embeddings
+ embedding = embedding.permute(0, 3, 1, 2) # (batch_size, hidden_dim, height, width)
+ embedding = nn.functional.interpolate(
+ embedding,
+ scale_factor=(h0, w0),
+ mode="bicubic",
+ align_corners=False,
+ )
+ embedding = embedding.permute(0, 2, 3, 1) # (batch_size, height, width, hidden_dim)
+ return embedding
+
+ def add_2d_positional_embeddings(self, grid, interpolate_pos_encoding: bool = False):
+ """
+ Args:
+ grid: (batch_size, height, width, hidden_dim)
+ interpolate_pos_encoding: (`bool`, *optional*, defaults to `False`):
+ Whether to interpolate the pre-trained position encodings.
+ Returns:
+ grid + col_position_embeddings.view(*col_shape): (batch_size, *, height, width, hidden_dim)
+ """
+ batch_size, height, width, hidden_dim = grid.shape
+
+ # add row-wise position embeddings
+ # (height, )
+ row_height = min(self.max_grid_row_position_embeddings, height)
+ row_position_ids = torch.arange(row_height, dtype=torch.long, device=grid.device)
+ # (height, hidden_dim)
+ row_position_embeddings = self.row_position_embeddings(row_position_ids)
+ row_shape = (1,) * (len(grid.shape) - 3) + (row_height, 1, hidden_dim)
+ # (batch_size, height, 1, hidden_dim)
+ row_position_embeddings = row_position_embeddings.view(*row_shape)
+
+ # add column-wise position embeddings
+ row_width = min(self.max_grid_col_position_embeddings, width)
+ col_position_ids = torch.arange(row_width, dtype=torch.long, device=grid.device)
+ # (width, hidden_dim)
+ col_position_embeddings = self.col_position_embeddings(col_position_ids)
+ col_shape = (batch_size, 1, row_width, hidden_dim)
+ # (batch_size, 1, width, hidden_dim)
+ col_position_embeddings = col_position_embeddings.view(*col_shape)
+ # (batch_size, height, width, hidden_dim)
+ positional_embeddings = row_position_embeddings + col_position_embeddings
+
+ # This interpolation gets triggered ONLY when the input image dim is larger in any dimension than the original position embeddings
+ if interpolate_pos_encoding and (
+ height > self.max_grid_row_position_embeddings or width > self.max_grid_col_position_embeddings
+ ):
+ grid = grid + self.interpolate_pos_encoding(positional_embeddings, height, width)
+ else:
+ grid = grid + positional_embeddings
+ return grid
+
+ def forward(self, grid, interpolate_pos_encoding: bool = False):
+ """
+ Args:
+ grid: Array of shape (batch_size, num_frames, height, width, num_channels).
+ It contains processed frames extracted from videos, and is generated by Tvp image preprocessor. Note,
+ num_frames can be 1
+ interpolate_pos_encoding: (bool, *optional*, defaults to `False`):
+ Whether to interpolate the pre-trained position encodings.
+
+ Returns:
+ embeddings: The embedding of grid with size (batch_size, height*width, num_channels)
+
+ """
+ batch_size, num_frames, height, width, num_channels = grid.shape
+ # temporal mean pooling, (batch_size, height, width, hidden_size)
+ grid = grid.mean(1)
+ grid = self.add_2d_positional_embeddings(grid, interpolate_pos_encoding=interpolate_pos_encoding)
+ # image token sequence, (batch_size, height*width, num_channels)
+ visual_tokens = grid.view(batch_size, -1, num_channels)
+ visual_tokens_shape = visual_tokens.shape[:-1]
+ device = visual_tokens.device
+
+ # image token type embeddings.
+ token_type_ids = torch.zeros(visual_tokens_shape, dtype=torch.long, device=device)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = visual_tokens + token_type_embeddings
+ embeddings = self.layer_norm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class TvpTextInputEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None):
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+ if position_ids is None:
+ position_ids = torch.arange(seq_length, dtype=torch.long, device=device)
+ position_ids = position_ids.unsqueeze(0).expand(input_shape)
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ position_embeddings = self.position_embeddings(position_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + position_embeddings + token_type_embeddings
+ embeddings = self.layer_norm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class TvpAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention heads {config.num_attention_heads}"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+ self.attn_dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ mask = torch.ones(self.num_attention_heads, self.attention_head_size)
+ heads = set(heads) - self.pruned_heads # Convert to set and remove already pruned heads
+ for head in heads:
+ # Compute how many pruned heads are before the head and move the index accordingly
+ head = head - sum(1 if h < head else 0 for h in self.pruned_heads)
+ mask[head] = 0
+ mask = mask.view(-1).contiguous().eq(1)
+ index = torch.arange(len(mask))[mask].long()
+
+ # Prune linear layers
+ self.query = prune_linear_layer(self.query, index)
+ self.key = prune_linear_layer(self.key, index)
+ self.value = prune_linear_layer(self.value, index)
+ self.dense = prune_linear_layer(self.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.num_attention_heads = self.num_attention_heads - len(heads)
+ self.all_head_size = self.attention_head_size * self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def _reshape(self, tensor: torch.Tensor, sequence_length: int, batch_size: int):
+ return (
+ tensor.view(batch_size, sequence_length, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ .contiguous()
+ )
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions: Optional[bool] = None,
+ ):
+ batch_size, sequence_length = hidden_states.shape[:2]
+ mixed_query_layer = self.query(hidden_states)
+
+ mixed_key_layer = self.key(hidden_states)
+ mixed_value_layer = self.value(hidden_states)
+
+ query_layer = self._reshape(mixed_query_layer, sequence_length, batch_size)
+ key_layer = self._reshape(mixed_key_layer, sequence_length, batch_size)
+ value_layer = self._reshape(mixed_value_layer, sequence_length, batch_size)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.attn_dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ attn_output = torch.matmul(attention_probs, value_layer)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ attn_output = attn_output.reshape(batch_size, sequence_length, self.all_head_size)
+
+ attn_output = self.dense(attn_output)
+ attn_output = self.dropout(attn_output)
+ attn_output = self.layer_norm(attn_output + hidden_states)
+ # add attentions if we output them
+ outputs = (attn_output, attention_probs) if output_attentions else (attn_output,)
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertIntermediate with Bert->Tvp
+class TvpIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+class TvpOutputLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.layer_norm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class TvpEncodeLayer(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = TvpAttention(config)
+ self.intermediate = TvpIntermediate(config)
+ self.output = TvpOutputLayer(config)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions: Optional[bool] = None,
+ ):
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ output_attentions=output_attentions,
+ )
+ attention_output = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ outputs = (layer_output,) + outputs
+ return outputs
+
+
+class TvpEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([TvpEncodeLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ):
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ all_hidden_states = ()
+ all_attentions = ()
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(hidden_states, attention_mask, head_mask[i], output_attentions)
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ outputs = (hidden_states,)
+ if output_hidden_states:
+ outputs = outputs + (all_hidden_states,)
+ if output_attentions:
+ outputs = outputs + (all_attentions,)
+ return outputs # last-layer hidden state, (all hidden states), (all attentions)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states if output_hidden_states else None,
+ attentions=all_attentions if output_attentions else None,
+ )
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPooler with Bert->Tvp
+class TvpPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+@auto_docstring
+class TvpPreTrainedModel(PreTrainedModel):
+ config: TvpConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module: nn.Module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Embedding)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv2d):
+ nn.init.kaiming_normal_(module.weight, mode="fan_out", nonlinearity="relu")
+ if module.bias is not None:
+ nn.init.constant_(module.bias, 0)
+ elif isinstance(module, TvpModel):
+ nn.init.normal_(module.text_prompt)
+
+ if isinstance(module, nn.Linear) and module.bias is not None:
+ module.bias.data.zero_()
+ if hasattr(module, "pad_up"):
+ nn.init.normal_(module.pad_up)
+ if hasattr(module, "pad_down"):
+ nn.init.normal_(module.pad_down)
+ if hasattr(module, "pad_left"):
+ nn.init.normal_(module.pad_left)
+ if hasattr(module, "pad_right"):
+ nn.init.normal_(module.pad_right)
+
+
+class TvpFrameDownPadPrompter(nn.Module):
+ """
+ Pad frames extracted from videos only at the bottom.
+ """
+
+ def __init__(self, config):
+ if config.visual_prompter_apply not in ("add", "replace", "remove"):
+ raise ValueError("`visual_prompter_apply` must be in (add, replace, remove)")
+
+ super().__init__()
+ self.visual_prompt_size = config.visual_prompt_size
+ self.frame_num = config.frame_num
+ self.max_img_size = config.max_img_size
+ self.visual_prompter_apply = config.visual_prompter_apply
+
+ self.pad_down = nn.Parameter(
+ torch.randn([1, config.frame_num, 3, config.visual_prompt_size, config.max_img_size])
+ )
+
+ def forward(self, pixel_values):
+ if self.visual_prompter_apply != "add":
+ visual_prompt_mask = torch.ones(
+ [self.max_img_size, self.max_img_size], dtype=pixel_values.dtype, device=pixel_values.device
+ )
+ visual_prompt_mask[self.max_img_size - self.visual_prompt_size : self.max_img_size, :] = 0.0
+ pixel_values *= visual_prompt_mask
+ if self.visual_prompter_apply != "remove":
+ prompt = torch.zeros(
+ [pixel_values.shape[0], pixel_values.shape[1], 3, self.max_img_size, self.max_img_size],
+ device=pixel_values.device,
+ )
+ start_point = self.max_img_size - self.visual_prompt_size
+ prompt[:, :, :, start_point : self.max_img_size, :] = self.pad_down
+ pixel_values += prompt.to(pixel_values.dtype)
+ return pixel_values
+
+
+class TvpFramePadPrompter(nn.Module):
+ """
+ Pad frames extracted from videos in the surroundings.
+ """
+
+ def __init__(self, config):
+ if config.visual_prompter_apply not in ("add", "replace", "remove"):
+ raise ValueError("`visual_prompter_apply` must be in (add, replace, remove)")
+
+ super().__init__()
+ self.num_frames = config.num_frames
+ self.max_img_size = config.max_img_size
+ self.visual_prompter_apply = config.visual_prompter_apply
+ self.base_size = config.max_img_size - config.visual_prompt_size * 2
+ self.pad_up = nn.Parameter(
+ torch.randn([1, config.num_frames, 3, config.visual_prompt_size, config.max_img_size])
+ )
+ self.pad_down = nn.Parameter(
+ torch.randn([1, config.num_frames, 3, config.visual_prompt_size, config.max_img_size])
+ )
+ self.pad_left = nn.Parameter(
+ torch.randn(
+ [
+ 1,
+ config.num_frames,
+ 3,
+ config.max_img_size - config.visual_prompt_size * 2,
+ config.visual_prompt_size,
+ ]
+ )
+ )
+ self.pad_right = nn.Parameter(
+ torch.randn(
+ [
+ 1,
+ config.num_frames,
+ 3,
+ config.max_img_size - config.visual_prompt_size * 2,
+ config.visual_prompt_size,
+ ]
+ )
+ )
+
+ def interpolate_pad_encoding(self, prompt: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained pad weights, to be able to use the model on collection of high
+ resolution images (high resolution videos).
+
+ """
+
+ # creates scale factor from height and width of original image wrt to the config.max_img_size
+ h0, w0 = height / self.max_img_size, width / self.max_img_size
+
+ batch, num_frames, channels, prompt_height, prompt_width = prompt.shape
+
+ # reshaping the batch and num_frames dimension into a single one (i.e (b,frames,c,h,w)-->(b*frames,c,h,w)), to apply bicubic interpolation
+ prompt = prompt.reshape(batch * num_frames, channels, prompt_height, prompt_width)
+ prompt = nn.functional.interpolate(
+ prompt,
+ scale_factor=(h0, w0),
+ mode="bicubic",
+ align_corners=False,
+ )
+ # reversing back to (batch,frames,channels,height,width), where height and width is the new interpolated height and width
+ prompt = prompt.reshape(batch, num_frames, channels, height, width)
+ return prompt
+
+ def forward(self, pixel_values, interpolate_pad_encoding: bool = False):
+ height, width = (
+ (pixel_values.shape[-2], pixel_values.shape[-1])
+ if interpolate_pad_encoding
+ else (self.max_img_size, self.max_img_size)
+ )
+ if self.visual_prompter_apply not in ("add", "remove", "replace"):
+ raise ValueError(f"Invalid visual_prompter_apply value {self.visual_prompter_apply}")
+ if self.visual_prompter_apply in ("replace", "remove"):
+ visual_prompt_mask = torch.ones([height, width], dtype=pixel_values.dtype, device=pixel_values.device)
+ pixel_values *= visual_prompt_mask
+ if self.visual_prompter_apply in ("replace", "add"):
+ base = torch.zeros(1, self.num_frames, 3, self.base_size, self.base_size, device=pixel_values.device)
+
+ prompt = torch.cat([self.pad_left, base, self.pad_right], dim=4)
+ prompt = torch.cat([self.pad_up, prompt, self.pad_down], dim=3)
+ prompt = torch.cat(pixel_values.size(0) * [prompt])
+ if interpolate_pad_encoding:
+ prompt = self.interpolate_pad_encoding(prompt, height, width)
+ pixel_values = pixel_values + prompt.to(pixel_values.dtype)
+ return pixel_values
+
+
+TVP_PROMPTER_CLASSES_MAPPING = {
+ "framedownpad": TvpFrameDownPadPrompter,
+ "framepad": TvpFramePadPrompter,
+}
+
+
+@auto_docstring(
+ custom_intro="""
+ The bare Tvp Model transformer outputting BaseModelOutputWithPooling object without any specific head on top.
+ """
+)
+class TvpModel(TvpPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+ self.vision_model = TvpVisionModel(config)
+ self.embeddings = TvpTextInputEmbeddings(config)
+ self.visual_embeddings = TvpVisualInputEmbedding(config)
+ self.encoder = TvpEncoder(config)
+ self.pooler = TvpPooler(config)
+ self.text_prompt = nn.Parameter(torch.randn([1, 10, config.hidden_size]))
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ if config.visual_prompter_type not in TVP_PROMPTER_CLASSES_MAPPING:
+ raise ValueError("`visual_prompter_type` must be in (framedownpad, framepad)")
+ self.visual_prompter = TVP_PROMPTER_CLASSES_MAPPING[config.visual_prompter_type](config)
+
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """Prunes heads of the model.
+ heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ ):
+ r"""
+ Examples:
+ ```python
+ >>> import torch
+ >>> from transformers import AutoConfig, AutoTokenizer, TvpModel
+
+ >>> model = TvpModel.from_pretrained("Jiqing/tiny-random-tvp")
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("Jiqing/tiny-random-tvp")
+
+ >>> pixel_values = torch.rand(1, 1, 3, 448, 448)
+ >>> text_inputs = tokenizer("This is an example input", return_tensors="pt")
+ >>> output = model(text_inputs.input_ids, pixel_values, text_inputs.attention_mask)
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+ # Add visual prompt, it compensates for the spatiotemporal information loss in 2D visual features.
+ pixel_values = self.vision_model(
+ self.visual_prompter(pixel_values, interpolate_pad_encoding=interpolate_pos_encoding)
+ )
+ # (batch_size, sequence_length, hidden_size)
+ text_embedding_output = self.embeddings(input_ids=input_ids)
+ # (batch_size, visual_sequence_length, hidden_size)
+ visual_embedding_output = self.visual_embeddings(
+ pixel_values, interpolate_pos_encoding=interpolate_pos_encoding
+ )
+
+ if attention_mask is not None:
+ # (batch_size, visual_sequence_length)
+ visual_attention_mask = attention_mask.new_ones(visual_embedding_output.shape[:2])
+ pt_mask = torch.ones(attention_mask.shape[0], 10).to(
+ device=attention_mask.device, dtype=attention_mask.dtype
+ )
+ attention_mask = torch.cat([pt_mask, attention_mask, visual_attention_mask], dim=-1)
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ attention_mask = self.get_extended_attention_mask(attention_mask, input_ids.size()).to(input_ids.device)
+ text_prompt = self.text_prompt.expand(text_embedding_output.shape[0], -1, -1)
+ # (batch_size, sequence_length + visual_sequence_length, hidden_size)
+ embedding_output = torch.cat([text_prompt, text_embedding_output, visual_embedding_output], dim=1)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=attention_mask,
+ head_mask=self.get_head_mask(head_mask, self.config.num_hidden_layers),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ last_hidden_state = encoder_outputs.last_hidden_state if return_dict else encoder_outputs[0]
+ pooled_output = self.pooler(last_hidden_state)
+ last_hidden_state = self.dropout(last_hidden_state)
+ pooled_output = self.dropout(pooled_output)
+ if not return_dict:
+ return (last_hidden_state, pooled_output) + encoder_outputs[1:]
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class TvpVideoGroundingHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_0 = nn.Linear(config.hidden_size, config.hidden_size * 2)
+ self.layer_1 = nn.Linear(config.hidden_size * 2, 2)
+ self.activation_0 = nn.ReLU()
+ self.activation_1 = nn.Sigmoid()
+
+ def forward(self, pooler_output):
+ logits = self.activation_0(self.layer_0(pooler_output))
+ logits = self.activation_1(self.layer_1(logits))
+ return logits
+
+
+@auto_docstring(
+ custom_intro="""
+ Tvp Model with a video grounding head on top computing IoU, distance, and duration loss.
+ """
+)
+class TvpForVideoGrounding(TvpPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+ self.model = TvpModel(config)
+ self.video_grounding_head = TvpVideoGroundingHead(config)
+
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ labels: Optional[tuple[torch.Tensor]] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ ):
+ r"""
+ labels (`torch.FloatTensor` of shape `(batch_size, 3)`, *optional*):
+ The labels contains duration, start time, and end time of the video corresponding to the text.
+
+ Examples:
+ ```python
+ >>> import torch
+ >>> from transformers import AutoConfig, AutoTokenizer, TvpForVideoGrounding
+
+ >>> model = TvpForVideoGrounding.from_pretrained("Jiqing/tiny-random-tvp")
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("Jiqing/tiny-random-tvp")
+
+ >>> pixel_values = torch.rand(1, 1, 3, 448, 448)
+ >>> text_inputs = tokenizer("This is an example input", return_tensors="pt")
+ >>> output = model(text_inputs.input_ids, pixel_values, text_inputs.attention_mask)
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+ outputs = self.model(
+ input_ids,
+ pixel_values,
+ attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+ pooler_output = outputs[1]
+ logits = self.video_grounding_head(pooler_output)
+
+ loss = None
+ if labels is not None:
+ criterion = TvpLoss(["iou", "distance", "duration"])
+ criterion.to(self.device)
+ loss_dict = criterion(logits, labels)
+ loss = (
+ loss_dict["iou"]
+ + self.config.distance_loss_weight * loss_dict["distance"]
+ + self.config.duration_loss_weight * loss_dict["duration"]
+ )
+ if not return_dict:
+ outputs = (logits,) + outputs[2:]
+ if loss is not None:
+ outputs = (loss,) + outputs
+ return outputs
+
+ return TvpVideoGroundingOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["TvpModel", "TvpPreTrainedModel", "TvpForVideoGrounding"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/processing_tvp.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/processing_tvp.py
new file mode 100644
index 0000000000000000000000000000000000000000..a4fbe2adeae32ae1821844778fb52fbf2111af3b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/tvp/processing_tvp.py
@@ -0,0 +1,135 @@
+# coding=utf-8
+# Copyright 2023 The Intel AIA Team Authors, and HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License=, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing=, software
+# distributed under the License is distributed on an "AS IS" BASIS=,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND=, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Processor class for TVP.
+"""
+
+from ...processing_utils import ProcessorMixin
+from ...tokenization_utils_base import BatchEncoding
+
+
+class TvpProcessor(ProcessorMixin):
+ r"""
+ Constructs an TVP processor which wraps a TVP image processor and a Bert tokenizer into a single processor.
+
+ [`TvpProcessor`] offers all the functionalities of [`TvpImageProcessor`] and [`BertTokenizerFast`]. See the
+ [`~TvpProcessor.__call__`] and [`~TvpProcessor.decode`] for more information.
+
+ Args:
+ image_processor ([`TvpImageProcessor`], *optional*):
+ The image processor is a required input.
+ tokenizer ([`BertTokenizerFast`], *optional*):
+ The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+ image_processor_class = "TvpImageProcessor"
+ tokenizer_class = ("BertTokenizer", "BertTokenizerFast")
+
+ def __init__(self, image_processor=None, tokenizer=None, **kwargs):
+ if image_processor is None:
+ raise ValueError("You need to specify an `image_processor`.")
+ if tokenizer is None:
+ raise ValueError("You need to specify a `tokenizer`.")
+
+ super().__init__(image_processor, tokenizer)
+
+ def __call__(self, text=None, videos=None, return_tensors=None, **kwargs):
+ """
+ Main method to prepare for the model one or several sequences(s) and image(s). This method forwards the `text`
+ and `kwargs` arguments to BertTokenizerFast's [`~BertTokenizerFast.__call__`] if `text` is not `None` to encode
+ the text. To prepare the image(s), this method forwards the `videos` and `kwargs` arguments to
+ TvpImageProcessor's [`~TvpImageProcessor.__call__`] if `videos` is not `None`. Please refer to the docstring of
+ the above two methods for more information.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ videos (`list[PIL.Image.Image]`, `list[np.ndarray]`, `list[torch.Tensor]`, `list[list[PIL.Image.Image]]`, `list[list[np.ndarray]]`,:
+ `list[list[torch.Tensor]]`): The video or batch of videos to be prepared. Each video should be a list
+ of frames, which can be either PIL images or NumPy arrays. In case of NumPy arrays/PyTorch tensors,
+ each frame should be of shape (H, W, C), where H and W are frame height and width, and C is a number of
+ channels.
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors of a particular framework. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+
+ Returns:
+ [`BatchEncoding`]: A [`BatchEncoding`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`.
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not
+ `None`).
+ - **pixel_values** -- Pixel values to be fed to a model. Returned when `videos` is not `None`.
+ """
+
+ max_text_length = kwargs.pop("max_text_length", None)
+
+ if text is None and videos is None:
+ raise ValueError("You have to specify either text or videos. Both cannot be none.")
+
+ encoding = {}
+ if text is not None:
+ textual_input = self.tokenizer.batch_encode_plus(
+ text,
+ truncation=True,
+ padding="max_length",
+ max_length=max_text_length,
+ pad_to_max_length=True,
+ return_tensors=return_tensors,
+ return_token_type_ids=False,
+ **kwargs,
+ )
+ encoding.update(textual_input)
+
+ if videos is not None:
+ image_features = self.image_processor(videos, return_tensors=return_tensors, **kwargs)
+ encoding.update(image_features)
+
+ return BatchEncoding(data=encoding, tensor_type=return_tensors)
+
+ def post_process_video_grounding(self, logits, video_durations):
+ """
+ Compute the time of the video.
+
+ Args:
+ logits (`torch.Tensor`):
+ The logits output of TvpForVideoGrounding.
+ video_durations (`float`):
+ The video's duration.
+
+ Returns:
+ start (`float`):
+ The start time of the video.
+ end (`float`):
+ The end time of the video.
+ """
+ start, end = (
+ round(logits.tolist()[0][0] * video_durations, 1),
+ round(logits.tolist()[0][1] * video_durations, 1),
+ )
+
+ return start, end
+
+
+__all__ = ["TvpProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..cf4c36f6363f5f9704526b0cb302952abe6f87dc
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_udop import *
+ from .modeling_udop import *
+ from .processing_udop import *
+ from .tokenization_udop import *
+ from .tokenization_udop_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/configuration_udop.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/configuration_udop.py
new file mode 100644
index 0000000000000000000000000000000000000000..d55717af2b8b90722d64224c150d2463fbe992e9
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/configuration_udop.py
@@ -0,0 +1,160 @@
+# coding=utf-8
+# Copyright 2024 HuggingFace Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""UDOP model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class UdopConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`UdopForConditionalGeneration`]. It is used to
+ instantiate a UDOP model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the UDOP
+ [microsoft/udop-large](https://huggingface.co/microsoft/udop-large) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Arguments:
+ vocab_size (`int`, *optional*, defaults to 33201):
+ Vocabulary size of the UDOP model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`UdopForConditionalGeneration`].
+ d_model (`int`, *optional*, defaults to 1024):
+ Size of the encoder layers and the pooler layer.
+ d_kv (`int`, *optional*, defaults to 64):
+ Size of the key, query, value projections per attention head. The `inner_dim` of the projection layer will
+ be defined as `num_heads * d_kv`.
+ d_ff (`int`, *optional*, defaults to 4096):
+ Size of the intermediate feed forward layer in each `UdopBlock`.
+ num_layers (`int`, *optional*, defaults to 24):
+ Number of hidden layers in the Transformer encoder and decoder.
+ num_decoder_layers (`int`, *optional*):
+ Number of hidden layers in the Transformer decoder. Will use the same value as `num_layers` if not set.
+ num_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder and decoder.
+ relative_attention_num_buckets (`int`, *optional*, defaults to 32):
+ The number of buckets to use for each attention layer.
+ relative_attention_max_distance (`int`, *optional*, defaults to 128):
+ The maximum distance of the longer sequences for the bucket separation.
+ relative_bias_args (`list[dict]`, *optional*, defaults to `[{'type': '1d'}, {'type': 'horizontal'}, {'type': 'vertical'}]`):
+ A list of dictionaries containing the arguments for the relative bias layers.
+ dropout_rate (`float`, *optional*, defaults to 0.1):
+ The ratio for all dropout layers.
+ layer_norm_epsilon (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ initializer_factor (`float`, *optional*, defaults to 1.0):
+ A factor for initializing all weight matrices (should be kept to 1, used internally for initialization
+ testing).
+ feed_forward_proj (`string`, *optional*, defaults to `"relu"`):
+ Type of feed forward layer to be used. Should be one of `"relu"` or `"gated-gelu"`. Udopv1.1 uses the
+ `"gated-gelu"` feed forward projection. Original Udop uses `"relu"`.
+ is_encoder_decoder (`bool`, *optional*, defaults to `True`):
+ Whether the model should behave as an encoder/decoder or not.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+ pad_token_id (`int`, *optional*, defaults to 0):
+ The id of the padding token in the vocabulary.
+ eos_token_id (`int`, *optional*, defaults to 1):
+ The id of the end-of-sequence token in the vocabulary.
+ max_2d_position_embeddings (`int`, *optional*, defaults to 1024):
+ The maximum absolute position embeddings for relative position encoding.
+ image_size (`int`, *optional*, defaults to 224):
+ The size of the input images.
+ patch_size (`int`, *optional*, defaults to 16):
+ The patch size used by the vision encoder.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of channels in the input images.
+ """
+
+ model_type = "udop"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {"hidden_size": "d_model", "num_attention_heads": "num_heads", "num_hidden_layers": "num_layers"}
+
+ def __init__(
+ self,
+ vocab_size=33201,
+ d_model=1024,
+ d_kv=64,
+ d_ff=4096,
+ num_layers=24,
+ num_decoder_layers=None,
+ num_heads=16,
+ relative_attention_num_buckets=32,
+ relative_attention_max_distance=128,
+ relative_bias_args=[{"type": "1d"}, {"type": "horizontal"}, {"type": "vertical"}],
+ dropout_rate=0.1,
+ layer_norm_epsilon=1e-6,
+ initializer_factor=1.0,
+ feed_forward_proj="relu",
+ is_encoder_decoder=True,
+ use_cache=True,
+ pad_token_id=0,
+ eos_token_id=1,
+ max_2d_position_embeddings=1024,
+ image_size=224,
+ patch_size=16,
+ num_channels=3,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.d_model = d_model
+ self.d_kv = d_kv
+ self.d_ff = d_ff
+ self.num_layers = num_layers
+ self.num_decoder_layers = (
+ num_decoder_layers if num_decoder_layers is not None else self.num_layers
+ ) # default = symmetry
+ self.num_heads = num_heads
+ self.relative_attention_num_buckets = relative_attention_num_buckets
+ self.relative_attention_max_distance = relative_attention_max_distance
+ self.dropout_rate = dropout_rate
+ self.layer_norm_epsilon = layer_norm_epsilon
+ self.initializer_factor = initializer_factor
+ self.feed_forward_proj = feed_forward_proj
+ self.use_cache = use_cache
+
+ # UDOP attributes
+ self.max_2d_position_embeddings = max_2d_position_embeddings
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ if not isinstance(relative_bias_args, list):
+ raise TypeError("`relative_bias_args` should be a list of dictionaries.")
+ self.relative_bias_args = relative_bias_args
+
+ act_info = self.feed_forward_proj.split("-")
+ self.dense_act_fn = act_info[-1]
+ self.is_gated_act = act_info[0] == "gated"
+
+ if len(act_info) > 1 and act_info[0] != "gated" or len(act_info) > 2:
+ raise ValueError(
+ f"`feed_forward_proj`: {feed_forward_proj} is not a valid activation function of the dense layer."
+ "Please make sure `feed_forward_proj` is of the format `gated-{ACT_FN}` or `{ACT_FN}`, e.g. "
+ "'gated-gelu' or 'relu'"
+ )
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ eos_token_id=eos_token_id,
+ is_encoder_decoder=is_encoder_decoder,
+ **kwargs,
+ )
+
+
+__all__ = ["UdopConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/modeling_udop.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/modeling_udop.py
new file mode 100644
index 0000000000000000000000000000000000000000..d5c9904c3db357a5657b7b8995a0b6aa6cb756f4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/modeling_udop.py
@@ -0,0 +1,2007 @@
+# coding=utf-8
+# Copyright 2024 Microsoft Research and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch UDOP model."""
+
+import collections
+import logging
+import math
+import random
+from abc import ABC, abstractmethod
+from collections.abc import Sequence
+from copy import deepcopy
+from dataclasses import dataclass
+from typing import Any, Optional, Union
+
+import torch
+from torch import Tensor, nn
+from torch.nn import CrossEntropyLoss
+
+from transformers import UdopConfig
+from transformers.modeling_outputs import (
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+)
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import (
+ ModelOutput,
+ auto_docstring,
+ is_torch_flex_attn_available,
+ is_torchdynamo_compiling,
+)
+from ...utils.deprecation import deprecate_kwarg
+
+
+if is_torch_flex_attn_available():
+ from torch.nn.attention.flex_attention import BlockMask
+
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.getLogger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for the model's outputs that may also contain a past key/values (to speed up sequential decoding). Includes
+ an additional attention mask.
+ """
+)
+class BaseModelOutputWithAttentionMask(ModelOutput):
+ r"""
+ last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model. If `past_key_values` is used only
+ the last hidden-state of the sequences of shape `(batch_size, 1, hidden_size)` is output.
+ attention_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Attention mask used in the model's forward pass to avoid performing attention on padding token indices.
+ Mask values selected in `[0, 1]`:
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+ past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and optionally if
+ `config.is_encoder_decoder=True` 2 additional tensors of shape `(batch_size, num_heads,
+ encoder_sequence_length, embed_size_per_head)`. Contains pre-computed hidden-states (key and values in the
+ self-attention blocks and optionally if `config.is_encoder_decoder=True` in the cross-attention blocks)
+ that can be used (see `past_key_values` input) to speed up sequential decoding.
+ hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, +
+ one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`. Hidden-states of
+ the model at the output of each layer plus the optional initial embedding outputs.
+ attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in
+ the self-attention heads.
+ cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`):
+ Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax,
+ used to compute the weighted average in the cross-attention heads.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ attention_mask: Optional[torch.FloatTensor] = None
+ past_key_values: Optional[Cache] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ cross_attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+def get_visual_bbox(image_size=224, patch_size=16):
+ image_feature_pool_shape = [image_size // patch_size, image_size // patch_size]
+ visual_bbox_x = torch.arange(0, 1.0 * (image_feature_pool_shape[1] + 1), 1.0)
+ visual_bbox_x /= image_feature_pool_shape[1]
+
+ visual_bbox_y = torch.arange(0, 1.0 * (image_feature_pool_shape[0] + 1), 1.0)
+ visual_bbox_y /= image_feature_pool_shape[0]
+
+ visual_bbox_input = torch.stack(
+ [
+ visual_bbox_x[:-1].repeat(image_feature_pool_shape[0], 1),
+ visual_bbox_y[:-1].repeat(image_feature_pool_shape[1], 1).transpose(0, 1),
+ visual_bbox_x[1:].repeat(image_feature_pool_shape[0], 1),
+ visual_bbox_y[1:].repeat(image_feature_pool_shape[1], 1).transpose(0, 1),
+ ],
+ dim=-1,
+ )
+
+ visual_bbox_input = visual_bbox_input.view(-1, 4)
+
+ return visual_bbox_input
+
+
+def pad_sequence(seq, target_len, pad_value=0):
+ if isinstance(seq, torch.Tensor):
+ n = seq.shape[0]
+ else:
+ n = len(seq)
+ seq = torch.tensor(seq)
+ m = target_len - n
+ if m > 0:
+ ret = torch.stack([pad_value] * m).to(seq)
+ seq = torch.cat([seq, ret], dim=0)
+ return seq[:target_len]
+
+
+def combine_image_text_embeddings(
+ image_embeddings,
+ inputs_embeds,
+ bbox,
+ visual_bbox,
+ attention_mask=None,
+ num_patches=14,
+ max_len=0,
+ image_size=224,
+ patch_size=16,
+):
+ """
+ Combine the image and text embeddings for the input to the encoder/decoder of UDOP.
+
+ First, the image embeddings are created by checking for each visual patch if it is inside the bounding box of a
+ token. If it is, the visual patch is combined with the token embedding. Then, the visual bounding boxes are combined
+ with the text bounding boxes. Finally, the visual bounding boxes are combined with the text attention mask.
+ """
+
+ sequence_length = num_patches
+ ocr_points_x = torch.clip(
+ torch.floor((bbox[:, :, 0] + bbox[:, :, 2]) / 2.0 * sequence_length).long(), 0, sequence_length - 1
+ )
+ ocr_points_y = (
+ torch.clip(torch.floor((bbox[:, :, 1] + bbox[:, :, 3]) / 2.0 * sequence_length).long(), 0, sequence_length - 1)
+ * sequence_length
+ )
+ ocr_points = ocr_points_x + ocr_points_y
+ # make sure bounding boxes are of type float to calculate means
+ bbox = bbox.to(torch.float64)
+ target_seg = (bbox.mean(-1) == 0.0) | (bbox.mean(-1) == 1.0)
+ repeated_vision_embeds = torch.gather(
+ image_embeddings, 1, ocr_points.unsqueeze(-1).repeat(1, 1, image_embeddings.size(-1))
+ )
+ repeated_vision_embeds[target_seg] = 0.0
+ inputs_embeds += repeated_vision_embeds
+
+ patch_inds = torch.full_like(image_embeddings[:, :, 0], True).bool()
+ ind = torch.cat(
+ [
+ torch.arange(len(ocr_points))[:, None].repeat(1, ocr_points.size(-1))[:, :, None].to(ocr_points),
+ ocr_points[:, :, None],
+ ],
+ dim=-1,
+ )
+ ind = ind.flatten(0, 1)
+ rows, cols = zip(*ind)
+ patch_inds[rows, cols] = False
+
+ input_vision_patches = [image_embeddings[i][patch_inds[i]] for i in range(len(patch_inds))]
+
+ if visual_bbox is None:
+ visual_bbox = get_visual_bbox(image_size=image_size, patch_size=patch_size)
+ visual_bbox = visual_bbox.unsqueeze(0).repeat(image_embeddings.size(0), 1, 1)
+ visual_bbox = visual_bbox.to(image_embeddings.device)
+
+ visual_bbox = [visual_bbox[i][patch_inds[i]] for i in range(len(patch_inds))]
+ if attention_mask is not None:
+ visual_attention_mask = [torch.tensor([1] * len(item)).to(attention_mask) for item in visual_bbox]
+
+ if max_len == 0:
+ max_len = image_embeddings.size(1)
+ else:
+ max_len = max_len - inputs_embeds.size(1)
+ inputs_vision_patches = torch.stack(
+ [pad_sequence(item, max_len, torch.zeros_like(image_embeddings[0, 0])) for item in input_vision_patches]
+ )
+ visual_bbox = torch.stack([pad_sequence(item, max_len, torch.zeros_like(bbox[0, 0])) for item in visual_bbox])
+ if attention_mask is not None:
+ visual_attention_mask = torch.stack(
+ [pad_sequence(item, max_len, torch.zeros_like(attention_mask[0, 0])) for item in visual_attention_mask]
+ )
+
+ inputs_embeds = torch.cat([inputs_embeds, inputs_vision_patches], 1)
+ bbox = torch.cat([bbox, visual_bbox], 1)
+ if attention_mask is not None:
+ attention_mask = torch.cat([attention_mask, visual_attention_mask], 1)
+ return inputs_embeds, bbox, attention_mask
+
+
+class UdopPatchEmbeddings(nn.Module):
+ """2D Image to Patch Embeddings"""
+
+ def __init__(self, config):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+
+ self.proj = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def forward(self, pixel_values):
+ batch_size, num_channels, height, width = pixel_values.shape
+ if height != self.image_size[0] or width != self.image_size[1]:
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})."
+ )
+ embeddings = self.proj(pixel_values)
+ embeddings = embeddings.flatten(2).transpose(1, 2)
+ return embeddings
+
+
+@auto_docstring
+class UdopPreTrainedModel(PreTrainedModel):
+ config: UdopConfig
+ base_model_prefix = "transformer"
+ supports_gradient_checkpointing = True
+
+ _can_compile_fullgraph = False
+ _keep_in_fp32_modules = ["wo"]
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ factor = self.config.initializer_factor # Used for testing weights initialization
+ if isinstance(module, UdopLayerNorm):
+ module.weight.data.fill_(factor * 1.0)
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=factor)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.Conv2d):
+ # Upcast the input in `fp32` and cast it back to desired `dtype` to avoid
+ # `trunc_normal_cpu` not implemented in `half` issues
+ module.weight.data = nn.init.trunc_normal_(module.weight.data.to(torch.float32), mean=0.0, std=factor).to(
+ module.weight.dtype
+ )
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, RelativePositionBiasBase):
+ factor = self.config.initializer_factor
+ d_model = self.config.d_model
+ module.relative_attention_bias.weight.data.normal_(mean=0.0, std=factor * ((d_model) ** -0.5))
+ elif isinstance(module, UdopModel):
+ # Mesh TensorFlow embeddings initialization
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L1624
+ module.shared.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ elif isinstance(module, UdopForConditionalGeneration):
+ if hasattr(module, "lm_head") and not self.config.tie_word_embeddings:
+ module.lm_head.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ elif isinstance(module, UdopDenseActDense):
+ # Mesh TensorFlow FF initialization
+ # See https://github.com/tensorflow/mesh/blob/master/mesh_tensorflow/transformer/transformer_layers.py#L56
+ # and https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L89
+ module.wi.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi, "bias") and module.wi.bias is not None:
+ module.wi.bias.data.zero_()
+ module.wo.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_ff) ** -0.5))
+ if hasattr(module.wo, "bias") and module.wo.bias is not None:
+ module.wo.bias.data.zero_()
+ elif isinstance(module, UdopDenseGatedActDense):
+ module.wi_0.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi_0, "bias") and module.wi_0.bias is not None:
+ module.wi_0.bias.data.zero_()
+ module.wi_1.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi_1, "bias") and module.wi_1.bias is not None:
+ module.wi_1.bias.data.zero_()
+ module.wo.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_ff) ** -0.5))
+ if hasattr(module.wo, "bias") and module.wo.bias is not None:
+ module.wo.bias.data.zero_()
+ elif isinstance(module, UdopAttention):
+ # Mesh TensorFlow attention initialization to avoid scaling before softmax
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/attention.py#L136
+ d_model = self.config.d_model
+ key_value_proj_dim = self.config.d_kv
+ n_heads = self.config.num_heads
+ module.q.weight.data.normal_(mean=0.0, std=factor * ((d_model * key_value_proj_dim) ** -0.5))
+ module.k.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.v.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.o.weight.data.normal_(mean=0.0, std=factor * ((n_heads * key_value_proj_dim) ** -0.5))
+ if module.has_relative_attention_bias:
+ module.relative_attention_bias.weight.data.normal_(mean=0.0, std=factor * ((d_model) ** -0.5))
+
+ # Copied from transformers.models.prophetnet.modeling_prophetnet.ProphetNetPreTrainedModel._shift_right with ProphetNet->Udop
+ def _shift_right(self, input_ids):
+ decoder_start_token_id = self.config.decoder_start_token_id
+ pad_token_id = self.config.pad_token_id
+
+ assert decoder_start_token_id is not None, (
+ "self.model.config.decoder_start_token_id has to be defined. In Udop it is usually set to the"
+ " pad_token_id. See Udop docs for more information"
+ )
+
+ # shift inputs to the right
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
+ shifted_input_ids[..., 0] = decoder_start_token_id
+
+ assert pad_token_id is not None, "self.model.config.pad_token_id has to be defined."
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ assert torch.all(shifted_input_ids >= 0).item(), "Verify that `shifted_input_ids` has only positive values"
+
+ return shifted_input_ids
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerNorm with T5->Udop
+class UdopLayerNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ Construct a layernorm module in the Udop style. No bias and no subtraction of mean.
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ # Udop uses a layer_norm which only scales and doesn't shift, which is also known as Root Mean
+ # Square Layer Normalization https://huggingface.co/papers/1910.07467 thus variance is calculated
+ # w/o mean and there is no bias. Additionally we want to make sure that the accumulation for
+ # half-precision inputs is done in fp32
+
+ variance = hidden_states.to(torch.float32).pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+
+ # convert into half-precision if necessary
+ if self.weight.dtype in [torch.float16, torch.bfloat16]:
+ hidden_states = hidden_states.to(self.weight.dtype)
+
+ return self.weight * hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5DenseActDense with T5->Udop
+class UdopDenseActDense(nn.Module):
+ def __init__(self, config: UdopConfig):
+ super().__init__()
+ self.wi = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.act = ACT2FN[config.dense_act_fn]
+
+ def forward(self, hidden_states):
+ hidden_states = self.wi(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ if (
+ isinstance(self.wo.weight, torch.Tensor)
+ and hidden_states.dtype != self.wo.weight.dtype
+ and self.wo.weight.dtype != torch.int8
+ ):
+ hidden_states = hidden_states.to(self.wo.weight.dtype)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5DenseGatedActDense with T5->Udop
+class UdopDenseGatedActDense(nn.Module):
+ def __init__(self, config: UdopConfig):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.act = ACT2FN[config.dense_act_fn]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+
+ # To make 8bit quantization work for google/flan-t5-xxl, self.wo is kept in float32.
+ # See https://github.com/huggingface/transformers/issues/20287
+ # we also make sure the weights are not in `int8` in case users will force `_keep_in_fp32_modules` to be `None``
+ if (
+ isinstance(self.wo.weight, torch.Tensor)
+ and hidden_states.dtype != self.wo.weight.dtype
+ and self.wo.weight.dtype != torch.int8
+ ):
+ hidden_states = hidden_states.to(self.wo.weight.dtype)
+
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerFF with T5->Udop
+class UdopLayerFF(nn.Module):
+ def __init__(self, config: UdopConfig):
+ super().__init__()
+ if config.is_gated_act:
+ self.DenseReluDense = UdopDenseGatedActDense(config)
+ else:
+ self.DenseReluDense = UdopDenseActDense(config)
+
+ self.layer_norm = UdopLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ hidden_states = hidden_states + self.dropout(forwarded_states)
+ return hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5Attention with T5->Udop
+class UdopAttention(nn.Module):
+ def __init__(
+ self,
+ config: UdopConfig,
+ has_relative_attention_bias=False,
+ layer_idx: Optional[int] = None,
+ ):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.has_relative_attention_bias = has_relative_attention_bias
+ self.relative_attention_num_buckets = config.relative_attention_num_buckets
+ self.relative_attention_max_distance = config.relative_attention_max_distance
+ self.d_model = config.d_model
+ self.key_value_proj_dim = config.d_kv
+ self.n_heads = config.num_heads
+ self.dropout = config.dropout_rate
+ self.inner_dim = self.n_heads * self.key_value_proj_dim
+ self.layer_idx = layer_idx
+ if layer_idx is None and self.is_decoder:
+ logger.warning_once(
+ f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and "
+ "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+
+ # Mesh TensorFlow initialization to avoid scaling before softmax
+ self.q = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.k = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.v = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.o = nn.Linear(self.inner_dim, self.d_model, bias=False)
+
+ if self.has_relative_attention_bias:
+ self.relative_attention_bias = nn.Embedding(self.relative_attention_num_buckets, self.n_heads)
+ self.pruned_heads = set()
+ self.gradient_checkpointing = False
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.n_heads, self.key_value_proj_dim, self.pruned_heads
+ )
+ # Prune linear layers
+ self.q = prune_linear_layer(self.q, index)
+ self.k = prune_linear_layer(self.k, index)
+ self.v = prune_linear_layer(self.v, index)
+ self.o = prune_linear_layer(self.o, index, dim=1)
+ # Update hyper params
+ self.n_heads = self.n_heads - len(heads)
+ self.inner_dim = self.key_value_proj_dim * self.n_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ @staticmethod
+ def _relative_position_bucket(relative_position, bidirectional=True, num_buckets=32, max_distance=128):
+ """
+ Adapted from Mesh Tensorflow:
+ https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593
+
+ Translate relative position to a bucket number for relative attention. The relative position is defined as
+ memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to
+ position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for
+ small absolute relative_position and larger buckets for larger absolute relative_positions. All relative
+ positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket.
+ This should allow for more graceful generalization to longer sequences than the model has been trained on
+
+ Args:
+ relative_position: an int32 Tensor
+ bidirectional: a boolean - whether the attention is bidirectional
+ num_buckets: an integer
+ max_distance: an integer
+
+ Returns:
+ a Tensor with the same shape as relative_position, containing int32 values in the range [0, num_buckets)
+ """
+ relative_buckets = 0
+ if bidirectional:
+ num_buckets //= 2
+ relative_buckets += (relative_position > 0).to(torch.long) * num_buckets
+ relative_position = torch.abs(relative_position)
+ else:
+ relative_position = -torch.min(relative_position, torch.zeros_like(relative_position))
+ # now relative_position is in the range [0, inf)
+
+ # half of the buckets are for exact increments in positions
+ max_exact = num_buckets // 2
+ is_small = relative_position < max_exact
+
+ # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance
+ relative_position_if_large = max_exact + (
+ torch.log(relative_position.float() / max_exact)
+ / math.log(max_distance / max_exact)
+ * (num_buckets - max_exact)
+ ).to(torch.long)
+ relative_position_if_large = torch.min(
+ relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1)
+ )
+
+ relative_buckets += torch.where(is_small, relative_position, relative_position_if_large)
+ return relative_buckets
+
+ def compute_bias(self, query_length, key_length, device=None, cache_position=None):
+ """Compute binned relative position bias"""
+ if device is None:
+ device = self.relative_attention_bias.weight.device
+ if cache_position is None:
+ context_position = torch.arange(query_length, dtype=torch.long, device=device)[:, None]
+ else:
+ context_position = cache_position[:, None].to(device)
+ memory_position = torch.arange(key_length, dtype=torch.long, device=device)[None, :]
+ relative_position = memory_position - context_position # shape (query_length, key_length)
+ relative_position_bucket = self._relative_position_bucket(
+ relative_position, # shape (query_length, key_length)
+ bidirectional=(not self.is_decoder),
+ num_buckets=self.relative_attention_num_buckets,
+ max_distance=self.relative_attention_max_distance,
+ )
+ values = self.relative_attention_bias(relative_position_bucket) # shape (query_length, key_length, num_heads)
+ values = values.permute([2, 0, 1]).unsqueeze(0) # shape (1, num_heads, query_length, key_length)
+ return values
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ mask=None,
+ key_value_states=None,
+ position_bias=None,
+ past_key_values=None,
+ layer_head_mask=None,
+ query_length=None,
+ use_cache=False,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ """
+ Self-attention (if key_value_states is None) or attention over source sentence (provided by key_value_states).
+ """
+ # Input is (batch_size, seq_length, dim)
+ # Mask is (batch_size, 1, 1, key_length) (non-causal encoder) or (batch_size, 1, seq_length, key_length) (causal decoder)
+ batch_size, seq_length = hidden_states.shape[:2]
+
+ # if key_value_states are provided this layer is used as a cross-attention layer for the decoder
+ is_cross_attention = key_value_states is not None
+
+ query_states = self.q(hidden_states)
+ query_states = query_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ # Check is encoder-decoder model is being used. Otherwise we'll get `DynamicCache`
+ if past_key_values is not None and isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k(current_states)
+ value_states = self.v(current_states)
+ key_states = key_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+ value_states = value_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # compute scores, equivalent of torch.einsum("bnqd,bnkd->bnqk", query_states, key_states), compatible with onnx op>9
+ scores = torch.matmul(query_states, key_states.transpose(3, 2))
+
+ if position_bias is None:
+ key_length = key_states.shape[-2]
+ # cache position is 0-indexed so we add 1 to get the real length of queries (aka with past)
+ real_seq_length = query_length if query_length is not None else cache_position[-1] + 1
+ if not self.has_relative_attention_bias:
+ position_bias = torch.zeros(
+ (1, self.n_heads, seq_length, key_length), device=scores.device, dtype=scores.dtype
+ )
+ if self.gradient_checkpointing and self.training:
+ position_bias.requires_grad = True
+ else:
+ position_bias = self.compute_bias(
+ real_seq_length, key_length, device=scores.device, cache_position=cache_position
+ )
+ position_bias = position_bias[:, :, -seq_length:, :]
+
+ if mask is not None:
+ causal_mask = mask[:, :, :, : key_states.shape[-2]]
+ position_bias = position_bias + causal_mask
+
+ if self.pruned_heads:
+ mask = torch.ones(position_bias.shape[1])
+ mask[list(self.pruned_heads)] = 0
+ position_bias_masked = position_bias[:, mask.bool()]
+ else:
+ position_bias_masked = position_bias
+
+ scores += position_bias_masked
+
+ # (batch_size, n_heads, seq_length, key_length)
+ attn_weights = nn.functional.softmax(scores.float(), dim=-1).type_as(scores)
+ attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ # Mask heads if we want to
+ if layer_head_mask is not None:
+ attn_weights = attn_weights * layer_head_mask
+
+ attn_output = torch.matmul(attn_weights, value_states)
+
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ attn_output = attn_output.view(batch_size, -1, self.inner_dim)
+ attn_output = self.o(attn_output)
+
+ outputs = (attn_output, position_bias)
+
+ if output_attentions:
+ outputs = outputs + (attn_weights,)
+ return outputs
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerSelfAttention with T5->Udop
+class UdopLayerSelfAttention(nn.Module):
+ def __init__(self, config, has_relative_attention_bias=False, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.SelfAttention = UdopAttention(
+ config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx
+ )
+ self.layer_norm = UdopLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.SelfAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0])
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerCrossAttention with T5->Udop
+class UdopLayerCrossAttention(nn.Module):
+ def __init__(self, config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.EncDecAttention = UdopAttention(config, has_relative_attention_bias=False, layer_idx=layer_idx)
+ self.layer_norm = UdopLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ key_value_states,
+ attention_mask=None,
+ position_bias=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ query_length=None,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.EncDecAttention(
+ normed_hidden_states,
+ mask=attention_mask,
+ key_value_states=key_value_states,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ query_length=query_length,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ layer_output = hidden_states + self.dropout(attention_output[0])
+ outputs = (layer_output,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.t5.modeling_t5.T5Block with T5->Udop
+class UdopBlock(GradientCheckpointingLayer):
+ def __init__(self, config, has_relative_attention_bias=False, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.layer = nn.ModuleList()
+ self.layer.append(
+ UdopLayerSelfAttention(
+ config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx
+ )
+ )
+ if self.is_decoder:
+ self.layer.append(UdopLayerCrossAttention(config, layer_idx=layer_idx))
+
+ self.layer.append(UdopLayerFF(config))
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ position_bias=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ encoder_decoder_position_bias=None,
+ layer_head_mask=None,
+ cross_attn_layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=False,
+ return_dict=True,
+ cache_position=None,
+ ):
+ self_attention_outputs = self.layer[0](
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = self_attention_outputs[0]
+ attention_outputs = self_attention_outputs[1:] # Keep self-attention outputs and relative position weights
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.where(
+ torch.isinf(hidden_states).any(),
+ torch.finfo(hidden_states.dtype).max - 1000,
+ torch.finfo(hidden_states.dtype).max,
+ )
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ do_cross_attention = self.is_decoder and encoder_hidden_states is not None
+ if do_cross_attention:
+ cross_attention_outputs = self.layer[1](
+ hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ position_bias=encoder_decoder_position_bias,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ query_length=cache_position[-1] + 1,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ )
+ hidden_states = cross_attention_outputs[0]
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.where(
+ torch.isinf(hidden_states).any(),
+ torch.finfo(hidden_states.dtype).max - 1000,
+ torch.finfo(hidden_states.dtype).max,
+ )
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ # Keep cross-attention outputs and relative position weights
+ attention_outputs = attention_outputs + cross_attention_outputs[1:]
+
+ # Apply Feed Forward layer
+ hidden_states = self.layer[-1](hidden_states)
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.where(
+ torch.isinf(hidden_states).any(),
+ torch.finfo(hidden_states.dtype).max - 1000,
+ torch.finfo(hidden_states.dtype).max,
+ )
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ outputs = (hidden_states,)
+
+ return (
+ outputs + attention_outputs
+ ) # hidden-states, (self-attention position bias), (self-attention weights), (cross-attention position bias), (cross-attention weights)
+
+
+class UdopCellEmbeddings(nn.Module):
+ def __init__(self, max_2d_position_embeddings=501, hidden_size=1024):
+ super().__init__()
+ self.max_2d_position_embeddings = max_2d_position_embeddings
+
+ self.x_position_embeddings = nn.Embedding(max_2d_position_embeddings, hidden_size)
+ self.y_position_embeddings = nn.Embedding(max_2d_position_embeddings, hidden_size)
+
+ def forward(self, bbox):
+ bbox = torch.clip(bbox, 0.0, 1.0)
+ bbox = (bbox * (self.max_2d_position_embeddings - 1)).long()
+ left_position_embeddings = self.x_position_embeddings(bbox[:, :, 0])
+ upper_position_embeddings = self.y_position_embeddings(bbox[:, :, 1])
+ right_position_embeddings = self.x_position_embeddings(bbox[:, :, 2])
+ lower_position_embeddings = self.y_position_embeddings(bbox[:, :, 3])
+
+ embeddings = (
+ left_position_embeddings
+ + upper_position_embeddings
+ + right_position_embeddings
+ + lower_position_embeddings
+ )
+
+ return embeddings
+
+
+# get function for bucket computation
+# protected member access seems to be lesser evil than copy paste whole function
+get_relative_position_bucket = UdopAttention._relative_position_bucket
+AUGMENTATION_RANGE = (0.80, 1.25)
+
+
+class RelativePositionBiasBase(nn.Module, ABC):
+ """
+ Base class of relative biases.
+
+ Args:
+ num_heads (`int`):
+ Number of attention heads in the model, it will create embeddings of size `num_heads`, which will be added to the scores of each token pair.
+ relative_attention_num_buckets (`int`, *optional*, defaults to 32):
+ Pair token metric (distance in the sequence, distance in pixels etc.) will be bucketed, parameter is defining number of such
+ buckets.
+ bidirectional (`bool`, *optional*, defaults to `True`):
+ Whether the distance should be bidirectional for a pair of tokens. If `False`, then distance(tok1, tok2) == distance(tok2, tok1).
+ scaling_factor (`int`, *optional*, defaults to 1):
+ Defining factor which will be used to scale relative distance.
+ max_distance (`int`, *optional*, defaults to 128):
+ All distances above this value will end up in the one/same bucket.
+ augmentation (`bool`, *optional*, defaults to `False`):
+ Whether to multiply relative distances by a random scalar.
+ expand (`bool`, *optional*, defaults to `False`):
+ Whether to expand an existing pretrained model with subsequent additions of prefix_bucket.
+ """
+
+ def __init__(
+ self,
+ num_heads=None,
+ relative_attention_num_buckets=32,
+ bidirectional=True,
+ scaling_factor=1,
+ max_distance=128,
+ level="tokens",
+ augmentation=False,
+ prefix_bucket=False,
+ expand=False,
+ ):
+ super().__init__()
+ self.prefix_bucket = prefix_bucket
+ self.augmentation = augmentation
+ self.level = level
+ self.max_distance = max_distance
+ self.scaling_factor = scaling_factor
+ self.bidirectional = bidirectional
+ self.num_heads = num_heads
+ self.expand = expand
+ self.relative_attention_num_buckets = relative_attention_num_buckets
+ extra_head = 2 if prefix_bucket and not self.expand else 0
+ self.relative_attention_bias = nn.Embedding(self.relative_attention_num_buckets + extra_head, self.num_heads)
+
+ @abstractmethod
+ def prepare_input(
+ self,
+ attention_mask: Optional[Tensor] = None,
+ bbox: Optional[dict[str, Any]] = None,
+ ) -> Tensor:
+ pass
+
+ def get_bucket(self, attention_mask: Optional[Tensor] = None, bbox: Optional[dict[str, Any]] = None) -> Tensor:
+ relative_position = self.prepare_input(attention_mask, bbox)
+ rp_bucket: Tensor = get_relative_position_bucket(
+ relative_position,
+ bidirectional=self.bidirectional,
+ num_buckets=self.relative_attention_num_buckets,
+ max_distance=self.max_distance,
+ )
+ return rp_bucket
+
+ def get_relative_position(self, positions):
+ context_position = positions[:, :, None]
+ memory_position = positions[:, None, :]
+ relative_position = memory_position - context_position
+ if self.augmentation and self.training:
+ relative_position *= random.uniform(*AUGMENTATION_RANGE)
+ relative_position *= self.scaling_factor
+
+ return relative_position.to(torch.long)
+
+ def forward(self, attention_mask: Optional[Tensor] = None, bbox: Optional[dict[str, Any]] = None) -> Tensor:
+ # re-using pretrained model with subsequent addition of prefix_bucket
+ if self.expand and self.prefix_bucket:
+ new_bias = nn.Embedding(self.relative_attention_num_buckets + 2, self.num_heads)
+ new_bias.weight.data[: self.relative_attention_num_buckets] = self.relative_attention_bias.weight.data
+ new_bias.weight.data[self.relative_attention_num_buckets :] = 0.1
+ self.relative_attention_bias = new_bias
+ self.expand = False
+
+ rp_bucket = self.get_bucket(attention_mask, bbox)
+
+ if self.prefix_bucket:
+ if rp_bucket.size(0) == 1 and attention_mask.size(0) > 1:
+ rp_bucket = rp_bucket.repeat(attention_mask.size(0), 1, 1)
+ # based on assumption that prefix bboxes are negative
+ is_prefix = bbox[:, :, 1] < 0
+ num_prefix = is_prefix.sum(-1)
+ for idx, num_prefix_row in enumerate(num_prefix.cpu().numpy()):
+ rp_bucket[idx, :num_prefix_row, num_prefix_row:] = self.relative_attention_num_buckets
+ rp_bucket[idx, num_prefix_row:, :num_prefix_row] = self.relative_attention_num_buckets + 1
+
+ values: Tensor = self.relative_attention_bias(rp_bucket)
+ if values.dim() != 4:
+ raise ValueError("Wrong dimension of values tensor")
+ values = values.permute([0, 3, 1, 2])
+
+ return values
+
+
+class RelativePositionBias1D(RelativePositionBiasBase):
+ def __init__(self, scaling_factor=1, max_distance=128, **kwargs):
+ """
+ Reimplementation of T5 relative position bias. Distance between given tokens is their distance in the sequence.
+ Parameters are the same as in base class
+ """
+ super().__init__(scaling_factor=scaling_factor, max_distance=max_distance, **kwargs)
+
+ def prepare_input(self, attention_mask: Optional[Tensor] = None, bbox: Optional[dict[str, Any]] = None) -> Tensor:
+ if self.scaling_factor != 1:
+ raise ValueError("No need to scale 1d features")
+ relative_position = self.get_relative_position(
+ torch.arange(attention_mask.size(1), dtype=torch.long, device=attention_mask.device)[None, :]
+ )
+
+ return relative_position
+
+
+class RelativePositionBiasHorizontal(RelativePositionBiasBase):
+ def __init__(self, scaling_factor=100, max_distance=100, **kwargs):
+ """
+ Represents in the bucket embeddings horizontal distance between two tokens. Parameters are the same as in base
+ class
+ """
+ super().__init__(scaling_factor=scaling_factor, max_distance=max_distance, **kwargs)
+
+ def prepare_input(self, attention_mask: Optional[Tensor] = None, bbox: Optional[dict[str, Any]] = None) -> Tensor:
+ if not self.scaling_factor > 1.0:
+ raise ValueError("Need to scale the values of bboxes, as there are in small (0,1) range")
+ if bbox is None:
+ raise ValueError("Bbox is required for horizontal relative position bias")
+ # get x positions of left point of bbox
+ horizontal_position: Tensor = bbox[:, :, [0, 2]].mean(dim=-1)
+
+ return self.get_relative_position(horizontal_position)
+
+
+class RelativePositionBiasVertical(RelativePositionBiasBase):
+ def __init__(self, scaling_factor=100, max_distance=100, **kwargs):
+ """
+ Represents in the bucket embeddings vertical distance between two tokens. Parameters are the same as in base
+ class
+ """
+ super().__init__(scaling_factor=scaling_factor, max_distance=max_distance, **kwargs)
+
+ def prepare_input(self, attention_mask: Optional[Tensor] = None, bbox: Optional[dict[str, Any]] = None) -> Tensor:
+ if not self.scaling_factor > 1.0:
+ raise ValueError("Need to scale the values of bboxes, as there are in small (0,1) range")
+ if bbox is None:
+ raise ValueError("Bbox is required for vertical relative position bias")
+ # get y positions of middle of bbox
+ vertical_position: Tensor = bbox[:, :, [1, 3]].mean(dim=-1)
+
+ return self.get_relative_position(vertical_position)
+
+
+class RelativePositionBiasAggregated(nn.Module):
+ def __init__(self, modules: Sequence[RelativePositionBiasBase]):
+ """
+ Class which sums up various computed biases.
+
+ Args:
+ modules (Sequence[RelativePositionBiasBase]):
+ List of relative bias modules.
+ """
+ super().__init__()
+ self.biases = nn.ModuleList(modules)
+
+ def forward(
+ self, attention_mask: Optional[Tensor] = None, bbox: Optional[dict[str, Any]] = None
+ ) -> Union[float, Tensor]:
+ output = 0.0
+ for bias in self.biases: # type: ignore
+ output = bias(attention_mask, bbox) + output
+
+ return output
+
+
+BIAS_CLASSES = {
+ "1d": RelativePositionBias1D,
+ "horizontal": RelativePositionBiasHorizontal,
+ "vertical": RelativePositionBiasVertical,
+}
+
+
+def create_relative_bias(config: UdopConfig) -> Sequence[RelativePositionBiasBase]:
+ """
+ Creates empty list or one/multiple relative biases.
+
+ :param config: Model's configuration :return: Sequence with created bias modules.
+ """
+ bias_list = []
+ if hasattr(config, "relative_bias_args"):
+ for bias_kwargs_org in config.relative_bias_args:
+ bias_kwargs = deepcopy(bias_kwargs_org)
+ bias_type = bias_kwargs.pop("type")
+ model_num_heads = config.num_heads if hasattr(config, "num_heads") else config.num_attention_heads
+ if "num_heads" in bias_kwargs:
+ if bias_kwargs["num_heads"] != model_num_heads:
+ raise ValueError("Number of heads must match num of heads in the model")
+ else:
+ bias_kwargs["num_heads"] = model_num_heads
+ bias_list.append(BIAS_CLASSES[bias_type](**bias_kwargs)) # type: ignore
+
+ return bias_list
+
+
+class UdopStack(UdopPreTrainedModel):
+ """
+ This class is based on `T5Stack`, but modified to take into account the image modality as well as 2D position
+ embeddings.
+ """
+
+ def __init__(self, config, embed_tokens=None, embed_patches=None):
+ super().__init__(config)
+
+ self.embed_tokens = embed_tokens
+ self.embed_patches = embed_patches
+ self.is_decoder = config.is_decoder
+ self._max_length = config.max_length
+ self.num_layers = config.num_layers
+
+ self.block = nn.ModuleList(
+ [UdopBlock(config, has_relative_attention_bias=bool(i == 0), layer_idx=i) for i in range(self.num_layers)]
+ )
+ self.final_layer_norm = UdopLayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ if not self.is_decoder:
+ self.cell_2d_embedding = UdopCellEmbeddings(config.max_2d_position_embeddings, config.hidden_size)
+
+ # get weights from encoder position bias
+ self.relative_bias = self._get_relative_bias(config)
+
+ def _tie_weights(self):
+ for bias in self.relative_bias.biases:
+ if isinstance(bias, RelativePositionBias1D):
+ self._tie_or_clone_weights(
+ bias.relative_attention_bias, self.block[0].layer[0].SelfAttention.relative_attention_bias
+ )
+
+ @staticmethod
+ def _get_relative_bias(config: UdopConfig) -> RelativePositionBiasAggregated:
+ relative_bias_list = create_relative_bias(config)
+ return RelativePositionBiasAggregated(relative_bias_list)
+
+ def get_output_embeddings(self):
+ return self.embed_tokens
+
+ def set_input_embeddings(self, new_embeddings):
+ self.embed_tokens = new_embeddings
+
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ bbox=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ inputs_embeds=None,
+ pixel_values=None,
+ visual_bbox=None,
+ image_embeddings=None,
+ position_bias=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ cache_position=None,
+ ):
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # input embeddings processing
+
+ if input_ids is not None and inputs_embeds is not None:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(
+ f"You cannot specify both {err_msg_prefix}inputs and {err_msg_prefix}inputs_embeds at the same time"
+ )
+ elif input_ids is not None and torch.numel(input_ids) > 0:
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ elif inputs_embeds is None and input_ids is not None and torch.numel(input_ids) == 0:
+ input_ids = torch.full((4, 1024), self.config.pad_token_id, device=input_ids.device, dtype=input_ids.dtype)
+ attention_mask = torch.zeros((4, 1024), device=input_ids.device, dtype=input_ids.dtype)
+ bbox = torch.zeros((4, 1024, 4), device=input_ids.device, dtype=input_ids.dtype)
+ input_shape = input_ids.size()
+ position_bias = torch.zeros_like(self.get_extended_attention_mask(attention_mask, input_shape))
+ # encoder_attention_mask = attention_mask
+ logger.warning("Empty batch")
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(f"You have to specify either {err_msg_prefix}inputs or {err_msg_prefix}inputs_embeds")
+
+ if inputs_embeds is None:
+ if self.embed_tokens is None:
+ raise ValueError("You have to initialize the model with valid token embeddings")
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if pixel_values is not None:
+ image_embeddings = self.embed_patches(pixel_values)
+
+ if image_embeddings is not None:
+ # combine visual and OCR text embeddings
+ num_patches = self.config.image_size // self.config.patch_size
+ inputs_embeds, bbox, attention_mask = combine_image_text_embeddings(
+ image_embeddings,
+ inputs_embeds,
+ bbox,
+ visual_bbox,
+ attention_mask,
+ num_patches,
+ 0,
+ self.config.image_size,
+ self.config.patch_size,
+ )
+ input_shape = inputs_embeds.size()[:-1]
+
+ if not self.is_decoder and bbox is not None:
+ inputs_embeds += self.cell_2d_embedding(bbox)
+
+ batch_size, seq_length = input_shape
+
+ if use_cache is True:
+ assert self.is_decoder, f"`use_cache` can only be set to `True` if {self} is used as a decoder"
+
+ if self.is_decoder:
+ if use_cache and past_key_values is None:
+ if self.config.is_encoder_decoder:
+ past_key_values = EncoderDecoderCache(
+ DynamicCache(config=self.config), DynamicCache(config=self.config)
+ )
+ else:
+ past_key_values = DynamicCache(config=self.config)
+ elif not self.is_decoder:
+ # do not pass cache object down the line for encoder stack
+ # it messes indexing later in decoder-stack because cache object is modified in-place
+ past_key_values = None
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+ if cache_position is None:
+ cache_position = torch.arange(
+ past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device
+ )
+
+ if attention_mask is None and not is_torchdynamo_compiling():
+ # required mask seq length can be calculated via length of past cache
+ mask_seq_length = past_key_values_length + seq_length
+ attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device)
+
+ if self.config.is_decoder:
+ causal_mask = self._update_causal_mask(
+ attention_mask,
+ inputs_embeds,
+ cache_position,
+ past_key_values.self_attention_cache
+ if isinstance(past_key_values, EncoderDecoderCache)
+ else past_key_values,
+ output_attentions,
+ )
+ else:
+ causal_mask = attention_mask[:, None, None, :]
+ causal_mask = causal_mask.to(dtype=inputs_embeds.dtype)
+ causal_mask = (1.0 - causal_mask) * torch.finfo(inputs_embeds.dtype).min
+
+ if self.is_decoder and encoder_attention_mask is not None:
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ head_mask = self.get_head_mask(head_mask, self.num_layers)
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and self.is_decoder) else None
+
+ if self.is_decoder: # modified lines
+ position_bias = None
+ else:
+ position_bias = self.relative_bias(attention_mask=attention_mask, bbox=bbox)
+ position_bias = position_bias + causal_mask
+ encoder_decoder_position_bias = None
+
+ hidden_states = inputs_embeds
+
+ hidden_states = self.dropout(hidden_states)
+
+ for i, layer_module in enumerate(self.block):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states,
+ causal_mask,
+ position_bias,
+ encoder_hidden_states,
+ encoder_extended_attention_mask,
+ encoder_decoder_position_bias, # as a positional argument for gradient checkpointing
+ layer_head_mask=head_mask[i],
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ # We share the position biases between the layers - the first layer store them
+ # layer_outputs = hidden-states, key-value-states (self-attention weights),
+ # (self-attention position bias), (cross-attention weights), (cross-attention position bias)
+
+ position_bias = layer_outputs[1]
+ if self.is_decoder and encoder_hidden_states is not None:
+ encoder_decoder_position_bias = layer_outputs[3 if output_attentions else 2]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[2],) # We keep only self-attention weights for now
+ if self.is_decoder:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[4],)
+
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ attention_mask,
+ past_key_values,
+ all_hidden_states,
+ all_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+
+ return BaseModelOutputWithAttentionMask(
+ last_hidden_state=hidden_states,
+ attention_mask=attention_mask,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._update_causal_mask
+ def _update_causal_mask(
+ self,
+ attention_mask: Union[torch.Tensor, "BlockMask"],
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool = False,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+ if self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask)
+ return attention_mask
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_compilable_cache = past_key_values.is_compileable if past_key_values is not None else False
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_compilable_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype = input_tensor.dtype
+ sequence_length = input_tensor.shape[1]
+ if using_compilable_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type in ["cuda", "xpu", "npu"]
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._prepare_4d_causal_attention_mask_with_cache_position
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=cache_position.device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=cache_position.device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :].to(
+ causal_mask.device
+ )
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
+
+
+@auto_docstring
+class UdopModel(UdopPreTrainedModel):
+ _tied_weights_keys = [
+ "encoder.embed_tokens.weight",
+ "decoder.embed_tokens.weight",
+ "encoder.embed_patches.proj.weight",
+ "encoder.embed_patches.proj.bias",
+ "encoder.relative_bias.biases.0.relative_attention_bias.weight",
+ "decoder.relative_bias.biases.0.relative_attention_bias.weight",
+ ]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ # text and image embeddings
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+ self.patch_embed = UdopPatchEmbeddings(config)
+
+ encoder_config = deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = UdopStack(encoder_config, self.shared, self.patch_embed)
+
+ decoder_config = deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = UdopStack(decoder_config, self.shared)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[Tensor] = None,
+ attention_mask: Optional[Tensor] = None,
+ bbox: Optional[dict[str, Any]] = None,
+ pixel_values: Optional[Tensor] = None,
+ visual_bbox: Optional[dict[str, Any]] = None,
+ decoder_input_ids: Optional[Tensor] = None,
+ decoder_attention_mask: Optional[Tensor] = None,
+ inputs_embeds: Optional[Tensor] = None,
+ encoder_outputs: Optional[Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ head_mask: Optional[Tensor] = None,
+ decoder_inputs_embeds: Optional[Tensor] = None,
+ decoder_head_mask: Optional[Tensor] = None,
+ cross_attn_head_mask: Optional[Tensor] = None,
+ use_cache=True,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> tuple[Tensor, ...]:
+ r"""
+ bbox (`torch.LongTensor` of shape `({0}, 4)`, *optional*):
+ Bounding boxes of each input sequence tokens. Selected in the range `[0,
+ config.max_2d_position_embeddings-1]`. Each bounding box should be a normalized version in (x0, y0, x1, y1)
+ format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1,
+ y1) represents the position of the lower right corner.
+
+ Note that `sequence_length = token_sequence_length + patch_sequence_length + 1` where `1` is for [CLS]
+ token. See `pixel_values` for `patch_sequence_length`.
+ visual_bbox (`torch.LongTensor` of shape `(batch_size, patch_sequence_length, 4)`, *optional*):
+ Bounding boxes of each patch in the image. If not provided, bounding boxes are created in the model.
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary. Indices can be obtained using
+ [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details.
+ [What are decoder input IDs?](../glossary#decoder-input-ids) T5 uses the `pad_token_id` as the starting
+ token for `decoder_input_ids` generation. If `past_key_values` is used, optionally only the last
+ `decoder_input_ids` have to be input (see `past_key_values`). To know more on how to prepare
+ `decoder_input_ids` for pretraining take a look at [T5 Training](./t5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> from datasets import load_dataset
+ >>> import torch
+
+ >>> # load model and processor
+ >>> # in this case, we already have performed OCR ourselves
+ >>> # so we initialize the processor with `apply_ocr=False`
+ >>> processor = AutoProcessor.from_pretrained("microsoft/udop-large", apply_ocr=False)
+ >>> model = AutoModel.from_pretrained("microsoft/udop-large")
+
+ >>> # load an example image, along with the words and coordinates
+ >>> # which were extracted using an OCR engine
+ >>> dataset = load_dataset("nielsr/funsd-layoutlmv3", split="train")
+ >>> example = dataset[0]
+ >>> image = example["image"]
+ >>> words = example["tokens"]
+ >>> boxes = example["bboxes"]
+ >>> inputs = processor(image, words, boxes=boxes, return_tensors="pt")
+
+ >>> decoder_input_ids = torch.tensor([[model.config.decoder_start_token_id]])
+
+ >>> # forward pass
+ >>> outputs = model(**inputs, decoder_input_ids=decoder_input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ >>> list(last_hidden_states.shape)
+ [1, 1, 1024]
+ ```"""
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ bbox=bbox,
+ pixel_values=pixel_values,
+ visual_bbox=visual_bbox,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+ encoder_attention_mask = encoder_outputs.attention_mask if return_dict else encoder_outputs[1]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ if not return_dict:
+ # we filter out the attention mask
+ decoder_outputs = tuple(value for idx, value in enumerate(decoder_outputs) if idx != 1)
+ encoder_outputs = tuple(value for idx, value in enumerate(encoder_outputs) if idx != 1)
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The UDOP encoder-decoder Transformer with a language modeling head on top, enabling to generate text given document
+ images and an optional prompt.
+
+ This class is based on [`T5ForConditionalGeneration`], extended to deal with images and layout (2D) data.
+ """
+)
+class UdopForConditionalGeneration(UdopPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = [
+ "encoder.embed_tokens.weight",
+ "decoder.embed_tokens.weight",
+ "encoder.embed_patches.proj.weight",
+ "encoder.embed_patches.proj.bias",
+ "encoder.relative_bias.biases.0.relative_attention_bias.weight",
+ "decoder.relative_bias.biases.0.relative_attention_bias.weight",
+ "lm_head.weight",
+ ]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ # text and image embeddings
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+ self.patch_embed = UdopPatchEmbeddings(config)
+
+ encoder_config = deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = UdopStack(encoder_config, self.shared, self.patch_embed)
+
+ decoder_config = deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = UdopStack(decoder_config, self.shared)
+
+ # The weights of the language modeling head are shared with those of the encoder and decoder
+ self.lm_head = nn.Linear(config.d_model, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[Tensor] = None,
+ attention_mask: Optional[Tensor] = None,
+ bbox: Optional[dict[str, Any]] = None,
+ pixel_values: Optional[Tensor] = None,
+ visual_bbox: Optional[dict[str, Any]] = None,
+ decoder_input_ids: Optional[Tensor] = None,
+ decoder_attention_mask: Optional[Tensor] = None,
+ inputs_embeds: Optional[Tensor] = None,
+ encoder_outputs: Optional[Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ head_mask: Optional[Tensor] = None,
+ decoder_inputs_embeds: Optional[Tensor] = None,
+ decoder_head_mask: Optional[Tensor] = None,
+ cross_attn_head_mask: Optional[Tensor] = None,
+ use_cache=True,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[Tensor] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> tuple[Tensor, ...]:
+ r"""
+ bbox (`torch.LongTensor` of shape `({0}, 4)`, *optional*):
+ Bounding boxes of each input sequence tokens. Selected in the range `[0,
+ config.max_2d_position_embeddings-1]`. Each bounding box should be a normalized version in (x0, y0, x1, y1)
+ format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1,
+ y1) represents the position of the lower right corner.
+
+ Note that `sequence_length = token_sequence_length + patch_sequence_length + 1` where `1` is for [CLS]
+ token. See `pixel_values` for `patch_sequence_length`.
+ visual_bbox (`torch.LongTensor` of shape `(batch_size, patch_sequence_length, 4)`, *optional*):
+ Bounding boxes of each patch in the image. If not provided, bounding boxes are created in the model.
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary. Indices can be obtained using
+ [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details.
+ [What are decoder input IDs?](../glossary#decoder-input-ids) T5 uses the `pad_token_id` as the starting
+ token for `decoder_input_ids` generation. If `past_key_values` is used, optionally only the last
+ `decoder_input_ids` have to be input (see `past_key_values`). To know more on how to prepare
+ `decoder_input_ids` for pretraining take a look at [T5 Training](./t5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the language modeling loss. Indices should be in `[-100, 0, ..., config.vocab_size -
+ 1]`. All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size]`.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoProcessor, UdopForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> # load model and processor
+ >>> # in this case, we already have performed OCR ourselves
+ >>> # so we initialize the processor with `apply_ocr=False`
+ >>> processor = AutoProcessor.from_pretrained("microsoft/udop-large", apply_ocr=False)
+ >>> model = UdopForConditionalGeneration.from_pretrained("microsoft/udop-large")
+
+ >>> # load an example image, along with the words and coordinates
+ >>> # which were extracted using an OCR engine
+ >>> dataset = load_dataset("nielsr/funsd-layoutlmv3", split="train")
+ >>> example = dataset[0]
+ >>> image = example["image"]
+ >>> words = example["tokens"]
+ >>> boxes = example["bboxes"]
+
+ >>> # one can use the various task prefixes (prompts) used during pre-training
+ >>> # e.g. the task prefix for DocVQA is "Question answering. "
+ >>> question = "Question answering. What is the date on the form?"
+ >>> encoding = processor(image, question, text_pair=words, boxes=boxes, return_tensors="pt")
+
+ >>> # autoregressive generation
+ >>> predicted_ids = model.generate(**encoding)
+ >>> print(processor.batch_decode(predicted_ids, skip_special_tokens=True)[0])
+ 9/30/92
+ ```"""
+
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if decoder_input_ids is None and labels is not None:
+ decoder_input_ids = self._shift_right(labels)
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ bbox=bbox,
+ visual_bbox=visual_bbox,
+ pixel_values=pixel_values,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+ encoder_attention_mask = encoder_outputs.attention_mask if return_dict else encoder_outputs[1]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ if self.config.tie_word_embeddings:
+ # Rescale output before projecting on vocab
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/transformer.py#L586
+ sequence_output = sequence_output * (self.config.d_model**-0.5)
+
+ lm_logits = self.lm_head(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss(ignore_index=-100)
+ loss = loss_fct(lm_logits.view(-1, lm_logits.size(-1)), labels.view(-1))
+
+ if not return_dict:
+ output = (lm_logits,) + decoder_outputs[2:] + (encoder_outputs[0],) + encoder_outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=lm_logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring
+class UdopEncoderModel(UdopPreTrainedModel):
+ _tied_weights_keys = [
+ "encoder.embed_tokens.weight",
+ "encoder.embed_patches.proj.weight",
+ "encoder.embed_patches.proj.bias",
+ "encoder.relative_bias.biases.0.relative_attention_bias.weight",
+ ]
+
+ def __init__(self, config: UdopConfig):
+ super().__init__(config)
+
+ # text and image embeddings
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+ self.patch_embed = UdopPatchEmbeddings(config)
+
+ encoder_config = deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.is_encoder_decoder = False
+ self.encoder = UdopStack(encoder_config, self.shared, self.patch_embed)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.shared
+
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+
+ def get_encoder(self):
+ return self.encoder
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.block[layer].layer[0].SelfAttention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[Tensor] = None,
+ bbox: Optional[dict[str, Any]] = None,
+ attention_mask: Optional[Tensor] = None,
+ pixel_values: Optional[Tensor] = None,
+ visual_bbox: Optional[dict[str, Any]] = None,
+ head_mask: Optional[Tensor] = None,
+ inputs_embeds: Optional[Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], BaseModelOutputWithAttentionMask]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. T5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [T5 Training](./t5#training).
+ bbox (`torch.LongTensor` of shape `({0}, 4)`, *optional*):
+ Bounding boxes of each input sequence tokens. Selected in the range `[0,
+ config.max_2d_position_embeddings-1]`. Each bounding box should be a normalized version in (x0, y0, x1, y1)
+ format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1,
+ y1) represents the position of the lower right corner.
+
+ Note that `sequence_length = token_sequence_length + patch_sequence_length + 1` where `1` is for [CLS]
+ token. See `pixel_values` for `patch_sequence_length`.
+ visual_bbox (`torch.LongTensor` of shape `(batch_size, patch_sequence_length, 4)`, *optional*):
+ Bounding boxes of each patch in the image. If not provided, bounding boxes are created in the model.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoProcessor, UdopEncoderModel
+ >>> from huggingface_hub import hf_hub_download
+ >>> from datasets import load_dataset
+
+ >>> # load model and processor
+ >>> # in this case, we already have performed OCR ourselves
+ >>> # so we initialize the processor with `apply_ocr=False`
+ >>> processor = AutoProcessor.from_pretrained("microsoft/udop-large", apply_ocr=False)
+ >>> model = UdopEncoderModel.from_pretrained("microsoft/udop-large")
+
+ >>> # load an example image, along with the words and coordinates
+ >>> # which were extracted using an OCR engine
+ >>> dataset = load_dataset("nielsr/funsd-layoutlmv3", split="train")
+ >>> example = dataset[0]
+ >>> image = example["image"]
+ >>> words = example["tokens"]
+ >>> boxes = example["bboxes"]
+ >>> encoding = processor(image, words, boxes=boxes, return_tensors="pt")
+
+ >>> outputs = model(**encoding)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ bbox=bbox,
+ visual_bbox=visual_bbox,
+ pixel_values=pixel_values,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ return encoder_outputs
+
+
+__all__ = ["UdopForConditionalGeneration", "UdopPreTrainedModel", "UdopModel", "UdopEncoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/processing_udop.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/processing_udop.py
new file mode 100644
index 0000000000000000000000000000000000000000..94b1565c9a22fdf87505cebbe9ae500c8660372c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/processing_udop.py
@@ -0,0 +1,194 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Processor class for UDOP.
+"""
+
+from typing import Optional, Union
+
+from transformers import logging
+
+from ...image_processing_utils import BatchFeature
+from ...image_utils import ImageInput
+from ...processing_utils import ProcessingKwargs, ProcessorMixin, TextKwargs, Unpack
+from ...tokenization_utils_base import PreTokenizedInput, TextInput
+
+
+logger = logging.get_logger(__name__)
+
+
+class UdopTextKwargs(TextKwargs, total=False):
+ word_labels: Optional[Union[list[int], list[list[int]]]]
+ boxes: Union[list[list[int]], list[list[list[int]]]]
+
+
+class UdopProcessorKwargs(ProcessingKwargs, total=False):
+ text_kwargs: UdopTextKwargs
+ _defaults = {
+ "text_kwargs": {
+ "add_special_tokens": True,
+ "padding": False,
+ "truncation": False,
+ "stride": 0,
+ "return_overflowing_tokens": False,
+ "return_special_tokens_mask": False,
+ "return_offsets_mapping": False,
+ "return_length": False,
+ "verbose": True,
+ },
+ "images_kwargs": {},
+ }
+
+
+class UdopProcessor(ProcessorMixin):
+ r"""
+ Constructs a UDOP processor which combines a LayoutLMv3 image processor and a UDOP tokenizer into a single processor.
+
+ [`UdopProcessor`] offers all the functionalities you need to prepare data for the model.
+
+ It first uses [`LayoutLMv3ImageProcessor`] to resize, rescale and normalize document images, and optionally applies OCR
+ to get words and normalized bounding boxes. These are then provided to [`UdopTokenizer`] or [`UdopTokenizerFast`],
+ which turns the words and bounding boxes into token-level `input_ids`, `attention_mask`, `token_type_ids`, `bbox`.
+ Optionally, one can provide integer `word_labels`, which are turned into token-level `labels` for token
+ classification tasks (such as FUNSD, CORD).
+
+ Additionally, it also supports passing `text_target` and `text_pair_target` to the tokenizer, which can be used to
+ prepare labels for language modeling tasks.
+
+ Args:
+ image_processor (`LayoutLMv3ImageProcessor`):
+ An instance of [`LayoutLMv3ImageProcessor`]. The image processor is a required input.
+ tokenizer (`UdopTokenizer` or `UdopTokenizerFast`):
+ An instance of [`UdopTokenizer`] or [`UdopTokenizerFast`]. The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+ image_processor_class = "LayoutLMv3ImageProcessor"
+ tokenizer_class = ("UdopTokenizer", "UdopTokenizerFast")
+
+ def __init__(self, image_processor, tokenizer):
+ super().__init__(image_processor, tokenizer)
+
+ def __call__(
+ self,
+ images: Optional[ImageInput] = None,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ audio=None,
+ videos=None,
+ **kwargs: Unpack[UdopProcessorKwargs],
+ ) -> BatchFeature:
+ """
+ This method first forwards the `images` argument to [`~UdopImageProcessor.__call__`]. In case
+ [`UdopImageProcessor`] was initialized with `apply_ocr` set to `True`, it passes the obtained words and
+ bounding boxes along with the additional arguments to [`~UdopTokenizer.__call__`] and returns the output,
+ together with the prepared `pixel_values`. In case [`UdopImageProcessor`] was initialized with `apply_ocr` set
+ to `False`, it passes the words (`text`/``text_pair`) and `boxes` specified by the user along with the
+ additional arguments to [`~UdopTokenizer.__call__`] and returns the output, together with the prepared
+ `pixel_values`.
+
+ Alternatively, one can pass `text_target` and `text_pair_target` to prepare the targets of UDOP.
+
+ Please refer to the docstring of the above two methods for more information.
+ """
+ # verify input
+ output_kwargs = self._merge_kwargs(
+ UdopProcessorKwargs,
+ tokenizer_init_kwargs=self.tokenizer.init_kwargs,
+ **kwargs,
+ )
+
+ boxes = output_kwargs["text_kwargs"].pop("boxes", None)
+ word_labels = output_kwargs["text_kwargs"].pop("word_labels", None)
+ text_pair = output_kwargs["text_kwargs"].pop("text_pair", None)
+ return_overflowing_tokens = output_kwargs["text_kwargs"].get("return_overflowing_tokens", False)
+ return_offsets_mapping = output_kwargs["text_kwargs"].get("return_offsets_mapping", False)
+ text_target = output_kwargs["text_kwargs"].get("text_target", None)
+
+ if self.image_processor.apply_ocr and (boxes is not None):
+ raise ValueError(
+ "You cannot provide bounding boxes if you initialized the image processor with apply_ocr set to True."
+ )
+
+ if self.image_processor.apply_ocr and (word_labels is not None):
+ raise ValueError(
+ "You cannot provide word labels if you initialized the image processor with apply_ocr set to True."
+ )
+
+ if return_overflowing_tokens and not return_offsets_mapping:
+ raise ValueError("You cannot return overflowing tokens without returning the offsets mapping.")
+
+ if text_target is not None:
+ # use the processor to prepare the targets of UDOP
+ return self.tokenizer(
+ **output_kwargs["text_kwargs"],
+ )
+
+ else:
+ # use the processor to prepare the inputs of UDOP
+ # first, apply the image processor
+ features = self.image_processor(images=images, **output_kwargs["images_kwargs"])
+ features_words = features.pop("words", None)
+ features_boxes = features.pop("boxes", None)
+
+ output_kwargs["text_kwargs"].pop("text_target", None)
+ output_kwargs["text_kwargs"].pop("text_pair_target", None)
+ output_kwargs["text_kwargs"]["text_pair"] = text_pair
+ output_kwargs["text_kwargs"]["boxes"] = boxes if boxes is not None else features_boxes
+ output_kwargs["text_kwargs"]["word_labels"] = word_labels
+
+ # second, apply the tokenizer
+ if text is not None and self.image_processor.apply_ocr and text_pair is None:
+ if isinstance(text, str):
+ text = [text] # add batch dimension (as the image processor always adds a batch dimension)
+ output_kwargs["text_kwargs"]["text_pair"] = features_words
+
+ encoded_inputs = self.tokenizer(
+ text=text if text is not None else features_words,
+ **output_kwargs["text_kwargs"],
+ )
+
+ # add pixel values
+ if return_overflowing_tokens is True:
+ features["pixel_values"] = self.get_overflowing_images(
+ features["pixel_values"], encoded_inputs["overflow_to_sample_mapping"]
+ )
+ features.update(encoded_inputs)
+
+ return features
+
+ # Copied from transformers.models.layoutlmv3.processing_layoutlmv3.LayoutLMv3Processor.get_overflowing_images
+ def get_overflowing_images(self, images, overflow_to_sample_mapping):
+ # in case there's an overflow, ensure each `input_ids` sample is mapped to its corresponding image
+ images_with_overflow = []
+ for sample_idx in overflow_to_sample_mapping:
+ images_with_overflow.append(images[sample_idx])
+
+ if len(images_with_overflow) != len(overflow_to_sample_mapping):
+ raise ValueError(
+ "Expected length of images to be the same as the length of `overflow_to_sample_mapping`, but got"
+ f" {len(images_with_overflow)} and {len(overflow_to_sample_mapping)}"
+ )
+
+ return images_with_overflow
+
+ @property
+ def model_input_names(self):
+ tokenizer_input_names = self.tokenizer.model_input_names
+ image_processor_input_names = self.image_processor.model_input_names
+
+ return list(tokenizer_input_names + image_processor_input_names + ["bbox"])
+
+
+__all__ = ["UdopProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/tokenization_udop.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/tokenization_udop.py
new file mode 100644
index 0000000000000000000000000000000000000000..29b4b3ee24e40161ce8c662269252de63ebf36ec
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/tokenization_udop.py
@@ -0,0 +1,1490 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License
+"""Tokenization classes for UDOP model."""
+
+import os
+import re
+import warnings
+from shutil import copyfile
+from typing import Any, Optional, Union
+
+import sentencepiece as spm
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...tokenization_utils_base import (
+ AddedToken,
+ BatchEncoding,
+ EncodedInput,
+ PreTokenizedInput,
+ TextInput,
+ TextInputPair,
+ TruncationStrategy,
+)
+from ...utils import PaddingStrategy, TensorType, add_end_docstrings, logging
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+
+SPIECE_UNDERLINE = "▁"
+
+
+UDOP_ENCODE_KWARGS_DOCSTRING = r"""
+ add_special_tokens (`bool`, *optional*, defaults to `True`):
+ Whether or not to encode the sequences with the special tokens relative to their model.
+ padding (`bool`, `str` or [`~file_utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Activates and controls padding. Accepts the following values:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ truncation (`bool`, `str` or [`~tokenization_utils_base.TruncationStrategy`], *optional*, defaults to `False`):
+ Activates and controls truncation. Accepts the following values:
+
+ - `True` or `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or
+ to the maximum acceptable input length for the model if that argument is not provided. This will
+ truncate token by token, removing a token from the longest sequence in the pair if a pair of
+ sequences (or a batch of pairs) is provided.
+ - `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided. This will only
+ truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
+ - `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided. This will only
+ truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
+ - `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths
+ greater than the model maximum admissible input size).
+ max_length (`int`, *optional*):
+ Controls the maximum length to use by one of the truncation/padding parameters.
+
+ If left unset or set to `None`, this will use the predefined model maximum length if a maximum length
+ is required by one of the truncation/padding parameters. If the model has no specific maximum input
+ length (like XLNet) truncation/padding to a maximum length will be deactivated.
+ stride (`int`, *optional*, defaults to 0):
+ If set to a number along with `max_length`, the overflowing tokens returned when
+ `return_overflowing_tokens=True` will contain some tokens from the end of the truncated sequence
+ returned to provide some overlap between truncated and overflowing sequences. The value of this
+ argument defines the number of overlapping tokens.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value. This is especially useful to enable
+ the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta).
+ return_tensors (`str` or [`~file_utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ return_token_type_ids (`bool`, *optional*):
+ Whether to return token type IDs. If left to the default, will return the token type IDs according to
+ the specific tokenizer's default, defined by the `return_outputs` attribute.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ return_attention_mask (`bool`, *optional*):
+ Whether to return the attention mask. If left to the default, will return the attention mask according
+ to the specific tokenizer's default, defined by the `return_outputs` attribute.
+
+ [What are attention masks?](../glossary#attention-mask)
+ return_overflowing_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to return overflowing token sequences. If a pair of sequences of input ids (or a batch
+ of pairs) is provided with `truncation_strategy = longest_first` or `True`, an error is raised instead
+ of returning overflowing tokens.
+ return_special_tokens_mask (`bool`, *optional*, defaults to `False`):
+ Whether or not to return special tokens mask information.
+ return_offsets_mapping (`bool`, *optional*, defaults to `False`):
+ Whether or not to return `(char_start, char_end)` for each token.
+
+ This is only available on fast tokenizers inheriting from [`PreTrainedTokenizerFast`], if using
+ Python's tokenizer, this method will raise `NotImplementedError`.
+ return_length (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the lengths of the encoded inputs.
+ verbose (`bool`, *optional*, defaults to `True`):
+ Whether or not to print more information and warnings.
+ **kwargs: passed to the `self.tokenize()` method
+
+ Return:
+ [`BatchEncoding`]: A [`BatchEncoding`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ - **bbox** -- List of bounding boxes to be fed to a model.
+
+ - **token_type_ids** -- List of token type ids to be fed to a model (when `return_token_type_ids=True` or
+ if *"token_type_ids"* is in `self.model_input_names`).
+
+ [What are token type IDs?](../glossary#token-type-ids)
+
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names`).
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ - **labels** -- List of labels to be fed to a model. (when `word_labels` is specified).
+ - **overflowing_tokens** -- List of overflowing tokens sequences (when a `max_length` is specified and
+ `return_overflowing_tokens=True`).
+ - **num_truncated_tokens** -- Number of tokens truncated (when a `max_length` is specified and
+ `return_overflowing_tokens=True`).
+ - **special_tokens_mask** -- List of 0s and 1s, with 1 specifying added special tokens and 0 specifying
+ regular sequence tokens (when `add_special_tokens=True` and `return_special_tokens_mask=True`).
+ - **length** -- The length of the inputs (when `return_length=True`).
+"""
+
+VOCAB_FILES_NAMES = {"vocab_file": "spiece.model", "tokenizer_file": "tokenizer.json"}
+
+
+@requires(backends=("sentencepiece",))
+class UdopTokenizer(PreTrainedTokenizer):
+ """
+ Adapted from [`LayoutXLMTokenizer`] and [`T5Tokenizer`]. Based on
+ [SentencePiece](https://github.com/google/sentencepiece).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ Path to the vocabulary file.
+
+ eos_token (`str`, *optional*, defaults to `""`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+
+ sep_token (`str`, *optional*, defaults to `""`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ sep_token_box (`list[int]`, *optional*, defaults to `[1000, 1000, 1000, 1000]`):
+ The bounding box to use for the special [SEP] token.
+ pad_token_box (`list[int]`, *optional*, defaults to `[0, 0, 0, 0]`):
+ The bounding box to use for the special [PAD] token.
+ pad_token_label (`int`, *optional*, defaults to -100):
+ The label to use for padding tokens. Defaults to -100, which is the `ignore_index` of PyTorch's
+ CrossEntropyLoss.
+ only_label_first_subword (`bool`, *optional*, defaults to `True`):
+ Whether or not to only label the first subword, in case word labels are provided.
+ additional_special_tokens (`list[str]`, *optional*, defaults to `["NOTUSED", " NOTUSED"]`):
+ Additional special tokens used by the tokenizer.
+
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+ legacy (`bool`, *optional*, defaults to `True`):
+ Whether or not the `legacy` behaviour of the tokenizer should be used. Legacy is before the merge of #24622
+ which includes fixes to properly handle tokens that appear after special tokens. A simple example:
+ - `legacy=True`:
+ ```python
+ >>> from transformers import T5Tokenizer
+
+ >>> tokenizer = T5Tokenizer.from_pretrained("t5-base", legacy=True)
+ >>> tokenizer.encode("Hello .")
+ [8774, 32099, 3, 5, 1]
+ ```
+ - `legacy=False`:
+ ```python
+ >>> from transformers import T5Tokenizer
+
+ >>> tokenizer = T5Tokenizer.from_pretrained("t5-base", legacy=False)
+ >>> tokenizer.encode("Hello .") # the extra space `[3]` is no longer here
+ [8774, 32099, 5, 1]
+ ```
+ Checkout the pull request and the issue [here](https://github.com/huggingface/transformers/pull/24565) for
+ more details.
+ add_prefix_space (`bool`, *optional*, defaults to `True`):
+ Whether or not to add an initial space to the input. This allows to treat the leading word just as any
+ other word.
+
+
+ Attributes:
+ sp_model (`SentencePieceProcessor`):
+ The *SentencePiece* processor that is used for every conversion (string, tokens and IDs).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ eos_token="",
+ unk_token="",
+ sep_token="",
+ pad_token="",
+ sep_token_box=[1000, 1000, 1000, 1000],
+ pad_token_box=[0, 0, 0, 0],
+ pad_token_label=-100,
+ only_label_first_subword=True,
+ additional_special_tokens=None,
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ legacy=True,
+ add_prefix_space=True,
+ **kwargs,
+ ) -> None:
+ eos_token = AddedToken(eos_token, special=True) if isinstance(eos_token, str) else eos_token
+ unk_token = AddedToken(unk_token, special=True) if isinstance(unk_token, str) else unk_token
+ sep_token = AddedToken(sep_token, special=True) if isinstance(sep_token, str) else sep_token
+ pad_token = AddedToken(pad_token, special=True) if isinstance(pad_token, str) else pad_token
+
+ self.legacy = legacy
+ self.add_prefix_space = add_prefix_space
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+
+ self.vocab_file = vocab_file
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(vocab_file)
+
+ # additional properties
+ self.sep_token_box = sep_token_box
+ self.pad_token_box = pad_token_box
+ self.pad_token_label = pad_token_label
+ self.only_label_first_subword = only_label_first_subword
+
+ super().__init__(
+ eos_token=eos_token,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ sep_token_box=sep_token_box,
+ pad_token_box=pad_token_box,
+ pad_token_label=pad_token_label,
+ only_label_first_subword=only_label_first_subword,
+ additional_special_tokens=additional_special_tokens,
+ sp_model_kwargs=self.sp_model_kwargs,
+ legacy=legacy,
+ add_prefix_space=add_prefix_space,
+ **kwargs,
+ )
+
+ @property
+ def vocab_size(self):
+ return len(self.sp_model)
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.get_vocab
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.get_special_tokens_mask
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ # normal case: some special tokens
+ if token_ids_1 is None:
+ return ([0] * len(token_ids_0)) + [1]
+ return ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.get_sentinel_tokens
+ def get_sentinel_tokens(self):
+ return list(
+ set(filter(lambda x: bool(re.search(r"", x)) is not None, self.additional_special_tokens))
+ )
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.get_sentinel_token_ids
+ def get_sentinel_token_ids(self):
+ return [self.convert_tokens_to_ids(token) for token in self.get_sentinel_tokens()]
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer._add_eos_if_not_present
+ def _add_eos_if_not_present(self, token_ids: list[int]) -> list[int]:
+ """Do not add eos again if user already added it."""
+ if len(token_ids) > 0 and token_ids[-1] == self.eos_token_id:
+ warnings.warn(
+ f"This sequence already has {self.eos_token}. In future versions this behavior may lead to duplicated"
+ " eos tokens being added."
+ )
+ return token_ids
+ else:
+ return token_ids + [self.eos_token_id]
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.create_token_type_ids_from_sequences
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. T5 does not make
+ use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+ """
+ eos = [self.eos_token_id]
+
+ if token_ids_1 is None:
+ return len(token_ids_0 + eos) * [0]
+ return len(token_ids_0 + eos + token_ids_1 + eos) * [0]
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.build_inputs_with_special_tokens
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. A sequence has the following format:
+
+ - single sequence: `X `
+ - pair of sequences: `A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ token_ids_0 = self._add_eos_if_not_present(token_ids_0)
+ if token_ids_1 is None:
+ return token_ids_0
+ else:
+ token_ids_1 = self._add_eos_if_not_present(token_ids_1)
+ return token_ids_0 + token_ids_1
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.__getstate__
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ return state
+
+ def __setstate__(self, d):
+ self.__dict__.update(d)
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(self.vocab_file)
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.tokenize
+ def tokenize(self, text: "TextInput", **kwargs) -> list[str]:
+ """
+ Converts a string to a list of tokens. If `self.legacy` is set to `False`, a prefix token is added unless the
+ first token is special.
+ """
+ if self.legacy or len(text) == 0:
+ return super().tokenize(text, **kwargs)
+
+ text = text.replace(SPIECE_UNDERLINE, " ")
+ if self.add_prefix_space:
+ text = SPIECE_UNDERLINE + text
+
+ tokens = super().tokenize(text, **kwargs)
+
+ if len(tokens) > 1 and tokens[0] == SPIECE_UNDERLINE and tokens[1] in self.all_special_tokens:
+ tokens = tokens[1:]
+ return tokens
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer._tokenize
+ def _tokenize(self, text, **kwargs):
+ """
+ Returns a tokenized string.
+
+ We de-activated the `add_dummy_prefix` option, thus the sentencepiece internals will always strip any
+ SPIECE_UNDERLINE. For example: `self.sp_model.encode(f"{SPIECE_UNDERLINE}Hey", out_type = str)` will give
+ `['H', 'e', 'y']` instead of `['▁He', 'y']`. Thus we always encode `f"{unk_token}text"` and strip the
+ `unk_token`. Here is an example with `unk_token = ""` and `unk_token_length = 4`.
+ `self.tokenizer.sp_model.encode(" Hey", out_type = str)[4:]`.
+ """
+ if self.legacy or not text.startswith((SPIECE_UNDERLINE, " ")):
+ return self.sp_model.encode(text, out_type=str)
+
+ # 1. Encode string + prefix ex: " Hey"
+ tokens = self.sp_model.encode(self.unk_token + text, out_type=str)
+ # 2. Remove self.unk_token from ['<','unk','>', '▁Hey']
+ return tokens[self.unk_token_length :] if len(tokens) >= self.unk_token_length else tokens
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.sp_model.piece_to_id(token)
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ return self.sp_model.IdToPiece(index)
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.convert_tokens_to_string
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ # since we manually add the prefix space, we have to remove it when decoding
+ if tokens[0].startswith(SPIECE_UNDERLINE) and self.add_prefix_space:
+ tokens[0] = tokens[0][1:]
+
+ current_sub_tokens = []
+ out_string = ""
+ prev_is_special = False
+ for token in tokens:
+ # make sure that special tokens are not decoded using sentencepiece model
+ if token in self.all_special_tokens:
+ if not prev_is_special:
+ out_string += " "
+ out_string += self.sp_model.decode(current_sub_tokens) + token
+ prev_is_special = True
+ current_sub_tokens = []
+ else:
+ current_sub_tokens.append(token)
+ prev_is_special = False
+ out_string += self.sp_model.decode(current_sub_tokens)
+ return out_string.strip()
+
+ # Copied from transformers.models.t5.tokenization_t5.T5Tokenizer.save_vocabulary
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ elif not os.path.isfile(self.vocab_file):
+ with open(out_vocab_file, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (out_vocab_file,)
+
+ @add_end_docstrings(UDOP_ENCODE_KWARGS_DOCSTRING)
+ def __call__(
+ self,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ text_pair: Optional[Union[PreTokenizedInput, list[PreTokenizedInput]]] = None,
+ boxes: Optional[Union[list[list[int]], list[list[list[int]]]]] = None,
+ word_labels: Optional[Union[list[int], list[list[int]]]] = None,
+ text_target: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ text_pair_target: Optional[
+ Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]]
+ ] = None,
+ **kwargs,
+ ) -> BatchEncoding:
+ if text is None and text_target is None:
+ raise ValueError("You need to specify either `text` or `text_target`.")
+ if text is not None:
+ # The context manager will send the inputs as normal texts and not text_target, but we shouldn't change the
+ # input mode in this case.
+ if not self._in_target_context_manager:
+ self._switch_to_input_mode()
+ encodings = self.call_boxes(text=text, text_pair=text_pair, boxes=boxes, word_labels=word_labels, **kwargs)
+ if text_target is not None:
+ self._switch_to_target_mode()
+ target_encodings = self._call_one(text=text_target, text_pair=text_pair_target, **kwargs)
+ # Leave back tokenizer in input mode
+ self._switch_to_input_mode()
+
+ if text_target is None:
+ return encodings
+ elif text is None:
+ return target_encodings
+ else:
+ encodings["labels"] = target_encodings["input_ids"]
+ return encodings
+
+ def call_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]],
+ text_pair: Optional[Union[PreTokenizedInput, list[PreTokenizedInput]]] = None,
+ boxes: Optional[Union[list[list[int]], list[list[list[int]]]]] = None,
+ word_labels: Optional[Union[list[int], list[list[int]]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Main method to tokenize and prepare for the model one or several sequence(s) or one or several pair(s) of
+ sequences with word-level normalized bounding boxes and optional labels.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string, a list of strings
+ (words of a single example or questions of a batch of examples) or a list of list of strings (batch of
+ words).
+ text_pair (`list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence should be a list of strings
+ (pretokenized string).
+ boxes (`list[list[int]]`, `list[list[list[int]]]`):
+ Word-level bounding boxes. Each bounding box should be normalized to be on a 0-1000 scale.
+ word_labels (`list[int]`, `list[list[int]]`, *optional*):
+ Word-level integer labels (for token classification tasks such as FUNSD, CORD).
+ """
+
+ # Input type checking for clearer error
+ def _is_valid_text_input(t):
+ if isinstance(t, str):
+ # Strings are fine
+ return True
+ elif isinstance(t, (list, tuple)):
+ # List are fine as long as they are...
+ if len(t) == 0:
+ # ... empty
+ return True
+ elif isinstance(t[0], str):
+ # ... list of strings
+ return True
+ elif isinstance(t[0], (list, tuple)):
+ # ... list with an empty list or with a list of strings
+ return len(t[0]) == 0 or isinstance(t[0][0], str)
+ else:
+ return False
+ else:
+ return False
+
+ if text_pair is not None:
+ # in case text + text_pair are provided, text = questions, text_pair = words
+ if not _is_valid_text_input(text):
+ raise ValueError("text input must of type `str` (single example) or `list[str]` (batch of examples). ")
+ if not isinstance(text_pair, (list, tuple)):
+ raise ValueError(
+ "words must of type `list[str]` (single pretokenized example), "
+ "or `list[list[str]]` (batch of pretokenized examples)."
+ )
+ else:
+ # in case only text is provided => must be words
+ if not isinstance(text, (list, tuple)):
+ raise ValueError(
+ "Words must of type `list[str]` (single pretokenized example), "
+ "or `list[list[str]]` (batch of pretokenized examples)."
+ )
+
+ if text_pair is not None:
+ is_batched = isinstance(text, (list, tuple))
+ else:
+ is_batched = isinstance(text, (list, tuple)) and text and isinstance(text[0], (list, tuple))
+
+ words = text if text_pair is None else text_pair
+ if boxes is None:
+ raise ValueError("You must provide corresponding bounding boxes")
+ if is_batched:
+ if len(words) != len(boxes):
+ raise ValueError("You must provide words and boxes for an equal amount of examples")
+ for words_example, boxes_example in zip(words, boxes):
+ if len(words_example) != len(boxes_example):
+ raise ValueError("You must provide as many words as there are bounding boxes")
+ else:
+ if len(words) != len(boxes):
+ raise ValueError("You must provide as many words as there are bounding boxes")
+
+ if is_batched:
+ if text_pair is not None and len(text) != len(text_pair):
+ raise ValueError(
+ f"batch length of `text`: {len(text)} does not match batch length of `text_pair`:"
+ f" {len(text_pair)}."
+ )
+ batch_text_or_text_pairs = list(zip(text, text_pair)) if text_pair is not None else text
+ is_pair = bool(text_pair is not None)
+ return self.batch_encode_plus_boxes(
+ batch_text_or_text_pairs=batch_text_or_text_pairs,
+ is_pair=is_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+ else:
+ return self.encode_plus_boxes(
+ text=text,
+ text_pair=text_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ def batch_encode_plus_boxes(
+ self,
+ batch_text_or_text_pairs: Union[
+ list[TextInput],
+ list[TextInputPair],
+ list[PreTokenizedInput],
+ ],
+ is_pair: Optional[bool] = None,
+ boxes: Optional[list[list[list[int]]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ is_split_into_words: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Tokenize and prepare for the model a list of sequences or a list of pairs of sequences.
+
+ Args:
+ batch_text_or_text_pairs (`list[str]`, `list[tuple[str, str]]`, `list[list[str]]`, `list[tuple[list[str], list[str]]]`, and for not-fast tokenizers, also `list[list[int]]`, `list[tuple[list[int], list[int]]]`):
+ Batch of sequences or pair of sequences to be encoded. This can be a list of
+ string/string-sequences/int-sequences or a list of pair of string/string-sequences/int-sequence (see
+ details in `encode_plus`).
+ """
+
+ # Backward compatibility for 'truncation_strategy', 'pad_to_max_length'
+ padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies(
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ return self._batch_encode_plus_boxes(
+ batch_text_or_text_pairs=batch_text_or_text_pairs,
+ is_pair=is_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding_strategy=padding_strategy,
+ truncation_strategy=truncation_strategy,
+ max_length=max_length,
+ stride=stride,
+ is_split_into_words=is_split_into_words,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ def encode_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput, EncodedInput],
+ text_pair: Optional[Union[TextInput, PreTokenizedInput, EncodedInput]] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ) -> list[int]:
+ """
+ Args:
+ Converts a string to a sequence of ids (integer), using the tokenizer and vocabulary. Same as doing
+ `self.convert_tokens_to_ids(self.tokenize(text))`.
+ text (`str`, `list[str]` or `list[int]`):
+ The first sequence to be encoded. This can be a string, a list of strings (tokenized string using the
+ `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ text_pair (`str`, `list[str]` or `list[int]`, *optional*):
+ Optional second sequence to be encoded. This can be a string, a list of strings (tokenized string using
+ the `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ """
+ encoded_inputs = self.encode_plus_boxes(
+ text,
+ text_pair=text_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ stride=stride,
+ return_tensors=return_tensors,
+ **kwargs,
+ )
+
+ return encoded_inputs["input_ids"]
+
+ def encode_plus_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput],
+ text_pair: Optional[PreTokenizedInput] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ is_split_into_words: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Tokenize and prepare for the model a sequence or a pair of sequences.
+
+
+
+ This method is deprecated, `__call__` should be used instead.
+
+
+
+ Args:
+ text (`str`, `list[str]` or (for non-fast tokenizers) `list[int]`):
+ The first sequence to be encoded. This can be a string, a list of strings (tokenized string using the
+ `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ text_pair (`str`, `list[str]` or `list[int]`, *optional*):
+ Optional second sequence to be encoded. This can be a string, a list of strings (tokenized string using
+ the `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ """
+
+ # Backward compatibility for 'truncation_strategy', 'pad_to_max_length'
+ padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies(
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ return self._encode_plus_boxes(
+ text=text,
+ text_pair=text_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding_strategy=padding_strategy,
+ truncation_strategy=truncation_strategy,
+ max_length=max_length,
+ stride=stride,
+ is_split_into_words=is_split_into_words,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ def _batch_encode_plus_boxes(
+ self,
+ batch_text_or_text_pairs: Union[
+ list[TextInput],
+ list[TextInputPair],
+ list[PreTokenizedInput],
+ ],
+ is_pair: Optional[bool] = None,
+ boxes: Optional[list[list[list[int]]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ if return_offsets_mapping:
+ raise NotImplementedError(
+ "return_offset_mapping is not available when using Python tokenizers. "
+ "To use this feature, change your tokenizer to one deriving from "
+ "transformers.PreTrainedTokenizerFast."
+ )
+
+ batch_outputs = self._batch_prepare_for_model_boxes(
+ batch_text_or_text_pairs=batch_text_or_text_pairs,
+ is_pair=is_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding_strategy=padding_strategy,
+ truncation_strategy=truncation_strategy,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_attention_mask=return_attention_mask,
+ return_token_type_ids=return_token_type_ids,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_length=return_length,
+ return_tensors=return_tensors,
+ verbose=verbose,
+ )
+
+ return BatchEncoding(batch_outputs)
+
+ @add_end_docstrings(UDOP_ENCODE_KWARGS_DOCSTRING)
+ def _batch_prepare_for_model_boxes(
+ self,
+ batch_text_or_text_pairs,
+ is_pair: Optional[bool] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[str] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ ) -> BatchEncoding:
+ """
+ Prepares a sequence of input id, or a pair of sequences of inputs ids so that it can be used by the model. It
+ adds special tokens, truncates sequences if overflowing while taking into account the special tokens and
+ manages a moving window (with user defined stride) for overflowing tokens
+
+ Args:
+ batch_ids_pairs: list of tokenized input ids or input ids pairs
+ """
+
+ batch_outputs = {}
+ for idx, example in enumerate(zip(batch_text_or_text_pairs, boxes)):
+ batch_text_or_text_pair, boxes_example = example
+ outputs = self.prepare_for_model_boxes(
+ batch_text_or_text_pair[0] if is_pair else batch_text_or_text_pair,
+ batch_text_or_text_pair[1] if is_pair else None,
+ boxes_example,
+ word_labels=word_labels[idx] if word_labels is not None else None,
+ add_special_tokens=add_special_tokens,
+ padding=PaddingStrategy.DO_NOT_PAD.value, # we pad in batch afterward
+ truncation=truncation_strategy.value,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=None, # we pad in batch afterward
+ padding_side=None, # we pad in batch afterward
+ return_attention_mask=False, # we pad in batch afterward
+ return_token_type_ids=return_token_type_ids,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_length=return_length,
+ return_tensors=None, # We convert the whole batch to tensors at the end
+ prepend_batch_axis=False,
+ verbose=verbose,
+ )
+
+ for key, value in outputs.items():
+ if key not in batch_outputs:
+ batch_outputs[key] = []
+ batch_outputs[key].append(value)
+
+ batch_outputs = self.pad(
+ batch_outputs,
+ padding=padding_strategy.value,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_attention_mask=return_attention_mask,
+ )
+
+ batch_outputs = BatchEncoding(batch_outputs, tensor_type=return_tensors)
+
+ return batch_outputs
+
+ def _encode_plus_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput],
+ text_pair: Optional[PreTokenizedInput] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[int]] = None,
+ add_special_tokens: bool = True,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ if return_offsets_mapping:
+ raise NotImplementedError(
+ "return_offset_mapping is not available when using Python tokenizers. "
+ "To use this feature, change your tokenizer to one deriving from "
+ "transformers.PreTrainedTokenizerFast. "
+ "More information on available tokenizers at "
+ "https://github.com/huggingface/transformers/pull/2674"
+ )
+
+ return self.prepare_for_model_boxes(
+ text=text,
+ text_pair=text_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding=padding_strategy.value,
+ truncation=truncation_strategy.value,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ prepend_batch_axis=True,
+ return_attention_mask=return_attention_mask,
+ return_token_type_ids=return_token_type_ids,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_length=return_length,
+ verbose=verbose,
+ )
+
+ @add_end_docstrings(UDOP_ENCODE_KWARGS_DOCSTRING)
+ def prepare_for_model_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput],
+ text_pair: Optional[PreTokenizedInput] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[int]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ prepend_batch_axis: bool = False,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Prepares a sequence or a pair of sequences so that it can be used by the model. It adds special tokens,
+ truncates sequences if overflowing while taking into account the special tokens and manages a moving window
+ (with user defined stride) for overflowing tokens.
+
+ Word-level `boxes` are turned into token-level `bbox`. If provided, word-level `word_labels` are turned into
+ token-level `labels`. The word label is used for the first token of the word, while remaining tokens are
+ labeled with -100, such that they will be ignored by the loss function.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The first sequence to be encoded. This can be a string, a list of strings or a list of list of strings.
+ text_pair (`list[str]` or `list[int]`, *optional*):
+ Optional second sequence to be encoded. This can be a list of strings (words of a single example) or a
+ list of list of strings (words of a batch of examples).
+ """
+
+ # Backward compatibility for 'truncation_strategy', 'pad_to_max_length'
+ padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies(
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ tokens = []
+ pair_tokens = []
+ token_boxes = []
+ pair_token_boxes = []
+ labels = []
+
+ if text_pair is None:
+ if word_labels is None:
+ # CASE 1: document image classification (training + inference) + CASE 2: token classification (inference)
+ for word, box in zip(text, boxes):
+ if len(word) < 1: # skip empty words
+ continue
+ word_tokens = self.tokenize(word)
+ tokens.extend(word_tokens)
+ token_boxes.extend([box] * len(word_tokens))
+ else:
+ # CASE 2: token classification (training)
+ for word, box, label in zip(text, boxes, word_labels):
+ if len(word) < 1: # skip empty words
+ continue
+ word_tokens = self.tokenize(word)
+ tokens.extend(word_tokens)
+ token_boxes.extend([box] * len(word_tokens))
+ if self.only_label_first_subword:
+ # Use the real label id for the first token of the word, and padding ids for the remaining tokens
+ labels.extend([label] + [self.pad_token_label] * (len(word_tokens) - 1))
+ else:
+ labels.extend([label] * len(word_tokens))
+ else:
+ # CASE 3: document visual question answering (inference)
+ # text = question
+ # text_pair = words
+ tokens = self.tokenize(text)
+ token_boxes = [self.pad_token_box for _ in range(len(tokens))]
+
+ for word, box in zip(text_pair, boxes):
+ if len(word) < 1: # skip empty words
+ continue
+ word_tokens = self.tokenize(word)
+ pair_tokens.extend(word_tokens)
+ pair_token_boxes.extend([box] * len(word_tokens))
+
+ # Create ids + pair_ids
+ ids = self.convert_tokens_to_ids(tokens)
+ pair_ids = self.convert_tokens_to_ids(pair_tokens) if pair_tokens else None
+
+ # Compute the total size of the returned encodings
+ pair = bool(pair_ids is not None)
+ len_ids = len(ids)
+ len_pair_ids = len(pair_ids) if pair else 0
+ total_len = len_ids + len_pair_ids + (self.num_special_tokens_to_add(pair=pair) if add_special_tokens else 0)
+
+ # Truncation: Handle max sequence length
+ overflowing_tokens = []
+ overflowing_token_boxes = []
+ overflowing_labels = []
+ if truncation_strategy != TruncationStrategy.DO_NOT_TRUNCATE and max_length and total_len > max_length:
+ (
+ ids,
+ token_boxes,
+ pair_ids,
+ pair_token_boxes,
+ labels,
+ overflowing_tokens,
+ overflowing_token_boxes,
+ overflowing_labels,
+ ) = self.truncate_sequences(
+ ids,
+ token_boxes,
+ pair_ids=pair_ids,
+ pair_token_boxes=pair_token_boxes,
+ labels=labels,
+ num_tokens_to_remove=total_len - max_length,
+ truncation_strategy=truncation_strategy,
+ stride=stride,
+ )
+
+ if return_token_type_ids and not add_special_tokens:
+ raise ValueError(
+ "Asking to return token_type_ids while setting add_special_tokens to False "
+ "results in an undefined behavior. Please set add_special_tokens to True or "
+ "set return_token_type_ids to None."
+ )
+
+ # Load from model defaults
+ if return_token_type_ids is None:
+ return_token_type_ids = "token_type_ids" in self.model_input_names
+ if return_attention_mask is None:
+ return_attention_mask = "attention_mask" in self.model_input_names
+
+ encoded_inputs = {}
+
+ if return_overflowing_tokens:
+ encoded_inputs["overflowing_tokens"] = overflowing_tokens
+ encoded_inputs["overflowing_token_boxes"] = overflowing_token_boxes
+ encoded_inputs["overflowing_labels"] = overflowing_labels
+ encoded_inputs["num_truncated_tokens"] = total_len - max_length
+
+ # Add special tokens
+ if add_special_tokens:
+ sequence = self.build_inputs_with_special_tokens(ids, pair_ids)
+ token_type_ids = self.create_token_type_ids_from_sequences(ids, pair_ids)
+ token_boxes = token_boxes + [self.sep_token_box]
+ if pair_token_boxes:
+ pair_token_boxes = pair_token_boxes + [self.sep_token_box]
+ if labels:
+ labels = labels + [self.pad_token_label]
+ else:
+ sequence = ids + pair_ids if pair else ids
+ token_type_ids = [0] * len(ids) + ([0] * len(pair_ids) if pair else [])
+
+ # Build output dictionary
+ encoded_inputs["input_ids"] = sequence
+ encoded_inputs["bbox"] = token_boxes + pair_token_boxes
+ if return_token_type_ids:
+ encoded_inputs["token_type_ids"] = token_type_ids
+ if return_special_tokens_mask:
+ if add_special_tokens:
+ encoded_inputs["special_tokens_mask"] = self.get_special_tokens_mask(ids, pair_ids)
+ else:
+ encoded_inputs["special_tokens_mask"] = [0] * len(sequence)
+
+ if labels:
+ encoded_inputs["labels"] = labels
+
+ # Check lengths
+ self._eventual_warn_about_too_long_sequence(encoded_inputs["input_ids"], max_length, verbose)
+
+ # Padding
+ if padding_strategy != PaddingStrategy.DO_NOT_PAD or return_attention_mask:
+ encoded_inputs = self.pad(
+ encoded_inputs,
+ max_length=max_length,
+ padding=padding_strategy.value,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_attention_mask=return_attention_mask,
+ )
+
+ if return_length:
+ encoded_inputs["length"] = len(encoded_inputs["input_ids"])
+
+ batch_outputs = BatchEncoding(
+ encoded_inputs, tensor_type=return_tensors, prepend_batch_axis=prepend_batch_axis
+ )
+
+ return batch_outputs
+
+ # Copied from transformers.models.layoutxlm.tokenization_layoutxlm.LayoutXLMTokenizer.truncate_sequences
+ def truncate_sequences(
+ self,
+ ids: list[int],
+ token_boxes: list[list[int]],
+ pair_ids: Optional[list[int]] = None,
+ pair_token_boxes: Optional[list[list[int]]] = None,
+ labels: Optional[list[int]] = None,
+ num_tokens_to_remove: int = 0,
+ truncation_strategy: Union[str, TruncationStrategy] = "longest_first",
+ stride: int = 0,
+ ) -> tuple[list[int], list[int], list[int]]:
+ """
+ Truncates a sequence pair in-place following the strategy.
+
+ Args:
+ ids (`list[int]`):
+ Tokenized input ids of the first sequence. Can be obtained from a string by chaining the `tokenize` and
+ `convert_tokens_to_ids` methods.
+ token_boxes (`list[list[int]]`):
+ Bounding boxes of the first sequence.
+ pair_ids (`list[int]`, *optional*):
+ Tokenized input ids of the second sequence. Can be obtained from a string by chaining the `tokenize`
+ and `convert_tokens_to_ids` methods.
+ pair_token_boxes (`list[list[int]]`, *optional*):
+ Bounding boxes of the second sequence.
+ labels (`list[int]`, *optional*):
+ Labels of the first sequence (for token classification tasks).
+ num_tokens_to_remove (`int`, *optional*, defaults to 0):
+ Number of tokens to remove using the truncation strategy.
+ truncation_strategy (`str` or [`~tokenization_utils_base.TruncationStrategy`], *optional*, defaults to `False`):
+ The strategy to follow for truncation. Can be:
+
+ - `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided. This will truncate
+ token by token, removing a token from the longest sequence in the pair if a pair of sequences (or a
+ batch of pairs) is provided.
+ - `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided. This will only
+ truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
+ - `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided. This will only
+ truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
+ - `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths greater
+ than the model maximum admissible input size).
+ stride (`int`, *optional*, defaults to 0):
+ If set to a positive number, the overflowing tokens returned will contain some tokens from the main
+ sequence returned. The value of this argument defines the number of additional tokens.
+
+ Returns:
+ `tuple[list[int], list[int], list[int]]`: The truncated `ids`, the truncated `pair_ids` and the list of
+ overflowing tokens.
+ """
+ if num_tokens_to_remove <= 0:
+ return ids, token_boxes, pair_ids, pair_token_boxes, labels, [], [], []
+
+ if not isinstance(truncation_strategy, TruncationStrategy):
+ truncation_strategy = TruncationStrategy(truncation_strategy)
+
+ overflowing_tokens = []
+ overflowing_token_boxes = []
+ overflowing_labels = []
+ if truncation_strategy == TruncationStrategy.LONGEST_FIRST:
+ for _ in range(num_tokens_to_remove):
+ if pair_ids is None or len(ids) > len(pair_ids):
+ if not overflowing_tokens:
+ window_len = min(len(ids), stride + 1)
+ else:
+ window_len = 1
+ overflowing_tokens.extend(ids[-window_len:])
+ overflowing_token_boxes.extend(token_boxes[-window_len:])
+ overflowing_labels.extend(labels[-window_len:])
+ ids = ids[:-1]
+ token_boxes = token_boxes[:-1]
+ labels = labels[:-1]
+ else:
+ if not overflowing_tokens:
+ window_len = min(len(pair_ids), stride + 1)
+ else:
+ window_len = 1
+ overflowing_tokens.extend(pair_ids[-window_len:])
+ overflowing_token_boxes.extend(pair_token_boxes[-window_len:])
+ pair_ids = pair_ids[:-1]
+ pair_token_boxes = pair_token_boxes[:-1]
+ elif truncation_strategy == TruncationStrategy.ONLY_FIRST:
+ if len(ids) > num_tokens_to_remove:
+ window_len = min(len(ids), stride + num_tokens_to_remove)
+ overflowing_tokens = ids[-window_len:]
+ overflowing_token_boxes = token_boxes[-window_len:]
+ overflowing_labels = labels[-window_len:]
+ ids = ids[:-num_tokens_to_remove]
+ token_boxes = token_boxes[:-num_tokens_to_remove]
+ labels = labels[:-num_tokens_to_remove]
+ else:
+ logger.error(
+ f"We need to remove {num_tokens_to_remove} to truncate the input "
+ f"but the first sequence has a length {len(ids)}. "
+ f"Please select another truncation strategy than {truncation_strategy}, "
+ "for instance 'longest_first' or 'only_second'."
+ )
+ elif truncation_strategy == TruncationStrategy.ONLY_SECOND and pair_ids is not None:
+ if len(pair_ids) > num_tokens_to_remove:
+ window_len = min(len(pair_ids), stride + num_tokens_to_remove)
+ overflowing_tokens = pair_ids[-window_len:]
+ overflowing_token_boxes = pair_token_boxes[-window_len:]
+ pair_ids = pair_ids[:-num_tokens_to_remove]
+ pair_token_boxes = pair_token_boxes[:-num_tokens_to_remove]
+ else:
+ logger.error(
+ f"We need to remove {num_tokens_to_remove} to truncate the input "
+ f"but the second sequence has a length {len(pair_ids)}. "
+ f"Please select another truncation strategy than {truncation_strategy}, "
+ "for instance 'longest_first' or 'only_first'."
+ )
+
+ return (
+ ids,
+ token_boxes,
+ pair_ids,
+ pair_token_boxes,
+ labels,
+ overflowing_tokens,
+ overflowing_token_boxes,
+ overflowing_labels,
+ )
+
+ # Copied from transformers.models.layoutxlm.tokenization_layoutxlm.LayoutXLMTokenizer._pad
+ def _pad(
+ self,
+ encoded_inputs: Union[dict[str, EncodedInput], BatchEncoding],
+ max_length: Optional[int] = None,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_attention_mask: Optional[bool] = None,
+ ) -> dict:
+ """
+ Pad encoded inputs (on left/right and up to predefined length or max length in the batch)
+
+ Args:
+ encoded_inputs:
+ Dictionary of tokenized inputs (`list[int]`) or batch of tokenized inputs (`list[list[int]]`).
+ max_length: maximum length of the returned list and optionally padding length (see below).
+ Will truncate by taking into account the special tokens.
+ padding_strategy: PaddingStrategy to use for padding.
+
+ - PaddingStrategy.LONGEST Pad to the longest sequence in the batch
+ - PaddingStrategy.MAX_LENGTH: Pad to the max length (default)
+ - PaddingStrategy.DO_NOT_PAD: Do not pad
+ The tokenizer padding sides are defined in self.padding_side:
+
+ - 'left': pads on the left of the sequences
+ - 'right': pads on the right of the sequences
+ pad_to_multiple_of: (optional) Integer if set will pad the sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Core on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta).
+ padding_side (`str`, *optional*):
+ The side on which the model should have padding applied. Should be selected between ['right', 'left'].
+ Default value is picked from the class attribute of the same name.
+ return_attention_mask:
+ (optional) Set to False to avoid returning attention mask (default: set to model specifics)
+ """
+ # Load from model defaults
+ if return_attention_mask is None:
+ return_attention_mask = "attention_mask" in self.model_input_names
+
+ required_input = encoded_inputs[self.model_input_names[0]]
+
+ if padding_strategy == PaddingStrategy.LONGEST:
+ max_length = len(required_input)
+
+ if max_length is not None and pad_to_multiple_of is not None and (max_length % pad_to_multiple_of != 0):
+ max_length = ((max_length // pad_to_multiple_of) + 1) * pad_to_multiple_of
+
+ needs_to_be_padded = padding_strategy != PaddingStrategy.DO_NOT_PAD and len(required_input) != max_length
+
+ # Initialize attention mask if not present.
+ if return_attention_mask and "attention_mask" not in encoded_inputs:
+ encoded_inputs["attention_mask"] = [1] * len(required_input)
+
+ if needs_to_be_padded:
+ difference = max_length - len(required_input)
+ padding_side = padding_side if padding_side is not None else self.padding_side
+ if padding_side == "right":
+ if return_attention_mask:
+ encoded_inputs["attention_mask"] = encoded_inputs["attention_mask"] + [0] * difference
+ if "token_type_ids" in encoded_inputs:
+ encoded_inputs["token_type_ids"] = (
+ encoded_inputs["token_type_ids"] + [self.pad_token_type_id] * difference
+ )
+ if "bbox" in encoded_inputs:
+ encoded_inputs["bbox"] = encoded_inputs["bbox"] + [self.pad_token_box] * difference
+ if "labels" in encoded_inputs:
+ encoded_inputs["labels"] = encoded_inputs["labels"] + [self.pad_token_label] * difference
+ if "special_tokens_mask" in encoded_inputs:
+ encoded_inputs["special_tokens_mask"] = encoded_inputs["special_tokens_mask"] + [1] * difference
+ encoded_inputs[self.model_input_names[0]] = required_input + [self.pad_token_id] * difference
+ elif padding_side == "left":
+ if return_attention_mask:
+ encoded_inputs["attention_mask"] = [0] * difference + encoded_inputs["attention_mask"]
+ if "token_type_ids" in encoded_inputs:
+ encoded_inputs["token_type_ids"] = [self.pad_token_type_id] * difference + encoded_inputs[
+ "token_type_ids"
+ ]
+ if "bbox" in encoded_inputs:
+ encoded_inputs["bbox"] = [self.pad_token_box] * difference + encoded_inputs["bbox"]
+ if "labels" in encoded_inputs:
+ encoded_inputs["labels"] = [self.pad_token_label] * difference + encoded_inputs["labels"]
+ if "special_tokens_mask" in encoded_inputs:
+ encoded_inputs["special_tokens_mask"] = [1] * difference + encoded_inputs["special_tokens_mask"]
+ encoded_inputs[self.model_input_names[0]] = [self.pad_token_id] * difference + required_input
+ else:
+ raise ValueError("Invalid padding strategy:" + str(padding_side))
+
+ return encoded_inputs
+
+
+__all__ = ["UdopTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/tokenization_udop_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/tokenization_udop_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..a8878b9b514c27a7caa3653d771e868a6cfc3356
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/udop/tokenization_udop_fast.py
@@ -0,0 +1,1027 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License
+"""Tokenization classes for UDOP model."""
+
+import os
+from shutil import copyfile
+from typing import Optional, Union
+
+from ...tokenization_utils_base import (
+ BatchEncoding,
+ EncodedInput,
+ PreTokenizedInput,
+ TextInput,
+ TextInputPair,
+ TruncationStrategy,
+)
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import PaddingStrategy, TensorType, add_end_docstrings, is_sentencepiece_available, logging
+
+
+if is_sentencepiece_available():
+ from .tokenization_udop import UdopTokenizer
+else:
+ UdopTokenizer = None
+
+
+VOCAB_FILES_NAMES = {"vocab_file": "spiece.model", "tokenizer_file": "tokenizer.json"}
+
+
+logger = logging.get_logger(__name__)
+
+UDOP_ENCODE_KWARGS_DOCSTRING = r"""
+ add_special_tokens (`bool`, *optional*, defaults to `True`):
+ Whether or not to encode the sequences with the special tokens relative to their model.
+ padding (`bool`, `str` or [`~file_utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Activates and controls padding. Accepts the following values:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ truncation (`bool`, `str` or [`~tokenization_utils_base.TruncationStrategy`], *optional*, defaults to `False`):
+ Activates and controls truncation. Accepts the following values:
+
+ - `True` or `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or
+ to the maximum acceptable input length for the model if that argument is not provided. This will
+ truncate token by token, removing a token from the longest sequence in the pair if a pair of
+ sequences (or a batch of pairs) is provided.
+ - `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided. This will only
+ truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
+ - `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the
+ maximum acceptable input length for the model if that argument is not provided. This will only
+ truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
+ - `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths
+ greater than the model maximum admissible input size).
+ max_length (`int`, *optional*):
+ Controls the maximum length to use by one of the truncation/padding parameters.
+
+ If left unset or set to `None`, this will use the predefined model maximum length if a maximum length
+ is required by one of the truncation/padding parameters. If the model has no specific maximum input
+ length (like XLNet) truncation/padding to a maximum length will be deactivated.
+ stride (`int`, *optional*, defaults to 0):
+ If set to a number along with `max_length`, the overflowing tokens returned when
+ `return_overflowing_tokens=True` will contain some tokens from the end of the truncated sequence
+ returned to provide some overlap between truncated and overflowing sequences. The value of this
+ argument defines the number of overlapping tokens.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value. This is especially useful to enable
+ the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta).
+ return_tensors (`str` or [`~file_utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ return_token_type_ids (`bool`, *optional*):
+ Whether to return token type IDs. If left to the default, will return the token type IDs according to
+ the specific tokenizer's default, defined by the `return_outputs` attribute.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ return_attention_mask (`bool`, *optional*):
+ Whether to return the attention mask. If left to the default, will return the attention mask according
+ to the specific tokenizer's default, defined by the `return_outputs` attribute.
+
+ [What are attention masks?](../glossary#attention-mask)
+ return_overflowing_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to return overflowing token sequences. If a pair of sequences of input ids (or a batch
+ of pairs) is provided with `truncation_strategy = longest_first` or `True`, an error is raised instead
+ of returning overflowing tokens.
+ return_special_tokens_mask (`bool`, *optional*, defaults to `False`):
+ Whether or not to return special tokens mask information.
+ return_offsets_mapping (`bool`, *optional*, defaults to `False`):
+ Whether or not to return `(char_start, char_end)` for each token.
+
+ This is only available on fast tokenizers inheriting from [`PreTrainedTokenizerFast`], if using
+ Python's tokenizer, this method will raise `NotImplementedError`.
+ return_length (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the lengths of the encoded inputs.
+ verbose (`bool`, *optional*, defaults to `True`):
+ Whether or not to print more information and warnings.
+ **kwargs: passed to the `self.tokenize()` method
+
+ Return:
+ [`BatchEncoding`]: A [`BatchEncoding`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ - **bbox** -- List of bounding boxes to be fed to a model.
+
+ - **token_type_ids** -- List of token type ids to be fed to a model (when `return_token_type_ids=True` or
+ if *"token_type_ids"* is in `self.model_input_names`).
+
+ [What are token type IDs?](../glossary#token-type-ids)
+
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names`).
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ - **labels** -- List of labels to be fed to a model. (when `word_labels` is specified).
+ - **overflowing_tokens** -- List of overflowing tokens sequences (when a `max_length` is specified and
+ `return_overflowing_tokens=True`).
+ - **num_truncated_tokens** -- Number of tokens truncated (when a `max_length` is specified and
+ `return_overflowing_tokens=True`).
+ - **special_tokens_mask** -- List of 0s and 1s, with 1 specifying added special tokens and 0 specifying
+ regular sequence tokens (when `add_special_tokens=True` and `return_special_tokens_mask=True`).
+ - **length** -- The length of the inputs (when `return_length=True`).
+"""
+
+
+class UdopTokenizerFast(PreTrainedTokenizerFast):
+ """
+ Construct a "fast" UDOP tokenizer (backed by HuggingFace's *tokenizers* library). Adapted from
+ [`LayoutXLMTokenizer`] and [`T5Tokenizer`]. Based on
+ [BPE](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=BPE#models).
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`, *optional*):
+ Path to the vocabulary file.
+
+ tokenizer_file (`str`, *optional*):
+ Path to the tokenizer file.
+ eos_token (`str`, *optional*, defaults to `""`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ sep_token (`str`, *optional*, defaults to `""`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ sep_token_box (`list[int]`, *optional*, defaults to `[1000, 1000, 1000, 1000]`):
+ The bounding box to use for the special [SEP] token.
+ pad_token_box (`list[int]`, *optional*, defaults to `[0, 0, 0, 0]`):
+ The bounding box to use for the special [PAD] token.
+ pad_token_label (`int`, *optional*, defaults to -100):
+ The label to use for padding tokens. Defaults to -100, which is the `ignore_index` of PyTorch's
+ CrossEntropyLoss.
+ only_label_first_subword (`bool`, *optional*, defaults to `True`):
+ Whether or not to only label the first subword, in case word labels are provided.
+ additional_special_tokens (`list[str]`, *optional*, defaults to `["NOTUSED", " NOTUSED"]`):
+ Additional special tokens used by the tokenizer.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+ slow_tokenizer_class = UdopTokenizer
+
+ def __init__(
+ self,
+ vocab_file=None,
+ tokenizer_file=None,
+ eos_token="",
+ sep_token="",
+ unk_token="",
+ pad_token="",
+ sep_token_box=[1000, 1000, 1000, 1000],
+ pad_token_box=[0, 0, 0, 0],
+ pad_token_label=-100,
+ only_label_first_subword=True,
+ additional_special_tokens=None,
+ **kwargs,
+ ):
+ super().__init__(
+ vocab_file,
+ tokenizer_file=tokenizer_file,
+ eos_token=eos_token,
+ sep_token=sep_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ sep_token_box=sep_token_box,
+ pad_token_box=pad_token_box,
+ pad_token_label=pad_token_label,
+ only_label_first_subword=only_label_first_subword,
+ additional_special_tokens=additional_special_tokens,
+ **kwargs,
+ )
+
+ self.vocab_file = vocab_file
+
+ # additional properties
+ self.sep_token_box = sep_token_box
+ self.pad_token_box = pad_token_box
+ self.pad_token_label = pad_token_label
+ self.only_label_first_subword = only_label_first_subword
+
+ @add_end_docstrings(UDOP_ENCODE_KWARGS_DOCSTRING)
+ def __call__(
+ self,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ text_pair: Optional[Union[PreTokenizedInput, list[PreTokenizedInput]]] = None,
+ boxes: Optional[Union[list[list[int]], list[list[list[int]]]]] = None,
+ word_labels: Optional[Union[list[int], list[list[int]]]] = None,
+ text_target: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ text_pair_target: Optional[
+ Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]]
+ ] = None,
+ **kwargs,
+ ) -> BatchEncoding:
+ if text is None and text_target is None:
+ raise ValueError("You need to specify either `text` or `text_target`.")
+ if text is not None:
+ # The context manager will send the inputs as normal texts and not text_target, but we shouldn't change the
+ # input mode in this case.
+ if not self._in_target_context_manager:
+ self._switch_to_input_mode()
+ encodings = self.call_boxes(text=text, text_pair=text_pair, boxes=boxes, word_labels=word_labels, **kwargs)
+ if text_target is not None:
+ self._switch_to_target_mode()
+ target_encodings = self._call_one(text=text_target, text_pair=text_pair_target, **kwargs)
+ # Leave back tokenizer in input mode
+ self._switch_to_input_mode()
+
+ if text_target is None:
+ return encodings
+ elif text is None:
+ return target_encodings
+ else:
+ encodings["labels"] = target_encodings["input_ids"]
+ return encodings
+
+ @add_end_docstrings(UDOP_ENCODE_KWARGS_DOCSTRING)
+ def call_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]],
+ text_pair: Optional[Union[PreTokenizedInput, list[PreTokenizedInput]]] = None,
+ boxes: Optional[Union[list[list[int]], list[list[list[int]]]]] = None,
+ word_labels: Optional[Union[list[int], list[list[int]]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Main method to tokenize and prepare for the model one or several sequence(s) or one or several pair(s) of
+ sequences with word-level normalized bounding boxes and optional labels.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string, a list of strings
+ (words of a single example or questions of a batch of examples) or a list of list of strings (batch of
+ words).
+ text_pair (`list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence should be a list of strings
+ (pretokenized string).
+ boxes (`list[list[int]]`, `list[list[list[int]]]`):
+ Word-level bounding boxes. Each bounding box should be normalized to be on a 0-1000 scale.
+ word_labels (`list[int]`, `list[list[int]]`, *optional*):
+ Word-level integer labels (for token classification tasks such as FUNSD, CORD).
+ """
+
+ # Input type checking for clearer error
+ def _is_valid_text_input(t):
+ if isinstance(t, str):
+ # Strings are fine
+ return True
+ elif isinstance(t, (list, tuple)):
+ # List are fine as long as they are...
+ if len(t) == 0:
+ # ... empty
+ return True
+ elif isinstance(t[0], str):
+ # ... list of strings
+ return True
+ elif isinstance(t[0], (list, tuple)):
+ # ... list with an empty list or with a list of strings
+ return len(t[0]) == 0 or isinstance(t[0][0], str)
+ else:
+ return False
+ else:
+ return False
+
+ if text_pair is not None:
+ # in case text + text_pair are provided, text = questions, text_pair = words
+ if not _is_valid_text_input(text):
+ raise ValueError("text input must of type `str` (single example) or `list[str]` (batch of examples). ")
+ if not isinstance(text_pair, (list, tuple)):
+ raise ValueError(
+ "words must of type `list[str]` (single pretokenized example), "
+ "or `list[list[str]]` (batch of pretokenized examples)."
+ )
+ else:
+ # in case only text is provided => must be words
+ if not isinstance(text, (list, tuple)):
+ raise ValueError(
+ "Words must of type `list[str]` (single pretokenized example), "
+ "or `list[list[str]]` (batch of pretokenized examples)."
+ )
+
+ if text_pair is not None:
+ is_batched = isinstance(text, (list, tuple))
+ else:
+ is_batched = isinstance(text, (list, tuple)) and text and isinstance(text[0], (list, tuple))
+
+ words = text if text_pair is None else text_pair
+ if boxes is None:
+ raise ValueError("You must provide corresponding bounding boxes")
+ if is_batched:
+ if len(words) != len(boxes):
+ raise ValueError("You must provide words and boxes for an equal amount of examples")
+ for words_example, boxes_example in zip(words, boxes):
+ if len(words_example) != len(boxes_example):
+ raise ValueError("You must provide as many words as there are bounding boxes")
+ else:
+ if len(words) != len(boxes):
+ raise ValueError("You must provide as many words as there are bounding boxes")
+
+ if is_batched:
+ if text_pair is not None and len(text) != len(text_pair):
+ raise ValueError(
+ f"batch length of `text`: {len(text)} does not match batch length of `text_pair`:"
+ f" {len(text_pair)}."
+ )
+ batch_text_or_text_pairs = list(zip(text, text_pair)) if text_pair is not None else text
+ is_pair = bool(text_pair is not None)
+ return self.batch_encode_plus_boxes(
+ batch_text_or_text_pairs=batch_text_or_text_pairs,
+ is_pair=is_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+ else:
+ return self.encode_plus_boxes(
+ text=text,
+ text_pair=text_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ # Copied from transformers.models.layoutxlm.tokenization_layoutxlm_fast.LayoutXLMTokenizerFast.tokenize
+ def tokenize(self, text: str, pair: Optional[str] = None, add_special_tokens: bool = False, **kwargs) -> list[str]:
+ batched_input = [(text, pair)] if pair else [text]
+
+ self._tokenizer.encode_special_tokens = kwargs.pop(
+ "split_special_tokens", self._tokenizer.encode_special_tokens
+ )
+
+ encodings = self._tokenizer.encode_batch(
+ batched_input, add_special_tokens=add_special_tokens, is_pretokenized=False, **kwargs
+ )
+
+ return encodings[0].tokens
+
+ def batch_encode_plus_boxes(
+ self,
+ batch_text_or_text_pairs: Union[
+ list[TextInput],
+ list[TextInputPair],
+ list[PreTokenizedInput],
+ ],
+ is_pair: Optional[bool] = None,
+ boxes: Optional[list[list[list[int]]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ is_split_into_words: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Tokenize and prepare for the model a list of sequences or a list of pairs of sequences.
+
+
+
+ This method is deprecated, `__call__` should be used instead.
+
+
+
+ Args:
+ batch_text_or_text_pairs (`list[str]`, `list[tuple[str, str]]`, `list[list[str]]`, `list[tuple[list[str], list[str]]]`, and for not-fast tokenizers, also `list[list[int]]`, `list[tuple[list[int], list[int]]]`):
+ Batch of sequences or pair of sequences to be encoded. This can be a list of
+ string/string-sequences/int-sequences or a list of pair of string/string-sequences/int-sequence (see
+ details in `encode_plus`).
+ """
+
+ # Backward compatibility for 'truncation_strategy', 'pad_to_max_length'
+ padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies(
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ return self._batch_encode_plus_boxes(
+ batch_text_or_text_pairs=batch_text_or_text_pairs,
+ is_pair=is_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding_strategy=padding_strategy,
+ truncation_strategy=truncation_strategy,
+ max_length=max_length,
+ stride=stride,
+ is_split_into_words=is_split_into_words,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ def _batch_encode_plus_boxes(
+ self,
+ batch_text_or_text_pairs: Union[
+ list[TextInput],
+ list[TextInputPair],
+ list[PreTokenizedInput],
+ ],
+ is_pair: Optional[bool] = None,
+ boxes: Optional[list[list[list[int]]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[str] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ if not isinstance(batch_text_or_text_pairs, list):
+ raise TypeError(f"batch_text_or_text_pairs has to be a list (got {type(batch_text_or_text_pairs)})")
+
+ # Set the truncation and padding strategy and restore the initial configuration
+ self.set_truncation_and_padding(
+ padding_strategy=padding_strategy,
+ truncation_strategy=truncation_strategy,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ )
+
+ if is_pair:
+ batch_text_or_text_pairs = [(text.split(), text_pair) for text, text_pair in batch_text_or_text_pairs]
+
+ encodings = self._tokenizer.encode_batch(
+ batch_text_or_text_pairs,
+ add_special_tokens=add_special_tokens,
+ is_pretokenized=True, # we set this to True as LayoutLMv2 always expects pretokenized inputs
+ )
+
+ # Convert encoding to dict
+ # `Tokens` has type: tuple[
+ # list[dict[str, list[list[int]]]] or list[dict[str, 2D-Tensor]],
+ # list[EncodingFast]
+ # ]
+ # with nested dimensions corresponding to batch, overflows, sequence length
+ tokens_and_encodings = [
+ self._convert_encoding(
+ encoding=encoding,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=True
+ if word_labels is not None
+ else return_offsets_mapping, # we use offsets to create the labels
+ return_length=return_length,
+ verbose=verbose,
+ )
+ for encoding in encodings
+ ]
+
+ # Convert the output to have dict[list] from list[dict] and remove the additional overflows dimension
+ # From (variable) shape (batch, overflows, sequence length) to ~ (batch * overflows, sequence length)
+ # (we say ~ because the number of overflow varies with the example in the batch)
+ #
+ # To match each overflowing sample with the original sample in the batch
+ # we add an overflow_to_sample_mapping array (see below)
+ sanitized_tokens = {}
+ for key in tokens_and_encodings[0][0]:
+ stack = [e for item, _ in tokens_and_encodings for e in item[key]]
+ sanitized_tokens[key] = stack
+ sanitized_encodings = [e for _, item in tokens_and_encodings for e in item]
+
+ # If returning overflowing tokens, we need to return a mapping
+ # from the batch idx to the original sample
+ if return_overflowing_tokens:
+ overflow_to_sample_mapping = []
+ for i, (toks, _) in enumerate(tokens_and_encodings):
+ overflow_to_sample_mapping += [i] * len(toks["input_ids"])
+ sanitized_tokens["overflow_to_sample_mapping"] = overflow_to_sample_mapping
+
+ for input_ids in sanitized_tokens["input_ids"]:
+ self._eventual_warn_about_too_long_sequence(input_ids, max_length, verbose)
+
+ # create the token boxes
+ token_boxes = []
+ for batch_index in range(len(sanitized_tokens["input_ids"])):
+ if return_overflowing_tokens:
+ original_index = sanitized_tokens["overflow_to_sample_mapping"][batch_index]
+ else:
+ original_index = batch_index
+ token_boxes_example = []
+ for id, sequence_id, word_id in zip(
+ sanitized_tokens["input_ids"][batch_index],
+ sanitized_encodings[batch_index].sequence_ids,
+ sanitized_encodings[batch_index].word_ids,
+ ):
+ if word_id is not None:
+ if is_pair and sequence_id == 0:
+ token_boxes_example.append(self.pad_token_box)
+ else:
+ token_boxes_example.append(boxes[original_index][word_id])
+ else:
+ if id == self.sep_token_id:
+ token_boxes_example.append(self.sep_token_box)
+ elif id == self.pad_token_id:
+ token_boxes_example.append(self.pad_token_box)
+ else:
+ raise ValueError("Id not recognized")
+ token_boxes.append(token_boxes_example)
+
+ sanitized_tokens["bbox"] = token_boxes
+
+ # optionally, create the labels
+ if word_labels is not None:
+ labels = []
+ for batch_index in range(len(sanitized_tokens["input_ids"])):
+ if return_overflowing_tokens:
+ original_index = sanitized_tokens["overflow_to_sample_mapping"][batch_index]
+ else:
+ original_index = batch_index
+ labels_example = []
+ previous_token_empty = False
+ for id, offset, word_id in zip(
+ sanitized_tokens["input_ids"][batch_index],
+ sanitized_tokens["offset_mapping"][batch_index],
+ sanitized_encodings[batch_index].word_ids,
+ ):
+ if word_id is not None:
+ if self.only_label_first_subword:
+ if offset[0] == 0 and not previous_token_empty:
+ # Use the real label id for the first token of the word, and padding ids for the remaining tokens
+ labels_example.append(word_labels[original_index][word_id])
+ else:
+ labels_example.append(self.pad_token_label)
+ else:
+ labels_example.append(word_labels[original_index][word_id])
+ if self.decode(id) == "":
+ previous_token_empty = True
+ else:
+ previous_token_empty = False
+ else:
+ labels_example.append(self.pad_token_label)
+ labels.append(labels_example)
+
+ sanitized_tokens["labels"] = labels
+ # finally, remove offsets if the user didn't want them
+ if not return_offsets_mapping:
+ del sanitized_tokens["offset_mapping"]
+
+ return BatchEncoding(sanitized_tokens, sanitized_encodings, tensor_type=return_tensors)
+
+ def _encode_plus_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput],
+ text_pair: Optional[PreTokenizedInput] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[int]] = None,
+ add_special_tokens: bool = True,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[bool] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ # make it a batched input
+ # 2 options:
+ # 1) only text, in case text must be a list of str
+ # 2) text + text_pair, in which case text = str and text_pair a list of str
+ batched_input = [(text, text_pair)] if text_pair else [text]
+ batched_boxes = [boxes]
+ batched_word_labels = [word_labels] if word_labels is not None else None
+ batched_output = self._batch_encode_plus_boxes(
+ batched_input,
+ is_pair=bool(text_pair is not None),
+ boxes=batched_boxes,
+ word_labels=batched_word_labels,
+ add_special_tokens=add_special_tokens,
+ padding_strategy=padding_strategy,
+ truncation_strategy=truncation_strategy,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ # Return tensor is None, then we can remove the leading batch axis
+ # Overflowing tokens are returned as a batch of output so we keep them in this case
+ if return_tensors is None and not return_overflowing_tokens:
+ batched_output = BatchEncoding(
+ {
+ key: value[0] if len(value) > 0 and isinstance(value[0], list) else value
+ for key, value in batched_output.items()
+ },
+ batched_output.encodings,
+ )
+
+ self._eventual_warn_about_too_long_sequence(batched_output["input_ids"], max_length, verbose)
+
+ return batched_output
+
+ def encode_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput, EncodedInput],
+ text_pair: Optional[Union[TextInput, PreTokenizedInput, EncodedInput]] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ) -> list[int]:
+ """
+ Args:
+ Converts a string to a sequence of ids (integer), using the tokenizer and vocabulary. Same as doing
+ `self.convert_tokens_to_ids(self.tokenize(text))`.
+ text (`str`, `list[str]` or `list[int]`):
+ The first sequence to be encoded. This can be a string, a list of strings (tokenized string using the
+ `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ text_pair (`str`, `list[str]` or `list[int]`, *optional*):
+ Optional second sequence to be encoded. This can be a string, a list of strings (tokenized string using
+ the `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ """
+ encoded_inputs = self.encode_plus_boxes(
+ text,
+ text_pair=text_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ stride=stride,
+ return_tensors=return_tensors,
+ **kwargs,
+ )
+
+ return encoded_inputs["input_ids"]
+
+ def encode_plus_boxes(
+ self,
+ text: Union[TextInput, PreTokenizedInput],
+ text_pair: Optional[PreTokenizedInput] = None,
+ boxes: Optional[list[list[int]]] = None,
+ word_labels: Optional[list[list[int]]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ is_split_into_words: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Tokenize and prepare for the model a sequence or a pair of sequences.
+
+
+
+ This method is deprecated, `__call__` should be used instead.
+
+
+
+ Args:
+ text (`str`, `list[str]` or (for non-fast tokenizers) `list[int]`):
+ The first sequence to be encoded. This can be a string, a list of strings (tokenized string using the
+ `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ text_pair (`str`, `list[str]` or `list[int]`, *optional*):
+ Optional second sequence to be encoded. This can be a string, a list of strings (tokenized string using
+ the `tokenize` method) or a list of integers (tokenized string ids using the `convert_tokens_to_ids`
+ method).
+ """
+
+ # Backward compatibility for 'truncation_strategy', 'pad_to_max_length'
+ padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies(
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ return self._encode_plus_boxes(
+ text=text,
+ text_pair=text_pair,
+ boxes=boxes,
+ word_labels=word_labels,
+ add_special_tokens=add_special_tokens,
+ padding_strategy=padding_strategy,
+ truncation_strategy=truncation_strategy,
+ max_length=max_length,
+ stride=stride,
+ is_split_into_words=is_split_into_words,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_tensors=return_tensors,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ **kwargs,
+ )
+
+ # Copied from transformers.models.layoutxlm.tokenization_layoutxlm_fast.LayoutXLMTokenizerFast._pad
+ def _pad(
+ self,
+ encoded_inputs: Union[dict[str, EncodedInput], BatchEncoding],
+ max_length: Optional[int] = None,
+ padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_attention_mask: Optional[bool] = None,
+ ) -> dict:
+ """
+ Pad encoded inputs (on left/right and up to predefined length or max length in the batch)
+
+ Args:
+ encoded_inputs:
+ Dictionary of tokenized inputs (`list[int]`) or batch of tokenized inputs (`list[list[int]]`).
+ max_length: maximum length of the returned list and optionally padding length (see below).
+ Will truncate by taking into account the special tokens.
+ padding_strategy: PaddingStrategy to use for padding.
+
+ - PaddingStrategy.LONGEST Pad to the longest sequence in the batch
+ - PaddingStrategy.MAX_LENGTH: Pad to the max length (default)
+ - PaddingStrategy.DO_NOT_PAD: Do not pad
+ The tokenizer padding sides are defined in self.padding_side:
+
+ - 'left': pads on the left of the sequences
+ - 'right': pads on the right of the sequences
+ pad_to_multiple_of: (optional) Integer if set will pad the sequence to a multiple of the provided value.
+ This is especially useful to enable the use of Tensor Core on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta).
+ padding_side (`str`, *optional*):
+ The side on which the model should have padding applied. Should be selected between ['right', 'left'].
+ Default value is picked from the class attribute of the same name.
+ return_attention_mask:
+ (optional) Set to False to avoid returning attention mask (default: set to model specifics)
+ """
+ # Load from model defaults
+ if return_attention_mask is None:
+ return_attention_mask = "attention_mask" in self.model_input_names
+
+ required_input = encoded_inputs[self.model_input_names[0]]
+
+ if padding_strategy == PaddingStrategy.LONGEST:
+ max_length = len(required_input)
+
+ if max_length is not None and pad_to_multiple_of is not None and (max_length % pad_to_multiple_of != 0):
+ max_length = ((max_length // pad_to_multiple_of) + 1) * pad_to_multiple_of
+
+ needs_to_be_padded = padding_strategy != PaddingStrategy.DO_NOT_PAD and len(required_input) != max_length
+
+ # Initialize attention mask if not present.
+ if return_attention_mask and "attention_mask" not in encoded_inputs:
+ encoded_inputs["attention_mask"] = [1] * len(required_input)
+
+ if needs_to_be_padded:
+ difference = max_length - len(required_input)
+ padding_side = padding_side if padding_side is not None else self.padding_side
+ if padding_side == "right":
+ if return_attention_mask:
+ encoded_inputs["attention_mask"] = encoded_inputs["attention_mask"] + [0] * difference
+ if "token_type_ids" in encoded_inputs:
+ encoded_inputs["token_type_ids"] = (
+ encoded_inputs["token_type_ids"] + [self.pad_token_type_id] * difference
+ )
+ if "bbox" in encoded_inputs:
+ encoded_inputs["bbox"] = encoded_inputs["bbox"] + [self.pad_token_box] * difference
+ if "labels" in encoded_inputs:
+ encoded_inputs["labels"] = encoded_inputs["labels"] + [self.pad_token_label] * difference
+ if "special_tokens_mask" in encoded_inputs:
+ encoded_inputs["special_tokens_mask"] = encoded_inputs["special_tokens_mask"] + [1] * difference
+ encoded_inputs[self.model_input_names[0]] = required_input + [self.pad_token_id] * difference
+ elif padding_side == "left":
+ if return_attention_mask:
+ encoded_inputs["attention_mask"] = [0] * difference + encoded_inputs["attention_mask"]
+ if "token_type_ids" in encoded_inputs:
+ encoded_inputs["token_type_ids"] = [self.pad_token_type_id] * difference + encoded_inputs[
+ "token_type_ids"
+ ]
+ if "bbox" in encoded_inputs:
+ encoded_inputs["bbox"] = [self.pad_token_box] * difference + encoded_inputs["bbox"]
+ if "labels" in encoded_inputs:
+ encoded_inputs["labels"] = [self.pad_token_label] * difference + encoded_inputs["labels"]
+ if "special_tokens_mask" in encoded_inputs:
+ encoded_inputs["special_tokens_mask"] = [1] * difference + encoded_inputs["special_tokens_mask"]
+ encoded_inputs[self.model_input_names[0]] = [self.pad_token_id] * difference + required_input
+ else:
+ raise ValueError("Invalid padding strategy:" + str(padding_side))
+
+ return encoded_inputs
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLM-RoBERTa sequence has the following format:
+
+ - single sequence: ` X `
+ - pair of sequences: ` A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+
+ if token_ids_1 is None:
+ return token_ids_0 + [self.sep_token_id]
+ sep = [self.sep_token_id]
+ return token_ids_0 + sep + token_ids_1 + sep
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. XLM-RoBERTa does
+ not make use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+
+ """
+
+ sep = [self.sep_token_id]
+
+ if token_ids_1 is None:
+ return len(token_ids_0 + sep) * [0]
+ return len(token_ids_0 + sep + token_ids_1 + sep) * [0]
+
+ # Copied from transformers.models.layoutxlm.tokenization_layoutxlm_fast.LayoutXLMTokenizerFast.save_vocabulary
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not self.can_save_slow_tokenizer:
+ raise ValueError(
+ "Your fast tokenizer does not have the necessary information to save the vocabulary for a slow "
+ "tokenizer."
+ )
+
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory.")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["UdopTokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..5dc2e041359770eca293bd2cce968e1b19d22bc2
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_umt5 import *
+ from .modeling_umt5 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/configuration_umt5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/configuration_umt5.py
new file mode 100644
index 0000000000000000000000000000000000000000..c23f171e4d643e7b3b839b3f63333c7cef7f362e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/configuration_umt5.py
@@ -0,0 +1,181 @@
+# coding=utf-8
+# Copyright 2023, The T5 Authors and HuggingFace Inc.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""UMT5 model configuration"""
+
+from collections.abc import Mapping
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxSeq2SeqConfigWithPast
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class UMT5Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`UMT5Model`]. It is used to instantiate a UMT5
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the UMT5
+ [google/umt5-small](https://huggingface.co/google/umt5-small) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Arguments:
+ vocab_size (`int`, *optional*, defaults to 250112):
+ Vocabulary size of the UMT5 model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`UMT5Model`] or [`TFUMT5Model`].
+ d_model (`int`, *optional*, defaults to 512):
+ Size of the encoder layers and the pooler layer.
+ d_kv (`int`, *optional*, defaults to 64):
+ Size of the key, query, value projections per attention head. `d_kv` has to be equal to `d_model //
+ num_heads`.
+ d_ff (`int`, *optional*, defaults to 1024):
+ Size of the intermediate feed forward layer in each `UMT5Block`.
+ num_layers (`int`, *optional*, defaults to 8):
+ Number of hidden layers in the Transformer encoder.
+ num_decoder_layers (`int`, *optional*):
+ Number of hidden layers in the Transformer decoder. Will use the same value as `num_layers` if not set.
+ num_heads (`int`, *optional*, defaults to 6):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ relative_attention_num_buckets (`int`, *optional*, defaults to 32):
+ The number of buckets to use for each attention layer.
+ relative_attention_max_distance (`int`, *optional*, defaults to 128):
+ The maximum distance of the longer sequences for the bucket separation.
+ dropout_rate (`float`, *optional*, defaults to 0.1):
+ The ratio for all dropout layers.
+ classifier_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for classifier.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-6):
+ The epsilon used by the layer normalization layers.
+ initializer_factor (`float`, *optional*, defaults to 1):
+ A factor for initializing all weight matrices (should be kept to 1, used internally for initialization
+ testing).
+ feed_forward_proj (`string`, *optional*, defaults to `"gated-gelu"`):
+ Type of feed forward layer to be used. Should be one of `"relu"` or `"gated-gelu"`.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+ """
+
+ model_type = "umt5"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {
+ "hidden_size": "d_model",
+ "num_attention_heads": "num_heads",
+ "num_hidden_layers": "num_layers",
+ "head_dim": "d_kv",
+ }
+
+ def __init__(
+ self,
+ vocab_size=250112,
+ d_model=512,
+ d_kv=64,
+ d_ff=1024,
+ num_layers=8,
+ num_decoder_layers=None,
+ num_heads=6,
+ relative_attention_num_buckets=32,
+ relative_attention_max_distance=128,
+ dropout_rate=0.1,
+ layer_norm_epsilon=1e-6,
+ initializer_factor=1.0,
+ feed_forward_proj="gated-gelu",
+ is_encoder_decoder=True,
+ use_cache=True,
+ tokenizer_class="T5Tokenizer",
+ tie_word_embeddings=True,
+ pad_token_id=0,
+ eos_token_id=1,
+ decoder_start_token_id=0,
+ classifier_dropout=0.0,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.d_model = d_model
+ self.d_kv = d_kv
+ self.d_ff = d_ff
+ self.num_layers = num_layers
+ self.num_decoder_layers = (
+ num_decoder_layers if num_decoder_layers is not None else self.num_layers
+ ) # default = symmetry
+ self.num_heads = num_heads
+ self.relative_attention_num_buckets = relative_attention_num_buckets
+ self.relative_attention_max_distance = relative_attention_max_distance
+ self.dropout_rate = dropout_rate
+ self.classifier_dropout = classifier_dropout
+ self.layer_norm_epsilon = layer_norm_epsilon
+ self.initializer_factor = initializer_factor
+ self.feed_forward_proj = feed_forward_proj
+ self.use_cache = use_cache
+
+ act_info = self.feed_forward_proj.split("-")
+ self.dense_act_fn = act_info[-1]
+ self.is_gated_act = act_info[0] == "gated"
+
+ if len(act_info) > 1 and act_info[0] != "gated" or len(act_info) > 2:
+ raise ValueError(
+ f"`feed_forward_proj`: {feed_forward_proj} is not a valid activation function of the dense layer. "
+ "Please make sure `feed_forward_proj` is of the format `gated-{ACT_FN}` or `{ACT_FN}`, e.g. "
+ "'gated-gelu' or 'relu'"
+ )
+
+ if feed_forward_proj == "gated-gelu":
+ self.dense_act_fn = "gelu_new"
+
+ super().__init__(
+ is_encoder_decoder=is_encoder_decoder,
+ tokenizer_class=tokenizer_class,
+ tie_word_embeddings=tie_word_embeddings,
+ pad_token_id=pad_token_id,
+ eos_token_id=eos_token_id,
+ decoder_start_token_id=decoder_start_token_id,
+ **kwargs,
+ )
+
+
+class UMT5OnnxConfig(OnnxSeq2SeqConfigWithPast):
+ @property
+ # Copied from transformers.models.t5.configuration_t5.T5OnnxConfig.inputs
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ common_inputs = {
+ "input_ids": {0: "batch", 1: "encoder_sequence"},
+ "attention_mask": {0: "batch", 1: "encoder_sequence"},
+ }
+ if self.use_past:
+ common_inputs["attention_mask"][1] = "past_encoder_sequence + sequence"
+ common_inputs["decoder_input_ids"] = {0: "batch"}
+ common_inputs["decoder_attention_mask"] = {0: "batch", 1: "past_decoder_sequence + sequence"}
+ else:
+ common_inputs["decoder_input_ids"] = {0: "batch", 1: "decoder_sequence"}
+ common_inputs["decoder_attention_mask"] = {0: "batch", 1: "decoder_sequence"}
+
+ if self.use_past:
+ self.fill_with_past_key_values_(common_inputs, direction="inputs")
+
+ return common_inputs
+
+ @property
+ # Copied from transformers.models.t5.configuration_t5.T5OnnxConfig.default_onnx_opset
+ def default_onnx_opset(self) -> int:
+ return 13
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 5e-4
+
+
+__all__ = ["UMT5Config", "UMT5OnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/modeling_umt5.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/modeling_umt5.py
new file mode 100644
index 0000000000000000000000000000000000000000..73bedc363ed84f3b36172f0e7a6e445b352ec6d0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/umt5/modeling_umt5.py
@@ -0,0 +1,1949 @@
+# coding=utf-8
+# Copyright 2023 Mesh TensorFlow authors, T5 Authors and HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch UMT5 model."""
+
+import copy
+import math
+from typing import Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+ Seq2SeqQuestionAnsweringModelOutput,
+ Seq2SeqSequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...utils import (
+ DUMMY_INPUTS,
+ DUMMY_MASK,
+ auto_docstring,
+ is_torch_flex_attn_available,
+ is_torch_fx_proxy,
+ is_torchdynamo_compiling,
+ logging,
+)
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_umt5 import UMT5Config
+
+
+if is_torch_flex_attn_available():
+ from torch.nn.attention.flex_attention import BlockMask
+
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerNorm with T5->UMT5
+class UMT5LayerNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ Construct a layernorm module in the UMT5 style. No bias and no subtraction of mean.
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ # UMT5 uses a layer_norm which only scales and doesn't shift, which is also known as Root Mean
+ # Square Layer Normalization https://huggingface.co/papers/1910.07467 thus variance is calculated
+ # w/o mean and there is no bias. Additionally we want to make sure that the accumulation for
+ # half-precision inputs is done in fp32
+
+ variance = hidden_states.to(torch.float32).pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+
+ # convert into half-precision if necessary
+ if self.weight.dtype in [torch.float16, torch.bfloat16]:
+ hidden_states = hidden_states.to(self.weight.dtype)
+
+ return self.weight * hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5DenseActDense with T5->UMT5
+class UMT5DenseActDense(nn.Module):
+ def __init__(self, config: UMT5Config):
+ super().__init__()
+ self.wi = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.act = ACT2FN[config.dense_act_fn]
+
+ def forward(self, hidden_states):
+ hidden_states = self.wi(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ if (
+ isinstance(self.wo.weight, torch.Tensor)
+ and hidden_states.dtype != self.wo.weight.dtype
+ and self.wo.weight.dtype != torch.int8
+ ):
+ hidden_states = hidden_states.to(self.wo.weight.dtype)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5DenseGatedActDense with T5->UMT5
+class UMT5DenseGatedActDense(nn.Module):
+ def __init__(self, config: UMT5Config):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.act = ACT2FN[config.dense_act_fn]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+
+ # To make 8bit quantization work for google/flan-t5-xxl, self.wo is kept in float32.
+ # See https://github.com/huggingface/transformers/issues/20287
+ # we also make sure the weights are not in `int8` in case users will force `_keep_in_fp32_modules` to be `None``
+ if (
+ isinstance(self.wo.weight, torch.Tensor)
+ and hidden_states.dtype != self.wo.weight.dtype
+ and self.wo.weight.dtype != torch.int8
+ ):
+ hidden_states = hidden_states.to(self.wo.weight.dtype)
+
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.t5.modeling_t5.T5LayerFF with T5->UMT5
+class UMT5LayerFF(nn.Module):
+ def __init__(self, config: UMT5Config):
+ super().__init__()
+ if config.is_gated_act:
+ self.DenseReluDense = UMT5DenseGatedActDense(config)
+ else:
+ self.DenseReluDense = UMT5DenseActDense(config)
+
+ self.layer_norm = UMT5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ hidden_states = hidden_states + self.dropout(forwarded_states)
+ return hidden_states
+
+
+class UMT5Attention(nn.Module):
+ """
+ T5's attention using relative_attention_bias.
+ """
+
+ def __init__(self, config, has_relative_attention_bias=False, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.has_relative_attention_bias = has_relative_attention_bias
+ self.relative_attention_num_buckets = config.relative_attention_num_buckets
+ self.relative_attention_max_distance = config.relative_attention_max_distance
+ self.d_model = config.d_model
+ self.key_value_proj_dim = config.d_kv
+ self.n_heads = config.num_heads
+ self.dropout = config.dropout_rate
+ self.inner_dim = self.n_heads * self.key_value_proj_dim
+ self.layer_idx = layer_idx
+ if layer_idx is None and self.is_decoder:
+ logger.warning_once(
+ f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and "
+ "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+
+ # Mesh TensorFlow initialization to avoid scaling before softmax
+ self.q = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.k = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.v = nn.Linear(self.d_model, self.inner_dim, bias=False)
+ self.o = nn.Linear(self.inner_dim, self.d_model, bias=False)
+
+ if self.has_relative_attention_bias:
+ self.relative_attention_bias = nn.Embedding(self.relative_attention_num_buckets, self.n_heads)
+ self.pruned_heads = set()
+
+ def _shape(self, projection: torch.Tensor) -> torch.Tensor:
+ new_projection_shape = projection.size()[:-1] + (self.n_heads, self.key_value_proj_dim)
+ # move heads to 2nd position (B, T, H * D) -> (B, T, H, D) -> (B, H, T, D)
+ new_projection = projection.view(new_projection_shape).permute(0, 2, 1, 3)
+ return new_projection
+
+ def _relative_position_bucket(self, relative_position):
+ """
+ Adapted from Mesh Tensorflow:
+ https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593
+
+ Translate relative position to a bucket number for relative attention. The relative position is defined as
+ memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to
+ position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for
+ small absolute relative_position and larger buckets for larger absolute relative_positions. All relative
+ positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket.
+ This should allow for more graceful generalization to longer sequences than the model has been trained on
+
+ Args:
+ relative_position: an int32 Tensor
+ bidirectional: a boolean - whether the attention is bidirectional
+ num_buckets: an integer
+ max_distance: an integer
+
+ Returns:
+ a Tensor with the same shape as relative_position, containing int32 values in the range [0, num_buckets)
+ """
+ relative_buckets = 0
+ num_buckets = self.relative_attention_num_buckets
+ max_distance = self.relative_attention_max_distance
+ if not self.is_decoder:
+ num_buckets //= 2
+ relative_buckets += (relative_position > 0).to(torch.long) * num_buckets
+ relative_position = torch.abs(relative_position)
+ else:
+ relative_position = -torch.min(relative_position, torch.zeros_like(relative_position))
+ # now relative_position is in the range [0, inf)
+
+ # half of the buckets are for exact increments in positions
+ max_exact = num_buckets // 2
+ is_small = relative_position < max_exact
+
+ # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance
+ log_ratio = torch.log(relative_position.float() / max_exact) / math.log(max_distance / max_exact)
+ log_ratio = log_ratio * (num_buckets - max_exact)
+ relative_position_if_large = max_exact + log_ratio.to(torch.long)
+ relative_position_if_large = torch.min(
+ relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1)
+ )
+
+ relative_buckets += torch.where(is_small, relative_position, relative_position_if_large)
+ return relative_buckets
+
+ def compute_bias(self, query_length, key_length, device=None, cache_position=None):
+ """Compute binned relative position bias"""
+ if device is None:
+ device = self.relative_attention_bias.weight.device
+ if cache_position is None:
+ context_position = torch.arange(query_length, dtype=torch.long, device=device)[:, None]
+ else:
+ context_position = cache_position[:, None]
+ memory_position = torch.arange(key_length, dtype=torch.long, device=device)[None, :]
+ relative_position = memory_position - context_position # shape (query_length, key_length)
+ relative_position_bucket = self._relative_position_bucket(relative_position)
+ values = self.relative_attention_bias(relative_position_bucket) # shape (query_length, key_length, num_heads)
+ values = values.permute([2, 0, 1]).unsqueeze(0) # shape (1, num_heads, query_length, key_length)
+ return values
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ past_key_values: Optional[tuple[torch.Tensor]] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ):
+ batch_size, seq_length = hidden_states.shape[:2]
+
+ # if encoder_hidden_states are provided this layer is used as a cross-attention layer for the decoder
+ is_cross_attention = encoder_hidden_states is not None
+
+ query_states = self.q(hidden_states)
+ query_states = query_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ # Check is encoder-decoder model is being used. Otherwise we'll get `DynamicCache`
+ if past_key_values is not None and isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k(current_states)
+ value_states = self.v(current_states)
+ key_states = key_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+ value_states = value_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # compute scores, equivalent of torch.einsum("bnqd,bnkd->bnqk", query_states, key_states), compatible with onnx op>9
+ scores = torch.matmul(query_states, key_states.transpose(3, 2))
+
+ # cache position is 0-indexed so we add 1 to get the real length of queries (aka with past)
+ real_seq_length = seq_length + past_key_values.get_seq_length() if past_key_values is not None else seq_length
+ key_length = key_states.shape[-2]
+ if not self.has_relative_attention_bias:
+ position_bias = torch.zeros(
+ (1, self.n_heads, seq_length, key_length), device=scores.device, dtype=scores.dtype
+ )
+ else:
+ position_bias = self.compute_bias(
+ real_seq_length, key_length, device=scores.device, cache_position=cache_position
+ )
+ position_bias = position_bias[:, :, -seq_length:, :]
+
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ position_bias = position_bias + causal_mask
+
+ if self.pruned_heads:
+ mask = torch.ones(position_bias.shape[1])
+ mask[list(self.pruned_heads)] = 0
+ position_bias_masked = position_bias[:, mask.bool()]
+ else:
+ position_bias_masked = position_bias
+
+ scores += position_bias_masked
+
+ # (batch_size, n_heads, seq_length, key_length)
+ attn_weights = nn.functional.softmax(scores.float(), dim=-1).type_as(scores)
+ attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ # Mask heads if we want to
+ if layer_head_mask is not None:
+ attn_weights = attn_weights * layer_head_mask
+
+ attn_output = torch.matmul(attn_weights, value_states)
+
+ attn_output = attn_output.transpose(1, 2).contiguous()
+ attn_output = attn_output.view(batch_size, seq_length, -1)
+
+ attn_output = self.o(attn_output)
+ return attn_output, attn_weights
+
+
+class UMT5LayerSelfAttention(nn.Module):
+ def __init__(self, config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.SelfAttention = UMT5Attention(config, has_relative_attention_bias=True, layer_idx=layer_idx)
+ self.layer_norm = UMT5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.SelfAttention(
+ normed_hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+ hidden_states = hidden_states + self.dropout(attention_output[0])
+ outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+class UMT5LayerCrossAttention(nn.Module):
+ def __init__(self, config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.EncDecAttention = UMT5Attention(config, has_relative_attention_bias=False, layer_idx=layer_idx)
+ self.layer_norm = UMT5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ encoder_hidden_states=None,
+ attention_mask=None,
+ layer_head_mask=None,
+ past_key_values=None,
+ cache_position=None,
+ ):
+ normed_hidden_states = self.layer_norm(hidden_states)
+ attention_output = self.EncDecAttention(
+ normed_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+ layer_output = hidden_states + self.dropout(attention_output[0])
+ outputs = (layer_output,) + attention_output[1:] # add attentions if we output them
+ return outputs
+
+
+class UMT5Block(GradientCheckpointingLayer):
+ def __init__(self, config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.is_decoder = config.is_decoder
+ self.layer = nn.ModuleList()
+ self.layer.append(UMT5LayerSelfAttention(config, layer_idx=layer_idx))
+ if self.is_decoder:
+ self.layer.append(UMT5LayerCrossAttention(config, layer_idx=layer_idx))
+
+ self.layer.append(UMT5LayerFF(config))
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ layer_head_mask=None,
+ cross_attn_layer_head_mask=None,
+ past_key_values=None,
+ use_cache=False,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ hidden_states, self_attn_weights = self.layer[0](
+ hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ max_dtype = torch.finfo(hidden_states.dtype).max
+ clamp_value = torch.where(torch.isinf(hidden_states).any(), max_dtype - 1000, max_dtype)
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ do_cross_attention = self.is_decoder and encoder_hidden_states is not None
+ if do_cross_attention:
+ hidden_states, cross_attn_weights = self.layer[1](
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ max_dtype = torch.finfo(hidden_states.dtype).max
+ clamp_value = torch.where(torch.isinf(hidden_states).any(), max_dtype - 1000, max_dtype)
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ # Apply Feed Forward layer
+ hidden_states = self.layer[-1](hidden_states)
+
+ # clamp inf values to enable fp16 training
+ if hidden_states.dtype == torch.float16:
+ max_dtype = torch.finfo(hidden_states.dtype).max
+ clamp_value = torch.where(torch.isinf(hidden_states).any(), max_dtype - 1000, max_dtype)
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+# Copied from transformers.models.t5.modeling_t5.T5ClassificationHead with T5->UMT5
+class UMT5ClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, config: UMT5Config):
+ super().__init__()
+ self.dense = nn.Linear(config.d_model, config.d_model)
+ self.dropout = nn.Dropout(p=config.classifier_dropout)
+ self.out_proj = nn.Linear(config.d_model, config.num_labels)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.dense(hidden_states)
+ hidden_states = torch.tanh(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.out_proj(hidden_states)
+ return hidden_states
+
+
+@auto_docstring
+class UMT5PreTrainedModel(PreTrainedModel):
+ config: UMT5Config
+ base_model_prefix = "transformer"
+ supports_gradient_checkpointing = True
+
+ _can_compile_fullgraph = True
+ _no_split_modules = ["UMT5Block"]
+ _keep_in_fp32_modules = ["wo"]
+
+ @property
+ def dummy_inputs(self):
+ input_ids = torch.tensor(DUMMY_INPUTS)
+ input_mask = torch.tensor(DUMMY_MASK)
+ dummy_inputs = {
+ "decoder_input_ids": input_ids,
+ "input_ids": input_ids,
+ "decoder_attention_mask": input_mask,
+ }
+ return dummy_inputs
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ factor = self.config.initializer_factor # Used for testing weights initialization
+ if isinstance(module, UMT5LayerNorm):
+ module.weight.data.fill_(factor * 1.0)
+ elif isinstance(
+ module,
+ (
+ UMT5Model,
+ UMT5ForConditionalGeneration,
+ UMT5EncoderModel,
+ UMT5ForQuestionAnswering,
+ ),
+ ):
+ # Mesh TensorFlow embeddings initialization
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L1624
+ module.shared.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ if hasattr(module, "lm_head") and not self.config.tie_word_embeddings:
+ module.lm_head.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ if hasattr(module, "qa_outputs"):
+ module.qa_outputs.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ module.qa_outputs.bias.data.zero_()
+ elif isinstance(module, UMT5ForTokenClassification):
+ if hasattr(module, "classifier"):
+ module.classifier.weight.data.normal_(mean=0.0, std=factor * 1.0)
+ module.classifier.bias.data.zero_()
+ elif isinstance(module, UMT5ClassificationHead):
+ module.dense.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.dense, "bias") and module.dense.bias is not None:
+ module.dense.bias.data.zero_()
+ module.out_proj.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.out_proj, "bias") and module.out_proj.bias is not None:
+ module.out_proj.bias.data.zero_()
+ elif isinstance(module, UMT5DenseActDense):
+ # Mesh TensorFlow FF initialization
+ # See https://github.com/tensorflow/mesh/blob/master/mesh_tensorflow/transformer/transformer_layers.py#L56
+ # and https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L89
+ module.wi.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi, "bias") and module.wi.bias is not None:
+ module.wi.bias.data.zero_()
+ module.wo.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_ff) ** -0.5))
+ if hasattr(module.wo, "bias") and module.wo.bias is not None:
+ module.wo.bias.data.zero_()
+ elif isinstance(module, UMT5DenseGatedActDense):
+ module.wi_0.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi_0, "bias") and module.wi_0.bias is not None:
+ module.wi_0.bias.data.zero_()
+ module.wi_1.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_model) ** -0.5))
+ if hasattr(module.wi_1, "bias") and module.wi_1.bias is not None:
+ module.wi_1.bias.data.zero_()
+ module.wo.weight.data.normal_(mean=0.0, std=factor * ((self.config.d_ff) ** -0.5))
+ if hasattr(module.wo, "bias") and module.wo.bias is not None:
+ module.wo.bias.data.zero_()
+ elif isinstance(module, UMT5Attention):
+ # Mesh TensorFlow attention initialization to avoid scaling before softmax
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/attention.py#L136
+ d_model = self.config.d_model
+ key_value_proj_dim = self.config.d_kv
+ n_heads = self.config.num_heads
+ module.q.weight.data.normal_(mean=0.0, std=factor * ((d_model * key_value_proj_dim) ** -0.5))
+ module.k.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.v.weight.data.normal_(mean=0.0, std=factor * (d_model**-0.5))
+ module.o.weight.data.normal_(mean=0.0, std=factor * ((n_heads * key_value_proj_dim) ** -0.5))
+ if module.has_relative_attention_bias:
+ module.relative_attention_bias.weight.data.normal_(mean=0.0, std=factor * ((d_model) ** -0.5))
+
+ def _shift_right(self, input_ids):
+ decoder_start_token_id = self.config.decoder_start_token_id
+ pad_token_id = self.config.pad_token_id
+
+ if decoder_start_token_id is None:
+ raise ValueError(
+ "self.model.config.decoder_start_token_id has to be defined. In UMT5 it is usually set to the pad_token_id. "
+ "See UMT5 docs for more information."
+ )
+
+ # shift inputs to the right
+ if is_torch_fx_proxy(input_ids):
+ # Item assignment is not supported natively for proxies.
+ shifted_input_ids = torch.full(input_ids.shape[:-1] + (1,), decoder_start_token_id)
+ shifted_input_ids = torch.cat([shifted_input_ids, input_ids[..., :-1]], dim=-1)
+ else:
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
+ shifted_input_ids[..., 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.pad_token_id has to be defined.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+class UMT5Stack(UMT5PreTrainedModel):
+ def __init__(self, config, embed_tokens=None):
+ super().__init__(config)
+ self.embed_tokens = embed_tokens
+ self.is_decoder = config.is_decoder
+ self.block = nn.ModuleList([UMT5Block(config, layer_idx=i) for i in range(config.num_layers)])
+ self.final_layer_norm = UMT5LayerNorm(config.d_model, eps=config.layer_norm_epsilon)
+ self.dropout = nn.Dropout(config.dropout_rate)
+
+ # Initialize weights and apply final processing
+ self.gradient_checkpointing = False
+ self.post_init()
+
+ def set_input_embeddings(self, new_embeddings):
+ self.embed_tokens = new_embeddings
+
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ inputs_embeds=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ cache_position=None,
+ ):
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(
+ f"You cannot specify both {err_msg_prefix}input_ids and {err_msg_prefix}inputs_embeds at the same time"
+ )
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ err_msg_prefix = "decoder_" if self.is_decoder else ""
+ raise ValueError(f"You have to specify either {err_msg_prefix}input_ids or {err_msg_prefix}inputs_embeds")
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ if self.embed_tokens is None:
+ raise ValueError("You have to initialize the model with valid token embeddings")
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ batch_size, seq_length = input_shape
+
+ if use_cache is True:
+ if not self.is_decoder:
+ raise ValueError(f"`use_cache` can only be set to `True` if {self} is used as a decoder")
+
+ # initialize past_key_values
+ if self.is_decoder:
+ if use_cache and past_key_values is None:
+ if self.config.is_encoder_decoder:
+ past_key_values = EncoderDecoderCache(
+ DynamicCache(config=self.config), DynamicCache(config=self.config)
+ )
+ else:
+ past_key_values = DynamicCache(config=self.config)
+ elif not self.is_decoder:
+ # do not pass cache object down the line for encoder stack
+ # it messes indexing later in decoder-stack because cache object is modified in-place
+ past_key_values = None
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+ if cache_position is None:
+ cache_position = torch.arange(
+ past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device
+ )
+
+ if attention_mask is None and not is_torchdynamo_compiling():
+ # required mask seq length can be calculated via length of past cache
+ mask_seq_length = past_key_values_length + seq_length
+ attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device)
+
+ if self.is_decoder:
+ causal_mask = self._update_causal_mask(
+ attention_mask,
+ inputs_embeds,
+ cache_position,
+ past_key_values.self_attention_cache
+ if isinstance(past_key_values, EncoderDecoderCache)
+ else past_key_values,
+ output_attentions,
+ )
+ elif attention_mask is not None:
+ causal_mask = attention_mask[:, None, None, :]
+ causal_mask = causal_mask.to(dtype=inputs_embeds.dtype)
+ causal_mask = (1.0 - causal_mask) * torch.finfo(inputs_embeds.dtype).min
+ else:
+ causal_mask = None
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=inputs_embeds.device)
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ head_mask = self.get_head_mask(head_mask, self.config.num_layers)
+ cross_attn_head_mask = self.get_head_mask(cross_attn_head_mask, self.config.num_layers)
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.is_decoder else None
+
+ hidden_states = self.dropout(inputs_embeds)
+
+ for i, layer_module in enumerate(self.block):
+ layer_head_mask = head_mask[i]
+ cross_attn_layer_head_mask = cross_attn_head_mask[i]
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states,
+ causal_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_extended_attention_mask,
+ layer_head_mask=layer_head_mask,
+ cross_attn_layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions += (layer_outputs[1],)
+ if self.is_decoder:
+ all_cross_attentions += (layer_outputs[2],)
+
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ past_key_values,
+ all_hidden_states,
+ all_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._update_causal_mask
+ def _update_causal_mask(
+ self,
+ attention_mask: Union[torch.Tensor, "BlockMask"],
+ input_tensor: torch.Tensor,
+ cache_position: torch.Tensor,
+ past_key_values: Cache,
+ output_attentions: bool = False,
+ ):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and (attention_mask == 0.0).any():
+ return attention_mask
+ return None
+ if self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask)
+ return attention_mask
+
+ # For SDPA, when possible, we will rely on its `is_causal` argument instead of its `attn_mask` argument, in
+ # order to dispatch on Flash Attention 2. This feature is not compatible with static cache, as SDPA will fail
+ # to infer the attention mask.
+ past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0
+ using_compilable_cache = past_key_values.is_compileable if past_key_values is not None else False
+
+ # When output attentions is True, sdpa implementation's forward method calls the eager implementation's forward
+ if self.config._attn_implementation == "sdpa" and not using_compilable_cache and not output_attentions:
+ if AttentionMaskConverter._ignore_causal_mask_sdpa(
+ attention_mask,
+ inputs_embeds=input_tensor,
+ past_key_values_length=past_seen_tokens,
+ is_training=self.training,
+ ):
+ return None
+
+ dtype = input_tensor.dtype
+ sequence_length = input_tensor.shape[1]
+ if using_compilable_cache:
+ target_length = past_key_values.get_max_cache_shape()
+ else:
+ target_length = (
+ attention_mask.shape[-1]
+ if isinstance(attention_mask, torch.Tensor)
+ else past_seen_tokens + sequence_length + 1
+ )
+
+ # In case the provided `attention` mask is 2D, we generate a causal mask here (4D).
+ causal_mask = self._prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask,
+ sequence_length=sequence_length,
+ target_length=target_length,
+ dtype=dtype,
+ cache_position=cache_position,
+ batch_size=input_tensor.shape[0],
+ )
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type in ["cuda", "xpu", "npu"]
+ and not output_attentions
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ @staticmethod
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._prepare_4d_causal_attention_mask_with_cache_position
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=cache_position.device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=cache_position.device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :].to(
+ causal_mask.device
+ )
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
+
+
+@auto_docstring
+class UMT5Model(UMT5PreTrainedModel):
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import UMT5Model, AutoTokenizer
+
+ >>> model = UMT5Model.from_pretrained("google/umt5-small")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+ >>> noisy_text = "UN Offizier sagt, dass weiter werden muss in Syrien."
+ >>> label = " verhandelt"
+ >>> inputs = tokenizer(inputs, return_tensors="pt")
+ >>> labels = tokenizer(label=label, return_tensors="pt")
+
+ >>> outputs = model(input_ids=inputs["input_ids"], decoder_input_ids=labels["input_ids"])
+ >>> hidden_states = outputs.last_hidden_state
+ ```"""
+
+ model_type = "umt5"
+ config: UMT5Config
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = UMT5Stack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = UMT5Stack(decoder_config, self.shared)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Copied from transformers.models.t5.modeling_t5.T5Model.get_input_embeddings
+ def get_input_embeddings(self):
+ return self.shared
+
+ # Copied from transformers.models.t5.modeling_t5.T5Model.set_input_embeddings
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ # Copied from transformers.models.t5.modeling_t5.T5Model._tie_weights
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ # Copied from transformers.models.t5.modeling_t5.T5Model.get_encoder
+ def get_encoder(self):
+ return self.encoder
+
+ # Copied from transformers.models.t5.modeling_t5.T5Model._prune_heads
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ decoder_inputs_embeds: Optional[torch.Tensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. UMT5 is a model with relative position embeddings so
+ you should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [UMT5 Training](./umt5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ UMT5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [UMT5
+ Training](./umt5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, UMT5Model
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+ >>> model = UMT5Model.from_pretrained("google/umt5-small")
+
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> decoder_input_ids = tokenizer("Studies show that", return_tensors="pt").input_ids # Batch size 1
+
+ >>> # preprocess: Prepend decoder_input_ids with start token which is pad token for UMT5Model.
+ >>> # This is not needed for torch's UMT5ForConditionalGeneration as it does this internally using labels arg.
+ >>> decoder_input_ids = model._shift_right(decoder_input_ids)
+
+ >>> # forward pass
+ >>> outputs = model(input_ids=input_ids, decoder_input_ids=decoder_input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ UMT5 Model with a `language modeling` head on top.
+ """
+)
+class UMT5ForConditionalGeneration(UMT5PreTrainedModel, GenerationMixin):
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import UMT5ForConditionalGeneration, AutoTokenizer
+
+ >>> model = UMT5ForConditionalGeneration.from_pretrained("google/umt5-small")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+ >>> article = "UN Offizier sagt, dass weiter verhandelt werden muss in Syrien."
+ >>> summary = "Weiter Verhandlung in Syrien."
+ >>> inputs = tokenizer(article, text_target=summary, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> loss = outputs.loss
+ ```"""
+
+ model_type = "umt5"
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight", "lm_head.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.model_dim = config.d_model
+
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = UMT5Stack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = UMT5Stack(decoder_config, self.shared)
+
+ self.lm_head = nn.Linear(config.d_model, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForConditionalGeneration.get_input_embeddings
+ def get_input_embeddings(self):
+ return self.shared
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForConditionalGeneration.set_input_embeddings
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForConditionalGeneration._tie_weights
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForConditionalGeneration.get_encoder
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.Tensor]]] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. UMT5 is a model with relative position embeddings so
+ you should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [UMT5 Training](./umt5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ UMT5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [UMT5
+ Training](./umt5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size - 1]`. All labels set to `-100` are ignored (masked), the loss is only computed for
+ labels in `[0, ..., config.vocab_size]`
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, UMT5ForConditionalGeneration
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+ >>> model = UMT5ForConditionalGeneration.from_pretrained("google/umt5-small")
+
+ >>> # training
+ >>> input_ids = tokenizer("The walks in park", return_tensors="pt").input_ids
+ >>> labels = tokenizer(" cute dog the ", return_tensors="pt").input_ids
+ >>> outputs = model(input_ids=input_ids, labels=labels)
+ >>> loss = outputs.loss
+ >>> logits = outputs.logits
+
+ >>> # inference
+ >>> input_ids = tokenizer("Studies have shown that good for you", return_tensors="pt").input_ids
+ >>> outputs = model.generate(input_ids)
+ >>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+ ```"""
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ # Convert encoder inputs in embeddings if needed
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None:
+ # get decoder inputs from shifting lm labels to the right
+ decoder_input_ids = self._shift_right(labels)
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=past_key_values,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ if self.config.tie_word_embeddings:
+ # Rescale output before projecting on vocab
+ # See https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/transformer/transformer.py#L586
+ sequence_output = sequence_output * (self.model_dim**-0.5)
+
+ lm_logits = self.lm_head(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss(ignore_index=-100)
+ # move labels to correct device to enable PP
+ labels = labels.to(lm_logits.device)
+ loss = loss_fct(lm_logits.view(-1, lm_logits.size(-1)), labels.view(-1))
+
+ if not return_dict:
+ output = (lm_logits,) + decoder_outputs[1:] + encoder_outputs
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=lm_logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForConditionalGeneration.prepare_decoder_input_ids_from_labels
+ def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor):
+ return self._shift_right(labels)
+
+
+@auto_docstring
+class UMT5EncoderModel(UMT5PreTrainedModel):
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import UMT5EncoderModel, AutoTokenizer
+
+ >>> model = UMT5EncoderModel.from_pretrained("google/umt5-small")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+ >>> article = "UN Offizier sagt, dass weiter verhandelt werden muss in Syrien."
+ >>> input_ids = tokenizer(article, return_tensors="pt").input_ids
+ >>> outputs = model(input_ids)
+ >>> hidden_state = outputs.last_hidden_state
+ ```"""
+
+ model_type = "umt5"
+ # config_class = UMT5Config
+ _tied_weights_keys = ["encoder.embed_tokens.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.use_cache = False
+ encoder_config.is_encoder_decoder = False
+ self.encoder = UMT5Stack(encoder_config, self.shared)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Copied from transformers.models.t5.modeling_t5.T5EncoderModel.get_input_embeddings
+ def get_input_embeddings(self):
+ return self.shared
+
+ # Copied from transformers.models.t5.modeling_t5.T5EncoderModel.set_input_embeddings
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+
+ # Copied from transformers.models.t5.modeling_t5.T5EncoderModel._tie_weights
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+
+ # Copied from transformers.models.t5.modeling_t5.T5EncoderModel.get_encoder
+ def get_encoder(self):
+ return self.encoder
+
+ # Copied from transformers.models.t5.modeling_t5.T5EncoderModel._prune_heads
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.block[layer].layer[0].SelfAttention.prune_heads(heads)
+
+ @auto_docstring
+ # Copied from transformers.models.t5.modeling_t5.T5EncoderModel.forward with T5->UMT5, google-t5/t5-small->google/umt5-small, t5#training->umt5#training
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], BaseModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. UMT5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [UMT5 Training](./umt5#training).
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, UMT5EncoderModel
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+ >>> model = UMT5EncoderModel.from_pretrained("google/umt5-small")
+ >>> input_ids = tokenizer(
+ ... "Studies have been shown that owning a dog is good for you", return_tensors="pt"
+ ... ).input_ids # Batch size 1
+ >>> outputs = model(input_ids=input_ids)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ return encoder_outputs
+
+
+@auto_docstring(
+ custom_intro="""
+ UMT5 model with a sequence classification/head on top (a linear layer on top of the pooled output) e.g. for GLUE
+ tasks.
+ """
+)
+class UMT5ForSequenceClassification(UMT5PreTrainedModel):
+ _keys_to_ignore_on_load_unexpected = ["decoder.block.0.layer.1.EncDecAttention.relative_attention_bias.weight"]
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight"]
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForSequenceClassification.__init__ with T5->UMT5
+ def __init__(self, config: UMT5Config):
+ super().__init__(config)
+ self.transformer = UMT5Model(config)
+ self.classification_head = UMT5ClassificationHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ self.model_parallel = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[list[torch.FloatTensor]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Seq2SeqSequenceClassifierOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. UMT5 is a model with relative position embeddings so
+ you should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [UMT5 Training](./umt5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ UMT5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [UMT5
+ Training](./umt5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ if labels is not None:
+ use_cache = False
+
+ if input_ids is None and inputs_embeds is not None:
+ raise NotImplementedError(
+ f"Passing input embeddings is currently not supported for {self.__class__.__name__}"
+ )
+
+ # Copied from models.bart.modeling_bart.BartModel.forward different to other models, T5 automatically creates
+ # decoder_input_ids from input_ids if no decoder_input_ids are provided
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ inputs_embeds=inputs_embeds,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+
+ eos_mask = input_ids.eq(self.config.eos_token_id).to(sequence_output.device)
+
+ if len(torch.unique_consecutive(eos_mask.sum(1))) > 1:
+ raise ValueError("All examples must have the same number of tokens.")
+ batch_size, _, hidden_size = sequence_output.shape
+ sentence_representation = sequence_output[eos_mask, :].view(batch_size, -1, hidden_size)[:, -1, :]
+ logits = self.classification_head(sentence_representation)
+
+ loss = None
+ if labels is not None:
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.config.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.config.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.config.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqSequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+
+@auto_docstring
+class UMT5ForTokenClassification(UMT5PreTrainedModel):
+ _keys_to_ignore_on_load_unexpected = ["decoder.block.0.layer.1.EncDecAttention.relative_attention_bias.weight"]
+ _tied_weights_keys = ["transformer.encoder.embed_tokens.weight"]
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForTokenClassification.__init__ with T5->UMT5
+ def __init__(self, config: UMT5Config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.transformer = UMT5EncoderModel(config)
+ self.dropout = nn.Dropout(config.classifier_dropout)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ # Copied from transformers.models.t5.modeling_t5.T5ForTokenClassification.forward with T5->UMT5, t5->umt5
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], TokenClassifierOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. UMT5 is a model with relative position embeddings so you
+ should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [UMT5 Training](./umt5#training).
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits, outputs[2:-1])
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class UMT5ForQuestionAnswering(UMT5PreTrainedModel):
+ _tied_weights_keys = ["encoder.embed_tokens.weight", "decoder.embed_tokens.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.model_dim = config.d_model
+
+ self.shared = nn.Embedding(config.vocab_size, config.d_model)
+
+ encoder_config = copy.deepcopy(config)
+ encoder_config.is_decoder = False
+ encoder_config.use_cache = False
+ encoder_config.tie_encoder_decoder = False
+ self.encoder = UMT5Stack(encoder_config, self.shared)
+
+ decoder_config = copy.deepcopy(config)
+ decoder_config.is_decoder = True
+ decoder_config.tie_encoder_decoder = False
+ decoder_config.num_layers = config.num_decoder_layers
+ self.decoder = UMT5Stack(decoder_config, self.shared)
+
+ self.num_labels = config.num_labels
+ self.qa_outputs = nn.Linear(config.d_model, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForQuestionAnswering.get_input_embeddings
+ def get_input_embeddings(self):
+ return self.shared
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForQuestionAnswering.set_input_embeddings
+ def set_input_embeddings(self, new_embeddings):
+ self.shared = new_embeddings
+ self.encoder.set_input_embeddings(new_embeddings)
+ self.decoder.set_input_embeddings(new_embeddings)
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForQuestionAnswering._tie_weights
+ def _tie_weights(self):
+ if self.config.tie_word_embeddings:
+ self._tie_or_clone_weights(self.encoder.embed_tokens, self.shared)
+ self._tie_or_clone_weights(self.decoder.embed_tokens, self.shared)
+
+ # Copied from transformers.models.t5.modeling_t5.T5ForQuestionAnswering.get_encoder
+ def get_encoder(self):
+ return self.encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ decoder_head_mask: Optional[torch.FloatTensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.Tensor]]] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqQuestionAnsweringModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. UMT5 is a model with relative position embeddings so
+ you should be able to pad the inputs on both the right and the left.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for detail.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ To know more on how to prepare `input_ids` for pretraining take a look a [UMT5 Training](./umt5#training).
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ UMT5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values`
+ is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
+
+ To know more on how to prepare `decoder_input_ids` for pretraining take a look at [UMT5
+ Training](./umt5#training).
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules in the decoder. Mask values selected in `[0,
+ 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules in the decoder. Mask values selected in
+ `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ if start_positions is not None and end_positions is not None:
+ use_cache = False
+
+ # Copied from models.bart.modeling_bart.BartModel.forward
+ # different to other models, T5 automatically creates decoder_input_ids from
+ # input_ids if no decoder_input_ids are provided
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ if input_ids is None:
+ raise ValueError(
+ "If no `decoder_input_ids` or `decoder_inputs_embeds` are "
+ "passed, `input_ids` cannot be `None`. Please pass either "
+ "`input_ids` or `decoder_input_ids` or `decoder_inputs_embeds`."
+ )
+ decoder_input_ids = self._shift_right(input_ids)
+
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Encode if needed (training, first prediction pass)
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ inputs_embeds=inputs_embeds,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ past_key_values=None,
+ encoder_hidden_states=hidden_states,
+ encoder_attention_mask=attention_mask,
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = decoder_outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1).to(start_logits.device)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1).to(end_logits.device)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + decoder_outputs[1:] + encoder_outputs
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return Seq2SeqQuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+__all__ = [
+ "UMT5EncoderModel",
+ "UMT5ForConditionalGeneration",
+ "UMT5ForQuestionAnswering",
+ "UMT5ForSequenceClassification",
+ "UMT5ForTokenClassification",
+ "UMT5Model",
+ "UMT5PreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..a03daae25f4535c96c32e20dc4b13a817518bc06
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_unispeech import *
+ from .modeling_unispeech import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/configuration_unispeech.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/configuration_unispeech.py
new file mode 100644
index 0000000000000000000000000000000000000000..a71ba7f1b7d2a57671e8e75f1c773b0665e1614a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/configuration_unispeech.py
@@ -0,0 +1,309 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""UniSpeech model configuration"""
+
+import functools
+import operator
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class UniSpeechConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`UniSpeechModel`]. It is used to instantiate an
+ UniSpeech model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the UniSpeech
+ [microsoft/unispeech-large-1500h-cv](https://huggingface.co/microsoft/unispeech-large-1500h-cv) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32):
+ Vocabulary size of the UniSpeech model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`UniSpeechModel`]. Vocabulary size of the model. Defines the
+ different tokens that can be represented by the *inputs_ids* passed to the forward method of
+ [`UniSpeechModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for activations inside the fully connected layer.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ feat_proj_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for output of the feature encoder.
+ feat_quantizer_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the output of the feature encoder that's used by the quantizer.
+ final_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the final projection layer of [`UniSpeechForCTC`].
+ layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) for more
+ details.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the layer normalization layers.
+ feat_extract_norm (`str`, *optional*, defaults to `"group"`):
+ The norm to be applied to 1D convolutional layers in feature encoder. One of `"group"` for group
+ normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D
+ convolutional layers.
+ feat_extract_activation (`str, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the 1D convolutional layers of the feature
+ extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 512, 512, 512)`):
+ A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the
+ feature encoder. The length of *conv_dim* defines the number of 1D convolutional layers.
+ conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 2, 2, 2, 2, 2)`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the feature encoder. The length
+ of *conv_stride* defines the number of convolutional layers and has to match the length of *conv_dim*.
+ conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 3, 3, 3, 2, 2)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the feature encoder. The
+ length of *conv_kernel* defines the number of convolutional layers and has to match the length of
+ *conv_dim*.
+ conv_bias (`bool`, *optional*, defaults to `False`):
+ Whether the 1D convolutional layers have a bias.
+ num_conv_pos_embeddings (`int`, *optional*, defaults to 128):
+ Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional
+ embeddings layer.
+ num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16):
+ Number of groups of 1D convolutional positional embeddings layer.
+ do_stable_layer_norm (`bool`, *optional*, defaults to `False`):
+ Whether to apply *stable* layer norm architecture of the Transformer encoder. `do_stable_layer_norm is
+ True` corresponds to applying layer norm before the attention layer, whereas `do_stable_layer_norm is
+ False` corresponds to applying layer norm after the attention layer.
+ apply_spec_augment (`bool`, *optional*, defaults to `True`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see
+ [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking
+ procedure generates ''mask_time_prob*len(time_axis)/mask_time_length'' independent masks over the axis. If
+ reasoning from the probability of each feature vector to be chosen as the start of the vector span to be
+ masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the
+ actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2):
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks''
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The
+ masking procedure generates ''mask_feature_prob*len(feature_axis)/mask_time_length'' independent masks over
+ the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector
+ span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap
+ may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is
+ True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ mask_feature_min_masks (`int`, *optional*, defaults to 0):
+ The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time
+ step, irrespectively of `mask_feature_prob`. Only relevant if
+ ''mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks''
+ num_codevectors_per_group (`int`, *optional*, defaults to 320):
+ Number of entries in each quantization codebook (group).
+ num_codevector_groups (`int`, *optional*, defaults to 2):
+ Number of codevector groups for product codevector quantization.
+ contrastive_logits_temperature (`float`, *optional*, defaults to 0.1):
+ The temperature *kappa* in the contrastive loss.
+ num_negatives (`int`, *optional*, defaults to 100):
+ Number of negative samples for the contrastive loss.
+ codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the quantized feature vectors.
+ proj_codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the final projection of both the quantized and the transformer features.
+ diversity_loss_weight (`int`, *optional*, defaults to 0.1):
+ The weight of the codebook diversity loss component.
+ ctc_loss_reduction (`str`, *optional*, defaults to `"mean"`):
+ Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an
+ instance of [`UniSpeechForCTC`].
+ ctc_zero_infinity (`bool`, *optional*, defaults to `False`):
+ Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly
+ occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance
+ of [`UniSpeechForCTC`].
+ use_weighted_layer_sum (`bool`, *optional*, defaults to `False`):
+ Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an
+ instance of [`UniSpeechForSequenceClassification`].
+ classifier_proj_size (`int`, *optional*, defaults to 256):
+ Dimensionality of the projection before token mean-pooling for classification.
+ num_ctc_classes (`int`, *optional*, defaults to 80):
+ Specifies the number of classes (phoneme tokens and blank token) for phoneme-level CTC loss. Only relevant
+ when using an instance of [`UniSpeechForPreTraining`].
+ pad_token_id (`int`, *optional*, defaults to 0):
+ The id of the padding token.
+ bos_token_id (`int`, *optional*, defaults to 1):
+ The id of the "beginning-of-sequence" token.
+ eos_token_id (`int`, *optional*, defaults to 2):
+ The id of the "end-of-sequence" token.
+ replace_prob (`float`, *optional*, defaults to 0.5):
+ Probability that transformer feature is replaced by quantized feature for pretraining.
+
+ Example:
+
+ ```python
+ >>> from transformers import UniSpeechConfig, UniSpeechModel
+
+ >>> # Initializing a UniSpeech facebook/unispeech-base-960h style configuration
+ >>> configuration = UniSpeechConfig()
+
+ >>> # Initializing a model (with random weights) from the facebook/unispeech-base-960h style configuration
+ >>> model = UniSpeechModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "unispeech"
+
+ def __init__(
+ self,
+ vocab_size=32,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout=0.1,
+ activation_dropout=0.1,
+ attention_dropout=0.1,
+ feat_proj_dropout=0.0,
+ feat_quantizer_dropout=0.0,
+ final_dropout=0.1,
+ layerdrop=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ feat_extract_norm="group",
+ feat_extract_activation="gelu",
+ conv_dim=(512, 512, 512, 512, 512, 512, 512),
+ conv_stride=(5, 2, 2, 2, 2, 2, 2),
+ conv_kernel=(10, 3, 3, 3, 3, 2, 2),
+ conv_bias=False,
+ num_conv_pos_embeddings=128,
+ num_conv_pos_embedding_groups=16,
+ do_stable_layer_norm=False,
+ apply_spec_augment=True,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ mask_feature_min_masks=0,
+ num_codevectors_per_group=320,
+ num_codevector_groups=2,
+ contrastive_logits_temperature=0.1,
+ num_negatives=100,
+ codevector_dim=256,
+ proj_codevector_dim=256,
+ diversity_loss_weight=0.1,
+ ctc_loss_reduction="mean",
+ ctc_zero_infinity=False,
+ use_weighted_layer_sum=False,
+ classifier_proj_size=256,
+ num_ctc_classes=80,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ replace_prob=0.5,
+ **kwargs,
+ ):
+ super().__init__(**kwargs, pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id)
+ self.hidden_size = hidden_size
+ self.feat_extract_norm = feat_extract_norm
+ self.feat_extract_activation = feat_extract_activation
+ self.conv_dim = list(conv_dim)
+ self.conv_stride = list(conv_stride)
+ self.conv_kernel = list(conv_kernel)
+ self.conv_bias = conv_bias
+ self.num_conv_pos_embeddings = num_conv_pos_embeddings
+ self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups
+ self.num_feat_extract_layers = len(self.conv_dim)
+ self.num_hidden_layers = num_hidden_layers
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.num_attention_heads = num_attention_heads
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.feat_proj_dropout = feat_proj_dropout
+ self.final_dropout = final_dropout
+ self.layerdrop = layerdrop
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.num_ctc_classes = num_ctc_classes
+ self.vocab_size = vocab_size
+ self.do_stable_layer_norm = do_stable_layer_norm
+ self.use_weighted_layer_sum = use_weighted_layer_sum
+ self.classifier_proj_size = classifier_proj_size
+
+ if (
+ (len(self.conv_stride) != self.num_feat_extract_layers)
+ or (len(self.conv_kernel) != self.num_feat_extract_layers)
+ or (len(self.conv_dim) != self.num_feat_extract_layers)
+ ):
+ raise ValueError(
+ "Configuration for convolutional layers is incorrect. It is required that `len(config.conv_dim)` =="
+ " `len(config.conv_stride)` == `len(config.conv_kernel)`, but is `len(config.conv_dim) ="
+ f" {len(self.conv_dim)}`, `len(config.conv_stride) = {len(self.conv_stride)}`,"
+ f" `len(config.conv_kernel) = {len(self.conv_kernel)}`."
+ )
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+ self.mask_feature_min_masks = mask_feature_min_masks
+
+ # parameters for pretraining with codevector quantized representations
+ self.num_codevectors_per_group = num_codevectors_per_group
+ self.num_codevector_groups = num_codevector_groups
+ self.contrastive_logits_temperature = contrastive_logits_temperature
+ self.feat_quantizer_dropout = feat_quantizer_dropout
+ self.num_negatives = num_negatives
+ self.codevector_dim = codevector_dim
+ self.proj_codevector_dim = proj_codevector_dim
+ self.diversity_loss_weight = diversity_loss_weight
+
+ # ctc loss
+ self.ctc_loss_reduction = ctc_loss_reduction
+ self.ctc_zero_infinity = ctc_zero_infinity
+
+ # pretraining loss
+ self.replace_prob = replace_prob
+
+ @property
+ def inputs_to_logits_ratio(self):
+ return functools.reduce(operator.mul, self.conv_stride, 1)
+
+
+__all__ = ["UniSpeechConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/modeling_unispeech.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/modeling_unispeech.py
new file mode 100644
index 0000000000000000000000000000000000000000..233653a36b39c58d3edcc984cefec9f8e44961be
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/modeling_unispeech.py
@@ -0,0 +1,1518 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/unispeech/modular_unispeech.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_unispeech.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import numpy as np
+import torch
+import torch.nn as nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask, _prepare_4d_attention_mask_for_sdpa
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ CausalLMOutput,
+ ModelOutput,
+ SequenceClassifierOutput,
+ Wav2Vec2BaseModelOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import auto_docstring, is_torch_flex_attn_available, logging
+from .configuration_unispeech import UniSpeechConfig
+
+
+if is_torch_flex_attn_available():
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`UniSpeechForPreTrainingOutput`], with potential hidden states and attentions.
+ """
+)
+class UniSpeechForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when model is in train mode, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ projected_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ codevector_perplexity (`torch.FloatTensor` of shape `(1,)`):
+ The perplexity of the codevector distribution, used to measure the diversity of the codebook.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ projected_states: Optional[torch.FloatTensor] = None
+ projected_quantized_states: Optional[torch.FloatTensor] = None
+ codevector_perplexity: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+class UniSpeechSamePadLayer(nn.Module):
+ def __init__(self, num_conv_pos_embeddings):
+ super().__init__()
+ self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0
+
+ def forward(self, hidden_states):
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, :, : -self.num_pad_remove]
+ return hidden_states
+
+
+class UniSpeechPositionalConvEmbedding(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=config.num_conv_pos_embeddings,
+ padding=config.num_conv_pos_embeddings // 2,
+ groups=config.num_conv_pos_embedding_groups,
+ )
+
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0):
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+ if hasattr(self.conv, "parametrizations"):
+ weight_g = self.conv.parametrizations.weight.original0
+ weight_v = self.conv.parametrizations.weight.original1
+ else:
+ weight_g = self.conv.weight_g
+ weight_v = self.conv.weight_v
+ deepspeed.zero.register_external_parameter(self, weight_v)
+ deepspeed.zero.register_external_parameter(self, weight_g)
+ else:
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+
+ self.padding = UniSpeechSamePadLayer(config.num_conv_pos_embeddings)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.padding(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class UniSpeechNoLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class UniSpeechLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+
+ hidden_states = hidden_states.transpose(-2, -1)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states.transpose(-2, -1)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class UniSpeechGroupNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class UniSpeechFeatureEncoder(nn.Module):
+ """Construct the features from raw audio waveform"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ if config.feat_extract_norm == "group":
+ conv_layers = [UniSpeechGroupNormConvLayer(config, layer_id=0)] + [
+ UniSpeechNoLayerNormConvLayer(config, layer_id=i + 1)
+ for i in range(config.num_feat_extract_layers - 1)
+ ]
+ elif config.feat_extract_norm == "layer":
+ conv_layers = [
+ UniSpeechLayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)
+ ]
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']"
+ )
+ self.conv_layers = nn.ModuleList(conv_layers)
+ self.gradient_checkpointing = False
+ self._requires_grad = True
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def forward(self, input_values):
+ hidden_states = input_values[:, None]
+
+ # make sure hidden_states require grad for gradient_checkpointing
+ if self._requires_grad and self.training:
+ hidden_states.requires_grad = True
+
+ for conv_layer in self.conv_layers:
+ hidden_states = conv_layer(hidden_states)
+
+ return hidden_states
+
+
+class UniSpeechFeatureProjection(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps)
+ self.projection = nn.Linear(config.conv_dim[-1], config.hidden_size)
+ self.dropout = nn.Dropout(config.feat_proj_dropout)
+
+ def forward(self, hidden_states):
+ # non-projected hidden states are needed for quantization
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states, norm_hidden_states
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: Optional[float] = None,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ if scaling is None:
+ scaling = query.size(-1) ** -0.5
+
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class UniSpeechAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ is_causal: bool = False,
+ config: Optional[UniSpeechConfig] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ self.config = config
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.is_causal = is_causal
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ # TODO: we need a refactor so that the different attention modules can get their specific kwargs
+ # ATM, we have mixed things encoder, decoder, and encoder-decoder attn
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ # determine input shapes
+ bsz, tgt_len = hidden_states.shape[:-1]
+ src_len = key_value_states.shape[1] if is_cross_attention else tgt_len
+
+ q_input_shape = (bsz, tgt_len, -1, self.head_dim)
+ kv_input_shape = (bsz, src_len, -1, self.head_dim)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2)
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ key_states = self.k_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+ value_states = self.v_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.dropout,
+ scaling=self.scaling,
+ output_attentions=output_attentions,
+ head_mask=layer_head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights, None
+
+
+class UniSpeechFeedForward(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.intermediate_dropout = nn.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ self.output_dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.output_dropout = nn.Dropout(config.hidden_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states)
+ return hidden_states
+
+
+class UniSpeechEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = UniSpeechAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ config=config,
+ )
+
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = UniSpeechFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, output_attentions=False):
+ attn_residual = hidden_states
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class UniSpeechEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = UniSpeechPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList([UniSpeechEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ hidden_states,
+ )
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+
+class UniSpeechAttnAdapterLayer(nn.Module):
+ def __init__(self, config):
+ """
+ Implements adapter modules directly with 3D tensor weight as parameters and without using ModuleList to speed
+ up training throughput.
+ """
+ super().__init__()
+ self.input_dim = config.adapter_attn_dim
+ self.hidden_dim = config.hidden_size
+
+ self.norm = nn.LayerNorm(self.hidden_dim)
+ self.linear_1 = nn.Linear(self.hidden_dim, self.input_dim)
+ self.act_fn = nn.ReLU()
+ self.linear_2 = nn.Linear(self.input_dim, self.hidden_dim)
+
+ def forward(self, hidden_states: torch.FloatTensor):
+ hidden_states = self.norm(hidden_states)
+
+ hidden_states = self.linear_1(hidden_states)
+ hidden_states = self.act_fn(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+
+ return hidden_states
+
+
+class UniSpeechEncoderLayerStableLayerNorm(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = UniSpeechAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ config=config,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = UniSpeechFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ if getattr(config, "adapter_attn_dim", None) is not None:
+ self.adapter_layer = UniSpeechAttnAdapterLayer(config)
+ else:
+ self.adapter_layer = None
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ attn_residual = hidden_states
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+ hidden_states = hidden_states + self.feed_forward(self.final_layer_norm(hidden_states))
+
+ if self.adapter_layer is not None:
+ hidden_states = hidden_states + self.adapter_layer(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class UniSpeechEncoderStableLayerNorm(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = UniSpeechPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList(
+ [UniSpeechEncoderLayerStableLayerNorm(config) for _ in range(config.num_hidden_layers)]
+ )
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ hidden_states,
+ )
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ # XXX: could optimize this like synced_gpus in generate_utils but not sure if it's worth the code complication
+ layer_outputs = layer(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+
+class UniSpeechGumbelVectorQuantizer(nn.Module):
+ """
+ Vector quantization using gumbel softmax. See `[CATEGORICAL REPARAMETERIZATION WITH
+ GUMBEL-SOFTMAX](https://huggingface.co/papers/1611.01144) for more information.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.num_groups = config.num_codevector_groups
+ self.num_vars = config.num_codevectors_per_group
+
+ if config.codevector_dim % self.num_groups != 0:
+ raise ValueError(
+ f"`config.codevector_dim {config.codevector_dim} must be divisible "
+ f"by `config.num_codevector_groups` {self.num_groups} for concatenation"
+ )
+
+ # storage for codebook variables (codewords)
+ self.codevectors = nn.Parameter(
+ torch.FloatTensor(1, self.num_groups * self.num_vars, config.codevector_dim // self.num_groups)
+ )
+ self.weight_proj = nn.Linear(config.conv_dim[-1], self.num_groups * self.num_vars)
+
+ # can be decayed for training
+ self.temperature = 2
+
+ @staticmethod
+ def _compute_perplexity(probs):
+ marginal_probs = probs.mean(dim=0)
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(
+ hidden_states.float(), tau=self.temperature, hard=True
+ ).type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(*hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+@auto_docstring
+class UniSpeechPreTrainedModel(PreTrainedModel):
+ config: UniSpeechConfig
+ base_model_prefix = "unispeech"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # gumbel softmax requires special init
+ if isinstance(module, UniSpeechGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, UniSpeechPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, UniSpeechFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths).to(torch.long)
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+UniSpeechBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+@auto_docstring
+class UniSpeechModel(UniSpeechPreTrainedModel):
+ def __init__(self, config: UniSpeechConfig):
+ super().__init__(config)
+ self.config = config
+ self.feature_extractor = UniSpeechFeatureEncoder(config)
+ self.feature_projection = UniSpeechFeatureProjection(config)
+
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ if config.do_stable_layer_norm:
+ self.encoder = UniSpeechEncoderStableLayerNorm(config)
+ else:
+ self.encoder = UniSpeechEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _mask_hidden_states(
+ self,
+ hidden_states: torch.FloatTensor,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+ elif self.config.mask_time_prob > 0 and self.training:
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool)
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool)
+ mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1)
+ hidden_states[mask_feature_indices] = 0
+
+ return hidden_states
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(extract_features.shape[1], attention_mask)
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return UniSpeechBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeech Model with a vector-quantization module and ctc loss for pre-training.
+ """
+)
+class UniSpeechForPreTraining(UniSpeechPreTrainedModel):
+ def __init__(self, config: UniSpeechConfig):
+ super().__init__(config)
+ self.unispeech = UniSpeechModel(config)
+ self.dropout_features = nn.Dropout(config.feat_quantizer_dropout)
+
+ self.quantizer = UniSpeechGumbelVectorQuantizer(config)
+ self.project_q = nn.Linear(config.codevector_dim, config.proj_codevector_dim)
+ self.project_hid = nn.Linear(config.proj_codevector_dim, config.hidden_size)
+
+ self.ctc_proj = nn.Linear(config.hidden_size, config.num_ctc_classes)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def set_gumbel_temperature(self, temperature: int):
+ """
+ Set the Gumbel softmax temperature to a given value. Only necessary for training
+ """
+ self.quantizer.temperature = temperature
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech.feature_extractor._freeze_parameters()
+
+ @staticmethod
+ def compute_contrastive_logits(
+ target_features: torch.FloatTensor,
+ negative_features: torch.FloatTensor,
+ predicted_features: torch.FloatTensor,
+ temperature: int = 1,
+ ):
+ """
+ Compute logits for contrastive loss based using cosine similarity as the distance measure between
+ `[positive_feature, negative_features]` and `[predicted_features]`. Additionally, temperature can be applied.
+ """
+ target_features = torch.cat([target_features, negative_features], dim=0)
+
+ logits = torch.cosine_similarity(predicted_features.float(), target_features.float(), dim=-1)
+ logits = logits.type_as(target_features)
+
+ # apply temperature
+ logits = logits / temperature
+ return logits
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechForPreTrainingOutput]:
+ r"""
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, UniSpeechForPreTraining
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("microsoft/unispeech-large-1500h-cv")
+ >>> model = UniSpeechForPreTraining.from_pretrained("microsoft/unispeech-large-1500h-cv")
+ >>> # TODO: Add full pretraining example
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.unispeech(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ transformer_features = outputs[0]
+
+ # quantize all (unmasked) extracted features and project to final vq dim
+ extract_features = self.dropout_features(outputs[1])
+ quantized_features, codevector_perplexity = self.quantizer(extract_features)
+
+ # project quantized features twice
+ quantized_features = self.project_q(quantized_features.to(self.project_q.weight.dtype))
+ quantized_features = self.project_hid(quantized_features)
+
+ prob_replace_matrix = torch.empty(transformer_features.size(0), transformer_features.size(1)).fill_(
+ self.config.replace_prob
+ )
+ prob_replace_matrix = prob_replace_matrix.transpose(0, 1)
+ sampled_replace_matrix = torch.bernoulli(prob_replace_matrix).bool().to(transformer_features.device)
+ sampled_replace_matrix = sampled_replace_matrix.transpose(0, 1)
+ sampled_replace_matrix = sampled_replace_matrix.unsqueeze(-1)
+ logits = transformer_features.masked_fill(sampled_replace_matrix, 0.0) + (
+ quantized_features.masked_fill(~sampled_replace_matrix, 0.0)
+ )
+
+ # project to ctc units
+ logits = self.dropout(logits)
+ logits = self.ctc_proj(logits)
+
+ # TODO(PVP) - add negative sampling & loss computation
+ loss = None
+ if not return_dict:
+ if loss is not None:
+ return (loss, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+ return (transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+
+ return UniSpeechForPreTrainingOutput(
+ loss=loss,
+ projected_states=transformer_features,
+ projected_quantized_states=quantized_features,
+ codevector_perplexity=codevector_perplexity,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeech Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).
+ """
+)
+class UniSpeechForCTC(UniSpeechPreTrainedModel):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`UniSpeechForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ self.unispeech = UniSpeechModel(config)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.target_lang = target_lang
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that "
+ "does not define the vocabulary size of the language model head. Please "
+ "instantiate the model as follows: `UniSpeechForCTC.from_pretrained(..., vocab_size=vocab_size)`. "
+ "or define `vocab_size` of your model's configuration."
+ )
+ output_hidden_size = (
+ config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size
+ )
+ self.lm_head = nn.Linear(output_hidden_size, config.vocab_size)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def tie_weights(self):
+ """
+ This method overwrites [`~PreTrainedModel.tie_weights`] so that adapter weights can be correctly loaded when
+ passing `target_lang=...` to `from_pretrained(...)`.
+
+ This method is **not** supposed to be called by the user and is prone to be changed in the future.
+ """
+
+ # Note that `tie_weights` is usually used to tie input and output embedding weights. The method is re-purposed to
+ # correctly load adapter layers for UniSpeech so that we do not have to introduce a new API to
+ # [`PreTrainedModel`]. While slightly hacky, UniSpeech never has to tie input and output embeddings, so that it is
+ # ok to repurpose this function here.
+ target_lang = self.target_lang
+
+ if target_lang is not None and getattr(self.config, "adapter_attn_dim", None) is None:
+ raise ValueError(f"Cannot pass `target_lang`: {target_lang} if `config.adapter_attn_dim` is not defined.")
+ elif target_lang is None and getattr(self.config, "adapter_attn_dim", None) is not None:
+ logger.info("By default `target_lang` is set to 'eng'.")
+ elif target_lang is not None:
+ self.load_adapter(target_lang, force_load=True)
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.unispeech.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*):
+ Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to
+ the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`.
+ All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None and labels.max() >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ outputs = self.unispeech(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+
+ logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # retrieve loss input_lengths from attention_mask
+ attention_mask = (
+ attention_mask if attention_mask is not None else torch.ones_like(input_values, dtype=torch.long)
+ )
+ input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long)
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = labels >= 0
+ target_lengths = labels_mask.sum(-1)
+ flattened_targets = labels.masked_select(labels_mask)
+
+ # ctc_loss doesn't support fp16
+ log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1)
+
+ with torch.backends.cudnn.flags(enabled=False):
+ loss = nn.functional.ctc_loss(
+ log_probs,
+ flattened_targets,
+ input_lengths,
+ target_lengths,
+ blank=self.config.pad_token_id,
+ reduction=self.config.ctc_loss_reduction,
+ zero_infinity=self.config.ctc_zero_infinity,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return CausalLMOutput(
+ loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeech Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like
+ SUPERB Keyword Spotting.
+ """
+)
+class UniSpeechForSequenceClassification(UniSpeechPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Sequence classification does not support the use of UniSpeech adapters (config.add_adapter=True)"
+ )
+ self.unispeech = UniSpeechModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size)
+ self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.unispeech.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`UniSpeechProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.unispeech(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = hidden_states.mean(dim=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask)
+ expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_padding_mask] = 0.0
+ pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "UniSpeechForCTC",
+ "UniSpeechForPreTraining",
+ "UniSpeechForSequenceClassification",
+ "UniSpeechModel",
+ "UniSpeechPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/modular_unispeech.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/modular_unispeech.py
new file mode 100644
index 0000000000000000000000000000000000000000..900079b7bb9b469f562bab3be8ea3605f03bd0f4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech/modular_unispeech.py
@@ -0,0 +1,445 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch UniSpeech model."""
+
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.nn as nn
+
+from ...modeling_outputs import ModelOutput, Wav2Vec2BaseModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ..wav2vec2.modeling_wav2vec2 import (
+ Wav2Vec2Encoder,
+ Wav2Vec2EncoderStableLayerNorm,
+ Wav2Vec2FeatureEncoder,
+ Wav2Vec2FeatureProjection,
+ Wav2Vec2ForCTC,
+ Wav2Vec2ForSequenceClassification,
+ Wav2Vec2GumbelVectorQuantizer,
+ Wav2Vec2Model,
+ Wav2Vec2PositionalConvEmbedding,
+)
+from .configuration_unispeech import UniSpeechConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`UniSpeechForPreTrainingOutput`], with potential hidden states and attentions.
+ """
+)
+class UniSpeechForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when model is in train mode, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ projected_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ codevector_perplexity (`torch.FloatTensor` of shape `(1,)`):
+ The perplexity of the codevector distribution, used to measure the diversity of the codebook.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ projected_states: Optional[torch.FloatTensor] = None
+ projected_quantized_states: Optional[torch.FloatTensor] = None
+ codevector_perplexity: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+class UniSpeechPositionalConvEmbedding(Wav2Vec2PositionalConvEmbedding):
+ pass
+
+
+class UniSpeechFeatureEncoder(Wav2Vec2FeatureEncoder):
+ pass
+
+
+class UniSpeechFeatureProjection(Wav2Vec2FeatureProjection):
+ pass
+
+
+class UniSpeechEncoder(Wav2Vec2Encoder):
+ pass
+
+
+class UniSpeechEncoderStableLayerNorm(Wav2Vec2EncoderStableLayerNorm):
+ pass
+
+
+class UniSpeechGumbelVectorQuantizer(Wav2Vec2GumbelVectorQuantizer):
+ @staticmethod
+ def _compute_perplexity(probs):
+ marginal_probs = probs.mean(dim=0)
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(
+ hidden_states.float(), tau=self.temperature, hard=True
+ ).type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(*hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+@auto_docstring
+class UniSpeechPreTrainedModel(PreTrainedModel):
+ config: UniSpeechConfig
+ base_model_prefix = "unispeech"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # gumbel softmax requires special init
+ if isinstance(module, UniSpeechGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, UniSpeechPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, UniSpeechFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths).to(torch.long)
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+UniSpeechBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+class UniSpeechModel(UniSpeechPreTrainedModel, Wav2Vec2Model):
+ def __init__(self, config: UniSpeechConfig):
+ UniSpeechPreTrainedModel.__init__(self, config)
+ self.config = config
+ self.feature_extractor = UniSpeechFeatureEncoder(config)
+ self.feature_projection = UniSpeechFeatureProjection(config)
+
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ if config.do_stable_layer_norm:
+ self.encoder = UniSpeechEncoderStableLayerNorm(config)
+ else:
+ self.encoder = UniSpeechEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for UniSpeech")
+
+ def freeze_feature_encoder(self):
+ raise AttributeError("Not needed for UniSpeech")
+
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(extract_features.shape[1], attention_mask)
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return UniSpeechBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeech Model with a vector-quantization module and ctc loss for pre-training.
+ """
+)
+class UniSpeechForPreTraining(UniSpeechPreTrainedModel):
+ def __init__(self, config: UniSpeechConfig):
+ super().__init__(config)
+ self.unispeech = UniSpeechModel(config)
+ self.dropout_features = nn.Dropout(config.feat_quantizer_dropout)
+
+ self.quantizer = UniSpeechGumbelVectorQuantizer(config)
+ self.project_q = nn.Linear(config.codevector_dim, config.proj_codevector_dim)
+ self.project_hid = nn.Linear(config.proj_codevector_dim, config.hidden_size)
+
+ self.ctc_proj = nn.Linear(config.hidden_size, config.num_ctc_classes)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def set_gumbel_temperature(self, temperature: int):
+ """
+ Set the Gumbel softmax temperature to a given value. Only necessary for training
+ """
+ self.quantizer.temperature = temperature
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech.feature_extractor._freeze_parameters()
+
+ @staticmethod
+ def compute_contrastive_logits(
+ target_features: torch.FloatTensor,
+ negative_features: torch.FloatTensor,
+ predicted_features: torch.FloatTensor,
+ temperature: int = 1,
+ ):
+ """
+ Compute logits for contrastive loss based using cosine similarity as the distance measure between
+ `[positive_feature, negative_features]` and `[predicted_features]`. Additionally, temperature can be applied.
+ """
+ target_features = torch.cat([target_features, negative_features], dim=0)
+
+ logits = torch.cosine_similarity(predicted_features.float(), target_features.float(), dim=-1)
+ logits = logits.type_as(target_features)
+
+ # apply temperature
+ logits = logits / temperature
+ return logits
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechForPreTrainingOutput]:
+ r"""
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, UniSpeechForPreTraining
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("microsoft/unispeech-large-1500h-cv")
+ >>> model = UniSpeechForPreTraining.from_pretrained("microsoft/unispeech-large-1500h-cv")
+ >>> # TODO: Add full pretraining example
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.unispeech(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ transformer_features = outputs[0]
+
+ # quantize all (unmasked) extracted features and project to final vq dim
+ extract_features = self.dropout_features(outputs[1])
+ quantized_features, codevector_perplexity = self.quantizer(extract_features)
+
+ # project quantized features twice
+ quantized_features = self.project_q(quantized_features.to(self.project_q.weight.dtype))
+ quantized_features = self.project_hid(quantized_features)
+
+ prob_replace_matrix = torch.empty(transformer_features.size(0), transformer_features.size(1)).fill_(
+ self.config.replace_prob
+ )
+ prob_replace_matrix = prob_replace_matrix.transpose(0, 1)
+ sampled_replace_matrix = torch.bernoulli(prob_replace_matrix).bool().to(transformer_features.device)
+ sampled_replace_matrix = sampled_replace_matrix.transpose(0, 1)
+ sampled_replace_matrix = sampled_replace_matrix.unsqueeze(-1)
+ logits = transformer_features.masked_fill(sampled_replace_matrix, 0.0) + (
+ quantized_features.masked_fill(~sampled_replace_matrix, 0.0)
+ )
+
+ # project to ctc units
+ logits = self.dropout(logits)
+ logits = self.ctc_proj(logits)
+
+ # TODO(PVP) - add negative sampling & loss computation
+ loss = None
+ if not return_dict:
+ if loss is not None:
+ return (loss, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+ return (transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+
+ return UniSpeechForPreTrainingOutput(
+ loss=loss,
+ projected_states=transformer_features,
+ projected_quantized_states=quantized_features,
+ codevector_perplexity=codevector_perplexity,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class UniSpeechForCTC(Wav2Vec2ForCTC):
+ pass
+
+
+class UniSpeechForSequenceClassification(Wav2Vec2ForSequenceClassification):
+ pass
+
+
+__all__ = [
+ "UniSpeechForCTC",
+ "UniSpeechForPreTraining",
+ "UniSpeechForSequenceClassification",
+ "UniSpeechModel",
+ "UniSpeechPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..cc3144ed17d14cd7db2b93b05d21d0a0e3ffe3d0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_unispeech_sat import *
+ from .modeling_unispeech_sat import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/configuration_unispeech_sat.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/configuration_unispeech_sat.py
new file mode 100644
index 0000000000000000000000000000000000000000..2bebff802e8a72b46cfe863df60ec99cd277f929
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/configuration_unispeech_sat.py
@@ -0,0 +1,327 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""UniSpeechSat model configuration"""
+
+import functools
+import operator
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class UniSpeechSatConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`UniSpeechSatModel`]. It is used to instantiate an
+ UniSpeechSat model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the UniSpeechSat
+ [microsoft/unispeech-sat-base-100h-libri-ft](https://huggingface.co/microsoft/unispeech-sat-base-100h-libri-ft)
+ architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32):
+ Vocabulary size of the UniSpeechSat model. Defines the number of different tokens that can be represented
+ by the `inputs_ids` passed when calling [`UniSpeechSatModel`]. Vocabulary size of the model. Defines the
+ different tokens that can be represented by the *inputs_ids* passed to the forward method of
+ [`UniSpeechSatModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for activations inside the fully connected layer.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ feat_proj_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for output of the feature encoder.
+ feat_quantizer_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the output of the feature encoder that's used by the quantizer.
+ final_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the final projection layer of [`UniSpeechSatForCTC`].
+ layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) for more
+ details.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the layer normalization layers.
+ feat_extract_norm (`str`, *optional*, defaults to `"group"`):
+ The norm to be applied to 1D convolutional layers in feature encoder. One of `"group"` for group
+ normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D
+ convolutional layers.
+ feat_extract_activation (`str, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the 1D convolutional layers of the feature
+ extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 512, 512, 512)`):
+ A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the
+ feature encoder. The length of *conv_dim* defines the number of 1D convolutional layers.
+ conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 2, 2, 2, 2, 2)`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the feature encoder. The length
+ of *conv_stride* defines the number of convolutional layers and has to match the length of *conv_dim*.
+ conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 3, 3, 3, 2, 2)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the feature encoder. The
+ length of *conv_kernel* defines the number of convolutional layers and has to match the length of
+ *conv_dim*.
+ conv_bias (`bool`, *optional*, defaults to `False`):
+ Whether the 1D convolutional layers have a bias.
+ num_conv_pos_embeddings (`int`, *optional*, defaults to 128):
+ Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional
+ embeddings layer.
+ num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16):
+ Number of groups of 1D convolutional positional embeddings layer.
+ do_stable_layer_norm (`bool`, *optional*, defaults to `False`):
+ Whether to apply *stable* layer norm architecture of the Transformer encoder. `do_stable_layer_norm is
+ True` corresponds to applying layer norm before the attention layer, whereas `do_stable_layer_norm is
+ False` corresponds to applying layer norm after the attention layer.
+ apply_spec_augment (`bool`, *optional*, defaults to `True`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see
+ [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking
+ procedure generates ''mask_time_prob*len(time_axis)/mask_time_length'' independent masks over the axis. If
+ reasoning from the probability of each feature vector to be chosen as the start of the vector span to be
+ masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the
+ actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2):
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks''
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The
+ masking procedure generates ''mask_feature_prob*len(feature_axis)/mask_time_length'' independent masks over
+ the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector
+ span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap
+ may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is
+ True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ mask_feature_min_masks (`int`, *optional*, defaults to 0):
+ The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time
+ step, irrespectively of `mask_feature_prob`. Only relevant if
+ ''mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks''
+ num_codevectors_per_group (`int`, *optional*, defaults to 320):
+ Number of entries in each quantization codebook (group).
+ num_codevector_groups (`int`, *optional*, defaults to 2):
+ Number of codevector groups for product codevector quantization.
+ contrastive_logits_temperature (`float`, *optional*, defaults to 0.1):
+ The temperature *kappa* in the contrastive loss.
+ num_negatives (`int`, *optional*, defaults to 100):
+ Number of negative samples for the contrastive loss.
+ codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the quantized feature vectors.
+ proj_codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the final projection of both the quantized and the transformer features.
+ diversity_loss_weight (`int`, *optional*, defaults to 0.1):
+ The weight of the codebook diversity loss component.
+ ctc_loss_reduction (`str`, *optional*, defaults to `"mean"`):
+ Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an
+ instance of [`UniSpeechSatForCTC`].
+ ctc_zero_infinity (`bool`, *optional*, defaults to `False`):
+ Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly
+ occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance
+ of [`UniSpeechSatForCTC`].
+ use_weighted_layer_sum (`bool`, *optional*, defaults to `False`):
+ Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an
+ instance of [`UniSpeechSatForSequenceClassification`].
+ classifier_proj_size (`int`, *optional*, defaults to 256):
+ Dimensionality of the projection before token mean-pooling for classification.
+ tdnn_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 1500)`):
+ A tuple of integers defining the number of output channels of each 1D convolutional layer in the *TDNN*
+ module of the *XVector* model. The length of *tdnn_dim* defines the number of *TDNN* layers.
+ tdnn_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 3, 3, 1, 1)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the *TDNN* module of the
+ *XVector* model. The length of *tdnn_kernel* has to match the length of *tdnn_dim*.
+ tdnn_dilation (`tuple[int]` or `list[int]`, *optional*, defaults to `(1, 2, 3, 1, 1)`):
+ A tuple of integers defining the dilation factor of each 1D convolutional layer in *TDNN* module of the
+ *XVector* model. The length of *tdnn_dilation* has to match the length of *tdnn_dim*.
+ xvector_output_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of the *XVector* embedding vectors.
+ pad_token_id (`int`, *optional*, defaults to 0):
+ The id of the padding token.
+ bos_token_id (`int`, *optional*, defaults to 1):
+ The id of the "beginning-of-sequence" token.
+ eos_token_id (`int`, *optional*, defaults to 2):
+ The id of the "end-of-sequence" token.
+ num_clusters (`int`, *optional*, defaults to 504):
+ Number of clusters for weak labeling. Only relevant when using an instance of
+ [`UniSpeechSatForPreTraining`].
+
+ Example:
+
+ ```python
+ >>> from transformers import UniSpeechSatModel, UniSpeechSatConfig
+
+ >>> # Initializing a UniSpeechSat microsoft/unispeech-sat-base-100h-libri-ft style configuration
+ >>> configuration = UniSpeechSatConfig()
+
+ >>> # Initializing a model from the microsoft/unispeech-sat-base-100h-libri-ft style configuration
+ >>> model = UniSpeechSatModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "unispeech-sat"
+
+ def __init__(
+ self,
+ vocab_size=32,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout=0.1,
+ activation_dropout=0.1,
+ attention_dropout=0.1,
+ feat_proj_dropout=0.0,
+ feat_quantizer_dropout=0.0,
+ final_dropout=0.1,
+ layerdrop=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ feat_extract_norm="group",
+ feat_extract_activation="gelu",
+ conv_dim=(512, 512, 512, 512, 512, 512, 512),
+ conv_stride=(5, 2, 2, 2, 2, 2, 2),
+ conv_kernel=(10, 3, 3, 3, 3, 2, 2),
+ conv_bias=False,
+ num_conv_pos_embeddings=128,
+ num_conv_pos_embedding_groups=16,
+ do_stable_layer_norm=False,
+ apply_spec_augment=True,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ mask_feature_min_masks=0,
+ num_codevectors_per_group=320,
+ num_codevector_groups=2,
+ contrastive_logits_temperature=0.1,
+ num_negatives=100,
+ codevector_dim=256,
+ proj_codevector_dim=256,
+ diversity_loss_weight=0.1,
+ ctc_loss_reduction="mean",
+ ctc_zero_infinity=False,
+ use_weighted_layer_sum=False,
+ classifier_proj_size=256,
+ tdnn_dim=(512, 512, 512, 512, 1500),
+ tdnn_kernel=(5, 3, 3, 1, 1),
+ tdnn_dilation=(1, 2, 3, 1, 1),
+ xvector_output_dim=512,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ num_clusters=504,
+ **kwargs,
+ ):
+ super().__init__(**kwargs, pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id)
+ self.hidden_size = hidden_size
+ self.feat_extract_norm = feat_extract_norm
+ self.feat_extract_activation = feat_extract_activation
+ self.conv_dim = list(conv_dim)
+ self.conv_stride = list(conv_stride)
+ self.conv_kernel = list(conv_kernel)
+ self.conv_bias = conv_bias
+ self.num_conv_pos_embeddings = num_conv_pos_embeddings
+ self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups
+ self.num_feat_extract_layers = len(self.conv_dim)
+ self.num_hidden_layers = num_hidden_layers
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.num_attention_heads = num_attention_heads
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.feat_proj_dropout = feat_proj_dropout
+ self.final_dropout = final_dropout
+ self.layerdrop = layerdrop
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.vocab_size = vocab_size
+ self.num_clusters = num_clusters
+ self.do_stable_layer_norm = do_stable_layer_norm
+ self.use_weighted_layer_sum = use_weighted_layer_sum
+
+ if (
+ (len(self.conv_stride) != self.num_feat_extract_layers)
+ or (len(self.conv_kernel) != self.num_feat_extract_layers)
+ or (len(self.conv_dim) != self.num_feat_extract_layers)
+ ):
+ raise ValueError(
+ "Configuration for convolutional layers is incorrect. It is required that `len(config.conv_dim)` =="
+ " `len(config.conv_stride)` == `len(config.conv_kernel)`, but is `len(config.conv_dim) ="
+ f" {len(self.conv_dim)}`, `len(config.conv_stride) = {len(self.conv_stride)}`,"
+ f" `len(config.conv_kernel) = {len(self.conv_kernel)}`."
+ )
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+ self.mask_feature_min_masks = mask_feature_min_masks
+
+ # parameters for pretraining with codevector quantized representations
+ self.num_codevectors_per_group = num_codevectors_per_group
+ self.num_codevector_groups = num_codevector_groups
+ self.contrastive_logits_temperature = contrastive_logits_temperature
+ self.feat_quantizer_dropout = feat_quantizer_dropout
+ self.num_negatives = num_negatives
+ self.codevector_dim = codevector_dim
+ self.proj_codevector_dim = proj_codevector_dim
+ self.diversity_loss_weight = diversity_loss_weight
+
+ # ctc loss
+ self.ctc_loss_reduction = ctc_loss_reduction
+ self.ctc_zero_infinity = ctc_zero_infinity
+
+ # SequenceClassification-specific parameter. Feel free to ignore for other classes.
+ self.classifier_proj_size = classifier_proj_size
+
+ # XVector-specific parameters. Feel free to ignore for other classes.
+ self.tdnn_dim = list(tdnn_dim)
+ self.tdnn_kernel = list(tdnn_kernel)
+ self.tdnn_dilation = list(tdnn_dilation)
+ self.xvector_output_dim = xvector_output_dim
+
+ @property
+ def inputs_to_logits_ratio(self):
+ return functools.reduce(operator.mul, self.conv_stride, 1)
+
+
+__all__ = ["UniSpeechSatConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/modeling_unispeech_sat.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/modeling_unispeech_sat.py
new file mode 100644
index 0000000000000000000000000000000000000000..c1281f7955afa8ee7c93b1248500ee17815269de
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/modeling_unispeech_sat.py
@@ -0,0 +1,1826 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/unispeech_sat/modular_unispeech_sat.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_unispeech_sat.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import numpy as np
+import torch
+import torch.nn as nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask, _prepare_4d_attention_mask_for_sdpa
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ CausalLMOutput,
+ ModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+ Wav2Vec2BaseModelOutput,
+ XVectorOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import auto_docstring, is_peft_available, is_torch_flex_attn_available, logging
+from .configuration_unispeech_sat import UniSpeechSatConfig
+
+
+if is_torch_flex_attn_available():
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`UniSpeechSatForPreTrainingOutput`], with potential hidden states and attentions.
+ """
+)
+class UniSpeechSatForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when model is in train mode, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`, *optional*):
+ Prediction scores of the contrastive loss model, i.e. the output of the model before the final softmax.
+ projected_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ codevector_perplexity (`torch.FloatTensor` of shape `(1,)`):
+ The perplexity of the codevector distribution, used to measure the diversity of the codebook.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ projected_states: Optional[torch.FloatTensor] = None
+ projected_quantized_states: Optional[torch.FloatTensor] = None
+ codevector_perplexity: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+class UniSpeechSatSamePadLayer(nn.Module):
+ def __init__(self, num_conv_pos_embeddings):
+ super().__init__()
+ self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0
+
+ def forward(self, hidden_states):
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, :, : -self.num_pad_remove]
+ return hidden_states
+
+
+class UniSpeechSatPositionalConvEmbedding(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=config.num_conv_pos_embeddings,
+ padding=config.num_conv_pos_embeddings // 2,
+ groups=config.num_conv_pos_embedding_groups,
+ )
+
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0):
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+ if hasattr(self.conv, "parametrizations"):
+ weight_g = self.conv.parametrizations.weight.original0
+ weight_v = self.conv.parametrizations.weight.original1
+ else:
+ weight_g = self.conv.weight_g
+ weight_v = self.conv.weight_v
+ deepspeed.zero.register_external_parameter(self, weight_v)
+ deepspeed.zero.register_external_parameter(self, weight_g)
+ else:
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+
+ self.padding = UniSpeechSatSamePadLayer(config.num_conv_pos_embeddings)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.padding(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class UniSpeechSatNoLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class UniSpeechSatLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+
+ hidden_states = hidden_states.transpose(-2, -1)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states.transpose(-2, -1)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class UniSpeechSatGroupNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class UniSpeechSatFeatureEncoder(nn.Module):
+ """Construct the features from raw audio waveform"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ if config.feat_extract_norm == "group":
+ conv_layers = [UniSpeechSatGroupNormConvLayer(config, layer_id=0)] + [
+ UniSpeechSatNoLayerNormConvLayer(config, layer_id=i + 1)
+ for i in range(config.num_feat_extract_layers - 1)
+ ]
+ elif config.feat_extract_norm == "layer":
+ conv_layers = [
+ UniSpeechSatLayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)
+ ]
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']"
+ )
+ self.conv_layers = nn.ModuleList(conv_layers)
+ self.gradient_checkpointing = False
+ self._requires_grad = True
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def forward(self, input_values):
+ hidden_states = input_values[:, None]
+
+ # make sure hidden_states require grad for gradient_checkpointing
+ if self._requires_grad and self.training:
+ hidden_states.requires_grad = True
+
+ for conv_layer in self.conv_layers:
+ hidden_states = conv_layer(hidden_states)
+
+ return hidden_states
+
+
+class UniSpeechSatFeatureProjection(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps)
+ self.projection = nn.Linear(config.conv_dim[-1], config.hidden_size)
+ self.dropout = nn.Dropout(config.feat_proj_dropout)
+
+ def forward(self, hidden_states):
+ # non-projected hidden states are needed for quantization
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states, norm_hidden_states
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: Optional[float] = None,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ if scaling is None:
+ scaling = query.size(-1) ** -0.5
+
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class UniSpeechSatAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ is_causal: bool = False,
+ config: Optional[UniSpeechSatConfig] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ self.config = config
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.is_causal = is_causal
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ # TODO: we need a refactor so that the different attention modules can get their specific kwargs
+ # ATM, we have mixed things encoder, decoder, and encoder-decoder attn
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ # determine input shapes
+ bsz, tgt_len = hidden_states.shape[:-1]
+ src_len = key_value_states.shape[1] if is_cross_attention else tgt_len
+
+ q_input_shape = (bsz, tgt_len, -1, self.head_dim)
+ kv_input_shape = (bsz, src_len, -1, self.head_dim)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2)
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ key_states = self.k_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+ value_states = self.v_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.dropout,
+ scaling=self.scaling,
+ output_attentions=output_attentions,
+ head_mask=layer_head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights, None
+
+
+class UniSpeechSatFeedForward(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.intermediate_dropout = nn.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ self.output_dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.output_dropout = nn.Dropout(config.hidden_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states)
+ return hidden_states
+
+
+class UniSpeechSatEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = UniSpeechSatAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ config=config,
+ )
+
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = UniSpeechSatFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, output_attentions=False):
+ attn_residual = hidden_states
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class UniSpeechSatEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = UniSpeechSatPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList([UniSpeechSatEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ hidden_states,
+ )
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+
+class UniSpeechSatAttnAdapterLayer(nn.Module):
+ def __init__(self, config):
+ """
+ Implements adapter modules directly with 3D tensor weight as parameters and without using ModuleList to speed
+ up training throughput.
+ """
+ super().__init__()
+ self.input_dim = config.adapter_attn_dim
+ self.hidden_dim = config.hidden_size
+
+ self.norm = nn.LayerNorm(self.hidden_dim)
+ self.linear_1 = nn.Linear(self.hidden_dim, self.input_dim)
+ self.act_fn = nn.ReLU()
+ self.linear_2 = nn.Linear(self.input_dim, self.hidden_dim)
+
+ def forward(self, hidden_states: torch.FloatTensor):
+ hidden_states = self.norm(hidden_states)
+
+ hidden_states = self.linear_1(hidden_states)
+ hidden_states = self.act_fn(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+
+ return hidden_states
+
+
+class UniSpeechSatEncoderLayerStableLayerNorm(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = UniSpeechSatAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ config=config,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = UniSpeechSatFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ if getattr(config, "adapter_attn_dim", None) is not None:
+ self.adapter_layer = UniSpeechSatAttnAdapterLayer(config)
+ else:
+ self.adapter_layer = None
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ attn_residual = hidden_states
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+ hidden_states = hidden_states + self.feed_forward(self.final_layer_norm(hidden_states))
+
+ if self.adapter_layer is not None:
+ hidden_states = hidden_states + self.adapter_layer(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class UniSpeechSatEncoderStableLayerNorm(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = UniSpeechSatPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList(
+ [UniSpeechSatEncoderLayerStableLayerNorm(config) for _ in range(config.num_hidden_layers)]
+ )
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ hidden_states,
+ )
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ # XXX: could optimize this like synced_gpus in generate_utils but not sure if it's worth the code complication
+ layer_outputs = layer(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+
+class UniSpeechSatGumbelVectorQuantizer(nn.Module):
+ """
+ Vector quantization using gumbel softmax. See `[CATEGORICAL REPARAMETERIZATION WITH
+ GUMBEL-SOFTMAX](https://huggingface.co/papers/1611.01144) for more information.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.num_groups = config.num_codevector_groups
+ self.num_vars = config.num_codevectors_per_group
+
+ if config.codevector_dim % self.num_groups != 0:
+ raise ValueError(
+ f"`config.codevector_dim {config.codevector_dim} must be divisible "
+ f"by `config.num_codevector_groups` {self.num_groups} for concatenation"
+ )
+
+ # storage for codebook variables (codewords)
+ self.codevectors = nn.Parameter(
+ torch.FloatTensor(1, self.num_groups * self.num_vars, config.codevector_dim // self.num_groups)
+ )
+ self.weight_proj = nn.Linear(config.hidden_size, self.num_groups * self.num_vars)
+
+ # can be decayed for training
+ self.temperature = 2
+
+ @staticmethod
+ def _compute_perplexity(probs, mask=None):
+ marginal_probs = probs.mean(dim=0)
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(
+ hidden_states.float(), tau=self.temperature, hard=True
+ ).type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(*hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+@auto_docstring
+class UniSpeechSatPreTrainedModel(PreTrainedModel):
+ config: UniSpeechSatConfig
+ base_model_prefix = "unispeech_sat"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # gumbel softmax requires special init
+ if isinstance(module, UniSpeechSatGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, UniSpeechSatPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, UniSpeechSatFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths).to(torch.long)
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+UniSpeechSatBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+@auto_docstring
+class UniSpeechSatModel(UniSpeechSatPreTrainedModel):
+ def __init__(self, config: UniSpeechSatConfig):
+ super().__init__(config)
+ self.config = config
+ self.feature_extractor = UniSpeechSatFeatureEncoder(config)
+ self.feature_projection = UniSpeechSatFeatureProjection(config)
+
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ if config.do_stable_layer_norm:
+ self.encoder = UniSpeechSatEncoderStableLayerNorm(config)
+ else:
+ self.encoder = UniSpeechSatEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _mask_hidden_states(
+ self,
+ hidden_states: torch.FloatTensor,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+ elif self.config.mask_time_prob > 0 and self.training:
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool)
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool)
+ mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1)
+ hidden_states[mask_feature_indices] = 0
+
+ return hidden_states
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechSatBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(extract_features.shape[1], attention_mask)
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return UniSpeechSatBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeechSat Model with a vector-quantization module and ctc loss for pre-training.
+ """
+)
+class UniSpeechSatForPreTraining(UniSpeechSatPreTrainedModel):
+ def __init__(self, config: UniSpeechSatConfig):
+ super().__init__(config)
+ self.unispeech_sat = UniSpeechSatModel(config)
+ self.dropout_features = nn.Dropout(config.feat_quantizer_dropout)
+
+ self.quantizer = UniSpeechSatGumbelVectorQuantizer(config)
+ self.project_q = nn.Linear(config.codevector_dim, config.proj_codevector_dim)
+ self.project_hid = nn.Linear(config.hidden_size, config.proj_codevector_dim)
+
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.speaker_proj = nn.Linear(config.hidden_size, config.codevector_dim)
+ self.label_embeddings_concat = nn.Parameter(torch.FloatTensor(config.num_clusters, config.codevector_dim))
+ self.label_embeddings_concat.data.zero_()
+
+ self.layer_norm_for_extract = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ if self.config.do_stable_layer_norm:
+ self.layer_norm_for_extract.requires_grad = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def set_gumbel_temperature(self, temperature: int):
+ """
+ Set the Gumbel softmax temperature to a given value. Only necessary for training
+ """
+ self.quantizer.temperature = temperature
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech_sat.feature_extractor._freeze_parameters()
+
+ @staticmethod
+ def compute_contrastive_logits(
+ target_features: torch.FloatTensor,
+ negative_features: torch.FloatTensor,
+ predicted_features: torch.FloatTensor,
+ temperature: int = 1,
+ ):
+ """
+ Compute logits for contrastive loss based using cosine similarity as the distance measure between
+ `[positive_feature, negative_features]` and `[predicted_features]`. Additionally, temperature can be applied.
+ """
+ target_features = torch.cat([target_features, negative_features], dim=0)
+
+ logits = torch.cosine_similarity(predicted_features.float(), target_features.float(), dim=-1)
+ logits = logits.type_as(target_features)
+
+ # apply temperature
+ logits = logits / temperature
+ return logits
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechSatForPreTrainingOutput]:
+ r"""
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, UniSpeechSatForPreTraining
+ >>> from transformers.models.unispeech_sat.modeling_unispeech_sat import _compute_mask_indices
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("microsoft/unispeech-sat-base")
+ >>> model = UniSpeechSatForPreTraining.from_pretrained("microsoft/unispeech-sat-base")
+ >>> # TODO: Add full pretraining example
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.unispeech_sat(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ transformer_features = outputs[0]
+
+ # quantize all (unmasked) extracted features and project to final vq dim
+ extract_features = self.dropout_features(outputs[1])
+
+ # TODO(PVP) - add pretraining logic and add to tests
+ logits = extract_features
+ loss = quantized_features = codevector_perplexity = None
+
+ if not return_dict:
+ if loss is not None:
+ return (loss, logits, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+ return (logits, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+
+ return UniSpeechSatForPreTrainingOutput(
+ loss=loss,
+ logits=logits,
+ projected_states=transformer_features,
+ projected_quantized_states=quantized_features,
+ codevector_perplexity=codevector_perplexity,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeechSat Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).
+ """
+)
+class UniSpeechSatForCTC(UniSpeechSatPreTrainedModel):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`UniSpeechSatForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ self.unispeech_sat = UniSpeechSatModel(config)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.target_lang = target_lang
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that "
+ "does not define the vocabulary size of the language model head. Please "
+ "instantiate the model as follows: `UniSpeechSatForCTC.from_pretrained(..., vocab_size=vocab_size)`. "
+ "or define `vocab_size` of your model's configuration."
+ )
+ output_hidden_size = (
+ config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size
+ )
+ self.lm_head = nn.Linear(output_hidden_size, config.vocab_size)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def tie_weights(self):
+ """
+ This method overwrites [`~PreTrainedModel.tie_weights`] so that adapter weights can be correctly loaded when
+ passing `target_lang=...` to `from_pretrained(...)`.
+
+ This method is **not** supposed to be called by the user and is prone to be changed in the future.
+ """
+
+ # Note that `tie_weights` is usually used to tie input and output embedding weights. The method is re-purposed to
+ # correctly load adapter layers for UniSpeechSat so that we do not have to introduce a new API to
+ # [`PreTrainedModel`]. While slightly hacky, UniSpeechSat never has to tie input and output embeddings, so that it is
+ # ok to repurpose this function here.
+ target_lang = self.target_lang
+
+ if target_lang is not None and getattr(self.config, "adapter_attn_dim", None) is None:
+ raise ValueError(f"Cannot pass `target_lang`: {target_lang} if `config.adapter_attn_dim` is not defined.")
+ elif target_lang is None and getattr(self.config, "adapter_attn_dim", None) is not None:
+ logger.info("By default `target_lang` is set to 'eng'.")
+ elif target_lang is not None:
+ self.load_adapter(target_lang, force_load=True)
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech_sat.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.unispeech_sat.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*):
+ Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to
+ the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`.
+ All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None and labels.max() >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ outputs = self.unispeech_sat(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+
+ logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # retrieve loss input_lengths from attention_mask
+ attention_mask = (
+ attention_mask if attention_mask is not None else torch.ones_like(input_values, dtype=torch.long)
+ )
+ input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long)
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = labels >= 0
+ target_lengths = labels_mask.sum(-1)
+ flattened_targets = labels.masked_select(labels_mask)
+
+ # ctc_loss doesn't support fp16
+ log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1)
+
+ with torch.backends.cudnn.flags(enabled=False):
+ loss = nn.functional.ctc_loss(
+ log_probs,
+ flattened_targets,
+ input_lengths,
+ target_lengths,
+ blank=self.config.pad_token_id,
+ reduction=self.config.ctc_loss_reduction,
+ zero_infinity=self.config.ctc_zero_infinity,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return CausalLMOutput(
+ loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeechSat Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like
+ SUPERB Keyword Spotting.
+ """
+)
+class UniSpeechSatForSequenceClassification(UniSpeechSatPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Sequence classification does not support the use of UniSpeechSat adapters (config.add_adapter=True)"
+ )
+ self.unispeech_sat = UniSpeechSatModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size)
+ self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech_sat.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.unispeech_sat.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`UniSpeechSatProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.unispeech_sat(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = hidden_states.mean(dim=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask)
+ expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_padding_mask] = 0.0
+ pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class UniSpeechSatForAudioFrameClassification(UniSpeechSatPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Audio frame classification does not support the use of UniSpeechSat adapters (config.add_adapter=True)"
+ )
+ self.unispeech_sat = UniSpeechSatModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+ self.num_labels = config.num_labels
+
+ self.init_weights()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech_sat.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.unispeech_sat.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`UniSpeechSatProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.unispeech_sat(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), torch.argmax(labels.view(-1, self.num_labels), axis=1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class AMSoftmaxLoss(nn.Module):
+ def __init__(self, input_dim, num_labels, scale=30.0, margin=0.4):
+ super().__init__()
+ self.scale = scale
+ self.margin = margin
+ self.num_labels = num_labels
+ self.weight = nn.Parameter(torch.randn(input_dim, num_labels), requires_grad=True)
+ self.loss = nn.CrossEntropyLoss()
+
+ def forward(self, hidden_states, labels):
+ labels = labels.flatten()
+ weight = nn.functional.normalize(self.weight, dim=0)
+ hidden_states = nn.functional.normalize(hidden_states, dim=1)
+ cos_theta = torch.mm(hidden_states, weight)
+ psi = cos_theta - self.margin
+
+ onehot = nn.functional.one_hot(labels, self.num_labels)
+ logits = self.scale * torch.where(onehot.bool(), psi, cos_theta)
+ loss = self.loss(logits, labels)
+
+ return loss
+
+
+class TDNNLayer(nn.Module):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.tdnn_dim[layer_id - 1] if layer_id > 0 else config.tdnn_dim[layer_id]
+ self.out_conv_dim = config.tdnn_dim[layer_id]
+ self.kernel_size = config.tdnn_kernel[layer_id]
+ self.dilation = config.tdnn_dilation[layer_id]
+
+ self.kernel = nn.Linear(self.in_conv_dim * self.kernel_size, self.out_conv_dim)
+ self.activation = nn.ReLU()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ if is_peft_available():
+ from peft.tuners.lora import LoraLayer
+
+ if is_peft_available():
+ if isinstance(self.kernel, LoraLayer):
+ warnings.warn(
+ "Detected LoRA on TDNNLayer. LoRA weights won't be applied due to optimization. "
+ "You should exclude TDNNLayer from LoRA's target modules.",
+ )
+
+ # for backward compatibility, we keep nn.Linear but call F.conv1d for speed up
+ hidden_states = hidden_states.transpose(1, 2)
+ weight = self.kernel.weight.view(self.out_conv_dim, self.kernel_size, self.in_conv_dim).transpose(1, 2)
+ hidden_states = nn.functional.conv1d(hidden_states, weight, self.kernel.bias, dilation=self.dilation)
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeechSat Model with an XVector feature extraction head on top for tasks like Speaker Verification.
+ """
+)
+class UniSpeechSatForXVector(UniSpeechSatPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.unispeech_sat = UniSpeechSatModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.tdnn_dim[0])
+
+ tdnn_layers = [TDNNLayer(config, i) for i in range(len(config.tdnn_dim))]
+ self.tdnn = nn.ModuleList(tdnn_layers)
+
+ self.feature_extractor = nn.Linear(config.tdnn_dim[-1] * 2, config.xvector_output_dim)
+ self.classifier = nn.Linear(config.xvector_output_dim, config.xvector_output_dim)
+
+ self.objective = AMSoftmaxLoss(config.xvector_output_dim, config.num_labels)
+
+ self.init_weights()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech_sat.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.unispeech_sat.parameters():
+ param.requires_grad = False
+
+ def _get_tdnn_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the TDNN layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size in self.config.tdnn_kernel:
+ input_lengths = _conv_out_length(input_lengths, kernel_size, 1)
+
+ return input_lengths
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, XVectorOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`UniSpeechSatProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.unispeech_sat(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+
+ for tdnn_layer in self.tdnn:
+ hidden_states = tdnn_layer(hidden_states)
+
+ # Statistic Pooling
+ if attention_mask is None:
+ mean_features = hidden_states.mean(dim=1)
+ std_features = hidden_states.std(dim=1)
+ else:
+ feat_extract_output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(dim=1))
+ tdnn_output_lengths = self._get_tdnn_output_lengths(feat_extract_output_lengths)
+ mean_features = []
+ std_features = []
+ for i, length in enumerate(tdnn_output_lengths):
+ mean_features.append(hidden_states[i, :length].mean(dim=0))
+ std_features.append(hidden_states[i, :length].std(dim=0))
+ mean_features = torch.stack(mean_features)
+ std_features = torch.stack(std_features)
+ statistic_pooling = torch.cat([mean_features, std_features], dim=-1)
+
+ output_embeddings = self.feature_extractor(statistic_pooling)
+ logits = self.classifier(output_embeddings)
+
+ loss = None
+ if labels is not None:
+ loss = self.objective(logits, labels)
+
+ if not return_dict:
+ output = (logits, output_embeddings) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XVectorOutput(
+ loss=loss,
+ logits=logits,
+ embeddings=output_embeddings,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "UniSpeechSatForAudioFrameClassification",
+ "UniSpeechSatForCTC",
+ "UniSpeechSatForPreTraining",
+ "UniSpeechSatForSequenceClassification",
+ "UniSpeechSatForXVector",
+ "UniSpeechSatModel",
+ "UniSpeechSatPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/modular_unispeech_sat.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/modular_unispeech_sat.py
new file mode 100644
index 0000000000000000000000000000000000000000..3e1d999392150890adc54c4cf345a2e9a3624c8e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/unispeech_sat/modular_unispeech_sat.py
@@ -0,0 +1,457 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch UniSpeechSat model."""
+
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.nn as nn
+
+from ...modeling_outputs import ModelOutput, Wav2Vec2BaseModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ..wav2vec2.modeling_wav2vec2 import (
+ Wav2Vec2Encoder,
+ Wav2Vec2EncoderStableLayerNorm,
+ Wav2Vec2FeatureEncoder,
+ Wav2Vec2FeatureProjection,
+ Wav2Vec2ForAudioFrameClassification,
+ Wav2Vec2ForCTC,
+ Wav2Vec2ForSequenceClassification,
+ Wav2Vec2ForXVector,
+ Wav2Vec2GumbelVectorQuantizer,
+ Wav2Vec2Model,
+ Wav2Vec2PositionalConvEmbedding,
+)
+from .configuration_unispeech_sat import UniSpeechSatConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`UniSpeechSatForPreTrainingOutput`], with potential hidden states and attentions.
+ """
+)
+class UniSpeechSatForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when model is in train mode, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`, *optional*):
+ Prediction scores of the contrastive loss model, i.e. the output of the model before the final softmax.
+ projected_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ codevector_perplexity (`torch.FloatTensor` of shape `(1,)`):
+ The perplexity of the codevector distribution, used to measure the diversity of the codebook.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ projected_states: Optional[torch.FloatTensor] = None
+ projected_quantized_states: Optional[torch.FloatTensor] = None
+ codevector_perplexity: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+class UniSpeechSatPositionalConvEmbedding(Wav2Vec2PositionalConvEmbedding):
+ pass
+
+
+class UniSpeechSatFeatureEncoder(Wav2Vec2FeatureEncoder):
+ pass
+
+
+class UniSpeechSatFeatureProjection(Wav2Vec2FeatureProjection):
+ pass
+
+
+class UniSpeechSatEncoder(Wav2Vec2Encoder):
+ pass
+
+
+class UniSpeechSatEncoderStableLayerNorm(Wav2Vec2EncoderStableLayerNorm):
+ pass
+
+
+class UniSpeechSatGumbelVectorQuantizer(Wav2Vec2GumbelVectorQuantizer):
+ def __init__(self, config):
+ super().__init__(config)
+ self.weight_proj = nn.Linear(config.hidden_size, self.num_groups * self.num_vars)
+
+ @staticmethod
+ def _compute_perplexity(probs, mask=None):
+ marginal_probs = probs.mean(dim=0)
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(
+ hidden_states.float(), tau=self.temperature, hard=True
+ ).type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(*hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+@auto_docstring
+class UniSpeechSatPreTrainedModel(PreTrainedModel):
+ config: UniSpeechSatConfig
+ base_model_prefix = "unispeech_sat"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # gumbel softmax requires special init
+ if isinstance(module, UniSpeechSatGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, UniSpeechSatPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, UniSpeechSatFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths).to(torch.long)
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+UniSpeechSatBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+class UniSpeechSatModel(UniSpeechSatPreTrainedModel, Wav2Vec2Model):
+ def __init__(self, config: UniSpeechSatConfig):
+ UniSpeechSatPreTrainedModel.__init__(self, config)
+ self.config = config
+ self.feature_extractor = UniSpeechSatFeatureEncoder(config)
+ self.feature_projection = UniSpeechSatFeatureProjection(config)
+
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ if config.do_stable_layer_norm:
+ self.encoder = UniSpeechSatEncoderStableLayerNorm(config)
+ else:
+ self.encoder = UniSpeechSatEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for UniSpeechSat")
+
+ def freeze_feature_encoder(self):
+ raise AttributeError("Not needed for UniSpeechSat")
+
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechSatBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(extract_features.shape[1], attention_mask)
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return UniSpeechSatBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ UniSpeechSat Model with a vector-quantization module and ctc loss for pre-training.
+ """
+)
+class UniSpeechSatForPreTraining(UniSpeechSatPreTrainedModel):
+ def __init__(self, config: UniSpeechSatConfig):
+ super().__init__(config)
+ self.unispeech_sat = UniSpeechSatModel(config)
+ self.dropout_features = nn.Dropout(config.feat_quantizer_dropout)
+
+ self.quantizer = UniSpeechSatGumbelVectorQuantizer(config)
+ self.project_q = nn.Linear(config.codevector_dim, config.proj_codevector_dim)
+ self.project_hid = nn.Linear(config.hidden_size, config.proj_codevector_dim)
+
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.speaker_proj = nn.Linear(config.hidden_size, config.codevector_dim)
+ self.label_embeddings_concat = nn.Parameter(torch.FloatTensor(config.num_clusters, config.codevector_dim))
+ self.label_embeddings_concat.data.zero_()
+
+ self.layer_norm_for_extract = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ if self.config.do_stable_layer_norm:
+ self.layer_norm_for_extract.requires_grad = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def set_gumbel_temperature(self, temperature: int):
+ """
+ Set the Gumbel softmax temperature to a given value. Only necessary for training
+ """
+ self.quantizer.temperature = temperature
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.unispeech_sat.feature_extractor._freeze_parameters()
+
+ @staticmethod
+ def compute_contrastive_logits(
+ target_features: torch.FloatTensor,
+ negative_features: torch.FloatTensor,
+ predicted_features: torch.FloatTensor,
+ temperature: int = 1,
+ ):
+ """
+ Compute logits for contrastive loss based using cosine similarity as the distance measure between
+ `[positive_feature, negative_features]` and `[predicted_features]`. Additionally, temperature can be applied.
+ """
+ target_features = torch.cat([target_features, negative_features], dim=0)
+
+ logits = torch.cosine_similarity(predicted_features.float(), target_features.float(), dim=-1)
+ logits = logits.type_as(target_features)
+
+ # apply temperature
+ logits = logits / temperature
+ return logits
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, UniSpeechSatForPreTrainingOutput]:
+ r"""
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, UniSpeechSatForPreTraining
+ >>> from transformers.models.unispeech_sat.modeling_unispeech_sat import _compute_mask_indices
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("microsoft/unispeech-sat-base")
+ >>> model = UniSpeechSatForPreTraining.from_pretrained("microsoft/unispeech-sat-base")
+ >>> # TODO: Add full pretraining example
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.unispeech_sat(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ transformer_features = outputs[0]
+
+ # quantize all (unmasked) extracted features and project to final vq dim
+ extract_features = self.dropout_features(outputs[1])
+
+ # TODO(PVP) - add pretraining logic and add to tests
+ logits = extract_features
+ loss = quantized_features = codevector_perplexity = None
+
+ if not return_dict:
+ if loss is not None:
+ return (loss, logits, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+ return (logits, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+
+ return UniSpeechSatForPreTrainingOutput(
+ loss=loss,
+ logits=logits,
+ projected_states=transformer_features,
+ projected_quantized_states=quantized_features,
+ codevector_perplexity=codevector_perplexity,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class UniSpeechSatForCTC(Wav2Vec2ForCTC):
+ pass
+
+
+class UniSpeechSatForSequenceClassification(Wav2Vec2ForSequenceClassification):
+ pass
+
+
+class UniSpeechSatForAudioFrameClassification(Wav2Vec2ForAudioFrameClassification):
+ pass
+
+
+class UniSpeechSatForXVector(Wav2Vec2ForXVector):
+ pass
+
+
+__all__ = [
+ "UniSpeechSatForAudioFrameClassification",
+ "UniSpeechSatForCTC",
+ "UniSpeechSatForPreTraining",
+ "UniSpeechSatForSequenceClassification",
+ "UniSpeechSatForXVector",
+ "UniSpeechSatModel",
+ "UniSpeechSatPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..5d02d0dbe574ebac34022e5e8727c900e16f5977
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_univnet import *
+ from .feature_extraction_univnet import *
+ from .modeling_univnet import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/configuration_univnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/configuration_univnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..4c1bad6da2537ecf2f0c7aabeb5799449295e81e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/configuration_univnet.py
@@ -0,0 +1,125 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""UnivNetModel model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class UnivNetConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`UnivNetModel`]. It is used to instantiate a
+ UnivNet vocoder model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the UnivNet
+ [dg845/univnet-dev](https://huggingface.co/dg845/univnet-dev) architecture, which corresponds to the 'c32'
+ architecture in [maum-ai/univnet](https://github.com/maum-ai/univnet/blob/master/config/default_c32.yaml).
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ model_in_channels (`int`, *optional*, defaults to 64):
+ The number of input channels for the UnivNet residual network. This should correspond to
+ `noise_sequence.shape[1]` and the value used in the [`UnivNetFeatureExtractor`] class.
+ model_hidden_channels (`int`, *optional*, defaults to 32):
+ The number of hidden channels of each residual block in the UnivNet residual network.
+ num_mel_bins (`int`, *optional*, defaults to 100):
+ The number of frequency bins in the conditioning log-mel spectrogram. This should correspond to the value
+ used in the [`UnivNetFeatureExtractor`] class.
+ resblock_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[3, 3, 3]`):
+ A tuple of integers defining the kernel sizes of the 1D convolutional layers in the UnivNet residual
+ network. The length of `resblock_kernel_sizes` defines the number of resnet blocks and should match that of
+ `resblock_stride_sizes` and `resblock_dilation_sizes`.
+ resblock_stride_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[8, 8, 4]`):
+ A tuple of integers defining the stride sizes of the 1D convolutional layers in the UnivNet residual
+ network. The length of `resblock_stride_sizes` should match that of `resblock_kernel_sizes` and
+ `resblock_dilation_sizes`.
+ resblock_dilation_sizes (`tuple[tuple[int]]` or `list[list[int]]`, *optional*, defaults to `[[1, 3, 9, 27], [1, 3, 9, 27], [1, 3, 9, 27]]`):
+ A nested tuple of integers defining the dilation rates of the dilated 1D convolutional layers in the
+ UnivNet residual network. The length of `resblock_dilation_sizes` should match that of
+ `resblock_kernel_sizes` and `resblock_stride_sizes`. The length of each nested list in
+ `resblock_dilation_sizes` defines the number of convolutional layers per resnet block.
+ kernel_predictor_num_blocks (`int`, *optional*, defaults to 3):
+ The number of residual blocks in the kernel predictor network, which calculates the kernel and bias for
+ each location variable convolution layer in the UnivNet residual network.
+ kernel_predictor_hidden_channels (`int`, *optional*, defaults to 64):
+ The number of hidden channels for each residual block in the kernel predictor network.
+ kernel_predictor_conv_size (`int`, *optional*, defaults to 3):
+ The kernel size of each 1D convolutional layer in the kernel predictor network.
+ kernel_predictor_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for each residual block in the kernel predictor network.
+ initializer_range (`float`, *optional*, defaults to 0.01):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ leaky_relu_slope (`float`, *optional*, defaults to 0.2):
+ The angle of the negative slope used by the leaky ReLU activation.
+
+ Example:
+
+ ```python
+ >>> from transformers import UnivNetModel, UnivNetConfig
+
+ >>> # Initializing a Tortoise TTS style configuration
+ >>> configuration = UnivNetConfig()
+
+ >>> # Initializing a model (with random weights) from the Tortoise TTS style configuration
+ >>> model = UnivNetModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```
+ """
+
+ model_type = "univnet"
+
+ def __init__(
+ self,
+ model_in_channels=64,
+ model_hidden_channels=32,
+ num_mel_bins=100,
+ resblock_kernel_sizes=[3, 3, 3],
+ resblock_stride_sizes=[8, 8, 4],
+ resblock_dilation_sizes=[[1, 3, 9, 27], [1, 3, 9, 27], [1, 3, 9, 27]],
+ kernel_predictor_num_blocks=3,
+ kernel_predictor_hidden_channels=64,
+ kernel_predictor_conv_size=3,
+ kernel_predictor_dropout=0.0,
+ initializer_range=0.01,
+ leaky_relu_slope=0.2,
+ **kwargs,
+ ):
+ if not (len(resblock_kernel_sizes) == len(resblock_stride_sizes) == len(resblock_dilation_sizes)):
+ raise ValueError(
+ "`resblock_kernel_sizes`, `resblock_stride_sizes`, and `resblock_dilation_sizes` must all have the"
+ " same length (which will be the number of resnet blocks in the model)."
+ )
+
+ self.model_in_channels = model_in_channels
+ self.model_hidden_channels = model_hidden_channels
+ self.num_mel_bins = num_mel_bins
+ self.resblock_kernel_sizes = resblock_kernel_sizes
+ self.resblock_stride_sizes = resblock_stride_sizes
+ self.resblock_dilation_sizes = resblock_dilation_sizes
+ self.kernel_predictor_num_blocks = kernel_predictor_num_blocks
+ self.kernel_predictor_hidden_channels = kernel_predictor_hidden_channels
+ self.kernel_predictor_conv_size = kernel_predictor_conv_size
+ self.kernel_predictor_dropout = kernel_predictor_dropout
+ self.initializer_range = initializer_range
+ self.leaky_relu_slope = leaky_relu_slope
+ super().__init__(**kwargs)
+
+
+__all__ = ["UnivNetConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/feature_extraction_univnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/feature_extraction_univnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..059226afe1d1147da2fb96626dce57b7c2f41715
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/feature_extraction_univnet.py
@@ -0,0 +1,459 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Feature extractor class for UnivNetModel."""
+
+from typing import Any, Optional, Union
+
+import numpy as np
+
+from ...audio_utils import mel_filter_bank, optimal_fft_length, spectrogram, window_function
+from ...feature_extraction_sequence_utils import SequenceFeatureExtractor
+from ...feature_extraction_utils import BatchFeature
+from ...utils import PaddingStrategy, TensorType, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class UnivNetFeatureExtractor(SequenceFeatureExtractor):
+ r"""
+ Constructs a UnivNet feature extractor.
+
+ This class extracts log-mel-filter bank features from raw speech using the short time Fourier Transform (STFT). The
+ STFT implementation follows that of TacoTron 2 and Hifi-GAN.
+
+ This feature extractor inherits from [`~feature_extraction_sequence_utils.SequenceFeatureExtractor`] which contains
+ most of the main methods. Users should refer to this superclass for more information regarding those methods.
+
+ Args:
+ feature_size (`int`, *optional*, defaults to 1):
+ The feature dimension of the extracted features.
+ sampling_rate (`int`, *optional*, defaults to 24000):
+ The sampling rate at which the audio files should be digitalized expressed in hertz (Hz).
+ padding_value (`float`, *optional*, defaults to 0.0):
+ The value to pad with when applying the padding strategy defined by the `padding` argument to
+ [`UnivNetFeatureExtractor.__call__`]. Should correspond to audio silence. The `pad_end` argument to
+ `__call__` will also use this padding value.
+ do_normalize (`bool`, *optional*, defaults to `False`):
+ Whether to perform Tacotron 2 normalization on the input. Normalizing can help to significantly improve the
+ performance for some models.
+ num_mel_bins (`int`, *optional*, defaults to 100):
+ The number of mel-frequency bins in the extracted spectrogram features. This should match
+ `UnivNetModel.config.num_mel_bins`.
+ hop_length (`int`, *optional*, defaults to 256):
+ The direct number of samples between sliding windows. Otherwise referred to as "shift" in many papers. Note
+ that this is different from other audio feature extractors such as [`SpeechT5FeatureExtractor`] which take
+ the `hop_length` in ms.
+ win_length (`int`, *optional*, defaults to 1024):
+ The direct number of samples for each sliding window. Note that this is different from other audio feature
+ extractors such as [`SpeechT5FeatureExtractor`] which take the `win_length` in ms.
+ win_function (`str`, *optional*, defaults to `"hann_window"`):
+ Name for the window function used for windowing, must be accessible via `torch.{win_function}`
+ filter_length (`int`, *optional*, defaults to 1024):
+ The number of FFT components to use. If `None`, this is determined using
+ `transformers.audio_utils.optimal_fft_length`.
+ max_length_s (`int`, *optional*, defaults to 10):
+ The maximum input length of the model in seconds. This is used to pad the audio.
+ fmin (`float`, *optional*, defaults to 0.0):
+ Minimum mel frequency in Hz.
+ fmax (`float`, *optional*):
+ Maximum mel frequency in Hz. If not set, defaults to `sampling_rate / 2`.
+ mel_floor (`float`, *optional*, defaults to 1e-09):
+ Minimum value of mel frequency banks. Note that the way [`UnivNetFeatureExtractor`] uses `mel_floor` is
+ different than in [`transformers.audio_utils.spectrogram`].
+ center (`bool`, *optional*, defaults to `False`):
+ Whether to pad the waveform so that frame `t` is centered around time `t * hop_length`. If `False`, frame
+ `t` will start at time `t * hop_length`.
+ compression_factor (`float`, *optional*, defaults to 1.0):
+ The multiplicative compression factor for dynamic range compression during spectral normalization.
+ compression_clip_val (`float`, *optional*, defaults to 1e-05):
+ The clip value applied to the waveform before applying dynamic range compression during spectral
+ normalization.
+ normalize_min (`float`, *optional*, defaults to -11.512925148010254):
+ The min value used for Tacotron 2-style linear normalization. The default is the original value from the
+ Tacotron 2 implementation.
+ normalize_max (`float`, *optional*, defaults to 2.3143386840820312):
+ The max value used for Tacotron 2-style linear normalization. The default is the original value from the
+ Tacotron 2 implementation.
+ model_in_channels (`int`, *optional*, defaults to 64):
+ The number of input channels to the [`UnivNetModel`] model. This should match
+ `UnivNetModel.config.model_in_channels`.
+ pad_end_length (`int`, *optional*, defaults to 10):
+ If padding the end of each waveform, the number of spectrogram frames worth of samples to append. The
+ number of appended samples will be `pad_end_length * hop_length`.
+ return_attention_mask (`bool`, *optional*, defaults to `True`):
+ Whether or not [`~UnivNetFeatureExtractor.__call__`] should return `attention_mask`.
+ """
+
+ model_input_names = ["input_features", "noise_sequence", "padding_mask"]
+
+ def __init__(
+ self,
+ feature_size: int = 1,
+ sampling_rate: int = 24000,
+ padding_value: float = 0.0,
+ do_normalize: bool = False,
+ num_mel_bins: int = 100,
+ hop_length: int = 256,
+ win_length: int = 1024,
+ win_function: str = "hann_window",
+ filter_length: Optional[int] = 1024,
+ max_length_s: int = 10,
+ fmin: float = 0.0,
+ fmax: Optional[float] = None,
+ mel_floor: float = 1e-9,
+ center: bool = False,
+ compression_factor: float = 1.0,
+ compression_clip_val: float = 1e-5,
+ normalize_min: float = -11.512925148010254,
+ normalize_max: float = 2.3143386840820312,
+ model_in_channels: int = 64,
+ pad_end_length: int = 10,
+ return_attention_mask=True,
+ **kwargs,
+ ):
+ super().__init__(
+ feature_size=feature_size,
+ sampling_rate=sampling_rate,
+ padding_value=padding_value,
+ return_attention_mask=return_attention_mask,
+ **kwargs,
+ )
+
+ self.do_normalize = do_normalize
+
+ self.num_mel_bins = num_mel_bins
+ self.hop_length = hop_length
+ self.win_length = win_length
+ self.win_function = win_function
+ self.filter_length = filter_length
+ self.fmin = fmin
+ if fmax is None:
+ # Follows the librosa.filters.mel implementation
+ fmax = float(sampling_rate) / 2
+ self.fmax = fmax
+ self.mel_floor = mel_floor
+
+ self.max_length_s = max_length_s
+ self.num_max_samples = max_length_s * sampling_rate
+
+ if self.filter_length is None:
+ self.n_fft = optimal_fft_length(self.win_length)
+ else:
+ self.n_fft = self.filter_length
+ self.n_freqs = (self.n_fft // 2) + 1
+
+ self.window = window_function(window_length=self.win_length, name=self.win_function, periodic=True)
+
+ self.mel_filters = mel_filter_bank(
+ num_frequency_bins=self.n_freqs,
+ num_mel_filters=self.num_mel_bins,
+ min_frequency=self.fmin,
+ max_frequency=self.fmax,
+ sampling_rate=self.sampling_rate,
+ norm="slaney",
+ mel_scale="slaney",
+ )
+
+ self.center = center
+ self.compression_factor = compression_factor
+ self.compression_clip_val = compression_clip_val
+ self.normalize_min = normalize_min
+ self.normalize_max = normalize_max
+ self.model_in_channels = model_in_channels
+ self.pad_end_length = pad_end_length
+
+ def normalize(self, spectrogram):
+ return 2 * ((spectrogram - self.normalize_min) / (self.normalize_max - self.normalize_min)) - 1
+
+ def denormalize(self, spectrogram):
+ return self.normalize_min + (self.normalize_max - self.normalize_min) * ((spectrogram + 1) / 2)
+
+ def mel_spectrogram(self, waveform: np.ndarray) -> np.ndarray:
+ """
+ Calculates log MEL spectrograms from a batch of waveforms. Note that the input waveform(s) will be padded by
+ `int(self.n_fft - self.hop_length) / 2` on both sides using the `reflect` padding mode.
+
+ Args:
+ waveform (`np.ndarray` of shape `(length,)`):
+ The input waveform. This must be a single real-valued, mono waveform.
+
+ Returns:
+ `numpy.ndarray`: Array containing a log-mel spectrogram of shape `(num_frames, num_mel_bins)`.
+ """
+ # Do custom padding based on the official MelGAN and Hifi-GAN implementations
+ # See https://github.com/maum-ai/univnet/blob/9bb2b54838bb6d7ce767131cc7b8b61198bc7558/utils/stft.py#L84-L86
+ waveform = np.pad(
+ waveform,
+ (int((self.n_fft - self.hop_length) / 2), int((self.n_fft - self.hop_length) / 2)),
+ mode="reflect",
+ )
+
+ # Get the complex spectrogram.
+ # Note: waveform must be unbatched currently due to the implementation of spectrogram(...).
+ complex_spectrogram = spectrogram(
+ waveform,
+ window=self.window,
+ frame_length=self.n_fft,
+ hop_length=self.hop_length,
+ fft_length=self.n_fft,
+ power=None,
+ center=self.center,
+ mel_filters=None,
+ mel_floor=None,
+ )
+
+ # Apply the MEL filter bank and MEL floor manually since UnivNet uses a slightly different implementation
+ amplitude_spectrogram = np.sqrt(
+ np.real(complex_spectrogram) ** 2 + np.imag(complex_spectrogram) ** 2 + self.mel_floor
+ )
+ mel_spectrogram = np.matmul(self.mel_filters.T, amplitude_spectrogram)
+
+ # Perform spectral normalization to get the log mel spectrogram.
+ log_mel_spectrogram = np.log(
+ np.clip(mel_spectrogram, a_min=self.compression_clip_val, a_max=None) * self.compression_factor
+ )
+
+ # Return spectrogram with num_mel_bins last
+ return log_mel_spectrogram.T
+
+ def generate_noise(
+ self,
+ noise_length: int,
+ generator: Optional[np.random.Generator] = None,
+ ) -> np.ndarray:
+ """
+ Generates a random noise sequence of standard Gaussian noise for use in the `noise_sequence` argument of
+ [`UnivNetModel.forward`].
+
+ Args:
+ spectrogram_length (`int`):
+ The length (dim 0) of the generated noise.
+ model_in_channels (`int`, *optional*, defaults to `None`):
+ The number of features (dim 1) of the generated noise. This should correspond to the
+ `model_in_channels` of the [`UnivNetGan`] model. If not set, this will default to
+ `self.config.model_in_channels`.
+ generator (`numpy.random.Generator`, *optional*, defaults to `None`)
+ An optional `numpy.random.Generator` random number generator to control noise generation. If not set, a
+ new generator with fresh entropy will be created.
+
+ Returns:
+ `numpy.ndarray`: Array containing random standard Gaussian noise of shape `(noise_length,
+ model_in_channels)`.
+ """
+ if generator is None:
+ generator = np.random.default_rng()
+
+ noise_shape = (noise_length, self.model_in_channels)
+ noise = generator.standard_normal(noise_shape, dtype=np.float32)
+
+ return noise
+
+ def batch_decode(self, waveforms, waveform_lengths=None) -> list[np.ndarray]:
+ r"""
+ Removes padding from generated audio after running [`UnivNetModel.forward`]. This returns a ragged list of 1D
+ audio waveform arrays and not a single tensor/array because in general the waveforms will have different
+ lengths after removing padding.
+
+ Args:
+ waveforms (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ The batched output waveforms from the [`UnivNetModel`].
+ waveform_lengths (`torch.FloatTensor` of shape `(batch_size,)`, *optional*):
+ The batched lengths of each waveform before padding.
+
+ Returns:
+ `list[np.ndarray]`: A ragged list of 1D waveform arrays with padding removed.
+ """
+ # Collapse the batched waveform tensor to a list of 1D audio waveforms
+ waveforms = [waveform.detach().to(device="cpu", copy=True).numpy() for waveform in waveforms]
+
+ if waveform_lengths is not None:
+ waveforms = [waveform[: waveform_lengths[i]] for i, waveform in enumerate(waveforms)]
+
+ return waveforms
+
+ def __call__(
+ self,
+ raw_speech: Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]],
+ sampling_rate: Optional[int] = None,
+ padding: Union[bool, str, PaddingStrategy] = True,
+ max_length: Optional[int] = None,
+ truncation: bool = True,
+ pad_to_multiple_of: Optional[int] = None,
+ return_noise: bool = True,
+ generator: Optional[np.random.Generator] = None,
+ pad_end: bool = False,
+ pad_length: Optional[int] = None,
+ do_normalize: Optional[str] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ ) -> BatchFeature:
+ """
+ Main method to featurize and prepare for the model one or several sequence(s).
+
+ Args:
+ raw_speech (`np.ndarray`, `list[float]`, `list[np.ndarray]`, `list[list[float]]`):
+ The sequence or batch of sequences to be padded. Each sequence can be a numpy array, a list of float
+ values, a list of numpy arrays or a list of list of float values. Must be mono channel audio, not
+ stereo, i.e. single float per timestep.
+ sampling_rate (`int`, *optional*):
+ The sampling rate at which the `raw_speech` input was sampled. It is strongly recommended to pass
+ `sampling_rate` at the forward call to prevent silent errors and allow automatic speech recognition
+ pipeline.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `True`):
+ Select a strategy to pad the input `raw_speech` waveforms (according to the model's padding side and
+ padding index) among:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+
+ If `pad_end = True`, that padding will occur before the `padding` strategy is applied.
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ truncation (`bool`, *optional*, defaults to `True`):
+ Activates truncation to cut input sequences longer than `max_length` to `max_length`.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value.
+
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta), or on TPUs which benefit from having sequence lengths be a multiple of 128.
+ return_noise (`bool`, *optional*, defaults to `True`):
+ Whether to generate and return a noise waveform for use in [`UnivNetModel.forward`].
+ generator (`numpy.random.Generator`, *optional*, defaults to `None`):
+ An optional `numpy.random.Generator` random number generator to use when generating noise.
+ pad_end (`bool`, *optional*, defaults to `False`):
+ Whether to pad the end of each waveform with silence. This can help reduce artifacts at the end of the
+ generated audio sample; see https://github.com/seungwonpark/melgan/issues/8 for more details. This
+ padding will be done before the padding strategy specified in `padding` is performed.
+ pad_length (`int`, *optional*, defaults to `None`):
+ If padding the end of each waveform, the length of the padding in spectrogram frames. If not set, this
+ will default to `self.config.pad_end_length`.
+ do_normalize (`bool`, *optional*):
+ Whether to perform Tacotron 2 normalization on the input. Normalizing can help to significantly improve
+ the performance for some models. If not set, this will default to `self.config.do_normalize`.
+ return_attention_mask (`bool`, *optional*):
+ Whether to return the attention mask. If left to the default, will return the attention mask according
+ to the specific feature_extractor's default.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.np.array` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ """
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+
+ if sampling_rate is not None:
+ if sampling_rate != self.sampling_rate:
+ raise ValueError(
+ f"The model corresponding to this feature extractor: {self.__class__.__name__} was trained using a"
+ f" sampling rate of {self.sampling_rate}. Please make sure that the provided `raw_speech` input"
+ f" was sampled with {self.sampling_rate} and not {sampling_rate}."
+ )
+ else:
+ logger.warning(
+ f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. "
+ "Failing to do so can result in silent errors that might be hard to debug."
+ )
+
+ is_batched_numpy = isinstance(raw_speech, np.ndarray) and len(raw_speech.shape) > 1
+ if is_batched_numpy and len(raw_speech.shape) > 2:
+ raise ValueError(f"Only mono-channel audio is supported for input to {self}")
+ is_batched = is_batched_numpy or (
+ isinstance(raw_speech, (list, tuple)) and (isinstance(raw_speech[0], (np.ndarray, tuple, list)))
+ )
+
+ if is_batched:
+ raw_speech = [np.asarray(speech, dtype=np.float32) for speech in raw_speech]
+ elif not is_batched and not isinstance(raw_speech, np.ndarray):
+ raw_speech = np.asarray(raw_speech, dtype=np.float32)
+ elif isinstance(raw_speech, np.ndarray) and raw_speech.dtype is np.dtype(np.float64):
+ raw_speech = raw_speech.astype(np.float32)
+
+ # always return batch
+ if not is_batched:
+ raw_speech = [np.asarray(raw_speech, dtype=np.float32)]
+
+ # Pad end to reduce artifacts
+ if pad_end:
+ pad_length = pad_length if pad_length is not None else self.pad_end_length
+ raw_speech = [
+ np.pad(waveform, (0, pad_length * self.hop_length), constant_values=self.padding_value)
+ for waveform in raw_speech
+ ]
+
+ batched_speech = BatchFeature({"input_features": raw_speech})
+
+ padded_inputs = self.pad(
+ batched_speech,
+ padding=padding,
+ max_length=max_length if max_length is not None else self.num_max_samples,
+ truncation=truncation,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_attention_mask=return_attention_mask,
+ )
+
+ # make sure list is in array format
+ # input_features = padded_inputs.get("input_features").transpose(2, 0, 1)
+ input_features = padded_inputs.get("input_features")
+
+ mel_spectrograms = [self.mel_spectrogram(waveform) for waveform in input_features]
+
+ if isinstance(input_features[0], list):
+ batched_speech["input_features"] = [np.asarray(mel, dtype=np.float32) for mel in mel_spectrograms]
+ else:
+ batched_speech["input_features"] = [mel.astype(np.float32) for mel in mel_spectrograms]
+
+ # convert attention_mask to correct format
+ attention_mask = padded_inputs.get("attention_mask")
+ if attention_mask is not None:
+ batched_speech["padding_mask"] = [np.asarray(array, dtype=np.int32) for array in attention_mask]
+
+ if return_noise:
+ noise = [
+ self.generate_noise(spectrogram.shape[0], generator)
+ for spectrogram in batched_speech["input_features"]
+ ]
+ batched_speech["noise_sequence"] = noise
+
+ if do_normalize:
+ batched_speech["input_features"] = [
+ self.normalize(spectrogram) for spectrogram in batched_speech["input_features"]
+ ]
+
+ if return_tensors is not None:
+ batched_speech = batched_speech.convert_to_tensors(return_tensors)
+
+ return batched_speech
+
+ def to_dict(self) -> dict[str, Any]:
+ output = super().to_dict()
+
+ # Don't serialize these as they are derived from the other properties.
+ names = ["window", "mel_filters", "n_fft", "n_freqs", "num_max_samples"]
+ for name in names:
+ if name in output:
+ del output[name]
+
+ return output
+
+
+__all__ = ["UnivNetFeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/modeling_univnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/modeling_univnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..1a9c2aa54e72a948716f69b40eeb3acb01f54b26
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/univnet/modeling_univnet.py
@@ -0,0 +1,618 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch UnivNetModel model."""
+
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...modeling_outputs import ModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from .configuration_univnet import UnivNetConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output class for the [`UnivNetModel`], which includes the generated audio waveforms and the original unpadded
+ lengths of those waveforms (so that the padding can be removed by [`UnivNetModel.batch_decode`]).
+ """
+)
+class UnivNetModelOutput(ModelOutput):
+ r"""
+ waveforms (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Batched 1D (mono-channel) output audio waveforms.
+ waveform_lengths (`torch.FloatTensor` of shape `(batch_size,)`):
+ The batched length in samples of each unpadded waveform in `waveforms`.
+ """
+
+ waveforms: Optional[torch.FloatTensor] = None
+ waveform_lengths: Optional[torch.FloatTensor] = None
+
+
+class UnivNetKernelPredictorResidualBlock(nn.Module):
+ """
+ Implementation of the residual block for the kernel predictor network inside each location variable convolution
+ block (LVCBlock).
+
+ Parameters:
+ config: (`UnivNetConfig`):
+ Config for the `UnivNetModel` model.
+ """
+
+ def __init__(
+ self,
+ config: UnivNetConfig,
+ ):
+ super().__init__()
+ self.channels = config.model_in_channels
+ self.kernel_size = config.kernel_predictor_conv_size
+ self.dropout_prob = config.kernel_predictor_dropout
+ self.leaky_relu_slope = config.leaky_relu_slope
+
+ padding = (self.kernel_size - 1) // 2
+
+ self.dropout = nn.Dropout(self.dropout_prob)
+ self.conv1 = nn.Conv1d(self.channels, self.channels, self.kernel_size, padding=padding, bias=True)
+ self.conv2 = nn.Conv1d(self.channels, self.channels, self.kernel_size, padding=padding, bias=True)
+
+ def forward(self, hidden_states: torch.FloatTensor):
+ # hidden_states should have shape (batch_size, channels, seq_length)
+ residual = hidden_states
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.conv1(hidden_states)
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = self.conv2(hidden_states)
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ return hidden_states + residual
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ weight_norm(self.conv1)
+ weight_norm(self.conv2)
+
+ def remove_weight_norm(self):
+ nn.utils.remove_weight_norm(self.conv1)
+ nn.utils.remove_weight_norm(self.conv2)
+
+
+class UnivNetKernelPredictor(nn.Module):
+ """
+ Implementation of the kernel predictor network which supplies the kernel and bias for the location variable
+ convolutional layers (LVCs) in each UnivNet LVCBlock.
+
+ Based on the KernelPredictor implementation in
+ [maum-ai/univnet](https://github.com/maum-ai/univnet/blob/9bb2b54838bb6d7ce767131cc7b8b61198bc7558/model/lvcnet.py#L7).
+
+ Parameters:
+ config: (`UnivNetConfig`):
+ Config for the `UnivNetModel` model.
+ conv_kernel_size (`int`, *optional*, defaults to 3):
+ The kernel size for the location variable convolutional layer kernels (convolutional weight tensor).
+ conv_layers (`int`, *optional*, defaults to 4):
+ The number of location variable convolutional layers to output kernels and biases for.
+ """
+
+ def __init__(
+ self,
+ config: UnivNetConfig,
+ conv_kernel_size: int = 3,
+ conv_layers: int = 4,
+ ):
+ super().__init__()
+
+ self.conv_in_channels = config.model_hidden_channels
+ self.conv_out_channels = 2 * config.model_hidden_channels
+ self.conv_kernel_size = conv_kernel_size
+ self.conv_layers = conv_layers
+
+ self.kernel_channels = (
+ self.conv_in_channels * self.conv_out_channels * self.conv_kernel_size * self.conv_layers
+ )
+ self.bias_channels = self.conv_out_channels * self.conv_layers
+
+ self.resnet_in_channels = config.num_mel_bins
+ self.resnet_hidden_channels = config.kernel_predictor_hidden_channels
+ self.resnet_kernel_size = config.kernel_predictor_conv_size
+ self.num_blocks = config.kernel_predictor_num_blocks
+
+ self.leaky_relu_slope = config.leaky_relu_slope
+
+ padding = (self.resnet_kernel_size - 1) // 2
+
+ self.input_conv = nn.Conv1d(self.resnet_in_channels, self.resnet_hidden_channels, 5, padding=2, bias=True)
+
+ self.resblocks = nn.ModuleList([UnivNetKernelPredictorResidualBlock(config) for _ in range(self.num_blocks)])
+
+ self.kernel_conv = nn.Conv1d(
+ self.resnet_hidden_channels, self.kernel_channels, self.resnet_kernel_size, padding=padding, bias=True
+ )
+ self.bias_conv = nn.Conv1d(
+ self.resnet_hidden_channels, self.bias_channels, self.resnet_kernel_size, padding=padding, bias=True
+ )
+
+ def forward(self, spectrogram: torch.FloatTensor):
+ """
+ Maps a conditioning log-mel spectrogram to a tensor of convolutional kernels and biases, for use in location
+ variable convolutional layers. Note that the input spectrogram should have shape (batch_size, input_channels,
+ seq_length).
+
+ Args:
+ spectrogram (`torch.FloatTensor` of shape `(batch_size, input_channels, seq_length)`):
+ Tensor containing the log-mel spectrograms.
+
+ Returns:
+ tuple[`torch.FloatTensor, `torch.FloatTensor`]: tuple of tensors where the first element is the tensor of
+ location variable convolution kernels of shape `(batch_size, self.conv_layers, self.conv_in_channels,
+ self.conv_out_channels, self.conv_kernel_size, seq_length)` and the second element is the tensor of
+ location variable convolution biases of shape `(batch_size, self.conv_layers. self.conv_out_channels,
+ seq_length)`.
+ """
+ batch_size, _, seq_length = spectrogram.shape
+
+ hidden_states = self.input_conv(spectrogram)
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+
+ for resblock in self.resblocks:
+ hidden_states = resblock(hidden_states)
+
+ kernel_hidden_states = self.kernel_conv(hidden_states)
+ bias_hidden_states = self.bias_conv(hidden_states)
+
+ # Reshape kernels and biases to appropriate shape
+ kernels = kernel_hidden_states.view(
+ batch_size,
+ self.conv_layers,
+ self.conv_in_channels,
+ self.conv_out_channels,
+ self.conv_kernel_size,
+ seq_length,
+ ).contiguous()
+ biases = bias_hidden_states.view(
+ batch_size,
+ self.conv_layers,
+ self.conv_out_channels,
+ seq_length,
+ ).contiguous()
+
+ return kernels, biases
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ weight_norm(self.input_conv)
+ for layer in self.resblocks:
+ layer.apply_weight_norm()
+ weight_norm(self.kernel_conv)
+ weight_norm(self.bias_conv)
+
+ def remove_weight_norm(self):
+ nn.utils.remove_weight_norm(self.input_conv)
+ for layer in self.resblocks:
+ layer.remove_weight_norm()
+ nn.utils.remove_weight_norm(self.kernel_conv)
+ nn.utils.remove_weight_norm(self.bias_conv)
+
+
+class UnivNetLvcResidualBlock(nn.Module):
+ """
+ Implementation of the location variable convolution (LVC) residual block for the UnivNet residual network.
+
+ Parameters:
+ config: (`UnivNetConfig`):
+ Config for the `UnivNetModel` model.
+ kernel_size (`int`):
+ The kernel size for the dilated 1D convolutional layer.
+ dilation (`int`):
+ The dilation for the dilated 1D convolutional layer.
+ """
+
+ def __init__(
+ self,
+ config: UnivNetConfig,
+ kernel_size: int,
+ dilation: int,
+ ):
+ super().__init__()
+ self.hidden_channels = config.model_hidden_channels
+ self.kernel_size = kernel_size
+ self.dilation = dilation
+ self.leaky_relu_slope = config.leaky_relu_slope
+
+ padding = self.dilation * (self.kernel_size - 1) // 2
+
+ self.conv = nn.Conv1d(
+ self.hidden_channels,
+ self.hidden_channels,
+ self.kernel_size,
+ padding=padding,
+ dilation=self.dilation,
+ )
+
+ def forward(self, hidden_states, kernel, bias, hop_size=256):
+ residual = hidden_states
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = self.conv(hidden_states)
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = self.location_variable_convolution(hidden_states, kernel, bias, hop_size=hop_size)
+ # Gated activation unit
+ hidden_states = torch.sigmoid(hidden_states[:, : self.hidden_channels, :]) * torch.tanh(
+ hidden_states[:, self.hidden_channels :, :]
+ )
+ # Skip connection
+ hidden_states = residual + hidden_states
+
+ return hidden_states
+
+ # Based on https://github.com/maum-ai/univnet/blob/9bb2b54838bb6d7ce767131cc7b8b61198bc7558/model/lvcnet.py#L171
+ def location_variable_convolution(
+ self,
+ hidden_states: torch.FloatTensor,
+ kernel: torch.FloatTensor,
+ bias: torch.FloatTensor,
+ dilation: int = 1,
+ hop_size: int = 256,
+ ):
+ """
+ Performs location-variable convolution operation on the input sequence (hidden_states) using the local
+ convolution kernel. This was introduced in [LVCNet: Efficient Condition-Dependent Modeling Network for Waveform
+ Generation](https://huggingface.co/papers/2102.10815) by Zhen Zheng, Jianzong Wang, Ning Cheng, and Jing Xiao.
+
+ Time: 414 μs ± 309 ns per loop (mean ± std. dev. of 7 runs, 1000 loops each), test on NVIDIA V100.
+
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, in_channels, in_length)`):
+ The input sequence of shape (batch, in_channels, in_length).
+ kernel (`torch.FloatTensor` of shape `(batch_size, in_channels, out_channels, kernel_size, kernel_length)`):
+ The local convolution kernel of shape (batch, in_channels, out_channels, kernel_size, kernel_length).
+ bias (`torch.FloatTensor` of shape `(batch_size, out_channels, kernel_length)`):
+ The bias for the local convolution of shape (batch, out_channels, kernel_length).
+ dilation (`int`, *optional*, defaults to 1):
+ The dilation of convolution.
+ hop_size (`int`, *optional*, defaults to 256):
+ The hop_size of the conditioning sequence.
+ Returns:
+ `torch.FloatTensor`: the output sequence after performing local convolution with shape (batch_size,
+ out_channels, in_length).
+ """
+ batch, _, in_length = hidden_states.shape
+ batch, _, out_channels, kernel_size, kernel_length = kernel.shape
+ if in_length != (kernel_length * hop_size):
+ raise ValueError(
+ f"Dim 2 of `hidden_states` should be {kernel_length * hop_size}) but got {in_length}. Please check"
+ " `hidden_states` or `kernel` and `hop_size` to make sure they are correct."
+ )
+
+ padding = dilation * int((kernel_size - 1) / 2)
+
+ # (batch, in_channels, in_length + 2*padding)
+ hidden_states = nn.functional.pad(hidden_states, (padding, padding), "constant", 0)
+ # (batch, in_channels, kernel_length, hop_size + 2*padding)
+ hidden_states = hidden_states.unfold(2, hop_size + 2 * padding, hop_size)
+
+ if hop_size < dilation:
+ hidden_states = nn.functional.pad(hidden_states, (0, dilation), "constant", 0)
+ # (batch, in_channels, kernel_length, (hop_size + 2*padding)/dilation, dilation)
+ hidden_states = hidden_states.unfold(3, dilation, dilation)
+ hidden_states = hidden_states[:, :, :, :, :hop_size]
+ # (batch, in_channels, kernel_length, dilation, (hop_size + 2*padding)/dilation)
+ hidden_states = hidden_states.transpose(3, 4)
+ # (batch, in_channels, kernel_length, dilation, _, kernel_size)
+ hidden_states = hidden_states.unfold(4, kernel_size, 1)
+
+ # Apply local convolution kernel to hidden_states.
+ output_hidden_states = torch.einsum("bildsk,biokl->bolsd", hidden_states, kernel)
+
+ output_hidden_states = output_hidden_states.to(memory_format=torch.channels_last_3d)
+ bias = bias.unsqueeze(-1).unsqueeze(-1).to(memory_format=torch.channels_last_3d)
+ output_hidden_states = output_hidden_states + bias
+ output_hidden_states = output_hidden_states.contiguous().view(batch, out_channels, -1)
+
+ return output_hidden_states
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ weight_norm(self.conv)
+
+ def remove_weight_norm(self):
+ nn.utils.remove_weight_norm(self.conv)
+
+
+class UnivNetLvcBlock(nn.Module):
+ """
+ Implementation of the location variable convolution (LVC) residual block of the UnivNet residual block. Includes a
+ `UnivNetKernelPredictor` inside to predict the kernels and biases of the LVC layers.
+
+ Based on LVCBlock in
+ [maum-ai/univnet](https://github.com/maum-ai/univnet/blob/9bb2b54838bb6d7ce767131cc7b8b61198bc7558/model/lvcnet.py#L98)
+
+ Parameters:
+ config (`UnivNetConfig`):
+ Config for the `UnivNetModel` model.
+ layer_id (`int`):
+ An integer corresponding to the index of the current LVC resnet block layer. This should be between 0 and
+ `len(config.resblock_stride_sizes) - 1)` inclusive.
+ lvc_hop_size (`int`, *optional*, defaults to 256):
+ The hop size for the location variable convolutional layers.
+ """
+
+ def __init__(
+ self,
+ config: UnivNetConfig,
+ layer_id: int,
+ lvc_hop_size: int = 256,
+ ):
+ super().__init__()
+ self.hidden_channels = config.model_hidden_channels
+ self.kernel_size = config.resblock_kernel_sizes[layer_id]
+ self.stride = config.resblock_stride_sizes[layer_id]
+ self.dilations = config.resblock_dilation_sizes[layer_id]
+ self.cond_hop_length = lvc_hop_size
+ self.leaky_relu_slope = config.leaky_relu_slope
+ self.num_blocks = len(self.dilations)
+
+ self.convt_pre = nn.ConvTranspose1d(
+ self.hidden_channels,
+ self.hidden_channels,
+ 2 * self.stride,
+ stride=self.stride,
+ padding=self.stride // 2 + self.stride % 2,
+ output_padding=self.stride % 2,
+ )
+
+ self.kernel_predictor = UnivNetKernelPredictor(config, self.kernel_size, self.num_blocks)
+
+ self.resblocks = nn.ModuleList(
+ [UnivNetLvcResidualBlock(config, self.kernel_size, self.dilations[i]) for i in range(self.num_blocks)]
+ )
+
+ def forward(self, hidden_states: torch.FloatTensor, spectrogram: torch.FloatTensor):
+ # hidden_states: (batch_size, hidden_channels, seq_length)
+ # spectrogram: (batch_size, cond_channels, cond_length)
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = self.convt_pre(hidden_states)
+
+ kernels, biases = self.kernel_predictor(spectrogram)
+
+ for i, resblock in enumerate(self.resblocks):
+ kernel = kernels[:, i, :, :, :, :]
+ bias = biases[:, i, :, :]
+ hidden_states = resblock(hidden_states, kernel, bias, hop_size=self.cond_hop_length)
+
+ return hidden_states
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ weight_norm(self.convt_pre)
+ self.kernel_predictor.apply_weight_norm()
+ for layer in self.resblocks:
+ layer.apply_weight_norm()
+
+ def remove_weight_norm(self):
+ nn.utils.remove_weight_norm(self.convt_pre)
+ self.kernel_predictor.remove_weight_norm()
+ for layer in self.resblocks:
+ layer.remove_weight_norm()
+
+
+@auto_docstring
+class UnivNetModel(PreTrainedModel):
+ config: UnivNetConfig
+ main_input_name = "input_features"
+
+ def __init__(self, config: UnivNetConfig):
+ super().__init__(config)
+
+ self.num_kernels = len(config.resblock_kernel_sizes)
+ self.leaky_relu_slope = config.leaky_relu_slope
+
+ self.conv_pre = nn.Conv1d(
+ config.model_in_channels,
+ config.model_hidden_channels,
+ kernel_size=7,
+ stride=1,
+ padding=3,
+ padding_mode="reflect",
+ )
+
+ # Initialize location-variable convolution ResNet Blocks.
+ num_layers = len(config.resblock_stride_sizes)
+ hop_length = 1
+ hop_lengths = []
+ for stride in config.resblock_stride_sizes:
+ hop_length = hop_length * stride
+ hop_lengths.append(hop_length)
+
+ self.resblocks = nn.ModuleList(
+ [
+ UnivNetLvcBlock(
+ config,
+ layer_id=i,
+ lvc_hop_size=hop_lengths[i],
+ )
+ for i in range(num_layers)
+ ]
+ )
+
+ self.conv_post = nn.Conv1d(config.model_hidden_channels, 1, 7, padding=3, padding_mode="reflect")
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: torch.FloatTensor,
+ noise_sequence: Optional[torch.FloatTensor] = None,
+ padding_mask: Optional[torch.FloatTensor] = None,
+ generator: Optional[torch.Generator] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.FloatTensor], UnivNetModelOutput]:
+ r"""
+ noise_sequence (`torch.FloatTensor`, *optional*):
+ Tensor containing a noise sequence of standard Gaussian noise. Can be batched and of shape `(batch_size,
+ sequence_length, config.model_in_channels)`, or un-batched and of shape (sequence_length,
+ config.model_in_channels)`. If not supplied, will be randomly generated.
+ padding_mask (`torch.BoolTensor`, *optional*):
+ Mask indicating which parts of each sequence are padded. Mask values are selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**
+ - 0 for tokens that are **masked**
+
+ The mask can be batched and of shape `(batch_size, sequence_length)` or un-batched and of shape
+ `(sequence_length,)`.
+ generator (`torch.Generator`, *optional*):
+ A [torch generator](https://pytorch.org/docs/stable/generated/torch.Generator.html) to make generation
+ deterministic.
+ return_dict:
+ Whether to return a [`~utils.ModelOutput`] subclass instead of a plain tuple.
+
+ Example:
+
+ ```python
+ >>> from transformers import UnivNetFeatureExtractor, UnivNetModel
+ >>> from datasets import load_dataset, Audio
+
+ >>> model = UnivNetModel.from_pretrained("dg845/univnet-dev")
+ >>> feature_extractor = UnivNetFeatureExtractor.from_pretrained("dg845/univnet-dev")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> # Resample the audio to the feature extractor's sampling rate.
+ >>> ds = ds.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+ >>> inputs = feature_extractor(
+ ... ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], return_tensors="pt"
+ ... )
+ >>> audio = model(**inputs).waveforms
+ >>> list(audio.shape)
+ [1, 140288]
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Resolve batch sizes for noise_sequence and spectrogram
+ spectrogram_batched = input_features.dim() == 3
+ if not spectrogram_batched:
+ input_features = input_features.unsqueeze(0)
+ spectrogram_batch_size, spectrogram_length, _ = input_features.shape
+
+ if noise_sequence is not None:
+ noise_sequence_batched = noise_sequence.dim() == 3
+ if not noise_sequence_batched:
+ noise_sequence = noise_sequence.unsqueeze(0)
+ else:
+ # Randomly generate noise_sequence
+ noise_sequence_shape = (spectrogram_batch_size, spectrogram_length, self.config.model_in_channels)
+ noise_sequence = torch.randn(
+ noise_sequence_shape, generator=generator, dtype=input_features.dtype, device=input_features.device
+ )
+ noise_sequence_batch_size = noise_sequence.shape[0]
+
+ if spectrogram_batch_size > 1 and noise_sequence_batch_size == 1:
+ # Repeat noise_sequence spectrogram_batch_size times
+ noise_sequence = noise_sequence.repeat(spectrogram_batch_size, 1, 1)
+ elif noise_sequence_batch_size > 1 and spectrogram_batch_size == 1:
+ # Repeat spectrogram noise_sequence_batch_size times
+ input_features = input_features.repeat(noise_sequence_batch_size, 1, 1)
+
+ if noise_sequence_batch_size != spectrogram_batch_size:
+ raise ValueError(
+ f"The batch size of `noise_sequence` is {noise_sequence_batch_size} and the batch size of"
+ f" `input_features` is {spectrogram_batch_size}, but the two are expected to be equal."
+ )
+
+ if padding_mask is not None:
+ if padding_mask.dim() == 1:
+ padding_mask = padding_mask.unsqueeze(0)
+ padding_mask_batch_size = padding_mask.shape[0]
+ if padding_mask_batch_size != spectrogram_batch_size:
+ raise ValueError(
+ f"The batch size of `padding_mask` is {padding_mask_batch_size} and the batch size of"
+ f" `input_features` is {spectrogram_batch_size}, but the two are expected to be equal."
+ )
+
+ # Change shapes to have channels before sequence lengths
+ hidden_states = noise_sequence.transpose(2, 1)
+ input_features = input_features.transpose(2, 1)
+
+ hidden_states = self.conv_pre(hidden_states)
+
+ for resblock in self.resblocks:
+ hidden_states = resblock(hidden_states, input_features)
+
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = self.conv_post(hidden_states)
+ hidden_states = torch.tanh(hidden_states)
+
+ # Remove sequence length dimension since this collapses to 1
+ # NOTE: keep waveforms batched even if there's only one
+ waveform = hidden_states.squeeze(1)
+
+ # Get sequence lengths for UnivNetFeatureExtractor.batch_decode.
+ waveform_lengths = None
+ if padding_mask is not None:
+ # Padding is always contiguous and added on the right
+ waveform_lengths = torch.sum(padding_mask, dim=1)
+
+ if not return_dict:
+ outputs = (waveform, waveform_lengths)
+ return outputs
+
+ return UnivNetModelOutput(
+ waveforms=waveform,
+ waveform_lengths=waveform_lengths,
+ )
+
+ def _init_weights(self, module):
+ """Initialize the weights."""
+ if isinstance(module, (nn.Linear, nn.Conv1d, nn.ConvTranspose1d)):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ weight_norm(self.conv_pre)
+ for layer in self.resblocks:
+ layer.apply_weight_norm()
+ weight_norm(self.conv_post)
+
+ def remove_weight_norm(self):
+ nn.utils.remove_weight_norm(self.conv_pre)
+ for layer in self.resblocks:
+ layer.remove_weight_norm()
+ nn.utils.remove_weight_norm(self.conv_post)
+
+
+__all__ = ["UnivNetModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..dee32c4758f0e4c54406473ec7146caa5514c413
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_upernet import *
+ from .modeling_upernet import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/configuration_upernet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/configuration_upernet.py
new file mode 100644
index 0000000000000000000000000000000000000000..d116b22fcfba681d5a1b25d52a597ab6b28f9362
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/configuration_upernet.py
@@ -0,0 +1,148 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""UperNet model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ...utils.backbone_utils import verify_backbone_config_arguments
+from ..auto.configuration_auto import CONFIG_MAPPING
+
+
+logger = logging.get_logger(__name__)
+
+
+class UperNetConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of an [`UperNetForSemanticSegmentation`]. It is used to
+ instantiate an UperNet model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the UperNet
+ [openmmlab/upernet-convnext-tiny](https://huggingface.co/openmmlab/upernet-convnext-tiny) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ backbone_config (`PretrainedConfig` or `dict`, *optional*, defaults to `ResNetConfig()`):
+ The configuration of the backbone model.
+ backbone (`str`, *optional*):
+ Name of backbone to use when `backbone_config` is `None`. If `use_pretrained_backbone` is `True`, this
+ will load the corresponding pretrained weights from the timm or transformers library. If `use_pretrained_backbone`
+ is `False`, this loads the backbone's config and uses that to initialize the backbone with random weights.
+ use_pretrained_backbone (`bool`, *optional*, `False`):
+ Whether to use pretrained weights for the backbone.
+ use_timm_backbone (`bool`, *optional*, `False`):
+ Whether to load `backbone` from the timm library. If `False`, the backbone is loaded from the transformers
+ library.
+ backbone_kwargs (`dict`, *optional*):
+ Keyword arguments to be passed to AutoBackbone when loading from a checkpoint
+ e.g. `{'out_indices': (0, 1, 2, 3)}`. Cannot be specified if `backbone_config` is set.
+ hidden_size (`int`, *optional*, defaults to 512):
+ The number of hidden units in the convolutional layers.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ pool_scales (`tuple[int]`, *optional*, defaults to `[1, 2, 3, 6]`):
+ Pooling scales used in Pooling Pyramid Module applied on the last feature map.
+ use_auxiliary_head (`bool`, *optional*, defaults to `True`):
+ Whether to use an auxiliary head during training.
+ auxiliary_loss_weight (`float`, *optional*, defaults to 0.4):
+ Weight of the cross-entropy loss of the auxiliary head.
+ auxiliary_channels (`int`, *optional*, defaults to 256):
+ Number of channels to use in the auxiliary head.
+ auxiliary_num_convs (`int`, *optional*, defaults to 1):
+ Number of convolutional layers to use in the auxiliary head.
+ auxiliary_concat_input (`bool`, *optional*, defaults to `False`):
+ Whether to concatenate the output of the auxiliary head with the input before the classification layer.
+ loss_ignore_index (`int`, *optional*, defaults to 255):
+ The index that is ignored by the loss function.
+
+ Examples:
+
+ ```python
+ >>> from transformers import UperNetConfig, UperNetForSemanticSegmentation
+
+ >>> # Initializing a configuration
+ >>> configuration = UperNetConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = UperNetForSemanticSegmentation(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "upernet"
+
+ def __init__(
+ self,
+ backbone_config=None,
+ backbone=None,
+ use_pretrained_backbone=False,
+ use_timm_backbone=False,
+ backbone_kwargs=None,
+ hidden_size=512,
+ initializer_range=0.02,
+ pool_scales=[1, 2, 3, 6],
+ use_auxiliary_head=True,
+ auxiliary_loss_weight=0.4,
+ auxiliary_in_channels=None,
+ auxiliary_channels=256,
+ auxiliary_num_convs=1,
+ auxiliary_concat_input=False,
+ loss_ignore_index=255,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ if backbone_config is None and backbone is None:
+ logger.info("`backbone_config` is `None`. Initializing the config with the default `ResNet` backbone.")
+ backbone_config = CONFIG_MAPPING["resnet"](out_features=["stage1", "stage2", "stage3", "stage4"])
+ elif isinstance(backbone_config, dict):
+ backbone_model_type = backbone_config.get("model_type")
+ config_class = CONFIG_MAPPING[backbone_model_type]
+ backbone_config = config_class.from_dict(backbone_config)
+
+ verify_backbone_config_arguments(
+ use_timm_backbone=use_timm_backbone,
+ use_pretrained_backbone=use_pretrained_backbone,
+ backbone=backbone,
+ backbone_config=backbone_config,
+ backbone_kwargs=backbone_kwargs,
+ )
+
+ self.backbone_config = backbone_config
+ self.backbone = backbone
+ self.use_pretrained_backbone = use_pretrained_backbone
+ self.use_timm_backbone = use_timm_backbone
+ self.backbone_kwargs = backbone_kwargs
+ self.hidden_size = hidden_size
+ self.initializer_range = initializer_range
+ self.pool_scales = pool_scales
+ self.use_auxiliary_head = use_auxiliary_head
+ self.auxiliary_loss_weight = auxiliary_loss_weight
+ self.auxiliary_in_channels = auxiliary_in_channels
+ self.auxiliary_channels = auxiliary_channels
+ self.auxiliary_num_convs = auxiliary_num_convs
+ self.auxiliary_concat_input = auxiliary_concat_input
+ self.loss_ignore_index = loss_ignore_index
+
+ @property
+ def sub_configs(self):
+ return (
+ {"backbone_config": type(self.backbone_config)}
+ if getattr(self, "backbone_config", None) is not None
+ else {}
+ )
+
+
+__all__ = ["UperNetConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/modeling_upernet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/modeling_upernet.py
new file mode 100644
index 0000000000000000000000000000000000000000..36dc90c30adbed46231881d3a62582316e8e46f0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/upernet/modeling_upernet.py
@@ -0,0 +1,388 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch UperNet model. Based on OpenMMLab's implementation, found in https://github.com/open-mmlab/mmsegmentation."""
+
+from typing import Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...modeling_outputs import SemanticSegmenterOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring
+from ...utils.backbone_utils import load_backbone
+from .configuration_upernet import UperNetConfig
+
+
+class UperNetConvModule(nn.Module):
+ """
+ A convolutional block that bundles conv/norm/activation layers. This block simplifies the usage of convolution
+ layers, which are commonly used with a norm layer (e.g., BatchNorm) and activation layer (e.g., ReLU).
+ """
+
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ kernel_size: Union[int, tuple[int, int]],
+ padding: Union[int, tuple[int, int], str] = 0,
+ bias: bool = False,
+ dilation: Union[int, tuple[int, int]] = 1,
+ ) -> None:
+ super().__init__()
+ self.conv = nn.Conv2d(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=kernel_size,
+ padding=padding,
+ bias=bias,
+ dilation=dilation,
+ )
+ self.batch_norm = nn.BatchNorm2d(out_channels)
+ self.activation = nn.ReLU()
+
+ def forward(self, input: torch.Tensor) -> torch.Tensor:
+ output = self.conv(input)
+ output = self.batch_norm(output)
+ output = self.activation(output)
+
+ return output
+
+
+class UperNetPyramidPoolingBlock(nn.Module):
+ def __init__(self, pool_scale: int, in_channels: int, channels: int) -> None:
+ super().__init__()
+ self.layers = [
+ nn.AdaptiveAvgPool2d(pool_scale),
+ UperNetConvModule(in_channels, channels, kernel_size=1),
+ ]
+ for i, layer in enumerate(self.layers):
+ self.add_module(str(i), layer)
+
+ def forward(self, input: torch.Tensor) -> torch.Tensor:
+ hidden_state = input
+ for layer in self.layers:
+ hidden_state = layer(hidden_state)
+ return hidden_state
+
+
+class UperNetPyramidPoolingModule(nn.Module):
+ """
+ Pyramid Pooling Module (PPM) used in PSPNet.
+
+ Args:
+ pool_scales (`tuple[int]`):
+ Pooling scales used in Pooling Pyramid Module.
+ in_channels (`int`):
+ Input channels.
+ channels (`int`):
+ Channels after modules, before conv_seg.
+ align_corners (`bool`):
+ align_corners argument of F.interpolate.
+ """
+
+ def __init__(self, pool_scales: tuple[int, ...], in_channels: int, channels: int, align_corners: bool) -> None:
+ super().__init__()
+ self.pool_scales = pool_scales
+ self.align_corners = align_corners
+ self.in_channels = in_channels
+ self.channels = channels
+ self.blocks = []
+ for i, pool_scale in enumerate(pool_scales):
+ block = UperNetPyramidPoolingBlock(pool_scale=pool_scale, in_channels=in_channels, channels=channels)
+ self.blocks.append(block)
+ self.add_module(str(i), block)
+
+ def forward(self, x: torch.Tensor) -> list[torch.Tensor]:
+ ppm_outs = []
+ for ppm in self.blocks:
+ ppm_out = ppm(x)
+ upsampled_ppm_out = nn.functional.interpolate(
+ ppm_out, size=x.size()[2:], mode="bilinear", align_corners=self.align_corners
+ )
+ ppm_outs.append(upsampled_ppm_out)
+ return ppm_outs
+
+
+class UperNetHead(nn.Module):
+ """
+ Unified Perceptual Parsing for Scene Understanding. This head is the implementation of
+ [UPerNet](https://huggingface.co/papers/1807.10221).
+ """
+
+ def __init__(self, config, in_channels):
+ super().__init__()
+
+ self.config = config
+ self.pool_scales = config.pool_scales # e.g. (1, 2, 3, 6)
+ self.in_channels = in_channels
+ self.channels = config.hidden_size
+ self.align_corners = False
+ self.classifier = nn.Conv2d(self.channels, config.num_labels, kernel_size=1)
+
+ # PSP Module
+ self.psp_modules = UperNetPyramidPoolingModule(
+ self.pool_scales,
+ self.in_channels[-1],
+ self.channels,
+ align_corners=self.align_corners,
+ )
+ self.bottleneck = UperNetConvModule(
+ self.in_channels[-1] + len(self.pool_scales) * self.channels,
+ self.channels,
+ kernel_size=3,
+ padding=1,
+ )
+ # FPN Module
+ self.lateral_convs = nn.ModuleList()
+ self.fpn_convs = nn.ModuleList()
+ for in_channels in self.in_channels[:-1]: # skip the top layer
+ l_conv = UperNetConvModule(in_channels, self.channels, kernel_size=1)
+ fpn_conv = UperNetConvModule(self.channels, self.channels, kernel_size=3, padding=1)
+ self.lateral_convs.append(l_conv)
+ self.fpn_convs.append(fpn_conv)
+
+ self.fpn_bottleneck = UperNetConvModule(
+ len(self.in_channels) * self.channels,
+ self.channels,
+ kernel_size=3,
+ padding=1,
+ )
+
+ def psp_forward(self, inputs):
+ x = inputs[-1]
+ psp_outs = [x]
+ psp_outs.extend(self.psp_modules(x))
+ psp_outs = torch.cat(psp_outs, dim=1)
+ output = self.bottleneck(psp_outs)
+
+ return output
+
+ def forward(self, encoder_hidden_states: torch.Tensor) -> torch.Tensor:
+ # build laterals
+ laterals = [lateral_conv(encoder_hidden_states[i]) for i, lateral_conv in enumerate(self.lateral_convs)]
+
+ laterals.append(self.psp_forward(encoder_hidden_states))
+
+ # build top-down path
+ used_backbone_levels = len(laterals)
+ for i in range(used_backbone_levels - 1, 0, -1):
+ prev_shape = laterals[i - 1].shape[2:]
+ laterals[i - 1] = laterals[i - 1] + nn.functional.interpolate(
+ laterals[i], size=prev_shape, mode="bilinear", align_corners=self.align_corners
+ )
+
+ # build outputs
+ fpn_outs = [self.fpn_convs[i](laterals[i]) for i in range(used_backbone_levels - 1)]
+ # append psp feature
+ fpn_outs.append(laterals[-1])
+
+ for i in range(used_backbone_levels - 1, 0, -1):
+ fpn_outs[i] = nn.functional.interpolate(
+ fpn_outs[i], size=fpn_outs[0].shape[2:], mode="bilinear", align_corners=self.align_corners
+ )
+ fpn_outs = torch.cat(fpn_outs, dim=1)
+ output = self.fpn_bottleneck(fpn_outs)
+ output = self.classifier(output)
+
+ return output
+
+
+class UperNetFCNHead(nn.Module):
+ """
+ Fully Convolution Networks for Semantic Segmentation. This head is the implementation of
+ [FCNNet](https://huggingface.co/papers/1411.4038>).
+
+ Args:
+ config:
+ Configuration.
+ in_channels (int):
+ Number of input channels.
+ kernel_size (int):
+ The kernel size for convs in the head. Default: 3.
+ dilation (int):
+ The dilation rate for convs in the head. Default: 1.
+ """
+
+ def __init__(
+ self, config, in_channels, in_index: int = 2, kernel_size: int = 3, dilation: Union[int, tuple[int, int]] = 1
+ ) -> None:
+ super().__init__()
+
+ self.config = config
+ self.in_channels = (
+ in_channels[in_index] if config.auxiliary_in_channels is None else config.auxiliary_in_channels
+ )
+ self.channels = config.auxiliary_channels
+ self.num_convs = config.auxiliary_num_convs
+ self.concat_input = config.auxiliary_concat_input
+ self.in_index = in_index
+
+ conv_padding = (kernel_size // 2) * dilation
+ convs = []
+ convs.append(
+ UperNetConvModule(
+ self.in_channels, self.channels, kernel_size=kernel_size, padding=conv_padding, dilation=dilation
+ )
+ )
+ for i in range(self.num_convs - 1):
+ convs.append(
+ UperNetConvModule(
+ self.channels, self.channels, kernel_size=kernel_size, padding=conv_padding, dilation=dilation
+ )
+ )
+ if self.num_convs == 0:
+ self.convs = nn.Identity()
+ else:
+ self.convs = nn.Sequential(*convs)
+ if self.concat_input:
+ self.conv_cat = UperNetConvModule(
+ self.in_channels + self.channels, self.channels, kernel_size=kernel_size, padding=kernel_size // 2
+ )
+
+ self.classifier = nn.Conv2d(self.channels, config.num_labels, kernel_size=1)
+
+ def forward(self, encoder_hidden_states: torch.Tensor) -> torch.Tensor:
+ # just take the relevant feature maps
+ hidden_states = encoder_hidden_states[self.in_index]
+ output = self.convs(hidden_states)
+ if self.concat_input:
+ output = self.conv_cat(torch.cat([hidden_states, output], dim=1))
+ output = self.classifier(output)
+ return output
+
+
+@auto_docstring
+class UperNetPreTrainedModel(PreTrainedModel):
+ config: UperNetConfig
+ main_input_name = "pixel_values"
+ _no_split_modules = []
+
+ def _init_weights(self, module):
+ if isinstance(module, nn.Conv2d):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.BatchNorm2d):
+ module.weight.data.fill_(1.0)
+ module.bias.data.zero_()
+
+
+@auto_docstring(
+ custom_intro="""
+ UperNet framework leveraging any vision backbone e.g. for ADE20k, CityScapes.
+ """
+)
+class UperNetForSemanticSegmentation(UperNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.backbone = load_backbone(config)
+
+ # Semantic segmentation head(s)
+ self.decode_head = UperNetHead(config, in_channels=self.backbone.channels)
+ self.auxiliary_head = (
+ UperNetFCNHead(config, in_channels=self.backbone.channels) if config.use_auxiliary_head else None
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SemanticSegmenterOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, height, width)`, *optional*):
+ Ground truth semantic segmentation maps for computing the loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels > 1`, a classification loss is computed (Cross-Entropy).
+
+ Examples:
+ ```python
+ >>> from transformers import AutoImageProcessor, UperNetForSemanticSegmentation
+ >>> from PIL import Image
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("openmmlab/upernet-convnext-tiny")
+ >>> model = UperNetForSemanticSegmentation.from_pretrained("openmmlab/upernet-convnext-tiny")
+
+ >>> filepath = hf_hub_download(
+ ... repo_id="hf-internal-testing/fixtures_ade20k", filename="ADE_val_00000001.jpg", repo_type="dataset"
+ ... )
+ >>> image = Image.open(filepath).convert("RGB")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+
+ >>> logits = outputs.logits # shape (batch_size, num_labels, height, width)
+ >>> list(logits.shape)
+ [1, 150, 512, 512]
+ ```"""
+ if labels is not None and self.config.num_labels == 1:
+ raise ValueError("The number of labels should be greater than one")
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ outputs = self.backbone.forward_with_filtered_kwargs(
+ pixel_values, output_hidden_states=output_hidden_states, output_attentions=output_attentions
+ )
+ features = outputs.feature_maps
+
+ logits = self.decode_head(features)
+ logits = nn.functional.interpolate(logits, size=pixel_values.shape[2:], mode="bilinear", align_corners=False)
+
+ auxiliary_logits = None
+ if self.auxiliary_head is not None:
+ auxiliary_logits = self.auxiliary_head(features)
+ auxiliary_logits = nn.functional.interpolate(
+ auxiliary_logits, size=pixel_values.shape[2:], mode="bilinear", align_corners=False
+ )
+
+ loss = None
+ if labels is not None:
+ # compute weighted loss
+ loss_fct = CrossEntropyLoss(ignore_index=self.config.loss_ignore_index)
+ loss = loss_fct(logits, labels)
+ if auxiliary_logits is not None:
+ auxiliary_loss = loss_fct(auxiliary_logits, labels)
+ loss += self.config.auxiliary_loss_weight * auxiliary_loss
+
+ if not return_dict:
+ if output_hidden_states:
+ output = (logits,) + outputs[1:]
+ else:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SemanticSegmenterOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["UperNetForSemanticSegmentation", "UperNetPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..bb5f5971a167997ffc89de76d5cc5ba3d8216b4b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_video_llava import *
+ from .image_processing_video_llava import *
+ from .modeling_video_llava import *
+ from .processing_video_llava import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/configuration_video_llava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/configuration_video_llava.py
new file mode 100644
index 0000000000000000000000000000000000000000..561d2e3a9254932ec795ca31b9d51e9fc6ee0d1d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/configuration_video_llava.py
@@ -0,0 +1,143 @@
+# coding=utf-8
+# Copyright 2024 Microsoft Research & University of Wisconsin-Madison and the HuggingFace Inc. team. All rights reserved.
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VideoLlava model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ..auto import CONFIG_MAPPING, AutoConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class VideoLlavaConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VideoLlavaForConditionalGeneration`]. It is used to instantiate an
+ VideoLlava model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the like LanguageBind/Video-LLaVA-7B-hf.
+
+ e.g. [LanguageBind/Video-LLaVA-7B-hf](https://huggingface.co/LanguageBind/Video-LLaVA-7B-hf)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vision_config (`VideoLlavaVisionConfig`, *optional*):
+ Custom vision config or dict. Defaults to `CLIPVisionConfig` if not indicated.
+ text_config (`Union[AutoConfig, dict]`, *optional*):
+ The config object of the text backbone. Can be any of `LlamaConfig` or `MistralConfig`.
+ Defaults to `LlamaConfig` if not indicated.
+ image_token_index (`int`, *optional*, defaults to 32000):
+ The image token index to encode the image prompt.
+ video_token_index (`int`, *optional*, defaults to 32001):
+ The video token index to encode the image prompt.
+ projector_hidden_act (`str`, *optional*, defaults to `"gelu"`):
+ The activation function used by the multimodal projector.
+ vision_feature_select_strategy (`str`, *optional*, defaults to `"default"`):
+ The feature selection strategy used to select the vision feature from the CLIP backbone.
+ Can be either "full" to select all features or "default" to select features without `CLS`.
+ vision_feature_layer (`Union[int, list[int]]`, *optional*, defaults to -2):
+ The index of the layer to select the vision feature. If multiple indices are provided,
+ the vision feature of the corresponding indices will be concatenated to form the
+ vision features.
+ image_seq_length (`int`, *optional*, defaults to 256):
+ Sequence length of one image embedding.
+ video_seq_length (`int`, *optional*, defaults to 2056):
+ Sequence length of one video embedding.
+ multimodal_projector_bias (`bool`, *optional*, defaults to `True`):
+ Whether to use bias in the multimodal projector.
+
+ Example:
+
+ ```python
+ >>> from transformers import VideoLlavaForConditionalGeneration, VideoLlavaConfig, CLIPVisionConfig, LlamaConfig
+
+ >>> # Initializing a CLIP-vision config
+ >>> vision_config = CLIPVisionConfig()
+
+ >>> # Initializing a Llama config
+ >>> text_config = LlamaConfig()
+
+ >>> # Initializing a VideoLlava video_llava-1.5-7b style configuration
+ >>> configuration = VideoLlavaConfig(vision_config, text_config)
+
+ >>> # Initializing a model from the video_llava-1.5-7b style configuration
+ >>> model = VideoLlavaForConditionalGeneration(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "video_llava"
+ attribute_map = {
+ "image_token_id": "image_token_index",
+ "video_token_id": "video_token_index",
+ }
+ sub_configs = {"text_config": AutoConfig, "vision_config": AutoConfig}
+
+ def __init__(
+ self,
+ vision_config=None,
+ text_config=None,
+ image_token_index=32000,
+ video_token_index=32001,
+ projector_hidden_act="gelu",
+ vision_feature_select_strategy="default",
+ vision_feature_layer=-2,
+ image_seq_length=256,
+ video_seq_length=2056,
+ multimodal_projector_bias=True,
+ **kwargs,
+ ):
+ self.image_token_index = image_token_index
+ self.video_token_index = video_token_index
+ self.projector_hidden_act = projector_hidden_act
+ self.vision_feature_select_strategy = vision_feature_select_strategy
+ self.vision_feature_layer = vision_feature_layer
+ self.image_seq_length = image_seq_length
+ self.video_seq_length = video_seq_length
+ self.multimodal_projector_bias = multimodal_projector_bias
+
+ self.vision_config = vision_config
+
+ if isinstance(self.vision_config, dict):
+ if "model_type" not in vision_config:
+ vision_config["model_type"] = "clip_vision_model"
+ logger.warning("Key=`model_type` not found in vision config, setting it to `clip_vision_model`")
+ self.vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config)
+ elif vision_config is None:
+ self.vision_config = CONFIG_MAPPING["clip_vision_model"](
+ intermediate_size=4096,
+ hidden_size=1024,
+ patch_size=14,
+ image_size=224,
+ num_hidden_layers=24,
+ num_attention_heads=16,
+ vocab_size=32000,
+ projection_dim=768,
+ )
+
+ if isinstance(text_config, dict):
+ if "model_type" not in text_config:
+ text_config["model_type"] = "llama"
+ logger.warning("Key=`model_type` not found in text config, setting it to `llama`")
+ text_config = CONFIG_MAPPING[text_config["model_type"]](**text_config)
+ elif text_config is None:
+ text_config = CONFIG_MAPPING["llama"]()
+
+ self.text_config = text_config
+ super().__init__(**kwargs)
+
+
+__all__ = ["VideoLlavaConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/image_processing_video_llava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/image_processing_video_llava.py
new file mode 100644
index 0000000000000000000000000000000000000000..47b51869f600206cb1eabee9fcf50584b2db4c8a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/image_processing_video_llava.py
@@ -0,0 +1,391 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for Video-LLaVA."""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import (
+ convert_to_rgb,
+ get_resize_output_image_size,
+ resize,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ OPENAI_CLIP_MEAN,
+ OPENAI_CLIP_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, logging
+from ...video_utils import VideoInput, make_batched_videos
+
+
+logger = logging.get_logger(__name__)
+
+
+class VideoLlavaImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a CLIP image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by
+ `do_resize` in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"shortest_edge": 224}`):
+ Size of the image after resizing. The shortest edge of the image is resized to size["shortest_edge"], with
+ the longest edge resized to keep the input aspect ratio. Can be overridden by `size` in the `preprocess`
+ method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`):
+ Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method.
+ do_center_crop (`bool`, *optional*, defaults to `True`):
+ Whether to center crop the image to the specified `crop_size`. Can be overridden by `do_center_crop` in the
+ `preprocess` method.
+ crop_size (`dict[str, int]` *optional*, defaults to 224):
+ Size of the output image after applying `center_crop`. Can be overridden by `crop_size` in the `preprocess`
+ method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in
+ the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess`
+ method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by `do_normalize` in the `preprocess` method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `[0.48145466, 0.4578275, 0.40821073]`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `[0.26862954, 0.26130258, 0.27577711]`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_convert_rgb (`bool`, *optional*, defaults to `True`):
+ Whether to convert the image to RGB.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BICUBIC,
+ do_center_crop: bool = True,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_rgb: bool = True,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"shortest_edge": 224}
+ size = get_size_dict(size, default_to_square=False)
+ crop_size = crop_size if crop_size is not None else {"height": 224, "width": 224}
+ crop_size = get_size_dict(crop_size, default_to_square=True, param_name="crop_size")
+
+ self.do_resize = do_resize
+ self.size = size
+ self.resample = resample
+ self.do_center_crop = do_center_crop
+ self.crop_size = crop_size
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else OPENAI_CLIP_MEAN
+ self.image_std = image_std if image_std is not None else OPENAI_CLIP_STD
+ self.do_convert_rgb = do_convert_rgb
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BICUBIC,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image. The shortest edge of the image is resized to size["shortest_edge"], with the longest edge
+ resized to keep the input aspect ratio.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Size of the output image.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`):
+ Resampling filter to use when resiizing the image.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ default_to_square = True
+ if "shortest_edge" in size:
+ size = size["shortest_edge"]
+ default_to_square = False
+ elif "height" in size and "width" in size:
+ size = (size["height"], size["width"])
+ else:
+ raise ValueError("Size must contain either 'shortest_edge' or 'height' and 'width'.")
+
+ output_size = get_resize_output_image_size(
+ image,
+ size=size,
+ default_to_square=default_to_square,
+ input_data_format=input_data_format,
+ )
+ return resize(
+ image,
+ size=output_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: Optional[list[ImageInput]] = None,
+ videos: Optional[list[VideoInput]] = None,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[int] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Optional[ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> BatchFeature:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`, *optional*):
+ List of images to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ videos (`VideoInput`, *optional*):
+ List of videos to preprocess. Expects a single or batch of videos with pixel values ranging from 0 to 255. If
+ passing in videos with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after resizing. Shortest edge of the image is resized to size["shortest_edge"], with
+ the longest edge resized to keep the input aspect ratio.
+ resample (`int`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only
+ has an effect if `do_resize` is set to `True`.
+ do_center_crop (`bool`, *optional*, defaults to `self.do_center_crop`):
+ Whether to center crop the image.
+ crop_size (`dict[str, int]`, *optional*, defaults to `self.crop_size`):
+ Size of the center crop. Only has an effect if `do_center_crop` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image.
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to
+ `True`.
+ do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`):
+ Whether to convert the image to RGB.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ size = size if size is not None else self.size
+ size = get_size_dict(size, param_name="size", default_to_square=False)
+ resample = resample if resample is not None else self.resample
+ do_center_crop = do_center_crop if do_center_crop is not None else self.do_center_crop
+ crop_size = crop_size if crop_size is not None else self.crop_size
+ crop_size = get_size_dict(crop_size, param_name="crop_size", default_to_square=True)
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb
+
+ if images is not None:
+ images = self.fetch_images(images)
+ images = make_list_of_images(images)
+
+ if images is not None and not valid_images(images):
+ raise ValueError(
+ "Invalid input type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ data = {}
+ if videos is not None:
+ logger.warning(
+ "`VideoLlavaImageProcessor` works only with image inputs and doesn't process videos anymore. "
+ "This is a deprecated behavior and will be removed in v5.0. "
+ "Your videos should be forwarded to `VideoLlavaVideoProcessor`. "
+ )
+ videos = make_batched_videos(videos)
+ pixel_values_videos = [
+ [
+ self._preprocess_image(
+ image=frame,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_convert_rgb=do_convert_rgb,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ for frame in video
+ ]
+ for video in videos
+ ]
+ data["pixel_values_videos"] = pixel_values_videos
+
+ if images is not None:
+ pixel_values_images = [
+ self._preprocess_image(
+ image=image,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_convert_rgb=do_convert_rgb,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ for image in images
+ ]
+ data["pixel_values_images"] = pixel_values_images
+
+ encoded_outputs = BatchFeature(data, tensor_type=return_tensors)
+
+ return encoded_outputs
+
+ def _preprocess_image(
+ self,
+ image: ImageInput = None,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[int] = None,
+ do_convert_rgb: Optional[bool] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ # PIL RGBA images are converted to RGB
+ if do_convert_rgb:
+ image = convert_to_rgb(image)
+
+ # All transformations expect numpy arrays.
+ image = to_numpy_array(image)
+
+ if do_rescale and is_scaled_image(image):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images/video frames. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(image)
+
+ if do_resize:
+ image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+
+ if do_center_crop:
+ image = self.center_crop(image=image, size=crop_size, input_data_format=input_data_format)
+
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+
+ if do_normalize:
+ image = self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+
+ image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+
+ return image
+
+
+__all__ = ["VideoLlavaImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/modeling_video_llava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/modeling_video_llava.py
new file mode 100644
index 0000000000000000000000000000000000000000..f2a967144b5344b20d9fb71c6374f93f889b8355
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/modeling_video_llava.py
@@ -0,0 +1,721 @@
+# coding=utf-8
+# Copyright 2024 the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch VideoLlava model."""
+
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache
+from ...generation import GenerationMixin
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import ModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, auto_docstring, can_return_tuple, logging
+from ..auto import AutoModel
+from .configuration_video_llava import VideoLlavaConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for VideoLlava base model outputs.
+ """
+)
+class VideoLlavaModelOutputWithPast(ModelOutput):
+ r"""
+ past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`)
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see
+ `past_key_values` input) to speed up sequential decoding.
+ image_hidden_states (`torch.FloatTensor`, *optional*):
+ A `torch.FloatTensor` of size (batch_size, num_images, sequence_length, hidden_size)`.
+ image_hidden_states of the model produced by the vision encoder and after projecting the last hidden state.
+ video_hidden_states (`torch.FloatTensor`, *optional*):
+ A `torch.FloatTensor` of size `(batch_size * num_frames, num_videos, sequence_length, hidden_size)`.
+ video_hidden_states of the model produced by the vision encoder and after projecting the last hidden state.
+ """
+
+ last_hidden_state: torch.FloatTensor = None
+ past_key_values: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ image_hidden_states: Optional[torch.FloatTensor] = None
+ video_hidden_states: Optional[torch.FloatTensor] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for VideoLlava causal language model (or autoregressive) outputs.
+ """
+)
+class VideoLlavaCausalLMOutputWithPast(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Language modeling loss (for next-token prediction).
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+ past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`)
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see
+ `past_key_values` input) to speed up sequential decoding.
+ image_hidden_states (`torch.FloatTensor`, *optional*):
+ A `torch.FloatTensor` of size (batch_size, num_images, sequence_length, hidden_size)`.
+ image_hidden_states of the model produced by the vision encoder and after projecting the last hidden state.
+ video_hidden_states (`torch.FloatTensor`, *optional*):
+ A `torch.FloatTensor` of size `(batch_size * num_frames, num_videos, sequence_length, hidden_size)`.
+ video_hidden_states of the model produced by the vision encoder and after projecting the last hidden state.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ past_key_values: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ image_hidden_states: Optional[torch.FloatTensor] = None
+ video_hidden_states: Optional[torch.FloatTensor] = None
+
+
+# Copied from transformers.models.llava.modeling_llava.LlavaMultiModalProjector with Llava->VideoLlava
+class VideoLlavaMultiModalProjector(nn.Module):
+ def __init__(self, config: VideoLlavaConfig):
+ super().__init__()
+ # We have hidden_size * the number of vision feature layers
+ num_feature_layers = 1 if isinstance(config.vision_feature_layer, int) else len(config.vision_feature_layer)
+ self.linear_1 = nn.Linear(
+ config.vision_config.hidden_size * num_feature_layers,
+ config.text_config.hidden_size,
+ bias=config.multimodal_projector_bias,
+ )
+ self.act = ACT2FN[config.projector_hidden_act]
+ self.linear_2 = nn.Linear(
+ config.text_config.hidden_size, config.text_config.hidden_size, bias=config.multimodal_projector_bias
+ )
+
+ def forward(self, image_features):
+ hidden_states = self.linear_1(image_features)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+ return hidden_states
+
+
+@auto_docstring
+class VideoLlavaPreTrainedModel(PreTrainedModel):
+ config: VideoLlavaConfig
+ base_model_prefix = ""
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["VideoLlavaVisionAttention"]
+ _skip_keys_device_placement = "past_key_values"
+
+ _supports_flash_attn = True
+ _supports_sdpa = True
+
+ _can_compile_fullgraph = True
+ _supports_attention_backend = True
+
+ def _init_weights(self, module):
+ std = (
+ self.config.initializer_range
+ if hasattr(self.config, "initializer_range")
+ else self.config.text_config.initializer_range
+ )
+
+ if hasattr(module, "class_embedding"):
+ module.class_embedding.data.normal_(mean=0.0, std=std)
+
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+@auto_docstring(
+ custom_intro="""
+ The VideoLlava model which consists of a vision backbone and a language model without language modeling head.
+ """,
+)
+class VideoLlavaModel(VideoLlavaPreTrainedModel):
+ _checkpoint_conversion_mapping = {"language_model.model": "language_model"}
+
+ def __init__(self, config: VideoLlavaConfig):
+ super().__init__(config)
+ self.video_tower = AutoModel.from_config(config.vision_config)
+ self.image_tower = AutoModel.from_config(config.vision_config)
+
+ self.multi_modal_projector = VideoLlavaMultiModalProjector(config)
+ self.vocab_size = config.text_config.vocab_size
+ self.language_model = AutoModel.from_config(config.text_config)
+ self.pad_token_id = self.config.pad_token_id if self.config.pad_token_id is not None else -1
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.language_model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.language_model.set_input_embeddings(value)
+
+ def set_decoder(self, decoder):
+ self.language_model = decoder
+
+ def get_decoder(self):
+ return self.language_model
+
+ def get_image_features(
+ self,
+ pixel_values_images: torch.FloatTensor,
+ vision_feature_layer: Optional[Union[int, list[int]]] = None,
+ vision_feature_select_strategy: Optional[str] = None,
+ ):
+ """
+ Obtains image last hidden states from the vision tower and apply multimodal projection.
+
+ Args:
+ pixel_values_images (`torch.FloatTensor]` of shape `(batch_size, channels, height, width)`)
+ The tensors corresponding to the input images.
+ vision_feature_layer (`Union[int, list[int]]`, *optional*):
+ The index of the layer to select the vision feature. If multiple indices are provided,
+ the vision feature of the corresponding indices will be concatenated to form the
+ vision features.
+ vision_feature_select_strategy (`str`, *optional*):
+ The feature selection strategy used to select the vision feature from the vision backbone.
+ Can be one of `"default"` or `"full"`
+ Returns:
+ image_features (`torch.Tensor`): Image feature tensor of shape `(num_images, image_length, embed_dim)`).
+ """
+ vision_feature_layer = (
+ vision_feature_layer if vision_feature_layer is not None else self.config.vision_feature_layer
+ )
+ vision_feature_select_strategy = (
+ vision_feature_select_strategy
+ if vision_feature_select_strategy is not None
+ else self.config.vision_feature_select_strategy
+ )
+
+ if vision_feature_select_strategy not in ["default", "full"]:
+ raise ValueError(f"Unexpected select feature strategy: {self.config.vision_feature_select_strategy}")
+
+ image_outputs = self.image_tower(pixel_values_images, output_hidden_states=True)
+
+ # If we have one vision feature layer, return the corresponding hidden states,
+ # otherwise, select the hidden states of each feature layer and concatenate them
+ if isinstance(vision_feature_layer, int):
+ image_outputs = image_outputs.hidden_states[vision_feature_layer]
+ if vision_feature_select_strategy == "default":
+ image_outputs = image_outputs[:, 1:]
+ else:
+ hs_pool = [image_outputs.hidden_states[layer_idx] for layer_idx in vision_feature_layer]
+ # For default; crop CLS from each hidden state in the hidden state pool
+ if vision_feature_select_strategy == "default":
+ hs_pool = [hs[:, 1:] for hs in hs_pool]
+ image_outputs = torch.cat(hs_pool, dim=-1)
+
+ image_features = self.multi_modal_projector(image_outputs)
+
+ return image_features
+
+ def get_video_features(
+ self,
+ pixel_values_videos: torch.FloatTensor,
+ vision_feature_layer: Optional[Union[int, list[int]]] = None,
+ ):
+ """
+ Obtains video last hidden states from the vision tower and apply multimodal projection.
+
+ Args:
+ pixel_values_videos (`torch.FloatTensor]` of shape `(batch_size, num_frames, channels, height, width)`)
+ The tensors corresponding to the input videos.
+ vision_feature_layer (`Union[int, list[int]]`, *optional*):
+ The index of the layer to select the vision feature. If multiple indices are provided,
+ the vision feature of the corresponding indices will be concatenated to form the
+ vision features.
+ Returns:
+ video_features (`torch.Tensor`): Video feature tensor of shape `(num_videos * num_frames, image_length, embed_dim)`).
+ frames (`int`): Number of frames the videos have.
+ """
+ vision_feature_layer = (
+ vision_feature_layer if vision_feature_layer is not None else self.config.vision_feature_layer
+ )
+
+ batch_size_vid, num_frames, channels, height, width = pixel_values_videos.shape
+
+ pixel_values = pixel_values_videos.reshape(batch_size_vid * num_frames, channels, height, width)
+ video_outputs = self.video_tower(pixel_values, output_hidden_states=True)
+
+ # If we have one vision feature layer, return the corresponding hidden states,
+ # otherwise, select the hidden states of each feature layer and concatenate them
+ if isinstance(vision_feature_layer, int):
+ video_features = video_outputs.hidden_states[vision_feature_layer]
+ else:
+ hs_pool = [video_outputs.hidden_states[layer_idx] for layer_idx in vision_feature_layer]
+ video_features = torch.cat(hs_pool, dim=-1)
+
+ video_features = self.multi_modal_projector(video_features)
+
+ return video_features, num_frames
+
+ def get_placeholder_mask(
+ self,
+ input_ids: torch.LongTensor,
+ inputs_embeds: torch.FloatTensor,
+ image_features: torch.FloatTensor = None,
+ video_features: torch.FloatTensor = None,
+ ):
+ """
+ Obtains multimodal placeholder mask from `input_ids` or `inputs_embeds`, and checks that the placeholder token count is
+ equal to the length of multimodal features. If the lengths are different, an error is raised.
+ """
+ if input_ids is None:
+ special_image_mask = inputs_embeds == self.get_input_embeddings()(
+ torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device)
+ )
+ special_image_mask = special_image_mask.all(-1)
+ special_video_mask = inputs_embeds == self.get_input_embeddings()(
+ torch.tensor(self.config.video_token_id, dtype=torch.long, device=inputs_embeds.device)
+ )
+ special_video_mask = special_video_mask.all(-1)
+ else:
+ special_image_mask = input_ids == self.config.image_token_id
+ special_video_mask = input_ids == self.config.video_token_id
+
+ n_image_tokens = special_image_mask.sum()
+ special_image_mask = special_image_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device)
+ if image_features is not None and inputs_embeds[special_image_mask].numel() != image_features.numel():
+ raise ValueError(
+ f"Image features and image tokens do not match: tokens: {n_image_tokens}, features {image_features.shape[0] * image_features.shape[1]}"
+ )
+
+ n_video_tokens = special_video_mask.sum()
+ special_video_mask = special_video_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device)
+ if video_features is not None and inputs_embeds[special_video_mask].numel() != video_features.numel():
+ raise ValueError(
+ f"Videos features and image tokens do not match: tokens: {n_video_tokens}, features {video_features.shape[0] * video_features.shape[1]}"
+ )
+
+ return special_image_mask, special_video_mask
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values_images: torch.FloatTensor = None,
+ pixel_values_videos: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ vision_feature_layer: Optional[Union[int, list[int]]] = None,
+ vision_feature_select_strategy: Optional[str] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> Union[tuple, VideoLlavaModelOutputWithPast]:
+ r"""
+ pixel_values_images (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)):
+ The tensors corresponding to the input images. Pixel values can be obtained using
+ [`AutoImageProcessor`]. See [`VideoLlavaImageProcessor.__call__`] for details ([]`LlavaProcessor`] uses
+ [`VideoLlavaImageProcessor`] for processing images).
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ vision_feature_layer = (
+ vision_feature_layer if vision_feature_layer is not None else self.config.vision_feature_layer
+ )
+ vision_feature_select_strategy = (
+ vision_feature_select_strategy
+ if vision_feature_select_strategy is not None
+ else self.config.vision_feature_select_strategy
+ )
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.get_input_embeddings()(input_ids)
+
+ if pixel_values_images is not None:
+ image_features = self.get_image_features(
+ pixel_values_images,
+ vision_feature_layer=vision_feature_layer,
+ vision_feature_select_strategy=vision_feature_select_strategy,
+ )
+ image_features = image_features.to(inputs_embeds.device, inputs_embeds.dtype)
+ special_image_mask, _ = self.get_placeholder_mask(
+ input_ids, inputs_embeds=inputs_embeds, image_features=image_features
+ )
+ inputs_embeds = inputs_embeds.masked_scatter(special_image_mask, image_features)
+
+ if pixel_values_videos is not None:
+ video_features, num_frames = self.get_video_features(
+ pixel_values_videos=pixel_values_videos, vision_feature_layer=vision_feature_layer
+ )
+ video_features = video_features.to(inputs_embeds.device, inputs_embeds.dtype)
+ _, special_video_mask = self.get_placeholder_mask(
+ input_ids, inputs_embeds=inputs_embeds, video_features=video_features
+ )
+ inputs_embeds = inputs_embeds.masked_scatter(special_video_mask, video_features)
+
+ outputs = self.language_model(
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ return VideoLlavaModelOutputWithPast(
+ last_hidden_state=outputs.last_hidden_state,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=image_features if pixel_values_images is not None else None,
+ video_hidden_states=video_features if pixel_values_videos is not None else None,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The VideoLlava model which consists of a vision backbone and a language model.
+ """
+)
+class VideoLlavaForConditionalGeneration(VideoLlavaPreTrainedModel, GenerationMixin):
+ _checkpoint_conversion_mapping = {
+ "^language_model.model": "model.language_model",
+ "^image_tower": "model.image_tower",
+ "^video_tower": "model.video_tower",
+ "^multi_modal_projector": "model.multi_modal_projector",
+ "^language_model.lm_head": "lm_head",
+ }
+ _tied_weights_keys = ["lm_head.weight"]
+
+ def __init__(self, config: VideoLlavaConfig):
+ super().__init__(config)
+ self.model = VideoLlavaModel(config)
+ self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False)
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.set_input_embeddings(value)
+
+ def get_output_embeddings(self) -> nn.Module:
+ return self.lm_head
+
+ def set_decoder(self, decoder):
+ self.model.set_decoder(decoder)
+
+ def get_decoder(self):
+ return self.model.get_decoder()
+
+ def get_image_features(
+ self,
+ pixel_values_images: torch.FloatTensor,
+ vision_feature_layer: Optional[Union[int, list[int]]] = None,
+ vision_feature_select_strategy: Optional[str] = None,
+ ):
+ return self.model.get_image_features(
+ pixel_values_images=pixel_values_images,
+ vision_feature_layer=vision_feature_layer,
+ vision_feature_select_strategy=vision_feature_select_strategy,
+ )
+
+ # Make modules available through conditional class for BC
+ @property
+ def language_model(self):
+ return self.model.language_model
+
+ @property
+ def video_tower(self):
+ return self.model.video_tower
+
+ @property
+ def image_tower(self):
+ return self.model.image_tower
+
+ @property
+ def multi_modal_projector(self):
+ return self.model.multi_modal_projector
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values_images: torch.FloatTensor = None,
+ pixel_values_videos: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ vision_feature_layer: Optional[Union[int, list[int]]] = None,
+ vision_feature_select_strategy: Optional[str] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> Union[tuple, VideoLlavaCausalLMOutputWithPast]:
+ r"""
+ pixel_values_images (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)):
+ The tensors corresponding to the input images. Pixel values can be obtained using
+ [`AutoImageProcessor`]. See [`VideoLlavaImageProcessor.__call__`] for details ([]`LlavaProcessor`] uses
+ [`VideoLlavaImageProcessor`] for processing images).
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> import numpy as np
+ >>> import av
+ >>> from huggingface_hub import hf_hub_download
+ >>> from transformers import VideoLlavaProcessor, VideoLlavaForConditionalGeneration
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+ >>> model = VideoLlavaForConditionalGeneration.from_pretrained("LanguageBind/Video-LLaVA-7B-hf")
+ >>> processor = VideoLlavaProcessor.from_pretrained("LanguageBind/Video-LLaVA-7B-hf")
+
+ >>> prompt = "USER: \nWhy is this video funny? ASSISTANT:"
+ >>> video_path = hf_hub_download(repo_id="raushan-testing-hf/videos-test", filename="sample_demo_1.mp4", repo_type="dataset")
+ >>> container = av.open(video_path)
+
+ >>> # sample uniformly 8 frames from the video
+ >>> total_frames = container.streams.video[0].frames
+ >>> indices = np.arange(0, total_frames, total_frames / 8).astype(int)
+ >>> clip = read_video_pyav(container, indices)
+
+ >>> inputs = processor(text=prompt, videos=clip, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(**inputs, max_length=80)
+ >>> processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+ "USER: Why is this video funny? ASSISTANT: The video is funny because the baby is playing with a Wii remote while sitting on the floor, and the baby is wearing glasses.Ъ. The baby's actions are amusing because it is a young child trying to interact with a video game, which is not a typical activity for a"
+
+ >>> # to generate from image and video mix
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+ >>> prompt = [
+ ... "USER: \nHow many cats do you see? ASSISTANT:",
+ ... "USER: \nWhy is this video funny? ASSISTANT:"
+ ... ]
+ >>> inputs = processor(text=prompt, images=image, videos=clip, padding=True, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(**inputs, max_length=50)
+ >>> processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+ ['USER: How many cats do you see? ASSISTANT: There are two cats visible in the image. (or three, if you count the one in the background).', 'USER: Why is this video funny? ASSISTANT: The video is funny because it shows a baby sitting on a bed and playing with a Wii remote.Ъ. The baby is holding the remote']
+ ```
+ """
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ vision_feature_layer = (
+ vision_feature_layer if vision_feature_layer is not None else self.config.vision_feature_layer
+ )
+ vision_feature_select_strategy = (
+ vision_feature_select_strategy
+ if vision_feature_select_strategy is not None
+ else self.config.vision_feature_select_strategy
+ )
+
+ outputs = self.model(
+ input_ids=input_ids,
+ pixel_values_images=pixel_values_images,
+ pixel_values_videos=pixel_values_videos,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ vision_feature_layer=vision_feature_layer,
+ vision_feature_select_strategy=vision_feature_select_strategy,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ hidden_states = outputs[0]
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(
+ logits=logits, labels=labels, vocab_size=self.config.text_config.vocab_size, **kwargs
+ )
+
+ return VideoLlavaCausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=outputs.image_hidden_states,
+ video_hidden_states=outputs.video_hidden_states,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ past_key_values=None,
+ inputs_embeds=None,
+ pixel_values_images=None,
+ pixel_values_videos=None,
+ attention_mask=None,
+ cache_position=None,
+ logits_to_keep=None,
+ **kwargs,
+ ):
+ # Overwritten -- in specific circumstances we don't want to forward image inputs to the model
+
+ model_inputs = super().prepare_inputs_for_generation(
+ input_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ cache_position=cache_position,
+ logits_to_keep=logits_to_keep,
+ **kwargs,
+ )
+
+ if cache_position[0] == 0:
+ # If we're in cached decoding stage, pixel values should be None because input ids do not contain special image token anymore
+ # Otherwise we need pixel values to be passed to model
+ model_inputs["pixel_values_images"] = pixel_values_images
+ model_inputs["pixel_values_videos"] = pixel_values_videos
+
+ return model_inputs
+
+ @staticmethod
+ # Copied from transformers.models.gptj.modeling_gptj.GPTJModel._prepare_4d_causal_attention_mask_with_cache_position
+ def _prepare_4d_causal_attention_mask_with_cache_position(
+ attention_mask: torch.Tensor,
+ sequence_length: int,
+ target_length: int,
+ dtype: torch.dtype,
+ cache_position: torch.Tensor,
+ batch_size: int,
+ **kwargs,
+ ):
+ """
+ Creates a causal 4D mask of shape `(batch_size, 1, query_length, key_value_length)` from a 2D mask of shape
+ `(batch_size, key_value_length)`, or if the input `attention_mask` is already 4D, do nothing.
+
+ Args:
+ attention_mask (`torch.Tensor`):
+ A 2D attention mask of shape `(batch_size, key_value_length)` or a 4D attention mask of shape
+ `(batch_size, 1, query_length, key_value_length)`.
+ sequence_length (`int`):
+ The sequence length being processed.
+ target_length (`int`):
+ The target length: when generating with static cache, the mask should be as long as the static cache,
+ to account for the 0 padding, the part of the cache that is not filled yet.
+ dtype (`torch.dtype`):
+ The dtype to use for the 4D attention mask.
+ cache_position (`torch.Tensor`):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ batch_size (`torch.Tensor`):
+ Batch size.
+ """
+ if attention_mask is not None and attention_mask.dim() == 4:
+ # In this case we assume that the mask comes already in inverted form and requires no inversion or slicing.
+ causal_mask = attention_mask
+ else:
+ min_dtype = torch.finfo(dtype).min
+ causal_mask = torch.full(
+ (sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=cache_position.device
+ )
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=cache_position.device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(batch_size, 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[:, :, :, :mask_length] + attention_mask[:, None, None, :].to(
+ causal_mask.device
+ )
+ padding_mask = padding_mask == 0
+ causal_mask[:, :, :, :mask_length] = causal_mask[:, :, :, :mask_length].masked_fill(
+ padding_mask, min_dtype
+ )
+
+ return causal_mask
+
+
+__all__ = ["VideoLlavaPreTrainedModel", "VideoLlavaModel", "VideoLlavaForConditionalGeneration"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/processing_video_llava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/processing_video_llava.py
new file mode 100644
index 0000000000000000000000000000000000000000..2c7119fdc2a63662b7cf82337e4752fa2038f823
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/processing_video_llava.py
@@ -0,0 +1,200 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Processor class for VideoLlava.
+"""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...feature_extraction_utils import BatchFeature
+from ...image_utils import ImageInput, get_image_size, to_numpy_array
+from ...processing_utils import ProcessorMixin
+from ...tokenization_utils_base import PaddingStrategy, PreTokenizedInput, TextInput, TruncationStrategy
+from ...utils import TensorType, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class VideoLlavaProcessor(ProcessorMixin):
+ r"""
+ Constructs a VideoLlava processor which wraps a VideoLlava image processor and a Llava tokenizer into a single processor.
+
+ [`VideoLlavaProcessor`] offers all the functionalities of [`VideoLlavaImageProcessor`] and [`LlamaTokenizerFast`]. See the
+ [`~VideoLlavaProcessor.__call__`] and [`~VideoLlavaProcessor.decode`] for more information.
+
+ Args:
+ image_processor ([`VideoLlavaImageProcessor`], *optional*):
+ The image processor is a required input.
+ video_processor ([`VideoLlavaVideoProcessor`], *optional*):
+ The video processor is a required input.
+ tokenizer ([`LlamaTokenizerFast`], *optional*):
+ The tokenizer is a required input.
+ patch_size (`int`, *optional*, defaults to 14):
+ Patch size from the vision tower.
+ vision_feature_select_strategy (`str`, *optional*, defaults to `"default"`):
+ The feature selection strategy used to select the vision feature from the vision backbone.
+ Should be same as in model's config
+ image_token (`str`, *optional*, defaults to `""`):
+ Special token used to denote image location.
+ video_token (`str`, *optional*, defaults to `""`):
+ Special token used to denote video location.
+ chat_template (`str`, *optional*): A Jinja template which will be used to convert lists of messages
+ in a chat into a tokenizable string.
+ num_additional_image_tokens (`int`, *optional*, defaults to 1):
+ Number of additional tokens added to the image embeddings, such as CLS (+1). If the backbone has no CLS or other
+ extra tokens appended, no need to set this arg.
+ """
+
+ attributes = ["image_processor", "video_processor", "tokenizer"]
+ image_processor_class = "VideoLlavaImageProcessor"
+ video_processor_class = "AutoVideoProcessor"
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(
+ self,
+ image_processor=None,
+ video_processor=None,
+ tokenizer=None,
+ patch_size=14,
+ vision_feature_select_strategy="default",
+ image_token="", # set the default and let users change if they have peculiar special tokens in rare cases
+ video_token="",
+ chat_template=None,
+ num_additional_image_tokens=1,
+ **kwargs,
+ ):
+ self.patch_size = patch_size
+ self.num_additional_image_tokens = num_additional_image_tokens
+ self.vision_feature_select_strategy = vision_feature_select_strategy
+ self.image_token = tokenizer.image_token if hasattr(tokenizer, "image_token") else image_token
+ self.video_token = tokenizer.video_token if hasattr(tokenizer, "video_token") else video_token
+ self.image_token_id = tokenizer.convert_tokens_to_ids(self.image_token)
+ self.video_token_id = tokenizer.convert_tokens_to_ids(self.video_token)
+ super().__init__(image_processor, video_processor, tokenizer, chat_template=chat_template)
+
+ def __call__(
+ self,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ images: ImageInput = None,
+ videos: ImageInput = None,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length=None,
+ return_tensors: Optional[Union[str, TensorType]] = TensorType.PYTORCH,
+ ) -> BatchFeature:
+ """
+ Main method to prepare for the model one or several sequences(s) and image(s). This method forwards the `text`
+ and `kwargs` arguments to LlamaTokenizerFast's [`~LlamaTokenizerFast.__call__`] if `text` is not `None` to encode
+ the text. To prepare the image(s), this method forwards the `images` and `kwrags` arguments to
+ VideoLlavaImageProcessor's [`~VideoLlavaImageProcessor.__call__`] if `images` is not `None`. Please refer to the docstring
+ of the above two methods for more information.
+
+ Args:
+ text (`TextInput`, `PreTokenizedInput`, `list[TextInput]`, `list[PreTokenizedInput]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ images (`PIL.Image.Image`, `np.ndarray`, `torch.Tensor`, `list[PIL.Image.Image]`, `list[np.ndarray]`, `list[torch.Tensor]`):
+ The image or batch of images to be prepared. Each image can be a PIL image, NumPy array or PyTorch
+ tensor. In case of a NumPy array/PyTorch tensor, each image should be of shape (C, H, W), where C is a
+ number of channels, H and W are image height and width.
+ videos (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, `list[torch.Tensor]`):
+ Video frames to preprocess. Expects a single or batch of video frames in NumPy array or PyTorch
+ tensor. Each video should be of shape (T, C, H, W), where T is number of frames, C is
+ number of channels, H and W are image height and width.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding
+ index) among:
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ truncation (`bool`, *optional*):
+ Activates truncation to cut input sequences longer than `max_length` to `max_length`.
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors of a particular framework. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+
+ Returns:
+ [`BatchFeature`]: A [`BatchFeature`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`.
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not
+ `None`).
+ - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is not `None`.
+ - **pixel_values_videos** -- Pixel values to be fed to a model. Returned when `videos` is not `None`.
+ """
+
+ if isinstance(text, str):
+ text = [text]
+ elif not isinstance(text, list) and not isinstance(text[0], str):
+ raise TypeError("Invalid input text. Please provide a string, or a list of strings")
+
+ data = {}
+ if images is not None:
+ encoded_images = self.image_processor(images=images, return_tensors=return_tensors)
+ data.update(encoded_images)
+
+ height, width = get_image_size(to_numpy_array(encoded_images.get("pixel_values_images")[0]))
+ num_image_tokens = (height // self.patch_size) * (width // self.patch_size)
+ num_image_tokens += self.num_additional_image_tokens
+ if self.vision_feature_select_strategy == "default":
+ num_image_tokens -= 1
+ text = [sample.replace(self.image_token, self.image_token * num_image_tokens) for sample in text]
+
+ if videos is not None:
+ encoded_videos = self.video_processor(videos=videos, return_tensors=return_tensors)
+ data.update(encoded_videos)
+
+ one_video = encoded_videos.get("pixel_values_videos")[0]
+ if isinstance(encoded_videos.get("pixel_values_videos")[0], (list, tuple)):
+ one_video = np.array(one_video)
+ else:
+ one_video = to_numpy_array(one_video)
+ height, width = get_image_size(one_video[0])
+ num_frames = one_video.shape[0] # frame dim is always after batch dim
+
+ num_image_tokens = (height // self.patch_size) * (width // self.patch_size)
+ num_image_tokens += self.num_additional_image_tokens
+ num_video_tokens = num_image_tokens * num_frames
+ text = [sample.replace(self.video_token, self.video_token * num_video_tokens) for sample in text]
+
+ text_inputs = self.tokenizer(
+ text,
+ return_tensors=None,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ )
+ self._check_special_mm_tokens(text, text_inputs, modalities=["image", "video"])
+
+ data.update(text_inputs)
+
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["VideoLlavaProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/video_processing_video_llava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/video_processing_video_llava.py
new file mode 100644
index 0000000000000000000000000000000000000000..a05ce9303fe6c72038cc66700ee8ca08127dab58
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/video_llava/video_processing_video_llava.py
@@ -0,0 +1,57 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Video processor class for Video-LLaVA."""
+
+from ...image_utils import (
+ OPENAI_CLIP_MEAN,
+ OPENAI_CLIP_STD,
+)
+from ...processing_utils import Unpack, VideosKwargs
+from ...utils import is_vision_available
+from ...utils.import_utils import requires
+from ...video_processing_utils import (
+ BaseVideoProcessor,
+)
+
+
+if is_vision_available():
+ from ...image_utils import PILImageResampling
+
+
+class VideoLlavaFastVideoProcessorInitKwargs(VideosKwargs): ...
+
+
+@requires(backends=("torchvision",))
+class VideoLlavaVideoProcessor(BaseVideoProcessor):
+ resample = PILImageResampling.BICUBIC
+ image_mean = OPENAI_CLIP_MEAN
+ image_std = OPENAI_CLIP_STD
+ size = {"shortest_edge": 224}
+ default_to_square = False
+ crop_size = {"height": 224, "width": 224}
+ do_resize = True
+ do_center_crop = True
+ do_rescale = True
+ do_normalize = True
+ do_convert_rgb = True
+ do_sample_frames = False # Set to False for BC, recommended to set `True` in new models
+ valid_kwargs = VideoLlavaFastVideoProcessorInitKwargs
+ model_input_names = ["pixel_values_videos"]
+
+ def __init__(self, **kwargs: Unpack[VideoLlavaFastVideoProcessorInitKwargs]):
+ super().__init__(**kwargs)
+
+
+__all__ = ["VideoLlavaVideoProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..13b7f6e1bf1cb09f446df5cd8aada2e0ee942cbc
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_videomae import *
+ from .feature_extraction_videomae import *
+ from .image_processing_videomae import *
+ from .modeling_videomae import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/configuration_videomae.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/configuration_videomae.py
new file mode 100644
index 0000000000000000000000000000000000000000..3940b6f010036cb3b3957f2fad94fed50737c85d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/configuration_videomae.py
@@ -0,0 +1,148 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VideoMAE model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class VideoMAEConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VideoMAEModel`]. It is used to instantiate a
+ VideoMAE model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the VideoMAE
+ [MCG-NJU/videomae-base](https://huggingface.co/MCG-NJU/videomae-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ num_frames (`int`, *optional*, defaults to 16):
+ The number of frames in each video.
+ tubelet_size (`int`, *optional*, defaults to 2):
+ The number of tubelets.
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ use_mean_pooling (`bool`, *optional*, defaults to `True`):
+ Whether to mean pool the final hidden states instead of using the final hidden state of the [CLS] token.
+ decoder_num_attention_heads (`int`, *optional*, defaults to 6):
+ Number of attention heads for each attention layer in the decoder.
+ decoder_hidden_size (`int`, *optional*, defaults to 384):
+ Dimensionality of the decoder.
+ decoder_num_hidden_layers (`int`, *optional*, defaults to 4):
+ Number of hidden layers in the decoder.
+ decoder_intermediate_size (`int`, *optional*, defaults to 1536):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the decoder.
+ norm_pix_loss (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the target patch pixels.
+
+ Example:
+
+ ```python
+ >>> from transformers import VideoMAEConfig, VideoMAEModel
+
+ >>> # Initializing a VideoMAE videomae-base style configuration
+ >>> configuration = VideoMAEConfig()
+
+ >>> # Randomly initializing a model from the configuration
+ >>> model = VideoMAEModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "videomae"
+
+ def __init__(
+ self,
+ image_size=224,
+ patch_size=16,
+ num_channels=3,
+ num_frames=16,
+ tubelet_size=2,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ qkv_bias=True,
+ use_mean_pooling=True,
+ decoder_num_attention_heads=6,
+ decoder_hidden_size=384,
+ decoder_num_hidden_layers=4,
+ decoder_intermediate_size=1536,
+ norm_pix_loss=True,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_frames = num_frames
+ self.tubelet_size = tubelet_size
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.qkv_bias = qkv_bias
+ self.use_mean_pooling = use_mean_pooling
+
+ self.decoder_num_attention_heads = decoder_num_attention_heads
+ self.decoder_hidden_size = decoder_hidden_size
+ self.decoder_num_hidden_layers = decoder_num_hidden_layers
+ self.decoder_intermediate_size = decoder_intermediate_size
+ self.norm_pix_loss = norm_pix_loss
+
+
+__all__ = ["VideoMAEConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/feature_extraction_videomae.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/feature_extraction_videomae.py
new file mode 100644
index 0000000000000000000000000000000000000000..44a1a42a1876017f4179ca0ff810d5966a3e4f1f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/feature_extraction_videomae.py
@@ -0,0 +1,38 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Feature extractor class for VideoMAE."""
+
+import warnings
+
+from ...utils import logging
+from ...utils.import_utils import requires
+from .image_processing_videomae import VideoMAEImageProcessor
+
+
+logger = logging.get_logger(__name__)
+
+
+@requires(backends=("vision",))
+class VideoMAEFeatureExtractor(VideoMAEImageProcessor):
+ def __init__(self, *args, **kwargs) -> None:
+ warnings.warn(
+ "The class VideoMAEFeatureExtractor is deprecated and will be removed in version 5 of Transformers."
+ " Please use VideoMAEImageProcessor instead.",
+ FutureWarning,
+ )
+ super().__init__(*args, **kwargs)
+
+
+__all__ = ["VideoMAEFeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/image_processing_videomae.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/image_processing_videomae.py
new file mode 100644
index 0000000000000000000000000000000000000000..489506831913b66a7eee4c4b9ffce5104e66daac
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/image_processing_videomae.py
@@ -0,0 +1,350 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for VideoMAE."""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import (
+ get_resize_output_image_size,
+ resize,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ is_valid_image,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging
+from ...utils.import_utils import requires
+
+
+if is_vision_available():
+ import PIL
+
+
+logger = logging.get_logger(__name__)
+
+
+def make_batched(videos) -> list[list[ImageInput]]:
+ if isinstance(videos, (list, tuple)) and isinstance(videos[0], (list, tuple)) and is_valid_image(videos[0][0]):
+ return videos
+
+ elif isinstance(videos, (list, tuple)) and is_valid_image(videos[0]):
+ return [videos]
+
+ elif is_valid_image(videos):
+ return [[videos]]
+
+ raise ValueError(f"Could not make batched video from {videos}")
+
+
+@requires(backends=("vision",))
+class VideoMAEImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a VideoMAE image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by the
+ `do_resize` parameter in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"shortest_edge": 224}`):
+ Size of the output image after resizing. The shortest edge of the image will be resized to
+ `size["shortest_edge"]` while maintaining the aspect ratio of the original image. Can be overridden by
+ `size` in the `preprocess` method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the
+ `preprocess` method.
+ do_center_crop (`bool`, *optional*, defaults to `True`):
+ Whether to center crop the image to the specified `crop_size`. Can be overridden by the `do_center_crop`
+ parameter in the `preprocess` method.
+ crop_size (`dict[str, int]`, *optional*, defaults to `{"height": 224, "width": 224}`):
+ Size of the image after applying the center crop. Can be overridden by the `crop_size` parameter in the
+ `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale`
+ parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Defines the scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter
+ in the `preprocess` method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_center_crop: bool = True,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"shortest_edge": 224}
+ size = get_size_dict(size, default_to_square=False)
+ crop_size = crop_size if crop_size is not None else {"height": 224, "width": 224}
+ crop_size = get_size_dict(crop_size, param_name="crop_size")
+
+ self.do_resize = do_resize
+ self.size = size
+ self.do_center_crop = do_center_crop
+ self.crop_size = crop_size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Size of the output image. If `size` is of the form `{"height": h, "width": w}`, the output image will
+ have the size `(h, w)`. If `size` is of the form `{"shortest_edge": s}`, the output image will have its
+ shortest edge of length `s` while keeping the aspect ratio of the original image.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ Resampling filter to use when resiizing the image.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ size = get_size_dict(size, default_to_square=False)
+ if "shortest_edge" in size:
+ output_size = get_resize_output_image_size(
+ image, size["shortest_edge"], default_to_square=False, input_data_format=input_data_format
+ )
+ elif "height" in size and "width" in size:
+ output_size = (size["height"], size["width"])
+ else:
+ raise ValueError(f"Size must have 'height' and 'width' or 'shortest_edge' as keys. Got {size.keys()}")
+ return resize(
+ image,
+ size=output_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ def _preprocess_image(
+ self,
+ image: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ data_format: Optional[ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ """Preprocesses a single image."""
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ # All transformations expect numpy arrays.
+ image = to_numpy_array(image)
+
+ if do_rescale and is_scaled_image(image):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(image)
+
+ if do_resize:
+ image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+
+ if do_center_crop:
+ image = self.center_crop(image, size=crop_size, input_data_format=input_data_format)
+
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+
+ if do_normalize:
+ image = self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+
+ image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+ return image
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ videos: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after applying resize.
+ resample (`PILImageResampling`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only
+ has an effect if `do_resize` is set to `True`.
+ do_center_crop (`bool`, *optional*, defaults to `self.do_centre_crop`):
+ Whether to centre crop the image.
+ crop_size (`dict[str, int]`, *optional*, defaults to `self.crop_size`):
+ Size of the image after applying the centre crop.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the inferred channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ resample = resample if resample is not None else self.resample
+ do_center_crop = do_center_crop if do_center_crop is not None else self.do_center_crop
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+
+ size = size if size is not None else self.size
+ size = get_size_dict(size, default_to_square=False)
+ crop_size = crop_size if crop_size is not None else self.crop_size
+ crop_size = get_size_dict(crop_size, param_name="crop_size")
+
+ if not valid_images(videos):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ videos = make_batched(videos)
+
+ videos = [
+ [
+ self._preprocess_image(
+ image=img,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ for img in video
+ ]
+ for video in videos
+ ]
+
+ data = {"pixel_values": videos}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["VideoMAEImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/modeling_videomae.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/modeling_videomae.py
new file mode 100644
index 0000000000000000000000000000000000000000..335ae485289a52a3c961e339c3382bdc4cf706ea
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/videomae/modeling_videomae.py
@@ -0,0 +1,906 @@
+# coding=utf-8
+# Copyright 2022 Multimedia Computing Group, Nanjing University and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch VideoMAE (masked autoencoder) model."""
+
+import collections.abc
+from copy import deepcopy
+from dataclasses import dataclass
+from typing import Callable, Optional
+
+import numpy as np
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import MSELoss
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ImageClassifierOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import ModelOutput, TransformersKwargs, auto_docstring, logging
+from ...utils.constants import IMAGENET_DEFAULT_MEAN, IMAGENET_DEFAULT_STD
+from ...utils.generic import can_return_tuple, check_model_inputs
+from .configuration_videomae import VideoMAEConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for VideoMAEDecoder's outputs, with potential hidden states and attentions.
+ """
+)
+class VideoMAEDecoderOutput(ModelOutput):
+ r"""
+ logits (`torch.FloatTensor` of shape `(batch_size, patch_size ** 2 * num_channels)`):
+ Pixel reconstruction logits.
+ """
+
+ logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for VideoMAEForPreTraining's outputs, with potential hidden states and attentions.
+ """
+)
+class VideoMAEForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`):
+ Pixel reconstruction loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, patch_size ** 2 * num_channels)`):
+ Pixel reconstruction logits.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+# sin-cos position encoding
+# https://github.com/jadore801120/attention-is-all-you-need-pytorch/blob/master/transformer/Models.py#L31
+def get_sinusoid_encoding_table(n_position, d_hid):
+ """Sinusoid position encoding table"""
+
+ # TODO: make it with torch instead of numpy
+ def get_position_angle_vec(position):
+ return [position / np.power(10000, 2 * (hid_j // 2) / d_hid) for hid_j in range(d_hid)]
+
+ sinusoid_table = np.array([get_position_angle_vec(pos_i) for pos_i in range(n_position)])
+ sinusoid_table[:, 0::2] = np.sin(sinusoid_table[:, 0::2]) # dim 2i
+ sinusoid_table[:, 1::2] = np.cos(sinusoid_table[:, 1::2]) # dim 2i+1
+
+ return torch.FloatTensor(sinusoid_table).unsqueeze(0)
+
+
+class VideoMAEEmbeddings(nn.Module):
+ """
+ Construct the patch and position embeddings.
+
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.patch_embeddings = VideoMAEPatchEmbeddings(config)
+ self.num_patches = self.patch_embeddings.num_patches
+ # fixed sin-cos embedding
+ self.position_embeddings = get_sinusoid_encoding_table(self.num_patches, config.hidden_size)
+ self.config = config
+
+ def forward(self, pixel_values, bool_masked_pos):
+ # create patch embeddings
+ embeddings = self.patch_embeddings(pixel_values)
+
+ # add position embeddings
+ embeddings = embeddings + self.position_embeddings.detach().type_as(embeddings).to(
+ device=embeddings.device, copy=True
+ )
+ # only keep visible patches
+ # ~bool_masked_pos means visible
+ if bool_masked_pos is not None:
+ batch_size, _, num_channels = embeddings.shape
+ embeddings = embeddings[~bool_masked_pos]
+ embeddings = embeddings.reshape(batch_size, -1, num_channels)
+
+ return embeddings
+
+
+class VideoMAEPatchEmbeddings(nn.Module):
+ """
+ Video to Patch Embedding. This module turns a batch of videos of shape (batch_size, num_frames, num_channels,
+ height, width) into a tensor of shape (batch_size, seq_len, hidden_size) to be consumed by a Transformer encoder.
+
+ The seq_len (the number of patches) equals (number of frames // tubelet_size) * (height // patch_size) * (width //
+ patch_size).
+
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ image_size = config.image_size
+ patch_size = config.patch_size
+ num_channels = config.num_channels
+ hidden_size = config.hidden_size
+ num_frames = config.num_frames
+ tubelet_size = config.tubelet_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.tubelet_size = int(tubelet_size)
+ num_patches = (
+ (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0]) * (num_frames // self.tubelet_size)
+ )
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+ self.projection = nn.Conv3d(
+ in_channels=num_channels,
+ out_channels=hidden_size,
+ kernel_size=(self.tubelet_size, patch_size[0], patch_size[1]),
+ stride=(self.tubelet_size, patch_size[0], patch_size[1]),
+ )
+
+ def forward(self, pixel_values):
+ batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ )
+ if height != self.image_size[0] or width != self.image_size[1]:
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})."
+ )
+ # permute to (batch_size, num_channels, num_frames, height, width)
+ pixel_values = pixel_values.permute(0, 2, 1, 3, 4)
+ embeddings = self.projection(pixel_values).flatten(2).transpose(1, 2)
+ return embeddings
+
+
+# Copied from transformers.models.vit.modeling_vit.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class VideoMAESelfAttention(nn.Module):
+ def __init__(self, config: VideoMAEConfig) -> None:
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=False)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=False)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=False)
+
+ if config.qkv_bias:
+ self.q_bias = nn.Parameter(torch.zeros(self.all_head_size))
+ self.v_bias = nn.Parameter(torch.zeros(self.all_head_size))
+ else:
+ self.q_bias = None
+ self.v_bias = None
+
+ def forward(self, hidden_states, head_mask: Optional[torch.Tensor] = None) -> tuple[torch.Tensor, torch.Tensor]:
+ batch_size, seq_length, _ = hidden_states.shape
+
+ k_bias = torch.zeros_like(self.v_bias, requires_grad=False) if self.q_bias is not None else None
+ keys = nn.functional.linear(input=hidden_states, weight=self.key.weight, bias=k_bias)
+ values = nn.functional.linear(input=hidden_states, weight=self.value.weight, bias=self.v_bias)
+ queries = nn.functional.linear(input=hidden_states, weight=self.query.weight, bias=self.q_bias)
+
+ key_layer = keys.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ value_layer = values.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ query_layer = queries.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.reshape(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfOutput with ViT->VideoMAE
+class VideoMAESelfOutput(nn.Module):
+ """
+ The residual connection is defined in VideoMAELayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: VideoMAEConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTAttention with ViT->VideoMAE
+class VideoMAEAttention(nn.Module):
+ def __init__(self, config: VideoMAEConfig):
+ super().__init__()
+ self.attention = VideoMAESelfAttention(config)
+ self.output = VideoMAESelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads: set[int]):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ self_attn_output, _ = self.attention(hidden_states, head_mask)
+ output = self.output(self_attn_output, hidden_states)
+ return output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTIntermediate ViT->VideoMAE
+class VideoMAEIntermediate(nn.Module):
+ def __init__(self, config: VideoMAEConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTOutput ViT->VideoMAE
+class VideoMAEOutput(nn.Module):
+ def __init__(self, config: VideoMAEConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTLayer with ViT->VideoMAE,VIT->VIDEOMAE
+class VideoMAELayer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config: VideoMAEConfig):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = VideoMAEAttention(config)
+ self.intermediate = VideoMAEIntermediate(config)
+ self.output = VideoMAEOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ hidden_states_norm = self.layernorm_before(hidden_states)
+ attention_output = self.attention(hidden_states_norm, head_mask)
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in VideoMAE, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+
+ # second residual connection is done here
+ layer_output = self.output(layer_output, hidden_states)
+
+ return layer_output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTEncoder with ViT->VideoMAE
+class VideoMAEEncoder(nn.Module):
+ def __init__(self, config: VideoMAEConfig):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([VideoMAELayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> BaseModelOutput:
+ for i, layer_module in enumerate(self.layer):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ hidden_states = layer_module(hidden_states, layer_head_mask)
+
+ return BaseModelOutput(last_hidden_state=hidden_states)
+
+
+@auto_docstring
+class VideoMAEPreTrainedModel(PreTrainedModel):
+ config: VideoMAEConfig
+ base_model_prefix = "videomae"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": VideoMAELayer,
+ "attentions": VideoMAESelfAttention,
+ }
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv3d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+@auto_docstring
+class VideoMAEModel(VideoMAEPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = VideoMAEEmbeddings(config)
+ self.encoder = VideoMAEEncoder(config)
+
+ if config.use_mean_pooling:
+ self.layernorm = None
+ else:
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutput:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0). Each video in the
+ batch must have the same number of masked patches. If `None`, then all patches are considered. Sequence
+ length is `(num_frames // tubelet_size) * (image_size // patch_size) ** 2`.
+
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import numpy as np
+
+ >>> from transformers import AutoImageProcessor, VideoMAEModel
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 16 frames
+ >>> indices = sample_frame_indices(clip_len=16, frame_sample_rate=1, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container, indices)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("MCG-NJU/videomae-base")
+ >>> model = VideoMAEModel.from_pretrained("MCG-NJU/videomae-base")
+
+ >>> # prepare video for the model
+ >>> inputs = image_processor(list(video), return_tensors="pt")
+
+ >>> # forward pass
+ >>> outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ >>> list(last_hidden_states.shape)
+ [1, 1568, 768]
+ ```"""
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(pixel_values, bool_masked_pos)
+
+ encoder_outputs: BaseModelOutput = self.encoder(embedding_output, head_mask=head_mask)
+ sequence_output = encoder_outputs.last_hidden_state
+ if self.layernorm is not None:
+ sequence_output = self.layernorm(sequence_output)
+
+ return BaseModelOutput(last_hidden_state=sequence_output)
+
+
+class VideoMAEDecoder(nn.Module):
+ def __init__(self, config: VideoMAEConfig):
+ super().__init__()
+
+ decoder_num_labels = config.num_channels * config.tubelet_size * config.patch_size**2
+
+ decoder_config = deepcopy(config)
+ decoder_config.hidden_size = config.decoder_hidden_size
+ decoder_config.num_hidden_layers = config.decoder_num_hidden_layers
+ decoder_config.num_attention_heads = config.decoder_num_attention_heads
+ decoder_config.intermediate_size = config.decoder_intermediate_size
+ self.decoder_layers = nn.ModuleList(
+ [VideoMAELayer(decoder_config) for _ in range(config.decoder_num_hidden_layers)]
+ )
+
+ self.norm = nn.LayerNorm(config.decoder_hidden_size)
+ self.head = (
+ nn.Linear(config.decoder_hidden_size, decoder_num_labels) if decoder_num_labels > 0 else nn.Identity()
+ )
+
+ self.gradient_checkpointing = False
+ self.config = decoder_config
+
+ def forward(self, hidden_states: torch.Tensor, return_token_num: int):
+ # Apply transformer layers
+ for layer_module in self.decoder_layers:
+ hidden_states = layer_module(hidden_states, head_mask=None)
+
+ if return_token_num > 0:
+ hidden_states = hidden_states[:, -return_token_num:]
+
+ # predictor projection
+ hidden_states = self.norm(hidden_states)
+ logits = self.head(hidden_states)
+
+ return VideoMAEDecoderOutput(logits=logits)
+
+
+@auto_docstring(
+ custom_intro="""
+ The VideoMAE Model transformer with the decoder on top for self-supervised pre-training.
+ """
+)
+class VideoMAEForPreTraining(VideoMAEPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.videomae = VideoMAEModel(config)
+
+ self.encoder_to_decoder = nn.Linear(config.hidden_size, config.decoder_hidden_size, bias=False)
+ self.mask_token = nn.Parameter(torch.zeros(1, 1, config.decoder_hidden_size))
+ self.position_embeddings = get_sinusoid_encoding_table(
+ self.videomae.embeddings.num_patches, config.decoder_hidden_size
+ )
+
+ self.decoder = VideoMAEDecoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ bool_masked_pos: torch.BoolTensor,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> VideoMAEForPreTrainingOutput:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, sequence_length)`):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0). Each video in the
+ batch must have the same number of masked patches. Sequence length is `(num_frames // tubelet_size) *
+ (image_size // patch_size) ** 2`.
+
+ Examples:
+ ```python
+ >>> from transformers import AutoImageProcessor, VideoMAEForPreTraining
+ >>> import numpy as np
+ >>> import torch
+
+ >>> num_frames = 16
+ >>> video = list(np.random.randint(0, 256, (num_frames, 3, 224, 224)))
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("MCG-NJU/videomae-base")
+ >>> model = VideoMAEForPreTraining.from_pretrained("MCG-NJU/videomae-base")
+
+ >>> pixel_values = image_processor(video, return_tensors="pt").pixel_values
+
+ >>> num_patches_per_frame = (model.config.image_size // model.config.patch_size) ** 2
+ >>> seq_length = (num_frames // model.config.tubelet_size) * num_patches_per_frame
+ >>> bool_masked_pos = torch.randint(0, 2, (1, seq_length)).bool()
+
+ >>> outputs = model(pixel_values, bool_masked_pos=bool_masked_pos)
+ >>> loss = outputs.loss
+ ```"""
+ outputs: BaseModelOutput = self.videomae(
+ pixel_values, bool_masked_pos=bool_masked_pos, head_mask=head_mask, **kwargs
+ )
+
+ sequence_output = outputs.last_hidden_state
+ sequence_output = self.encoder_to_decoder(sequence_output)
+
+ # [batch_size, num_visible_patches, decoder_hidden_size]
+ batch_size, _, num_channels = sequence_output.shape
+
+ # we don't unshuffle the correct visible token order, but shuffle the position embeddings accordingly.
+ if bool_masked_pos is None:
+ raise ValueError("One must provided a boolean mask ")
+
+ expanded_position_embeddings = self.position_embeddings.expand(batch_size, -1, -1).type_as(pixel_values)
+ expanded_position_embeddings = expanded_position_embeddings.detach().to(device=pixel_values.device, copy=True)
+ pos_emb_visible = expanded_position_embeddings[~bool_masked_pos].reshape(batch_size, -1, num_channels)
+ pos_emb_mask = expanded_position_embeddings[bool_masked_pos].reshape(batch_size, -1, num_channels)
+
+ # [batch_size, num_patches, decoder_hidden_size]
+ x_full = torch.cat([sequence_output + pos_emb_visible, self.mask_token + pos_emb_mask], dim=1)
+
+ # [batch_size, num_masked_patches, num_channels * patch_size * patch_size]
+ decoder_outputs: VideoMAEDecoderOutput = self.decoder(x_full, pos_emb_mask.shape[1])
+ logits = decoder_outputs.logits
+
+ loss = None
+ with torch.no_grad():
+ # calculate the labels to be predicted
+ if self.config.num_channels != 3:
+ # Can't unnormalize with default means/stds
+ frames = pixel_values
+ else:
+ # first, unnormalize the frames
+ device = pixel_values.device
+ dtype = pixel_values.dtype
+ mean = torch.as_tensor(IMAGENET_DEFAULT_MEAN).to(device=device, dtype=dtype)[None, None, :, None, None]
+ std = torch.as_tensor(IMAGENET_DEFAULT_STD).to(device=device, dtype=dtype)[None, None, :, None, None]
+ frames = pixel_values * std + mean # in [0, 1]
+
+ batch_size, time, num_channels, height, width = frames.shape
+ tubelet_size, patch_size = self.config.tubelet_size, self.config.patch_size
+ if self.config.norm_pix_loss:
+ # step 1: split up dimensions (time by tubelet_size, height by patch_size, width by patch_size)
+ frames = frames.view(
+ batch_size,
+ time // tubelet_size,
+ tubelet_size,
+ num_channels,
+ height // patch_size,
+ patch_size,
+ width // patch_size,
+ patch_size,
+ )
+ # step 2: move dimensions to concatenate:
+ frames = frames.permute(0, 1, 4, 6, 2, 5, 7, 3).contiguous()
+ # step 3: concatenate:
+ frames = frames.view(
+ batch_size,
+ time // tubelet_size * height // patch_size * width // patch_size,
+ tubelet_size * patch_size * patch_size,
+ num_channels,
+ )
+ # step 4: normalize. The authors find that the mean is about 0.48 and standard deviation is about 0.08.
+ frames_norm = (frames - frames.mean(dim=-2, keepdim=True)) / (
+ frames.var(dim=-2, unbiased=True, keepdim=True).sqrt() + 1e-6
+ )
+ # step 5: reshape to (batch_size, T//ts * H//ps * W//ps, ts * ps * ps * C)
+ videos_patch = frames_norm.view(
+ batch_size,
+ time // tubelet_size * height // patch_size * width // patch_size,
+ tubelet_size * patch_size * patch_size * num_channels,
+ )
+ else:
+ if self.config.num_channels != 3:
+ raise ValueError(
+ "Can't unnormalize non-RGB images. Consider setting config.norm_pix_loss to False."
+ )
+ # step 1: split up dimensions (time by tubelet_size, height by patch_size, width by patch_size)
+ frames = frames.view(
+ batch_size,
+ time // tubelet_size,
+ tubelet_size,
+ num_channels,
+ height // patch_size,
+ patch_size,
+ width // patch_size,
+ patch_size,
+ )
+ # step 2: move dimensions to concatenate: (batch_size, T//ts, H//ps, W//ps, ts, ps, ps, C)
+ frames = frames.permute(0, 1, 4, 6, 2, 5, 7, 3).contiguous()
+ # step 3: concatenate
+ videos_patch = frames.view(
+ batch_size,
+ time // tubelet_size * height // patch_size * width // patch_size,
+ tubelet_size * patch_size * patch_size * num_channels,
+ )
+
+ batch_size, _, num_channels = videos_patch.shape
+ labels = videos_patch[bool_masked_pos].reshape(batch_size, -1, num_channels)
+
+ loss_fct = MSELoss()
+ loss = loss_fct(logits, labels)
+
+ return VideoMAEForPreTrainingOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ VideoMAE Model transformer with a video classification head on top (a linear layer on top of the average pooled hidden
+ states of all tokens) e.g. for ImageNet.
+ """
+)
+class VideoMAEForVideoClassification(VideoMAEPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.videomae = VideoMAEModel(config)
+
+ # Classifier head
+ self.fc_norm = nn.LayerNorm(config.hidden_size) if config.use_mean_pooling else None
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity()
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> ImageClassifierOutput:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import torch
+ >>> import numpy as np
+
+ >>> from transformers import AutoImageProcessor, VideoMAEForVideoClassification
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 16 frames
+ >>> indices = sample_frame_indices(clip_len=16, frame_sample_rate=1, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container, indices)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("MCG-NJU/videomae-base-finetuned-kinetics")
+ >>> model = VideoMAEForVideoClassification.from_pretrained("MCG-NJU/videomae-base-finetuned-kinetics")
+
+ >>> inputs = image_processor(list(video), return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+ ... logits = outputs.logits
+
+ >>> # model predicts one of the 400 Kinetics-400 classes
+ >>> predicted_label = logits.argmax(-1).item()
+ >>> print(model.config.id2label[predicted_label])
+ eating spaghetti
+ ```"""
+
+ outputs: BaseModelOutput = self.videomae(pixel_values, head_mask=head_mask, **kwargs)
+ sequence_output = outputs.last_hidden_state
+
+ if self.fc_norm is not None:
+ output = sequence_output.mean(1)
+ output = self.fc_norm(output)
+ else:
+ output = sequence_output[:, 0]
+
+ logits = self.classifier(output)
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(labels, logits, self.config, **kwargs)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["VideoMAEForPreTraining", "VideoMAEModel", "VideoMAEPreTrainedModel", "VideoMAEForVideoClassification"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..4f154e79e7b9985cefa83c0df78d6f3db3f70e6e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/__init__.py
@@ -0,0 +1,31 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vilt import *
+ from .feature_extraction_vilt import *
+ from .image_processing_vilt import *
+ from .image_processing_vilt_fast import *
+ from .modeling_vilt import *
+ from .processing_vilt import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/configuration_vilt.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/configuration_vilt.py
new file mode 100644
index 0000000000000000000000000000000000000000..baa30704f781864509a137a4a8424c68496b1730
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/configuration_vilt.py
@@ -0,0 +1,147 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VilT model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class ViltConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`ViLTModel`]. It is used to instantiate an ViLT
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the ViLT
+ [dandelin/vilt-b32-mlm](https://huggingface.co/dandelin/vilt-b32-mlm) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the text part of the model. Defines the number of different tokens that can be
+ represented by the `inputs_ids` passed when calling [`ViltModel`].
+ type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the `token_type_ids` passed when calling [`ViltModel`]. This is used when encoding
+ text.
+ modality_type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the modalities passed when calling [`ViltModel`]. This is used after concatenating the
+ embeddings of the text and image modalities.
+ max_position_embeddings (`int`, *optional*, defaults to 40):
+ The maximum sequence length that this model might ever be used with.
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ image_size (`int`, *optional*, defaults to 384):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 32):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ max_image_length (`int`, *optional*, defaults to -1):
+ The maximum number of patches to take as input for the Transformer encoder. If set to a positive integer,
+ the encoder will sample `max_image_length` patches at maximum. If set to -1, will not be taken into
+ account.
+ num_images (`int`, *optional*, defaults to -1):
+ The number of images to use for natural language visual reasoning. If set to a positive integer, will be
+ used by [`ViltForImagesAndTextClassification`] for defining the classifier head.
+
+ Example:
+
+ ```python
+ >>> from transformers import ViLTModel, ViLTConfig
+
+ >>> # Initializing a ViLT dandelin/vilt-b32-mlm style configuration
+ >>> configuration = ViLTConfig()
+
+ >>> # Initializing a model from the dandelin/vilt-b32-mlm style configuration
+ >>> model = ViLTModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vilt"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ type_vocab_size=2,
+ modality_type_vocab_size=2,
+ max_position_embeddings=40,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ image_size=384,
+ patch_size=32,
+ num_channels=3,
+ qkv_bias=True,
+ max_image_length=-1,
+ tie_word_embeddings=False,
+ num_images=-1,
+ **kwargs,
+ ):
+ super().__init__(tie_word_embeddings=tie_word_embeddings, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.type_vocab_size = type_vocab_size
+ self.modality_type_vocab_size = modality_type_vocab_size
+ self.max_position_embeddings = max_position_embeddings
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+ self.max_image_length = max_image_length
+ self.num_images = num_images
+
+
+__all__ = ["ViltConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/feature_extraction_vilt.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/feature_extraction_vilt.py
new file mode 100644
index 0000000000000000000000000000000000000000..e76fc89b9e8b93d7a106010d8c187ed68f8a59c0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/feature_extraction_vilt.py
@@ -0,0 +1,38 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Feature extractor class for ViLT."""
+
+import warnings
+
+from ...utils import logging
+from ...utils.import_utils import requires
+from .image_processing_vilt import ViltImageProcessor
+
+
+logger = logging.get_logger(__name__)
+
+
+@requires(backends=("vision",))
+class ViltFeatureExtractor(ViltImageProcessor):
+ def __init__(self, *args, **kwargs) -> None:
+ warnings.warn(
+ "The class ViltFeatureExtractor is deprecated and will be removed in version 5 of Transformers. Please"
+ " use ViltImageProcessor instead.",
+ FutureWarning,
+ )
+ super().__init__(*args, **kwargs)
+
+
+__all__ = ["ViltFeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/image_processing_vilt.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/image_processing_vilt.py
new file mode 100644
index 0000000000000000000000000000000000000000..6c9a727f0f9aa11662d14df5fc20d5870c30a245
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/image_processing_vilt.py
@@ -0,0 +1,492 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for Vilt."""
+
+from collections.abc import Iterable
+from typing import Any, Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import PaddingMode, pad, resize, to_channel_dimension_format
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ get_image_size,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging
+from ...utils.import_utils import requires
+
+
+if is_vision_available():
+ import PIL
+
+
+logger = logging.get_logger(__name__)
+
+
+def max_across_indices(values: Iterable[Any]) -> list[Any]:
+ """
+ Return the maximum value across all indices of an iterable of values.
+ """
+ return [max(values_i) for values_i in zip(*values)]
+
+
+def make_pixel_mask(
+ image: np.ndarray, output_size: tuple[int, int], input_data_format: Optional[Union[str, ChannelDimension]] = None
+) -> np.ndarray:
+ """
+ Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding.
+
+ Args:
+ image (`np.ndarray`):
+ Image to make the pixel mask for.
+ output_size (`tuple[int, int]`):
+ Output size of the mask.
+ """
+ input_height, input_width = get_image_size(image, channel_dim=input_data_format)
+ mask = np.zeros(output_size, dtype=np.int64)
+ mask[:input_height, :input_width] = 1
+ return mask
+
+
+def get_max_height_width(
+ images: list[np.ndarray], input_data_format: Optional[Union[str, ChannelDimension]] = None
+) -> list[int]:
+ """
+ Get the maximum height and width across all images in a batch.
+ """
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if input_data_format == ChannelDimension.FIRST:
+ _, max_height, max_width = max_across_indices([img.shape for img in images])
+ elif input_data_format == ChannelDimension.LAST:
+ max_height, max_width, _ = max_across_indices([img.shape for img in images])
+ else:
+ raise ValueError(f"Invalid channel dimension format: {input_data_format}")
+ return (max_height, max_width)
+
+
+def get_resize_output_image_size(
+ input_image: np.ndarray,
+ shorter: int = 800,
+ longer: int = 1333,
+ size_divisor: int = 32,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> tuple[int, int]:
+ input_height, input_width = get_image_size(input_image, input_data_format)
+ min_size, max_size = shorter, longer
+
+ scale = min_size / min(input_height, input_width)
+
+ if input_height < input_width:
+ new_height = min_size
+ new_width = scale * input_width
+ else:
+ new_height = scale * input_height
+ new_width = min_size
+
+ if max(new_height, new_width) > max_size:
+ scale = max_size / max(new_height, new_width)
+ new_height = scale * new_height
+ new_width = scale * new_width
+
+ new_height, new_width = int(new_height + 0.5), int(new_width + 0.5)
+ new_height = new_height // size_divisor * size_divisor
+ new_width = new_width // size_divisor * size_divisor
+
+ return new_height, new_width
+
+
+@requires(backends=("vision",))
+class ViltImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a ViLT image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by the
+ `do_resize` parameter in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"shortest_edge": 384}`):
+ Resize the shorter side of the input to `size["shortest_edge"]`. The longer side will be limited to under
+ `int((1333 / 800) * size["shortest_edge"])` while preserving the aspect ratio. Only has an effect if
+ `do_resize` is set to `True`. Can be overridden by the `size` parameter in the `preprocess` method.
+ size_divisor (`int`, *optional*, defaults to 32):
+ The size by which to make sure both the height and width can be divided. Only has an effect if `do_resize`
+ is set to `True`. Can be overridden by the `size_divisor` parameter in the `preprocess` method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`):
+ Resampling filter to use if resizing the image. Only has an effect if `do_resize` is set to `True`. Can be
+ overridden by the `resample` parameter in the `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Wwhether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the
+ `do_rescale` parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Only has an effect if `do_rescale` is set to `True`. Can be
+ overridden by the `rescale_factor` parameter in the `preprocess` method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method. Can be overridden by the `do_normalize` parameter in the `preprocess` method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. Can be
+ overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image to the `(max_height, max_width)` of the images in the batch. Can be overridden by
+ the `do_pad` parameter in the `preprocess` method.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ size_divisor: int = 32,
+ resample: PILImageResampling = PILImageResampling.BICUBIC,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_pad: bool = True,
+ **kwargs,
+ ) -> None:
+ if "pad_and_return_pixel_mask" in kwargs:
+ do_pad = kwargs.pop("pad_and_return_pixel_mask")
+
+ super().__init__(**kwargs)
+ size = size if size is not None else {"shortest_edge": 384}
+ size = get_size_dict(size, default_to_square=False)
+
+ self.do_resize = do_resize
+ self.size = size
+ self.size_divisor = size_divisor
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+ self.do_pad = do_pad
+
+ @classmethod
+ def from_dict(cls, image_processor_dict: dict[str, Any], **kwargs):
+ """
+ Overrides the `from_dict` method from the base class to make sure `pad_and_return_pixel_mask` is updated if image processor
+ is created using from_dict and kwargs e.g. `ViltImageProcessor.from_pretrained(checkpoint,
+ pad_and_return_pixel_mask=False)`
+ """
+ image_processor_dict = image_processor_dict.copy()
+ if "pad_and_return_pixel_mask" in kwargs:
+ image_processor_dict["pad_and_return_pixel_mask"] = kwargs.pop("pad_and_return_pixel_mask")
+ return super().from_dict(image_processor_dict, **kwargs)
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ size_divisor: int = 32,
+ resample: PILImageResampling = PILImageResampling.BICUBIC,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image.
+
+ Resizes the shorter side of the image to `size["shortest_edge"]` while preserving the aspect ratio. If the
+ longer side is larger than the max size `(int(`size["shortest_edge"]` * 1333 / 800))`, the longer side is then
+ resized to the max size while preserving the aspect ratio.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Controls the size of the output image. Should be of the form `{"shortest_edge": int}`.
+ size_divisor (`int`, *optional*, defaults to 32):
+ The image is resized to a size that is a multiple of this value.
+ resample (`PILImageResampling` filter, *optional*, defaults to `PILImageResampling.BICUBIC`):
+ Resampling filter to use when resiizing the image.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ size = get_size_dict(size, default_to_square=False)
+ if "shortest_edge" not in size:
+ raise ValueError(f"The `size` dictionary must contain the key `shortest_edge`. Got {size.keys()}")
+ shorter = size["shortest_edge"]
+ longer = int(1333 / 800 * shorter)
+ output_size = get_resize_output_image_size(
+ image, shorter=shorter, longer=longer, size_divisor=size_divisor, input_data_format=input_data_format
+ )
+ return resize(
+ image,
+ size=output_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ def _pad_image(
+ self,
+ image: np.ndarray,
+ output_size: tuple[int, int],
+ constant_values: Union[float, Iterable[float]] = 0,
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ """
+ Pad an image with zeros to the given size.
+ """
+ input_height, input_width = get_image_size(image, channel_dim=input_data_format)
+ output_height, output_width = output_size
+
+ pad_bottom = output_height - input_height
+ pad_right = output_width - input_width
+ padding = ((0, pad_bottom), (0, pad_right))
+ padded_image = pad(
+ image,
+ padding,
+ mode=PaddingMode.CONSTANT,
+ constant_values=constant_values,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ return padded_image
+
+ def pad(
+ self,
+ images: list[np.ndarray],
+ constant_values: Union[float, Iterable[float]] = 0,
+ return_pixel_mask: bool = True,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> BatchFeature:
+ """
+ Pads a batch of images to the bottom and right of the image with zeros to the size of largest height and width
+ in the batch and optionally returns their corresponding pixel mask.
+
+ Args:
+ image (`np.ndarray`):
+ Image to pad.
+ constant_values (`float` or `Iterable[float]`, *optional*):
+ The value to use for the padding if `mode` is `"constant"`.
+ return_pixel_mask (`bool`, *optional*, defaults to `True`):
+ Whether to return a pixel mask.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ pad_size = get_max_height_width(images, input_data_format=input_data_format)
+
+ padded_images = [
+ self._pad_image(
+ image,
+ pad_size,
+ constant_values=constant_values,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ for image in images
+ ]
+ data = {"pixel_values": padded_images}
+
+ if return_pixel_mask:
+ masks = [
+ make_pixel_mask(image=image, output_size=pad_size, input_data_format=input_data_format)
+ for image in images
+ ]
+ data["pixel_mask"] = masks
+
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ size_divisor: Optional[int] = None,
+ resample: PILImageResampling = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_pad: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Controls the size of the image after `resize`. The shortest edge of the image is resized to
+ `size["shortest_edge"]` whilst preserving the aspect ratio. If the longest edge of this resized image
+ is > `int(size["shortest_edge"] * (1333 / 800))`, then the image is resized again to make the longest
+ edge equal to `int(size["shortest_edge"] * (1333 / 800))`.
+ size_divisor (`int`, *optional*, defaults to `self.size_divisor`):
+ The image is resized to a size that is a multiple of this value.
+ resample (`PILImageResampling`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. Only has an effect if `do_resize` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to normalize the image by if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to normalize the image by if `do_normalize` is set to `True`.
+ do_pad (`bool`, *optional*, defaults to `self.do_pad`):
+ Whether to pad the image to the (max_height, max_width) in the batch. If `True`, a pixel mask is also
+ created and returned.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ size_divisor = size_divisor if size_divisor is not None else self.size_divisor
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_pad = do_pad if do_pad is not None else self.do_pad
+
+ size = size if size is not None else self.size
+ size = get_size_dict(size, default_to_square=False)
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ # Here the pad() method does not require any additional argument as it takes the maximum of (height, width).
+ # Hence, it does not need to be passed to a validate_preprocess_arguments() method.
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_resize:
+ images = [
+ self.resize(
+ image=image,
+ size=size,
+ size_divisor=size_divisor,
+ resample=resample,
+ input_data_format=input_data_format,
+ )
+ for image in images
+ ]
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_normalize:
+ images = [
+ self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images
+ ]
+
+ if do_pad:
+ encoded_outputs = self.pad(
+ images, return_pixel_mask=True, return_tensors=return_tensors, input_data_format=data_format
+ )
+ else:
+ encoded_outputs = BatchFeature(data={"pixel_values": images}, tensor_type=return_tensors)
+
+ return encoded_outputs
+
+
+__all__ = ["ViltImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/image_processing_vilt_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/image_processing_vilt_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..3e6571f159e14742fbdc2117942798d860114ee8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/image_processing_vilt_fast.py
@@ -0,0 +1,263 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for Vilt."""
+
+from typing import Optional, Union
+
+from ...image_processing_utils import BatchFeature
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ get_max_height_width,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import IMAGENET_STANDARD_MEAN, IMAGENET_STANDARD_STD, PILImageResampling, SizeDict
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+)
+
+
+if is_torch_available():
+ import torch
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+# Set maximum size based on the typical aspect ratio of the COCO dataset
+MAX_LONGER_EDGE = 1333
+MAX_SHORTER_EDGE = 800
+
+
+class ViltFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ """
+ Args:
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image. If `True`, will pad the images in the batch to the largest height and width
+ in the batch. Padding will be applied to the bottom and right with zeros.
+ size_divisor (`int`, *optional*, defaults to 32):
+ The size to make the height and width divisible by.
+ rescale_factor (`float`, *optional*, defaults to 1/255):
+ The factor to rescale the image by.
+ """
+
+ do_pad: Optional[bool]
+ size_divisor: Optional[int]
+ rescale_factor: Optional[float]
+
+
+@auto_docstring
+class ViltImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BICUBIC
+ image_mean = IMAGENET_STANDARD_MEAN
+ image_std = IMAGENET_STANDARD_STD
+ size = {"shortest_edge": 384}
+ do_resize = True
+ do_rescale = True
+ do_normalize = True
+ size_divisor = 32
+ do_pad = True
+ default_to_square = False
+ model_input_names = ["pixel_values", "pixel_mask"]
+ valid_kwargs = ViltFastImageProcessorKwargs
+
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ do_resize: bool,
+ size: SizeDict,
+ interpolation: Optional["F.InterpolationMode"],
+ size_divisor: Optional[int],
+ do_pad: bool,
+ do_rescale: bool,
+ rescale_factor: float,
+ do_normalize: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ disable_grouping: Optional[bool],
+ return_tensors: Optional[Union[str, TensorType]],
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Preprocess an image or batch of images.
+
+ This method overrides the base class method to include padding and pixel mask generation.
+ """
+ # Group images by size for batched resizing
+ grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping)
+ resized_images_grouped = {}
+
+ for shape, stacked_images in grouped_images.items():
+ if do_resize:
+ stacked_images = self.resize(stacked_images, size, interpolation, size_divisor)
+ resized_images_grouped[shape] = stacked_images
+ resized_images = reorder_images(resized_images_grouped, grouped_images_index)
+
+ # Group images by size for further processing
+ grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping)
+ processed_images_grouped = {}
+
+ for shape, stacked_images in grouped_images.items():
+ # Fused rescale and normalize
+ stacked_images = self.rescale_and_normalize(
+ stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std
+ )
+ processed_images_grouped[shape] = stacked_images
+
+ processed_images = reorder_images(processed_images_grouped, grouped_images_index)
+
+ # Handle padding if required
+ data = {}
+ if do_pad:
+ pixel_values, pixel_mask = self._pad_batch(
+ processed_images, return_tensors, disable_grouping=disable_grouping
+ )
+ data = {"pixel_values": pixel_values, "pixel_mask": pixel_mask}
+ else:
+ # If no padding, just return the processed images
+ if return_tensors == "pt":
+ processed_images = torch.stack(processed_images)
+ data = {"pixel_values": processed_images}
+
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+ def resize(
+ self,
+ images: "torch.Tensor",
+ size: SizeDict,
+ interpolation: Optional["F.InterpolationMode"] = None,
+ size_divisor: Optional[int] = None,
+ ) -> "torch.Tensor":
+ """
+ Resize an image or batch of images to specified size.
+
+ Args:
+ images (`torch.Tensor`): Image or batch of images to resize.
+ size (`dict[str, int]`): Size dictionary with shortest_edge key.
+ interpolation (`F.InterpolationMode`, *optional*): Interpolation method to use.
+ size_divisor (`int`, *optional*): Value to ensure height/width are divisible by.
+
+ Returns:
+ `torch.Tensor`: Resized image or batch of images.
+ """
+ if interpolation is None:
+ interpolation = self.resample
+
+ # Resize with aspect ratio preservation
+ shorter = size.shortest_edge
+ longer = int(MAX_LONGER_EDGE / MAX_SHORTER_EDGE * shorter)
+
+ heights = images.shape[-2]
+ widths = images.shape[-1]
+
+ # Determine the new dimensions
+ if heights < widths:
+ new_heights = shorter
+ new_widths = widths * (shorter / heights)
+ else:
+ new_heights = heights * (shorter / widths)
+ new_widths = shorter
+
+ # Check if the longer side exceeds max size
+ if max(new_heights, new_widths) > longer:
+ scale = longer / max(new_heights, new_widths)
+ new_heights = new_heights * scale
+ new_widths = new_widths * scale
+
+ new_heights = int(new_heights + 0.5)
+ new_widths = int(new_widths + 0.5)
+
+ # Make dimensions divisible by size_divisor
+ if size_divisor is not None:
+ new_heights = new_heights // size_divisor * size_divisor
+ new_widths = new_widths // size_divisor * size_divisor
+
+ # Resize the image
+ return F.resize(images, [new_heights, new_widths], interpolation=interpolation)
+
+ def _pad_batch(
+ self,
+ images: list["torch.Tensor"],
+ return_tensors: Optional[Union[str, TensorType]],
+ disable_grouping: Optional[bool],
+ ) -> tuple:
+ """
+ Pad a batch of images to the same size based on the maximum dimensions.
+
+ Args:
+ images (`list[torch.Tensor]`): List of images to pad.
+ return_tensors (`str` or `TensorType`, *optional*): The type of tensors to return.
+
+ Returns:
+ `tuple`: Tuple containing padded images and pixel masks.
+ """
+ # Calculate global maximum dimensions across all images
+ max_size = get_max_height_width(images)
+
+ # Group images by shape before padding
+ grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping)
+ processed_images = {}
+ processed_masks = {}
+
+ for shape, stacked_images in grouped_images.items():
+ # Create mask template for efficient masking
+ if return_tensors == "pt" and len(stacked_images) > 0:
+ device = stacked_images.device
+ mask_template = torch.zeros(max_size, dtype=torch.int64, device=device)
+
+ original_size = stacked_images.shape[-2:]
+ needs_padding = original_size[0] != max_size[0] or original_size[1] != max_size[1]
+
+ if needs_padding:
+ padding_bottom = max_size[0] - original_size[0]
+ padding_right = max_size[1] - original_size[1]
+ padding = [0, 0, padding_right, padding_bottom]
+
+ padded_images = F.pad(stacked_images, padding, fill=0)
+ pixel_mask = mask_template.clone()
+ pixel_mask[: original_size[0], : original_size[1]].fill_(1)
+ pixel_masks = pixel_mask.unsqueeze(0).repeat(stacked_images.shape[0], 1, 1)
+ else:
+ padded_images = stacked_images
+ pixel_masks = torch.ones(
+ (stacked_images.shape[0], max_size[0], max_size[1]),
+ dtype=torch.int64,
+ device=stacked_images.device,
+ )
+
+ # Store processed group
+ processed_images[shape] = padded_images
+ processed_masks[shape] = pixel_masks
+
+ # Reorder images back to original order
+ padded_images = reorder_images(processed_images, grouped_images_index)
+ pixel_masks = reorder_images(processed_masks, grouped_images_index)
+
+ # Stack if tensors are requested for final result
+ if return_tensors == "pt" and padded_images:
+ padded_images = torch.stack(padded_images)
+ pixel_masks = torch.stack(pixel_masks)
+
+ return padded_images, pixel_masks
+
+
+__all__ = ["ViltImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/modeling_vilt.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/modeling_vilt.py
new file mode 100644
index 0000000000000000000000000000000000000000..ed749f85362ae43a627815e9a69653d32012b76c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/modeling_vilt.py
@@ -0,0 +1,1352 @@
+# coding=utf-8
+# Copyright 2022 NAVER AI Labs and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ViLT model."""
+
+import collections.abc
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPooling,
+ MaskedLMOutput,
+ ModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, meshgrid, prune_linear_layer
+from ...utils import auto_docstring, logging
+from .configuration_vilt import ViltConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for outputs of [`ViltForImagesAndTextClassification`].
+ """
+)
+class ViltForImagesAndTextClassificationOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ hidden_states (`list[tuple(torch.FloatTensor)]`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ List of tuples of `torch.FloatTensor` (one for each image-text pair, each tuple containing the output of
+ the embeddings + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[list[tuple[torch.FloatTensor]]] = None
+ attentions: Optional[list[tuple[torch.FloatTensor]]] = None
+
+
+class ViltEmbeddings(nn.Module):
+ """
+ Construct the text and patch embeddings.
+
+ Text embeddings are equivalent to BERT embeddings.
+
+ Patch embeddings are equivalent to ViT embeddings.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ # text embeddings
+ self.text_embeddings = TextEmbeddings(config)
+ # patch embeddings
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, config.hidden_size))
+ self.patch_embeddings = ViltPatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+ self.position_embeddings = nn.Parameter(torch.zeros(1, num_patches + 1, config.hidden_size))
+ # modality type (text/patch) embeddings
+ self.token_type_embeddings = nn.Embedding(config.modality_type_vocab_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.config = config
+
+ def visual_embed(self, pixel_values, pixel_mask, max_image_length=200):
+ _, _, ph, pw = self.patch_embeddings.projection.weight.shape
+
+ x = self.patch_embeddings(pixel_values)
+ x_mask = pixel_mask[:, None, :, :].float()
+ x_mask = nn.functional.interpolate(x_mask, size=(x.shape[2], x.shape[3])).long()
+ x_h = x_mask[:, 0].sum(dim=1)[:, 0]
+ x_w = x_mask[:, 0].sum(dim=2)[:, 0]
+
+ batch_size, num_channels, height, width = x.shape
+ patch_dim = self.config.image_size // self.config.patch_size
+ spatial_pos = self.position_embeddings[:, 1:, :].transpose(1, 2).view(1, num_channels, patch_dim, patch_dim)
+ pos_embed = torch.cat(
+ [
+ nn.functional.pad(
+ nn.functional.interpolate(
+ spatial_pos,
+ size=(h, w),
+ mode="bilinear",
+ align_corners=True,
+ ),
+ (0, width - w, 0, height - h),
+ )
+ for h, w in zip(x_h, x_w)
+ ],
+ dim=0,
+ )
+
+ pos_embed = pos_embed.flatten(2).transpose(1, 2)
+ x = x.flatten(2).transpose(1, 2)
+ # Set `device` here, otherwise `patch_index` will always be on `CPU` and will fail near the end for torch>=1.13
+ patch_index = torch.stack(
+ meshgrid(torch.arange(x_mask.shape[-2]), torch.arange(x_mask.shape[-1]), indexing="ij"), dim=-1
+ ).to(device=x_mask.device)
+ patch_index = patch_index[None, None, :, :, :]
+ patch_index = patch_index.expand(x_mask.shape[0], x_mask.shape[1], -1, -1, -1)
+ patch_index = patch_index.flatten(1, 3)
+ x_mask = x_mask.flatten(1)
+
+ if max_image_length < 0 or max_image_length is None or not isinstance(max_image_length, int):
+ # suppose aug is 800 x 1333, then, maximum effective res is 800 x 1333 (if one side gets bigger, the other will be constrained and be shrunk)
+ # (800 // self.patch_size) * (1333 // self.patch_size) is the maximum number of patches that single image can get.
+ # if self.patch_size = 32, 25 * 41 = 1025
+ # if res is 384 x 640, 12 * 20 = 240
+ effective_resolution = x_h * x_w
+ max_image_length = effective_resolution.max()
+ else:
+ effective_resolution = x_h * x_w
+ max_image_length = min(effective_resolution.max(), max_image_length)
+
+ valid_idx = x_mask.nonzero(as_tuple=False)
+ non_valid_idx = (1 - x_mask).nonzero(as_tuple=False)
+ unique_rows = valid_idx[:, 0].unique()
+ valid_row_idx = [valid_idx[valid_idx[:, 0] == u] for u in unique_rows]
+ non_valid_row_idx = [non_valid_idx[non_valid_idx[:, 0] == u] for u in unique_rows]
+
+ valid_nums = [v.size(0) for v in valid_row_idx]
+ non_valid_nums = [v.size(0) for v in non_valid_row_idx]
+ pad_nums = [max_image_length - v for v in valid_nums]
+
+ select = []
+ for i, (v, nv, p) in enumerate(zip(valid_nums, non_valid_nums, pad_nums)):
+ if p <= 0:
+ valid_choice = torch.multinomial(torch.ones(v).float(), max_image_length)
+ select.append(valid_row_idx[i][valid_choice])
+ else:
+ pad_choice = torch.multinomial(torch.ones(nv).float(), p, replacement=True)
+ select.append(torch.cat([valid_row_idx[i], non_valid_row_idx[i][pad_choice]], dim=0))
+
+ select = torch.cat(select, dim=0)
+ x = x[select[:, 0], select[:, 1]].view(batch_size, -1, num_channels)
+ x_mask = x_mask[select[:, 0], select[:, 1]].view(batch_size, -1)
+ # `patch_index` should be on the same device as `select`, which is ensured at definition time.
+ patch_index = patch_index[select[:, 0], select[:, 1]].view(batch_size, -1, 2)
+ pos_embed = pos_embed[select[:, 0], select[:, 1]].view(batch_size, -1, num_channels)
+
+ cls_tokens = self.cls_token.expand(batch_size, -1, -1)
+ x = torch.cat((cls_tokens, x), dim=1)
+ pos_embed = torch.cat(
+ (self.position_embeddings[:, 0, :][:, None, :].expand(batch_size, -1, -1), pos_embed), dim=1
+ )
+ x = x + pos_embed
+ x = self.dropout(x)
+
+ x_mask = torch.cat([torch.ones(x_mask.shape[0], 1).to(x_mask), x_mask], dim=1)
+
+ return x, x_mask, (patch_index, (height, width))
+
+ def forward(
+ self,
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ pixel_values,
+ pixel_mask,
+ inputs_embeds,
+ image_embeds,
+ image_token_type_idx=1,
+ ):
+ # PART 1: text embeddings
+ text_embeds = self.text_embeddings(
+ input_ids=input_ids, token_type_ids=token_type_ids, inputs_embeds=inputs_embeds
+ )
+
+ # PART 2: patch embeddings (with interpolated position encodings)
+ if image_embeds is None:
+ image_embeds, image_masks, patch_index = self.visual_embed(
+ pixel_values, pixel_mask, max_image_length=self.config.max_image_length
+ )
+ else:
+ image_masks = pixel_mask.flatten(1)
+
+ # PART 3: add modality type embeddings
+ # 0 indicates text, 1 indicates image, 2 is optionally used when a second image is provided (NLVR2)
+ if image_token_type_idx is None:
+ image_token_type_idx = 1
+ text_embeds = text_embeds + self.token_type_embeddings(
+ torch.zeros_like(attention_mask, dtype=torch.long, device=text_embeds.device)
+ )
+ image_embeds = image_embeds + self.token_type_embeddings(
+ torch.full_like(image_masks, image_token_type_idx, dtype=torch.long, device=text_embeds.device)
+ )
+
+ # PART 4: concatenate
+ embeddings = torch.cat([text_embeds, image_embeds], dim=1)
+ masks = torch.cat([attention_mask, image_masks], dim=1)
+
+ return embeddings, masks
+
+
+class TextEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+ self.register_buffer(
+ "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False
+ )
+
+ def forward(self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None):
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs
+ # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves
+ # issue #5664
+ if token_type_ids is None:
+ if hasattr(self, "token_type_ids"):
+ buffered_token_type_ids = self.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(input_shape[0], seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class ViltPatchEmbeddings(nn.Module):
+ """
+ Image to Patch Embedding.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def forward(self, pixel_values):
+ batch_size, num_channels, height, width = pixel_values.shape
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ )
+ target_dtype = self.projection.weight.dtype
+ x = self.projection(pixel_values.to(dtype=target_dtype))
+ return x
+
+
+class ViltSelfAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(self, hidden_states, attention_mask=None, head_mask=None, output_attentions=False):
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ key_layer = (
+ self.key(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in BertModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.Softmax(dim=-1)(attention_scores)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(*new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfOutput with ViT->Vilt
+class ViltSelfOutput(nn.Module):
+ """
+ The residual connection is defined in ViltLayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: ViltConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+class ViltAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = ViltSelfAttention(config)
+ self.output = ViltSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states, attention_mask=None, head_mask=None, output_attentions=False):
+ self_outputs = self.attention(hidden_states, attention_mask, head_mask, output_attentions)
+
+ attention_output = self.output(self_outputs[0], hidden_states)
+
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTIntermediate with ViT->Vilt
+class ViltIntermediate(nn.Module):
+ def __init__(self, config: ViltConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTOutput with ViT->Vilt
+class ViltOutput(nn.Module):
+ def __init__(self, config: ViltConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+class ViltLayer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = ViltAttention(config)
+ self.intermediate = ViltIntermediate(config)
+ self.output = ViltOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, head_mask=None, output_attentions=False):
+ self_attention_outputs = self.attention(
+ self.layernorm_before(hidden_states), # in ViLT, layernorm is applied before self-attention
+ attention_mask,
+ head_mask,
+ output_attentions=output_attentions,
+ )
+ attention_output = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states.to(attention_output.device)
+
+ # in ViLT, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+
+ # second residual connection is done here
+ layer_output = self.output(layer_output, hidden_states)
+
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+
+class ViltEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([ViltLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(hidden_states, attention_mask, layer_head_mask, output_attentions)
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+@auto_docstring
+class ViltPreTrainedModel(PreTrainedModel):
+ config: ViltConfig
+ base_model_prefix = "vilt"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["ViltEmbeddings", "ViltSelfAttention"]
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+@auto_docstring
+class ViltModel(ViltPreTrainedModel):
+ def __init__(self, config, add_pooling_layer=True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = ViltEmbeddings(config)
+ self.encoder = ViltEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.pooler = ViltPooler(config) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.text_embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.text_embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ image_embeds: Optional[torch.FloatTensor] = None,
+ image_token_type_idx: Optional[int] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[BaseModelOutputWithPooling, tuple[torch.FloatTensor]]:
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, num_patches, hidden_size)`, *optional*):
+ Optionally, instead of passing `pixel_values`, you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `pixel_values` into patch embeddings.
+ image_token_type_idx (`int`, *optional*):
+ - The token type ids for images.
+
+ Examples:
+
+ ```python
+ >>> from transformers import ViltProcessor, ViltModel
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> # prepare image and text
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+ >>> text = "hello world"
+
+ >>> processor = ViltProcessor.from_pretrained("dandelin/vilt-b32-mlm")
+ >>> model = ViltModel.from_pretrained("dandelin/vilt-b32-mlm")
+
+ >>> inputs = processor(image, text, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ text_batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(((text_batch_size, seq_length)), device=device)
+
+ if pixel_values is not None and image_embeds is not None:
+ raise ValueError("You cannot specify both pixel_values and image_embeds at the same time")
+ elif pixel_values is None and image_embeds is None:
+ raise ValueError("You have to specify either pixel_values or image_embeds")
+
+ image_batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeds.shape[0]
+ if image_batch_size != text_batch_size:
+ raise ValueError("The text inputs and image inputs need to have the same batch size")
+ if pixel_mask is None:
+ pixel_mask = torch.ones((image_batch_size, self.config.image_size, self.config.image_size), device=device)
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output, attention_mask = self.embeddings(
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ pixel_values,
+ pixel_mask,
+ inputs_embeds,
+ image_embeds,
+ image_token_type_idx=image_token_type_idx,
+ )
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+ sequence_output = self.layernorm(sequence_output)
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class ViltPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states):
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+@auto_docstring(
+ custom_intro="""
+ ViLT Model with a language modeling head on top as done during pretraining.
+ """
+)
+class ViltForMaskedLM(ViltPreTrainedModel):
+ _tied_weights_keys = ["mlm_score.decoder.weight", "mlm_score.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.vilt = ViltModel(config)
+ self.mlm_score = ViltMLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.mlm_score.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.mlm_score.decoder = new_embeddings
+ self.mlm_score.bias = new_embeddings.bias
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ image_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[MaskedLMOutput, tuple[torch.FloatTensor]]:
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, num_patches, hidden_size)`, *optional*):
+ Optionally, instead of passing `pixel_values`, you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `pixel_values` into patch embeddings.
+ labels (*torch.LongTensor* of shape *(batch_size, sequence_length)*, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in *[-100, 0, ...,
+ config.vocab_size]* (see *input_ids* docstring) Tokens with indices set to *-100* are ignored (masked), the
+ loss is only computed for the tokens with labels in *[0, ..., config.vocab_size]*
+
+ Examples:
+
+ ```python
+ >>> from transformers import ViltProcessor, ViltForMaskedLM
+ >>> import requests
+ >>> from PIL import Image
+ >>> import re
+ >>> import torch
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+ >>> text = "a bunch of [MASK] laying on a [MASK]."
+
+ >>> processor = ViltProcessor.from_pretrained("dandelin/vilt-b32-mlm")
+ >>> model = ViltForMaskedLM.from_pretrained("dandelin/vilt-b32-mlm")
+
+ >>> # prepare inputs
+ >>> encoding = processor(image, text, return_tensors="pt")
+
+ >>> # forward pass
+ >>> outputs = model(**encoding)
+
+ >>> tl = len(re.findall("\[MASK\]", text))
+ >>> inferred_token = [text]
+
+ >>> # gradually fill in the MASK tokens, one by one
+ >>> with torch.no_grad():
+ ... for i in range(tl):
+ ... encoded = processor.tokenizer(inferred_token)
+ ... input_ids = torch.tensor(encoded.input_ids)
+ ... encoded = encoded["input_ids"][0][1:-1]
+ ... outputs = model(input_ids=input_ids, pixel_values=encoding.pixel_values)
+ ... mlm_logits = outputs.logits[0] # shape (seq_len, vocab_size)
+ ... # only take into account text features (minus CLS and SEP token)
+ ... mlm_logits = mlm_logits[1 : input_ids.shape[1] - 1, :]
+ ... mlm_values, mlm_ids = mlm_logits.softmax(dim=-1).max(dim=-1)
+ ... # only take into account text
+ ... mlm_values[torch.tensor(encoded) != 103] = 0
+ ... select = mlm_values.argmax().item()
+ ... encoded[select] = mlm_ids[select].item()
+ ... inferred_token = [processor.decode(encoded)]
+
+ >>> selected_token = ""
+ >>> encoded = processor.tokenizer(inferred_token)
+ >>> output = processor.decode(encoded.input_ids[0], skip_special_tokens=True)
+ >>> print(output)
+ a bunch of cats laying on a couch.
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.vilt(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ pixel_values=pixel_values,
+ pixel_mask=pixel_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ image_embeds=image_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output, pooled_output = outputs[:2]
+ # split up final hidden states into text and image features
+ text_seq_len = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+ text_features, _ = (sequence_output[:, :text_seq_len], sequence_output[:, text_seq_len:])
+
+ mlm_logits = self.mlm_score(text_features)
+
+ masked_lm_loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss() # -100 index = padding token
+ # move labels to correct device to enable PP
+ labels = labels.to(mlm_logits.device)
+ masked_lm_loss = loss_fct(mlm_logits.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (mlm_logits,) + outputs[2:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return MaskedLMOutput(
+ loss=masked_lm_loss,
+ logits=mlm_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class ViltPredictionHeadTransform(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ if isinstance(config.hidden_act, str):
+ self.transform_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.transform_act_fn = config.hidden_act
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.transform_act_fn(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states)
+ return hidden_states
+
+
+class ViltMLMHead(nn.Module):
+ def __init__(self, config, weight=None):
+ super().__init__()
+ self.config = config
+ self.transform = ViltPredictionHeadTransform(config)
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+ if weight is not None:
+ self.decoder.weight = weight
+
+ # Need a link between the two variables so that the bias is correctly resized with `resize_token_embeddings`
+ self.decoder.bias = self.bias
+
+ def _tie_weights(self):
+ self.decoder.bias = self.bias
+
+ def forward(self, x):
+ x = self.transform(x)
+ x = self.decoder(x)
+ return x
+
+
+@auto_docstring(
+ custom_intro="""
+ Vilt Model transformer with a classifier head on top (a linear layer on top of the final hidden state of the [CLS]
+ token) for visual question answering, e.g. for VQAv2.
+ """
+)
+class ViltForQuestionAnswering(ViltPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.vilt = ViltModel(config)
+
+ # Classifier head
+ self.classifier = nn.Sequential(
+ nn.Linear(config.hidden_size, config.hidden_size * 2),
+ nn.LayerNorm(config.hidden_size * 2),
+ nn.GELU(),
+ nn.Linear(config.hidden_size * 2, config.num_labels),
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ image_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[SequenceClassifierOutput, tuple[torch.FloatTensor]]:
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, num_patches, hidden_size)`, *optional*):
+ Optionally, instead of passing `pixel_values`, you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `pixel_values` into patch embeddings.
+ labels (`torch.FloatTensor` of shape `(batch_size, num_labels)`, *optional*):
+ Labels for computing the visual question answering loss. This tensor must be either a one-hot encoding of
+ all answers that are applicable for a given example in the batch, or a soft encoding indicating which
+ answers are applicable, where 1.0 is the highest score.
+
+ Examples:
+
+ ```python
+ >>> from transformers import ViltProcessor, ViltForQuestionAnswering
+ >>> import requests
+ >>> from PIL import Image
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+ >>> text = "How many cats are there?"
+
+ >>> processor = ViltProcessor.from_pretrained("dandelin/vilt-b32-finetuned-vqa")
+ >>> model = ViltForQuestionAnswering.from_pretrained("dandelin/vilt-b32-finetuned-vqa")
+
+ >>> # prepare inputs
+ >>> encoding = processor(image, text, return_tensors="pt")
+
+ >>> # forward pass
+ >>> outputs = model(**encoding)
+ >>> logits = outputs.logits
+ >>> idx = logits.argmax(-1).item()
+ >>> print("Predicted answer:", model.config.id2label[idx])
+ Predicted answer: 2
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.vilt(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ pixel_values=pixel_values,
+ pixel_mask=pixel_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ image_embeds=image_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooler_output = outputs.pooler_output if return_dict else outputs[1]
+
+ logits = self.classifier(pooler_output)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable PP
+ labels = labels.to(logits.device)
+ loss = nn.functional.binary_cross_entropy_with_logits(logits, labels) * labels.shape[1]
+ # see https://github.com/jnhwkim/ban-vqa/blob/master/train.py#L19
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Vilt Model transformer with a classifier head on top (a linear layer on top of the final hidden state of the [CLS]
+ token) for image-to-text or text-to-image retrieval, e.g. MSCOCO and F30K.
+ """
+)
+class ViltForImageAndTextRetrieval(ViltPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.vilt = ViltModel(config)
+
+ # Classifier head
+ self.rank_output = nn.Linear(config.hidden_size, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ image_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[SequenceClassifierOutput, tuple[torch.FloatTensor]]:
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, num_patches, hidden_size)`, *optional*):
+ Optionally, instead of passing `pixel_values`, you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `pixel_values` into patch embeddings.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels are currently not supported.
+
+ Examples:
+
+ ```python
+ >>> from transformers import ViltProcessor, ViltForImageAndTextRetrieval
+ >>> import requests
+ >>> from PIL import Image
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+ >>> texts = ["An image of two cats chilling on a couch", "A football player scoring a goal"]
+
+ >>> processor = ViltProcessor.from_pretrained("dandelin/vilt-b32-finetuned-coco")
+ >>> model = ViltForImageAndTextRetrieval.from_pretrained("dandelin/vilt-b32-finetuned-coco")
+
+ >>> # forward pass
+ >>> scores = dict()
+ >>> for text in texts:
+ ... # prepare inputs
+ ... encoding = processor(image, text, return_tensors="pt")
+ ... outputs = model(**encoding)
+ ... scores[text] = outputs.logits[0, :].item()
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ loss = None
+ if labels is not None:
+ raise NotImplementedError("Training is not yet supported.")
+
+ outputs = self.vilt(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ pixel_values=pixel_values,
+ pixel_mask=pixel_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ image_embeds=image_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooler_output = outputs.pooler_output if return_dict else outputs[1]
+
+ logits = self.rank_output(pooler_output)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Vilt Model transformer with a classifier head on top for natural language visual reasoning, e.g. NLVR2.
+ """
+)
+class ViltForImagesAndTextClassification(ViltPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.vilt = ViltModel(config)
+
+ # Classifier head
+ num_images = config.num_images
+ self.classifier = nn.Sequential(
+ nn.Linear(config.hidden_size * num_images, config.hidden_size * num_images),
+ nn.LayerNorm(config.hidden_size * num_images),
+ nn.GELU(),
+ nn.Linear(config.hidden_size * num_images, config.num_labels),
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ image_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[ViltForImagesAndTextClassificationOutput, tuple[torch.FloatTensor]]:
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, num_patches, hidden_size)`, *optional*):
+ Optionally, instead of passing `pixel_values`, you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `pixel_values` into patch embeddings.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Binary classification labels.
+
+ Examples:
+
+ ```python
+ >>> from transformers import ViltProcessor, ViltForImagesAndTextClassification
+ >>> import requests
+ >>> from PIL import Image
+
+ >>> image1 = Image.open(requests.get("https://lil.nlp.cornell.edu/nlvr/exs/ex0_0.jpg", stream=True).raw)
+ >>> image2 = Image.open(requests.get("https://lil.nlp.cornell.edu/nlvr/exs/ex0_1.jpg", stream=True).raw)
+ >>> text = "The left image contains twice the number of dogs as the right image."
+
+ >>> processor = ViltProcessor.from_pretrained("dandelin/vilt-b32-finetuned-nlvr2")
+ >>> model = ViltForImagesAndTextClassification.from_pretrained("dandelin/vilt-b32-finetuned-nlvr2")
+
+ >>> # prepare inputs
+ >>> encoding = processor([image1, image2], text, return_tensors="pt")
+
+ >>> # forward pass
+ >>> outputs = model(input_ids=encoding.input_ids, pixel_values=encoding.pixel_values.unsqueeze(0))
+ >>> logits = outputs.logits
+ >>> idx = logits.argmax(-1).item()
+ >>> print("Predicted answer:", model.config.id2label[idx])
+ Predicted answer: True
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is not None and pixel_values.ndim == 4:
+ # add dummy num_images dimension
+ pixel_values = pixel_values.unsqueeze(1)
+
+ if image_embeds is not None and image_embeds.ndim == 3:
+ # add dummy num_images dimension
+ image_embeds = image_embeds.unsqueeze(1)
+
+ num_images = pixel_values.shape[1] if pixel_values is not None else None
+ if num_images is None:
+ num_images = image_embeds.shape[1] if image_embeds is not None else None
+ if num_images != self.config.num_images:
+ raise ValueError(
+ "Make sure to match the number of images in the model with the number of images in the input."
+ )
+ pooler_outputs = []
+ hidden_states = [] if output_hidden_states else None
+ attentions = [] if output_attentions else None
+ for i in range(num_images):
+ # forward every image through the model
+ outputs = self.vilt(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ pixel_values=pixel_values[:, i, :, :, :] if pixel_values is not None else None,
+ pixel_mask=pixel_mask[:, i, :, :] if pixel_mask is not None else None,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ image_embeds=image_embeds[:, i, :, :] if image_embeds is not None else None,
+ image_token_type_idx=i + 1,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ pooler_output = outputs.pooler_output if return_dict else outputs[1]
+ pooler_outputs.append(pooler_output)
+ if output_hidden_states:
+ hidden_states.append(outputs.hidden_states)
+ if output_attentions:
+ attentions.append(outputs.attentions)
+
+ pooled_output = torch.cat(pooler_outputs, dim=-1)
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ # move labels to correct device to enable PP
+ labels = labels.to(logits.device)
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits, hidden_states, attentions)
+ return ((loss,) + output) if loss is not None else output
+
+ return ViltForImagesAndTextClassificationOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=hidden_states,
+ attentions=attentions,
+ )
+
+
+@auto_docstring
+class ViltForTokenClassification(ViltPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.vilt = ViltModel(config, add_pooling_layer=False)
+
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ pixel_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ image_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[TokenClassifierOutput, tuple[torch.FloatTensor]]:
+ r"""
+ image_embeds (`torch.FloatTensor` of shape `(batch_size, num_patches, hidden_size)`, *optional*):
+ Optionally, instead of passing `pixel_values`, you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `pixel_values` into patch embeddings.
+ labels (`torch.LongTensor` of shape `(batch_size, text_sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.vilt(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ pixel_values=pixel_values,
+ pixel_mask=pixel_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ image_embeds=image_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ text_input_size = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ sequence_output = self.dropout(sequence_output)
+ logits = self.classifier(sequence_output[:, :text_input_size])
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ # move labels to correct device to enable PP
+ labels = labels.to(logits.device)
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "ViltForImageAndTextRetrieval",
+ "ViltForImagesAndTextClassification",
+ "ViltForTokenClassification",
+ "ViltForMaskedLM",
+ "ViltForQuestionAnswering",
+ "ViltLayer",
+ "ViltModel",
+ "ViltPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/processing_vilt.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/processing_vilt.py
new file mode 100644
index 0000000000000000000000000000000000000000..91cc5c17561dff5dbdc83a23f170e57960fc2808
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vilt/processing_vilt.py
@@ -0,0 +1,131 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Processor class for ViLT.
+"""
+
+import warnings
+from typing import Optional, Union
+
+from ...processing_utils import ProcessorMixin
+from ...tokenization_utils_base import BatchEncoding, PaddingStrategy, PreTokenizedInput, TextInput, TruncationStrategy
+from ...utils import TensorType
+
+
+class ViltProcessor(ProcessorMixin):
+ r"""
+ Constructs a ViLT processor which wraps a BERT tokenizer and ViLT image processor into a single processor.
+
+ [`ViltProcessor`] offers all the functionalities of [`ViltImageProcessor`] and [`BertTokenizerFast`]. See the
+ docstring of [`~ViltProcessor.__call__`] and [`~ViltProcessor.decode`] for more information.
+
+ Args:
+ image_processor (`ViltImageProcessor`, *optional*):
+ An instance of [`ViltImageProcessor`]. The image processor is a required input.
+ tokenizer (`BertTokenizerFast`, *optional*):
+ An instance of ['BertTokenizerFast`]. The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+ image_processor_class = "ViltImageProcessor"
+ tokenizer_class = ("BertTokenizer", "BertTokenizerFast")
+
+ def __init__(self, image_processor=None, tokenizer=None, **kwargs):
+ feature_extractor = None
+ if "feature_extractor" in kwargs:
+ warnings.warn(
+ "The `feature_extractor` argument is deprecated and will be removed in v5, use `image_processor`"
+ " instead.",
+ FutureWarning,
+ )
+ feature_extractor = kwargs.pop("feature_extractor")
+
+ image_processor = image_processor if image_processor is not None else feature_extractor
+ if image_processor is None:
+ raise ValueError("You need to specify an `image_processor`.")
+ if tokenizer is None:
+ raise ValueError("You need to specify a `tokenizer`.")
+
+ super().__init__(image_processor, tokenizer)
+ self.current_processor = self.image_processor
+
+ def __call__(
+ self,
+ images,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ add_special_tokens: bool = True,
+ padding: Union[bool, str, PaddingStrategy] = False,
+ truncation: Union[bool, str, TruncationStrategy] = None,
+ max_length: Optional[int] = None,
+ stride: int = 0,
+ pad_to_multiple_of: Optional[int] = None,
+ return_token_type_ids: Optional[bool] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_overflowing_tokens: bool = False,
+ return_special_tokens_mask: bool = False,
+ return_offsets_mapping: bool = False,
+ return_length: bool = False,
+ verbose: bool = True,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ This method uses [`ViltImageProcessor.__call__`] method to prepare image(s) for the model, and
+ [`BertTokenizerFast.__call__`] to prepare text for the model.
+
+ Please refer to the docstring of the above two methods for more information.
+ """
+ encoding = self.tokenizer(
+ text=text,
+ add_special_tokens=add_special_tokens,
+ padding=padding,
+ truncation=truncation,
+ max_length=max_length,
+ stride=stride,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_token_type_ids=return_token_type_ids,
+ return_attention_mask=return_attention_mask,
+ return_overflowing_tokens=return_overflowing_tokens,
+ return_special_tokens_mask=return_special_tokens_mask,
+ return_offsets_mapping=return_offsets_mapping,
+ return_length=return_length,
+ verbose=verbose,
+ return_tensors=return_tensors,
+ **kwargs,
+ )
+ # add pixel_values + pixel_mask
+ encoding_image_processor = self.image_processor(images, return_tensors=return_tensors)
+ encoding.update(encoding_image_processor)
+
+ return encoding
+
+ @property
+ def feature_extractor_class(self):
+ warnings.warn(
+ "`feature_extractor_class` is deprecated and will be removed in v5. Use `image_processor_class` instead.",
+ FutureWarning,
+ )
+ return self.image_processor_class
+
+ @property
+ def feature_extractor(self):
+ warnings.warn(
+ "`feature_extractor` is deprecated and will be removed in v5. Use `image_processor` instead.",
+ FutureWarning,
+ )
+ return self.image_processor
+
+
+__all__ = ["ViltProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..2ff5c6838dfaff4eb96663c6e2a808e5f082f0de
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vipllava import *
+ from .modeling_vipllava import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/configuration_vipllava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/configuration_vipllava.py
new file mode 100644
index 0000000000000000000000000000000000000000..cdeb7823ad4638951f2569849612d88aa1552a00
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/configuration_vipllava.py
@@ -0,0 +1,122 @@
+# coding=utf-8
+# Copyright 2023 Microsoft Research & University of Wisconsin-Madison and the HuggingFace Inc. team. All rights reserved.
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VipLlava model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ..auto import CONFIG_MAPPING, AutoConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class VipLlavaConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VipLlavaForConditionalGeneration`]. It is used to instantiate an
+ VipLlava model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the VipLlava-9B.
+
+ e.g. [ybelkada/vip-llava-7b-hf](https://huggingface.co/ybelkada/vip-llava-7b-hf)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vision_config (`VipLlavaVisionConfig`, *optional*):
+ Custom vision config or dict
+ text_config (`Union[AutoConfig, dict]`, *optional*):
+ The config object of the text backbone. Can be any of `LlamaConfig` or `MistralConfig`.
+ image_token_index (`int`, *optional*, defaults to 32000):
+ The image token index to encode the image prompt.
+ projector_hidden_act (`str`, *optional*, defaults to `"gelu"`):
+ The activation function used by the multimodal projector.
+ projector_layernorm_eps (`float`, *optional*, defaults to 1e-05):
+ The layer norm epsilon of the projector layernorm
+ vision_feature_layers (`Union[int, list[int]]`, *optional*, defaults to `[-2, -5, -8, -11, 6]`):
+ The vision feature layer, or list of layers to select the vision features from.
+ image_seq_length (`int`, *optional*, defaults to 576):
+ Sequence length of one image embedding.
+
+ Example:
+
+ ```python
+ >>> from transformers import VipLlavaForConditionalGeneration, VipLlavaConfig, CLIPVisionConfig, LlamaConfig
+
+ >>> # Initializing a CLIP-vision config
+ >>> vision_config = CLIPVisionConfig()
+
+ >>> # Initializing a Llama config
+ >>> text_config = LlamaConfig()
+
+ >>> # Initializing a VipLlava vipllava-7b style configuration
+ >>> configuration = VipLlavaConfig(vision_config, text_config)
+
+ >>> # Initializing a model from the vipllava-7b style configuration
+ >>> model = VipLlavaForConditionalGeneration(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vipllava"
+ attribute_map = {
+ "image_token_id": "image_token_index",
+ }
+ sub_configs = {"text_config": AutoConfig, "vision_config": AutoConfig}
+
+ def __init__(
+ self,
+ vision_config=None,
+ text_config=None,
+ image_token_index=32000,
+ projector_hidden_act="gelu",
+ projector_layernorm_eps=1e-5,
+ vision_feature_layers=[-2, -5, -8, -11, 6],
+ image_seq_length=576,
+ **kwargs,
+ ):
+ self.image_token_index = image_token_index
+ self.projector_hidden_act = projector_hidden_act
+ self.projector_layernorm_eps = projector_layernorm_eps
+ self.vision_feature_layers = vision_feature_layers
+ self.image_seq_length = image_seq_length
+ self.vision_config = vision_config
+
+ if isinstance(self.vision_config, dict):
+ vision_config["model_type"] = vision_config.get("model_type", "clip_vision_model")
+ self.vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config)
+ elif vision_config is None:
+ self.vision_config = CONFIG_MAPPING["clip_vision_model"](
+ intermediate_size=4096,
+ hidden_size=1024,
+ patch_size=14,
+ image_size=336,
+ num_hidden_layers=24,
+ num_attention_heads=16,
+ vocab_size=32000,
+ projection_dim=768,
+ )
+
+ if isinstance(text_config, dict):
+ text_config["model_type"] = text_config.get("model_type", "llama")
+ text_config = CONFIG_MAPPING[text_config["model_type"]](**text_config)
+ elif text_config is None:
+ text_config = CONFIG_MAPPING["llama"]()
+
+ self.text_config = text_config
+
+ super().__init__(**kwargs)
+
+
+__all__ = ["VipLlavaConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/modeling_vipllava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/modeling_vipllava.py
new file mode 100644
index 0000000000000000000000000000000000000000..f435e8b75fc0ab5105415263b7edcfe6b2d23edd
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/modeling_vipllava.py
@@ -0,0 +1,464 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/vipllava/modular_vipllava.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_vipllava.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2023 the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache
+from ...generation import GenerationMixin
+from ...modeling_outputs import BaseModelOutputWithPast, ModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, can_return_tuple
+from ..auto import AutoModel
+from .configuration_vipllava import VipLlavaConfig
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for VipLlava outputs, with hidden states and attentions.
+ """
+)
+class VipLlavaModelOutputWithPast(BaseModelOutputWithPast):
+ r"""
+ past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`)
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see
+ `past_key_values` input) to speed up sequential decoding.
+ image_hidden_states (`torch.FloatTensor`, *optional*):
+ A `torch.FloatTensor` of size `(batch_size, num_images, sequence_length, hidden_size)`.
+ image_hidden_states of the model produced by the vision encoder and after projecting the last hidden state.
+ """
+
+ image_hidden_states: Optional[torch.FloatTensor] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for VipLlava causal language model (or autoregressive) outputs.
+ """
+)
+class VipLlavaCausalLMOutputWithPast(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Language modeling loss (for next-token prediction).
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+ past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`)
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see
+ `past_key_values` input) to speed up sequential decoding.
+ image_hidden_states (`torch.FloatTensor`, *optional*):
+ A `torch.FloatTensor` of size `(batch_size, num_images, sequence_length, hidden_size)`.
+ image_hidden_states of the model produced by the vision encoder and after projecting the last hidden state.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ past_key_values: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ image_hidden_states: Optional[torch.FloatTensor] = None
+
+
+class VipLlavaMultiModalProjector(nn.Module):
+ def __init__(self, config: VipLlavaConfig):
+ super().__init__()
+ num_feature_layers = 1 if isinstance(config.vision_feature_layers, int) else len(config.vision_feature_layers)
+ self.projector_layernorm = nn.LayerNorm(
+ num_feature_layers * config.vision_config.hidden_size, eps=config.projector_layernorm_eps
+ )
+
+ self.linear_1 = nn.Linear(
+ num_feature_layers * config.vision_config.hidden_size,
+ config.text_config.hidden_size,
+ bias=True,
+ )
+ self.act = ACT2FN[config.projector_hidden_act]
+ self.linear_2 = nn.Linear(config.text_config.hidden_size, config.text_config.hidden_size, bias=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.projector_layernorm(hidden_states)
+ hidden_states = self.linear_1(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+ return hidden_states
+
+
+@auto_docstring
+class VipLlavaPreTrainedModel(PreTrainedModel):
+ config: VipLlavaConfig
+ base_model_prefix = ""
+ supports_gradient_checkpointing = True
+ _skip_keys_device_placement = "past_key_values"
+
+ _supports_flash_attn = True
+ _supports_sdpa = True
+
+ _can_compile_fullgraph = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+
+
+@auto_docstring(
+ custom_intro="""
+ The VipLlava model which consists of a vision backbone and a language model, without a language modeling head.
+ """
+)
+class VipLlavaModel(VipLlavaPreTrainedModel):
+ _checkpoint_conversion_mapping = {"language_model.model": "language_model"}
+
+ def __init__(self, config: VipLlavaConfig):
+ super().__init__(config)
+ self.vision_tower = AutoModel.from_config(config.vision_config)
+
+ self.multi_modal_projector = VipLlavaMultiModalProjector(config)
+ self.language_model = AutoModel.from_config(config.text_config)
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.language_model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.language_model.set_input_embeddings(value)
+
+ def set_decoder(self, decoder):
+ self.language_model = decoder
+
+ def get_decoder(self):
+ return self.language_model
+
+ def get_image_features(
+ self, pixel_values: torch.FloatTensor, vision_feature_layers: Optional[Union[int, list[int]]] = None
+ ):
+ """
+ Obtains image last hidden states from the vision tower and apply multimodal projection.
+
+ Args:
+ pixel_values (`torch.FloatTensor]` of shape `(batch_size, channels, height, width)`)
+ The tensors corresponding to the input images.
+ vision_feature_layers (`Union[int, list[int]]`):
+ The vision feature layer, or the list of indexes of the layers to select
+ the vision feature.
+ Returns:
+ image_features (`torch.Tensor`): Image feature tensor of shape `(num_images, image_length, embed_dim)`).
+ """
+ vision_feature_layers = (
+ vision_feature_layers if vision_feature_layers is not None else self.config.vision_feature_layers
+ )
+ image_outputs = self.vision_tower(pixel_values, output_hidden_states=True)
+
+ # If multiple feature layers are provided (which is usually the case)
+ # then the image features are concatenated after the CLS is removed.
+ if isinstance(vision_feature_layers, int):
+ image_features = image_outputs.hidden_states[vision_feature_layers][:, 1:]
+ else:
+ # Usually, we select the features from index 1: the layers -2, -5, -8, -11 and 6
+ image_features = [image_outputs.hidden_states[index][:, 1:] for index in vision_feature_layers]
+ image_features = torch.cat(image_features, dim=-1)
+ image_features = self.multi_modal_projector(image_features)
+ return image_features
+
+ def get_placeholder_mask(
+ self, input_ids: torch.LongTensor, inputs_embeds: torch.FloatTensor, image_features: torch.FloatTensor
+ ):
+ """
+ Obtains multimodal placeholder mask from `input_ids` or `inputs_embeds`, and checks that the placeholder token count is
+ equal to the length of multimodal features. If the lengths are different, an error is raised.
+ """
+ if input_ids is None:
+ special_image_mask = inputs_embeds == self.get_input_embeddings()(
+ torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device)
+ )
+ special_image_mask = special_image_mask.all(-1)
+ else:
+ special_image_mask = input_ids == self.config.image_token_id
+
+ n_image_tokens = special_image_mask.sum()
+ special_image_mask = special_image_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device)
+ n_image_features = image_features.shape[0] * image_features.shape[1]
+ if inputs_embeds[special_image_mask].numel() != image_features.numel():
+ raise ValueError(
+ f"Image features and image tokens do not match: tokens: {n_image_tokens}, features {n_image_features}"
+ )
+ return special_image_mask
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ vision_feature_layers: Optional[Union[int, list[int]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **lm_kwargs,
+ ) -> Union[tuple, VipLlavaModelOutputWithPast]:
+ r"""
+ vision_feature_layers (`Union[int, list[int]]`, *optional*):
+ The vision feature layer, or the list of indexes of the layers to select
+ the vision feature.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ vision_feature_layers = (
+ vision_feature_layers if vision_feature_layers is not None else self.config.vision_feature_layers
+ )
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.get_input_embeddings()(input_ids)
+
+ if pixel_values is not None:
+ image_features = self.get_image_features(
+ pixel_values=pixel_values, vision_feature_layers=vision_feature_layers
+ )
+ image_features = image_features.to(inputs_embeds.device, inputs_embeds.dtype)
+ special_image_mask = self.get_placeholder_mask(
+ input_ids, inputs_embeds=inputs_embeds, image_features=image_features
+ )
+ inputs_embeds = inputs_embeds.masked_scatter(special_image_mask, image_features)
+
+ outputs = self.language_model(
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **lm_kwargs,
+ )
+
+ output = VipLlavaModelOutputWithPast(
+ last_hidden_state=outputs.last_hidden_state,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=image_features if pixel_values is not None else None,
+ )
+ return output if return_dict else output.to_tuple()
+
+
+@auto_docstring(
+ custom_intro="""
+ The VIPLLAVA model which consists of a vision backbone and a language model.
+ """
+)
+class VipLlavaForConditionalGeneration(VipLlavaPreTrainedModel, GenerationMixin):
+ _checkpoint_conversion_mapping = {
+ "^language_model.model": "model.language_model",
+ "^vision_tower": "model.vision_tower",
+ "^multi_modal_projector": "model.multi_modal_projector",
+ "^language_model.lm_head": "lm_head",
+ }
+ _tied_weights_keys = ["lm_head.weight"]
+
+ def __init__(self, config: VipLlavaConfig):
+ super().__init__(config)
+ self.model = VipLlavaModel(config)
+ self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False)
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.set_input_embeddings(value)
+
+ def get_output_embeddings(self) -> nn.Module:
+ return self.lm_head
+
+ def set_decoder(self, decoder):
+ self.model.set_decoder(decoder)
+
+ def get_decoder(self):
+ return self.model.get_decoder()
+
+ def get_image_features(
+ self, pixel_values: torch.FloatTensor, vision_feature_layers: Optional[Union[int, list[int]]] = None
+ ):
+ return self.model.get_image_features(pixel_values=pixel_values, vision_feature_layers=vision_feature_layers)
+
+ # Make modules available through conditional class for BC
+ @property
+ def language_model(self):
+ return self.model.language_model
+
+ @property
+ def vision_tower(self):
+ return self.model.vision_tower
+
+ @property
+ def multi_modal_projector(self):
+ return self.model.multi_modal_projector
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ vision_feature_layers: Optional[Union[int, list[int]]] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **lm_kwargs,
+ ) -> Union[tuple, VipLlavaCausalLMOutputWithPast]:
+ r"""
+ vision_feature_layers (`Union[int, list[int]]`, *optional*):
+ The vision feature layer, or the list of indexes of the layers to select
+ the vision feature.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, VipLlavaForConditionalGeneration
+
+ >>> model = VipLlavaForConditionalGeneration.from_pretrained("llava-hf/vip-llava-7b-hf", device_map="auto", dtype=torch.float16)
+ >>> processor = AutoProcessor.from_pretrained("llava-hf/vip-llava-7b-hf")
+
+ >>> prompt = "A chat between a curious human and an artificial intelligence assistant. The assistant gives helpful, detailed, and polite answers to the human's questions.###Human: \n{}###Assistant:"
+ >>> question = "Can you please describe this image?"
+ >>> prompt = prompt.format(question)
+ >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/compel-neg.png"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(text=text, images=image, return_tensors="pt").to(0, torch.float16)
+
+ >>> # Generate
+ >>> generate_ids = model.generate(**inputs, max_new_tokens=20)
+ >>> processor.decode(generate_ids[0][len(inputs["input_ids"][0]):], skip_special_tokens=True)
+ The image features a brown and white cat sitting on a green surface, with a red ball in its
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ vision_feature_layers = (
+ vision_feature_layers if vision_feature_layers is not None else self.config.vision_feature_layers
+ )
+
+ outputs = self.model(
+ input_ids=input_ids,
+ pixel_values=pixel_values,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ vision_feature_layers=vision_feature_layers,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **lm_kwargs,
+ )
+
+ hidden_states = outputs[0]
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.text_config.vocab_size)
+
+ return VipLlavaCausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=outputs.image_hidden_states,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ past_key_values=None,
+ inputs_embeds=None,
+ pixel_values=None,
+ attention_mask=None,
+ cache_position=None,
+ logits_to_keep=None,
+ **kwargs,
+ ):
+ # Overwritten -- in specific circumstances we don't want to forward image inputs to the model
+
+ model_inputs = super().prepare_inputs_for_generation(
+ input_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ cache_position=cache_position,
+ logits_to_keep=logits_to_keep,
+ **kwargs,
+ )
+
+ if cache_position[0] == 0:
+ # If we're in cached decoding stage, pixel values should be None because input ids do not contain special image token anymore
+ # Otherwise we need pixel values to be passed to model
+ model_inputs["pixel_values"] = pixel_values
+
+ return model_inputs
+
+
+__all__ = ["VipLlavaModel", "VipLlavaForConditionalGeneration", "VipLlavaPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/modular_vipllava.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/modular_vipllava.py
new file mode 100644
index 0000000000000000000000000000000000000000..a715d2e6d817d38dcabfa40d7ff834fda095dfa1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vipllava/modular_vipllava.py
@@ -0,0 +1,278 @@
+# coding=utf-8
+# Copyright 2023 the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from transformers.models.llava.modeling_llava import (
+ LlavaCausalLMOutputWithPast,
+ LlavaForConditionalGeneration,
+ LlavaModel,
+ LlavaModelOutputWithPast,
+ LlavaPreTrainedModel,
+)
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache
+from ...utils import auto_docstring, logging
+from .configuration_vipllava import VipLlavaConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class VipLlavaModelOutputWithPast(LlavaModelOutputWithPast):
+ pass
+
+
+class VipLlavaCausalLMOutputWithPast(LlavaCausalLMOutputWithPast):
+ pass
+
+
+class VipLlavaMultiModalProjector(nn.Module):
+ def __init__(self, config: VipLlavaConfig):
+ super().__init__()
+ num_feature_layers = 1 if isinstance(config.vision_feature_layers, int) else len(config.vision_feature_layers)
+ self.projector_layernorm = nn.LayerNorm(
+ num_feature_layers * config.vision_config.hidden_size, eps=config.projector_layernorm_eps
+ )
+
+ self.linear_1 = nn.Linear(
+ num_feature_layers * config.vision_config.hidden_size,
+ config.text_config.hidden_size,
+ bias=True,
+ )
+ self.act = ACT2FN[config.projector_hidden_act]
+ self.linear_2 = nn.Linear(config.text_config.hidden_size, config.text_config.hidden_size, bias=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.projector_layernorm(hidden_states)
+ hidden_states = self.linear_1(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+ return hidden_states
+
+
+class VipLlavaPreTrainedModel(LlavaPreTrainedModel):
+ pass
+
+
+class VipLlavaModel(LlavaModel):
+ def get_image_features(
+ self, pixel_values: torch.FloatTensor, vision_feature_layers: Optional[Union[int, list[int]]] = None
+ ):
+ """
+ Obtains image last hidden states from the vision tower and apply multimodal projection.
+
+ Args:
+ pixel_values (`torch.FloatTensor]` of shape `(batch_size, channels, height, width)`)
+ The tensors corresponding to the input images.
+ vision_feature_layers (`Union[int, list[int]]`):
+ The vision feature layer, or the list of indexes of the layers to select
+ the vision feature.
+ Returns:
+ image_features (`torch.Tensor`): Image feature tensor of shape `(num_images, image_length, embed_dim)`).
+ """
+ vision_feature_layers = (
+ vision_feature_layers if vision_feature_layers is not None else self.config.vision_feature_layers
+ )
+ image_outputs = self.vision_tower(pixel_values, output_hidden_states=True)
+
+ # If multiple feature layers are provided (which is usually the case)
+ # then the image features are concatenated after the CLS is removed.
+ if isinstance(vision_feature_layers, int):
+ image_features = image_outputs.hidden_states[vision_feature_layers][:, 1:]
+ else:
+ # Usually, we select the features from index 1: the layers -2, -5, -8, -11 and 6
+ image_features = [image_outputs.hidden_states[index][:, 1:] for index in vision_feature_layers]
+ image_features = torch.cat(image_features, dim=-1)
+ image_features = self.multi_modal_projector(image_features)
+ return image_features
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ vision_feature_layers: Optional[Union[int, list[int]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **lm_kwargs,
+ ) -> Union[tuple, VipLlavaModelOutputWithPast]:
+ r"""
+ vision_feature_layers (`Union[int, list[int]]`, *optional*):
+ The vision feature layer, or the list of indexes of the layers to select
+ the vision feature.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ vision_feature_layers = (
+ vision_feature_layers if vision_feature_layers is not None else self.config.vision_feature_layers
+ )
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.get_input_embeddings()(input_ids)
+
+ if pixel_values is not None:
+ image_features = self.get_image_features(
+ pixel_values=pixel_values, vision_feature_layers=vision_feature_layers
+ )
+ image_features = image_features.to(inputs_embeds.device, inputs_embeds.dtype)
+ special_image_mask = self.get_placeholder_mask(
+ input_ids, inputs_embeds=inputs_embeds, image_features=image_features
+ )
+ inputs_embeds = inputs_embeds.masked_scatter(special_image_mask, image_features)
+
+ outputs = self.language_model(
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **lm_kwargs,
+ )
+
+ output = VipLlavaModelOutputWithPast(
+ last_hidden_state=outputs.last_hidden_state,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=image_features if pixel_values is not None else None,
+ )
+ return output if return_dict else output.to_tuple()
+
+
+class VipLlavaForConditionalGeneration(LlavaForConditionalGeneration):
+ def get_image_features(
+ self, pixel_values: torch.FloatTensor, vision_feature_layers: Optional[Union[int, list[int]]] = None
+ ):
+ return self.model.get_image_features(pixel_values=pixel_values, vision_feature_layers=vision_feature_layers)
+
+ def forward(
+ self,
+ input_ids: torch.LongTensor = None,
+ pixel_values: torch.FloatTensor = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ vision_feature_layers: Optional[Union[int, list[int]]] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **lm_kwargs,
+ ) -> Union[tuple, VipLlavaCausalLMOutputWithPast]:
+ r"""
+ vision_feature_layers (`Union[int, list[int]]`, *optional*):
+ The vision feature layer, or the list of indexes of the layers to select
+ the vision feature.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import AutoProcessor, VipLlavaForConditionalGeneration
+
+ >>> model = VipLlavaForConditionalGeneration.from_pretrained("llava-hf/vip-llava-7b-hf", device_map="auto", dtype=torch.float16)
+ >>> processor = AutoProcessor.from_pretrained("llava-hf/vip-llava-7b-hf")
+
+ >>> prompt = "A chat between a curious human and an artificial intelligence assistant. The assistant gives helpful, detailed, and polite answers to the human's questions.###Human: \n{}###Assistant:"
+ >>> question = "Can you please describe this image?"
+ >>> prompt = prompt.format(question)
+ >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/compel-neg.png"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = processor(text=text, images=image, return_tensors="pt").to(0, torch.float16)
+
+ >>> # Generate
+ >>> generate_ids = model.generate(**inputs, max_new_tokens=20)
+ >>> processor.decode(generate_ids[0][len(inputs["input_ids"][0]):], skip_special_tokens=True)
+ The image features a brown and white cat sitting on a green surface, with a red ball in its
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ vision_feature_layers = (
+ vision_feature_layers if vision_feature_layers is not None else self.config.vision_feature_layers
+ )
+
+ outputs = self.model(
+ input_ids=input_ids,
+ pixel_values=pixel_values,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ vision_feature_layers=vision_feature_layers,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=True,
+ cache_position=cache_position,
+ **lm_kwargs,
+ )
+
+ hidden_states = outputs[0]
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.text_config.vocab_size)
+
+ return VipLlavaCausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ image_hidden_states=outputs.image_hidden_states,
+ )
+
+
+__all__ = ["VipLlavaModel", "VipLlavaForConditionalGeneration", "VipLlavaPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..613aae114b339649af52e6000dfa52ee18438f5f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vision_encoder_decoder import *
+ from .modeling_flax_vision_encoder_decoder import *
+ from .modeling_tf_vision_encoder_decoder import *
+ from .modeling_vision_encoder_decoder import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/configuration_vision_encoder_decoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/configuration_vision_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..248bf73ff9faf4ec54388c7fd947a1e3a3333b13
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/configuration_vision_encoder_decoder.py
@@ -0,0 +1,215 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from collections import OrderedDict
+from collections.abc import Mapping
+from typing import TYPE_CHECKING, Any, Optional
+
+from packaging import version
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+from ..auto.configuration_auto import AutoConfig
+
+
+if TYPE_CHECKING:
+ from ... import PreTrainedTokenizerBase, TensorType
+
+logger = logging.get_logger(__name__)
+
+
+class VisionEncoderDecoderConfig(PretrainedConfig):
+ r"""
+ [`VisionEncoderDecoderConfig`] is the configuration class to store the configuration of a
+ [`VisionEncoderDecoderModel`]. It is used to instantiate a Vision-Encoder-Text-Decoder model according to the
+ specified arguments, defining the encoder and decoder configs.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ kwargs (*optional*):
+ Dictionary of keyword arguments. Notably:
+
+ - **encoder** ([`PretrainedConfig`], *optional*) -- An instance of a configuration object that defines
+ the encoder config.
+ - **decoder** ([`PretrainedConfig`], *optional*) -- An instance of a configuration object that defines
+ the decoder config.
+
+ Examples:
+
+ ```python
+ >>> from transformers import BertConfig, ViTConfig, VisionEncoderDecoderConfig, VisionEncoderDecoderModel
+
+ >>> # Initializing a ViT & BERT style configuration
+ >>> config_encoder = ViTConfig()
+ >>> config_decoder = BertConfig()
+
+ >>> config = VisionEncoderDecoderConfig.from_encoder_decoder_configs(config_encoder, config_decoder)
+
+ >>> # Initializing a ViTBert model (with random weights) from a ViT & google-bert/bert-base-uncased style configurations
+ >>> model = VisionEncoderDecoderModel(config=config)
+
+ >>> # Accessing the model configuration
+ >>> config_encoder = model.config.encoder
+ >>> config_decoder = model.config.decoder
+ >>> # set decoder config to causal lm
+ >>> config_decoder.is_decoder = True
+ >>> config_decoder.add_cross_attention = True
+
+ >>> # Saving the model, including its configuration
+ >>> model.save_pretrained("my-model")
+
+ >>> # loading model and config from pretrained folder
+ >>> encoder_decoder_config = VisionEncoderDecoderConfig.from_pretrained("my-model")
+ >>> model = VisionEncoderDecoderModel.from_pretrained("my-model", config=encoder_decoder_config)
+ ```"""
+
+ model_type = "vision-encoder-decoder"
+ sub_configs = {"encoder": AutoConfig, "decoder": AutoConfig}
+ has_no_defaults_at_init = True
+
+ def __init__(self, **kwargs):
+ super().__init__(**kwargs)
+ if "encoder" not in kwargs or "decoder" not in kwargs:
+ raise ValueError(
+ f"A configuration of type {self.model_type} cannot be instantiated because "
+ f"not both `encoder` and `decoder` sub-configurations are passed, but only {kwargs}"
+ )
+
+ encoder_config = kwargs.pop("encoder")
+ encoder_model_type = encoder_config.pop("model_type")
+ decoder_config = kwargs.pop("decoder")
+ decoder_model_type = decoder_config.pop("model_type")
+
+ self.encoder = AutoConfig.for_model(encoder_model_type, **encoder_config)
+ self.decoder = AutoConfig.for_model(decoder_model_type, **decoder_config)
+ self.is_encoder_decoder = True
+
+ @classmethod
+ def from_encoder_decoder_configs(
+ cls, encoder_config: PretrainedConfig, decoder_config: PretrainedConfig, **kwargs
+ ) -> PretrainedConfig:
+ r"""
+ Instantiate a [`VisionEncoderDecoderConfig`] (or a derived class) from a pre-trained encoder model
+ configuration and decoder model configuration.
+
+ Returns:
+ [`VisionEncoderDecoderConfig`]: An instance of a configuration object
+ """
+ logger.info("Setting `config.is_decoder=True` and `config.add_cross_attention=True` for decoder_config")
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ return cls(encoder=encoder_config.to_dict(), decoder=decoder_config.to_dict(), **kwargs)
+
+
+class VisionEncoderDecoderEncoderOnnxConfig(OnnxConfig):
+ torch_onnx_minimum_version = version.parse("1.11")
+
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ return OrderedDict(
+ [
+ ("pixel_values", {0: "batch", 1: "num_channels", 2: "height", 3: "width"}),
+ ]
+ )
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 1e-4
+
+ @property
+ def outputs(self) -> Mapping[str, Mapping[int, str]]:
+ return OrderedDict({"last_hidden_state": {0: "batch", 1: "encoder_sequence"}})
+
+
+class VisionEncoderDecoderDecoderOnnxConfig(OnnxConfig):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ common_inputs = OrderedDict()
+ common_inputs["input_ids"] = {0: "batch", 1: "past_decoder_sequence + sequence"}
+ common_inputs["attention_mask"] = {0: "batch", 1: "past_decoder_sequence + sequence"}
+ common_inputs["encoder_hidden_states"] = {0: "batch", 1: "encoder_sequence"}
+
+ return common_inputs
+
+ def generate_dummy_inputs(
+ self,
+ tokenizer: "PreTrainedTokenizerBase",
+ batch_size: int = -1,
+ seq_length: int = -1,
+ is_pair: bool = False,
+ framework: Optional["TensorType"] = None,
+ ) -> Mapping[str, Any]:
+ import torch
+
+ common_inputs = OrderedDict()
+
+ dummy_input = super().generate_dummy_inputs(
+ tokenizer, batch_size=batch_size, seq_length=seq_length, is_pair=is_pair, framework=framework
+ )
+
+ batch, encoder_sequence = dummy_input["input_ids"].shape
+ encoder_hidden_states_shape = (batch, encoder_sequence, self._config.encoder_hidden_size)
+ common_inputs["input_ids"] = dummy_input.pop("input_ids")
+ common_inputs["attention_mask"] = dummy_input.pop("attention_mask")
+ common_inputs["encoder_hidden_states"] = torch.zeros(encoder_hidden_states_shape)
+
+ return common_inputs
+
+
+class VisionEncoderDecoderOnnxConfig(OnnxConfig):
+ @property
+ def inputs(self) -> None:
+ pass
+
+ def get_encoder_config(self, encoder_config: PretrainedConfig) -> OnnxConfig:
+ r"""
+ Returns ONNX encoder config for `VisionEncoderDecoder` model.
+
+ Args:
+ encoder_config (`PretrainedConfig`):
+ The encoder model's configuration to use when exporting to ONNX.
+
+ Returns:
+ [`VisionEncoderDecoderEncoderOnnxConfig`]: An instance of the ONNX configuration object
+ """
+ return VisionEncoderDecoderEncoderOnnxConfig(encoder_config)
+
+ def get_decoder_config(
+ self, encoder_config: PretrainedConfig, decoder_config: PretrainedConfig, feature: str = "default"
+ ) -> OnnxConfig:
+ r"""
+ Returns ONNX decoder config for `VisionEncoderDecoder` model.
+
+ Args:
+ encoder_config (`PretrainedConfig`):
+ The encoder model's configuration to use when exporting to ONNX.
+ decoder_config (`PretrainedConfig`):
+ The decoder model's configuration to use when exporting to ONNX
+ feature (`str`, *optional*):
+ The type of feature to export the model with.
+
+ Returns:
+ [`VisionEncoderDecoderDecoderOnnxConfig`]: An instance of the ONNX configuration object.
+ """
+ decoder_config.encoder_hidden_size = encoder_config.hidden_size
+ return VisionEncoderDecoderDecoderOnnxConfig(decoder_config, feature)
+
+
+__all__ = ["VisionEncoderDecoderConfig", "VisionEncoderDecoderOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_flax_vision_encoder_decoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_flax_vision_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..a59c799cc04afa51c0f2156baa06a88683f1dbf6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_flax_vision_encoder_decoder.py
@@ -0,0 +1,864 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Classes to support Vision-Encoder-Text-Decoder architectures"""
+
+import os
+from typing import Optional, Union
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.traverse_util import flatten_dict, unflatten_dict
+from jax import lax
+from jax.random import PRNGKey
+
+from ...modeling_flax_outputs import FlaxBaseModelOutput, FlaxCausalLMOutputWithCrossAttentions, FlaxSeq2SeqLMOutput
+from ...modeling_flax_utils import FlaxPreTrainedModel
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging, replace_return_docstrings
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_flax_auto import FlaxAutoModel, FlaxAutoModelForCausalLM
+from .configuration_vision_encoder_decoder import VisionEncoderDecoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "VisionEncoderDecoderConfig"
+
+VISION_ENCODER_DECODER_START_DOCSTRING = r"""
+ This class can be used to initialize an image-to-text-sequence model with any pretrained vision autoencoding model
+ as the encoder and any pretrained text autoregressive model as the decoder. The encoder is loaded via
+ [`~AutoModel.from_pretrained`] function and the decoder is loaded via [`~AutoModelForCausalLM.from_pretrained`]
+ function. Cross-attention layers are automatically added to the decoder and should be fine-tuned on a downstream
+ generative task, like image captioning.
+
+ The effectiveness of initializing sequence-to-sequence models with pretrained checkpoints for sequence generation
+ tasks was shown in [Leveraging Pre-trained Checkpoints for Sequence Generation
+ Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn. Michael Matena, Yanqi
+ Zhou, Wei Li, Peter J. Liu.
+
+ Additionally, in [TrOCR: Transformer-based Optical Character Recognition with Pre-trained
+ Models](https://huggingface.co/papers/2109.10282) it is shown how leveraging large pretrained vision models for optical
+ character recognition (OCR) yields a significant performance improvement.
+
+ After such a Vision-Encoder-Text-Decoder model has been trained/fine-tuned, it can be saved/loaded just like any
+ other models (see the examples for more information).
+
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a Flax Linen
+ [flax.nn.Module](https://flax.readthedocs.io/en/latest/_autosummary/flax.nn.module.html) subclass. Use it as a
+ regular Flax Module and refer to the Flax documentation for all matter related to general usage and behavior.
+
+ Parameters:
+ config ([`VisionEncoderDecoderConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs).
+
+ This can be used to enable mixed-precision training or half-precision inference on GPUs or TPUs. If
+ specified all the computation will be performed with the given `dtype`.
+
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.**
+
+ If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`] and
+ [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+VISION_ENCODER_DECODER_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`jnp.ndarray` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using the vision model's image processor. For example, using
+ [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`] for details.
+ decoder_input_ids (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+ decoder_attention_mask (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_position_ids (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the
+ range `[0, config.decoder.max_position_embeddings - 1]`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ If set to `True`, the model will return a [`~utils.FlaxSeq2SeqLMOutput`] instead of a plain tuple.
+"""
+
+VISION_ENCODER_DECODER_ENCODE_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`jnp.ndarray` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using the vision model's image processor. For example, using
+ [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`] for details.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ If set to `True`, the model will return a [`~utils.FlaxBaseModelOutput`] instead of a plain tuple.
+"""
+
+VISION_ENCODER_DECODER_DECODE_INPUTS_DOCSTRING = r"""
+ Args:
+ decoder_input_ids (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ For sequence to sequence training, `decoder_input_ids` should be provided. If no `decoder_input_ids` is
+ provided, the model will create this tensor by shifting the `input_ids` to the right for denoising
+ pre-training.
+ encoder_outputs (`tuple(tuple(jnp.ndarray)`):
+ Tuple consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*: `attentions`)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ decoder_attention_mask (`jnp.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_position_ids (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the
+ range `[0, config.decoder.max_position_embeddings - 1]`.
+ past_key_values (`dict[str, jnp.ndarray]`, *optional*, returned by `init_cache` or when passing previous `past_key_values`):
+ Dictionary of pre-computed hidden-states (key and values in the attention blocks) that can be used for fast
+ auto-regressive decoding. Pre-computed key and value hidden-states are of shape *[batch_size, max_length]*.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ If set to `True`, the model will return a [`~utils.FlaxCausalLMOutputWithCrossAttentions`] instead of a
+ plain tuple.
+"""
+
+
+class FlaxVisionEncoderDecoderModule(nn.Module):
+ config: VisionEncoderDecoderConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ encoder_config = self.config.encoder
+ decoder_config = self.config.decoder
+
+ # Copied from `modeling_hybrid_clip.py` with modifications.
+ from ...models.auto.modeling_flax_auto import FLAX_MODEL_FOR_CAUSAL_LM_MAPPING, FLAX_MODEL_MAPPING
+
+ encoder_module = FLAX_MODEL_MAPPING[encoder_config.__class__].module_class
+ decoder_module = FLAX_MODEL_FOR_CAUSAL_LM_MAPPING[decoder_config.__class__].module_class
+
+ self.encoder = encoder_module(encoder_config, dtype=self.dtype)
+ self.decoder = decoder_module(decoder_config, dtype=self.dtype)
+
+ # encoder outputs might need to be projected to different dimension for decoder
+ if (
+ self.encoder.config.hidden_size != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ self.enc_to_dec_proj = nn.Dense(
+ self.decoder.config.hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.decoder.config.initializer_range),
+ dtype=self.dtype,
+ )
+ else:
+ self.enc_to_dec_proj = None
+
+ def _get_encoder_module(self):
+ return self.encoder
+
+ def _get_projection_module(self):
+ return self.enc_to_dec_proj
+
+ def _get_decoder_module(self):
+ return self.decoder
+
+ def __call__(
+ self,
+ pixel_values,
+ decoder_input_ids,
+ decoder_attention_mask,
+ decoder_position_ids,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ):
+ encoder_outputs = self.encoder(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ # optionally project encoder_hidden_states
+ if self.enc_to_dec_proj is not None:
+ encoder_hidden_states = self.enc_to_dec_proj(encoder_hidden_states)
+
+ # The advantage of explicitly setting this is TPU XLA compiler knows as soon as possible what shape this
+ # variable has and can better optimize. Also passing `None` can lead to some problems when jitting the model.
+ # In Flax/JAX, we only want to pass `None` for non-tensor function inputs. For all tensor function inputs, we
+ # should always pass a tensor and not `None`.
+ batch_size, sequence_length = encoder_hidden_states.shape[:2]
+ encoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return FlaxSeq2SeqLMOutput(
+ logits=decoder_outputs.logits,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@add_start_docstrings(VISION_ENCODER_DECODER_START_DOCSTRING)
+class FlaxVisionEncoderDecoderModel(FlaxPreTrainedModel):
+ r"""
+ [`FlaxVisionEncoderDecoderModel`] is a generic model class that will be instantiated as a transformer architecture
+ with the module (flax.nn.Module) of one of the base vision model classes of the library as encoder module and
+ another one as decoder module when created with the :meth*~transformers.FlaxAutoModel.from_pretrained* class method
+ for the encoder and :meth*~transformers.FlaxAutoModelForCausalLM.from_pretrained* class method for the decoder.
+ """
+
+ config_class = VisionEncoderDecoderConfig
+ base_model_prefix = "vision_encoder_decoder"
+ main_input_name = "pixel_values"
+ module_class = FlaxVisionEncoderDecoderModule
+
+ def __init__(
+ self,
+ config: VisionEncoderDecoderConfig,
+ input_shape: Optional[tuple] = None,
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ **kwargs,
+ ):
+ if not _do_init:
+ raise ValueError(
+ "`FlaxVisionEncoderDecoderModel` cannot be created without initializing, `_do_init` must be `True`."
+ )
+
+ if input_shape is None:
+ num_channels = getattr(config.encoder, "num_channels", 3)
+ input_shape = (
+ (1, config.encoder.image_size, config.encoder.image_size, num_channels),
+ (1, 1),
+ )
+
+ if config.decoder.cross_attention_hidden_size is not None:
+ if config.decoder.cross_attention_hidden_size != config.encoder.hidden_size:
+ raise ValueError(
+ "If `cross_attention_hidden_size` is specified in the decoder's configuration, it has to be equal"
+ f" to the encoder's `hidden_size`. Got {config.decoder.cross_attention_hidden_size} for"
+ f" `config.decoder.cross_attention_hidden_size` and {config.encoder.hidden_size} for"
+ " `config.encoder.hidden_size`."
+ )
+
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ encoder_input_shape, decoder_input_shape = input_shape
+
+ # init input tensors
+ pixel_values = jnp.zeros(encoder_input_shape, dtype=self.dtype)
+ decoder_input_ids = jnp.zeros(decoder_input_shape, dtype="i4")
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+
+ batch_size, _, _, _ = pixel_values.shape
+ decoder_batch_size, decoder_sequence_length = decoder_input_ids.shape
+ if not decoder_batch_size == batch_size:
+ raise ValueError(
+ f"The inputs of encoder and decoder should have the same batch size, but got {batch_size} for encoder "
+ f"and {decoder_batch_size} for decoder."
+ )
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(decoder_sequence_length)[None, :], (decoder_batch_size, decoder_sequence_length)
+ )
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(
+ rngs,
+ pixel_values,
+ decoder_input_ids,
+ decoder_attention_mask,
+ decoder_position_ids,
+ )["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ def init_cache(self, batch_size, max_length, encoder_outputs):
+ r"""
+ Args:
+ batch_size (`int`):
+ batch_size used for fast auto-regressive decoding. Defines the batch size of the initialized cache.
+ max_length (`int`):
+ maximum possible length for auto-regressive decoding. Defines the sequence length of the initialized
+ cache.
+ encoder_outputs (`Union[FlaxBaseModelOutput, tuple(tuple(jnp.ndarray)]`):
+ `encoder_outputs` consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*:
+ `attentions`). `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*)
+ is a sequence of hidden-states at the output of the last layer of the encoder. Used in the
+ cross-attention of the decoder.
+ """
+ # init input variables to retrieve cache
+ decoder_input_ids = jnp.ones((batch_size, max_length), dtype="i4")
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(jnp.atleast_2d(decoder_input_ids).shape[-1]), decoder_input_ids.shape
+ )
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, decoder_position_ids, **kwargs):
+ decoder_module = module._get_decoder_module()
+ return decoder_module(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ **kwargs,
+ )
+
+ init_variables = self.module.init(
+ jax.random.PRNGKey(0),
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_hidden_states=encoder_outputs[0],
+ init_cache=True,
+ method=_decoder_forward, # we only need to call the decoder to init the cache
+ )
+ return unfreeze(init_variables["cache"])
+
+ @add_start_docstrings(VISION_ENCODER_DECODER_ENCODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxBaseModelOutput, config_class=_CONFIG_FOR_DOC)
+ def encode(
+ self,
+ pixel_values: jnp.ndarray,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, FlaxVisionEncoderDecoderModel
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224-in21k")
+
+ >>> # initialize a vit-gpt2 from pretrained ViT and GPT2 models. Note that the cross-attention layers will be randomly initialized
+ >>> model = FlaxVisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "google/vit-base-patch16-224-in21k", "openai-community/gpt2"
+ ... )
+
+ >>> pixel_values = image_processor(images=image, return_tensors="np").pixel_values
+ >>> encoder_outputs = model.encode(pixel_values)
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # `FlaxViTModel` expects channel first format, but `FlaxViTModule` expects channel last format.
+ # Currently, we assume this holds for all Flax vision models, and perform a transpose here.
+ pixel_values = jnp.transpose(pixel_values, (0, 2, 3, 1))
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _encoder_forward(module, pixel_values, **kwargs):
+ encode_module = module._get_encoder_module()
+ return encode_module(pixel_values, **kwargs)
+
+ outputs = self.module.apply(
+ {"params": params or self.params},
+ pixel_values=jnp.array(pixel_values, dtype=self.dtype),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ method=_encoder_forward,
+ )
+
+ if return_dict:
+ outputs = FlaxBaseModelOutput(
+ last_hidden_state=outputs.last_hidden_state,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ return outputs
+
+ @add_start_docstrings(VISION_ENCODER_DECODER_DECODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxCausalLMOutputWithCrossAttentions, config_class=_CONFIG_FOR_DOC)
+ def decode(
+ self,
+ decoder_input_ids,
+ encoder_outputs,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_position_ids: Optional[jnp.ndarray] = None,
+ past_key_values: Optional[dict] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, FlaxVisionEncoderDecoderModel
+ >>> import jax.numpy as jnp
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224-in21k")
+
+ >>> # initialize a vit-gpt2 from pretrained ViT and GPT2 models. Note that the cross-attention layers will be randomly initialized
+ >>> model = FlaxVisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "google/vit-base-patch16-224-in21k", "openai-community/gpt2"
+ ... )
+
+ >>> pixel_values = image_processor(images=image, return_tensors="np").pixel_values
+ >>> encoder_outputs = model.encode(pixel_values)
+
+ >>> decoder_start_token_id = model.config.decoder.bos_token_id
+ >>> decoder_input_ids = jnp.ones((pixel_values.shape[0], 1), dtype="i4") * decoder_start_token_id
+
+ >>> outputs = model.decode(decoder_input_ids, encoder_outputs)
+ >>> logits = outputs.logits
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ batch_size, sequence_length = encoder_hidden_states.shape[:2]
+ encoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ batch_size, sequence_length = decoder_input_ids.shape
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ if decoder_position_ids is None:
+ if past_key_values is not None:
+ raise ValueError("Make sure to provide `decoder_position_ids` when passing `past_key_values`.")
+
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(sequence_length)[None, :], (batch_size, sequence_length)
+ )
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ inputs = {"params": params or self.params}
+
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be
+ # passed down to ensure cache is used. It has to be made sure that cache is marked as mutable so that
+ # it can be changed by FlaxBartAttention module
+ if past_key_values:
+ inputs["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ def _decoder_forward(
+ module, decoder_input_ids, decoder_attention_mask, decoder_position_ids, encoder_hidden_states, **kwargs
+ ):
+ projection_module = module._get_projection_module()
+ decoder_module = module._get_decoder_module()
+
+ # optionally project encoder_hidden_states
+ if projection_module is not None:
+ encoder_hidden_states = projection_module(encoder_hidden_states)
+
+ return decoder_module(
+ decoder_input_ids,
+ decoder_attention_mask,
+ decoder_position_ids,
+ encoder_hidden_states,
+ **kwargs,
+ )
+
+ outputs = self.module.apply(
+ inputs,
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ decoder_position_ids=jnp.array(decoder_position_ids, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=jnp.array(encoder_attention_mask, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ mutable=mutable,
+ method=_decoder_forward,
+ )
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs, past = outputs
+ outputs["past_key_values"] = unfreeze(past["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs, past = outputs
+ outputs = outputs[:1] + (unfreeze(past["cache"]),) + outputs[1:]
+
+ return outputs
+
+ @add_start_docstrings_to_model_forward(VISION_ENCODER_DECODER_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+ def __call__(
+ self,
+ pixel_values: jnp.ndarray,
+ decoder_input_ids: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_position_ids: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import FlaxVisionEncoderDecoderModel, AutoImageProcessor, AutoTokenizer
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224-in21k")
+
+ >>> # load output tokenizer
+ >>> tokenizer_output = AutoTokenizer.from_pretrained("openai-community/gpt2")
+
+ >>> # initialize a vit-gpt2 from pretrained ViT and GPT2 models. Note that the cross-attention layers will be randomly initialized
+ >>> model = FlaxVisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "google/vit-base-patch16-224-in21k", "openai-community/gpt2"
+ ... )
+
+ >>> pixel_values = image_processor(images=image, return_tensors="np").pixel_values
+
+ >>> # use GPT2's eos_token as the pad as well as eos token
+ >>> model.config.eos_token_id = model.config.decoder.eos_token_id
+ >>> model.config.pad_token_id = model.config.eos_token_id
+
+ >>> # generation
+ >>> sequences = model.generate(pixel_values, num_beams=4, max_length=12).sequences
+
+ >>> captions = tokenizer_output.batch_decode(sequences, skip_special_tokens=True)
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # prepare encoder inputs
+
+ # `FlaxViTModel` expects channel first format, but `FlaxViTModule` expects channel last format.
+ # Currently, we assume this holds for all Flax vision models, and perform a transpose here.
+ pixel_values = jnp.transpose(pixel_values, (0, 2, 3, 1))
+
+ # prepare decoder inputs
+ if decoder_input_ids is None:
+ raise ValueError("`decoder_input_ids` can't be `None`.")
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+ if decoder_position_ids is None:
+ batch_size, sequence_length = decoder_input_ids.shape
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(sequence_length)[None, :], (batch_size, sequence_length)
+ )
+
+ # Handle any PRNG if needed
+ rngs = {"dropout": dropout_rng} if dropout_rng is not None else {}
+
+ return self.module.apply(
+ {"params": params or self.params},
+ pixel_values=jnp.array(pixel_values, dtype=self.dtype),
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ decoder_position_ids=jnp.array(decoder_position_ids, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ decoder_input_ids,
+ max_length,
+ decoder_attention_mask: Optional[jax.Array] = None,
+ encoder_outputs=None,
+ **kwargs,
+ ):
+ # initializing the cache
+ batch_size, seq_length = decoder_input_ids.shape
+
+ past_key_values = self.init_cache(batch_size, max_length, encoder_outputs)
+ # Note that usually one would have to put 0's in the attention_mask for x > input_ids.shape[-1] and x < cache_length.
+ # But since the decoder uses a causal mask, those positions are masked anyways.
+ # Thus we can create a single static attention_mask here, which is more efficient for compilation
+ extended_attention_mask = jnp.ones((batch_size, max_length), dtype="i4")
+ if decoder_attention_mask is not None:
+ decoder_position_ids = decoder_attention_mask.cumsum(axis=-1) - 1
+ extended_attention_mask = lax.dynamic_update_slice(extended_attention_mask, decoder_attention_mask, (0, 0))
+ else:
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(seq_length, dtype="i4")[None, :], (batch_size, seq_length)
+ )
+
+ return {
+ "past_key_values": past_key_values,
+ "encoder_outputs": encoder_outputs,
+ "decoder_attention_mask": extended_attention_mask,
+ "decoder_position_ids": decoder_position_ids,
+ }
+
+ def update_inputs_for_generation(self, model_outputs, model_kwargs):
+ model_kwargs["past_key_values"] = model_outputs.past_key_values
+ model_kwargs["decoder_position_ids"] = model_kwargs["decoder_position_ids"][:, -1:] + 1
+ return model_kwargs
+
+ @classmethod
+ def from_encoder_decoder_pretrained(
+ cls,
+ encoder_pretrained_model_name_or_path: Optional[Union[str, os.PathLike]] = None,
+ decoder_pretrained_model_name_or_path: Optional[Union[str, os.PathLike]] = None,
+ *model_args,
+ **kwargs,
+ ) -> FlaxPreTrainedModel:
+ r"""
+ Instantiate an encoder and a decoder from one or two base classes of the library from pretrained model
+ checkpoints.
+
+ Params:
+ encoder_pretrained_model_name_or_path (`Union[str, os.PathLike]`, *optional*):
+ Information necessary to initiate the encoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co. An
+ example is `google/vit-base-patch16-224-in21k`.
+ - A path to a *directory* containing model weights saved using
+ [`~FlaxPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+
+ decoder_pretrained_model_name_or_path (`Union[str, os.PathLike]`, *optional*, defaults to `None`):
+ Information necessary to initiate the decoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~FlaxPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the encoder configuration, use the prefix *encoder_* for each configuration parameter.
+ - To update the decoder configuration, use the prefix *decoder_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import FlaxVisionEncoderDecoderModel
+
+ >>> # initialize a vit-gpt2 from a pretrained ViT and a pretrained GPT2 model. Note that the cross-attention layers will be randomly initialized
+ >>> model = FlaxVisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "google/vit-base-patch16-224-in21k", "openai-community/gpt2"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./vit-gpt2")
+ >>> # load fine-tuned model
+ >>> model = FlaxVisionEncoderDecoderModel.from_pretrained("./vit-gpt2")
+ ```"""
+
+ kwargs_encoder = {
+ argument[len("encoder_") :]: value for argument, value in kwargs.items() if argument.startswith("encoder_")
+ }
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+
+ # remove encoder, decoder kwargs from kwargs
+ for key in kwargs_encoder:
+ del kwargs["encoder_" + key]
+ for key in kwargs_decoder:
+ del kwargs["decoder_" + key]
+
+ # Load and initialize the encoder and decoder
+ # The distinction between encoder and decoder at the model level is made
+ # by the value of the flag `is_decoder` that we need to set correctly.
+ encoder = kwargs_encoder.pop("model", None)
+ if encoder is None:
+ if encoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `encoder_model` is not defined as an argument, a `encoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_encoder:
+ encoder_config = AutoConfig.from_pretrained(encoder_pretrained_model_name_or_path)
+ if encoder_config.is_decoder is True or encoder_config.add_cross_attention is True:
+ logger.info(
+ f"Initializing {encoder_pretrained_model_name_or_path} as a encoder model "
+ "from a decoder model. Cross-attention and causal mask are disabled."
+ )
+ encoder_config.is_decoder = False
+ encoder_config.add_cross_attention = False
+
+ kwargs_encoder["config"] = encoder_config
+
+ encoder = FlaxAutoModel.from_pretrained(
+ encoder_pretrained_model_name_or_path, *model_args, **kwargs_encoder
+ )
+
+ decoder = kwargs_decoder.pop("model", None)
+ if decoder is None:
+ if decoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `decoder_model` is not defined as an argument, a `decoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_decoder:
+ decoder_config = AutoConfig.from_pretrained(decoder_pretrained_model_name_or_path)
+ if decoder_config.is_decoder is False or decoder_config.add_cross_attention is False:
+ logger.info(
+ f"Initializing {decoder_pretrained_model_name_or_path} as a decoder model. Cross attention"
+ f" layers are added to {decoder_pretrained_model_name_or_path} and randomly initialized if"
+ f" {decoder_pretrained_model_name_or_path}'s architecture allows for cross attention layers."
+ )
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ kwargs_decoder["config"] = decoder_config
+
+ if kwargs_decoder["config"].is_decoder is False or kwargs_decoder["config"].add_cross_attention is False:
+ logger.warning(
+ f"Decoder model {decoder_pretrained_model_name_or_path} is not initialized as a decoder. "
+ f"In order to initialize {decoder_pretrained_model_name_or_path} as a decoder, "
+ "make sure that the attributes `is_decoder` and `add_cross_attention` of `decoder_config` "
+ "passed to `.from_encoder_decoder_pretrained(...)` are set to `True` or do not pass a "
+ "`decoder_config` to `.from_encoder_decoder_pretrained(...)`"
+ )
+
+ decoder = FlaxAutoModelForCausalLM.from_pretrained(decoder_pretrained_model_name_or_path, **kwargs_decoder)
+
+ # instantiate config with corresponding kwargs
+ dtype = kwargs.pop("dtype", jnp.float32)
+ config = VisionEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config, **kwargs)
+
+ # init model
+ model = cls(config, dtype=dtype)
+ model.params["encoder"] = encoder.params
+ model.params["decoder"] = decoder.params
+
+ return model
+
+
+__all__ = ["FlaxVisionEncoderDecoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_tf_vision_encoder_decoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_tf_vision_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef2ea2109987beabf5f8dc7b758d055f0a543bbf
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_tf_vision_encoder_decoder.py
@@ -0,0 +1,696 @@
+# coding=utf-8
+# Copyright 2022 HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Classes to support TF Vision-Encoder-Text-Decoder architectures"""
+
+from __future__ import annotations
+
+import re
+import warnings
+
+import numpy as np
+import tensorflow as tf
+
+from ...configuration_utils import PretrainedConfig
+from ...modeling_tf_outputs import TFBaseModelOutput, TFSeq2SeqLMOutput
+from ...modeling_tf_utils import TFCausalLanguageModelingLoss, TFPreTrainedModel, get_initializer, keras, unpack_inputs
+from ...tf_utils import shape_list
+from ...utils import (
+ ModelOutput,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+ replace_return_docstrings,
+)
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_tf_auto import TFAutoModel, TFAutoModelForCausalLM
+from .configuration_vision_encoder_decoder import VisionEncoderDecoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "VisionEncoderDecoderConfig"
+
+DEPRECATION_WARNING = (
+ "Version v4.17.0 introduces a better way to train encoder-decoder models by computing the loss inside the"
+ " encoder-decoder framework rather than in the decoder itself. You may observe training discrepancies if"
+ " fine-tuning a model trained with versions anterior to 4.17.0. The decoder_input_ids are now created based on the"
+ " labels, no need to pass them yourself anymore."
+)
+
+VISION_ENCODER_DECODER_START_DOCSTRING = r"""
+ This class can be used to initialize an image-to-text-sequence model with any pretrained vision autoencoding model
+ as the encoder and any pretrained text autoregressive model as the decoder. The encoder is loaded via
+ [`~TFAutoModel.from_pretrained`] function and the decoder is loaded via [`~TFAutoModelForCausalLM.from_pretrained`]
+ function. Cross-attention layers are automatically added to the decoder and should be fine-tuned on a downstream
+ generative task, like image captioning.
+
+ The effectiveness of initializing sequence-to-sequence models with pretrained checkpoints for sequence generation
+ tasks was shown in [Leveraging Pre-trained Checkpoints for Sequence Generation
+ Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn. Michael Matena, Yanqi
+ Zhou, Wei Li, Peter J. Liu.
+
+ Additionally, in [TrOCR: Transformer-based Optical Character Recognition with Pre-trained
+ Models](https://huggingface.co/papers/2109.10282) it is shown how leveraging large pretrained vision models for optical
+ character recognition (OCR) yields a significant performance improvement.
+
+ After such a Vision-Encoder-Text-Decoder model has been trained/fine-tuned, it can be saved/loaded just like any
+ other models (see the examples for more information).
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+ Parameters:
+ config ([`VisionEncoderDecoderConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~TFPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+VISION_ENCODER_DECODER_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`np.ndarray`, `tf.Tensor`, `list[tf.Tensor]` ``dict[str, tf.Tensor]` or `dict[str, np.ndarray]` and each example must have the shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using the vision's model's image processor. For example, using
+ [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`] for details.
+ decoder_input_ids (`np.ndarray` or `tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ Provide for sequence to sequence training to the decoder. Indices can be obtained using
+ [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for
+ details.
+ decoder_attention_mask (`np.ndarray` or `tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ encoder_outputs (`tuple(tuple(tf.Tensor)`, *optional*):
+ This tuple must consist of (`last_hidden_state`, *optional*: `hidden_states`, *optional*: `attentions`)
+ `last_hidden_state` (`tf.Tensor` of shape `({0}, hidden_size)`) is a tensor of hidden-states at the output
+ of the last layer of the encoder. Used in the cross-attention of the decoder.
+ past_key_values (`tuple(tuple(tf.Tensor))` of length `config.n_layers` with each tuple having 4 tensors of shape `(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`):
+ Contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `({0})`.
+ decoder_inputs_embeds (`np.ndarray` or `tf.Tensor` of shape `(batch_size, target_sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `decoder_input_ids` you can choose to directly pass an embedded
+ representation. This is useful if you want more control over how to convert `decoder_input_ids` indices
+ into associated vectors than the model's internal embedding lookup matrix.
+ labels (`np.ndarray` or `tf.Tensor` of shape `({0})`, *optional*):
+ Labels for computing the masked language modeling loss for the decoder. Indices should be in `[-100, 0,
+ ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ If set to `True`, the model will return a [`~utils.Seq2SeqLMOutput`] instead of a plain tuple.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+ kwargs (*optional*): Remaining dictionary of keyword arguments. Keyword arguments come in two flavors:
+
+ - Without a prefix which will be input as `**encoder_kwargs` for the encoder forward function.
+ - With a *decoder_* prefix which will be input as `**decoder_kwargs` for the decoder forward function.
+"""
+
+
+# Copied from transformers.models.encoder_decoder.modeling_tf_encoder_decoder.shift_tokens_right
+def shift_tokens_right(input_ids: tf.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ if pad_token_id is None:
+ raise ValueError("Make sure to set the pad_token_id attribute of the model's configuration.")
+ pad_token_id = tf.cast(pad_token_id, input_ids.dtype)
+
+ if decoder_start_token_id is None:
+ raise ValueError("Make sure to set the decoder_start_token_id attribute of the model's configuration.")
+ decoder_start_token_id = tf.cast(decoder_start_token_id, input_ids.dtype)
+
+ start_tokens = tf.fill((shape_list(input_ids)[0], 1), decoder_start_token_id)
+ shifted_input_ids = tf.concat([start_tokens, input_ids[:, :-1]], -1)
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids = tf.where(
+ shifted_input_ids == -100, tf.fill(shape_list(shifted_input_ids), pad_token_id), shifted_input_ids
+ )
+
+ # "Verify that `labels` has only positive values and -100"
+ assert_gte0 = tf.debugging.assert_greater_equal(shifted_input_ids, tf.constant(0, dtype=input_ids.dtype))
+
+ # Make sure the assertion op is called by wrapping the result in an identity no-op
+ with tf.control_dependencies([assert_gte0]):
+ shifted_input_ids = tf.identity(shifted_input_ids)
+
+ return shifted_input_ids
+
+
+@add_start_docstrings(VISION_ENCODER_DECODER_START_DOCSTRING)
+class TFVisionEncoderDecoderModel(TFPreTrainedModel, TFCausalLanguageModelingLoss):
+ r"""
+ [`TFVisionEncoderDecoderModel`] is a generic model class that will be instantiated as a transformer architecture
+ with one of the base vision model classes of the library as encoder and another one of the base model classes as
+ decoder when created with the [`~TFAutoModel.from_pretrained`] class method for the encoder and
+ [`~TFAutoModelForCausalLM.from_pretrained`] class method for the decoder.
+ """
+
+ config_class = VisionEncoderDecoderConfig
+ base_model_prefix = "vision_encoder_decoder"
+ load_weight_prefix = "tf_vision_encoder_decoder_model"
+ main_input_name = "pixel_values"
+
+ def __init__(
+ self,
+ config: PretrainedConfig | None = None,
+ encoder: TFPreTrainedModel | None = None,
+ decoder: TFPreTrainedModel | None = None,
+ ):
+ if config is None and (encoder is None or decoder is None):
+ raise ValueError("Either a configuration or an encoder and a decoder has to be provided.")
+ if config is None:
+ config = VisionEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config)
+ else:
+ if not isinstance(config, self.config_class):
+ raise ValueError(f"config: {config} has to be of type {self.config_class}")
+
+ if config.decoder.cross_attention_hidden_size is not None:
+ if config.decoder.cross_attention_hidden_size != config.encoder.hidden_size:
+ raise ValueError(
+ "If `cross_attention_hidden_size` is specified in the decoder's configuration, it has to be equal"
+ f" to the encoder's `hidden_size`. Got {config.decoder.cross_attention_hidden_size} for"
+ f" `config.decoder.cross_attention_hidden_size` and {config.encoder.hidden_size} for"
+ " `config.encoder.hidden_size`."
+ )
+
+ # initialize with config
+ super().__init__(config)
+
+ if encoder is None:
+ encoder = TFAutoModel.from_config(config.encoder, name="encoder")
+
+ if decoder is None:
+ decoder = TFAutoModelForCausalLM.from_config(config.decoder, name="decoder")
+
+ self.encoder = encoder
+ self.decoder = decoder
+
+ if self.encoder.config.to_dict() != self.config.encoder.to_dict():
+ logger.warning(
+ f"Config of the encoder: {self.encoder.__class__} is overwritten by shared encoder config:"
+ f" {self.config.encoder}"
+ )
+ if self.decoder.config.to_dict() != self.config.decoder.to_dict():
+ logger.warning(
+ f"Config of the decoder: {self.decoder.__class__} is overwritten by shared decoder config:"
+ f" {self.config.decoder}"
+ )
+
+ # make sure that the individual model's config refers to the shared config
+ # so that the updates to the config will be synced
+ self.encoder.config = self.config.encoder
+ self.decoder.config = self.config.decoder
+
+ # encoder outputs might need to be projected to different dimension for decoder
+ if (
+ self.encoder.config.hidden_size != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ self.enc_to_dec_proj = keras.layers.Dense(
+ units=self.decoder.config.hidden_size,
+ kernel_initializer=get_initializer(config.encoder.initializer_range),
+ name="enc_to_dec_proj",
+ )
+
+ if self.encoder.get_output_embeddings() is not None:
+ raise ValueError(
+ f"The encoder {self.encoder} should not have a LM Head. Please use a model without LM Head"
+ )
+
+ @property
+ def input_signature(self):
+ vision_config = self.config.encoder
+ if hasattr(vision_config, "vision_config"):
+ vision_config = vision_config.vision_config
+ if hasattr(vision_config, "image_size"):
+ image_size = vision_config.image_size
+ else:
+ image_size = vision_config.input_size
+ return {
+ "pixel_values": tf.TensorSpec(
+ shape=(
+ None,
+ vision_config.num_channels,
+ image_size,
+ image_size,
+ ),
+ dtype=tf.float32,
+ ),
+ "decoder_input_ids": tf.TensorSpec(shape=(None, None), dtype=tf.int32, name="decoder_input_ids"),
+ }
+
+ def get_encoder(self):
+ return self.encoder
+
+ def get_input_embeddings(self):
+ return self.encoder.get_input_embeddings()
+
+ def get_output_embeddings(self):
+ return self.decoder.get_output_embeddings()
+
+ def set_output_embeddings(self, new_embeddings):
+ return self.decoder.set_output_embeddings(new_embeddings)
+
+ def tf_to_pt_weight_rename(self, tf_weight):
+ # Matt: The TF and PT weights don't align because our TF base classes have an extra layer compared to PT models
+ # (the main model stem is in the MainLayer class). If we remove that layer, then weight names sync up as normal.
+ # However, the name of that extra layer is the name of the MainLayer in the base model. We make the assumption
+ # here that the config model_type is the same as the name of the MainLayer. I don't know of anywhere that's
+ # not the case, and I wasn't sure how else to go from the config to the correct MainLayer name!
+
+ # This override is only needed in the case where we're crossloading weights from PT. However, since weights are
+ # often safetensors now, we don't know if we're going to be crossloading until we sniff the weights file.
+ # Therefore, we specify tf_to_pt_weight_rename anyway, and let the super method figure out if it needs it
+ # or not.
+ encoder_model_type = self.config.encoder.model_type
+ if "encoder" in tf_weight and "decoder" not in tf_weight:
+ return (re.sub(rf"encoder\.{encoder_model_type}\.", "encoder.", tf_weight),)
+ else:
+ return (tf_weight,)
+
+ @classmethod
+ def from_encoder_decoder_pretrained(
+ cls,
+ encoder_pretrained_model_name_or_path: str | None = None,
+ decoder_pretrained_model_name_or_path: str | None = None,
+ *model_args,
+ **kwargs,
+ ) -> TFPreTrainedModel:
+ r"""
+ Instantiate an encoder and a decoder from one or two base classes of the library from pretrained model
+ checkpoints.
+
+
+ Params:
+ encoder_pretrained_model_name_or_path (`str`, *optional*):
+ Information necessary to initiate the encoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co. An
+ example is `google/vit-base-patch16-224-in21k`.
+ - A path to a *directory* containing model weights saved using
+ [`~TFPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *pytorch index checkpoint file* (e.g, `./pt_model/`). In this case,
+ `encoder_from_pt` should be set to `True`.
+
+ decoder_pretrained_model_name_or_path (`str`, *optional*, defaults to *None*):
+ Information necessary to initiate the decoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~TFPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *pytorch checkpoint file* (e.g, `./pt_model/`). In this case,
+ `decoder_from_pt` should be set to `True`.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the encoder configuration, use the prefix *encoder_* for each configuration parameter.
+ - To update the decoder configuration, use the prefix *decoder_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import TFVisionEncoderDecoderModel
+
+ >>> # initialize a vit-bert from a pretrained ViT and a pretrained BERT model. Note that the cross-attention layers will be randomly initialized
+ >>> model = TFVisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "google/vit-base-patch16-224-in21k", "google-bert/bert-base-uncased"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./vit-bert")
+ >>> # load fine-tuned model
+ >>> model = TFVisionEncoderDecoderModel.from_pretrained("./vit-bert")
+ ```"""
+
+ kwargs_encoder = {
+ argument[len("encoder_") :]: value for argument, value in kwargs.items() if argument.startswith("encoder_")
+ }
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+
+ # remove encoder, decoder kwargs from kwargs
+ for key in kwargs_encoder:
+ del kwargs["encoder_" + key]
+ for key in kwargs_decoder:
+ del kwargs["decoder_" + key]
+
+ # Load and initialize the encoder and decoder
+ # The distinction between encoder and decoder at the model level is made
+ # by the value of the flag `is_decoder` that we need to set correctly.
+ encoder = kwargs_encoder.pop("model", None)
+ if encoder is None:
+ if encoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `encoder_model` is not defined as an argument, a `encoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_encoder:
+ encoder_config = AutoConfig.from_pretrained(encoder_pretrained_model_name_or_path)
+ if encoder_config.is_decoder is True or encoder_config.add_cross_attention is True:
+ logger.info(
+ f"Initializing {encoder_pretrained_model_name_or_path} as a encoder model "
+ "from a decoder model. Cross-attention and causal mask are disabled."
+ )
+ encoder_config.is_decoder = False
+ encoder_config.add_cross_attention = False
+
+ kwargs_encoder["config"] = encoder_config
+
+ kwargs_encoder["name"] = "encoder"
+ kwargs_encoder["load_weight_prefix"] = cls.load_weight_prefix
+ encoder = TFAutoModel.from_pretrained(encoder_pretrained_model_name_or_path, *model_args, **kwargs_encoder)
+
+ decoder = kwargs_decoder.pop("model", None)
+ if decoder is None:
+ if decoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `decoder_model` is not defined as an argument, a `decoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_decoder:
+ decoder_config = AutoConfig.from_pretrained(decoder_pretrained_model_name_or_path)
+ if decoder_config.is_decoder is False or decoder_config.add_cross_attention is False:
+ logger.info(
+ f"Initializing {decoder_pretrained_model_name_or_path} as a decoder model. Cross attention"
+ f" layers are added to {decoder_pretrained_model_name_or_path} and randomly initialized if"
+ f" {decoder_pretrained_model_name_or_path}'s architecture allows for cross attention layers."
+ )
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ kwargs_decoder["config"] = decoder_config
+
+ if kwargs_decoder["config"].is_decoder is False or kwargs_decoder["config"].add_cross_attention is False:
+ logger.warning(
+ f"Decoder model {decoder_pretrained_model_name_or_path} is not initialized as a decoder. "
+ f"In order to initialize {decoder_pretrained_model_name_or_path} as a decoder, "
+ "make sure that the attributes `is_decoder` and `add_cross_attention` of `decoder_config` "
+ "passed to `.from_encoder_decoder_pretrained(...)` are set to `True` or do not pass a "
+ "`decoder_config` to `.from_encoder_decoder_pretrained(...)`"
+ )
+
+ kwargs_decoder["name"] = "decoder"
+ kwargs_decoder["load_weight_prefix"] = cls.load_weight_prefix
+ decoder = TFAutoModelForCausalLM.from_pretrained(decoder_pretrained_model_name_or_path, **kwargs_decoder)
+
+ # Make sure these 2 `keras.Model` have fixed names so `from_pretrained` could load model weights correctly.
+ if encoder.name != "encoder":
+ raise ValueError("encoder model must be created with the name `encoder`.")
+ if decoder.name != "decoder":
+ raise ValueError("decoder model must be created with the name `decoder`.")
+
+ # instantiate config with corresponding kwargs
+ config = VisionEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config, **kwargs)
+ return cls(encoder=encoder, decoder=decoder, config=config)
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(
+ VISION_ENCODER_DECODER_INPUTS_DOCSTRING.format("batch_size, sequence_length")
+ )
+ @replace_return_docstrings(output_type=TFSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ pixel_values: np.ndarray | tf.Tensor | None = None,
+ decoder_input_ids: np.ndarray | tf.Tensor | None = None,
+ decoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ encoder_outputs: tuple | TFBaseModelOutput | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ decoder_inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ **kwargs,
+ ) -> TFSeq2SeqLMOutput | tuple[tf.Tensor]:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, AutoTokenizer, TFVisionEncoderDecoderModel
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224-in21k")
+ >>> decoder_tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2")
+
+ >>> # initialize a bert2gpt2 from a pretrained BERT and GPT2 models. Note that the cross-attention layers will be randomly initialized
+ >>> model = TFVisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "google/vit-base-patch16-224-in21k", "openai-community/gpt2"
+ ... )
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> img = Image.open(requests.get(url, stream=True).raw)
+
+ >>> # forward
+ >>> pixel_values = image_processor(images=img, return_tensors="tf").pixel_values # Batch size 1
+ >>> decoder_input_ids = decoder_tokenizer("Linda Davis", return_tensors="tf").input_ids # Batch size 1
+ >>> outputs = model(pixel_values=pixel_values, decoder_input_ids=decoder_input_ids)
+
+ >>> # training
+ >>> outputs = model(pixel_values=pixel_values, decoder_input_ids=decoder_input_ids, labels=decoder_input_ids)
+ >>> loss, logits = outputs.loss, outputs.logits
+
+ >>> # save and load from pretrained
+ >>> model.save_pretrained("vit-gpt2")
+ >>> model = TFVisionEncoderDecoderModel.from_pretrained("vit-gpt2")
+
+ >>> # generation
+ >>> generated = model.generate(pixel_values, decoder_start_token_id=model.config.decoder.bos_token_id)
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ kwargs_encoder = {argument: value for argument, value in kwargs.items() if not argument.startswith("decoder_")}
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+
+ # Let the user be responsible for the expected format.
+ if encoder_outputs is not None:
+ if return_dict and not isinstance(encoder_outputs, ModelOutput):
+ raise ValueError(
+ "If `return_dict=True` and `encoder_outputs` is provided, it should be an instance of "
+ f"`ModelOutput`. Got an instance {type(encoder_outputs)} for `encoder_outputs`."
+ )
+
+ if encoder_outputs is None:
+ encoder_inputs = {
+ "input_ids": pixel_values,
+ "output_attentions": output_attentions,
+ "output_hidden_states": output_hidden_states,
+ "return_dict": return_dict,
+ "training": training,
+ }
+
+ # Add arguments to encoder from `kwargs_encoder`
+ encoder_inputs.update(kwargs_encoder)
+
+ if "input_ids" in encoder_inputs:
+ encoder_inputs["pixel_values"] = encoder_inputs.pop("input_ids")
+
+ if encoder_inputs["pixel_values"] is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Handle the case where the inputs are passed as a single dict which contains `labels`.
+ # The `labels` shouldn't be passed to `self.encoder` below, because it is a based model without this
+ # parameter (otherwise, an error occurs when `input_processing` is called inside `self.encoder.call()`).
+ if "labels" in encoder_inputs:
+ labels = encoder_inputs.pop("labels")
+
+ # handle the init case where `dummy_inputs` returns a dict containing `decoder_input_ids`.
+ if "decoder_input_ids" in encoder_inputs:
+ decoder_input_ids = encoder_inputs.pop("decoder_input_ids")
+ # handle the init case where `dummy_inputs` returns a dict containing `decoder_input_ids`.
+ if "decoder_attention_mask" in encoder_inputs:
+ decoder_attention_mask = encoder_inputs.pop("decoder_attention_mask")
+
+ encoder_outputs = self.encoder(**encoder_inputs)
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ # optionally project encoder_hidden_states
+ if (
+ self.encoder.config.hidden_size != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ encoder_hidden_states = self.enc_to_dec_proj(encoder_hidden_states)
+
+ if (labels is not None) and (decoder_input_ids is None and decoder_inputs_embeds is None):
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ batch_size, sequence_length = shape_list(encoder_hidden_states)[:2]
+ encoder_attention_mask = tf.ones(shape=(batch_size, sequence_length), dtype=tf.int32)
+
+ decoder_inputs = {
+ "input_ids": decoder_input_ids,
+ "attention_mask": decoder_attention_mask,
+ "encoder_hidden_states": encoder_hidden_states,
+ "encoder_attention_mask": encoder_attention_mask,
+ "inputs_embeds": decoder_inputs_embeds,
+ "output_attentions": output_attentions,
+ "output_hidden_states": output_hidden_states,
+ "use_cache": use_cache,
+ "past_key_values": past_key_values,
+ "return_dict": return_dict,
+ "training": training,
+ }
+
+ # Add arguments to decoder from `kwargs_decoder`
+ decoder_inputs.update(kwargs_decoder)
+
+ decoder_outputs = self.decoder(**decoder_inputs)
+
+ logits = decoder_outputs[0]
+
+ # Compute loss independent from decoder (as some shift the logits inside them)
+ loss = None
+ if labels is not None:
+ warnings.warn(DEPRECATION_WARNING, FutureWarning)
+ loss = self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ past_key_values = None
+ if use_cache:
+ past_key_values = decoder_outputs[1]
+ # The starting index of the remaining elements in `decoder_outputs`
+ start_index = sum([1 if x is not None else 0 for x in (loss, logits, past_key_values)])
+
+ if not isinstance(encoder_outputs, tuple):
+ encoder_outputs = encoder_outputs.to_tuple()
+ output = (loss, logits, past_key_values) + decoder_outputs[start_index:] + encoder_outputs
+ output = tuple(x for x in output if x is not None)
+ return output
+
+ return TFSeq2SeqLMOutput(
+ loss=loss,
+ logits=decoder_outputs.logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def serving_output(self, output):
+ pkv = tf.tuple(output.past_key_values)[1] if self.config.decoder.use_cache else None
+ dec_hs = (
+ tf.convert_to_tensor(output.decoder_hidden_states) if self.config.decoder.output_hidden_states else None
+ )
+ dec_attns = tf.convert_to_tensor(output.decoder_attentions) if self.config.decoder.output_attentions else None
+ enc_hs = (
+ tf.convert_to_tensor(output.encoder_hidden_states) if self.config.encoder.output_hidden_states else None
+ )
+ enc_attns = tf.convert_to_tensor(output.encoder_attentions) if self.config.encoder.output_attentions else None
+ cross_attns = (
+ tf.convert_to_tensor(output.cross_attentions)
+ if self.config.decoder.output_attentions and output.cross_attentions is not None
+ else None
+ )
+
+ return TFSeq2SeqLMOutput(
+ logits=output.logits,
+ past_key_values=pkv,
+ decoder_hidden_states=dec_hs,
+ decoder_attentions=dec_attns,
+ encoder_last_hidden_state=output.encoder_last_hidden_state,
+ encoder_hidden_states=enc_hs,
+ encoder_attentions=enc_attns,
+ cross_attentions=cross_attns,
+ )
+
+ def prepare_inputs_for_generation(
+ self, input_ids, past_key_values=None, attention_mask=None, use_cache=None, encoder_outputs=None, **kwargs
+ ):
+ decoder_inputs = self.decoder.prepare_inputs_for_generation(input_ids, past_key_values=past_key_values)
+ decoder_attention_mask = decoder_inputs.get("attention_mask", None)
+ past_key_values = decoder_inputs.get("past_key_values")
+ input_dict = {
+ "pixel_values": None, # needs to be passed to make Keras.layer.__call__ happy
+ "attention_mask": attention_mask,
+ "decoder_attention_mask": decoder_attention_mask,
+ "decoder_input_ids": decoder_inputs["input_ids"],
+ # TODO (joao): the `TFBaseModelOutput` wrapper should not be needed after the generate refactor is complete
+ "encoder_outputs": TFBaseModelOutput(last_hidden_state=encoder_outputs[0]),
+ "past_key_values": past_key_values,
+ "use_cache": use_cache,
+ }
+ return input_dict
+
+ def prepare_decoder_input_ids_from_labels(self, labels: tf.Tensor):
+ return shift_tokens_right(labels, self.config.pad_token_id, self.config.decoder_start_token_id)
+
+ def resize_token_embeddings(self, *args, **kwargs):
+ raise NotImplementedError(
+ "Resizing the embedding layers via the TFVisionEncoderDecoderModel directly is not supported. "
+ "Please use the respective methods of the wrapped objects (model.decoder.resize_token_embeddings(...))"
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "enc_to_dec_proj", None) is not None:
+ with tf.name_scope(self.enc_to_dec_proj.name):
+ self.enc_to_dec_proj.build([None, None, self.encoder.config.hidden_size])
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "decoder", None) is not None:
+ with tf.name_scope(self.decoder.name):
+ self.decoder.build(None)
+
+
+__all__ = ["TFVisionEncoderDecoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_vision_encoder_decoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_vision_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..d9f2c593a026933df8999d361020e7ad72ee9a7f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_encoder_decoder/modeling_vision_encoder_decoder.py
@@ -0,0 +1,601 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Classes to support Vision-Encoder-Text-Decoder architectures"""
+
+import gc
+import os
+import tempfile
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from ...configuration_utils import PretrainedConfig
+from ...generation import GenerationMixin
+from ...modeling_outputs import BaseModelOutput, Seq2SeqLMOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_auto import AutoModel, AutoModelForCausalLM
+from .configuration_vision_encoder_decoder import VisionEncoderDecoderConfig
+
+
+# Copied from transformers.models.encoder_decoder.modeling_encoder_decoder.shift_tokens_right
+def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ """
+ Shift input ids one token to the right.
+ """
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[:, 1:] = input_ids[:, :-1].clone()
+ if decoder_start_token_id is None:
+ raise ValueError("Make sure to set the decoder_start_token_id attribute of the model's configuration.")
+ shifted_input_ids[:, 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("Make sure to set the pad_token_id attribute of the model's configuration.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+logger = logging.get_logger(__name__)
+
+
+@auto_docstring
+class VisionEncoderDecoderModel(PreTrainedModel, GenerationMixin):
+ r"""
+ [`VisionEncoderDecoderModel`] is a generic model class that will be instantiated as a transformer architecture with
+ one of the base vision model classes of the library as encoder and another one as decoder when created with the
+ :meth*~transformers.AutoModel.from_pretrained* class method for the encoder and
+ :meth*~transformers.AutoModelForCausalLM.from_pretrained* class method for the decoder.
+ """
+
+ config: VisionEncoderDecoderConfig
+ base_model_prefix = "vision_encoder_decoder"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _supports_param_buffer_assignment = False
+ _supports_flash_attn = True
+ _supports_sdpa = True
+
+ def __init__(
+ self,
+ config: Optional[PretrainedConfig] = None,
+ encoder: Optional[PreTrainedModel] = None,
+ decoder: Optional[PreTrainedModel] = None,
+ ):
+ r"""
+ encoder (`PreTrainedModel`, *optional*):
+ The encoder model to use.
+ decoder (`PreTrainedModel`, *optional*):
+ The decoder model to use.
+ """
+ if config is None and (encoder is None or decoder is None):
+ raise ValueError("Either a configuration or an encoder and a decoder has to be provided.")
+ if config is None:
+ config = VisionEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config)
+ else:
+ if not isinstance(config, self.config_class):
+ raise ValueError(f"Config: {config} has to be of type {self.config_class}")
+
+ if config.decoder.cross_attention_hidden_size is not None:
+ if config.decoder.cross_attention_hidden_size != config.encoder.hidden_size:
+ raise ValueError(
+ "If `cross_attention_hidden_size` is specified in the decoder's configuration, it has to be equal"
+ f" to the encoder's `hidden_size`. Got {config.decoder.cross_attention_hidden_size} for"
+ f" `config.decoder.cross_attention_hidden_size` and {config.encoder.hidden_size} for"
+ " `config.encoder.hidden_size`."
+ )
+
+ # initialize with config
+ # make sure input & output embeddings is not tied
+ config.tie_word_embeddings = False
+ super().__init__(config)
+
+ if encoder is None:
+ encoder = AutoModel.from_config(config.encoder)
+
+ if decoder is None:
+ decoder = AutoModelForCausalLM.from_config(config.decoder)
+
+ self.encoder = encoder
+ self.decoder = decoder
+ self._can_compile_fullgraph = decoder._can_compile_fullgraph
+
+ if self.encoder.config.to_dict() != self.config.encoder.to_dict():
+ logger.warning(
+ f"Config of the encoder: {self.encoder.__class__} is overwritten by shared encoder config:"
+ f" {self.config.encoder}"
+ )
+ if self.decoder.config.to_dict() != self.config.decoder.to_dict():
+ logger.warning(
+ f"Config of the decoder: {self.decoder.__class__} is overwritten by shared decoder config:"
+ f" {self.config.decoder}"
+ )
+
+ # make sure that the individual model's config refers to the shared config
+ # so that the updates to the config will be synced
+ self.config.encoder._attn_implementation = self.encoder.config._attn_implementation
+ self.config.decoder._attn_implementation = self.decoder.config._attn_implementation
+ self.encoder.config = self.config.encoder
+ self.decoder.config = self.config.decoder
+
+ # encoder outputs might need to be projected to different dimension for decoder
+ if (
+ self.encoder.config.hidden_size != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ self.enc_to_dec_proj = nn.Linear(self.encoder.config.hidden_size, self.decoder.config.hidden_size)
+
+ if self.encoder.get_output_embeddings() is not None:
+ raise ValueError(
+ f"The encoder {self.encoder} should not have a LM Head. Please use a model without LM Head"
+ )
+
+ def get_encoder(self):
+ return self.encoder
+
+ def get_input_embeddings(self):
+ return self.decoder.get_input_embeddings()
+
+ def get_output_embeddings(self):
+ return self.decoder.get_output_embeddings()
+
+ def set_output_embeddings(self, new_embeddings):
+ return self.decoder.set_output_embeddings(new_embeddings)
+
+ @classmethod
+ def from_pretrained(cls, pretrained_model_name_or_path, *model_args, **kwargs):
+ r"""
+ Example:
+
+ ```python
+ >>> from transformers import VisionEncoderDecoderModel, AutoImageProcessor, AutoTokenizer
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("ydshieh/vit-gpt2-coco-en")
+ >>> decoder_tokenizer = AutoTokenizer.from_pretrained("ydshieh/vit-gpt2-coco-en")
+ >>> model = VisionEncoderDecoderModel.from_pretrained("ydshieh/vit-gpt2-coco-en")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> img = Image.open(requests.get(url, stream=True).raw)
+ >>> pixel_values = image_processor(images=img, return_tensors="pt").pixel_values # Batch size 1
+
+ >>> output_ids = model.generate(
+ ... pixel_values, max_length=16, num_beams=4, return_dict_in_generate=True
+ ... ).sequences
+
+ >>> preds = decoder_tokenizer.batch_decode(output_ids, skip_special_tokens=True)
+ >>> preds = [pred.strip() for pred in preds]
+
+ >>> assert preds == ["a cat laying on top of a couch next to another cat"]
+ ```"""
+
+ from_tf = kwargs.pop("from_tf", False)
+ if from_tf:
+ from transformers import TFVisionEncoderDecoderModel
+
+ # a workaround to load from tensorflow checkpoint
+ # Using `_tf_model` won't work, because the weight names in the encoder/decoder of `_tf_model` get
+ # extended before saving those components. For example, The name of `_tf_model.encoder.vit` is
+ # `[top model name]/encoder/vit`, but the name of `tf_model.encoder.vit` is `[top model name]/vit`. The
+ # [top model name] is handled (stripped) by the conversion method, and the former case gets extra `encoder`,
+ # which should not occur when we want to save the components alone.
+ # There was a (very) ugly potential fix, which wasn't integrated to `transformers`: see
+ # https://github.com/huggingface/transformers/pull/13222/commits/dbb3c9de76eee235791d2064094654637c99f36d#r697304245
+ # (the change in `src/transformers/modeling_tf_utils.py`)
+ _tf_model = TFVisionEncoderDecoderModel.from_pretrained(
+ pretrained_model_name_or_path, *model_args, **kwargs
+ )
+ config = _tf_model.config
+
+ # Using `tf_model` instead
+ encoder = _tf_model.encoder.__class__(_tf_model.config.encoder)
+ decoder = _tf_model.decoder.__class__(_tf_model.config.decoder)
+ # Make sure models are built
+ encoder(encoder.dummy_inputs)
+ decoder(decoder.dummy_inputs)
+
+ # Get the variable correspondence between `_tf_model` and `encoder` and `decoder`
+ encoder_variables = {}
+ for v in encoder.trainable_variables + encoder.non_trainable_variables:
+ encoder_variables["/".join(v.name.split("/")[1:])] = v
+ decoder_variables = {}
+ for v in decoder.trainable_variables + decoder.non_trainable_variables:
+ decoder_variables["/".join(v.name.split("/")[1:])] = v
+
+ _encoder_variables = {}
+ for v in _tf_model.encoder.trainable_variables + _tf_model.encoder.non_trainable_variables:
+ _encoder_variables["/".join(v.name.split("/")[2:])] = v
+ _decoder_variables = {}
+ for v in _tf_model.decoder.trainable_variables + _tf_model.decoder.non_trainable_variables:
+ _decoder_variables["/".join(v.name.split("/")[2:])] = v
+
+ # assign weight values to `encoder` and `decoder` from `_tf_model`
+ for name, v in encoder_variables.items():
+ v.assign(_encoder_variables[name])
+ for name, v in decoder_variables.items():
+ v.assign(_decoder_variables[name])
+
+ tf_model = TFVisionEncoderDecoderModel(encoder=encoder, decoder=decoder)
+
+ # Deal with `enc_to_dec_proj`
+ if hasattr(_tf_model, "enc_to_dec_proj"):
+ tf_model(tf_model.dummy_inputs)
+ tf_model.enc_to_dec_proj.kernel.assign(_tf_model.enc_to_dec_proj.kernel)
+ tf_model.enc_to_dec_proj.bias.assign(_tf_model.enc_to_dec_proj.bias)
+
+ with tempfile.TemporaryDirectory() as tmpdirname:
+ encoder_dir = os.path.join(tmpdirname, "encoder")
+ decoder_dir = os.path.join(tmpdirname, "decoder")
+ tf_model.encoder.save_pretrained(encoder_dir)
+ tf_model.decoder.save_pretrained(decoder_dir)
+
+ if hasattr(tf_model, "enc_to_dec_proj"):
+ enc_to_dec_proj_weight = torch.transpose(
+ torch.from_numpy(tf_model.enc_to_dec_proj.kernel.numpy()), 1, 0
+ )
+ enc_to_dec_proj_bias = torch.from_numpy(tf_model.enc_to_dec_proj.bias.numpy())
+
+ del _tf_model
+ del tf_model
+ gc.collect()
+
+ attn_implementation = kwargs.get("attn_implementation")
+ kwargs_encoder_decoder = {}
+ if attn_implementation:
+ kwargs_encoder_decoder = {
+ "encoder_attn_implementation": attn_implementation,
+ "decoder_attn_implementation": attn_implementation,
+ }
+
+ model = VisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ encoder_dir,
+ decoder_dir,
+ encoder_from_tf=True,
+ decoder_from_tf=True,
+ **kwargs_encoder_decoder,
+ )
+ # This is only for copying some specific attributes of this particular model.
+ model.config = config
+
+ if hasattr(model, "enc_to_dec_proj"):
+ model.enc_to_dec_proj.weight.data = enc_to_dec_proj_weight.contiguous()
+ model.enc_to_dec_proj.bias.data = enc_to_dec_proj_bias.contiguous()
+
+ return model
+
+ return super().from_pretrained(pretrained_model_name_or_path, *model_args, **kwargs)
+
+ @classmethod
+ def from_encoder_decoder_pretrained(
+ cls,
+ encoder_pretrained_model_name_or_path: Optional[str] = None,
+ decoder_pretrained_model_name_or_path: Optional[str] = None,
+ *model_args,
+ **kwargs,
+ ) -> PreTrainedModel:
+ r"""
+ Instantiate an encoder and a decoder from one or two base classes of the library from pretrained model
+ checkpoints.
+
+
+ The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated). To train
+ the model, you need to first set it back in training mode with `model.train()`.
+
+ Params:
+ encoder_pretrained_model_name_or_path (`str`, *optional*):
+ Information necessary to initiate the image encoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co. An
+ example is `google/vit-base-patch16-224-in21k`.
+ - A path to a *directory* containing model weights saved using
+ [`~PreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *tensorflow index checkpoint file* (e.g, `./tf_model/model.ckpt.index`). In
+ this case, `from_tf` should be set to `True` and a configuration object should be provided as
+ `config` argument. This loading path is slower than converting the TensorFlow checkpoint in a
+ PyTorch model using the provided conversion scripts and loading the PyTorch model afterwards.
+
+ decoder_pretrained_model_name_or_path (`str`, *optional*, defaults to `None`):
+ Information necessary to initiate the text decoder. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~PreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *tensorflow index checkpoint file* (e.g, `./tf_model/model.ckpt.index`). In
+ this case, `from_tf` should be set to `True` and a configuration object should be provided as
+ `config` argument. This loading path is slower than converting the TensorFlow checkpoint in a
+ PyTorch model using the provided conversion scripts and loading the PyTorch model afterwards.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the encoder configuration, use the prefix *encoder_* for each configuration parameter.
+ - To update the decoder configuration, use the prefix *decoder_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import VisionEncoderDecoderModel
+
+ >>> # initialize a vit-bert from a pretrained ViT and a pretrained BERT model. Note that the cross-attention layers will be randomly initialized
+ >>> model = VisionEncoderDecoderModel.from_encoder_decoder_pretrained(
+ ... "google/vit-base-patch16-224-in21k", "google-bert/bert-base-uncased"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./vit-bert")
+ >>> # load fine-tuned model
+ >>> model = VisionEncoderDecoderModel.from_pretrained("./vit-bert")
+ ```"""
+
+ kwargs_encoder = {
+ argument[len("encoder_") :]: value for argument, value in kwargs.items() if argument.startswith("encoder_")
+ }
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+
+ # remove encoder, decoder kwargs from kwargs
+ for key in kwargs_encoder:
+ del kwargs["encoder_" + key]
+ for key in kwargs_decoder:
+ del kwargs["decoder_" + key]
+
+ # Load and initialize the encoder and decoder
+ # The distinction between encoder and decoder at the model level is made
+ # by the value of the flag `is_decoder` that we need to set correctly.
+ encoder = kwargs_encoder.pop("model", None)
+ if encoder is None:
+ if encoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `encoder_model` is not defined as an argument, a `encoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_encoder:
+ encoder_config, kwargs_encoder = AutoConfig.from_pretrained(
+ encoder_pretrained_model_name_or_path, **kwargs_encoder, return_unused_kwargs=True
+ )
+
+ if encoder_config.is_decoder is True or encoder_config.add_cross_attention is True:
+ logger.info(
+ f"Initializing {encoder_pretrained_model_name_or_path} as a encoder model "
+ "from a decoder model. Cross-attention and causal mask are disabled."
+ )
+ encoder_config.is_decoder = False
+ encoder_config.add_cross_attention = False
+
+ kwargs_encoder["config"] = encoder_config
+
+ encoder = AutoModel.from_pretrained(encoder_pretrained_model_name_or_path, *model_args, **kwargs_encoder)
+
+ decoder = kwargs_decoder.pop("model", None)
+ if decoder is None:
+ if decoder_pretrained_model_name_or_path is None:
+ raise ValueError(
+ "If `decoder_model` is not defined as an argument, a `decoder_pretrained_model_name_or_path` has "
+ "to be defined."
+ )
+
+ if "config" not in kwargs_decoder:
+ decoder_config, kwargs_decoder = AutoConfig.from_pretrained(
+ decoder_pretrained_model_name_or_path, **kwargs_decoder, return_unused_kwargs=True
+ )
+
+ if decoder_config.is_decoder is False or decoder_config.add_cross_attention is False:
+ logger.info(
+ f"Initializing {decoder_pretrained_model_name_or_path} as a decoder model. Cross attention"
+ f" layers are added to {decoder_pretrained_model_name_or_path} and randomly initialized if"
+ f" {decoder_pretrained_model_name_or_path}'s architecture allows for cross attention layers."
+ )
+ decoder_config.is_decoder = True
+ decoder_config.add_cross_attention = True
+
+ kwargs_decoder["config"] = decoder_config
+
+ if kwargs_decoder["config"].is_decoder is False or kwargs_decoder["config"].add_cross_attention is False:
+ logger.warning(
+ f"Decoder model {decoder_pretrained_model_name_or_path} is not initialized as a decoder. "
+ f"In order to initialize {decoder_pretrained_model_name_or_path} as a decoder, "
+ "make sure that the attributes `is_decoder` and `add_cross_attention` of `decoder_config` "
+ "passed to `.from_encoder_decoder_pretrained(...)` are set to `True` or do not pass a "
+ "`decoder_config` to `.from_encoder_decoder_pretrained(...)`"
+ )
+
+ decoder = AutoModelForCausalLM.from_pretrained(decoder_pretrained_model_name_or_path, **kwargs_decoder)
+
+ # instantiate config with corresponding kwargs
+ config = VisionEncoderDecoderConfig.from_encoder_decoder_configs(encoder.config, decoder.config, **kwargs)
+
+ # make sure input & output embeddings is not tied
+ config.tie_word_embeddings = False
+ return cls(encoder=encoder, decoder=decoder, config=config)
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.BoolTensor] = None,
+ encoder_outputs: Optional[tuple[torch.FloatTensor]] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ decoder_inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ **kwargs,
+ ) -> Union[tuple[torch.FloatTensor], Seq2SeqLMOutput]:
+ r"""
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+
+ For training, `decoder_input_ids` are automatically created by the model by shifting the `labels` to the
+ right, replacing -100 by the `pad_token_id` and prepending them with the `decoder_start_token_id`.
+ decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+ decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, target_sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `decoder_input_ids` you can choose to directly pass an embedded
+ representation. This is useful if you want more control over how to convert `decoder_input_ids` indices
+ into associated vectors than the model's internal embedding lookup matrix.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss for the decoder. Indices should be in `[-100, 0,
+ ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoProcessor, VisionEncoderDecoderModel
+ >>> import requests
+ >>> from PIL import Image
+ >>> import torch
+
+ >>> processor = AutoProcessor.from_pretrained("microsoft/trocr-base-handwritten")
+ >>> model = VisionEncoderDecoderModel.from_pretrained("microsoft/trocr-base-handwritten")
+
+ >>> # load image from the IAM dataset
+ >>> url = "https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+ >>> # training
+ >>> model.config.decoder_start_token_id = processor.tokenizer.eos_token_id
+ >>> model.config.pad_token_id = processor.tokenizer.pad_token_id
+ >>> model.config.vocab_size = model.config.decoder.vocab_size
+
+ >>> pixel_values = processor(image, return_tensors="pt").pixel_values
+ >>> text = "hello world"
+ >>> labels = processor.tokenizer(text, return_tensors="pt").input_ids
+ >>> outputs = model(pixel_values=pixel_values, labels=labels)
+ >>> loss = outputs.loss
+
+ >>> # inference (generation)
+ >>> generated_ids = model.generate(pixel_values)
+ >>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # num_items_in_batch is only needed for loss computation
+ num_items_in_batch = kwargs.pop("num_items_in_batch", None)
+
+ kwargs_encoder = {argument: value for argument, value in kwargs.items() if not argument.startswith("decoder_")}
+
+ kwargs_decoder = {
+ argument[len("decoder_") :]: value for argument, value in kwargs.items() if argument.startswith("decoder_")
+ }
+
+ if encoder_outputs is None:
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ encoder_outputs = self.encoder(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ **kwargs_encoder,
+ )
+ elif isinstance(encoder_outputs, tuple):
+ encoder_outputs = BaseModelOutput(*encoder_outputs)
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ # optionally project encoder_hidden_states
+ if (
+ self.encoder.config.hidden_size != self.decoder.config.hidden_size
+ and self.decoder.config.cross_attention_hidden_size is None
+ ):
+ encoder_hidden_states = self.enc_to_dec_proj(encoder_hidden_states)
+
+ # else:
+ encoder_attention_mask = None
+
+ if (labels is not None) and (decoder_input_ids is None and decoder_inputs_embeds is None):
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ # Decode
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ inputs_embeds=decoder_inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ use_cache=use_cache,
+ past_key_values=past_key_values,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ **kwargs_decoder,
+ )
+
+ # Compute loss independent from decoder (as some shift the logits inside them)
+ loss = None
+ if labels is not None:
+ logits = decoder_outputs.logits if return_dict else decoder_outputs[0]
+
+ loss = self.loss_function(
+ logits=logits,
+ labels=labels,
+ vocab_size=self.decoder.config.vocab_size,
+ num_items_in_batch=num_items_in_batch,
+ )
+
+ if not return_dict:
+ if loss is not None:
+ return (loss,) + decoder_outputs + encoder_outputs
+ else:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=decoder_outputs.logits,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor):
+ return shift_tokens_right(labels, self.config.pad_token_id, self.config.decoder_start_token_id)
+
+
+__all__ = ["VisionEncoderDecoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..4b68df9c336f8ec77dd6a9efc87175dc6e50eaa6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vision_text_dual_encoder import *
+ from .modeling_flax_vision_text_dual_encoder import *
+ from .modeling_tf_vision_text_dual_encoder import *
+ from .modeling_vision_text_dual_encoder import *
+ from .processing_vision_text_dual_encoder import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/configuration_vision_text_dual_encoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/configuration_vision_text_dual_encoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..3f544e9eaf05061d1a362059edc5fea654952c5f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/configuration_vision_text_dual_encoder.py
@@ -0,0 +1,122 @@
+# coding=utf-8
+# Copyright The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VisionTextDualEncoder model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ..auto.configuration_auto import AutoConfig
+from ..chinese_clip.configuration_chinese_clip import ChineseCLIPVisionConfig
+from ..clip.configuration_clip import CLIPVisionConfig
+from ..siglip.configuration_siglip import SiglipVisionConfig
+
+
+logger = logging.get_logger(__name__)
+
+VISION_MODEL_CONFIGS = {
+ "clip_vision_model": CLIPVisionConfig,
+ "chinese_clip_vision_model": ChineseCLIPVisionConfig,
+ "siglip_vision_model": SiglipVisionConfig,
+}
+
+
+class VisionTextDualEncoderConfig(PretrainedConfig):
+ r"""
+ [`VisionTextDualEncoderConfig`] is the configuration class to store the configuration of a
+ [`VisionTextDualEncoderModel`]. It is used to instantiate [`VisionTextDualEncoderModel`] model according to the
+ specified arguments, defining the text model and vision model configs.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ projection_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of text and vision projection layers.
+ logit_scale_init_value (`float`, *optional*, defaults to 2.6592):
+ The initial value of the *logit_scale* parameter. Default is used as per the original CLIP implementation.
+ kwargs (*optional*):
+ Dictionary of keyword arguments.
+
+ Examples:
+
+ ```python
+ >>> from transformers import ViTConfig, BertConfig, VisionTextDualEncoderConfig, VisionTextDualEncoderModel
+
+ >>> # Initializing a BERT and ViT configuration
+ >>> config_vision = ViTConfig()
+ >>> config_text = BertConfig()
+
+ >>> config = VisionTextDualEncoderConfig.from_vision_text_configs(config_vision, config_text, projection_dim=512)
+
+ >>> # Initializing a BERT and ViT model (with random weights)
+ >>> model = VisionTextDualEncoderModel(config=config)
+
+ >>> # Accessing the model configuration
+ >>> config_vision = model.config.vision_config
+ >>> config_text = model.config.text_config
+
+ >>> # Saving the model, including its configuration
+ >>> model.save_pretrained("vit-bert")
+
+ >>> # loading model and config from pretrained folder
+ >>> vision_text_config = VisionTextDualEncoderConfig.from_pretrained("vit-bert")
+ >>> model = VisionTextDualEncoderModel.from_pretrained("vit-bert", config=vision_text_config)
+ ```"""
+
+ model_type = "vision-text-dual-encoder"
+ sub_configs = {"vision_config": AutoConfig, "text_config": AutoConfig}
+ has_no_defaults_at_init = True
+
+ def __init__(self, projection_dim=512, logit_scale_init_value=2.6592, **kwargs):
+ super().__init__(**kwargs)
+
+ if "vision_config" not in kwargs:
+ raise ValueError("`vision_config` can not be `None`.")
+
+ if "text_config" not in kwargs:
+ raise ValueError("`text_config` can not be `None`.")
+
+ vision_config = kwargs.pop("vision_config")
+ text_config = kwargs.pop("text_config")
+
+ vision_model_type = vision_config.pop("model_type")
+ text_model_type = text_config.pop("model_type")
+
+ vision_config_class = VISION_MODEL_CONFIGS.get(vision_model_type)
+ if vision_config_class is not None:
+ self.vision_config = vision_config_class(**vision_config)
+ else:
+ self.vision_config = AutoConfig.for_model(vision_model_type, **vision_config)
+ if hasattr(self.vision_config, "vision_config"):
+ self.vision_config = self.vision_config.vision_config
+
+ self.text_config = AutoConfig.for_model(text_model_type, **text_config)
+
+ self.projection_dim = projection_dim
+ self.logit_scale_init_value = logit_scale_init_value
+
+ @classmethod
+ def from_vision_text_configs(cls, vision_config: PretrainedConfig, text_config: PretrainedConfig, **kwargs):
+ r"""
+ Instantiate a [`VisionTextDualEncoderConfig`] (or a derived class) from text model configuration and vision
+ model configuration.
+
+ Returns:
+ [`VisionTextDualEncoderConfig`]: An instance of a configuration object
+ """
+
+ return cls(vision_config=vision_config.to_dict(), text_config=text_config.to_dict(), **kwargs)
+
+
+__all__ = ["VisionTextDualEncoderConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_flax_vision_text_dual_encoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_flax_vision_text_dual_encoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..15ef5d48a32d6d2f67c5dd7d5107683dd6261181
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_flax_vision_text_dual_encoder.py
@@ -0,0 +1,601 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Flax VisionTextDualEncoder model."""
+
+from typing import Optional
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.traverse_util import flatten_dict, unflatten_dict
+
+from ...modeling_flax_utils import FlaxPreTrainedModel, append_replace_return_docstrings, overwrite_call_docstring
+from ...utils import add_start_docstrings, logging
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_flax_auto import FLAX_MODEL_MAPPING, FlaxAutoModel
+from ..clip.modeling_flax_clip import FlaxCLIPOutput, FlaxCLIPVisionModel
+from .configuration_vision_text_dual_encoder import VisionTextDualEncoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "VisionTextDualEncoderConfig"
+
+VISION_TEXT_DUAL_ENCODER_START_DOCSTRING = r"""
+ This class can be used to initialize a vision-text dual encoder model with any pretrained vision autoencoding model
+ as the vision encoder and any pretrained text model as the text encoder. The vision and text encoders are loaded
+ via the [`~FlaxAutoModel.from_pretrained`] method. The projection layers are automatically added to the model and
+ should be fine-tuned on a downstream task, like contrastive image-text modeling.
+
+ In [LiT: Zero-Shot Transfer with Locked-image Text Tuning](https://huggingface.co/papers/2111.07991) it is shown how
+ leveraging pre-trained (locked/frozen) image and text model for contrastive learning yields significant improvement
+ on new zero-shot vision tasks such as image classification or retrieval.
+
+ After such a Vision-Text-Dual-Encoder model has been trained/fine-tuned, it can be saved/loaded just like any other
+ models (see the examples for more information).
+
+ This model inherits from [`PreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a
+ [flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html) subclass. Use it
+ as a regular Flax linen Module and refer to the Flax documentation for all matter related to general usage and
+ behavior.
+
+ Finally, this model supports inherent JAX features such as:
+
+ - [Just-In-Time (JIT) compilation](https://jax.readthedocs.io/en/latest/jax.html#just-in-time-compilation-jit)
+ - [Automatic Differentiation](https://jax.readthedocs.io/en/latest/jax.html#automatic-differentiation)
+ - [Vectorization](https://jax.readthedocs.io/en/latest/jax.html#vectorization-vmap)
+ - [Parallelization](https://jax.readthedocs.io/en/latest/jax.html#parallelization-pmap)
+
+ Parameters:
+ config ([`VisionTextDualEncoderConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs).
+
+ This can be used to enable mixed-precision training or half-precision inference on GPUs or TPUs. If
+ specified all the computation will be performed with the given `dtype`.
+
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.**
+
+ If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`] and
+ [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+
+VISION_TEXT_DUAL_ENCODER_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ position_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Padding will be ignored by default should you provide it. Pixel values can be obtained using
+ an image processor (e.g. if you use ViT as the encoder, you should use [`AutoImageProcessor`]). See
+ [`ViTImageProcessor.__call__`] for details.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+class FlaxVisionTextDualEncoderModule(nn.Module):
+ config: VisionTextDualEncoderConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ vision_config = self.config.vision_config
+ text_config = self.config.text_config
+
+ self.vision_embed_dim = vision_config.hidden_size
+ self.text_embed_dim = text_config.hidden_size
+ self.projection_dim = self.config.projection_dim
+
+ vision_module = FLAX_MODEL_MAPPING.get(self.config.vision_config.__class__, FlaxCLIPVisionModel).module_class
+ text_module = FLAX_MODEL_MAPPING[self.config.text_config.__class__].module_class
+
+ self.vision_model = vision_module(vision_config, dtype=self.dtype)
+ self.text_model = text_module(text_config, dtype=self.dtype)
+
+ self.visual_projection = nn.Dense(
+ self.projection_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(0.02),
+ use_bias=False,
+ )
+ self.text_projection = nn.Dense(
+ self.projection_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(0.02),
+ use_bias=False,
+ )
+
+ self.logit_scale = self.param(
+ "logit_scale", lambda _, shape: jnp.ones(shape) * self.config.logit_scale_init_value, []
+ )
+
+ def __call__(
+ self,
+ input_ids=None,
+ pixel_values=None,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ deterministic: bool = True,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ image_embeds = vision_outputs[1]
+ image_embeds = self.visual_projection(image_embeds)
+
+ text_embeds = text_outputs[1]
+ text_embeds = self.text_projection(text_embeds)
+
+ # normalized features
+ image_embeds = image_embeds / jnp.linalg.norm(image_embeds, axis=-1, keepdims=True)
+ text_embeds = text_embeds / jnp.linalg.norm(text_embeds, axis=-1, keepdims=True)
+
+ # cosine similarity as logits
+ logit_scale = jnp.exp(self.logit_scale)
+ logits_per_text = jnp.matmul(text_embeds, image_embeds.T) * logit_scale
+ logits_per_image = logits_per_text.T
+
+ if not return_dict:
+ return (logits_per_image, logits_per_text, text_embeds, image_embeds, text_outputs, vision_outputs)
+
+ return FlaxCLIPOutput(
+ logits_per_image=logits_per_image,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ image_embeds=image_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ )
+
+
+@add_start_docstrings(VISION_TEXT_DUAL_ENCODER_START_DOCSTRING)
+class FlaxVisionTextDualEncoderModel(FlaxPreTrainedModel):
+ config_class = VisionTextDualEncoderConfig
+ module_class = FlaxVisionTextDualEncoderModule
+
+ def __init__(
+ self,
+ config: VisionTextDualEncoderConfig,
+ input_shape: Optional[tuple] = None,
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ **kwargs,
+ ):
+ if not _do_init:
+ raise ValueError(
+ "`FlaxVisionTextDualEncoderModel` cannot be created without initializing, `_do_init` must be `True`."
+ )
+
+ if input_shape is None:
+ input_shape = ((1, 1), (1, config.vision_config.image_size, config.vision_config.image_size, 3))
+
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype)
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensor
+ input_ids = jnp.zeros(input_shape[0], dtype="i4")
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_shape[0])
+ token_type_ids = jnp.ones_like(input_ids)
+ attention_mask = jnp.ones_like(input_ids)
+
+ pixel_values = jax.random.normal(rng, input_shape[1])
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(rngs, input_ids, pixel_values, attention_mask, position_ids, token_type_ids)[
+ "params"
+ ]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ def __call__(
+ self,
+ input_ids,
+ pixel_values,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ params: Optional[dict] = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ train: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ pixel_values = jnp.transpose(pixel_values, (0, 2, 3, 1))
+
+ if position_ids is None:
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_ids.shape)
+
+ if token_type_ids is None:
+ token_type_ids = jnp.zeros_like(input_ids)
+
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ return self.module.apply(
+ {"params": params or self.params},
+ jnp.array(input_ids, dtype="i4"),
+ jnp.array(pixel_values, dtype=jnp.float32),
+ jnp.array(attention_mask, dtype="i4"),
+ jnp.array(position_ids, dtype="i4"),
+ jnp.array(token_type_ids, dtype="i4"),
+ not train,
+ output_attentions,
+ output_hidden_states,
+ return_dict,
+ rngs=rngs,
+ )
+
+ def get_text_features(
+ self,
+ input_ids,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ params: Optional[dict] = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ train=False,
+ ):
+ r"""
+ Args:
+ input_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you
+ provide it.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+
+ Returns:
+ text_features (`jnp.ndarray` of shape `(batch_size, output_dim`): The text embeddings obtained by applying
+ the projection layer to the pooled output of text model.
+ """
+ if position_ids is None:
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_ids.shape)
+
+ if token_type_ids is None:
+ token_type_ids = jnp.zeros_like(input_ids)
+
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _get_features(module, input_ids, attention_mask, position_ids, token_type_ids, deterministic):
+ text_outputs = module.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ deterministic=deterministic,
+ )
+ pooled_output = text_outputs[1]
+ text_features = module.text_projection(pooled_output)
+ return text_features
+
+ return self.module.apply(
+ {"params": params or self.params},
+ jnp.array(input_ids, dtype="i4"),
+ jnp.array(attention_mask, dtype="i4"),
+ jnp.array(position_ids, dtype="i4"),
+ jnp.array(token_type_ids, dtype="i4"),
+ not train,
+ method=_get_features,
+ rngs=rngs,
+ )
+
+ def get_image_features(
+ self, pixel_values, params: Optional[dict] = None, dropout_rng: jax.random.PRNGKey = None, train=False
+ ):
+ r"""
+ Args:
+ pixel_values (`numpy.ndarray` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Padding will be ignored by default should you provide it. Pixel values can be obtained
+ using [`ImageFeatureExtractionMixin`]. See [`ImageFeatureExtractionMixin.__call__`] for details.
+
+ Returns:
+ image_features (`jnp.ndarray` of shape `(batch_size, output_dim`): The image embeddings obtained by
+ applying the projection layer to the pooled output of vision model.
+ """
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _get_features(module, pixel_values, deterministic):
+ vision_outputs = module.vision_model(pixel_values=pixel_values, deterministic=deterministic)
+ pooled_output = vision_outputs[1] # pooled_output
+ image_features = module.visual_projection(pooled_output)
+ return image_features
+
+ return self.module.apply(
+ {"params": params or self.params},
+ jnp.array(pixel_values, dtype=jnp.float32),
+ not train,
+ method=_get_features,
+ rngs=rngs,
+ )
+
+ @classmethod
+ def from_vision_text_pretrained(
+ cls,
+ vision_model_name_or_path: Optional[str] = None,
+ text_model_name_or_path: Optional[str] = None,
+ *model_args,
+ **kwargs,
+ ) -> FlaxPreTrainedModel:
+ """
+ Params:
+ vision_model_name_or_path (`str`, *optional*, defaults to `None`):
+ Information necessary to initiate the vision model. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~FlaxPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *PyTorch checkpoint folder* (e.g, `./pt_model`). In this case, `from_pt`
+ should be set to `True` and a configuration object should be provided as `config` argument. This
+ loading path is slower than converting the PyTorch checkpoint in a Flax model using the provided
+ conversion scripts and loading the Flax model afterwards.
+
+ text_model_name_or_path (`str`, *optional*):
+ Information necessary to initiate the text model. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~FlaxPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *PyTorch checkpoint folder* (e.g, `./pt_model`). In this case, `from_pt`
+ should be set to `True` and a configuration object should be provided as `config` argument. This
+ loading path is slower than converting the PyTorch checkpoint in a Flax model using the provided
+ conversion scripts and loading the Flax model afterwards.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the text configuration, use the prefix *text_* for each configuration parameter.
+ - To update the vision configuration, use the prefix *vision_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import FlaxVisionTextDualEncoderModel
+
+ >>> # initialize a model from pretrained ViT and BERT models. Note that the projection layers will be randomly initialized.
+ >>> model = FlaxVisionTextDualEncoderModel.from_vision_text_pretrained(
+ ... "google/vit-base-patch16-224", "google-bert/bert-base-uncased"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./vit-bert")
+ >>> # load fine-tuned model
+ >>> model = FlaxVisionTextDualEncoderModel.from_pretrained("./vit-bert")
+ ```"""
+
+ kwargs_vision = {
+ argument[len("vision_") :]: value for argument, value in kwargs.items() if argument.startswith("vision_")
+ }
+
+ kwargs_text = {
+ argument[len("text_") :]: value for argument, value in kwargs.items() if argument.startswith("text_")
+ }
+
+ # remove text, vision kwargs from kwargs
+ for key in kwargs_vision:
+ del kwargs["vision_" + key]
+ for key in kwargs_text:
+ del kwargs["text_" + key]
+
+ # Load and initialize the text and vision model
+ vision_model = kwargs_vision.pop("model", None)
+ if vision_model is None:
+ if vision_model_name_or_path is None:
+ raise ValueError(
+ "If `vision_model` is not defined as an argument, a `vision_model_name_or_path` has to be defined"
+ )
+
+ if "config" not in kwargs_vision:
+ vision_config = AutoConfig.from_pretrained(vision_model_name_or_path)
+
+ if vision_config.model_type == "clip":
+ kwargs_vision["config"] = vision_config.vision_config
+ vision_model = FlaxCLIPVisionModel.from_pretrained(
+ vision_model_name_or_path, *model_args, **kwargs_vision
+ )
+ else:
+ kwargs_vision["config"] = vision_config
+ vision_model = FlaxAutoModel.from_pretrained(vision_model_name_or_path, *model_args, **kwargs_vision)
+
+ text_model = kwargs_text.pop("model", None)
+ if text_model is None:
+ if text_model_name_or_path is None:
+ raise ValueError(
+ "If `text_model` is not defined as an argument, a `text_model_name_or_path` has to be defined"
+ )
+
+ if "config" not in kwargs_text:
+ text_config = AutoConfig.from_pretrained(text_model_name_or_path)
+ kwargs_text["config"] = text_config
+
+ text_model = FlaxAutoModel.from_pretrained(text_model_name_or_path, *model_args, **kwargs_text)
+
+ # instantiate config with corresponding kwargs
+ dtype = kwargs.pop("dtype", jnp.float32)
+ config = VisionTextDualEncoderConfig.from_vision_text_configs(vision_model.config, text_model.config, **kwargs)
+
+ # init model
+ model = cls(config, *model_args, dtype=dtype, **kwargs)
+
+ model.params["vision_model"] = vision_model.params
+ model.params["text_model"] = text_model.params
+
+ # the projection layers are always newly initialized when loading the model
+ # using pre-trained vision and text model.
+ logger.warning(
+ "The projection layer and logit scale weights `[('visual_projection', 'kernel'), ('text_projection',"
+ " 'kernel'), ('logit_scale',)]` are newly initialized. You should probably TRAIN this model on a"
+ " down-stream task to be able to use it for predictions and inference."
+ )
+
+ return model
+
+
+VISION_TEXT_DUAL_ENCODER_MODEL_DOCSTRING = r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> import jax
+ >>> from transformers import (
+ ... FlaxVisionTextDualEncoderModel,
+ ... VisionTextDualEncoderProcessor,
+ ... AutoImageProcessor,
+ ... AutoTokenizer,
+ ... )
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+ >>> processor = VisionTextDualEncoderProcessor(image_processor, tokenizer)
+ >>> model = FlaxVisionTextDualEncoderModel.from_vision_text_pretrained(
+ ... "google/vit-base-patch16-224", "google-bert/bert-base-uncased"
+ ... )
+
+ >>> # contrastive training
+ >>> urls = [
+ ... "http://images.cocodataset.org/val2017/000000039769.jpg",
+ ... "https://farm3.staticflickr.com/2674/5850229113_4fe05d5265_z.jpg",
+ ... ]
+ >>> images = [Image.open(requests.get(url, stream=True).raw) for url in urls]
+ >>> inputs = processor(
+ ... text=["a photo of a cat", "a photo of a dog"], images=images, return_tensors="np", padding=True
+ ... )
+ >>> outputs = model(
+ ... input_ids=inputs.input_ids,
+ ... attention_mask=inputs.attention_mask,
+ ... pixel_values=inputs.pixel_values,
+ ... )
+ >>> logits_per_image = outputs.logits_per_image # this is the image-text similarity score
+
+ >>> # save and load from pretrained
+ >>> model.save_pretrained("vit-bert")
+ >>> model = FlaxVisionTextDualEncoderModel.from_pretrained("vit-bert")
+
+ >>> # inference
+ >>> outputs = model(**inputs)
+ >>> logits_per_image = outputs.logits_per_image # this is the image-text similarity score
+ >>> probs = jax.nn.softmax(logits_per_image, axis=1) # we can take the softmax to get the label probabilities
+ ```
+"""
+
+overwrite_call_docstring(
+ FlaxVisionTextDualEncoderModel,
+ VISION_TEXT_DUAL_ENCODER_INPUTS_DOCSTRING + VISION_TEXT_DUAL_ENCODER_MODEL_DOCSTRING,
+)
+append_replace_return_docstrings(
+ FlaxVisionTextDualEncoderModel, output_type=FlaxCLIPOutput, config_class=_CONFIG_FOR_DOC
+)
+
+
+__all__ = ["FlaxVisionTextDualEncoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_tf_vision_text_dual_encoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_tf_vision_text_dual_encoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..42ff0be7a9e8548ce2fbd4dc75235aae9aa8aefc
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_tf_vision_text_dual_encoder.py
@@ -0,0 +1,623 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TensorFlow VisionTextDualEncoder model."""
+
+from __future__ import annotations
+
+import re
+
+import tensorflow as tf
+
+from ...configuration_utils import PretrainedConfig
+from ...modeling_tf_utils import TFPreTrainedModel, keras, unpack_inputs
+from ...tf_utils import shape_list
+from ...utils import (
+ DUMMY_INPUTS,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+ replace_return_docstrings,
+)
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_tf_auto import TFAutoModel
+from ..clip.modeling_tf_clip import CLIPVisionConfig, TFCLIPOutput, TFCLIPVisionModel
+from .configuration_vision_text_dual_encoder import VisionTextDualEncoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "VisionTextDualEncoderConfig"
+
+VISION_TEXT_DUAL_ENCODER_START_DOCSTRING = r"""
+ This class can be used to initialize a vision-text dual encoder model with any pretrained vision autoencoding model
+ as the vision encoder and any pretrained text model as the text encoder. The vision and text encoders are loaded
+ via the [`~TFAutoModel.from_pretrained`] method. The projection layers are automatically added to the model and
+ should be fine-tuned on a downstream task, like contrastive image-text modeling.
+
+ In [LiT: Zero-Shot Transfer with Locked-image Text Tuning](https://huggingface.co/papers/2111.07991) it is shown how
+ leveraging pre-trained (locked/frozen) image and text model for contrastive learning yields significant improvement
+ on new zero-shot vision tasks such as image classification or retrieval.
+
+ After such a Vision-Text-Dual-Encoder model has been trained/fine-tuned, it can be saved/loaded just like any other
+ models (see the examples for more information).
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a Keras [Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it as a
+ regular Keras Model and refer to the TF documentation for all matter related to general usage and behavior.
+
+ Parameters:
+ config ([`VisionEncoderDecoderConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~TFPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+
+VISION_TEXT_DUAL_ENCODER_TEXT_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`PreTrainedTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ position_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+VISION_TEXT_DUAL_ENCODER_VISION_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`tf.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Padding will be ignored by default should you provide it. Pixel values can be obtained using
+ [`AutoImageProcessor`]. See [`CLIPImageProcessor.__call__`] for details.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+VISION_TEXT_DUAL_ENCODER_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ position_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ pixel_values (`tf.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Padding will be ignored by default should you provide it. Pixel values can be obtained using
+ an image processor (e.g. if you use ViT as the encoder, you should use [`AutoImageProcessor`]). See
+ [`ViTImageProcessor.__call__`] for details.
+ return_loss (`bool`, *optional*):
+ Whether or not to return the contrastive loss.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+# Copied from transformers.models.clip.modeling_tf_clip.contrastive_loss
+def contrastive_loss(logits: tf.Tensor) -> tf.Tensor:
+ return tf.math.reduce_mean(
+ keras.metrics.sparse_categorical_crossentropy(
+ y_true=tf.range(shape_list(logits)[0]), y_pred=logits, from_logits=True
+ )
+ )
+
+
+# Copied from transformers.models.clip.modeling_tf_clip.clip_loss
+def clip_loss(similarity: tf.Tensor) -> tf.Tensor:
+ caption_loss = contrastive_loss(similarity)
+ image_loss = contrastive_loss(tf.transpose(similarity))
+ return (caption_loss + image_loss) / 2.0
+
+
+@add_start_docstrings(VISION_TEXT_DUAL_ENCODER_START_DOCSTRING)
+class TFVisionTextDualEncoderModel(TFPreTrainedModel):
+ config_class = VisionTextDualEncoderConfig
+ base_model_prefix = "vision_text_dual_encoder"
+ load_weight_prefix = "tf_vision_text_dual_encoder_model"
+
+ def __init__(
+ self,
+ config: VisionTextDualEncoderConfig | None = None,
+ vision_model: TFPreTrainedModel | None = None,
+ text_model: TFPreTrainedModel | None = None,
+ ):
+ if config is None and (vision_model is None or text_model is None):
+ raise ValueError("Either a configuration or an vision and a text model has to be provided")
+
+ if config is None:
+ config = VisionTextDualEncoderConfig.from_vision_text_configs(vision_model.config, text_model.config)
+ else:
+ if not isinstance(config, self.config_class):
+ raise ValueError(f"config: {config} has to be of type {self.config_class}")
+
+ # initialize with config
+ super().__init__(config)
+
+ if vision_model is None:
+ if isinstance(config.vision_config, CLIPVisionConfig):
+ vision_model = TFCLIPVisionModel.from_config(config.vision_config, name="vision_model")
+ else:
+ vision_model = TFAutoModel.from_config(config.vision_config, name="vision_model")
+
+ if text_model is None:
+ text_model = TFAutoModel.from_config(config.text_config, name="text_model")
+
+ self.vision_model = vision_model
+ self.text_model = text_model
+
+ # make sure that the individual model's config refers to the shared config
+ # so that the updates to the config will be synced
+ self.vision_model.config = self.config.vision_config
+ self.text_model.config = self.config.text_config
+
+ self.vision_embed_dim = config.vision_config.hidden_size
+ self.text_embed_dim = config.text_config.hidden_size
+ self.projection_dim = config.projection_dim
+
+ self.visual_projection = keras.layers.Dense(self.projection_dim, use_bias=False, name="visual_projection")
+ self.text_projection = keras.layers.Dense(self.projection_dim, use_bias=False, name="text_projection")
+ self.logit_scale = None
+ self.config = config
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ # Build in the build() method to make sure the names are right
+ initializer = keras.initializers.Constant(self.config.logit_scale_init_value)
+ self.logit_scale = self.add_weight(shape=(1,), initializer=initializer, name="logit_scale")
+
+ if getattr(self, "visual_projection", None) is not None:
+ with tf.name_scope(self.visual_projection.name):
+ self.visual_projection.build([None, None, self.vision_embed_dim])
+ if getattr(self, "text_projection", None) is not None:
+ with tf.name_scope(self.text_projection.name):
+ self.text_projection.build([None, None, self.text_embed_dim])
+ with tf.name_scope(self.vision_model.name):
+ self.vision_model.build(None)
+ with tf.name_scope(self.text_model.name):
+ self.text_model.build(None)
+
+ def tf_to_pt_weight_rename(self, tf_weight):
+ # Matt: The TF and PT weights don't align because our TF base classes have an extra layer compared to PT models
+ # (the main model stem is in the MainLayer class). If we remove that layer, then weight names sync up as normal.
+ # However, the name of that extra layer is the name of the MainLayer in the base model.
+ if "vision_model" in tf_weight:
+ if tf_weight.count("vision_model") == 1:
+ return (re.sub(r"vision_model\..*?\.", "vision_model.", tf_weight),)
+ elif tf_weight.count("vision_model") == 2:
+ return (re.sub(r"vision_model\..*?\.vision_model", "vision_model.vision_model", tf_weight),)
+ else:
+ raise ValueError(
+ f"Unexpected weight name {tf_weight}. Please file an issue on the"
+ " Transformers repo to let us know about this error!"
+ )
+ elif "text_model" in tf_weight:
+ return (re.sub(r"text_model\..*?\.", "text_model.", tf_weight),)
+ else:
+ return (tf_weight,)
+
+ @add_start_docstrings_to_model_forward(VISION_TEXT_DUAL_ENCODER_TEXT_INPUTS_DOCSTRING)
+ def get_text_features(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Returns:
+ text_features (`tf.Tensor` of shape `(batch_size, output_dim`): The text embeddings obtained by applying
+ the projection layer to the pooled output of [`TFCLIPTextModel`].
+
+ Examples:
+
+ ```python
+ >>> from transformers import TFVisionTextDualEncoderModel, AutoTokenizer
+
+ >>> model = TFVisionTextDualEncoderModel.from_pretrained("clip-italian/clip-italian", from_pt=True)
+ >>> tokenizer = AutoTokenizer.from_pretrained("clip-italian/clip-italian")
+
+ >>> inputs = tokenizer(["una foto di un gatto", "una foto di un cane"], padding=True, return_tensors="np")
+ >>> text_features = model.get_text_features(**inputs)
+ ```"""
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = text_outputs[1]
+ text_features = self.text_projection(pooled_output)
+
+ return text_features
+
+ @add_start_docstrings_to_model_forward(VISION_TEXT_DUAL_ENCODER_VISION_INPUTS_DOCSTRING)
+ def get_image_features(
+ self,
+ pixel_values=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Returns:
+ image_features (`tf.Tensor` of shape `(batch_size, output_dim`): The image embeddings obtained by applying
+ the projection layer to the pooled output of [`TFCLIPVisionModel`].
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import TFVisionTextDualEncoderModel, AutoImageProcessor
+
+ >>> model = TFVisionTextDualEncoderModel.from_pretrained("clip-italian/clip-italian", from_pt=True)
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = image_processor(images=image, return_tensors="np")
+
+ >>> image_features = model.get_image_features(**inputs)
+ ```"""
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = vision_outputs[1] # pooled_output
+ image_features = self.visual_projection(pooled_output)
+
+ return image_features
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(VISION_TEXT_DUAL_ENCODER_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFCLIPOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: tf.Tensor | None = None,
+ pixel_values: tf.Tensor | None = None,
+ attention_mask: tf.Tensor | None = None,
+ position_ids: tf.Tensor | None = None,
+ return_loss: bool | None = None,
+ token_type_ids: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> tuple[tf.Tensor] | TFCLIPOutput:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import (
+ ... TFVisionTextDualEncoderModel,
+ ... VisionTextDualEncoderProcessor,
+ ... AutoImageProcessor,
+ ... AutoTokenizer,
+ ... )
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+ >>> processor = VisionTextDualEncoderProcessor(image_processor, tokenizer)
+ >>> model = TFVisionTextDualEncoderModel.from_vision_text_pretrained(
+ ... "google/vit-base-patch16-224", "google-bert/bert-base-uncased"
+ ... )
+
+ >>> # contrastive training
+ >>> urls = [
+ ... "http://images.cocodataset.org/val2017/000000039769.jpg",
+ ... "https://farm3.staticflickr.com/2674/5850229113_4fe05d5265_z.jpg",
+ ... ]
+ >>> images = [Image.open(requests.get(url, stream=True).raw) for url in urls]
+ >>> inputs = processor(
+ ... text=["a photo of a cat", "a photo of a dog"], images=images, return_tensors="np", padding=True
+ ... )
+ >>> outputs = model(
+ ... input_ids=inputs.input_ids,
+ ... attention_mask=inputs.attention_mask,
+ ... pixel_values=inputs.pixel_values,
+ ... return_loss=True,
+ ... )
+ >>> loss, logits_per_image = outputs.loss, outputs.logits_per_image # this is the image-text similarity score
+
+ >>> # save and load from pretrained
+ >>> model.save_pretrained("vit-bert")
+ >>> model = TFVisionTextDualEncoderModel.from_pretrained("vit-bert")
+
+ >>> # inference
+ >>> outputs = model(**inputs)
+ >>> logits_per_image = outputs.logits_per_image # this is the image-text similarity score
+ >>> probs = tf.nn.softmax(logits_per_image, axis=1) # we can take the softmax to get the label probabilities
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ image_embeds = vision_outputs[1] # pooler_output
+ image_embeds = self.visual_projection(image_embeds)
+
+ text_embeds = text_outputs[1] # pooler_output
+ text_embeds = self.text_projection(text_embeds)
+
+ # normalized features
+ image_embeds = image_embeds / tf.norm(image_embeds, axis=-1, keepdims=True)
+ text_embeds = text_embeds / tf.norm(text_embeds, axis=-1, keepdims=True)
+
+ # cosine similarity as logits
+ logit_scale = tf.math.exp(self.logit_scale)
+ logits_per_text = tf.matmul(text_embeds, image_embeds, transpose_b=True) * logit_scale
+ logits_per_image = tf.transpose(logits_per_text)
+
+ loss = None
+ if return_loss:
+ loss = clip_loss(logits_per_text)
+ if loss.shape.rank == 0:
+ loss = tf.expand_dims(loss, 0)
+
+ if not return_dict:
+ output = (logits_per_image, logits_per_text, text_embeds, image_embeds, text_outputs, vision_outputs)
+ return ((loss,) + output) if loss is not None else output
+
+ return TFCLIPOutput(
+ loss=loss,
+ logits_per_image=logits_per_image,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ image_embeds=image_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ )
+
+ @classmethod
+ def from_vision_text_pretrained(
+ cls,
+ vision_model_name_or_path: str | None = None,
+ text_model_name_or_path: str | None = None,
+ *model_args,
+ **kwargs,
+ ) -> TFPreTrainedModel:
+ """
+ Params:
+ vision_model_name_or_path (`str`, *optional*, defaults to `None`):
+ Information necessary to initiate the vision model. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~TFPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *PyTorch checkpoint folder* (e.g, `./pt_model`). In this case, `from_pt`
+ should be set to `True` and a configuration object should be provided as `config` argument.
+
+ text_model_name_or_path (`str`, *optional*):
+ Information necessary to initiate the text model. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~TFPreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *PyTorch checkpoint folder* (e.g, `./pt_model`). In this case, `from_pt`
+ should be set to `True` and a configuration object should be provided as `config` argument.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the text configuration, use the prefix *text_* for each configuration parameter.
+ - To update the vision configuration, use the prefix *vision_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import TFVisionTextDualEncoderModel
+
+ >>> # initialize a model from pretrained ViT and BERT models. Note that the projection layers will be randomly initialized.
+ >>> model = TFVisionTextDualEncoderModel.from_vision_text_pretrained(
+ ... "google/vit-base-patch16-224", "google-bert/bert-base-uncased"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./vit-bert")
+ >>> # load fine-tuned model
+ >>> model = TFVisionTextDualEncoderModel.from_pretrained("./vit-bert")
+ ```"""
+ kwargs_vision = {
+ argument[len("vision_") :]: value for argument, value in kwargs.items() if argument.startswith("vision_")
+ }
+
+ kwargs_text = {
+ argument[len("text_") :]: value for argument, value in kwargs.items() if argument.startswith("text_")
+ }
+
+ # remove vision, text kwargs from kwargs
+ for key in kwargs_vision:
+ del kwargs["vision_" + key]
+ for key in kwargs_text:
+ del kwargs["text_" + key]
+
+ # Load and initialize the vision and text model
+ vision_model = kwargs_vision.pop("model", None)
+ if vision_model is None:
+ if vision_model_name_or_path is None:
+ raise ValueError(
+ "If `vision_model` is not defined as an argument, a `vision_model_name_or_path` has to be defined"
+ )
+ kwargs_vision["name"] = "vision_model"
+ kwargs_vision["load_weight_prefix"] = cls.load_weight_prefix
+
+ vision_config_dict, unused_args = PretrainedConfig.get_config_dict(vision_model_name_or_path, **kwargs)
+ if vision_config_dict.get("model_type", None) == "clip_vision_model":
+ vision_config = CLIPVisionConfig.from_dict(vision_config_dict)
+ else:
+ vision_config = AutoConfig.from_pretrained(vision_model_name_or_path)
+
+ if vision_config.model_type == "clip_vision_model":
+ kwargs_vision["config"] = vision_config
+ vision_class = TFCLIPVisionModel
+ elif vision_config.model_type == "clip":
+ kwargs_vision["config"] = vision_config.vision_config
+ vision_class = TFCLIPVisionModel
+ else:
+ kwargs_vision["config"] = vision_config
+ vision_class = TFAutoModel
+ vision_model = vision_class.from_pretrained(vision_model_name_or_path, *model_args, **kwargs_vision)
+
+ text_model = kwargs_text.pop("model", None)
+ if text_model is None:
+ if text_model_name_or_path is None:
+ raise ValueError(
+ "If `text_model` is not defined as an argument, a `text_model_name_or_path` has to be defined"
+ )
+ kwargs_text["name"] = "text_model"
+ kwargs_text["load_weight_prefix"] = cls.load_weight_prefix
+
+ if "config" not in kwargs_text:
+ text_config = AutoConfig.from_pretrained(text_model_name_or_path)
+ kwargs_text["config"] = text_config
+
+ text_model = TFAutoModel.from_pretrained(text_model_name_or_path, *model_args, **kwargs_text)
+
+ # instantiate config with corresponding kwargs
+ config = VisionTextDualEncoderConfig.from_vision_text_configs(vision_model.config, text_model.config, **kwargs)
+
+ # init model
+ model = cls(config=config, vision_model=vision_model, text_model=text_model)
+
+ # the projection layers are always newly initialized when loading the model
+ # using pre-trained vision and text model.
+ logger.warning(
+ "The projection layer and logit scale weights `['visual_projection.weight', 'text_projection.weight',"
+ " 'logit_scale']` are newly initialized. You should probably TRAIN this model on a down-stream task to be"
+ " able to use it for predictions and inference."
+ )
+
+ if vision_model.name != "vision_model":
+ raise ValueError("vision model must be created with the name `vision_model`.")
+ if text_model.name != "text_model":
+ raise ValueError("text model must be created with the name `text_model`.")
+
+ model.build_in_name_scope() # Ensure model is fully built
+
+ return model
+
+ @property
+ def dummy_inputs(self):
+ """
+ Dummy inputs to build the network.
+
+ Returns:
+ `dict[str, tf.Tensor]`: The dummy inputs.
+ """
+ input_ids = tf.constant(DUMMY_INPUTS, dtype=tf.int32)
+ batch_size, seq_len = input_ids.shape
+
+ VISION_DUMMY_INPUTS = tf.random.uniform(
+ shape=(
+ batch_size,
+ self.config.vision_config.num_channels,
+ self.config.vision_config.image_size,
+ self.config.vision_config.image_size,
+ ),
+ dtype=tf.float32,
+ )
+ pixel_values = tf.constant(VISION_DUMMY_INPUTS)
+ dummy = {"pixel_values": pixel_values, "input_ids": input_ids}
+ return dummy
+
+
+__all__ = ["TFVisionTextDualEncoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_vision_text_dual_encoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_vision_text_dual_encoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..fd36c7afafb85b910e6174d292e885e02b451047
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/modeling_vision_text_dual_encoder.py
@@ -0,0 +1,423 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch VisionTextDualEncoder model."""
+
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ..auto.configuration_auto import AutoConfig
+from ..auto.modeling_auto import AutoModel
+from ..clip.modeling_clip import CLIPOutput, CLIPVisionConfig, CLIPVisionModel
+from .configuration_vision_text_dual_encoder import VisionTextDualEncoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.clip.modeling_clip.contrastive_loss
+def contrastive_loss(logits: torch.Tensor) -> torch.Tensor:
+ return nn.functional.cross_entropy(logits, torch.arange(len(logits), device=logits.device))
+
+
+# Copied from transformers.models.clip.modeling_clip.clip_loss
+def clip_loss(similarity: torch.Tensor) -> torch.Tensor:
+ caption_loss = contrastive_loss(similarity)
+ image_loss = contrastive_loss(similarity.t())
+ return (caption_loss + image_loss) / 2.0
+
+
+@auto_docstring
+class VisionTextDualEncoderModel(PreTrainedModel):
+ config: VisionTextDualEncoderConfig
+ base_model_prefix = "vision_text_dual_encoder"
+ _supports_flash_attn = True
+ _supports_sdpa = True
+
+ def __init__(
+ self,
+ config: Optional[VisionTextDualEncoderConfig] = None,
+ vision_model: Optional[PreTrainedModel] = None,
+ text_model: Optional[PreTrainedModel] = None,
+ ):
+ r"""
+ vision_model (`PreTrainedModel`):
+ The vision model to use.
+ text_model (`PreTrainedModel`):
+ The text model to use.
+ """
+ if config is None and (vision_model is None or text_model is None):
+ raise ValueError("Either a configuration or an vision and a text model has to be provided")
+
+ if config is None:
+ config = VisionTextDualEncoderConfig.from_vision_text_configs(vision_model.config, text_model.config)
+ else:
+ if not isinstance(config, self.config_class):
+ raise ValueError(f"config: {config} has to be of type {self.config_class}")
+
+ # initialize with config
+ super().__init__(config)
+
+ if vision_model is None:
+ if isinstance(config.vision_config, CLIPVisionConfig):
+ vision_model = CLIPVisionModel(config.vision_config)
+ else:
+ vision_model = AutoModel.from_config(config.vision_config)
+
+ if text_model is None:
+ text_model = AutoModel.from_config(config.text_config)
+
+ self.vision_model = vision_model
+ self.text_model = text_model
+
+ # make sure that the individual model's config refers to the shared config
+ # so that the updates to the config will be synced
+ self.config.vision_config._attn_implementation = self.vision_model.config._attn_implementation
+ self.config.text_config._attn_implementation = self.text_model.config._attn_implementation
+ self.vision_model.config = self.config.vision_config
+ self.text_model.config = self.config.text_config
+
+ self.vision_embed_dim = config.vision_config.hidden_size
+ self.text_embed_dim = config.text_config.hidden_size
+ self.projection_dim = config.projection_dim
+
+ self.visual_projection = nn.Linear(self.vision_embed_dim, self.projection_dim, bias=False)
+ self.text_projection = nn.Linear(self.text_embed_dim, self.projection_dim, bias=False)
+ self.logit_scale = nn.Parameter(torch.tensor(self.config.logit_scale_init_value))
+
+ @auto_docstring
+ def get_text_features(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ position_ids=None,
+ token_type_ids=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Returns:
+ text_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The text embeddings obtained by
+ applying the projection layer to the pooled output of [`CLIPTextModel`].
+
+ Examples:
+
+ ```python
+ >>> from transformers import VisionTextDualEncoderModel, AutoTokenizer
+
+ >>> model = VisionTextDualEncoderModel.from_pretrained("clip-italian/clip-italian")
+ >>> tokenizer = AutoTokenizer.from_pretrained("clip-italian/clip-italian")
+
+ >>> inputs = tokenizer(["una foto di un gatto", "una foto di un cane"], padding=True, return_tensors="pt")
+ >>> text_features = model.get_text_features(**inputs)
+ ```"""
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = text_outputs[1]
+ text_features = self.text_projection(pooled_output)
+
+ return text_features
+
+ @auto_docstring
+ def get_image_features(
+ self,
+ pixel_values=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Returns:
+ image_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The image embeddings obtained by
+ applying the projection layer to the pooled output of [`CLIPVisionModel`].
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import VisionTextDualEncoderModel, AutoImageProcessor
+
+ >>> model = VisionTextDualEncoderModel.from_pretrained("clip-italian/clip-italian")
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+
+ >>> image_features = model.get_image_features(**inputs)
+ ```"""
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = vision_outputs[1] # pooled_output
+ image_features = self.visual_projection(pooled_output)
+
+ return image_features
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ return_loss: Optional[bool] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], CLIPOutput]:
+ r"""
+ return_loss (`bool`, *optional*):
+ Whether or not to return the contrastive loss.
+
+ Examples:
+
+ ```python
+ >>> from PIL import Image
+ >>> import requests
+ >>> from transformers import (
+ ... VisionTextDualEncoderModel,
+ ... VisionTextDualEncoderProcessor,
+ ... AutoImageProcessor,
+ ... AutoTokenizer,
+ ... )
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+ >>> processor = VisionTextDualEncoderProcessor(image_processor, tokenizer)
+ >>> model = VisionTextDualEncoderModel.from_vision_text_pretrained(
+ ... "google/vit-base-patch16-224", "google-bert/bert-base-uncased"
+ ... )
+
+ >>> # contrastive training
+ >>> urls = [
+ ... "http://images.cocodataset.org/val2017/000000039769.jpg",
+ ... "https://farm3.staticflickr.com/2674/5850229113_4fe05d5265_z.jpg",
+ ... ]
+ >>> images = [Image.open(requests.get(url, stream=True).raw) for url in urls]
+ >>> inputs = processor(
+ ... text=["a photo of a cat", "a photo of a dog"], images=images, return_tensors="pt", padding=True
+ ... )
+ >>> outputs = model(
+ ... input_ids=inputs.input_ids,
+ ... attention_mask=inputs.attention_mask,
+ ... pixel_values=inputs.pixel_values,
+ ... return_loss=True,
+ ... )
+ >>> loss, logits_per_image = outputs.loss, outputs.logits_per_image # this is the image-text similarity score
+
+ >>> # save and load from pretrained
+ >>> model.save_pretrained("vit-bert")
+ >>> model = VisionTextDualEncoderModel.from_pretrained("vit-bert")
+
+ >>> # inference
+ >>> outputs = model(**inputs)
+ >>> logits_per_image = outputs.logits_per_image # this is the image-text similarity score
+ >>> probs = logits_per_image.softmax(dim=1) # we can take the softmax to get the label probabilities
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ image_embeds = vision_outputs[1] # pooler_output
+ image_embeds = self.visual_projection(image_embeds)
+
+ text_embeds = text_outputs[1] # pooler_output
+ text_embeds = self.text_projection(text_embeds)
+
+ # normalized features
+ image_embeds = image_embeds / image_embeds.norm(dim=-1, keepdim=True)
+ text_embeds = text_embeds / text_embeds.norm(dim=-1, keepdim=True)
+
+ # cosine similarity as logits
+ logit_scale = self.logit_scale.exp()
+ logits_per_text = torch.matmul(text_embeds, image_embeds.t()) * logit_scale
+ logits_per_image = logits_per_text.T
+
+ loss = None
+ if return_loss:
+ loss = clip_loss(logits_per_text)
+
+ if not return_dict:
+ output = (logits_per_image, logits_per_text, text_embeds, image_embeds, text_outputs, vision_outputs)
+ return ((loss,) + output) if loss is not None else output
+
+ return CLIPOutput(
+ loss=loss,
+ logits_per_image=logits_per_image,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ image_embeds=image_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ )
+
+ @classmethod
+ def from_vision_text_pretrained(
+ cls,
+ vision_model_name_or_path: Optional[str] = None,
+ text_model_name_or_path: Optional[str] = None,
+ *model_args,
+ **kwargs,
+ ) -> PreTrainedModel:
+ """
+ Params:
+ vision_model_name_or_path (`str`, *optional*, defaults to `None`):
+ Information necessary to initiate the vision model. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~PreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *PyTorch checkpoint folder* (e.g, `./pt_model`). In this case, `from_pt`
+ should be set to `True` and a configuration object should be provided as `config` argument. This
+ loading path is slower than converting the PyTorch checkpoint in a Flax model using the provided
+ conversion scripts and loading the Flax model afterwards.
+
+ text_model_name_or_path (`str`, *optional*):
+ Information necessary to initiate the text model. Can be either:
+
+ - A string, the *model id* of a pretrained model hosted inside a model repo on huggingface.co.
+ - A path to a *directory* containing model weights saved using
+ [`~PreTrainedModel.save_pretrained`], e.g., `./my_model_directory/`.
+ - A path or url to a *PyTorch checkpoint folder* (e.g, `./pt_model`). In this case, `from_pt`
+ should be set to `True` and a configuration object should be provided as `config` argument. This
+ loading path is slower than converting the PyTorch checkpoint in a Flax model using the provided
+ conversion scripts and loading the Flax model afterwards.
+
+ model_args (remaining positional arguments, *optional*):
+ All remaining positional arguments will be passed to the underlying model's `__init__` method.
+
+ kwargs (remaining dictionary of keyword arguments, *optional*):
+ Can be used to update the configuration object (after it being loaded) and initiate the model (e.g.,
+ `output_attentions=True`).
+
+ - To update the text configuration, use the prefix *text_* for each configuration parameter.
+ - To update the vision configuration, use the prefix *vision_* for each configuration parameter.
+ - To update the parent model configuration, do not use a prefix for each configuration parameter.
+
+ Behaves differently depending on whether a `config` is provided or automatically loaded.
+
+ Example:
+
+ ```python
+ >>> from transformers import VisionTextDualEncoderModel
+
+ >>> # initialize a model from pretrained ViT and BERT models. Note that the projection layers will be randomly initialized.
+ >>> model = VisionTextDualEncoderModel.from_vision_text_pretrained(
+ ... "google/vit-base-patch16-224", "google-bert/bert-base-uncased"
+ ... )
+ >>> # saving model after fine-tuning
+ >>> model.save_pretrained("./vit-bert")
+ >>> # load fine-tuned model
+ >>> model = VisionTextDualEncoderModel.from_pretrained("./vit-bert")
+ ```"""
+ kwargs_vision = {
+ argument[len("vision_") :]: value for argument, value in kwargs.items() if argument.startswith("vision_")
+ }
+
+ kwargs_text = {
+ argument[len("text_") :]: value for argument, value in kwargs.items() if argument.startswith("text_")
+ }
+
+ # remove vision, text kwargs from kwargs
+ for key in kwargs_vision:
+ del kwargs["vision_" + key]
+ for key in kwargs_text:
+ del kwargs["text_" + key]
+
+ # Load and initialize the vision and text model
+ vision_model = kwargs_vision.pop("model", None)
+ if vision_model is None:
+ if vision_model_name_or_path is None:
+ raise ValueError(
+ "If `vision_model` is not defined as an argument, a `vision_model_name_or_path` has to be defined"
+ )
+
+ if "config" not in kwargs_vision:
+ vision_config = AutoConfig.from_pretrained(vision_model_name_or_path)
+
+ if vision_config.model_type == "clip":
+ kwargs_vision["config"] = vision_config.vision_config
+ vision_model = CLIPVisionModel.from_pretrained(vision_model_name_or_path, *model_args, **kwargs_vision)
+ # TODO: Should we use the pre-trained projection as well ?
+ else:
+ kwargs_vision["config"] = vision_config
+ vision_model = AutoModel.from_pretrained(vision_model_name_or_path, *model_args, **kwargs_vision)
+
+ text_model = kwargs_text.pop("model", None)
+ if text_model is None:
+ if text_model_name_or_path is None:
+ raise ValueError(
+ "If `text_model` is not defined as an argument, a `text_model_name_or_path` has to be defined"
+ )
+
+ if "config" not in kwargs_text:
+ text_config = AutoConfig.from_pretrained(text_model_name_or_path)
+ kwargs_text["config"] = text_config
+
+ text_model = AutoModel.from_pretrained(text_model_name_or_path, *model_args, **kwargs_text)
+
+ # instantiate config with corresponding kwargs
+ config = VisionTextDualEncoderConfig.from_vision_text_configs(vision_model.config, text_model.config, **kwargs)
+
+ # init model
+ model = cls(config=config, vision_model=vision_model, text_model=text_model)
+
+ # the projection layers are always newly initialized when loading the model
+ # using pre-trained vision and text model.
+ logger.warning(
+ "The projection layer and logit scale weights `['visual_projection.weight', 'text_projection.weight',"
+ " 'logit_scale']` are newly initialized. You should probably TRAIN this model on a down-stream task to be"
+ " able to use it for predictions and inference."
+ )
+
+ return model
+
+
+__all__ = ["VisionTextDualEncoderModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/processing_vision_text_dual_encoder.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/processing_vision_text_dual_encoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..816d229ceac72c9de7b91e3f4b877ea299780d17
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vision_text_dual_encoder/processing_vision_text_dual_encoder.py
@@ -0,0 +1,155 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Processor class for VisionTextDualEncoder
+"""
+
+import warnings
+from typing import Optional, Union
+
+from ...image_utils import ImageInput
+from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack
+from ...tokenization_utils_base import BatchEncoding, PreTokenizedInput, TextInput
+
+
+class VisionTextDualEncoderProcessorKwargs(ProcessingKwargs, total=False):
+ _defaults = {}
+
+
+class VisionTextDualEncoderProcessor(ProcessorMixin):
+ r"""
+ Constructs a VisionTextDualEncoder processor which wraps an image processor and a tokenizer into a single
+ processor.
+
+ [`VisionTextDualEncoderProcessor`] offers all the functionalities of [`AutoImageProcessor`] and [`AutoTokenizer`].
+ See the [`~VisionTextDualEncoderProcessor.__call__`] and [`~VisionTextDualEncoderProcessor.decode`] for more
+ information.
+
+ Args:
+ image_processor ([`AutoImageProcessor`], *optional*):
+ The image processor is a required input.
+ tokenizer ([`PreTrainedTokenizer`], *optional*):
+ The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+ image_processor_class = "AutoImageProcessor"
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(self, image_processor=None, tokenizer=None, **kwargs):
+ feature_extractor = None
+ if "feature_extractor" in kwargs:
+ warnings.warn(
+ "The `feature_extractor` argument is deprecated and will be removed in v5, use `image_processor`"
+ " instead.",
+ FutureWarning,
+ )
+ feature_extractor = kwargs.pop("feature_extractor")
+
+ image_processor = image_processor if image_processor is not None else feature_extractor
+ if image_processor is None:
+ raise ValueError("You have to specify an image_processor.")
+ if tokenizer is None:
+ raise ValueError("You have to specify a tokenizer.")
+
+ super().__init__(image_processor, tokenizer)
+ self.current_processor = self.image_processor
+
+ def __call__(
+ self,
+ images: Optional[ImageInput] = None,
+ text: Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]] = None,
+ audio=None,
+ videos=None,
+ **kwargs: Unpack[VisionTextDualEncoderProcessorKwargs],
+ ) -> BatchEncoding:
+ """
+ Main method to prepare for the model one or several sequences(s) and image(s). This method forwards the `text`
+ and `kwargs` arguments to VisionTextDualEncoderTokenizer's [`~PreTrainedTokenizer.__call__`] if `text` is not
+ `None` to encode the text. To prepare the image(s), this method forwards the `images` and `kwargs` arguments to
+ AutoImageProcessor's [`~AutoImageProcessor.__call__`] if `images` is not `None`. Please refer to the docstring
+ of the above two methods for more information.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ images (`PIL.Image.Image`, `np.ndarray`, `torch.Tensor`, `list[PIL.Image.Image]`, `list[np.ndarray]`, `list[torch.Tensor]`):
+ The image or batch of images to be prepared. Each image can be a PIL image, NumPy array or PyTorch
+ tensor. Both channels-first and channels-last formats are supported.
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors of a particular framework. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+
+ Returns:
+ [`BatchEncoding`]: A [`BatchEncoding`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`.
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not
+ `None`).
+ - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is not `None`.
+ """
+
+ if text is None and images is None:
+ raise ValueError("You have to specify either text or images. Both cannot be none.")
+
+ output_kwargs = self._merge_kwargs(
+ VisionTextDualEncoderProcessorKwargs,
+ tokenizer_init_kwargs=self.tokenizer.init_kwargs,
+ **kwargs,
+ )
+
+ if text is not None:
+ encoding = self.tokenizer(text, **output_kwargs["text_kwargs"])
+
+ if images is not None:
+ image_features = self.image_processor(images, **output_kwargs["images_kwargs"])
+
+ if text is not None and images is not None:
+ encoding["pixel_values"] = image_features.pixel_values
+ return encoding
+ elif text is not None:
+ return encoding
+ else:
+ return BatchEncoding(
+ data=dict(**image_features),
+ tensor_type=output_kwargs["common_kwargs"].get("return_tensors"),
+ )
+
+ @property
+ def feature_extractor_class(self):
+ warnings.warn(
+ "`feature_extractor_class` is deprecated and will be removed in v5. Use `image_processor_class` instead.",
+ FutureWarning,
+ )
+ return self.image_processor_class
+
+ @property
+ def feature_extractor(self):
+ warnings.warn(
+ "`feature_extractor` is deprecated and will be removed in v5. Use `image_processor` instead.",
+ FutureWarning,
+ )
+ return self.image_processor
+
+
+__all__ = ["VisionTextDualEncoderProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..723dc4904f5537488df71acb3163f5830ea66479
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_visual_bert import *
+ from .modeling_visual_bert import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/configuration_visual_bert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/configuration_visual_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..a866227d3470b9b63f5ca7f2afad458b90cbd11d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/configuration_visual_bert.py
@@ -0,0 +1,135 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VisualBERT model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class VisualBertConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VisualBertModel`]. It is used to instantiate an
+ VisualBERT model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the VisualBERT
+ [uclanlp/visualbert-vqa-coco-pre](https://huggingface.co/uclanlp/visualbert-vqa-coco-pre) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the VisualBERT model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`VisualBertModel`]. Vocabulary size of the model. Defines the
+ different tokens that can be represented by the `inputs_ids` passed to the forward method of
+ [`VisualBertModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ visual_embedding_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of the visual embeddings to be passed to the model.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the `token_type_ids` passed when calling [`VisualBertModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ bypass_transformer (`bool`, *optional*, defaults to `False`):
+ Whether or not the model should bypass the transformer for the visual embeddings. If set to `True`, the
+ model directly concatenates the visual embeddings from [`VisualBertEmbeddings`] with text output from
+ transformers, and then pass it to a self-attention layer.
+ special_visual_initialize (`bool`, *optional*, defaults to `True`):
+ Whether or not the visual token type and position type embedding weights should be initialized the same as
+ the textual token type and positive type embeddings. When set to `True`, the weights of the textual token
+ type and position type embeddings are copied to the respective visual embedding layers.
+
+
+ Example:
+
+ ```python
+ >>> from transformers import VisualBertConfig, VisualBertModel
+
+ >>> # Initializing a VisualBERT visualbert-vqa-coco-pre style configuration
+ >>> configuration = VisualBertConfig.from_pretrained("uclanlp/visualbert-vqa-coco-pre")
+
+ >>> # Initializing a model (with random weights) from the visualbert-vqa-coco-pre style configuration
+ >>> model = VisualBertModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "visual_bert"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ hidden_size=768,
+ visual_embedding_dim=512,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=512,
+ type_vocab_size=2,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ bypass_transformer=False,
+ special_visual_initialize=True,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.visual_embedding_dim = visual_embedding_dim
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.type_vocab_size = type_vocab_size
+ self.layer_norm_eps = layer_norm_eps
+ self.bypass_transformer = bypass_transformer
+ self.special_visual_initialize = special_visual_initialize
+
+
+__all__ = ["VisualBertConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/modeling_visual_bert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/modeling_visual_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..b8b50d3024a01e3c4d8a29af7141191ef781d345
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/visual_bert/modeling_visual_bert.py
@@ -0,0 +1,1573 @@
+# coding=utf-8
+# Copyright 2021 The UCLA NLP Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch VisualBERT model."""
+
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import CrossEntropyLoss, KLDivLoss, LogSoftmax
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPooling,
+ MultipleChoiceModelOutput,
+ SequenceClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import ModelOutput, auto_docstring, logging
+from .configuration_visual_bert import VisualBertConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class VisualBertEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings and visual embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+
+ # For Visual Features
+ # Token type and position embedding for image features
+ self.visual_token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+ self.visual_position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+
+ if config.special_visual_initialize:
+ self.visual_token_type_embeddings.weight.data = nn.Parameter(
+ self.token_type_embeddings.weight.data.clone(), requires_grad=True
+ )
+ self.visual_position_embeddings.weight.data = nn.Parameter(
+ self.position_embeddings.weight.data.clone(), requires_grad=True
+ )
+
+ self.visual_projection = nn.Linear(config.visual_embedding_dim, config.hidden_size)
+
+ def forward(
+ self,
+ input_ids=None,
+ token_type_ids=None,
+ position_ids=None,
+ inputs_embeds=None,
+ visual_embeds=None,
+ visual_token_type_ids=None,
+ image_text_alignment=None,
+ ):
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+
+ if token_type_ids is None:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+
+ # Absolute Position Embeddings
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+
+ if visual_embeds is not None:
+ if visual_token_type_ids is None:
+ visual_token_type_ids = torch.ones(
+ visual_embeds.size()[:-1], dtype=torch.long, device=self.position_ids.device
+ )
+
+ visual_embeds = self.visual_projection(visual_embeds)
+ visual_token_type_embeddings = self.visual_token_type_embeddings(visual_token_type_ids)
+
+ if image_text_alignment is not None:
+ # image_text_alignment = Batch x image_length x alignment_number.
+ # Each element denotes the position of the word corresponding to the image feature. -1 is the padding value.
+
+ dtype = token_type_embeddings.dtype
+ image_text_alignment_mask = (image_text_alignment != -1).long()
+ # Get rid of the -1.
+ image_text_alignment = image_text_alignment_mask * image_text_alignment
+
+ # Batch x image_length x alignment length x dim
+ visual_position_embeddings = self.position_embeddings(image_text_alignment)
+ visual_position_embeddings *= image_text_alignment_mask.to(dtype=dtype).unsqueeze(-1)
+ visual_position_embeddings = visual_position_embeddings.sum(2)
+
+ # We want to average along the alignment_number dimension.
+ image_text_alignment_mask = image_text_alignment_mask.to(dtype=dtype).sum(2)
+
+ if (image_text_alignment_mask == 0).sum() != 0:
+ image_text_alignment_mask[image_text_alignment_mask == 0] = 1 # Avoid divide by zero error
+ logger.warning(
+ "Found 0 values in `image_text_alignment_mask`. Setting them to 1 to avoid divide-by-zero"
+ " error."
+ )
+ visual_position_embeddings = visual_position_embeddings / image_text_alignment_mask.unsqueeze(-1)
+
+ visual_position_ids = torch.zeros(
+ *visual_embeds.size()[:-1], dtype=torch.long, device=visual_embeds.device
+ )
+
+ # When fine-tuning the detector , the image_text_alignment is sometimes padded too long.
+ if visual_position_embeddings.size(1) != visual_embeds.size(1):
+ if visual_position_embeddings.size(1) < visual_embeds.size(1):
+ raise ValueError(
+ f"Visual position embeddings length: {visual_position_embeddings.size(1)} "
+ f"should be the same as `visual_embeds` length: {visual_embeds.size(1)}"
+ )
+ visual_position_embeddings = visual_position_embeddings[:, : visual_embeds.size(1), :]
+
+ visual_position_embeddings = visual_position_embeddings + self.visual_position_embeddings(
+ visual_position_ids
+ )
+ else:
+ visual_position_ids = torch.zeros(
+ *visual_embeds.size()[:-1], dtype=torch.long, device=visual_embeds.device
+ )
+ visual_position_embeddings = self.visual_position_embeddings(visual_position_ids)
+
+ visual_embeddings = visual_embeds + visual_position_embeddings + visual_token_type_embeddings
+
+ embeddings = torch.cat((embeddings, visual_embeddings), dim=1)
+
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class VisualBertSelfAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ ):
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ key_layer = (
+ self.key(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in VisualBertSelfAttentionModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(*new_context_layer_shape)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertSelfOutput with Bert->VisualBert
+class VisualBertSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class VisualBertAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.self = VisualBertSelfAttention(config)
+ self.output = VisualBertSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ ):
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ output_attentions,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertIntermediate with Bert->VisualBert
+class VisualBertIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertOutput with Bert->VisualBert
+class VisualBertOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class VisualBertLayer(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = VisualBertAttention(config)
+ self.intermediate = VisualBertIntermediate(config)
+ self.output = VisualBertOutput(config)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ ):
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ output_attentions=output_attentions,
+ )
+ attention_output = self_attention_outputs[0]
+
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+class VisualBertEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([VisualBertLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(hidden_states, attention_mask, layer_head_mask, output_attentions)
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ all_hidden_states,
+ all_self_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_self_attentions
+ )
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPooler with Bert->VisualBert
+class VisualBertPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPredictionHeadTransform with Bert->VisualBert
+class VisualBertPredictionHeadTransform(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ if isinstance(config.hidden_act, str):
+ self.transform_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.transform_act_fn = config.hidden_act
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.transform_act_fn(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertLMPredictionHead with Bert->VisualBert
+class VisualBertLMPredictionHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.transform = VisualBertPredictionHeadTransform(config)
+
+ # The output weights are the same as the input embeddings, but there is
+ # an output-only bias for each token.
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+
+ # Need a link between the two variables so that the bias is correctly resized with `resize_token_embeddings`
+ self.decoder.bias = self.bias
+
+ def _tie_weights(self):
+ self.decoder.bias = self.bias
+
+ def forward(self, hidden_states):
+ hidden_states = self.transform(hidden_states)
+ hidden_states = self.decoder(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPreTrainingHeads with Bert->VisualBert
+class VisualBertPreTrainingHeads(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.predictions = VisualBertLMPredictionHead(config)
+ self.seq_relationship = nn.Linear(config.hidden_size, 2)
+
+ def forward(self, sequence_output, pooled_output):
+ prediction_scores = self.predictions(sequence_output)
+ seq_relationship_score = self.seq_relationship(pooled_output)
+ return prediction_scores, seq_relationship_score
+
+
+@auto_docstring
+class VisualBertPreTrainedModel(PreTrainedModel):
+ config: VisualBertConfig
+ base_model_prefix = "visual_bert"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Embedding)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if hasattr(module, "bias") and module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, VisualBertLMPredictionHead):
+ module.bias.data.zero_()
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`VisualBertForPreTraining`].
+ """
+)
+class VisualBertForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when `labels` is provided, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the masked language modeling loss and the sentence-image prediction
+ (classification) loss.
+ prediction_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+ seq_relationship_logits (`torch.FloatTensor` of shape `(batch_size, 2)`):
+ Prediction scores of the sentence-image prediction (classification) head (scores of True/False continuation
+ before SoftMax).
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ prediction_logits: Optional[torch.FloatTensor] = None
+ seq_relationship_logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@auto_docstring(
+ custom_intro="""
+ The model can behave as an encoder (with only self-attention) following the architecture described in [Attention is
+ all you need](https://huggingface.co/papers/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit,
+ Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin.
+ """
+)
+class VisualBertModel(VisualBertPreTrainedModel):
+ def __init__(self, config, add_pooling_layer=True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = VisualBertEmbeddings(config)
+ self.encoder = VisualBertEncoder(config)
+
+ self.pooler = VisualBertPooler(config) if add_pooling_layer else None
+
+ self.bypass_transformer = config.bypass_transformer
+
+ if self.bypass_transformer:
+ self.additional_layer = VisualBertLayer(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ visual_embeds: Optional[torch.FloatTensor] = None,
+ visual_attention_mask: Optional[torch.LongTensor] = None,
+ visual_token_type_ids: Optional[torch.LongTensor] = None,
+ image_text_alignment: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutputWithPooling]:
+ r"""
+ visual_embeds (`torch.FloatTensor` of shape `(batch_size, visual_seq_length, visual_embedding_dim)`, *optional*):
+ The embedded representation of the visual inputs, generally derived using using an object detector.
+ visual_attention_mask (`torch.FloatTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Mask to avoid performing attention on visual embeddings. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ visual_token_type_ids (`torch.LongTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Segment token indices to indicate different portions of the visual embeds.
+
+ [What are token type IDs?](../glossary#token-type-ids) The authors of VisualBERT set the
+ *visual_token_type_ids* to *1* for all tokens.
+ image_text_alignment (`torch.LongTensor` of shape `(batch_size, visual_seq_length, alignment_number)`, *optional*):
+ Image-Text alignment uses to decide the position IDs of the visual embeddings.
+
+ Example:
+
+ ```python
+ # Assumption: *get_visual_embeddings(image)* gets the visual embeddings of the image.
+ from transformers import AutoTokenizer, VisualBertModel
+ import torch
+
+ tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ model = VisualBertModel.from_pretrained("uclanlp/visualbert-vqa-coco-pre")
+
+ inputs = tokenizer("The capital of France is Paris.", return_tensors="pt")
+ visual_embeds = get_visual_embeddings(image).unsqueeze(0)
+ visual_token_type_ids = torch.ones(visual_embeds.shape[:-1], dtype=torch.long)
+ visual_attention_mask = torch.ones(visual_embeds.shape[:-1], dtype=torch.float)
+
+ inputs.update(
+ {
+ "visual_embeds": visual_embeds,
+ "visual_token_type_ids": visual_token_type_ids,
+ "visual_attention_mask": visual_attention_mask,
+ }
+ )
+
+ outputs = model(**inputs)
+
+ last_hidden_states = outputs.last_hidden_state
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if visual_embeds is not None:
+ visual_input_shape = visual_embeds.size()[:-1]
+
+ if attention_mask is None:
+ attention_mask = torch.ones(input_shape, device=device)
+
+ if visual_embeds is not None and visual_attention_mask is None:
+ visual_attention_mask = torch.ones(visual_input_shape, device=device)
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ if visual_embeds is not None:
+ combined_attention_mask = torch.cat((attention_mask, visual_attention_mask), dim=-1)
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(
+ combined_attention_mask, (batch_size, input_shape + visual_input_shape)
+ )
+
+ else:
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(
+ attention_mask, (batch_size, input_shape)
+ )
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ visual_embeds=visual_embeds,
+ visual_token_type_ids=visual_token_type_ids,
+ image_text_alignment=image_text_alignment,
+ )
+
+ if self.bypass_transformer and visual_embeds is not None:
+ text_length = input_ids.size(1)
+ text_embedding_output = embedding_output[:, :text_length, :]
+ visual_embedding_output = embedding_output[:, text_length:, :]
+
+ text_extended_attention_mask = extended_attention_mask[:, :, text_length, :text_length]
+
+ encoded_outputs = self.encoder(
+ text_embedding_output,
+ attention_mask=text_extended_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoded_outputs[0]
+ concatenated_input = torch.cat((sequence_output, visual_embedding_output), dim=1)
+ sequence_output = self.additional_layer(concatenated_input, extended_attention_mask)
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ else:
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ VisualBert Model with two heads on top as done during the pretraining: a `masked language modeling` head and a
+ `sentence-image prediction (classification)` head.
+ """
+)
+class VisualBertForPreTraining(VisualBertPreTrainedModel):
+ _tied_weights_keys = ["cls.predictions.decoder.weight", "cls.predictions.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.visual_bert = VisualBertModel(config)
+ self.cls = VisualBertPreTrainingHeads(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.cls.predictions.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.cls.predictions.decoder = new_embeddings
+ self.cls.predictions.bias = new_embeddings.bias
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ visual_embeds: Optional[torch.FloatTensor] = None,
+ visual_attention_mask: Optional[torch.LongTensor] = None,
+ visual_token_type_ids: Optional[torch.LongTensor] = None,
+ image_text_alignment: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.LongTensor] = None,
+ sentence_image_labels: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.Tensor], VisualBertForPreTrainingOutput]:
+ r"""
+ visual_embeds (`torch.FloatTensor` of shape `(batch_size, visual_seq_length, visual_embedding_dim)`, *optional*):
+ The embedded representation of the visual inputs, generally derived using using an object detector.
+ visual_attention_mask (`torch.FloatTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Mask to avoid performing attention on visual embeddings. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ visual_token_type_ids (`torch.LongTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Segment token indices to indicate different portions of the visual embeds.
+
+ [What are token type IDs?](../glossary#token-type-ids) The authors of VisualBERT set the
+ *visual_token_type_ids* to *1* for all tokens.
+ image_text_alignment (`torch.LongTensor` of shape `(batch_size, visual_seq_length, alignment_number)`, *optional*):
+ Image-Text alignment uses to decide the position IDs of the visual embeddings.
+ labels (`torch.LongTensor` of shape `(batch_size, total_sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ sentence_image_labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sentence-image prediction (classification) loss. Input should be a sequence pair
+ (see `input_ids` docstring) Indices should be in `[0, 1]`:
+
+ - 0 indicates sequence B is a matching pair of sequence A for the given image,
+ - 1 indicates sequence B is a random sequence w.r.t A for the given image.
+
+ Example:
+
+ ```python
+ # Assumption: *get_visual_embeddings(image)* gets the visual embeddings of the image in the batch.
+ from transformers import AutoTokenizer, VisualBertForPreTraining
+
+ tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ model = VisualBertForPreTraining.from_pretrained("uclanlp/visualbert-vqa-coco-pre")
+
+ inputs = tokenizer("The capital of France is [MASK].", return_tensors="pt")
+ visual_embeds = get_visual_embeddings(image).unsqueeze(0)
+ visual_token_type_ids = torch.ones(visual_embeds.shape[:-1], dtype=torch.long)
+ visual_attention_mask = torch.ones(visual_embeds.shape[:-1], dtype=torch.float)
+
+ inputs.update(
+ {
+ "visual_embeds": visual_embeds,
+ "visual_token_type_ids": visual_token_type_ids,
+ "visual_attention_mask": visual_attention_mask,
+ }
+ )
+ max_length = inputs["input_ids"].shape[-1] + visual_embeds.shape[-2]
+ labels = tokenizer(
+ "The capital of France is Paris.", return_tensors="pt", padding="max_length", max_length=max_length
+ )["input_ids"]
+ sentence_image_labels = torch.tensor(1).unsqueeze(0) # Batch_size
+
+
+ outputs = model(**inputs, labels=labels, sentence_image_labels=sentence_image_labels)
+ loss = outputs.loss
+ prediction_logits = outputs.prediction_logits
+ seq_relationship_logits = outputs.seq_relationship_logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ total_size = attention_mask.size(-1) + visual_attention_mask.size(-1)
+ if labels.size(-1) != total_size:
+ raise ValueError(
+ "The labels provided should have same sequence length as total attention mask. "
+ f"Found labels with sequence length {labels.size(-1)}, expected {total_size}."
+ )
+
+ outputs = self.visual_bert(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ visual_embeds=visual_embeds,
+ visual_attention_mask=visual_attention_mask,
+ visual_token_type_ids=visual_token_type_ids,
+ image_text_alignment=image_text_alignment,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output, pooled_output = outputs[:2]
+ prediction_scores, seq_relationship_score = self.cls(sequence_output, pooled_output)
+
+ total_loss = None
+ if labels is not None and sentence_image_labels is not None:
+ loss_fct = CrossEntropyLoss()
+ masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+ sentence_image_loss = loss_fct(seq_relationship_score.view(-1, 2), sentence_image_labels.view(-1))
+ total_loss = masked_lm_loss + sentence_image_loss
+
+ elif labels is not None:
+ loss_fct = CrossEntropyLoss()
+ total_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (prediction_scores, seq_relationship_score) + outputs[2:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return VisualBertForPreTrainingOutput(
+ loss=total_loss,
+ prediction_logits=prediction_scores,
+ seq_relationship_logits=seq_relationship_score,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class VisualBertForMultipleChoice(VisualBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.visual_bert = VisualBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.cls = nn.Linear(config.hidden_size, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ visual_embeds: Optional[torch.FloatTensor] = None,
+ visual_attention_mask: Optional[torch.LongTensor] = None,
+ visual_token_type_ids: Optional[torch.LongTensor] = None,
+ image_text_alignment: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.Tensor], MultipleChoiceModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ visual_embeds (`torch.FloatTensor` of shape `(batch_size, visual_seq_length, visual_embedding_dim)`, *optional*):
+ The embedded representation of the visual inputs, generally derived using using an object detector.
+ visual_attention_mask (`torch.FloatTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Mask to avoid performing attention on visual embeddings. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ visual_token_type_ids (`torch.LongTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Segment token indices to indicate different portions of the visual embeds.
+
+ [What are token type IDs?](../glossary#token-type-ids) The authors of VisualBERT set the
+ *visual_token_type_ids* to *1* for all tokens.
+ image_text_alignment (`torch.LongTensor` of shape `(batch_size, visual_seq_length, alignment_number)`, *optional*):
+ Image-Text alignment uses to decide the position IDs of the visual embeddings.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See
+ `input_ids` above)
+
+ Example:
+
+ ```python
+ # Assumption: *get_visual_embeddings(image)* gets the visual embeddings of the image in the batch.
+ from transformers import AutoTokenizer, VisualBertForMultipleChoice
+ import torch
+
+ tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ model = VisualBertForMultipleChoice.from_pretrained("uclanlp/visualbert-vcr")
+
+ prompt = "In Italy, pizza served in formal settings, such as at a restaurant, is presented unsliced."
+ choice0 = "It is eaten with a fork and a knife."
+ choice1 = "It is eaten while held in the hand."
+
+ visual_embeds = get_visual_embeddings(image)
+ # (batch_size, num_choices, visual_seq_length, visual_embedding_dim)
+ visual_embeds = visual_embeds.expand(1, 2, *visual_embeds.shape)
+ visual_token_type_ids = torch.ones(visual_embeds.shape[:-1], dtype=torch.long)
+ visual_attention_mask = torch.ones(visual_embeds.shape[:-1], dtype=torch.float)
+
+ labels = torch.tensor(0).unsqueeze(0) # choice0 is correct (according to Wikipedia ;)), batch size 1
+
+ encoding = tokenizer([[prompt, prompt], [choice0, choice1]], return_tensors="pt", padding=True)
+ # batch size is 1
+ inputs_dict = {k: v.unsqueeze(0) for k, v in encoding.items()}
+ inputs_dict.update(
+ {
+ "visual_embeds": visual_embeds,
+ "visual_attention_mask": visual_attention_mask,
+ "visual_token_type_ids": visual_token_type_ids,
+ "labels": labels,
+ }
+ )
+ outputs = model(**inputs_dict)
+
+ loss = outputs.loss
+ logits = outputs.logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None
+ inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ visual_embeds = (
+ visual_embeds.view(-1, visual_embeds.size(-2), visual_embeds.size(-1))
+ if visual_embeds is not None
+ else None
+ )
+ visual_attention_mask = (
+ visual_attention_mask.view(-1, visual_attention_mask.size(-1))
+ if visual_attention_mask is not None
+ else None
+ )
+ visual_token_type_ids = (
+ visual_token_type_ids.view(-1, visual_token_type_ids.size(-1))
+ if visual_token_type_ids is not None
+ else None
+ )
+
+ outputs = self.visual_bert(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ visual_embeds=visual_embeds,
+ visual_attention_mask=visual_attention_mask,
+ visual_token_type_ids=visual_token_type_ids,
+ image_text_alignment=image_text_alignment,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ _, pooled_output = outputs[0], outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.cls(pooled_output)
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels)
+
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return MultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ VisualBert Model with a classification/regression head on top (a dropout and a linear layer on top of the pooled
+ output) for VQA.
+ """
+)
+class VisualBertForQuestionAnswering(VisualBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.visual_bert = VisualBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.cls = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ visual_embeds: Optional[torch.FloatTensor] = None,
+ visual_attention_mask: Optional[torch.LongTensor] = None,
+ visual_token_type_ids: Optional[torch.LongTensor] = None,
+ image_text_alignment: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.Tensor], SequenceClassifierOutput]:
+ r"""
+ visual_embeds (`torch.FloatTensor` of shape `(batch_size, visual_seq_length, visual_embedding_dim)`, *optional*):
+ The embedded representation of the visual inputs, generally derived using using an object detector.
+ visual_attention_mask (`torch.FloatTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Mask to avoid performing attention on visual embeddings. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ visual_token_type_ids (`torch.LongTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Segment token indices to indicate different portions of the visual embeds.
+
+ [What are token type IDs?](../glossary#token-type-ids) The authors of VisualBERT set the
+ *visual_token_type_ids* to *1* for all tokens.
+ image_text_alignment (`torch.LongTensor` of shape `(batch_size, visual_seq_length, alignment_number)`, *optional*):
+ Image-Text alignment uses to decide the position IDs of the visual embeddings.
+ labels (`torch.LongTensor` of shape `(batch_size, total_sequence_length)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. A KLDivLoss is computed between the labels and the returned logits.
+
+ Example:
+
+ ```python
+ # Assumption: *get_visual_embeddings(image)* gets the visual embeddings of the image in the batch.
+ from transformers import AutoTokenizer, VisualBertForQuestionAnswering
+ import torch
+
+ tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ model = VisualBertForQuestionAnswering.from_pretrained("uclanlp/visualbert-vqa")
+
+ text = "Who is eating the apple?"
+ inputs = tokenizer(text, return_tensors="pt")
+ visual_embeds = get_visual_embeddings(image).unsqueeze(0)
+ visual_token_type_ids = torch.ones(visual_embeds.shape[:-1], dtype=torch.long)
+ visual_attention_mask = torch.ones(visual_embeds.shape[:-1], dtype=torch.float)
+
+ inputs.update(
+ {
+ "visual_embeds": visual_embeds,
+ "visual_token_type_ids": visual_token_type_ids,
+ "visual_attention_mask": visual_attention_mask,
+ }
+ )
+
+ labels = torch.tensor([[0.0, 1.0]]).unsqueeze(0) # Batch size 1, Num labels 2
+
+ outputs = model(**inputs, labels=labels)
+ loss = outputs.loss
+ scores = outputs.logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # Get the index of the last text token
+ index_to_gather = attention_mask.sum(1) - 2 # as in original code
+
+ outputs = self.visual_bert(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ visual_embeds=visual_embeds,
+ visual_attention_mask=visual_attention_mask,
+ visual_token_type_ids=visual_token_type_ids,
+ image_text_alignment=image_text_alignment,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ # TO-CHECK: From the original code
+ index_to_gather = (
+ index_to_gather.unsqueeze(-1).unsqueeze(-1).expand(index_to_gather.size(0), 1, sequence_output.size(-1))
+ )
+ pooled_output = torch.gather(sequence_output, 1, index_to_gather)
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.cls(pooled_output)
+ reshaped_logits = logits.view(-1, self.num_labels)
+
+ loss = None
+ if labels is not None:
+ loss_fct = nn.KLDivLoss(reduction="batchmean")
+ log_softmax = nn.LogSoftmax(dim=-1)
+ reshaped_logits = log_softmax(reshaped_logits)
+ loss = loss_fct(reshaped_logits, labels.contiguous())
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ VisualBert Model with a sequence classification head on top (a dropout and a linear layer on top of the pooled
+ output) for Visual Reasoning e.g. for NLVR task.
+ """
+)
+class VisualBertForVisualReasoning(VisualBertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.visual_bert = VisualBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.cls = nn.Linear(config.hidden_size, config.num_labels) # 2
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ visual_embeds: Optional[torch.FloatTensor] = None,
+ visual_attention_mask: Optional[torch.LongTensor] = None,
+ visual_token_type_ids: Optional[torch.LongTensor] = None,
+ image_text_alignment: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.Tensor], SequenceClassifierOutput]:
+ r"""
+ visual_embeds (`torch.FloatTensor` of shape `(batch_size, visual_seq_length, visual_embedding_dim)`, *optional*):
+ The embedded representation of the visual inputs, generally derived using using an object detector.
+ visual_attention_mask (`torch.FloatTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Mask to avoid performing attention on visual embeddings. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ visual_token_type_ids (`torch.LongTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Segment token indices to indicate different portions of the visual embeds.
+
+ [What are token type IDs?](../glossary#token-type-ids) The authors of VisualBERT set the
+ *visual_token_type_ids* to *1* for all tokens.
+ image_text_alignment (`torch.LongTensor` of shape `(batch_size, visual_seq_length, alignment_number)`, *optional*):
+ Image-Text alignment uses to decide the position IDs of the visual embeddings.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. A classification loss is computed (Cross-Entropy) against these labels.
+
+ Example:
+
+ ```python
+ # Assumption: *get_visual_embeddings(image)* gets the visual embeddings of the image in the batch.
+ from transformers import AutoTokenizer, VisualBertForVisualReasoning
+ import torch
+
+ tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ model = VisualBertForVisualReasoning.from_pretrained("uclanlp/visualbert-nlvr2")
+
+ text = "Who is eating the apple?"
+ inputs = tokenizer(text, return_tensors="pt")
+ visual_embeds = get_visual_embeddings(image).unsqueeze(0)
+ visual_token_type_ids = torch.ones(visual_embeds.shape[:-1], dtype=torch.long)
+ visual_attention_mask = torch.ones(visual_embeds.shape[:-1], dtype=torch.float)
+
+ inputs.update(
+ {
+ "visual_embeds": visual_embeds,
+ "visual_token_type_ids": visual_token_type_ids,
+ "visual_attention_mask": visual_attention_mask,
+ }
+ )
+
+ labels = torch.tensor(1).unsqueeze(0) # Batch size 1, Num choices 2
+
+ outputs = model(**inputs, labels=labels)
+ loss = outputs.loss
+ scores = outputs.logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.visual_bert(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ visual_embeds=visual_embeds,
+ visual_attention_mask=visual_attention_mask,
+ visual_token_type_ids=visual_token_type_ids,
+ image_text_alignment=image_text_alignment,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ # sequence_output = outputs[0]
+ pooled_output = outputs[1]
+ pooled_output = self.dropout(pooled_output)
+ logits = self.cls(pooled_output)
+ reshaped_logits = logits.contiguous()
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class VisualBertRegionToPhraseAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0:
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+ self.num_attention_heads = 1 # config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+
+ def forward(self, query, key, attention_mask):
+ batch_size, seq_length, _ = query.shape
+ attention_mask = attention_mask.to(query.dtype)
+ attention_mask = attention_mask.unsqueeze(1).unsqueeze(2)
+ attention_mask = (1.0 - attention_mask) * torch.finfo(query.dtype).min
+
+ query_layer = (
+ self.query(query).view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ )
+ key_layer = (
+ self.key(key).view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ )
+
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+
+ attention_scores = attention_scores + attention_mask
+
+ attention_scores = attention_scores.squeeze(1)
+ return attention_scores
+
+
+@auto_docstring(
+ custom_intro="""
+ VisualBert Model with a Masked Language Modeling head and an attention layer on top for Region-to-Phrase Alignment
+ e.g. for Flickr30 Entities task.
+ """
+)
+class VisualBertForRegionToPhraseAlignment(VisualBertPreTrainedModel):
+ _tied_weights_keys = ["cls.predictions.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.visual_bert = VisualBertModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.cls = VisualBertPreTrainingHeads(config)
+ self.attention = VisualBertRegionToPhraseAttention(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ visual_embeds: Optional[torch.FloatTensor] = None,
+ visual_attention_mask: Optional[torch.LongTensor] = None,
+ visual_token_type_ids: Optional[torch.LongTensor] = None,
+ image_text_alignment: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ region_to_phrase_position: Optional[torch.LongTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.Tensor], SequenceClassifierOutput]:
+ r"""
+ visual_embeds (`torch.FloatTensor` of shape `(batch_size, visual_seq_length, visual_embedding_dim)`, *optional*):
+ The embedded representation of the visual inputs, generally derived using using an object detector.
+ visual_attention_mask (`torch.FloatTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Mask to avoid performing attention on visual embeddings. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ visual_token_type_ids (`torch.LongTensor` of shape `(batch_size, visual_seq_length)`, *optional*):
+ Segment token indices to indicate different portions of the visual embeds.
+
+ [What are token type IDs?](../glossary#token-type-ids) The authors of VisualBERT set the
+ *visual_token_type_ids* to *1* for all tokens.
+ image_text_alignment (`torch.LongTensor` of shape `(batch_size, visual_seq_length, alignment_number)`, *optional*):
+ Image-Text alignment uses to decide the position IDs of the visual embeddings.
+ region_to_phrase_position (`torch.LongTensor` of shape `(batch_size, total_sequence_length)`, *optional*):
+ The positions depicting the position of the image embedding corresponding to the textual tokens.
+ labels (`torch.LongTensor` of shape `(batch_size, total_sequence_length, visual_sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. KLDivLoss is computed against these labels and the
+ outputs from the attention layer.
+
+ Example:
+
+ ```python
+ # Assumption: *get_visual_embeddings(image)* gets the visual embeddings of the image in the batch.
+ from transformers import AutoTokenizer, VisualBertForRegionToPhraseAlignment
+ import torch
+
+ tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+ model = VisualBertForRegionToPhraseAlignment.from_pretrained("uclanlp/visualbert-vqa-coco-pre")
+
+ text = "Who is eating the apple?"
+ inputs = tokenizer(text, return_tensors="pt")
+ visual_embeds = get_visual_embeddings(image).unsqueeze(0)
+ visual_token_type_ids = torch.ones(visual_embeds.shape[:-1], dtype=torch.long)
+ visual_attention_mask = torch.ones(visual_embeds.shape[:-1], dtype=torch.float)
+ region_to_phrase_position = torch.ones((1, inputs["input_ids"].shape[-1] + visual_embeds.shape[-2]))
+
+ inputs.update(
+ {
+ "region_to_phrase_position": region_to_phrase_position,
+ "visual_embeds": visual_embeds,
+ "visual_token_type_ids": visual_token_type_ids,
+ "visual_attention_mask": visual_attention_mask,
+ }
+ )
+
+ labels = torch.ones(
+ (1, inputs["input_ids"].shape[-1] + visual_embeds.shape[-2], visual_embeds.shape[-2])
+ ) # Batch size 1
+
+ outputs = model(**inputs, labels=labels)
+ loss = outputs.loss
+ scores = outputs.logits
+ ```"""
+ if region_to_phrase_position is None:
+ raise ValueError("`region_to_phrase_position` should not be None when using Flickr Model.")
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.visual_bert(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ visual_embeds=visual_embeds,
+ visual_attention_mask=visual_attention_mask,
+ visual_token_type_ids=visual_token_type_ids,
+ image_text_alignment=image_text_alignment,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ region_to_phrase_position_mask = (region_to_phrase_position != -1).long()
+
+ # Make the -1 become 0
+ region_to_phrase_position = region_to_phrase_position * region_to_phrase_position_mask
+
+ # Selected_positions = batch x selected position x dim
+ expanded_region_to_phrase_positions = region_to_phrase_position.unsqueeze(2).expand(
+ region_to_phrase_position.size(0), region_to_phrase_position.size(1), sequence_output.size(2)
+ )
+ selected_positions = sequence_output.gather(1, expanded_region_to_phrase_positions)
+
+ # Visual Features = batch x visual_feature_length x dim
+ # This will need separate image and visual masks.
+ visual_features = sequence_output[:, attention_mask.size(1) :]
+
+ if visual_features.size(1) != visual_attention_mask.size(1):
+ raise ValueError(
+ f"Visual features length :{visual_features.size(1)} should be the same"
+ f" as visual attention mask length: {visual_attention_mask.size(1)}."
+ )
+
+ logits = self.attention(selected_positions, visual_features, visual_attention_mask)
+
+ loss = None
+
+ if labels is not None:
+ # scores = batch x selected position x visual_feature
+ # scores = selected_positions.bmm(visual_features.transpose(1,2))
+ # label = batch x selected_postion x needed position
+ loss_fct = KLDivLoss(reduction="batchmean")
+ log_softmax = LogSoftmax(dim=-1)
+ scores = log_softmax(logits)
+ labels = labels.contiguous()
+ loss = loss_fct(scores, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "VisualBertForMultipleChoice",
+ "VisualBertForPreTraining",
+ "VisualBertForQuestionAnswering",
+ "VisualBertForRegionToPhraseAlignment",
+ "VisualBertForVisualReasoning",
+ "VisualBertLayer",
+ "VisualBertModel",
+ "VisualBertPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..4d6a7a23fa63f4c95102584b90d7f775b746ce49
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/__init__.py
@@ -0,0 +1,32 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vit import *
+ from .feature_extraction_vit import *
+ from .image_processing_vit import *
+ from .image_processing_vit_fast import *
+ from .modeling_flax_vit import *
+ from .modeling_tf_vit import *
+ from .modeling_vit import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/configuration_vit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/configuration_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..ead272d0086d00149706b6880d3f0b1b530dd58f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/configuration_vit.py
@@ -0,0 +1,151 @@
+# coding=utf-8
+# Copyright 2021 Google AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""ViT model configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from packaging import version
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class ViTConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`ViTModel`]. It is used to instantiate an ViT
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the ViT
+ [google/vit-base-patch16-224](https://huggingface.co/google/vit-base-patch16-224) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ encoder_stride (`int`, *optional*, defaults to 16):
+ Factor to increase the spatial resolution by in the decoder head for masked image modeling.
+ pooler_output_size (`int`, *optional*):
+ Dimensionality of the pooler layer. If None, defaults to `hidden_size`.
+ pooler_act (`str`, *optional*, defaults to `"tanh"`):
+ The activation function to be used by the pooler. Keys of ACT2FN are supported for Flax and
+ Pytorch, and elements of https://www.tensorflow.org/api_docs/python/tf/keras/activations are
+ supported for Tensorflow.
+
+ Example:
+
+ ```python
+ >>> from transformers import ViTConfig, ViTModel
+
+ >>> # Initializing a ViT vit-base-patch16-224 style configuration
+ >>> configuration = ViTConfig()
+
+ >>> # Initializing a model (with random weights) from the vit-base-patch16-224 style configuration
+ >>> model = ViTModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vit"
+
+ def __init__(
+ self,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ image_size=224,
+ patch_size=16,
+ num_channels=3,
+ qkv_bias=True,
+ encoder_stride=16,
+ pooler_output_size=None,
+ pooler_act="tanh",
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+ self.encoder_stride = encoder_stride
+ self.pooler_output_size = pooler_output_size if pooler_output_size else hidden_size
+ self.pooler_act = pooler_act
+
+
+class ViTOnnxConfig(OnnxConfig):
+ torch_onnx_minimum_version = version.parse("1.11")
+
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ return OrderedDict(
+ [
+ ("pixel_values", {0: "batch", 1: "num_channels", 2: "height", 3: "width"}),
+ ]
+ )
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 1e-4
+
+
+__all__ = ["ViTConfig", "ViTOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/feature_extraction_vit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/feature_extraction_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..c6a93df0bd8f82c81a715f78713a27b17672ecf6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/feature_extraction_vit.py
@@ -0,0 +1,38 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Feature extractor class for ViT."""
+
+import warnings
+
+from ...utils import logging
+from ...utils.import_utils import requires
+from .image_processing_vit import ViTImageProcessor
+
+
+logger = logging.get_logger(__name__)
+
+
+@requires(backends=("vision",))
+class ViTFeatureExtractor(ViTImageProcessor):
+ def __init__(self, *args, **kwargs) -> None:
+ warnings.warn(
+ "The class ViTFeatureExtractor is deprecated and will be removed in version 5 of Transformers. Please"
+ " use ViTImageProcessor instead.",
+ FutureWarning,
+ )
+ super().__init__(*args, **kwargs)
+
+
+__all__ = ["ViTFeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/image_processing_vit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/image_processing_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..8da5f302d475b0ebefcbd46b3e7d29bd4d5d658e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/image_processing_vit.py
@@ -0,0 +1,288 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for ViT."""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import convert_to_rgb, resize, to_channel_dimension_format
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, logging
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+
+@requires(backends=("vision",))
+class ViTImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a ViT image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `(size["height"],
+ size["width"])`. Can be overridden by the `do_resize` parameter in the `preprocess` method.
+ size (`dict`, *optional*, defaults to `{"height": 224, "width": 224}`):
+ Size of the output image after resizing. Can be overridden by the `size` parameter in the `preprocess`
+ method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the
+ `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale`
+ parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the
+ `preprocess` method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_convert_rgb (`bool`, *optional*):
+ Whether to convert the image to RGB.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"height": 224, "width": 224}
+ size = get_size_dict(size)
+ self.do_resize = do_resize
+ self.do_rescale = do_rescale
+ self.do_normalize = do_normalize
+ self.size = size
+ self.resample = resample
+ self.rescale_factor = rescale_factor
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+ self.do_convert_rgb = do_convert_rgb
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image to `(size["height"], size["width"])`.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Dictionary in the format `{"height": int, "width": int}` specifying the size of the output image.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BILINEAR`.
+ data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the output image. If unset, the channel dimension format of the input
+ image is used. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+
+ Returns:
+ `np.ndarray`: The resized image.
+ """
+ size = get_size_dict(size)
+ if "height" not in size or "width" not in size:
+ raise ValueError(f"The `size` dictionary must contain the keys `height` and `width`. Got {size.keys()}")
+ output_size = (size["height"], size["width"])
+ return resize(
+ image,
+ size=output_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Union[str, ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ do_convert_rgb: Optional[bool] = None,
+ ):
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Dictionary in the format `{"height": h, "width": w}` specifying the size of the output image after
+ resizing.
+ resample (`PILImageResampling` filter, *optional*, defaults to `self.resample`):
+ `PILImageResampling` filter to use if resizing the image e.g. `PILImageResampling.BILINEAR`. Only has
+ an effect if `do_resize` is set to `True`.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use if `do_normalize` is set to `True`.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`):
+ Whether to convert the image to RGB.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ resample = resample if resample is not None else self.resample
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb
+
+ size = size if size is not None else self.size
+ size_dict = get_size_dict(size)
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ if do_convert_rgb:
+ images = [convert_to_rgb(image) for image in images]
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_resize:
+ images = [
+ self.resize(image=image, size=size_dict, resample=resample, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_normalize:
+ images = [
+ self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images
+ ]
+
+ data = {"pixel_values": images}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["ViTImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/image_processing_vit_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/image_processing_vit_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..20aa73f73c5c8e847cc2c4ec33ce79e3f178c90d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/image_processing_vit_fast.py
@@ -0,0 +1,41 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for ViT."""
+
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ PILImageResampling,
+)
+from ...utils import (
+ auto_docstring,
+)
+
+
+@auto_docstring
+class ViTImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BILINEAR
+ image_mean = IMAGENET_STANDARD_MEAN
+ image_std = IMAGENET_STANDARD_STD
+ size = {"height": 224, "width": 224}
+ do_resize = True
+ do_rescale = True
+ do_normalize = True
+
+
+__all__ = ["ViTImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_flax_vit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_flax_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..d62ef1b6b9280d5e66046dfc9771381c23c1a979
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_flax_vit.py
@@ -0,0 +1,677 @@
+# coding=utf-8
+# Copyright 2021 The Google Flax Team Authors and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Optional
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.linen.attention import dot_product_attention_weights
+from flax.traverse_util import flatten_dict, unflatten_dict
+
+from ...modeling_flax_outputs import FlaxBaseModelOutput, FlaxBaseModelOutputWithPooling, FlaxSequenceClassifierOutput
+from ...modeling_flax_utils import (
+ ACT2FN,
+ FlaxPreTrainedModel,
+ append_replace_return_docstrings,
+ overwrite_call_docstring,
+)
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward
+from .configuration_vit import ViTConfig
+
+
+VIT_START_DOCSTRING = r"""
+
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading, saving and converting weights from PyTorch models)
+
+ This model is also a
+ [flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html) subclass. Use it as
+ a regular Flax linen Module and refer to the Flax documentation for all matter related to general usage and
+ behavior.
+
+ Finally, this model supports inherent JAX features such as:
+
+ - [Just-In-Time (JIT) compilation](https://jax.readthedocs.io/en/latest/jax.html#just-in-time-compilation-jit)
+ - [Automatic Differentiation](https://jax.readthedocs.io/en/latest/jax.html#automatic-differentiation)
+ - [Vectorization](https://jax.readthedocs.io/en/latest/jax.html#vectorization-vmap)
+ - [Parallelization](https://jax.readthedocs.io/en/latest/jax.html#parallelization-pmap)
+
+ Parameters:
+ config ([`ViTConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs).
+
+ This can be used to enable mixed-precision training or half-precision inference on GPUs or TPUs. If
+ specified all the computation will be performed with the given `dtype`.
+
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.**
+
+ If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`] and
+ [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+VIT_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`numpy.ndarray` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`]
+ for details.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+class FlaxViTPatchEmbeddings(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ image_size = self.config.image_size
+ patch_size = self.config.patch_size
+ num_patches = (image_size // patch_size) * (image_size // patch_size)
+ self.num_patches = num_patches
+ self.num_channels = self.config.num_channels
+ self.projection = nn.Conv(
+ self.config.hidden_size,
+ kernel_size=(patch_size, patch_size),
+ strides=(patch_size, patch_size),
+ padding="VALID",
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, "fan_in", "truncated_normal"
+ ),
+ )
+
+ def __call__(self, pixel_values):
+ num_channels = pixel_values.shape[-1]
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ )
+ embeddings = self.projection(pixel_values)
+ batch_size, _, _, channels = embeddings.shape
+ return jnp.reshape(embeddings, (batch_size, -1, channels))
+
+
+class FlaxViTEmbeddings(nn.Module):
+ """Construct the CLS token, position and patch embeddings."""
+
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.cls_token = self.param(
+ "cls_token",
+ jax.nn.initializers.variance_scaling(self.config.initializer_range**2, "fan_in", "truncated_normal"),
+ (1, 1, self.config.hidden_size),
+ )
+ self.patch_embeddings = FlaxViTPatchEmbeddings(self.config, dtype=self.dtype)
+ num_patches = self.patch_embeddings.num_patches
+ self.position_embeddings = self.param(
+ "position_embeddings",
+ jax.nn.initializers.variance_scaling(self.config.initializer_range**2, "fan_in", "truncated_normal"),
+ (1, num_patches + 1, self.config.hidden_size),
+ )
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout_prob)
+
+ def __call__(self, pixel_values, deterministic=True):
+ batch_size = pixel_values.shape[0]
+
+ embeddings = self.patch_embeddings(pixel_values)
+
+ cls_tokens = jnp.broadcast_to(self.cls_token, (batch_size, 1, self.config.hidden_size))
+ embeddings = jnp.concatenate((cls_tokens, embeddings), axis=1)
+ embeddings = embeddings + self.position_embeddings
+ embeddings = self.dropout(embeddings, deterministic=deterministic)
+ return embeddings
+
+
+class FlaxViTSelfAttention(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ if self.config.hidden_size % self.config.num_attention_heads != 0:
+ raise ValueError(
+ "`config.hidden_size`: {self.config.hidden_size} has to be a multiple of `config.num_attention_heads`:"
+ " {self.config.num_attention_heads}"
+ )
+
+ self.query = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, mode="fan_in", distribution="truncated_normal"
+ ),
+ use_bias=self.config.qkv_bias,
+ )
+ self.key = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, mode="fan_in", distribution="truncated_normal"
+ ),
+ use_bias=self.config.qkv_bias,
+ )
+ self.value = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, mode="fan_in", distribution="truncated_normal"
+ ),
+ use_bias=self.config.qkv_bias,
+ )
+
+ def __call__(self, hidden_states, deterministic: bool = True, output_attentions: bool = False):
+ head_dim = self.config.hidden_size // self.config.num_attention_heads
+
+ query_states = self.query(hidden_states).reshape(
+ hidden_states.shape[:2] + (self.config.num_attention_heads, head_dim)
+ )
+ value_states = self.value(hidden_states).reshape(
+ hidden_states.shape[:2] + (self.config.num_attention_heads, head_dim)
+ )
+ key_states = self.key(hidden_states).reshape(
+ hidden_states.shape[:2] + (self.config.num_attention_heads, head_dim)
+ )
+
+ dropout_rng = None
+ if not deterministic and self.config.attention_probs_dropout_prob > 0.0:
+ dropout_rng = self.make_rng("dropout")
+
+ attn_weights = dot_product_attention_weights(
+ query_states,
+ key_states,
+ dropout_rng=dropout_rng,
+ dropout_rate=self.config.attention_probs_dropout_prob,
+ broadcast_dropout=True,
+ deterministic=deterministic,
+ dtype=self.dtype,
+ precision=None,
+ )
+
+ attn_output = jnp.einsum("...hqk,...khd->...qhd", attn_weights, value_states)
+ attn_output = attn_output.reshape(attn_output.shape[:2] + (-1,))
+
+ outputs = (attn_output, attn_weights) if output_attentions else (attn_output,)
+ return outputs
+
+
+class FlaxViTSelfOutput(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.hidden_size,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, "fan_in", "truncated_normal"
+ ),
+ dtype=self.dtype,
+ )
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout_prob)
+
+ def __call__(self, hidden_states, input_tensor, deterministic: bool = True):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ return hidden_states
+
+
+class FlaxViTAttention(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.attention = FlaxViTSelfAttention(self.config, dtype=self.dtype)
+ self.output = FlaxViTSelfOutput(self.config, dtype=self.dtype)
+
+ def __call__(self, hidden_states, deterministic=True, output_attentions: bool = False):
+ attn_outputs = self.attention(hidden_states, deterministic=deterministic, output_attentions=output_attentions)
+ attn_output = attn_outputs[0]
+ hidden_states = self.output(attn_output, hidden_states, deterministic=deterministic)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_outputs[1],)
+
+ return outputs
+
+
+class FlaxViTIntermediate(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.intermediate_size,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, "fan_in", "truncated_normal"
+ ),
+ dtype=self.dtype,
+ )
+ self.activation = ACT2FN[self.config.hidden_act]
+
+ def __call__(self, hidden_states):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class FlaxViTOutput(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.hidden_size,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, "fan_in", "truncated_normal"
+ ),
+ dtype=self.dtype,
+ )
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout_prob)
+
+ def __call__(self, hidden_states, attention_output, deterministic: bool = True):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = hidden_states + attention_output
+ return hidden_states
+
+
+class FlaxViTLayer(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.attention = FlaxViTAttention(self.config, dtype=self.dtype)
+ self.intermediate = FlaxViTIntermediate(self.config, dtype=self.dtype)
+ self.output = FlaxViTOutput(self.config, dtype=self.dtype)
+ self.layernorm_before = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.layernorm_after = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+
+ def __call__(self, hidden_states, deterministic: bool = True, output_attentions: bool = False):
+ attention_outputs = self.attention(
+ self.layernorm_before(hidden_states), # in ViT, layernorm is applied before self-attention
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ )
+
+ attention_output = attention_outputs[0]
+
+ # first residual connection
+ attention_output = attention_output + hidden_states
+
+ # in ViT, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(attention_output)
+
+ hidden_states = self.intermediate(layer_output)
+ hidden_states = self.output(hidden_states, attention_output, deterministic=deterministic)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attention_outputs[1],)
+ return outputs
+
+
+class FlaxViTLayerCollection(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.layers = [
+ FlaxViTLayer(self.config, name=str(i), dtype=self.dtype) for i in range(self.config.num_hidden_layers)
+ ]
+
+ def __call__(
+ self,
+ hidden_states,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ all_attentions = () if output_attentions else None
+ all_hidden_states = () if output_hidden_states else None
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ layer_outputs = layer(hidden_states, deterministic=deterministic, output_attentions=output_attentions)
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions += (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ outputs = (hidden_states,)
+ if not return_dict:
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_attentions
+ )
+
+
+class FlaxViTEncoder(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.layer = FlaxViTLayerCollection(self.config, dtype=self.dtype)
+
+ def __call__(
+ self,
+ hidden_states,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ return self.layer(
+ hidden_states,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+
+class FlaxViTPooler(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.pooler_output_size,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, "fan_in", "truncated_normal"
+ ),
+ dtype=self.dtype,
+ )
+ self.activation = ACT2FN[self.config.pooler_act]
+
+ def __call__(self, hidden_states):
+ cls_hidden_state = hidden_states[:, 0]
+ cls_hidden_state = self.dense(cls_hidden_state)
+ return self.activation(cls_hidden_state)
+
+
+class FlaxViTPreTrainedModel(FlaxPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = ViTConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+ module_class: nn.Module = None
+
+ def __init__(
+ self,
+ config: ViTConfig,
+ input_shape=None,
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ **kwargs,
+ ):
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+ if input_shape is None:
+ input_shape = (1, config.image_size, config.image_size, config.num_channels)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensors
+ pixel_values = jnp.zeros(input_shape, dtype=self.dtype)
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(rngs, pixel_values, return_dict=False)["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ @add_start_docstrings_to_model_forward(VIT_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ def __call__(
+ self,
+ pixel_values,
+ params: Optional[dict] = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ train: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ pixel_values = jnp.transpose(pixel_values, (0, 2, 3, 1))
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ return self.module.apply(
+ {"params": params or self.params},
+ jnp.array(pixel_values, dtype=jnp.float32),
+ not train,
+ output_attentions,
+ output_hidden_states,
+ return_dict,
+ rngs=rngs,
+ )
+
+
+class FlaxViTModule(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ add_pooling_layer: bool = True
+
+ def setup(self):
+ self.embeddings = FlaxViTEmbeddings(self.config, dtype=self.dtype)
+ self.encoder = FlaxViTEncoder(self.config, dtype=self.dtype)
+ self.layernorm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.pooler = FlaxViTPooler(self.config, dtype=self.dtype) if self.add_pooling_layer else None
+
+ def __call__(
+ self,
+ pixel_values,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ hidden_states = self.embeddings(pixel_values, deterministic=deterministic)
+
+ outputs = self.encoder(
+ hidden_states,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ hidden_states = outputs[0]
+ hidden_states = self.layernorm(hidden_states)
+ pooled = self.pooler(hidden_states) if self.add_pooling_layer else None
+
+ if not return_dict:
+ # if pooled is None, don't return it
+ if pooled is None:
+ return (hidden_states,) + outputs[1:]
+ return (hidden_states, pooled) + outputs[1:]
+
+ return FlaxBaseModelOutputWithPooling(
+ last_hidden_state=hidden_states,
+ pooler_output=pooled,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@add_start_docstrings(
+ "The bare ViT Model transformer outputting raw hidden-states without any specific head on top.",
+ VIT_START_DOCSTRING,
+)
+class FlaxViTModel(FlaxViTPreTrainedModel):
+ module_class = FlaxViTModule
+
+
+FLAX_VISION_MODEL_DOCSTRING = """
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, FlaxViTModel
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224-in21k")
+ >>> model = FlaxViTModel.from_pretrained("google/vit-base-patch16-224-in21k")
+
+ >>> inputs = image_processor(images=image, return_tensors="np")
+ >>> outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```
+"""
+
+overwrite_call_docstring(FlaxViTModel, FLAX_VISION_MODEL_DOCSTRING)
+append_replace_return_docstrings(FlaxViTModel, output_type=FlaxBaseModelOutputWithPooling, config_class=ViTConfig)
+
+
+class FlaxViTForImageClassificationModule(nn.Module):
+ config: ViTConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.vit = FlaxViTModule(config=self.config, dtype=self.dtype, add_pooling_layer=False)
+ self.classifier = nn.Dense(
+ self.config.num_labels,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.variance_scaling(
+ self.config.initializer_range**2, "fan_in", "truncated_normal"
+ ),
+ )
+
+ def __call__(
+ self,
+ pixel_values=None,
+ deterministic: bool = True,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.vit(
+ pixel_values,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ logits = self.classifier(hidden_states[:, 0, :])
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return output
+
+ return FlaxSequenceClassifierOutput(
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@add_start_docstrings(
+ """
+ ViT Model transformer with an image classification head on top (a linear layer on top of the final hidden state of
+ the [CLS] token) e.g. for ImageNet.
+ """,
+ VIT_START_DOCSTRING,
+)
+class FlaxViTForImageClassification(FlaxViTPreTrainedModel):
+ module_class = FlaxViTForImageClassificationModule
+
+
+FLAX_VISION_CLASSIF_DOCSTRING = """
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, FlaxViTForImageClassification
+ >>> from PIL import Image
+ >>> import jax
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+ >>> model = FlaxViTForImageClassification.from_pretrained("google/vit-base-patch16-224")
+
+ >>> inputs = image_processor(images=image, return_tensors="np")
+ >>> outputs = model(**inputs)
+ >>> logits = outputs.logits
+
+ >>> # model predicts one of the 1000 ImageNet classes
+ >>> predicted_class_idx = jax.numpy.argmax(logits, axis=-1)
+ >>> print("Predicted class:", model.config.id2label[predicted_class_idx.item()])
+ ```
+"""
+
+overwrite_call_docstring(FlaxViTForImageClassification, FLAX_VISION_CLASSIF_DOCSTRING)
+append_replace_return_docstrings(
+ FlaxViTForImageClassification, output_type=FlaxSequenceClassifierOutput, config_class=ViTConfig
+)
+
+
+__all__ = ["FlaxViTForImageClassification", "FlaxViTModel", "FlaxViTPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_tf_vit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_tf_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..80d785e321144ba7675a93aab08d573712791d17
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_tf_vit.py
@@ -0,0 +1,906 @@
+# coding=utf-8
+# Copyright 2021 Google AI, Ross Wightman, The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TF 2.0 ViT model."""
+
+from __future__ import annotations
+
+import collections.abc
+import math
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_outputs import TFBaseModelOutput, TFBaseModelOutputWithPooling, TFSequenceClassifierOutput
+from ...modeling_tf_utils import (
+ TFModelInputType,
+ TFPreTrainedModel,
+ TFSequenceClassificationLoss,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import shape_list, stable_softmax
+from ...utils import add_code_sample_docstrings, add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_vit import ViTConfig
+
+
+logger = logging.get_logger(__name__)
+
+# General docstring
+_CONFIG_FOR_DOC = "ViTConfig"
+
+# Base docstring
+_CHECKPOINT_FOR_DOC = "google/vit-base-patch16-224-in21k"
+_EXPECTED_OUTPUT_SHAPE = [1, 197, 768]
+
+# Image classification docstring
+_IMAGE_CLASS_CHECKPOINT = "google/vit-base-patch16-224"
+_IMAGE_CLASS_EXPECTED_OUTPUT = "Egyptian cat"
+
+
+class TFViTEmbeddings(keras.layers.Layer):
+ """
+ Construct the CLS token, position and patch embeddings.
+
+ """
+
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.patch_embeddings = TFViTPatchEmbeddings(config, name="patch_embeddings")
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def build(self, input_shape=None):
+ num_patches = self.patch_embeddings.num_patches
+ self.cls_token = self.add_weight(
+ shape=(1, 1, self.config.hidden_size),
+ initializer=get_initializer(self.config.initializer_range),
+ trainable=True,
+ name="cls_token",
+ )
+ self.position_embeddings = self.add_weight(
+ shape=(1, num_patches + 1, self.config.hidden_size),
+ initializer=get_initializer(self.config.initializer_range),
+ trainable=True,
+ name="position_embeddings",
+ )
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "patch_embeddings", None) is not None:
+ with tf.name_scope(self.patch_embeddings.name):
+ self.patch_embeddings.build(None)
+
+ def interpolate_pos_encoding(self, embeddings, height, width) -> tf.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher
+ resolution images.
+
+ Source:
+ https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174
+ """
+
+ batch_size, seq_len, dim = shape_list(embeddings)
+ num_patches = seq_len - 1
+
+ _, num_positions, _ = shape_list(self.position_embeddings)
+ num_positions -= 1
+
+ if num_patches == num_positions and height == width:
+ return self.position_embeddings
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+ h0 = height // self.config.patch_size
+ w0 = width // self.config.patch_size
+ patch_pos_embed = tf.image.resize(
+ images=tf.reshape(
+ patch_pos_embed, shape=(1, int(math.sqrt(num_positions)), int(math.sqrt(num_positions)), dim)
+ ),
+ size=(h0, w0),
+ method="bicubic",
+ )
+
+ shape = shape_list(patch_pos_embed)
+ assert h0 == shape[-3] and w0 == shape[-2]
+ patch_pos_embed = tf.reshape(tensor=patch_pos_embed, shape=(1, -1, dim))
+ return tf.concat(values=(class_pos_embed, patch_pos_embed), axis=1)
+
+ def call(
+ self, pixel_values: tf.Tensor, interpolate_pos_encoding: bool = False, training: bool = False
+ ) -> tf.Tensor:
+ batch_size, num_channels, height, width = shape_list(pixel_values)
+ embeddings = self.patch_embeddings(
+ pixel_values, interpolate_pos_encoding=interpolate_pos_encoding, training=training
+ )
+
+ # add the [CLS] token to the embedded patch tokens
+ cls_tokens = tf.repeat(self.cls_token, repeats=batch_size, axis=0)
+ embeddings = tf.concat((cls_tokens, embeddings), axis=1)
+
+ # add positional encoding to each token
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings, training=training)
+
+ return embeddings
+
+
+# Based on timm implementation, which can be found here:
+# https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/vision_transformer.py
+class TFViTPatchEmbeddings(keras.layers.Layer):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_patches = num_patches
+ self.num_channels = num_channels
+ self.config = config
+
+ self.projection = keras.layers.Conv2D(
+ filters=hidden_size,
+ kernel_size=patch_size,
+ strides=patch_size,
+ padding="valid",
+ data_format="channels_last",
+ use_bias=True,
+ kernel_initializer=get_initializer(self.config.initializer_range),
+ bias_initializer="zeros",
+ name="projection",
+ )
+
+ def call(
+ self, pixel_values: tf.Tensor, interpolate_pos_encoding: bool = False, training: bool = False
+ ) -> tf.Tensor:
+ batch_size, num_channels, height, width = shape_list(pixel_values)
+ if tf.executing_eagerly() and num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ )
+ if not interpolate_pos_encoding:
+ if tf.executing_eagerly():
+ if height != self.image_size[0] or width != self.image_size[1]:
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model"
+ f" ({self.image_size[0]}*{self.image_size[1]})."
+ )
+
+ # When running on CPU, `keras.layers.Conv2D` doesn't support `NCHW` format.
+ # So change the input format from `NCHW` to `NHWC`.
+ # shape = (batch_size, in_height, in_width, in_channels=num_channels)
+ pixel_values = tf.transpose(pixel_values, perm=(0, 2, 3, 1))
+
+ projection = self.projection(pixel_values)
+
+ # Change the 2D spatial dimensions to a single temporal dimension.
+ # shape = (batch_size, num_patches, out_channels=embed_dim)
+ num_patches = (width // self.patch_size[1]) * (height // self.patch_size[0])
+ embeddings = tf.reshape(tensor=projection, shape=(batch_size, num_patches, -1))
+
+ return embeddings
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "projection", None) is not None:
+ with tf.name_scope(self.projection.name):
+ self.projection.build([None, None, None, self.num_channels])
+
+
+class TFViTSelfAttention(keras.layers.Layer):
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ if config.hidden_size % config.num_attention_heads != 0:
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number "
+ f"of attention heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.sqrt_att_head_size = math.sqrt(self.attention_head_size)
+
+ self.query = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="query"
+ )
+ self.key = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="key"
+ )
+ self.value = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="value"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.attention_probs_dropout_prob)
+ self.config = config
+
+ def transpose_for_scores(self, tensor: tf.Tensor, batch_size: int) -> tf.Tensor:
+ # Reshape from [batch_size, seq_length, all_head_size] to [batch_size, seq_length, num_attention_heads, attention_head_size]
+ tensor = tf.reshape(tensor=tensor, shape=(batch_size, -1, self.num_attention_heads, self.attention_head_size))
+
+ # Transpose the tensor from [batch_size, seq_length, num_attention_heads, attention_head_size] to [batch_size, num_attention_heads, seq_length, attention_head_size]
+ return tf.transpose(tensor, perm=[0, 2, 1, 3])
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ batch_size = shape_list(hidden_states)[0]
+ mixed_query_layer = self.query(inputs=hidden_states)
+ mixed_key_layer = self.key(inputs=hidden_states)
+ mixed_value_layer = self.value(inputs=hidden_states)
+ query_layer = self.transpose_for_scores(mixed_query_layer, batch_size)
+ key_layer = self.transpose_for_scores(mixed_key_layer, batch_size)
+ value_layer = self.transpose_for_scores(mixed_value_layer, batch_size)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ # (batch size, num_heads, seq_len_q, seq_len_k)
+ attention_scores = tf.matmul(query_layer, key_layer, transpose_b=True)
+ dk = tf.cast(self.sqrt_att_head_size, dtype=attention_scores.dtype)
+ attention_scores = tf.divide(attention_scores, dk)
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = stable_softmax(logits=attention_scores, axis=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(inputs=attention_probs, training=training)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = tf.multiply(attention_probs, head_mask)
+
+ attention_output = tf.matmul(attention_probs, value_layer)
+ attention_output = tf.transpose(attention_output, perm=[0, 2, 1, 3])
+
+ # (batch_size, seq_len_q, all_head_size)
+ attention_output = tf.reshape(tensor=attention_output, shape=(batch_size, -1, self.all_head_size))
+ outputs = (attention_output, attention_probs) if output_attentions else (attention_output,)
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "query", None) is not None:
+ with tf.name_scope(self.query.name):
+ self.query.build([None, None, self.config.hidden_size])
+ if getattr(self, "key", None) is not None:
+ with tf.name_scope(self.key.name):
+ self.key.build([None, None, self.config.hidden_size])
+ if getattr(self, "value", None) is not None:
+ with tf.name_scope(self.value.name):
+ self.value.build([None, None, self.config.hidden_size])
+
+
+class TFViTSelfOutput(keras.layers.Layer):
+ """
+ The residual connection is defined in TFViTLayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+class TFViTAttention(keras.layers.Layer):
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.self_attention = TFViTSelfAttention(config, name="attention")
+ self.dense_output = TFViTSelfOutput(config, name="output")
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ def call(
+ self,
+ input_tensor: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ self_outputs = self.self_attention(
+ hidden_states=input_tensor, head_mask=head_mask, output_attentions=output_attentions, training=training
+ )
+ attention_output = self.dense_output(
+ hidden_states=self_outputs[0], input_tensor=input_tensor, training=training
+ )
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attention", None) is not None:
+ with tf.name_scope(self.self_attention.name):
+ self.self_attention.build(None)
+ if getattr(self, "dense_output", None) is not None:
+ with tf.name_scope(self.dense_output.name):
+ self.dense_output.build(None)
+
+
+class TFViTIntermediate(keras.layers.Layer):
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.intermediate_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = get_tf_activation(config.hidden_act)
+ else:
+ self.intermediate_act_fn = config.hidden_act
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+class TFViTOutput(keras.layers.Layer):
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+ hidden_states = hidden_states + input_tensor
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.intermediate_size])
+
+
+class TFViTLayer(keras.layers.Layer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.attention = TFViTAttention(config, name="attention")
+ self.intermediate = TFViTIntermediate(config, name="intermediate")
+ self.vit_output = TFViTOutput(config, name="output")
+
+ self.layernorm_before = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm_before")
+ self.layernorm_after = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm_after")
+ self.config = config
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ attention_outputs = self.attention(
+ # in ViT, layernorm is applied before self-attention
+ input_tensor=self.layernorm_before(inputs=hidden_states),
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = attention_outputs[0]
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in ViT, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(inputs=hidden_states)
+
+ intermediate_output = self.intermediate(hidden_states=layer_output)
+
+ # second residual connection is done here
+ layer_output = self.vit_output(
+ hidden_states=intermediate_output, input_tensor=hidden_states, training=training
+ )
+ outputs = (layer_output,) + attention_outputs[1:] # add attentions if we output them
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "attention", None) is not None:
+ with tf.name_scope(self.attention.name):
+ self.attention.build(None)
+ if getattr(self, "intermediate", None) is not None:
+ with tf.name_scope(self.intermediate.name):
+ self.intermediate.build(None)
+ if getattr(self, "vit_output", None) is not None:
+ with tf.name_scope(self.vit_output.name):
+ self.vit_output.build(None)
+ if getattr(self, "layernorm_before", None) is not None:
+ with tf.name_scope(self.layernorm_before.name):
+ self.layernorm_before.build([None, None, self.config.hidden_size])
+ if getattr(self, "layernorm_after", None) is not None:
+ with tf.name_scope(self.layernorm_after.name):
+ self.layernorm_after.build([None, None, self.config.hidden_size])
+
+
+class TFViTEncoder(keras.layers.Layer):
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.layer = [TFViTLayer(config, name=f"layer_._{i}") for i in range(config.num_hidden_layers)]
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ output_hidden_states: bool,
+ return_dict: bool,
+ training: bool = False,
+ ) -> TFBaseModelOutput | tuple[tf.Tensor]:
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states=hidden_states,
+ head_mask=head_mask[i],
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_attentions] if v is not None)
+
+ return TFBaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_attentions
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer", None) is not None:
+ for layer in self.layer:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@keras_serializable
+class TFViTMainLayer(keras.layers.Layer):
+ config_class = ViTConfig
+
+ def __init__(self, config: ViTConfig, add_pooling_layer: bool = True, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+
+ self.embeddings = TFViTEmbeddings(config, name="embeddings")
+ self.encoder = TFViTEncoder(config, name="encoder")
+ self.layernorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm")
+ self.pooler = TFViTPooler(config, name="pooler") if add_pooling_layer else None
+
+ def get_input_embeddings(self) -> keras.layers.Layer:
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ raise NotImplementedError
+
+ @unpack_inputs
+ def call(
+ self,
+ pixel_values: TFModelInputType | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ interpolate_pos_encoding: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFBaseModelOutputWithPooling | tuple[tf.Tensor]:
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ embedding_output = self.embeddings(
+ pixel_values=pixel_values,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ training=training,
+ )
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ if head_mask is not None:
+ raise NotImplementedError
+ else:
+ head_mask = [None] * self.config.num_hidden_layers
+
+ encoder_outputs = self.encoder(
+ hidden_states=embedding_output,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = encoder_outputs[0]
+ sequence_output = self.layernorm(inputs=sequence_output)
+ pooled_output = self.pooler(hidden_states=sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return TFBaseModelOutputWithPooling(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "embeddings", None) is not None:
+ with tf.name_scope(self.embeddings.name):
+ self.embeddings.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "layernorm", None) is not None:
+ with tf.name_scope(self.layernorm.name):
+ self.layernorm.build([None, None, self.config.hidden_size])
+ if getattr(self, "pooler", None) is not None:
+ with tf.name_scope(self.pooler.name):
+ self.pooler.build(None)
+
+
+class TFViTPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = ViTConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+
+
+VIT_START_DOCSTRING = r"""
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `pixel_values` only and nothing else: `model(pixel_values)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([pixel_values, attention_mask])` or `model([pixel_values, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"pixel_values": pixel_values, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Args:
+ config ([`ViTConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~TFPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+VIT_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`np.ndarray`, `tf.Tensor`, `list[tf.Tensor]` ``dict[str, tf.Tensor]` or `dict[str, np.ndarray]` and each example must have the shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`]
+ for details.
+
+ head_mask (`np.ndarray` or `tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ interpolate_pos_encoding (`bool`, *optional*):
+ Whether to interpolate the pre-trained position encodings.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False``):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+
+@add_start_docstrings(
+ "The bare ViT Model transformer outputting raw hidden-states without any specific head on top.",
+ VIT_START_DOCSTRING,
+)
+class TFViTModel(TFViTPreTrainedModel):
+ def __init__(self, config: ViTConfig, *inputs, add_pooling_layer=True, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.vit = TFViTMainLayer(config, add_pooling_layer=add_pooling_layer, name="vit")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(VIT_INPUTS_DOCSTRING)
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFBaseModelOutputWithPooling,
+ config_class=_CONFIG_FOR_DOC,
+ modality="vision",
+ expected_output=_EXPECTED_OUTPUT_SHAPE,
+ )
+ def call(
+ self,
+ pixel_values: TFModelInputType | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ interpolate_pos_encoding: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFBaseModelOutputWithPooling | tuple[tf.Tensor]:
+ outputs = self.vit(
+ pixel_values=pixel_values,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "vit", None) is not None:
+ with tf.name_scope(self.vit.name):
+ self.vit.build(None)
+
+
+class TFViTPooler(keras.layers.Layer):
+ def __init__(self, config: ViTConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.pooler_output_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ activation=config.pooler_act,
+ name="dense",
+ )
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(inputs=first_token_tensor)
+
+ return pooled_output
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+@add_start_docstrings(
+ """
+ ViT Model transformer with an image classification head on top (a linear layer on top of the final hidden state of
+ the [CLS] token) e.g. for ImageNet.
+
+
+
+ Note that it's possible to fine-tune ViT on higher resolution images than the ones it has been trained on, by
+ setting `interpolate_pos_encoding` to `True` in the forward of the model. This will interpolate the pre-trained
+ position embeddings to the higher resolution.
+
+
+ """,
+ VIT_START_DOCSTRING,
+)
+class TFViTForImageClassification(TFViTPreTrainedModel, TFSequenceClassificationLoss):
+ def __init__(self, config: ViTConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.num_labels = config.num_labels
+ self.vit = TFViTMainLayer(config, add_pooling_layer=False, name="vit")
+
+ # Classifier head
+ self.classifier = keras.layers.Dense(
+ units=config.num_labels,
+ kernel_initializer=get_initializer(config.initializer_range),
+ name="classifier",
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(VIT_INPUTS_DOCSTRING)
+ @add_code_sample_docstrings(
+ checkpoint=_IMAGE_CLASS_CHECKPOINT,
+ output_type=TFSequenceClassifierOutput,
+ config_class=_CONFIG_FOR_DOC,
+ expected_output=_IMAGE_CLASS_EXPECTED_OUTPUT,
+ )
+ def call(
+ self,
+ pixel_values: TFModelInputType | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ interpolate_pos_encoding: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFSequenceClassifierOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` or `np.ndarray` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ outputs = self.vit(
+ pixel_values=pixel_values,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = outputs[0]
+ logits = self.classifier(inputs=sequence_output[:, 0, :])
+ loss = None if labels is None else self.hf_compute_loss(labels=labels, logits=logits)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFSequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "vit", None) is not None:
+ with tf.name_scope(self.vit.name):
+ self.vit.build(None)
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.config.hidden_size])
+
+
+__all__ = ["TFViTForImageClassification", "TFViTModel", "TFViTPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_vit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..3e84687d8ffa8449d48865938e96d21cd949ae49
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit/modeling_vit.py
@@ -0,0 +1,692 @@
+# coding=utf-8
+# Copyright 2021 Google AI, Ross Wightman, The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ViT model."""
+
+import collections.abc
+import math
+from typing import Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPooling,
+ ImageClassifierOutput,
+ MaskedImageModelingOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import TransformersKwargs, auto_docstring, logging, torch_int
+from ...utils.generic import can_return_tuple, check_model_inputs
+from .configuration_vit import ViTConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class ViTEmbeddings(nn.Module):
+ """
+ Construct the CLS token, position and patch embeddings. Optionally, also the mask token.
+ """
+
+ def __init__(self, config: ViTConfig, use_mask_token: bool = False):
+ super().__init__()
+
+ self.cls_token = nn.Parameter(torch.randn(1, 1, config.hidden_size))
+ self.mask_token = nn.Parameter(torch.zeros(1, 1, config.hidden_size)) if use_mask_token else None
+ self.patch_embeddings = ViTPatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+ self.position_embeddings = nn.Parameter(torch.randn(1, num_patches + 1, config.hidden_size))
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.patch_size = config.patch_size
+ self.config = config
+
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ num_positions = self.position_embeddings.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embeddings
+
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def forward(
+ self,
+ pixel_values: torch.Tensor,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> torch.Tensor:
+ batch_size, num_channels, height, width = pixel_values.shape
+ embeddings = self.patch_embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+
+ if bool_masked_pos is not None:
+ seq_length = embeddings.shape[1]
+ mask_tokens = self.mask_token.expand(batch_size, seq_length, -1)
+ # replace the masked visual tokens by mask_tokens
+ mask = bool_masked_pos.unsqueeze(-1).type_as(mask_tokens)
+ embeddings = embeddings * (1.0 - mask) + mask_tokens * mask
+
+ # add the [CLS] token to the embedded patch tokens
+ cls_tokens = self.cls_token.expand(batch_size, -1, -1)
+ embeddings = torch.cat((cls_tokens, embeddings), dim=1)
+
+ # add positional encoding to each token
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings)
+
+ return embeddings
+
+
+class ViTPatchEmbeddings(nn.Module):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def forward(self, pixel_values: torch.Tensor, interpolate_pos_encoding: bool = False) -> torch.Tensor:
+ batch_size, num_channels, height, width = pixel_values.shape
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ f" Expected {self.num_channels} but got {num_channels}."
+ )
+ if not interpolate_pos_encoding:
+ if height != self.image_size[0] or width != self.image_size[1]:
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model"
+ f" ({self.image_size[0]}*{self.image_size[1]})."
+ )
+ embeddings = self.projection(pixel_values).flatten(2).transpose(1, 2)
+ return embeddings
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class ViTSelfAttention(nn.Module):
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ def forward(
+ self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ batch_size = hidden_states.shape[0]
+ new_shape = batch_size, -1, self.num_attention_heads, self.attention_head_size
+
+ key_layer = self.key(hidden_states).view(*new_shape).transpose(1, 2)
+ value_layer = self.value(hidden_states).view(*new_shape).transpose(1, 2)
+ query_layer = self.query(hidden_states).view(*new_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.reshape(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+class ViTSelfOutput(nn.Module):
+ """
+ The residual connection is defined in ViTLayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+class ViTAttention(nn.Module):
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ self.attention = ViTSelfAttention(config)
+ self.output = ViTSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads: set[int]):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ self_attn_output, _ = self.attention(hidden_states, head_mask)
+ output = self.output(self_attn_output, hidden_states)
+ return output
+
+
+class ViTIntermediate(nn.Module):
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+class ViTOutput(nn.Module):
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+class ViTLayer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = ViTAttention(config)
+ self.intermediate = ViTIntermediate(config)
+ self.output = ViTOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ hidden_states_norm = self.layernorm_before(hidden_states)
+ attention_output = self.attention(hidden_states_norm, head_mask)
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in ViT, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+
+ # second residual connection is done here
+ layer_output = self.output(layer_output, hidden_states)
+
+ return layer_output
+
+
+class ViTEncoder(nn.Module):
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([ViTLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> BaseModelOutput:
+ for i, layer_module in enumerate(self.layer):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ hidden_states = layer_module(hidden_states, layer_head_mask)
+
+ return BaseModelOutput(last_hidden_state=hidden_states)
+
+
+@auto_docstring
+class ViTPreTrainedModel(PreTrainedModel):
+ config: ViTConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["ViTEmbeddings", "ViTLayer"]
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": ViTLayer,
+ "attentions": ViTSelfAttention,
+ }
+
+ def _init_weights(self, module: Union[nn.Linear, nn.Conv2d, nn.LayerNorm]):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Upcast the input in `fp32` and cast it back to desired `dtype` to avoid
+ # `trunc_normal_cpu` not implemented in `half` issues
+ module.weight.data = nn.init.trunc_normal_(
+ module.weight.data.to(torch.float32), mean=0.0, std=self.config.initializer_range
+ ).to(module.weight.dtype)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, ViTEmbeddings):
+ module.position_embeddings.data = nn.init.trunc_normal_(
+ module.position_embeddings.data.to(torch.float32),
+ mean=0.0,
+ std=self.config.initializer_range,
+ ).to(module.position_embeddings.dtype)
+
+ module.cls_token.data = nn.init.trunc_normal_(
+ module.cls_token.data.to(torch.float32),
+ mean=0.0,
+ std=self.config.initializer_range,
+ ).to(module.cls_token.dtype)
+
+ if module.mask_token is not None:
+ module.mask_token.data.zero_()
+
+
+@auto_docstring
+class ViTModel(ViTPreTrainedModel):
+ def __init__(self, config: ViTConfig, add_pooling_layer: bool = True, use_mask_token: bool = False):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ use_mask_token (`bool`, *optional*, defaults to `False`):
+ Whether to use a mask token for masked image modeling.
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = ViTEmbeddings(config, use_mask_token=use_mask_token)
+ self.encoder = ViTEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.pooler = ViTPooler(config) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> ViTPatchEmbeddings:
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune: dict[int, list[int]]):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ interpolate_pos_encoding: Optional[bool] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`, *optional*):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+ """
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ # TODO: maybe have a cleaner way to cast the input (from `ImageProcessor` side?)
+ expected_dtype = self.embeddings.patch_embeddings.projection.weight.dtype
+ if pixel_values.dtype != expected_dtype:
+ pixel_values = pixel_values.to(expected_dtype)
+
+ embedding_output = self.embeddings(
+ pixel_values, bool_masked_pos=bool_masked_pos, interpolate_pos_encoding=interpolate_pos_encoding
+ )
+
+ encoder_outputs: BaseModelOutput = self.encoder(embedding_output, head_mask=head_mask)
+
+ sequence_output = encoder_outputs.last_hidden_state
+ sequence_output = self.layernorm(sequence_output)
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ return BaseModelOutputWithPooling(last_hidden_state=sequence_output, pooler_output=pooled_output)
+
+
+class ViTPooler(nn.Module):
+ def __init__(self, config: ViTConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.pooler_output_size)
+ self.activation = ACT2FN[config.pooler_act]
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+@auto_docstring(
+ custom_intro="""
+ ViT Model with a decoder on top for masked image modeling, as proposed in [SimMIM](https://huggingface.co/papers/2111.09886).
+
+
+
+ Note that we provide a script to pre-train this model on custom data in our [examples
+ directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
+
+
+ """
+)
+class ViTForMaskedImageModeling(ViTPreTrainedModel):
+ def __init__(self, config: ViTConfig):
+ super().__init__(config)
+
+ self.vit = ViTModel(config, add_pooling_layer=False, use_mask_token=True)
+
+ self.decoder = nn.Sequential(
+ nn.Conv2d(
+ in_channels=config.hidden_size,
+ out_channels=config.encoder_stride**2 * config.num_channels,
+ kernel_size=1,
+ ),
+ nn.PixelShuffle(config.encoder_stride),
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ interpolate_pos_encoding: Optional[bool] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> MaskedImageModelingOutput:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+
+ Examples:
+ ```python
+ >>> from transformers import AutoImageProcessor, ViTForMaskedImageModeling
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224-in21k")
+ >>> model = ViTForMaskedImageModeling.from_pretrained("google/vit-base-patch16-224-in21k")
+
+ >>> num_patches = (model.config.image_size // model.config.patch_size) ** 2
+ >>> pixel_values = image_processor(images=image, return_tensors="pt").pixel_values
+ >>> # create random boolean mask of shape (batch_size, num_patches)
+ >>> bool_masked_pos = torch.randint(low=0, high=2, size=(1, num_patches)).bool()
+
+ >>> outputs = model(pixel_values, bool_masked_pos=bool_masked_pos)
+ >>> loss, reconstructed_pixel_values = outputs.loss, outputs.reconstruction
+ >>> list(reconstructed_pixel_values.shape)
+ [1, 3, 224, 224]
+ ```"""
+
+ if bool_masked_pos is not None and (self.config.patch_size != self.config.encoder_stride):
+ raise ValueError(
+ "When `bool_masked_pos` is provided, `patch_size` must be equal to `encoder_stride` to ensure that "
+ "the reconstructed image has the same dimensions as the input. "
+ f"Got `patch_size` = {self.config.patch_size} and `encoder_stride` = {self.config.encoder_stride}."
+ )
+
+ outputs: BaseModelOutputWithPooling = self.vit(
+ pixel_values,
+ bool_masked_pos=bool_masked_pos,
+ head_mask=head_mask,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ **kwargs,
+ )
+
+ sequence_output = outputs.last_hidden_state
+
+ # Reshape to (batch_size, num_channels, height, width)
+ sequence_output = sequence_output[:, 1:]
+ batch_size, sequence_length, num_channels = sequence_output.shape
+ height = width = math.floor(sequence_length**0.5)
+ sequence_output = sequence_output.permute(0, 2, 1).reshape(batch_size, num_channels, height, width)
+
+ # Reconstruct pixel values
+ reconstructed_pixel_values = self.decoder(sequence_output)
+
+ masked_im_loss = None
+ if bool_masked_pos is not None:
+ size = self.config.image_size // self.config.patch_size
+ bool_masked_pos = bool_masked_pos.reshape(-1, size, size)
+ mask = (
+ bool_masked_pos.repeat_interleave(self.config.patch_size, 1)
+ .repeat_interleave(self.config.patch_size, 2)
+ .unsqueeze(1)
+ .contiguous()
+ )
+ reconstruction_loss = nn.functional.l1_loss(pixel_values, reconstructed_pixel_values, reduction="none")
+ masked_im_loss = (reconstruction_loss * mask).sum() / (mask.sum() + 1e-5) / self.config.num_channels
+
+ return MaskedImageModelingOutput(
+ loss=masked_im_loss,
+ reconstruction=reconstructed_pixel_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ ViT Model transformer with an image classification head on top (a linear layer on top of the final hidden state of
+ the [CLS] token) e.g. for ImageNet.
+
+
+
+ Note that it's possible to fine-tune ViT on higher resolution images than the ones it has been trained on, by
+ setting `interpolate_pos_encoding` to `True` in the forward of the model. This will interpolate the pre-trained
+ position embeddings to the higher resolution.
+
+
+ """
+)
+class ViTForImageClassification(ViTPreTrainedModel):
+ def __init__(self, config: ViTConfig):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.vit = ViTModel(config, add_pooling_layer=False)
+
+ # Classifier head
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity()
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ interpolate_pos_encoding: Optional[bool] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> ImageClassifierOutput:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ outputs: BaseModelOutputWithPooling = self.vit(
+ pixel_values,
+ head_mask=head_mask,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ **kwargs,
+ )
+
+ sequence_output = outputs.last_hidden_state
+ pooled_output = sequence_output[:, 0, :]
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(labels, logits, self.config, **kwargs)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["ViTForImageClassification", "ViTForMaskedImageModeling", "ViTModel", "ViTPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..253017c39d6a2bb0e835d83c23526c8d7b08665a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vit_mae import *
+ from .modeling_tf_vit_mae import *
+ from .modeling_vit_mae import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/configuration_vit_mae.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/configuration_vit_mae.py
new file mode 100644
index 0000000000000000000000000000000000000000..2c5ec3600599e6ad3f2708880ce35a9ec9a626e1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/configuration_vit_mae.py
@@ -0,0 +1,140 @@
+# coding=utf-8
+# Copyright 2022 Facebook AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""ViT MAE model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class ViTMAEConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`ViTMAEModel`]. It is used to instantiate an ViT
+ MAE model according to the specified arguments, defining the model architecture. Instantiating a configuration with
+ the defaults will yield a similar configuration to that of the ViT
+ [facebook/vit-mae-base](https://huggingface.co/facebook/vit-mae-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ decoder_num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the decoder.
+ decoder_hidden_size (`int`, *optional*, defaults to 512):
+ Dimensionality of the decoder.
+ decoder_num_hidden_layers (`int`, *optional*, defaults to 8):
+ Number of hidden layers in the decoder.
+ decoder_intermediate_size (`int`, *optional*, defaults to 2048):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the decoder.
+ mask_ratio (`float`, *optional*, defaults to 0.75):
+ The ratio of the number of masked tokens in the input sequence.
+ norm_pix_loss (`bool`, *optional*, defaults to `False`):
+ Whether or not to train with normalized pixels (see Table 3 in the paper). Using normalized pixels improved
+ representation quality in the experiments of the authors.
+
+ Example:
+
+ ```python
+ >>> from transformers import ViTMAEConfig, ViTMAEModel
+
+ >>> # Initializing a ViT MAE vit-mae-base style configuration
+ >>> configuration = ViTMAEConfig()
+
+ >>> # Initializing a model (with random weights) from the vit-mae-base style configuration
+ >>> model = ViTMAEModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vit_mae"
+
+ def __init__(
+ self,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ image_size=224,
+ patch_size=16,
+ num_channels=3,
+ qkv_bias=True,
+ decoder_num_attention_heads=16,
+ decoder_hidden_size=512,
+ decoder_num_hidden_layers=8,
+ decoder_intermediate_size=2048,
+ mask_ratio=0.75,
+ norm_pix_loss=False,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+ self.decoder_num_attention_heads = decoder_num_attention_heads
+ self.decoder_hidden_size = decoder_hidden_size
+ self.decoder_num_hidden_layers = decoder_num_hidden_layers
+ self.decoder_intermediate_size = decoder_intermediate_size
+ self.mask_ratio = mask_ratio
+ self.norm_pix_loss = norm_pix_loss
+
+
+__all__ = ["ViTMAEConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/modeling_tf_vit_mae.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/modeling_tf_vit_mae.py
new file mode 100644
index 0000000000000000000000000000000000000000..d0184e92b37b283e935659787968ff92d0944bbd
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/modeling_tf_vit_mae.py
@@ -0,0 +1,1374 @@
+# coding=utf-8
+# Copyright 2022 Facebook AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TF 2.0 ViT MAE (masked autoencoder) model."""
+
+from __future__ import annotations
+
+import collections.abc
+import math
+from copy import deepcopy
+from dataclasses import dataclass
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...file_utils import (
+ ModelOutput,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ replace_return_docstrings,
+)
+from ...modeling_tf_outputs import TFBaseModelOutput
+from ...modeling_tf_utils import (
+ TFModelInputType,
+ TFPreTrainedModel,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import shape_list, stable_softmax
+from ...utils import logging
+from .configuration_vit_mae import ViTMAEConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "ViTMAEConfig"
+_CHECKPOINT_FOR_DOC = "facebook/vit-mae-base"
+
+
+@dataclass
+class TFViTMAEModelOutput(ModelOutput):
+ """
+ Class for TFViTMAEModel's outputs, with potential hidden states and attentions.
+
+ Args:
+ last_hidden_state (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ mask (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Tensor indicating which patches are masked (1) and which are not (0).
+ ids_restore (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Tensor containing the original index of the (shuffled) masked patches.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`. Hidden-states of the model at the output of each layer plus
+ the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in
+ the self-attention heads.
+ """
+
+ last_hidden_state: tf.Tensor | None = None
+ mask: tf.Tensor | None = None
+ ids_restore: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor] | None = None
+ attentions: tuple[tf.Tensor] | None = None
+
+
+@dataclass
+class TFViTMAEDecoderOutput(ModelOutput):
+ """
+ Class for TFViTMAEDecoder's outputs, with potential hidden states and attentions.
+
+ Args:
+ logits (`tf.Tensor` of shape `(batch_size, sequence_length, patch_size ** 2 * num_channels)`):
+ Pixel reconstruction logits.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`. Hidden-states of the model at the output of each layer plus
+ the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in
+ the self-attention heads.
+ """
+
+ logits: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor] | None = None
+ attentions: tuple[tf.Tensor] | None = None
+
+
+@dataclass
+class TFViTMAEForPreTrainingOutput(ModelOutput):
+ """
+ Class for TFViTMAEForPreTraining's outputs, with potential hidden states and attentions.
+
+ Args:
+ loss (`tf.Tensor` of shape `(1,)`):
+ Pixel reconstruction loss.
+ logits (`tf.Tensor` of shape `(batch_size, sequence_length, patch_size ** 2 * num_channels)`):
+ Pixel reconstruction logits.
+ mask (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Tensor indicating which patches are masked (1) and which are not (0).
+ ids_restore (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Tensor containing the original index of the (shuffled) masked patches.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`. Hidden-states of the model at the output of each layer plus
+ the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in
+ the self-attention heads.
+ """
+
+ loss: tf.Tensor | None = None
+ logits: tf.Tensor | None = None
+ mask: tf.Tensor | None = None
+ ids_restore: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor] | None = None
+ attentions: tuple[tf.Tensor] | None = None
+
+
+def get_2d_sincos_pos_embed(embed_dim, grid_size, add_cls_token=False):
+ """
+ Create 2D sin/cos positional embeddings.
+
+ Args:
+ embed_dim (`int`):
+ Embedding dimension.
+ grid_size (`int`):
+ The grid height and width.
+ add_cls_token (`bool`, *optional*, defaults to `False`):
+ Whether or not to add a classification (CLS) token.
+
+ Returns:
+ (`tf.Tensor` of shape (grid_size*grid_size, embed_dim) or (1+grid_size*grid_size, embed_dim): the position
+ embeddings (with or without classification token)
+ """
+ grid_h = tf.range(grid_size, dtype=tf.float32)
+ grid_w = tf.range(grid_size, dtype=tf.float32)
+ grid = tf.meshgrid(grid_w, grid_h) # here w goes first
+ grid = tf.stack(grid, axis=0)
+
+ grid = tf.reshape(grid, [2, 1, grid_size, grid_size])
+ pos_embed = get_2d_sincos_pos_embed_from_grid(embed_dim, grid)
+ if add_cls_token:
+ pos_embed = tf.concat([tf.zeros((1, embed_dim)), pos_embed], axis=0)
+ return pos_embed
+
+
+def get_2d_sincos_pos_embed_from_grid(embed_dim, grid):
+ if embed_dim % 2 != 0:
+ raise ValueError("embed_dim must be even")
+
+ # use half of dimensions to encode grid_h
+ emb_h = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[0]) # (H*W, D/2)
+ emb_w = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[1]) # (H*W, D/2)
+
+ emb = tf.concat([emb_h, emb_w], axis=1) # (H*W, D)
+ return emb
+
+
+def get_1d_sincos_pos_embed_from_grid(embed_dim, pos):
+ """
+ embed_dim: output dimension for each position pos: a list of positions to be encoded: size (M,) out: (M, D)
+ """
+ if embed_dim % 2 != 0:
+ raise ValueError("embed_dim must be even")
+
+ omega = tf.range(embed_dim // 2, dtype="float32")
+ omega /= embed_dim / 2.0
+ omega = 1.0 / 10000**omega # (D/2,)
+
+ pos = tf.reshape(pos, [-1]) # (M,)
+ out = tf.einsum("m,d->md", pos, omega) # (M, D/2), outer product
+
+ # half of the positions get sinusoidal pattern and the rest gets
+ # cosine pattern and then they are concatenated
+ emb_sin = tf.sin(out) # (M, D/2)
+ emb_cos = tf.cos(out) # (M, D/2)
+
+ emb = tf.concat([emb_sin, emb_cos], axis=1) # (M, D)
+ return emb
+
+
+class TFViTMAEEmbeddings(keras.layers.Layer):
+ """
+ Construct the CLS token, position and patch embeddings.
+
+ """
+
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.patch_embeddings = TFViTMAEPatchEmbeddings(config, name="patch_embeddings")
+ self.num_patches = self.patch_embeddings.num_patches
+
+ self.config = config
+
+ def build(self, input_shape=None):
+ self.cls_token = self.add_weight(
+ shape=(1, 1, self.config.hidden_size),
+ initializer=tf.random_normal_initializer(stddev=self.config.initializer_range),
+ trainable=True,
+ name="cls_token",
+ )
+ self.position_embeddings = self.add_weight(
+ shape=(1, self.num_patches + 1, self.config.hidden_size),
+ initializer="zeros",
+ trainable=False, # fixed sin-cos embedding
+ name="position_embeddings",
+ )
+ pos_embed = get_2d_sincos_pos_embed(
+ self.position_embeddings.shape[-1],
+ int(self.patch_embeddings.num_patches**0.5),
+ add_cls_token=True,
+ )[None, ...]
+ self.position_embeddings.assign(pos_embed)
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "patch_embeddings", None) is not None:
+ with tf.name_scope(self.patch_embeddings.name):
+ self.patch_embeddings.build(None)
+
+ def interpolate_pos_encoding(self, embeddings, height, width) -> tf.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher
+ resolution images.
+
+ Source:
+ https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174
+ """
+
+ batch_size, seq_len, dim = shape_list(embeddings)
+ num_patches = seq_len - 1
+
+ _, num_positions, _ = shape_list(self.position_embeddings)
+ num_positions -= 1
+
+ if num_patches == num_positions and height == width:
+ return self.position_embeddings
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+ h0 = height // self.config.patch_size
+ w0 = width // self.config.patch_size
+ patch_pos_embed = tf.image.resize(
+ images=tf.reshape(
+ patch_pos_embed, shape=(1, int(math.sqrt(num_positions)), int(math.sqrt(num_positions)), dim)
+ ),
+ size=(h0, w0),
+ method="bicubic",
+ )
+
+ patch_pos_embed = tf.reshape(tensor=patch_pos_embed, shape=(1, -1, dim))
+ return tf.concat(values=(class_pos_embed, patch_pos_embed), axis=1)
+
+ def random_masking(self, sequence: tf.Tensor, noise: tf.Tensor | None = None):
+ """
+ Perform per-sample random masking by per-sample shuffling. Per-sample shuffling is done by argsort random
+ noise.
+
+ Args:
+ sequence (`tf.Tensor` of shape `(batch_size, sequence_length, dim)`)
+ noise (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*) which is
+ mainly used for testing purposes to control randomness and maintain the reproducibility
+ """
+ batch_size, seq_length, dim = shape_list(sequence)
+ len_keep = int(seq_length * (1 - self.config.mask_ratio))
+
+ if noise is None:
+ noise = tf.random.uniform(shape=(batch_size, seq_length), minval=0.0, maxval=1.0) # noise in [0, 1)
+
+ # sort noise for each sample
+ ids_shuffle = tf.argsort(noise, axis=1) # ascend: small is keep, large is remove
+ ids_restore = tf.argsort(ids_shuffle, axis=1)
+
+ # keep the first subset
+ ids_keep = ids_shuffle[:, :len_keep]
+ sequence_unmasked = tf.gather(
+ sequence,
+ axis=1,
+ batch_dims=1,
+ indices=ids_keep,
+ )
+
+ # generate the binary mask: 0 is keep, 1 is remove
+ # this hack is needed because TF's EagerTensors don't support
+ # assignment
+ mask_keep = tf.zeros((batch_size, len_keep))
+ mask_remove = tf.ones((batch_size, seq_length - len_keep))
+ mask = tf.concat([mask_keep, mask_remove], axis=-1)
+
+ # unshuffle to get the binary mask
+ mask = tf.gather(mask, axis=1, batch_dims=1, indices=ids_restore)
+
+ return sequence_unmasked, mask, ids_restore
+
+ def call(
+ self, pixel_values: tf.Tensor, noise: tf.Tensor | None = None, interpolate_pos_encoding: bool = False
+ ) -> tf.Tensor:
+ batch_size, num_channels, height, width = shape_list(pixel_values)
+ embeddings = self.patch_embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+ if interpolate_pos_encoding:
+ position_embeddings = self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ position_embeddings = self.position_embeddings
+ # add position embeddings w/o cls token
+ embeddings = embeddings + position_embeddings[:, 1:, :]
+
+ # masking: length -> length * config.mask_ratio
+ embeddings, mask, ids_restore = self.random_masking(embeddings, noise)
+
+ # append cls token
+ cls_token = self.cls_token + position_embeddings[:, :1, :]
+ cls_tokens = tf.tile(cls_token, (shape_list(embeddings)[0], 1, 1))
+ embeddings = tf.concat([cls_tokens, embeddings], axis=1)
+
+ return embeddings, mask, ids_restore
+
+
+class TFViTMAEPatchEmbeddings(keras.layers.Layer):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_patches = num_patches
+ self.num_channels = num_channels
+ self.config = config
+
+ self.projection = keras.layers.Conv2D(
+ filters=hidden_size,
+ kernel_size=patch_size,
+ strides=patch_size,
+ padding="valid",
+ data_format="channels_last",
+ kernel_initializer="glorot_uniform", # following torch.nn.Linear
+ bias_initializer="zeros",
+ name="projection",
+ )
+
+ def call(
+ self, pixel_values: tf.Tensor, training: bool = False, interpolate_pos_encoding: bool = False
+ ) -> tf.Tensor:
+ batch_size, num_channels, height, width = shape_list(pixel_values)
+ if tf.executing_eagerly():
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the"
+ " configuration."
+ )
+ if not interpolate_pos_encoding and (height != self.image_size[0] or width != self.image_size[1]):
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model"
+ f" ({self.image_size[0]}*{self.image_size[1]})."
+ )
+
+ # When running on CPU, `keras.layers.Conv2D` doesn't support `NCHW` format.
+ # So change the input format from `NCHW` to `NHWC`.
+ # shape = (batch_size, in_height, in_width, in_channels=num_channels)
+ pixel_values = tf.transpose(pixel_values, perm=(0, 2, 3, 1))
+
+ projection = self.projection(pixel_values)
+
+ # Change the 2D spatial dimensions to a single temporal dimension.
+ # shape = (batch_size, num_patches, out_channels=embed_dim)
+ num_patches = (width // self.patch_size[1]) * (height // self.patch_size[0])
+ x = tf.reshape(tensor=projection, shape=(batch_size, num_patches, -1))
+
+ return x
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "projection", None) is not None:
+ with tf.name_scope(self.projection.name):
+ self.projection.build([None, None, None, self.num_channels])
+
+
+# Copied from transformers.models.vit.modeling_tf_vit.TFViTSelfAttention with ViT->ViTMAE
+class TFViTMAESelfAttention(keras.layers.Layer):
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ if config.hidden_size % config.num_attention_heads != 0:
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number "
+ f"of attention heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.sqrt_att_head_size = math.sqrt(self.attention_head_size)
+
+ self.query = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="query"
+ )
+ self.key = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="key"
+ )
+ self.value = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="value"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.attention_probs_dropout_prob)
+ self.config = config
+
+ def transpose_for_scores(self, tensor: tf.Tensor, batch_size: int) -> tf.Tensor:
+ # Reshape from [batch_size, seq_length, all_head_size] to [batch_size, seq_length, num_attention_heads, attention_head_size]
+ tensor = tf.reshape(tensor=tensor, shape=(batch_size, -1, self.num_attention_heads, self.attention_head_size))
+
+ # Transpose the tensor from [batch_size, seq_length, num_attention_heads, attention_head_size] to [batch_size, num_attention_heads, seq_length, attention_head_size]
+ return tf.transpose(tensor, perm=[0, 2, 1, 3])
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ batch_size = shape_list(hidden_states)[0]
+ mixed_query_layer = self.query(inputs=hidden_states)
+ mixed_key_layer = self.key(inputs=hidden_states)
+ mixed_value_layer = self.value(inputs=hidden_states)
+ query_layer = self.transpose_for_scores(mixed_query_layer, batch_size)
+ key_layer = self.transpose_for_scores(mixed_key_layer, batch_size)
+ value_layer = self.transpose_for_scores(mixed_value_layer, batch_size)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ # (batch size, num_heads, seq_len_q, seq_len_k)
+ attention_scores = tf.matmul(query_layer, key_layer, transpose_b=True)
+ dk = tf.cast(self.sqrt_att_head_size, dtype=attention_scores.dtype)
+ attention_scores = tf.divide(attention_scores, dk)
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = stable_softmax(logits=attention_scores, axis=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(inputs=attention_probs, training=training)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = tf.multiply(attention_probs, head_mask)
+
+ attention_output = tf.matmul(attention_probs, value_layer)
+ attention_output = tf.transpose(attention_output, perm=[0, 2, 1, 3])
+
+ # (batch_size, seq_len_q, all_head_size)
+ attention_output = tf.reshape(tensor=attention_output, shape=(batch_size, -1, self.all_head_size))
+ outputs = (attention_output, attention_probs) if output_attentions else (attention_output,)
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "query", None) is not None:
+ with tf.name_scope(self.query.name):
+ self.query.build([None, None, self.config.hidden_size])
+ if getattr(self, "key", None) is not None:
+ with tf.name_scope(self.key.name):
+ self.key.build([None, None, self.config.hidden_size])
+ if getattr(self, "value", None) is not None:
+ with tf.name_scope(self.value.name):
+ self.value.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.vit.modeling_tf_vit.TFViTSelfOutput with ViT->ViTMAE
+class TFViTMAESelfOutput(keras.layers.Layer):
+ """
+ The residual connection is defined in TFViTMAELayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.vit.modeling_tf_vit.TFViTAttention with ViT->ViTMAE
+class TFViTMAEAttention(keras.layers.Layer):
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.self_attention = TFViTMAESelfAttention(config, name="attention")
+ self.dense_output = TFViTMAESelfOutput(config, name="output")
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ def call(
+ self,
+ input_tensor: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ self_outputs = self.self_attention(
+ hidden_states=input_tensor, head_mask=head_mask, output_attentions=output_attentions, training=training
+ )
+ attention_output = self.dense_output(
+ hidden_states=self_outputs[0], input_tensor=input_tensor, training=training
+ )
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attention", None) is not None:
+ with tf.name_scope(self.self_attention.name):
+ self.self_attention.build(None)
+ if getattr(self, "dense_output", None) is not None:
+ with tf.name_scope(self.dense_output.name):
+ self.dense_output.build(None)
+
+
+# Copied from transformers.models.vit.modeling_tf_vit.TFViTIntermediate with ViT->ViTMAE
+class TFViTMAEIntermediate(keras.layers.Layer):
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.intermediate_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = get_tf_activation(config.hidden_act)
+ else:
+ self.intermediate_act_fn = config.hidden_act
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.vit.modeling_tf_vit.TFViTOutput with ViT->ViTMAE
+class TFViTMAEOutput(keras.layers.Layer):
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+ hidden_states = hidden_states + input_tensor
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.intermediate_size])
+
+
+# Copied from transformers.models.vit.modeling_tf_vit.TFViTLayer with ViT->ViTMAE
+class TFViTMAELayer(keras.layers.Layer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.attention = TFViTMAEAttention(config, name="attention")
+ self.intermediate = TFViTMAEIntermediate(config, name="intermediate")
+ self.vit_output = TFViTMAEOutput(config, name="output")
+
+ self.layernorm_before = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm_before")
+ self.layernorm_after = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm_after")
+ self.config = config
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ attention_outputs = self.attention(
+ # in ViTMAE, layernorm is applied before self-attention
+ input_tensor=self.layernorm_before(inputs=hidden_states),
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = attention_outputs[0]
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in ViTMAE, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(inputs=hidden_states)
+
+ intermediate_output = self.intermediate(hidden_states=layer_output)
+
+ # second residual connection is done here
+ layer_output = self.vit_output(
+ hidden_states=intermediate_output, input_tensor=hidden_states, training=training
+ )
+ outputs = (layer_output,) + attention_outputs[1:] # add attentions if we output them
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "attention", None) is not None:
+ with tf.name_scope(self.attention.name):
+ self.attention.build(None)
+ if getattr(self, "intermediate", None) is not None:
+ with tf.name_scope(self.intermediate.name):
+ self.intermediate.build(None)
+ if getattr(self, "vit_output", None) is not None:
+ with tf.name_scope(self.vit_output.name):
+ self.vit_output.build(None)
+ if getattr(self, "layernorm_before", None) is not None:
+ with tf.name_scope(self.layernorm_before.name):
+ self.layernorm_before.build([None, None, self.config.hidden_size])
+ if getattr(self, "layernorm_after", None) is not None:
+ with tf.name_scope(self.layernorm_after.name):
+ self.layernorm_after.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.vit.modeling_tf_vit.TFViTEncoder with ViT->ViTMAE
+class TFViTMAEEncoder(keras.layers.Layer):
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.layer = [TFViTMAELayer(config, name=f"layer_._{i}") for i in range(config.num_hidden_layers)]
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ head_mask: tf.Tensor,
+ output_attentions: bool,
+ output_hidden_states: bool,
+ return_dict: bool,
+ training: bool = False,
+ ) -> TFBaseModelOutput | tuple[tf.Tensor]:
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states=hidden_states,
+ head_mask=head_mask[i],
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_attentions] if v is not None)
+
+ return TFBaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_attentions
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer", None) is not None:
+ for layer in self.layer:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@keras_serializable
+class TFViTMAEMainLayer(keras.layers.Layer):
+ config_class = ViTMAEConfig
+
+ def __init__(self, config: ViTMAEConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+
+ self.embeddings = TFViTMAEEmbeddings(config, name="embeddings")
+ self.encoder = TFViTMAEEncoder(config, name="encoder")
+ self.layernorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layernorm")
+
+ def get_input_embeddings(self) -> keras.layers.Layer:
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ raise NotImplementedError
+
+ @unpack_inputs
+ def call(
+ self,
+ pixel_values: TFModelInputType | None = None,
+ noise: tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ interpolate_pos_encoding: bool = False,
+ ) -> TFViTMAEModelOutput | tuple[tf.Tensor]:
+ embedding_output, mask, ids_restore = self.embeddings(
+ pixel_values=pixel_values,
+ training=training,
+ noise=noise,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ if head_mask is not None:
+ raise NotImplementedError
+ else:
+ head_mask = [None] * self.config.num_hidden_layers
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = encoder_outputs[0]
+ sequence_output = self.layernorm(inputs=sequence_output)
+
+ if not return_dict:
+ return (sequence_output, mask, ids_restore) + encoder_outputs[1:]
+
+ return TFViTMAEModelOutput(
+ last_hidden_state=sequence_output,
+ mask=mask,
+ ids_restore=ids_restore,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "embeddings", None) is not None:
+ with tf.name_scope(self.embeddings.name):
+ self.embeddings.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "layernorm", None) is not None:
+ with tf.name_scope(self.layernorm.name):
+ self.layernorm.build([None, None, self.config.hidden_size])
+
+
+class TFViTMAEPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = ViTMAEConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+
+
+VIT_MAE_START_DOCSTRING = r"""
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `pixel_values` only and nothing else: `model(pixel_values)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([pixel_values, attention_mask])` or `model([pixel_values, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"pixel_values": pixel_values, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Args:
+ config ([`ViTMAEConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~TFPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+VIT_MAE_INPUTS_DOCSTRING = r"""
+ Args:
+ pixel_values (`np.ndarray`, `tf.Tensor`, `list[tf.Tensor]` ``dict[str, tf.Tensor]` or `dict[str, np.ndarray]` and each example must have the shape `(batch_size, num_channels, height, width)`):
+ Pixel values. Pixel values can be obtained using [`AutoImageProcessor`]. See [`ViTImageProcessor.__call__`]
+ for details.
+
+ head_mask (`np.ndarray` or `tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~file_utils.ModelOutput`] instead of a plain tuple. This argument can be used
+ in eager mode, in graph mode the value will always be set to True.
+
+ training (`bool`, *optional*, defaults to `False``):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+
+ interpolate_pos_encoding (`bool`, *optional*, defaults to `False`):
+ Whether to interpolate the position encodings at the encoder and decoder.
+"""
+
+
+@add_start_docstrings(
+ "The bare ViTMAE Model transformer outputting raw hidden-states without any specific head on top.",
+ VIT_MAE_START_DOCSTRING,
+)
+class TFViTMAEModel(TFViTMAEPreTrainedModel):
+ def __init__(self, config: ViTMAEConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.vit = TFViTMAEMainLayer(config, name="vit")
+
+ def get_input_embeddings(self):
+ return self.vit.get_input_embeddings()
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(VIT_MAE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFViTMAEModelOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ pixel_values: TFModelInputType | None = None,
+ noise: tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ interpolate_pos_encoding: bool = False,
+ ) -> TFViTMAEModelOutput | tuple[tf.Tensor]:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, TFViTMAEModel
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("facebook/vit-mae-base")
+ >>> model = TFViTMAEModel.from_pretrained("facebook/vit-mae-base")
+
+ >>> inputs = image_processor(images=image, return_tensors="tf")
+ >>> outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+ outputs = self.vit(
+ pixel_values=pixel_values,
+ noise=noise,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "vit", None) is not None:
+ with tf.name_scope(self.vit.name):
+ self.vit.build(None)
+
+
+class TFViTMAEDecoder(keras.layers.Layer):
+ def __init__(self, config, num_patches, **kwargs):
+ super().__init__(**kwargs)
+ self.decoder_embed = keras.layers.Dense(config.decoder_hidden_size, name="decoder_embed")
+
+ decoder_config = deepcopy(config)
+ decoder_config.hidden_size = config.decoder_hidden_size
+ decoder_config.num_hidden_layers = config.decoder_num_hidden_layers
+ decoder_config.num_attention_heads = config.decoder_num_attention_heads
+ decoder_config.intermediate_size = config.decoder_intermediate_size
+ self.decoder_layers = [
+ TFViTMAELayer(decoder_config, name=f"decoder_layers.{j}") for j in range(config.decoder_num_hidden_layers)
+ ]
+
+ self.decoder_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="decoder_norm")
+ self.decoder_pred = keras.layers.Dense(
+ config.patch_size**2 * config.num_channels,
+ kernel_initializer=get_initializer(config.initializer_range),
+ name="decoder_pred",
+ ) # encoder to decoder
+ self.config = config
+ self.num_patches = num_patches
+
+ def build(self, input_shape=None):
+ self.mask_token = self.add_weight(
+ shape=(1, 1, self.config.decoder_hidden_size),
+ initializer=tf.random_normal_initializer(stddev=self.config.initializer_range),
+ trainable=True,
+ name="mask_token",
+ )
+ self.decoder_pos_embed = self.add_weight(
+ shape=(1, self.num_patches + 1, self.config.decoder_hidden_size),
+ initializer="zeros",
+ trainable=False,
+ name="decoder_pos_embed",
+ )
+ decoder_pos_embed = get_2d_sincos_pos_embed(
+ self.decoder_pos_embed.shape[-1],
+ int(self.num_patches**0.5),
+ add_cls_token=True,
+ )[None, ...]
+ self.decoder_pos_embed.assign(decoder_pos_embed)
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "decoder_embed", None) is not None:
+ with tf.name_scope(self.decoder_embed.name):
+ self.decoder_embed.build([None, None, self.config.hidden_size])
+ if getattr(self, "decoder_norm", None) is not None:
+ with tf.name_scope(self.decoder_norm.name):
+ self.decoder_norm.build([None, None, self.config.decoder_hidden_size])
+ if getattr(self, "decoder_pred", None) is not None:
+ with tf.name_scope(self.decoder_pred.name):
+ self.decoder_pred.build([None, None, self.config.decoder_hidden_size])
+ if getattr(self, "decoder_layers", None) is not None:
+ for layer in self.decoder_layers:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+ def interpolate_pos_encoding(self, embeddings) -> tf.Tensor:
+ """
+ This method is a modified version of the interpolation function for ViT-mae model at the decoder, that
+ allows to interpolate the pre-trained decoder position encodings, to be able to use the model on higher
+ resolution images.
+
+ Source:
+ https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174
+ """
+
+ # [batch_size, num_patches + 1, hidden_size]
+ _, num_positions, dim = shape_list(self.decoder_pos_embed)
+
+ # -1 removes the class dimension since we later append it without interpolation
+ seq_len = shape_list(embeddings)[1] - 1
+ num_positions = num_positions - 1
+
+ # Separation of class token and patch tokens
+ class_pos_embed = self.decoder_pos_embed[:, :1, :]
+ patch_pos_embed = self.decoder_pos_embed[:, 1:, :]
+
+ # interpolate the position embeddings
+ patch_pos_embed = tf.image.resize(
+ images=tf.reshape(patch_pos_embed, shape=(1, 1, -1, dim)),
+ size=(1, seq_len),
+ method="bicubic",
+ )
+
+ # [1, seq_len, hidden_size]
+ patch_pos_embed = tf.reshape(tensor=patch_pos_embed, shape=(1, -1, dim))
+ # Adding the class token back
+ return tf.concat(values=(class_pos_embed, patch_pos_embed), axis=1)
+
+ def call(
+ self,
+ hidden_states,
+ ids_restore,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ interpolate_pos_encoding=False,
+ ):
+ # embed tokens
+ x = self.decoder_embed(hidden_states)
+ # append mask tokens to sequence
+ mask_tokens = tf.tile(
+ self.mask_token,
+ (shape_list(x)[0], shape_list(ids_restore)[1] + 1 - shape_list(x)[1], 1),
+ )
+ x_ = tf.concat([x[:, 1:, :], mask_tokens], axis=1) # no cls token
+ x_ = tf.gather(x_, axis=1, batch_dims=1, indices=ids_restore) # unshuffle
+ x = tf.concat([x[:, :1, :], x_], axis=1) # append cls token
+ if interpolate_pos_encoding:
+ decoder_pos_embed = self.interpolate_pos_encoding(x)
+ else:
+ decoder_pos_embed = self.decoder_pos_embed
+ # add pos embed
+ hidden_states = x + decoder_pos_embed
+ # apply Transformer layers (blocks)
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+ for i, layer_module in enumerate(self.decoder_layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(
+ hidden_states,
+ head_mask=None,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ hidden_states = self.decoder_norm(hidden_states)
+
+ # predictor projection
+ logits = self.decoder_pred(hidden_states)
+
+ # remove cls token
+ logits = logits[:, 1:, :]
+
+ if not return_dict:
+ return tuple(v for v in [logits, all_hidden_states, all_self_attentions] if v is not None)
+ return TFViTMAEDecoderOutput(logits=logits, hidden_states=all_hidden_states, attentions=all_self_attentions)
+
+
+@add_start_docstrings(
+ "The ViTMAE Model transformer with the decoder on top for self-supervised pre-training.",
+ VIT_MAE_START_DOCSTRING,
+)
+class TFViTMAEForPreTraining(TFViTMAEPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.vit = TFViTMAEMainLayer(config, name="vit")
+ self.decoder = TFViTMAEDecoder(
+ config,
+ num_patches=self.vit.embeddings.num_patches,
+ name="decoder",
+ )
+
+ def get_input_embeddings(self):
+ return self.vit.get_input_embeddings()
+
+ def _prune_heads(self, heads_to_prune):
+ raise NotImplementedError
+
+ def patchify(self, pixel_values, interpolate_pos_encoding: bool = False):
+ """
+ Args:
+ pixel_values (`tf.Tensor` of shape `(batch_size, height, width, num_channels)` or `(batch_size, num_channels, height, width)`):
+ Pixel values.
+ interpolate_pos_encoding (`bool`, default `False`):
+ interpolation flag passed during the forward pass.
+
+ Returns:
+ `tf.Tensor` of shape `(batch_size, num_patches, patch_size**2 * num_channels)`:
+ Patchified pixel values.
+ """
+ patch_size, num_channels = self.config.patch_size, self.config.num_channels
+ # make sure channels are last
+ if shape_list(pixel_values)[1] == num_channels:
+ pixel_values = tf.transpose(pixel_values, perm=(0, 2, 3, 1))
+
+ # sanity checks
+ if not interpolate_pos_encoding:
+ tf.debugging.assert_equal(
+ shape_list(pixel_values)[1],
+ shape_list(pixel_values)[2],
+ message="Make sure the pixel values have a squared size",
+ )
+ tf.debugging.assert_equal(
+ shape_list(pixel_values)[1] % patch_size,
+ 0,
+ message="Make sure the pixel values have a size that is divisible by the patch size",
+ )
+ tf.debugging.assert_equal(
+ shape_list(pixel_values)[3],
+ num_channels,
+ message=(
+ "Make sure the number of channels of the pixel values is equal to the one set in the configuration"
+ ),
+ )
+
+ # patchify
+ batch_size = shape_list(pixel_values)[0]
+ num_patches_h = shape_list(pixel_values)[1] // patch_size
+ num_patches_w = shape_list(pixel_values)[2] // patch_size
+ patchified_pixel_values = tf.reshape(
+ pixel_values,
+ (batch_size, num_patches_h, patch_size, num_patches_w, patch_size, num_channels),
+ )
+ patchified_pixel_values = tf.einsum("nhpwqc->nhwpqc", patchified_pixel_values)
+ patchified_pixel_values = tf.reshape(
+ patchified_pixel_values,
+ (batch_size, num_patches_h * num_patches_w, patch_size**2 * num_channels),
+ )
+ return patchified_pixel_values
+
+ def unpatchify(self, patchified_pixel_values, original_image_size: tuple[int, int] | None = None):
+ """
+ Args:
+ patchified_pixel_values (`tf.Tensor` of shape `(batch_size, num_patches, patch_size**2 * num_channels)`:
+ Patchified pixel values.
+ original_image_size (`tuple[int, int]`, *optional*):
+ Original image size.
+
+ Returns:
+ `tf.Tensor` of shape `(batch_size, height, width, num_channels)`:
+ Pixel values.
+ """
+ patch_size, num_channels = self.config.patch_size, self.config.num_channels
+ original_image_size = (
+ original_image_size
+ if original_image_size is not None
+ else (self.config.image_size, self.config.image_size)
+ )
+ original_height, original_width = original_image_size
+ num_patches_h = original_height // patch_size
+ num_patches_w = original_width // patch_size
+ # sanity check
+ tf.debugging.assert_equal(
+ num_patches_h * num_patches_w,
+ shape_list(patchified_pixel_values)[1],
+ message=f"The number of patches in the patchified pixel values is {shape_list(patchified_pixel_values)[1]} does not match the patches of original image {num_patches_w}*{num_patches_h}",
+ )
+
+ # unpatchify
+ batch_size = shape_list(patchified_pixel_values)[0]
+ patchified_pixel_values = tf.reshape(
+ patchified_pixel_values,
+ (batch_size, num_patches_h, num_patches_w, patch_size, patch_size, num_channels),
+ )
+ patchified_pixel_values = tf.einsum("nhwpqc->nhpwqc", patchified_pixel_values)
+ pixel_values = tf.reshape(
+ patchified_pixel_values,
+ (batch_size, num_patches_h * patch_size, num_patches_w * patch_size, num_channels),
+ )
+ return pixel_values
+
+ def forward_loss(self, pixel_values, pred, mask, interpolate_pos_encoding: bool = False):
+ """
+ Args:
+ pixel_values (`tf.Tensor` of shape `(batch_size, height, width, num_channels)`):
+ Pixel values.
+ pred (`tf.Tensor` of shape `(batch_size, num_patches, patch_size**2 * num_channels)`:
+ Predicted pixel values.
+ mask (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Tensor indicating which patches are masked (1) and which are not (0).
+ interpolate_pos_encoding (`bool`, *optional*, default `False`):
+ interpolation flag passed during the forward pass.
+
+ Returns:
+ `tf.Tensor`: Pixel reconstruction loss.
+ """
+ target = self.patchify(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+ if self.config.norm_pix_loss:
+ mean = tf.reduce_mean(target, axis=-1, keepdims=True)
+ var = tf.math.reduce_variance(target, axis=-1, keepdims=True)
+ target = (target - mean) / (var + 1.0e-6) ** 0.5
+
+ loss = (pred - target) ** 2
+ loss = tf.reduce_mean(loss, axis=-1) # [batch_size, num_patches], mean loss per patch
+
+ loss = tf.reduce_sum(loss * mask) / tf.reduce_sum(mask) # mean loss on removed patches
+ loss = tf.reshape(loss, (1,))
+ return loss
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(VIT_MAE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFViTMAEForPreTrainingOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ pixel_values: TFModelInputType | None = None,
+ noise: tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ interpolate_pos_encoding: bool = False,
+ ) -> TFViTMAEForPreTrainingOutput | tuple[tf.Tensor]:
+ r"""
+ Returns:
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, TFViTMAEForPreTraining
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("facebook/vit-mae-base")
+ >>> model = TFViTMAEForPreTraining.from_pretrained("facebook/vit-mae-base")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> loss = outputs.loss
+ >>> mask = outputs.mask
+ >>> ids_restore = outputs.ids_restore
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.vit(
+ pixel_values=pixel_values,
+ noise=noise,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ )
+
+ latent = outputs.last_hidden_state
+ ids_restore = outputs.ids_restore
+ mask = outputs.mask
+
+ # [batch_size, num_patches, patch_size**2*3]
+ decoder_outputs = self.decoder(latent, ids_restore, interpolate_pos_encoding=interpolate_pos_encoding)
+ logits = decoder_outputs.logits
+
+ loss = self.forward_loss(pixel_values, logits, mask, interpolate_pos_encoding=interpolate_pos_encoding)
+
+ if not return_dict:
+ output = (logits, mask, ids_restore) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFViTMAEForPreTrainingOutput(
+ loss=loss,
+ logits=logits,
+ mask=mask,
+ ids_restore=ids_restore,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "vit", None) is not None:
+ with tf.name_scope(self.vit.name):
+ self.vit.build(None)
+ if getattr(self, "decoder", None) is not None:
+ with tf.name_scope(self.decoder.name):
+ self.decoder.build(None)
+
+
+__all__ = ["TFViTMAEForPreTraining", "TFViTMAEModel", "TFViTMAEPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/modeling_vit_mae.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/modeling_vit_mae.py
new file mode 100644
index 0000000000000000000000000000000000000000..8b4b9efafeb5b0331d29af926954a31c5ca8f54f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_mae/modeling_vit_mae.py
@@ -0,0 +1,969 @@
+# coding=utf-8
+# Copyright 2022 Facebook AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ViT MAE (masked autoencoder) model."""
+
+import collections.abc
+from copy import deepcopy
+from dataclasses import dataclass
+from typing import Callable, Optional
+
+import numpy as np
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import ModelOutput, TransformersKwargs, auto_docstring, logging, torch_int
+from ...utils.generic import can_return_tuple, check_model_inputs
+from .configuration_vit_mae import ViTMAEConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for ViTMAEModel's outputs, with potential hidden states and attentions.
+ """
+)
+class ViTMAEModelOutput(ModelOutput):
+ r"""
+ mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Tensor indicating which patches are masked (1) and which are not (0).
+ ids_restore (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Tensor containing the original index of the (shuffled) masked patches.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ mask: Optional[torch.LongTensor] = None
+ ids_restore: Optional[torch.LongTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for ViTMAEDecoder's outputs, with potential hidden states and attentions.
+ """
+)
+class ViTMAEDecoderOutput(ModelOutput):
+ r"""
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, patch_size ** 2 * num_channels)`):
+ Pixel reconstruction logits.
+ """
+
+ logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for ViTMAEForPreTraining's outputs, with potential hidden states and attentions.
+ """
+)
+class ViTMAEForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`):
+ Pixel reconstruction loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, patch_size ** 2 * num_channels)`):
+ Pixel reconstruction logits.
+ mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Tensor indicating which patches are masked (1) and which are not (0).
+ ids_restore (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Tensor containing the original index of the (shuffled) masked patches.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ mask: Optional[torch.LongTensor] = None
+ ids_restore: Optional[torch.LongTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+def get_2d_sincos_pos_embed(embed_dim, grid_size, add_cls_token=False):
+ """
+ Create 2D sin/cos positional embeddings.
+
+ Args:
+ embed_dim (`int`):
+ Embedding dimension.
+ grid_size (`int`):
+ The grid height and width.
+ add_cls_token (`bool`, *optional*, defaults to `False`):
+ Whether or not to add a classification (CLS) token.
+
+ Returns:
+ (`torch.FloatTensor` of shape (grid_size*grid_size, embed_dim) or (1+grid_size*grid_size, embed_dim): the
+ position embeddings (with or without classification token)
+ """
+ grid_h = np.arange(grid_size, dtype=np.float32)
+ grid_w = np.arange(grid_size, dtype=np.float32)
+ grid = np.meshgrid(grid_w, grid_h) # here w goes first
+ grid = np.stack(grid, axis=0)
+
+ grid = grid.reshape([2, 1, grid_size, grid_size])
+ pos_embed = get_2d_sincos_pos_embed_from_grid(embed_dim, grid)
+ if add_cls_token:
+ pos_embed = np.concatenate([np.zeros([1, embed_dim]), pos_embed], axis=0)
+ return pos_embed
+
+
+def get_2d_sincos_pos_embed_from_grid(embed_dim, grid):
+ if embed_dim % 2 != 0:
+ raise ValueError("embed_dim must be even")
+
+ # use half of dimensions to encode grid_h
+ emb_h = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[0]) # (H*W, D/2)
+ emb_w = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[1]) # (H*W, D/2)
+
+ emb = np.concatenate([emb_h, emb_w], axis=1) # (H*W, D)
+ return emb
+
+
+def get_1d_sincos_pos_embed_from_grid(embed_dim, pos):
+ """
+ embed_dim: output dimension for each position pos: a list of positions to be encoded: size (M,) out: (M, D)
+ """
+ if embed_dim % 2 != 0:
+ raise ValueError("embed_dim must be even")
+
+ omega = np.arange(embed_dim // 2, dtype=float)
+ omega /= embed_dim / 2.0
+ omega = 1.0 / 10000**omega # (D/2,)
+
+ pos = pos.reshape(-1) # (M,)
+ out = np.einsum("m,d->md", pos, omega) # (M, D/2), outer product
+
+ emb_sin = np.sin(out) # (M, D/2)
+ emb_cos = np.cos(out) # (M, D/2)
+
+ emb = np.concatenate([emb_sin, emb_cos], axis=1) # (M, D)
+ return emb
+
+
+class ViTMAEEmbeddings(nn.Module):
+ """
+ Construct the CLS token, position and patch embeddings.
+
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, config.hidden_size))
+ self.patch_embeddings = ViTMAEPatchEmbeddings(config)
+ self.num_patches = self.patch_embeddings.num_patches
+ # fixed sin-cos embedding
+ self.position_embeddings = nn.Parameter(
+ torch.zeros(1, self.num_patches + 1, config.hidden_size), requires_grad=False
+ )
+ self.patch_size = config.patch_size
+ self.config = config
+
+ def initialize_weights(self):
+ # initialize (and freeze) position embeddings by sin-cos embedding
+ pos_embed = get_2d_sincos_pos_embed(
+ self.position_embeddings.shape[-1], int(self.patch_embeddings.num_patches**0.5), add_cls_token=True
+ )
+ self.position_embeddings.data.copy_(torch.from_numpy(pos_embed).float().unsqueeze(0))
+
+ # initialize patch_embeddings like nn.Linear (instead of nn.Conv2d)
+ w = self.patch_embeddings.projection.weight.data
+ torch.nn.init.xavier_uniform_(w.view([w.shape[0], -1]))
+
+ # timm's trunc_normal_(std=.02) is effectively normal_(std=0.02) as cutoff is too big (2.)
+ torch.nn.init.normal_(self.cls_token, std=self.config.initializer_range)
+
+ # Copied from transformers.models.vit.modeling_vit.ViTEmbeddings.interpolate_pos_encoding
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ num_positions = self.position_embeddings.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embeddings
+
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def random_masking(self, sequence, noise=None):
+ """
+ Perform per-sample random masking by per-sample shuffling. Per-sample shuffling is done by argsort random
+ noise.
+
+ Args:
+ sequence (`torch.LongTensor` of shape `(batch_size, sequence_length, dim)`)
+ noise (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*) which is
+ mainly used for testing purposes to control randomness and maintain the reproducibility
+ """
+ batch_size, seq_length, dim = sequence.shape
+ len_keep = int(seq_length * (1 - self.config.mask_ratio))
+
+ if noise is None:
+ noise = torch.rand(batch_size, seq_length, device=sequence.device) # noise in [0, 1]
+
+ # sort noise for each sample
+ ids_shuffle = torch.argsort(noise, dim=1).to(sequence.device) # ascend: small is keep, large is remove
+ ids_restore = torch.argsort(ids_shuffle, dim=1).to(sequence.device)
+
+ # keep the first subset
+ ids_keep = ids_shuffle[:, :len_keep]
+ sequence_unmasked = torch.gather(sequence, dim=1, index=ids_keep.unsqueeze(-1).repeat(1, 1, dim))
+
+ # generate the binary mask: 0 is keep, 1 is remove
+ mask = torch.ones([batch_size, seq_length], device=sequence.device)
+ mask[:, :len_keep] = 0
+ # unshuffle to get the binary mask
+ mask = torch.gather(mask, dim=1, index=ids_restore)
+
+ return sequence_unmasked, mask, ids_restore
+
+ def forward(self, pixel_values, noise=None, interpolate_pos_encoding: bool = False):
+ batch_size, num_channels, height, width = pixel_values.shape
+ embeddings = self.patch_embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+ if interpolate_pos_encoding:
+ position_embeddings = self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ position_embeddings = self.position_embeddings
+
+ # add position embeddings w/o cls token
+ embeddings = embeddings + position_embeddings[:, 1:, :]
+
+ # masking: length -> length * config.mask_ratio
+ embeddings, mask, ids_restore = self.random_masking(embeddings, noise)
+
+ # append cls token
+ cls_token = self.cls_token + position_embeddings[:, :1, :]
+ cls_tokens = cls_token.expand(embeddings.shape[0], -1, -1)
+ embeddings = torch.cat((cls_tokens, embeddings), dim=1)
+
+ return embeddings, mask, ids_restore
+
+
+class ViTMAEPatchEmbeddings(nn.Module):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def forward(self, pixel_values, interpolate_pos_encoding: bool = False):
+ batch_size, num_channels, height, width = pixel_values.shape
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ )
+
+ if not interpolate_pos_encoding and (height != self.image_size[0] or width != self.image_size[1]):
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})."
+ )
+ x = self.projection(pixel_values).flatten(2).transpose(1, 2)
+ return x
+
+
+# Copied from transformers.models.vit.modeling_vit.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfAttention ViT->ViTMAE
+class ViTMAESelfAttention(nn.Module):
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ def forward(
+ self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ batch_size = hidden_states.shape[0]
+ new_shape = batch_size, -1, self.num_attention_heads, self.attention_head_size
+
+ key_layer = self.key(hidden_states).view(*new_shape).transpose(1, 2)
+ value_layer = self.value(hidden_states).view(*new_shape).transpose(1, 2)
+ query_layer = self.query(hidden_states).view(*new_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.reshape(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfOutput with ViT->ViTMAE
+class ViTMAESelfOutput(nn.Module):
+ """
+ The residual connection is defined in ViTMAELayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTAttention with ViT->ViTMAE
+class ViTMAEAttention(nn.Module):
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__()
+ self.attention = ViTMAESelfAttention(config)
+ self.output = ViTMAESelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads: set[int]):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ self_attn_output, _ = self.attention(hidden_states, head_mask)
+ output = self.output(self_attn_output, hidden_states)
+ return output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTIntermediate ViT->ViTMAE
+class ViTMAEIntermediate(nn.Module):
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTOutput ViT->ViTMAE
+class ViTMAEOutput(nn.Module):
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTLayer with ViT->ViTMAE,VIT->VITMAE
+class ViTMAELayer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = ViTMAEAttention(config)
+ self.intermediate = ViTMAEIntermediate(config)
+ self.output = ViTMAEOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ hidden_states_norm = self.layernorm_before(hidden_states)
+ attention_output = self.attention(hidden_states_norm, head_mask)
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in ViTMAE, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+
+ # second residual connection is done here
+ layer_output = self.output(layer_output, hidden_states)
+
+ return layer_output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTEncoder with ViT->ViTMAE
+class ViTMAEEncoder(nn.Module):
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([ViTMAELayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> BaseModelOutput:
+ for i, layer_module in enumerate(self.layer):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ hidden_states = layer_module(hidden_states, layer_head_mask)
+
+ return BaseModelOutput(last_hidden_state=hidden_states)
+
+
+@auto_docstring
+class ViTMAEPreTrainedModel(PreTrainedModel):
+ config: ViTMAEConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": ViTMAELayer,
+ "attentions": ViTMAESelfAttention,
+ }
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, ViTMAEEmbeddings):
+ module.initialize_weights()
+ elif isinstance(module, ViTMAEDecoder):
+ module.mask_token.data.zero_()
+ module.decoder_pos_embed.data.zero_()
+
+
+@auto_docstring
+class ViTMAEModel(ViTMAEPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = ViTMAEEmbeddings(config)
+ self.encoder = ViTMAEEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ noise: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> ViTMAEModelOutput:
+ r"""
+ noise (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mainly used for testing purposes to control randomness and maintain the reproducibility
+ interpolate_pos_encoding (`bool`, *optional*, default `False`):
+ Whether to interpolate the pre-trained position encodings. This is mainly used to use the model on higher
+ resolution images.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, ViTMAEModel
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("facebook/vit-mae-base")
+ >>> model = ViTMAEModel.from_pretrained("facebook/vit-mae-base")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output, mask, ids_restore = self.embeddings(
+ pixel_values, noise=noise, interpolate_pos_encoding=interpolate_pos_encoding
+ )
+
+ encoder_outputs: BaseModelOutput = self.encoder(embedding_output, head_mask=head_mask)
+ sequence_output = encoder_outputs.last_hidden_state
+ sequence_output = self.layernorm(sequence_output)
+
+ return ViTMAEModelOutput(last_hidden_state=sequence_output, mask=mask, ids_restore=ids_restore)
+
+
+class ViTMAEDecoder(nn.Module):
+ def __init__(self, config: ViTMAEConfig, num_patches: int):
+ super().__init__()
+ self.decoder_embed = nn.Linear(config.hidden_size, config.decoder_hidden_size, bias=True)
+ self.mask_token = nn.Parameter(torch.zeros(1, 1, config.decoder_hidden_size))
+ self.decoder_pos_embed = nn.Parameter(
+ torch.zeros(1, num_patches + 1, config.decoder_hidden_size), requires_grad=False
+ ) # fixed sin-cos embedding
+
+ decoder_config = deepcopy(config)
+ decoder_config.hidden_size = config.decoder_hidden_size
+ decoder_config.num_hidden_layers = config.decoder_num_hidden_layers
+ decoder_config.num_attention_heads = config.decoder_num_attention_heads
+ decoder_config.intermediate_size = config.decoder_intermediate_size
+ self.decoder_layers = nn.ModuleList(
+ [ViTMAELayer(decoder_config) for _ in range(config.decoder_num_hidden_layers)]
+ )
+
+ self.decoder_norm = nn.LayerNorm(config.decoder_hidden_size, eps=config.layer_norm_eps)
+ self.decoder_pred = nn.Linear(
+ config.decoder_hidden_size, config.patch_size**2 * config.num_channels, bias=True
+ ) # encoder to decoder
+ self.gradient_checkpointing = False
+ self.config = decoder_config
+ self.initialize_weights(num_patches)
+
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor) -> torch.Tensor:
+ """
+ This method is a modified version of the interpolation function for ViT-mae model at the decoder, that
+ allows to interpolate the pre-trained decoder position encodings, to be able to use the model on higher
+ resolution images.
+
+ Adapted from:
+ https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174
+ """
+
+ # -1 removes the class dimension since we later append it without interpolation
+ embeddings_positions = embeddings.shape[1] - 1
+
+ # Separation of class token and patch tokens
+ class_pos_embed = self.decoder_pos_embed[:, :1]
+ patch_pos_embed = self.decoder_pos_embed[:, 1:]
+
+ # To retain the final 3d tensor with the required dimensions
+ dim = self.decoder_pos_embed.shape[-1]
+
+ # Increasing a dimension to enable bicubic interpolation
+ patch_pos_embed = patch_pos_embed.reshape(1, 1, -1, dim)
+
+ # permute to bring the dimension to be interpolated, to the last
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ # Interpolating the decoder position embeddings shape wrt embeddings shape i.e (x).
+ # we keep the second last dimension constant
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(patch_pos_embed.shape[-2], embeddings_positions),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ # Converting back to the original shape
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+ # Adding the class token back
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def initialize_weights(self, num_patches):
+ # initialize (and freeze) position embeddings by sin-cos embedding
+ decoder_pos_embed = get_2d_sincos_pos_embed(
+ self.decoder_pos_embed.shape[-1], int(num_patches**0.5), add_cls_token=True
+ )
+ self.decoder_pos_embed.data.copy_(torch.from_numpy(decoder_pos_embed).float().unsqueeze(0))
+
+ # timm's trunc_normal_(std=.02) is effectively normal_(std=0.02) as cutoff is too big (2.)
+ torch.nn.init.normal_(self.mask_token, std=self.config.initializer_range)
+
+ def forward(self, hidden_states: torch.Tensor, ids_restore: torch.Tensor, interpolate_pos_encoding: bool = False):
+ # Embed tokens
+ x = self.decoder_embed(hidden_states)
+
+ # Append mask tokens to sequence
+ mask_tokens = self.mask_token.repeat(x.shape[0], ids_restore.shape[1] + 1 - x.shape[1], 1)
+ x_ = torch.cat([x[:, 1:, :], mask_tokens], dim=1) # no cls token
+
+ # Unshuffle
+ x_ = torch.gather(x_, dim=1, index=ids_restore.unsqueeze(-1).repeat(1, 1, x.shape[2]).to(x_.device))
+ x = torch.cat([x[:, :1, :], x_], dim=1) # append cls token
+
+ # Add pos embed
+ if interpolate_pos_encoding:
+ decoder_pos_embed = self.interpolate_pos_encoding(x)
+ else:
+ decoder_pos_embed = self.decoder_pos_embed
+ hidden_states = x + decoder_pos_embed
+
+ # Apply Transformer layers (blocks)
+ for layer_module in self.decoder_layers:
+ hidden_states = layer_module(hidden_states, head_mask=None)
+
+ hidden_states = self.decoder_norm(hidden_states)
+
+ # Predictor projection
+ logits = self.decoder_pred(hidden_states)
+
+ # Remove cls token
+ logits = logits[:, 1:, :]
+
+ return ViTMAEDecoderOutput(logits=logits)
+
+
+@auto_docstring(
+ custom_intro="""
+ The ViTMAE Model transformer with the decoder on top for self-supervised pre-training.
+
+
+
+ Note that we provide a script to pre-train this model on custom data in our [examples
+ directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
+
+
+ """
+)
+class ViTMAEForPreTraining(ViTMAEPreTrainedModel):
+ def __init__(self, config: ViTMAEConfig):
+ super().__init__(config)
+ self.config = config
+
+ self.vit = ViTMAEModel(config)
+ self.decoder = ViTMAEDecoder(config, num_patches=self.vit.embeddings.num_patches)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.vit.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ def patchify(self, pixel_values, interpolate_pos_encoding: bool = False):
+ """
+ Args:
+ pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values.
+ interpolate_pos_encoding (`bool`, *optional*, default `False`):
+ interpolation flag passed during the forward pass.
+
+ Returns:
+ `torch.FloatTensor` of shape `(batch_size, num_patches, patch_size**2 * num_channels)`:
+ Patchified pixel values.
+ """
+ patch_size, num_channels = self.config.patch_size, self.config.num_channels
+ # sanity checks
+ if not interpolate_pos_encoding and (
+ pixel_values.shape[2] != pixel_values.shape[3] or pixel_values.shape[2] % patch_size != 0
+ ):
+ raise ValueError("Make sure the pixel values have a squared size that is divisible by the patch size")
+ if pixel_values.shape[1] != num_channels:
+ raise ValueError(
+ "Make sure the number of channels of the pixel values is equal to the one set in the configuration"
+ )
+
+ # patchify
+ batch_size = pixel_values.shape[0]
+ num_patches_h = pixel_values.shape[2] // patch_size
+ num_patches_w = pixel_values.shape[3] // patch_size
+ patchified_pixel_values = pixel_values.reshape(
+ batch_size, num_channels, num_patches_h, patch_size, num_patches_w, patch_size
+ )
+ patchified_pixel_values = torch.einsum("nchpwq->nhwpqc", patchified_pixel_values)
+ patchified_pixel_values = patchified_pixel_values.reshape(
+ batch_size, num_patches_h * num_patches_w, patch_size**2 * num_channels
+ )
+ return patchified_pixel_values
+
+ def unpatchify(self, patchified_pixel_values, original_image_size: Optional[tuple[int, int]] = None):
+ """
+ Args:
+ patchified_pixel_values (`torch.FloatTensor` of shape `(batch_size, num_patches, patch_size**2 * num_channels)`:
+ Patchified pixel values.
+ original_image_size (`tuple[int, int]`, *optional*):
+ Original image size.
+
+ Returns:
+ `torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`:
+ Pixel values.
+ """
+ patch_size, num_channels = self.config.patch_size, self.config.num_channels
+ original_image_size = (
+ original_image_size
+ if original_image_size is not None
+ else (self.config.image_size, self.config.image_size)
+ )
+ original_height, original_width = original_image_size
+ num_patches_h = original_height // patch_size
+ num_patches_w = original_width // patch_size
+ # sanity check
+ if num_patches_h * num_patches_w != patchified_pixel_values.shape[1]:
+ raise ValueError(
+ f"The number of patches in the patchified pixel values {patchified_pixel_values.shape[1]}, does not match the number of patches on original image {num_patches_h}*{num_patches_w}"
+ )
+
+ # unpatchify
+ batch_size = patchified_pixel_values.shape[0]
+ patchified_pixel_values = patchified_pixel_values.reshape(
+ batch_size,
+ num_patches_h,
+ num_patches_w,
+ patch_size,
+ patch_size,
+ num_channels,
+ )
+ patchified_pixel_values = torch.einsum("nhwpqc->nchpwq", patchified_pixel_values)
+ pixel_values = patchified_pixel_values.reshape(
+ batch_size,
+ num_channels,
+ num_patches_h * patch_size,
+ num_patches_w * patch_size,
+ )
+ return pixel_values
+
+ def forward_loss(self, pixel_values, pred, mask, interpolate_pos_encoding: bool = False):
+ """
+ Args:
+ pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ Pixel values.
+ pred (`torch.FloatTensor` of shape `(batch_size, num_patches, patch_size**2 * num_channels)`:
+ Predicted pixel values.
+ mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Tensor indicating which patches are masked (1) and which are not (0).
+ interpolate_pos_encoding (`bool`, *optional*, default `False`):
+ interpolation flag passed during the forward pass.
+
+ Returns:
+ `torch.FloatTensor`: Pixel reconstruction loss.
+ """
+ target = self.patchify(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+ if self.config.norm_pix_loss:
+ mean = target.mean(dim=-1, keepdim=True)
+ var = target.var(dim=-1, keepdim=True)
+ target = (target - mean) / (var + 1.0e-6) ** 0.5
+
+ loss = (pred - target) ** 2
+ loss = loss.mean(dim=-1) # [N, L], mean loss per patch
+ loss = (loss * mask).sum() / mask.sum() # mean loss on removed patches
+ return loss
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ noise: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> ViTMAEForPreTrainingOutput:
+ r"""
+ noise (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mainly used for testing purposes to control randomness and maintain the reproducibility
+ interpolate_pos_encoding (`bool`, *optional*, default `False`):
+ Whether to interpolate the pre-trained position encodings. This is mainly used to use the model on higher
+ resolution images.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, ViTMAEForPreTraining
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("facebook/vit-mae-base")
+ >>> model = ViTMAEForPreTraining.from_pretrained("facebook/vit-mae-base")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> loss = outputs.loss
+ >>> mask = outputs.mask
+ >>> ids_restore = outputs.ids_restore
+ ```"""
+
+ outputs: ViTMAEModelOutput = self.vit(
+ pixel_values, noise=noise, head_mask=head_mask, interpolate_pos_encoding=interpolate_pos_encoding, **kwargs
+ )
+
+ latent = outputs.last_hidden_state
+ ids_restore = outputs.ids_restore
+ mask = outputs.mask
+
+ decoder_outputs: ViTMAEDecoderOutput = self.decoder(
+ latent, ids_restore, interpolate_pos_encoding=interpolate_pos_encoding
+ )
+ logits = decoder_outputs.logits # shape (batch_size, num_patches, patch_size*patch_size*num_channels)
+
+ loss = self.forward_loss(pixel_values, logits, mask, interpolate_pos_encoding=interpolate_pos_encoding)
+
+ return ViTMAEForPreTrainingOutput(
+ loss=loss,
+ logits=logits,
+ mask=mask,
+ ids_restore=ids_restore,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["ViTMAEForPreTraining", "ViTMAELayer", "ViTMAEModel", "ViTMAEPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..547c5f4c04b912fe69a09470106c0d523df63931
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vit_msn import *
+ from .modeling_vit_msn import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/configuration_vit_msn.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/configuration_vit_msn.py
new file mode 100644
index 0000000000000000000000000000000000000000..cd47df3e9932e0a7e4fa1a9084976214fa9d2939
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/configuration_vit_msn.py
@@ -0,0 +1,115 @@
+# coding=utf-8
+# Copyright 2022 Facebook AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""ViT MSN model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class ViTMSNConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`ViTMSNModel`]. It is used to instantiate an ViT
+ MSN model according to the specified arguments, defining the model architecture. Instantiating a configuration with
+ the defaults will yield a similar configuration to that of the ViT
+ [facebook/vit_msn_base](https://huggingface.co/facebook/vit_msn_base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+
+ Example:
+
+ ```python
+ >>> from transformers import ViTMSNModel, ViTMSNConfig
+
+ >>> # Initializing a ViT MSN vit-msn-base style configuration
+ >>> configuration = ViTConfig()
+
+ >>> # Initializing a model from the vit-msn-base style configuration
+ >>> model = ViTMSNModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vit_msn"
+
+ def __init__(
+ self,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-06,
+ image_size=224,
+ patch_size=16,
+ num_channels=3,
+ qkv_bias=True,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+
+
+__all__ = ["ViTMSNConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/modeling_vit_msn.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/modeling_vit_msn.py
new file mode 100644
index 0000000000000000000000000000000000000000..fa99fa62a753b13e37e2195149cfb4a6d47ff657
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vit_msn/modeling_vit_msn.py
@@ -0,0 +1,567 @@
+# coding=utf-8
+# Copyright 2022 Facebook AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ViT MSN (masked siamese network) model."""
+
+import collections.abc
+from typing import Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ImageClassifierOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import TransformersKwargs, auto_docstring, logging, torch_int
+from ...utils.generic import can_return_tuple, check_model_inputs
+from .configuration_vit_msn import ViTMSNConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class ViTMSNEmbeddings(nn.Module):
+ """
+ Construct the CLS token, position and patch embeddings. Optionally, also the mask token.
+ """
+
+ def __init__(self, config: ViTMSNConfig, use_mask_token: bool = False) -> None:
+ super().__init__()
+
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, config.hidden_size))
+ self.mask_token = nn.Parameter(torch.zeros(1, 1, config.hidden_size)) if use_mask_token else None
+ self.patch_embeddings = ViTMSNPatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+ self.position_embeddings = nn.Parameter(torch.zeros(1, num_patches + 1, config.hidden_size))
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.patch_size = config.patch_size
+ self.config = config
+
+ # Copied from transformers.models.vit.modeling_vit.ViTEmbeddings.interpolate_pos_encoding
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ num_positions = self.position_embeddings.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embeddings
+
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def forward(
+ self,
+ pixel_values: torch.Tensor,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ ) -> torch.Tensor:
+ batch_size, num_channels, height, width = pixel_values.shape
+ embeddings = self.patch_embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+
+ if bool_masked_pos is not None:
+ seq_length = embeddings.shape[1]
+ mask_tokens = self.mask_token.expand(batch_size, seq_length, -1)
+ # replace the masked visual tokens by mask_tokens
+ mask = bool_masked_pos.unsqueeze(-1).type_as(mask_tokens)
+ embeddings = embeddings * (1.0 - mask) + mask_tokens * mask
+
+ # add the [CLS] token to the embedded patch tokens
+ cls_tokens = self.cls_token.expand(batch_size, -1, -1)
+ embeddings = torch.cat((cls_tokens, embeddings), dim=1)
+
+ # add positional encoding to each token
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings)
+
+ return embeddings
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTPatchEmbeddings with ViT->ViTMSN
+class ViTMSNPatchEmbeddings(nn.Module):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def forward(self, pixel_values: torch.Tensor, interpolate_pos_encoding: bool = False) -> torch.Tensor:
+ batch_size, num_channels, height, width = pixel_values.shape
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ f" Expected {self.num_channels} but got {num_channels}."
+ )
+ if not interpolate_pos_encoding:
+ if height != self.image_size[0] or width != self.image_size[1]:
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model"
+ f" ({self.image_size[0]}*{self.image_size[1]})."
+ )
+ embeddings = self.projection(pixel_values).flatten(2).transpose(1, 2)
+ return embeddings
+
+
+# Copied from transformers.models.vit.modeling_vit.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfAttention with ViT->ViTMSN
+class ViTMSNSelfAttention(nn.Module):
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ def forward(
+ self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ batch_size = hidden_states.shape[0]
+ new_shape = batch_size, -1, self.num_attention_heads, self.attention_head_size
+
+ key_layer = self.key(hidden_states).view(*new_shape).transpose(1, 2)
+ value_layer = self.value(hidden_states).view(*new_shape).transpose(1, 2)
+ query_layer = self.query(hidden_states).view(*new_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.reshape(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfOutput with ViT->ViTMSN
+class ViTMSNSelfOutput(nn.Module):
+ """
+ The residual connection is defined in ViTMSNLayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTAttention with ViT->ViTMSN
+class ViTMSNAttention(nn.Module):
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ self.attention = ViTMSNSelfAttention(config)
+ self.output = ViTMSNSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads: set[int]):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ self_attn_output, _ = self.attention(hidden_states, head_mask)
+ output = self.output(self_attn_output, hidden_states)
+ return output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTIntermediate with ViT->ViTMSN
+class ViTMSNIntermediate(nn.Module):
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTOutput with ViT->ViTMSN
+class ViTMSNOutput(nn.Module):
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTLayer with ViT->ViTMSN, VIT->VITMSN
+class ViTMSNLayer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = ViTMSNAttention(config)
+ self.intermediate = ViTMSNIntermediate(config)
+ self.output = ViTMSNOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ hidden_states_norm = self.layernorm_before(hidden_states)
+ attention_output = self.attention(hidden_states_norm, head_mask)
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in ViTMSN, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+
+ # second residual connection is done here
+ layer_output = self.output(layer_output, hidden_states)
+
+ return layer_output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTEncoder with ViT->ViTMSN
+class ViTMSNEncoder(nn.Module):
+ def __init__(self, config: ViTMSNConfig):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([ViTMSNLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> BaseModelOutput:
+ for i, layer_module in enumerate(self.layer):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ hidden_states = layer_module(hidden_states, layer_head_mask)
+
+ return BaseModelOutput(last_hidden_state=hidden_states)
+
+
+@auto_docstring
+class ViTMSNPreTrainedModel(PreTrainedModel):
+ config: ViTMSNConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["ViTMSNAttention", "ViTMSNSdpaAttention"]
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": ViTMSNLayer,
+ "attentions": ViTMSNSelfAttention,
+ }
+
+ # todo: Resort to https://github.com/facebookresearch/msn/blob/main/src/deit.py#L200-#L211
+ # when creating pre-training scripts.
+ def _init_weights(self, module: Union[nn.Linear, nn.Conv2d, nn.LayerNorm]) -> None:
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, ViTMSNEmbeddings):
+ module.cls_token.data.zero_()
+ module.position_embeddings.data.zero_()
+ if module.mask_token is not None:
+ module.mask_token.data.zero_()
+
+
+@auto_docstring
+class ViTMSNModel(ViTMSNPreTrainedModel):
+ def __init__(self, config: ViTMSNConfig, use_mask_token: bool = False):
+ r"""
+ use_mask_token (`bool`, *optional*, defaults to `False`):
+ Whether to use a mask token for masked image modeling.
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = ViTMSNEmbeddings(config, use_mask_token=use_mask_token)
+ self.encoder = ViTMSNEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> ViTMSNPatchEmbeddings:
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune: dict[int, list[int]]) -> None:
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ bool_masked_pos: Optional[torch.BoolTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ interpolate_pos_encoding: Optional[bool] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutput:
+ r"""
+ bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`, *optional*):
+ Boolean masked positions. Indicates which patches are masked (1) and which aren't (0).
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, ViTMSNModel
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("facebook/vit-msn-small")
+ >>> model = ViTMSNModel.from_pretrained("facebook/vit-msn-small")
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ ```"""
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ pixel_values, bool_masked_pos=bool_masked_pos, interpolate_pos_encoding=interpolate_pos_encoding
+ )
+ encoder_outputs: BaseModelOutput = self.encoder(embedding_output, head_mask=head_mask)
+ sequence_output = encoder_outputs.last_hidden_state
+ sequence_output = self.layernorm(sequence_output)
+
+ return BaseModelOutput(last_hidden_state=sequence_output)
+
+
+# Caution: We don't have the weights for the classification head yet. This class
+# is here for the users that are interested to fine-tune the base model (ViTMSNModel).
+@auto_docstring
+class ViTMSNForImageClassification(ViTMSNPreTrainedModel):
+ def __init__(self, config: ViTMSNConfig) -> None:
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.vit = ViTMSNModel(config)
+
+ # Classifier head
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity()
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ interpolate_pos_encoding: Optional[bool] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> ImageClassifierOutput:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, ViTMSNForImageClassification
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> torch.manual_seed(2) # doctest: +IGNORE_RESULT
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("facebook/vit-msn-small")
+ >>> model = ViTMSNForImageClassification.from_pretrained("facebook/vit-msn-small")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> with torch.no_grad():
+ ... logits = model(**inputs).logits
+ >>> # model predicts one of the 1000 ImageNet classes
+ >>> predicted_label = logits.argmax(-1).item()
+ >>> print(model.config.id2label[predicted_label])
+ tusker
+ ```
+ """
+
+ outputs: BaseModelOutput = self.vit(
+ pixel_values, head_mask=head_mask, interpolate_pos_encoding=interpolate_pos_encoding, **kwargs
+ )
+ sequence_output = outputs.last_hidden_state
+ logits = self.classifier(sequence_output[:, 0, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(labels, logits, self.config, **kwargs)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["ViTMSNModel", "ViTMSNForImageClassification", "ViTMSNPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..f96b2fdf7d6247455c115ef40700507076fe6a12
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vitdet import *
+ from .modeling_vitdet import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/configuration_vitdet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/configuration_vitdet.py
new file mode 100644
index 0000000000000000000000000000000000000000..7cc7f6b875c97552bcca86445a76f504c1495901
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/configuration_vitdet.py
@@ -0,0 +1,156 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VitDet model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ...utils.backbone_utils import BackboneConfigMixin, get_aligned_output_features_output_indices
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitDetConfig(BackboneConfigMixin, PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VitDetModel`]. It is used to instantiate an
+ VitDet model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the VitDet
+ [google/vitdet-base-patch16-224](https://huggingface.co/google/vitdet-base-patch16-224) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ mlp_ratio (`int`, *optional*, defaults to 4):
+ Ratio of mlp hidden dim to embedding dim.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ pretrain_image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image during pretraining.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ drop_path_rate (`float`, *optional*, defaults to 0.0):
+ Stochastic depth rate.
+ window_block_indices (`list[int]`, *optional*, defaults to `[]`):
+ List of indices of blocks that should have window attention instead of regular global self-attention.
+ residual_block_indices (`list[int]`, *optional*, defaults to `[]`):
+ List of indices of blocks that should have an extra residual block after the MLP.
+ use_absolute_position_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether to add absolute position embeddings to the patch embeddings.
+ use_relative_position_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether to add relative position embeddings to the attention maps.
+ window_size (`int`, *optional*, defaults to 0):
+ The size of the attention window.
+ out_features (`list[str]`, *optional*):
+ If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc.
+ (depending on how many stages the model has). If unset and `out_indices` is set, will default to the
+ corresponding stages. If unset and `out_indices` is unset, will default to the last stage. Must be in the
+ same order as defined in the `stage_names` attribute.
+ out_indices (`list[int]`, *optional*):
+ If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how
+ many stages the model has). If unset and `out_features` is set, will default to the corresponding stages.
+ If unset and `out_features` is unset, will default to the last stage. Must be in the
+ same order as defined in the `stage_names` attribute.
+
+ Example:
+
+ ```python
+ >>> from transformers import VitDetConfig, VitDetModel
+
+ >>> # Initializing a VitDet configuration
+ >>> configuration = VitDetConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = VitDetModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vitdet"
+
+ def __init__(
+ self,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ mlp_ratio=4,
+ hidden_act="gelu",
+ dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-6,
+ image_size=224,
+ pretrain_image_size=224,
+ patch_size=16,
+ num_channels=3,
+ qkv_bias=True,
+ drop_path_rate=0.0,
+ window_block_indices=[],
+ residual_block_indices=[],
+ use_absolute_position_embeddings=True,
+ use_relative_position_embeddings=False,
+ window_size=0,
+ out_features=None,
+ out_indices=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.mlp_ratio = mlp_ratio
+ self.hidden_act = hidden_act
+ self.dropout_prob = dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.image_size = image_size
+ self.pretrain_image_size = pretrain_image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+ self.drop_path_rate = drop_path_rate
+ self.window_block_indices = window_block_indices
+ self.residual_block_indices = residual_block_indices
+ self.use_absolute_position_embeddings = use_absolute_position_embeddings
+ self.use_relative_position_embeddings = use_relative_position_embeddings
+ self.window_size = window_size
+
+ self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, self.num_hidden_layers + 1)]
+ self._out_features, self._out_indices = get_aligned_output_features_output_indices(
+ out_features=out_features, out_indices=out_indices, stage_names=self.stage_names
+ )
+
+
+__all__ = ["VitDetConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/modeling_vitdet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/modeling_vitdet.py
new file mode 100644
index 0000000000000000000000000000000000000000..1498b72d856d2038011c499b06643be4cfa118f7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitdet/modeling_vitdet.py
@@ -0,0 +1,820 @@
+# coding=utf-8
+# Copyright 2023 Meta AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ViTDet backbone."""
+
+import collections.abc
+import math
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BackboneOutput, BaseModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ...utils.backbone_utils import BackboneMixin
+from .configuration_vitdet import VitDetConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitDetEmbeddings(nn.Module):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) to be consumed by a Transformer.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ image_size, patch_size = config.pretrain_image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+
+ if config.use_absolute_position_embeddings:
+ # Initialize absolute positional embedding with pretrain image size.
+ num_positions = num_patches + 1
+ self.position_embeddings = nn.Parameter(torch.zeros(1, num_positions, config.hidden_size))
+ else:
+ self.position_embeddings = None
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def get_absolute_positions(self, abs_pos_embeddings, has_cls_token, height, width):
+ """
+ Calculate absolute positional embeddings. If needed, resize embeddings and remove cls_token dimension for the
+ original embeddings.
+
+ Args:
+ abs_pos_embeddings (`torch.Tensor`):
+ Absolute positional embeddings with (1, num_position, num_channels).
+ has_cls_token (`bool`):
+ If true, has 1 embedding in abs_pos_embeddings for cls token.
+ height (`int`):
+ Height of input image tokens.
+ width (`int`):
+ Width of input image tokens.
+
+ Returns:
+ Absolute positional embeddings after processing with shape (1, height, width, num_channels)
+ """
+ if has_cls_token:
+ abs_pos_embeddings = abs_pos_embeddings[:, 1:]
+ num_position = abs_pos_embeddings.shape[1]
+ size = int(math.sqrt(num_position)) # This is a constant and can be recorded as such in the ONNX export.
+ if size * size != num_position:
+ raise ValueError("Absolute position embeddings must be a square number.")
+
+ if torch.jit.is_tracing() or (size != height or size != width):
+ # nn.functional.interpolate is a noop in case size == height and size == width - we need to always capture this path with jit.trace.
+ new_abs_pos_embeddings = nn.functional.interpolate(
+ abs_pos_embeddings.reshape(1, size, size, -1).permute(0, 3, 1, 2),
+ size=(height, width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ return new_abs_pos_embeddings.permute(0, 2, 3, 1)
+ else:
+ return abs_pos_embeddings.reshape(1, height, width, -1)
+
+ def forward(self, pixel_values: torch.Tensor) -> torch.Tensor:
+ num_channels = pixel_values.shape[1]
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ f" Expected {self.num_channels} but got {num_channels}."
+ )
+ embeddings = self.projection(pixel_values)
+
+ if self.position_embeddings is not None:
+ # (batch_size, num_channels, height, width) -> (batch_size, height, width, num_channels)
+ embeddings = embeddings.permute(0, 2, 3, 1)
+ # add position embeddings
+ embeddings = embeddings + self.get_absolute_positions(
+ self.position_embeddings, True, embeddings.shape[1], embeddings.shape[2]
+ )
+ # (batch_size, height, width, num_channels) -> (batch_size, num_channels, height, width)
+ embeddings = embeddings.permute(0, 3, 1, 2)
+
+ return embeddings
+
+
+@torch.jit.script_if_tracing # nn.functional.interpolate's `size` needs to be dynamic.
+def get_rel_pos(q_size, k_size, rel_pos):
+ """
+ Get relative positional embeddings according to the relative positions of query and key sizes.
+
+ Args:
+ q_size (`int`):
+ Size of query q.
+ k_size (`int`):
+ Size of key k.
+ rel_pos (`torch.Tensor`):
+ Relative position embeddings (num_embeddings, num_channels).
+
+ Returns:
+ Extracted positional embeddings according to relative positions.
+ """
+ max_rel_dist = int(2 * max(q_size, k_size) - 1)
+ # Interpolate rel pos if needed.
+ if rel_pos.shape[0] != max_rel_dist:
+ # Interpolate rel position embeddings.
+ rel_pos_resized = nn.functional.interpolate(
+ rel_pos.reshape(1, rel_pos.shape[0], -1).permute(0, 2, 1),
+ size=max_rel_dist,
+ mode="linear",
+ )
+ rel_pos_resized = rel_pos_resized.reshape(-1, max_rel_dist).permute(1, 0)
+ else:
+ rel_pos_resized = rel_pos
+
+ # Scale the coords with short length if shapes for q and k are different.
+ q_coords = torch.arange(q_size)[:, None] * max(k_size / q_size, 1.0)
+ k_coords = torch.arange(k_size)[None, :] * max(q_size / k_size, 1.0)
+ relative_coords = (q_coords - k_coords) + (k_size - 1) * max(q_size / k_size, 1.0)
+
+ return rel_pos_resized[relative_coords.long()]
+
+
+def add_decomposed_relative_positions(attn, queries, rel_pos_h, rel_pos_w, q_size, k_size):
+ """
+ Calculate decomposed Relative Positional Embeddings as introduced in
+ [MViT2](https://github.com/facebookresearch/mvit/blob/19786631e330df9f3622e5402b4a419a263a2c80/mvit/models/attention.py).
+
+ Args:
+ attn (`torch.Tensor`):
+ Attention map.
+ queries (`torch.Tensor`):
+ Query q in the attention layer with shape (batch_size, queries_height * queries_width, num_channels).
+ rel_pos_h (`torch.Tensor`):
+ Relative position embeddings (Lh, num_channels) for height axis.
+ rel_pos_w (`torch.Tensor`):
+ Relative position embeddings (Lw, num_channels) for width axis.
+ q_size (`tuple[int]`):
+ Spatial sequence size of query q with (queries_height, queries_width).
+ k_size (`tuple[int]`):
+ Spatial sequence size of key k with (keys_height, keys_width).
+
+ Returns:
+ attn (Tensor): attention map with added relative positional embeddings.
+ """
+ queries_height, queries_width = q_size
+ keys_height, keys_width = k_size
+ relative_height = get_rel_pos(queries_height, keys_height, rel_pos_h)
+ relative_width = get_rel_pos(queries_width, keys_width, rel_pos_w)
+
+ batch_size, _, dim = queries.shape
+ r_q = queries.reshape(batch_size, queries_height, queries_width, dim)
+ relative_height = torch.einsum("bhwc,hkc->bhwk", r_q, relative_height)
+ relative_weight = torch.einsum("bhwc,wkc->bhwk", r_q, relative_width)
+
+ attn = (
+ attn.view(batch_size, queries_height, queries_width, keys_height, keys_width)
+ + relative_height[:, :, :, :, None]
+ + relative_weight[:, :, :, None, :]
+ ).view(batch_size, queries_height * queries_width, keys_height * keys_width)
+
+ return attn
+
+
+class VitDetAttention(nn.Module):
+ """Multi-head Attention block with relative position embeddings."""
+
+ def __init__(self, config, input_size=None):
+ """
+ Args:
+ config (`VitDetConfig`):
+ Model configuration.
+ input_size (`tuple[int]`, *optional*):
+ Input resolution, only required in case relative position embeddings are added.
+ """
+ super().__init__()
+
+ dim = config.hidden_size
+ num_heads = config.num_attention_heads
+
+ self.num_heads = num_heads
+ head_dim = dim // num_heads
+ self.scale = head_dim**-0.5
+
+ self.qkv = nn.Linear(dim, dim * 3, bias=config.qkv_bias)
+ self.proj = nn.Linear(dim, dim)
+
+ self.use_relative_position_embeddings = config.use_relative_position_embeddings
+ if self.use_relative_position_embeddings:
+ # initialize relative positional embeddings
+ self.rel_pos_h = nn.Parameter(torch.zeros(2 * input_size[0] - 1, head_dim))
+ self.rel_pos_w = nn.Parameter(torch.zeros(2 * input_size[1] - 1, head_dim))
+
+ def forward(self, hidden_state, output_attentions=False):
+ batch_size, height, width, _ = hidden_state.shape
+ # qkv with shape (3, batch_size, num_heads, height * width, num_channels)
+ qkv = self.qkv(hidden_state).reshape(batch_size, height * width, 3, self.num_heads, -1).permute(2, 0, 3, 1, 4)
+ # queries, keys and values have shape (batch_size * num_heads, height * width, num_channels)
+ queries, keys, values = qkv.reshape(3, batch_size * self.num_heads, height * width, -1).unbind(0)
+
+ attention_scores = (queries * self.scale) @ keys.transpose(-2, -1)
+
+ if self.use_relative_position_embeddings:
+ attention_scores = add_decomposed_relative_positions(
+ attention_scores, queries, self.rel_pos_h, self.rel_pos_w, (height, width), (height, width)
+ )
+
+ attention_probs = attention_scores.softmax(dim=-1)
+
+ hidden_state = attention_probs @ values
+ hidden_state = hidden_state.view(batch_size, self.num_heads, height, width, -1)
+ hidden_state = hidden_state.permute(0, 2, 3, 1, 4)
+ hidden_state = hidden_state.reshape(batch_size, height, width, -1)
+ hidden_state = self.proj(hidden_state)
+
+ if output_attentions:
+ attention_probs = attention_probs.reshape(
+ batch_size, self.num_heads, attention_probs.shape[-2], attention_probs.shape[-1]
+ )
+ outputs = (hidden_state, attention_probs)
+ else:
+ outputs = (hidden_state,)
+
+ return outputs
+
+
+# Copied from transformers.models.beit.modeling_beit.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+# Copied from transformers.models.beit.modeling_beit.BeitDropPath
+class VitDetDropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: Optional[float] = None) -> None:
+ super().__init__()
+ self.drop_prob = drop_prob
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+class VitDetLayerNorm(nn.Module):
+ """
+ A LayerNorm variant, popularized by Transformers, that performs point-wise mean and variance normalization over the
+ channel dimension for inputs that have shape (batch_size, channels, height, width).
+ https://github.com/facebookresearch/ConvNeXt/blob/d1fa8f6fef0a165b27399986cc2bdacc92777e40/models/convnext.py#L119
+ """
+
+ def __init__(self, normalized_shape, eps=1e-6):
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(normalized_shape))
+ self.bias = nn.Parameter(torch.zeros(normalized_shape))
+ self.eps = eps
+ self.normalized_shape = (normalized_shape,)
+
+ def forward(self, x):
+ u = x.mean(1, keepdim=True)
+ s = (x - u).pow(2).mean(1, keepdim=True)
+ x = (x - u) / torch.sqrt(s + self.eps)
+ x = self.weight[:, None, None] * x + self.bias[:, None, None]
+ return x
+
+
+class VitDetResBottleneckBlock(nn.Module):
+ """
+ The standard bottleneck residual block without the last activation layer. It contains 3 conv layers with kernels
+ 1x1, 3x3, 1x1.
+ """
+
+ def __init__(self, config, in_channels, out_channels, bottleneck_channels):
+ """
+ Args:
+ config (`VitDetConfig`):
+ Model configuration.
+ in_channels (`int`):
+ Number of input channels.
+ out_channels (`int`):
+ Number of output channels.
+ bottleneck_channels (`int`):
+ Number of output channels for the 3x3 "bottleneck" conv layers.
+ """
+ super().__init__()
+ self.conv1 = nn.Conv2d(in_channels, bottleneck_channels, 1, bias=False)
+ self.norm1 = VitDetLayerNorm(bottleneck_channels)
+ self.act1 = ACT2FN[config.hidden_act]
+
+ self.conv2 = nn.Conv2d(bottleneck_channels, bottleneck_channels, 3, padding=1, bias=False)
+ self.norm2 = VitDetLayerNorm(bottleneck_channels)
+ self.act2 = ACT2FN[config.hidden_act]
+
+ self.conv3 = nn.Conv2d(bottleneck_channels, out_channels, 1, bias=False)
+ self.norm3 = VitDetLayerNorm(out_channels)
+
+ def forward(self, x):
+ out = x
+ for layer in self.children():
+ out = layer(out)
+
+ out = x + out
+ return out
+
+
+class VitDetMlp(nn.Module):
+ def __init__(self, config, in_features: int, hidden_features: int) -> None:
+ super().__init__()
+ self.fc1 = nn.Linear(in_features, hidden_features)
+ self.act = ACT2FN[config.hidden_act]
+ self.fc2 = nn.Linear(hidden_features, in_features)
+ self.drop = nn.Dropout(config.dropout_prob)
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ x = self.fc1(x)
+ x = self.act(x)
+ x = self.drop(x)
+ x = self.fc2(x)
+ x = self.drop(x)
+
+ return x
+
+
+def window_partition(hidden_state, window_size):
+ """
+ Partition into non-overlapping windows with padding if needed.
+
+ Args:
+ hidden_state (`torch.Tensor`):
+ Input tokens with [batch_size, height, width, num_channels].
+ window_size (`int`):
+ Window size.
+
+ Returns:
+ `tuple(torch.FloatTensor)` comprising various elements:
+ - windows: windows after partition with [batch_size * num_windows, window_size, window_size, num_channels].
+ - (padded_height, padded_width): padded height and width before partition
+ """
+ batch_size, height, width, num_channels = hidden_state.shape
+
+ pad_height = (window_size - height % window_size) % window_size
+ pad_width = (window_size - width % window_size) % window_size
+
+ # Noop in case pad_width == 0 and pad_height == 0.
+ hidden_state = nn.functional.pad(hidden_state, (0, 0, 0, pad_width, 0, pad_height))
+
+ padded_height, padded_width = height + pad_height, width + pad_width
+
+ hidden_state = hidden_state.view(
+ batch_size, padded_height // window_size, window_size, padded_width // window_size, window_size, num_channels
+ )
+ windows = hidden_state.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, window_size, window_size, num_channels)
+ return windows, (padded_height, padded_width)
+
+
+def window_unpartition(windows, window_size, pad_height_width, height_width):
+ """
+ Window unpartition into original sequences and removing padding.
+
+ Args:
+ windows (`torch.Tensor`):
+ Input tokens with [batch_size * num_windows, window_size, window_size, num_channels].
+ window_size (`int`):
+ Window size.
+ pad_height_width (`tuple[int]`):
+ Padded height and width (padded_height, padded_width).
+ height_width (`tuple[int]`):
+ Original height and width before padding.
+
+ Returns:
+ hidden_state: unpartitioned sequences with [batch_size, height, width, num_channels].
+ """
+ padded_height, padded_width = pad_height_width
+ height, width = height_width
+ batch_size = windows.shape[0] // (padded_height * padded_width // window_size // window_size)
+ hidden_state = windows.view(
+ batch_size, padded_height // window_size, padded_width // window_size, window_size, window_size, -1
+ )
+ hidden_state = hidden_state.permute(0, 1, 3, 2, 4, 5).contiguous()
+ hidden_state = hidden_state.view(batch_size, padded_height, padded_width, -1)
+
+ # We always have height <= padded_height and width <= padded_width
+ hidden_state = hidden_state[:, :height, :width, :].contiguous()
+ return hidden_state
+
+
+class VitDetLayer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the original implementation."""
+
+ def __init__(
+ self, config: VitDetConfig, drop_path_rate: float = 0, window_size: int = 0, use_residual_block: bool = False
+ ) -> None:
+ super().__init__()
+
+ dim = config.hidden_size
+
+ image_size = config.image_size
+ image_size = image_size if isinstance(image_size, (list, tuple)) else (image_size, image_size)
+
+ patch_size = config.patch_size
+ patch_size = patch_size if isinstance(patch_size, (list, tuple)) else (patch_size, patch_size)
+
+ input_size = (image_size[0] // patch_size[0], image_size[1] // patch_size[1])
+ self.norm1 = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+ self.attention = VitDetAttention(
+ config, input_size=input_size if window_size == 0 else (window_size, window_size)
+ )
+
+ self.drop_path = VitDetDropPath(drop_path_rate) if drop_path_rate > 0.0 else nn.Identity()
+ self.norm2 = nn.LayerNorm(dim, eps=config.layer_norm_eps)
+ self.mlp = VitDetMlp(config=config, in_features=dim, hidden_features=int(dim * config.mlp_ratio))
+
+ self.window_size = window_size
+
+ self.use_residual_block = use_residual_block
+ if self.use_residual_block:
+ # Use a residual block with bottleneck channel as dim // 2
+ self.residual = VitDetResBottleneckBlock(
+ config=config,
+ in_channels=dim,
+ out_channels=dim,
+ bottleneck_channels=dim // 2,
+ )
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> Union[tuple[torch.Tensor, torch.Tensor], tuple[torch.Tensor]]:
+ hidden_states = hidden_states.permute(0, 2, 3, 1)
+
+ shortcut = hidden_states
+
+ hidden_states = self.norm1(hidden_states)
+
+ # Window partition
+ if self.window_size > 0:
+ height, width = hidden_states.shape[1], hidden_states.shape[2]
+ hidden_states, pad_height_width = window_partition(hidden_states, self.window_size)
+
+ self_attention_outputs = self.attention(
+ hidden_states,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ # Reverse window partition
+ if self.window_size > 0:
+ hidden_states = window_unpartition(hidden_states, self.window_size, pad_height_width, (height, width))
+
+ # first residual connection
+ hidden_states = shortcut + self.drop_path(hidden_states)
+
+ hidden_states = hidden_states + self.drop_path(self.mlp(self.norm2(hidden_states)))
+
+ hidden_states = hidden_states.permute(0, 3, 1, 2)
+
+ if self.use_residual_block:
+ hidden_states = self.residual(hidden_states)
+
+ outputs = (hidden_states,) + outputs
+
+ return outputs
+
+
+class VitDetEncoder(nn.Module):
+ def __init__(self, config: VitDetConfig) -> None:
+ super().__init__()
+ self.config = config
+ depth = config.num_hidden_layers
+
+ # stochastic depth decay rule
+ drop_path_rate = [x.item() for x in torch.linspace(0, config.drop_path_rate, depth, device="cpu")]
+
+ layers = []
+ for i in range(depth):
+ layers.append(
+ VitDetLayer(
+ config,
+ drop_path_rate=drop_path_rate[i],
+ window_size=config.window_size if i in config.window_block_indices else 0,
+ use_residual_block=i in config.residual_block_indices,
+ )
+ )
+
+ self.layer = nn.ModuleList(layers)
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ) -> Union[tuple, BaseModelOutput]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(hidden_states, layer_head_mask, output_attentions)
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+def caffe2_msra_fill(module: nn.Module) -> None:
+ """
+ Initialize `module.weight` using the "MSRAFill" implemented in Caffe2. Also initializes `module.bias` to 0.
+
+ Source: https://detectron2.readthedocs.io/en/latest/_modules/fvcore/nn/weight_init.html.
+
+ Args:
+ module (torch.nn.Module): module to initialize.
+ """
+ nn.init.kaiming_normal_(module.weight, mode="fan_out", nonlinearity="relu")
+ if module.bias is not None:
+ nn.init.constant_(module.bias, 0)
+
+
+@auto_docstring
+class VitDetPreTrainedModel(PreTrainedModel):
+ config: VitDetConfig
+ base_model_prefix = "vitdet"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = []
+
+ def _init_weights(self, module: Union[nn.Linear, nn.Conv2d, nn.LayerNorm]) -> None:
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Upcast the input in `fp32` and cast it back to desired `dtype` to avoid
+ # `trunc_normal_cpu` not implemented in `half` issues
+ module.weight.data = nn.init.trunc_normal_(
+ module.weight.data.to(torch.float32), mean=0.0, std=self.config.initializer_range
+ ).to(module.weight.dtype)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+ elif isinstance(module, VitDetEmbeddings):
+ module.position_embeddings.data = nn.init.trunc_normal_(
+ module.position_embeddings.data.to(torch.float32),
+ mean=0.0,
+ std=self.config.initializer_range,
+ ).to(module.position_embeddings.dtype)
+
+ elif isinstance(module, VitDetAttention) and self.config.use_relative_position_embeddings:
+ module.rel_pos_h.data = nn.init.trunc_normal_(
+ module.rel_pos_h.data.to(torch.float32),
+ mean=0.0,
+ std=self.config.initializer_range,
+ )
+ module.rel_pos_w.data = nn.init.trunc_normal_(
+ module.rel_pos_w.data.to(torch.float32),
+ mean=0.0,
+ std=self.config.initializer_range,
+ )
+
+ elif isinstance(module, VitDetResBottleneckBlock):
+ for layer in [module.conv1, module.conv2, module.conv3]:
+ caffe2_msra_fill(layer)
+ for layer in [module.norm1, module.norm2]:
+ layer.weight.data.fill_(1.0)
+ layer.bias.data.zero_()
+ # zero init last norm layer.
+ module.norm3.weight.data.zero_()
+ module.norm3.bias.data.zero_()
+
+
+@auto_docstring
+class VitDetModel(VitDetPreTrainedModel):
+ def __init__(self, config: VitDetConfig):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = VitDetEmbeddings(config)
+ self.encoder = VitDetEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> VitDetEmbeddings:
+ return self.embeddings.projection
+
+ def _prune_heads(self, heads_to_prune: dict[int, list[int]]) -> None:
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import VitDetConfig, VitDetModel
+ >>> import torch
+
+ >>> config = VitDetConfig()
+ >>> model = VitDetModel(config)
+
+ >>> pixel_values = torch.randn(1, 3, 224, 224)
+
+ >>> with torch.no_grad():
+ ... outputs = model(pixel_values)
+
+ >>> last_hidden_states = outputs.last_hidden_state
+ >>> list(last_hidden_states.shape)
+ [1, 768, 14, 14]
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(pixel_values)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+
+ if not return_dict:
+ return (sequence_output,) + encoder_outputs[1:]
+
+ return BaseModelOutput(
+ last_hidden_state=sequence_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ ViTDet backbone, to be used with frameworks like Mask R-CNN.
+ """
+)
+class VitDetBackbone(VitDetPreTrainedModel, BackboneMixin):
+ def __init__(self, config):
+ super().__init__(config)
+ super()._init_backbone(config)
+
+ self.embeddings = VitDetEmbeddings(config)
+ self.encoder = VitDetEncoder(config)
+ self.num_features = [config.hidden_size for _ in range(config.num_hidden_layers + 1)]
+
+ # initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> VitDetEmbeddings:
+ return self.embeddings.projection
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.Tensor,
+ output_hidden_states: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> BackboneOutput:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import VitDetConfig, VitDetBackbone
+ >>> import torch
+
+ >>> config = VitDetConfig()
+ >>> model = VitDetBackbone(config)
+
+ >>> pixel_values = torch.randn(1, 3, 224, 224)
+
+ >>> with torch.no_grad():
+ ... outputs = model(pixel_values)
+
+ >>> feature_maps = outputs.feature_maps
+ >>> list(feature_maps[-1].shape)
+ [1, 768, 14, 14]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ embedding_output = self.embeddings(pixel_values)
+
+ outputs = self.encoder(
+ embedding_output,
+ output_hidden_states=True,
+ output_attentions=output_attentions,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs.hidden_states if return_dict else outputs[1]
+
+ feature_maps = ()
+ for stage, hidden_state in zip(self.stage_names, hidden_states):
+ if stage in self.out_features:
+ feature_maps += (hidden_state,)
+
+ if not return_dict:
+ if output_hidden_states:
+ output = (feature_maps,) + outputs[1:]
+ else:
+ output = (feature_maps,) + outputs[2:]
+ return output
+
+ return BackboneOutput(
+ feature_maps=feature_maps,
+ hidden_states=outputs.hidden_states if output_hidden_states else None,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["VitDetModel", "VitDetPreTrainedModel", "VitDetBackbone"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..863c6b5f8f46677b530fcc0b8f79a7fb0f83457b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vitmatte import *
+ from .image_processing_vitmatte import *
+ from .image_processing_vitmatte_fast import *
+ from .modeling_vitmatte import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/configuration_vitmatte.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/configuration_vitmatte.py
new file mode 100644
index 0000000000000000000000000000000000000000..f63c3e4eb85dfbe77dd03abdae6b5ae2e5a90954
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/configuration_vitmatte.py
@@ -0,0 +1,143 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VitMatte model configuration"""
+
+import copy
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ...utils.backbone_utils import verify_backbone_config_arguments
+from ..auto.configuration_auto import CONFIG_MAPPING
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitMatteConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of [`VitMatteForImageMatting`]. It is used to
+ instantiate a ViTMatte model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the ViTMatte
+ [hustvl/vitmatte-small-composition-1k](https://huggingface.co/hustvl/vitmatte-small-composition-1k) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ backbone_config (`PretrainedConfig` or `dict`, *optional*, defaults to `VitDetConfig()`):
+ The configuration of the backbone model.
+ backbone (`str`, *optional*):
+ Name of backbone to use when `backbone_config` is `None`. If `use_pretrained_backbone` is `True`, this
+ will load the corresponding pretrained weights from the timm or transformers library. If `use_pretrained_backbone`
+ is `False`, this loads the backbone's config and uses that to initialize the backbone with random weights.
+ use_pretrained_backbone (`bool`, *optional*, defaults to `False`):
+ Whether to use pretrained weights for the backbone.
+ use_timm_backbone (`bool`, *optional*, defaults to `False`):
+ Whether to load `backbone` from the timm library. If `False`, the backbone is loaded from the transformers
+ library.
+ backbone_kwargs (`dict`, *optional*):
+ Keyword arguments to be passed to AutoBackbone when loading from a checkpoint
+ e.g. `{'out_indices': (0, 1, 2, 3)}`. Cannot be specified if `backbone_config` is set.
+ hidden_size (`int`, *optional*, defaults to 384):
+ The number of input channels of the decoder.
+ batch_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the batch norm layers.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ convstream_hidden_sizes (`list[int]`, *optional*, defaults to `[48, 96, 192]`):
+ The output channels of the ConvStream module.
+ fusion_hidden_sizes (`list[int]`, *optional*, defaults to `[256, 128, 64, 32]`):
+ The output channels of the Fusion blocks.
+
+ Example:
+
+ ```python
+ >>> from transformers import VitMatteConfig, VitMatteForImageMatting
+
+ >>> # Initializing a ViTMatte hustvl/vitmatte-small-composition-1k style configuration
+ >>> configuration = VitMatteConfig()
+
+ >>> # Initializing a model (with random weights) from the hustvl/vitmatte-small-composition-1k style configuration
+ >>> model = VitMatteForImageMatting(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vitmatte"
+
+ def __init__(
+ self,
+ backbone_config: PretrainedConfig = None,
+ backbone=None,
+ use_pretrained_backbone=False,
+ use_timm_backbone=False,
+ backbone_kwargs=None,
+ hidden_size: int = 384,
+ batch_norm_eps: float = 1e-5,
+ initializer_range: float = 0.02,
+ convstream_hidden_sizes: list[int] = [48, 96, 192],
+ fusion_hidden_sizes: list[int] = [256, 128, 64, 32],
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ if backbone_config is None and backbone is None:
+ logger.info("`backbone_config` is `None`. Initializing the config with the default `VitDet` backbone.")
+ backbone_config = CONFIG_MAPPING["vitdet"](out_features=["stage4"])
+ elif isinstance(backbone_config, dict):
+ backbone_model_type = backbone_config.get("model_type")
+ config_class = CONFIG_MAPPING[backbone_model_type]
+ backbone_config = config_class.from_dict(backbone_config)
+
+ verify_backbone_config_arguments(
+ use_timm_backbone=use_timm_backbone,
+ use_pretrained_backbone=use_pretrained_backbone,
+ backbone=backbone,
+ backbone_config=backbone_config,
+ backbone_kwargs=backbone_kwargs,
+ )
+
+ self.backbone_config = backbone_config
+ self.backbone = backbone
+ self.use_pretrained_backbone = use_pretrained_backbone
+ self.use_timm_backbone = use_timm_backbone
+ self.backbone_kwargs = backbone_kwargs
+ self.batch_norm_eps = batch_norm_eps
+ self.hidden_size = hidden_size
+ self.initializer_range = initializer_range
+ self.convstream_hidden_sizes = convstream_hidden_sizes
+ self.fusion_hidden_sizes = fusion_hidden_sizes
+
+ @property
+ def sub_configs(self):
+ return (
+ {"backbone_config": type(self.backbone_config)}
+ if getattr(self, "backbone_config", None) is not None
+ else {}
+ )
+
+ def to_dict(self):
+ """
+ Serializes this instance to a Python dictionary. Override the default [`~PretrainedConfig.to_dict`]. Returns:
+ `dict[str, any]`: Dictionary of all the attributes that make up this configuration instance,
+ """
+ output = copy.deepcopy(self.__dict__)
+ output["backbone_config"] = self.backbone_config.to_dict()
+ output["model_type"] = self.__class__.model_type
+ return output
+
+
+__all__ = ["VitMatteConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/image_processing_vitmatte.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/image_processing_vitmatte.py
new file mode 100644
index 0000000000000000000000000000000000000000..15d3ec604601cacd40c05edaf12ebed7a2b0c53f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/image_processing_vitmatte.py
@@ -0,0 +1,274 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for ViTMatte."""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature
+from ...image_transforms import pad, to_channel_dimension_format
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ get_image_size,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import TensorType, filter_out_non_signature_kwargs, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitMatteImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a ViTMatte image processor.
+
+ Args:
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale`
+ parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the
+ `preprocess` method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image to make the width and height divisible by `size_divisibility`. Can be overridden
+ by the `do_pad` parameter in the `preprocess` method.
+ size_divisibility (`int`, *optional*, defaults to 32):
+ The width and height of the image will be padded to be divisible by this number.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_pad: bool = True,
+ size_divisibility: int = 32,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ self.do_rescale = do_rescale
+ self.do_normalize = do_normalize
+ self.do_pad = do_pad
+ self.rescale_factor = rescale_factor
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+ self.size_divisibility = size_divisibility
+
+ def pad_image(
+ self,
+ image: np.ndarray,
+ size_divisibility: int = 32,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ """
+ Args:
+ image (`np.ndarray`):
+ Image to pad.
+ size_divisibility (`int`, *optional*, defaults to 32):
+ The width and height of the image will be padded to be divisible by this number.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(image)
+
+ height, width = get_image_size(image, input_data_format)
+
+ pad_height = 0 if height % size_divisibility == 0 else size_divisibility - height % size_divisibility
+ pad_width = 0 if width % size_divisibility == 0 else size_divisibility - width % size_divisibility
+ if pad_width + pad_height > 0:
+ padding = ((0, pad_height), (0, pad_width))
+ image = pad(image, padding=padding, data_format=data_format, input_data_format=input_data_format)
+
+ if data_format is not None:
+ image = to_channel_dimension_format(image, data_format, input_data_format)
+
+ return image
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ trimaps: ImageInput,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_pad: Optional[bool] = None,
+ size_divisibility: Optional[int] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Union[str, ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ):
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ trimaps (`ImageInput`):
+ Trimap to preprocess.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use if `do_normalize` is set to `True`.
+ do_pad (`bool`, *optional*, defaults to `self.do_pad`):
+ Whether to pad the image.
+ size_divisibility (`int`, *optional*, defaults to `self.size_divisibility`):
+ The size divisibility to pad the image to if `do_pad` is set to `True`.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ do_pad = do_pad if do_pad is not None else self.do_pad
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ size_divisibility = size_divisibility if size_divisibility is not None else self.size_divisibility
+
+ images = make_list_of_images(images)
+ trimaps = make_list_of_images(trimaps, expected_ndims=2)
+
+ if not valid_images(trimaps):
+ raise ValueError(
+ "Invalid trimap type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_pad=do_pad,
+ size_divisibility=size_divisibility,
+ )
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+ trimaps = [to_numpy_array(trimap) for trimap in trimaps]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+ trimaps = [
+ self.rescale(image=trimap, scale=rescale_factor, input_data_format=input_data_format)
+ for trimap in trimaps
+ ]
+
+ if do_normalize:
+ images = [
+ self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ # concatenate images and trimaps
+ axis = -1 if input_data_format == ChannelDimension.LAST else 0
+ images = [
+ np.concatenate([image, np.expand_dims(trimap, axis=axis)], axis=axis)
+ for image, trimap in zip(images, trimaps)
+ ]
+
+ if do_pad:
+ images = [
+ self.pad_image(image, size_divisibility=size_divisibility, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ images = [
+ to_channel_dimension_format(image=image, channel_dim=data_format, input_channel_dim=input_data_format)
+ for image in images
+ ]
+
+ data = {"pixel_values": images}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["VitMatteImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/image_processing_vitmatte_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/image_processing_vitmatte_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..e2cd7d331253e02228de55ae99db347f547fba4f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/image_processing_vitmatte_fast.py
@@ -0,0 +1,182 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for ViTMatte."""
+
+from typing import Optional, Union
+
+from ...image_processing_utils import BatchFeature
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ get_image_size,
+)
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ filter_out_non_signature_kwargs,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+ logging,
+)
+
+
+if is_torch_available():
+ import torch
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitMatteFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ """
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to pad the image to make the width and height divisible by `size_divisibility`. Can be overridden
+ by the `do_pad` parameter in the `preprocess` method.
+ size_divisibility (`int`, *optional*, defaults to 32):
+ The width and height of the image will be padded to be divisible by this number.
+ """
+
+ do_pad: Optional[bool]
+ size_divisibility: int
+
+
+@auto_docstring
+class VitMatteImageProcessorFast(BaseImageProcessorFast):
+ do_rescale: bool = True
+ rescale_factor: Union[int, float] = 1 / 255
+ do_normalize: bool = True
+ image_mean: Optional[Union[float, list[float]]] = IMAGENET_STANDARD_MEAN
+ image_std: Optional[Union[float, list[float]]] = IMAGENET_STANDARD_STD
+ do_pad: bool = True
+ size_divisibility: int = 32
+ valid_kwargs = VitMatteFastImageProcessorKwargs
+
+ def __init__(self, **kwargs: Unpack[VitMatteFastImageProcessorKwargs]) -> None:
+ super().__init__(**kwargs)
+
+ def _pad_image(
+ self,
+ images: "torch.tensor",
+ size_divisibility: int = 32,
+ ) -> "torch.tensor":
+ """
+ Pads an image or batched images constantly so that width and height are divisible by size_divisibility
+
+ Args:
+ image (`torch,tensor`):
+ Image to pad.
+ size_divisibility (`int`, *optional*, defaults to 32):
+ The width and height of the image will be padded to be divisible by this number.
+ """
+ height, width = get_image_size(images, channel_dim=ChannelDimension.FIRST)
+
+ pad_height = 0 if height % size_divisibility == 0 else size_divisibility - height % size_divisibility
+ pad_width = 0 if width % size_divisibility == 0 else size_divisibility - width % size_divisibility
+
+ if pad_width + pad_height > 0:
+ padding = (0, 0, pad_width, pad_height)
+ images = F.pad(images, padding)
+
+ return images
+
+ @auto_docstring
+ def preprocess(
+ self,
+ images: list["torch.Tensor"],
+ trimaps: list["torch.Tensor"],
+ **kwargs: Unpack[VitMatteFastImageProcessorKwargs],
+ ) -> BatchFeature:
+ r"""
+ trimaps (`list[torch.Tensor]`):
+ The trimaps to preprocess.
+ """
+ return super().preprocess(images, trimaps, **kwargs)
+
+ def _preprocess_image_like_inputs(
+ self,
+ images: ImageInput,
+ trimaps: ImageInput,
+ do_convert_rgb: bool,
+ input_data_format: ChannelDimension,
+ device: Optional[Union[str, "torch.device"]] = None,
+ **kwargs: Unpack[VitMatteFastImageProcessorKwargs],
+ ) -> BatchFeature:
+ """
+ Preprocess image-like inputs.
+ """
+ images = self._prepare_image_like_inputs(
+ images=images, do_convert_rgb=do_convert_rgb, input_data_format=input_data_format, device=device
+ )
+ trimaps = self._prepare_image_like_inputs(images=trimaps, expected_ndims=2, device=device)
+
+ return self._preprocess(images, trimaps, **kwargs)
+
+ @filter_out_non_signature_kwargs()
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ trimaps: list["torch.Tensor"],
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_pad: Optional[bool] = None,
+ size_divisibility: Optional[int] = None,
+ disable_grouping: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping)
+ grouped_trimaps, grouped_trimaps_index = group_images_by_shape(trimaps, disable_grouping=disable_grouping)
+ processed_images_grouped = {}
+ for shape in grouped_images:
+ stacked_images = grouped_images[shape]
+ stacked_trimaps = grouped_trimaps[shape]
+ # Fused rescale and normalize
+ stacked_images = self.rescale_and_normalize(
+ stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std
+ )
+ stacked_trimaps = self.rescale_and_normalize(
+ stacked_trimaps, do_rescale, rescale_factor, False, image_mean, image_std
+ )
+ stacked_images = torch.cat([stacked_images, stacked_trimaps], dim=1)
+ if do_pad:
+ stacked_images = self._pad_image(stacked_images, self.size_divisibility)
+ processed_images_grouped[shape] = stacked_images
+
+ processed_images = reorder_images(processed_images_grouped, grouped_images_index)
+ processed_images = torch.stack(processed_images, dim=0) if return_tensors else processed_images
+
+ return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors)
+
+
+__all__ = ["VitMatteImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/modeling_vitmatte.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/modeling_vitmatte.py
new file mode 100644
index 0000000000000000000000000000000000000000..50cec9c153d31b0c4ad3cbce45646896e5ab17ac
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitmatte/modeling_vitmatte.py
@@ -0,0 +1,296 @@
+# coding=utf-8
+# Copyright 2023 HUST-VL and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ViTMatte model."""
+
+from dataclasses import dataclass
+from typing import Optional
+
+import torch
+from torch import nn
+
+from ...modeling_utils import PreTrainedModel
+from ...utils import ModelOutput, auto_docstring
+from ...utils.backbone_utils import load_backbone
+from .configuration_vitmatte import VitMatteConfig
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for outputs of image matting models.
+ """
+)
+class ImageMattingOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Loss.
+ alphas (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ Estimated alpha values.
+ hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, +
+ one for the output of each stage) of shape `(batch_size, sequence_length, hidden_size)`. Hidden-states
+ (also called feature maps) of the model at the output of each stage.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ alphas: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@auto_docstring
+class VitMattePreTrainedModel(PreTrainedModel):
+ config: VitMatteConfig
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = []
+
+ def _init_weights(self, module: nn.Module):
+ if isinstance(module, (nn.Conv2d, nn.BatchNorm2d)):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+
+
+class VitMatteBasicConv3x3(nn.Module):
+ """
+ Basic convolution layers including: Conv3x3, BatchNorm2d, ReLU layers.
+ """
+
+ def __init__(self, config, in_channels, out_channels, stride=2, padding=1):
+ super().__init__()
+ self.conv = nn.Conv2d(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=3,
+ stride=stride,
+ padding=padding,
+ bias=False,
+ )
+ self.batch_norm = nn.BatchNorm2d(out_channels, eps=config.batch_norm_eps)
+ self.relu = nn.ReLU()
+
+ def forward(self, hidden_state):
+ hidden_state = self.conv(hidden_state)
+ hidden_state = self.batch_norm(hidden_state)
+ hidden_state = self.relu(hidden_state)
+
+ return hidden_state
+
+
+class VitMatteConvStream(nn.Module):
+ """
+ Simple ConvStream containing a series of basic conv3x3 layers to extract detail features.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ # We use a default in-case there isn't a backbone config set. This is for backwards compatibility and
+ # to enable loading HF backbone models.
+ in_channels = 4
+ if config.backbone_config is not None:
+ in_channels = config.backbone_config.num_channels
+
+ out_channels = config.convstream_hidden_sizes
+
+ self.convs = nn.ModuleList()
+ self.conv_chans = [in_channels] + out_channels
+
+ for i in range(len(self.conv_chans) - 1):
+ in_chan_ = self.conv_chans[i]
+ out_chan_ = self.conv_chans[i + 1]
+ self.convs.append(VitMatteBasicConv3x3(config, in_chan_, out_chan_))
+
+ def forward(self, pixel_values):
+ out_dict = {"detailed_feature_map_0": pixel_values}
+ embeddings = pixel_values
+ for i in range(len(self.convs)):
+ embeddings = self.convs[i](embeddings)
+ name_ = "detailed_feature_map_" + str(i + 1)
+ out_dict[name_] = embeddings
+
+ return out_dict
+
+
+class VitMatteFusionBlock(nn.Module):
+ """
+ Simple fusion block to fuse features from ConvStream and Plain Vision Transformer.
+ """
+
+ def __init__(self, config, in_channels, out_channels):
+ super().__init__()
+ self.conv = VitMatteBasicConv3x3(config, in_channels, out_channels, stride=1, padding=1)
+
+ def forward(self, features, detailed_feature_map):
+ upscaled_features = nn.functional.interpolate(features, scale_factor=2, mode="bilinear", align_corners=False)
+ out = torch.cat([detailed_feature_map, upscaled_features], dim=1)
+ out = self.conv(out)
+
+ return out
+
+
+class VitMatteHead(nn.Module):
+ """
+ Simple Matting Head, containing only conv3x3 and conv1x1 layers.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ in_channels = config.fusion_hidden_sizes[-1]
+ mid_channels = 16
+
+ self.matting_convs = nn.Sequential(
+ nn.Conv2d(in_channels, mid_channels, kernel_size=3, stride=1, padding=1),
+ nn.BatchNorm2d(mid_channels),
+ nn.ReLU(True),
+ nn.Conv2d(mid_channels, 1, kernel_size=1, stride=1, padding=0),
+ )
+
+ def forward(self, hidden_state):
+ hidden_state = self.matting_convs(hidden_state)
+
+ return hidden_state
+
+
+class VitMatteDetailCaptureModule(nn.Module):
+ """
+ Simple and lightweight Detail Capture Module for ViT Matting.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ if len(config.fusion_hidden_sizes) != len(config.convstream_hidden_sizes) + 1:
+ raise ValueError(
+ "The length of fusion_hidden_sizes should be equal to the length of convstream_hidden_sizes + 1."
+ )
+
+ self.config = config
+ self.convstream = VitMatteConvStream(config)
+ self.conv_chans = self.convstream.conv_chans
+
+ self.fusion_blocks = nn.ModuleList()
+ self.fusion_channels = [config.hidden_size] + config.fusion_hidden_sizes
+
+ for i in range(len(self.fusion_channels) - 1):
+ self.fusion_blocks.append(
+ VitMatteFusionBlock(
+ config=config,
+ in_channels=self.fusion_channels[i] + self.conv_chans[-(i + 1)],
+ out_channels=self.fusion_channels[i + 1],
+ )
+ )
+
+ self.matting_head = VitMatteHead(config)
+
+ def forward(self, features, pixel_values):
+ detail_features = self.convstream(pixel_values)
+ for i in range(len(self.fusion_blocks)):
+ detailed_feature_map_name = "detailed_feature_map_" + str(len(self.fusion_blocks) - i - 1)
+ features = self.fusion_blocks[i](features, detail_features[detailed_feature_map_name])
+
+ alphas = torch.sigmoid(self.matting_head(features))
+
+ return alphas
+
+
+@auto_docstring(
+ custom_intro="""
+ ViTMatte framework leveraging any vision backbone e.g. for ADE20k, CityScapes.
+ """
+)
+class VitMatteForImageMatting(VitMattePreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.backbone = load_backbone(config)
+ self.decoder = VitMatteDetailCaptureModule(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ return_dict: Optional[bool] = None,
+ ):
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, height, width)`, *optional*):
+ Ground truth image matting for computing the loss.
+
+ Examples:
+
+ ```python
+ >>> from transformers import VitMatteImageProcessor, VitMatteForImageMatting
+ >>> import torch
+ >>> from PIL import Image
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> processor = VitMatteImageProcessor.from_pretrained("hustvl/vitmatte-small-composition-1k")
+ >>> model = VitMatteForImageMatting.from_pretrained("hustvl/vitmatte-small-composition-1k")
+
+ >>> filepath = hf_hub_download(
+ ... repo_id="hf-internal-testing/image-matting-fixtures", filename="image.png", repo_type="dataset"
+ ... )
+ >>> image = Image.open(filepath).convert("RGB")
+ >>> filepath = hf_hub_download(
+ ... repo_id="hf-internal-testing/image-matting-fixtures", filename="trimap.png", repo_type="dataset"
+ ... )
+ >>> trimap = Image.open(filepath).convert("L")
+
+ >>> # prepare image + trimap for the model
+ >>> inputs = processor(images=image, trimaps=trimap, return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... alphas = model(**inputs).alphas
+ >>> print(alphas.shape)
+ torch.Size([1, 1, 640, 960])
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ loss = None
+ if labels is not None:
+ raise NotImplementedError("Training is not yet supported")
+
+ outputs = self.backbone.forward_with_filtered_kwargs(
+ pixel_values, output_hidden_states=output_hidden_states, output_attentions=output_attentions
+ )
+
+ features = outputs.feature_maps[-1]
+ alphas = self.decoder(features, pixel_values)
+
+ if not return_dict:
+ output = (alphas,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return ImageMattingOutput(
+ loss=loss,
+ alphas=alphas,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["VitMattePreTrainedModel", "VitMatteForImageMatting"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..4a57524cce2143830e294c1920e395436d670add
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vitpose import *
+ from .image_processing_vitpose import *
+ from .modeling_vitpose import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/configuration_vitpose.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/configuration_vitpose.py
new file mode 100644
index 0000000000000000000000000000000000000000..777e3d3c60cca9b5d955463573a52f118a639197
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/configuration_vitpose.py
@@ -0,0 +1,134 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VitPose model configuration"""
+
+from typing import Optional
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ...utils.backbone_utils import verify_backbone_config_arguments
+from ..auto.configuration_auto import CONFIG_MAPPING
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitPoseConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VitPoseForPoseEstimation`]. It is used to instantiate a
+ VitPose model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the VitPose
+ [usyd-community/vitpose-base-simple](https://huggingface.co/usyd-community/vitpose-base-simple) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ backbone_config (`PretrainedConfig` or `dict`, *optional*, defaults to `VitPoseBackboneConfig()`):
+ The configuration of the backbone model. Currently, only `backbone_config` with `vitpose_backbone` as `model_type` is supported.
+ backbone (`str`, *optional*):
+ Name of backbone to use when `backbone_config` is `None`. If `use_pretrained_backbone` is `True`, this
+ will load the corresponding pretrained weights from the timm or transformers library. If `use_pretrained_backbone`
+ is `False`, this loads the backbone's config and uses that to initialize the backbone with random weights.
+ use_pretrained_backbone (`bool`, *optional*, defaults to `False`):
+ Whether to use pretrained weights for the backbone.
+ use_timm_backbone (`bool`, *optional*, defaults to `False`):
+ Whether to load `backbone` from the timm library. If `False`, the backbone is loaded from the transformers
+ library.
+ backbone_kwargs (`dict`, *optional*):
+ Keyword arguments to be passed to AutoBackbone when loading from a checkpoint
+ e.g. `{'out_indices': (0, 1, 2, 3)}`. Cannot be specified if `backbone_config` is set.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ scale_factor (`int`, *optional*, defaults to 4):
+ Factor to upscale the feature maps coming from the ViT backbone.
+ use_simple_decoder (`bool`, *optional*, defaults to `True`):
+ Whether to use a `VitPoseSimpleDecoder` to decode the feature maps from the backbone into heatmaps. Otherwise it uses `VitPoseClassicDecoder`.
+
+
+ Example:
+
+ ```python
+ >>> from transformers import VitPoseConfig, VitPoseForPoseEstimation
+
+ >>> # Initializing a VitPose configuration
+ >>> configuration = VitPoseConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = VitPoseForPoseEstimation(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vitpose"
+
+ def __init__(
+ self,
+ backbone_config: Optional[PretrainedConfig] = None,
+ backbone: Optional[str] = None,
+ use_pretrained_backbone: bool = False,
+ use_timm_backbone: bool = False,
+ backbone_kwargs: Optional[dict] = None,
+ initializer_range: float = 0.02,
+ scale_factor: int = 4,
+ use_simple_decoder: bool = True,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ if use_pretrained_backbone:
+ logger.info(
+ "`use_pretrained_backbone` is `True`. For the pure inference purpose of VitPose weight do not set this value."
+ )
+ if use_timm_backbone:
+ raise ValueError("use_timm_backbone set `True` is not supported at the moment.")
+
+ if backbone_config is None and backbone is None:
+ logger.info("`backbone_config` is `None`. Initializing the config with the default `VitPose` backbone.")
+ backbone_config = CONFIG_MAPPING["vitpose_backbone"](out_indices=[4])
+ elif isinstance(backbone_config, dict):
+ backbone_model_type = backbone_config.get("model_type")
+ config_class = CONFIG_MAPPING[backbone_model_type]
+ backbone_config = config_class.from_dict(backbone_config)
+
+ verify_backbone_config_arguments(
+ use_timm_backbone=use_timm_backbone,
+ use_pretrained_backbone=use_pretrained_backbone,
+ backbone=backbone,
+ backbone_config=backbone_config,
+ backbone_kwargs=backbone_kwargs,
+ )
+
+ self.backbone_config = backbone_config
+ self.backbone = backbone
+ self.use_pretrained_backbone = use_pretrained_backbone
+ self.use_timm_backbone = use_timm_backbone
+ self.backbone_kwargs = backbone_kwargs
+
+ self.initializer_range = initializer_range
+ self.scale_factor = scale_factor
+ self.use_simple_decoder = use_simple_decoder
+
+ @property
+ def sub_configs(self):
+ return (
+ {"backbone_config": type(self.backbone_config)}
+ if getattr(self, "backbone_config", None) is not None
+ else {}
+ )
+
+
+__all__ = ["VitPoseConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/image_processing_vitpose.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/image_processing_vitpose.py
new file mode 100644
index 0000000000000000000000000000000000000000..32c048a8a9d09e553495f7500100d7fdd5534e2a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/image_processing_vitpose.py
@@ -0,0 +1,684 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for VitPose."""
+
+import itertools
+import math
+from typing import TYPE_CHECKING, Optional, Union
+
+import numpy as np
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature
+from ...image_transforms import to_channel_dimension_format
+from ...image_utils import (
+ IMAGENET_DEFAULT_MEAN,
+ IMAGENET_DEFAULT_STD,
+ ChannelDimension,
+ ImageInput,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+)
+from ...utils import TensorType, is_scipy_available, is_torch_available, is_vision_available, logging
+
+
+if is_torch_available():
+ import torch
+
+if is_vision_available():
+ import PIL
+
+if is_scipy_available():
+ from scipy.linalg import inv
+ from scipy.ndimage import affine_transform, gaussian_filter
+
+if TYPE_CHECKING:
+ from .modeling_vitpose import VitPoseEstimatorOutput
+
+logger = logging.get_logger(__name__)
+
+
+# inspired by https://github.com/ViTAE-Transformer/ViTPose/blob/d5216452796c90c6bc29f5c5ec0bdba94366768a/mmpose/datasets/datasets/base/kpt_2d_sview_rgb_img_top_down_dataset.py#L132
+def box_to_center_and_scale(
+ box: Union[tuple, list, np.ndarray],
+ image_width: int,
+ image_height: int,
+ normalize_factor: float = 200.0,
+ padding_factor: float = 1.25,
+):
+ """
+ Encodes a bounding box in COCO format into (center, scale).
+
+ Args:
+ box (`Tuple`, `List`, or `np.ndarray`):
+ Bounding box in COCO format (top_left_x, top_left_y, width, height).
+ image_width (`int`):
+ Image width.
+ image_height (`int`):
+ Image height.
+ normalize_factor (`float`):
+ Width and height scale factor.
+ padding_factor (`float`):
+ Bounding box padding factor.
+
+ Returns:
+ tuple: A tuple containing center and scale.
+
+ - `np.ndarray` [float32](2,): Center of the bbox (x, y).
+ - `np.ndarray` [float32](2,): Scale of the bbox width & height.
+ """
+
+ top_left_x, top_left_y, width, height = box[:4]
+ aspect_ratio = image_width / image_height
+ center = np.array([top_left_x + width * 0.5, top_left_y + height * 0.5], dtype=np.float32)
+
+ if width > aspect_ratio * height:
+ height = width * 1.0 / aspect_ratio
+ elif width < aspect_ratio * height:
+ width = height * aspect_ratio
+
+ scale = np.array([width / normalize_factor, height / normalize_factor], dtype=np.float32)
+ scale = scale * padding_factor
+
+ return center, scale
+
+
+def coco_to_pascal_voc(bboxes: np.ndarray) -> np.ndarray:
+ """
+ Converts bounding boxes from the COCO format to the Pascal VOC format.
+
+ In other words, converts from (top_left_x, top_left_y, width, height) format
+ to (top_left_x, top_left_y, bottom_right_x, bottom_right_y).
+
+ Args:
+ bboxes (`np.ndarray` of shape `(batch_size, 4)):
+ Bounding boxes in COCO format.
+
+ Returns:
+ `np.ndarray` of shape `(batch_size, 4) in Pascal VOC format.
+ """
+ bboxes[:, 2] = bboxes[:, 2] + bboxes[:, 0] - 1
+ bboxes[:, 3] = bboxes[:, 3] + bboxes[:, 1] - 1
+
+ return bboxes
+
+
+def get_keypoint_predictions(heatmaps: np.ndarray) -> tuple[np.ndarray, np.ndarray]:
+ """Get keypoint predictions from score maps.
+
+ Args:
+ heatmaps (`np.ndarray` of shape `(batch_size, num_keypoints, height, width)`):
+ Model predicted heatmaps.
+
+ Returns:
+ tuple: A tuple containing aggregated results.
+
+ - coords (`np.ndarray` of shape `(batch_size, num_keypoints, 2)`):
+ Predicted keypoint location.
+ - scores (`np.ndarray` of shape `(batch_size, num_keypoints, 1)`):
+ Scores (confidence) of the keypoints.
+ """
+ if not isinstance(heatmaps, np.ndarray):
+ raise TypeError("Heatmaps should be np.ndarray")
+ if heatmaps.ndim != 4:
+ raise ValueError("Heatmaps should be 4-dimensional")
+
+ batch_size, num_keypoints, _, width = heatmaps.shape
+ heatmaps_reshaped = heatmaps.reshape((batch_size, num_keypoints, -1))
+ idx = np.argmax(heatmaps_reshaped, 2).reshape((batch_size, num_keypoints, 1))
+ scores = np.amax(heatmaps_reshaped, 2).reshape((batch_size, num_keypoints, 1))
+
+ preds = np.tile(idx, (1, 1, 2)).astype(np.float32)
+ preds[:, :, 0] = preds[:, :, 0] % width
+ preds[:, :, 1] = preds[:, :, 1] // width
+
+ preds = np.where(np.tile(scores, (1, 1, 2)) > 0.0, preds, -1)
+ return preds, scores
+
+
+def post_dark_unbiased_data_processing(coords: np.ndarray, batch_heatmaps: np.ndarray, kernel: int = 3) -> np.ndarray:
+ """DARK post-pocessing. Implemented by unbiased_data_processing.
+
+ Paper references:
+ - Huang et al. The Devil is in the Details: Delving into Unbiased Data Processing for Human Pose Estimation (CVPR 2020).
+ - Zhang et al. Distribution-Aware Coordinate Representation for Human Pose Estimation (CVPR 2020).
+
+ Args:
+ coords (`np.ndarray` of shape `(num_persons, num_keypoints, 2)`):
+ Initial coordinates of human pose.
+ batch_heatmaps (`np.ndarray` of shape `(batch_size, num_keypoints, height, width)`):
+ Batched heatmaps as predicted by the model.
+ A batch_size of 1 is used for the bottom up paradigm where all persons share the same heatmap.
+ A batch_size of `num_persons` is used for the top down paradigm where each person has its own heatmaps.
+ kernel (`int`, *optional*, defaults to 3):
+ Gaussian kernel size (K) for modulation.
+
+ Returns:
+ `np.ndarray` of shape `(num_persons, num_keypoints, 2)` ):
+ Refined coordinates.
+ """
+ batch_size, num_keypoints, height, width = batch_heatmaps.shape
+ num_coords = coords.shape[0]
+ if not (batch_size == 1 or batch_size == num_coords):
+ raise ValueError("The batch size of heatmaps should be 1 or equal to the batch size of coordinates.")
+ radius = int((kernel - 1) // 2)
+ batch_heatmaps = np.array(
+ [
+ [gaussian_filter(heatmap, sigma=0.8, radius=(radius, radius), axes=(0, 1)) for heatmap in heatmaps]
+ for heatmaps in batch_heatmaps
+ ]
+ )
+ batch_heatmaps = np.clip(batch_heatmaps, 0.001, 50)
+ batch_heatmaps = np.log(batch_heatmaps)
+
+ batch_heatmaps_pad = np.pad(batch_heatmaps, ((0, 0), (0, 0), (1, 1), (1, 1)), mode="edge").flatten()
+
+ # calculate indices for coordinates
+ index = coords[..., 0] + 1 + (coords[..., 1] + 1) * (width + 2)
+ index += (width + 2) * (height + 2) * np.arange(0, batch_size * num_keypoints).reshape(-1, num_keypoints)
+ index = index.astype(int).reshape(-1, 1)
+ i_ = batch_heatmaps_pad[index]
+ ix1 = batch_heatmaps_pad[index + 1]
+ iy1 = batch_heatmaps_pad[index + width + 2]
+ ix1y1 = batch_heatmaps_pad[index + width + 3]
+ ix1_y1_ = batch_heatmaps_pad[index - width - 3]
+ ix1_ = batch_heatmaps_pad[index - 1]
+ iy1_ = batch_heatmaps_pad[index - 2 - width]
+
+ # calculate refined coordinates using Newton's method
+ dx = 0.5 * (ix1 - ix1_)
+ dy = 0.5 * (iy1 - iy1_)
+ derivative = np.concatenate([dx, dy], axis=1)
+ derivative = derivative.reshape(num_coords, num_keypoints, 2, 1)
+ dxx = ix1 - 2 * i_ + ix1_
+ dyy = iy1 - 2 * i_ + iy1_
+ dxy = 0.5 * (ix1y1 - ix1 - iy1 + i_ + i_ - ix1_ - iy1_ + ix1_y1_)
+ hessian = np.concatenate([dxx, dxy, dxy, dyy], axis=1)
+ hessian = hessian.reshape(num_coords, num_keypoints, 2, 2)
+ hessian = np.linalg.inv(hessian + np.finfo(np.float32).eps * np.eye(2))
+ coords -= np.einsum("ijmn,ijnk->ijmk", hessian, derivative).squeeze()
+ return coords
+
+
+def transform_preds(coords: np.ndarray, center: np.ndarray, scale: np.ndarray, output_size: np.ndarray) -> np.ndarray:
+ """Get final keypoint predictions from heatmaps and apply scaling and
+ translation to map them back to the image.
+
+ Note:
+ num_keypoints: K
+
+ Args:
+ coords (`np.ndarray` of shape `(num_keypoints, ndims)`):
+
+ * If ndims=2, corrds are predicted keypoint location.
+ * If ndims=4, corrds are composed of (x, y, scores, tags)
+ * If ndims=5, corrds are composed of (x, y, scores, tags,
+ flipped_tags)
+
+ center (`np.ndarray` of shape `(2,)`):
+ Center of the bounding box (x, y).
+ scale (`np.ndarray` of shape `(2,)`):
+ Scale of the bounding box wrt original image of width and height.
+ output_size (`np.ndarray` of shape `(2,)`):
+ Size of the destination heatmaps in (height, width) format.
+
+ Returns:
+ np.ndarray: Predicted coordinates in the images.
+ """
+ if coords.shape[1] not in (2, 4, 5):
+ raise ValueError("Coordinates need to have either 2, 4 or 5 dimensions.")
+ if len(center) != 2:
+ raise ValueError("Center needs to have 2 elements, one for x and one for y.")
+ if len(scale) != 2:
+ raise ValueError("Scale needs to consist of a width and height")
+ if len(output_size) != 2:
+ raise ValueError("Output size needs to consist of a height and width")
+
+ # Recover the scale which is normalized by a factor of 200.
+ scale = scale * 200.0
+
+ # We use unbiased data processing
+ scale_y = scale[1] / (output_size[0] - 1.0)
+ scale_x = scale[0] / (output_size[1] - 1.0)
+
+ target_coords = np.ones_like(coords)
+ target_coords[:, 0] = coords[:, 0] * scale_x + center[0] - scale[0] * 0.5
+ target_coords[:, 1] = coords[:, 1] * scale_y + center[1] - scale[1] * 0.5
+
+ return target_coords
+
+
+def get_warp_matrix(theta: float, size_input: np.ndarray, size_dst: np.ndarray, size_target: np.ndarray):
+ """
+ Calculate the transformation matrix under the constraint of unbiased. Paper ref: Huang et al. The Devil is in the
+ Details: Delving into Unbiased Data Processing for Human Pose Estimation (CVPR 2020).
+
+ Source: https://github.com/open-mmlab/mmpose/blob/master/mmpose/core/post_processing/post_transforms.py
+
+ Args:
+ theta (`float`):
+ Rotation angle in degrees.
+ size_input (`np.ndarray`):
+ Size of input image [width, height].
+ size_dst (`np.ndarray`):
+ Size of output image [width, height].
+ size_target (`np.ndarray`):
+ Size of ROI in input plane [w, h].
+
+ Returns:
+ `np.ndarray`: A matrix for transformation.
+ """
+ theta = np.deg2rad(theta)
+ matrix = np.zeros((2, 3), dtype=np.float32)
+ scale_x = size_dst[0] / size_target[0]
+ scale_y = size_dst[1] / size_target[1]
+ matrix[0, 0] = math.cos(theta) * scale_x
+ matrix[0, 1] = -math.sin(theta) * scale_x
+ matrix[0, 2] = scale_x * (
+ -0.5 * size_input[0] * math.cos(theta) + 0.5 * size_input[1] * math.sin(theta) + 0.5 * size_target[0]
+ )
+ matrix[1, 0] = math.sin(theta) * scale_y
+ matrix[1, 1] = math.cos(theta) * scale_y
+ matrix[1, 2] = scale_y * (
+ -0.5 * size_input[0] * math.sin(theta) - 0.5 * size_input[1] * math.cos(theta) + 0.5 * size_target[1]
+ )
+ return matrix
+
+
+def scipy_warp_affine(src, M, size):
+ """
+ This function implements cv2.warpAffine function using affine_transform in scipy. See https://docs.scipy.org/doc/scipy/reference/generated/scipy.ndimage.affine_transform.html and https://docs.opencv.org/4.x/d4/d61/tutorial_warp_affine.html for more details.
+
+ Note: the original implementation of cv2.warpAffine uses cv2.INTER_LINEAR.
+ """
+ channels = [src[..., i] for i in range(src.shape[-1])]
+
+ # Convert to a 3x3 matrix used by SciPy
+ M_scipy = np.vstack([M, [0, 0, 1]])
+ # If you have a matrix for the ‘push’ transformation, use its inverse (numpy.linalg.inv) in this function.
+ M_inv = inv(M_scipy)
+ M_inv[0, 0], M_inv[0, 1], M_inv[1, 0], M_inv[1, 1], M_inv[0, 2], M_inv[1, 2] = (
+ M_inv[1, 1],
+ M_inv[1, 0],
+ M_inv[0, 1],
+ M_inv[0, 0],
+ M_inv[1, 2],
+ M_inv[0, 2],
+ )
+
+ new_src = [affine_transform(channel, M_inv, output_shape=size, order=1) for channel in channels]
+ new_src = np.stack(new_src, axis=-1)
+ return new_src
+
+
+class VitPoseImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a VitPose image processor.
+
+ Args:
+ do_affine_transform (`bool`, *optional*, defaults to `True`):
+ Whether to apply an affine transformation to the input images.
+ size (`dict[str, int]` *optional*, defaults to `{"height": 256, "width": 192}`):
+ Resolution of the image after `affine_transform` is applied. Only has an effect if `do_affine_transform` is set to `True`. Can
+ be overridden by `size` in the `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether or not to apply the scaling factor (to make pixel values floats between 0. and 1.).
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess`
+ method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether or not to normalize the input with mean and standard deviation.
+ image_mean (`list[int]`, defaults to `[0.485, 0.456, 0.406]`, *optional*):
+ The sequence of means for each channel, to be used when normalizing images.
+ image_std (`list[int]`, defaults to `[0.229, 0.224, 0.225]`, *optional*):
+ The sequence of standard deviations for each channel, to be used when normalizing images.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_affine_transform: bool = True,
+ size: Optional[dict[str, int]] = None,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.do_affine_transform = do_affine_transform
+ self.size = size if size is not None else {"height": 256, "width": 192}
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD
+ self.normalize_factor = 200.0
+
+ def affine_transform(
+ self,
+ image: np.array,
+ center: tuple[float],
+ scale: tuple[float],
+ rotation: float,
+ size: dict[str, int],
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.array:
+ """
+ Apply an affine transformation to an image.
+
+ Args:
+ image (`np.array`):
+ Image to transform.
+ center (`tuple[float]`):
+ Center of the bounding box (x, y).
+ scale (`tuple[float]`):
+ Scale of the bounding box with respect to height/width.
+ rotation (`float`):
+ Rotation angle in degrees.
+ size (`dict[str, int]`):
+ Size of the destination image.
+ data_format (`ChannelDimension`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format of the output image.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the input image.
+ """
+
+ data_format = input_data_format if data_format is None else data_format
+
+ size = (size["width"], size["height"])
+
+ # one uses a pixel standard deviation of 200 pixels
+ transformation = get_warp_matrix(rotation, center * 2.0, np.array(size) - 1.0, scale * 200.0)
+
+ # input image requires channels last format
+ image = (
+ image
+ if input_data_format == ChannelDimension.LAST
+ else to_channel_dimension_format(image, ChannelDimension.LAST, input_data_format)
+ )
+ image = scipy_warp_affine(src=image, M=transformation, size=(size[1], size[0]))
+
+ image = to_channel_dimension_format(image, data_format, ChannelDimension.LAST)
+
+ return image
+
+ def preprocess(
+ self,
+ images: ImageInput,
+ boxes: Union[list[list[float]], np.ndarray],
+ do_affine_transform: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Union[str, ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+
+ boxes (`list[list[list[float]]]` or `np.ndarray`):
+ List or array of bounding boxes for each image. Each box should be a list of 4 floats representing the bounding
+ box coordinates in COCO format (top_left_x, top_left_y, width, height).
+
+ do_affine_transform (`bool`, *optional*, defaults to `self.do_affine_transform`):
+ Whether to apply an affine transformation to the input images.
+ size (`dict[str, int]` *optional*, defaults to `self.size`):
+ Dictionary in the format `{"height": h, "width": w}` specifying the size of the output image after
+ resizing.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean to use if `do_normalize` is set to `True`.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation to use if `do_normalize` is set to `True`.
+ return_tensors (`str` or [`~utils.TensorType`], *optional*, defaults to `'np'`):
+ If set, will return tensors of a particular framework. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+
+ Returns:
+ [`BatchFeature`]: A [`BatchFeature`] with the following fields:
+
+ - **pixel_values** -- Pixel values to be fed to a model, of shape (batch_size, num_channels, height,
+ width).
+ """
+ do_affine_transform = do_affine_transform if do_affine_transform is not None else self.do_affine_transform
+ size = size if size is not None else self.size
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ if isinstance(boxes, list) and len(images) != len(boxes):
+ raise ValueError(f"Batch of images and boxes mismatch : {len(images)} != {len(boxes)}")
+ elif isinstance(boxes, np.ndarray) and len(images) != boxes.shape[0]:
+ raise ValueError(f"Batch of images and boxes mismatch : {len(images)} != {boxes.shape[0]}")
+
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if is_scaled_image(images[0]) and do_rescale:
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ # transformations (affine transformation + rescaling + normalization)
+ if self.do_affine_transform:
+ new_images = []
+ for image, image_boxes in zip(images, boxes):
+ for box in image_boxes:
+ center, scale = box_to_center_and_scale(
+ box,
+ image_width=size["width"],
+ image_height=size["height"],
+ normalize_factor=self.normalize_factor,
+ )
+ transformed_image = self.affine_transform(
+ image, center, scale, rotation=0, size=size, input_data_format=input_data_format
+ )
+ new_images.append(transformed_image)
+ images = new_images
+
+ # For batch processing, the number of boxes must be consistent across all images in the batch.
+ # When using a list input, the number of boxes can vary dynamically per image.
+ # The image processor creates pixel_values of shape (batch_size*num_persons, num_channels, height, width)
+
+ all_images = []
+ for image in images:
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+
+ if do_normalize:
+ image = self.normalize(
+ image=image, mean=image_mean, std=image_std, input_data_format=input_data_format
+ )
+
+ all_images.append(image)
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+ for image in all_images
+ ]
+
+ data = {"pixel_values": images}
+ encoded_inputs = BatchFeature(data=data, tensor_type=return_tensors)
+
+ return encoded_inputs
+
+ def keypoints_from_heatmaps(
+ self,
+ heatmaps: np.ndarray,
+ center: np.ndarray,
+ scale: np.ndarray,
+ kernel: int = 11,
+ ):
+ """
+ Get final keypoint predictions from heatmaps and transform them back to
+ the image.
+
+ Args:
+ heatmaps (`np.ndarray` of shape `(batch_size, num_keypoints, height, width])`):
+ Model predicted heatmaps.
+ center (`np.ndarray` of shape `(batch_size, 2)`):
+ Center of the bounding box (x, y).
+ scale (`np.ndarray` of shape `(batch_size, 2)`):
+ Scale of the bounding box wrt original images of width and height.
+ kernel (int, *optional*, defaults to 11):
+ Gaussian kernel size (K) for modulation, which should match the heatmap gaussian sigma when training.
+ K=17 for sigma=3 and k=11 for sigma=2.
+
+ Returns:
+ tuple: A tuple containing keypoint predictions and scores.
+
+ - preds (`np.ndarray` of shape `(batch_size, num_keypoints, 2)`):
+ Predicted keypoint location in images.
+ - scores (`np.ndarray` of shape `(batch_size, num_keypoints, 1)`):
+ Scores (confidence) of the keypoints.
+ """
+ batch_size, _, height, width = heatmaps.shape
+
+ coords, scores = get_keypoint_predictions(heatmaps)
+
+ preds = post_dark_unbiased_data_processing(coords, heatmaps, kernel=kernel)
+
+ # Transform back to the image
+ for i in range(batch_size):
+ preds[i] = transform_preds(preds[i], center=center[i], scale=scale[i], output_size=[height, width])
+
+ return preds, scores
+
+ def post_process_pose_estimation(
+ self,
+ outputs: "VitPoseEstimatorOutput",
+ boxes: Union[list[list[list[float]]], np.ndarray],
+ kernel_size: int = 11,
+ threshold: Optional[float] = None,
+ target_sizes: Union[TensorType, list[tuple]] = None,
+ ):
+ """
+ Transform the heatmaps into keypoint predictions and transform them back to the image.
+
+ Args:
+ outputs (`VitPoseEstimatorOutput`):
+ VitPoseForPoseEstimation model outputs.
+ boxes (`list[list[list[float]]]` or `np.ndarray`):
+ List or array of bounding boxes for each image. Each box should be a list of 4 floats representing the bounding
+ box coordinates in COCO format (top_left_x, top_left_y, width, height).
+ kernel_size (`int`, *optional*, defaults to 11):
+ Gaussian kernel size (K) for modulation.
+ threshold (`float`, *optional*, defaults to None):
+ Score threshold to keep object detection predictions.
+ target_sizes (`torch.Tensor` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size
+ `(height, width)` of each image in the batch. If unset, predictions will be resize with the default value.
+ Returns:
+ `list[list[Dict]]`: A list of dictionaries, each dictionary containing the keypoints and boxes for an image
+ in the batch as predicted by the model.
+ """
+
+ # First compute centers and scales for each bounding box
+ batch_size, num_keypoints, _, _ = outputs.heatmaps.shape
+
+ if target_sizes is not None:
+ if batch_size != len(target_sizes):
+ raise ValueError(
+ "Make sure that you pass in as many target sizes as the batch dimension of the logits"
+ )
+
+ centers = np.zeros((batch_size, 2), dtype=np.float32)
+ scales = np.zeros((batch_size, 2), dtype=np.float32)
+ flattened_boxes = list(itertools.chain(*boxes))
+ for i in range(batch_size):
+ if target_sizes is not None:
+ image_width, image_height = target_sizes[i][0], target_sizes[i][1]
+ scale_factor = np.array([image_width, image_height, image_width, image_height])
+ flattened_boxes[i] = flattened_boxes[i] * scale_factor
+ width, height = self.size["width"], self.size["height"]
+ center, scale = box_to_center_and_scale(flattened_boxes[i], image_width=width, image_height=height)
+ centers[i, :] = center
+ scales[i, :] = scale
+
+ preds, scores = self.keypoints_from_heatmaps(
+ outputs.heatmaps.cpu().numpy(), centers, scales, kernel=kernel_size
+ )
+
+ all_boxes = np.zeros((batch_size, 4), dtype=np.float32)
+ all_boxes[:, 0:2] = centers[:, 0:2]
+ all_boxes[:, 2:4] = scales[:, 0:2]
+
+ poses = torch.tensor(preds)
+ scores = torch.tensor(scores)
+ labels = torch.arange(0, num_keypoints)
+ bboxes_xyxy = torch.tensor(coco_to_pascal_voc(all_boxes))
+
+ results: list[list[dict[str, torch.Tensor]]] = []
+
+ pose_bbox_pairs = zip(poses, scores, bboxes_xyxy)
+
+ for image_bboxes in boxes:
+ image_results: list[dict[str, torch.Tensor]] = []
+ for _ in image_bboxes:
+ # Unpack the next pose and bbox_xyxy from the iterator
+ pose, score, bbox_xyxy = next(pose_bbox_pairs)
+ score = score.squeeze()
+ keypoints_labels = labels
+ if threshold is not None:
+ keep = score > threshold
+ pose = pose[keep]
+ score = score[keep]
+ keypoints_labels = keypoints_labels[keep]
+ pose_result = {"keypoints": pose, "scores": score, "labels": keypoints_labels, "bbox": bbox_xyxy}
+ image_results.append(pose_result)
+ results.append(image_results)
+
+ return results
+
+
+__all__ = ["VitPoseImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/modeling_vitpose.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/modeling_vitpose.py
new file mode 100644
index 0000000000000000000000000000000000000000..900eb3aadf7b5cf89a02f00c54d7a5d292020018
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose/modeling_vitpose.py
@@ -0,0 +1,280 @@
+# coding=utf-8
+# Copyright 2024 University of Sydney and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch VitPose model."""
+
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...modeling_outputs import BackboneOutput
+from ...modeling_utils import PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import ModelOutput, TransformersKwargs, auto_docstring, logging
+from ...utils.backbone_utils import load_backbone
+from ...utils.generic import can_return_tuple
+from .configuration_vitpose import VitPoseConfig
+
+
+logger = logging.get_logger(__name__)
+
+# General docstring
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Class for outputs of pose estimation models.
+ """
+)
+class VitPoseEstimatorOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Loss is not supported at this moment. See https://github.com/ViTAE-Transformer/ViTPose/tree/main/mmpose/models/losses for further detail.
+ heatmaps (`torch.FloatTensor` of shape `(batch_size, num_keypoints, height, width)`):
+ Heatmaps as predicted by the model.
+ hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, +
+ one for the output of each stage) of shape `(batch_size, sequence_length, hidden_size)`. Hidden-states
+ (also called feature maps) of the model at the output of each stage.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ heatmaps: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@auto_docstring
+class VitPosePreTrainedModel(PreTrainedModel):
+ config: VitPoseConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module: Union[nn.Linear, nn.Conv2d, nn.LayerNorm]):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Upcast the input in `fp32` and cast it back to desired `dtype` to avoid
+ # `trunc_normal_cpu` not implemented in `half` issues
+ module.weight.data = nn.init.trunc_normal_(
+ module.weight.data.to(torch.float32), mean=0.0, std=self.config.initializer_range
+ ).to(module.weight.dtype)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+def flip_back(output_flipped, flip_pairs, target_type="gaussian-heatmap"):
+ """Flip the flipped heatmaps back to the original form.
+
+ Args:
+ output_flipped (`torch.tensor` of shape `(batch_size, num_keypoints, height, width)`):
+ The output heatmaps obtained from the flipped images.
+ flip_pairs (`torch.Tensor` of shape `(num_keypoints, 2)`):
+ Pairs of keypoints which are mirrored (for example, left ear -- right ear).
+ target_type (`str`, *optional*, defaults to `"gaussian-heatmap"`):
+ Target type to use. Can be gaussian-heatmap or combined-target.
+ gaussian-heatmap: Classification target with gaussian distribution.
+ combined-target: The combination of classification target (response map) and regression target (offset map).
+ Paper ref: Huang et al. The Devil is in the Details: Delving into Unbiased Data Processing for Human Pose Estimation (CVPR 2020).
+
+ Returns:
+ torch.Tensor: heatmaps that flipped back to the original image
+ """
+ if target_type not in ["gaussian-heatmap", "combined-target"]:
+ raise ValueError("target_type should be gaussian-heatmap or combined-target")
+
+ if output_flipped.ndim != 4:
+ raise ValueError("output_flipped should be [batch_size, num_keypoints, height, width]")
+ batch_size, num_keypoints, height, width = output_flipped.shape
+ channels = 1
+ if target_type == "combined-target":
+ channels = 3
+ output_flipped[:, 1::3, ...] = -output_flipped[:, 1::3, ...]
+ output_flipped = output_flipped.reshape(batch_size, -1, channels, height, width)
+ output_flipped_back = output_flipped.clone()
+
+ # Swap left-right parts
+ for left, right in flip_pairs.tolist():
+ output_flipped_back[:, left, ...] = output_flipped[:, right, ...]
+ output_flipped_back[:, right, ...] = output_flipped[:, left, ...]
+ output_flipped_back = output_flipped_back.reshape((batch_size, num_keypoints, height, width))
+ # Flip horizontally
+ output_flipped_back = output_flipped_back.flip(-1)
+ return output_flipped_back
+
+
+class VitPoseSimpleDecoder(nn.Module):
+ """
+ Simple decoding head consisting of a ReLU activation, 4x upsampling and a 3x3 convolution, turning the
+ feature maps into heatmaps.
+ """
+
+ def __init__(self, config: VitPoseConfig):
+ super().__init__()
+
+ self.activation = nn.ReLU()
+ self.upsampling = nn.Upsample(scale_factor=config.scale_factor, mode="bilinear", align_corners=False)
+ self.conv = nn.Conv2d(
+ config.backbone_config.hidden_size, config.num_labels, kernel_size=3, stride=1, padding=1
+ )
+
+ def forward(self, hidden_state: torch.Tensor, flip_pairs: Optional[torch.Tensor] = None) -> torch.Tensor:
+ # Transform input: ReLU + upsample
+ hidden_state = self.activation(hidden_state)
+ hidden_state = self.upsampling(hidden_state)
+ heatmaps = self.conv(hidden_state)
+
+ if flip_pairs is not None:
+ heatmaps = flip_back(heatmaps, flip_pairs)
+
+ return heatmaps
+
+
+class VitPoseClassicDecoder(nn.Module):
+ """
+ Classic decoding head consisting of a 2 deconvolutional blocks, followed by a 1x1 convolution layer,
+ turning the feature maps into heatmaps.
+ """
+
+ def __init__(self, config: VitPoseConfig):
+ super().__init__()
+
+ self.deconv1 = nn.ConvTranspose2d(
+ config.backbone_config.hidden_size, 256, kernel_size=4, stride=2, padding=1, bias=False
+ )
+ self.batchnorm1 = nn.BatchNorm2d(256)
+ self.relu1 = nn.ReLU()
+
+ self.deconv2 = nn.ConvTranspose2d(256, 256, kernel_size=4, stride=2, padding=1, bias=False)
+ self.batchnorm2 = nn.BatchNorm2d(256)
+ self.relu2 = nn.ReLU()
+
+ self.conv = nn.Conv2d(256, config.num_labels, kernel_size=1, stride=1, padding=0)
+
+ def forward(self, hidden_state: torch.Tensor, flip_pairs: Optional[torch.Tensor] = None):
+ hidden_state = self.deconv1(hidden_state)
+ hidden_state = self.batchnorm1(hidden_state)
+ hidden_state = self.relu1(hidden_state)
+
+ hidden_state = self.deconv2(hidden_state)
+ hidden_state = self.batchnorm2(hidden_state)
+ hidden_state = self.relu2(hidden_state)
+
+ heatmaps = self.conv(hidden_state)
+
+ if flip_pairs is not None:
+ heatmaps = flip_back(heatmaps, flip_pairs)
+
+ return heatmaps
+
+
+@auto_docstring(
+ custom_intro="""
+ The VitPose model with a pose estimation head on top.
+ """
+)
+class VitPoseForPoseEstimation(VitPosePreTrainedModel):
+ def __init__(self, config: VitPoseConfig):
+ super().__init__(config)
+
+ self.backbone = load_backbone(config)
+
+ # add backbone attributes
+ if not hasattr(self.backbone.config, "hidden_size"):
+ raise ValueError("The backbone should have a hidden_size attribute")
+ if not hasattr(self.backbone.config, "image_size"):
+ raise ValueError("The backbone should have an image_size attribute")
+ if not hasattr(self.backbone.config, "patch_size"):
+ raise ValueError("The backbone should have a patch_size attribute")
+
+ self.head = VitPoseSimpleDecoder(config) if config.use_simple_decoder else VitPoseClassicDecoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.Tensor,
+ dataset_index: Optional[torch.Tensor] = None,
+ flip_pairs: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> VitPoseEstimatorOutput:
+ r"""
+ dataset_index (`torch.Tensor` of shape `(batch_size,)`):
+ Index to use in the Mixture-of-Experts (MoE) blocks of the backbone.
+
+ This corresponds to the dataset index used during training, e.g. For the single dataset index 0 refers to the corresponding dataset. For the multiple datasets index 0 refers to dataset A (e.g. MPII) and index 1 refers to dataset B (e.g. CrowdPose).
+ flip_pairs (`torch.tensor`, *optional*):
+ Whether to mirror pairs of keypoints (for example, left ear -- right ear).
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, VitPoseForPoseEstimation
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> processor = AutoImageProcessor.from_pretrained("usyd-community/vitpose-base-simple")
+ >>> model = VitPoseForPoseEstimation.from_pretrained("usyd-community/vitpose-base-simple")
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+ >>> boxes = [[[412.8, 157.61, 53.05, 138.01], [384.43, 172.21, 15.12, 35.74]]]
+ >>> inputs = processor(image, boxes=boxes, return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+ >>> heatmaps = outputs.heatmaps
+ ```"""
+
+ loss = None
+ if labels is not None:
+ raise NotImplementedError("Training is not yet supported")
+
+ outputs: BackboneOutput = self.backbone.forward_with_filtered_kwargs(
+ pixel_values,
+ dataset_index=dataset_index,
+ **kwargs,
+ )
+
+ # Turn output hidden states in tensor of shape (batch_size, num_channels, height, width)
+ sequence_output = outputs.feature_maps[-1]
+ batch_size = sequence_output.shape[0]
+ patch_height = self.config.backbone_config.image_size[0] // self.config.backbone_config.patch_size[0]
+ patch_width = self.config.backbone_config.image_size[1] // self.config.backbone_config.patch_size[1]
+ sequence_output = sequence_output.permute(0, 2, 1)
+ sequence_output = sequence_output.reshape(batch_size, -1, patch_height, patch_width).contiguous()
+
+ heatmaps = self.head(sequence_output, flip_pairs=flip_pairs)
+
+ return VitPoseEstimatorOutput(
+ loss=loss,
+ heatmaps=heatmaps,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["VitPosePreTrainedModel", "VitPoseForPoseEstimation"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..858e93797d26948970f209e6429e4a586a5044a6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/__init__.py
@@ -0,0 +1,17 @@
+# flake8: noqa
+# There's no way to ignore "F401 '...' imported but unused" warnings in this
+# module, but to preserve other warnings. So, don't check this module at all.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vitpose_backbone import *
+ from .modeling_vitpose_backbone import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/configuration_vitpose_backbone.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/configuration_vitpose_backbone.py
new file mode 100644
index 0000000000000000000000000000000000000000..b3edc62f485360851730e04cf1486533fed6e107
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/configuration_vitpose_backbone.py
@@ -0,0 +1,139 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VitPose backbone configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ...utils.backbone_utils import BackboneConfigMixin, get_aligned_output_features_output_indices
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitPoseBackboneConfig(BackboneConfigMixin, PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VitPoseBackbone`]. It is used to instantiate a
+ VitPose model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the VitPose
+ [usyd-community/vitpose-base-simple](https://huggingface.co/usyd-community/vitpose-base-simple) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ image_size (`int`, *optional*, defaults to `[256, 192]`):
+ The size (resolution) of each image.
+ patch_size (`list[int]`, *optional*, defaults to `[16, 16]`):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ mlp_ratio (`int`, *optional*, defaults to 4):
+ The ratio of the hidden size in the feedforward network to the hidden size in the attention layers.
+ num_experts (`int`, *optional*, defaults to 1):
+ The number of experts in the MoE layer.
+ part_features (`int`, *optional*):
+ The number of part features to output. Only used in case `num_experts` is greater than 1.
+ hidden_act (`str`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probabilitiy for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ out_features (`list[str]`, *optional*):
+ If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc.
+ (depending on how many stages the model has). If unset and `out_indices` is set, will default to the
+ corresponding stages. If unset and `out_indices` is unset, will default to the last stage. Must be in the
+ same order as defined in the `stage_names` attribute.
+ out_indices (`list[int]`, *optional*):
+ If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how
+ many stages the model has). If unset and `out_features` is set, will default to the corresponding stages.
+ If unset and `out_features` is unset, will default to the last stage. Must be in the
+ same order as defined in the `stage_names` attribute.
+
+ Example:
+
+ ```python
+ >>> from transformers import VitPoseBackboneConfig, VitPoseBackbone
+
+ >>> # Initializing a VitPose configuration
+ >>> configuration = VitPoseBackboneConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = VitPoseBackbone(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vitpose_backbone"
+
+ def __init__(
+ self,
+ image_size=[256, 192],
+ patch_size=[16, 16],
+ num_channels=3,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ mlp_ratio=4,
+ num_experts=1,
+ part_features=256,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ qkv_bias=True,
+ out_features=None,
+ out_indices=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.mlp_ratio = mlp_ratio
+ self.num_experts = num_experts
+ self.part_features = part_features
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+ self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, num_hidden_layers + 1)]
+ self._out_features, self._out_indices = get_aligned_output_features_output_indices(
+ out_features=out_features, out_indices=out_indices, stage_names=self.stage_names
+ )
+
+
+__all__ = ["VitPoseBackboneConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/modeling_vitpose_backbone.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/modeling_vitpose_backbone.py
new file mode 100644
index 0000000000000000000000000000000000000000..b5c596832fb46b61e383a179bd20a8dcd6200241
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vitpose_backbone/modeling_vitpose_backbone.py
@@ -0,0 +1,469 @@
+# coding=utf-8
+# Copyright 2024 University of Sydney and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch VitPose backbone model.
+
+This code is the same as the original Vision Transformer (ViT) with 2 modifications:
+- use of padding=2 in the patch embedding layer
+- addition of a mixture-of-experts MLP layer
+"""
+
+import collections.abc
+from typing import Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BackboneOutput, BaseModelOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import auto_docstring, logging
+from ...utils.backbone_utils import BackboneMixin
+from ...utils.generic import check_model_inputs
+from .configuration_vitpose_backbone import VitPoseBackboneConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitPoseBackbonePatchEmbeddings(nn.Module):
+ """Image to Patch Embedding."""
+
+ def __init__(self, config):
+ super().__init__()
+
+ image_size = config.image_size
+ patch_size = config.patch_size
+ num_channels = config.num_channels
+ embed_dim = config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_patches = num_patches
+
+ self.projection = nn.Conv2d(num_channels, embed_dim, kernel_size=patch_size, stride=patch_size, padding=2)
+
+ def forward(self, pixel_values: torch.Tensor) -> torch.Tensor:
+ height, width = pixel_values.shape[-2:]
+ if height != self.image_size[0] or width != self.image_size[1]:
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})."
+ )
+ embeddings = self.projection(pixel_values)
+
+ embeddings = embeddings.flatten(2).transpose(1, 2)
+ return embeddings
+
+
+class VitPoseBackboneEmbeddings(nn.Module):
+ """
+ Construct the position and patch embeddings.
+ """
+
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+
+ self.patch_embeddings = VitPoseBackbonePatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+ self.position_embeddings = nn.Parameter(torch.zeros(1, num_patches + 1, config.hidden_size))
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, pixel_values: torch.Tensor) -> torch.Tensor:
+ embeddings = self.patch_embeddings(pixel_values)
+
+ # add positional encoding to each token
+ embeddings = embeddings + self.position_embeddings[:, 1:] + self.position_embeddings[:, :1]
+
+ embeddings = self.dropout(embeddings)
+
+ return embeddings
+
+
+# Copied from transformers.models.vit.modeling_vit.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfAttention with ViT->VitPoseBackbone
+class VitPoseBackboneSelfAttention(nn.Module):
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ def forward(
+ self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ batch_size = hidden_states.shape[0]
+ new_shape = batch_size, -1, self.num_attention_heads, self.attention_head_size
+
+ key_layer = self.key(hidden_states).view(*new_shape).transpose(1, 2)
+ value_layer = self.value(hidden_states).view(*new_shape).transpose(1, 2)
+ query_layer = self.query(hidden_states).view(*new_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.reshape(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfOutput with ViT->VitPoseBackbone
+class VitPoseBackboneSelfOutput(nn.Module):
+ """
+ The residual connection is defined in VitPoseBackboneLayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTAttention with ViT->VitPoseBackbone
+class VitPoseBackboneAttention(nn.Module):
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+ self.attention = VitPoseBackboneSelfAttention(config)
+ self.output = VitPoseBackboneSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads: set[int]):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ self_attn_output, _ = self.attention(hidden_states, head_mask)
+ output = self.output(self_attn_output, hidden_states)
+ return output
+
+
+class VitPoseBackboneMoeMLP(nn.Module):
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+
+ in_features = out_features = config.hidden_size
+ hidden_features = int(config.hidden_size * config.mlp_ratio)
+
+ num_experts = config.num_experts
+ part_features = config.part_features
+
+ self.part_features = part_features
+ self.fc1 = nn.Linear(in_features, hidden_features)
+ self.act = ACT2FN[config.hidden_act]
+ self.fc2 = nn.Linear(hidden_features, out_features - part_features)
+ self.drop = nn.Dropout(config.hidden_dropout_prob)
+
+ self.num_experts = num_experts
+ experts = [nn.Linear(hidden_features, part_features) for _ in range(num_experts)]
+ self.experts = nn.ModuleList(experts)
+
+ def forward(self, hidden_state: torch.Tensor, indices: torch.Tensor) -> torch.Tensor:
+ expert_hidden_state = torch.zeros_like(hidden_state[:, :, -self.part_features :])
+
+ hidden_state = self.fc1(hidden_state)
+ hidden_state = self.act(hidden_state)
+ shared_hidden_state = self.fc2(hidden_state)
+ indices = indices.view(-1, 1, 1)
+
+ # to support ddp training
+ for i in range(self.num_experts):
+ selected_index = indices == i
+ current_hidden_state = self.experts[i](hidden_state) * selected_index
+ expert_hidden_state = expert_hidden_state + current_hidden_state
+
+ hidden_state = torch.cat([shared_hidden_state, expert_hidden_state], dim=-1)
+
+ return hidden_state
+
+
+class VitPoseBackboneMLP(nn.Module):
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+ in_features = out_features = config.hidden_size
+ hidden_features = int(config.hidden_size * config.mlp_ratio)
+ self.fc1 = nn.Linear(in_features, hidden_features, bias=True)
+ self.activation = ACT2FN[config.hidden_act]
+ self.fc2 = nn.Linear(hidden_features, out_features, bias=True)
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ hidden_state = self.fc1(hidden_state)
+ hidden_state = self.activation(hidden_state)
+ hidden_state = self.fc2(hidden_state)
+ return hidden_state
+
+
+class VitPoseBackboneLayer(GradientCheckpointingLayer):
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+ self.num_experts = config.num_experts
+ self.attention = VitPoseBackboneAttention(config)
+ self.mlp = VitPoseBackboneMLP(config) if self.num_experts == 1 else VitPoseBackboneMoeMLP(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ dataset_index: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ ) -> torch.Tensor:
+ # Validate dataset_index when using multiple experts
+ if self.num_experts > 1 and dataset_index is None:
+ raise ValueError(
+ "dataset_index must be provided when using multiple experts "
+ f"(num_experts={self.num_experts}). Please provide dataset_index "
+ "to the forward pass."
+ )
+
+ hidden_states_norm = self.layernorm_before(hidden_states)
+ attention_output = self.attention(hidden_states_norm, head_mask)
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ layer_output = self.layernorm_after(hidden_states)
+ if self.num_experts == 1:
+ layer_output = self.mlp(layer_output)
+ else:
+ layer_output = self.mlp(layer_output, indices=dataset_index)
+
+ # second residual connection
+ layer_output = layer_output + hidden_states
+
+ return layer_output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTEncoder with ViT->VitPoseBackbone
+class VitPoseBackboneEncoder(nn.Module):
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([VitPoseBackboneLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ # Ignore copy
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ dataset_index: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> BaseModelOutput:
+ all_hidden_states = [hidden_states] if output_hidden_states else None
+ for i, layer_module in enumerate(self.layer):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ hidden_states = layer_module(hidden_states, dataset_index, layer_head_mask)
+ if all_hidden_states is not None:
+ all_hidden_states.append(hidden_states)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=tuple(all_hidden_states) if all_hidden_states else None,
+ )
+
+
+@auto_docstring
+class VitPoseBackbonePreTrainedModel(PreTrainedModel):
+ config: VitPoseBackboneConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["VitPoseBackboneEmbeddings", "VitPoseBackboneLayer"]
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _can_record_outputs = {
+ "attentions": VitPoseBackboneSelfAttention,
+ }
+
+ def _init_weights(self, module: Union[nn.Linear, nn.Conv2d, nn.LayerNorm, VitPoseBackboneEmbeddings]):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Upcast the input in `fp32` and cast it back to desired `dtype` to avoid
+ # `trunc_normal_cpu` not implemented in `half` issues
+ module.weight.data = nn.init.trunc_normal_(
+ module.weight.data.to(torch.float32), mean=0.0, std=self.config.initializer_range
+ ).to(module.weight.dtype)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, VitPoseBackboneEmbeddings):
+ module.position_embeddings.data = nn.init.trunc_normal_(
+ module.position_embeddings.data.to(torch.float32),
+ mean=0.0,
+ std=self.config.initializer_range,
+ ).to(module.position_embeddings.dtype)
+
+
+@auto_docstring(
+ custom_intro="""
+ The VitPose backbone useful for downstream tasks.
+ """
+)
+class VitPoseBackbone(VitPoseBackbonePreTrainedModel, BackboneMixin):
+ def __init__(self, config: VitPoseBackboneConfig):
+ super().__init__(config)
+ super()._init_backbone(config)
+
+ self.num_features = [config.hidden_size for _ in range(config.num_hidden_layers + 1)]
+ self.embeddings = VitPoseBackboneEmbeddings(config)
+ self.encoder = VitPoseBackboneEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.Tensor,
+ dataset_index: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_hidden_states: Optional[bool] = None,
+ **kwargs,
+ ):
+ r"""
+ dataset_index (`torch.Tensor` of shape `(batch_size,)`):
+ Index to use in the Mixture-of-Experts (MoE) blocks of the backbone.
+
+ This corresponds to the dataset index used during training, e.g. index 0 refers to COCO.
+
+ Examples:
+
+ ```python
+ >>> from transformers import VitPoseBackboneConfig, VitPoseBackbone
+ >>> import torch
+
+ >>> config = VitPoseBackboneConfig(out_indices=[-1])
+ >>> model = VitPoseBackbone(config)
+
+ >>> pixel_values = torch.randn(1, 3, 256, 192)
+ >>> dataset_index = torch.tensor([1])
+ >>> outputs = model(pixel_values, dataset_index)
+ ```"""
+
+ if output_hidden_states is None:
+ output_hidden_states = self.config.output_hidden_states
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(pixel_values)
+ outputs: BaseModelOutput = self.encoder(
+ embedding_output, dataset_index=dataset_index, head_mask=head_mask, output_hidden_states=True
+ )
+ hidden_states = outputs.hidden_states
+
+ feature_maps = []
+ for stage, hidden_state in zip(self.stage_names, hidden_states):
+ if stage in self.out_features:
+ hidden_state = self.layernorm(hidden_state)
+ feature_maps.append(hidden_state)
+
+ return BackboneOutput(
+ feature_maps=tuple(feature_maps),
+ hidden_states=outputs.hidden_states if output_hidden_states else None,
+ )
+
+
+__all__ = ["VitPoseBackbonePreTrainedModel", "VitPoseBackbone"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..0cf54b7884848784ac7e94062be8da91f4fedcf7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vits import *
+ from .modeling_vits import *
+ from .tokenization_vits import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/configuration_vits.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/configuration_vits.py
new file mode 100644
index 0000000000000000000000000000000000000000..96407d1ac0d2d7a98035a8345728cedd53a1534e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/configuration_vits.py
@@ -0,0 +1,253 @@
+# coding=utf-8
+# Copyright 2023 The Kakao Enterprise Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VITS model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class VitsConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VitsModel`]. It is used to instantiate a VITS
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the VITS
+ [facebook/mms-tts-eng](https://huggingface.co/facebook/mms-tts-eng) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 38):
+ Vocabulary size of the VITS model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed to the forward method of [`VitsModel`].
+ hidden_size (`int`, *optional*, defaults to 192):
+ Dimensionality of the text encoder layers.
+ num_hidden_layers (`int`, *optional*, defaults to 6):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 2):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ window_size (`int`, *optional*, defaults to 4):
+ Window size for the relative positional embeddings in the attention layers of the Transformer encoder.
+ use_bias (`bool`, *optional*, defaults to `True`):
+ Whether to use bias in the key, query, value projection layers in the Transformer encoder.
+ ffn_dim (`int`, *optional*, defaults to 768):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ ffn_kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size of the 1D convolution layers used by the feed-forward network in the Transformer encoder.
+ flow_size (`int`, *optional*, defaults to 192):
+ Dimensionality of the flow layers.
+ spectrogram_bins (`int`, *optional*, defaults to 513):
+ Number of frequency bins in the target spectrogram.
+ hidden_act (`str` or `function`, *optional*, defaults to `"relu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings and encoder.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for activations inside the fully connected layer.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the layer normalization layers.
+ use_stochastic_duration_prediction (`bool`, *optional*, defaults to `True`):
+ Whether to use the stochastic duration prediction module or the regular duration predictor.
+ num_speakers (`int`, *optional*, defaults to 1):
+ Number of speakers if this is a multi-speaker model.
+ speaker_embedding_size (`int`, *optional*, defaults to 0):
+ Number of channels used by the speaker embeddings. Is zero for single-speaker models.
+ upsample_initial_channel (`int`, *optional*, defaults to 512):
+ The number of input channels into the HiFi-GAN upsampling network.
+ upsample_rates (`tuple[int]` or `list[int]`, *optional*, defaults to `[8, 8, 2, 2]`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the HiFi-GAN upsampling network.
+ The length of `upsample_rates` defines the number of convolutional layers and has to match the length of
+ `upsample_kernel_sizes`.
+ upsample_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[16, 16, 4, 4]`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the HiFi-GAN upsampling
+ network. The length of `upsample_kernel_sizes` defines the number of convolutional layers and has to match
+ the length of `upsample_rates`.
+ resblock_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[3, 7, 11]`):
+ A tuple of integers defining the kernel sizes of the 1D convolutional layers in the HiFi-GAN
+ multi-receptive field fusion (MRF) module.
+ resblock_dilation_sizes (`tuple[tuple[int]]` or `list[list[int]]`, *optional*, defaults to `[[1, 3, 5], [1, 3, 5], [1, 3, 5]]`):
+ A nested tuple of integers defining the dilation rates of the dilated 1D convolutional layers in the
+ HiFi-GAN multi-receptive field fusion (MRF) module.
+ leaky_relu_slope (`float`, *optional*, defaults to 0.1):
+ The angle of the negative slope used by the leaky ReLU activation.
+ depth_separable_channels (`int`, *optional*, defaults to 2):
+ Number of channels to use in each depth-separable block.
+ depth_separable_num_layers (`int`, *optional*, defaults to 3):
+ Number of convolutional layers to use in each depth-separable block.
+ duration_predictor_flow_bins (`int`, *optional*, defaults to 10):
+ Number of channels to map using the unonstrained rational spline in the duration predictor model.
+ duration_predictor_tail_bound (`float`, *optional*, defaults to 5.0):
+ Value of the tail bin boundary when computing the unconstrained rational spline in the duration predictor
+ model.
+ duration_predictor_kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size of the 1D convolution layers used in the duration predictor model.
+ duration_predictor_dropout (`float`, *optional*, defaults to 0.5):
+ The dropout ratio for the duration predictor model.
+ duration_predictor_num_flows (`int`, *optional*, defaults to 4):
+ Number of flow stages used by the duration predictor model.
+ duration_predictor_filter_channels (`int`, *optional*, defaults to 256):
+ Number of channels for the convolution layers used in the duration predictor model.
+ prior_encoder_num_flows (`int`, *optional*, defaults to 4):
+ Number of flow stages used by the prior encoder flow model.
+ prior_encoder_num_wavenet_layers (`int`, *optional*, defaults to 4):
+ Number of WaveNet layers used by the prior encoder flow model.
+ posterior_encoder_num_wavenet_layers (`int`, *optional*, defaults to 16):
+ Number of WaveNet layers used by the posterior encoder model.
+ wavenet_kernel_size (`int`, *optional*, defaults to 5):
+ Kernel size of the 1D convolution layers used in the WaveNet model.
+ wavenet_dilation_rate (`int`, *optional*, defaults to 1):
+ Dilation rates of the dilated 1D convolutional layers used in the WaveNet model.
+ wavenet_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the WaveNet layers.
+ speaking_rate (`float`, *optional*, defaults to 1.0):
+ Speaking rate. Larger values give faster synthesised speech.
+ noise_scale (`float`, *optional*, defaults to 0.667):
+ How random the speech prediction is. Larger values create more variation in the predicted speech.
+ noise_scale_duration (`float`, *optional*, defaults to 0.8):
+ How random the duration prediction is. Larger values create more variation in the predicted durations.
+ sampling_rate (`int`, *optional*, defaults to 16000):
+ The sampling rate at which the output audio waveform is digitalized expressed in hertz (Hz).
+
+ Example:
+
+ ```python
+ >>> from transformers import VitsModel, VitsConfig
+
+ >>> # Initializing a "facebook/mms-tts-eng" style configuration
+ >>> configuration = VitsConfig()
+
+ >>> # Initializing a model (with random weights) from the "facebook/mms-tts-eng" style configuration
+ >>> model = VitsModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vits"
+
+ def __init__(
+ self,
+ vocab_size=38,
+ hidden_size=192,
+ num_hidden_layers=6,
+ num_attention_heads=2,
+ window_size=4,
+ use_bias=True,
+ ffn_dim=768,
+ layerdrop=0.1,
+ ffn_kernel_size=3,
+ flow_size=192,
+ spectrogram_bins=513,
+ hidden_act="relu",
+ hidden_dropout=0.1,
+ attention_dropout=0.1,
+ activation_dropout=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ use_stochastic_duration_prediction=True,
+ num_speakers=1,
+ speaker_embedding_size=0,
+ upsample_initial_channel=512,
+ upsample_rates=[8, 8, 2, 2],
+ upsample_kernel_sizes=[16, 16, 4, 4],
+ resblock_kernel_sizes=[3, 7, 11],
+ resblock_dilation_sizes=[[1, 3, 5], [1, 3, 5], [1, 3, 5]],
+ leaky_relu_slope=0.1,
+ depth_separable_channels=2,
+ depth_separable_num_layers=3,
+ duration_predictor_flow_bins=10,
+ duration_predictor_tail_bound=5.0,
+ duration_predictor_kernel_size=3,
+ duration_predictor_dropout=0.5,
+ duration_predictor_num_flows=4,
+ duration_predictor_filter_channels=256,
+ prior_encoder_num_flows=4,
+ prior_encoder_num_wavenet_layers=4,
+ posterior_encoder_num_wavenet_layers=16,
+ wavenet_kernel_size=5,
+ wavenet_dilation_rate=1,
+ wavenet_dropout=0.0,
+ speaking_rate=1.0,
+ noise_scale=0.667,
+ noise_scale_duration=0.8,
+ sampling_rate=16_000,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.window_size = window_size
+ self.use_bias = use_bias
+ self.ffn_dim = ffn_dim
+ self.layerdrop = layerdrop
+ self.ffn_kernel_size = ffn_kernel_size
+ self.flow_size = flow_size
+ self.spectrogram_bins = spectrogram_bins
+ self.hidden_act = hidden_act
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.use_stochastic_duration_prediction = use_stochastic_duration_prediction
+ self.num_speakers = num_speakers
+ self.speaker_embedding_size = speaker_embedding_size
+ self.upsample_initial_channel = upsample_initial_channel
+ self.upsample_rates = upsample_rates
+ self.upsample_kernel_sizes = upsample_kernel_sizes
+ self.resblock_kernel_sizes = resblock_kernel_sizes
+ self.resblock_dilation_sizes = resblock_dilation_sizes
+ self.leaky_relu_slope = leaky_relu_slope
+ self.depth_separable_channels = depth_separable_channels
+ self.depth_separable_num_layers = depth_separable_num_layers
+ self.duration_predictor_flow_bins = duration_predictor_flow_bins
+ self.duration_predictor_tail_bound = duration_predictor_tail_bound
+ self.duration_predictor_kernel_size = duration_predictor_kernel_size
+ self.duration_predictor_dropout = duration_predictor_dropout
+ self.duration_predictor_num_flows = duration_predictor_num_flows
+ self.duration_predictor_filter_channels = duration_predictor_filter_channels
+ self.prior_encoder_num_flows = prior_encoder_num_flows
+ self.prior_encoder_num_wavenet_layers = prior_encoder_num_wavenet_layers
+ self.posterior_encoder_num_wavenet_layers = posterior_encoder_num_wavenet_layers
+ self.wavenet_kernel_size = wavenet_kernel_size
+ self.wavenet_dilation_rate = wavenet_dilation_rate
+ self.wavenet_dropout = wavenet_dropout
+ self.speaking_rate = speaking_rate
+ self.noise_scale = noise_scale
+ self.noise_scale_duration = noise_scale_duration
+ self.sampling_rate = sampling_rate
+
+ if len(upsample_kernel_sizes) != len(upsample_rates):
+ raise ValueError(
+ f"The length of `upsample_kernel_sizes` ({len(upsample_kernel_sizes)}) must match the length of "
+ f"`upsample_rates` ({len(upsample_rates)})"
+ )
+
+ super().__init__(**kwargs)
+
+
+__all__ = ["VitsConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/modeling_vits.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/modeling_vits.py
new file mode 100644
index 0000000000000000000000000000000000000000..40ce1e1083c8009b0df852e3445f4e6025cf28ef
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/modeling_vits.py
@@ -0,0 +1,1409 @@
+# coding=utf-8
+# Copyright 2023 The Kakao Enterprise Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch VITS model."""
+
+import math
+from dataclasses import dataclass
+from typing import Any, Optional, Union
+
+import numpy as np
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from .configuration_vits import VitsConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Describes the outputs for the VITS model, with potential hidden states and attentions.
+ """
+)
+class VitsModelOutput(ModelOutput):
+ r"""
+ waveform (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ The final audio waveform predicted by the model.
+ sequence_lengths (`torch.FloatTensor` of shape `(batch_size,)`):
+ The length in samples of each element in the `waveform` batch.
+ spectrogram (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_bins)`):
+ The log-mel spectrogram predicted at the output of the flow model. This spectrogram is passed to the Hi-Fi
+ GAN decoder model to obtain the final audio waveform.
+ """
+
+ waveform: Optional[torch.FloatTensor] = None
+ sequence_lengths: Optional[torch.FloatTensor] = None
+ spectrogram: Optional[tuple[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Describes the outputs for the VITS text encoder model, with potential hidden states and attentions.
+ """
+)
+class VitsTextEncoderOutput(ModelOutput):
+ r"""
+ prior_means (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ The predicted mean values of the prior distribution for the latent text variables.
+ prior_log_variances (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ The predicted log-variance values of the prior distribution for the latent text variables.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ prior_means: Optional[torch.FloatTensor] = None
+ prior_log_variances: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+@torch.jit.script
+def fused_add_tanh_sigmoid_multiply(input_a, input_b, num_channels):
+ in_act = input_a + input_b
+ t_act = torch.tanh(in_act[:, :num_channels, :])
+ s_act = torch.sigmoid(in_act[:, num_channels:, :])
+ acts = t_act * s_act
+ return acts
+
+
+def _unconstrained_rational_quadratic_spline(
+ inputs,
+ unnormalized_widths,
+ unnormalized_heights,
+ unnormalized_derivatives,
+ reverse=False,
+ tail_bound=5.0,
+ min_bin_width=1e-3,
+ min_bin_height=1e-3,
+ min_derivative=1e-3,
+):
+ """
+ This transformation represents a monotonically increasing piecewise rational quadratic function. Outside of the
+ `tail_bound`, the transform behaves as an identity function.
+
+ Args:
+ inputs (`torch.FloatTensor` of shape `(batch_size, channels, seq_len)`:
+ Second half of the hidden-states input to the Vits convolutional flow module.
+ unnormalized_widths (`torch.FloatTensor` of shape `(batch_size, channels, seq_len, duration_predictor_flow_bins)`):
+ First `duration_predictor_flow_bins` of the hidden-states from the output of the convolution projection
+ layer in the convolutional flow module
+ unnormalized_heights (`torch.FloatTensor` of shape `(batch_size, channels, seq_len, duration_predictor_flow_bins)`):
+ Second `duration_predictor_flow_bins` of the hidden-states from the output of the convolution projection
+ layer in the convolutional flow module
+ unnormalized_derivatives (`torch.FloatTensor` of shape `(batch_size, channels, seq_len, duration_predictor_flow_bins)`):
+ Third `duration_predictor_flow_bins` of the hidden-states from the output of the convolution projection
+ layer in the convolutional flow module
+ reverse (`bool`, *optional*, defaults to `False`):
+ Whether the model is being run in reverse mode.
+ tail_bound (`float`, *optional* defaults to 5):
+ Upper and lower limit bound for the rational quadratic function. Outside of this `tail_bound`, the
+ transform behaves as an identity function.
+ min_bin_width (`float`, *optional*, defaults to 1e-3):
+ Minimum bin value across the width dimension for the piecewise rational quadratic function.
+ min_bin_height (`float`, *optional*, defaults to 1e-3):
+ Minimum bin value across the height dimension for the piecewise rational quadratic function.
+ min_derivative (`float`, *optional*, defaults to 1e-3):
+ Minimum bin value across the derivatives for the piecewise rational quadratic function.
+ Returns:
+ outputs (`torch.FloatTensor` of shape `(batch_size, channels, seq_len)`:
+ Hidden-states as transformed by the piecewise rational quadratic function with the `tail_bound` limits
+ applied.
+ log_abs_det (`torch.FloatTensor` of shape `(batch_size, channels, seq_len)`:
+ Logarithm of the absolute value of the determinants corresponding to the `outputs` with the `tail_bound`
+ limits applied.
+ """
+ inside_interval_mask = (inputs >= -tail_bound) & (inputs <= tail_bound)
+ outside_interval_mask = ~inside_interval_mask
+
+ outputs = torch.zeros_like(inputs)
+ log_abs_det = torch.zeros_like(inputs)
+ constant = np.log(np.exp(1 - min_derivative) - 1)
+
+ unnormalized_derivatives = nn.functional.pad(unnormalized_derivatives, pad=(1, 1))
+ unnormalized_derivatives[..., 0] = constant
+ unnormalized_derivatives[..., -1] = constant
+
+ outputs[outside_interval_mask] = inputs[outside_interval_mask]
+ log_abs_det[outside_interval_mask] = 0.0
+
+ outputs[inside_interval_mask], log_abs_det[inside_interval_mask] = _rational_quadratic_spline(
+ inputs=inputs[inside_interval_mask],
+ unnormalized_widths=unnormalized_widths[inside_interval_mask, :],
+ unnormalized_heights=unnormalized_heights[inside_interval_mask, :],
+ unnormalized_derivatives=unnormalized_derivatives[inside_interval_mask, :],
+ reverse=reverse,
+ tail_bound=tail_bound,
+ min_bin_width=min_bin_width,
+ min_bin_height=min_bin_height,
+ min_derivative=min_derivative,
+ )
+ return outputs, log_abs_det
+
+
+def _rational_quadratic_spline(
+ inputs,
+ unnormalized_widths,
+ unnormalized_heights,
+ unnormalized_derivatives,
+ reverse,
+ tail_bound,
+ min_bin_width,
+ min_bin_height,
+ min_derivative,
+):
+ """
+ This transformation represents a monotonically increasing piecewise rational quadratic function. Unlike the
+ function `_unconstrained_rational_quadratic_spline`, the function behaves the same across the `tail_bound`.
+
+ Args:
+ inputs (`torch.FloatTensor` of shape `(batch_size, channels, seq_len)`:
+ Second half of the hidden-states input to the Vits convolutional flow module.
+ unnormalized_widths (`torch.FloatTensor` of shape `(batch_size, channels, seq_len, duration_predictor_flow_bins)`):
+ First `duration_predictor_flow_bins` of the hidden-states from the output of the convolution projection
+ layer in the convolutional flow module
+ unnormalized_heights (`torch.FloatTensor` of shape `(batch_size, channels, seq_len, duration_predictor_flow_bins)`):
+ Second `duration_predictor_flow_bins` of the hidden-states from the output of the convolution projection
+ layer in the convolutional flow module
+ unnormalized_derivatives (`torch.FloatTensor` of shape `(batch_size, channels, seq_len, duration_predictor_flow_bins)`):
+ Third `duration_predictor_flow_bins` of the hidden-states from the output of the convolution projection
+ layer in the convolutional flow module
+ reverse (`bool`):
+ Whether the model is being run in reverse mode.
+ tail_bound (`float`):
+ Upper and lower limit bound for the rational quadratic function. Outside of this `tail_bound`, the
+ transform behaves as an identity function.
+ min_bin_width (`float`):
+ Minimum bin value across the width dimension for the piecewise rational quadratic function.
+ min_bin_height (`float`):
+ Minimum bin value across the height dimension for the piecewise rational quadratic function.
+ min_derivative (`float`):
+ Minimum bin value across the derivatives for the piecewise rational quadratic function.
+ Returns:
+ outputs (`torch.FloatTensor` of shape `(batch_size, channels, seq_len)`:
+ Hidden-states as transformed by the piecewise rational quadratic function.
+ log_abs_det (`torch.FloatTensor` of shape `(batch_size, channels, seq_len)`:
+ Logarithm of the absolute value of the determinants corresponding to the `outputs`.
+ """
+ upper_bound = tail_bound
+ lower_bound = -tail_bound
+
+ if torch.min(inputs) < lower_bound or torch.max(inputs) > upper_bound:
+ raise ValueError("Input to a transform is not within its domain")
+
+ num_bins = unnormalized_widths.shape[-1]
+
+ if min_bin_width * num_bins > 1.0:
+ raise ValueError(f"Minimal bin width {min_bin_width} too large for the number of bins {num_bins}")
+ if min_bin_height * num_bins > 1.0:
+ raise ValueError(f"Minimal bin height {min_bin_height} too large for the number of bins {num_bins}")
+
+ widths = nn.functional.softmax(unnormalized_widths, dim=-1)
+ widths = min_bin_width + (1 - min_bin_width * num_bins) * widths
+ cumwidths = torch.cumsum(widths, dim=-1)
+ cumwidths = nn.functional.pad(cumwidths, pad=(1, 0), mode="constant", value=0.0)
+ cumwidths = (upper_bound - lower_bound) * cumwidths + lower_bound
+ cumwidths[..., 0] = lower_bound
+ cumwidths[..., -1] = upper_bound
+ widths = cumwidths[..., 1:] - cumwidths[..., :-1]
+
+ derivatives = min_derivative + nn.functional.softplus(unnormalized_derivatives)
+
+ heights = nn.functional.softmax(unnormalized_heights, dim=-1)
+ heights = min_bin_height + (1 - min_bin_height * num_bins) * heights
+ cumheights = torch.cumsum(heights, dim=-1)
+ cumheights = nn.functional.pad(cumheights, pad=(1, 0), mode="constant", value=0.0)
+ cumheights = (upper_bound - lower_bound) * cumheights + lower_bound
+ cumheights[..., 0] = lower_bound
+ cumheights[..., -1] = upper_bound
+ heights = cumheights[..., 1:] - cumheights[..., :-1]
+
+ bin_locations = cumheights if reverse else cumwidths
+ bin_locations[..., -1] += 1e-6
+ bin_idx = torch.sum(inputs[..., None] >= bin_locations, dim=-1) - 1
+ bin_idx = bin_idx[..., None]
+
+ input_cumwidths = cumwidths.gather(-1, bin_idx)[..., 0]
+ input_bin_widths = widths.gather(-1, bin_idx)[..., 0]
+
+ input_cumheights = cumheights.gather(-1, bin_idx)[..., 0]
+ delta = heights / widths
+ input_delta = delta.gather(-1, bin_idx)[..., 0]
+
+ input_derivatives = derivatives.gather(-1, bin_idx)[..., 0]
+ input_derivatives_plus_one = derivatives[..., 1:].gather(-1, bin_idx)[..., 0]
+
+ input_heights = heights.gather(-1, bin_idx)[..., 0]
+
+ intermediate1 = input_derivatives + input_derivatives_plus_one - 2 * input_delta
+ if not reverse:
+ theta = (inputs - input_cumwidths) / input_bin_widths
+ theta_one_minus_theta = theta * (1 - theta)
+
+ numerator = input_heights * (input_delta * theta.pow(2) + input_derivatives * theta_one_minus_theta)
+ denominator = input_delta + intermediate1 * theta_one_minus_theta
+ outputs = input_cumheights + numerator / denominator
+
+ derivative_numerator = input_delta.pow(2) * (
+ input_derivatives_plus_one * theta.pow(2)
+ + 2 * input_delta * theta_one_minus_theta
+ + input_derivatives * (1 - theta).pow(2)
+ )
+ log_abs_det = torch.log(derivative_numerator) - 2 * torch.log(denominator)
+ return outputs, log_abs_det
+ else:
+ # find the roots of a quadratic equation
+ intermediate2 = inputs - input_cumheights
+ intermediate3 = intermediate2 * intermediate1
+ a = input_heights * (input_delta - input_derivatives) + intermediate3
+ b = input_heights * input_derivatives - intermediate3
+ c = -input_delta * intermediate2
+
+ discriminant = b.pow(2) - 4 * a * c
+ if not (discriminant >= 0).all():
+ raise RuntimeError(f"invalid discriminant {discriminant}")
+
+ root = (2 * c) / (-b - torch.sqrt(discriminant))
+ outputs = root * input_bin_widths + input_cumwidths
+
+ theta_one_minus_theta = root * (1 - root)
+ denominator = input_delta + intermediate1 * theta_one_minus_theta
+ derivative_numerator = input_delta.pow(2) * (
+ input_derivatives_plus_one * root.pow(2)
+ + 2 * input_delta * theta_one_minus_theta
+ + input_derivatives * (1 - root).pow(2)
+ )
+ log_abs_det = torch.log(derivative_numerator) - 2 * torch.log(denominator)
+ return outputs, -log_abs_det
+
+
+class VitsWaveNet(torch.nn.Module):
+ def __init__(self, config: VitsConfig, num_layers: int):
+ super().__init__()
+ self.hidden_size = config.hidden_size
+ self.num_layers = num_layers
+
+ self.in_layers = torch.nn.ModuleList()
+ self.res_skip_layers = torch.nn.ModuleList()
+ self.dropout = nn.Dropout(config.wavenet_dropout)
+
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+ else:
+ weight_norm = nn.utils.weight_norm
+
+ if config.speaker_embedding_size != 0:
+ cond_layer = torch.nn.Conv1d(config.speaker_embedding_size, 2 * config.hidden_size * num_layers, 1)
+ self.cond_layer = weight_norm(cond_layer, name="weight")
+
+ for i in range(num_layers):
+ dilation = config.wavenet_dilation_rate**i
+ padding = (config.wavenet_kernel_size * dilation - dilation) // 2
+ in_layer = torch.nn.Conv1d(
+ in_channels=config.hidden_size,
+ out_channels=2 * config.hidden_size,
+ kernel_size=config.wavenet_kernel_size,
+ dilation=dilation,
+ padding=padding,
+ )
+ in_layer = weight_norm(in_layer, name="weight")
+ self.in_layers.append(in_layer)
+
+ # last one is not necessary
+ if i < num_layers - 1:
+ res_skip_channels = 2 * config.hidden_size
+ else:
+ res_skip_channels = config.hidden_size
+
+ res_skip_layer = torch.nn.Conv1d(config.hidden_size, res_skip_channels, 1)
+ res_skip_layer = weight_norm(res_skip_layer, name="weight")
+ self.res_skip_layers.append(res_skip_layer)
+
+ def forward(self, inputs, padding_mask, global_conditioning=None):
+ outputs = torch.zeros_like(inputs)
+ num_channels_tensor = torch.IntTensor([self.hidden_size])
+
+ if global_conditioning is not None:
+ global_conditioning = self.cond_layer(global_conditioning)
+
+ for i in range(self.num_layers):
+ hidden_states = self.in_layers[i](inputs)
+
+ if global_conditioning is not None:
+ cond_offset = i * 2 * self.hidden_size
+ global_states = global_conditioning[:, cond_offset : cond_offset + 2 * self.hidden_size, :]
+ else:
+ global_states = torch.zeros_like(hidden_states)
+
+ acts = fused_add_tanh_sigmoid_multiply(hidden_states, global_states, num_channels_tensor[0])
+ acts = self.dropout(acts)
+
+ res_skip_acts = self.res_skip_layers[i](acts)
+ if i < self.num_layers - 1:
+ res_acts = res_skip_acts[:, : self.hidden_size, :]
+ inputs = (inputs + res_acts) * padding_mask
+ outputs = outputs + res_skip_acts[:, self.hidden_size :, :]
+ else:
+ outputs = outputs + res_skip_acts
+
+ return outputs * padding_mask
+
+ def remove_weight_norm(self):
+ if self.speaker_embedding_size != 0:
+ torch.nn.utils.remove_weight_norm(self.cond_layer)
+ for layer in self.in_layers:
+ torch.nn.utils.remove_weight_norm(layer)
+ for layer in self.res_skip_layers:
+ torch.nn.utils.remove_weight_norm(layer)
+
+
+class VitsPosteriorEncoder(nn.Module):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.out_channels = config.flow_size
+
+ self.conv_pre = nn.Conv1d(config.spectrogram_bins, config.hidden_size, 1)
+ self.wavenet = VitsWaveNet(config, num_layers=config.posterior_encoder_num_wavenet_layers)
+ self.conv_proj = nn.Conv1d(config.hidden_size, self.out_channels * 2, 1)
+
+ def forward(self, inputs, padding_mask, global_conditioning=None):
+ inputs = self.conv_pre(inputs) * padding_mask
+ inputs = self.wavenet(inputs, padding_mask, global_conditioning)
+ stats = self.conv_proj(inputs) * padding_mask
+ mean, log_stddev = torch.split(stats, self.out_channels, dim=1)
+ sampled = (mean + torch.randn_like(mean) * torch.exp(log_stddev)) * padding_mask
+ return sampled, mean, log_stddev
+
+
+# Copied from transformers.models.speecht5.modeling_speecht5.HifiGanResidualBlock
+class HifiGanResidualBlock(nn.Module):
+ def __init__(self, channels, kernel_size=3, dilation=(1, 3, 5), leaky_relu_slope=0.1):
+ super().__init__()
+ self.leaky_relu_slope = leaky_relu_slope
+
+ self.convs1 = nn.ModuleList(
+ [
+ nn.Conv1d(
+ channels,
+ channels,
+ kernel_size,
+ stride=1,
+ dilation=dilation[i],
+ padding=self.get_padding(kernel_size, dilation[i]),
+ )
+ for i in range(len(dilation))
+ ]
+ )
+ self.convs2 = nn.ModuleList(
+ [
+ nn.Conv1d(
+ channels,
+ channels,
+ kernel_size,
+ stride=1,
+ dilation=1,
+ padding=self.get_padding(kernel_size, 1),
+ )
+ for _ in range(len(dilation))
+ ]
+ )
+
+ def get_padding(self, kernel_size, dilation=1):
+ return (kernel_size * dilation - dilation) // 2
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ for layer in self.convs1:
+ weight_norm(layer)
+ for layer in self.convs2:
+ weight_norm(layer)
+
+ def remove_weight_norm(self):
+ for layer in self.convs1:
+ nn.utils.remove_weight_norm(layer)
+ for layer in self.convs2:
+ nn.utils.remove_weight_norm(layer)
+
+ def forward(self, hidden_states):
+ for conv1, conv2 in zip(self.convs1, self.convs2):
+ residual = hidden_states
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = conv1(hidden_states)
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope)
+ hidden_states = conv2(hidden_states)
+ hidden_states = hidden_states + residual
+ return hidden_states
+
+
+class VitsHifiGan(nn.Module):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.config = config
+ self.num_kernels = len(config.resblock_kernel_sizes)
+ self.num_upsamples = len(config.upsample_rates)
+ self.conv_pre = nn.Conv1d(
+ config.flow_size,
+ config.upsample_initial_channel,
+ kernel_size=7,
+ stride=1,
+ padding=3,
+ )
+
+ self.upsampler = nn.ModuleList()
+ for i, (upsample_rate, kernel_size) in enumerate(zip(config.upsample_rates, config.upsample_kernel_sizes)):
+ self.upsampler.append(
+ nn.ConvTranspose1d(
+ config.upsample_initial_channel // (2**i),
+ config.upsample_initial_channel // (2 ** (i + 1)),
+ kernel_size=kernel_size,
+ stride=upsample_rate,
+ padding=(kernel_size - upsample_rate) // 2,
+ )
+ )
+
+ self.resblocks = nn.ModuleList()
+ for i in range(len(self.upsampler)):
+ channels = config.upsample_initial_channel // (2 ** (i + 1))
+ for kernel_size, dilation in zip(config.resblock_kernel_sizes, config.resblock_dilation_sizes):
+ self.resblocks.append(HifiGanResidualBlock(channels, kernel_size, dilation, config.leaky_relu_slope))
+
+ self.conv_post = nn.Conv1d(channels, 1, kernel_size=7, stride=1, padding=3, bias=False)
+
+ if config.speaker_embedding_size != 0:
+ self.cond = nn.Conv1d(config.speaker_embedding_size, config.upsample_initial_channel, 1)
+
+ def apply_weight_norm(self):
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ for layer in self.upsampler:
+ weight_norm(layer)
+ for layer in self.resblocks:
+ layer.apply_weight_norm()
+
+ def remove_weight_norm(self):
+ for layer in self.upsampler:
+ nn.utils.remove_weight_norm(layer)
+ for layer in self.resblocks:
+ layer.remove_weight_norm()
+
+ def forward(
+ self, spectrogram: torch.FloatTensor, global_conditioning: Optional[torch.FloatTensor] = None
+ ) -> torch.FloatTensor:
+ r"""
+ Converts a spectrogram into a speech waveform.
+
+ Args:
+ spectrogram (`torch.FloatTensor` of shape `(batch_size, config.spectrogram_bins, sequence_length)`):
+ Tensor containing the spectrograms.
+ global_conditioning (`torch.FloatTensor` of shape `(batch_size, config.speaker_embedding_size, 1)`, *optional*):
+ Tensor containing speaker embeddings, for multispeaker models.
+
+ Returns:
+ `torch.FloatTensor`: Tensor of shape shape `(batch_size, 1, num_frames)` containing the speech waveform.
+ """
+ hidden_states = self.conv_pre(spectrogram)
+
+ if global_conditioning is not None:
+ hidden_states = hidden_states + self.cond(global_conditioning)
+
+ for i in range(self.num_upsamples):
+ hidden_states = nn.functional.leaky_relu(hidden_states, self.config.leaky_relu_slope)
+ hidden_states = self.upsampler[i](hidden_states)
+
+ res_state = self.resblocks[i * self.num_kernels](hidden_states)
+ for j in range(1, self.num_kernels):
+ res_state += self.resblocks[i * self.num_kernels + j](hidden_states)
+ hidden_states = res_state / self.num_kernels
+
+ hidden_states = nn.functional.leaky_relu(hidden_states)
+ hidden_states = self.conv_post(hidden_states)
+ waveform = torch.tanh(hidden_states)
+ return waveform
+
+
+class VitsResidualCouplingLayer(nn.Module):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.half_channels = config.flow_size // 2
+
+ self.conv_pre = nn.Conv1d(self.half_channels, config.hidden_size, 1)
+ self.wavenet = VitsWaveNet(config, num_layers=config.prior_encoder_num_wavenet_layers)
+ self.conv_post = nn.Conv1d(config.hidden_size, self.half_channels, 1)
+
+ def forward(self, inputs, padding_mask, global_conditioning=None, reverse=False):
+ first_half, second_half = torch.split(inputs, [self.half_channels] * 2, dim=1)
+ hidden_states = self.conv_pre(first_half) * padding_mask
+ hidden_states = self.wavenet(hidden_states, padding_mask, global_conditioning)
+ mean = self.conv_post(hidden_states) * padding_mask
+ log_stddev = torch.zeros_like(mean)
+
+ if not reverse:
+ second_half = mean + second_half * torch.exp(log_stddev) * padding_mask
+ outputs = torch.cat([first_half, second_half], dim=1)
+ log_determinant = torch.sum(log_stddev, [1, 2])
+ return outputs, log_determinant
+ else:
+ second_half = (second_half - mean) * torch.exp(-log_stddev) * padding_mask
+ outputs = torch.cat([first_half, second_half], dim=1)
+ return outputs, None
+
+
+class VitsResidualCouplingBlock(nn.Module):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.flows = nn.ModuleList()
+ for _ in range(config.prior_encoder_num_flows):
+ self.flows.append(VitsResidualCouplingLayer(config))
+
+ def forward(self, inputs, padding_mask, global_conditioning=None, reverse=False):
+ if not reverse:
+ for flow in self.flows:
+ inputs, _ = flow(inputs, padding_mask, global_conditioning)
+ inputs = torch.flip(inputs, [1])
+ else:
+ for flow in reversed(self.flows):
+ inputs = torch.flip(inputs, [1])
+ inputs, _ = flow(inputs, padding_mask, global_conditioning, reverse=True)
+ return inputs
+
+
+class VitsDilatedDepthSeparableConv(nn.Module):
+ def __init__(self, config: VitsConfig, dropout_rate=0.0):
+ super().__init__()
+ kernel_size = config.duration_predictor_kernel_size
+ channels = config.hidden_size
+ self.num_layers = config.depth_separable_num_layers
+
+ self.dropout = nn.Dropout(dropout_rate)
+ self.convs_dilated = nn.ModuleList()
+ self.convs_pointwise = nn.ModuleList()
+ self.norms_1 = nn.ModuleList()
+ self.norms_2 = nn.ModuleList()
+ for i in range(self.num_layers):
+ dilation = kernel_size**i
+ padding = (kernel_size * dilation - dilation) // 2
+ self.convs_dilated.append(
+ nn.Conv1d(
+ in_channels=channels,
+ out_channels=channels,
+ kernel_size=kernel_size,
+ groups=channels,
+ dilation=dilation,
+ padding=padding,
+ )
+ )
+ self.convs_pointwise.append(nn.Conv1d(channels, channels, 1))
+ self.norms_1.append(nn.LayerNorm(channels))
+ self.norms_2.append(nn.LayerNorm(channels))
+
+ def forward(self, inputs, padding_mask, global_conditioning=None):
+ if global_conditioning is not None:
+ inputs = inputs + global_conditioning
+
+ for i in range(self.num_layers):
+ hidden_states = self.convs_dilated[i](inputs * padding_mask)
+ hidden_states = self.norms_1[i](hidden_states.transpose(1, -1)).transpose(1, -1)
+ hidden_states = nn.functional.gelu(hidden_states)
+ hidden_states = self.convs_pointwise[i](hidden_states)
+ hidden_states = self.norms_2[i](hidden_states.transpose(1, -1)).transpose(1, -1)
+ hidden_states = nn.functional.gelu(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ inputs = inputs + hidden_states
+
+ return inputs * padding_mask
+
+
+class VitsConvFlow(nn.Module):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.filter_channels = config.hidden_size
+ self.half_channels = config.depth_separable_channels // 2
+ self.num_bins = config.duration_predictor_flow_bins
+ self.tail_bound = config.duration_predictor_tail_bound
+
+ self.conv_pre = nn.Conv1d(self.half_channels, self.filter_channels, 1)
+ self.conv_dds = VitsDilatedDepthSeparableConv(config)
+ self.conv_proj = nn.Conv1d(self.filter_channels, self.half_channels * (self.num_bins * 3 - 1), 1)
+
+ def forward(self, inputs, padding_mask, global_conditioning=None, reverse=False):
+ first_half, second_half = torch.split(inputs, [self.half_channels] * 2, dim=1)
+
+ hidden_states = self.conv_pre(first_half)
+ hidden_states = self.conv_dds(hidden_states, padding_mask, global_conditioning)
+ hidden_states = self.conv_proj(hidden_states) * padding_mask
+
+ batch_size, channels, length = first_half.shape
+ hidden_states = hidden_states.reshape(batch_size, channels, -1, length).permute(0, 1, 3, 2)
+
+ unnormalized_widths = hidden_states[..., : self.num_bins] / math.sqrt(self.filter_channels)
+ unnormalized_heights = hidden_states[..., self.num_bins : 2 * self.num_bins] / math.sqrt(self.filter_channels)
+ unnormalized_derivatives = hidden_states[..., 2 * self.num_bins :]
+
+ second_half, log_abs_det = _unconstrained_rational_quadratic_spline(
+ second_half,
+ unnormalized_widths,
+ unnormalized_heights,
+ unnormalized_derivatives,
+ reverse=reverse,
+ tail_bound=self.tail_bound,
+ )
+
+ outputs = torch.cat([first_half, second_half], dim=1) * padding_mask
+ if not reverse:
+ log_determinant = torch.sum(log_abs_det * padding_mask, [1, 2])
+ return outputs, log_determinant
+ else:
+ return outputs, None
+
+
+class VitsElementwiseAffine(nn.Module):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.channels = config.depth_separable_channels
+ self.translate = nn.Parameter(torch.zeros(self.channels, 1))
+ self.log_scale = nn.Parameter(torch.zeros(self.channels, 1))
+
+ def forward(self, inputs, padding_mask, global_conditioning=None, reverse=False):
+ if not reverse:
+ outputs = self.translate + torch.exp(self.log_scale) * inputs
+ outputs = outputs * padding_mask
+ log_determinant = torch.sum(self.log_scale * padding_mask, [1, 2])
+ return outputs, log_determinant
+ else:
+ outputs = (inputs - self.translate) * torch.exp(-self.log_scale) * padding_mask
+ return outputs, None
+
+
+class VitsStochasticDurationPredictor(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.speaker_embedding_size
+ filter_channels = config.hidden_size
+
+ self.conv_pre = nn.Conv1d(filter_channels, filter_channels, 1)
+ self.conv_proj = nn.Conv1d(filter_channels, filter_channels, 1)
+ self.conv_dds = VitsDilatedDepthSeparableConv(
+ config,
+ dropout_rate=config.duration_predictor_dropout,
+ )
+
+ if embed_dim != 0:
+ self.cond = nn.Conv1d(embed_dim, filter_channels, 1)
+
+ self.flows = nn.ModuleList()
+ self.flows.append(VitsElementwiseAffine(config))
+ for _ in range(config.duration_predictor_num_flows):
+ self.flows.append(VitsConvFlow(config))
+
+ self.post_conv_pre = nn.Conv1d(1, filter_channels, 1)
+ self.post_conv_proj = nn.Conv1d(filter_channels, filter_channels, 1)
+ self.post_conv_dds = VitsDilatedDepthSeparableConv(
+ config,
+ dropout_rate=config.duration_predictor_dropout,
+ )
+
+ self.post_flows = nn.ModuleList()
+ self.post_flows.append(VitsElementwiseAffine(config))
+ for _ in range(config.duration_predictor_num_flows):
+ self.post_flows.append(VitsConvFlow(config))
+
+ def forward(self, inputs, padding_mask, global_conditioning=None, durations=None, reverse=False, noise_scale=1.0):
+ inputs = torch.detach(inputs)
+ inputs = self.conv_pre(inputs)
+
+ if global_conditioning is not None:
+ global_conditioning = torch.detach(global_conditioning)
+ inputs = inputs + self.cond(global_conditioning)
+
+ inputs = self.conv_dds(inputs, padding_mask)
+ inputs = self.conv_proj(inputs) * padding_mask
+
+ if not reverse:
+ hidden_states = self.post_conv_pre(durations)
+ hidden_states = self.post_conv_dds(hidden_states, padding_mask)
+ hidden_states = self.post_conv_proj(hidden_states) * padding_mask
+
+ random_posterior = (
+ torch.randn(durations.size(0), 2, durations.size(2)).to(device=inputs.device, dtype=inputs.dtype)
+ * padding_mask
+ )
+ log_determinant_posterior_sum = 0
+ latents_posterior = random_posterior
+ for flow in self.post_flows:
+ latents_posterior, log_determinant = flow(
+ latents_posterior, padding_mask, global_conditioning=inputs + hidden_states
+ )
+ latents_posterior = torch.flip(latents_posterior, [1])
+ log_determinant_posterior_sum += log_determinant
+
+ first_half, second_half = torch.split(latents_posterior, [1, 1], dim=1)
+
+ log_determinant_posterior_sum += torch.sum(
+ (nn.functional.logsigmoid(first_half) + nn.functional.logsigmoid(-first_half)) * padding_mask, [1, 2]
+ )
+ logq = (
+ torch.sum(-0.5 * (math.log(2 * math.pi) + (random_posterior**2)) * padding_mask, [1, 2])
+ - log_determinant_posterior_sum
+ )
+
+ first_half = (durations - torch.sigmoid(first_half)) * padding_mask
+ first_half = torch.log(torch.clamp_min(first_half, 1e-5)) * padding_mask
+ log_determinant_sum = torch.sum(-first_half, [1, 2])
+
+ latents = torch.cat([first_half, second_half], dim=1)
+ for flow in self.flows:
+ latents, log_determinant = flow(latents, padding_mask, global_conditioning=inputs)
+ latents = torch.flip(latents, [1])
+ log_determinant_sum += log_determinant
+
+ nll = torch.sum(0.5 * (math.log(2 * math.pi) + (latents**2)) * padding_mask, [1, 2]) - log_determinant_sum
+ return nll + logq
+ else:
+ flows = list(reversed(self.flows))
+ flows = flows[:-2] + [flows[-1]] # remove a useless vflow
+
+ latents = (
+ torch.randn(inputs.size(0), 2, inputs.size(2)).to(device=inputs.device, dtype=inputs.dtype)
+ * noise_scale
+ )
+ for flow in flows:
+ latents = torch.flip(latents, [1])
+ latents, _ = flow(latents, padding_mask, global_conditioning=inputs, reverse=True)
+
+ log_duration, _ = torch.split(latents, [1, 1], dim=1)
+ return log_duration
+
+
+class VitsDurationPredictor(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ kernel_size = config.duration_predictor_kernel_size
+ filter_channels = config.duration_predictor_filter_channels
+
+ self.dropout = nn.Dropout(config.duration_predictor_dropout)
+ self.conv_1 = nn.Conv1d(config.hidden_size, filter_channels, kernel_size, padding=kernel_size // 2)
+ self.norm_1 = nn.LayerNorm(filter_channels, eps=config.layer_norm_eps)
+ self.conv_2 = nn.Conv1d(filter_channels, filter_channels, kernel_size, padding=kernel_size // 2)
+ self.norm_2 = nn.LayerNorm(filter_channels, eps=config.layer_norm_eps)
+ self.proj = nn.Conv1d(filter_channels, 1, 1)
+
+ if config.speaker_embedding_size != 0:
+ self.cond = nn.Conv1d(config.speaker_embedding_size, config.hidden_size, 1)
+
+ def forward(self, inputs, padding_mask, global_conditioning=None):
+ inputs = torch.detach(inputs)
+
+ if global_conditioning is not None:
+ global_conditioning = torch.detach(global_conditioning)
+ inputs = inputs + self.cond(global_conditioning)
+
+ inputs = self.conv_1(inputs * padding_mask)
+ inputs = torch.relu(inputs)
+ inputs = self.norm_1(inputs.transpose(1, -1)).transpose(1, -1)
+ inputs = self.dropout(inputs)
+
+ inputs = self.conv_2(inputs * padding_mask)
+ inputs = torch.relu(inputs)
+ inputs = self.norm_2(inputs.transpose(1, -1)).transpose(1, -1)
+ inputs = self.dropout(inputs)
+
+ inputs = self.proj(inputs * padding_mask)
+ return inputs * padding_mask
+
+
+class VitsAttention(nn.Module):
+ """Multi-headed attention with relative positional representation."""
+
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.dropout = config.attention_dropout
+ self.window_size = config.window_size
+
+ self.head_dim = self.embed_dim // self.num_heads
+ self.scaling = self.head_dim**-0.5
+
+ if (self.head_dim * self.num_heads) != self.embed_dim:
+ raise ValueError(
+ f"hidden_size must be divisible by num_attention_heads (got `hidden_size`: {self.embed_dim}"
+ f" and `num_attention_heads`: {self.num_heads})."
+ )
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=config.use_bias)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=config.use_bias)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=config.use_bias)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=config.use_bias)
+
+ if self.window_size:
+ self.emb_rel_k = nn.Parameter(torch.randn(1, self.window_size * 2 + 1, self.head_dim) * self.scaling)
+ self.emb_rel_v = nn.Parameter(torch.randn(1, self.window_size * 2 + 1, self.head_dim) * self.scaling)
+
+ def _shape(self, tensor: torch.Tensor, seq_len: int, bsz: int):
+ return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+
+ bsz, tgt_len, _ = hidden_states.size()
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+
+ # self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = self._shape(query_states, tgt_len, bsz).view(*proj_shape)
+ key_states = key_states.view(*proj_shape)
+ value_states = value_states.view(*proj_shape)
+
+ src_len = key_states.size(1)
+ attn_weights = torch.bmm(query_states, key_states.transpose(1, 2))
+
+ if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len):
+ raise ValueError(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ if self.window_size is not None:
+ key_relative_embeddings = self._get_relative_embeddings(self.emb_rel_k, src_len)
+ relative_logits = torch.matmul(query_states, key_relative_embeddings.transpose(-2, -1))
+ rel_pos_bias = self._relative_position_to_absolute_position(relative_logits)
+ attn_weights += rel_pos_bias
+
+ if attention_mask is not None:
+ if attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is {attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attention_mask
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if layer_head_mask is not None:
+ if layer_head_mask.size() != (self.num_heads,):
+ raise ValueError(
+ f"Head mask for a single layer should be of size {(self.num_heads,)}, but is"
+ f" {layer_head_mask.size()}"
+ )
+ attn_weights = layer_head_mask.view(1, -1, 1, 1) * attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ if output_attentions:
+ # this operation is a bit awkward, but it's required to
+ # make sure that attn_weights keeps its gradient.
+ # In order to do so, attn_weights have to be reshaped
+ # twice and have to be reused in the following
+ attn_weights_reshaped = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights_reshaped.view(bsz * self.num_heads, tgt_len, src_len)
+ else:
+ attn_weights_reshaped = None
+
+ attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ attn_output = torch.bmm(attn_probs, value_states)
+
+ if attn_output.size() != (bsz * self.num_heads, tgt_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ if self.window_size is not None:
+ value_relative_embeddings = self._get_relative_embeddings(self.emb_rel_v, src_len)
+ relative_weights = self._absolute_position_to_relative_position(attn_probs)
+ rel_pos_bias = torch.matmul(relative_weights, value_relative_embeddings)
+ attn_output += rel_pos_bias
+
+ attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim)
+ attn_output = attn_output.transpose(1, 2)
+
+ # Use the `embed_dim` from the config (stored in the class) rather than `hidden_state` because `attn_output` can be
+ # partitioned aross GPUs when using tensor-parallelism.
+ attn_output = attn_output.reshape(bsz, tgt_len, self.embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights_reshaped
+
+ def _get_relative_embeddings(self, relative_embeddings, length):
+ pad_length = max(length - (self.window_size + 1), 0)
+ if pad_length > 0:
+ relative_embeddings = nn.functional.pad(relative_embeddings, [0, 0, pad_length, pad_length, 0, 0])
+
+ slice_start_position = max((self.window_size + 1) - length, 0)
+ slice_end_position = slice_start_position + 2 * length - 1
+ return relative_embeddings[:, slice_start_position:slice_end_position]
+
+ def _relative_position_to_absolute_position(self, x):
+ batch_heads, length, _ = x.size()
+
+ # Concat columns of pad to shift from relative to absolute indexing.
+ x = nn.functional.pad(x, [0, 1, 0, 0, 0, 0])
+
+ # Concat extra elements so to add up to shape (len+1, 2*len-1).
+ x_flat = x.view([batch_heads, length * 2 * length])
+ x_flat = nn.functional.pad(x_flat, [0, length - 1, 0, 0])
+
+ # Reshape and slice out the padded elements.
+ x_final = x_flat.view([batch_heads, length + 1, 2 * length - 1])
+ x_final = x_final[:, :length, length - 1 :]
+ return x_final
+
+ def _absolute_position_to_relative_position(self, x):
+ batch_heads, length, _ = x.size()
+
+ # Pad along column
+ x = nn.functional.pad(x, [0, length - 1, 0, 0, 0, 0])
+ x_flat = x.view([batch_heads, length * (2 * length - 1)])
+
+ # Add 0's in the beginning that will skew the elements after reshape
+ x_flat = nn.functional.pad(x_flat, [length, 0, 0, 0])
+ x_final = x_flat.view([batch_heads, length, 2 * length])[:, :, 1:]
+ return x_final
+
+
+class VitsFeedForward(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv_1 = nn.Conv1d(config.hidden_size, config.ffn_dim, config.ffn_kernel_size)
+ self.conv_2 = nn.Conv1d(config.ffn_dim, config.hidden_size, config.ffn_kernel_size)
+ self.dropout = nn.Dropout(config.activation_dropout)
+
+ if isinstance(config.hidden_act, str):
+ self.act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.act_fn = config.hidden_act
+
+ if config.ffn_kernel_size > 1:
+ pad_left = (config.ffn_kernel_size - 1) // 2
+ pad_right = config.ffn_kernel_size // 2
+ self.padding = [pad_left, pad_right, 0, 0, 0, 0]
+ else:
+ self.padding = None
+
+ def forward(self, hidden_states, padding_mask):
+ hidden_states = hidden_states.permute(0, 2, 1)
+ padding_mask = padding_mask.permute(0, 2, 1)
+
+ hidden_states = hidden_states * padding_mask
+ if self.padding is not None:
+ hidden_states = nn.functional.pad(hidden_states, self.padding)
+
+ hidden_states = self.conv_1(hidden_states)
+ hidden_states = self.act_fn(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ hidden_states = hidden_states * padding_mask
+ if self.padding is not None:
+ hidden_states = nn.functional.pad(hidden_states, self.padding)
+
+ hidden_states = self.conv_2(hidden_states)
+ hidden_states = hidden_states * padding_mask
+
+ hidden_states = hidden_states.permute(0, 2, 1)
+ return hidden_states
+
+
+class VitsEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.attention = VitsAttention(config)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = VitsFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ padding_mask: torch.FloatTensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ residual = hidden_states
+ hidden_states, attn_weights = self.attention(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.layer_norm(residual + hidden_states)
+
+ residual = hidden_states
+ hidden_states = self.feed_forward(hidden_states, padding_mask)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.final_layer_norm(residual + hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class VitsEncoder(nn.Module):
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.config = config
+ self.layers = nn.ModuleList([VitsEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+ self.layerdrop = config.layerdrop
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ padding_mask: torch.FloatTensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ # expand attention_mask
+ if attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_states.dtype)
+
+ hidden_states = hidden_states * padding_mask
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for encoder_layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = np.random.uniform(0, 1)
+
+ skip_the_layer = self.training and (dropout_probability < self.layerdrop)
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ padding_mask=padding_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = hidden_states * padding_mask
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class VitsTextEncoder(nn.Module):
+ """
+ Transformer encoder that uses relative positional representation instead of absolute positional encoding.
+ """
+
+ def __init__(self, config: VitsConfig):
+ super().__init__()
+ self.config = config
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id)
+ self.encoder = VitsEncoder(config)
+ self.project = nn.Conv1d(config.hidden_size, config.flow_size * 2, kernel_size=1)
+
+ def forward(
+ self,
+ input_ids: torch.Tensor,
+ padding_mask: torch.FloatTensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = True,
+ ) -> Union[tuple[torch.Tensor], VitsTextEncoderOutput]:
+ hidden_states = self.embed_tokens(input_ids) * math.sqrt(self.config.hidden_size)
+
+ encoder_outputs = self.encoder(
+ hidden_states=hidden_states,
+ padding_mask=padding_mask,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_state = encoder_outputs[0] if not return_dict else encoder_outputs.last_hidden_state
+
+ stats = self.project(last_hidden_state.transpose(1, 2)).transpose(1, 2) * padding_mask
+ prior_means, prior_log_variances = torch.split(stats, self.config.flow_size, dim=2)
+
+ if not return_dict:
+ outputs = (last_hidden_state, prior_means, prior_log_variances) + encoder_outputs[1:]
+ return outputs
+
+ return VitsTextEncoderOutput(
+ last_hidden_state=last_hidden_state,
+ prior_means=prior_means,
+ prior_log_variances=prior_log_variances,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring
+class VitsPreTrainedModel(PreTrainedModel):
+ config: VitsConfig
+ base_model_prefix = "vits"
+ main_input_name = "input_ids"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module: nn.Module):
+ """Initialize the weights"""
+ std = self.config.initializer_range
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, (nn.Conv1d, nn.ConvTranspose1d)):
+ nn.init.kaiming_normal_(module.weight)
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, VitsAttention):
+ if self.config.window_size:
+ head_dim = self.config.hidden_size // self.config.num_attention_heads
+ nn.init.normal_(module.emb_rel_k, std=head_dim**-0.5)
+ nn.init.normal_(module.emb_rel_v, std=head_dim**-0.5)
+ elif isinstance(module, VitsElementwiseAffine):
+ module.translate.data.zero_()
+ module.log_scale.data.zero_()
+
+
+@auto_docstring(
+ custom_intro="""
+ The complete VITS model, for text-to-speech synthesis.
+ """
+)
+class VitsModel(VitsPreTrainedModel):
+ def __init__(self, config: VitsConfig):
+ super().__init__(config)
+ self.config = config
+ self.text_encoder = VitsTextEncoder(config)
+ self.flow = VitsResidualCouplingBlock(config)
+ self.decoder = VitsHifiGan(config)
+
+ if config.use_stochastic_duration_prediction:
+ self.duration_predictor = VitsStochasticDurationPredictor(config)
+ else:
+ self.duration_predictor = VitsDurationPredictor(config)
+
+ if config.num_speakers > 1:
+ self.embed_speaker = nn.Embedding(config.num_speakers, config.speaker_embedding_size)
+
+ # This is used only for training.
+ self.posterior_encoder = VitsPosteriorEncoder(config)
+
+ # These parameters control the synthesised speech properties
+ self.speaking_rate = config.speaking_rate
+ self.noise_scale = config.noise_scale
+ self.noise_scale_duration = config.noise_scale_duration
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_encoder(self):
+ return self.text_encoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ speaker_id: Optional[int] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.FloatTensor] = None,
+ ) -> Union[tuple[Any], VitsModelOutput]:
+ r"""
+ speaker_id (`int`, *optional*):
+ Which speaker embedding to use. Only used for multispeaker models.
+ labels (`torch.FloatTensor` of shape `(batch_size, config.spectrogram_bins, sequence_length)`, *optional*):
+ Float values of target spectrogram. Timesteps set to `-100.0` are ignored (masked) for the loss
+ computation.
+
+ Example:
+
+ ```python
+ >>> from transformers import VitsTokenizer, VitsModel, set_seed
+ >>> import torch
+
+ >>> tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-eng")
+ >>> model = VitsModel.from_pretrained("facebook/mms-tts-eng")
+
+ >>> inputs = tokenizer(text="Hello - my dog is cute", return_tensors="pt")
+
+ >>> set_seed(555) # make deterministic
+
+ >>> with torch.no_grad():
+ ... outputs = model(inputs["input_ids"])
+ >>> outputs.waveform.shape
+ torch.Size([1, 45824])
+ ```
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ raise NotImplementedError("Training of VITS is not supported yet.")
+
+ mask_dtype = self.text_encoder.embed_tokens.weight.dtype
+ if attention_mask is not None:
+ input_padding_mask = attention_mask.unsqueeze(-1).to(mask_dtype)
+ else:
+ input_padding_mask = torch.ones_like(input_ids).unsqueeze(-1).to(mask_dtype)
+
+ if self.config.num_speakers > 1 and speaker_id is not None:
+ if not 0 <= speaker_id < self.config.num_speakers:
+ raise ValueError(f"Set `speaker_id` in the range 0-{self.config.num_speakers - 1}.")
+ if isinstance(speaker_id, int):
+ speaker_id = torch.full(size=(1,), fill_value=speaker_id, device=self.device)
+ speaker_embeddings = self.embed_speaker(speaker_id).unsqueeze(-1)
+ else:
+ speaker_embeddings = None
+
+ text_encoder_output = self.text_encoder(
+ input_ids=input_ids,
+ padding_mask=input_padding_mask,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ hidden_states = text_encoder_output[0] if not return_dict else text_encoder_output.last_hidden_state
+ hidden_states = hidden_states.transpose(1, 2)
+ input_padding_mask = input_padding_mask.transpose(1, 2)
+ prior_means = text_encoder_output[1] if not return_dict else text_encoder_output.prior_means
+ prior_log_variances = text_encoder_output[2] if not return_dict else text_encoder_output.prior_log_variances
+
+ if self.config.use_stochastic_duration_prediction:
+ log_duration = self.duration_predictor(
+ hidden_states,
+ input_padding_mask,
+ speaker_embeddings,
+ reverse=True,
+ noise_scale=self.noise_scale_duration,
+ )
+ else:
+ log_duration = self.duration_predictor(hidden_states, input_padding_mask, speaker_embeddings)
+
+ length_scale = 1.0 / self.speaking_rate
+ duration = torch.ceil(torch.exp(log_duration) * input_padding_mask * length_scale)
+ predicted_lengths = torch.clamp_min(torch.sum(duration, [1, 2]), 1).long()
+
+ # Create a padding mask for the output lengths of shape (batch, 1, max_output_length)
+ indices = torch.arange(predicted_lengths.max(), dtype=predicted_lengths.dtype, device=predicted_lengths.device)
+ output_padding_mask = indices.unsqueeze(0) < predicted_lengths.unsqueeze(1)
+ output_padding_mask = output_padding_mask.unsqueeze(1).to(input_padding_mask.dtype)
+
+ # Reconstruct an attention tensor of shape (batch, 1, out_length, in_length)
+ attn_mask = torch.unsqueeze(input_padding_mask, 2) * torch.unsqueeze(output_padding_mask, -1)
+ batch_size, _, output_length, input_length = attn_mask.shape
+ cum_duration = torch.cumsum(duration, -1).view(batch_size * input_length, 1)
+ indices = torch.arange(output_length, dtype=duration.dtype, device=duration.device)
+ valid_indices = indices.unsqueeze(0) < cum_duration
+ valid_indices = valid_indices.to(attn_mask.dtype).view(batch_size, input_length, output_length)
+ padded_indices = valid_indices - nn.functional.pad(valid_indices, [0, 0, 1, 0, 0, 0])[:, :-1]
+ attn = padded_indices.unsqueeze(1).transpose(2, 3) * attn_mask
+
+ # Expand prior distribution
+ prior_means = torch.matmul(attn.squeeze(1), prior_means).transpose(1, 2)
+ prior_log_variances = torch.matmul(attn.squeeze(1), prior_log_variances).transpose(1, 2)
+
+ prior_latents = prior_means + torch.randn_like(prior_means) * torch.exp(prior_log_variances) * self.noise_scale
+ latents = self.flow(prior_latents, output_padding_mask, speaker_embeddings, reverse=True)
+
+ spectrogram = latents * output_padding_mask
+ waveform = self.decoder(spectrogram, speaker_embeddings)
+ waveform = waveform.squeeze(1)
+ sequence_lengths = predicted_lengths * np.prod(self.config.upsample_rates)
+
+ if not return_dict:
+ outputs = (waveform, sequence_lengths, spectrogram) + text_encoder_output[3:]
+ return outputs
+
+ return VitsModelOutput(
+ waveform=waveform,
+ sequence_lengths=sequence_lengths,
+ spectrogram=spectrogram,
+ hidden_states=text_encoder_output.hidden_states,
+ attentions=text_encoder_output.attentions,
+ )
+
+
+__all__ = ["VitsModel", "VitsPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/tokenization_vits.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/tokenization_vits.py
new file mode 100644
index 0000000000000000000000000000000000000000..cf2d47bc4e885968e681e65cf33f3e2e9954113c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vits/tokenization_vits.py
@@ -0,0 +1,246 @@
+# coding=utf-8
+# Copyright 2023 The Kakao Enterprise Authors, the MMS-TTS Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for VITS."""
+
+import json
+import os
+import re
+from typing import Any, Optional, Union
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...utils import is_phonemizer_available, is_uroman_available, logging
+
+
+if is_phonemizer_available():
+ import phonemizer
+
+if is_uroman_available():
+ import uroman as ur
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "vocab.json"}
+
+
+def has_non_roman_characters(input_string):
+ # Find any character outside the ASCII range
+ non_roman_pattern = re.compile(r"[^\x00-\x7F]")
+
+ # Search the input string for non-Roman characters
+ match = non_roman_pattern.search(input_string)
+ has_non_roman = match is not None
+ return has_non_roman
+
+
+class VitsTokenizer(PreTrainedTokenizer):
+ """
+ Construct a VITS tokenizer. Also supports MMS-TTS.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ Path to the vocabulary file.
+ language (`str`, *optional*):
+ Language identifier.
+ add_blank (`bool`, *optional*, defaults to `True`):
+ Whether to insert token id 0 in between the other tokens.
+ normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the input text by removing all casing and punctuation.
+ phonemize (`bool`, *optional*, defaults to `True`):
+ Whether to convert the input text into phonemes.
+ is_uroman (`bool`, *optional*, defaults to `False`):
+ Whether the `uroman` Romanizer needs to be applied to the input text prior to tokenizing.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ pad_token="",
+ unk_token="",
+ language=None,
+ add_blank=True,
+ normalize=True,
+ phonemize=True,
+ is_uroman=False,
+ **kwargs,
+ ) -> None:
+ with open(vocab_file, encoding="utf-8") as vocab_handle:
+ self.encoder = json.load(vocab_handle)
+
+ self.decoder = {v: k for k, v in self.encoder.items()}
+ self.language = language
+ self.add_blank = add_blank
+ self.normalize = normalize
+ self.phonemize = phonemize
+
+ self.is_uroman = is_uroman
+
+ super().__init__(
+ pad_token=pad_token,
+ unk_token=unk_token,
+ language=language,
+ add_blank=add_blank,
+ normalize=normalize,
+ phonemize=phonemize,
+ is_uroman=is_uroman,
+ **kwargs,
+ )
+
+ @property
+ def vocab_size(self):
+ return len(self.encoder)
+
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def normalize_text(self, input_string):
+ """Lowercase the input string, respecting any special token ids that may be part or entirely upper-cased."""
+ all_vocabulary = list(self.encoder.keys()) + list(self.added_tokens_encoder.keys())
+ filtered_text = ""
+
+ i = 0
+ while i < len(input_string):
+ found_match = False
+ for word in all_vocabulary:
+ if input_string[i : i + len(word)] == word:
+ filtered_text += word
+ i += len(word)
+ found_match = True
+ break
+
+ if not found_match:
+ filtered_text += input_string[i].lower()
+ i += 1
+
+ return filtered_text
+
+ def _preprocess_char(self, text):
+ """Special treatment of characters in certain languages"""
+ if self.language == "ron":
+ text = text.replace("ț", "ţ")
+ return text
+
+ def prepare_for_tokenization(
+ self, text: str, is_split_into_words: bool = False, normalize: Optional[bool] = None, **kwargs
+ ) -> tuple[str, dict[str, Any]]:
+ """
+ Performs any necessary transformations before tokenization.
+
+ This method should pop the arguments from kwargs and return the remaining `kwargs` as well. We test the
+ `kwargs` at the end of the encoding process to be sure all the arguments have been used.
+
+ Args:
+ text (`str`):
+ The text to prepare.
+ is_split_into_words (`bool`, *optional*, defaults to `False`):
+ Whether or not the input is already pre-tokenized (e.g., split into words). If set to `True`, the
+ tokenizer assumes the input is already split into words (for instance, by splitting it on whitespace)
+ which it will tokenize.
+ normalize (`bool`, *optional*, defaults to `None`):
+ Whether or not to apply punctuation and casing normalization to the text inputs. Typically, VITS is
+ trained on lower-cased and un-punctuated text. Hence, normalization is used to ensure that the input
+ text consists only of lower-case characters.
+ kwargs (`dict[str, Any]`, *optional*):
+ Keyword arguments to use for the tokenization.
+
+ Returns:
+ `tuple[str, dict[str, Any]]`: The prepared text and the unused kwargs.
+ """
+ normalize = normalize if normalize is not None else self.normalize
+
+ if normalize:
+ # normalise for casing
+ text = self.normalize_text(text)
+
+ filtered_text = self._preprocess_char(text)
+
+ if has_non_roman_characters(filtered_text) and self.is_uroman:
+ if not is_uroman_available():
+ logger.warning(
+ "Text to the tokenizer contains non-Roman characters. To apply the `uroman` pre-processing "
+ "step automatically, ensure the `uroman` Romanizer is installed with: `pip install uroman` "
+ "Note `uroman` requires python version >= 3.10"
+ "Otherwise, apply the Romanizer manually as per the instructions: https://github.com/isi-nlp/uroman"
+ )
+ else:
+ uroman = ur.Uroman()
+ filtered_text = uroman.romanize_string(filtered_text)
+
+ if self.phonemize:
+ if not is_phonemizer_available():
+ raise ImportError("Please install the `phonemizer` Python package to use this tokenizer.")
+
+ filtered_text = phonemizer.phonemize(
+ filtered_text,
+ language="en-us",
+ backend="espeak",
+ strip=True,
+ preserve_punctuation=True,
+ with_stress=True,
+ )
+ filtered_text = re.sub(r"\s+", " ", filtered_text)
+ elif normalize:
+ # strip any chars outside of the vocab (punctuation)
+ filtered_text = "".join(list(filter(lambda char: char in self.encoder, filtered_text))).strip()
+
+ return filtered_text, kwargs
+
+ def _tokenize(self, text: str) -> list[str]:
+ """Tokenize a string by inserting the `` token at the boundary between adjacent characters."""
+ tokens = list(text)
+
+ if self.add_blank:
+ interspersed = [self._convert_id_to_token(0)] * (len(tokens) * 2 + 1)
+ interspersed[1::2] = tokens
+ tokens = interspersed
+
+ return tokens
+
+ def convert_tokens_to_string(self, tokens: list[str]) -> str:
+ if self.add_blank and len(tokens) > 1:
+ tokens = tokens[1::2]
+ return "".join(tokens)
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.encoder.get(token, self.encoder.get(self.unk_token))
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ return self.decoder.get(index)
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> Union[tuple[str], None]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ with open(vocab_file, "w", encoding="utf-8") as f:
+ f.write(json.dumps(self.encoder, indent=2, sort_keys=True, ensure_ascii=False) + "\n")
+
+ return (vocab_file,)
+
+
+__all__ = ["VitsTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..13c52cbcff0b3fc6dc3255f41729754991dd3c8f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vivit import *
+ from .image_processing_vivit import *
+ from .modeling_vivit import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/configuration_vivit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/configuration_vivit.py
new file mode 100644
index 0000000000000000000000000000000000000000..02c776b3500399200000e0a389d41f37f52dfab4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/configuration_vivit.py
@@ -0,0 +1,119 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""ViViT model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class VivitConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VivitModel`]. It is used to instantiate a ViViT
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the ViViT
+ [google/vivit-b-16x2-kinetics400](https://huggingface.co/google/vivit-b-16x2-kinetics400) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ num_frames (`int`, *optional*, defaults to 32):
+ The number of frames in each video.
+ tubelet_size (`list[int]`, *optional*, defaults to `[2, 16, 16]`):
+ The size (resolution) of each tubelet.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu_fast"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"`, `"gelu_fast"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+
+ Example:
+
+ ```python
+ >>> from transformers import VivitConfig, VivitModel
+
+ >>> # Initializing a ViViT google/vivit-b-16x2-kinetics400 style configuration
+ >>> configuration = VivitConfig()
+
+ >>> # Initializing a model (with random weights) from the google/vivit-b-16x2-kinetics400 style configuration
+ >>> model = VivitModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vivit"
+
+ def __init__(
+ self,
+ image_size=224,
+ num_frames=32,
+ tubelet_size=[2, 16, 16],
+ num_channels=3,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu_fast",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-06,
+ qkv_bias=True,
+ **kwargs,
+ ):
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+
+ self.image_size = image_size
+ self.num_frames = num_frames
+ self.tubelet_size = tubelet_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+
+ super().__init__(**kwargs)
+
+
+__all__ = ["VivitConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/image_processing_vivit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/image_processing_vivit.py
new file mode 100644
index 0000000000000000000000000000000000000000..140f7fc5fe7f4b267a45e38f70b15c04cfc6aa9f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/image_processing_vivit.py
@@ -0,0 +1,407 @@
+# coding=utf-8
+# Copyright 2023 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for Vivit."""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from transformers.utils import is_vision_available
+from transformers.utils.generic import TensorType
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import (
+ get_resize_output_image_size,
+ rescale,
+ resize,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ is_valid_image,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import filter_out_non_signature_kwargs, logging
+
+
+if is_vision_available():
+ import PIL
+
+logger = logging.get_logger(__name__)
+
+
+def make_batched(videos) -> list[list[ImageInput]]:
+ if isinstance(videos, (list, tuple)) and isinstance(videos[0], (list, tuple)) and is_valid_image(videos[0][0]):
+ return videos
+
+ elif isinstance(videos, (list, tuple)) and is_valid_image(videos[0]):
+ return [videos]
+
+ elif is_valid_image(videos):
+ return [[videos]]
+
+ raise ValueError(f"Could not make batched video from {videos}")
+
+
+class VivitImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a Vivit image processor.
+
+ Args:
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by the
+ `do_resize` parameter in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"shortest_edge": 256}`):
+ Size of the output image after resizing. The shortest edge of the image will be resized to
+ `size["shortest_edge"]` while maintaining the aspect ratio of the original image. Can be overridden by
+ `size` in the `preprocess` method.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the
+ `preprocess` method.
+ do_center_crop (`bool`, *optional*, defaults to `True`):
+ Whether to center crop the image to the specified `crop_size`. Can be overridden by the `do_center_crop`
+ parameter in the `preprocess` method.
+ crop_size (`dict[str, int]`, *optional*, defaults to `{"height": 224, "width": 224}`):
+ Size of the image after applying the center crop. Can be overridden by the `crop_size` parameter in the
+ `preprocess` method.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale`
+ parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/127.5`):
+ Defines the scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter
+ in the `preprocess` method.
+ offset (`bool`, *optional*, defaults to `True`):
+ Whether to scale the image in both negative and positive directions. Can be overridden by the `offset` in
+ the `preprocess` method.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_center_crop: bool = True,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 127.5,
+ offset: bool = True,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ size = size if size is not None else {"shortest_edge": 256}
+ size = get_size_dict(size, default_to_square=False)
+ crop_size = crop_size if crop_size is not None else {"height": 224, "width": 224}
+ crop_size = get_size_dict(crop_size, param_name="crop_size")
+
+ self.do_resize = do_resize
+ self.size = size
+ self.do_center_crop = do_center_crop
+ self.crop_size = crop_size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.offset = offset
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize an image.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Size of the output image. If `size` is of the form `{"height": h, "width": w}`, the output image will
+ have the size `(h, w)`. If `size` is of the form `{"shortest_edge": s}`, the output image will have its
+ shortest edge of length `s` while keeping the aspect ratio of the original image.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ Resampling filter to use when resiizing the image.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ size = get_size_dict(size, default_to_square=False)
+ if "shortest_edge" in size:
+ output_size = get_resize_output_image_size(
+ image, size["shortest_edge"], default_to_square=False, input_data_format=input_data_format
+ )
+ elif "height" in size and "width" in size:
+ output_size = (size["height"], size["width"])
+ else:
+ raise ValueError(f"Size must have 'height' and 'width' or 'shortest_edge' as keys. Got {size.keys()}")
+ return resize(
+ image,
+ size=output_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+
+ # Copied from transformers.models.efficientnet.image_processing_efficientnet.EfficientNetImageProcessor.rescale
+ def rescale(
+ self,
+ image: np.ndarray,
+ scale: Union[int, float],
+ offset: bool = True,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ):
+ """
+ Rescale an image by a scale factor.
+
+ If `offset` is `True`, the image has its values rescaled by `scale` and then offset by 1. If `scale` is
+ 1/127.5, the image is rescaled between [-1, 1].
+ image = image * scale - 1
+
+ If `offset` is `False`, and `scale` is 1/255, the image is rescaled between [0, 1].
+ image = image * scale
+
+ Args:
+ image (`np.ndarray`):
+ Image to rescale.
+ scale (`int` or `float`):
+ Scale to apply to the image.
+ offset (`bool`, *optional*):
+ Whether to scale the image in both negative and positive directions.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ rescaled_image = rescale(
+ image, scale=scale, data_format=data_format, input_data_format=input_data_format, **kwargs
+ )
+
+ if offset:
+ rescaled_image = rescaled_image - 1
+
+ return rescaled_image
+
+ def _preprocess_image(
+ self,
+ image: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ offset: Optional[bool] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ data_format: Optional[ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ """Preprocesses a single image."""
+
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ if offset and not do_rescale:
+ raise ValueError("For offset, do_rescale must also be set to True.")
+
+ # All transformations expect numpy arrays.
+ image = to_numpy_array(image)
+
+ if do_rescale and is_scaled_image(image):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(image)
+
+ if do_resize:
+ image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format)
+
+ if do_center_crop:
+ image = self.center_crop(image, size=crop_size, input_data_format=input_data_format)
+
+ if do_rescale:
+ image = self.rescale(image=image, scale=rescale_factor, offset=offset, input_data_format=input_data_format)
+
+ if do_normalize:
+ image = self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+
+ image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+ return image
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ videos: ImageInput,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = None,
+ do_center_crop: Optional[bool] = None,
+ crop_size: Optional[dict[str, int]] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ offset: Optional[bool] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ videos (`ImageInput`):
+ Video frames to preprocess. Expects a single or batch of video frames with pixel values ranging from 0
+ to 255. If passing in frames with pixel values between 0 and 1, set `do_rescale=False`.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after applying resize.
+ resample (`PILImageResampling`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only
+ has an effect if `do_resize` is set to `True`.
+ do_center_crop (`bool`, *optional*, defaults to `self.do_centre_crop`):
+ Whether to centre crop the image.
+ crop_size (`dict[str, int]`, *optional*, defaults to `self.crop_size`):
+ Size of the image after applying the centre crop.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between `[-1 - 1]` if `offset` is `True`, `[0, 1]` otherwise.
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ offset (`bool`, *optional*, defaults to `self.offset`):
+ Whether to scale the image in both negative and positive directions.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the inferred channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ resample = resample if resample is not None else self.resample
+ do_center_crop = do_center_crop if do_center_crop is not None else self.do_center_crop
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ offset = offset if offset is not None else self.offset
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+
+ size = size if size is not None else self.size
+ size = get_size_dict(size, default_to_square=False)
+ crop_size = crop_size if crop_size is not None else self.crop_size
+ crop_size = get_size_dict(crop_size, param_name="crop_size")
+
+ if not valid_images(videos):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+
+ videos = make_batched(videos)
+
+ videos = [
+ [
+ self._preprocess_image(
+ image=img,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ do_center_crop=do_center_crop,
+ crop_size=crop_size,
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ offset=offset,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ for img in video
+ ]
+ for video in videos
+ ]
+
+ data = {"pixel_values": videos}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+
+__all__ = ["VivitImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/modeling_vivit.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/modeling_vivit.py
new file mode 100644
index 0000000000000000000000000000000000000000..aca26da1669550caddb74fc8dd2ea629b69ef4cb
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vivit/modeling_vivit.py
@@ -0,0 +1,690 @@
+# coding=utf-8
+# Copyright 2023 Google AI and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ViViT model."""
+
+from typing import Callable, Optional
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, ImageClassifierOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import TransformersKwargs, auto_docstring, logging, torch_int
+from ...utils.generic import can_return_tuple, check_model_inputs
+from .configuration_vivit import VivitConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class VivitTubeletEmbeddings(nn.Module):
+ """
+ Construct Vivit Tubelet embeddings.
+
+ This module turns a batch of videos of shape (batch_size, num_frames, num_channels, height, width) into a tensor of
+ shape (batch_size, seq_len, hidden_size) to be consumed by a Transformer encoder.
+
+ The seq_len (the number of patches) equals (number of frames // tubelet_size[0]) * (height // tubelet_size[1]) *
+ (width // tubelet_size[2]).
+ """
+
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.num_frames = config.num_frames
+ self.image_size = config.image_size
+ self.patch_size = config.tubelet_size
+ self.num_patches = (
+ (self.image_size // self.patch_size[2])
+ * (self.image_size // self.patch_size[1])
+ * (self.num_frames // self.patch_size[0])
+ )
+ self.embed_dim = config.hidden_size
+
+ self.projection = nn.Conv3d(
+ config.num_channels, config.hidden_size, kernel_size=config.tubelet_size, stride=config.tubelet_size
+ )
+
+ def forward(self, pixel_values: torch.Tensor, interpolate_pos_encoding: bool = False) -> torch.Tensor:
+ batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ if not interpolate_pos_encoding and (height != self.image_size or width != self.image_size):
+ raise ValueError(
+ f"Image image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})."
+ )
+
+ # permute to (batch_size, num_channels, num_frames, height, width)
+ pixel_values = pixel_values.permute(0, 2, 1, 3, 4)
+
+ x = self.projection(pixel_values)
+ # out_batch_size, out_num_channels, out_num_frames, out_height, out_width = x.shape
+ # flattens time and space dimensions, transposes to (out_batch_size, flat_tokens, out_num_channels)
+ x = x.flatten(2).transpose(1, 2)
+ return x
+
+
+class VivitEmbeddings(nn.Module):
+ """
+ Vivit Embeddings.
+
+ Creates embeddings from a video using VivitTubeletEmbeddings, adds CLS token and positional embeddings.
+ """
+
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, config.hidden_size))
+ self.patch_embeddings = VivitTubeletEmbeddings(config)
+
+ self.position_embeddings = nn.Parameter(
+ torch.zeros(1, self.patch_embeddings.num_patches + 1, config.hidden_size)
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.patch_size = config.tubelet_size[1:]
+ self.config = config
+
+ # Adapted from transformers.models.vit.modeling_vit.ViTEmbeddings.interpolate_pos_encoding
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ num_positions = self.position_embeddings.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embeddings
+
+ class_pos_embed = self.position_embeddings[:, :1]
+ patch_pos_embed = self.position_embeddings[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size[0]
+ new_width = width // self.patch_size[1]
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def forward(self, pixel_values: torch.Tensor, interpolate_pos_encoding: bool = False) -> torch.Tensor:
+ batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ embeddings = self.patch_embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+
+ cls_tokens = self.cls_token.tile([batch_size, 1, 1])
+ embeddings = torch.cat((cls_tokens, embeddings), dim=1)
+
+ # add positional encoding to each token
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embeddings
+
+ embeddings = self.dropout(embeddings)
+
+ return embeddings
+
+
+# Copied from transformers.models.vit.modeling_vit.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfAttention with ViT->Vivit
+class VivitSelfAttention(nn.Module):
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ def forward(
+ self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ batch_size = hidden_states.shape[0]
+ new_shape = batch_size, -1, self.num_attention_heads, self.attention_head_size
+
+ key_layer = self.key(hidden_states).view(*new_shape).transpose(1, 2)
+ value_layer = self.value(hidden_states).view(*new_shape).transpose(1, 2)
+ query_layer = self.query(hidden_states).view(*new_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.reshape(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfOutput with ViT->Vivit
+class VivitSelfOutput(nn.Module):
+ """
+ The residual connection is defined in VivitLayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTAttention with ViT->Vivit
+class VivitAttention(nn.Module):
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.attention = VivitSelfAttention(config)
+ self.output = VivitSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads: set[int]):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ self_attn_output, _ = self.attention(hidden_states, head_mask)
+ output = self.output(self_attn_output, hidden_states)
+ return output
+
+
+class VivitIntermediate(nn.Module):
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ return hidden_states
+
+
+class VivitOutput(nn.Module):
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+class VivitLayer(GradientCheckpointingLayer):
+ """This corresponds to the EncoderBlock class in the scenic/vivit implementation."""
+
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = VivitAttention(config)
+ self.intermediate = VivitIntermediate(config)
+ self.output = VivitOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ hidden_states_norm = self.layernorm_before(hidden_states)
+ attention_output = self.attention(hidden_states_norm, head_mask)
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in Vivit, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+
+ # second residual connection is done here
+ layer_output = self.output(layer_output, hidden_states)
+
+ return layer_output
+
+
+class VivitEncoder(nn.Module):
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([VivitLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> BaseModelOutput:
+ for i, layer_module in enumerate(self.layer):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ hidden_states = layer_module(hidden_states, layer_head_mask)
+
+ return BaseModelOutput(last_hidden_state=hidden_states)
+
+
+class VivitPooler(nn.Module):
+ def __init__(self, config: VivitConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+@auto_docstring
+class VivitPreTrainedModel(PreTrainedModel):
+ config: VivitConfig
+ base_model_prefix = "vivit"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = []
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": VivitLayer,
+ "attentions": VivitSelfAttention,
+ }
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv3d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, VivitEmbeddings):
+ module.cls_token.data.zero_()
+ module.position_embeddings.data.zero_()
+
+
+@auto_docstring
+class VivitModel(VivitPreTrainedModel):
+ def __init__(self, config: VivitConfig, add_pooling_layer: bool = True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = VivitEmbeddings(config)
+ self.encoder = VivitEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.pooler = VivitPooler(config) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model.
+
+ Args:
+ heads_to_prune:
+ dict of {layer_num: list of heads to prune in this layer}
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPooling:
+ r"""
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import numpy as np
+
+ >>> from transformers import VivitImageProcessor, VivitModel
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 32 frames
+ >>> indices = sample_frame_indices(clip_len=32, frame_sample_rate=1, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container=container, indices=indices)
+
+ >>> image_processor = VivitImageProcessor.from_pretrained("google/vivit-b-16x2-kinetics400")
+ >>> model = VivitModel.from_pretrained("google/vivit-b-16x2-kinetics400")
+
+ >>> # prepare video for the model
+ >>> inputs = image_processor(list(video), return_tensors="pt")
+
+ >>> # forward pass
+ >>> outputs = model(**inputs)
+ >>> last_hidden_states = outputs.last_hidden_state
+ >>> list(last_hidden_states.shape)
+ [1, 3137, 768]
+ ```"""
+
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+ encoder_outputs: BaseModelOutput = self.encoder(embedding_output, head_mask=head_mask)
+ sequence_output = encoder_outputs.last_hidden_state
+ sequence_output = self.layernorm(sequence_output)
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ return BaseModelOutputWithPooling(last_hidden_state=sequence_output, pooler_output=pooled_output)
+
+
+@auto_docstring(
+ custom_intro="""
+ ViViT Transformer model with a video classification head on top (a linear layer on top of the final hidden state of the
+ [CLS] token) e.g. for Kinetics-400.
+
+
+
+ Note that it's possible to fine-tune ViT on higher resolution images than the ones it has been trained on, by
+ setting `interpolate_pos_encoding` to `True` in the forward of the model. This will interpolate the pre-trained
+ position embeddings to the higher resolution.
+
+
+ """
+)
+class VivitForVideoClassification(VivitPreTrainedModel):
+ def __init__(self, config: VivitConfig):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.vivit = VivitModel(config, add_pooling_layer=False)
+
+ # Classifier head
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity()
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ interpolate_pos_encoding: bool = False,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> ImageClassifierOutput:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import numpy as np
+ >>> import torch
+
+ >>> from transformers import VivitImageProcessor, VivitForVideoClassification
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 32 frames
+ >>> indices = sample_frame_indices(clip_len=32, frame_sample_rate=4, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container=container, indices=indices)
+
+ >>> image_processor = VivitImageProcessor.from_pretrained("google/vivit-b-16x2-kinetics400")
+ >>> model = VivitForVideoClassification.from_pretrained("google/vivit-b-16x2-kinetics400")
+
+ >>> inputs = image_processor(list(video), return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+ ... logits = outputs.logits
+
+ >>> # model predicts one of the 400 Kinetics-400 classes
+ >>> predicted_label = logits.argmax(-1).item()
+ >>> print(model.config.id2label[predicted_label])
+ LABEL_116
+ ```"""
+
+ outputs: BaseModelOutput = self.vivit(
+ pixel_values, head_mask=head_mask, interpolate_pos_encoding=interpolate_pos_encoding, **kwargs
+ )
+ sequence_output = outputs.last_hidden_state
+ logits = self.classifier(sequence_output[:, 0, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(labels, logits, self.config, **kwargs)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["VivitModel", "VivitPreTrainedModel", "VivitForVideoClassification"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..f184d058a8e4fe8c88bc179d72903679461a1fe1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/__init__.py
@@ -0,0 +1,29 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_vjepa2 import *
+ from .modeling_vjepa2 import *
+ from .video_processing_vjepa2 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/configuration_vjepa2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/configuration_vjepa2.py
new file mode 100644
index 0000000000000000000000000000000000000000..1fd19c4d0782695010e0e889aacd1d2795748262
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/configuration_vjepa2.py
@@ -0,0 +1,154 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""VJEPA 2 model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+
+
+class VJEPA2Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VJEPA2Model`]. It is used to instantiate an
+ VJEPA2 model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the VJEPA2
+ [facebook/vjepa2-vitl-fpc64-256](https://huggingface.co/facebook/vjepa2-vitl-fpc64-256) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ crop_size (`int`, *optional*, defaults to 256):
+ Input resolution of the model
+ frames_per_clip (`int`, *optional*, defaults to 64):
+ The number of frames the model has been pretrained with. Does not impact inference.
+ tubelet_size (`int`, *optional*, defaults to 2):
+ The number of temporal frames used for a single rastor, check paper for more information.
+ hidden_size (`int`, *optional*, defaults to 1024):
+ Dimensionality of the encoder layers
+ in_chans (`int`, *optional*, defaults to 3):
+ The number of input channels
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Encoder
+ num_hidden_layers (`int`, *optional*, defaults to 24):
+ The number of hidden layers
+ drop_path_rate (`float`, *optional*, defaults to 0.0):
+ Stochastic depth rate per sample (when applied in the main path of residual layers).
+ mlp_ratio (`float`, *optional*, defaults to 4.0):
+ Ratio of the hidden size of the MLPs used in Encoder relative to the `hidden_size`.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-06):
+ The epsilon used by the layer normalization layers.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for attentions.
+ The dropout probability for all fully connected layers.
+ hidden_act (`str`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for attentions.
+ num_pooler_layers (`int`, *optional*, defaults to 3):
+ The number of self-attention layers in the pooler.
+ pred_hidden_size (`int`, *optional*, defaults to 384):
+ Dimensionality of the predictor layers
+ pred_num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Predictor
+ pred_num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Predictor
+ pred_num_mask_tokens (`int`, *optional*, defaults to 10):
+ Define the number of mask tokens to use in the Predictor
+ pred_zero_init_mask_tokens (`bool`, *optional*, defaults to `True`):
+ Initialize the mask tokens in the predictor with 0.
+ pred_mlp_ratio (`float`, *optional*, defaults to 4.0):
+ Ratio of the hidden size of the MLPs used in Predictor relative to the `pred_hidden_size`.
+
+ Example:
+
+ ```python
+ >>> from transformers import VJEPA2Config, VJEPA2Model
+
+ >>> # Initializing a VJEPA2 vjepa2-vitl-fpc64-256 style configuration
+ >>> configuration = VJEPA2Config()
+
+ >>> # Initializing a model (with random weights) from the vjepa2-vitl-fpc64-256 style configuration
+ >>> model = VJEPA2Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "vjepa2"
+
+ def __init__(
+ self,
+ patch_size=16,
+ crop_size=256,
+ frames_per_clip=64,
+ tubelet_size=2,
+ hidden_size=1024,
+ in_chans=3,
+ num_attention_heads=16,
+ num_hidden_layers=24,
+ drop_path_rate=0.0,
+ mlp_ratio=4.0,
+ layer_norm_eps=1e-6,
+ qkv_bias=True,
+ attention_probs_dropout_prob=0.0,
+ hidden_act="gelu",
+ initializer_range=0.02,
+ attention_dropout=0.0,
+ num_pooler_layers=3,
+ # predictor params
+ pred_hidden_size=384,
+ pred_num_attention_heads=12,
+ pred_num_hidden_layers=12,
+ pred_num_mask_tokens=10,
+ pred_zero_init_mask_tokens=True,
+ pred_mlp_ratio=4.0,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.crop_size = crop_size
+ self.frames_per_clip = frames_per_clip
+ self.patch_size = patch_size
+ self.tubelet_size = tubelet_size
+ self.hidden_size = hidden_size
+ self.in_chans = in_chans
+ self.num_attention_heads = num_attention_heads
+ self.num_hidden_layers = num_hidden_layers
+ self.drop_path_rate = drop_path_rate
+ self.mlp_ratio = mlp_ratio
+ self.layer_norm_eps = layer_norm_eps
+ self.qkv_bias = qkv_bias
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.image_size = crop_size
+ self.attention_dropout = attention_dropout
+ self.num_pooler_layers = num_pooler_layers
+ # predictor params
+ self.pred_hidden_size = pred_hidden_size
+ self.pred_num_attention_heads = pred_num_attention_heads
+ self.pred_num_hidden_layers = pred_num_hidden_layers
+ self.pred_num_mask_tokens = pred_num_mask_tokens
+ self.pred_zero_init_mask_tokens = pred_zero_init_mask_tokens
+ self.pred_mlp_ratio = pred_mlp_ratio
+
+
+__all__ = ["VJEPA2Config"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/modeling_vjepa2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/modeling_vjepa2.py
new file mode 100644
index 0000000000000000000000000000000000000000..fb27ffdb6a5adc1f5817b8a5562d7e82466c84c1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/modeling_vjepa2.py
@@ -0,0 +1,1236 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, ImageClassifierOutput
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...utils import ModelOutput, auto_docstring, can_return_tuple, logging
+from .configuration_vjepa2 import VJEPA2Config
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ VJEPA Predictor outputs that also contains the masked encoder outputs
+ """
+)
+class VJEPA2WithMaskedInputPredictorOutput(ModelOutput):
+ r"""
+ masked_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*, returned when `context_mask` is provided which is applied on VJEPA2Encoder outputs):
+ The masked hidden state of the model.
+ target_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*, returned when `target_mask` is provided which is applied on VJEPA2Encoder outputs):
+ The target hidden state of the model.
+ """
+
+ last_hidden_state: torch.FloatTensor
+ masked_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ target_hidden_state: Optional[torch.FloatTensor] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ VJEPA outputs that also contains the masked encoder outputs
+ Optionally contains the predictor outputs
+ """
+)
+class VJEPA2WithMaskedInputModelOutput(ModelOutput):
+ r"""
+ masked_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*, returned when `context_mask` is provided which is applied on VJEPA2Encoder outputs):
+ The masked hidden state of the model.
+ predictor_output (`VJEPA2WithMaskedInputPredictorOutput`, *optional*):
+ The output from the Predictor module.
+ """
+
+ last_hidden_state: torch.FloatTensor
+ masked_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+ predictor_output: Optional[VJEPA2WithMaskedInputPredictorOutput] = None
+
+ def to_tuple(self):
+ output = list(super().to_tuple())
+ if isinstance(output[-1], VJEPA2WithMaskedInputPredictorOutput):
+ output[-1] = output[-1].to_tuple()
+ return tuple(output)
+
+
+class VJEPA2PatchEmbeddings3D(nn.Module):
+ """
+ Image to Patch Embedding
+ """
+
+ def __init__(
+ self,
+ config: VJEPA2Config,
+ hidden_size: int = 1024,
+ ):
+ super().__init__()
+ self.patch_size = config.patch_size
+ self.tubelet_size = config.tubelet_size
+ self.hidden_size = hidden_size
+
+ self.proj = nn.Conv3d(
+ in_channels=config.in_chans,
+ out_channels=hidden_size,
+ kernel_size=(config.tubelet_size, config.patch_size, config.patch_size),
+ stride=(config.tubelet_size, config.patch_size, config.patch_size),
+ )
+
+ @staticmethod
+ def num_patches(config):
+ return (
+ (config.frames_per_clip // config.tubelet_size)
+ * (config.crop_size // config.patch_size)
+ * (config.crop_size // config.patch_size)
+ )
+
+ def forward(self, pixel_values_videos: torch.Tensor) -> torch.Tensor:
+ x = self.proj(pixel_values_videos).flatten(2).transpose(1, 2)
+ return x
+
+
+class VJEPA2Embeddings(nn.Module):
+ """
+ Construct mask token, position and patch embeddings.
+ """
+
+ def __init__(self, config: VJEPA2Config, hidden_size: int = 1024):
+ super().__init__()
+
+ self.config = config
+ self.hidden_size = hidden_size
+ self.patch_embeddings = VJEPA2PatchEmbeddings3D(config, hidden_size=hidden_size)
+
+ self.num_patches = self.patch_embeddings.num_patches
+ self.patch_size = config.patch_size
+
+ def forward(self, pixel_values_videos: torch.Tensor) -> torch.Tensor:
+ num_frames = pixel_values_videos.shape[1]
+
+ # Swap `frames` and `channels` dims, the result is:
+ # (batch_size, channels, num_frames, height, width)
+ pixel_values_videos = pixel_values_videos.permute(0, 2, 1, 3, 4)
+
+ # For some cases, if the input vision (image/video) consists of num_frames < tubelet_size,
+ # then embedding lookup fails. In these cases, we duplicate the frames.
+ if num_frames < self.config.tubelet_size:
+ pixel_values_videos = pixel_values_videos.repeat(1, 1, self.config.tubelet_size, 1, 1)
+
+ target_dtype = self.patch_embeddings.proj.weight.dtype
+ pixel_values_videos = pixel_values_videos.to(dtype=target_dtype)
+ embeddings = self.patch_embeddings(pixel_values_videos)
+
+ return embeddings
+
+
+# Adapted from transformers.models.vit.modeling_vit.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+def rotate_queries_or_keys(x, pos):
+ B, num_heads, N, D = x.size()
+
+ # similar to inv_freq = 1.0 / (theta ** (torch.arange(0, dim, 2, dtype=torch.float) / dim))
+ # they are computing this every time. instead HF style is to compute the inv_freq once and store it
+ # -- compute angle for each position
+ omega = torch.arange(D // 2, dtype=x.dtype, device=x.device)
+ omega /= D / 2.0
+ omega = 1.0 / 10000**omega # (D/2,)
+ freq = pos.unsqueeze(-1) * omega # (..., N, D/2), outer product
+
+ # -- build rotation matrix and apply
+ emb_sin = freq.sin() # (..., N, D/2)
+ emb_cos = freq.cos() # (..., N, D/2)
+
+ emb_sin = emb_sin.squeeze(-1).repeat(1, 1, 1, 2)
+ emb_cos = emb_cos.squeeze(-1).repeat(1, 1, 1, 2)
+
+ # --
+ y = x.unflatten(-1, (-1, 2))
+ y1, y2 = y.unbind(dim=-1)
+
+ y = torch.stack((-y2, y1), dim=-1)
+ y = y.flatten(-2)
+ return (x * emb_cos) + (y * emb_sin)
+
+
+class VJEPA2RopeAttention(nn.Module):
+ def __init__(
+ self,
+ config: VJEPA2Config,
+ hidden_size: int = 1024,
+ num_attention_heads: int = 16,
+ ):
+ super().__init__()
+ self.config = config
+ self.hidden_size = hidden_size
+ self.num_attention_heads = num_attention_heads
+ if hidden_size % num_attention_heads != 0:
+ raise ValueError(
+ f"The hidden size {(hidden_size,)} is not a multiple of the number of attention "
+ f"heads {num_attention_heads}."
+ )
+
+ self.attention_head_size = int(hidden_size / num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ self.proj = nn.Linear(hidden_size, hidden_size)
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.dropout = nn.Dropout(self.dropout_prob)
+
+ self.grid_size = self.config.crop_size // self.config.patch_size
+ self.grid_depth = self.config.frames_per_clip // self.config.tubelet_size
+
+ self.d_dim = int(2 * ((self.attention_head_size // 3) // 2))
+ self.h_dim = int(2 * ((self.attention_head_size // 3) // 2))
+ self.w_dim = int(2 * ((self.attention_head_size // 3) // 2))
+
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ def _get_frame_pos(self, ids):
+ tokens_per_frame = int(self.grid_size * self.grid_size)
+ return ids // tokens_per_frame
+
+ def _get_height_pos(self, ids):
+ # Remove frame component from ids
+ tokens_per_frame = int(self.grid_size * self.grid_size)
+ frame_ids = self._get_frame_pos(ids)
+ ids = ids - tokens_per_frame * frame_ids
+ # --
+ tokens_per_row = self.grid_size
+ return ids // tokens_per_row
+
+ def get_position_ids(self, x, masks=None):
+ device = x.device
+ token_size = x.size(1)
+
+ # Note: when masks is none, we use a 1d id instead of Bxnum_attention_heads mask,
+ # as 1d vector is broadcasted to the correct shapes.
+ if masks is not None:
+ ids = masks.unsqueeze(1).repeat(1, self.num_attention_heads, 1)
+ else:
+ ids = torch.arange(token_size, device=device)
+ # change to allow for extrapolation
+ tokens_per_frame = int(self.grid_size * self.grid_size)
+ frame_ids = self._get_frame_pos(ids)
+ # --
+ tokens_per_row = self.grid_size
+ height_ids = self._get_height_pos(ids)
+ # --
+ # Remove frame component from ids (1st term) and height component (2nd term)
+ width_ids = (ids - tokens_per_frame * frame_ids) - tokens_per_row * height_ids
+ return frame_ids, height_ids, width_ids
+
+ def apply_rotary_embeddings(self, qk, pos_ids):
+ d_mask, h_mask, w_mask = pos_ids
+ s = 0
+ qkd = rotate_queries_or_keys(qk[..., s : s + self.d_dim], pos=d_mask)
+ s += self.d_dim
+ qkh = rotate_queries_or_keys(qk[..., s : s + self.h_dim], pos=h_mask)
+ s += self.h_dim
+ qkw = rotate_queries_or_keys(qk[..., s : s + self.w_dim], pos=w_mask)
+ s += self.w_dim
+ # Combine rotated dimension
+ if s < self.attention_head_size:
+ qkr = qk[..., s:]
+ qk = torch.cat([qkd, qkh, qkw, qkr], dim=-1)
+ else:
+ qk = torch.cat([qkd, qkh, qkw], dim=-1)
+ return qk
+
+ def forward(
+ self,
+ hidden_states,
+ position_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ head_mask: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.Tensor, torch.Tensor], tuple[torch.Tensor]]:
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ key_layer = (
+ self.key(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ pos_ids = self.get_position_ids(hidden_states, masks=position_mask)
+ key_layer = self.apply_rotary_embeddings(key_layer, pos_ids)
+ query_layer = self.apply_rotary_embeddings(query_layer, pos_ids)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and output_attentions:
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = self.proj(context_layer.reshape(new_context_layer_shape))
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+# Adapted from transformers.models.beit.modeling_dinov2.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+# Adapted from transformers.models.beit.modeling_beit.BeitDropPath
+class VJEPA2DropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: Optional[float] = None):
+ super().__init__()
+ self.drop_prob = drop_prob
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+class VJEPA2MLP(nn.Module):
+ def __init__(self, config: VJEPA2Config, hidden_size: int = 1024, mlp_ratio: float = 4.0):
+ super().__init__()
+ in_features = out_features = hidden_size
+ hidden_features = int(hidden_size * mlp_ratio)
+ self.fc1 = nn.Linear(in_features, hidden_features, bias=True)
+ self.activation = ACT2FN[config.hidden_act]
+ self.fc2 = nn.Linear(hidden_features, out_features, bias=True)
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ hidden_state = self.fc1(hidden_state)
+ hidden_state = self.activation(hidden_state)
+ hidden_state = self.fc2(hidden_state)
+ return hidden_state
+
+
+class VJEPA2Layer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the original implementation."""
+
+ def __init__(
+ self,
+ config: VJEPA2Config,
+ drop_path_rate: float = 0.0,
+ hidden_size: int = 1024,
+ num_attention_heads: int = 16,
+ mlp_ratio: float = 4.0,
+ ):
+ super().__init__()
+ self.config = config
+ self.hidden_size = hidden_size
+ self.num_attention_heads = num_attention_heads
+ self.mlp_ratio = mlp_ratio
+
+ self.norm1 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps)
+ self.attention = VJEPA2RopeAttention(config, hidden_size, num_attention_heads)
+ self.drop_path = VJEPA2DropPath(drop_path_rate) if config.drop_path_rate > 0.0 else nn.Identity()
+ self.norm2 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps)
+ self.mlp = VJEPA2MLP(config, hidden_size=hidden_size, mlp_ratio=mlp_ratio)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ position_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, ...]:
+ # Self-Attention
+ residual = hidden_states
+ hidden_states = self.norm1(hidden_states)
+ self_attention_outputs = self.attention(
+ hidden_states,
+ position_mask=position_mask, # position mask for context/target selection
+ head_mask=head_mask, # head mask is applied at F.scaled_dot_product_attention
+ output_attentions=output_attentions,
+ )
+ attention_output = self_attention_outputs[0]
+ hidden_states = self.drop_path(attention_output) + residual
+
+ # MLP
+ residual = hidden_states
+ hidden_states = self.norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = self.drop_path(hidden_states) + residual
+
+ # Add self attentions if we output attention weights
+ outputs = self_attention_outputs[1:]
+ outputs = (hidden_states,) + outputs
+
+ return outputs
+
+
+class VJEPA2Encoder(nn.Module):
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+ self.config = config
+
+ self.embeddings = VJEPA2Embeddings(config, hidden_size=config.hidden_size)
+ drop_path_rates = [
+ (config.drop_path_rate * i / (config.num_hidden_layers - 1) if config.num_hidden_layers > 1 else 0.0)
+ for i in range(config.num_hidden_layers)
+ ]
+ self.layer = nn.ModuleList(
+ [
+ VJEPA2Layer(
+ config,
+ drop_path_rate=drop_path_rates[i],
+ hidden_size=config.hidden_size,
+ num_attention_heads=config.num_attention_heads,
+ mlp_ratio=config.mlp_ratio,
+ )
+ for i in range(config.num_hidden_layers)
+ ]
+ )
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.gradient_checkpointing = False
+
+ @can_return_tuple
+ def forward(
+ self,
+ pixel_values_videos: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ **kwargs,
+ ) -> BaseModelOutput:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ hidden_states = self.embeddings(pixel_values_videos)
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ layer_outputs = layer_module(hidden_states, None, layer_head_mask, output_attentions)
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layernorm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+def apply_masks(tensor: torch.Tensor, masks: list[torch.Tensor]) -> torch.Tensor:
+ """
+ Args:
+ tensor (`torch.Tensor`):
+ Tensor of shape [batch_size, num_patches, feature_dim]
+ masks (`List[torch.Tensor]`):
+ List of tensors of shape [batch_size, num_patches] containing indices of patches to keep
+ """
+ all_masked_tensors = []
+ for mask in masks:
+ mask = mask.to(tensor.device)
+ mask_keep = mask.unsqueeze(-1).repeat(1, 1, tensor.size(-1))
+ all_masked_tensors += [torch.gather(tensor, dim=1, index=mask_keep)]
+
+ return torch.cat(all_masked_tensors, dim=0)
+
+
+class VJEPA2PredictorEmbeddings(nn.Module):
+ """
+ Construct mask token, position and patch embeddings.
+ """
+
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+
+ self.config = config
+ self.predictor_embeddings = nn.Linear(config.hidden_size, config.pred_hidden_size)
+ self.num_mask_tokens = 0
+ self.zero_init_mask_tokens = config.pred_zero_init_mask_tokens
+ self.num_mask_tokens = config.pred_num_mask_tokens
+ self.mask_tokens = nn.Parameter(torch.zeros(self.num_mask_tokens, 1, 1, config.pred_hidden_size))
+
+ self.patch_size = config.patch_size
+ self.config = config
+
+ @staticmethod
+ def num_patches(config):
+ if config.frames_per_clip > 1:
+ return (
+ (config.frames_per_clip // config.tubelet_size)
+ * (config.crop_size // config.patch_size)
+ * (config.crop_size // config.patch_size)
+ )
+ else:
+ return (config.crop_size // config.patch_size) * (config.crop_size // config.patch_size)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ context_mask: list[torch.Tensor],
+ target_mask: list[torch.Tensor],
+ mask_index: int = 1,
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ """
+ hidden_states : encoder outputs (context)
+ context_mask: tokens of the context (outputs from the encoder)
+ target_mask: tokens to predict
+ mask_index: index of the target mask to choose (useful for multiclip?)
+ """
+
+ B = hidden_states.size(0)
+ context = self.predictor_embeddings(hidden_states)
+
+ # Make target tokens
+ mask_index = mask_index % self.num_mask_tokens
+ target = self.mask_tokens[mask_index]
+
+ # Note: this is problematic if the config isn't initialized with the right frames_per_clip value,
+ # e.g. for scenarios if we want to run predictor for more tokens than in the config.
+ # target = target.repeat(B, self.num_patches(self.config), 1)
+ # Remedy: use the provided target mask to get the max patch num
+ max_patch_num = target_mask[0].max() + 1 # one extra to include the last patch
+ target = target.repeat(B, max_patch_num, 1)
+ target = apply_masks(target, target_mask)
+
+ # Concatenate context & target tokens
+ context = context.repeat(len(context_mask), 1, 1)
+ embeddings = torch.cat([context, target], dim=1)
+
+ # Positions of context & target tokens
+ cm = torch.cat(context_mask, dim=0)
+ tm = torch.cat(target_mask, dim=0)
+ masks = torch.cat([cm, tm], dim=1)
+
+ return embeddings, masks
+
+
+class VJEPA2Predictor(nn.Module):
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+ self.config = config
+ self.gradient_checkpointing = False
+ self.embeddings = VJEPA2PredictorEmbeddings(config)
+ drop_path_rates = [
+ (
+ config.drop_path_rate * i / (config.pred_num_hidden_layers - 1)
+ if config.pred_num_hidden_layers > 1
+ else 0.0
+ )
+ for i in range(config.pred_num_hidden_layers)
+ ]
+ self.layer = nn.ModuleList(
+ [
+ VJEPA2Layer(
+ config,
+ drop_path_rate=drop_path_rates[i],
+ hidden_size=config.pred_hidden_size,
+ num_attention_heads=config.pred_num_attention_heads,
+ mlp_ratio=config.pred_mlp_ratio,
+ )
+ for i in range(config.pred_num_hidden_layers)
+ ]
+ )
+ self.layernorm = nn.LayerNorm(config.pred_hidden_size, eps=config.layer_norm_eps)
+ self.proj = nn.Linear(config.pred_hidden_size, config.hidden_size, bias=True)
+
+ def sort_tokens(self, hidden_states, position_masks, argsort, head_mask=None):
+ # gather position masks
+ argsort = argsort.to(position_masks.device)
+ position_masks = torch.gather(position_masks, dim=1, index=argsort)
+
+ # gather hidden states
+ argsort = argsort.to(hidden_states.device)
+ hidden_states_argsort = argsort.unsqueeze(-1).expand(-1, -1, hidden_states.size(-1))
+ hidden_states = torch.gather(hidden_states, dim=1, index=hidden_states_argsort)
+
+ # gather head mask
+ if head_mask is not None and head_mask[0] is not None:
+ argsort = argsort.to(head_mask.device)
+ head_mask = head_mask.permute(1, 0, 2, 3, 4)
+ argsort_4d = (
+ argsort.unsqueeze(1)
+ .unsqueeze(1)
+ .expand(-1, head_mask.size(1), head_mask.size(2), -1)
+ .unsqueeze(-1)
+ .expand(-1, -1, -1, -1, head_mask.size(-1))
+ )
+ head_mask = torch.gather(head_mask, dim=3, index=argsort_4d)
+ argsort_5d = (
+ argsort.unsqueeze(1)
+ .unsqueeze(1)
+ .unsqueeze(1)
+ .expand(-1, head_mask.size(1), head_mask.size(2), head_mask.size(3), -1)
+ )
+ head_mask = torch.gather(head_mask, dim=4, index=argsort_5d)
+ head_mask = head_mask.permute(1, 0, 2, 3, 4)
+
+ return hidden_states, position_masks, head_mask
+
+ def unsort_tokens(self, hidden_states, argsort):
+ argsort = argsort.to(hidden_states.device)
+ reverse_argsort = torch.argsort(argsort, dim=1)
+ reverse_argsort = reverse_argsort.unsqueeze(-1).expand(-1, -1, hidden_states.size(-1))
+ hidden_states = torch.gather(hidden_states, dim=1, index=reverse_argsort)
+ return hidden_states
+
+ @can_return_tuple
+ def forward(
+ self,
+ encoder_hidden_states: torch.Tensor,
+ context_mask: list[torch.Tensor],
+ target_mask: list[torch.Tensor],
+ head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ **kwargs,
+ ) -> BaseModelOutput:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ # mask out the encoder hidden states
+ # this is implemented here as in VJEPA training a separate encoder is used for target
+ encoder_hidden_states = apply_masks(encoder_hidden_states, context_mask)
+ _, N_ctxt, D = encoder_hidden_states.shape
+ hidden_states, position_masks = self.embeddings(encoder_hidden_states, context_mask, target_mask)
+
+ # Put tokens in sorted order
+ argsort = torch.argsort(position_masks, dim=1) # [B, N]
+ hidden_states, position_masks, head_mask = self.sort_tokens(hidden_states, position_masks, argsort, head_mask)
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ layer_outputs = layer_module(hidden_states, position_masks, layer_head_mask, output_attentions)
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ hidden_states = self.layernorm(hidden_states)
+ # unsort and extract the predicted tokens
+ hidden_states = self.unsort_tokens(hidden_states, argsort)
+ hidden_states = hidden_states[:, N_ctxt:]
+ # projection
+ hidden_states = self.proj(hidden_states)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class VJEPA2PoolerSelfAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+ self.is_causal = False
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ batch_size, seq_length, embed_dim = hidden_states.shape
+
+ queries = self.q_proj(hidden_states)
+ keys = self.k_proj(hidden_states)
+ values = self.v_proj(hidden_states)
+
+ queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and output_attentions:
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ queries,
+ keys,
+ values,
+ attention_mask,
+ is_causal=self.is_causal,
+ scaling=self.scale,
+ dropout=0.0 if not self.training else self.dropout,
+ )
+
+ attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights
+
+
+class VJEPA2PoolerCrossAttention(nn.Module):
+ """It's different from other cross-attention layers, doesn't have output projection layer (o_proj)"""
+
+ # in case of modular refactoring - o_proj can be replaces with nn.Identity()
+
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+ self.is_causal = False
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ def forward(
+ self,
+ queries: torch.Tensor,
+ keys: torch.Tensor,
+ values: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ batch_size, q_seq_length, embed_dim = queries.shape
+ kv_seq_length = keys.shape[1]
+
+ queries = self.q_proj(queries)
+ keys = self.k_proj(keys)
+ values = self.v_proj(values)
+
+ queries = queries.view(batch_size, q_seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ keys = keys.view(batch_size, kv_seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ values = values.view(batch_size, kv_seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and output_attentions:
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ queries,
+ keys,
+ values,
+ attention_mask,
+ is_causal=self.is_causal,
+ scaling=self.scale,
+ dropout=0.0 if not self.training else self.dropout,
+ )
+
+ attn_output = attn_output.reshape(batch_size, q_seq_length, embed_dim).contiguous()
+
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights
+
+
+# Modified from SiglipEncoderLayer, but we have to propagate proper hidden_size to VJEPA2MLP
+class VJEPA2PoolerSelfAttentionLayer(GradientCheckpointingLayer):
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+ self.layer_norm1 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.self_attn = VJEPA2PoolerSelfAttention(config)
+ self.layer_norm2 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.mlp = VJEPA2MLP(config, hidden_size=config.hidden_size)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, ...]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`):
+ Input to the layer of shape `(batch, seq_len, embed_dim)`.
+ attention_mask (`torch.FloatTensor`):
+ Attention mask of shape `(batch, 1, q_len, k_v_seq_len)` where padding elements are indicated by very large negative values.
+ output_attentions (`bool`, *optional*, defaults to `False`):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class VJEPA2PoolerCrossAttentionLayer(GradientCheckpointingLayer):
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+ self.layer_norm1 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.cross_attn = VJEPA2PoolerCrossAttention(config)
+ self.layer_norm2 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.mlp = VJEPA2MLP(config, hidden_size=config.hidden_size)
+
+ def forward(
+ self,
+ queries: torch.Tensor,
+ hidden_state: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, ...]:
+ # Apply cross-attention
+ residual = queries
+ hidden_state = self.layer_norm1(hidden_state)
+ hidden_state, *attn_weights = self.cross_attn(
+ queries,
+ hidden_state,
+ hidden_state,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_state = residual + hidden_state
+
+ # Apply MLP
+ residual = hidden_state
+ hidden_state = self.layer_norm2(hidden_state)
+ hidden_state = self.mlp(hidden_state)
+ hidden_state = residual + hidden_state
+
+ outputs = (hidden_state,)
+ if output_attentions:
+ outputs += tuple(attn_weights)
+
+ return outputs
+
+
+class VJEPA2AttentivePooler(nn.Module):
+ """Attentive Pooler"""
+
+ def __init__(self, config: VJEPA2Config):
+ super().__init__()
+ self.query_tokens = nn.Parameter(torch.zeros(1, 1, config.hidden_size))
+ self.cross_attention_layer = VJEPA2PoolerCrossAttentionLayer(config)
+ self.self_attention_layers = nn.ModuleList(
+ [VJEPA2PoolerSelfAttentionLayer(config) for _ in range(config.num_pooler_layers)]
+ )
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ for layer in self.self_attention_layers:
+ hidden_state = layer(hidden_state, attention_mask=None)[0]
+ queries = self.query_tokens.repeat(hidden_state.shape[0], 1, 1)
+ hidden_state = self.cross_attention_layer(queries, hidden_state)[0]
+ return hidden_state.squeeze(1)
+
+
+@auto_docstring
+class VJEPA2PreTrainedModel(PreTrainedModel):
+ config: VJEPA2Config
+ base_model_prefix = "vjepa2"
+ main_input_name = "pixel_values_videos"
+ supports_gradient_checkpointing = True
+ _no_split_modules = [
+ "VJEPA2Layer",
+ "VJEPA2PoolerSelfAttentionLayer",
+ "VJEPA2PoolerCrossAttentionLayer",
+ "VJEPA2PredictorEmbeddings",
+ ]
+ _supports_sdpa = True
+ _supports_flash_attn = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+
+ init_std = self.config.initializer_range
+
+ # Upcast the input in `fp32` and cast it back to desired `dtype` to avoid
+ # `trunc_normal_cpu` not implemented in `half` issues
+ def trunc_normal_f32_(weight, std):
+ data_float_32 = weight.data.to(torch.float32)
+ data_init = nn.init.trunc_normal_(data_float_32, mean=0.0, std=std)
+ weight.data = data_init.to(weight.dtype)
+
+ if isinstance(module, VJEPA2AttentivePooler):
+ trunc_normal_f32_(module.query_tokens, std=init_std)
+ for i, layer in enumerate(module.self_attention_layers, 1):
+ std = init_std / (i**0.5)
+ trunc_normal_f32_(layer.self_attn.out_proj.weight, std=std)
+ trunc_normal_f32_(layer.mlp.fc2.weight, std=std)
+ std = init_std / (len(module.self_attention_layers) + 1) ** 0.5
+ trunc_normal_f32_(module.cross_attention_layer.mlp.fc2.weight, std=std)
+ elif isinstance(module, VJEPA2PredictorEmbeddings):
+ if module.zero_init_mask_tokens:
+ module.mask_tokens.data.zero_()
+ else:
+ trunc_normal_f32_(module.mask_tokens, std=init_std)
+ elif isinstance(module, (nn.Linear, nn.Conv2d, nn.Conv3d)):
+ trunc_normal_f32_(module.weight, std=init_std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+def _convert_head_mask_to_5d(head_mask, num_hidden_layers):
+ """
+ Inputs:
+ - head_mask: bsz x seq_length x seq_length | None
+ Returns
+ - [num_hidden_layers x batch x num_heads x seq_length x seq_length] | [num_hidden_layers]
+ """
+ if head_mask is not None:
+ head_mask = head_mask.unsqueeze(1).unsqueeze(0)
+ head_mask = head_mask.expand(num_hidden_layers, -1, -1, -1, -1)
+ else:
+ head_mask = [None] * num_hidden_layers
+ return head_mask
+
+
+@auto_docstring
+class VJEPA2Model(VJEPA2PreTrainedModel):
+ def __init__(self, config: VJEPA2Config):
+ super().__init__(config)
+ self.config = config
+
+ self.encoder = VJEPA2Encoder(config)
+ self.predictor = VJEPA2Predictor(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> VJEPA2PatchEmbeddings3D:
+ return self.encoder.embeddings.patch_embeddings
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values_videos: torch.Tensor,
+ context_head_mask: Optional[torch.Tensor] = None,
+ context_mask: Optional[list[torch.Tensor]] = None,
+ target_head_mask: Optional[torch.Tensor] = None,
+ target_mask: Optional[list[torch.Tensor]] = None,
+ skip_predictor: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ **kwargs,
+ ) -> VJEPA2WithMaskedInputModelOutput:
+ r"""
+ context_head_mask (`torch.Tensor` with shape `[num_heads]` or `[num_hidden_layers x num_heads]`, *optional*):
+ The mask indicating if we should keep the heads or not (1.0 for keep, 0.0 for discard) for the context.
+ context_mask (`torch.Tensor` with shape `[batch_size, patch_size, 1]`, *optional*):
+ The mask position ids indicating which encoder output patches are going to be exposed to the predictor.
+ By default, this mask is created as torch.arange(N).unsqueeze(0).repeat(B,1), indicating full context
+ available to the predictor.
+ target_head_mask (`torch.Tensor` with shape `[num_heads]` or `[num_hidden_layers x num_heads]`, *optional*):
+ The mask indicating if we should keep the heads or not (1.0 for keep, 0.0 for discard) for the target.
+ target_mask (`torch.Tensor` with shape `[batch_size, patch_size, 1]`, *optional*):
+ The mask position ids indicating which encoder output patches are going to be used as a prediction target
+ for the predictor. By default, this mask is created as torch.arange(N).unsqueeze(0).repeat(B,1), indicating
+ that the predictor should predict all encoder patches.
+ skip_predictor (bool):
+ flag to skip the predictor forward, useful if you just need the encoder outputs
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+
+ if pixel_values_videos is None:
+ raise ValueError("You have to specify pixel_values_videos")
+
+ # Prepare head mask if needed
+ context_head_mask = _convert_head_mask_to_5d(context_head_mask, self.config.num_hidden_layers)
+ target_head_mask = _convert_head_mask_to_5d(target_head_mask, self.config.pred_num_hidden_layers)
+
+ encoder_outputs: BaseModelOutput = self.encoder(
+ pixel_values_videos=pixel_values_videos,
+ head_mask=context_head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+ sequence_output = encoder_outputs.last_hidden_state
+
+ if context_mask is None and target_mask is None:
+ B = pixel_values_videos.size(0)
+ N = sequence_output.size(1) # ensure we are using dynamic patch size
+ context_mask = [torch.arange(N, device=pixel_values_videos.device).unsqueeze(0).repeat((B, 1))]
+ target_mask = [torch.arange(N, device=pixel_values_videos.device).unsqueeze(0).repeat((B, 1))]
+
+ if not skip_predictor:
+ predictor_outputs: BaseModelOutput = self.predictor(
+ encoder_hidden_states=sequence_output,
+ context_mask=context_mask,
+ target_mask=target_mask,
+ head_mask=target_head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+ predictor_output = VJEPA2WithMaskedInputPredictorOutput(
+ last_hidden_state=predictor_outputs.last_hidden_state,
+ target_hidden_state=apply_masks(sequence_output, target_mask),
+ hidden_states=predictor_outputs.hidden_states,
+ attentions=predictor_outputs.attentions,
+ )
+ else:
+ predictor_output = None
+
+ encoder_output = VJEPA2WithMaskedInputModelOutput(
+ last_hidden_state=sequence_output,
+ masked_hidden_state=apply_masks(sequence_output, context_mask),
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ predictor_output=predictor_output,
+ )
+
+ return encoder_output
+
+ def get_vision_features(self, pixel_values_videos) -> torch.Tensor:
+ encoder_output = self.forward(pixel_values_videos)
+ return encoder_output.last_hidden_state
+
+
+@auto_docstring(
+ custom_intro="""
+ V-JEPA 2 Model transformer with a video classification head on top (a linear layer on top of the attentive pooler).
+ """
+)
+class VJEPA2ForVideoClassification(VJEPA2PreTrainedModel):
+ def __init__(self, config: VJEPA2Config):
+ super().__init__(config)
+
+ self.num_labels = config.num_labels
+ self.vjepa2 = VJEPA2Model(config)
+
+ # Classifier head
+ self.pooler = VJEPA2AttentivePooler(config)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels, bias=True)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values_videos: torch.Tensor,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ ) -> Union[tuple, ImageClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the image classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Examples:
+
+ ```python
+ >>> import torch
+ >>> import numpy as np
+ >>> from transformers import AutoVideoProcessor, VJEPA2ForVideoClassification
+
+ >>> device = "cuda"
+
+ >>> video_processor = AutoVideoProcessor.from_pretrained("facebook/vjepa2-vitl-fpc16-256-ssv2")
+ >>> model = VJEPA2ForVideoClassification.from_pretrained("facebook/vjepa2-vitl-fpc16-256-ssv2").to(device)
+
+ >>> video = np.ones((64, 256, 256, 3)) # 64 frames, 256x256 RGB
+ >>> inputs = video_processor(video, return_tensors="pt").to(device)
+
+ >>> # For inference
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+ >>> logits = outputs.logits
+
+ >>> predicted_label = logits.argmax(-1).item()
+ >>> print(model.config.id2label[predicted_label])
+
+ >>> # For training
+ >>> labels = torch.ones(1, dtype=torch.long, device=device)
+ >>> loss = model(**inputs, labels=labels).loss
+
+ ```"""
+
+ outputs = self.vjepa2(
+ pixel_values_videos=pixel_values_videos,
+ skip_predictor=True,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ )
+
+ last_hidden_state = outputs.last_hidden_state
+ pooler_output = self.pooler(last_hidden_state)
+ logits = self.classifier(pooler_output)
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(pooled_logits=logits, labels=labels, config=self.config)
+
+ return ImageClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["VJEPA2Model", "VJEPA2PreTrainedModel", "VJEPA2ForVideoClassification"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/video_processing_vjepa2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/video_processing_vjepa2.py
new file mode 100644
index 0000000000000000000000000000000000000000..2df100f7eb782293c40b8fcd8e19d9a1ff98fc94
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/vjepa2/video_processing_vjepa2.py
@@ -0,0 +1,59 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Video processor class for VJEPA2."""
+
+from ...image_utils import (
+ IMAGENET_DEFAULT_MEAN,
+ IMAGENET_DEFAULT_STD,
+)
+from ...processing_utils import Unpack, VideosKwargs
+from ...utils import is_vision_available
+from ...utils.import_utils import requires
+from ...video_processing_utils import BaseVideoProcessor
+
+
+if is_vision_available():
+ from ...image_utils import PILImageResampling
+
+
+class VJEPA2VideoProcessorInitKwargs(VideosKwargs): ...
+
+
+@requires(backends=("torchvision",))
+class VJEPA2VideoProcessor(BaseVideoProcessor):
+ resample = PILImageResampling.BILINEAR
+ image_mean = IMAGENET_DEFAULT_MEAN
+ image_std = IMAGENET_DEFAULT_STD
+ size = {"shortest_edge": int(256 * 256 / 224)}
+ crop_size = 256
+ do_resize = True
+ do_rescale = True
+ do_center_crop = True
+ do_normalize = True
+ valid_kwargs = VJEPA2VideoProcessorInitKwargs
+ model_input_names = ["pixel_values_videos"]
+
+ def __init__(self, **kwargs: Unpack[VJEPA2VideoProcessorInitKwargs]):
+ crop_size = kwargs.get("crop_size", 256)
+ if not isinstance(crop_size, int):
+ if not isinstance(crop_size, dict) or "height" not in crop_size:
+ raise ValueError("crop_size must be an integer or a dictionary with a 'height' key")
+ crop_size = crop_size["height"]
+ resize_size = int(crop_size * 256 / 224)
+ kwargs["size"] = {"shortest_edge": resize_size}
+ super().__init__(**kwargs)
+
+
+__all__ = ["VJEPA2VideoProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..fa7fc1b411d35ab272c3217221eead1c0082e7cf
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/__init__.py
@@ -0,0 +1,29 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_voxtral import *
+ from .modeling_voxtral import *
+ from .processing_voxtral import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/configuration_voxtral.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/configuration_voxtral.py
new file mode 100644
index 0000000000000000000000000000000000000000..8cdd499cdeaae9d1e28d8c8981f7261e7d09564a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/configuration_voxtral.py
@@ -0,0 +1,201 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from ...configuration_utils import PretrainedConfig
+from ..auto import CONFIG_MAPPING, AutoConfig
+
+
+class VoxtralEncoderConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VoxtralEncoder`]. It is used to instantiate a
+ Voxtral audio encoder according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the audio encoder of the Voxtral
+ architecture.
+
+ e.g. [mistralai/Voxtral-Mini-3B-2507](https://huggingface.co/mistralai/Voxtral-Mini-3B-2507)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 51866):
+ Vocabulary size of the model.
+ hidden_size (`int`, *optional*, defaults to 1280):
+ Dimensionality of the hidden representations.
+ intermediate_size (`int`, *optional*, defaults to 5120):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 32):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 20):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ scale_embedding (`bool`, *optional*, defaults to `False`):
+ Scale embeddings by dividing by sqrt(hidden_size) if True.
+ activation_function (`str`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, "gelu",
+ num_mel_bins (`int`, *optional*, defaults to 128):
+ Number of mel features used per input features. Should correspond to the value used in the
+ `VoxtralProcessor` class.
+ max_source_positions (`int`, *optional*, defaults to 1500):
+ The maximum sequence length of log-mel filter-bank features that this model might ever be used with.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+
+ ```python
+ >>> from transformers import VoxtralEncoderConfig, VoxtralEncoder
+
+ >>> # Initializing a VoxtralEncoderConfig
+ >>> configuration = VoxtralEncoderConfig()
+
+ >>> # Initializing a VoxtralEncoder (with random weights)
+ >>> model = VoxtralEncoder(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "voxtral_encoder"
+
+ attribute_map = {
+ "d_model": "hidden_size",
+ "encoder_layers": "num_hidden_layers",
+ "encoder_attention_heads": "num_attention_heads",
+ "encoder_ffn_dim": "intermediate_size",
+ "encoder_layerdrop": "layerdrop",
+ }
+
+ def __init__(
+ self,
+ vocab_size=51866,
+ hidden_size=1280,
+ intermediate_size=5120,
+ num_hidden_layers=32,
+ num_attention_heads=20,
+ scale_embedding=False,
+ activation_function="gelu",
+ num_mel_bins=128,
+ max_source_positions=1500,
+ initializer_range=0.02,
+ attention_dropout=0.0,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+
+ self.num_attention_heads = num_attention_heads
+ self.scale_embedding = scale_embedding # scale factor will be sqrt(hidden_size) if True
+ self.activation_function = activation_function
+ self.num_mel_bins = num_mel_bins
+ self.max_source_positions = max_source_positions
+ self.initializer_range = initializer_range
+
+ # TODO: @eustlb, we do not use dropout and layerdrop, yet we need to hardcode them
+ # to be able to use Whisper with modular (here actually from Qwen2-Audio and copied from).
+ # After a future Whisper refactor, we should remove this.
+ self.dropout = 0.0
+ self.layerdrop = 0.0
+ self.activation_dropout = 0.0
+
+ self.attention_dropout = attention_dropout
+
+
+class VoxtralConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`VoxtralForConditionalGeneration`]. It is used to instantiate an
+ Voxtral model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the Voxtral-Mini-3B.
+
+ e.g. [mistralai/Voxtral-Mini-3B-2507](https://huggingface.co/mistralai/Voxtral-Mini-3B-2507)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ audio_config (`Union[AutoConfig, dict]`, *optional*):
+ The config object or dictionary of the audio encoder.
+ text_config (`Union[AutoConfig, dict]`, *optional*):
+ The config object or dictionary of the text model.
+ audio_token_id (`int`, *optional*):
+ The image token index to encode the image prompt.
+ projector_hidden_act (`str`, *optional*, defaults to `"gelu"`):
+ The activation function (function or string) in the multi-modal projector.
+
+ ```python
+ >>> from transformers import VoxtralForConditionalGeneration, VoxtralConfig
+
+ >>> # Initializing a Voxtral configuration
+ >>> configuration = VoxtralConfig(audio_token_id=24, projector_hidden_act="gelu")
+
+ >>> # Initializing a 3B model with random weights
+ >>> model = VoxtralForConditionalGeneration(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "voxtral"
+ sub_configs = {"text_config": AutoConfig, "audio_config": AutoConfig}
+
+ _default_text_config_kwargs = {
+ "vocab_size": 131072,
+ "hidden_size": 3072,
+ "intermediate_size": 8192,
+ "num_hidden_layers": 30,
+ "num_key_value_heads": 8,
+ "max_position_embeddings": 131072,
+ "rms_norm_eps": 1e-05,
+ "use_cache": True,
+ "rope_theta": 100000000.0,
+ "head_dim": 128,
+ }
+
+ def __init__(
+ self,
+ audio_config=None,
+ text_config=None,
+ audio_token_id=None,
+ projector_hidden_act="gelu",
+ **kwargs,
+ ):
+ if isinstance(audio_config, dict):
+ audio_config["model_type"] = audio_config.get("model_type", "voxtral_encoder")
+ audio_config = CONFIG_MAPPING[audio_config["model_type"]](**audio_config)
+ elif audio_config is None:
+ audio_config = CONFIG_MAPPING["voxtral_encoder"]()
+ self.audio_config = audio_config
+
+ if isinstance(text_config, dict):
+ text_config["model_type"] = text_config.get("model_type", "llama")
+ text_config = CONFIG_MAPPING[text_config["model_type"]](
+ **{**self._default_text_config_kwargs, **text_config}
+ )
+ elif text_config is None:
+ text_config = CONFIG_MAPPING["llama"](**self._default_text_config_kwargs)
+ self.text_config = text_config
+
+ self.vocab_size = text_config.vocab_size
+ self.hidden_size = text_config.hidden_size
+ self.audio_token_id = audio_token_id
+ self.projector_hidden_act = projector_hidden_act
+
+ super().__init__(**kwargs)
+
+
+__all__ = ["VoxtralEncoderConfig", "VoxtralConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/modeling_voxtral.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/modeling_voxtral.py
new file mode 100644
index 0000000000000000000000000000000000000000..3dbbbd9fee0b5f9fa6329cde417aad275f52c45d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/modeling_voxtral.py
@@ -0,0 +1,542 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/voxtral/modular_voxtral.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_voxtral.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import math
+from typing import Callable, Optional, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache
+from ...generation import GenerationMixin
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPast, CausalLMOutputWithPast
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, auto_docstring, can_return_tuple, logging
+from ...utils.generic import check_model_inputs
+from ..auto import AutoModel, AutoModelForCausalLM
+from .configuration_voxtral import VoxtralConfig, VoxtralEncoderConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: Optional[float] = None,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ if scaling is None:
+ scaling = query.size(-1) ** -0.5
+
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None and attention_mask.ndim == 4:
+ attn_weights = attn_weights + attention_mask[:, :, :, : key.shape[-2]]
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class VoxtralAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ is_causal: bool = False,
+ layer_idx: Optional[int] = None,
+ config: Optional[VoxtralConfig] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ self.config = config
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.is_causal = is_causal
+
+ if layer_idx is None and is_decoder:
+ logger.warning_once(
+ f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and "
+ "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+ self.layer_idx = layer_idx
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=False)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ def _shape(self, tensor: torch.Tensor, seq_len: int, bsz: int):
+ return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ **kwargs,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ bsz, tgt_len, _ = hidden_states.size()
+
+ # Scaling is susceptible to floating point arithmetics' inprecisions
+ # which can lead to different results (this is dependent from model
+ # to model, e.g. whisper is one such case). We therefore keep the
+ # original order of scaling to follow the original implementation
+ # and enforce no scaling (1.0) in the attention call below.
+ query_states = self._shape(self.q_proj(hidden_states) * self.scaling, tgt_len, bsz)
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.dropout,
+ scaling=1.0,
+ output_attentions=output_attentions,
+ head_mask=layer_head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+class VoxtralEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: VoxtralConfig):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = VoxtralAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.encoder_attention_heads,
+ dropout=config.attention_dropout,
+ config=config,
+ )
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+ self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim)
+ self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ layer_head_mask: torch.Tensor,
+ output_attentions: bool = False,
+ ) -> torch.Tensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ return hidden_states, attn_weights
+
+
+@auto_docstring
+class VoxtralPreTrainedModel(PreTrainedModel):
+ config: VoxtralConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = None
+ _skip_keys_device_placement = "past_key_values"
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+ _supports_cache_class = True
+ _supports_attention_backend = True
+ _can_compile_fullgraph = True
+
+ def _init_weights(self, module):
+ # important: this ported version of Voxtral isn't meant for training from scratch - only
+ # inference and fine-tuning - so the proper init weights code has been removed
+ std = (
+ self.config.initializer_range
+ if hasattr(self.config, "initializer_range")
+ else self.config.audio_config.initializer_range
+ )
+
+ if isinstance(module, (nn.Linear, nn.Conv1d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.weight.data.fill_(1.0)
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+@auto_docstring(
+ custom_intro="""
+ The Voxtral encoder, which is a Whisper encoder.
+ """
+)
+class VoxtralEncoder(VoxtralPreTrainedModel):
+ """
+ Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a
+ [`VoxtralEncoderLayer`].
+
+ Args:
+ config: VoxtralEncoderConfig
+ """
+
+ # Ignore copy
+ config: VoxtralEncoderConfig
+ main_input_name = "input_features"
+ _no_split_modules = ["VoxtralEncoderLayer"]
+ _can_record_outputs = {
+ "attentions": VoxtralAttention,
+ "hidden_states": VoxtralEncoderLayer,
+ }
+
+ def __init__(self, config: VoxtralEncoderConfig):
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.encoder_layerdrop
+
+ embed_dim = config.d_model
+ self.num_mel_bins = config.num_mel_bins
+ self.padding_idx = config.pad_token_id
+ self.max_source_positions = config.max_source_positions
+ self.embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0
+
+ self.conv1 = nn.Conv1d(self.num_mel_bins, embed_dim, kernel_size=3, padding=1)
+ self.conv2 = nn.Conv1d(embed_dim, embed_dim, kernel_size=3, stride=2, padding=1)
+
+ self.embed_positions = nn.Embedding(self.max_source_positions, embed_dim)
+ self.embed_positions.requires_grad_(False)
+
+ self.layers = nn.ModuleList([VoxtralEncoderLayer(config) for _ in range(config.encoder_layers)])
+ self.layer_norm = nn.LayerNorm(config.d_model)
+ # Ignore copy
+ self.avg_pooler = nn.AvgPool1d(2, stride=2)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.conv1
+
+ def set_input_embeddings(self, value: nn.Module):
+ self.conv1 = value
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_features,
+ attention_mask=None,
+ **kwargs: Unpack[TransformersKwargs],
+ ):
+ r"""
+ Args:
+ input_features (`torch.LongTensor` of shape `(batch_size, feature_size, sequence_length)`):
+ Float values of mel features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]` or a
+ `numpy.ndarray`, *e.g.* via the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the mel features, padding
+ and conversion into a tensor of type `torch.FloatTensor`. See [`~WhisperFeatureExtractor.__call__`]
+ attention_mask (`torch.Tensor`)`, *optional*):
+ Voxtral does not support masking of the `input_features`, this argument is preserved for compatibility,
+ but it is not used. By default the silence in the input log mel spectrogram are ignored.
+ """
+ expected_seq_length = self.config.max_source_positions * self.conv1.stride[0] * self.conv2.stride[0]
+ if input_features.shape[-1] != expected_seq_length:
+ raise ValueError(
+ f"Qwen2Audio expects the mel input features to be of length {expected_seq_length}, but found {input_features.shape[-1]}. Make sure to pad the input mel features to {expected_seq_length}."
+ )
+
+ input_features = input_features.to(dtype=self.conv1.weight.dtype, device=self.conv1.weight.device)
+ inputs_embeds = nn.functional.gelu(self.conv1(input_features))
+ inputs_embeds = nn.functional.gelu(self.conv2(inputs_embeds))
+ inputs_embeds = inputs_embeds.permute(0, 2, 1)
+
+ embed_pos = self.embed_positions.weight
+ hidden_states = (inputs_embeds + embed_pos).to(inputs_embeds.dtype)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ for idx, encoder_layer in enumerate(self.layers):
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=None,
+ )
+ hidden_states = layer_outputs[0]
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ )
+
+ # Ignore copy
+ def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor):
+ """
+ Computes the output length of the convolutional layers and the output length of the audio encoder
+ """
+ input_lengths = (input_lengths - 1) // 2 + 1
+ output_lengths = (input_lengths - 2) // 2 + 1
+ return input_lengths, output_lengths
+
+
+class VoxtralMultiModalProjector(nn.Module):
+ def __init__(self, config: VoxtralConfig):
+ super().__init__()
+ self.linear_1 = nn.Linear(config.audio_config.intermediate_size, config.text_config.hidden_size, bias=False)
+ self.act = ACT2FN[config.projector_hidden_act]
+ self.linear_2 = nn.Linear(config.text_config.hidden_size, config.text_config.hidden_size, bias=False)
+
+ def forward(self, audio_features):
+ hidden_states = self.linear_1(audio_features)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ The Voxtral model, which consists of Whisper encoder, a multi-modal projector and a LLama language model.
+ """
+)
+class VoxtralForConditionalGeneration(VoxtralPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.weight"]
+ _tp_plan = {"lm_head": "colwise_rep"}
+ _pp_plan = {"lm_head": (["hidden_states"], ["logits"])}
+ _keep_in_fp32_modules_strict = ["embed_positions"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.vocab_size = config.text_config.vocab_size
+ self.audio_tower = AutoModel.from_config(config.audio_config)
+ self.language_model = AutoModelForCausalLM.from_config(config.text_config)
+ self.multi_modal_projector = VoxtralMultiModalProjector(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.language_model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.language_model.set_input_embeddings(value)
+
+ def get_output_embeddings(self):
+ return self.language_model.get_output_embeddings()
+
+ def set_output_embeddings(self, new_embeddings):
+ self.language_model.set_output_embeddings(new_embeddings)
+
+ def set_decoder(self, decoder):
+ self.language_model.set_decoder(decoder)
+
+ def get_decoder(self):
+ return self.language_model.get_decoder()
+
+ def get_audio_embeds(self, input_features: torch.FloatTensor):
+ """
+ This method is used to get the audio embeddings from input features (a log mel spectrogram), meaning inferring the audio encoder and the multi-modal projector.
+ Args:
+ input_features (`torch.FloatTensor`):
+ Float values of mel features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]` or a
+ `numpy.ndarray`, *e.g.* via the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the mel features, padding
+ and conversion into a tensor of type `torch.FloatTensor`. See [`~WhisperFeatureExtractor.__call__`]
+
+ Returns:
+ `torch.FloatTensor`:
+ The audio embeddings.
+ """
+ audio_outputs = self.audio_tower(input_features)
+ audio_hidden_states = audio_outputs.last_hidden_state
+ audio_hidden_states = audio_hidden_states.reshape(-1, self.config.audio_config.intermediate_size)
+ audio_embeds = self.multi_modal_projector(audio_hidden_states)
+ return audio_embeds
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ input_features: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> CausalLMOutputWithPast:
+ r"""
+ Example:
+
+ ```python
+ >>> from transformers import VoxtralForConditionalGeneration, AutoProcessor
+ >>> import torch
+
+ >>> device = "cuda" if torch.cuda.is_available() else "cpu"
+ >>> repo_id = "mistralai/Voxtral-Mini-3B-2507"
+
+ >>> processor = AutoProcessor.from_pretrained(repo_id)
+ >>> model = VoxtralForConditionalGeneration.from_pretrained(repo_id, dtype=torch.bfloat16, device_map=device)
+
+ >>> conversation = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "audio",
+ "url": "https://huggingface.co/datasets/hf-internal-testing/dummy-audio-samples/resolve/main/dude_where_is_my_car.wav",
+ },
+ {"type": "text", "text": "What can you tell me about this audio?"},
+ ],
+ }
+ ]
+
+ >>> inputs = processor.apply_chat_template(conversation)
+ >>> inputs = inputs.to(device, dtype=torch.bfloat16)
+
+ >>> outputs = model.generate(**inputs, max_new_tokens=30)
+ >>> processor.batch_decode(outputs[:, inputs.input_ids.shape[1]:], skip_special_tokens=True)
+ ["This audio is a humorous conversation between two friends, likely in English, where one of them is trying to figure out what the other's tattoo says."]
+ ```"""
+ if inputs_embeds is None:
+ inputs_embeds = self.get_input_embeddings()(input_ids)
+
+ if input_features is not None:
+ audio_embeds = self.get_audio_embeds(input_features)
+
+ # replace text-audio token placeholders with audio embeddings
+ audio_token_mask = input_ids == self.config.audio_token_id
+ inputs_embeds[audio_token_mask] = audio_embeds
+
+ outputs: BaseModelOutputWithPast = self.language_model(
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ labels=labels,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ logits_to_keep=logits_to_keep,
+ **kwargs,
+ )
+ return outputs
+
+ def prepare_inputs_for_generation(self, *args, **kwargs):
+ # Overwritten -- we should not pass input_features when we are in cached decoding stage
+
+ input_features = kwargs.pop("input_features", None)
+ cache_position = kwargs.get("cache_position")
+
+ model_inputs = super().prepare_inputs_for_generation(*args, **kwargs)
+
+ if cache_position is not None and cache_position[0] == 0:
+ # input_features should only be passed when we are not in cached decoding stage
+ model_inputs["input_features"] = input_features
+
+ return model_inputs
+
+
+__all__ = ["VoxtralPreTrainedModel", "VoxtralEncoder", "VoxtralForConditionalGeneration"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/modular_voxtral.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/modular_voxtral.py
new file mode 100644
index 0000000000000000000000000000000000000000..0c325c0c605edf20ad11e1fc51aaa93d15fd30b6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/modular_voxtral.py
@@ -0,0 +1,277 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache
+from ...generation import GenerationMixin
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPast, CausalLMOutputWithPast
+from ...processing_utils import Unpack
+from ...utils import TransformersKwargs, auto_docstring, can_return_tuple
+from ...utils.generic import check_model_inputs
+from ..auto import AutoModel, AutoModelForCausalLM
+from ..qwen2_audio.modeling_qwen2_audio import (
+ Qwen2AudioAttention,
+ Qwen2AudioEncoder,
+ Qwen2AudioEncoderLayer,
+ Qwen2AudioPreTrainedModel,
+)
+from .configuration_voxtral import VoxtralConfig
+
+
+class VoxtralAttention(Qwen2AudioAttention):
+ pass
+
+
+class VoxtralEncoderLayer(Qwen2AudioEncoderLayer):
+ pass
+
+
+class VoxtralPreTrainedModel(Qwen2AudioPreTrainedModel):
+ _supports_flex_attn = True
+ _supports_cache_class = True
+ _supports_attention_backend = True
+ _can_compile_fullgraph = True
+ _supports_attention_backend = True
+ _no_split_modules = None
+
+
+# TODO: @eustlb, I would really prefer to use WhisperEncoder but it's messing with modular
+@auto_docstring(
+ custom_intro="""
+ The Voxtral encoder, which is a Whisper encoder.
+ """
+)
+class VoxtralEncoder(Qwen2AudioEncoder):
+ _can_record_outputs = {
+ "attentions": VoxtralAttention,
+ "hidden_states": VoxtralEncoderLayer,
+ }
+
+ @check_model_inputs
+ def forward(
+ self,
+ input_features,
+ attention_mask=None,
+ **kwargs: Unpack[TransformersKwargs],
+ ):
+ r"""
+ Args:
+ input_features (`torch.LongTensor` of shape `(batch_size, feature_size, sequence_length)`):
+ Float values of mel features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]` or a
+ `numpy.ndarray`, *e.g.* via the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the mel features, padding
+ and conversion into a tensor of type `torch.FloatTensor`. See [`~WhisperFeatureExtractor.__call__`]
+ attention_mask (`torch.Tensor`)`, *optional*):
+ Voxtral does not support masking of the `input_features`, this argument is preserved for compatibility,
+ but it is not used. By default the silence in the input log mel spectrogram are ignored.
+ """
+ expected_seq_length = self.config.max_source_positions * self.conv1.stride[0] * self.conv2.stride[0]
+ if input_features.shape[-1] != expected_seq_length:
+ raise ValueError(
+ f"Qwen2Audio expects the mel input features to be of length {expected_seq_length}, but found {input_features.shape[-1]}. Make sure to pad the input mel features to {expected_seq_length}."
+ )
+
+ input_features = input_features.to(dtype=self.conv1.weight.dtype, device=self.conv1.weight.device)
+ inputs_embeds = nn.functional.gelu(self.conv1(input_features))
+ inputs_embeds = nn.functional.gelu(self.conv2(inputs_embeds))
+ inputs_embeds = inputs_embeds.permute(0, 2, 1)
+
+ embed_pos = self.embed_positions.weight
+ hidden_states = (inputs_embeds + embed_pos).to(inputs_embeds.dtype)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ for idx, encoder_layer in enumerate(self.layers):
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=None,
+ )
+ hidden_states = layer_outputs[0]
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ )
+
+
+class VoxtralMultiModalProjector(nn.Module):
+ def __init__(self, config: VoxtralConfig):
+ super().__init__()
+ self.linear_1 = nn.Linear(config.audio_config.intermediate_size, config.text_config.hidden_size, bias=False)
+ self.act = ACT2FN[config.projector_hidden_act]
+ self.linear_2 = nn.Linear(config.text_config.hidden_size, config.text_config.hidden_size, bias=False)
+
+ def forward(self, audio_features):
+ hidden_states = self.linear_1(audio_features)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ The Voxtral model, which consists of Whisper encoder, a multi-modal projector and a LLama language model.
+ """
+)
+class VoxtralForConditionalGeneration(VoxtralPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.weight"]
+ _tp_plan = {"lm_head": "colwise_rep"}
+ _pp_plan = {"lm_head": (["hidden_states"], ["logits"])}
+ _keep_in_fp32_modules_strict = ["embed_positions"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.vocab_size = config.text_config.vocab_size
+ self.audio_tower = AutoModel.from_config(config.audio_config)
+ self.language_model = AutoModelForCausalLM.from_config(config.text_config)
+ self.multi_modal_projector = VoxtralMultiModalProjector(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.language_model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.language_model.set_input_embeddings(value)
+
+ def get_output_embeddings(self):
+ return self.language_model.get_output_embeddings()
+
+ def set_output_embeddings(self, new_embeddings):
+ self.language_model.set_output_embeddings(new_embeddings)
+
+ def set_decoder(self, decoder):
+ self.language_model.set_decoder(decoder)
+
+ def get_decoder(self):
+ return self.language_model.get_decoder()
+
+ def get_audio_embeds(self, input_features: torch.FloatTensor):
+ """
+ This method is used to get the audio embeddings from input features (a log mel spectrogram), meaning inferring the audio encoder and the multi-modal projector.
+ Args:
+ input_features (`torch.FloatTensor`):
+ Float values of mel features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]` or a
+ `numpy.ndarray`, *e.g.* via the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the mel features, padding
+ and conversion into a tensor of type `torch.FloatTensor`. See [`~WhisperFeatureExtractor.__call__`]
+
+ Returns:
+ `torch.FloatTensor`:
+ The audio embeddings.
+ """
+ audio_outputs = self.audio_tower(input_features)
+ audio_hidden_states = audio_outputs.last_hidden_state
+ audio_hidden_states = audio_hidden_states.reshape(-1, self.config.audio_config.intermediate_size)
+ audio_embeds = self.multi_modal_projector(audio_hidden_states)
+ return audio_embeds
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ input_features: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> CausalLMOutputWithPast:
+ r"""
+ Example:
+
+ ```python
+ >>> from transformers import VoxtralForConditionalGeneration, AutoProcessor
+ >>> import torch
+
+ >>> device = "cuda" if torch.cuda.is_available() else "cpu"
+ >>> repo_id = "mistralai/Voxtral-Mini-3B-2507"
+
+ >>> processor = AutoProcessor.from_pretrained(repo_id)
+ >>> model = VoxtralForConditionalGeneration.from_pretrained(repo_id, dtype=torch.bfloat16, device_map=device)
+
+ >>> conversation = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "audio",
+ "url": "https://huggingface.co/datasets/hf-internal-testing/dummy-audio-samples/resolve/main/dude_where_is_my_car.wav",
+ },
+ {"type": "text", "text": "What can you tell me about this audio?"},
+ ],
+ }
+ ]
+
+ >>> inputs = processor.apply_chat_template(conversation)
+ >>> inputs = inputs.to(device, dtype=torch.bfloat16)
+
+ >>> outputs = model.generate(**inputs, max_new_tokens=30)
+ >>> processor.batch_decode(outputs[:, inputs.input_ids.shape[1]:], skip_special_tokens=True)
+ ["This audio is a humorous conversation between two friends, likely in English, where one of them is trying to figure out what the other's tattoo says."]
+ ```"""
+ if inputs_embeds is None:
+ inputs_embeds = self.get_input_embeddings()(input_ids)
+
+ if input_features is not None:
+ audio_embeds = self.get_audio_embeds(input_features)
+
+ # replace text-audio token placeholders with audio embeddings
+ audio_token_mask = input_ids == self.config.audio_token_id
+ inputs_embeds[audio_token_mask] = audio_embeds
+
+ outputs: BaseModelOutputWithPast = self.language_model(
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ labels=labels,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ logits_to_keep=logits_to_keep,
+ **kwargs,
+ )
+ return outputs
+
+ def prepare_inputs_for_generation(self, *args, **kwargs):
+ # Overwritten -- we should not pass input_features when we are in cached decoding stage
+
+ input_features = kwargs.pop("input_features", None)
+ cache_position = kwargs.get("cache_position")
+
+ model_inputs = super().prepare_inputs_for_generation(*args, **kwargs)
+
+ if cache_position is not None and cache_position[0] == 0:
+ # input_features should only be passed when we are not in cached decoding stage
+ model_inputs["input_features"] = input_features
+
+ return model_inputs
+
+
+__all__ = ["VoxtralPreTrainedModel", "VoxtralEncoder", "VoxtralForConditionalGeneration"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/processing_voxtral.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/processing_voxtral.py
new file mode 100644
index 0000000000000000000000000000000000000000..0cf2d121f9daad7962ba6bd632cfb347d6f2c5c1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/voxtral/processing_voxtral.py
@@ -0,0 +1,435 @@
+# coding=utf-8
+# Copyright 2025 Sesame and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import io
+from typing import Optional, Union
+
+from ...utils import is_mistral_common_available, is_soundfile_available, is_torch_available, logging
+
+
+if is_torch_available():
+ import torch
+
+if is_soundfile_available():
+ import soundfile as sf
+
+if is_mistral_common_available():
+ from mistral_common.protocol.transcription.request import TranscriptionRequest
+
+from ...audio_utils import AudioInput, load_audio_as, make_list_of_audio
+from ...feature_extraction_utils import BatchFeature
+from ...processing_utils import AllKwargsForChatTemplate, AudioKwargs, ProcessingKwargs, ProcessorMixin, Unpack
+from ...tokenization_utils_base import PreTokenizedInput, TextInput
+
+
+logger = logging.get_logger(__name__)
+
+
+class VoxtralAudioKwargs(AudioKwargs, total=False):
+ max_source_positions: Optional[int]
+
+
+class VoxtralProcessorKwargs(ProcessingKwargs, total=False):
+ _defaults = {
+ "text_kwargs": {
+ "padding": True,
+ },
+ "audio_kwargs": {
+ "sampling_rate": 16000,
+ "padding": True,
+ "truncation": False,
+ "pad_to_multiple_of": 480000,
+ "max_source_positions": 3000,
+ },
+ "common_kwargs": {
+ "return_tensors": "pt",
+ "return_dict": True,
+ "tokenize": True,
+ },
+ }
+
+
+class VoxtralProcessor(ProcessorMixin):
+ r"""
+ Constructs a Voxtral processor which wraps [`WhisperFeatureExtractor`] and
+ [`MistralCommonTokenizer`] into a single processor that inherits both the audio feature extraction and
+ tokenizer functionalities.
+
+ Args:
+ feature_extractor ([`WhisperFeatureExtractor`]):
+ The feature extractor is a required input.
+ tokenizer ([`MistralCommonTokenizer`]):
+ The tokenizer is a required input.
+ """
+
+ attributes = ["feature_extractor", "tokenizer"]
+ feature_extractor_class = "WhisperFeatureExtractor"
+ tokenizer_class = "MistralCommonTokenizer"
+
+ def __init__(
+ self,
+ feature_extractor,
+ tokenizer,
+ ):
+ self.audio_token_id = 24
+ self.audio_token = tokenizer.convert_ids_to_tokens(self.audio_token_id)
+
+ super().__init__(feature_extractor, tokenizer)
+
+ def _retreive_input_features(self, audio, max_source_positions, **kwargs):
+ """
+ Handles specific logic of Voxtral expected input features: audio arrays should be padded to next multiple of 480000 (duration is a multiple of 30s), see VoxtralProcessorKwargs' default audio_kwargs.
+ Then mel input features are extracted and stacked along batch dimension, splitting into chunks of max_source_positions.
+ """
+ input_features_list = []
+ for audio_array in audio:
+ audio_inputs = self.feature_extractor(audio_array, **kwargs)
+
+ # let's split into chunks of max_source_positions, and then stack them along batch dimension
+ input_features = audio_inputs["input_features"].reshape(
+ self.feature_extractor.feature_size, -1, max_source_positions
+ )
+ input_features_list.append(input_features.transpose(0, 1))
+
+ return torch.cat(input_features_list)
+
+ def apply_chat_template(
+ self,
+ conversation: Union[list[dict[str, str]], list[list[dict[str, str]]]],
+ **kwargs: Unpack[AllKwargsForChatTemplate],
+ ) -> str:
+ """
+ This method applies the model's chat completion template given a conversation. It relies on MistralCommonTokenizer's
+ [`~MistralCommonTokenizer.apply_chat_template`] to prepare input ids to the model and on WhisperFeatureExtractor's
+ [`~WhisperFeatureExtractor.__call__`] to prepare input features to the model.
+
+ Note that audio is padded to the nearest 30-second multiple prior to mel feature extraction.
+
+ A `conversation` is a list of messages, where each message is a dictionary with a `role` and a `content` field.
+ For Voxtral, `role` can be `"user"` or `"assistant"`.
+ The `content` field can be a string or a list of dictionaries with a `type` field. See example below.
+
+ ```python
+ from huggingface_hub import hf_hub_download
+ from transformers.audio_utils import load_audio_as
+
+ audio_url = "https://huggingface.co/datasets/hf-internal-testing/dummy-audio-samples/resolve/main/bcn_weather.mp3"
+ audio_path = hf_hub_download(repo_id="hf-internal-testing/dummy-audio-samples", filename="bcn_weather.mp3", repo_type="dataset")
+ audio_base64 = load_audio_as(audio_path, return_format="base64", force_mono=True)
+
+ # audio + text
+ conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "audio", "url": audio_url},
+ {"type": "audio", "path": audio_path},
+ {"type": "audio", "base64": audio_base64},
+ {"type": "text", "text": "How many audio do you hear?"},
+ ],
+ },
+ ]
+
+ processor = VoxtralProcessor.from_pretrained("mistralai/Voxtral-Mini-3B-2507")
+ inputs = processor.apply_chat_template(conversation)
+ ```
+
+ Args:
+ conversation (`Union[list[Dict, [str, str]], list[list[dict[str, str]]]]`):
+ The conversation to format.
+ """
+ if kwargs.get("continue_final_message", False):
+ if kwargs.get("add_generation_prompt", False):
+ raise ValueError(
+ "continue_final_message and add_generation_prompt are not compatible. Use continue_final_message when you want the model to continue the final message, and add_generation_prompt when you want to add a header that will prompt it to start a new assistant message instead."
+ )
+ if kwargs.get("return_assistant_tokens_mask", False):
+ raise ValueError("continue_final_message is not compatible with return_assistant_tokens_mask.")
+
+ # Fill sets of kwargs that should be used by different parts of template
+ processed_kwargs = {
+ "mm_load_kwargs": {},
+ "template_kwargs": {},
+ }
+
+ for kwarg_type in processed_kwargs:
+ for key in AllKwargsForChatTemplate.__annotations__[kwarg_type].__annotations__:
+ kwarg_type_defaults = AllKwargsForChatTemplate.__annotations__[kwarg_type]
+ default_value = getattr(kwarg_type_defaults, key, None)
+ value = kwargs.pop(key, default_value)
+ if value is not None and not isinstance(value, dict):
+ processed_kwargs[kwarg_type][key] = value
+
+ # Pass unprocessed custom kwargs
+ processed_kwargs["template_kwargs"].update(kwargs)
+
+ if isinstance(conversation, (list, tuple)) and (
+ isinstance(conversation[0], (list, tuple)) or hasattr(conversation[0], "content")
+ ):
+ is_batched = True
+ conversations = conversation
+ else:
+ is_batched = False
+ conversations = [conversation]
+
+ # Check for any overlapping keys between mm_load_kwargs and kwargs
+ mm_load_kwargs = processed_kwargs["mm_load_kwargs"]
+ if any(key in kwargs for key in mm_load_kwargs):
+ overlapping_keys = [key for key in mm_load_kwargs if key in kwargs]
+ logger.warning(
+ f"{overlapping_keys[0] if len(overlapping_keys) == 1 else ', '.join(overlapping_keys)} load multimodal data kwarg{'s' if len(overlapping_keys) > 1 else ''} {'have' if len(overlapping_keys) > 1 else 'has'} been passed to the processor, but {'they are' if len(overlapping_keys) > 1 else 'it is'} not supported for VoxtralProcessor since it relies on mistral_common directly. {'They' if len(overlapping_keys) > 1 else 'It'} will be ignored."
+ )
+
+ output_kwargs = self._merge_kwargs(
+ VoxtralProcessorKwargs,
+ **kwargs,
+ )
+ text_kwargs = output_kwargs["text_kwargs"]
+ audio_kwargs = output_kwargs["audio_kwargs"]
+ common_kwargs = output_kwargs["common_kwargs"]
+
+ return_tensors = common_kwargs.pop("return_tensors", None)
+ if return_tensors != "pt":
+ raise ValueError(f"{self.__class__.__name__} only supports `return_tensors='pt'`.")
+
+ tokenizer_kwargs = {**processed_kwargs["template_kwargs"], **text_kwargs}
+ tokenizer_kwargs["return_tensors"] = None # let's not return tensors here
+ tokenize = tokenizer_kwargs.pop("tokenize", False)
+ return_dict = tokenizer_kwargs.pop("return_dict", False)
+
+ encoded_instruct_inputs = self.tokenizer.apply_chat_template(
+ conversations,
+ tokenize=tokenize,
+ return_dict=return_dict,
+ **tokenizer_kwargs,
+ )
+
+ if tokenize:
+ if return_dict:
+ audio = encoded_instruct_inputs.pop("audio", None)
+ data = dict(encoded_instruct_inputs)
+ if audio is not None:
+ max_source_positions = audio_kwargs.pop("max_source_positions")
+ data["input_features"] = self._retreive_input_features(audio, max_source_positions, **audio_kwargs)
+
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+ if not is_batched:
+ return encoded_instruct_inputs[0]
+
+ return encoded_instruct_inputs
+
+ def __call__(
+ self,
+ text: Optional[Union[TextInput, PreTokenizedInput, list[TextInput], list[PreTokenizedInput]]],
+ **kwargs: Unpack[VoxtralProcessorKwargs],
+ ):
+ r"""
+ Method to prepare text to be fed as input to the model. This method forwards the `text`
+ arguments to MistralCommonTokenizer's [`~MistralCommonTokenizer.__call__`] to encode
+ the text. Please refer to the docstring of the above methods for more information.
+ This methods does not support audio. To prepare the audio, please use:
+ 1. `apply_chat_template` [`~VoxtralProcessor.apply_chat_template`] method.
+ 2. `apply_transcription_request` [`~VoxtralProcessor.apply_transcription_request`] method.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors of a particular framework. Acceptable values are:
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+ Returns:
+ [`BatchFeature`]: A [`BatchFeature`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`.
+ - **input_features** -- List of audio values to be fed to a model. Returned when `audio` is not `None`.
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not
+ `None`).
+ """
+ if isinstance(text, str):
+ text = [text]
+
+ if any(self.audio_token in t for t in text):
+ raise ValueError(
+ f"{self.audio_token} is present in the provided text which is not supported by VoxtralProcessor. Please use the `apply_chat_template` method instead."
+ )
+
+ output_kwargs = self._merge_kwargs(
+ VoxtralProcessorKwargs,
+ **kwargs,
+ )
+ text_kwargs = output_kwargs["text_kwargs"]
+ common_kwargs = output_kwargs["common_kwargs"]
+
+ out = self.tokenizer(text, **text_kwargs)
+
+ return BatchFeature(data=out, tensor_type=common_kwargs.pop("return_tensors", None))
+
+ # TODO: @eustlb, this should be moved to mistral_common + testing
+ def apply_transcription_request(
+ self,
+ language: Union[str, list[str]],
+ audio: Union[str, list[str], AudioInput],
+ model_id: str,
+ sampling_rate: Optional[int] = None,
+ format: Optional[Union[str, list[str]]] = None,
+ **kwargs: Unpack[VoxtralProcessorKwargs],
+ ):
+ """
+ This method applies the model's transcription request template given a language and audio.
+ It relies on MistralCommonTokenizer and WhisperFeatureExtractor to prepare input ids and input features to the model.
+
+ ```python
+ from transformers import VoxtralProcessor
+
+ model_id = "mistralai/Voxtral-Mini-3B-2507"
+ processor = VoxtralProcessor.from_pretrained(model_id)
+
+ language = "en"
+ audio = "https://huggingface.co/datasets/hf-internal-testing/dummy-audio-samples/resolve/main/obama.mp3"
+
+ inputs = processor.apply_transcription_request(language=language, audio=audio, model_id=model_id)
+ ```
+
+ Args:
+ language (`str`, `list[str]`):
+ The language or languages of the audio. If provided as a string, will be applied uniformly to all audio.
+ If provided as a list, will be applied to each audio individually with a one-to-one mapping.
+ audio (`str`, `list[str]`, `np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, `list[torch.Tensor]`):
+ The audio or batch of audio to be prepared. If provided as a string, it should correspond to the path or url of the audio file.
+ model_id (`str`:
+ The hub model id of the model to use for transcription.
+ sampling_rate (`int`, *optional*):
+ The sampling rate of the audio. Necessary if it is provided as `np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, `list[torch.Tensor]`.
+ Used to avoid silent errors when passing audio that is not in the expected sampling rate.
+ format (`str`, `list[str]`, *optional*):
+ The format of the audio, necessary if is provided as `np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, `list[torch.Tensor]`.
+ """
+ output_kwargs = self._merge_kwargs(
+ VoxtralProcessorKwargs,
+ **kwargs,
+ )
+ text_kwargs = output_kwargs["text_kwargs"]
+ audio_kwargs = output_kwargs["audio_kwargs"]
+ common_kwargs = output_kwargs["common_kwargs"]
+
+ is_str = isinstance(audio, str)
+ is_list_of_str = all(isinstance(el, str) for el in audio)
+ is_list_of_audio = not (is_str or is_list_of_str)
+
+ if is_list_of_audio:
+ if sampling_rate is None:
+ logger.warning_once(
+ f"You've provided audio without specifying the sampling rate. It will be assumed to be {audio_kwargs['sampling_rate']}, which can result in silent errors."
+ )
+ elif sampling_rate != audio_kwargs["sampling_rate"]:
+ raise ValueError(
+ f"The sampling rate of the audio ({sampling_rate}) does not match the sampling rate of the processor ({audio_kwargs['sampling_rate']}). Please provide resampled the audio to the expected sampling rate."
+ )
+
+ sampling_rate = audio_kwargs["sampling_rate"]
+ return_dict = common_kwargs.pop("return_dict", False)
+ tokenize = common_kwargs.pop("tokenize", False)
+
+ # make sure to remove from text_kwargs and audio_kwargs
+ for k in ("return_dict", "tokenize"):
+ text_kwargs.pop(k, None)
+ audio_kwargs.pop(k, None)
+
+ return_tensors = common_kwargs.pop("return_tensors", None)
+ if return_tensors != "pt":
+ raise ValueError(f"{self.__class__.__name__} only supports `return_tensors='pt'`.")
+
+ # validate audio input
+ if is_str:
+ audio = [load_audio_as(audio, return_format="buffer", force_mono=True, sampling_rate=sampling_rate)]
+ elif is_list_of_str:
+ audio = [
+ load_audio_as(el, return_format="buffer", force_mono=True, sampling_rate=sampling_rate) for el in audio
+ ]
+ else:
+ audio = make_list_of_audio(audio)
+ if len(audio) != len(format):
+ raise ValueError(
+ f"When passed as a list of audio, the length ({len(audio)}) must match the number of format ({len(format)})"
+ )
+ audio_buffers = []
+ for array, f in zip(audio, format):
+ # Create new BytesIO object and write audio data to it
+ buffer = io.BytesIO()
+ # Convert to mono if needed
+ if array.ndim == 2:
+ array = array.mean(axis=1)
+ # Write to buffer with default format and sampling rate
+ sf.write(buffer, array, samplerate=audio_kwargs["sampling_rate"], format=f)
+ buffer.seek(0)
+ audio_buffers.append(buffer)
+ audio = audio_buffers
+
+ # validate language input
+ n_audio = len(audio)
+ if isinstance(language, str):
+ language = [language] * n_audio
+
+ if len(language) != n_audio:
+ raise ValueError(
+ f"When passed as a list of languages, the length ({len(language)}) must match the number of audio ({n_audio})"
+ )
+
+ input_ids = []
+ texts = []
+ audio_arrays = []
+ for audio_el, language_el in zip(audio, language):
+ openai_transcription_request = {
+ "model": model_id,
+ "file": audio_el,
+ "language": language_el,
+ }
+
+ transcription_request = TranscriptionRequest.from_openai(openai_transcription_request)
+ tokenized_transcription_request = self.tokenizer.tokenizer.encode_transcription(transcription_request)
+
+ input_ids.append(tokenized_transcription_request.tokens)
+ texts.append(tokenized_transcription_request.text)
+ audio_arrays.extend([el.audio_array for el in tokenized_transcription_request.audios])
+
+ if tokenize:
+ if return_dict:
+ # text are already tokenized but we need to pad etc
+ encoding = self.tokenizer(
+ input_ids,
+ add_special_tokens=False,
+ **text_kwargs,
+ )
+ data = dict(encoding)
+
+ # extract the input features
+ max_source_positions = audio_kwargs.pop("max_source_positions")
+ data["input_features"] = self._retreive_input_features(
+ audio_arrays, max_source_positions, **audio_kwargs
+ )
+
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+ return texts
+
+
+__all__ = ["VoxtralProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..3516b478194df713d15941c5d646fbdba987bfb0
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/__init__.py
@@ -0,0 +1,32 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_wav2vec2 import *
+ from .feature_extraction_wav2vec2 import *
+ from .modeling_flax_wav2vec2 import *
+ from .modeling_tf_wav2vec2 import *
+ from .modeling_wav2vec2 import *
+ from .processing_wav2vec2 import *
+ from .tokenization_wav2vec2 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/configuration_wav2vec2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/configuration_wav2vec2.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6fffc0ffa422017450f323658d97c84f744d729
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/configuration_wav2vec2.py
@@ -0,0 +1,347 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Wav2Vec2 model configuration"""
+
+import functools
+import operator
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Wav2Vec2Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Wav2Vec2Model`]. It is used to instantiate an
+ Wav2Vec2 model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the Wav2Vec2
+ [facebook/wav2vec2-base-960h](https://huggingface.co/facebook/wav2vec2-base-960h) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32):
+ Vocabulary size of the Wav2Vec2 model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`Wav2Vec2Model`] or [`TFWav2Vec2Model`]. Vocabulary size of the
+ model. Defines the different tokens that can be represented by the *inputs_ids* passed to the forward
+ method of [`Wav2Vec2Model`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for activations inside the fully connected layer.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ final_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the final projection layer of [`Wav2Vec2ForCTC`].
+ layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) for more
+ details.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ feat_extract_norm (`str`, *optional*, defaults to `"group"`):
+ The norm to be applied to 1D convolutional layers in feature encoder. One of `"group"` for group
+ normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D
+ convolutional layers.
+ feat_proj_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for output of the feature encoder.
+ feat_extract_activation (`str, `optional`, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the 1D convolutional layers of the feature
+ extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ feat_quantizer_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for quantized feature encoder states.
+ conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 512, 512, 512)`):
+ A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the
+ feature encoder. The length of *conv_dim* defines the number of 1D convolutional layers.
+ conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 2, 2, 2, 2, 2)`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the feature encoder. The length
+ of *conv_stride* defines the number of convolutional layers and has to match the length of *conv_dim*.
+ conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 3, 3, 3, 3, 3)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the feature encoder. The
+ length of *conv_kernel* defines the number of convolutional layers and has to match the length of
+ *conv_dim*.
+ conv_bias (`bool`, *optional*, defaults to `False`):
+ Whether the 1D convolutional layers have a bias.
+ num_conv_pos_embeddings (`int`, *optional*, defaults to 128):
+ Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional
+ embeddings layer.
+ num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16):
+ Number of groups of 1D convolutional positional embeddings layer.
+ do_stable_layer_norm (`bool`, *optional*, defaults to `False`):
+ Whether to apply *stable* layer norm architecture of the Transformer encoder. `do_stable_layer_norm is
+ True` corresponds to applying layer norm before the attention layer, whereas `do_stable_layer_norm is
+ False` corresponds to applying layer norm after the attention layer.
+ apply_spec_augment (`bool`, *optional*, defaults to `True`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see
+ [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking
+ procedure generates ''mask_time_prob*len(time_axis)/mask_time_length'' independent masks over the axis. If
+ reasoning from the probability of each feature vector to be chosen as the start of the vector span to be
+ masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the
+ actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2),:
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks''
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The
+ masking procedure generates ''mask_feature_prob*len(feature_axis)/mask_time_length'' independent masks over
+ the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector
+ span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap
+ may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is
+ True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ mask_feature_min_masks (`int`, *optional*, defaults to 0),:
+ The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time
+ step, irrespectively of `mask_feature_prob`. Only relevant if
+ ''mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks''
+ num_codevectors_per_group (`int`, *optional*, defaults to 320):
+ Number of entries in each quantization codebook (group).
+ num_codevector_groups (`int`, *optional*, defaults to 2):
+ Number of codevector groups for product codevector quantization.
+ contrastive_logits_temperature (`float`, *optional*, defaults to 0.1):
+ The temperature *kappa* in the contrastive loss.
+ feat_quantizer_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the output of the feature encoder that's used by the quantizer.
+ num_negatives (`int`, *optional*, defaults to 100):
+ Number of negative samples for the contrastive loss.
+ codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the quantized feature vectors.
+ proj_codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the final projection of both the quantized and the transformer features.
+ diversity_loss_weight (`int`, *optional*, defaults to 0.1):
+ The weight of the codebook diversity loss component.
+ ctc_loss_reduction (`str`, *optional*, defaults to `"sum"`):
+ Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an
+ instance of [`Wav2Vec2ForCTC`].
+ ctc_zero_infinity (`bool`, *optional*, defaults to `False`):
+ Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly
+ occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance
+ of [`Wav2Vec2ForCTC`].
+ use_weighted_layer_sum (`bool`, *optional*, defaults to `False`):
+ Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an
+ instance of [`Wav2Vec2ForSequenceClassification`].
+ classifier_proj_size (`int`, *optional*, defaults to 256):
+ Dimensionality of the projection before token mean-pooling for classification.
+ tdnn_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 1500)`):
+ A tuple of integers defining the number of output channels of each 1D convolutional layer in the *TDNN*
+ module of the *XVector* model. The length of *tdnn_dim* defines the number of *TDNN* layers.
+ tdnn_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 3, 3, 1, 1)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the *TDNN* module of the
+ *XVector* model. The length of *tdnn_kernel* has to match the length of *tdnn_dim*.
+ tdnn_dilation (`tuple[int]` or `list[int]`, *optional*, defaults to `(1, 2, 3, 1, 1)`):
+ A tuple of integers defining the dilation factor of each 1D convolutional layer in *TDNN* module of the
+ *XVector* model. The length of *tdnn_dilation* has to match the length of *tdnn_dim*.
+ xvector_output_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of the *XVector* embedding vectors.
+ add_adapter (`bool`, *optional*, defaults to `False`):
+ Whether a convolutional network should be stacked on top of the Wav2Vec2 Encoder. Can be very useful for
+ warm-starting Wav2Vec2 for SpeechEncoderDecoder models.
+ adapter_kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ adapter_stride (`int`, *optional*, defaults to 2):
+ Stride of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ num_adapter_layers (`int`, *optional*, defaults to 3):
+ Number of convolutional layers that should be used in the adapter network. Only relevant if `add_adapter is
+ True`.
+ adapter_attn_dim (`int`, *optional*):
+ Dimension of the attention adapter weights to be used in each attention block. An example of a model using
+ attention adapters is [facebook/mms-1b-all](https://huggingface.co/facebook/mms-1b-all).
+ output_hidden_size (`int`, *optional*):
+ Dimensionality of the encoder output layer. If not defined, this defaults to *hidden-size*. Only relevant
+ if `add_adapter is True`.
+
+ Example:
+
+ ```python
+ >>> from transformers import Wav2Vec2Config, Wav2Vec2Model
+
+ >>> # Initializing a Wav2Vec2 facebook/wav2vec2-base-960h style configuration
+ >>> configuration = Wav2Vec2Config()
+
+ >>> # Initializing a model (with random weights) from the facebook/wav2vec2-base-960h style configuration
+ >>> model = Wav2Vec2Model(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "wav2vec2"
+
+ def __init__(
+ self,
+ vocab_size=32,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout=0.1,
+ activation_dropout=0.1,
+ attention_dropout=0.1,
+ feat_proj_dropout=0.0,
+ feat_quantizer_dropout=0.0,
+ final_dropout=0.1,
+ layerdrop=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ feat_extract_norm="group",
+ feat_extract_activation="gelu",
+ conv_dim=(512, 512, 512, 512, 512, 512, 512),
+ conv_stride=(5, 2, 2, 2, 2, 2, 2),
+ conv_kernel=(10, 3, 3, 3, 3, 2, 2),
+ conv_bias=False,
+ num_conv_pos_embeddings=128,
+ num_conv_pos_embedding_groups=16,
+ do_stable_layer_norm=False,
+ apply_spec_augment=True,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ mask_feature_min_masks=0,
+ num_codevectors_per_group=320,
+ num_codevector_groups=2,
+ contrastive_logits_temperature=0.1,
+ num_negatives=100,
+ codevector_dim=256,
+ proj_codevector_dim=256,
+ diversity_loss_weight=0.1,
+ ctc_loss_reduction="sum",
+ ctc_zero_infinity=False,
+ use_weighted_layer_sum=False,
+ classifier_proj_size=256,
+ tdnn_dim=(512, 512, 512, 512, 1500),
+ tdnn_kernel=(5, 3, 3, 1, 1),
+ tdnn_dilation=(1, 2, 3, 1, 1),
+ xvector_output_dim=512,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ add_adapter=False,
+ adapter_kernel_size=3,
+ adapter_stride=2,
+ num_adapter_layers=3,
+ output_hidden_size=None,
+ adapter_attn_dim=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs, pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id)
+ self.hidden_size = hidden_size
+ self.feat_extract_norm = feat_extract_norm
+ self.feat_extract_activation = feat_extract_activation
+ self.conv_dim = list(conv_dim)
+ self.conv_stride = list(conv_stride)
+ self.conv_kernel = list(conv_kernel)
+ self.conv_bias = conv_bias
+ self.num_conv_pos_embeddings = num_conv_pos_embeddings
+ self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups
+ self.num_feat_extract_layers = len(self.conv_dim)
+ self.num_hidden_layers = num_hidden_layers
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.num_attention_heads = num_attention_heads
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.feat_proj_dropout = feat_proj_dropout
+ self.final_dropout = final_dropout
+ self.layerdrop = layerdrop
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.vocab_size = vocab_size
+ self.do_stable_layer_norm = do_stable_layer_norm
+ self.use_weighted_layer_sum = use_weighted_layer_sum
+
+ if (
+ (len(self.conv_stride) != self.num_feat_extract_layers)
+ or (len(self.conv_kernel) != self.num_feat_extract_layers)
+ or (len(self.conv_dim) != self.num_feat_extract_layers)
+ ):
+ raise ValueError(
+ "Configuration for convolutional layers is incorrect. It is required that `len(config.conv_dim)` =="
+ " `len(config.conv_stride)` == `len(config.conv_kernel)`, but is `len(config.conv_dim) ="
+ f" {len(self.conv_dim)}`, `len(config.conv_stride) = {len(self.conv_stride)}`,"
+ f" `len(config.conv_kernel) = {len(self.conv_kernel)}`."
+ )
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+ self.mask_feature_min_masks = mask_feature_min_masks
+
+ # parameters for pretraining with codevector quantized representations
+ self.num_codevectors_per_group = num_codevectors_per_group
+ self.num_codevector_groups = num_codevector_groups
+ self.contrastive_logits_temperature = contrastive_logits_temperature
+ self.feat_quantizer_dropout = feat_quantizer_dropout
+ self.num_negatives = num_negatives
+ self.codevector_dim = codevector_dim
+ self.proj_codevector_dim = proj_codevector_dim
+ self.diversity_loss_weight = diversity_loss_weight
+
+ # ctc loss
+ self.ctc_loss_reduction = ctc_loss_reduction
+ self.ctc_zero_infinity = ctc_zero_infinity
+
+ # adapter
+ self.add_adapter = add_adapter
+ self.adapter_kernel_size = adapter_kernel_size
+ self.adapter_stride = adapter_stride
+ self.num_adapter_layers = num_adapter_layers
+ self.output_hidden_size = output_hidden_size or hidden_size
+ self.adapter_attn_dim = adapter_attn_dim
+
+ # SequenceClassification-specific parameter. Feel free to ignore for other classes.
+ self.classifier_proj_size = classifier_proj_size
+
+ # XVector-specific parameters. Feel free to ignore for other classes.
+ self.tdnn_dim = list(tdnn_dim)
+ self.tdnn_kernel = list(tdnn_kernel)
+ self.tdnn_dilation = list(tdnn_dilation)
+ self.xvector_output_dim = xvector_output_dim
+
+ @property
+ def inputs_to_logits_ratio(self):
+ return functools.reduce(operator.mul, self.conv_stride, 1)
+
+
+__all__ = ["Wav2Vec2Config"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/feature_extraction_wav2vec2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/feature_extraction_wav2vec2.py
new file mode 100644
index 0000000000000000000000000000000000000000..6bca69e82d09d600ed29243811a9b670f8b71011
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/feature_extraction_wav2vec2.py
@@ -0,0 +1,243 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Feature extractor class for Wav2Vec2
+"""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ...feature_extraction_sequence_utils import SequenceFeatureExtractor
+from ...feature_extraction_utils import BatchFeature
+from ...utils import PaddingStrategy, TensorType, logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Wav2Vec2FeatureExtractor(SequenceFeatureExtractor):
+ r"""
+ Constructs a Wav2Vec2 feature extractor.
+
+ This feature extractor inherits from [`~feature_extraction_sequence_utils.SequenceFeatureExtractor`] which contains
+ most of the main methods. Users should refer to this superclass for more information regarding those methods.
+
+ Args:
+ feature_size (`int`, *optional*, defaults to 1):
+ The feature dimension of the extracted features.
+ sampling_rate (`int`, *optional*, defaults to 16000):
+ The sampling rate at which the audio files should be digitalized expressed in hertz (Hz).
+ padding_value (`float`, *optional*, defaults to 0.0):
+ The value that is used to fill the padding values.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether or not to zero-mean unit-variance normalize the input. Normalizing can help to significantly
+ improve the performance for some models, *e.g.*,
+ [wav2vec2-lv60](https://huggingface.co/models?search=lv60).
+ return_attention_mask (`bool`, *optional*, defaults to `False`):
+ Whether or not [`~Wav2Vec2FeatureExtractor.__call__`] should return `attention_mask`.
+
+
+
+ Wav2Vec2 models that have set `config.feat_extract_norm == "group"`, such as
+ [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base-960h), have **not** been trained using
+ `attention_mask`. For such models, `input_values` should simply be padded with 0 and no `attention_mask`
+ should be passed.
+
+ For Wav2Vec2 models that have set `config.feat_extract_norm == "layer"`, such as
+ [wav2vec2-lv60](https://huggingface.co/facebook/wav2vec2-large-960h-lv60-self), `attention_mask` should be
+ passed for batched inference.
+
+ """
+
+ model_input_names = ["input_values", "attention_mask"]
+
+ def __init__(
+ self,
+ feature_size=1,
+ sampling_rate=16000,
+ padding_value=0.0,
+ return_attention_mask=False,
+ do_normalize=True,
+ **kwargs,
+ ):
+ super().__init__(feature_size=feature_size, sampling_rate=sampling_rate, padding_value=padding_value, **kwargs)
+ self.return_attention_mask = return_attention_mask
+ self.do_normalize = do_normalize
+
+ @staticmethod
+ def zero_mean_unit_var_norm(
+ input_values: list[np.ndarray], attention_mask: list[np.ndarray], padding_value: float = 0.0
+ ) -> list[np.ndarray]:
+ """
+ Every array in the list is normalized to have zero mean and unit variance
+ """
+ if attention_mask is not None:
+ attention_mask = np.array(attention_mask, np.int32)
+ normed_input_values = []
+
+ for vector, length in zip(input_values, attention_mask.sum(-1)):
+ normed_slice = (vector - vector[:length].mean()) / np.sqrt(vector[:length].var() + 1e-7)
+ if length < normed_slice.shape[0]:
+ normed_slice[length:] = padding_value
+
+ normed_input_values.append(normed_slice)
+ else:
+ normed_input_values = [(x - x.mean()) / np.sqrt(x.var() + 1e-7) for x in input_values]
+
+ return normed_input_values
+
+ def __call__(
+ self,
+ raw_speech: Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]],
+ padding: Union[bool, str, PaddingStrategy] = False,
+ max_length: Optional[int] = None,
+ truncation: bool = False,
+ pad_to_multiple_of: Optional[int] = None,
+ return_attention_mask: Optional[bool] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ sampling_rate: Optional[int] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Main method to featurize and prepare for the model one or several sequence(s).
+
+ Args:
+ raw_speech (`np.ndarray`, `list[float]`, `list[np.ndarray]`, `list[list[float]]`):
+ The sequence or batch of sequences to be padded. Each sequence can be a numpy array, a list of float
+ values, a list of numpy arrays or a list of list of float values. Must be mono channel audio, not
+ stereo, i.e. single float per timestep.
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Select a strategy to pad the returned sequences (according to the model's padding side and padding
+ index) among:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Maximum length of the returned list and optionally padding length (see above).
+ truncation (`bool`):
+ Activates truncation to cut input sequences longer than *max_length* to *max_length*.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value.
+
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta), or on TPUs which benefit from having sequence lengths be a multiple of 128.
+ return_attention_mask (`bool`, *optional*):
+ Whether to return the attention mask. If left to the default, will return the attention mask according
+ to the specific feature_extractor's default.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+
+
+ Wav2Vec2 models that have set `config.feat_extract_norm == "group"`, such as
+ [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base-960h), have **not** been trained using
+ `attention_mask`. For such models, `input_values` should simply be padded with 0 and no
+ `attention_mask` should be passed.
+
+ For Wav2Vec2 models that have set `config.feat_extract_norm == "layer"`, such as
+ [wav2vec2-lv60](https://huggingface.co/facebook/wav2vec2-large-960h-lv60-self), `attention_mask` should
+ be passed for batched inference.
+
+
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ sampling_rate (`int`, *optional*):
+ The sampling rate at which the `raw_speech` input was sampled. It is strongly recommended to pass
+ `sampling_rate` at the forward call to prevent silent errors.
+ padding_value (`float`, *optional*, defaults to 0.0):
+ """
+
+ if sampling_rate is not None:
+ if sampling_rate != self.sampling_rate:
+ raise ValueError(
+ f"The model corresponding to this feature extractor: {self} was trained using a sampling rate of"
+ f" {self.sampling_rate}. Please make sure that the provided `raw_speech` input was sampled with"
+ f" {self.sampling_rate} and not {sampling_rate}."
+ )
+ else:
+ logger.warning(
+ f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. "
+ "Failing to do so can result in silent errors that might be hard to debug."
+ )
+
+ is_batched_numpy = isinstance(raw_speech, np.ndarray) and len(raw_speech.shape) > 1
+ if is_batched_numpy and len(raw_speech.shape) > 2:
+ raise ValueError(f"Only mono-channel audio is supported for input to {self}")
+ is_batched = is_batched_numpy or (
+ isinstance(raw_speech, (list, tuple)) and (isinstance(raw_speech[0], (np.ndarray, tuple, list)))
+ )
+
+ # always return batch
+ if not is_batched:
+ raw_speech = [raw_speech]
+
+ # convert into correct format for padding
+ encoded_inputs = BatchFeature({"input_values": raw_speech})
+
+ padded_inputs = self.pad(
+ encoded_inputs,
+ padding=padding,
+ max_length=max_length,
+ truncation=truncation,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_attention_mask=return_attention_mask,
+ )
+
+ # convert input values to correct format
+ input_values = padded_inputs["input_values"]
+ if not isinstance(input_values[0], np.ndarray):
+ padded_inputs["input_values"] = [np.asarray(array, dtype=np.float32) for array in input_values]
+ elif (
+ not isinstance(input_values, np.ndarray)
+ and isinstance(input_values[0], np.ndarray)
+ and input_values[0].dtype is np.dtype(np.float64)
+ ):
+ padded_inputs["input_values"] = [array.astype(np.float32) for array in input_values]
+ elif isinstance(input_values, np.ndarray) and input_values.dtype is np.dtype(np.float64):
+ padded_inputs["input_values"] = input_values.astype(np.float32)
+
+ # convert attention_mask to correct format
+ attention_mask = padded_inputs.get("attention_mask")
+ if attention_mask is not None:
+ padded_inputs["attention_mask"] = [np.asarray(array, dtype=np.int32) for array in attention_mask]
+
+ # zero-mean and unit-variance normalization
+ if self.do_normalize:
+ attention_mask = (
+ attention_mask
+ if self._get_padding_strategies(padding, max_length=max_length) is not PaddingStrategy.DO_NOT_PAD
+ else None
+ )
+ padded_inputs["input_values"] = self.zero_mean_unit_var_norm(
+ padded_inputs["input_values"], attention_mask=attention_mask, padding_value=self.padding_value
+ )
+
+ if return_tensors is not None:
+ padded_inputs = padded_inputs.convert_to_tensors(return_tensors)
+
+ return padded_inputs
+
+
+__all__ = ["Wav2Vec2FeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_flax_wav2vec2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_flax_wav2vec2.py
new file mode 100644
index 0000000000000000000000000000000000000000..99db1d37fa55ddc9eaa795e6cc019a00717309f4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_flax_wav2vec2.py
@@ -0,0 +1,1423 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Flax Wav2Vec2 model."""
+
+from functools import partial
+from typing import Optional, Union
+
+import flax
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+import numpy as np
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.linen.attention import dot_product_attention_weights
+from flax.traverse_util import flatten_dict, unflatten_dict
+from jax import lax
+
+from ...modeling_flax_outputs import FlaxBaseModelOutput, FlaxCausalLMOutput
+from ...modeling_flax_utils import (
+ ACT2FN,
+ FlaxPreTrainedModel,
+ append_replace_return_docstrings,
+ overwrite_call_docstring,
+)
+from ...utils import ModelOutput, add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_wav2vec2 import Wav2Vec2Config
+
+
+logger = logging.get_logger(__name__)
+
+
+@flax.struct.dataclass
+class FlaxWav2Vec2BaseModelOutput(ModelOutput):
+ """
+ Output type of [`FlaxWav2Vec2BaseModelOutput`], with potential hidden states and attentions.
+
+ Args:
+ last_hidden_state (`jnp.ndarray` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ extract_features (`jnp.ndarray` of shape `(batch_size, sequence_length, last_conv_dim)`):
+ Sequence of extracted feature vectors of the last convolutional layer of the model with `last_conv_dim`
+ being the dimension of the last convolutional layer.
+ hidden_states (`tuple(jnp.ndarray)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `jnp.ndarray` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(jnp.ndarray)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `jnp.ndarray` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ last_hidden_state: jnp.ndarray = None
+ extract_features: jnp.ndarray = None
+ hidden_states: Optional[tuple[jnp.ndarray]] = None
+ attentions: Optional[tuple[jnp.ndarray]] = None
+
+
+@flax.struct.dataclass
+class FlaxWav2Vec2ForPreTrainingOutput(ModelOutput):
+ """
+ Output type of [`FlaxWav2Vec2ForPreTrainingOutput`], with potential hidden states and attentions.
+
+ Args:
+ loss (*optional*, returned when model is in train mode, `jnp.ndarray` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ projected_states (`jnp.ndarray` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`jnp.ndarray` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ hidden_states (`tuple(jnp.ndarray)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `jnp.ndarray` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(jnp.ndarray)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `jnp.ndarray` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ projected_states: jnp.ndarray = None
+ projected_quantized_states: jnp.ndarray = None
+ codevector_perplexity: jnp.ndarray = None
+ hidden_states: Optional[tuple[jnp.ndarray]] = None
+ attentions: Optional[tuple[jnp.ndarray]] = None
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[np.ndarray] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: the shape for which to compute masks.
+ should be of size 2 where first element is batch size and 2nd is timesteps
+ mask_prob:
+ probability for each token to be chosen as start of the span to be masked. this will be multiplied by
+ number of timesteps divided by length of mask span to mask approximately this percentage of all elements.
+ however due to overlaps, the actual number will be smaller (unless no_overlap is True)
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length} and"
+ f" `sequence_length`: {sequence_length}`"
+ )
+
+ # compute number of masked spans in batch
+ num_masked_spans = int(mask_prob * sequence_length / mask_length + np.random.rand(1).item())
+ num_masked_spans = max(num_masked_spans, min_masks)
+
+ # make sure num masked indices <= sequence_length
+ if num_masked_spans * mask_length > sequence_length:
+ num_masked_spans = sequence_length // mask_length
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+
+ # get random indices to mask
+ spec_aug_mask_idxs = np.array(
+ [
+ np.random.choice(np.arange(sequence_length - (mask_length - 1)), num_masked_spans, replace=False)
+ for _ in range(batch_size)
+ ]
+ )
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(spec_aug_mask_idxs[:, :, None], (batch_size, num_masked_spans, mask_length))
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, num_masked_spans * mask_length)
+
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, num_masked_spans, mask_length)).reshape(
+ batch_size, num_masked_spans * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ if attention_mask is not None:
+ # make sure padded input ids cannot be masked
+ spec_aug_mask = np.where(attention_mask, spec_aug_mask, False)
+
+ return spec_aug_mask
+
+
+def _sample_negative_indices(features_shape: tuple, num_negatives: int, attention_mask: Optional[np.ndarray] = None):
+ """
+ Sample `num_negatives` vectors from feature vectors.
+ """
+ batch_size, sequence_length, hidden_size = features_shape
+ if sequence_length <= 1:
+ raise ValueError(
+ "`features should have `sequence_length` > 1, but are of shape "
+ f"(batch_size, sequence_length, hidden_size) = ({batch_size, sequence_length, hidden_size})."
+ )
+
+ # get `num_negatives` random vector indices from the same utterance
+ sampled_negative_indices = []
+ for batch_idx in range(batch_size):
+ high = attention_mask[batch_idx].sum() - 1 if attention_mask is not None else sequence_length - 1
+ sampled_indices_slice = np.random.randint(0, high, size=(num_negatives * sequence_length,))
+ sampled_negative_indices.append(sampled_indices_slice)
+
+ sampled_negative_indices = np.asarray(sampled_negative_indices, dtype=np.int32)
+
+ # generate indices of the positive vectors themselves, repeat them `num_negatives` times
+ feature_indices = np.broadcast_to(np.arange(sequence_length)[:, None], (sequence_length, num_negatives)).flatten()
+
+ # avoid sampling the same positive vector, but keep the distribution uniform
+ sampled_negative_indices[sampled_negative_indices >= feature_indices] += 1
+
+ # correct for batch size
+ for batch_idx in range(1, batch_size):
+ sampled_negative_indices[batch_idx] += batch_idx * sequence_length
+
+ return sampled_negative_indices
+
+
+WAV2VEC2_START_DOCSTRING = r"""
+ Wav2Vec2 was proposed in [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech
+ Representations](https://huggingface.co/papers/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael
+ Auli.
+
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a Flax Linen
+ [flax.nn.Module](https://flax.readthedocs.io/en/latest/_autosummary/flax.nn.module.html) subclass. Use it as a
+ regular Flax Module and refer to the Flax documentation for all matter related to general usage and behavior.
+
+ Finally, this model supports inherent JAX features such as:
+
+ - [Just-In-Time (JIT) compilation](https://jax.readthedocs.io/en/latest/jax.html#just-in-time-compilation-jit)
+ - [Automatic Differentiation](https://jax.readthedocs.io/en/latest/jax.html#automatic-differentiation)
+ - [Vectorization](https://jax.readthedocs.io/en/latest/jax.html#vectorization-vmap)
+ - [Parallelization](https://jax.readthedocs.io/en/latest/jax.html#parallelization-pmap)
+
+ Parameters:
+ config ([`Wav2Vec2Config`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs).
+
+ This can be used to enable mixed-precision training or half-precision inference on GPUs or TPUs. If
+ specified all the computation will be performed with the given `dtype`.
+
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.**
+
+ If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`] and
+ [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+
+WAV2VEC2_INPUTS_DOCSTRING = r"""
+ Args:
+ input_values (`jnp.ndarray` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `jnp.ndarray`. See [`Wav2Vec2Processor.__call__`] for details.
+ attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing convolution and attention on padding token indices. Mask values selected in `[0,
+ 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask) .. warning:: `attention_mask` should only be passed
+ if the corresponding processor has `config.return_attention_mask == True`. For all models whose processor
+ has `config.return_attention_mask == False`, such as
+ [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base-960h), `attention_mask` should **not** be
+ passed to avoid degraded performance when doing batched inference. For such models `input_values` should
+ simply be padded with 0 and passed without `attention_mask`. Be aware that these models also yield slightly
+ different results depending on whether `input_values` is padded or not.
+ mask_time_indices (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+class FlaxWav2Vec2LayerNormConvLayer(nn.Module):
+ config: Wav2Vec2Config
+ layer_id: int = 0
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.in_conv_dim = self.config.conv_dim[self.layer_id] if self.layer_id > 0 else 1
+ self.out_conv_dim = self.config.conv_dim[self.layer_id]
+
+ self.conv = nn.Conv(
+ features=self.config.conv_dim[self.layer_id],
+ kernel_size=(self.config.conv_kernel[self.layer_id],),
+ strides=(self.config.conv_stride[self.layer_id],),
+ use_bias=self.config.conv_bias,
+ kernel_init=jax.nn.initializers.he_normal(),
+ padding="VALID",
+ dtype=self.dtype,
+ )
+ self.layer_norm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.activation = ACT2FN[self.config.feat_extract_activation]
+
+ def __call__(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class FlaxConvWithWeightNorm(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.conv = nn.Conv(
+ features=self.config.hidden_size,
+ kernel_size=(self.config.num_conv_pos_embeddings,),
+ kernel_init=jax.nn.initializers.he_normal(),
+ padding="VALID",
+ feature_group_count=self.config.num_conv_pos_embedding_groups,
+ dtype=self.dtype,
+ )
+ weight_shape = (
+ self.conv.features,
+ self.conv.features // self.conv.feature_group_count,
+ self.conv.kernel_size[0],
+ )
+ self.weight_v = self.param("weight_v", jax.nn.initializers.he_normal(), weight_shape)
+ self.weight_g = self.param("weight_g", lambda _: jnp.linalg.norm(self.weight_v, axis=(0, 1))[None, None, :])
+ self.bias = self.param("bias", jax.nn.initializers.zeros, (self.conv.features,))
+ self.prev_padding = self.conv.kernel_size[0] // 2
+
+ def _get_normed_weights(self):
+ weight_v_norm = jnp.linalg.norm(self.weight_v, axis=(0, 1))[None, None, :]
+ normed_weight_v = jnp.divide(self.weight_v, weight_v_norm)
+ normed_kernel = jnp.multiply(normed_weight_v, self.weight_g)
+ return normed_kernel
+
+ def __call__(self, hidden_states):
+ kernel = self._get_normed_weights()
+ hidden_states = jnp.pad(hidden_states, ((0, 0), (self.prev_padding, self.prev_padding), (0, 0)))
+ hidden_states = self.conv.apply({"params": {"kernel": kernel.T, "bias": self.bias}}, hidden_states)
+ return hidden_states
+
+
+class FlaxWav2Vec2PositionalConvEmbedding(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.conv = FlaxConvWithWeightNorm(self.config, dtype=self.dtype)
+ self.activation = ACT2FN[self.config.feat_extract_activation]
+ self.num_pad_remove = 1 if self.config.num_conv_pos_embeddings % 2 == 0 else 0
+
+ def __call__(self, hidden_states):
+ hidden_states = hidden_states.transpose((0, 1, 2))
+
+ hidden_states = self.conv(hidden_states)
+
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, : -self.num_pad_remove, :]
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = hidden_states.transpose((0, 1, 2))
+ return hidden_states
+
+
+class FlaxConvLayersCollection(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ if self.config.feat_extract_norm == "layer":
+ self.layers = [
+ FlaxWav2Vec2LayerNormConvLayer(self.config, layer_id=i, name=str(i), dtype=self.dtype)
+ for i in range(self.config.num_feat_extract_layers)
+ ]
+ elif self.config.feat_extract_norm == "group":
+ raise NotImplementedError("At the moment only ``config.feat_extact_norm == 'layer'`` is supported")
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {self.config.feat_extract_norm}, but has to be one of ['group',"
+ " 'layer']"
+ )
+
+ def __call__(self, hidden_states):
+ for i, conv_layer in enumerate(self.layers):
+ hidden_states = conv_layer(hidden_states)
+ return hidden_states
+
+
+class FlaxWav2Vec2FeatureEncoder(nn.Module):
+ """Construct the features from raw audio waveform"""
+
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.conv_layers = FlaxConvLayersCollection(self.config, dtype=self.dtype)
+
+ def __call__(self, input_values, freeze_feature_encoder=False):
+ hidden_states = input_values[:, :, None]
+ hidden_states = self.conv_layers(hidden_states)
+ if freeze_feature_encoder:
+ hidden_states = jax.lax.stop_gradient(hidden_states)
+ return hidden_states
+
+
+class FlaxWav2Vec2FeatureProjection(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.layer_norm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.projection = nn.Dense(
+ self.config.hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.dropout = nn.Dropout(rate=self.config.feat_proj_dropout)
+
+ def __call__(self, hidden_states, deterministic=True):
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ return hidden_states, norm_hidden_states
+
+
+class FlaxWav2Vec2Attention(nn.Module):
+ config: Wav2Vec2Config
+ embed_dim: int
+ num_heads: int
+ dropout: float = 0.0
+ bias: bool = True
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self) -> None:
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+
+ dense = partial(
+ nn.Dense,
+ self.embed_dim,
+ use_bias=self.bias,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+
+ self.q_proj, self.k_proj, self.v_proj = dense(), dense(), dense()
+ self.out_proj = dense()
+
+ self.dropout_layer = nn.Dropout(rate=self.dropout)
+
+ def _split_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.num_heads, self.head_dim))
+
+ def _merge_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.embed_dim,))
+
+ def __call__(
+ self,
+ hidden_states: jnp.ndarray,
+ key_value_states: Optional[jnp.ndarray] = None,
+ attention_mask: Optional[jnp.ndarray] = None,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ """Input shape: Batch x Time x Channel"""
+
+ # get query proj
+ query_states = self.q_proj(hidden_states)
+
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ query_states = self._split_heads(query_states)
+ key_states = self._split_heads(key_states)
+ value_states = self._split_heads(value_states)
+
+ if attention_mask is not None:
+ attention_mask = jnp.expand_dims(attention_mask, axis=(-3, -2))
+
+ # Convert the boolean attention mask to an attention bias.
+ if attention_mask is not None:
+ # attention mask in the form of attention bias
+ attention_bias = lax.select(
+ attention_mask > 0,
+ jnp.full(attention_mask.shape, 0.0).astype(self.dtype),
+ jnp.full(attention_mask.shape, jnp.finfo(self.dtype).min).astype(self.dtype),
+ )
+ else:
+ attention_bias = None
+
+ dropout_rng = None
+ if not deterministic and self.dropout > 0.0:
+ dropout_rng = self.make_rng("dropout")
+
+ attn_weights = dot_product_attention_weights(
+ query_states,
+ key_states,
+ bias=attention_bias,
+ dropout_rng=dropout_rng,
+ dropout_rate=self.dropout,
+ broadcast_dropout=True,
+ deterministic=deterministic,
+ dtype=self.dtype,
+ precision=None,
+ )
+
+ attn_output = jnp.einsum("...hqk,...khd->...qhd", attn_weights, value_states)
+ attn_output = self._merge_heads(attn_output)
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+class FlaxWav2Vec2FeedForward(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.intermediate_dropout = nn.Dropout(rate=self.config.activation_dropout)
+
+ self.intermediate_dense = nn.Dense(
+ self.config.intermediate_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ if isinstance(self.config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[self.config.hidden_act]
+ else:
+ self.intermediate_act_fn = self.config.hidden_act
+
+ self.output_dense = nn.Dense(
+ self.config.hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.output_dropout = nn.Dropout(rate=self.config.hidden_dropout)
+
+ def __call__(self, hidden_states, deterministic=True):
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states, deterministic=deterministic)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states, deterministic=deterministic)
+ return hidden_states
+
+
+class FlaxWav2Vec2EncoderLayerStableLayerNorm(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.attention = FlaxWav2Vec2Attention(
+ config=self.config,
+ embed_dim=self.config.hidden_size,
+ num_heads=self.config.num_attention_heads,
+ dropout=self.config.attention_dropout,
+ dtype=self.dtype,
+ )
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.feed_forward = FlaxWav2Vec2FeedForward(self.config, dtype=self.dtype)
+ self.final_layer_norm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+
+ def __call__(self, hidden_states, attention_mask=None, deterministic=True, output_attentions=False):
+ attn_residual = hidden_states
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states, attn_weights = self.attention(
+ hidden_states, attention_mask=attention_mask, deterministic=deterministic
+ )
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = attn_residual + hidden_states
+ hidden_states = hidden_states + self.feed_forward(
+ self.final_layer_norm(hidden_states), deterministic=deterministic
+ )
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class FlaxWav2Vec2EncoderLayerStableLayerNormCollection(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.layers = [
+ FlaxWav2Vec2EncoderLayerStableLayerNorm(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.num_hidden_layers)
+ ]
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask=None,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ all_attentions = () if output_attentions else None
+ all_hidden_states = () if output_hidden_states else None
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ layer_outputs = layer(
+ hidden_states, attention_mask, deterministic=deterministic, output_attentions=output_attentions
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions += (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ outputs = (hidden_states, all_hidden_states, all_attentions)
+
+ if not return_dict:
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_attentions
+ )
+
+
+class FlaxWav2Vec2StableLayerNormEncoder(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.pos_conv_embed = FlaxWav2Vec2PositionalConvEmbedding(self.config, dtype=self.dtype)
+ self.layer_norm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout)
+ self.layers = FlaxWav2Vec2EncoderLayerStableLayerNormCollection(self.config, dtype=self.dtype)
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask=None,
+ deterministic=True,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ if attention_mask is not None:
+ # make sure padded tokens are not attended to
+ hidden_states = jnp.where(
+ jnp.broadcast_to(attention_mask[:, :, None], hidden_states.shape), hidden_states, 0
+ )
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+
+ outputs = self.layers(
+ hidden_states,
+ attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_state = self.layer_norm(outputs[0])
+
+ # update the last element in `hidden_states` after applying `layernorm` above
+ hidden_states = None
+ if output_hidden_states:
+ hidden_states = outputs[1]
+ hidden_states = hidden_states[:-1] + (last_hidden_state,)
+
+ if not return_dict:
+ outputs = (last_hidden_state, hidden_states) + (outputs[2:] if output_hidden_states else outputs[1:])
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutput(
+ last_hidden_state=last_hidden_state, hidden_states=hidden_states, attentions=outputs.attentions
+ )
+
+
+class FlaxWav2Vec2GumbelVectorQuantizer(nn.Module):
+ """
+ Vector quantization using gumbel softmax. See [CATEGORICAL REPARAMETERIZATION WITH
+ GUMBEL-SOFTMAX](https://huggingface.co/papers/1611.01144) for more information.
+ """
+
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.num_groups = self.config.num_codevector_groups
+ self.num_vars = self.config.num_codevectors_per_group
+
+ if self.config.codevector_dim % self.num_groups != 0:
+ raise ValueError(
+ f"`config.codevector_dim {self.config.codevector_dim} must be divisible by"
+ f" `config.num_codevector_groups` {self.num_groups} for concatenation"
+ )
+
+ # storage for codebook variables (codewords)
+ self.codevectors = self.param(
+ "codevectors",
+ jax.nn.initializers.uniform(),
+ (1, self.num_groups * self.num_vars, self.config.codevector_dim // self.num_groups),
+ )
+ self.weight_proj = nn.Dense(
+ self.num_groups * self.num_vars,
+ kernel_init=jax.nn.initializers.normal(1.0),
+ dtype=self.dtype,
+ )
+
+ @staticmethod
+ def _compute_perplexity(probs, mask=None):
+ if mask is not None:
+ mask_extended = jnp.broadcast_to(mask.flatten()[:, None, None], probs.shape)
+ probs = jnp.where(mask_extended, probs, jnp.zeros_like(probs))
+ marginal_probs = probs.sum(axis=0) / mask.sum()
+ else:
+ marginal_probs = probs.mean(axis=0)
+
+ perplexity = jnp.exp(-jnp.sum(marginal_probs * jnp.log(marginal_probs + 1e-7), axis=-1)).sum()
+ return perplexity
+
+ def __call__(self, hidden_states, mask_time_indices=None, deterministic=True, temperature=1):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.reshape(batch_size * sequence_length * self.num_groups, -1)
+
+ if not deterministic:
+ # sample code vector probs via gumbel in differentiateable way
+ gumbel_rng = self.make_rng("gumbel")
+ gumbels = jax.random.gumbel(gumbel_rng, hidden_states.shape)
+ codevector_probs = nn.softmax((hidden_states + gumbels) / temperature)
+
+ # compute perplexity
+ codevector_soft_dist = nn.softmax(
+ hidden_states.reshape(batch_size * sequence_length, self.num_groups, -1), axis=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist, mask_time_indices)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(axis=-1)
+ codevector_probs = jax.nn.one_hot(codevector_idx, hidden_states.shape[-1]) * 1.0
+ codevector_probs = codevector_probs.reshape(batch_size * sequence_length, self.num_groups, -1)
+ perplexity = self._compute_perplexity(codevector_probs, mask_time_indices)
+
+ codevector_probs = codevector_probs.reshape(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = jnp.expand_dims(codevector_probs, axis=-1) * self.codevectors
+ codevectors = codevectors_per_group.reshape(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).reshape(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+class FlaxWav2Vec2Adapter(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ # hidden_states require down-projection if feature dims don't match
+ if self.config.output_hidden_size != self.config.hidden_size:
+ self.proj = nn.Dense(
+ self.config.output_hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.proj_layer_norm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ else:
+ self.proj = self.proj_layer_norm = None
+
+ self.layers = FlaxWav2Vec2AdapterLayersCollection(self.config, dtype=self.dtype)
+
+ def __call__(self, hidden_states, deterministic=True):
+ # down-project hidden_states if required
+ if self.proj is not None and self.proj_layer_norm is not None:
+ hidden_states = self.proj(hidden_states)
+ hidden_states = self.proj_layer_norm(hidden_states)
+
+ hidden_states = self.layers(hidden_states)
+
+ return hidden_states
+
+
+class FlaxWav2Vec2AdapterLayer(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.conv = nn.Conv(
+ features=2 * self.config.output_hidden_size,
+ kernel_size=(self.config.adapter_kernel_size,),
+ strides=(self.config.adapter_stride,),
+ padding=((1, 1),),
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+
+ def __call__(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = nn.glu(hidden_states, axis=2)
+
+ return hidden_states
+
+
+class FlaxWav2Vec2AdapterLayersCollection(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.layers = [
+ FlaxWav2Vec2AdapterLayer(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.num_adapter_layers)
+ ]
+
+ def __call__(self, hidden_states):
+ for conv_layer in self.layers:
+ hidden_states = conv_layer(hidden_states)
+
+ return hidden_states
+
+
+class FlaxWav2Vec2PreTrainedModel(FlaxPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = Wav2Vec2Config
+ base_model_prefix: str = "wav2vec2"
+ main_input_name = "input_values"
+ module_class: nn.Module = None
+
+ def __init__(
+ self,
+ config: Wav2Vec2Config,
+ input_shape: tuple = (1, 1024),
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ **kwargs,
+ ):
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensors
+ input_values = jnp.zeros(input_shape, dtype="i4")
+ attention_mask = jnp.ones_like(input_values)
+ params_rng, dropout_rng = jax.random.split(rng, 2)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(rngs, input_values, attention_mask, return_dict=False)["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ @add_start_docstrings_to_model_forward(WAV2VEC2_INPUTS_DOCSTRING)
+ def __call__(
+ self,
+ input_values,
+ attention_mask=None,
+ mask_time_indices=None,
+ params: Optional[dict] = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ train: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ freeze_feature_encoder: bool = False,
+ return_dict: Optional[bool] = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ batch_size, sequence_length = input_values.shape
+
+ if attention_mask is None:
+ attention_mask = jnp.ones((batch_size, sequence_length))
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ inputs = {"params": params or self.params}
+
+ return self.module.apply(
+ inputs,
+ jnp.array(input_values, dtype="f4"),
+ jnp.array(attention_mask, dtype="i4"),
+ mask_time_indices,
+ not train,
+ output_attentions,
+ output_hidden_states,
+ freeze_feature_encoder,
+ return_dict,
+ rngs=rngs,
+ )
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[jnp.ndarray, int], add_adapter: Optional[bool] = None
+ ):
+ return self.module._get_feat_extract_output_lengths(input_lengths, add_adapter=add_adapter)
+
+
+class FlaxWav2Vec2Module(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.feature_extractor = FlaxWav2Vec2FeatureEncoder(self.config, dtype=self.dtype)
+ self.feature_projection = FlaxWav2Vec2FeatureProjection(self.config, dtype=self.dtype)
+ self.masked_spec_embed = self.param(
+ "masked_spec_embed", jax.nn.initializers.uniform(), (self.config.hidden_size,)
+ )
+
+ if self.config.do_stable_layer_norm:
+ self.encoder = FlaxWav2Vec2StableLayerNormEncoder(self.config, dtype=self.dtype)
+ else:
+ raise NotImplementedError("``config.do_stable_layer_norm is False`` is currently not supported.")
+
+ self.adapter = FlaxWav2Vec2Adapter(self.config, dtype=self.dtype) if self.config.add_adapter else None
+
+ def __call__(
+ self,
+ input_values,
+ attention_mask=None,
+ mask_time_indices=None,
+ deterministic=True,
+ output_attentions=None,
+ output_hidden_states=None,
+ freeze_feature_encoder=False,
+ return_dict=None,
+ ):
+ extract_features = self.feature_extractor(input_values, freeze_feature_encoder=freeze_feature_encoder)
+
+ # make sure that no loss is computed on padded inputs
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features, deterministic=deterministic)
+ if mask_time_indices is not None: # apply SpecAugment along time axis with given indices
+ hidden_states = jnp.where(
+ jnp.broadcast_to(mask_time_indices[:, :, None], hidden_states.shape),
+ jnp.broadcast_to(self.masked_spec_embed[None, None, :], hidden_states.shape),
+ hidden_states,
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states)
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return FlaxWav2Vec2BaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[jnp.ndarray, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: jnp.ndarray, add_adapter=None
+ ):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(axis=-1)[:, -1]
+
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = jnp.zeros((batch_size, feature_vector_length), dtype=attention_mask.dtype)
+ # these two operations makes sure that all values
+ # before the output lengths indices are attended to
+ attention_mask = attention_mask.at[jnp.arange(attention_mask.shape[0]), output_lengths - 1].set(1)
+ attention_mask = jnp.flip(jnp.flip(attention_mask, -1).cumsum(-1), -1).astype("bool")
+ return attention_mask
+
+
+@add_start_docstrings(
+ "The bare Wav2Vec2 Model transformer outputting raw hidden-states without any specific head on top.",
+ WAV2VEC2_START_DOCSTRING,
+)
+class FlaxWav2Vec2Model(FlaxWav2Vec2PreTrainedModel):
+ module_class = FlaxWav2Vec2Module
+
+
+FLAX_WAV2VEC2_MODEL_DOCSTRING = """
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoProcessor, FlaxWav2Vec2Model
+ >>> from datasets import load_dataset
+
+ >>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-large-lv60")
+ >>> model = FlaxWav2Vec2Model.from_pretrained("facebook/wav2vec2-large-lv60")
+
+
+ >>> def map_to_array(example):
+ ... example["speech"] = example["audio"]["array"]
+ ... return example
+
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> ds = ds.map(map_to_array)
+
+ >>> input_values = processor(
+ ... ds["speech"][0], sampling_rate=16_000, return_tensors="np"
+ ... ).input_values # Batch size 1
+ >>> hidden_states = model(input_values).last_hidden_state
+ ```
+"""
+
+overwrite_call_docstring(
+ FlaxWav2Vec2Model,
+ WAV2VEC2_INPUTS_DOCSTRING + FLAX_WAV2VEC2_MODEL_DOCSTRING,
+)
+append_replace_return_docstrings(
+ FlaxWav2Vec2Model, output_type=FlaxWav2Vec2BaseModelOutput, config_class=Wav2Vec2Config
+)
+
+
+class FlaxWav2Vec2ForCTCModule(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.wav2vec2 = FlaxWav2Vec2Module(self.config, dtype=self.dtype)
+ self.dropout = nn.Dropout(rate=self.config.final_dropout)
+ self.lm_head = nn.Dense(
+ self.config.vocab_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+
+ def __call__(
+ self,
+ input_values,
+ attention_mask=None,
+ mask_time_indices=None,
+ deterministic=True,
+ output_attentions=None,
+ output_hidden_states=None,
+ freeze_feature_encoder=False,
+ return_dict=None,
+ ):
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ mask_time_indices=mask_time_indices,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ freeze_feature_encoder=freeze_feature_encoder,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+
+ logits = self.lm_head(hidden_states)
+
+ if not return_dict:
+ return (logits,) + outputs[2:]
+
+ return FlaxCausalLMOutput(logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions)
+
+ def _get_feat_extract_output_lengths(
+ self,
+ input_lengths: Union[jnp.ndarray, int],
+ add_adapter: Optional[bool] = None,
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+
+ return input_lengths
+
+
+@add_start_docstrings(
+ "Wav2Vec2 Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).",
+ WAV2VEC2_START_DOCSTRING,
+)
+class FlaxWav2Vec2ForCTC(FlaxWav2Vec2PreTrainedModel):
+ module_class = FlaxWav2Vec2ForCTCModule
+
+
+FLAX_WAV2VEC2_FOR_CTC_DOCSTRING = """
+ Returns:
+
+ Example:
+
+ ```python
+ >>> import jax.numpy as jnp
+ >>> from transformers import AutoProcessor, FlaxWav2Vec2ForCTC
+ >>> from datasets import load_dataset
+
+ >>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-large-960h-lv60")
+ >>> model = FlaxWav2Vec2ForCTC.from_pretrained("facebook/wav2vec2-large-960h-lv60")
+
+
+ >>> def map_to_array(example):
+ ... example["speech"] = example["audio"]["array"]
+ ... return example
+
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> ds = ds.map(map_to_array)
+
+ >>> input_values = processor(
+ ... ds["speech"][0], sampling_rate=16_000, return_tensors="np"
+ ... ).input_values # Batch size 1
+ >>> logits = model(input_values).logits
+ >>> predicted_ids = jnp.argmax(logits, axis=-1)
+
+ >>> transcription = processor.decode(predicted_ids[0])
+ >>> # should give: "A MAN SAID TO THE UNIVERSE SIR I EXIST"
+ ```
+"""
+
+overwrite_call_docstring(
+ FlaxWav2Vec2ForCTC,
+ WAV2VEC2_INPUTS_DOCSTRING + FLAX_WAV2VEC2_FOR_CTC_DOCSTRING,
+)
+append_replace_return_docstrings(FlaxWav2Vec2ForCTC, output_type=FlaxCausalLMOutput, config_class=Wav2Vec2Config)
+
+
+class FlaxWav2Vec2ForPreTrainingModule(nn.Module):
+ config: Wav2Vec2Config
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.wav2vec2 = FlaxWav2Vec2Module(self.config, dtype=self.dtype)
+ self.dropout_features = nn.Dropout(self.config.feat_quantizer_dropout)
+
+ self.quantizer = FlaxWav2Vec2GumbelVectorQuantizer(self.config, dtype=self.dtype)
+ self.project_q = nn.Dense(
+ self.config.proj_codevector_dim,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.project_hid = nn.Dense(
+ self.config.proj_codevector_dim,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+
+ def __call__(
+ self,
+ input_values,
+ attention_mask=None,
+ mask_time_indices=None,
+ gumbel_temperature: int = 1,
+ deterministic: bool = True,
+ output_attentions=None,
+ output_hidden_states=None,
+ freeze_feature_encoder=False,
+ return_dict=None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ mask_time_indices=mask_time_indices,
+ deterministic=deterministic,
+ freeze_feature_encoder=freeze_feature_encoder,
+ return_dict=return_dict,
+ )
+
+ # project all transformed features (including masked) to final vq dim
+ transformer_features = self.project_hid(outputs[0])
+
+ # quantize all (unmasked) extracted features and project to final vq dim
+ extract_features = self.dropout_features(outputs[1], deterministic=deterministic)
+ quantized_features, codevector_perplexity = self.quantizer(
+ extract_features, mask_time_indices, deterministic=deterministic, temperature=gumbel_temperature
+ )
+ quantized_features = self.project_q(quantized_features)
+
+ if not return_dict:
+ return (transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+
+ return FlaxWav2Vec2ForPreTrainingOutput(
+ projected_states=transformer_features,
+ projected_quantized_states=quantized_features,
+ codevector_perplexity=codevector_perplexity,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[jnp.ndarray, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+
+ return input_lengths
+
+
+@add_start_docstrings("""Wav2Vec2 Model with a quantizer and `VQ` head on top.""", WAV2VEC2_START_DOCSTRING)
+class FlaxWav2Vec2ForPreTraining(FlaxWav2Vec2PreTrainedModel):
+ module_class = FlaxWav2Vec2ForPreTrainingModule
+
+ @add_start_docstrings_to_model_forward(WAV2VEC2_INPUTS_DOCSTRING)
+ # overwrite since has `gumbel_temperature` input
+ def __call__(
+ self,
+ input_values,
+ attention_mask=None,
+ mask_time_indices=None,
+ gumbel_temperature: int = 1,
+ params: Optional[dict] = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ gumbel_rng: jax.random.PRNGKey = None,
+ train: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ freeze_feature_encoder: bool = False,
+ return_dict: Optional[bool] = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ batch_size, sequence_length = input_values.shape
+
+ if attention_mask is None:
+ attention_mask = jnp.ones((batch_size, sequence_length))
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ if gumbel_rng is not None:
+ rngs["gumbel"] = gumbel_rng
+
+ inputs = {"params": params or self.params}
+
+ return self.module.apply(
+ inputs,
+ jnp.array(input_values, dtype="f4"),
+ jnp.array(attention_mask, dtype="i4"),
+ mask_time_indices,
+ gumbel_temperature,
+ not train,
+ output_attentions,
+ output_hidden_states,
+ freeze_feature_encoder,
+ return_dict,
+ rngs=rngs,
+ )
+
+
+FLAX_WAV2VEC2_FOR_PRETRAINING_DOCSTRING = """
+ Returns:
+
+ Example:
+
+ ```python
+ >>> import optax
+ >>> import numpy as np
+ >>> import jax.numpy as jnp
+ >>> from transformers import AutoFeatureExtractor, FlaxWav2Vec2ForPreTraining
+ >>> from transformers.models.wav2vec2.modeling_flax_wav2vec2 import _compute_mask_indices
+ >>> from datasets import load_dataset
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-large-lv60")
+ >>> model = FlaxWav2Vec2ForPreTraining.from_pretrained("facebook/wav2vec2-large-lv60")
+
+
+ >>> def map_to_array(example):
+ ... example["speech"] = example["audio"]["array"]
+ ... return example
+
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> ds = ds.map(map_to_array)
+
+ >>> input_values = feature_extractor(ds["speech"][0], return_tensors="np").input_values # Batch size 1
+
+ >>> # compute masked indices
+ >>> batch_size, raw_sequence_length = input_values.shape
+ >>> sequence_length = model._get_feat_extract_output_lengths(raw_sequence_length)
+ >>> mask_time_indices = _compute_mask_indices((batch_size, sequence_length), mask_prob=0.2, mask_length=2)
+
+ >>> outputs = model(input_values, mask_time_indices=mask_time_indices)
+
+ >>> # compute cosine similarity between predicted (=projected_states) and target (=projected_quantized_states)
+ >>> cosine_sim = optax.cosine_similarity(outputs.projected_states, outputs.projected_quantized_states)
+
+ >>> # show that cosine similarity is much higher than random
+ >>> assert np.asarray(cosine_sim)[mask_time_indices].mean() > 0.5
+ ```
+"""
+
+overwrite_call_docstring(
+ FlaxWav2Vec2ForPreTraining,
+ WAV2VEC2_INPUTS_DOCSTRING + FLAX_WAV2VEC2_FOR_PRETRAINING_DOCSTRING,
+)
+append_replace_return_docstrings(
+ FlaxWav2Vec2ForPreTraining, output_type=FlaxWav2Vec2ForPreTrainingOutput, config_class=Wav2Vec2Config
+)
+
+
+__all__ = ["FlaxWav2Vec2ForCTC", "FlaxWav2Vec2ForPreTraining", "FlaxWav2Vec2Model", "FlaxWav2Vec2PreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_tf_wav2vec2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_tf_wav2vec2.py
new file mode 100644
index 0000000000000000000000000000000000000000..427cd7261f44b0affce0864a8c2c391644cae504
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_tf_wav2vec2.py
@@ -0,0 +1,1855 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TensorFlow Wav2Vec2 model."""
+
+from __future__ import annotations
+
+import warnings
+from dataclasses import dataclass
+from typing import Any
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_outputs import TFBaseModelOutput, TFCausalLMOutput, TFSequenceClassifierOutput
+from ...modeling_tf_utils import (
+ TFPreTrainedModel,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import shape_list, stable_softmax
+from ...utils import (
+ ModelOutput,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+ replace_return_docstrings,
+)
+from .configuration_wav2vec2 import Wav2Vec2Config
+
+
+logger = logging.get_logger(__name__)
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+_CHECKPOINT_FOR_DOC = "facebook/wav2vec2-base-960h"
+_CONFIG_FOR_DOC = "Wav2Vec2Config"
+
+
+LARGE_NEGATIVE = -1e8
+
+
+@dataclass
+class TFWav2Vec2BaseModelOutput(ModelOutput):
+ """
+ Output type of [`TFWav2Vec2BaseModelOutput`], with potential hidden states and attentions.
+
+ Args:
+ last_hidden_state (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Sequence of hidden-states at the output of the last layer of the model.
+ extract_features (`tf.Tensor` of shape `(batch_size, sequence_length, conv_dim[-1])`):
+ Sequence of extracted feature vectors of the last convolutional layer of the model.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ last_hidden_state: tf.Tensor | None = None
+ extract_features: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor] | None = None
+ attentions: tuple[tf.Tensor] | None = None
+
+
+def _sample_without_replacement(distribution, num_samples):
+ """
+ Categorical sampling without replacement is currently not implemented. The gumbel-max trick will do for now - see
+ https://github.com/tensorflow/tensorflow/issues/9260 for more info
+ """
+ z = -tf.math.log(tf.random.uniform(shape_list(distribution), 0, 1))
+ _, indices = tf.nn.top_k(distribution + z, num_samples)
+ return indices
+
+
+def _scatter_values_on_batch_indices(values, batch_indices, output_shape):
+ """
+ Scatter function as in PyTorch with indices in format (batch_dim, indixes)
+ """
+ indices_shape = shape_list(batch_indices)
+ # broadcast batch dim to indices_shape
+ broad_casted_batch_dims = tf.reshape(
+ tf.broadcast_to(tf.expand_dims(tf.range(indices_shape[0]), axis=-1), indices_shape), [1, -1]
+ )
+ # transform batch_indices to pair_indices
+ pair_indices = tf.transpose(tf.concat([broad_casted_batch_dims, tf.reshape(batch_indices, [1, -1])], 0))
+ # scatter values to pair indices
+ return tf.scatter_nd(pair_indices, tf.reshape(values, [-1]), output_shape)
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ min_masks: int = 0,
+) -> tf.Tensor:
+ """
+ Computes random mask spans for a given shape
+
+ Args:
+ shape: the shape for which to compute masks.
+ should be of size 2 where first element is batch size and 2nd is timesteps
+ attention_mask: optional padding mask of the same size as shape, which will prevent masking padded elements
+ mask_prob:
+ probability for each token to be chosen as start of the span to be masked. this will be multiplied by
+ number of timesteps divided by length of mask span to mask approximately this percentage of all elements.
+ however due to overlaps, the actual number will be smaller (unless no_overlap is True)
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+
+ Adapted from [fairseq's
+ data_utils.py](https://github.com/pytorch/fairseq/blob/e0788f7007a8473a76db573985031f3c94201e79/fairseq/data/data_utils.py#L376).
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ tf.debugging.assert_less(
+ mask_length,
+ sequence_length,
+ message=(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length} and"
+ f" `sequence_length`: {sequence_length}`"
+ ),
+ )
+
+ # compute number of masked spans in batch
+ num_masked_spans = mask_prob * tf.cast(sequence_length, tf.float32) / mask_length + tf.random.uniform((1,))
+ num_masked_spans = tf.maximum(num_masked_spans, min_masks)
+ num_masked_spans = tf.cast(num_masked_spans, tf.int32)
+
+ # make sure num masked indices <= sequence_length
+ num_masked_spans = tf.math.minimum(sequence_length // mask_length, num_masked_spans)
+ num_masked_spans = tf.squeeze(num_masked_spans)
+
+ # SpecAugment mask to fill
+ spec_aug_mask = tf.zeros((batch_size, sequence_length), dtype=tf.int32)
+
+ # uniform distribution to sample from, make sure that offset samples are < sequence_length
+ uniform_dist = tf.ones((batch_size, sequence_length - (mask_length - 1)))
+
+ # get random indices to mask
+ spec_aug_mask_idxs = _sample_without_replacement(uniform_dist, num_masked_spans)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = tf.expand_dims(spec_aug_mask_idxs, -1)
+ spec_aug_mask_idxs = tf.tile(spec_aug_mask_idxs, (1, 1, mask_length))
+ spec_aug_mask_idxs = tf.reshape(spec_aug_mask_idxs, (batch_size, num_masked_spans * mask_length))
+
+ offsets = tf.range(mask_length)[tf.newaxis, tf.newaxis, :]
+ offsets = tf.tile(offsets, (batch_size, num_masked_spans, 1))
+ offsets = tf.reshape(offsets, (batch_size, num_masked_spans * mask_length))
+
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # scatter indices to mask
+ spec_aug_mask = _scatter_values_on_batch_indices(
+ tf.ones_like(spec_aug_mask_idxs), spec_aug_mask_idxs, tf.shape(spec_aug_mask)
+ )
+
+ return spec_aug_mask
+
+
+# Copied from transformers.models.bart.modeling_tf_bart._expand_mask
+def _expand_mask(mask: tf.Tensor, tgt_len: int | None = None):
+ """
+ Expands attention_mask from `[bsz, seq_len]` to `[bsz, 1, tgt_seq_len, src_seq_len]`.
+ """
+ src_len = shape_list(mask)[1]
+ tgt_len = tgt_len if tgt_len is not None else src_len
+ one_cst = tf.constant(1.0)
+ mask = tf.cast(mask, dtype=one_cst.dtype)
+ expanded_mask = tf.tile(mask[:, None, None, :], (1, 1, tgt_len, 1))
+
+ return (one_cst - expanded_mask) * LARGE_NEGATIVE
+
+
+class TFWav2Vec2GroupNorm(keras.layers.Layer):
+ """
+ From tensorflow-addons https://www.tensorflow.org/addons/api_docs/python/tfa/layers/GroupNormalization
+ """
+
+ def __init__(
+ self,
+ groups: int = 32,
+ axis: int = -1,
+ epsilon: float = 1e-3,
+ center: bool = True,
+ scale: bool = True,
+ beta_initializer: keras.initializers.Initializer = "zeros",
+ gamma_initializer: keras.initializers.Initializer = "ones",
+ beta_regularizer: keras.regularizers.Regularizer = None,
+ gamma_regularizer: keras.regularizers.Regularizer = None,
+ beta_constraint: keras.constraints.Constraint = None,
+ gamma_constraint: keras.constraints.Constraint = None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.supports_masking = True
+ self.groups = groups
+ self.axis = axis
+ self.epsilon = epsilon
+ self.center = center
+ self.scale = scale
+ self.beta_initializer = keras.initializers.get(beta_initializer)
+ self.gamma_initializer = keras.initializers.get(gamma_initializer)
+ self.beta_regularizer = keras.regularizers.get(beta_regularizer)
+ self.gamma_regularizer = keras.regularizers.get(gamma_regularizer)
+ self.beta_constraint = keras.constraints.get(beta_constraint)
+ self.gamma_constraint = keras.constraints.get(gamma_constraint)
+ self._check_axis()
+
+ def build(self, input_shape):
+ self._check_if_input_shape_is_none(input_shape)
+ self._set_number_of_groups_for_instance_norm(input_shape)
+ self._check_size_of_dimensions(input_shape)
+ self._create_input_spec(input_shape)
+
+ self._add_gamma_weight(input_shape)
+ self._add_beta_weight(input_shape)
+ self.built = True
+ super().build(input_shape)
+
+ def call(self, inputs):
+ input_shape = keras.backend.int_shape(inputs)
+ tensor_input_shape = tf.shape(inputs)
+
+ reshaped_inputs, group_shape = self._reshape_into_groups(inputs, input_shape, tensor_input_shape)
+
+ normalized_inputs = self._apply_normalization(reshaped_inputs, input_shape)
+
+ is_instance_norm = (input_shape[self.axis] // self.groups) == 1
+ if not is_instance_norm:
+ outputs = tf.reshape(normalized_inputs, tensor_input_shape)
+ else:
+ outputs = normalized_inputs
+
+ return outputs
+
+ def get_config(self):
+ config = {
+ "groups": self.groups,
+ "axis": self.axis,
+ "epsilon": self.epsilon,
+ "center": self.center,
+ "scale": self.scale,
+ "beta_initializer": keras.initializers.serialize(self.beta_initializer),
+ "gamma_initializer": keras.initializers.serialize(self.gamma_initializer),
+ "beta_regularizer": keras.regularizers.serialize(self.beta_regularizer),
+ "gamma_regularizer": keras.regularizers.serialize(self.gamma_regularizer),
+ "beta_constraint": keras.constraints.serialize(self.beta_constraint),
+ "gamma_constraint": keras.constraints.serialize(self.gamma_constraint),
+ }
+ base_config = super().get_config()
+ return {**base_config, **config}
+
+ def compute_output_shape(self, input_shape):
+ return input_shape
+
+ def _reshape_into_groups(self, inputs, input_shape, tensor_input_shape):
+ group_shape = [tensor_input_shape[i] for i in range(len(input_shape))]
+ is_instance_norm = (input_shape[self.axis] // self.groups) == 1
+ if not is_instance_norm:
+ group_shape[self.axis] = input_shape[self.axis] // self.groups
+ group_shape.insert(self.axis, self.groups)
+ group_shape = tf.stack(group_shape)
+ reshaped_inputs = tf.reshape(inputs, group_shape)
+ return reshaped_inputs, group_shape
+ else:
+ return inputs, group_shape
+
+ def _apply_normalization(self, reshaped_inputs, input_shape):
+ group_shape = keras.backend.int_shape(reshaped_inputs)
+ group_reduction_axes = list(range(1, len(group_shape)))
+ is_instance_norm = (input_shape[self.axis] // self.groups) == 1
+ if not is_instance_norm:
+ axis = -2 if self.axis == -1 else self.axis - 1
+ else:
+ axis = -1 if self.axis == -1 else self.axis - 1
+ group_reduction_axes.pop(axis)
+
+ mean, variance = tf.nn.moments(reshaped_inputs, group_reduction_axes, keepdims=True)
+
+ gamma, beta = self._get_reshaped_weights(input_shape)
+ normalized_inputs = tf.nn.batch_normalization(
+ reshaped_inputs,
+ mean=mean,
+ variance=variance,
+ scale=gamma,
+ offset=beta,
+ variance_epsilon=self.epsilon,
+ )
+ return normalized_inputs
+
+ def _get_reshaped_weights(self, input_shape):
+ broadcast_shape = self._create_broadcast_shape(input_shape)
+ gamma = None
+ beta = None
+ if self.scale:
+ gamma = tf.reshape(self.gamma, broadcast_shape)
+
+ if self.center:
+ beta = tf.reshape(self.beta, broadcast_shape)
+ return gamma, beta
+
+ def _check_if_input_shape_is_none(self, input_shape):
+ dim = input_shape[self.axis]
+ if dim is None:
+ raise ValueError(
+ "Axis "
+ + str(self.axis)
+ + " of input tensor should have a defined dimension but the layer received an input with shape "
+ + str(input_shape)
+ + "."
+ )
+
+ def _set_number_of_groups_for_instance_norm(self, input_shape):
+ dim = input_shape[self.axis]
+
+ if self.groups == -1:
+ self.groups = dim
+
+ def _check_size_of_dimensions(self, input_shape):
+ dim = input_shape[self.axis]
+ if dim < self.groups:
+ raise ValueError(
+ "Number of groups ("
+ + str(self.groups)
+ + ") cannot be more than the number of channels ("
+ + str(dim)
+ + ")."
+ )
+
+ if dim % self.groups != 0:
+ raise ValueError(
+ "Number of groups ("
+ + str(self.groups)
+ + ") must be a multiple of the number of channels ("
+ + str(dim)
+ + ")."
+ )
+
+ def _check_axis(self):
+ if self.axis == 0:
+ raise ValueError(
+ "You are trying to normalize your batch axis. Do you want to use tf.layer.batch_normalization instead"
+ )
+
+ def _create_input_spec(self, input_shape):
+ dim = input_shape[self.axis]
+ self.input_spec = keras.layers.InputSpec(ndim=len(input_shape), axes={self.axis: dim})
+
+ def _add_gamma_weight(self, input_shape):
+ dim = input_shape[self.axis]
+ shape = (dim,)
+
+ if self.scale:
+ self.gamma = self.add_weight(
+ shape=shape,
+ name="gamma",
+ initializer=self.gamma_initializer,
+ regularizer=self.gamma_regularizer,
+ constraint=self.gamma_constraint,
+ )
+ else:
+ self.gamma = None
+
+ def _add_beta_weight(self, input_shape):
+ dim = input_shape[self.axis]
+ shape = (dim,)
+
+ if self.center:
+ self.beta = self.add_weight(
+ shape=shape,
+ name="beta",
+ initializer=self.beta_initializer,
+ regularizer=self.beta_regularizer,
+ constraint=self.beta_constraint,
+ )
+ else:
+ self.beta = None
+
+ def _create_broadcast_shape(self, input_shape):
+ broadcast_shape = [1] * len(input_shape)
+ is_instance_norm = (input_shape[self.axis] // self.groups) == 1
+ if not is_instance_norm:
+ broadcast_shape[self.axis] = input_shape[self.axis] // self.groups
+ broadcast_shape.insert(self.axis, self.groups)
+ else:
+ broadcast_shape[self.axis] = self.groups
+ return broadcast_shape
+
+
+class TFWav2Vec2WeightNormConv1D(keras.layers.Conv1D):
+ """Adapted from https://www.tensorflow.org/probability/api_docs/python/tfp/layers/weight_norm/WeightNorm"""
+
+ def __init__(self, filters, kernel_size, groups, explicit_padding, **kwargs):
+ super().__init__(
+ filters=filters,
+ kernel_size=kernel_size,
+ groups=groups,
+ padding="valid",
+ use_bias=True,
+ bias_initializer="he_normal",
+ **kwargs,
+ )
+ self.explicit_padding = explicit_padding
+ self.filter_axis = 2
+ self.kernel_norm_axes = tf.constant([0, 1])
+
+ def _init_norm(self):
+ """Set the norm of the weight vector."""
+ kernel_norm = tf.sqrt(tf.reduce_sum(tf.square(self.weight_v), axis=self.kernel_norm_axes))
+ self.weight_g.assign(kernel_norm[:, tf.newaxis, tf.newaxis])
+
+ def _normalize_kernel(self):
+ """Generate normalized weights."""
+ kernel = tf.nn.l2_normalize(self.weight_v, axis=self.kernel_norm_axes) * tf.transpose(self.weight_g)
+ self.kernel = tf.transpose(kernel)
+
+ def build(self, input_shape):
+ if not self.built:
+ super().build(input_shape)
+
+ self.kernel = tf.Variable(tf.transpose(self.kernel), name="weight_v", trainable=True)
+ self.weight_v = self.kernel
+
+ self.weight_g = self.add_weight(
+ name="weight_g",
+ shape=(int(self.weight_v.shape[self.filter_axis]), 1, 1),
+ initializer="ones",
+ dtype=self.weight_v.dtype,
+ trainable=True,
+ )
+ self._init_norm()
+ self.bias = self.add_weight(name="bias", shape=(self.filters,), initializer="zeros", trainable=True)
+
+ def call(self, inputs):
+ # TODO Matt: Assigning to attributes in call() is deeply sinful in TensorFlow, as it should be idempotent.
+ # This whole layer should be replaced by a layer that doesn't inherit from Conv1D, but instead calls
+ # a functional 1d convolution with normalized weights that it generates (but does not store!)
+ self._normalize_kernel()
+
+ padded_inputs = tf.pad(inputs, ((0, 0), (self.explicit_padding, self.explicit_padding), (0, 0)))
+ output = super().call(padded_inputs)
+
+ return output
+
+
+class TFWav2Vec2NoLayerNormConvLayer(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, layer_id: int = 0, **kwargs: Any) -> None:
+ super().__init__(**kwargs)
+ self.in_conv_dim = config.conv_dim[layer_id] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = keras.layers.Conv1D(
+ filters=self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ strides=config.conv_stride[layer_id],
+ use_bias=config.conv_bias,
+ name="conv",
+ )
+ self.activation = get_tf_activation(config.feat_extract_activation)
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv", None) is not None:
+ with tf.name_scope(self.conv.name):
+ self.conv.build([None, None, self.in_conv_dim])
+
+
+class TFWav2Vec2LayerNormConvLayer(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, layer_id: int = 0, **kwargs: Any) -> None:
+ super().__init__(**kwargs)
+ self.in_conv_dim = config.conv_dim[layer_id] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = keras.layers.Conv1D(
+ filters=self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ strides=config.conv_stride[layer_id],
+ use_bias=config.conv_bias,
+ name="conv",
+ )
+ self.layer_norm = keras.layers.LayerNormalization(name="layer_norm", epsilon=config.layer_norm_eps)
+ self.activation = get_tf_activation(config.feat_extract_activation)
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv", None) is not None:
+ with tf.name_scope(self.conv.name):
+ self.conv.build([None, None, self.in_conv_dim])
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.out_conv_dim])
+
+
+class TFWav2Vec2GroupNormConvLayer(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, layer_id: int = 0, **kwargs: Any) -> None:
+ super().__init__(**kwargs)
+ self.in_conv_dim = config.conv_dim[layer_id] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = keras.layers.Conv1D(
+ filters=self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ strides=config.conv_stride[layer_id],
+ use_bias=config.conv_bias,
+ name="conv",
+ )
+ self.activation = get_tf_activation(config.feat_extract_activation)
+ self.layer_norm = TFWav2Vec2GroupNorm(
+ groups=self.out_conv_dim, epsilon=config.layer_norm_eps, name="layer_norm"
+ )
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv", None) is not None:
+ with tf.name_scope(self.conv.name):
+ self.conv.build([None, None, self.in_conv_dim])
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.out_conv_dim])
+
+
+class TFWav2Vec2PositionalConvEmbedding(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs: Any) -> None:
+ super().__init__(**kwargs)
+ self.conv = TFWav2Vec2WeightNormConv1D(
+ filters=config.hidden_size,
+ kernel_size=config.num_conv_pos_embeddings,
+ groups=config.num_conv_pos_embedding_groups,
+ explicit_padding=config.num_conv_pos_embeddings // 2,
+ name="conv",
+ )
+ self.padding = TFWav2Vec2SamePadLayer(config.num_conv_pos_embeddings)
+ self.activation = get_tf_activation(config.feat_extract_activation)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.padding(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv", None) is not None:
+ with tf.name_scope(self.conv.name):
+ self.conv.build([None, None, self.config.hidden_size])
+
+
+class TFWav2Vec2SamePadLayer(keras.layers.Layer):
+ def __init__(self, num_conv_pos_embeddings, **kwargs):
+ super().__init__(**kwargs)
+ self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0
+
+ def call(self, hidden_states):
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, : -self.num_pad_remove, :]
+ return hidden_states
+
+
+class TFWav2Vec2FeatureEncoder(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs: Any) -> None:
+ super().__init__(**kwargs)
+
+ if config.feat_extract_norm == "group":
+ conv_layers = [TFWav2Vec2GroupNormConvLayer(config, layer_id=0, name=f"conv_layers.{0}")] + [
+ TFWav2Vec2NoLayerNormConvLayer(config, layer_id=i + 1, name=f"conv_layers.{i + 1}")
+ for i in range(config.num_feat_extract_layers - 1)
+ ]
+ elif config.feat_extract_norm == "layer":
+ conv_layers = [
+ TFWav2Vec2LayerNormConvLayer(config, layer_id=i, name=f"conv_layers.{i}")
+ for i in range(config.num_feat_extract_layers)
+ ]
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']"
+ )
+ self.conv_layers = conv_layers
+
+ def call(self, input_values):
+ hidden_states = tf.expand_dims(input_values, -1)
+ for conv_layer in self.conv_layers:
+ hidden_states = conv_layer(hidden_states)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv_layers", None) is not None:
+ for conv_layer in self.conv_layers:
+ with tf.name_scope(conv_layer.name):
+ conv_layer.build(None)
+
+
+class TFWav2Vec2FeatureExtractor(TFWav2Vec2FeatureEncoder):
+ def __init__(self, config, **kwargs):
+ super().__init__(config, **kwargs)
+ warnings.warn(
+ f"The class `{self.__class__.__name__}` has been depreciated "
+ "and will be removed in Transformers v5. "
+ f"Use `{self.__class__.__bases__[0].__name__}` instead.",
+ FutureWarning,
+ )
+
+
+class TFWav2Vec2FeatureProjection(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs):
+ super().__init__(**kwargs)
+
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.projection = keras.layers.Dense(
+ units=config.hidden_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ bias_initializer="zeros",
+ name="projection",
+ )
+ self.dropout = keras.layers.Dropout(rate=config.feat_proj_dropout)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, training: bool = False) -> tf.Tensor:
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ return hidden_states, norm_hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.conv_dim[-1]])
+ if getattr(self, "projection", None) is not None:
+ with tf.name_scope(self.projection.name):
+ self.projection.build([None, None, self.config.conv_dim[-1]])
+
+
+# Copied from transformers.models.bart.modeling_tf_bart.TFBartAttention with TFBart->TFWav2Vec2
+class TFWav2Vec2Attention(keras.layers.Layer):
+ """Multi-headed attention from "Attention Is All You Need"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.embed_dim = embed_dim
+
+ self.num_heads = num_heads
+ self.dropout = keras.layers.Dropout(dropout)
+ self.head_dim = embed_dim // num_heads
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+
+ self.k_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="k_proj")
+ self.q_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="q_proj")
+ self.v_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="v_proj")
+ self.out_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="out_proj")
+
+ def _shape(self, tensor: tf.Tensor, seq_len: int, bsz: int):
+ return tf.transpose(tf.reshape(tensor, (bsz, seq_len, self.num_heads, self.head_dim)), (0, 2, 1, 3))
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ key_value_states: tf.Tensor | None = None,
+ past_key_value: tuple[tuple[tf.Tensor]] | None = None,
+ attention_mask: tf.Tensor | None = None,
+ layer_head_mask: tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> tuple[tf.Tensor, tf.Tensor | None]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ bsz, tgt_len, embed_dim = shape_list(hidden_states)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+ # get key, value proj
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_states = past_key_value[0]
+ value_states = past_key_value[1]
+ elif is_cross_attention:
+ # cross_attentions
+ key_states = self._shape(self.k_proj(key_value_states), -1, bsz)
+ value_states = self._shape(self.v_proj(key_value_states), -1, bsz)
+ elif past_key_value is not None:
+ # reuse k, v, self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+ key_states = tf.concat([past_key_value[0], key_states], axis=2)
+ value_states = tf.concat([past_key_value[1], value_states], axis=2)
+ else:
+ # self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(tf.Tensor, tf.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(tf.Tensor, tf.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_states, value_states)
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = tf.reshape(self._shape(query_states, tgt_len, bsz), proj_shape)
+ key_states = tf.reshape(key_states, proj_shape)
+ value_states = tf.reshape(value_states, proj_shape)
+
+ src_len = shape_list(key_states)[1]
+ attn_weights = tf.matmul(query_states, key_states, transpose_b=True)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_weights),
+ [bsz * self.num_heads, tgt_len, src_len],
+ message=(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {shape_list(attn_weights)}"
+ ),
+ )
+
+ if attention_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(attention_mask),
+ [bsz, 1, tgt_len, src_len],
+ message=(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is"
+ f" {shape_list(attention_mask)}"
+ ),
+ )
+
+ attention_mask = tf.cast(attention_mask, dtype=attn_weights.dtype)
+ attn_weights = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len)) + attention_mask
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_weights = stable_softmax(attn_weights, axis=-1)
+
+ if layer_head_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(layer_head_mask),
+ [self.num_heads],
+ message=(
+ f"Head mask for a single layer should be of size {(self.num_heads)}, but is"
+ f" {shape_list(layer_head_mask)}"
+ ),
+ )
+
+ attn_weights = tf.reshape(layer_head_mask, (1, -1, 1, 1)) * tf.reshape(
+ attn_weights, (bsz, self.num_heads, tgt_len, src_len)
+ )
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_probs = self.dropout(attn_weights, training=training)
+ attn_output = tf.matmul(attn_probs, value_states)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_output),
+ [bsz * self.num_heads, tgt_len, self.head_dim],
+ message=(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {shape_list(attn_output)}"
+ ),
+ )
+
+ attn_output = tf.transpose(
+ tf.reshape(attn_output, (bsz, self.num_heads, tgt_len, self.head_dim)), (0, 2, 1, 3)
+ )
+ attn_output = tf.reshape(attn_output, (bsz, tgt_len, embed_dim))
+
+ attn_output = self.out_proj(attn_output)
+ attn_weights: tf.Tensor = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len))
+
+ return attn_output, attn_weights, past_key_value
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "k_proj", None) is not None:
+ with tf.name_scope(self.k_proj.name):
+ self.k_proj.build([None, None, self.embed_dim])
+ if getattr(self, "q_proj", None) is not None:
+ with tf.name_scope(self.q_proj.name):
+ self.q_proj.build([None, None, self.embed_dim])
+ if getattr(self, "v_proj", None) is not None:
+ with tf.name_scope(self.v_proj.name):
+ self.v_proj.build([None, None, self.embed_dim])
+ if getattr(self, "out_proj", None) is not None:
+ with tf.name_scope(self.out_proj.name):
+ self.out_proj.build([None, None, self.embed_dim])
+
+
+class TFWav2Vec2FeedForward(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs):
+ super().__init__(**kwargs)
+
+ self.intermediate_dropout = keras.layers.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = keras.layers.Dense(
+ units=config.intermediate_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ bias_initializer="zeros",
+ name="intermediate_dense",
+ )
+ self.intermediate_act_fn = get_tf_activation(config.hidden_act)
+
+ self.output_dense = keras.layers.Dense(
+ units=config.hidden_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ bias_initializer="zeros",
+ name="output_dense",
+ )
+ self.output_dropout = keras.layers.Dropout(config.hidden_dropout)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states, training=training)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states, training=training)
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "intermediate_dense", None) is not None:
+ with tf.name_scope(self.intermediate_dense.name):
+ self.intermediate_dense.build([None, None, self.config.hidden_size])
+ if getattr(self, "output_dense", None) is not None:
+ with tf.name_scope(self.output_dense.name):
+ self.output_dense.build([None, None, self.config.intermediate_size])
+
+
+class TFWav2Vec2EncoderLayer(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs):
+ super().__init__(**kwargs)
+ self.attention = TFWav2Vec2Attention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ name="attention",
+ )
+ self.dropout = keras.layers.Dropout(config.hidden_dropout)
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.feed_forward = TFWav2Vec2FeedForward(config, name="feed_forward")
+ self.final_layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="final_layer_norm")
+ self.config = config
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = False,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ attn_residual = hidden_states
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, training=training
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = attn_residual + hidden_states
+
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "attention", None) is not None:
+ with tf.name_scope(self.attention.name):
+ self.attention.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.hidden_size])
+ if getattr(self, "feed_forward", None) is not None:
+ with tf.name_scope(self.feed_forward.name):
+ self.feed_forward.build(None)
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build([None, None, self.config.hidden_size])
+
+
+class TFWav2Vec2EncoderLayerStableLayerNorm(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs):
+ super().__init__(**kwargs)
+ self.attention = TFWav2Vec2Attention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ name="attention",
+ )
+ self.dropout = keras.layers.Dropout(config.hidden_dropout)
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.feed_forward = TFWav2Vec2FeedForward(config, name="feed_forward")
+ self.final_layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="final_layer_norm")
+ self.config = config
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = False,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ attn_residual = hidden_states
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, training=training
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = attn_residual + hidden_states
+ hidden_states = hidden_states + self.feed_forward(self.final_layer_norm(hidden_states))
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "attention", None) is not None:
+ with tf.name_scope(self.attention.name):
+ self.attention.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.hidden_size])
+ if getattr(self, "feed_forward", None) is not None:
+ with tf.name_scope(self.feed_forward.name):
+ self.feed_forward.build(None)
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build([None, None, self.config.hidden_size])
+
+
+class TFWav2Vec2Encoder(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.pos_conv_embed = TFWav2Vec2PositionalConvEmbedding(config, name="pos_conv_embed")
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.dropout = keras.layers.Dropout(config.hidden_dropout)
+ self.layer = [TFWav2Vec2EncoderLayer(config, name=f"layers.{i}") for i in range(config.num_hidden_layers)]
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = False,
+ output_hidden_states: bool | None = False,
+ return_dict: bool | None = True,
+ training: bool | None = False,
+ ) -> TFBaseModelOutput | tuple[tf.Tensor]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ hidden_states = hidden_states * tf.expand_dims(attention_mask, -1)
+ attention_mask = _expand_mask(attention_mask)
+ else:
+ attention_mask = None
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = np.random.uniform(0, 1)
+ if training and (dropout_probability < self.config.layerdrop): # skip the layer
+ continue
+
+ layer_outputs = layer_module(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return TFBaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "pos_conv_embed", None) is not None:
+ with tf.name_scope(self.pos_conv_embed.name):
+ self.pos_conv_embed.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.hidden_size])
+ if getattr(self, "layer", None) is not None:
+ for layer in self.layer:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+class TFWav2Vec2EncoderStableLayerNorm(keras.layers.Layer):
+ def __init__(self, config: Wav2Vec2Config, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.pos_conv_embed = TFWav2Vec2PositionalConvEmbedding(config, name="pos_conv_embed")
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.dropout = keras.layers.Dropout(config.hidden_dropout)
+ self.layer = [
+ TFWav2Vec2EncoderLayerStableLayerNorm(config, name=f"layers.{i}") for i in range(config.num_hidden_layers)
+ ]
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = False,
+ output_hidden_states: bool | None = False,
+ return_dict: bool | None = True,
+ training: bool | None = False,
+ ) -> TFBaseModelOutput | tuple[tf.Tensor]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ hidden_states = hidden_states * tf.expand_dims(attention_mask, -1)
+ attention_mask = _expand_mask(attention_mask)
+ else:
+ attention_mask = None
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = np.random.uniform(0, 1)
+ if training and (dropout_probability < self.config.layerdrop): # skip the layer
+ continue
+
+ layer_outputs = layer_module(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return TFBaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "pos_conv_embed", None) is not None:
+ with tf.name_scope(self.pos_conv_embed.name):
+ self.pos_conv_embed.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.hidden_size])
+ if getattr(self, "layer", None) is not None:
+ for layer in self.layer:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@keras_serializable
+class TFWav2Vec2MainLayer(keras.layers.Layer):
+ config_class = Wav2Vec2Config
+
+ def __init__(self, config: Wav2Vec2Config, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.feature_extractor = TFWav2Vec2FeatureEncoder(config, name="feature_extractor")
+ self.feature_projection = TFWav2Vec2FeatureProjection(config, name="feature_projection")
+
+ if config.do_stable_layer_norm:
+ self.encoder = TFWav2Vec2EncoderStableLayerNorm(config, name="encoder")
+ else:
+ self.encoder = TFWav2Vec2Encoder(config, name="encoder")
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if self.config.mask_time_prob > 0.0 or self.config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = self.add_weight(
+ shape=(self.config.hidden_size,), initializer="uniform", trainable=True, name="masked_spec_embed"
+ )
+ if getattr(self, "feature_extractor", None) is not None:
+ with tf.name_scope(self.feature_extractor.name):
+ self.feature_extractor.build(None)
+ if getattr(self, "feature_projection", None) is not None:
+ with tf.name_scope(self.feature_projection.name):
+ self.feature_projection.build(None)
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+
+ def _get_feat_extract_output_lengths(self, input_lengths: tf.Tensor):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ return input_lengths
+
+ def _mask_hidden_states(self, hidden_states: tf.Tensor, mask_time_indices: tf.Tensor | None = None):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+ batch_size, sequence_length, hidden_size = shape_list(hidden_states)
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states = tf.where(
+ tf.cast(mask_time_indices[:, :, tf.newaxis], tf.bool),
+ self.masked_spec_embed[tf.newaxis, tf.newaxis, :],
+ hidden_states,
+ )
+
+ elif self.config.mask_time_prob > 0:
+ # generate indices & apply SpecAugment along time axis
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ min_masks=2,
+ )
+ hidden_states = tf.where(
+ tf.cast(mask_time_indices[:, :, tf.newaxis], tf.bool),
+ self.masked_spec_embed[tf.newaxis, tf.newaxis, :],
+ hidden_states,
+ )
+
+ # apply SpecAugment along feature axis
+ if self.config.mask_feature_prob > 0:
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ )
+ hidden_states = tf.where(mask_feature_indices[:, tf.newaxis, :], hidden_states, 0)
+
+ return hidden_states
+
+ @unpack_inputs
+ def call(
+ self,
+ input_values: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ token_type_ids: tf.Tensor | None = None,
+ position_ids: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ inputs_embeds: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ **kwargs: Any,
+ ):
+ extract_features = self.feature_extractor(tf.cast(input_values, tf.float32), training=training)
+ # extract_features = tf.transpose(extract_features, perm=(0, 2, 1))
+
+ if attention_mask is not None:
+ # compute real output lengths according to convolution formula
+ output_lengths = self._get_feat_extract_output_lengths(tf.reduce_sum(attention_mask, -1))
+
+ attention_mask = tf.sequence_mask(
+ output_lengths, maxlen=shape_list(extract_features)[1], dtype=extract_features.dtype
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features, training=training)
+
+ mask_time_indices = kwargs.get("mask_time_indices")
+ if training:
+ hidden_states = self._mask_hidden_states(hidden_states, mask_time_indices=mask_time_indices)
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ hidden_states = encoder_outputs[0]
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return TFWav2Vec2BaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class TFWav2Vec2PreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = Wav2Vec2Config
+ base_model_prefix = "wav2vec2"
+ main_input_name = "input_values"
+
+ @property
+ def input_signature(self):
+ return {
+ "input_values": tf.TensorSpec((None, None), tf.float32, name="input_values"),
+ "attention_mask": tf.TensorSpec((None, None), tf.float32, name="attention_mask"),
+ }
+
+ @property
+ def dummy_inputs(self):
+ return {
+ "input_values": tf.random.uniform(shape=(1, 500), dtype=tf.float32),
+ "attention_mask": tf.ones(shape=(1, 500), dtype=tf.float32),
+ }
+
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ logger.warning(
+ f"\n{self.__class__.__name__} has backpropagation operations that are NOT supported on CPU. If you wish "
+ "to train/fine-tune this model, you need a GPU or a TPU"
+ )
+
+ def _get_feat_extract_output_lengths(self, input_lengths, add_adapter=None):
+ """
+ Computes the output length of the convolutional layers
+ """
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ return tf.math.floordiv(input_length - kernel_size, stride) + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: tf.Tensor, add_adapter=None
+ ):
+ non_padded_lengths = tf.math.cumsum(attention_mask, axis=-1)[:, -1]
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+ output_lengths = tf.cast(output_lengths, tf.int32)
+ batch_size = tf.shape(attention_mask)[0]
+ # check device here
+ attention_mask = tf.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, name="attention_mask"
+ ) # these two operations makes sure that all values before the output lengths idxs are attended to
+ ## check device
+ attention_mask = tf.tensor_scatter_nd_update(
+ attention_mask,
+ indices=tf.stack([tf.range(batch_size), output_lengths - 1], axis=1),
+ updates=tf.ones([batch_size], dtype=attention_mask.dtype),
+ )
+ attention_mask = tf.reverse(attention_mask, axis=[-1])
+ attention_mask = tf.cumsum(attention_mask, axis=-1)
+ attention_mask = tf.reverse(attention_mask, axis=[-1])
+ attention_mask = tf.cast(attention_mask, tf.bool)
+ return attention_mask
+
+
+WAV2VEC2_START_DOCSTRING = r"""
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_values` only and nothing else: `model(input_values)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_values, attention_mask])` or `model([input_values, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_values": input_values, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Args:
+ config ([`Wav2Vec2Config`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+WAV2VEC2_INPUTS_DOCSTRING = r"""
+ Args:
+ input_values (`np.ndarray`, `tf.Tensor`, `list[tf.Tensor]` `dict[str, tf.Tensor]` or `dict[str, np.ndarray]` and each example must have the shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.__call__`] and
+ [`PreTrainedTokenizer.encode`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`np.ndarray` or `tf.Tensor` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ token_type_ids (`np.ndarray` or `tf.Tensor` of shape `({0})`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`np.ndarray` or `tf.Tensor` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ head_mask (`np.ndarray` or `tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ inputs_embeds (`np.ndarray` or `tf.Tensor` of shape `({0}, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_values` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_values` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False``):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+
+@add_start_docstrings(
+ "The bare TFWav2Vec2 Model transformer outputting raw hidden-states without any specific head on top.",
+ WAV2VEC2_START_DOCSTRING,
+)
+class TFWav2Vec2Model(TFWav2Vec2PreTrainedModel):
+ def __init__(self, config: Wav2Vec2Config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.config = config
+ self.wav2vec2 = TFWav2Vec2MainLayer(config, name="wav2vec2")
+
+ @add_start_docstrings_to_model_forward(WAV2VEC2_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFBaseModelOutput, config_class=_CONFIG_FOR_DOC)
+ @unpack_inputs
+ def call(
+ self,
+ input_values: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ token_type_ids: tf.Tensor | None = None,
+ position_ids: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ inputs_embeds: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFBaseModelOutput | tuple[tf.Tensor]:
+ """
+
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoProcessor, TFWav2Vec2Model
+ >>> from datasets import load_dataset
+
+ >>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+ >>> model = TFWav2Vec2Model.from_pretrained("facebook/wav2vec2-base-960h")
+
+
+ >>> def map_to_array(example):
+ ... example["speech"] = example["audio"]["array"]
+ ... return example
+
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> ds = ds.map(map_to_array)
+
+ >>> input_values = processor(ds["speech"][0], return_tensors="tf").input_values # Batch size 1
+ >>> hidden_states = model(input_values).last_hidden_state
+ ```"""
+
+ output_hidden_states = output_hidden_states if output_hidden_states else self.config.output_hidden_states
+ output_attentions = output_attentions if output_attentions else self.config.output_attentions
+ return_dict = return_dict if return_dict else self.config.return_dict
+
+ outputs = self.wav2vec2(
+ input_values=input_values,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "wav2vec2", None) is not None:
+ with tf.name_scope(self.wav2vec2.name):
+ self.wav2vec2.build(None)
+
+
+@add_start_docstrings(
+ """TFWav2Vec2 Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).""",
+ WAV2VEC2_START_DOCSTRING,
+)
+class TFWav2Vec2ForCTC(TFWav2Vec2PreTrainedModel):
+ def __init__(self, config: Wav2Vec2Config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.wav2vec2 = TFWav2Vec2MainLayer(config, name="wav2vec2")
+ self.dropout = keras.layers.Dropout(config.final_dropout)
+ self.lm_head = keras.layers.Dense(config.vocab_size, name="lm_head")
+ self.output_hidden_size = (
+ config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size
+ )
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2.feature_extractor.trainable = False
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(WAV2VEC2_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFCausalLMOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_values: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ token_type_ids: tf.Tensor | None = None,
+ position_ids: tf.Tensor | None = None,
+ head_mask: tf.Tensor | None = None,
+ inputs_embeds: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ labels: tf.Tensor | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ ) -> TFCausalLMOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` or `np.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_values` docstring) Tokens with indices set to `-100` are ignored (masked),
+ the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+
+ Returns:
+
+ Example:
+
+ ```python
+ >>> import tensorflow as tf
+ >>> from transformers import AutoProcessor, TFWav2Vec2ForCTC
+ >>> from datasets import load_dataset
+ >>> from torchcodec.decoders import AudioDecoder
+
+ >>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+ >>> model = TFWav2Vec2ForCTC.from_pretrained("facebook/wav2vec2-base-960h")
+
+
+ >>> def map_to_array(example):
+ ... example["speech"] = example["audio"]["array"]
+ ... return example
+
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> ds = ds.map(map_to_array)
+
+ >>> input_values = processor(ds["speech"][0], return_tensors="tf").input_values # Batch size 1
+ >>> logits = model(input_values).logits
+ >>> predicted_ids = tf.argmax(logits, axis=-1)
+
+ >>> transcription = processor.decode(predicted_ids[0])
+
+ >>> # compute loss
+ >>> target_transcription = "A MAN SAID TO THE UNIVERSE SIR I EXIST"
+
+ >>> # Pass transcription as `text` to encode labels
+ >>> labels = processor(text=transcription, return_tensors="tf").input_ids
+
+ >>> loss = model(input_values, labels=labels).loss
+ ```"""
+ if labels is not None and tf.reduce_max(labels) >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ outputs = self.wav2vec2(
+ input_values=input_values,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ logits = self.lm_head(hidden_states)
+
+ if labels is not None:
+ attention_mask = (
+ attention_mask if attention_mask is not None else tf.ones_like(input_values, dtype=tf.float32)
+ )
+ input_lengths = self.wav2vec2._get_feat_extract_output_lengths(tf.reduce_sum(attention_mask, axis=-1))
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = tf.cast(labels >= 0, tf.int32)
+ target_lengths = tf.reduce_sum(labels_mask, axis=-1)
+
+ loss = tf.nn.ctc_loss(
+ logits=logits,
+ labels=labels,
+ logit_length=input_lengths,
+ label_length=target_lengths,
+ blank_index=self.config.pad_token_id,
+ logits_time_major=False,
+ )
+
+ if self.config.ctc_loss_reduction == "sum":
+ loss = tf.reduce_sum(loss)
+ if self.config.ctc_loss_reduction == "mean":
+ loss = tf.reduce_mean(loss)
+
+ loss = tf.reshape(loss, (1,))
+ else:
+ loss = None
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFCausalLMOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "wav2vec2", None) is not None:
+ with tf.name_scope(self.wav2vec2.name):
+ self.wav2vec2.build(None)
+ if getattr(self, "lm_head", None) is not None:
+ with tf.name_scope(self.lm_head.name):
+ self.lm_head.build([None, None, self.output_hidden_size])
+
+
+class TFWav2Vec2ForSequenceClassification(TFWav2Vec2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.wav2vec2 = TFWav2Vec2MainLayer(config, name="wav2vec2")
+ self.num_layers = config.num_hidden_layers + 1
+ with tf.name_scope(self._name_scope()):
+ if config.use_weighted_layer_sum:
+ self.layer_weights = self.add_weight(
+ shape=(self.num_layers,), initializer="ones", trainable=True, name="layer_weights"
+ )
+ self.config = config
+ self.projector = keras.layers.Dense(units=config.classifier_proj_size, name="projector")
+ self.classifier = keras.layers.Dense(units=config.num_labels, activation=None, name="classifier")
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2.feature_extractor.trainable = False
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for layer in self.wav2vec2.layers:
+ layer.trainable = False
+
+ @unpack_inputs
+ def call(
+ self,
+ input_values: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFSequenceClassifierOutput | tuple[tf.Tensor]:
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = tf.stack(hidden_states, axis=1)
+ norm_weights = tf.nn.softmax(self.layer_weights, axis=-1)
+ hidden_states = tf.reduce_sum(hidden_states * tf.reshape(norm_weights, [-1, 1, 1]), axis=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = tf.reduce_mean(hidden_states, axis=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(shape_list(hidden_states)[1], attention_mask)
+ padding_mask_float = tf.cast(padding_mask, hidden_states.dtype)
+ hidden_states = tf.multiply(hidden_states, tf.expand_dims(padding_mask_float, axis=-1))
+ pooled_output = tf.divide(
+ tf.reduce_sum(hidden_states, axis=1), tf.expand_dims(tf.reduce_sum(padding_mask_float, axis=1), axis=1)
+ )
+ logits = self.classifier(pooled_output)
+ loss = None
+ if labels is not None:
+ loss_fn = keras.losses.SparseCategoricalCrossentropy(from_logits=True)
+ loss = loss_fn(tf.reshape(labels, [-1]), tf.reshape(logits, [-1, self.config.num_labels]))
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFSequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "wav2vec2", None) is not None:
+ with tf.name_scope(self.wav2vec2.name):
+ self.wav2vec2.build(None)
+ if getattr(self, "projector", None) is not None:
+ with tf.name_scope(self.projector.name):
+ self.projector.build([None, None, self.config.hidden_size])
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.config.classifier_proj_size])
+
+
+__all__ = ["TFWav2Vec2ForCTC", "TFWav2Vec2Model", "TFWav2Vec2PreTrainedModel", "TFWav2Vec2ForSequenceClassification"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_wav2vec2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_wav2vec2.py
new file mode 100644
index 0000000000000000000000000000000000000000..90760d290e825e374186295eb2de59a5999f61f8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/modeling_wav2vec2.py
@@ -0,0 +1,2358 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Wav2Vec2 model."""
+
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import numpy as np
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_attn_mask_utils import (
+ _prepare_4d_attention_mask,
+ _prepare_4d_attention_mask_for_sdpa,
+)
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ CausalLMOutput,
+ MaskedLMOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+ Wav2Vec2BaseModelOutput,
+ XVectorOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import (
+ ModelOutput,
+ auto_docstring,
+ cached_file,
+ check_torch_load_is_safe,
+ is_peft_available,
+ is_safetensors_available,
+ is_torch_flex_attn_available,
+ logging,
+)
+from .configuration_wav2vec2 import Wav2Vec2Config
+
+
+WAV2VEC2_ADAPTER_PT_FILE = "adapter.{}.bin"
+WAV2VEC2_ADAPTER_SAFE_FILE = "adapter.{}.safetensors"
+
+if is_safetensors_available():
+ from safetensors.torch import load_file as safe_load_file
+
+
+if is_torch_flex_attn_available():
+ from ...integrations.flex_attention import make_flex_block_causal_mask
+
+
+logger = logging.get_logger(__name__)
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`Wav2Vec2ForPreTraining`], with potential hidden states and attentions.
+ """
+)
+class Wav2Vec2ForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ projected_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ codevector_perplexity (`torch.FloatTensor` of shape `(1,)`):
+ The perplexity of the codevector distribution, used to measure the diversity of the codebook.
+ contrastive_loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ The contrastive loss (L_m) as stated in the [official paper](https://huggingface.co/papers/2006.11477).
+ diversity_loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ The diversity loss (L_d) as stated in the [official paper](https://huggingface.co/papers/2006.11477).
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ projected_states: Optional[torch.FloatTensor] = None
+ projected_quantized_states: Optional[torch.FloatTensor] = None
+ codevector_perplexity: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ contrastive_loss: Optional[torch.FloatTensor] = None
+ diversity_loss: Optional[torch.FloatTensor] = None
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+def _sample_negative_indices(
+ features_shape: tuple, num_negatives: int, mask_time_indices: Optional[np.ndarray] = None
+):
+ """
+ Sample `num_negatives` vectors from feature vectors.
+ """
+ batch_size, sequence_length = features_shape
+
+ # generate indices of the positive vectors themselves, repeat them `num_negatives` times
+ sequence_length_range = np.arange(sequence_length)
+
+ # get `num_negatives` random vector indices from the same utterance
+ sampled_negative_indices = np.zeros(shape=(batch_size, sequence_length, num_negatives), dtype=np.int32)
+
+ mask_time_indices = (
+ mask_time_indices.astype(bool) if mask_time_indices is not None else np.ones(features_shape, dtype=bool)
+ )
+
+ for batch_idx in range(batch_size):
+ high = mask_time_indices[batch_idx].sum() - 1
+ mapped_masked_indices = sequence_length_range[mask_time_indices[batch_idx]]
+
+ feature_indices = np.broadcast_to(np.arange(high + 1)[:, None], (high + 1, num_negatives))
+ sampled_indices = np.random.randint(0, high, size=(high + 1, num_negatives))
+ # avoid sampling the same positive vector, but keep the distribution uniform
+ sampled_indices[sampled_indices >= feature_indices] += 1
+
+ # remap to actual indices
+ sampled_negative_indices[batch_idx][mask_time_indices[batch_idx]] = mapped_masked_indices[sampled_indices]
+
+ # correct for batch size
+ sampled_negative_indices[batch_idx] += batch_idx * sequence_length
+
+ return sampled_negative_indices
+
+
+class Wav2Vec2NoLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2LayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+
+ hidden_states = hidden_states.transpose(-2, -1)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states.transpose(-2, -1)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2GroupNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2PositionalConvEmbedding(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=config.num_conv_pos_embeddings,
+ padding=config.num_conv_pos_embeddings // 2,
+ groups=config.num_conv_pos_embedding_groups,
+ )
+
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0):
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+ if hasattr(self.conv, "parametrizations"):
+ weight_g = self.conv.parametrizations.weight.original0
+ weight_v = self.conv.parametrizations.weight.original1
+ else:
+ weight_g = self.conv.weight_g
+ weight_v = self.conv.weight_v
+ deepspeed.zero.register_external_parameter(self, weight_v)
+ deepspeed.zero.register_external_parameter(self, weight_g)
+ else:
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+
+ self.padding = Wav2Vec2SamePadLayer(config.num_conv_pos_embeddings)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.padding(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2SamePadLayer(nn.Module):
+ def __init__(self, num_conv_pos_embeddings):
+ super().__init__()
+ self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0
+
+ def forward(self, hidden_states):
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, :, : -self.num_pad_remove]
+ return hidden_states
+
+
+class Wav2Vec2FeatureEncoder(nn.Module):
+ """Construct the features from raw audio waveform"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ if config.feat_extract_norm == "group":
+ conv_layers = [Wav2Vec2GroupNormConvLayer(config, layer_id=0)] + [
+ Wav2Vec2NoLayerNormConvLayer(config, layer_id=i + 1) for i in range(config.num_feat_extract_layers - 1)
+ ]
+ elif config.feat_extract_norm == "layer":
+ conv_layers = [
+ Wav2Vec2LayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)
+ ]
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']"
+ )
+ self.conv_layers = nn.ModuleList(conv_layers)
+ self.gradient_checkpointing = False
+ self._requires_grad = True
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def forward(self, input_values):
+ hidden_states = input_values[:, None]
+
+ # make sure hidden_states require grad for gradient_checkpointing
+ if self._requires_grad and self.training:
+ hidden_states.requires_grad = True
+
+ for conv_layer in self.conv_layers:
+ hidden_states = conv_layer(hidden_states)
+
+ return hidden_states
+
+
+class Wav2Vec2FeatureExtractor(Wav2Vec2FeatureEncoder):
+ def __init__(self, config):
+ super().__init__(config)
+ warnings.warn(
+ f"The class `{self.__class__.__name__}` has been depreciated "
+ "and will be removed in Transformers v5. "
+ f"Use `{self.__class__.__bases__[0].__name__}` instead.",
+ FutureWarning,
+ )
+
+
+class Wav2Vec2FeatureProjection(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps)
+ self.projection = nn.Linear(config.conv_dim[-1], config.hidden_size)
+ self.dropout = nn.Dropout(config.feat_proj_dropout)
+
+ def forward(self, hidden_states):
+ # non-projected hidden states are needed for quantization
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states, norm_hidden_states
+
+
+# Copied from transformers.models.bart.modeling_bart.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: Optional[float] = None,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ if scaling is None:
+ scaling = query.size(-1) ** -0.5
+
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class Wav2Vec2Attention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ is_causal: bool = False,
+ config: Optional[Wav2Vec2Config] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ self.config = config
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.is_causal = is_causal
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ # TODO: we need a refactor so that the different attention modules can get their specific kwargs
+ # ATM, we have mixed things encoder, decoder, and encoder-decoder attn
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ # determine input shapes
+ bsz, tgt_len = hidden_states.shape[:-1]
+ src_len = key_value_states.shape[1] if is_cross_attention else tgt_len
+
+ q_input_shape = (bsz, tgt_len, -1, self.head_dim)
+ kv_input_shape = (bsz, src_len, -1, self.head_dim)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2)
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ key_states = self.k_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+ value_states = self.v_proj(current_states).view(*kv_input_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.dropout,
+ scaling=self.scaling,
+ output_attentions=output_attentions,
+ head_mask=layer_head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights, None
+
+
+class Wav2Vec2FeedForward(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.intermediate_dropout = nn.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ self.output_dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.output_dropout = nn.Dropout(config.hidden_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2EncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = Wav2Vec2Attention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ config=config,
+ )
+
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = Wav2Vec2FeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, output_attentions=False):
+ attn_residual = hidden_states
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class Wav2Vec2EncoderLayerStableLayerNorm(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.attention = Wav2Vec2Attention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=False,
+ config=config,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = Wav2Vec2FeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ if getattr(config, "adapter_attn_dim", None) is not None:
+ self.adapter_layer = Wav2Vec2AttnAdapterLayer(config)
+ else:
+ self.adapter_layer = None
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ attn_residual = hidden_states
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states, attn_weights, _ = self.attention(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+ hidden_states = hidden_states + self.feed_forward(self.final_layer_norm(hidden_states))
+
+ if self.adapter_layer is not None:
+ hidden_states = hidden_states + self.adapter_layer(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class Wav2Vec2Encoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = Wav2Vec2PositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList([Wav2Vec2EncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ hidden_states,
+ )
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ # Copied from transformers.models.bart.modeling_bart.BartPreTrainedModel._update_full_mask
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+
+class Wav2Vec2EncoderStableLayerNorm(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = Wav2Vec2PositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList(
+ [Wav2Vec2EncoderLayerStableLayerNorm(config) for _ in range(config.num_hidden_layers)]
+ )
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ attention_mask = self._update_full_mask(
+ attention_mask,
+ hidden_states,
+ )
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ # XXX: could optimize this like synced_gpus in generate_utils but not sure if it's worth the code complication
+ layer_outputs = layer(
+ hidden_states, attention_mask=attention_mask, output_attentions=output_attentions
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+ # Copied from transformers.models.bart.modeling_bart.BartPreTrainedModel._update_full_mask
+ def _update_full_mask(
+ self,
+ attention_mask: Union[torch.Tensor, None],
+ inputs_embeds: torch.Tensor,
+ ):
+ if attention_mask is not None:
+ if self.config._attn_implementation == "flash_attention_2":
+ attention_mask = attention_mask if 0 in attention_mask else None
+ elif self.config._attn_implementation == "sdpa":
+ # output_attentions=True & head_mask can not be supported when using SDPA, fall back to
+ # the manual implementation that requires a 4D causal mask in all cases.
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask_for_sdpa(attention_mask, inputs_embeds.dtype)
+ elif self.config._attn_implementation == "flex_attention":
+ if isinstance(attention_mask, torch.Tensor):
+ attention_mask = make_flex_block_causal_mask(attention_mask, is_causal=False)
+ else:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, inputs_embeds.dtype)
+
+ return attention_mask
+
+
+class Wav2Vec2GumbelVectorQuantizer(nn.Module):
+ """
+ Vector quantization using gumbel softmax. See `[CATEGORICAL REPARAMETERIZATION WITH
+ GUMBEL-SOFTMAX](https://huggingface.co/papers/1611.01144) for more information.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.num_groups = config.num_codevector_groups
+ self.num_vars = config.num_codevectors_per_group
+
+ if config.codevector_dim % self.num_groups != 0:
+ raise ValueError(
+ f"`config.codevector_dim {config.codevector_dim} must be divisible "
+ f"by `config.num_codevector_groups` {self.num_groups} for concatenation"
+ )
+
+ # storage for codebook variables (codewords)
+ self.codevectors = nn.Parameter(
+ torch.FloatTensor(1, self.num_groups * self.num_vars, config.codevector_dim // self.num_groups)
+ )
+ self.weight_proj = nn.Linear(config.conv_dim[-1], self.num_groups * self.num_vars)
+
+ # can be decayed for training
+ self.temperature = 2
+
+ @staticmethod
+ def _compute_perplexity(probs, mask=None):
+ if mask is not None:
+ mask_extended = mask.flatten()[:, None, None].expand(probs.shape)
+ probs = torch.where(mask_extended, probs, torch.zeros_like(probs))
+ marginal_probs = probs.sum(dim=0) / mask.sum()
+ else:
+ marginal_probs = probs.mean(dim=0)
+
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states, mask_time_indices=None):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(
+ hidden_states.float(), tau=self.temperature, hard=True
+ ).type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist, mask_time_indices)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs, mask_time_indices)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+class Wav2Vec2Adapter(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+
+ # feature dim might need to be down-projected
+ if config.output_hidden_size != config.hidden_size:
+ self.proj = nn.Linear(config.hidden_size, config.output_hidden_size)
+ self.proj_layer_norm = nn.LayerNorm(config.output_hidden_size)
+ else:
+ self.proj = self.proj_layer_norm = None
+
+ self.layers = nn.ModuleList(Wav2Vec2AdapterLayer(config) for _ in range(config.num_adapter_layers))
+ self.layerdrop = config.layerdrop
+
+ def forward(self, hidden_states):
+ # down project hidden_states if necessary
+ if self.proj is not None and self.proj_layer_norm is not None:
+ hidden_states = self.proj(hidden_states)
+ hidden_states = self.proj_layer_norm(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+
+ for layer in self.layers:
+ layerdrop_prob = np.random.random()
+ if not self.training or (layerdrop_prob > self.layerdrop):
+ hidden_states = layer(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2AdapterLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.output_hidden_size,
+ 2 * config.output_hidden_size,
+ config.adapter_kernel_size,
+ stride=config.adapter_stride,
+ padding=1,
+ )
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = nn.functional.glu(hidden_states, dim=1)
+
+ return hidden_states
+
+
+class Wav2Vec2AttnAdapterLayer(nn.Module):
+ def __init__(self, config):
+ """
+ Implements adapter modules directly with 3D tensor weight as parameters and without using ModuleList to speed
+ up training throughput.
+ """
+ super().__init__()
+ self.input_dim = config.adapter_attn_dim
+ self.hidden_dim = config.hidden_size
+
+ self.norm = nn.LayerNorm(self.hidden_dim)
+ self.linear_1 = nn.Linear(self.hidden_dim, self.input_dim)
+ self.act_fn = nn.ReLU()
+ self.linear_2 = nn.Linear(self.input_dim, self.hidden_dim)
+
+ def forward(self, hidden_states: torch.FloatTensor):
+ hidden_states = self.norm(hidden_states)
+
+ hidden_states = self.linear_1(hidden_states)
+ hidden_states = self.act_fn(hidden_states)
+ hidden_states = self.linear_2(hidden_states)
+
+ return hidden_states
+
+
+@auto_docstring
+class Wav2Vec2PreTrainedModel(PreTrainedModel):
+ config: Wav2Vec2Config
+ base_model_prefix = "wav2vec2"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # Wav2Vec2ForPreTraining last 2 linear layers need standard Linear init.
+ if isinstance(module, Wav2Vec2ForPreTraining):
+ module.project_hid.reset_parameters()
+ module.project_q.reset_parameters()
+ module.project_hid._is_hf_initialized = True
+ module.project_q._is_hf_initialized = True
+ # gumbel softmax requires special init
+ elif isinstance(module, Wav2Vec2GumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, Wav2Vec2PositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, Wav2Vec2FeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[torch.LongTensor, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: torch.LongTensor, add_adapter=None
+ ):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+ output_lengths = output_lengths.to(torch.long)
+
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+ def _get_adapters(self):
+ if self.config.adapter_attn_dim is None:
+ raise ValueError(f"{self.__class__} has no adapter layers. Make sure to define `config.adapter_attn_dim`.")
+
+ adapter_weights = {}
+ for name, module in self.named_modules():
+ if isinstance(module, Wav2Vec2AttnAdapterLayer):
+ for param_name, param in module.named_parameters():
+ adapter_weights[".".join([name, param_name])] = param
+
+ if isinstance(self, Wav2Vec2ForCTC):
+ for name, param in self.lm_head.named_parameters():
+ adapter_weights[".".join(["lm_head", name])] = param
+
+ return adapter_weights
+
+ def init_adapter_layers(self):
+ """
+ (Re-)initialize attention adapter layers and lm head for adapter-only fine-tuning
+ """
+ # init attention adapters
+ for module in self.modules():
+ if isinstance(module, Wav2Vec2AttnAdapterLayer):
+ self._init_weights(module)
+
+ # init lm head
+ if isinstance(self, Wav2Vec2ForCTC):
+ self._init_weights(self.lm_head)
+
+ def load_adapter(self, target_lang: str, force_load=True, **kwargs):
+ r"""
+ Load a language adapter model from a pre-trained adapter model.
+
+ Parameters:
+ target_lang (`str`):
+ Has to be a language id of an existing adapter weight. Adapter weights are stored in the format
+ adapter..safetensors or adapter..bin
+ force_load (`bool`, defaults to `True`):
+ Whether the weights shall be loaded even if `target_lang` matches `self.target_lang`.
+ cache_dir (`Union[str, os.PathLike]`, *optional*):
+ Path to a directory in which a downloaded pretrained model configuration should be cached if the
+ standard cache should not be used.
+ force_download (`bool`, *optional*, defaults to `False`):
+ Whether or not to force the (re-)download of the model weights and configuration files, overriding the
+ cached versions if they exist.
+ resume_download:
+ Deprecated and ignored. All downloads are now resumed by default when possible.
+ Will be removed in v5 of Transformers.
+ proxies (`dict[str, str]`, *optional*):
+ A dictionary of proxy servers to use by protocol or endpoint, e.g., `{'http': 'foo.bar:3128',
+ 'http://hostname': 'foo.bar:4012'}`. The proxies are used on each request.
+ local_files_only(`bool`, *optional*, defaults to `False`):
+ Whether or not to only look at local files (i.e., do not try to download the model).
+ token (`str` or `bool`, *optional*):
+ The token to use as HTTP bearer authorization for remote files. If `True`, or not specified, will use
+ the token generated when running `hf auth login` (stored in `~/.huggingface`).
+ revision (`str`, *optional*, defaults to `"main"`):
+ The specific model version to use. It can be a branch name, a tag name, or a commit id, since we use a
+ git-based system for storing models and other artifacts on huggingface.co, so `revision` can be any
+ identifier allowed by git.
+
+
+
+ To test a pull request you made on the Hub, you can pass `revision="refs/pr/"`.
+
+
+
+ mirror (`str`, *optional*):
+ Mirror source to accelerate downloads in China. If you are from China and have an accessibility
+ problem, you can set this option to resolve it. Note that we do not guarantee the timeliness or safety.
+ Please refer to the mirror site for more information.
+
+
+
+ Activate the special ["offline-mode"](https://huggingface.co/transformers/installation.html#offline-mode) to
+ use this method in a firewalled environment.
+
+
+
+ Examples:
+
+ ```python
+ >>> from transformers import Wav2Vec2ForCTC, AutoProcessor
+
+ >>> ckpt = "facebook/mms-1b-all"
+ >>> processor = AutoProcessor.from_pretrained(ckpt)
+ >>> model = Wav2Vec2ForCTC.from_pretrained(ckpt, target_lang="eng")
+ >>> # set specific language
+ >>> processor.tokenizer.set_target_lang("spa")
+ >>> model.load_adapter("spa")
+ ```
+ """
+ if self.config.adapter_attn_dim is None:
+ raise ValueError(f"Cannot load_adapter for {target_lang} if `config.adapter_attn_dim` is not defined.")
+
+ if target_lang == self.target_lang and not force_load:
+ logger.warning(f"Adapter weights are already set to {target_lang}.")
+ return
+
+ cache_dir = kwargs.pop("cache_dir", None)
+ force_download = kwargs.pop("force_download", False)
+ resume_download = kwargs.pop("resume_download", None)
+ proxies = kwargs.pop("proxies", None)
+ local_files_only = kwargs.pop("local_files_only", False)
+ token = kwargs.pop("token", None)
+ use_auth_token = kwargs.pop("use_auth_token", None)
+ revision = kwargs.pop("revision", None)
+ use_safetensors = kwargs.pop("use_safetensors", None if is_safetensors_available() else False)
+
+ if use_auth_token is not None:
+ warnings.warn(
+ "The `use_auth_token` argument is deprecated and will be removed in v5 of Transformers. Please use `token` instead.",
+ FutureWarning,
+ )
+ if token is not None:
+ raise ValueError(
+ "`token` and `use_auth_token` are both specified. Please set only the argument `token`."
+ )
+ token = use_auth_token
+
+ model_path_or_id = self.config._name_or_path
+ state_dict = None
+
+ # 1. Let's first try loading a safetensors adapter weight
+ if use_safetensors is not False:
+ filepath = WAV2VEC2_ADAPTER_SAFE_FILE.format(target_lang)
+
+ try:
+ weight_path = cached_file(
+ model_path_or_id,
+ filename=filepath,
+ force_download=force_download,
+ resume_download=resume_download,
+ proxies=proxies,
+ local_files_only=local_files_only,
+ token=token,
+ revision=revision,
+ cache_dir=cache_dir,
+ )
+
+ state_dict = safe_load_file(weight_path)
+
+ except OSError:
+ if use_safetensors:
+ # Raise any environment error raise by `cached_file`. It will have a helpful error message adapted
+ # to the original exception.
+ raise
+
+ except Exception:
+ # For any other exception, we throw a generic error.
+ if use_safetensors:
+ raise OSError(
+ f"Can't load the model for '{model_path_or_id}'. If you were trying to load it"
+ " from 'https://huggingface.co/models', make sure you don't have a local directory with the"
+ f" same name. Otherwise, make sure '{model_path_or_id}' is the correct path to a"
+ f" directory containing a file named {filepath}."
+ )
+
+ # 2. If this didn't work let's try loading a PyTorch adapter weight
+ if state_dict is None:
+ filepath = WAV2VEC2_ADAPTER_PT_FILE.format(target_lang)
+
+ try:
+ weight_path = cached_file(
+ model_path_or_id,
+ filename=filepath,
+ force_download=force_download,
+ resume_download=resume_download,
+ proxies=proxies,
+ local_files_only=local_files_only,
+ token=token,
+ revision=revision,
+ cache_dir=cache_dir,
+ )
+
+ check_torch_load_is_safe()
+ state_dict = torch.load(
+ weight_path,
+ map_location="cpu",
+ weights_only=True,
+ )
+
+ except OSError:
+ # Raise any environment error raise by `cached_file`. It will have a helpful error message adapted
+ # to the original exception.
+ raise
+
+ except ValueError:
+ raise
+
+ except Exception:
+ # For any other exception, we throw a generic error.
+ raise OSError(
+ f"Can't load the model for '{model_path_or_id}'. If you were trying to load it"
+ " from 'https://huggingface.co/models', make sure you don't have a local directory with the"
+ f" same name. Otherwise, make sure '{model_path_or_id}' is the correct path to a"
+ f" directory containing a file named {filepath}."
+ )
+
+ adapter_weights = self._get_adapters()
+ unexpected_keys = set(state_dict.keys()) - set(adapter_weights.keys())
+ missing_keys = set(adapter_weights.keys()) - set(state_dict.keys())
+
+ if len(unexpected_keys) > 0:
+ raise ValueError(f"The adapter weights {weight_path} has unexpected keys: {', '.join(unexpected_keys)}.")
+ elif len(missing_keys) > 0:
+ raise ValueError(f"The adapter weights {weight_path} has missing keys: {', '.join(missing_keys)}.")
+
+ # make sure now vocab size is correct
+ target_vocab_size = state_dict["lm_head.weight"].shape[0]
+ if target_vocab_size != self.config.vocab_size:
+ self.lm_head = nn.Linear(
+ self.config.output_hidden_size, target_vocab_size, device=self.device, dtype=self.dtype
+ )
+ self.config.vocab_size = target_vocab_size
+
+ # make sure that adapter weights are put in exactly the same precision and device placement and overwritten adapter weights
+ state_dict = {k: v.to(adapter_weights[k]) for k, v in state_dict.items()}
+ self.load_state_dict(state_dict, strict=False)
+
+ # set target language correctly
+ self.target_lang = target_lang
+
+
+@auto_docstring
+class Wav2Vec2Model(Wav2Vec2PreTrainedModel):
+ def __init__(self, config: Wav2Vec2Config):
+ super().__init__(config)
+ self.config = config
+ self.feature_extractor = Wav2Vec2FeatureEncoder(config)
+ self.feature_projection = Wav2Vec2FeatureProjection(config)
+
+ # model only needs masking vector if mask prob is > 0.0
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ if config.do_stable_layer_norm:
+ self.encoder = Wav2Vec2EncoderStableLayerNorm(config)
+ else:
+ self.encoder = Wav2Vec2Encoder(config)
+
+ self.adapter = Wav2Vec2Adapter(config) if config.add_adapter else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.feature_extractor._freeze_parameters()
+
+ def _mask_hidden_states(
+ self,
+ hidden_states: torch.FloatTensor,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+ elif self.config.mask_time_prob > 0 and self.training:
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool)
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool)
+ mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1)
+ hidden_states[mask_feature_indices] = 0
+
+ return hidden_states
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Wav2Vec2BaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states)
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return Wav2Vec2BaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2 Model with a quantizer and `VQ` head on top.
+ """
+)
+class Wav2Vec2ForPreTraining(Wav2Vec2PreTrainedModel):
+ def __init__(self, config: Wav2Vec2Config):
+ super().__init__(config)
+ self.wav2vec2 = Wav2Vec2Model(config)
+ self.dropout_features = nn.Dropout(config.feat_quantizer_dropout)
+
+ self.quantizer = Wav2Vec2GumbelVectorQuantizer(config)
+
+ self.project_hid = nn.Linear(config.hidden_size, config.proj_codevector_dim)
+ self.project_q = nn.Linear(config.codevector_dim, config.proj_codevector_dim)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def set_gumbel_temperature(self, temperature: int):
+ """
+ Set the Gumbel softmax temperature to a given value. Only necessary for training
+ """
+ self.quantizer.temperature = temperature
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2.feature_extractor._freeze_parameters()
+
+ @staticmethod
+ def compute_contrastive_logits(
+ target_features: torch.FloatTensor,
+ negative_features: torch.FloatTensor,
+ predicted_features: torch.FloatTensor,
+ temperature: int = 0.1,
+ ):
+ """
+ Compute logits for contrastive loss based using cosine similarity as the distance measure between
+ `[positive_feature, negative_features]` and `[predicted_features]`. Additionally, temperature can be applied.
+ """
+ target_features = torch.cat([target_features, negative_features], dim=0)
+
+ logits = torch.cosine_similarity(predicted_features.float(), target_features.float(), dim=-1).type_as(
+ target_features
+ )
+
+ # apply temperature
+ logits = logits / temperature
+ return logits
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.BoolTensor] = None,
+ sampled_negative_indices: Optional[torch.BoolTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Wav2Vec2ForPreTrainingOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ sampled_negative_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_negatives)`, *optional*):
+ Indices indicating which quantized target vectors are used as negative sampled vectors in contrastive loss.
+ Required input for pre-training.
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, Wav2Vec2ForPreTraining
+ >>> from transformers.models.wav2vec2.modeling_wav2vec2 import _compute_mask_indices, _sample_negative_indices
+ >>> from datasets import load_dataset
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+ >>> model = Wav2Vec2ForPreTraining.from_pretrained("facebook/wav2vec2-base")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> input_values = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt").input_values # Batch size 1
+
+ >>> # compute masked indices
+ >>> batch_size, raw_sequence_length = input_values.shape
+ >>> sequence_length = model._get_feat_extract_output_lengths(raw_sequence_length).item()
+ >>> mask_time_indices = _compute_mask_indices(
+ ... shape=(batch_size, sequence_length), mask_prob=0.2, mask_length=2
+ ... )
+ >>> sampled_negative_indices = _sample_negative_indices(
+ ... features_shape=(batch_size, sequence_length),
+ ... num_negatives=model.config.num_negatives,
+ ... mask_time_indices=mask_time_indices,
+ ... )
+ >>> mask_time_indices = torch.tensor(data=mask_time_indices, device=input_values.device, dtype=torch.long)
+ >>> sampled_negative_indices = torch.tensor(
+ ... data=sampled_negative_indices, device=input_values.device, dtype=torch.long
+ ... )
+
+ >>> with torch.no_grad():
+ ... outputs = model(input_values, mask_time_indices=mask_time_indices)
+
+ >>> # compute cosine similarity between predicted (=projected_states) and target (=projected_quantized_states)
+ >>> cosine_sim = torch.cosine_similarity(outputs.projected_states, outputs.projected_quantized_states, dim=-1)
+
+ >>> # show that cosine similarity is much higher than random
+ >>> cosine_sim[mask_time_indices.to(torch.bool)].mean() > 0.5
+ tensor(True)
+
+ >>> # for contrastive loss training model should be put into train mode
+ >>> model = model.train()
+ >>> loss = model(
+ ... input_values, mask_time_indices=mask_time_indices, sampled_negative_indices=sampled_negative_indices
+ ... ).loss
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if mask_time_indices is not None:
+ mask_time_indices = mask_time_indices.to(torch.bool)
+
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ mask_time_indices=mask_time_indices,
+ return_dict=return_dict,
+ )
+
+ # 1. project all transformed features (including masked) to final vq dim
+ transformer_features = self.project_hid(outputs[0])
+
+ # 2. quantize all (unmasked) extracted features and project to final vq dim
+ extract_features = self.dropout_features(outputs[1])
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ quantized_features, codevector_perplexity = self.quantizer(
+ extract_features, mask_time_indices=mask_time_indices
+ )
+
+ quantized_features = quantized_features.to(self.project_q.weight.dtype)
+ quantized_features = self.project_q(quantized_features)
+
+ loss = contrastive_loss = diversity_loss = None
+ if sampled_negative_indices is not None:
+ batch_size, sequence_length, hidden_size = quantized_features.shape
+
+ # for training, we sample negatives
+ # 3. sample K negatives (distractors) quantized states for contrastive loss
+ # if attention_mask is passed, make sure that padded feature vectors cannot be sampled
+ # sample negative quantized vectors BTC => (BxT)C
+ negative_quantized_features = quantized_features.view(-1, hidden_size)[
+ sampled_negative_indices.long().view(-1)
+ ]
+ negative_quantized_features = negative_quantized_features.view(
+ batch_size, sequence_length, -1, hidden_size
+ ).permute(2, 0, 1, 3)
+
+ # 4. compute logits, corresponding to `logs = sim(c_t, [q_t, \sim{q}_t]) / \kappa`
+ # of equation (3) in https://huggingface.co/papers/2006.11477
+ logits = self.compute_contrastive_logits(
+ quantized_features[None, :],
+ negative_quantized_features,
+ transformer_features,
+ self.config.contrastive_logits_temperature,
+ )
+
+ # 5. if a negative vector is identical to the positive (i.e. when codebook utilization is low),
+ # its cosine similarity will be masked
+ neg_is_pos = (quantized_features == negative_quantized_features).all(-1)
+
+ if neg_is_pos.any():
+ logits[1:][neg_is_pos] = float("-inf")
+
+ # 6. compute contrastive loss \mathbf{L}_m = cross_entropy(logs) =
+ # -log(exp(sim(c_t, q_t)/\kappa) / \sum_{\sim{q}} exp(sim(c_t, \sim{q})/\kappa))
+ logits = logits.transpose(0, 2).reshape(-1, logits.size(0))
+ target = ((1 - mask_time_indices.long()) * -100).transpose(0, 1).flatten()
+
+ contrastive_loss = nn.functional.cross_entropy(logits.float(), target, reduction="sum")
+ # 7. compute diversity loss: \mathbf{L}_d
+ num_codevectors = self.config.num_codevectors_per_group * self.config.num_codevector_groups
+ diversity_loss = ((num_codevectors - codevector_perplexity) / num_codevectors) * mask_time_indices.sum()
+
+ # 8. \mathbf{L} = \mathbf{L}_m + \alpha * \mathbf{L}_d
+ loss = contrastive_loss + self.config.diversity_loss_weight * diversity_loss
+
+ if not return_dict:
+ if loss is not None:
+ return (loss, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+ return (transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+
+ return Wav2Vec2ForPreTrainingOutput(
+ loss=loss,
+ projected_states=transformer_features,
+ projected_quantized_states=quantized_features,
+ codevector_perplexity=codevector_perplexity,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ contrastive_loss=contrastive_loss,
+ diversity_loss=diversity_loss,
+ )
+
+
+@auto_docstring
+class Wav2Vec2ForMaskedLM(Wav2Vec2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ warnings.warn(
+ "The class `Wav2Vec2ForMaskedLM` is deprecated. Please use `Wav2Vec2ForCTC` instead.", FutureWarning
+ )
+
+ self.wav2vec2 = Wav2Vec2Model(config)
+ self.dropout = nn.Dropout(config.final_dropout)
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: torch.FloatTensor,
+ attention_mask: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, MaskedLMOutput]:
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.wav2vec2(
+ input_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+ logits = self.lm_head(hidden_states)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return output
+
+ return MaskedLMOutput(logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions)
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2 Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).
+ """
+)
+class Wav2Vec2ForCTC(Wav2Vec2PreTrainedModel):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`Wav2Vec2ForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ self.wav2vec2 = Wav2Vec2Model(config)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.target_lang = target_lang
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that "
+ "does not define the vocabulary size of the language model head. Please "
+ "instantiate the model as follows: `Wav2Vec2ForCTC.from_pretrained(..., vocab_size=vocab_size)`. "
+ "or define `vocab_size` of your model's configuration."
+ )
+ output_hidden_size = (
+ config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size
+ )
+ self.lm_head = nn.Linear(output_hidden_size, config.vocab_size)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def tie_weights(self):
+ """
+ This method overwrites [`~PreTrainedModel.tie_weights`] so that adapter weights can be correctly loaded when
+ passing `target_lang=...` to `from_pretrained(...)`.
+
+ This method is **not** supposed to be called by the user and is prone to be changed in the future.
+ """
+
+ # Note that `tie_weights` is usually used to tie input and output embedding weights. The method is re-purposed to
+ # correctly load adapter layers for Wav2Vec2 so that we do not have to introduce a new API to
+ # [`PreTrainedModel`]. While slightly hacky, Wav2Vec2 never has to tie input and output embeddings, so that it is
+ # ok to repurpose this function here.
+ target_lang = self.target_lang
+
+ if target_lang is not None and getattr(self.config, "adapter_attn_dim", None) is None:
+ raise ValueError(f"Cannot pass `target_lang`: {target_lang} if `config.adapter_attn_dim` is not defined.")
+ elif target_lang is None and getattr(self.config, "adapter_attn_dim", None) is not None:
+ logger.info("By default `target_lang` is set to 'eng'.")
+ elif target_lang is not None:
+ self.load_adapter(target_lang, force_load=True)
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*):
+ Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to
+ the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`.
+ All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None and labels.max() >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+
+ logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # retrieve loss input_lengths from attention_mask
+ attention_mask = (
+ attention_mask if attention_mask is not None else torch.ones_like(input_values, dtype=torch.long)
+ )
+ input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long)
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = labels >= 0
+ target_lengths = labels_mask.sum(-1)
+ flattened_targets = labels.masked_select(labels_mask)
+
+ # ctc_loss doesn't support fp16
+ log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1)
+
+ with torch.backends.cudnn.flags(enabled=False):
+ loss = nn.functional.ctc_loss(
+ log_probs,
+ flattened_targets,
+ input_lengths,
+ target_lengths,
+ blank=self.config.pad_token_id,
+ reduction=self.config.ctc_loss_reduction,
+ zero_infinity=self.config.ctc_zero_infinity,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return CausalLMOutput(
+ loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2 Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like
+ SUPERB Keyword Spotting.
+ """
+)
+class Wav2Vec2ForSequenceClassification(Wav2Vec2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Sequence classification does not support the use of Wav2Vec2 adapters (config.add_adapter=True)"
+ )
+ self.wav2vec2 = Wav2Vec2Model(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size)
+ self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`Wav2Vec2Processor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = hidden_states.mean(dim=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask)
+ expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_padding_mask] = 0.0
+ pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class Wav2Vec2ForAudioFrameClassification(Wav2Vec2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Audio frame classification does not support the use of Wav2Vec2 adapters (config.add_adapter=True)"
+ )
+ self.wav2vec2 = Wav2Vec2Model(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+ self.num_labels = config.num_labels
+
+ self.init_weights()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`Wav2Vec2Processor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), torch.argmax(labels.view(-1, self.num_labels), axis=1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class AMSoftmaxLoss(nn.Module):
+ def __init__(self, input_dim, num_labels, scale=30.0, margin=0.4):
+ super().__init__()
+ self.scale = scale
+ self.margin = margin
+ self.num_labels = num_labels
+ self.weight = nn.Parameter(torch.randn(input_dim, num_labels), requires_grad=True)
+ self.loss = nn.CrossEntropyLoss()
+
+ def forward(self, hidden_states, labels):
+ labels = labels.flatten()
+ weight = nn.functional.normalize(self.weight, dim=0)
+ hidden_states = nn.functional.normalize(hidden_states, dim=1)
+ cos_theta = torch.mm(hidden_states, weight)
+ psi = cos_theta - self.margin
+
+ onehot = nn.functional.one_hot(labels, self.num_labels)
+ logits = self.scale * torch.where(onehot.bool(), psi, cos_theta)
+ loss = self.loss(logits, labels)
+
+ return loss
+
+
+class TDNNLayer(nn.Module):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.tdnn_dim[layer_id - 1] if layer_id > 0 else config.tdnn_dim[layer_id]
+ self.out_conv_dim = config.tdnn_dim[layer_id]
+ self.kernel_size = config.tdnn_kernel[layer_id]
+ self.dilation = config.tdnn_dilation[layer_id]
+
+ self.kernel = nn.Linear(self.in_conv_dim * self.kernel_size, self.out_conv_dim)
+ self.activation = nn.ReLU()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ if is_peft_available():
+ from peft.tuners.lora import LoraLayer
+
+ if is_peft_available():
+ if isinstance(self.kernel, LoraLayer):
+ warnings.warn(
+ "Detected LoRA on TDNNLayer. LoRA weights won't be applied due to optimization. "
+ "You should exclude TDNNLayer from LoRA's target modules.",
+ )
+
+ # for backward compatibility, we keep nn.Linear but call F.conv1d for speed up
+ hidden_states = hidden_states.transpose(1, 2)
+ weight = self.kernel.weight.view(self.out_conv_dim, self.kernel_size, self.in_conv_dim).transpose(1, 2)
+ hidden_states = nn.functional.conv1d(hidden_states, weight, self.kernel.bias, dilation=self.dilation)
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2 Model with an XVector feature extraction head on top for tasks like Speaker Verification.
+ """
+)
+class Wav2Vec2ForXVector(Wav2Vec2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.wav2vec2 = Wav2Vec2Model(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.tdnn_dim[0])
+
+ tdnn_layers = [TDNNLayer(config, i) for i in range(len(config.tdnn_dim))]
+ self.tdnn = nn.ModuleList(tdnn_layers)
+
+ self.feature_extractor = nn.Linear(config.tdnn_dim[-1] * 2, config.xvector_output_dim)
+ self.classifier = nn.Linear(config.xvector_output_dim, config.xvector_output_dim)
+
+ self.objective = AMSoftmaxLoss(config.xvector_output_dim, config.num_labels)
+
+ self.init_weights()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2.parameters():
+ param.requires_grad = False
+
+ def _get_tdnn_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the TDNN layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size in self.config.tdnn_kernel:
+ input_lengths = _conv_out_length(input_lengths, kernel_size, 1)
+
+ return input_lengths
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, XVectorOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`Wav2Vec2Processor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+
+ for tdnn_layer in self.tdnn:
+ hidden_states = tdnn_layer(hidden_states)
+
+ # Statistic Pooling
+ if attention_mask is None:
+ mean_features = hidden_states.mean(dim=1)
+ std_features = hidden_states.std(dim=1)
+ else:
+ feat_extract_output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(dim=1))
+ tdnn_output_lengths = self._get_tdnn_output_lengths(feat_extract_output_lengths)
+ mean_features = []
+ std_features = []
+ for i, length in enumerate(tdnn_output_lengths):
+ mean_features.append(hidden_states[i, :length].mean(dim=0))
+ std_features.append(hidden_states[i, :length].std(dim=0))
+ mean_features = torch.stack(mean_features)
+ std_features = torch.stack(std_features)
+ statistic_pooling = torch.cat([mean_features, std_features], dim=-1)
+
+ output_embeddings = self.feature_extractor(statistic_pooling)
+ logits = self.classifier(output_embeddings)
+
+ loss = None
+ if labels is not None:
+ loss = self.objective(logits, labels)
+
+ if not return_dict:
+ output = (logits, output_embeddings) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XVectorOutput(
+ loss=loss,
+ logits=logits,
+ embeddings=output_embeddings,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "Wav2Vec2ForAudioFrameClassification",
+ "Wav2Vec2ForCTC",
+ "Wav2Vec2ForMaskedLM",
+ "Wav2Vec2ForPreTraining",
+ "Wav2Vec2ForSequenceClassification",
+ "Wav2Vec2ForXVector",
+ "Wav2Vec2Model",
+ "Wav2Vec2PreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/processing_wav2vec2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/processing_wav2vec2.py
new file mode 100644
index 0000000000000000000000000000000000000000..c2da5ac9e398d4fa968ded541d7e19ce5083acb3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/processing_wav2vec2.py
@@ -0,0 +1,192 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Speech processor class for Wav2Vec2
+"""
+
+import warnings
+from contextlib import contextmanager
+from typing import Optional, Union
+
+from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack
+from ...tokenization_utils_base import AudioInput, PreTokenizedInput, TextInput
+from .feature_extraction_wav2vec2 import Wav2Vec2FeatureExtractor
+from .tokenization_wav2vec2 import Wav2Vec2CTCTokenizer
+
+
+class Wav2Vec2ProcessorKwargs(ProcessingKwargs, total=False):
+ _defaults = {}
+
+
+class Wav2Vec2Processor(ProcessorMixin):
+ r"""
+ Constructs a Wav2Vec2 processor which wraps a Wav2Vec2 feature extractor and a Wav2Vec2 CTC tokenizer into a single
+ processor.
+
+ [`Wav2Vec2Processor`] offers all the functionalities of [`Wav2Vec2FeatureExtractor`] and [`PreTrainedTokenizer`].
+ See the docstring of [`~Wav2Vec2Processor.__call__`] and [`~Wav2Vec2Processor.decode`] for more information.
+
+ Args:
+ feature_extractor (`Wav2Vec2FeatureExtractor`):
+ An instance of [`Wav2Vec2FeatureExtractor`]. The feature extractor is a required input.
+ tokenizer ([`PreTrainedTokenizer`]):
+ An instance of [`PreTrainedTokenizer`]. The tokenizer is a required input.
+ """
+
+ feature_extractor_class = "Wav2Vec2FeatureExtractor"
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(self, feature_extractor, tokenizer):
+ super().__init__(feature_extractor, tokenizer)
+ self.current_processor = self.feature_extractor
+ self._in_target_context_manager = False
+
+ @classmethod
+ def from_pretrained(cls, pretrained_model_name_or_path, **kwargs):
+ try:
+ return super().from_pretrained(pretrained_model_name_or_path, **kwargs)
+ except (OSError, ValueError):
+ warnings.warn(
+ f"Loading a tokenizer inside {cls.__name__} from a config that does not"
+ " include a `tokenizer_class` attribute is deprecated and will be "
+ "removed in v5. Please add `'tokenizer_class': 'Wav2Vec2CTCTokenizer'`"
+ " attribute to either your `config.json` or `tokenizer_config.json` "
+ "file to suppress this warning: ",
+ FutureWarning,
+ )
+
+ feature_extractor = Wav2Vec2FeatureExtractor.from_pretrained(pretrained_model_name_or_path, **kwargs)
+ tokenizer = Wav2Vec2CTCTokenizer.from_pretrained(pretrained_model_name_or_path, **kwargs)
+
+ return cls(feature_extractor=feature_extractor, tokenizer=tokenizer)
+
+ def __call__(
+ self,
+ audio: AudioInput = None,
+ text: Optional[Union[str, list[str], TextInput, PreTokenizedInput]] = None,
+ images=None,
+ videos=None,
+ **kwargs: Unpack[Wav2Vec2ProcessorKwargs],
+ ):
+ """
+ This method forwards all arguments to [`Wav2Vec2FeatureExtractor.__call__`] and/or
+ [`PreTrainedTokenizer.__call__`] depending on the input modality and returns their outputs. If both modalities are passed, [`Wav2Vec2FeatureExtractor.__call__`] and [`PreTrainedTokenizer.__call__`] are called.
+
+ Args:
+ audio (`np.ndarray`, `torch.Tensor`, `List[np.ndarray]`, `List[torch.Tensor]`, *optional*):
+ An audio input is passed to [`Wav2Vec2FeatureExtractor.__call__`].
+ text (`str`, `List[str]`, *optional*):
+ A text input is passed to [`PreTrainedTokenizer.__call__`].
+
+
+ Returns:
+ This method returns the results of each `call` method. If both are used, the output is a dictionary containing the results of both.
+ """
+ if "raw_speech" in kwargs:
+ warnings.warn("Using `raw_speech` as a keyword argument is deprecated. Use `audio` instead.")
+ audio = kwargs.pop("raw_speech")
+
+ if audio is None and text is None:
+ raise ValueError("You need to specify either an `audio` or `text` input to process.")
+
+ output_kwargs = self._merge_kwargs(
+ Wav2Vec2ProcessorKwargs,
+ tokenizer_init_kwargs=self.tokenizer.init_kwargs,
+ **kwargs,
+ )
+ # For backward compatibility
+ if self._in_target_context_manager:
+ return self.current_processor(
+ audio,
+ **output_kwargs["audio_kwargs"],
+ **output_kwargs["text_kwargs"],
+ **output_kwargs["common_kwargs"],
+ )
+
+ if audio is not None:
+ inputs = self.feature_extractor(audio, **output_kwargs["audio_kwargs"])
+ if text is not None:
+ encodings = self.tokenizer(text, **output_kwargs["text_kwargs"])
+
+ if text is None:
+ return inputs
+ elif audio is None:
+ return encodings
+ else:
+ inputs["labels"] = encodings["input_ids"]
+ return inputs
+
+ def pad(self, *args, **kwargs):
+ """
+ This method operates on batches of extracted features and/or tokenized text. It forwards all arguments to
+ [`Wav2Vec2FeatureExtractor.pad`] and/or [`PreTrainedTokenizer.pad`] depending on the input modality and returns their outputs. If both modalities are passed, [`Wav2Vec2FeatureExtractor.pad`] and [`PreTrainedTokenizer.pad`] are called.
+
+ Args:
+ input_features:
+ When the first argument is a dictionary containing a batch of tensors, or the `input_features` argument is present, it is passed to [`Wav2Vec2FeatureExtractor.pad`].
+ labels:
+ When the `label` argument is present, it is passed to [`PreTrainedTokenizer.pad`].
+
+ Returns:
+ This method returns the results of each `pad` method. If both are used, the output is a dictionary containing the results of both.
+ """
+ # For backward compatibility
+ if self._in_target_context_manager:
+ return self.current_processor.pad(*args, **kwargs)
+
+ input_features = kwargs.pop("input_features", None)
+ labels = kwargs.pop("labels", None)
+ if len(args) > 0:
+ input_features = args[0]
+ args = args[1:]
+
+ if input_features is not None:
+ input_features = self.feature_extractor.pad(input_features, *args, **kwargs)
+ if labels is not None:
+ labels = self.tokenizer.pad(labels, **kwargs)
+
+ if labels is None:
+ return input_features
+ elif input_features is None:
+ return labels
+ else:
+ input_features["labels"] = labels["input_ids"]
+ return input_features
+
+ @property
+ def model_input_names(self):
+ # The processor doesn't return text ids and the model seems to not need them
+ feature_extractor_input_names = self.feature_extractor.model_input_names
+ return feature_extractor_input_names + ["labels"]
+
+ @contextmanager
+ def as_target_processor(self):
+ """
+ Temporarily sets the tokenizer for processing the input. Useful for encoding the labels when fine-tuning
+ Wav2Vec2.
+ """
+ warnings.warn(
+ "`as_target_processor` is deprecated and will be removed in v5 of Transformers. You can process your "
+ "labels by using the argument `text` of the regular `__call__` method (either in the same call as "
+ "your audio inputs, or in a separate call."
+ )
+ self._in_target_context_manager = True
+ self.current_processor = self.tokenizer
+ yield
+ self.current_processor = self.feature_extractor
+ self._in_target_context_manager = False
+
+
+__all__ = ["Wav2Vec2Processor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/tokenization_wav2vec2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/tokenization_wav2vec2.py
new file mode 100644
index 0000000000000000000000000000000000000000..7fab737064214b7b76a5591a7449bf22935f41e5
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2/tokenization_wav2vec2.py
@@ -0,0 +1,924 @@
+# coding=utf-8
+# Copyright 2021 The Facebook Inc. and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for Wav2Vec2."""
+
+import json
+import os
+import warnings
+from dataclasses import dataclass
+from itertools import groupby
+from typing import TYPE_CHECKING, Optional, Union
+
+import numpy as np
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...tokenization_utils_base import AddedToken, BatchEncoding
+from ...utils import (
+ ModelOutput,
+ PaddingStrategy,
+ TensorType,
+ add_end_docstrings,
+ is_flax_available,
+ is_tf_available,
+ is_torch_available,
+ logging,
+ to_py_obj,
+)
+
+
+logger = logging.get_logger(__name__)
+
+
+if TYPE_CHECKING:
+ if is_torch_available():
+ import torch
+ if is_tf_available():
+ import tensorflow as tf
+ if is_flax_available():
+ import jax.numpy as jnp # noqa: F401
+
+
+VOCAB_FILES_NAMES = {
+ "vocab_file": "vocab.json",
+ "tokenizer_config_file": "tokenizer_config.json",
+}
+
+
+# Wav2Vec2 has no max input length
+
+WAV2VEC2_KWARGS_DOCSTRING = r"""
+ padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `False`):
+ Activates and controls padding. Accepts the following values:
+
+ - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
+ sequence if provided).
+ - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum
+ acceptable input length for the model if that argument is not provided.
+ - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different
+ lengths).
+ max_length (`int`, *optional*):
+ Controls the maximum length to use by one of the truncation/padding parameters.
+
+ If left unset or set to `None`, this will use the predefined model maximum length if a maximum length
+ is required by one of the truncation/padding parameters. If the model has no specific maximum input
+ length (like XLNet) truncation/padding to a maximum length will be deactivated.
+ pad_to_multiple_of (`int`, *optional*):
+ If set will pad the sequence to a multiple of the provided value. This is especially useful to enable
+ the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta).
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ verbose (`bool`, *optional*, defaults to `True`):
+ Whether or not to print more information and warnings.
+"""
+
+ListOfDict = list[dict[str, Union[int, str]]]
+
+
+@dataclass
+class Wav2Vec2CTCTokenizerOutput(ModelOutput):
+ """
+ Output type of [` Wav2Vec2CTCTokenizer`], with transcription.
+
+ Args:
+ text (list of `str` or `str`):
+ Decoded logits in text from. Usually the speech transcription.
+ char_offsets (list of `list[dict[str, Union[int, str]]]` or `list[dict[str, Union[int, str]]]`):
+ Offsets of the decoded characters. In combination with sampling rate and model downsampling rate char
+ offsets can be used to compute time stamps for each character. Total logit score of the beam associated with
+ produced text.
+ word_offsets (list of `list[dict[str, Union[int, str]]]` or `list[dict[str, Union[int, str]]]`):
+ Offsets of the decoded words. In combination with sampling rate and model downsampling rate word offsets
+ can be used to compute time stamps for each word.
+ """
+
+ text: Union[list[str], str]
+ char_offsets: Union[list[ListOfDict], ListOfDict] = None
+ word_offsets: Union[list[ListOfDict], ListOfDict] = None
+
+
+class Wav2Vec2CTCTokenizer(PreTrainedTokenizer):
+ """
+ Constructs a Wav2Vec2CTC tokenizer.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains some of the main methods. Users should refer to
+ the superclass for more information regarding such methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sentence token.
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sentence token.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ word_delimiter_token (`str`, *optional*, defaults to `"|"`):
+ The token used for defining the end of a word.
+ do_lower_case (`bool`, *optional*, defaults to `False`):
+ Whether or not to accept lowercase input and lowercase the output when decoding.
+ target_lang (`str`, *optional*):
+ A target language the tokenizer should set by default. `target_lang` has to be defined for multi-lingual,
+ nested vocabulary such as [facebook/mms-1b-all](https://huggingface.co/facebook/mms-1b-all).
+
+ **kwargs
+ Additional keyword arguments passed along to [`PreTrainedTokenizer`]
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ bos_token="",
+ eos_token=" ",
+ unk_token="",
+ pad_token="",
+ word_delimiter_token="|",
+ replace_word_delimiter_char=" ",
+ do_lower_case=False,
+ target_lang=None,
+ **kwargs,
+ ):
+ self._word_delimiter_token = word_delimiter_token
+
+ self.do_lower_case = do_lower_case
+ self.replace_word_delimiter_char = replace_word_delimiter_char
+ self.target_lang = target_lang
+
+ with open(vocab_file, encoding="utf-8") as vocab_handle:
+ self.vocab = json.load(vocab_handle)
+
+ # if target lang is defined vocab must be a nested dict
+ # with each target lang being one vocabulary
+ if target_lang is not None:
+ self.encoder = self.vocab[target_lang]
+ else:
+ self.encoder = self.vocab
+
+ self.decoder = {v: k for k, v in self.encoder.items()}
+
+ super().__init__(
+ unk_token=unk_token,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ pad_token=pad_token,
+ do_lower_case=do_lower_case,
+ word_delimiter_token=word_delimiter_token,
+ replace_word_delimiter_char=replace_word_delimiter_char,
+ target_lang=target_lang,
+ **kwargs,
+ )
+
+ # make sure that tokens made of several
+ # characters are not split at tokenization
+ for token in self.encoder:
+ if len(token) > 1:
+ self.add_tokens(AddedToken(token, rstrip=True, lstrip=True, normalized=False))
+
+ def set_target_lang(self, target_lang: str):
+ """
+ Set the target language of a nested multi-lingual dictionary
+ """
+ if self.vocab == self.encoder:
+ raise ValueError(f"{self.vocab} is not a multi-lingual, nested tokenizer. Cannot set target language.")
+
+ if target_lang not in self.vocab:
+ raise ValueError(f"{target_lang} does not exist. Choose one of {', '.join(self.vocab.keys())}.")
+
+ self.target_lang = target_lang
+ self.init_kwargs["target_lang"] = target_lang
+ self.encoder = self.vocab[target_lang]
+ self.decoder = {v: k for k, v in self.encoder.items()}
+
+ # make sure that tokens made of several
+ # characters are not split at tokenization
+ for token in self.encoder:
+ if len(token) > 1:
+ self.add_tokens(AddedToken(token, rstrip=True, lstrip=True, normalized=False))
+
+ @property
+ def word_delimiter_token(self) -> str:
+ """
+ `str`: Word delimiter token. Log an error if used while not having been set.
+ """
+ if self._word_delimiter_token is None and self.verbose:
+ logger.error("Using word_delimiter_token, but it is not set yet.")
+ return None
+ return str(self._word_delimiter_token)
+
+ @property
+ def word_delimiter_token_id(self) -> Optional[int]:
+ """
+ `Optional[int]`: Id of the word_delimiter_token in the vocabulary. Returns `None` if the token has not been
+ set.
+ """
+ if self._word_delimiter_token is None:
+ return None
+ return self.convert_tokens_to_ids(self.word_delimiter_token)
+
+ @word_delimiter_token.setter
+ def word_delimiter_token(self, value):
+ self._word_delimiter_token = value
+
+ @word_delimiter_token_id.setter
+ def word_delimiter_token_id(self, value):
+ self._word_delimiter_token = self.convert_tokens_to_ids(value)
+
+ @property
+ def vocab_size(self) -> int:
+ return len(self.decoder)
+
+ def get_vocab(self) -> dict:
+ vocab = dict(self.encoder)
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def _add_tokens(self, new_tokens: Union[list[str], list[AddedToken]], special_tokens: bool = False) -> int:
+ # Overwritten to never strip!
+ to_add = []
+ for token in new_tokens:
+ if isinstance(token, str):
+ to_add.append(AddedToken(token, rstrip=False, lstrip=False, normalized=False))
+ else:
+ to_add.append(token)
+
+ return super()._add_tokens(to_add, special_tokens)
+
+ def _tokenize(self, text, **kwargs):
+ """
+ Converts a string into a sequence of tokens (string), using the tokenizer.
+ """
+ if self.do_lower_case:
+ text = text.upper()
+
+ return list(text.replace(" ", self.word_delimiter_token))
+
+ def _convert_token_to_id(self, token: str) -> int:
+ """Converts a token (str) in an index (integer) using the vocab."""
+ return self.encoder.get(token, self.encoder.get(self.unk_token))
+
+ def _convert_id_to_token(self, index: int) -> str:
+ """Converts an index (integer) in a token (str) using the vocab."""
+ result = self.decoder.get(index, self.unk_token)
+ return result
+
+ def convert_tokens_to_string(
+ self,
+ tokens: list[str],
+ group_tokens: bool = True,
+ spaces_between_special_tokens: bool = False,
+ output_char_offsets: bool = False,
+ output_word_offsets: bool = False,
+ ) -> dict[str, Union[str, float]]:
+ """
+ Converts a connectionist-temporal-classification (CTC) output tokens into a single string.
+ """
+ if len(tokens) == 0:
+ return {"text": "", "char_offsets": [], "word_offsets": []}
+ # group same tokens into non-repeating tokens in CTC style decoding
+ if group_tokens:
+ chars, char_repetitions = zip(*((token, len(list(group_iter))) for token, group_iter in groupby(tokens)))
+ else:
+ chars = tokens
+ char_repetitions = len(tokens) * [1]
+
+ # filter self.pad_token which is used as CTC-blank token
+ processed_chars = list(filter(lambda char: char != self.pad_token, chars))
+
+ # replace delimiter token
+ processed_chars = [
+ self.replace_word_delimiter_char if char == self.word_delimiter_token else char for char in processed_chars
+ ]
+
+ # retrieve offsets
+ char_offsets = word_offsets = None
+ if output_char_offsets or output_word_offsets:
+ char_offsets = self._compute_offsets(char_repetitions, chars, self.pad_token)
+
+ if len(char_offsets) != len(processed_chars):
+ raise ValueError(
+ f"`char_offsets`: {char_offsets} and `processed_tokens`: {processed_chars}"
+ " have to be of the same length, but are: "
+ f"`len(offsets)`: {len(char_offsets)} and `len(processed_tokens)`:"
+ f" {len(processed_chars)}"
+ )
+
+ # set tokens to correct processed token
+ for i, char in enumerate(processed_chars):
+ char_offsets[i]["char"] = char
+
+ # retrieve word offsets from character offsets
+ word_offsets = None
+ if output_word_offsets:
+ word_offsets = self._get_word_offsets(char_offsets, self.replace_word_delimiter_char)
+
+ # don't output chars if not set to True
+ if not output_char_offsets:
+ char_offsets = None
+
+ # join to string
+ join_char = " " if spaces_between_special_tokens else ""
+ string = join_char.join(processed_chars).strip()
+
+ if self.do_lower_case:
+ string = string.lower()
+
+ return {"text": string, "char_offsets": char_offsets, "word_offsets": word_offsets}
+
+ @staticmethod
+ def _compute_offsets(
+ char_repetitions: list[int], chars: list[str], ctc_token: int
+ ) -> list[dict[str, Union[str, int]]]:
+ end_indices = np.asarray(char_repetitions).cumsum()
+ start_indices = np.concatenate(([0], end_indices[:-1]))
+
+ offsets = [
+ {"char": t, "start_offset": s, "end_offset": e} for t, s, e in zip(chars, start_indices, end_indices)
+ ]
+
+ # filter out CTC token
+ offsets = list(filter(lambda offsets: offsets["char"] != ctc_token, offsets))
+ return offsets
+
+ @staticmethod
+ def _get_word_offsets(
+ offsets: dict[str, Union[str, float]], word_delimiter_char: str = " "
+ ) -> dict[str, Union[str, float]]:
+ word_offsets = []
+
+ last_state = "SPACE"
+ word = ""
+ start_offset = 0
+ end_offset = 0
+ for i, offset in enumerate(offsets):
+ char = offset["char"]
+ state = "SPACE" if char == word_delimiter_char else "WORD"
+
+ if state == last_state:
+ # If we are in the same state as before, we simply repeat what we've done before
+ end_offset = offset["end_offset"]
+ word += char
+ else:
+ # Switching state
+ if state == "SPACE":
+ # Finishing a word
+ word_offsets.append({"word": word, "start_offset": start_offset, "end_offset": end_offset})
+ else:
+ # Starting a new word
+ start_offset = offset["start_offset"]
+ end_offset = offset["end_offset"]
+ word = char
+
+ last_state = state
+ if last_state == "WORD":
+ word_offsets.append({"word": word, "start_offset": start_offset, "end_offset": end_offset})
+
+ return word_offsets
+
+ def prepare_for_tokenization(self, text, is_split_into_words=False, **kwargs):
+ if is_split_into_words:
+ text = " " + text
+ return (text, kwargs)
+
+ def _decode(
+ self,
+ token_ids: list[int],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ group_tokens: bool = True,
+ spaces_between_special_tokens: bool = False,
+ output_word_offsets: Optional[bool] = False,
+ output_char_offsets: Optional[bool] = False,
+ ) -> str:
+ """
+ special _decode function is needed for Wav2Vec2Tokenizer because added tokens should be treated exactly the
+ same as tokens of the base vocabulary and therefore the function `convert_tokens_to_string` has to be called on
+ the whole token list and not individually on added tokens
+ """
+ filtered_tokens = self.convert_ids_to_tokens(token_ids, skip_special_tokens=skip_special_tokens)
+
+ result = []
+ for token in filtered_tokens:
+ if skip_special_tokens and (
+ token in self.all_special_ids or (token != self.pad_token and token in self.all_special_tokens)
+ ):
+ continue
+ result.append(token)
+
+ string_output = self.convert_tokens_to_string(
+ result,
+ group_tokens=group_tokens,
+ spaces_between_special_tokens=spaces_between_special_tokens,
+ output_word_offsets=output_word_offsets,
+ output_char_offsets=output_char_offsets,
+ )
+
+ text = string_output["text"]
+
+ clean_up_tokenization_spaces = (
+ clean_up_tokenization_spaces
+ if clean_up_tokenization_spaces is not None
+ else self.clean_up_tokenization_spaces
+ )
+ if clean_up_tokenization_spaces:
+ text = self.clean_up_tokenization(text)
+
+ if output_word_offsets or output_char_offsets:
+ return Wav2Vec2CTCTokenizerOutput(
+ text=text,
+ char_offsets=string_output["char_offsets"],
+ word_offsets=string_output["word_offsets"],
+ )
+ else:
+ return text
+
+ # overwritten from `tokenization_utils_base.py` because tokenizer can output
+ # `ModelOutput` which should not be a list for batched output and
+ # because we need docs for `output_char_offsets` here
+ def batch_decode(
+ self,
+ sequences: Union[list[int], list[list[int]], "np.ndarray", "torch.Tensor", "tf.Tensor"],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ output_char_offsets: bool = False,
+ output_word_offsets: bool = False,
+ **kwargs,
+ ) -> list[str]:
+ """
+ Convert a list of lists of token ids into a list of strings by calling decode.
+
+ Args:
+ sequences (`Union[list[int], list[list[int]], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens in the decoding.
+ clean_up_tokenization_spaces (`bool`, *optional*):
+ Whether or not to clean up the tokenization spaces.
+ output_char_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output character offsets. Character offsets can be used in combination with the
+ sampling rate and model downsampling rate to compute the time-stamps of transcribed characters.
+
+
+
+ Please take a look at the Example of [`~Wav2Vec2CTCTokenizer.decode`] to better understand how to make
+ use of `output_char_offsets`. [`~Wav2Vec2CTCTokenizer.batch_decode`] works the same way with batched
+ output.
+
+
+
+ output_word_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output word offsets. Word offsets can be used in combination with the sampling rate
+ and model downsampling rate to compute the time-stamps of transcribed words.
+
+
+
+ Please take a look at the Example of [`~Wav2Vec2CTCTokenizer.decode`] to better understand how to make
+ use of `output_word_offsets`. [`~Wav2Vec2CTCTokenizer.batch_decode`] works the same way with batched
+ output.
+
+
+
+ kwargs (additional keyword arguments, *optional*):
+ Will be passed to the underlying model specific decode method.
+
+ Returns:
+ `list[str]` or [`~models.wav2vec2.tokenization_wav2vec2.Wav2Vec2CTCTokenizerOutput`]: The list of decoded
+ sentences. Will be a [`~models.wav2vec2.tokenization_wav2vec2.Wav2Vec2CTCTokenizerOutput`] when
+ `output_char_offsets == True` or `output_word_offsets == True`.
+ """
+ batch_decoded = [
+ self.decode(
+ seq,
+ skip_special_tokens=skip_special_tokens,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ output_char_offsets=output_char_offsets,
+ output_word_offsets=output_word_offsets,
+ **kwargs,
+ )
+ for seq in sequences
+ ]
+ if output_char_offsets or output_word_offsets:
+ # transform list of dicts to dict of lists
+ return Wav2Vec2CTCTokenizerOutput({k: [d[k] for d in batch_decoded] for k in batch_decoded[0]})
+
+ return batch_decoded
+
+ # overwritten from `tokenization_utils_base.py` because we need docs for `output_char_offsets`
+ # and `output_word_offsets` here
+ def decode(
+ self,
+ token_ids: Union[int, list[int], "np.ndarray", "torch.Tensor", "tf.Tensor"],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ output_char_offsets: bool = False,
+ output_word_offsets: bool = False,
+ **kwargs,
+ ) -> str:
+ """
+ Converts a sequence of ids in a string, using the tokenizer and vocabulary with options to remove special
+ tokens and clean up tokenization spaces.
+
+ Similar to doing `self.convert_tokens_to_string(self.convert_ids_to_tokens(token_ids))`.
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens in the decoding.
+ clean_up_tokenization_spaces (`bool`, *optional*):
+ Whether or not to clean up the tokenization spaces.
+ output_char_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output character offsets. Character offsets can be used in combination with the
+ sampling rate and model downsampling rate to compute the time-stamps of transcribed characters.
+
+
+
+ Please take a look at the example below to better understand how to make use of `output_char_offsets`.
+
+
+
+ output_word_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output word offsets. Word offsets can be used in combination with the sampling rate
+ and model downsampling rate to compute the time-stamps of transcribed words.
+
+
+
+ Please take a look at the example below to better understand how to make use of `output_word_offsets`.
+
+
+
+ kwargs (additional keyword arguments, *optional*):
+ Will be passed to the underlying model specific decode method.
+
+ Returns:
+ `str` or [`~models.wav2vec2.tokenization_wav2vec2.Wav2Vec2CTCTokenizerOutput`]: The list of decoded
+ sentences. Will be a [`~models.wav2vec2.tokenization_wav2vec2.Wav2Vec2CTCTokenizerOutput`] when
+ `output_char_offsets == True` or `output_word_offsets == True`.
+
+ Example:
+
+ ```python
+ >>> # Let's see how to retrieve time steps for a model
+ >>> from transformers import AutoTokenizer, AutoFeatureExtractor, AutoModelForCTC
+ >>> from datasets import load_dataset
+ >>> import datasets
+ >>> import torch
+
+ >>> # import model, feature extractor, tokenizer
+ >>> model = AutoModelForCTC.from_pretrained("facebook/wav2vec2-base-960h")
+ >>> tokenizer = AutoTokenizer.from_pretrained("facebook/wav2vec2-base-960h")
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base-960h")
+
+ >>> # load first sample of English common_voice
+ >>> dataset = load_dataset("mozilla-foundation/common_voice_11_0", "en", split="train", streaming=True)
+ >>> dataset = dataset.cast_column("audio", datasets.Audio(sampling_rate=16_000))
+ >>> dataset_iter = iter(dataset)
+ >>> sample = next(dataset_iter)
+
+ >>> # forward sample through model to get greedily predicted transcription ids
+ >>> input_values = feature_extractor(sample["audio"]["array"], return_tensors="pt").input_values
+ >>> logits = model(input_values).logits[0]
+ >>> pred_ids = torch.argmax(logits, axis=-1)
+
+ >>> # retrieve word stamps (analogous commands for `output_char_offsets`)
+ >>> outputs = tokenizer.decode(pred_ids, output_word_offsets=True)
+ >>> # compute `time_offset` in seconds as product of downsampling ratio and sampling_rate
+ >>> time_offset = model.config.inputs_to_logits_ratio / feature_extractor.sampling_rate
+
+ >>> word_offsets = [
+ ... {
+ ... "word": d["word"],
+ ... "start_time": round(d["start_offset"] * time_offset, 2),
+ ... "end_time": round(d["end_offset"] * time_offset, 2),
+ ... }
+ ... for d in outputs.word_offsets
+ ... ]
+ >>> # compare word offsets with audio `en_train_0/common_voice_en_19121553.mp3` online on the dataset viewer:
+ >>> # https://huggingface.co/datasets/mozilla-foundation/common_voice_11_0/viewer/en
+ >>> word_offsets[:3]
+ [{'word': 'THE', 'start_time': 0.7, 'end_time': 0.78}, {'word': 'TRICK', 'start_time': 0.88, 'end_time': 1.08}, {'word': 'APPEARS', 'start_time': 1.2, 'end_time': 1.64}]
+ ```"""
+ # Convert inputs to python lists
+ token_ids = to_py_obj(token_ids)
+
+ return self._decode(
+ token_ids=token_ids,
+ skip_special_tokens=skip_special_tokens,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ output_char_offsets=output_char_offsets,
+ output_word_offsets=output_word_offsets,
+ **kwargs,
+ )
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ with open(vocab_file, "w", encoding="utf-8") as f:
+ f.write(json.dumps(self.vocab, indent=2, sort_keys=True, ensure_ascii=False) + "\n")
+
+ return (vocab_file,)
+
+
+class Wav2Vec2Tokenizer(PreTrainedTokenizer):
+ """
+ Constructs a Wav2Vec2 tokenizer.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains some of the main methods. Users should refer to
+ the superclass for more information regarding such methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sentence token.
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sentence token.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ word_delimiter_token (`str`, *optional*, defaults to `"|"`):
+ The token used for defining the end of a word.
+ do_lower_case (`bool`, *optional*, defaults to `False`):
+ Whether or not to lowercase the output when decoding.
+ do_normalize (`bool`, *optional*, defaults to `False`):
+ Whether or not to zero-mean unit-variance normalize the input. Normalizing can help to significantly
+ improve the performance for some models, *e.g.*,
+ [wav2vec2-lv60](https://huggingface.co/models?search=lv60).
+ return_attention_mask (`bool`, *optional*, defaults to `False`):
+ Whether or not [`~Wav2Vec2Tokenizer.__call__`] should return `attention_mask`.
+
+
+
+ Wav2Vec2 models that have set `config.feat_extract_norm == "group"`, such as
+ [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base-960h), have **not** been trained using
+ `attention_mask`. For such models, `input_values` should simply be padded with 0 and no `attention_mask`
+ should be passed.
+
+ For Wav2Vec2 models that have set `config.feat_extract_norm == "layer"`, such as
+ [wav2vec2-lv60](https://huggingface.co/facebook/wav2vec2-large-960h-lv60-self), `attention_mask` should be
+ passed for batched inference.
+
+
+
+ **kwargs
+ Additional keyword arguments passed along to [`PreTrainedTokenizer`]
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ pretrained_vocab_files_map = {
+ "vocab_file": {
+ "facebook/wav2vec2-base-960h": "https://huggingface.co/facebook/wav2vec2-base-960h/resolve/main/vocab.json"
+ },
+ "tokenizer_config_file": {
+ "facebook/wav2vec2-base-960h": (
+ "https://huggingface.co/facebook/wav2vec2-base-960h/resolve/main/tokenizer.json"
+ ),
+ },
+ }
+ model_input_names = ["input_values", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ bos_token="",
+ eos_token=" ",
+ unk_token="",
+ pad_token="",
+ word_delimiter_token="|",
+ do_lower_case=False,
+ do_normalize=False,
+ return_attention_mask=False,
+ **kwargs,
+ ):
+ warnings.warn(
+ "The class `Wav2Vec2Tokenizer` is deprecated and will be removed in version 5 of Transformers. Please use"
+ " `Wav2Vec2Processor` or `Wav2Vec2CTCTokenizer` instead.",
+ FutureWarning,
+ )
+
+ self._word_delimiter_token = word_delimiter_token
+
+ self.do_lower_case = do_lower_case
+ self.return_attention_mask = return_attention_mask
+ self.do_normalize = do_normalize
+
+ with open(vocab_file, encoding="utf-8") as vocab_handle:
+ self.encoder = json.load(vocab_handle)
+
+ self.decoder = {v: k for k, v in self.encoder.items()}
+
+ super().__init__(
+ unk_token=unk_token,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ pad_token=pad_token,
+ do_lower_case=do_lower_case,
+ do_normalize=do_normalize,
+ return_attention_mask=return_attention_mask,
+ word_delimiter_token=word_delimiter_token,
+ **kwargs,
+ )
+
+ @property
+ def word_delimiter_token(self) -> str:
+ """
+ `str`: Padding token. Log an error if used while not having been set.
+ """
+ if self._word_delimiter_token is None and self.verbose:
+ logger.error("Using word_delimiter_token, but it is not set yet.")
+ return None
+ return str(self._word_delimiter_token)
+
+ @property
+ def word_delimiter_token_id(self) -> Optional[int]:
+ """
+ `Optional[int]`: Id of the word_delimiter_token in the vocabulary. Returns `None` if the token has not been
+ set.
+ """
+ if self._word_delimiter_token is None:
+ return None
+ return self.convert_tokens_to_ids(self.word_delimiter_token)
+
+ @word_delimiter_token.setter
+ def word_delimiter_token(self, value):
+ self._word_delimiter_token = value
+
+ @word_delimiter_token_id.setter
+ def word_delimiter_token_id(self, value):
+ self._word_delimiter_token = self.convert_tokens_to_ids(value)
+
+ @add_end_docstrings(WAV2VEC2_KWARGS_DOCSTRING)
+ def __call__(
+ self,
+ raw_speech: Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]],
+ padding: Union[bool, str, PaddingStrategy] = False,
+ max_length: Optional[int] = None,
+ pad_to_multiple_of: Optional[int] = None,
+ padding_side: Optional[str] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ verbose: bool = True,
+ **kwargs,
+ ) -> BatchEncoding:
+ """
+ Main method to tokenize and prepare for the model one or several sequence(s) or one or several pair(s) of
+ sequences.
+
+ Args:
+ raw_speech (`np.ndarray`, `list[float]`, `list[np.ndarray]`, `list[list[float]]`):
+ The sequence or batch of sequences to be padded. Each sequence can be a numpy array, a list of float
+ values, a list of numpy array or a list of list of float values. Must be mono channel audio, not
+ stereo, i.e. single float per timestep.
+
+ padding_side (`str`, *optional*):
+ The side on which the model should have padding applied. Should be selected between ['right', 'left'].
+ Default value is picked from the class attribute of the same name.
+ """
+
+ is_batched_numpy = isinstance(raw_speech, np.ndarray) and len(raw_speech.shape) > 1
+ if is_batched_numpy and len(raw_speech.shape) > 2:
+ raise ValueError(f"Only mono-channel audio is supported for input to {self}")
+ is_batched = is_batched_numpy or (
+ isinstance(raw_speech, (list, tuple)) and (isinstance(raw_speech[0], (np.ndarray, tuple, list)))
+ )
+
+ # make sure input is in list format
+ if is_batched and not isinstance(raw_speech[0], np.ndarray):
+ raw_speech = [np.asarray(speech) for speech in raw_speech]
+ elif not is_batched and not isinstance(raw_speech, np.ndarray):
+ raw_speech = np.asarray(raw_speech)
+
+ # always return batch
+ if not is_batched:
+ raw_speech = [raw_speech]
+
+ # zero-mean and unit-variance normalization
+ if self.do_normalize:
+ raw_speech = [(x - np.mean(x)) / np.sqrt(np.var(x) + 1e-5) for x in raw_speech]
+
+ # convert into correct format for padding
+ encoded_inputs = BatchEncoding({"input_values": raw_speech})
+
+ padded_inputs = self.pad(
+ encoded_inputs,
+ padding=padding,
+ max_length=max_length,
+ pad_to_multiple_of=pad_to_multiple_of,
+ padding_side=padding_side,
+ return_attention_mask=self.return_attention_mask,
+ return_tensors=return_tensors,
+ verbose=verbose,
+ )
+
+ return padded_inputs
+
+ @property
+ def vocab_size(self) -> int:
+ return len(self.decoder)
+
+ def get_vocab(self) -> dict:
+ return dict(self.encoder, **self.added_tokens_encoder)
+
+ def _convert_token_to_id(self, token: str) -> int:
+ """Converts a token (str) in an index (integer) using the vocab."""
+ return self.encoder.get(token, self.encoder.get(self.unk_token))
+
+ def _convert_id_to_token(self, index: int) -> str:
+ """Converts an index (integer) in a token (str) using the vocab."""
+ result = self.decoder.get(index, self.unk_token)
+ return result
+
+ def convert_tokens_to_string(self, tokens: list[str]) -> str:
+ """
+ Converts a connectionist-temporal-classification (CTC) output tokens into a single string.
+ """
+ # group same tokens into non-repeating tokens in CTC style decoding
+ grouped_tokens = [token_group[0] for token_group in groupby(tokens)]
+
+ # filter self.pad_token which is used as CTC-blank token
+ filtered_tokens = list(filter(lambda token: token != self.pad_token, grouped_tokens))
+
+ # replace delimiter token
+ string = "".join([" " if token == self.word_delimiter_token else token for token in filtered_tokens]).strip()
+
+ if self.do_lower_case:
+ string = string.lower()
+
+ return string
+
+ def _decode(
+ self,
+ token_ids: list[int],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ **kwargs,
+ ) -> str:
+ """
+ special _decode function is needed for Wav2Vec2Tokenizer because added tokens should be treated exactly the
+ same as tokens of the base vocabulary and therefore the function `convert_tokens_to_string` has to be called on
+ the whole token list and not individually on added tokens
+ """
+ filtered_tokens = self.convert_ids_to_tokens(token_ids, skip_special_tokens=skip_special_tokens)
+
+ result = []
+ for token in filtered_tokens:
+ if skip_special_tokens and (
+ token in self.all_special_ids or (token != self.pad_token and token in self.all_special_tokens)
+ ):
+ continue
+ result.append(token)
+
+ text = self.convert_tokens_to_string(result)
+
+ clean_up_tokenization_spaces = (
+ clean_up_tokenization_spaces
+ if clean_up_tokenization_spaces is not None
+ else self.clean_up_tokenization_spaces
+ )
+ if clean_up_tokenization_spaces:
+ clean_text = self.clean_up_tokenization(text)
+ return clean_text
+ else:
+ return text
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ with open(vocab_file, "w", encoding="utf-8") as f:
+ f.write(json.dumps(self.encoder, indent=2, sort_keys=True, ensure_ascii=False) + "\n")
+
+ return (vocab_file,)
+
+
+__all__ = ["Wav2Vec2CTCTokenizer", "Wav2Vec2Tokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..7520263c51bcd3b63747ee0a55e1baff24a777f9
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_wav2vec2_bert import *
+ from .modeling_wav2vec2_bert import *
+ from .processing_wav2vec2_bert import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/configuration_wav2vec2_bert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/configuration_wav2vec2_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..2462976cfbbeb908fa3e8bbd04722f6aa066a7f8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/configuration_wav2vec2_bert.py
@@ -0,0 +1,313 @@
+# coding=utf-8
+# Copyright 2024 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Wav2Vec2Bert model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Wav2Vec2BertConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Wav2Vec2BertModel`]. It is used to
+ instantiate an Wav2Vec2Bert model according to the specified arguments, defining the model architecture.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the Wav2Vec2Bert
+ [facebook/wav2vec2-bert-rel-pos-large](https://huggingface.co/facebook/wav2vec2-bert-rel-pos-large)
+ architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*):
+ Vocabulary size of the Wav2Vec2Bert model. Defines the number of different tokens that can be
+ represented by the `inputs_ids` passed when calling [`Wav2Vec2BertModel`]. Vocabulary size of the
+ model. Defines the different tokens that can be represented by the *inputs_ids* passed to the forward
+ method of [`Wav2Vec2BertModel`].
+ hidden_size (`int`, *optional*, defaults to 1024):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 24):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 4096):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ feature_projection_input_dim (`int`, *optional*, defaults to 160):
+ Input dimension of this model, i.e the dimension after processing input audios with [`SeamlessM4TFeatureExtractor`] or [`Wav2Vec2BertProcessor`].
+ hidden_act (`str` or `function`, *optional*, defaults to `"swish"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"`, `"swish"` and `"gelu_new"` are supported.
+ hidden_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ activation_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for activations inside the fully connected layer.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ feat_proj_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the feature projection.
+ final_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the final projection layer of [`Wav2Vec2BertForCTC`].
+ layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) for more
+ details.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the layer normalization layers.
+ apply_spec_augment (`bool`, *optional*, defaults to `True`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see
+ [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking
+ procedure generates `mask_time_prob*len(time_axis)/mask_time_length ``independent masks over the axis. If
+ reasoning from the probability of each feature vector to be chosen as the start of the vector span to be
+ masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the
+ actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2):
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if `mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks`.
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The
+ masking procedure generates `mask_feature_prob*len(feature_axis)/mask_time_length` independent masks over
+ the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector
+ span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap
+ may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is
+ True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ mask_feature_min_masks (`int`, *optional*, defaults to 0):
+ The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time
+ step, irrespectively of `mask_feature_prob`. Only relevant if
+ `mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks`.
+ ctc_loss_reduction (`str`, *optional*, defaults to `"sum"`):
+ Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an
+ instance of [`Wav2Vec2BertForCTC`].
+ ctc_zero_infinity (`bool`, *optional*, defaults to `False`):
+ Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly
+ occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance
+ of [`Wav2Vec2BertForCTC`].
+ use_weighted_layer_sum (`bool`, *optional*, defaults to `False`):
+ Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an
+ instance of [`Wav2Vec2BertForSequenceClassification`].
+ classifier_proj_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the projection before token mean-pooling for classification.
+ tdnn_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 1500)`):
+ A tuple of integers defining the number of output channels of each 1D convolutional layer in the *TDNN*
+ module of the *XVector* model. The length of *tdnn_dim* defines the number of *TDNN* layers.
+ tdnn_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 3, 3, 1, 1)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the *TDNN* module of the
+ *XVector* model. The length of *tdnn_kernel* has to match the length of *tdnn_dim*.
+ tdnn_dilation (`tuple[int]` or `list[int]`, *optional*, defaults to `(1, 2, 3, 1, 1)`):
+ A tuple of integers defining the dilation factor of each 1D convolutional layer in *TDNN* module of the
+ *XVector* model. The length of *tdnn_dilation* has to match the length of *tdnn_dim*.
+ xvector_output_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of the *XVector* embedding vectors.
+ pad_token_id (`int`, *optional*, defaults to 0): The id of the _beginning-of-stream_ token.
+ bos_token_id (`int`, *optional*, defaults to 1): The id of the _padding_ token.
+ eos_token_id (`int`, *optional*, defaults to 2): The id of the _end-of-stream_ token.
+ add_adapter (`bool`, *optional*, defaults to `False`):
+ Whether a convolutional attention network should be stacked on top of the Wav2Vec2Bert Encoder. Can be very
+ useful for warm-starting Wav2Vec2Bert for SpeechEncoderDecoder models.
+ adapter_kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ adapter_stride (`int`, *optional*, defaults to 2):
+ Stride of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ num_adapter_layers (`int`, *optional*, defaults to 1):
+ Number of convolutional layers that should be used in the adapter network. Only relevant if `add_adapter is
+ True`.
+ adapter_act (`str` or `function`, *optional*, defaults to `"relu"`):
+ The non-linear activation function (function or string) in the adapter layers. If string, `"gelu"`,
+ `"relu"`, `"selu"`, `"swish"` and `"gelu_new"` are supported.
+ use_intermediate_ffn_before_adapter (`bool`, *optional*, defaults to `False`):
+ Whether an intermediate feed-forward block should be stacked on top of the Wav2Vec2Bert Encoder and before the adapter network.
+ Only relevant if `add_adapter is True`.
+ output_hidden_size (`int`, *optional*):
+ Dimensionality of the encoder output layer. If not defined, this defaults to *hidden-size*. Only relevant
+ if `add_adapter is True`.
+ position_embeddings_type (`str`, *optional*, defaults to `"relative_key"`):
+ Can be specified to :
+ - `rotary`, for rotary position embeddings.
+ - `relative`, for relative position embeddings.
+ - `relative_key`, for relative position embeddings as defined by Shaw in [Self-Attention
+ with Relative Position Representations (Shaw et al.)](https://huggingface.co/papers/1803.02155).
+ If left to `None`, no relative position embeddings is applied.
+ rotary_embedding_base (`int`, *optional*, defaults to 10000):
+ If `"rotary"` position embeddings are used, defines the size of the embedding base.
+ max_source_positions (`int`, *optional*, defaults to 5000):
+ if `"relative"` position embeddings are used, defines the maximum source input positions.
+ left_max_position_embeddings (`int`, *optional*, defaults to 64):
+ If `"relative_key"` (aka Shaw) position embeddings are used, defines the left clipping value for relative positions.
+ right_max_position_embeddings (`int`, *optional*, defaults to 8):
+ If `"relative_key"` (aka Shaw) position embeddings are used, defines the right clipping value for relative positions.
+ conv_depthwise_kernel_size (`int`, *optional*, defaults to 31):
+ Kernel size of convolutional depthwise 1D layer in Conformer blocks.
+ conformer_conv_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all convolutional layers in Conformer blocks.
+ Example:
+
+ ```python
+ >>> from transformers import Wav2Vec2BertConfig, Wav2Vec2BertModel
+
+ >>> # Initializing a Wav2Vec2Bert facebook/wav2vec2-bert-rel-pos-large style configuration
+ >>> configuration = Wav2Vec2BertConfig()
+
+ >>> # Initializing a model (with random weights) from the facebook/wav2vec2-bert-rel-pos-large style configuration
+ >>> model = Wav2Vec2BertModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "wav2vec2-bert"
+
+ def __init__(
+ self,
+ vocab_size=None,
+ hidden_size=1024,
+ num_hidden_layers=24,
+ num_attention_heads=16,
+ intermediate_size=4096,
+ feature_projection_input_dim=160,
+ hidden_act="swish",
+ hidden_dropout=0.0,
+ activation_dropout=0.0,
+ attention_dropout=0.0,
+ feat_proj_dropout=0.0,
+ final_dropout=0.1,
+ layerdrop=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ apply_spec_augment=True,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ mask_feature_min_masks=0,
+ ctc_loss_reduction="sum",
+ ctc_zero_infinity=False,
+ use_weighted_layer_sum=False,
+ classifier_proj_size=768,
+ tdnn_dim=(512, 512, 512, 512, 1500),
+ tdnn_kernel=(5, 3, 3, 1, 1),
+ tdnn_dilation=(1, 2, 3, 1, 1),
+ xvector_output_dim=512,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ add_adapter=False,
+ adapter_kernel_size=3,
+ adapter_stride=2,
+ num_adapter_layers=1,
+ adapter_act="relu",
+ use_intermediate_ffn_before_adapter=False,
+ output_hidden_size=None,
+ position_embeddings_type="relative_key",
+ rotary_embedding_base=10000,
+ max_source_positions=5000,
+ left_max_position_embeddings=64,
+ right_max_position_embeddings=8,
+ conv_depthwise_kernel_size=31,
+ conformer_conv_dropout=0.1,
+ **kwargs,
+ ):
+ super().__init__(**kwargs, pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id)
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.num_attention_heads = num_attention_heads
+ self.feature_projection_input_dim = feature_projection_input_dim
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.feat_proj_dropout = feat_proj_dropout
+ self.final_dropout = final_dropout
+ self.layerdrop = layerdrop
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.vocab_size = vocab_size
+ self.use_weighted_layer_sum = use_weighted_layer_sum
+ self.max_source_positions = max_source_positions
+
+ if position_embeddings_type is not None and position_embeddings_type not in [
+ "rotary",
+ "relative",
+ "relative_key",
+ ]:
+ raise ValueError(
+ """
+ `position_embeddings_type` is not valid. It must be one of the following values:
+ `["rotary", "relative", "relative_key"]` or left as `None`.
+ """
+ )
+ self.position_embeddings_type = position_embeddings_type
+ self.rotary_embedding_base = rotary_embedding_base
+ self.left_max_position_embeddings = left_max_position_embeddings
+ self.right_max_position_embeddings = right_max_position_embeddings
+
+ # Conformer-block related
+ self.conv_depthwise_kernel_size = conv_depthwise_kernel_size
+ self.conformer_conv_dropout = conformer_conv_dropout
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+ self.mask_feature_min_masks = mask_feature_min_masks
+
+ # ctc loss
+ self.ctc_loss_reduction = ctc_loss_reduction
+ self.ctc_zero_infinity = ctc_zero_infinity
+
+ # adapter
+ self.add_adapter = add_adapter
+ self.adapter_kernel_size = adapter_kernel_size
+ self.adapter_stride = adapter_stride
+ self.num_adapter_layers = num_adapter_layers
+ self.adapter_act = adapter_act
+ self.output_hidden_size = output_hidden_size if output_hidden_size is not None else hidden_size
+ if use_intermediate_ffn_before_adapter and not add_adapter:
+ raise ValueError("`use_intermediate_ffn_before_adapter` is `True` but `add_adapter` is `False`.")
+ self.use_intermediate_ffn_before_adapter = use_intermediate_ffn_before_adapter
+
+ # SequenceClassification-specific parameter. Feel free to ignore for other classes.
+ self.classifier_proj_size = classifier_proj_size
+
+ # XVector-specific parameters. Feel free to ignore for other classes.
+ self.tdnn_dim = list(tdnn_dim)
+ self.tdnn_kernel = list(tdnn_kernel)
+ self.tdnn_dilation = list(tdnn_dilation)
+ self.xvector_output_dim = xvector_output_dim
+
+ @property
+ def inputs_to_logits_ratio(self):
+ ratio = self.feature_projection_input_dim * 2
+ if self.add_adapter:
+ ratio = ratio * (self.adapter_stride**self.num_adapter_layers)
+ return ratio
+
+
+__all__ = ["Wav2Vec2BertConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/modeling_wav2vec2_bert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/modeling_wav2vec2_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..e8f67e2d73cde40d0d61608bb49298b2cf7e6bad
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/modeling_wav2vec2_bert.py
@@ -0,0 +1,1517 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/wav2vec2_bert/modular_wav2vec2_bert.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_wav2vec2_bert.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+import math
+import warnings
+from typing import Optional, Union
+
+import numpy as np
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ CausalLMOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+ Wav2Vec2BaseModelOutput,
+ XVectorOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, is_peft_available
+from .configuration_wav2vec2_bert import Wav2Vec2BertConfig
+
+
+class Wav2Vec2BertRotaryPositionalEmbedding(nn.Module):
+ """Rotary positional embedding
+ Reference : https://blog.eleuther.ai/rotary-embeddings/ Paper: https://huggingface.co/papers/2104.09864
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ dim = config.hidden_size // config.num_attention_heads
+ base = config.rotary_embedding_base
+
+ inv_freq = 1.0 / (base ** (torch.arange(0, dim, 2, dtype=torch.int64).float() / dim))
+ # Ignore copy
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.cached_sequence_length = None
+ self.cached_rotary_positional_embedding = None
+
+ def forward(self, hidden_states):
+ sequence_length = hidden_states.shape[1]
+
+ if sequence_length == self.cached_sequence_length and self.cached_rotary_positional_embedding is not None:
+ return self.cached_rotary_positional_embedding
+
+ self.cached_sequence_length = sequence_length
+ # Embeddings are computed in the dtype of the inv_freq constant
+ time_stamps = torch.arange(sequence_length).type_as(self.inv_freq)
+ freqs = torch.einsum("i,j->ij", time_stamps, self.inv_freq)
+ embeddings = torch.cat((freqs, freqs), dim=-1)
+
+ cos_embeddings = embeddings.cos()[:, None, None, :]
+ sin_embeddings = embeddings.sin()[:, None, None, :]
+ # Computed embeddings are cast to the dtype of the hidden state inputs
+ self.cached_rotary_positional_embedding = torch.stack([cos_embeddings, sin_embeddings]).type_as(hidden_states)
+ return self.cached_rotary_positional_embedding
+
+
+class Wav2Vec2BertRelPositionalEmbedding(nn.Module):
+ """Relative positional encoding module."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.max_len = config.max_source_positions
+ self.d_model = config.hidden_size
+ self.pe = None
+ self.extend_pe(torch.tensor(0.0).expand(1, self.max_len))
+
+ def extend_pe(self, x):
+ # Reset the positional encodings
+ if self.pe is not None:
+ # self.pe contains both positive and negative parts
+ # the length of self.pe is 2 * input_len - 1
+ if self.pe.size(1) >= x.size(1) * 2 - 1:
+ if self.pe.dtype != x.dtype or self.pe.device != x.device:
+ self.pe = self.pe.to(dtype=x.dtype, device=x.device)
+ return
+ # Suppose `i` is the position of query vector and `j` is the
+ # position of key vector. We use positive relative positions when keys
+ # are to the left (i>j) and negative relative positions otherwise (i (batch, 2*channel, dim)
+ hidden_states = self.pointwise_conv1(hidden_states)
+ # => (batch, channel, dim)
+ hidden_states = self.glu(hidden_states)
+
+ # Pad the sequence entirely on the left because of causal convolution.
+ hidden_states = torch.nn.functional.pad(hidden_states, (self.depthwise_conv.kernel_size[0] - 1, 0))
+
+ # 1D Depthwise Conv
+ hidden_states = self.depthwise_conv(hidden_states)
+
+ hidden_states = self.depthwise_layer_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
+
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = self.pointwise_conv2(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2BertSelfAttention(nn.Module):
+ """Construct an Wav2Vec2BertSelfAttention object.
+ Can be enhanced with rotary or relative position embeddings.
+ """
+
+ def __init__(self, config, is_adapter_attention=False):
+ super().__init__()
+ hidden_size = config.hidden_size if not is_adapter_attention else config.output_hidden_size
+
+ self.head_size = hidden_size // config.num_attention_heads
+ self.num_heads = config.num_attention_heads
+ self.position_embeddings_type = config.position_embeddings_type if not is_adapter_attention else None
+
+ self.linear_q = nn.Linear(hidden_size, hidden_size)
+ self.linear_k = nn.Linear(hidden_size, hidden_size)
+ self.linear_v = nn.Linear(hidden_size, hidden_size)
+ self.linear_out = nn.Linear(hidden_size, hidden_size)
+
+ self.dropout = nn.Dropout(p=config.attention_dropout)
+
+ if self.position_embeddings_type == "relative":
+ # linear transformation for positional encoding
+ self.linear_pos = nn.Linear(hidden_size, hidden_size, bias=False)
+ # these two learnable bias are used in matrix c and matrix d
+ # as described in https://huggingface.co/papers/1901.02860 Section 3.3
+ self.pos_bias_u = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+ self.pos_bias_v = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+
+ if self.position_embeddings_type == "relative_key":
+ self.left_max_position_embeddings = config.left_max_position_embeddings
+ self.right_max_position_embeddings = config.right_max_position_embeddings
+ num_positions = self.left_max_position_embeddings + self.right_max_position_embeddings + 1
+ self.distance_embedding = nn.Embedding(num_positions, self.head_size)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ # self-attention mechanism
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ # make sure query/key states can be != value states
+ query_key_states = hidden_states
+ value_states = hidden_states
+
+ if self.position_embeddings_type == "rotary":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type == 'rotary'"
+ )
+ query_key_states = self._apply_rotary_embedding(query_key_states, relative_position_embeddings)
+
+ # project query_key_states and value_states
+ query = self.linear_q(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ key = self.linear_k(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ value = self.linear_v(value_states).view(batch_size, -1, self.num_heads, self.head_size)
+
+ # => (batch, head, time1, d_k)
+ query = query.transpose(1, 2)
+ key = key.transpose(1, 2)
+ value = value.transpose(1, 2)
+
+ if self.position_embeddings_type == "relative":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type =="
+ " 'relative'"
+ )
+ # apply relative_position_embeddings to qk scores
+ # as proposed in Transformer_XL: https://huggingface.co/papers/1901.02860
+ scores = self._apply_relative_embeddings(
+ query=query, key=key, relative_position_embeddings=relative_position_embeddings
+ )
+ else:
+ scores = torch.matmul(query, key.transpose(-2, -1)) / math.sqrt(self.head_size)
+
+ if self.position_embeddings_type == "relative_key":
+ query_length, key_length = query.shape[2], key.shape[2]
+
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_r - position_ids_l
+ distance = torch.clamp(distance, -self.left_max_position_embeddings, self.right_max_position_embeddings)
+
+ positional_embedding = self.distance_embedding(distance + self.left_max_position_embeddings)
+ positional_embedding = positional_embedding.to(dtype=query.dtype) # fp16 compatibility
+
+ relative_position_attn_weights = torch.einsum("bhld,lrd->bhlr", query, positional_embedding)
+ scores = scores + (relative_position_attn_weights / math.sqrt(self.head_size))
+
+ # apply attention_mask if necessary
+ if attention_mask is not None:
+ scores = scores + attention_mask
+
+ # => (batch, head, time1, time2)
+ probs = torch.softmax(scores, dim=-1)
+ probs = self.dropout(probs)
+
+ # => (batch, head, time1, d_k)
+ hidden_states = torch.matmul(probs, value)
+
+ # => (batch, time1, hidden_size)
+ hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, self.num_heads * self.head_size)
+ hidden_states = self.linear_out(hidden_states)
+
+ return hidden_states, probs
+
+ def _apply_rotary_embedding(self, hidden_states, relative_position_embeddings):
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+ hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads, self.head_size)
+
+ cos = relative_position_embeddings[0, :sequence_length, ...]
+ sin = relative_position_embeddings[1, :sequence_length, ...]
+
+ # rotate hidden_states with rotary embeddings
+ hidden_states = hidden_states.transpose(0, 1)
+ rotated_states_begin = hidden_states[..., : self.head_size // 2]
+ rotated_states_end = hidden_states[..., self.head_size // 2 :]
+ rotated_states = torch.cat((-rotated_states_end, rotated_states_begin), dim=rotated_states_begin.ndim - 1)
+ hidden_states = (hidden_states * cos) + (rotated_states * sin)
+ hidden_states = hidden_states.transpose(0, 1)
+
+ hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads * self.head_size)
+
+ return hidden_states
+
+ def _apply_relative_embeddings(self, query, key, relative_position_embeddings):
+ # 1. project positional embeddings
+ # => (batch, head, 2*time1-1, d_k)
+ proj_relative_position_embeddings = self.linear_pos(relative_position_embeddings)
+ proj_relative_position_embeddings = proj_relative_position_embeddings.view(
+ relative_position_embeddings.size(0), -1, self.num_heads, self.head_size
+ )
+ proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(1, 2)
+ proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(2, 3)
+
+ # 2. Add bias to query
+ # => (batch, head, time1, d_k)
+ query = query.transpose(1, 2)
+ q_with_bias_u = (query + self.pos_bias_u).transpose(1, 2)
+ q_with_bias_v = (query + self.pos_bias_v).transpose(1, 2)
+
+ # 3. attention score: first compute matrix a and matrix c
+ # as described in https://huggingface.co/papers/1901.02860 Section 3.3
+ # => (batch, head, time1, time2)
+ scores_ac = torch.matmul(q_with_bias_u, key.transpose(-2, -1))
+
+ # 4. then compute matrix b and matrix d
+ # => (batch, head, time1, 2*time1-1)
+ scores_bd = torch.matmul(q_with_bias_v, proj_relative_position_embeddings)
+
+ # 5. shift matrix b and matrix d
+ zero_pad = torch.zeros((*scores_bd.size()[:3], 1), device=scores_bd.device, dtype=scores_bd.dtype)
+ scores_bd_padded = torch.cat([zero_pad, scores_bd], dim=-1)
+ scores_bd_padded_shape = scores_bd.size()[:2] + (scores_bd.shape[3] + 1, scores_bd.shape[2])
+ scores_bd_padded = scores_bd_padded.view(*scores_bd_padded_shape)
+ scores_bd = scores_bd_padded[:, :, 1:].view_as(scores_bd)
+ scores_bd = scores_bd[:, :, :, : scores_bd.size(-1) // 2 + 1]
+
+ # 6. sum matrices
+ # => (batch, head, time1, time2)
+ scores = (scores_ac + scores_bd) / math.sqrt(self.head_size)
+
+ return scores
+
+
+class Wav2Vec2BertEncoderLayer(GradientCheckpointingLayer):
+ """Conformer block based on https://huggingface.co/papers/2005.08100."""
+
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.hidden_size
+ dropout = config.attention_dropout
+
+ # Feed-forward 1
+ self.ffn1_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.ffn1 = Wav2Vec2BertFeedForward(config)
+
+ # Self-Attention
+ self.self_attn_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.self_attn_dropout = nn.Dropout(dropout)
+ self.self_attn = Wav2Vec2BertSelfAttention(config)
+
+ # Conformer Convolution
+ self.conv_module = Wav2Vec2BertConvolutionModule(config)
+
+ # Feed-forward 2
+ self.ffn2_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.ffn2 = Wav2Vec2BertFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ conv_attention_mask: Optional[torch.Tensor] = None,
+ ):
+ hidden_states = hidden_states
+
+ # 1. Feed-Forward 1 layer
+ residual = hidden_states
+ hidden_states = self.ffn1_layer_norm(hidden_states)
+ hidden_states = self.ffn1(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ residual = hidden_states
+
+ # 2. Self-Attention layer
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weigts = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.self_attn_dropout(hidden_states)
+ hidden_states = hidden_states + residual
+
+ # 3. Convolutional Layer
+ residual = hidden_states
+ hidden_states = self.conv_module(hidden_states, attention_mask=conv_attention_mask)
+ hidden_states = residual + hidden_states
+
+ # 4. Feed-Forward 2 Layer
+ residual = hidden_states
+ hidden_states = self.ffn2_layer_norm(hidden_states)
+ hidden_states = self.ffn2(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ return hidden_states, attn_weigts
+
+
+class Wav2Vec2BertEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+
+ if config.position_embeddings_type == "relative":
+ self.embed_positions = Wav2Vec2BertRelPositionalEmbedding(config)
+ elif config.position_embeddings_type == "rotary":
+ self.embed_positions = Wav2Vec2BertRotaryPositionalEmbedding(config)
+ else:
+ self.embed_positions = None
+
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList([Wav2Vec2BertEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ conv_attention_mask = attention_mask
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ hidden_states = hidden_states.masked_fill(~attention_mask.bool().unsqueeze(-1), 0.0)
+
+ # extend attention_mask
+ attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype)
+ attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min
+ attention_mask = attention_mask.expand(
+ attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1]
+ )
+
+ hidden_states = self.dropout(hidden_states)
+
+ if self.embed_positions is not None:
+ relative_position_embeddings = self.embed_positions(hidden_states)
+ else:
+ relative_position_embeddings = None
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ conv_attention_mask=conv_attention_mask,
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class Wav2Vec2BertAdapter(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ # feature dim might need to be down-projected
+ if config.output_hidden_size != config.hidden_size:
+ self.proj = nn.Linear(config.hidden_size, config.output_hidden_size)
+ self.proj_layer_norm = nn.LayerNorm(config.output_hidden_size, eps=config.layer_norm_eps)
+ else:
+ self.proj = self.proj_layer_norm = None
+ self.layers = nn.ModuleList(Wav2Vec2BertAdapterLayer(config) for _ in range(config.num_adapter_layers))
+ self.layerdrop = config.layerdrop
+
+ self.kernel_size = config.adapter_kernel_size
+ self.stride = config.adapter_stride
+
+ def _compute_sub_sample_lengths_from_attention_mask(self, seq_lens):
+ if seq_lens is None:
+ return seq_lens
+ pad = self.kernel_size // 2
+ seq_lens = ((seq_lens + 2 * pad - self.kernel_size) / self.stride) + 1
+ return seq_lens.floor()
+
+ def forward(self, hidden_states, attention_mask=None):
+ # down project hidden_states if necessary
+ if self.proj is not None and self.proj_layer_norm is not None:
+ hidden_states = self.proj(hidden_states)
+ hidden_states = self.proj_layer_norm(hidden_states)
+
+ sub_sampled_lengths = None
+ if attention_mask is not None:
+ sub_sampled_lengths = (attention_mask.size(1) - (1 - attention_mask.int()).sum(1)).to(hidden_states.device)
+
+ for layer in self.layers:
+ layerdrop_prob = torch.rand([])
+ sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(sub_sampled_lengths)
+ if not self.training or (layerdrop_prob > self.layerdrop):
+ hidden_states = layer(
+ hidden_states, attention_mask=attention_mask, sub_sampled_lengths=sub_sampled_lengths
+ )
+
+ return hidden_states
+
+
+# Copied from transformers.models.seamless_m4t_v2.modeling_seamless_m4t_v2._compute_new_attention_mask
+def _compute_new_attention_mask(hidden_states: torch.Tensor, seq_lens: torch.Tensor):
+ """
+ Computes an attention mask of the form `(batch, seq_len)` with an attention for each element in the batch that
+ stops at the corresponding element in `seq_lens`.
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch, seq_len, *)`):
+ The sequences to mask, where `*` is any number of sequence-specific dimensions including none.
+ seq_lens (`torch.Tensor` of shape `(batch)`:
+ Each element represents the length of the sequence at the same index in `hidden_states`
+ Returns:
+ `torch.FloatTensor`: The float attention mask of shape `(batch, seq_len)`
+ """
+ batch_size, mask_seq_len = hidden_states.shape[:2]
+
+ indices = torch.arange(mask_seq_len, device=seq_lens.device).expand(batch_size, -1)
+
+ bool_mask = indices >= seq_lens.unsqueeze(1).expand(-1, mask_seq_len)
+
+ mask = hidden_states.new_ones((batch_size, mask_seq_len))
+
+ mask = mask.masked_fill(bool_mask, 0)
+
+ return mask
+
+
+class Wav2Vec2BertAdapterLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.output_hidden_size
+ dropout = config.conformer_conv_dropout
+
+ self.kernel_size = config.adapter_kernel_size
+ self.stride = config.adapter_stride
+
+ # 1. residual convolution
+ self.residual_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.residual_conv = nn.Conv1d(
+ embed_dim,
+ 2 * embed_dim,
+ self.kernel_size,
+ stride=self.stride,
+ padding=self.stride // 2,
+ )
+ self.activation = nn.GLU(dim=1)
+
+ # Self-Attention
+ self.self_attn_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.self_attn_conv = nn.Conv1d(
+ embed_dim,
+ 2 * embed_dim,
+ self.kernel_size,
+ stride=self.stride,
+ padding=self.stride // 2,
+ )
+ self.self_attn = Wav2Vec2BertSelfAttention(config, is_adapter_attention=True)
+ self.self_attn_dropout = nn.Dropout(dropout)
+
+ # Feed-forward
+ self.ffn_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.ffn = Wav2Vec2BertFeedForward(config, act_fn=config.adapter_act, hidden_size=embed_dim)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ sub_sampled_lengths: Optional[torch.Tensor] = None,
+ ):
+ residual = self.residual_layer_norm(hidden_states)
+
+ # Apply pooling to the residual to match the sequence length of the
+ # multi-head attention output.
+ # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len)
+ residual = residual.transpose(1, 2)
+ residual = self.residual_conv(residual)
+ residual = self.activation(residual)
+ # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim)
+ residual = residual.transpose(1, 2)
+
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ # Apply pooling before feeding to the multihead-attention layer.
+ # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len)
+ hidden_states = hidden_states.transpose(1, 2)
+ hidden_states = self.self_attn_conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim)
+ hidden_states = hidden_states.transpose(1, 2)
+
+ if attention_mask is not None:
+ attention_mask = _compute_new_attention_mask(hidden_states=hidden_states, seq_lens=sub_sampled_lengths)
+ attention_mask = _prepare_4d_attention_mask(
+ attention_mask,
+ hidden_states.dtype,
+ )
+
+ # The rest of the computation is identical to a vanilla Transformer
+ # encoder layer.
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.self_attn_dropout(hidden_states)
+ hidden_states = hidden_states + residual
+
+ residual = hidden_states
+
+ hidden_states = self.ffn_layer_norm(hidden_states)
+ hidden_states = self.ffn(hidden_states) + residual
+
+ return hidden_states
+
+
+@auto_docstring
+class Wav2Vec2BertPreTrainedModel(PreTrainedModel):
+ config: Wav2Vec2BertConfig
+ base_model_prefix = "wav2vec2_bert"
+ main_input_name = "input_features"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, Wav2Vec2BertSelfAttention):
+ if hasattr(module, "pos_bias_u"):
+ nn.init.xavier_uniform_(module.pos_bias_u)
+ if hasattr(module, "pos_bias_v"):
+ nn.init.xavier_uniform_(module.pos_bias_v)
+ elif isinstance(module, Wav2Vec2BertFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+ elif isinstance(module, Wav2Vec2BertModel):
+ if hasattr(module, "masked_spec_embed"):
+ module.masked_spec_embed.data.uniform_()
+ elif isinstance(
+ module,
+ (Wav2Vec2BertForSequenceClassification, Wav2Vec2BertForAudioFrameClassification, Wav2Vec2BertForXVector),
+ ):
+ if hasattr(module, "layer_weights"):
+ module.layer_weights.data.fill_(1.0 / (self.config.num_hidden_layers + 1))
+ elif isinstance(module, AMSoftmaxLoss): # noqa: F821
+ module.weight.data.normal_()
+
+ # Ignore copy
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[torch.LongTensor, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride, padding):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length + 2 * padding - kernel_size, stride, rounding_mode="floor") + 1
+
+ if add_adapter:
+ padding = self.config.adapter_kernel_size // 2
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(
+ input_lengths, self.config.adapter_kernel_size, self.config.adapter_stride, padding
+ )
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: torch.LongTensor, add_adapter=None
+ ):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+ output_lengths = output_lengths.to(torch.long)
+
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+Wav2Vec2BertBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+@auto_docstring
+class Wav2Vec2BertModel(Wav2Vec2BertPreTrainedModel):
+ def __init__(self, config: Wav2Vec2BertConfig):
+ super().__init__(config)
+ self.config = config
+ self.feature_projection = Wav2Vec2BertFeatureProjection(config)
+
+ # model only needs masking vector if mask prob is > 0.0
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ self.encoder = Wav2Vec2BertEncoder(config)
+
+ self.adapter = Wav2Vec2BertAdapter(config) if config.add_adapter else None
+
+ self.intermediate_ffn = None
+ if config.use_intermediate_ffn_before_adapter:
+ self.intermediate_ffn = Wav2Vec2BertFeedForward(config, act_fn="relu")
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _mask_hidden_states(
+ self,
+ hidden_states: torch.FloatTensor,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+ elif self.config.mask_time_prob > 0 and self.training:
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool)
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool)
+ mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1)
+ hidden_states[mask_feature_indices] = 0
+
+ return hidden_states
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Wav2Vec2BertBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ hidden_states, extract_features = self.feature_projection(input_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.intermediate_ffn:
+ expanded_hidden_states = self.intermediate_ffn(hidden_states)
+ hidden_states = hidden_states + 0.5 * expanded_hidden_states
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states, attention_mask=attention_mask)
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return Wav2Vec2BertBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2Bert Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).
+ """
+)
+class Wav2Vec2BertForCTC(Wav2Vec2BertPreTrainedModel):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`UniSpeechSatForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ self.wav2vec2_bert = Wav2Vec2BertModel(config)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.target_lang = target_lang
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that "
+ "does not define the vocabulary size of the language model head. Please "
+ "instantiate the model as follows: `Wav2Vec2BertForCTC.from_pretrained(..., vocab_size=vocab_size)`. "
+ "or define `vocab_size` of your model's configuration."
+ )
+ output_hidden_size = (
+ config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size
+ )
+ self.lm_head = nn.Linear(output_hidden_size, config.vocab_size)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*):
+ Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to
+ the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`.
+ All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ if labels is not None and labels.max() >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+
+ logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # retrieve loss input_lengths from attention_mask
+ attention_mask = (
+ attention_mask
+ if attention_mask is not None
+ else torch.ones(input_features.shape[:2], device=input_features.device, dtype=torch.long)
+ )
+ input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum([-1])).to(torch.long)
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = labels >= 0
+ target_lengths = labels_mask.sum(-1)
+ flattened_targets = labels.masked_select(labels_mask)
+
+ # ctc_loss doesn't support fp16
+ log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1)
+
+ with torch.backends.cudnn.flags(enabled=False):
+ loss = nn.functional.ctc_loss(
+ log_probs,
+ flattened_targets,
+ input_lengths,
+ target_lengths,
+ blank=self.config.pad_token_id,
+ reduction=self.config.ctc_loss_reduction,
+ zero_infinity=self.config.ctc_zero_infinity,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return CausalLMOutput(
+ loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2Bert Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like
+ SUPERB Keyword Spotting.
+ """
+)
+class Wav2Vec2BertForSequenceClassification(Wav2Vec2BertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Sequence classification does not support the use of Wav2Vec2Bert adapters (config.add_adapter=True)"
+ )
+ self.wav2vec2_bert = Wav2Vec2BertModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size)
+ self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2_bert.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = hidden_states.mean(dim=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask)
+ expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_padding_mask] = 0.0
+ pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class Wav2Vec2BertForAudioFrameClassification(Wav2Vec2BertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Audio frame classification does not support the use of Wav2Vec2Bert adapters (config.add_adapter=True)"
+ )
+ self.wav2vec2_bert = Wav2Vec2BertModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+ self.num_labels = config.num_labels
+
+ self.init_weights()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2_bert.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), torch.argmax(labels.view(-1, self.num_labels), axis=1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class AMSoftmaxLoss(nn.Module):
+ def __init__(self, input_dim, num_labels, scale=30.0, margin=0.4):
+ super().__init__()
+ self.scale = scale
+ self.margin = margin
+ self.num_labels = num_labels
+ self.weight = nn.Parameter(torch.randn(input_dim, num_labels), requires_grad=True)
+ self.loss = nn.CrossEntropyLoss()
+
+ def forward(self, hidden_states, labels):
+ labels = labels.flatten()
+ weight = nn.functional.normalize(self.weight, dim=0)
+ hidden_states = nn.functional.normalize(hidden_states, dim=1)
+ cos_theta = torch.mm(hidden_states, weight)
+ psi = cos_theta - self.margin
+
+ onehot = nn.functional.one_hot(labels, self.num_labels)
+ logits = self.scale * torch.where(onehot.bool(), psi, cos_theta)
+ loss = self.loss(logits, labels)
+
+ return loss
+
+
+class TDNNLayer(nn.Module):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.tdnn_dim[layer_id - 1] if layer_id > 0 else config.tdnn_dim[layer_id]
+ self.out_conv_dim = config.tdnn_dim[layer_id]
+ self.kernel_size = config.tdnn_kernel[layer_id]
+ self.dilation = config.tdnn_dilation[layer_id]
+
+ self.kernel = nn.Linear(self.in_conv_dim * self.kernel_size, self.out_conv_dim)
+ self.activation = nn.ReLU()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ if is_peft_available():
+ from peft.tuners.lora import LoraLayer
+
+ if is_peft_available():
+ if isinstance(self.kernel, LoraLayer):
+ warnings.warn(
+ "Detected LoRA on TDNNLayer. LoRA weights won't be applied due to optimization. "
+ "You should exclude TDNNLayer from LoRA's target modules.",
+ )
+
+ # for backward compatibility, we keep nn.Linear but call F.conv1d for speed up
+ hidden_states = hidden_states.transpose(1, 2)
+ weight = self.kernel.weight.view(self.out_conv_dim, self.kernel_size, self.in_conv_dim).transpose(1, 2)
+ hidden_states = nn.functional.conv1d(hidden_states, weight, self.kernel.bias, dilation=self.dilation)
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2Bert Model with an XVector feature extraction head on top for tasks like Speaker Verification.
+ """
+)
+class Wav2Vec2BertForXVector(Wav2Vec2BertPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.wav2vec2_bert = Wav2Vec2BertModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.tdnn_dim[0])
+
+ tdnn_layers = [TDNNLayer(config, i) for i in range(len(config.tdnn_dim))]
+ self.tdnn = nn.ModuleList(tdnn_layers)
+
+ self.feature_extractor = nn.Linear(config.tdnn_dim[-1] * 2, config.xvector_output_dim)
+ self.classifier = nn.Linear(config.xvector_output_dim, config.xvector_output_dim)
+
+ self.objective = AMSoftmaxLoss(config.xvector_output_dim, config.num_labels)
+
+ self.init_weights()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2_bert.parameters():
+ param.requires_grad = False
+
+ def _get_tdnn_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the TDNN layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size in self.config.tdnn_kernel:
+ input_lengths = _conv_out_length(input_lengths, kernel_size, 1)
+
+ return input_lengths
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, XVectorOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+
+ for tdnn_layer in self.tdnn:
+ hidden_states = tdnn_layer(hidden_states)
+
+ # Statistic Pooling
+ if attention_mask is None:
+ mean_features = hidden_states.mean(dim=1)
+ std_features = hidden_states.std(dim=1)
+ else:
+ feat_extract_output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(dim=1))
+ tdnn_output_lengths = self._get_tdnn_output_lengths(feat_extract_output_lengths)
+ mean_features = []
+ std_features = []
+ for i, length in enumerate(tdnn_output_lengths):
+ mean_features.append(hidden_states[i, :length].mean(dim=0))
+ std_features.append(hidden_states[i, :length].std(dim=0))
+ mean_features = torch.stack(mean_features)
+ std_features = torch.stack(std_features)
+ statistic_pooling = torch.cat([mean_features, std_features], dim=-1)
+
+ output_embeddings = self.feature_extractor(statistic_pooling)
+ logits = self.classifier(output_embeddings)
+
+ loss = None
+ if labels is not None:
+ loss = self.objective(logits, labels)
+
+ if not return_dict:
+ output = (logits, output_embeddings) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XVectorOutput(
+ loss=loss,
+ logits=logits,
+ embeddings=output_embeddings,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "Wav2Vec2BertForAudioFrameClassification",
+ "Wav2Vec2BertForCTC",
+ "Wav2Vec2BertForSequenceClassification",
+ "Wav2Vec2BertForXVector",
+ "Wav2Vec2BertModel",
+ "Wav2Vec2BertPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/modular_wav2vec2_bert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/modular_wav2vec2_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..b9b60a6bd3ad839d9e01fdacdf52adbcd0b7edb4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/modular_wav2vec2_bert.py
@@ -0,0 +1,1070 @@
+import math
+from typing import Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ CausalLMOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+ Wav2Vec2BaseModelOutput,
+ XVectorOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ..wav2vec2.modeling_wav2vec2 import Wav2Vec2FeedForward, Wav2Vec2ForSequenceClassification, Wav2Vec2Model
+from ..wav2vec2_conformer.modeling_wav2vec2_conformer import (
+ Wav2Vec2ConformerForAudioFrameClassification,
+ Wav2Vec2ConformerForCTC,
+ Wav2Vec2ConformerForXVector,
+ Wav2Vec2ConformerRelPositionalEmbedding,
+ Wav2Vec2ConformerRotaryPositionalEmbedding,
+ Wav2Vec2ConformerSelfAttention,
+)
+from .configuration_wav2vec2_bert import Wav2Vec2BertConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+# Copied from transformers.models.seamless_m4t_v2.modeling_seamless_m4t_v2._compute_new_attention_mask
+def _compute_new_attention_mask(hidden_states: torch.Tensor, seq_lens: torch.Tensor):
+ """
+ Computes an attention mask of the form `(batch, seq_len)` with an attention for each element in the batch that
+ stops at the corresponding element in `seq_lens`.
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch, seq_len, *)`):
+ The sequences to mask, where `*` is any number of sequence-specific dimensions including none.
+ seq_lens (`torch.Tensor` of shape `(batch)`:
+ Each element represents the length of the sequence at the same index in `hidden_states`
+ Returns:
+ `torch.FloatTensor`: The float attention mask of shape `(batch, seq_len)`
+ """
+ batch_size, mask_seq_len = hidden_states.shape[:2]
+
+ indices = torch.arange(mask_seq_len, device=seq_lens.device).expand(batch_size, -1)
+
+ bool_mask = indices >= seq_lens.unsqueeze(1).expand(-1, mask_seq_len)
+
+ mask = hidden_states.new_ones((batch_size, mask_seq_len))
+
+ mask = mask.masked_fill(bool_mask, 0)
+
+ return mask
+
+
+class Wav2Vec2BertRotaryPositionalEmbedding(Wav2Vec2ConformerRotaryPositionalEmbedding):
+ def __init__(self, config):
+ nn.Module.__init__(self)
+ dim = config.hidden_size // config.num_attention_heads
+ base = config.rotary_embedding_base
+
+ inv_freq = 1.0 / (base ** (torch.arange(0, dim, 2, dtype=torch.int64).float() / dim))
+ # Ignore copy
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.cached_sequence_length = None
+ self.cached_rotary_positional_embedding = None
+
+
+class Wav2Vec2BertRelPositionalEmbedding(Wav2Vec2ConformerRelPositionalEmbedding):
+ pass
+
+
+class Wav2Vec2BertFeatureProjection(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.feature_projection_input_dim, eps=config.layer_norm_eps)
+ self.projection = nn.Linear(config.feature_projection_input_dim, config.hidden_size)
+ self.dropout = nn.Dropout(config.feat_proj_dropout)
+
+ def forward(self, hidden_states):
+ # non-projected hidden states are needed for quantization
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states, norm_hidden_states
+
+
+class Wav2Vec2BertFeedForward(Wav2Vec2FeedForward):
+ def __init__(self, config, act_fn=None, hidden_size=None):
+ nn.Module.__init__(self)
+ act_fn = act_fn if act_fn is not None else config.hidden_act
+ hidden_size = hidden_size if hidden_size is not None else config.hidden_size
+ self.intermediate_dropout = nn.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = nn.Linear(hidden_size, config.intermediate_size)
+ self.intermediate_act_fn = ACT2FN[act_fn] if isinstance(act_fn, str) else act_fn
+
+ self.output_dense = nn.Linear(config.intermediate_size, hidden_size)
+ self.output_dropout = nn.Dropout(config.hidden_dropout)
+
+
+class Wav2Vec2BertConvolutionModule(nn.Module):
+ """Convolution block used in the conformer block"""
+
+ def __init__(self, config):
+ super().__init__()
+ if (config.conv_depthwise_kernel_size - 1) % 2 == 1:
+ raise ValueError("`config.conv_depthwise_kernel_size` should be a odd number for 'SAME' padding")
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.pointwise_conv1 = nn.Conv1d(
+ config.hidden_size,
+ 2 * config.hidden_size,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ bias=False,
+ )
+ self.glu = nn.GLU(dim=1)
+ self.depthwise_conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ config.conv_depthwise_kernel_size,
+ stride=1,
+ padding=0,
+ groups=config.hidden_size,
+ bias=False,
+ )
+
+ self.depthwise_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.activation = ACT2FN[config.hidden_act]
+ self.pointwise_conv2 = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ bias=False,
+ )
+ self.dropout = nn.Dropout(config.conformer_conv_dropout)
+
+ def forward(self, hidden_states, attention_mask=None):
+ hidden_states = self.layer_norm(hidden_states)
+
+ # Ensure that we do not leak padded positions in depthwise convolution if attention mask is passed.
+ # Put 0 where necessary
+ if attention_mask is not None:
+ hidden_states = hidden_states.masked_fill(~attention_mask.bool().unsqueeze(-1), 0.0)
+
+ # exchange the temporal dimension and the feature dimension
+ hidden_states = hidden_states.transpose(1, 2)
+
+ # GLU mechanism
+ # => (batch, 2*channel, dim)
+ hidden_states = self.pointwise_conv1(hidden_states)
+ # => (batch, channel, dim)
+ hidden_states = self.glu(hidden_states)
+
+ # Pad the sequence entirely on the left because of causal convolution.
+ hidden_states = torch.nn.functional.pad(hidden_states, (self.depthwise_conv.kernel_size[0] - 1, 0))
+
+ # 1D Depthwise Conv
+ hidden_states = self.depthwise_conv(hidden_states)
+
+ hidden_states = self.depthwise_layer_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
+
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = self.pointwise_conv2(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2BertSelfAttention(Wav2Vec2ConformerSelfAttention, nn.Module):
+ """Construct an Wav2Vec2BertSelfAttention object.
+ Can be enhanced with rotary or relative position embeddings.
+ """
+
+ def __init__(self, config, is_adapter_attention=False):
+ nn.Module.__init__(self)
+ hidden_size = config.hidden_size if not is_adapter_attention else config.output_hidden_size
+
+ self.head_size = hidden_size // config.num_attention_heads
+ self.num_heads = config.num_attention_heads
+ self.position_embeddings_type = config.position_embeddings_type if not is_adapter_attention else None
+
+ self.linear_q = nn.Linear(hidden_size, hidden_size)
+ self.linear_k = nn.Linear(hidden_size, hidden_size)
+ self.linear_v = nn.Linear(hidden_size, hidden_size)
+ self.linear_out = nn.Linear(hidden_size, hidden_size)
+
+ self.dropout = nn.Dropout(p=config.attention_dropout)
+
+ if self.position_embeddings_type == "relative":
+ # linear transformation for positional encoding
+ self.linear_pos = nn.Linear(hidden_size, hidden_size, bias=False)
+ # these two learnable bias are used in matrix c and matrix d
+ # as described in https://huggingface.co/papers/1901.02860 Section 3.3
+ self.pos_bias_u = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+ self.pos_bias_v = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+
+ if self.position_embeddings_type == "relative_key":
+ self.left_max_position_embeddings = config.left_max_position_embeddings
+ self.right_max_position_embeddings = config.right_max_position_embeddings
+ num_positions = self.left_max_position_embeddings + self.right_max_position_embeddings + 1
+ self.distance_embedding = nn.Embedding(num_positions, self.head_size)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ # self-attention mechanism
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ # make sure query/key states can be != value states
+ query_key_states = hidden_states
+ value_states = hidden_states
+
+ if self.position_embeddings_type == "rotary":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type == 'rotary'"
+ )
+ query_key_states = self._apply_rotary_embedding(query_key_states, relative_position_embeddings)
+
+ # project query_key_states and value_states
+ query = self.linear_q(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ key = self.linear_k(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ value = self.linear_v(value_states).view(batch_size, -1, self.num_heads, self.head_size)
+
+ # => (batch, head, time1, d_k)
+ query = query.transpose(1, 2)
+ key = key.transpose(1, 2)
+ value = value.transpose(1, 2)
+
+ if self.position_embeddings_type == "relative":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type =="
+ " 'relative'"
+ )
+ # apply relative_position_embeddings to qk scores
+ # as proposed in Transformer_XL: https://huggingface.co/papers/1901.02860
+ scores = self._apply_relative_embeddings(
+ query=query, key=key, relative_position_embeddings=relative_position_embeddings
+ )
+ else:
+ scores = torch.matmul(query, key.transpose(-2, -1)) / math.sqrt(self.head_size)
+
+ if self.position_embeddings_type == "relative_key":
+ query_length, key_length = query.shape[2], key.shape[2]
+
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_r - position_ids_l
+ distance = torch.clamp(distance, -self.left_max_position_embeddings, self.right_max_position_embeddings)
+
+ positional_embedding = self.distance_embedding(distance + self.left_max_position_embeddings)
+ positional_embedding = positional_embedding.to(dtype=query.dtype) # fp16 compatibility
+
+ relative_position_attn_weights = torch.einsum("bhld,lrd->bhlr", query, positional_embedding)
+ scores = scores + (relative_position_attn_weights / math.sqrt(self.head_size))
+
+ # apply attention_mask if necessary
+ if attention_mask is not None:
+ scores = scores + attention_mask
+
+ # => (batch, head, time1, time2)
+ probs = torch.softmax(scores, dim=-1)
+ probs = self.dropout(probs)
+
+ # => (batch, head, time1, d_k)
+ hidden_states = torch.matmul(probs, value)
+
+ # => (batch, time1, hidden_size)
+ hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, self.num_heads * self.head_size)
+ hidden_states = self.linear_out(hidden_states)
+
+ return hidden_states, probs
+
+
+class Wav2Vec2BertEncoderLayer(GradientCheckpointingLayer):
+ """Conformer block based on https://huggingface.co/papers/2005.08100."""
+
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.hidden_size
+ dropout = config.attention_dropout
+
+ # Feed-forward 1
+ self.ffn1_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.ffn1 = Wav2Vec2BertFeedForward(config)
+
+ # Self-Attention
+ self.self_attn_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.self_attn_dropout = nn.Dropout(dropout)
+ self.self_attn = Wav2Vec2BertSelfAttention(config)
+
+ # Conformer Convolution
+ self.conv_module = Wav2Vec2BertConvolutionModule(config)
+
+ # Feed-forward 2
+ self.ffn2_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.ffn2 = Wav2Vec2BertFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ conv_attention_mask: Optional[torch.Tensor] = None,
+ ):
+ hidden_states = hidden_states
+
+ # 1. Feed-Forward 1 layer
+ residual = hidden_states
+ hidden_states = self.ffn1_layer_norm(hidden_states)
+ hidden_states = self.ffn1(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ residual = hidden_states
+
+ # 2. Self-Attention layer
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weigts = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.self_attn_dropout(hidden_states)
+ hidden_states = hidden_states + residual
+
+ # 3. Convolutional Layer
+ residual = hidden_states
+ hidden_states = self.conv_module(hidden_states, attention_mask=conv_attention_mask)
+ hidden_states = residual + hidden_states
+
+ # 4. Feed-Forward 2 Layer
+ residual = hidden_states
+ hidden_states = self.ffn2_layer_norm(hidden_states)
+ hidden_states = self.ffn2(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ return hidden_states, attn_weigts
+
+
+class Wav2Vec2BertEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+
+ if config.position_embeddings_type == "relative":
+ self.embed_positions = Wav2Vec2BertRelPositionalEmbedding(config)
+ elif config.position_embeddings_type == "rotary":
+ self.embed_positions = Wav2Vec2BertRotaryPositionalEmbedding(config)
+ else:
+ self.embed_positions = None
+
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList([Wav2Vec2BertEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ conv_attention_mask = attention_mask
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ hidden_states = hidden_states.masked_fill(~attention_mask.bool().unsqueeze(-1), 0.0)
+
+ # extend attention_mask
+ attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype)
+ attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min
+ attention_mask = attention_mask.expand(
+ attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1]
+ )
+
+ hidden_states = self.dropout(hidden_states)
+
+ if self.embed_positions is not None:
+ relative_position_embeddings = self.embed_positions(hidden_states)
+ else:
+ relative_position_embeddings = None
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ conv_attention_mask=conv_attention_mask,
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class Wav2Vec2BertAdapter(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ # feature dim might need to be down-projected
+ if config.output_hidden_size != config.hidden_size:
+ self.proj = nn.Linear(config.hidden_size, config.output_hidden_size)
+ self.proj_layer_norm = nn.LayerNorm(config.output_hidden_size, eps=config.layer_norm_eps)
+ else:
+ self.proj = self.proj_layer_norm = None
+ self.layers = nn.ModuleList(Wav2Vec2BertAdapterLayer(config) for _ in range(config.num_adapter_layers))
+ self.layerdrop = config.layerdrop
+
+ self.kernel_size = config.adapter_kernel_size
+ self.stride = config.adapter_stride
+
+ def _compute_sub_sample_lengths_from_attention_mask(self, seq_lens):
+ if seq_lens is None:
+ return seq_lens
+ pad = self.kernel_size // 2
+ seq_lens = ((seq_lens + 2 * pad - self.kernel_size) / self.stride) + 1
+ return seq_lens.floor()
+
+ def forward(self, hidden_states, attention_mask=None):
+ # down project hidden_states if necessary
+ if self.proj is not None and self.proj_layer_norm is not None:
+ hidden_states = self.proj(hidden_states)
+ hidden_states = self.proj_layer_norm(hidden_states)
+
+ sub_sampled_lengths = None
+ if attention_mask is not None:
+ sub_sampled_lengths = (attention_mask.size(1) - (1 - attention_mask.int()).sum(1)).to(hidden_states.device)
+
+ for layer in self.layers:
+ layerdrop_prob = torch.rand([])
+ sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(sub_sampled_lengths)
+ if not self.training or (layerdrop_prob > self.layerdrop):
+ hidden_states = layer(
+ hidden_states, attention_mask=attention_mask, sub_sampled_lengths=sub_sampled_lengths
+ )
+
+ return hidden_states
+
+
+class Wav2Vec2BertAdapterLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.output_hidden_size
+ dropout = config.conformer_conv_dropout
+
+ self.kernel_size = config.adapter_kernel_size
+ self.stride = config.adapter_stride
+
+ # 1. residual convolution
+ self.residual_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.residual_conv = nn.Conv1d(
+ embed_dim,
+ 2 * embed_dim,
+ self.kernel_size,
+ stride=self.stride,
+ padding=self.stride // 2,
+ )
+ self.activation = nn.GLU(dim=1)
+
+ # Self-Attention
+ self.self_attn_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.self_attn_conv = nn.Conv1d(
+ embed_dim,
+ 2 * embed_dim,
+ self.kernel_size,
+ stride=self.stride,
+ padding=self.stride // 2,
+ )
+ self.self_attn = Wav2Vec2BertSelfAttention(config, is_adapter_attention=True)
+ self.self_attn_dropout = nn.Dropout(dropout)
+
+ # Feed-forward
+ self.ffn_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.ffn = Wav2Vec2BertFeedForward(config, act_fn=config.adapter_act, hidden_size=embed_dim)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ sub_sampled_lengths: Optional[torch.Tensor] = None,
+ ):
+ residual = self.residual_layer_norm(hidden_states)
+
+ # Apply pooling to the residual to match the sequence length of the
+ # multi-head attention output.
+ # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len)
+ residual = residual.transpose(1, 2)
+ residual = self.residual_conv(residual)
+ residual = self.activation(residual)
+ # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim)
+ residual = residual.transpose(1, 2)
+
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ # Apply pooling before feeding to the multihead-attention layer.
+ # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len)
+ hidden_states = hidden_states.transpose(1, 2)
+ hidden_states = self.self_attn_conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim)
+ hidden_states = hidden_states.transpose(1, 2)
+
+ if attention_mask is not None:
+ attention_mask = _compute_new_attention_mask(hidden_states=hidden_states, seq_lens=sub_sampled_lengths)
+ attention_mask = _prepare_4d_attention_mask(
+ attention_mask,
+ hidden_states.dtype,
+ )
+
+ # The rest of the computation is identical to a vanilla Transformer
+ # encoder layer.
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.self_attn_dropout(hidden_states)
+ hidden_states = hidden_states + residual
+
+ residual = hidden_states
+
+ hidden_states = self.ffn_layer_norm(hidden_states)
+ hidden_states = self.ffn(hidden_states) + residual
+
+ return hidden_states
+
+
+@auto_docstring
+class Wav2Vec2BertPreTrainedModel(PreTrainedModel):
+ config: Wav2Vec2BertConfig
+ base_model_prefix = "wav2vec2_bert"
+ main_input_name = "input_features"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, Wav2Vec2BertSelfAttention):
+ if hasattr(module, "pos_bias_u"):
+ nn.init.xavier_uniform_(module.pos_bias_u)
+ if hasattr(module, "pos_bias_v"):
+ nn.init.xavier_uniform_(module.pos_bias_v)
+ elif isinstance(module, Wav2Vec2BertFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+ elif isinstance(module, Wav2Vec2BertModel):
+ if hasattr(module, "masked_spec_embed"):
+ module.masked_spec_embed.data.uniform_()
+ elif isinstance(
+ module,
+ (Wav2Vec2BertForSequenceClassification, Wav2Vec2BertForAudioFrameClassification, Wav2Vec2BertForXVector),
+ ):
+ if hasattr(module, "layer_weights"):
+ module.layer_weights.data.fill_(1.0 / (self.config.num_hidden_layers + 1))
+ elif isinstance(module, AMSoftmaxLoss): # noqa: F821
+ module.weight.data.normal_()
+
+ # Ignore copy
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[torch.LongTensor, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride, padding):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length + 2 * padding - kernel_size, stride, rounding_mode="floor") + 1
+
+ if add_adapter:
+ padding = self.config.adapter_kernel_size // 2
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(
+ input_lengths, self.config.adapter_kernel_size, self.config.adapter_stride, padding
+ )
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: torch.LongTensor, add_adapter=None
+ ):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+ output_lengths = output_lengths.to(torch.long)
+
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+Wav2Vec2BertBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+class Wav2Vec2BertModel(Wav2Vec2Model, Wav2Vec2BertPreTrainedModel):
+ def __init__(self, config: Wav2Vec2BertConfig):
+ Wav2Vec2BertPreTrainedModel.__init__(self, config)
+ self.config = config
+ self.feature_projection = Wav2Vec2BertFeatureProjection(config)
+
+ # model only needs masking vector if mask prob is > 0.0
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ self.encoder = Wav2Vec2BertEncoder(config)
+
+ self.adapter = Wav2Vec2BertAdapter(config) if config.add_adapter else None
+
+ self.intermediate_ffn = None
+ if config.use_intermediate_ffn_before_adapter:
+ self.intermediate_ffn = Wav2Vec2BertFeedForward(config, act_fn="relu")
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Bert")
+
+ def freeze_feature_encoder(self):
+ raise AttributeError("Not needed for Wav2Vec2Bert")
+
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Wav2Vec2BertBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ hidden_states, extract_features = self.feature_projection(input_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.intermediate_ffn:
+ expanded_hidden_states = self.intermediate_ffn(hidden_states)
+ hidden_states = hidden_states + 0.5 * expanded_hidden_states
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states, attention_mask=attention_mask)
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return Wav2Vec2BertBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class Wav2Vec2BertForCTC(Wav2Vec2ConformerForCTC):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`UniSpeechSatForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ def freeze_feature_encoder(self):
+ raise AttributeError("Not needed for Wav2Vec2Bert")
+
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*):
+ Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to
+ the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`.
+ All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ if labels is not None and labels.max() >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+
+ logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # retrieve loss input_lengths from attention_mask
+ attention_mask = (
+ attention_mask
+ if attention_mask is not None
+ else torch.ones(input_features.shape[:2], device=input_features.device, dtype=torch.long)
+ )
+ input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum([-1])).to(torch.long)
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = labels >= 0
+ target_lengths = labels_mask.sum(-1)
+ flattened_targets = labels.masked_select(labels_mask)
+
+ # ctc_loss doesn't support fp16
+ log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1)
+
+ with torch.backends.cudnn.flags(enabled=False):
+ loss = nn.functional.ctc_loss(
+ log_probs,
+ flattened_targets,
+ input_lengths,
+ target_lengths,
+ blank=self.config.pad_token_id,
+ reduction=self.config.ctc_loss_reduction,
+ zero_infinity=self.config.ctc_zero_infinity,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return CausalLMOutput(
+ loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions
+ )
+
+
+class Wav2Vec2BertForSequenceClassification(Wav2Vec2ForSequenceClassification):
+ def __init__(self, config):
+ super().__init__(config)
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Bert")
+
+ def freeze_feature_encoder(self):
+ raise AttributeError("Not needed for Wav2Vec2Bert")
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2_bert.parameters():
+ param.requires_grad = False
+
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = hidden_states.mean(dim=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask)
+ expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_padding_mask] = 0.0
+ pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class Wav2Vec2BertForAudioFrameClassification(Wav2Vec2ConformerForAudioFrameClassification):
+ def __init__(self, config):
+ super().__init__(config)
+
+ def freeze_feature_encoder(self):
+ raise AttributeError("Not needed for Wav2Vec2Bert")
+
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), torch.argmax(labels.view(-1, self.num_labels), axis=1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class Wav2Vec2BertForXVector(Wav2Vec2ConformerForXVector):
+ def __init__(self, config):
+ super().__init__(config)
+
+ def freeze_feature_encoder(self):
+ raise AttributeError("Not needed for Wav2Vec2Bert")
+
+ def forward(
+ self,
+ input_features: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, XVectorOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_bert(
+ input_features,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+
+ for tdnn_layer in self.tdnn:
+ hidden_states = tdnn_layer(hidden_states)
+
+ # Statistic Pooling
+ if attention_mask is None:
+ mean_features = hidden_states.mean(dim=1)
+ std_features = hidden_states.std(dim=1)
+ else:
+ feat_extract_output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(dim=1))
+ tdnn_output_lengths = self._get_tdnn_output_lengths(feat_extract_output_lengths)
+ mean_features = []
+ std_features = []
+ for i, length in enumerate(tdnn_output_lengths):
+ mean_features.append(hidden_states[i, :length].mean(dim=0))
+ std_features.append(hidden_states[i, :length].std(dim=0))
+ mean_features = torch.stack(mean_features)
+ std_features = torch.stack(std_features)
+ statistic_pooling = torch.cat([mean_features, std_features], dim=-1)
+
+ output_embeddings = self.feature_extractor(statistic_pooling)
+ logits = self.classifier(output_embeddings)
+
+ loss = None
+ if labels is not None:
+ loss = self.objective(logits, labels)
+
+ if not return_dict:
+ output = (logits, output_embeddings) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XVectorOutput(
+ loss=loss,
+ logits=logits,
+ embeddings=output_embeddings,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "Wav2Vec2BertForAudioFrameClassification",
+ "Wav2Vec2BertForCTC",
+ "Wav2Vec2BertForSequenceClassification",
+ "Wav2Vec2BertForXVector",
+ "Wav2Vec2BertModel",
+ "Wav2Vec2BertPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/processing_wav2vec2_bert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/processing_wav2vec2_bert.py
new file mode 100644
index 0000000000000000000000000000000000000000..253ddaac6c19996e70e26a4f59351d72caa5d6b5
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_bert/processing_wav2vec2_bert.py
@@ -0,0 +1,155 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Speech processor class for Wav2Vec2-BERT
+"""
+
+import warnings
+from typing import Optional, Union
+
+from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack
+from ...tokenization_utils_base import AudioInput, PreTokenizedInput, TextInput
+from ..seamless_m4t.feature_extraction_seamless_m4t import SeamlessM4TFeatureExtractor
+from ..wav2vec2.tokenization_wav2vec2 import Wav2Vec2CTCTokenizer
+
+
+class Wav2Vec2BertProcessorKwargs(ProcessingKwargs, total=False):
+ _defaults = {}
+
+
+class Wav2Vec2BertProcessor(ProcessorMixin):
+ r"""
+ Constructs a Wav2Vec2-BERT processor which wraps a Wav2Vec2-BERT feature extractor and a Wav2Vec2 CTC tokenizer into a single
+ processor.
+
+ [`Wav2Vec2Processor`] offers all the functionalities of [`SeamlessM4TFeatureExtractor`] and [`PreTrainedTokenizer`].
+ See the docstring of [`~Wav2Vec2Processor.__call__`] and [`~Wav2Vec2Processor.decode`] for more information.
+
+ Args:
+ feature_extractor (`SeamlessM4TFeatureExtractor`):
+ An instance of [`SeamlessM4TFeatureExtractor`]. The feature extractor is a required input.
+ tokenizer ([`PreTrainedTokenizer`]):
+ An instance of [`PreTrainedTokenizer`]. The tokenizer is a required input.
+ """
+
+ feature_extractor_class = "SeamlessM4TFeatureExtractor"
+ tokenizer_class = "AutoTokenizer"
+
+ def __init__(self, feature_extractor, tokenizer):
+ super().__init__(feature_extractor, tokenizer)
+
+ @classmethod
+ def from_pretrained(cls, pretrained_model_name_or_path, **kwargs):
+ try:
+ return super().from_pretrained(pretrained_model_name_or_path, **kwargs)
+ except OSError:
+ warnings.warn(
+ f"Loading a tokenizer inside {cls.__name__} from a config that does not"
+ " include a `tokenizer_class` attribute is deprecated and will be "
+ "removed in v5. Please add `'tokenizer_class': 'Wav2Vec2CTCTokenizer'`"
+ " attribute to either your `config.json` or `tokenizer_config.json` "
+ "file to suppress this warning: ",
+ FutureWarning,
+ )
+
+ feature_extractor = SeamlessM4TFeatureExtractor.from_pretrained(pretrained_model_name_or_path, **kwargs)
+ tokenizer = Wav2Vec2CTCTokenizer.from_pretrained(pretrained_model_name_or_path, **kwargs)
+
+ return cls(feature_extractor=feature_extractor, tokenizer=tokenizer)
+
+ def __call__(
+ self,
+ audio: AudioInput = None,
+ text: Optional[Union[str, list[str], TextInput, PreTokenizedInput]] = None,
+ images=None,
+ videos=None,
+ **kwargs: Unpack[Wav2Vec2BertProcessorKwargs],
+ ):
+ """
+ Main method to prepare for the model one or several sequences(s) and audio(s). This method forwards the `audio`
+ and `kwargs` arguments to SeamlessM4TFeatureExtractor's [`~SeamlessM4TFeatureExtractor.__call__`] if `audio` is not
+ `None` to pre-process the audio. To prepare the target sequences(s), this method forwards the `text` and `kwargs` arguments to
+ PreTrainedTokenizer's [`~PreTrainedTokenizer.__call__`] if `text` is not `None`. Please refer to the docstring of the above two methods for more information.
+
+ Args:
+ audio (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, `list[torch.Tensor]`):
+ The audio or batch of audios to be prepared. Each audio can be NumPy array or PyTorch tensor. In case
+ of a NumPy array/PyTorch tensor, each audio should be of shape (C, T), where C is a number of channels,
+ and T the sample length of the audio.
+
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ Returns:
+ [`BatchEncoding`]: A [`BatchEncoding`] with the following fields:
+ - **input_features** -- Audio input features to be fed to a model. Returned when `audio` is not `None`.
+ - **attention_mask** -- List of indices specifying which timestamps should be attended to by the model when `audio` is not `None`.
+ When only `text` is specified, returns the token attention mask.
+ - **labels** -- List of token ids to be fed to a model. Returned when both `text` and `audio` are not `None`.
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None` and `audio` is `None`.
+ """
+
+ if audio is None and text is None:
+ raise ValueError("You need to specify either an `audio` or `text` input to process.")
+ output_kwargs = self._merge_kwargs(
+ Wav2Vec2BertProcessorKwargs,
+ tokenizer_init_kwargs=self.tokenizer.init_kwargs,
+ **kwargs,
+ )
+
+ if audio is not None:
+ inputs = self.feature_extractor(audio, **output_kwargs["audio_kwargs"])
+ if text is not None:
+ encodings = self.tokenizer(text, **output_kwargs["text_kwargs"])
+
+ if text is None:
+ return inputs
+ elif audio is None:
+ return encodings
+ else:
+ inputs["labels"] = encodings["input_ids"]
+ return inputs
+
+ def pad(self, input_features=None, labels=None, **kwargs):
+ """
+ If `input_features` is not `None`, this method forwards the `input_features` and `kwargs` arguments to SeamlessM4TFeatureExtractor's [`~SeamlessM4TFeatureExtractor.pad`] to pad the input features.
+ If `labels` is not `None`, this method forwards the `labels` and `kwargs` arguments to PreTrainedTokenizer's [`~PreTrainedTokenizer.pad`] to pad the label(s).
+ Please refer to the docstring of the above two methods for more information.
+ """
+ if input_features is None and labels is None:
+ raise ValueError("You need to specify either an `input_features` or `labels` input to pad.")
+
+ if input_features is not None:
+ input_features = self.feature_extractor.pad(input_features, **kwargs)
+ if labels is not None:
+ labels = self.tokenizer.pad(labels, **kwargs)
+
+ if labels is None:
+ return input_features
+ elif input_features is None:
+ return labels
+ else:
+ input_features["labels"] = labels["input_ids"]
+ return input_features
+
+ @property
+ def model_input_names(self):
+ # The processor doesn't return text ids and the model seems to not need them
+ feature_extractor_input_names = self.feature_extractor.model_input_names
+ return feature_extractor_input_names + ["labels"]
+
+
+__all__ = ["Wav2Vec2BertProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..54d0d9e2c3997c4b2865b5a47e7b64c39ed40b68
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_wav2vec2_conformer import *
+ from .modeling_wav2vec2_conformer import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/configuration_wav2vec2_conformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/configuration_wav2vec2_conformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..493e96f44037d6b846ad702e0c765335d3ecee08
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/configuration_wav2vec2_conformer.py
@@ -0,0 +1,360 @@
+# coding=utf-8
+# Copyright 2022 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Wav2Vec2Conformer model configuration"""
+
+import functools
+import operator
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class Wav2Vec2ConformerConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Wav2Vec2ConformerModel`]. It is used to
+ instantiate an Wav2Vec2Conformer model according to the specified arguments, defining the model architecture.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the Wav2Vec2Conformer
+ [facebook/wav2vec2-conformer-rel-pos-large](https://huggingface.co/facebook/wav2vec2-conformer-rel-pos-large)
+ architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*):
+ Vocabulary size of the Wav2Vec2Conformer model. Defines the number of different tokens that can be
+ represented by the `inputs_ids` passed when calling [`Wav2Vec2ConformerModel`]. Vocabulary size of the
+ model. Defines the different tokens that can be represented by the *inputs_ids* passed to the forward
+ method of [`Wav2Vec2ConformerModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for activations inside the fully connected layer.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ final_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the final projection layer of [`Wav2Vec2ConformerForCTC`].
+ layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) for more
+ details.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ feat_extract_norm (`str`, *optional*, defaults to `"group"`):
+ The norm to be applied to 1D convolutional layers in feature encoder. One of `"group"` for group
+ normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D
+ convolutional layers.
+ feat_proj_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for output of the feature encoder.
+ feat_extract_activation (`str, `optional`, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the 1D convolutional layers of the feature
+ extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ feat_quantizer_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for quantized feature encoder states.
+ conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 512, 512, 512)`):
+ A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the
+ feature encoder. The length of *conv_dim* defines the number of 1D convolutional layers.
+ conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 2, 2, 2, 2, 2)`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the feature encoder. The length
+ of *conv_stride* defines the number of convolutional layers and has to match the length of *conv_dim*.
+ conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 3, 3, 3, 3, 3)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the feature encoder. The
+ length of *conv_kernel* defines the number of convolutional layers and has to match the length of
+ *conv_dim*.
+ conv_bias (`bool`, *optional*, defaults to `False`):
+ Whether the 1D convolutional layers have a bias.
+ num_conv_pos_embeddings (`int`, *optional*, defaults to 128):
+ Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional
+ embeddings layer.
+ num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16):
+ Number of groups of 1D convolutional positional embeddings layer.
+ apply_spec_augment (`bool`, *optional*, defaults to `True`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see
+ [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking
+ procedure generates ''mask_time_prob*len(time_axis)/mask_time_length'' independent masks over the axis. If
+ reasoning from the probability of each feature vector to be chosen as the start of the vector span to be
+ masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the
+ actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2),:
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks''
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The
+ masking procedure generates ''mask_feature_prob*len(feature_axis)/mask_time_length'' independent masks over
+ the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector
+ span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap
+ may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is
+ True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ mask_feature_min_masks (`int`, *optional*, defaults to 0),:
+ The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time
+ step, irrespectively of `mask_feature_prob`. Only relevant if
+ ''mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks''
+ num_codevectors_per_group (`int`, *optional*, defaults to 320):
+ Number of entries in each quantization codebook (group).
+ num_codevector_groups (`int`, *optional*, defaults to 2):
+ Number of codevector groups for product codevector quantization.
+ contrastive_logits_temperature (`float`, *optional*, defaults to 0.1):
+ The temperature *kappa* in the contrastive loss.
+ feat_quantizer_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the output of the feature encoder that's used by the quantizer.
+ num_negatives (`int`, *optional*, defaults to 100):
+ Number of negative samples for the contrastive loss.
+ codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the quantized feature vectors.
+ proj_codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the final projection of both the quantized and the transformer features.
+ diversity_loss_weight (`int`, *optional*, defaults to 0.1):
+ The weight of the codebook diversity loss component.
+ ctc_loss_reduction (`str`, *optional*, defaults to `"sum"`):
+ Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an
+ instance of [`Wav2Vec2ConformerForCTC`].
+ ctc_zero_infinity (`bool`, *optional*, defaults to `False`):
+ Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly
+ occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance
+ of [`Wav2Vec2ConformerForCTC`].
+ use_weighted_layer_sum (`bool`, *optional*, defaults to `False`):
+ Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an
+ instance of [`Wav2Vec2ConformerForSequenceClassification`].
+ classifier_proj_size (`int`, *optional*, defaults to 256):
+ Dimensionality of the projection before token mean-pooling for classification.
+ tdnn_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 1500)`):
+ A tuple of integers defining the number of output channels of each 1D convolutional layer in the *TDNN*
+ module of the *XVector* model. The length of *tdnn_dim* defines the number of *TDNN* layers.
+ tdnn_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 3, 3, 1, 1)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the *TDNN* module of the
+ *XVector* model. The length of *tdnn_kernel* has to match the length of *tdnn_dim*.
+ tdnn_dilation (`tuple[int]` or `list[int]`, *optional*, defaults to `(1, 2, 3, 1, 1)`):
+ A tuple of integers defining the dilation factor of each 1D convolutional layer in *TDNN* module of the
+ *XVector* model. The length of *tdnn_dilation* has to match the length of *tdnn_dim*.
+ xvector_output_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of the *XVector* embedding vectors.
+ add_adapter (`bool`, *optional*, defaults to `False`):
+ Whether a convolutional network should be stacked on top of the Wav2Vec2Conformer Encoder. Can be very
+ useful for warm-starting Wav2Vec2Conformer for SpeechEncoderDecoder models.
+ adapter_kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ adapter_stride (`int`, *optional*, defaults to 2):
+ Stride of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ num_adapter_layers (`int`, *optional*, defaults to 3):
+ Number of convolutional layers that should be used in the adapter network. Only relevant if `add_adapter is
+ True`.
+ output_hidden_size (`int`, *optional*):
+ Dimensionality of the encoder output layer. If not defined, this defaults to *hidden-size*. Only relevant
+ if `add_adapter is True`.
+ position_embeddings_type (`str`, *optional*, defaults to `"relative"`):
+ Can be specified to `relative` or `rotary` for relative or rotary position embeddings respectively. If left
+ `None` no relative position embedding is applied.
+ rotary_embedding_base (`int`, *optional*, defaults to 10000):
+ If `"rotary"` position embeddings are used, defines the size of the embedding base.
+ max_source_positions (`int`, *optional*, defaults to 5000):
+ if `"relative"` position embeddings are used, defines the maximum source input positions.
+ conv_depthwise_kernel_size (`int`, *optional*, defaults to 31):
+ Kernel size of convolutional depthwise 1D layer in Conformer blocks.
+ conformer_conv_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all convolutional layers in Conformer blocks.
+
+ Example:
+
+ ```python
+ >>> from transformers import Wav2Vec2ConformerConfig, Wav2Vec2ConformerModel
+
+ >>> # Initializing a Wav2Vec2Conformer facebook/wav2vec2-conformer-rel-pos-large style configuration
+ >>> configuration = Wav2Vec2ConformerConfig()
+
+ >>> # Initializing a model (with random weights) from the facebook/wav2vec2-conformer-rel-pos-large style configuration
+ >>> model = Wav2Vec2ConformerModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "wav2vec2-conformer"
+
+ def __init__(
+ self,
+ vocab_size=None,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout=0.1,
+ activation_dropout=0.1,
+ attention_dropout=0.1,
+ feat_proj_dropout=0.0,
+ feat_quantizer_dropout=0.0,
+ final_dropout=0.1,
+ layerdrop=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ feat_extract_norm="group",
+ feat_extract_activation="gelu",
+ conv_dim=(512, 512, 512, 512, 512, 512, 512),
+ conv_stride=(5, 2, 2, 2, 2, 2, 2),
+ conv_kernel=(10, 3, 3, 3, 3, 2, 2),
+ conv_bias=False,
+ num_conv_pos_embeddings=128,
+ num_conv_pos_embedding_groups=16,
+ apply_spec_augment=True,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ mask_feature_min_masks=0,
+ num_codevectors_per_group=320,
+ num_codevector_groups=2,
+ contrastive_logits_temperature=0.1,
+ num_negatives=100,
+ codevector_dim=256,
+ proj_codevector_dim=256,
+ diversity_loss_weight=0.1,
+ ctc_loss_reduction="sum",
+ ctc_zero_infinity=False,
+ use_weighted_layer_sum=False,
+ classifier_proj_size=256,
+ tdnn_dim=(512, 512, 512, 512, 1500),
+ tdnn_kernel=(5, 3, 3, 1, 1),
+ tdnn_dilation=(1, 2, 3, 1, 1),
+ xvector_output_dim=512,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ add_adapter=False,
+ adapter_kernel_size=3,
+ adapter_stride=2,
+ num_adapter_layers=3,
+ output_hidden_size=None,
+ position_embeddings_type="relative",
+ rotary_embedding_base=10000,
+ max_source_positions=5000,
+ conv_depthwise_kernel_size=31,
+ conformer_conv_dropout=0.1,
+ **kwargs,
+ ):
+ super().__init__(**kwargs, pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id)
+ self.hidden_size = hidden_size
+ self.feat_extract_norm = feat_extract_norm
+ self.feat_extract_activation = feat_extract_activation
+ self.conv_dim = list(conv_dim)
+ self.conv_stride = list(conv_stride)
+ self.conv_kernel = list(conv_kernel)
+ self.conv_bias = conv_bias
+ self.num_conv_pos_embeddings = num_conv_pos_embeddings
+ self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups
+ self.num_feat_extract_layers = len(self.conv_dim)
+ self.num_hidden_layers = num_hidden_layers
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.num_attention_heads = num_attention_heads
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.feat_proj_dropout = feat_proj_dropout
+ self.final_dropout = final_dropout
+ self.layerdrop = layerdrop
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.vocab_size = vocab_size
+ self.use_weighted_layer_sum = use_weighted_layer_sum
+ self.max_source_positions = max_source_positions
+ self.position_embeddings_type = position_embeddings_type
+ self.rotary_embedding_base = rotary_embedding_base
+
+ if (
+ (len(self.conv_stride) != self.num_feat_extract_layers)
+ or (len(self.conv_kernel) != self.num_feat_extract_layers)
+ or (len(self.conv_dim) != self.num_feat_extract_layers)
+ ):
+ raise ValueError(
+ "Configuration for convolutional layers is incorrect. It is required that `len(config.conv_dim)` =="
+ " `len(config.conv_stride)` == `len(config.conv_kernel)`, but is `len(config.conv_dim) ="
+ f" {len(self.conv_dim)}`, `len(config.conv_stride) = {len(self.conv_stride)}`,"
+ f" `len(config.conv_kernel) = {len(self.conv_kernel)}`."
+ )
+
+ # Conformer-block related
+ self.conv_depthwise_kernel_size = conv_depthwise_kernel_size
+ self.conformer_conv_dropout = conformer_conv_dropout
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+ self.mask_feature_min_masks = mask_feature_min_masks
+
+ # parameters for pretraining with codevector quantized representations
+ self.num_codevectors_per_group = num_codevectors_per_group
+ self.num_codevector_groups = num_codevector_groups
+ self.contrastive_logits_temperature = contrastive_logits_temperature
+ self.feat_quantizer_dropout = feat_quantizer_dropout
+ self.num_negatives = num_negatives
+ self.codevector_dim = codevector_dim
+ self.proj_codevector_dim = proj_codevector_dim
+ self.diversity_loss_weight = diversity_loss_weight
+
+ # ctc loss
+ self.ctc_loss_reduction = ctc_loss_reduction
+ self.ctc_zero_infinity = ctc_zero_infinity
+
+ # adapter
+ self.add_adapter = add_adapter
+ self.adapter_kernel_size = adapter_kernel_size
+ self.adapter_stride = adapter_stride
+ self.num_adapter_layers = num_adapter_layers
+ self.output_hidden_size = output_hidden_size or hidden_size
+
+ # SequenceClassification-specific parameter. Feel free to ignore for other classes.
+ self.classifier_proj_size = classifier_proj_size
+
+ # XVector-specific parameters. Feel free to ignore for other classes.
+ self.tdnn_dim = list(tdnn_dim)
+ self.tdnn_kernel = list(tdnn_kernel)
+ self.tdnn_dilation = list(tdnn_dilation)
+ self.xvector_output_dim = xvector_output_dim
+
+ @property
+ def inputs_to_logits_ratio(self):
+ return functools.reduce(operator.mul, self.conv_stride, 1)
+
+
+__all__ = ["Wav2Vec2ConformerConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/modeling_wav2vec2_conformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/modeling_wav2vec2_conformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..b786e415546e8dd61ce7824ab2e4627621c51d8c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/modeling_wav2vec2_conformer.py
@@ -0,0 +1,1934 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/wav2vec2_conformer/modular_wav2vec2_conformer.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_wav2vec2_conformer.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+import math
+import warnings
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import numpy as np
+import torch
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ CausalLMOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+ Wav2Vec2BaseModelOutput,
+ XVectorOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...utils import (
+ ModelOutput,
+ auto_docstring,
+ is_peft_available,
+)
+from .configuration_wav2vec2_conformer import Wav2Vec2ConformerConfig
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`Wav2Vec2ConformerForPreTraining`], with potential hidden states and attentions.
+ """
+)
+class Wav2Vec2ConformerForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ projected_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ codevector_perplexity (`torch.FloatTensor` of shape `(1,)`):
+ The perplexity of the codevector distribution, used to measure the diversity of the codebook.
+ contrastive_loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ The contrastive loss (L_m) as stated in the [official paper](https://huggingface.co/papers/2006.11477).
+ diversity_loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ The diversity loss (L_d) as stated in the [official paper](https://huggingface.co/papers/2006.11477).
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ projected_states: Optional[torch.FloatTensor] = None
+ projected_quantized_states: Optional[torch.FloatTensor] = None
+ codevector_perplexity: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ contrastive_loss: Optional[torch.FloatTensor] = None
+ diversity_loss: Optional[torch.FloatTensor] = None
+
+
+class Wav2Vec2ConformerSamePadLayer(nn.Module):
+ def __init__(self, num_conv_pos_embeddings):
+ super().__init__()
+ self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0
+
+ def forward(self, hidden_states):
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, :, : -self.num_pad_remove]
+ return hidden_states
+
+
+class Wav2Vec2ConformerPositionalConvEmbedding(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=config.num_conv_pos_embeddings,
+ padding=config.num_conv_pos_embeddings // 2,
+ groups=config.num_conv_pos_embedding_groups,
+ )
+
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0):
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+ if hasattr(self.conv, "parametrizations"):
+ weight_g = self.conv.parametrizations.weight.original0
+ weight_v = self.conv.parametrizations.weight.original1
+ else:
+ weight_g = self.conv.weight_g
+ weight_v = self.conv.weight_v
+ deepspeed.zero.register_external_parameter(self, weight_v)
+ deepspeed.zero.register_external_parameter(self, weight_g)
+ else:
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+
+ self.padding = Wav2Vec2ConformerSamePadLayer(config.num_conv_pos_embeddings)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.padding(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2ConformerRotaryPositionalEmbedding(nn.Module):
+ """Rotary positional embedding
+ Reference : https://blog.eleuther.ai/rotary-embeddings/ Paper: https://huggingface.co/papers/2104.09864
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ dim = config.hidden_size // config.num_attention_heads
+ base = config.rotary_embedding_base
+
+ inv_freq = 1.0 / (base ** (torch.arange(0, dim, 2, dtype=torch.int64).float() / dim))
+ self.register_buffer("inv_freq", inv_freq)
+ self.cached_sequence_length = None
+ self.cached_rotary_positional_embedding = None
+
+ def forward(self, hidden_states):
+ sequence_length = hidden_states.shape[1]
+
+ if sequence_length == self.cached_sequence_length and self.cached_rotary_positional_embedding is not None:
+ return self.cached_rotary_positional_embedding
+
+ self.cached_sequence_length = sequence_length
+ # Embeddings are computed in the dtype of the inv_freq constant
+ time_stamps = torch.arange(sequence_length).type_as(self.inv_freq)
+ freqs = torch.einsum("i,j->ij", time_stamps, self.inv_freq)
+ embeddings = torch.cat((freqs, freqs), dim=-1)
+
+ cos_embeddings = embeddings.cos()[:, None, None, :]
+ sin_embeddings = embeddings.sin()[:, None, None, :]
+ # Computed embeddings are cast to the dtype of the hidden state inputs
+ self.cached_rotary_positional_embedding = torch.stack([cos_embeddings, sin_embeddings]).type_as(hidden_states)
+ return self.cached_rotary_positional_embedding
+
+
+class Wav2Vec2ConformerRelPositionalEmbedding(nn.Module):
+ """Relative positional encoding module."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.max_len = config.max_source_positions
+ self.d_model = config.hidden_size
+ self.pe = None
+ self.extend_pe(torch.tensor(0.0).expand(1, self.max_len))
+
+ def extend_pe(self, x):
+ # Reset the positional encodings
+ if self.pe is not None:
+ # self.pe contains both positive and negative parts
+ # the length of self.pe is 2 * input_len - 1
+ if self.pe.size(1) >= x.size(1) * 2 - 1:
+ if self.pe.dtype != x.dtype or self.pe.device != x.device:
+ self.pe = self.pe.to(dtype=x.dtype, device=x.device)
+ return
+ # Suppose `i` is the position of query vector and `j` is the
+ # position of key vector. We use positive relative positions when keys
+ # are to the left (i>j) and negative relative positions otherwise (i 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2ConformerLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+
+ hidden_states = hidden_states.transpose(-2, -1)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states.transpose(-2, -1)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2ConformerGroupNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2ConformerFeatureEncoder(nn.Module):
+ """Construct the features from raw audio waveform"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ if config.feat_extract_norm == "group":
+ conv_layers = [Wav2Vec2ConformerGroupNormConvLayer(config, layer_id=0)] + [
+ Wav2Vec2ConformerNoLayerNormConvLayer(config, layer_id=i + 1)
+ for i in range(config.num_feat_extract_layers - 1)
+ ]
+ elif config.feat_extract_norm == "layer":
+ conv_layers = [
+ Wav2Vec2ConformerLayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)
+ ]
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']"
+ )
+ self.conv_layers = nn.ModuleList(conv_layers)
+ self.gradient_checkpointing = False
+ self._requires_grad = True
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def forward(self, input_values):
+ hidden_states = input_values[:, None]
+
+ # make sure hidden_states require grad for gradient_checkpointing
+ if self._requires_grad and self.training:
+ hidden_states.requires_grad = True
+
+ for conv_layer in self.conv_layers:
+ hidden_states = conv_layer(hidden_states)
+
+ return hidden_states
+
+
+class Wav2Vec2ConformerFeatureProjection(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps)
+ self.projection = nn.Linear(config.conv_dim[-1], config.hidden_size)
+ self.dropout = nn.Dropout(config.feat_proj_dropout)
+
+ def forward(self, hidden_states):
+ # non-projected hidden states are needed for quantization
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states, norm_hidden_states
+
+
+class Wav2Vec2ConformerFeedForward(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.intermediate_dropout = nn.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ self.output_dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.output_dropout = nn.Dropout(config.hidden_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states)
+ return hidden_states
+
+
+class Wav2Vec2ConformerConvolutionModule(nn.Module):
+ """Convolution block used in the conformer block"""
+
+ def __init__(self, config):
+ super().__init__()
+ if (config.conv_depthwise_kernel_size - 1) % 2 == 1:
+ raise ValueError("`config.conv_depthwise_kernel_size` should be a odd number for 'SAME' padding")
+ self.layer_norm = nn.LayerNorm(config.hidden_size)
+ self.pointwise_conv1 = nn.Conv1d(
+ config.hidden_size,
+ 2 * config.hidden_size,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ bias=False,
+ )
+ self.glu = nn.GLU(dim=1)
+ self.depthwise_conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ config.conv_depthwise_kernel_size,
+ stride=1,
+ padding=(config.conv_depthwise_kernel_size - 1) // 2,
+ groups=config.hidden_size,
+ bias=False,
+ )
+ self.batch_norm = nn.BatchNorm1d(config.hidden_size)
+ self.activation = ACT2FN[config.hidden_act]
+ self.pointwise_conv2 = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ bias=False,
+ )
+ self.dropout = nn.Dropout(config.conformer_conv_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.layer_norm(hidden_states)
+ # exchange the temporal dimension and the feature dimension
+ hidden_states = hidden_states.transpose(1, 2)
+
+ # GLU mechanism
+ # => (batch, 2*channel, dim)
+ hidden_states = self.pointwise_conv1(hidden_states)
+ # => (batch, channel, dim)
+ hidden_states = self.glu(hidden_states)
+
+ # 1D Depthwise Conv
+ hidden_states = self.depthwise_conv(hidden_states)
+ hidden_states = self.batch_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = self.pointwise_conv2(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2ConformerSelfAttention(nn.Module):
+ """Construct an Wav2Vec2ConformerSelfAttention object.
+ Can be enhanced with rotary or relative position embeddings.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.head_size = config.hidden_size // config.num_attention_heads
+ self.num_heads = config.num_attention_heads
+ self.position_embeddings_type = config.position_embeddings_type
+
+ self.linear_q = nn.Linear(config.hidden_size, config.hidden_size)
+ self.linear_k = nn.Linear(config.hidden_size, config.hidden_size)
+ self.linear_v = nn.Linear(config.hidden_size, config.hidden_size)
+ self.linear_out = nn.Linear(config.hidden_size, config.hidden_size)
+
+ self.dropout = nn.Dropout(p=config.attention_dropout)
+
+ if self.position_embeddings_type == "relative":
+ # linear transformation for positional encoding
+ self.linear_pos = nn.Linear(config.hidden_size, config.hidden_size, bias=False)
+ # these two learnable bias are used in matrix c and matrix d
+ # as described in https://huggingface.co/papers/1901.02860 Section 3.3
+ self.pos_bias_u = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+ self.pos_bias_v = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ # self-attention mechanism
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ # make sure query/key states can be != value states
+ query_key_states = hidden_states
+ value_states = hidden_states
+
+ if self.position_embeddings_type == "rotary":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type == 'rotary'"
+ )
+ query_key_states = self._apply_rotary_embedding(query_key_states, relative_position_embeddings)
+
+ # project query_key_states and value_states
+ query = self.linear_q(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ key = self.linear_k(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ value = self.linear_v(value_states).view(batch_size, -1, self.num_heads, self.head_size)
+
+ # => (batch, head, time1, d_k)
+ query = query.transpose(1, 2)
+ key = key.transpose(1, 2)
+ value = value.transpose(1, 2)
+
+ if self.position_embeddings_type == "relative":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type =="
+ " 'relative'"
+ )
+ # apply relative_position_embeddings to qk scores
+ # as proposed in Transformer_XL: https://huggingface.co/papers/1901.02860
+ scores = self._apply_relative_embeddings(
+ query=query, key=key, relative_position_embeddings=relative_position_embeddings
+ )
+ else:
+ scores = torch.matmul(query, key.transpose(-2, -1)) / math.sqrt(self.head_size)
+
+ # apply attention_mask if necessary
+ if attention_mask is not None:
+ scores = scores + attention_mask
+
+ # => (batch, head, time1, time2)
+ probs = torch.softmax(scores, dim=-1)
+ probs = self.dropout(probs)
+
+ # => (batch, head, time1, d_k)
+ hidden_states = torch.matmul(probs, value)
+
+ # => (batch, time1, hidden_size)
+ hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, self.num_heads * self.head_size)
+ hidden_states = self.linear_out(hidden_states)
+
+ return hidden_states, probs
+
+ def _apply_rotary_embedding(self, hidden_states, relative_position_embeddings):
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+ hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads, self.head_size)
+
+ cos = relative_position_embeddings[0, :sequence_length, ...]
+ sin = relative_position_embeddings[1, :sequence_length, ...]
+
+ # rotate hidden_states with rotary embeddings
+ hidden_states = hidden_states.transpose(0, 1)
+ rotated_states_begin = hidden_states[..., : self.head_size // 2]
+ rotated_states_end = hidden_states[..., self.head_size // 2 :]
+ rotated_states = torch.cat((-rotated_states_end, rotated_states_begin), dim=rotated_states_begin.ndim - 1)
+ hidden_states = (hidden_states * cos) + (rotated_states * sin)
+ hidden_states = hidden_states.transpose(0, 1)
+
+ hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads * self.head_size)
+
+ return hidden_states
+
+ def _apply_relative_embeddings(self, query, key, relative_position_embeddings):
+ # 1. project positional embeddings
+ # => (batch, head, 2*time1-1, d_k)
+ proj_relative_position_embeddings = self.linear_pos(relative_position_embeddings)
+ proj_relative_position_embeddings = proj_relative_position_embeddings.view(
+ relative_position_embeddings.size(0), -1, self.num_heads, self.head_size
+ )
+ proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(1, 2)
+ proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(2, 3)
+
+ # 2. Add bias to query
+ # => (batch, head, time1, d_k)
+ query = query.transpose(1, 2)
+ q_with_bias_u = (query + self.pos_bias_u).transpose(1, 2)
+ q_with_bias_v = (query + self.pos_bias_v).transpose(1, 2)
+
+ # 3. attention score: first compute matrix a and matrix c
+ # as described in https://huggingface.co/papers/1901.02860 Section 3.3
+ # => (batch, head, time1, time2)
+ scores_ac = torch.matmul(q_with_bias_u, key.transpose(-2, -1))
+
+ # 4. then compute matrix b and matrix d
+ # => (batch, head, time1, 2*time1-1)
+ scores_bd = torch.matmul(q_with_bias_v, proj_relative_position_embeddings)
+
+ # 5. shift matrix b and matrix d
+ zero_pad = torch.zeros((*scores_bd.size()[:3], 1), device=scores_bd.device, dtype=scores_bd.dtype)
+ scores_bd_padded = torch.cat([zero_pad, scores_bd], dim=-1)
+ scores_bd_padded_shape = scores_bd.size()[:2] + (scores_bd.shape[3] + 1, scores_bd.shape[2])
+ scores_bd_padded = scores_bd_padded.view(*scores_bd_padded_shape)
+ scores_bd = scores_bd_padded[:, :, 1:].view_as(scores_bd)
+ scores_bd = scores_bd[:, :, :, : scores_bd.size(-1) // 2 + 1]
+
+ # 6. sum matrices
+ # => (batch, head, time1, time2)
+ scores = (scores_ac + scores_bd) / math.sqrt(self.head_size)
+
+ return scores
+
+
+class Wav2Vec2ConformerEncoderLayer(GradientCheckpointingLayer):
+ """Conformer block based on https://huggingface.co/papers/2005.08100."""
+
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.hidden_size
+ dropout = config.attention_dropout
+
+ # Feed-forward 1
+ self.ffn1_layer_norm = nn.LayerNorm(embed_dim)
+ self.ffn1 = Wav2Vec2ConformerFeedForward(config)
+
+ # Self-Attention
+ self.self_attn_layer_norm = nn.LayerNorm(embed_dim)
+ self.self_attn_dropout = nn.Dropout(dropout)
+ self.self_attn = Wav2Vec2ConformerSelfAttention(config)
+
+ # Conformer Convolution
+ self.conv_module = Wav2Vec2ConformerConvolutionModule(config)
+
+ # Feed-forward 2
+ self.ffn2_layer_norm = nn.LayerNorm(embed_dim)
+ self.ffn2 = Wav2Vec2ConformerFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(embed_dim)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ hidden_states = hidden_states
+
+ # 1. Feed-Forward 1 layer
+ residual = hidden_states
+ hidden_states = self.ffn1_layer_norm(hidden_states)
+ hidden_states = self.ffn1(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ residual = hidden_states
+
+ # 2. Self-Attention layer
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weigts = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.self_attn_dropout(hidden_states)
+ hidden_states = hidden_states + residual
+
+ # 3. Convolutional Layer
+ residual = hidden_states
+ hidden_states = self.conv_module(hidden_states)
+ hidden_states = residual + hidden_states
+
+ # 4. Feed-Forward 2 Layer
+ residual = hidden_states
+ hidden_states = self.ffn2_layer_norm(hidden_states)
+ hidden_states = self.ffn2(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ return hidden_states, attn_weigts
+
+
+class Wav2Vec2ConformerEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+
+ if config.position_embeddings_type == "relative":
+ self.embed_positions = Wav2Vec2ConformerRelPositionalEmbedding(config)
+ elif config.position_embeddings_type == "rotary":
+ self.embed_positions = Wav2Vec2ConformerRotaryPositionalEmbedding(config)
+ else:
+ self.embed_positions = None
+
+ self.pos_conv_embed = Wav2Vec2ConformerPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList([Wav2Vec2ConformerEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0.0
+
+ # extend attention_mask
+ attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype)
+ attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min
+ attention_mask = attention_mask.expand(
+ attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1]
+ )
+
+ hidden_states = self.dropout(hidden_states)
+
+ if self.embed_positions is not None:
+ relative_position_embeddings = self.embed_positions(hidden_states)
+ else:
+ relative_position_embeddings = None
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class Wav2Vec2ConformerGumbelVectorQuantizer(nn.Module):
+ """
+ Vector quantization using gumbel softmax. See `[CATEGORICAL REPARAMETERIZATION WITH
+ GUMBEL-SOFTMAX](https://huggingface.co/papers/1611.01144) for more information.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.num_groups = config.num_codevector_groups
+ self.num_vars = config.num_codevectors_per_group
+
+ if config.codevector_dim % self.num_groups != 0:
+ raise ValueError(
+ f"`config.codevector_dim {config.codevector_dim} must be divisible "
+ f"by `config.num_codevector_groups` {self.num_groups} for concatenation"
+ )
+
+ # storage for codebook variables (codewords)
+ self.codevectors = nn.Parameter(
+ torch.FloatTensor(1, self.num_groups * self.num_vars, config.codevector_dim // self.num_groups)
+ )
+ self.weight_proj = nn.Linear(config.conv_dim[-1], self.num_groups * self.num_vars)
+
+ # can be decayed for training
+ self.temperature = 2
+
+ @staticmethod
+ def _compute_perplexity(probs, mask=None):
+ if mask is not None:
+ mask_extended = mask.flatten()[:, None, None].expand(probs.shape)
+ probs = torch.where(mask_extended, probs, torch.zeros_like(probs))
+ marginal_probs = probs.sum(dim=0) / mask.sum()
+ else:
+ marginal_probs = probs.mean(dim=0)
+
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states, mask_time_indices=None):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(
+ hidden_states.float(), tau=self.temperature, hard=True
+ ).type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist, mask_time_indices)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs, mask_time_indices)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+class Wav2Vec2ConformerAdapter(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+
+ # feature dim might need to be down-projected
+ if config.output_hidden_size != config.hidden_size:
+ self.proj = nn.Linear(config.hidden_size, config.output_hidden_size)
+ self.proj_layer_norm = nn.LayerNorm(config.output_hidden_size)
+ else:
+ self.proj = self.proj_layer_norm = None
+
+ self.layers = nn.ModuleList(Wav2Vec2ConformerAdapterLayer(config) for _ in range(config.num_adapter_layers))
+ self.layerdrop = config.layerdrop
+
+ def forward(self, hidden_states):
+ # down project hidden_states if necessary
+ if self.proj is not None and self.proj_layer_norm is not None:
+ hidden_states = self.proj(hidden_states)
+ hidden_states = self.proj_layer_norm(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+
+ for layer in self.layers:
+ layerdrop_prob = np.random.random()
+ if not self.training or (layerdrop_prob > self.layerdrop):
+ hidden_states = layer(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2ConformerAdapterLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.output_hidden_size,
+ 2 * config.output_hidden_size,
+ config.adapter_kernel_size,
+ stride=config.adapter_stride,
+ padding=1,
+ )
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = nn.functional.glu(hidden_states, dim=1)
+
+ return hidden_states
+
+
+@auto_docstring
+class Wav2Vec2ConformerPreTrainedModel(PreTrainedModel):
+ config: Wav2Vec2ConformerConfig
+ base_model_prefix = "wav2vec2_conformer"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # Wav2Vec2ForPreTraining last 2 linear layers need standard Linear init.
+ if isinstance(module, Wav2Vec2ConformerForPreTraining):
+ module.project_hid.reset_parameters()
+ module.project_q.reset_parameters()
+ module.project_hid._is_hf_initialized = True
+ module.project_q._is_hf_initialized = True
+ # gumbel softmax requires special init
+ elif isinstance(module, Wav2Vec2ConformerGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, Wav2Vec2ConformerSelfAttention):
+ if hasattr(module, "pos_bias_u"):
+ nn.init.xavier_uniform_(module.pos_bias_u)
+ if hasattr(module, "pos_bias_v"):
+ nn.init.xavier_uniform_(module.pos_bias_v)
+ elif isinstance(module, Wav2Vec2ConformerPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, Wav2Vec2ConformerFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[torch.LongTensor, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: torch.LongTensor, add_adapter=None
+ ):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+ output_lengths = output_lengths.to(torch.long)
+
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+Wav2Vec2ConformerBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+@auto_docstring
+class Wav2Vec2ConformerModel(Wav2Vec2ConformerPreTrainedModel):
+ def __init__(self, config: Wav2Vec2ConformerConfig):
+ super().__init__(config)
+ self.config = config
+ self.feature_extractor = Wav2Vec2ConformerFeatureEncoder(config)
+ self.feature_projection = Wav2Vec2ConformerFeatureProjection(config)
+
+ # model only needs masking vector if mask prob is > 0.0
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ self.encoder = Wav2Vec2ConformerEncoder(config)
+
+ self.adapter = Wav2Vec2ConformerAdapter(config) if config.add_adapter else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.feature_extractor._freeze_parameters()
+
+ def _mask_hidden_states(
+ self,
+ hidden_states: torch.FloatTensor,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+ elif self.config.mask_time_prob > 0 and self.training:
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool)
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool)
+ mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1)
+ hidden_states[mask_feature_indices] = 0
+
+ return hidden_states
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Wav2Vec2ConformerBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states)
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return Wav2Vec2ConformerBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2Conformer Model with a quantizer and `VQ` head on top.
+ """
+)
+class Wav2Vec2ConformerForPreTraining(Wav2Vec2ConformerPreTrainedModel):
+ def __init__(self, config: Wav2Vec2ConformerConfig):
+ super().__init__(config)
+ self.wav2vec2_conformer = Wav2Vec2ConformerModel(config)
+ self.dropout_features = nn.Dropout(config.feat_quantizer_dropout)
+
+ self.quantizer = Wav2Vec2ConformerGumbelVectorQuantizer(config)
+
+ self.project_hid = nn.Linear(config.hidden_size, config.proj_codevector_dim)
+ self.project_q = nn.Linear(config.codevector_dim, config.proj_codevector_dim)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def set_gumbel_temperature(self, temperature: int):
+ """
+ Set the Gumbel softmax temperature to a given value. Only necessary for training
+ """
+ self.quantizer.temperature = temperature
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2_conformer.feature_extractor._freeze_parameters()
+
+ @staticmethod
+ def compute_contrastive_logits(
+ target_features: torch.FloatTensor,
+ negative_features: torch.FloatTensor,
+ predicted_features: torch.FloatTensor,
+ temperature: int = 0.1,
+ ):
+ """
+ Compute logits for contrastive loss based using cosine similarity as the distance measure between
+ `[positive_feature, negative_features]` and `[predicted_features]`. Additionally, temperature can be applied.
+ """
+ target_features = torch.cat([target_features, negative_features], dim=0)
+
+ logits = torch.cosine_similarity(predicted_features.float(), target_features.float(), dim=-1).type_as(
+ target_features
+ )
+
+ # apply temperature
+ logits = logits / temperature
+ return logits
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.BoolTensor] = None,
+ sampled_negative_indices: Optional[torch.BoolTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, Wav2Vec2ConformerForPreTrainingOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ sampled_negative_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_negatives)`, *optional*):
+ Indices indicating which quantized target vectors are used as negative sampled vectors in contrastive loss.
+ Required input for pre-training.
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, Wav2Vec2ConformerForPreTraining
+ >>> from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer import _compute_mask_indices, _sample_negative_indices
+ >>> from datasets import load_dataset
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2_conformer-base")
+ >>> model = Wav2Vec2ConformerForPreTraining.from_pretrained("facebook/wav2vec2_conformer-base")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> input_values = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt").input_values # Batch size 1
+
+ >>> # compute masked indices
+ >>> batch_size, raw_sequence_length = input_values.shape
+ >>> sequence_length = model._get_feat_extract_output_lengths(raw_sequence_length).item()
+ >>> mask_time_indices = _compute_mask_indices(
+ ... shape=(batch_size, sequence_length), mask_prob=0.2, mask_length=2
+ ... )
+ >>> sampled_negative_indices = _sample_negative_indices(
+ ... features_shape=(batch_size, sequence_length),
+ ... num_negatives=model.config.num_negatives,
+ ... mask_time_indices=mask_time_indices,
+ ... )
+ >>> mask_time_indices = torch.tensor(data=mask_time_indices, device=input_values.device, dtype=torch.long)
+ >>> sampled_negative_indices = torch.tensor(
+ ... data=sampled_negative_indices, device=input_values.device, dtype=torch.long
+ ... )
+
+ >>> with torch.no_grad():
+ ... outputs = model(input_values, mask_time_indices=mask_time_indices)
+
+ >>> # compute cosine similarity between predicted (=projected_states) and target (=projected_quantized_states)
+ >>> cosine_sim = torch.cosine_similarity(outputs.projected_states, outputs.projected_quantized_states, dim=-1)
+
+ >>> # show that cosine similarity is much higher than random
+ >>> cosine_sim[mask_time_indices.to(torch.bool)].mean() > 0.5
+ tensor(True)
+
+ >>> # for contrastive loss training model should be put into train mode
+ >>> model = model.train()
+ >>> loss = model(
+ ... input_values, mask_time_indices=mask_time_indices, sampled_negative_indices=sampled_negative_indices
+ ... ).loss
+ ```"""
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if mask_time_indices is not None:
+ mask_time_indices = mask_time_indices.to(torch.bool)
+
+ outputs = self.wav2vec2_conformer(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ mask_time_indices=mask_time_indices,
+ return_dict=return_dict,
+ )
+
+ # 1. project all transformed features (including masked) to final vq dim
+ transformer_features = self.project_hid(outputs[0])
+
+ # 2. quantize all (unmasked) extracted features and project to final vq dim
+ extract_features = self.dropout_features(outputs[1])
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ quantized_features, codevector_perplexity = self.quantizer(
+ extract_features, mask_time_indices=mask_time_indices
+ )
+
+ quantized_features = quantized_features.to(self.project_q.weight.dtype)
+ quantized_features = self.project_q(quantized_features)
+
+ loss = contrastive_loss = diversity_loss = None
+ if sampled_negative_indices is not None:
+ batch_size, sequence_length, hidden_size = quantized_features.shape
+
+ # for training, we sample negatives
+ # 3. sample K negatives (distractors) quantized states for contrastive loss
+ # if attention_mask is passed, make sure that padded feature vectors cannot be sampled
+ # sample negative quantized vectors BTC => (BxT)C
+ negative_quantized_features = quantized_features.view(-1, hidden_size)[
+ sampled_negative_indices.long().view(-1)
+ ]
+ negative_quantized_features = negative_quantized_features.view(
+ batch_size, sequence_length, -1, hidden_size
+ ).permute(2, 0, 1, 3)
+
+ # 4. compute logits, corresponding to `logs = sim(c_t, [q_t, \sim{q}_t]) / \kappa`
+ # of equation (3) in https://huggingface.co/papers/2006.11477
+ logits = self.compute_contrastive_logits(
+ quantized_features[None, :],
+ negative_quantized_features,
+ transformer_features,
+ self.config.contrastive_logits_temperature,
+ )
+
+ # 5. if a negative vector is identical to the positive (i.e. when codebook utilization is low),
+ # its cosine similarity will be masked
+ neg_is_pos = (quantized_features == negative_quantized_features).all(-1)
+
+ if neg_is_pos.any():
+ logits[1:][neg_is_pos] = float("-inf")
+
+ # 6. compute contrastive loss \mathbf{L}_m = cross_entropy(logs) =
+ # -log(exp(sim(c_t, q_t)/\kappa) / \sum_{\sim{q}} exp(sim(c_t, \sim{q})/\kappa))
+ logits = logits.transpose(0, 2).reshape(-1, logits.size(0))
+ target = ((1 - mask_time_indices.long()) * -100).transpose(0, 1).flatten()
+
+ contrastive_loss = nn.functional.cross_entropy(logits.float(), target, reduction="sum")
+ # 7. compute diversity loss: \mathbf{L}_d
+ num_codevectors = self.config.num_codevectors_per_group * self.config.num_codevector_groups
+ diversity_loss = ((num_codevectors - codevector_perplexity) / num_codevectors) * mask_time_indices.sum()
+
+ # 8. \mathbf{L} = \mathbf{L}_m + \alpha * \mathbf{L}_d
+ loss = contrastive_loss + self.config.diversity_loss_weight * diversity_loss
+
+ if not return_dict:
+ if loss is not None:
+ return (loss, transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+ return (transformer_features, quantized_features, codevector_perplexity) + outputs[2:]
+
+ return Wav2Vec2ConformerForPreTrainingOutput(
+ loss=loss,
+ projected_states=transformer_features,
+ projected_quantized_states=quantized_features,
+ codevector_perplexity=codevector_perplexity,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ contrastive_loss=contrastive_loss,
+ diversity_loss=diversity_loss,
+ )
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2Conformer Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).
+ """
+)
+class Wav2Vec2ConformerForCTC(Wav2Vec2ConformerPreTrainedModel):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`UniSpeechSatForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ self.wav2vec2_conformer = Wav2Vec2ConformerModel(config)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.target_lang = target_lang
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that "
+ "does not define the vocabulary size of the language model head. Please "
+ "instantiate the model as follows: `Wav2Vec2ConformerForCTC.from_pretrained(..., vocab_size=vocab_size)`. "
+ "or define `vocab_size` of your model's configuration."
+ )
+ output_hidden_size = (
+ config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size
+ )
+ self.lm_head = nn.Linear(output_hidden_size, config.vocab_size)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2_conformer.feature_extractor._freeze_parameters()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*):
+ Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to
+ the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`.
+ All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None and labels.max() >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ outputs = self.wav2vec2_conformer(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+
+ logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # retrieve loss input_lengths from attention_mask
+ attention_mask = (
+ attention_mask if attention_mask is not None else torch.ones_like(input_values, dtype=torch.long)
+ )
+ input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long)
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = labels >= 0
+ target_lengths = labels_mask.sum(-1)
+ flattened_targets = labels.masked_select(labels_mask)
+
+ # ctc_loss doesn't support fp16
+ log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1)
+
+ with torch.backends.cudnn.flags(enabled=False):
+ loss = nn.functional.ctc_loss(
+ log_probs,
+ flattened_targets,
+ input_lengths,
+ target_lengths,
+ blank=self.config.pad_token_id,
+ reduction=self.config.ctc_loss_reduction,
+ zero_infinity=self.config.ctc_zero_infinity,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return CausalLMOutput(
+ loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2Conformer Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like
+ SUPERB Keyword Spotting.
+ """
+)
+class Wav2Vec2ConformerForSequenceClassification(Wav2Vec2ConformerPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Sequence classification does not support the use of Wav2Vec2Conformer adapters (config.add_adapter=True)"
+ )
+ self.wav2vec2_conformer = Wav2Vec2ConformerModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size)
+ self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2_conformer.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2_conformer.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`Wav2Vec2ConformerProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_conformer(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = hidden_states.mean(dim=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask)
+ expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_padding_mask] = 0.0
+ pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class Wav2Vec2ConformerForAudioFrameClassification(Wav2Vec2ConformerPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Audio frame classification does not support the use of Wav2Vec2Conformer adapters (config.add_adapter=True)"
+ )
+ self.wav2vec2_conformer = Wav2Vec2ConformerModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+ self.num_labels = config.num_labels
+
+ self.init_weights()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2_conformer.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2_conformer.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`Wav2Vec2ConformerProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_conformer(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), torch.argmax(labels.view(-1, self.num_labels), axis=1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class AMSoftmaxLoss(nn.Module):
+ def __init__(self, input_dim, num_labels, scale=30.0, margin=0.4):
+ super().__init__()
+ self.scale = scale
+ self.margin = margin
+ self.num_labels = num_labels
+ self.weight = nn.Parameter(torch.randn(input_dim, num_labels), requires_grad=True)
+ self.loss = nn.CrossEntropyLoss()
+
+ def forward(self, hidden_states, labels):
+ labels = labels.flatten()
+ weight = nn.functional.normalize(self.weight, dim=0)
+ hidden_states = nn.functional.normalize(hidden_states, dim=1)
+ cos_theta = torch.mm(hidden_states, weight)
+ psi = cos_theta - self.margin
+
+ onehot = nn.functional.one_hot(labels, self.num_labels)
+ logits = self.scale * torch.where(onehot.bool(), psi, cos_theta)
+ loss = self.loss(logits, labels)
+
+ return loss
+
+
+class TDNNLayer(nn.Module):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.tdnn_dim[layer_id - 1] if layer_id > 0 else config.tdnn_dim[layer_id]
+ self.out_conv_dim = config.tdnn_dim[layer_id]
+ self.kernel_size = config.tdnn_kernel[layer_id]
+ self.dilation = config.tdnn_dilation[layer_id]
+
+ self.kernel = nn.Linear(self.in_conv_dim * self.kernel_size, self.out_conv_dim)
+ self.activation = nn.ReLU()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ if is_peft_available():
+ from peft.tuners.lora import LoraLayer
+
+ if is_peft_available():
+ if isinstance(self.kernel, LoraLayer):
+ warnings.warn(
+ "Detected LoRA on TDNNLayer. LoRA weights won't be applied due to optimization. "
+ "You should exclude TDNNLayer from LoRA's target modules.",
+ )
+
+ # for backward compatibility, we keep nn.Linear but call F.conv1d for speed up
+ hidden_states = hidden_states.transpose(1, 2)
+ weight = self.kernel.weight.view(self.out_conv_dim, self.kernel_size, self.in_conv_dim).transpose(1, 2)
+ hidden_states = nn.functional.conv1d(hidden_states, weight, self.kernel.bias, dilation=self.dilation)
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ Wav2Vec2Conformer Model with an XVector feature extraction head on top for tasks like Speaker Verification.
+ """
+)
+class Wav2Vec2ConformerForXVector(Wav2Vec2ConformerPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.wav2vec2_conformer = Wav2Vec2ConformerModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.tdnn_dim[0])
+
+ tdnn_layers = [TDNNLayer(config, i) for i in range(len(config.tdnn_dim))]
+ self.tdnn = nn.ModuleList(tdnn_layers)
+
+ self.feature_extractor = nn.Linear(config.tdnn_dim[-1] * 2, config.xvector_output_dim)
+ self.classifier = nn.Linear(config.xvector_output_dim, config.xvector_output_dim)
+
+ self.objective = AMSoftmaxLoss(config.xvector_output_dim, config.num_labels)
+
+ self.init_weights()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wav2vec2_conformer.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wav2vec2_conformer.parameters():
+ param.requires_grad = False
+
+ def _get_tdnn_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the TDNN layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size in self.config.tdnn_kernel:
+ input_lengths = _conv_out_length(input_lengths, kernel_size, 1)
+
+ return input_lengths
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, XVectorOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`Wav2Vec2ConformerProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wav2vec2_conformer(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+
+ for tdnn_layer in self.tdnn:
+ hidden_states = tdnn_layer(hidden_states)
+
+ # Statistic Pooling
+ if attention_mask is None:
+ mean_features = hidden_states.mean(dim=1)
+ std_features = hidden_states.std(dim=1)
+ else:
+ feat_extract_output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(dim=1))
+ tdnn_output_lengths = self._get_tdnn_output_lengths(feat_extract_output_lengths)
+ mean_features = []
+ std_features = []
+ for i, length in enumerate(tdnn_output_lengths):
+ mean_features.append(hidden_states[i, :length].mean(dim=0))
+ std_features.append(hidden_states[i, :length].std(dim=0))
+ mean_features = torch.stack(mean_features)
+ std_features = torch.stack(std_features)
+ statistic_pooling = torch.cat([mean_features, std_features], dim=-1)
+
+ output_embeddings = self.feature_extractor(statistic_pooling)
+ logits = self.classifier(output_embeddings)
+
+ loss = None
+ if labels is not None:
+ loss = self.objective(logits, labels)
+
+ if not return_dict:
+ output = (logits, output_embeddings) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XVectorOutput(
+ loss=loss,
+ logits=logits,
+ embeddings=output_embeddings,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "Wav2Vec2ConformerForAudioFrameClassification",
+ "Wav2Vec2ConformerForCTC",
+ "Wav2Vec2ConformerForPreTraining",
+ "Wav2Vec2ConformerForSequenceClassification",
+ "Wav2Vec2ConformerForXVector",
+ "Wav2Vec2ConformerModel",
+ "Wav2Vec2ConformerPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/modular_wav2vec2_conformer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/modular_wav2vec2_conformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..2c009c004453314f074f91d8ed89cf694c82726c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_conformer/modular_wav2vec2_conformer.py
@@ -0,0 +1,730 @@
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+from torch import nn
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, Wav2Vec2BaseModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import ModelOutput, auto_docstring, logging
+from ..wav2vec2.modeling_wav2vec2 import (
+ Wav2Vec2Adapter,
+ Wav2Vec2AdapterLayer,
+ Wav2Vec2FeatureEncoder,
+ Wav2Vec2FeatureProjection,
+ Wav2Vec2FeedForward,
+ Wav2Vec2ForAudioFrameClassification,
+ Wav2Vec2ForCTC,
+ Wav2Vec2ForPreTraining,
+ Wav2Vec2ForSequenceClassification,
+ Wav2Vec2ForXVector,
+ Wav2Vec2GumbelVectorQuantizer,
+ Wav2Vec2Model,
+ Wav2Vec2PositionalConvEmbedding,
+)
+from .configuration_wav2vec2_conformer import Wav2Vec2ConformerConfig
+
+
+logger = logging.get_logger(__name__)
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`Wav2Vec2ConformerForPreTraining`], with potential hidden states and attentions.
+ """
+)
+class Wav2Vec2ConformerForPreTrainingOutput(ModelOutput):
+ r"""
+ loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ Total loss as the sum of the contrastive loss (L_m) and the diversity loss (L_d) as stated in the [official
+ paper](https://huggingface.co/papers/2006.11477).
+ projected_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Hidden-states of the model projected to *config.proj_codevector_dim* that can be used to predict the masked
+ projected quantized states.
+ projected_quantized_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.proj_codevector_dim)`):
+ Quantized extracted feature vectors projected to *config.proj_codevector_dim* representing the positive
+ target vectors for contrastive loss.
+ codevector_perplexity (`torch.FloatTensor` of shape `(1,)`):
+ The perplexity of the codevector distribution, used to measure the diversity of the codebook.
+ contrastive_loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ The contrastive loss (L_m) as stated in the [official paper](https://huggingface.co/papers/2006.11477).
+ diversity_loss (*optional*, returned when `sample_negative_indices` are passed, `torch.FloatTensor` of shape `(1,)`):
+ The diversity loss (L_d) as stated in the [official paper](https://huggingface.co/papers/2006.11477).
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ projected_states: Optional[torch.FloatTensor] = None
+ projected_quantized_states: Optional[torch.FloatTensor] = None
+ codevector_perplexity: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+ contrastive_loss: Optional[torch.FloatTensor] = None
+ diversity_loss: Optional[torch.FloatTensor] = None
+
+
+class Wav2Vec2ConformerPositionalConvEmbedding(Wav2Vec2PositionalConvEmbedding):
+ pass
+
+
+class Wav2Vec2ConformerRotaryPositionalEmbedding(nn.Module):
+ """Rotary positional embedding
+ Reference : https://blog.eleuther.ai/rotary-embeddings/ Paper: https://huggingface.co/papers/2104.09864
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ dim = config.hidden_size // config.num_attention_heads
+ base = config.rotary_embedding_base
+
+ inv_freq = 1.0 / (base ** (torch.arange(0, dim, 2, dtype=torch.int64).float() / dim))
+ self.register_buffer("inv_freq", inv_freq)
+ self.cached_sequence_length = None
+ self.cached_rotary_positional_embedding = None
+
+ def forward(self, hidden_states):
+ sequence_length = hidden_states.shape[1]
+
+ if sequence_length == self.cached_sequence_length and self.cached_rotary_positional_embedding is not None:
+ return self.cached_rotary_positional_embedding
+
+ self.cached_sequence_length = sequence_length
+ # Embeddings are computed in the dtype of the inv_freq constant
+ time_stamps = torch.arange(sequence_length).type_as(self.inv_freq)
+ freqs = torch.einsum("i,j->ij", time_stamps, self.inv_freq)
+ embeddings = torch.cat((freqs, freqs), dim=-1)
+
+ cos_embeddings = embeddings.cos()[:, None, None, :]
+ sin_embeddings = embeddings.sin()[:, None, None, :]
+ # Computed embeddings are cast to the dtype of the hidden state inputs
+ self.cached_rotary_positional_embedding = torch.stack([cos_embeddings, sin_embeddings]).type_as(hidden_states)
+ return self.cached_rotary_positional_embedding
+
+
+class Wav2Vec2ConformerRelPositionalEmbedding(nn.Module):
+ """Relative positional encoding module."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.max_len = config.max_source_positions
+ self.d_model = config.hidden_size
+ self.pe = None
+ self.extend_pe(torch.tensor(0.0).expand(1, self.max_len))
+
+ def extend_pe(self, x):
+ # Reset the positional encodings
+ if self.pe is not None:
+ # self.pe contains both positive and negative parts
+ # the length of self.pe is 2 * input_len - 1
+ if self.pe.size(1) >= x.size(1) * 2 - 1:
+ if self.pe.dtype != x.dtype or self.pe.device != x.device:
+ self.pe = self.pe.to(dtype=x.dtype, device=x.device)
+ return
+ # Suppose `i` is the position of query vector and `j` is the
+ # position of key vector. We use positive relative positions when keys
+ # are to the left (i>j) and negative relative positions otherwise (i (batch, 2*channel, dim)
+ hidden_states = self.pointwise_conv1(hidden_states)
+ # => (batch, channel, dim)
+ hidden_states = self.glu(hidden_states)
+
+ # 1D Depthwise Conv
+ hidden_states = self.depthwise_conv(hidden_states)
+ hidden_states = self.batch_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = self.pointwise_conv2(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class Wav2Vec2ConformerSelfAttention(nn.Module):
+ """Construct an Wav2Vec2ConformerSelfAttention object.
+ Can be enhanced with rotary or relative position embeddings.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.head_size = config.hidden_size // config.num_attention_heads
+ self.num_heads = config.num_attention_heads
+ self.position_embeddings_type = config.position_embeddings_type
+
+ self.linear_q = nn.Linear(config.hidden_size, config.hidden_size)
+ self.linear_k = nn.Linear(config.hidden_size, config.hidden_size)
+ self.linear_v = nn.Linear(config.hidden_size, config.hidden_size)
+ self.linear_out = nn.Linear(config.hidden_size, config.hidden_size)
+
+ self.dropout = nn.Dropout(p=config.attention_dropout)
+
+ if self.position_embeddings_type == "relative":
+ # linear transformation for positional encoding
+ self.linear_pos = nn.Linear(config.hidden_size, config.hidden_size, bias=False)
+ # these two learnable bias are used in matrix c and matrix d
+ # as described in https://huggingface.co/papers/1901.02860 Section 3.3
+ self.pos_bias_u = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+ self.pos_bias_v = nn.Parameter(torch.zeros(self.num_heads, self.head_size))
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ # self-attention mechanism
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ # make sure query/key states can be != value states
+ query_key_states = hidden_states
+ value_states = hidden_states
+
+ if self.position_embeddings_type == "rotary":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type == 'rotary'"
+ )
+ query_key_states = self._apply_rotary_embedding(query_key_states, relative_position_embeddings)
+
+ # project query_key_states and value_states
+ query = self.linear_q(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ key = self.linear_k(query_key_states).view(batch_size, -1, self.num_heads, self.head_size)
+ value = self.linear_v(value_states).view(batch_size, -1, self.num_heads, self.head_size)
+
+ # => (batch, head, time1, d_k)
+ query = query.transpose(1, 2)
+ key = key.transpose(1, 2)
+ value = value.transpose(1, 2)
+
+ if self.position_embeddings_type == "relative":
+ if relative_position_embeddings is None:
+ raise ValueError(
+ "`relative_position_embeddings` has to be defined when `self.position_embeddings_type =="
+ " 'relative'"
+ )
+ # apply relative_position_embeddings to qk scores
+ # as proposed in Transformer_XL: https://huggingface.co/papers/1901.02860
+ scores = self._apply_relative_embeddings(
+ query=query, key=key, relative_position_embeddings=relative_position_embeddings
+ )
+ else:
+ scores = torch.matmul(query, key.transpose(-2, -1)) / math.sqrt(self.head_size)
+
+ # apply attention_mask if necessary
+ if attention_mask is not None:
+ scores = scores + attention_mask
+
+ # => (batch, head, time1, time2)
+ probs = torch.softmax(scores, dim=-1)
+ probs = self.dropout(probs)
+
+ # => (batch, head, time1, d_k)
+ hidden_states = torch.matmul(probs, value)
+
+ # => (batch, time1, hidden_size)
+ hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, self.num_heads * self.head_size)
+ hidden_states = self.linear_out(hidden_states)
+
+ return hidden_states, probs
+
+ def _apply_rotary_embedding(self, hidden_states, relative_position_embeddings):
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+ hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads, self.head_size)
+
+ cos = relative_position_embeddings[0, :sequence_length, ...]
+ sin = relative_position_embeddings[1, :sequence_length, ...]
+
+ # rotate hidden_states with rotary embeddings
+ hidden_states = hidden_states.transpose(0, 1)
+ rotated_states_begin = hidden_states[..., : self.head_size // 2]
+ rotated_states_end = hidden_states[..., self.head_size // 2 :]
+ rotated_states = torch.cat((-rotated_states_end, rotated_states_begin), dim=rotated_states_begin.ndim - 1)
+ hidden_states = (hidden_states * cos) + (rotated_states * sin)
+ hidden_states = hidden_states.transpose(0, 1)
+
+ hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads * self.head_size)
+
+ return hidden_states
+
+ def _apply_relative_embeddings(self, query, key, relative_position_embeddings):
+ # 1. project positional embeddings
+ # => (batch, head, 2*time1-1, d_k)
+ proj_relative_position_embeddings = self.linear_pos(relative_position_embeddings)
+ proj_relative_position_embeddings = proj_relative_position_embeddings.view(
+ relative_position_embeddings.size(0), -1, self.num_heads, self.head_size
+ )
+ proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(1, 2)
+ proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(2, 3)
+
+ # 2. Add bias to query
+ # => (batch, head, time1, d_k)
+ query = query.transpose(1, 2)
+ q_with_bias_u = (query + self.pos_bias_u).transpose(1, 2)
+ q_with_bias_v = (query + self.pos_bias_v).transpose(1, 2)
+
+ # 3. attention score: first compute matrix a and matrix c
+ # as described in https://huggingface.co/papers/1901.02860 Section 3.3
+ # => (batch, head, time1, time2)
+ scores_ac = torch.matmul(q_with_bias_u, key.transpose(-2, -1))
+
+ # 4. then compute matrix b and matrix d
+ # => (batch, head, time1, 2*time1-1)
+ scores_bd = torch.matmul(q_with_bias_v, proj_relative_position_embeddings)
+
+ # 5. shift matrix b and matrix d
+ zero_pad = torch.zeros((*scores_bd.size()[:3], 1), device=scores_bd.device, dtype=scores_bd.dtype)
+ scores_bd_padded = torch.cat([zero_pad, scores_bd], dim=-1)
+ scores_bd_padded_shape = scores_bd.size()[:2] + (scores_bd.shape[3] + 1, scores_bd.shape[2])
+ scores_bd_padded = scores_bd_padded.view(*scores_bd_padded_shape)
+ scores_bd = scores_bd_padded[:, :, 1:].view_as(scores_bd)
+ scores_bd = scores_bd[:, :, :, : scores_bd.size(-1) // 2 + 1]
+
+ # 6. sum matrices
+ # => (batch, head, time1, time2)
+ scores = (scores_ac + scores_bd) / math.sqrt(self.head_size)
+
+ return scores
+
+
+class Wav2Vec2ConformerEncoderLayer(GradientCheckpointingLayer):
+ """Conformer block based on https://huggingface.co/papers/2005.08100."""
+
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.hidden_size
+ dropout = config.attention_dropout
+
+ # Feed-forward 1
+ self.ffn1_layer_norm = nn.LayerNorm(embed_dim)
+ self.ffn1 = Wav2Vec2ConformerFeedForward(config)
+
+ # Self-Attention
+ self.self_attn_layer_norm = nn.LayerNorm(embed_dim)
+ self.self_attn_dropout = nn.Dropout(dropout)
+ self.self_attn = Wav2Vec2ConformerSelfAttention(config)
+
+ # Conformer Convolution
+ self.conv_module = Wav2Vec2ConformerConvolutionModule(config)
+
+ # Feed-forward 2
+ self.ffn2_layer_norm = nn.LayerNorm(embed_dim)
+ self.ffn2 = Wav2Vec2ConformerFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(embed_dim)
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask: Optional[torch.Tensor] = None,
+ relative_position_embeddings: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ ):
+ hidden_states = hidden_states
+
+ # 1. Feed-Forward 1 layer
+ residual = hidden_states
+ hidden_states = self.ffn1_layer_norm(hidden_states)
+ hidden_states = self.ffn1(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ residual = hidden_states
+
+ # 2. Self-Attention layer
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weigts = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.self_attn_dropout(hidden_states)
+ hidden_states = hidden_states + residual
+
+ # 3. Convolutional Layer
+ residual = hidden_states
+ hidden_states = self.conv_module(hidden_states)
+ hidden_states = residual + hidden_states
+
+ # 4. Feed-Forward 2 Layer
+ residual = hidden_states
+ hidden_states = self.ffn2_layer_norm(hidden_states)
+ hidden_states = self.ffn2(hidden_states)
+ hidden_states = hidden_states * 0.5 + residual
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ return hidden_states, attn_weigts
+
+
+class Wav2Vec2ConformerEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+
+ if config.position_embeddings_type == "relative":
+ self.embed_positions = Wav2Vec2ConformerRelPositionalEmbedding(config)
+ elif config.position_embeddings_type == "rotary":
+ self.embed_positions = Wav2Vec2ConformerRotaryPositionalEmbedding(config)
+ else:
+ self.embed_positions = None
+
+ self.pos_conv_embed = Wav2Vec2ConformerPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList([Wav2Vec2ConformerEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0.0
+
+ # extend attention_mask
+ attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype)
+ attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min
+ attention_mask = attention_mask.expand(
+ attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1]
+ )
+
+ hidden_states = self.dropout(hidden_states)
+
+ if self.embed_positions is not None:
+ relative_position_embeddings = self.embed_positions(hidden_states)
+ else:
+ relative_position_embeddings = None
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and dropout_probability < self.config.layerdrop
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ relative_position_embeddings=relative_position_embeddings,
+ output_attentions=output_attentions,
+ )
+ hidden_states = layer_outputs[0]
+
+ if skip_the_layer:
+ layer_outputs = (None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class Wav2Vec2ConformerGumbelVectorQuantizer(Wav2Vec2GumbelVectorQuantizer):
+ pass
+
+
+class Wav2Vec2ConformerAdapter(Wav2Vec2Adapter):
+ pass
+
+
+class Wav2Vec2ConformerAdapterLayer(Wav2Vec2AdapterLayer):
+ pass
+
+
+@auto_docstring
+class Wav2Vec2ConformerPreTrainedModel(PreTrainedModel):
+ config: Wav2Vec2ConformerConfig
+ base_model_prefix = "wav2vec2_conformer"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # Wav2Vec2ForPreTraining last 2 linear layers need standard Linear init.
+ if isinstance(module, Wav2Vec2ConformerForPreTraining):
+ module.project_hid.reset_parameters()
+ module.project_q.reset_parameters()
+ module.project_hid._is_hf_initialized = True
+ module.project_q._is_hf_initialized = True
+ # gumbel softmax requires special init
+ elif isinstance(module, Wav2Vec2ConformerGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, Wav2Vec2ConformerSelfAttention):
+ if hasattr(module, "pos_bias_u"):
+ nn.init.xavier_uniform_(module.pos_bias_u)
+ if hasattr(module, "pos_bias_v"):
+ nn.init.xavier_uniform_(module.pos_bias_v)
+ elif isinstance(module, Wav2Vec2ConformerPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, Wav2Vec2ConformerFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[torch.LongTensor, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: torch.LongTensor, add_adapter=None
+ ):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+ output_lengths = output_lengths.to(torch.long)
+
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+WAV2VEC2_CONFORMER_START_DOCSTRING = None # will be automatically redefined
+
+
+Wav2Vec2ConformerBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+class Wav2Vec2ConformerModel(Wav2Vec2ConformerPreTrainedModel, Wav2Vec2Model):
+ def __init__(self, config: Wav2Vec2ConformerConfig):
+ Wav2Vec2ConformerPreTrainedModel.__init__(self, config)
+ self.config = config
+ self.feature_extractor = Wav2Vec2ConformerFeatureEncoder(config)
+ self.feature_projection = Wav2Vec2ConformerFeatureProjection(config)
+
+ # model only needs masking vector if mask prob is > 0.0
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ self.encoder = Wav2Vec2ConformerEncoder(config)
+
+ self.adapter = Wav2Vec2ConformerAdapter(config) if config.add_adapter else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+
+class Wav2Vec2ConformerForPreTraining(Wav2Vec2ForPreTraining):
+ def __init__(self, config: Wav2Vec2ConformerConfig):
+ super().__init__(config)
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+
+class Wav2Vec2ConformerForCTC(Wav2Vec2ForCTC):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`UniSpeechSatForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ def tie_weights(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+ def freeze_base_model(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+
+class Wav2Vec2ConformerForSequenceClassification(Wav2Vec2ForSequenceClassification):
+ def __init__(self, config):
+ super().__init__(config)
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+
+class Wav2Vec2ConformerForAudioFrameClassification(Wav2Vec2ForAudioFrameClassification):
+ def __init__(self, config):
+ super().__init__(config)
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+
+class Wav2Vec2ConformerForXVector(Wav2Vec2ForXVector):
+ def __init__(self, config):
+ super().__init__(config)
+
+ def freeze_feature_extractor(self):
+ raise AttributeError("Not needed for Wav2Vec2Conformer")
+
+
+__all__ = [
+ "Wav2Vec2ConformerForAudioFrameClassification",
+ "Wav2Vec2ConformerForCTC",
+ "Wav2Vec2ConformerForPreTraining",
+ "Wav2Vec2ConformerForSequenceClassification",
+ "Wav2Vec2ConformerForXVector",
+ "Wav2Vec2ConformerModel",
+ "Wav2Vec2ConformerPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_phoneme/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_phoneme/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..cbddfb4fe92d2c48a3c8f5ee7f8340650616e691
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_phoneme/__init__.py
@@ -0,0 +1,26 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .tokenization_wav2vec2_phoneme import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_phoneme/tokenization_wav2vec2_phoneme.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_phoneme/tokenization_wav2vec2_phoneme.py
new file mode 100644
index 0000000000000000000000000000000000000000..0715e3ce60f2450a3fa34cdef5a04ea79904b09b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_phoneme/tokenization_wav2vec2_phoneme.py
@@ -0,0 +1,580 @@
+# coding=utf-8
+# Copyright 2021 The Facebook Inc. and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization class for Wav2Vec2Phoneme."""
+
+import json
+import os
+from dataclasses import dataclass
+from itertools import groupby
+from typing import TYPE_CHECKING, Any, Optional, Union
+
+import numpy as np
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...tokenization_utils_base import AddedToken
+from ...utils import (
+ ModelOutput,
+ is_flax_available,
+ is_tf_available,
+ is_torch_available,
+ logging,
+ requires_backends,
+ to_py_obj,
+)
+
+
+logger = logging.get_logger(__name__)
+
+
+if TYPE_CHECKING:
+ if is_torch_available():
+ import torch
+ if is_tf_available():
+ import tensorflow as tf
+ if is_flax_available():
+ import jax.numpy as jnp # noqa: F401
+
+
+VOCAB_FILES_NAMES = {
+ "vocab_file": "vocab.json",
+ "tokenizer_config_file": "tokenizer_config.json",
+}
+
+
+# Wav2Vec2Phoneme has no max input length
+
+
+ListOfDict = list[dict[str, Union[int, str]]]
+
+
+@dataclass
+class Wav2Vec2PhonemeCTCTokenizerOutput(ModelOutput):
+ """
+ Output type of [` Wav2Vec2PhonemeCTCTokenizer`], with transcription.
+
+ Args:
+ text (list of `str` or `str`):
+ Decoded logits in text from. Usually the speech transcription.
+ char_offsets (list of `list[dict[str, Union[int, str]]]` or `list[dict[str, Union[int, str]]]`):
+ Offsets of the decoded characters. In combination with sampling rate and model downsampling rate char
+ offsets can be used to compute time stamps for each character. Total logit score of the beam associated with
+ produced text.
+ """
+
+ text: Union[list[str], str]
+ char_offsets: Union[list[ListOfDict], ListOfDict] = None
+
+
+class Wav2Vec2PhonemeCTCTokenizer(PreTrainedTokenizer):
+ """
+ Constructs a Wav2Vec2PhonemeCTC tokenizer.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains some of the main methods. Users should refer to
+ the superclass for more information regarding such methods.
+
+ Args:
+ vocab_file (`str`):
+ File containing the vocabulary.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sentence token.
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sentence token.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ do_phonemize (`bool`, *optional*, defaults to `True`):
+ Whether the tokenizer should phonetize the input or not. Only if a sequence of phonemes is passed to the
+ tokenizer, `do_phonemize` should be set to `False`.
+ phonemizer_lang (`str`, *optional*, defaults to `"en-us"`):
+ The language of the phoneme set to which the tokenizer should phonetize the input text to.
+ phonemizer_backend (`str`, *optional*. defaults to `"espeak"`):
+ The backend phonetization library that shall be used by the phonemizer library. Defaults to `espeak-ng`.
+ See the [phonemizer package](https://github.com/bootphon/phonemizer#readme). for more information.
+
+ **kwargs
+ Additional keyword arguments passed along to [`PreTrainedTokenizer`]
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ bos_token="",
+ eos_token=" ",
+ unk_token="",
+ pad_token="",
+ phone_delimiter_token=" ",
+ word_delimiter_token=None,
+ do_phonemize=True,
+ phonemizer_lang="en-us",
+ phonemizer_backend="espeak",
+ **kwargs,
+ ):
+ self._word_delimiter_token = word_delimiter_token
+ self._phone_delimiter_token = phone_delimiter_token
+ self.do_phonemize = do_phonemize
+ self.phonemizer_lang = phonemizer_lang
+ self.phonemizer_backend = phonemizer_backend
+
+ if do_phonemize:
+ self.init_backend(self.phonemizer_lang)
+
+ with open(vocab_file, encoding="utf-8") as vocab_handle:
+ self.encoder = json.load(vocab_handle)
+ self.decoder = {v: k for k, v in self.encoder.items()}
+
+ super().__init__(
+ unk_token=unk_token,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ pad_token=pad_token,
+ word_delimiter_token=word_delimiter_token,
+ phone_delimiter_token=phone_delimiter_token,
+ do_phonemize=do_phonemize,
+ phonemizer_lang=phonemizer_lang,
+ phonemizer_backend=phonemizer_backend,
+ **kwargs,
+ )
+
+ @property
+ def vocab_size(self) -> int:
+ return len(self.decoder)
+
+ def get_vocab(self) -> dict:
+ vocab = dict(self.encoder.copy())
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def _add_tokens(self, new_tokens: Union[list[str], list[AddedToken]], special_tokens: bool = False) -> int:
+ # Overwritten to never strip!
+ to_add = []
+ for token in new_tokens:
+ if isinstance(token, str):
+ to_add.append(AddedToken(token, rstrip=False, lstrip=False, normalized=True, special=special_tokens))
+ else:
+ to_add.append(token)
+
+ return super()._add_tokens(to_add, special_tokens)
+
+ def init_backend(self, phonemizer_lang: str):
+ """
+ Initializes the backend.
+
+ Args:
+ phonemizer_lang (`str`): The language to be used.
+ """
+ requires_backends(self, "phonemizer")
+ from phonemizer.backend import BACKENDS
+
+ self.backend = BACKENDS[self.phonemizer_backend](phonemizer_lang, language_switch="remove-flags")
+
+ def prepare_for_tokenization(
+ self,
+ text: str,
+ is_split_into_words: bool = False,
+ phonemizer_lang: Optional[str] = None,
+ do_phonemize: Optional[bool] = None,
+ ) -> tuple[str, dict[str, Any]]:
+ """
+ Performs any necessary transformations before tokenization.
+
+ This method should pop the arguments from kwargs and return the remaining `kwargs` as well. We test the
+ `kwargs` at the end of the encoding process to be sure all the arguments have been used.
+
+ Args:
+ text (`str`):
+ The text to prepare.
+ is_split_into_words (`bool`, *optional*, defaults to `False`):
+ Whether or not the input is already pre-tokenized (e.g., split into words). If set to `True`, the
+ tokenizer assumes the input is already split into words (for instance, by splitting it on whitespace)
+ which it will tokenize. This is useful for NER or token classification.
+ phonemizer_lang (`str`, *optional*):
+ The language of the phoneme set to which the tokenizer should phonetize the input text to.
+ do_phonemize (`bool`, *optional*):
+ Whether the tokenizer should phonetize the input text or not. Only if a sequence of phonemes is passed
+ to the tokenizer, `do_phonemize` should be set to `False`.
+
+
+ Returns:
+ `tuple[str, dict[str, Any]]`: The prepared text and the unused kwargs.
+ """
+ if is_split_into_words:
+ text = " " + text
+
+ # set whether tokenizer should phonemize or not
+ if do_phonemize is not None:
+ self.do_phonemize = do_phonemize
+
+ # set the correct phonemizer language
+ if phonemizer_lang is not None:
+ self.phonemizer_lang = phonemizer_lang
+ self.init_backend(phonemizer_lang)
+
+ return (text, {})
+
+ def _tokenize(self, text, **kwargs):
+ """
+ Converts a string into a sequence of tokens (string), using the tokenizer.
+ """
+
+ # make sure whitespace is stripped to prevent
+ text = text.strip()
+
+ # phonemize
+ if self.do_phonemize:
+ text = text.lower()
+
+ # create list of phonemes
+ text = self.phonemize(text, self.phonemizer_lang)
+
+ # make sure ' ' is between phonemes
+ tokens = text.split(" ")
+
+ tokens = list(filter(lambda p: p.strip() != "", tokens))
+ return tokens
+
+ def phonemize(self, text: str, phonemizer_lang: Optional[str] = None) -> str:
+ from phonemizer.separator import Separator
+
+ word_delimiter = self.word_delimiter_token + " " if self.word_delimiter_token is not None else ""
+ if phonemizer_lang is not None and phonemizer_lang != self.phonemizer_lang:
+ self.init_backend(phonemizer_lang)
+ else:
+ phonemizer_lang = self.phonemizer_lang
+
+ separator = Separator(phone=self.phone_delimiter_token, word=word_delimiter, syllable="")
+ phonemes = self.backend.phonemize(
+ [text],
+ separator=separator,
+ )
+ phonemes = phonemes[0].strip()
+
+ return phonemes
+
+ @property
+ def word_delimiter_token(self) -> str:
+ """
+ `str`: Word delimiter token. Log an error if used while not having been set.
+ """
+ if self._word_delimiter_token is None:
+ if self.verbose:
+ logger.error("Using word_delimiter_token, but it is not set yet.")
+ return None
+ return str(self._word_delimiter_token)
+
+ @property
+ def word_delimiter_token_id(self) -> Optional[int]:
+ """
+ `Optional[int]`: Id of the word_delimiter_token in the vocabulary. Returns `None` if the token has not been
+ set.
+ """
+ if self._word_delimiter_token is None:
+ return None
+ return self.convert_tokens_to_ids(self.word_delimiter_token)
+
+ @word_delimiter_token.setter
+ def word_delimiter_token(self, value):
+ self._word_delimiter_token = value
+
+ @word_delimiter_token_id.setter
+ def word_delimiter_token_id(self, value):
+ self._word_delimiter_token = self.convert_tokens_to_ids(value)
+
+ @property
+ def phone_delimiter_token(self) -> str:
+ """
+ `str`: Word delimiter token. Log an error if used while not having been set.
+ """
+ if self._phone_delimiter_token is None:
+ if self.verbose:
+ logger.error("Using phone_delimiter_token, but it is not set yet.")
+ return None
+ return str(self._phone_delimiter_token)
+
+ @property
+ def phone_delimiter_token_id(self) -> Optional[int]:
+ """
+ `Optional[int]`: Id of the phone_delimiter_token in the vocabulary. Returns `None` if the token has not been
+ set.
+ """
+ if self._phone_delimiter_token is None:
+ return None
+ return self.convert_tokens_to_ids(self.phone_delimiter_token)
+
+ @phone_delimiter_token.setter
+ def phone_delimiter_token(self, value):
+ self._phone_delimiter_token = value
+
+ @phone_delimiter_token_id.setter
+ def phone_delimiter_token_id(self, value):
+ self._phone_delimiter_token = self.convert_tokens_to_ids(value)
+
+ def _convert_token_to_id(self, token: str) -> int:
+ """Converts a token (str) in an index (integer) using the vocab."""
+ return self.encoder.get(token, self.encoder.get(self.unk_token))
+
+ def _convert_id_to_token(self, index: int) -> str:
+ """Converts an index (integer) in a token (str) using the vocab."""
+ result = self.decoder.get(index, self.unk_token)
+ return result
+
+ def convert_tokens_to_string(
+ self,
+ tokens: list[str],
+ group_tokens: bool = True,
+ spaces_between_special_tokens: bool = False,
+ filter_word_delimiter_token: bool = True,
+ output_char_offsets: bool = False,
+ ) -> str:
+ """
+ Converts a connectionist-temporal-classification (CTC) output tokens into a single string.
+ """
+ # group same tokens into non-repeating tokens in CTC style decoding
+ if group_tokens:
+ chars, char_repetitions = zip(*((token, len(list(group_iter))) for token, group_iter in groupby(tokens)))
+ else:
+ chars = tokens
+ char_repetitions = len(tokens) * [1]
+
+ # filter self.pad_token which is used as CTC-blank token
+ processed_chars = list(filter(lambda char: char != self.pad_token, chars))
+
+ # also filter self.word_delimiter_token if not not
+ if filter_word_delimiter_token and self.word_delimiter_token is not None:
+ processed_chars = list(filter(lambda token: token != self.word_delimiter_token, processed_chars))
+
+ # retrieve offsets
+ char_offsets = None
+ if output_char_offsets:
+ word_delimiter_token_for_offsets = (
+ self.word_delimiter_token if filter_word_delimiter_token is True else None
+ )
+ char_offsets = self._compute_offsets(
+ char_repetitions, chars, self.pad_token, word_delimiter_token=word_delimiter_token_for_offsets
+ )
+
+ if len(char_offsets) != len(processed_chars):
+ raise ValueError(
+ f"`char_offsets`: {char_offsets} and `processed_tokens`: {processed_chars}"
+ " have to be of the same length, but are: `len(offsets)`: "
+ f"{len(char_offsets)} and `len(processed_tokens)`: {len(processed_chars)}"
+ )
+
+ # set tokens to correct processed token
+ for i, char in enumerate(processed_chars):
+ char_offsets[i]["char"] = char
+
+ string = " ".join(processed_chars).strip()
+
+ return {"text": string, "char_offsets": char_offsets}
+
+ @staticmethod
+ def _compute_offsets(
+ char_repetitions: list[int], chars: list[str], ctc_token: int, word_delimiter_token: Optional[int] = None
+ ) -> list[dict[str, Union[str, int]]]:
+ end_indices = np.asarray(char_repetitions).cumsum()
+ start_indices = np.concatenate(([0], end_indices[:-1]))
+
+ offsets = [
+ {"char": t, "start_offset": s, "end_offset": e} for t, s, e in zip(chars, start_indices, end_indices)
+ ]
+
+ # filter out CTC token
+ offsets = list(filter(lambda offsets: offsets["char"] != ctc_token, offsets))
+
+ # filter out word delimiter token if necessary
+ if word_delimiter_token is not None:
+ offsets = list(filter(lambda offsets: offsets["char"] != word_delimiter_token, offsets))
+
+ return offsets
+
+ def _decode(
+ self,
+ token_ids: list[int],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ group_tokens: bool = True,
+ filter_word_delimiter_token: bool = True,
+ spaces_between_special_tokens: bool = False,
+ output_char_offsets: bool = False,
+ ) -> str:
+ """
+ special _decode function is needed for Wav2Vec2PhonemeTokenizer because added tokens should be treated exactly
+ the same as tokens of the base vocabulary and therefore the function `convert_tokens_to_string` has to be
+ called on the whole token list and not individually on added tokens
+ """
+ filtered_tokens = self.convert_ids_to_tokens(token_ids, skip_special_tokens=skip_special_tokens)
+
+ result = []
+ for token in filtered_tokens:
+ if skip_special_tokens and token in self.all_special_ids:
+ continue
+ result.append(token)
+
+ string_output = self.convert_tokens_to_string(
+ result,
+ group_tokens=group_tokens,
+ spaces_between_special_tokens=spaces_between_special_tokens,
+ filter_word_delimiter_token=filter_word_delimiter_token,
+ output_char_offsets=output_char_offsets,
+ )
+
+ text = string_output["text"]
+
+ clean_up_tokenization_spaces = (
+ clean_up_tokenization_spaces
+ if clean_up_tokenization_spaces is not None
+ else self.clean_up_tokenization_spaces
+ )
+ if clean_up_tokenization_spaces:
+ text = self.clean_up_tokenization(text)
+
+ if output_char_offsets:
+ return Wav2Vec2PhonemeCTCTokenizerOutput(text=text, char_offsets=string_output["char_offsets"])
+ else:
+ return text
+
+ # overwritten from `tokenization_utils_base.py` because we need docs for `output_char_offsets` here
+ def decode(
+ self,
+ token_ids: Union[int, list[int], "np.ndarray", "torch.Tensor", "tf.Tensor"],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ output_char_offsets: bool = False,
+ **kwargs,
+ ) -> str:
+ """
+ Converts a sequence of ids in a string, using the tokenizer and vocabulary with options to remove special
+ tokens and clean up tokenization spaces.
+
+ Similar to doing `self.convert_tokens_to_string(self.convert_ids_to_tokens(token_ids))`.
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens in the decoding.
+ clean_up_tokenization_spaces (`bool`, *optional*):
+ Whether or not to clean up the tokenization spaces.
+ output_char_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output character offsets. Character offsets can be used in combination with the
+ sampling rate and model downsampling rate to compute the time-stamps of transcribed characters.
+
+
+
+ Please take a look at the Example of [`~models.wav2vec2.tokenization_wav2vec2.decode`] to better
+ understand how to make use of `output_word_offsets`.
+ [`~model.wav2vec2_phoneme.tokenization_wav2vec2_phoneme.batch_decode`] works the same way with
+ phonemes.
+
+
+
+ kwargs (additional keyword arguments, *optional*):
+ Will be passed to the underlying model specific decode method.
+
+ Returns:
+ `str` or [`~models.wav2vec2.tokenization_wav2vec2_phoneme.Wav2Vec2PhonemeCTCTokenizerOutput`]: The decoded
+ sentence. Will be a [`~models.wav2vec2.tokenization_wav2vec2_phoneme.Wav2Vec2PhonemeCTCTokenizerOutput`]
+ when `output_char_offsets == True`.
+ """
+ # Convert inputs to python lists
+ token_ids = to_py_obj(token_ids)
+
+ return self._decode(
+ token_ids=token_ids,
+ skip_special_tokens=skip_special_tokens,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ output_char_offsets=output_char_offsets,
+ **kwargs,
+ )
+
+ # overwritten from `tokenization_utils_base.py` because tokenizer can output
+ # `ModelOutput` which should not be a list for batched output and because
+ # we need docs for `output_char_offsets` here
+ def batch_decode(
+ self,
+ sequences: Union[list[int], list[list[int]], "np.ndarray", "torch.Tensor", "tf.Tensor"],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ output_char_offsets: bool = False,
+ **kwargs,
+ ) -> list[str]:
+ """
+ Convert a list of lists of token ids into a list of strings by calling decode.
+
+ Args:
+ sequences (`Union[list[int], list[list[int]], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens in the decoding.
+ clean_up_tokenization_spaces (`bool`, *optional*):
+ Whether or not to clean up the tokenization spaces.
+ output_char_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output character offsets. Character offsets can be used in combination with the
+ sampling rate and model downsampling rate to compute the time-stamps of transcribed characters.
+
+
+
+ Please take a look at the Example of [`~models.wav2vec2.tokenization_wav2vec2.decode`] to better
+ understand how to make use of `output_word_offsets`.
+ [`~model.wav2vec2_phoneme.tokenization_wav2vec2_phoneme.batch_decode`] works analogous with phonemes
+ and batched output.
+
+
+
+ kwargs (additional keyword arguments, *optional*):
+ Will be passed to the underlying model specific decode method.
+
+ Returns:
+ `list[str]` or [`~models.wav2vec2.tokenization_wav2vec2_phoneme.Wav2Vec2PhonemeCTCTokenizerOutput`]: The
+ decoded sentence. Will be a
+ [`~models.wav2vec2.tokenization_wav2vec2_phoneme.Wav2Vec2PhonemeCTCTokenizerOutput`] when
+ `output_char_offsets == True`.
+ """
+ batch_decoded = [
+ self.decode(
+ seq,
+ skip_special_tokens=skip_special_tokens,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ output_char_offsets=output_char_offsets,
+ **kwargs,
+ )
+ for seq in sequences
+ ]
+ if output_char_offsets:
+ # transform list of dicts to dict of lists
+ return Wav2Vec2PhonemeCTCTokenizerOutput({k: [d[k] for d in batch_decoded] for k in batch_decoded[0]})
+
+ return batch_decoded
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ with open(vocab_file, "w", encoding="utf-8") as f:
+ f.write(json.dumps(self.encoder, indent=2, sort_keys=True, ensure_ascii=False) + "\n")
+
+ return (vocab_file,)
+
+
+__all__ = ["Wav2Vec2PhonemeCTCTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_with_lm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_with_lm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..95fd10dab7092fb8571a332b1ecf2e9a334d8fc4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_with_lm/__init__.py
@@ -0,0 +1,26 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .processing_wav2vec2_with_lm import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_with_lm/processing_wav2vec2_with_lm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_with_lm/processing_wav2vec2_with_lm.py
new file mode 100644
index 0000000000000000000000000000000000000000..beb22ca86749f01cde572cad7fe0b19e01f1e415
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wav2vec2_with_lm/processing_wav2vec2_with_lm.py
@@ -0,0 +1,659 @@
+# coding=utf-8
+# Copyright 2021 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Speech processor class for Wav2Vec2
+"""
+
+import os
+import warnings
+from collections.abc import Iterable
+from contextlib import contextmanager, nullcontext
+from dataclasses import dataclass
+from multiprocessing import Pool, get_context, get_start_method
+from typing import TYPE_CHECKING, Optional, Union
+
+import numpy as np
+
+from ...processing_utils import ProcessorMixin
+from ...utils import ModelOutput, logging, requires_backends
+
+
+logger = logging.get_logger(__name__)
+
+
+if TYPE_CHECKING:
+ from pyctcdecode import BeamSearchDecoderCTC
+
+ from ...feature_extraction_utils import FeatureExtractionMixin
+ from ...tokenization_utils import PreTrainedTokenizerBase
+
+
+ListOfDict = list[dict[str, Union[int, str]]]
+
+
+@dataclass
+class Wav2Vec2DecoderWithLMOutput(ModelOutput):
+ """
+ Output type of [`Wav2Vec2DecoderWithLM`], with transcription.
+
+ Args:
+ text (list of `str` or `str`):
+ Decoded logits in text from. Usually the speech transcription.
+ logit_score (list of `float` or `float`):
+ Total logit score of the beams associated with produced text.
+ lm_score (list of `float`):
+ Fused lm_score of the beams associated with produced text.
+ word_offsets (list of `list[dict[str, Union[int, str]]]` or `list[dict[str, Union[int, str]]]`):
+ Offsets of the decoded words. In combination with sampling rate and model downsampling rate word offsets
+ can be used to compute time stamps for each word.
+ """
+
+ text: Union[list[list[str]], list[str], str]
+ logit_score: Union[list[list[float]], list[float], float] = None
+ lm_score: Union[list[list[float]], list[float], float] = None
+ word_offsets: Union[list[list[ListOfDict]], list[ListOfDict], ListOfDict] = None
+
+
+class Wav2Vec2ProcessorWithLM(ProcessorMixin):
+ r"""
+ Constructs a Wav2Vec2 processor which wraps a Wav2Vec2 feature extractor, a Wav2Vec2 CTC tokenizer and a decoder
+ with language model support into a single processor for language model boosted speech recognition decoding.
+
+ Args:
+ feature_extractor ([`Wav2Vec2FeatureExtractor`] or [`SeamlessM4TFeatureExtractor`]):
+ An instance of [`Wav2Vec2FeatureExtractor`] or [`SeamlessM4TFeatureExtractor`]. The feature extractor is a required input.
+ tokenizer ([`Wav2Vec2CTCTokenizer`]):
+ An instance of [`Wav2Vec2CTCTokenizer`]. The tokenizer is a required input.
+ decoder (`pyctcdecode.BeamSearchDecoderCTC`):
+ An instance of [`pyctcdecode.BeamSearchDecoderCTC`]. The decoder is a required input.
+ """
+
+ feature_extractor_class = "AutoFeatureExtractor"
+ tokenizer_class = "Wav2Vec2CTCTokenizer"
+
+ def __init__(
+ self,
+ feature_extractor: "FeatureExtractionMixin",
+ tokenizer: "PreTrainedTokenizerBase",
+ decoder: "BeamSearchDecoderCTC",
+ ):
+ from pyctcdecode import BeamSearchDecoderCTC
+
+ super().__init__(feature_extractor, tokenizer)
+ if not isinstance(decoder, BeamSearchDecoderCTC):
+ raise TypeError(f"`decoder` has to be of type {BeamSearchDecoderCTC.__class__}, but is {type(decoder)}")
+
+ if feature_extractor.__class__.__name__ not in ["Wav2Vec2FeatureExtractor", "SeamlessM4TFeatureExtractor"]:
+ raise ValueError(
+ f"`feature_extractor` has to be of type `Wav2Vec2FeatureExtractor` or `SeamlessM4TFeatureExtractor`, but is {type(feature_extractor)}"
+ )
+
+ # make sure that decoder's alphabet and tokenizer's vocab match in content
+ missing_decoder_tokens = self.get_missing_alphabet_tokens(decoder, tokenizer)
+ if len(missing_decoder_tokens) > 0:
+ raise ValueError(
+ f"The tokens {missing_decoder_tokens} are defined in the tokenizer's "
+ "vocabulary, but not in the decoder's alphabet. "
+ f"Make sure to include {missing_decoder_tokens} in the decoder's alphabet."
+ )
+
+ self.decoder = decoder
+ self.current_processor = self.feature_extractor
+ self._in_target_context_manager = False
+
+ def save_pretrained(self, save_directory):
+ super().save_pretrained(save_directory)
+ self.decoder.save_to_dir(save_directory)
+
+ @classmethod
+ def from_pretrained(cls, pretrained_model_name_or_path, **kwargs):
+ r"""
+ Instantiate a [`Wav2Vec2ProcessorWithLM`] from a pretrained Wav2Vec2 processor.
+
+
+
+ This class method is simply calling the feature extractor's
+ [`~feature_extraction_utils.FeatureExtractionMixin.from_pretrained`], Wav2Vec2CTCTokenizer's
+ [`~tokenization_utils_base.PreTrainedTokenizerBase.from_pretrained`], and
+ [`pyctcdecode.BeamSearchDecoderCTC.load_from_hf_hub`].
+
+ Please refer to the docstrings of the methods above for more information.
+
+
+
+ Args:
+ pretrained_model_name_or_path (`str` or `os.PathLike`):
+ This can be either:
+
+ - a string, the *model id* of a pretrained feature_extractor hosted inside a model repo on
+ huggingface.co.
+ - a path to a *directory* containing a feature extractor file saved using the
+ [`~SequenceFeatureExtractor.save_pretrained`] method, e.g., `./my_model_directory/`.
+ - a path or url to a saved feature extractor JSON *file*, e.g.,
+ `./my_model_directory/preprocessor_config.json`.
+ **kwargs
+ Additional keyword arguments passed along to both [`SequenceFeatureExtractor`] and
+ [`PreTrainedTokenizer`]
+ """
+ requires_backends(cls, "pyctcdecode")
+ from pyctcdecode import BeamSearchDecoderCTC
+
+ feature_extractor, tokenizer = super()._get_arguments_from_pretrained(pretrained_model_name_or_path, **kwargs)
+
+ if os.path.isdir(pretrained_model_name_or_path) or os.path.isfile(pretrained_model_name_or_path):
+ unigram_encoding = kwargs.get("unigram_encoding", "utf-8")
+ decoder = BeamSearchDecoderCTC.load_from_dir(pretrained_model_name_or_path, unigram_encoding)
+ else:
+ # BeamSearchDecoderCTC has no auto class
+ kwargs.pop("_from_auto", None)
+ # snapshot_download has no `trust_remote_code` flag
+ kwargs.pop("trust_remote_code", None)
+
+ # make sure that only relevant filenames are downloaded
+ language_model_filenames = os.path.join(BeamSearchDecoderCTC._LANGUAGE_MODEL_SERIALIZED_DIRECTORY, "*")
+ alphabet_filename = BeamSearchDecoderCTC._ALPHABET_SERIALIZED_FILENAME
+ allow_patterns = [language_model_filenames, alphabet_filename]
+
+ decoder = BeamSearchDecoderCTC.load_from_hf_hub(
+ pretrained_model_name_or_path, allow_patterns=allow_patterns, **kwargs
+ )
+
+ # set language model attributes
+ for attribute in ["alpha", "beta", "unk_score_offset", "score_boundary"]:
+ value = kwargs.pop(attribute, None)
+
+ if value is not None:
+ cls._set_language_model_attribute(decoder, attribute, value)
+
+ # make sure that decoder's alphabet and tokenizer's vocab match in content
+ missing_decoder_tokens = cls.get_missing_alphabet_tokens(decoder, tokenizer)
+ if len(missing_decoder_tokens) > 0:
+ raise ValueError(
+ f"The tokens {missing_decoder_tokens} are defined in the tokenizer's "
+ "vocabulary, but not in the decoder's alphabet. "
+ f"Make sure to include {missing_decoder_tokens} in the decoder's alphabet."
+ )
+
+ return cls(feature_extractor=feature_extractor, tokenizer=tokenizer, decoder=decoder)
+
+ @staticmethod
+ def _set_language_model_attribute(decoder: "BeamSearchDecoderCTC", attribute: str, value: float):
+ setattr(decoder.model_container[decoder._model_key], attribute, value)
+
+ @property
+ def language_model(self):
+ return self.decoder.model_container[self.decoder._model_key]
+
+ @staticmethod
+ def get_missing_alphabet_tokens(decoder, tokenizer):
+ from pyctcdecode.alphabet import BLANK_TOKEN_PTN, UNK_TOKEN, UNK_TOKEN_PTN
+
+ # we need to make sure that all of the tokenizer's except the special tokens
+ # are present in the decoder's alphabet. Retrieve missing alphabet token
+ # from decoder
+ tokenizer_vocab_list = list(tokenizer.get_vocab().keys())
+
+ # replace special tokens
+ for i, token in enumerate(tokenizer_vocab_list):
+ if BLANK_TOKEN_PTN.match(token):
+ tokenizer_vocab_list[i] = ""
+ if token == tokenizer.word_delimiter_token:
+ tokenizer_vocab_list[i] = " "
+ if UNK_TOKEN_PTN.match(token):
+ tokenizer_vocab_list[i] = UNK_TOKEN
+
+ # are any of the extra tokens no special tokenizer tokens?
+ missing_tokens = set(tokenizer_vocab_list) - set(decoder._alphabet.labels)
+
+ return missing_tokens
+
+ def __call__(self, *args, **kwargs):
+ """
+ When used in normal mode, this method forwards all its arguments to the feature extractor's
+ [`~FeatureExtractionMixin.__call__`] and returns its output. If used in the context
+ [`~Wav2Vec2ProcessorWithLM.as_target_processor`] this method forwards all its arguments to
+ Wav2Vec2CTCTokenizer's [`~Wav2Vec2CTCTokenizer.__call__`]. Please refer to the docstring of the above two
+ methods for more information.
+ """
+ # For backward compatibility
+ if self._in_target_context_manager:
+ return self.current_processor(*args, **kwargs)
+
+ if "raw_speech" in kwargs:
+ warnings.warn("Using `raw_speech` as a keyword argument is deprecated. Use `audio` instead.")
+ audio = kwargs.pop("raw_speech")
+ else:
+ audio = kwargs.pop("audio", None)
+ sampling_rate = kwargs.pop("sampling_rate", None)
+ text = kwargs.pop("text", None)
+ if len(args) > 0:
+ audio = args[0]
+ args = args[1:]
+
+ if audio is None and text is None:
+ raise ValueError("You need to specify either an `audio` or `text` input to process.")
+
+ if audio is not None:
+ inputs = self.feature_extractor(audio, *args, sampling_rate=sampling_rate, **kwargs)
+ if text is not None:
+ encodings = self.tokenizer(text, **kwargs)
+
+ if text is None:
+ return inputs
+ elif audio is None:
+ return encodings
+ else:
+ inputs["labels"] = encodings["input_ids"]
+ return inputs
+
+ def pad(self, *args, **kwargs):
+ """
+ When used in normal mode, this method forwards all its arguments to the feature extractor's
+ [`~FeatureExtractionMixin.pad`] and returns its output. If used in the context
+ [`~Wav2Vec2ProcessorWithLM.as_target_processor`] this method forwards all its arguments to
+ Wav2Vec2CTCTokenizer's [`~Wav2Vec2CTCTokenizer.pad`]. Please refer to the docstring of the above two methods
+ for more information.
+ """
+ # For backward compatibility
+ if self._in_target_context_manager:
+ return self.current_processor.pad(*args, **kwargs)
+
+ input_features = kwargs.pop("input_features", None)
+ labels = kwargs.pop("labels", None)
+ if len(args) > 0:
+ input_features = args[0]
+ args = args[1:]
+
+ if input_features is not None:
+ input_features = self.feature_extractor.pad(input_features, *args, **kwargs)
+ if labels is not None:
+ labels = self.tokenizer.pad(labels, **kwargs)
+
+ if labels is None:
+ return input_features
+ elif input_features is None:
+ return labels
+ else:
+ input_features["labels"] = labels["input_ids"]
+ return input_features
+
+ def batch_decode(
+ self,
+ logits: np.ndarray,
+ pool: Optional[Pool] = None,
+ num_processes: Optional[int] = None,
+ beam_width: Optional[int] = None,
+ beam_prune_logp: Optional[float] = None,
+ token_min_logp: Optional[float] = None,
+ hotwords: Optional[Iterable[str]] = None,
+ hotword_weight: Optional[float] = None,
+ alpha: Optional[float] = None,
+ beta: Optional[float] = None,
+ unk_score_offset: Optional[float] = None,
+ lm_score_boundary: Optional[bool] = None,
+ output_word_offsets: bool = False,
+ n_best: int = 1,
+ ):
+ """
+ Batch decode output logits to audio transcription with language model support.
+
+
+
+ This function makes use of Python's multiprocessing. Currently, multiprocessing is available only on Unix
+ systems (see this [issue](https://github.com/kensho-technologies/pyctcdecode/issues/65)).
+
+ If you are decoding multiple batches, consider creating a `Pool` and passing it to `batch_decode`. Otherwise,
+ `batch_decode` will be very slow since it will create a fresh `Pool` for each call. See usage example below.
+
+
+
+ Args:
+ logits (`np.ndarray`):
+ The logits output vector of the model representing the log probabilities for each token.
+ pool (`multiprocessing.Pool`, *optional*):
+ An optional user-managed pool. If not set, one will be automatically created and closed. The pool
+ should be instantiated *after* `Wav2Vec2ProcessorWithLM`. Otherwise, the LM won't be available to the
+ pool's sub-processes.
+
+
+
+ Currently, only pools created with a 'fork' context can be used. If a 'spawn' pool is passed, it will
+ be ignored and sequential decoding will be used instead.
+
+
+
+ num_processes (`int`, *optional*):
+ If `pool` is not set, number of processes on which the function should be parallelized over. Defaults
+ to the number of available CPUs.
+ beam_width (`int`, *optional*):
+ Maximum number of beams at each step in decoding. Defaults to pyctcdecode's DEFAULT_BEAM_WIDTH.
+ beam_prune_logp (`int`, *optional*):
+ Beams that are much worse than best beam will be pruned Defaults to pyctcdecode's DEFAULT_PRUNE_LOGP.
+ token_min_logp (`int`, *optional*):
+ Tokens below this logp are skipped unless they are argmax of frame Defaults to pyctcdecode's
+ DEFAULT_MIN_TOKEN_LOGP.
+ hotwords (`list[str]`, *optional*):
+ List of words with extra importance, can be OOV for LM
+ hotword_weight (`int`, *optional*):
+ Weight factor for hotword importance Defaults to pyctcdecode's DEFAULT_HOTWORD_WEIGHT.
+ alpha (`float`, *optional*):
+ Weight for language model during shallow fusion
+ beta (`float`, *optional*):
+ Weight for length score adjustment of during scoring
+ unk_score_offset (`float`, *optional*):
+ Amount of log score offset for unknown tokens
+ lm_score_boundary (`bool`, *optional*):
+ Whether to have kenlm respect boundaries when scoring
+ output_word_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output word offsets. Word offsets can be used in combination with the sampling rate
+ and model downsampling rate to compute the time-stamps of transcribed words.
+ n_best (`int`, *optional*, defaults to `1`):
+ Number of best hypotheses to return. If `n_best` is greater than 1, the returned `text` will be a list
+ of lists of strings, `logit_score` will be a list of lists of floats, and `lm_score` will be a list of
+ lists of floats, where the length of the outer list will correspond to the batch size and the length of
+ the inner list will correspond to the number of returned hypotheses . The value should be >= 1.
+
+
+
+ Please take a look at the Example of [`~Wav2Vec2ProcessorWithLM.decode`] to better understand how to
+ make use of `output_word_offsets`. [`~Wav2Vec2ProcessorWithLM.batch_decode`] works the same way with
+ batched output.
+
+
+
+ Returns:
+ [`~models.wav2vec2.Wav2Vec2DecoderWithLMOutput`].
+
+ Example:
+ See [Decoding multiple audios](#decoding-multiple-audios).
+ """
+
+ from pyctcdecode.constants import (
+ DEFAULT_BEAM_WIDTH,
+ DEFAULT_HOTWORD_WEIGHT,
+ DEFAULT_MIN_TOKEN_LOGP,
+ DEFAULT_PRUNE_LOGP,
+ )
+
+ # set defaults
+ beam_width = beam_width if beam_width is not None else DEFAULT_BEAM_WIDTH
+ beam_prune_logp = beam_prune_logp if beam_prune_logp is not None else DEFAULT_PRUNE_LOGP
+ token_min_logp = token_min_logp if token_min_logp is not None else DEFAULT_MIN_TOKEN_LOGP
+ hotword_weight = hotword_weight if hotword_weight is not None else DEFAULT_HOTWORD_WEIGHT
+
+ # reset params at every forward call. It's just a `set` method in pyctcdecode
+ self.decoder.reset_params(
+ alpha=alpha, beta=beta, unk_score_offset=unk_score_offset, lm_score_boundary=lm_score_boundary
+ )
+
+ # create multiprocessing pool and list numpy arrays
+ # filter out logits padding
+ logits_list = [array[(array != -100.0).all(axis=-1)] for array in logits]
+
+ # create a pool if necessary while also using it as a context manager to close itself
+ if pool is None:
+ # fork is safe to use only on Unix, see "Contexts and start methods" section on
+ # multiprocessing's docs (https://docs.python.org/3/library/multiprocessing.html#contexts-and-start-methods)
+ default_context = get_start_method()
+
+ if default_context == "fork":
+ cm = pool = get_context().Pool(num_processes)
+ else:
+ logger.warning(
+ "Parallel batch decoding is not currently supported in this platform. "
+ "Falling back to sequential decoding."
+ )
+ cm = nullcontext()
+ else:
+ # pool is managed by the user, so we don't need to close it
+ cm = nullcontext()
+
+ if num_processes is not None:
+ logger.warning(
+ "Parameter `num_process` was passed, but it will be ignored since `pool` was also specified."
+ )
+
+ # pyctcdecode
+ with cm:
+ decoded_beams = self.decoder.decode_beams_batch(
+ pool=pool,
+ logits_list=logits_list,
+ beam_width=beam_width,
+ beam_prune_logp=beam_prune_logp,
+ token_min_logp=token_min_logp,
+ hotwords=hotwords,
+ hotword_weight=hotword_weight,
+ )
+
+ # extract text and scores
+ batch_texts, logit_scores, lm_scores, word_offsets = [], [], [], []
+
+ for d in decoded_beams:
+ batch_texts.append([beam[0] for beam in d])
+ logit_scores.append([beam[-2] for beam in d])
+ lm_scores.append([beam[-1] for beam in d])
+
+ # word_offsets.append([{"word": t[0], "start_offset": t[1][0], "end_offset": t[1][1]} for t in d[0][1]])
+
+ word_offsets.append(
+ [
+ [
+ {"word": word, "start_offset": start_offset, "end_offset": end_offset}
+ for word, (start_offset, end_offset) in beam[1]
+ ]
+ for beam in d
+ ]
+ )
+
+ word_offsets = word_offsets if output_word_offsets else None
+
+ if n_best == 1:
+ return Wav2Vec2DecoderWithLMOutput(
+ text=[hyps[0] for hyps in batch_texts],
+ logit_score=[hyps[0] for hyps in logit_scores],
+ lm_score=[hyps[0] for hyps in lm_scores],
+ word_offsets=[hyps[0] for hyps in word_offsets] if word_offsets is not None else None,
+ )
+ else:
+ return Wav2Vec2DecoderWithLMOutput(
+ text=[hyps[:n_best] for hyps in batch_texts],
+ logit_score=[hyps[:n_best] for hyps in logit_scores],
+ lm_score=[hyps[:n_best] for hyps in lm_scores],
+ word_offsets=[hyps[:n_best] for hyps in word_offsets] if word_offsets is not None else None,
+ )
+
+ def decode(
+ self,
+ logits: np.ndarray,
+ beam_width: Optional[int] = None,
+ beam_prune_logp: Optional[float] = None,
+ token_min_logp: Optional[float] = None,
+ hotwords: Optional[Iterable[str]] = None,
+ hotword_weight: Optional[float] = None,
+ alpha: Optional[float] = None,
+ beta: Optional[float] = None,
+ unk_score_offset: Optional[float] = None,
+ lm_score_boundary: Optional[bool] = None,
+ output_word_offsets: bool = False,
+ n_best: int = 1,
+ ):
+ """
+ Decode output logits to audio transcription with language model support.
+
+ Args:
+ logits (`np.ndarray`):
+ The logits output vector of the model representing the log probabilities for each token.
+ beam_width (`int`, *optional*):
+ Maximum number of beams at each step in decoding. Defaults to pyctcdecode's DEFAULT_BEAM_WIDTH.
+ beam_prune_logp (`int`, *optional*):
+ A threshold to prune beams with log-probs less than best_beam_logp + beam_prune_logp. The value should
+ be <= 0. Defaults to pyctcdecode's DEFAULT_PRUNE_LOGP.
+ token_min_logp (`int`, *optional*):
+ Tokens with log-probs below token_min_logp are skipped unless they are have the maximum log-prob for an
+ utterance. Defaults to pyctcdecode's DEFAULT_MIN_TOKEN_LOGP.
+ hotwords (`list[str]`, *optional*):
+ List of words with extra importance which can be missing from the LM's vocabulary, e.g. ["huggingface"]
+ hotword_weight (`int`, *optional*):
+ Weight multiplier that boosts hotword scores. Defaults to pyctcdecode's DEFAULT_HOTWORD_WEIGHT.
+ alpha (`float`, *optional*):
+ Weight for language model during shallow fusion
+ beta (`float`, *optional*):
+ Weight for length score adjustment of during scoring
+ unk_score_offset (`float`, *optional*):
+ Amount of log score offset for unknown tokens
+ lm_score_boundary (`bool`, *optional*):
+ Whether to have kenlm respect boundaries when scoring
+ output_word_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output word offsets. Word offsets can be used in combination with the sampling rate
+ and model downsampling rate to compute the time-stamps of transcribed words.
+ n_best (`int`, *optional*, defaults to `1`):
+ Number of best hypotheses to return. If `n_best` is greater than 1, the returned `text` will be a list
+ of strings, `logit_score` will be a list of floats, and `lm_score` will be a list of floats, where the
+ length of these lists will correspond to the number of returned hypotheses. The value should be >= 1.
+
+
+
+ Please take a look at the example below to better understand how to make use of `output_word_offsets`.
+
+
+
+ Returns:
+ [`~models.wav2vec2.Wav2Vec2DecoderWithLMOutput`].
+
+ Example:
+
+ ```python
+ >>> # Let's see how to retrieve time steps for a model
+ >>> from transformers import AutoTokenizer, AutoProcessor, AutoModelForCTC
+ >>> from datasets import load_dataset
+ >>> import datasets
+ >>> import torch
+
+ >>> # import model, feature extractor, tokenizer
+ >>> model = AutoModelForCTC.from_pretrained("patrickvonplaten/wav2vec2-base-100h-with-lm")
+ >>> processor = AutoProcessor.from_pretrained("patrickvonplaten/wav2vec2-base-100h-with-lm")
+
+ >>> # load first sample of English common_voice
+ >>> dataset = load_dataset("mozilla-foundation/common_voice_11_0", "en", split="train", streaming=True)
+ >>> dataset = dataset.cast_column("audio", datasets.Audio(sampling_rate=16_000))
+ >>> dataset_iter = iter(dataset)
+ >>> sample = next(dataset_iter)
+
+ >>> # forward sample through model to get greedily predicted transcription ids
+ >>> input_values = processor(sample["audio"]["array"], return_tensors="pt").input_values
+ >>> with torch.no_grad():
+ ... logits = model(input_values).logits[0].cpu().numpy()
+
+ >>> # retrieve word stamps (analogous commands for `output_char_offsets`)
+ >>> outputs = processor.decode(logits, output_word_offsets=True)
+ >>> # compute `time_offset` in seconds as product of downsampling ratio and sampling_rate
+ >>> time_offset = model.config.inputs_to_logits_ratio / processor.feature_extractor.sampling_rate
+
+ >>> word_offsets = [
+ ... {
+ ... "word": d["word"],
+ ... "start_time": round(d["start_offset"] * time_offset, 2),
+ ... "end_time": round(d["end_offset"] * time_offset, 2),
+ ... }
+ ... for d in outputs.word_offsets
+ ... ]
+ >>> # compare word offsets with audio `en_train_0/common_voice_en_19121553.mp3` online on the dataset viewer:
+ >>> # https://huggingface.co/datasets/mozilla-foundation/common_voice_11_0/viewer/en
+ >>> word_offsets[:4]
+ [{'word': 'THE', 'start_time': 0.68, 'end_time': 0.78}, {'word': 'TRACK', 'start_time': 0.88, 'end_time': 1.1}, {'word': 'APPEARS', 'start_time': 1.18, 'end_time': 1.66}, {'word': 'ON', 'start_time': 1.86, 'end_time': 1.92}]
+ ```"""
+
+ from pyctcdecode.constants import (
+ DEFAULT_BEAM_WIDTH,
+ DEFAULT_HOTWORD_WEIGHT,
+ DEFAULT_MIN_TOKEN_LOGP,
+ DEFAULT_PRUNE_LOGP,
+ )
+
+ # set defaults
+ beam_width = beam_width if beam_width is not None else DEFAULT_BEAM_WIDTH
+ beam_prune_logp = beam_prune_logp if beam_prune_logp is not None else DEFAULT_PRUNE_LOGP
+ token_min_logp = token_min_logp if token_min_logp is not None else DEFAULT_MIN_TOKEN_LOGP
+ hotword_weight = hotword_weight if hotword_weight is not None else DEFAULT_HOTWORD_WEIGHT
+
+ # reset params at every forward call. It's just a `set` method in pyctcdecode
+ self.decoder.reset_params(
+ alpha=alpha, beta=beta, unk_score_offset=unk_score_offset, lm_score_boundary=lm_score_boundary
+ )
+
+ # pyctcdecode
+ decoded_beams = self.decoder.decode_beams(
+ logits,
+ beam_width=beam_width,
+ beam_prune_logp=beam_prune_logp,
+ token_min_logp=token_min_logp,
+ hotwords=hotwords,
+ hotword_weight=hotword_weight,
+ )
+
+ word_offsets = None
+ if output_word_offsets:
+ word_offsets = [
+ [
+ {"word": word, "start_offset": start_offset, "end_offset": end_offset}
+ for word, (start_offset, end_offset) in beam[2]
+ ]
+ for beam in decoded_beams
+ ]
+ logit_scores = [beam[-2] for beam in decoded_beams]
+
+ lm_scores = [beam[-1] for beam in decoded_beams]
+
+ hypotheses = [beam[0] for beam in decoded_beams]
+
+ if n_best > len(decoded_beams):
+ logger.info(
+ "N-best size is larger than the number of generated hypotheses, all hypotheses will be returned."
+ )
+
+ if n_best == 1:
+ return Wav2Vec2DecoderWithLMOutput(
+ text=hypotheses[0],
+ logit_score=logit_scores[0],
+ lm_score=lm_scores[0],
+ word_offsets=word_offsets[0] if word_offsets is not None else None,
+ )
+ else:
+ return Wav2Vec2DecoderWithLMOutput(
+ text=hypotheses[:n_best],
+ logit_score=logit_scores[:n_best],
+ lm_score=lm_scores[:n_best],
+ word_offsets=word_offsets[:n_best] if word_offsets is not None else None,
+ )
+
+ @contextmanager
+ def as_target_processor(self):
+ """
+ Temporarily sets the processor for processing the target. Useful for encoding the labels when fine-tuning
+ Wav2Vec2.
+ """
+ warnings.warn(
+ "`as_target_processor` is deprecated and will be removed in v5 of Transformers. You can process your "
+ "labels by using the argument `text` of the regular `__call__` method (either in the same call as "
+ "your audio inputs, or in a separate call."
+ )
+ self._in_target_context_manager = True
+ self.current_processor = self.tokenizer
+ yield
+ self.current_processor = self.feature_extractor
+ self._in_target_context_manager = False
+
+
+__all__ = ["Wav2Vec2ProcessorWithLM"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..d230bf3f0924b436e1b9cd9ea509a989cf5bdb8b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_wavlm import *
+ from .modeling_wavlm import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/configuration_wavlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/configuration_wavlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..a137792e2a8da48684738ea396e6704dc849613a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/configuration_wavlm.py
@@ -0,0 +1,337 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors, Microsoft Research, and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""WavLM model configuration"""
+
+import functools
+import operator
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class WavLMConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`WavLMModel`]. It is used to instantiate an WavLM
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the WavLM
+ [microsoft/wavlm-base](https://huggingface.co/microsoft/wavlm-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32):
+ Vocabulary size of the WavLM model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`WavLMModel`]. Vocabulary size of the model. Defines the different tokens
+ that can be represented by the *inputs_ids* passed to the forward method of [`WavLMModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ activation_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for activations inside the fully connected layer.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ final_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the final projection layer of [`WavLMForCTC`].
+ layerdrop (`float`, *optional*, defaults to 0.1):
+ The LayerDrop probability. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) for more
+ details.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ feat_extract_norm (`str`, *optional*, defaults to `"group"`):
+ The norm to be applied to 1D convolutional layers in feature encoder. One of `"group"` for group
+ normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D
+ convolutional layers.
+ feat_proj_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for output of the feature encoder.
+ feat_extract_activation (`str, `optional`, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the 1D convolutional layers of the feature
+ extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 512, 512, 512)`):
+ A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the
+ feature encoder. The length of *conv_dim* defines the number of 1D convolutional layers.
+ conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 2, 2, 2, 2, 2)`):
+ A tuple of integers defining the stride of each 1D convolutional layer in the feature encoder. The length
+ of *conv_stride* defines the number of convolutional layers and has to match the length of *conv_dim*.
+ conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 3, 3, 3, 3, 3)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the feature encoder. The
+ length of *conv_kernel* defines the number of convolutional layers and has to match the length of
+ *conv_dim*.
+ conv_bias (`bool`, *optional*, defaults to `False`):
+ Whether the 1D convolutional layers have a bias.
+ num_conv_pos_embeddings (`int`, *optional*, defaults to 128):
+ Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional
+ embeddings layer.
+ num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16):
+ Number of groups of 1D convolutional positional embeddings layer.
+ do_stable_layer_norm (`bool`, *optional*, defaults to `False`):
+ Whether to apply *stable* layer norm architecture of the Transformer encoder. `do_stable_layer_norm is
+ True` corresponds to applying layer norm before the attention layer, whereas `do_stable_layer_norm is
+ False` corresponds to applying layer norm after the attention layer.
+ apply_spec_augment (`bool`, *optional*, defaults to `True`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see
+ [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Probability of each feature vector along the time axis to be chosen as the start of the vector span to be
+ masked. Approximately `mask_time_prob * sequence_length // mask_time_length` feature vectors will be masked
+ along the time axis. This is only relevant if `apply_spec_augment is True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2),:
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks''
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Probability of each feature vector along the feature axis to be chosen as the start of the vector span to
+ be masked. Approximately `mask_time_prob * hidden_size // mask_time_length` feature vectors will be masked
+ along the time axis. This is only relevant if `apply_spec_augment is True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ num_codevectors_per_group (`int`, *optional*, defaults to 320):
+ Number of entries in each quantization codebook (group).
+ num_codevector_groups (`int`, *optional*, defaults to 2):
+ Number of codevector groups for product codevector quantization.
+ contrastive_logits_temperature (`float`, *optional*, defaults to 0.1):
+ The temperature *kappa* in the contrastive loss.
+ num_negatives (`int`, *optional*, defaults to 100):
+ Number of negative samples for the contrastive loss.
+ codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the quantized feature vectors.
+ proj_codevector_dim (`int`, *optional*, defaults to 256):
+ Dimensionality of the final projection of both the quantized and the transformer features.
+ diversity_loss_weight (`int`, *optional*, defaults to 0.1):
+ The weight of the codebook diversity loss component.
+ ctc_loss_reduction (`str`, *optional*, defaults to `"mean"`):
+ Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an
+ instance of [`WavLMForCTC`].
+ ctc_zero_infinity (`bool`, *optional*, defaults to `False`):
+ Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly
+ occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance
+ of [`WavLMForCTC`].
+ use_weighted_layer_sum (`bool`, *optional*, defaults to `False`):
+ Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an
+ instance of [`WavLMForSequenceClassification`].
+ classifier_proj_size (`int`, *optional*, defaults to 256):
+ Dimensionality of the projection before token mean-pooling for classification.
+ tdnn_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(512, 512, 512, 512, 1500)`):
+ A tuple of integers defining the number of output channels of each 1D convolutional layer in the *TDNN*
+ module of the *XVector* model. The length of *tdnn_dim* defines the number of *TDNN* layers.
+ tdnn_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 3, 3, 1, 1)`):
+ A tuple of integers defining the kernel size of each 1D convolutional layer in the *TDNN* module of the
+ *XVector* model. The length of *tdnn_kernel* has to match the length of *tdnn_dim*.
+ tdnn_dilation (`tuple[int]` or `list[int]`, *optional*, defaults to `(1, 2, 3, 1, 1)`):
+ A tuple of integers defining the dilation factor of each 1D convolutional layer in *TDNN* module of the
+ *XVector* model. The length of *tdnn_dilation* has to match the length of *tdnn_dim*.
+ xvector_output_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of the *XVector* embedding vectors.
+ add_adapter (`bool`, *optional*, defaults to `False`):
+ Whether a convolutional network should be stacked on top of the Wav2Vec2 Encoder. Can be very useful for
+ warm-starting Wav2Vec2 for SpeechEncoderDecoder models.
+ adapter_kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ adapter_stride (`int`, *optional*, defaults to 2):
+ Stride of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`.
+ num_adapter_layers (`int`, *optional*, defaults to 3):
+ Number of convolutional layers that should be used in the adapter network. Only relevant if `add_adapter is
+ True`.
+ output_hidden_size (`int`, *optional*):
+ Dimensionality of the encoder output layer. If not defined, this defaults to *hidden-size*. Only relevant
+ if `add_adapter is True`.
+
+ Example:
+
+ ```python
+
+ ```
+
+ Example:
+
+ ```python
+ >>> from transformers import WavLMConfig, WavLMModel
+
+ >>> # Initializing a WavLM facebook/wavlm-base-960h style configuration
+ >>> configuration = WavLMConfig()
+
+ >>> # Initializing a model (with random weights) from the facebook/wavlm-base-960h style configuration
+ >>> model = WavLMModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "wavlm"
+
+ def __init__(
+ self,
+ vocab_size=32,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout=0.1,
+ activation_dropout=0.1,
+ attention_dropout=0.1,
+ feat_proj_dropout=0.0,
+ final_dropout=0.1,
+ layerdrop=0.1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-5,
+ feat_extract_norm="group",
+ feat_extract_activation="gelu",
+ conv_dim=(512, 512, 512, 512, 512, 512, 512),
+ conv_stride=(5, 2, 2, 2, 2, 2, 2),
+ conv_kernel=(10, 3, 3, 3, 3, 2, 2),
+ conv_bias=False,
+ num_conv_pos_embeddings=128,
+ num_conv_pos_embedding_groups=16,
+ num_buckets=320,
+ max_bucket_distance=800,
+ do_stable_layer_norm=False,
+ apply_spec_augment=True,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ num_codevectors_per_group=320,
+ num_codevector_groups=2,
+ contrastive_logits_temperature=0.1,
+ num_negatives=100,
+ codevector_dim=256,
+ proj_codevector_dim=256,
+ diversity_loss_weight=0.1,
+ ctc_loss_reduction="mean",
+ ctc_zero_infinity=False,
+ use_weighted_layer_sum=False,
+ classifier_proj_size=256,
+ tdnn_dim=(512, 512, 512, 512, 1500),
+ tdnn_kernel=(5, 3, 3, 1, 1),
+ tdnn_dilation=(1, 2, 3, 1, 1),
+ xvector_output_dim=512,
+ num_ctc_classes=80,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ add_adapter=False,
+ adapter_kernel_size=3,
+ adapter_stride=2,
+ num_adapter_layers=3,
+ output_hidden_size=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs, pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id)
+ self.hidden_size = hidden_size
+ self.feat_extract_norm = feat_extract_norm
+ self.feat_extract_activation = feat_extract_activation
+ self.conv_dim = list(conv_dim)
+ self.conv_stride = list(conv_stride)
+ self.conv_kernel = list(conv_kernel)
+ self.conv_bias = conv_bias
+ self.num_buckets = num_buckets
+ self.max_bucket_distance = max_bucket_distance
+ self.num_conv_pos_embeddings = num_conv_pos_embeddings
+ self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups
+ self.num_feat_extract_layers = len(self.conv_dim)
+ self.num_hidden_layers = num_hidden_layers
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.num_attention_heads = num_attention_heads
+ self.hidden_dropout = hidden_dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.feat_proj_dropout = feat_proj_dropout
+ self.final_dropout = final_dropout
+ self.layerdrop = layerdrop
+ self.layer_norm_eps = layer_norm_eps
+ self.initializer_range = initializer_range
+ self.num_ctc_classes = num_ctc_classes
+ self.vocab_size = vocab_size
+ self.do_stable_layer_norm = do_stable_layer_norm
+ self.use_weighted_layer_sum = use_weighted_layer_sum
+ self.classifier_proj_size = classifier_proj_size
+
+ if (
+ (len(self.conv_stride) != self.num_feat_extract_layers)
+ or (len(self.conv_kernel) != self.num_feat_extract_layers)
+ or (len(self.conv_dim) != self.num_feat_extract_layers)
+ ):
+ raise ValueError(
+ "Configuration for convolutional layers is incorrect. It is required that `len(config.conv_dim)` =="
+ " `len(config.conv_stride)` == `len(config.conv_kernel)`, but is `len(config.conv_dim) ="
+ f" {len(self.conv_dim)}`, `len(config.conv_stride) = {len(self.conv_stride)}`,"
+ f" `len(config.conv_kernel) = {len(self.conv_kernel)}`."
+ )
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+
+ # parameters for pretraining with codevector quantized representations
+ self.num_codevectors_per_group = num_codevectors_per_group
+ self.num_codevector_groups = num_codevector_groups
+ self.contrastive_logits_temperature = contrastive_logits_temperature
+ self.num_negatives = num_negatives
+ self.codevector_dim = codevector_dim
+ self.proj_codevector_dim = proj_codevector_dim
+ self.diversity_loss_weight = diversity_loss_weight
+
+ # ctc loss
+ self.ctc_loss_reduction = ctc_loss_reduction
+ self.ctc_zero_infinity = ctc_zero_infinity
+
+ # adapter
+ self.add_adapter = add_adapter
+ self.adapter_kernel_size = adapter_kernel_size
+ self.adapter_stride = adapter_stride
+ self.num_adapter_layers = num_adapter_layers
+ self.output_hidden_size = output_hidden_size or hidden_size
+
+ # SequenceClassification-specific parameter. Feel free to ignore for other classes.
+ self.classifier_proj_size = classifier_proj_size
+
+ # XVector-specific parameters. Feel free to ignore for other classes.
+ self.tdnn_dim = list(tdnn_dim)
+ self.tdnn_kernel = list(tdnn_kernel)
+ self.tdnn_dilation = list(tdnn_dilation)
+ self.xvector_output_dim = xvector_output_dim
+
+ @property
+ def inputs_to_logits_ratio(self):
+ return functools.reduce(operator.mul, self.conv_stride, 1)
+
+
+__all__ = ["WavLMConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/modeling_wavlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/modeling_wavlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..b6bf15794f2a3a15b7fd4a305a044cf1261d43c1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/modeling_wavlm.py
@@ -0,0 +1,1706 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/wavlm/modular_wavlm.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_wavlm.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+import math
+import warnings
+from typing import Optional, Union
+
+import numpy as np
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ CausalLMOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+ Wav2Vec2BaseModelOutput,
+ XVectorOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, is_peft_available, logging
+from .configuration_wavlm import WavLMConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class WavLMSamePadLayer(nn.Module):
+ def __init__(self, num_conv_pos_embeddings):
+ super().__init__()
+ self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0
+
+ def forward(self, hidden_states):
+ if self.num_pad_remove > 0:
+ hidden_states = hidden_states[:, :, : -self.num_pad_remove]
+ return hidden_states
+
+
+class WavLMPositionalConvEmbedding(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.hidden_size,
+ config.hidden_size,
+ kernel_size=config.num_conv_pos_embeddings,
+ padding=config.num_conv_pos_embeddings // 2,
+ groups=config.num_conv_pos_embedding_groups,
+ )
+
+ weight_norm = nn.utils.weight_norm
+ if hasattr(nn.utils.parametrizations, "weight_norm"):
+ weight_norm = nn.utils.parametrizations.weight_norm
+
+ if is_deepspeed_zero3_enabled():
+ import deepspeed
+
+ with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0):
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+ if hasattr(self.conv, "parametrizations"):
+ weight_g = self.conv.parametrizations.weight.original0
+ weight_v = self.conv.parametrizations.weight.original1
+ else:
+ weight_g = self.conv.weight_g
+ weight_v = self.conv.weight_v
+ deepspeed.zero.register_external_parameter(self, weight_v)
+ deepspeed.zero.register_external_parameter(self, weight_g)
+ else:
+ self.conv = weight_norm(self.conv, name="weight", dim=2)
+
+ self.padding = WavLMSamePadLayer(config.num_conv_pos_embeddings)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.padding(hidden_states)
+ hidden_states = self.activation(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+class WavLMFeatureProjection(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps)
+ self.projection = nn.Linear(config.conv_dim[-1], config.hidden_size)
+ self.dropout = nn.Dropout(config.feat_proj_dropout)
+
+ def forward(self, hidden_states):
+ # non-projected hidden states are needed for quantization
+ norm_hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.projection(norm_hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states, norm_hidden_states
+
+
+class WavLMAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ num_buckets: int = 320,
+ max_distance: int = 800,
+ has_relative_position_bias: bool = True,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim)
+ self.v_proj = nn.Linear(embed_dim, embed_dim)
+ self.q_proj = nn.Linear(embed_dim, embed_dim)
+ self.out_proj = nn.Linear(embed_dim, embed_dim)
+
+ self.num_buckets = num_buckets
+ self.max_distance = max_distance
+
+ self.gru_rel_pos_const = nn.Parameter(torch.ones(1, self.num_heads, 1, 1))
+ self.gru_rel_pos_linear = nn.Linear(self.head_dim, 8)
+
+ if has_relative_position_bias:
+ self.rel_attn_embed = nn.Embedding(self.num_buckets, self.num_heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_bias: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ index=0,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Attention layer with relative attention"""
+ bsz, tgt_len, _ = hidden_states.size()
+
+ # first pass of attention layer creates position bias
+ if position_bias is None:
+ position_bias = self.compute_bias(tgt_len, tgt_len)
+ position_bias = (
+ position_bias.unsqueeze(0).repeat(bsz, 1, 1, 1).view(bsz * self.num_heads, tgt_len, tgt_len)
+ )
+
+ # Compute relative position bias:
+ # 1) get reshape hidden_states
+ gated_hidden_states = hidden_states.view(hidden_states.shape[:-1] + (self.num_heads, -1))
+ gated_hidden_states = gated_hidden_states.permute(0, 2, 1, 3)
+
+ # 2) project hidden states
+ relative_position_proj = self.gru_rel_pos_linear(gated_hidden_states)
+ relative_position_proj = relative_position_proj.view(gated_hidden_states.shape[:-1] + (2, 4)).sum(-1)
+
+ # 3) compute gate for position bias from projected hidden states
+ gate_a, gate_b = torch.sigmoid(relative_position_proj).chunk(2, dim=-1)
+ gate_output = gate_a * (gate_b * self.gru_rel_pos_const - 1.0) + 2.0
+
+ # 4) apply gate to position bias to compute gated position_bias
+ gated_position_bias = gate_output.view(bsz * self.num_heads, -1, 1) * position_bias
+ gated_position_bias = gated_position_bias.view((-1, tgt_len, tgt_len))
+
+ attn_output, attn_weights = self.torch_multi_head_self_attention(
+ hidden_states, attention_mask, gated_position_bias, output_attentions
+ )
+
+ return attn_output, attn_weights, position_bias
+
+ def torch_multi_head_self_attention(
+ self,
+ hidden_states: torch.FloatTensor,
+ attention_mask: Union[torch.LongTensor, torch.BoolTensor],
+ gated_position_bias: torch.FloatTensor,
+ output_attentions: bool,
+ ) -> (torch.FloatTensor, torch.FloatTensor):
+ """simple wrapper around torch's multi_head_attention_forward function"""
+ # self-attention assumes q = k = v
+ query = key = value = hidden_states.transpose(0, 1)
+ key_padding_mask = attention_mask.ne(1) if attention_mask is not None else None
+
+ # disable bias and add_zero_attn
+ bias_k = bias_v = None
+ add_zero_attn = False
+
+ # PyTorch 1.3.0 has F.multi_head_attention_forward defined
+ # so no problem with backwards compatibility
+ attn_output, attn_weights = F.multi_head_attention_forward(
+ query,
+ key,
+ value,
+ self.embed_dim,
+ self.num_heads,
+ torch.empty([0]),
+ torch.cat((self.q_proj.bias, self.k_proj.bias, self.v_proj.bias)),
+ bias_k,
+ bias_v,
+ add_zero_attn,
+ self.dropout,
+ self.out_proj.weight,
+ self.out_proj.bias,
+ self.training,
+ key_padding_mask,
+ output_attentions,
+ gated_position_bias,
+ use_separate_proj_weight=True,
+ q_proj_weight=self.q_proj.weight,
+ k_proj_weight=self.k_proj.weight,
+ v_proj_weight=self.v_proj.weight,
+ )
+
+ # [Seq_Len, Batch Size, ...] -> [Batch Size, Seq_Len, ...]
+ attn_output = attn_output.transpose(0, 1)
+
+ if attn_weights is not None:
+ # IMPORTANT: Attention weights are averaged weights
+ # here which should not be the case. This is an open issue
+ # on PyTorch: https://github.com/pytorch/pytorch/issues/32590
+ attn_weights = attn_weights[:, None].broadcast_to(
+ attn_weights.shape[:1] + (self.num_heads,) + attn_weights.shape[1:]
+ )
+
+ return attn_output, attn_weights
+
+ def compute_bias(self, query_length: int, key_length: int) -> torch.FloatTensor:
+ context_position = torch.arange(query_length, dtype=torch.long)[:, None]
+ memory_position = torch.arange(key_length, dtype=torch.long)[None, :]
+ relative_position = memory_position - context_position
+ relative_position_bucket = self._relative_positions_bucket(relative_position)
+ relative_position_bucket = relative_position_bucket.to(self.rel_attn_embed.weight.device)
+ values = self.rel_attn_embed(relative_position_bucket)
+ values = values.permute([2, 0, 1])
+ return values
+
+ def _relative_positions_bucket(self, relative_positions: torch.FloatTensor) -> torch.FloatTensor:
+ num_buckets = self.num_buckets // 2
+
+ relative_buckets = (relative_positions > 0).to(torch.long) * num_buckets
+ relative_positions = torch.abs(relative_positions)
+
+ max_exact = num_buckets // 2
+ is_small = relative_positions < max_exact
+
+ relative_positions_if_large = torch.log(relative_positions.float() / max_exact)
+ relative_positions_if_large = relative_positions_if_large / math.log(self.max_distance / max_exact)
+ relative_positions_if_large = relative_positions_if_large * (num_buckets - max_exact)
+ relative_position_if_large = (max_exact + relative_positions_if_large).to(torch.long)
+ relative_position_if_large = torch.min(
+ relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1)
+ )
+
+ relative_buckets += torch.where(is_small, relative_positions, relative_position_if_large)
+ return relative_buckets
+
+
+class WavLMFeedForward(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.intermediate_dropout = nn.Dropout(config.activation_dropout)
+
+ self.intermediate_dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ self.output_dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.output_dropout = nn.Dropout(config.hidden_dropout)
+
+ def forward(self, hidden_states):
+ hidden_states = self.intermediate_dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ hidden_states = self.intermediate_dropout(hidden_states)
+
+ hidden_states = self.output_dense(hidden_states)
+ hidden_states = self.output_dropout(hidden_states)
+ return hidden_states
+
+
+class WavLMEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: WavLMConfig, has_relative_position_bias: bool = True):
+ super().__init__()
+ self.attention = WavLMAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ num_buckets=config.num_buckets,
+ max_distance=config.max_bucket_distance,
+ has_relative_position_bias=has_relative_position_bias,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = WavLMFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, position_bias=None, output_attentions=False, index=0):
+ attn_residual = hidden_states
+ hidden_states, attn_weights, position_bias = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ index=index,
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states, position_bias)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class WavLMEncoderLayerStableLayerNorm(GradientCheckpointingLayer):
+ def __init__(self, config: WavLMConfig, has_relative_position_bias: bool = True):
+ super().__init__()
+ self.attention = WavLMAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ num_buckets=config.num_buckets,
+ max_distance=config.max_bucket_distance,
+ has_relative_position_bias=has_relative_position_bias,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = WavLMFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, position_bias=None, output_attentions=False):
+ attn_residual = hidden_states
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states, attn_weights, position_bias = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+ hidden_states = hidden_states + self.feed_forward(self.final_layer_norm(hidden_states))
+
+ outputs = (hidden_states, position_bias)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class WavLMEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = WavLMPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList(
+ [WavLMEncoderLayer(config, has_relative_position_bias=(i == 0)) for i in range(config.num_hidden_layers)]
+ )
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+ position_bias = None
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and i > 0 and (dropout_probability < self.config.layerdrop)
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ index=i,
+ )
+
+ hidden_states, position_bias = layer_outputs[:2]
+
+ if skip_the_layer:
+ layer_outputs = (None, None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[2],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class WavLMEncoderStableLayerNorm(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = WavLMPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList(
+ [
+ WavLMEncoderLayerStableLayerNorm(config, has_relative_position_bias=(i == 0))
+ for i in range(config.num_hidden_layers)
+ ]
+ )
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens are not attended to
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+ position_bias = None
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and i > 0 and (dropout_probability < self.config.layerdrop)
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ # XXX: could optimize this like synced_gpus in generate_utils but not sure if it's worth the code complication
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ position_bias=position_bias,
+ )
+ hidden_states, position_bias = layer_outputs[:2]
+
+ if skip_the_layer:
+ layer_outputs = (None, None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[2],)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_self_attentions
+ )
+
+
+class WavLMGumbelVectorQuantizer(nn.Module):
+ """
+ Vector quantization using gumbel softmax. See [CATEGORICAL REPARAMETERIZATION WITH
+ GUMBEL-SOFTMAX](https://huggingface.co/papers/1611.01144) for more information.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.num_groups = config.num_codevector_groups
+ self.num_vars = config.num_codevectors_per_group
+
+ if config.codevector_dim % self.num_groups != 0:
+ raise ValueError(
+ f"`config.codevector_dim {config.codevector_dim} must be divisible"
+ f" by `config.num_codevector_groups` {self.num_groups} "
+ "for concatenation."
+ )
+
+ # storage for codebook variables (codewords)
+ self.codevectors = nn.Parameter(
+ torch.FloatTensor(1, self.num_groups * self.num_vars, config.codevector_dim // self.num_groups)
+ )
+ self.weight_proj = nn.Linear(config.conv_dim[-1], self.num_groups * self.num_vars)
+
+ # can be decayed for training
+ self.temperature = 2
+
+ @staticmethod
+ def _compute_perplexity(probs):
+ marginal_probs = probs.mean(dim=0)
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(hidden_states.float(), tau=self.temperature, hard=True)
+ codevector_probs = codevector_probs.type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(*hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+@auto_docstring
+class WavLMPreTrainedModel(PreTrainedModel):
+ config: WavLMConfig
+ base_model_prefix = "wavlm"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+ _supports_flash_attn = False
+ _supports_sdpa = False
+ _supports_flex_attn = False
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # gumbel softmax requires special init
+ if isinstance(module, WavLMGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, WavLMPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, WavLMFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_feat_extract_output_lengths(
+ self, input_lengths: Union[torch.LongTensor, int], add_adapter: Optional[bool] = None
+ ):
+ """
+ Computes the output length of the convolutional layers
+ """
+
+ add_adapter = self.config.add_adapter if add_adapter is None else add_adapter
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1
+
+ for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride):
+ input_lengths = _conv_out_length(input_lengths, kernel_size, stride)
+
+ if add_adapter:
+ for _ in range(self.config.num_adapter_layers):
+ input_lengths = _conv_out_length(input_lengths, 1, self.config.adapter_stride)
+
+ return input_lengths
+
+ def _get_feature_vector_attention_mask(
+ self, feature_vector_length: int, attention_mask: torch.LongTensor, add_adapter=None
+ ):
+ # Effectively attention_mask.sum(-1), but not inplace to be able to run
+ # on inference mode.
+ non_padded_lengths = attention_mask.cumsum(dim=-1)[:, -1]
+
+ output_lengths = self._get_feat_extract_output_lengths(non_padded_lengths, add_adapter=add_adapter)
+ output_lengths = output_lengths.to(torch.long)
+
+ batch_size = attention_mask.shape[0]
+
+ attention_mask = torch.zeros(
+ (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device
+ )
+ # these two operations makes sure that all values before the output lengths idxs are attended to
+ attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1
+ attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool()
+ return attention_mask
+
+
+class WavLMNoLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class WavLMLayerNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True)
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+
+ hidden_states = hidden_states.transpose(-2, -1)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = hidden_states.transpose(-2, -1)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class WavLMGroupNormConvLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1
+ self.out_conv_dim = config.conv_dim[layer_id]
+
+ self.conv = nn.Conv1d(
+ self.in_conv_dim,
+ self.out_conv_dim,
+ kernel_size=config.conv_kernel[layer_id],
+ stride=config.conv_stride[layer_id],
+ bias=config.conv_bias,
+ )
+ self.activation = ACT2FN[config.feat_extract_activation]
+
+ self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True)
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+class WavLMFeatureEncoder(nn.Module):
+ """Construct the features from raw audio waveform"""
+
+ def __init__(self, config):
+ super().__init__()
+
+ if config.feat_extract_norm == "group":
+ conv_layers = [WavLMGroupNormConvLayer(config, layer_id=0)] + [
+ WavLMNoLayerNormConvLayer(config, layer_id=i + 1) for i in range(config.num_feat_extract_layers - 1)
+ ]
+ elif config.feat_extract_norm == "layer":
+ conv_layers = [WavLMLayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)]
+ else:
+ raise ValueError(
+ f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']"
+ )
+ self.conv_layers = nn.ModuleList(conv_layers)
+ self.gradient_checkpointing = False
+ self._requires_grad = True
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def forward(self, input_values):
+ hidden_states = input_values[:, None]
+
+ # make sure hidden_states require grad for gradient_checkpointing
+ if self._requires_grad and self.training:
+ hidden_states.requires_grad = True
+
+ for conv_layer in self.conv_layers:
+ hidden_states = conv_layer(hidden_states)
+
+ return hidden_states
+
+
+class WavLMAdapterLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv = nn.Conv1d(
+ config.output_hidden_size,
+ 2 * config.output_hidden_size,
+ config.adapter_kernel_size,
+ stride=config.adapter_stride,
+ padding=1,
+ )
+
+ def forward(self, hidden_states):
+ hidden_states = self.conv(hidden_states)
+ hidden_states = nn.functional.glu(hidden_states, dim=1)
+
+ return hidden_states
+
+
+class WavLMAdapter(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+
+ # feature dim might need to be down-projected
+ if config.output_hidden_size != config.hidden_size:
+ self.proj = nn.Linear(config.hidden_size, config.output_hidden_size)
+ self.proj_layer_norm = nn.LayerNorm(config.output_hidden_size)
+ else:
+ self.proj = self.proj_layer_norm = None
+
+ self.layers = nn.ModuleList(WavLMAdapterLayer(config) for _ in range(config.num_adapter_layers))
+ self.layerdrop = config.layerdrop
+
+ def forward(self, hidden_states):
+ # down project hidden_states if necessary
+ if self.proj is not None and self.proj_layer_norm is not None:
+ hidden_states = self.proj(hidden_states)
+ hidden_states = self.proj_layer_norm(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+
+ for layer in self.layers:
+ layerdrop_prob = np.random.random()
+ if not self.training or (layerdrop_prob > self.layerdrop):
+ hidden_states = layer(hidden_states)
+
+ hidden_states = hidden_states.transpose(1, 2)
+ return hidden_states
+
+
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+WavLMBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+@auto_docstring
+class WavLMModel(WavLMPreTrainedModel):
+ def __init__(self, config: WavLMConfig):
+ super().__init__(config)
+ self.config = config
+ self.feature_extractor = WavLMFeatureEncoder(config)
+ self.feature_projection = WavLMFeatureProjection(config)
+
+ # model only needs masking vector if mask prob is > 0.0
+ if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0:
+ self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_())
+
+ if config.do_stable_layer_norm:
+ self.encoder = WavLMEncoderStableLayerNorm(config)
+ else:
+ self.encoder = WavLMEncoder(config)
+
+ self.adapter = WavLMAdapter(config) if config.add_adapter else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.feature_extractor._freeze_parameters()
+
+ def _mask_hidden_states(
+ self,
+ hidden_states: torch.FloatTensor,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return hidden_states
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, sequence_length, hidden_size = hidden_states.size()
+
+ if mask_time_indices is not None:
+ # apply SpecAugment along time axis with given mask_time_indices
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+ elif self.config.mask_time_prob > 0 and self.training:
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool)
+ hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype)
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool)
+ mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1)
+ hidden_states[mask_feature_indices] = 0
+
+ return hidden_states
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ mask_time_indices: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, WavLMBaseModelOutput]:
+ r"""
+ mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict
+ masked extracted features in *config.proj_codevector_dim* space.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states)
+
+ if not return_dict:
+ return (hidden_states, extract_features) + encoder_outputs[1:]
+
+ return WavLMBaseModelOutput(
+ last_hidden_state=hidden_states,
+ extract_features=extract_features,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+_HIDDEN_STATES_START_POSITION = 2
+
+
+@auto_docstring(
+ custom_intro="""
+ WavLM Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC).
+ """
+)
+class WavLMForCTC(WavLMPreTrainedModel):
+ def __init__(self, config, target_lang: Optional[str] = None):
+ r"""
+ target_lang (`str`, *optional*):
+ Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or
+ adapter..bin. Only relevant when using an instance of [`WavLMForCTC`] with adapters. Uses 'eng' by
+ default.
+ """
+ super().__init__(config)
+
+ self.wavlm = WavLMModel(config)
+ self.dropout = nn.Dropout(config.final_dropout)
+
+ self.target_lang = target_lang
+
+ if config.vocab_size is None:
+ raise ValueError(
+ f"You are trying to instantiate {self.__class__} with a configuration that "
+ "does not define the vocabulary size of the language model head. Please "
+ "instantiate the model as follows: `WavLMForCTC.from_pretrained(..., vocab_size=vocab_size)`. "
+ "or define `vocab_size` of your model's configuration."
+ )
+ output_hidden_size = (
+ config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size
+ )
+ self.lm_head = nn.Linear(output_hidden_size, config.vocab_size)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def tie_weights(self):
+ """
+ This method overwrites [`~PreTrainedModel.tie_weights`] so that adapter weights can be correctly loaded when
+ passing `target_lang=...` to `from_pretrained(...)`.
+
+ This method is **not** supposed to be called by the user and is prone to be changed in the future.
+ """
+
+ # Note that `tie_weights` is usually used to tie input and output embedding weights. The method is re-purposed to
+ # correctly load adapter layers for WavLM so that we do not have to introduce a new API to
+ # [`PreTrainedModel`]. While slightly hacky, WavLM never has to tie input and output embeddings, so that it is
+ # ok to repurpose this function here.
+ target_lang = self.target_lang
+
+ if target_lang is not None and getattr(self.config, "adapter_attn_dim", None) is None:
+ raise ValueError(f"Cannot pass `target_lang`: {target_lang} if `config.adapter_attn_dim` is not defined.")
+ elif target_lang is None and getattr(self.config, "adapter_attn_dim", None) is not None:
+ logger.info("By default `target_lang` is set to 'eng'.")
+ elif target_lang is not None:
+ self.load_adapter(target_lang, force_load=True)
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wavlm.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wavlm.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, CausalLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*):
+ Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to
+ the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`.
+ All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None and labels.max() >= self.config.vocab_size:
+ raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}")
+
+ outputs = self.wavlm(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states)
+
+ logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # retrieve loss input_lengths from attention_mask
+ attention_mask = (
+ attention_mask if attention_mask is not None else torch.ones_like(input_values, dtype=torch.long)
+ )
+ input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long)
+
+ # assuming that padded tokens are filled with -100
+ # when not being attended to
+ labels_mask = labels >= 0
+ target_lengths = labels_mask.sum(-1)
+ flattened_targets = labels.masked_select(labels_mask)
+
+ # ctc_loss doesn't support fp16
+ log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1)
+
+ with torch.backends.cudnn.flags(enabled=False):
+ loss = nn.functional.ctc_loss(
+ log_probs,
+ flattened_targets,
+ input_lengths,
+ target_lengths,
+ blank=self.config.pad_token_id,
+ reduction=self.config.ctc_loss_reduction,
+ zero_infinity=self.config.ctc_zero_infinity,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return CausalLMOutput(
+ loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ WavLM Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like
+ SUPERB Keyword Spotting.
+ """
+)
+class WavLMForSequenceClassification(WavLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Sequence classification does not support the use of WavLM adapters (config.add_adapter=True)"
+ )
+ self.wavlm = WavLMModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size)
+ self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameters will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wavlm.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wavlm.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`WavLMProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wavlm(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ if attention_mask is None:
+ pooled_output = hidden_states.mean(dim=1)
+ else:
+ padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask)
+ expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_padding_mask] = 0.0
+ pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class WavLMForAudioFrameClassification(WavLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ if hasattr(config, "add_adapter") and config.add_adapter:
+ raise ValueError(
+ "Audio frame classification does not support the use of WavLM adapters (config.add_adapter=True)"
+ )
+ self.wavlm = WavLMModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+ self.num_labels = config.num_labels
+
+ self.init_weights()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wavlm.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wavlm.parameters():
+ param.requires_grad = False
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`WavLMProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wavlm(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ logits = self.classifier(hidden_states)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), torch.argmax(labels.view(-1, self.num_labels), axis=1))
+
+ if not return_dict:
+ output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class AMSoftmaxLoss(nn.Module):
+ def __init__(self, input_dim, num_labels, scale=30.0, margin=0.4):
+ super().__init__()
+ self.scale = scale
+ self.margin = margin
+ self.num_labels = num_labels
+ self.weight = nn.Parameter(torch.randn(input_dim, num_labels), requires_grad=True)
+ self.loss = nn.CrossEntropyLoss()
+
+ def forward(self, hidden_states, labels):
+ labels = labels.flatten()
+ weight = nn.functional.normalize(self.weight, dim=0)
+ hidden_states = nn.functional.normalize(hidden_states, dim=1)
+ cos_theta = torch.mm(hidden_states, weight)
+ psi = cos_theta - self.margin
+
+ onehot = nn.functional.one_hot(labels, self.num_labels)
+ logits = self.scale * torch.where(onehot.bool(), psi, cos_theta)
+ loss = self.loss(logits, labels)
+
+ return loss
+
+
+class TDNNLayer(nn.Module):
+ def __init__(self, config, layer_id=0):
+ super().__init__()
+ self.in_conv_dim = config.tdnn_dim[layer_id - 1] if layer_id > 0 else config.tdnn_dim[layer_id]
+ self.out_conv_dim = config.tdnn_dim[layer_id]
+ self.kernel_size = config.tdnn_kernel[layer_id]
+ self.dilation = config.tdnn_dilation[layer_id]
+
+ self.kernel = nn.Linear(self.in_conv_dim * self.kernel_size, self.out_conv_dim)
+ self.activation = nn.ReLU()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ if is_peft_available():
+ from peft.tuners.lora import LoraLayer
+
+ if is_peft_available():
+ if isinstance(self.kernel, LoraLayer):
+ warnings.warn(
+ "Detected LoRA on TDNNLayer. LoRA weights won't be applied due to optimization. "
+ "You should exclude TDNNLayer from LoRA's target modules.",
+ )
+
+ # for backward compatibility, we keep nn.Linear but call F.conv1d for speed up
+ hidden_states = hidden_states.transpose(1, 2)
+ weight = self.kernel.weight.view(self.out_conv_dim, self.kernel_size, self.in_conv_dim).transpose(1, 2)
+ hidden_states = nn.functional.conv1d(hidden_states, weight, self.kernel.bias, dilation=self.dilation)
+ hidden_states = hidden_states.transpose(1, 2)
+
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+@auto_docstring(
+ custom_intro="""
+ WavLM Model with an XVector feature extraction head on top for tasks like Speaker Verification.
+ """
+)
+class WavLMForXVector(WavLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.wavlm = WavLMModel(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.tdnn_dim[0])
+
+ tdnn_layers = [TDNNLayer(config, i) for i in range(len(config.tdnn_dim))]
+ self.tdnn = nn.ModuleList(tdnn_layers)
+
+ self.feature_extractor = nn.Linear(config.tdnn_dim[-1] * 2, config.xvector_output_dim)
+ self.classifier = nn.Linear(config.xvector_output_dim, config.xvector_output_dim)
+
+ self.objective = AMSoftmaxLoss(config.xvector_output_dim, config.num_labels)
+
+ self.init_weights()
+
+ def freeze_feature_extractor(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ warnings.warn(
+ "The method `freeze_feature_extractor` is deprecated and will be removed in Transformers v5. "
+ "Please use the equivalent `freeze_feature_encoder` method instead.",
+ FutureWarning,
+ )
+ self.freeze_feature_encoder()
+
+ def freeze_feature_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the feature encoder so that its parameter will
+ not be updated during training.
+ """
+ self.wavlm.feature_extractor._freeze_parameters()
+
+ def freeze_base_model(self):
+ """
+ Calling this function will disable the gradient computation for the base model so that its parameters will not
+ be updated during training. Only the classification head will be updated.
+ """
+ for param in self.wavlm.parameters():
+ param.requires_grad = False
+
+ def _get_tdnn_output_lengths(self, input_lengths: Union[torch.LongTensor, int]):
+ """
+ Computes the output length of the TDNN layers
+ """
+
+ def _conv_out_length(input_length, kernel_size, stride):
+ # 1D convolutional layer output length formula taken
+ # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html
+ return (input_length - kernel_size) // stride + 1
+
+ for kernel_size in self.config.tdnn_kernel:
+ input_lengths = _conv_out_length(input_lengths, kernel_size, 1)
+
+ return input_lengths
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: Optional[torch.Tensor],
+ attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ labels: Optional[torch.Tensor] = None,
+ ) -> Union[tuple, XVectorOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`):
+ Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file
+ into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library
+ (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion
+ into a tensor of type `torch.FloatTensor`. See [`WavLMProcessor.__call__`] for details.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states
+
+ outputs = self.wavlm(
+ input_values,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+
+ for tdnn_layer in self.tdnn:
+ hidden_states = tdnn_layer(hidden_states)
+
+ # Statistic Pooling
+ if attention_mask is None:
+ mean_features = hidden_states.mean(dim=1)
+ std_features = hidden_states.std(dim=1)
+ else:
+ feat_extract_output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(dim=1))
+ tdnn_output_lengths = self._get_tdnn_output_lengths(feat_extract_output_lengths)
+ mean_features = []
+ std_features = []
+ for i, length in enumerate(tdnn_output_lengths):
+ mean_features.append(hidden_states[i, :length].mean(dim=0))
+ std_features.append(hidden_states[i, :length].std(dim=0))
+ mean_features = torch.stack(mean_features)
+ std_features = torch.stack(std_features)
+ statistic_pooling = torch.cat([mean_features, std_features], dim=-1)
+
+ output_embeddings = self.feature_extractor(statistic_pooling)
+ logits = self.classifier(output_embeddings)
+
+ loss = None
+ if labels is not None:
+ loss = self.objective(logits, labels)
+
+ if not return_dict:
+ output = (logits, output_embeddings) + outputs[_HIDDEN_STATES_START_POSITION:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XVectorOutput(
+ loss=loss,
+ logits=logits,
+ embeddings=output_embeddings,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "WavLMForAudioFrameClassification",
+ "WavLMForCTC",
+ "WavLMForSequenceClassification",
+ "WavLMForXVector",
+ "WavLMModel",
+ "WavLMPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/modular_wavlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/modular_wavlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..94b991dffbbde87721d41808ca048a037499a3dc
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/wavlm/modular_wavlm.py
@@ -0,0 +1,588 @@
+import math
+from typing import Optional, Union
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ...integrations.deepspeed import is_deepspeed_zero3_enabled
+from ...integrations.fsdp import is_fsdp_managed_module
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, Wav2Vec2BaseModelOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import logging
+from ..wav2vec2.modeling_wav2vec2 import (
+ Wav2Vec2FeatureProjection,
+ Wav2Vec2FeedForward,
+ Wav2Vec2ForAudioFrameClassification,
+ Wav2Vec2ForCTC,
+ Wav2Vec2ForSequenceClassification,
+ Wav2Vec2ForXVector,
+ Wav2Vec2Model,
+ Wav2Vec2PositionalConvEmbedding,
+ Wav2Vec2PreTrainedModel,
+)
+from .configuration_wavlm import WavLMConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class WavLMPositionalConvEmbedding(Wav2Vec2PositionalConvEmbedding):
+ pass
+
+
+class WavLMFeatureProjection(Wav2Vec2FeatureProjection):
+ pass
+
+
+class WavLMAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ num_buckets: int = 320,
+ max_distance: int = 800,
+ has_relative_position_bias: bool = True,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim)
+ self.v_proj = nn.Linear(embed_dim, embed_dim)
+ self.q_proj = nn.Linear(embed_dim, embed_dim)
+ self.out_proj = nn.Linear(embed_dim, embed_dim)
+
+ self.num_buckets = num_buckets
+ self.max_distance = max_distance
+
+ self.gru_rel_pos_const = nn.Parameter(torch.ones(1, self.num_heads, 1, 1))
+ self.gru_rel_pos_linear = nn.Linear(self.head_dim, 8)
+
+ if has_relative_position_bias:
+ self.rel_attn_embed = nn.Embedding(self.num_buckets, self.num_heads)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_bias: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ index=0,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Attention layer with relative attention"""
+ bsz, tgt_len, _ = hidden_states.size()
+
+ # first pass of attention layer creates position bias
+ if position_bias is None:
+ position_bias = self.compute_bias(tgt_len, tgt_len)
+ position_bias = (
+ position_bias.unsqueeze(0).repeat(bsz, 1, 1, 1).view(bsz * self.num_heads, tgt_len, tgt_len)
+ )
+
+ # Compute relative position bias:
+ # 1) get reshape hidden_states
+ gated_hidden_states = hidden_states.view(hidden_states.shape[:-1] + (self.num_heads, -1))
+ gated_hidden_states = gated_hidden_states.permute(0, 2, 1, 3)
+
+ # 2) project hidden states
+ relative_position_proj = self.gru_rel_pos_linear(gated_hidden_states)
+ relative_position_proj = relative_position_proj.view(gated_hidden_states.shape[:-1] + (2, 4)).sum(-1)
+
+ # 3) compute gate for position bias from projected hidden states
+ gate_a, gate_b = torch.sigmoid(relative_position_proj).chunk(2, dim=-1)
+ gate_output = gate_a * (gate_b * self.gru_rel_pos_const - 1.0) + 2.0
+
+ # 4) apply gate to position bias to compute gated position_bias
+ gated_position_bias = gate_output.view(bsz * self.num_heads, -1, 1) * position_bias
+ gated_position_bias = gated_position_bias.view((-1, tgt_len, tgt_len))
+
+ attn_output, attn_weights = self.torch_multi_head_self_attention(
+ hidden_states, attention_mask, gated_position_bias, output_attentions
+ )
+
+ return attn_output, attn_weights, position_bias
+
+ def torch_multi_head_self_attention(
+ self,
+ hidden_states: torch.FloatTensor,
+ attention_mask: Union[torch.LongTensor, torch.BoolTensor],
+ gated_position_bias: torch.FloatTensor,
+ output_attentions: bool,
+ ) -> (torch.FloatTensor, torch.FloatTensor):
+ """simple wrapper around torch's multi_head_attention_forward function"""
+ # self-attention assumes q = k = v
+ query = key = value = hidden_states.transpose(0, 1)
+ key_padding_mask = attention_mask.ne(1) if attention_mask is not None else None
+
+ # disable bias and add_zero_attn
+ bias_k = bias_v = None
+ add_zero_attn = False
+
+ # PyTorch 1.3.0 has F.multi_head_attention_forward defined
+ # so no problem with backwards compatibility
+ attn_output, attn_weights = F.multi_head_attention_forward(
+ query,
+ key,
+ value,
+ self.embed_dim,
+ self.num_heads,
+ torch.empty([0]),
+ torch.cat((self.q_proj.bias, self.k_proj.bias, self.v_proj.bias)),
+ bias_k,
+ bias_v,
+ add_zero_attn,
+ self.dropout,
+ self.out_proj.weight,
+ self.out_proj.bias,
+ self.training,
+ key_padding_mask,
+ output_attentions,
+ gated_position_bias,
+ use_separate_proj_weight=True,
+ q_proj_weight=self.q_proj.weight,
+ k_proj_weight=self.k_proj.weight,
+ v_proj_weight=self.v_proj.weight,
+ )
+
+ # [Seq_Len, Batch Size, ...] -> [Batch Size, Seq_Len, ...]
+ attn_output = attn_output.transpose(0, 1)
+
+ if attn_weights is not None:
+ # IMPORTANT: Attention weights are averaged weights
+ # here which should not be the case. This is an open issue
+ # on PyTorch: https://github.com/pytorch/pytorch/issues/32590
+ attn_weights = attn_weights[:, None].broadcast_to(
+ attn_weights.shape[:1] + (self.num_heads,) + attn_weights.shape[1:]
+ )
+
+ return attn_output, attn_weights
+
+ def compute_bias(self, query_length: int, key_length: int) -> torch.FloatTensor:
+ context_position = torch.arange(query_length, dtype=torch.long)[:, None]
+ memory_position = torch.arange(key_length, dtype=torch.long)[None, :]
+ relative_position = memory_position - context_position
+ relative_position_bucket = self._relative_positions_bucket(relative_position)
+ relative_position_bucket = relative_position_bucket.to(self.rel_attn_embed.weight.device)
+ values = self.rel_attn_embed(relative_position_bucket)
+ values = values.permute([2, 0, 1])
+ return values
+
+ def _relative_positions_bucket(self, relative_positions: torch.FloatTensor) -> torch.FloatTensor:
+ num_buckets = self.num_buckets // 2
+
+ relative_buckets = (relative_positions > 0).to(torch.long) * num_buckets
+ relative_positions = torch.abs(relative_positions)
+
+ max_exact = num_buckets // 2
+ is_small = relative_positions < max_exact
+
+ relative_positions_if_large = torch.log(relative_positions.float() / max_exact)
+ relative_positions_if_large = relative_positions_if_large / math.log(self.max_distance / max_exact)
+ relative_positions_if_large = relative_positions_if_large * (num_buckets - max_exact)
+ relative_position_if_large = (max_exact + relative_positions_if_large).to(torch.long)
+ relative_position_if_large = torch.min(
+ relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1)
+ )
+
+ relative_buckets += torch.where(is_small, relative_positions, relative_position_if_large)
+ return relative_buckets
+
+
+class WavLMFeedForward(Wav2Vec2FeedForward):
+ pass
+
+
+class WavLMEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: WavLMConfig, has_relative_position_bias: bool = True):
+ super().__init__()
+ self.attention = WavLMAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ num_buckets=config.num_buckets,
+ max_distance=config.max_bucket_distance,
+ has_relative_position_bias=has_relative_position_bias,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = WavLMFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, position_bias=None, output_attentions=False, index=0):
+ attn_residual = hidden_states
+ hidden_states, attn_weights, position_bias = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ index=index,
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ hidden_states = hidden_states + self.feed_forward(hidden_states)
+ hidden_states = self.final_layer_norm(hidden_states)
+
+ outputs = (hidden_states, position_bias)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class WavLMEncoderLayerStableLayerNorm(GradientCheckpointingLayer):
+ def __init__(self, config: WavLMConfig, has_relative_position_bias: bool = True):
+ super().__init__()
+ self.attention = WavLMAttention(
+ embed_dim=config.hidden_size,
+ num_heads=config.num_attention_heads,
+ dropout=config.attention_dropout,
+ num_buckets=config.num_buckets,
+ max_distance=config.max_bucket_distance,
+ has_relative_position_bias=has_relative_position_bias,
+ )
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.feed_forward = WavLMFeedForward(config)
+ self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states, attention_mask=None, position_bias=None, output_attentions=False):
+ attn_residual = hidden_states
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states, attn_weights, position_bias = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ )
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = attn_residual + hidden_states
+ hidden_states = hidden_states + self.feed_forward(self.final_layer_norm(hidden_states))
+
+ outputs = (hidden_states, position_bias)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class WavLMEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = WavLMPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList(
+ [WavLMEncoderLayer(config, has_relative_position_bias=(i == 0)) for i in range(config.num_hidden_layers)]
+ )
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens output 0
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.layer_norm(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+ position_bias = None
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and i > 0 and (dropout_probability < self.config.layerdrop)
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ position_bias=position_bias,
+ output_attentions=output_attentions,
+ index=i,
+ )
+
+ hidden_states, position_bias = layer_outputs[:2]
+
+ if skip_the_layer:
+ layer_outputs = (None, None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[2],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+class WavLMEncoderStableLayerNorm(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.pos_conv_embed = WavLMPositionalConvEmbedding(config)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout)
+ self.layers = nn.ModuleList(
+ [
+ WavLMEncoderLayerStableLayerNorm(config, has_relative_position_bias=(i == 0))
+ for i in range(config.num_hidden_layers)
+ ]
+ )
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ if attention_mask is not None:
+ # make sure padded tokens are not attended to
+ expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2])
+ hidden_states[~expand_attention_mask] = 0
+
+ position_embeddings = self.pos_conv_embed(hidden_states)
+ hidden_states = hidden_states + position_embeddings
+ hidden_states = self.dropout(hidden_states)
+
+ synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self)
+ position_bias = None
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = torch.rand([])
+
+ skip_the_layer = self.training and i > 0 and (dropout_probability < self.config.layerdrop)
+ if not skip_the_layer or synced_gpus:
+ # under fsdp or deepspeed zero3 all gpus must run in sync
+ # XXX: could optimize this like synced_gpus in generate_utils but not sure if it's worth the code complication
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ position_bias=position_bias,
+ )
+ hidden_states, position_bias = layer_outputs[:2]
+
+ if skip_the_layer:
+ layer_outputs = (None, None, None)
+
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[2],)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_self_attentions
+ )
+
+
+class WavLMGumbelVectorQuantizer(nn.Module):
+ """
+ Vector quantization using gumbel softmax. See [CATEGORICAL REPARAMETERIZATION WITH
+ GUMBEL-SOFTMAX](https://huggingface.co/papers/1611.01144) for more information.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.num_groups = config.num_codevector_groups
+ self.num_vars = config.num_codevectors_per_group
+
+ if config.codevector_dim % self.num_groups != 0:
+ raise ValueError(
+ f"`config.codevector_dim {config.codevector_dim} must be divisible"
+ f" by `config.num_codevector_groups` {self.num_groups} "
+ "for concatenation."
+ )
+
+ # storage for codebook variables (codewords)
+ self.codevectors = nn.Parameter(
+ torch.FloatTensor(1, self.num_groups * self.num_vars, config.codevector_dim // self.num_groups)
+ )
+ self.weight_proj = nn.Linear(config.conv_dim[-1], self.num_groups * self.num_vars)
+
+ # can be decayed for training
+ self.temperature = 2
+
+ @staticmethod
+ def _compute_perplexity(probs):
+ marginal_probs = probs.mean(dim=0)
+ perplexity = torch.exp(-torch.sum(marginal_probs * torch.log(marginal_probs + 1e-7), dim=-1)).sum()
+ return perplexity
+
+ def forward(self, hidden_states):
+ batch_size, sequence_length, hidden_size = hidden_states.shape
+
+ # project to codevector dim
+ hidden_states = self.weight_proj(hidden_states)
+ hidden_states = hidden_states.view(batch_size * sequence_length * self.num_groups, -1)
+
+ if self.training:
+ # sample code vector probs via gumbel in differentiateable way
+ codevector_probs = nn.functional.gumbel_softmax(hidden_states.float(), tau=self.temperature, hard=True)
+ codevector_probs = codevector_probs.type_as(hidden_states)
+
+ # compute perplexity
+ codevector_soft_dist = torch.softmax(
+ hidden_states.view(batch_size * sequence_length, self.num_groups, -1).float(), dim=-1
+ )
+ perplexity = self._compute_perplexity(codevector_soft_dist)
+ else:
+ # take argmax in non-differentiable way
+ # comptute hard codevector distribution (one hot)
+ codevector_idx = hidden_states.argmax(dim=-1)
+ codevector_probs = hidden_states.new_zeros(*hidden_states.shape).scatter_(
+ -1, codevector_idx.view(-1, 1), 1.0
+ )
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, self.num_groups, -1)
+
+ perplexity = self._compute_perplexity(codevector_probs)
+
+ codevector_probs = codevector_probs.view(batch_size * sequence_length, -1)
+ # use probs to retrieve codevectors
+ codevectors_per_group = codevector_probs.unsqueeze(-1) * self.codevectors
+ codevectors = codevectors_per_group.view(batch_size * sequence_length, self.num_groups, self.num_vars, -1)
+ codevectors = codevectors.sum(-2).view(batch_size, sequence_length, -1)
+
+ return codevectors, perplexity
+
+
+class WavLMPreTrainedModel(PreTrainedModel, Wav2Vec2PreTrainedModel):
+ config: WavLMConfig
+ base_model_prefix = "wavlm"
+ main_input_name = "input_values"
+ supports_gradient_checkpointing = True
+ _supports_flash_attn = False
+ _supports_sdpa = False
+ _supports_flex_attn = False
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ # gumbel softmax requires special init
+ if isinstance(module, WavLMGumbelVectorQuantizer):
+ module.weight_proj.weight.data.normal_(mean=0.0, std=1)
+ module.weight_proj.bias.data.zero_()
+ nn.init.uniform_(module.codevectors)
+ elif isinstance(module, WavLMPositionalConvEmbedding):
+ nn.init.normal_(
+ module.conv.weight,
+ mean=0,
+ std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)),
+ )
+ nn.init.constant_(module.conv.bias, 0)
+ elif isinstance(module, WavLMFeatureProjection):
+ k = math.sqrt(1 / module.projection.in_features)
+ nn.init.uniform_(module.projection.weight, a=-k, b=k)
+ nn.init.uniform_(module.projection.bias, a=-k, b=k)
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def _get_adapters(self):
+ raise AttributeError("Not needed for WavLM")
+
+ def init_adapter_layers(self):
+ raise AttributeError("Not needed for WavLM")
+
+ def load_adapter(self):
+ raise AttributeError("Not needed for WavLM")
+
+
+WavLMBaseModelOutput = Wav2Vec2BaseModelOutput
+
+
+class WavLMModel(Wav2Vec2Model):
+ pass
+
+
+class WavLMForCTC(Wav2Vec2ForCTC):
+ pass
+
+
+class WavLMForSequenceClassification(Wav2Vec2ForSequenceClassification):
+ pass
+
+
+class WavLMForAudioFrameClassification(Wav2Vec2ForAudioFrameClassification):
+ pass
+
+
+class WavLMForXVector(Wav2Vec2ForXVector):
+ pass
+
+
+__all__ = [
+ "WavLMForAudioFrameClassification",
+ "WavLMForCTC",
+ "WavLMForSequenceClassification",
+ "WavLMForXVector",
+ "WavLMModel",
+ "WavLMPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..a4956c5fbb257a20a3cb74a14cb48ea9005fdc73
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/__init__.py
@@ -0,0 +1,33 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_whisper import *
+ from .feature_extraction_whisper import *
+ from .modeling_flax_whisper import *
+ from .modeling_tf_whisper import *
+ from .modeling_whisper import *
+ from .processing_whisper import *
+ from .tokenization_whisper import *
+ from .tokenization_whisper_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/configuration_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/configuration_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..a8837cb1cdd2473723ff9bb55352cd5da6a59940
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/configuration_whisper.py
@@ -0,0 +1,348 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Whisper model configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+from typing import TYPE_CHECKING, Any, Optional, Union
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig, OnnxSeq2SeqConfigWithPast
+from ...utils import logging
+
+
+if TYPE_CHECKING:
+ from ...feature_extraction_utils import FeatureExtractionMixin
+ from ...tokenization_utils_base import PreTrainedTokenizerBase
+ from ...utils import TensorType
+
+logger = logging.get_logger(__name__)
+
+
+# fmt: off
+NON_SPEECH_TOKENS = [
+ 1, 2, 7, 8, 9, 10, 14, 25,
+ 26, 27, 28, 29, 31, 58, 59, 60, 61, 62,
+ 63, 90, 91, 92, 93, 357, 366, 438, 532, 685,
+ 705, 796, 930, 1058, 1220, 1267, 1279, 1303, 1343, 1377,
+ 1391, 1635, 1782, 1875, 2162, 2361, 2488, 3467, 4008, 4211,
+ 4600, 4808, 5299, 5855, 6329, 7203, 9609, 9959, 10563, 10786,
+ 11420, 11709, 11907, 13163, 13697, 13700, 14808, 15306, 16410, 16791,
+ 17992, 19203, 19510, 20724, 22305, 22935, 27007, 30109, 30420, 33409,
+ 34949, 40283, 40493, 40549, 47282, 49146, 50257, 50359, 50360, 50361
+]
+NON_SPEECH_TOKENS_MULTI = [
+ 1, 2, 7, 8, 9, 10, 14, 25,
+ 26, 27, 28, 29, 31, 58, 59, 60, 61, 62,
+ 63, 90, 91, 92, 93, 359, 503, 522, 542, 873,
+ 893, 902, 918, 922, 931, 1350, 1853, 1982, 2460, 2627,
+ 3246, 3253, 3268, 3536, 3846, 3961, 4183, 4667, 6585, 6647,
+ 7273, 9061, 9383, 10428, 10929, 11938, 12033, 12331, 12562, 13793,
+ 14157, 14635, 15265, 15618, 16553, 16604, 18362, 18956, 20075, 21675,
+ 22520, 26130, 26161, 26435, 28279, 29464, 31650, 32302, 32470, 36865,
+ 42863, 47425, 49870, 50254, 50258, 50360, 50361, 50362
+]
+# fmt: on
+
+
+class WhisperConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`WhisperModel`]. It is used to instantiate a
+ Whisper model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the Whisper
+ [openai/whisper-tiny](https://huggingface.co/openai/whisper-tiny) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 51865):
+ Vocabulary size of the Whisper model. Defines the number of different tokens that can be represented by the
+ `decoder_input_ids` passed when calling [`WhisperModel`]
+ num_mel_bins (`int`, *optional*, defaults to 80):
+ Number of mel features used per input features. Should correspond to the value used in the
+ `WhisperProcessor` class.
+ encoder_layers (`int`, *optional*, defaults to 4):
+ Number of encoder layers.
+ decoder_layers (`int`, *optional*, defaults to 4):
+ Number of decoder layers.
+ encoder_attention_heads (`int`, *optional*, defaults to 6):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ decoder_attention_heads (`int`, *optional*, defaults to 6):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ encoder_ffn_dim (`int`, *optional*, defaults to 1536):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in encoder.
+ decoder_ffn_dim (`int`, *optional*, defaults to 1536):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in decoder.
+ encoder_layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ decoder_layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the decoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ decoder_start_token_id (`int`, *optional*, defaults to 50257):
+ Corresponds to the "<|startoftranscript|>" token, which is automatically used when no `decoder_input_ids`
+ are provided to the `generate` function. It is used to guide the model`s generation process depending on
+ the task.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+ is_encoder_decoder (`bool`, *optional*, defaults to `True`):
+ Whether the model is used as an encoder/decoder or not.
+ activation_function (`str`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ d_model (`int`, *optional*, defaults to 384):
+ Dimensionality of the layers.
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for activations inside the fully connected layer.
+ init_std (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ scale_embedding (`bool`, *optional*, defaults to False):
+ Scale embeddings by diving by sqrt(d_model).
+ max_source_positions (`int`, *optional*, defaults to 1500):
+ The maximum sequence length of log-mel filter-bank features that this model might ever be used with.
+ max_target_positions (`int`, *optional*, defaults to 448):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ pad_token_id (`int`, *optional*, defaults to 50256):
+ Padding token id.
+ bos_token_id (`int`, *optional*, defaults to 50256):
+ Begin of stream token id.
+ eos_token_id (`int`, *optional*, defaults to 50256):
+ End of stream token id.
+ suppress_tokens (`list[int]`, *optional*):
+ A list containing the non-speech tokens that will be used by the logit processor in the `generate`
+ function. NON_SPEECH_TOKENS and NON_SPEECH_TOKENS_MULTI each correspond to the `english-only` and the
+ `multilingual` model.
+ begin_suppress_tokens (`list[int]`, *optional*, defaults to `[220,50256]`):
+ A list containing tokens that will be suppressed at the beginning of the sampling process. Initialized as
+ the token for `" "` (`blank_token_id`) and the `eos_token_id`
+ use_weighted_layer_sum (`bool`, *optional*, defaults to `False`):
+ Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an
+ instance of [`WhisperForAudioClassification`].
+ classifier_proj_size (`int`, *optional*, defaults to 256):
+ Dimensionality of the projection before token mean-pooling for classification. Only relevant when using an
+ instance of [`WhisperForAudioClassification`].
+ apply_spec_augment (`bool`, *optional*, defaults to `False`):
+ Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see
+ [SpecAugment: A Simple Data Augmentation Method for Automatic Speech
+ Recognition](https://huggingface.co/papers/1904.08779).
+ mask_time_prob (`float`, *optional*, defaults to 0.05):
+ Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking
+ procedure generates `mask_time_prob*len(time_axis)/mask_time_length` independent masks over the axis. If
+ reasoning from the probability of each feature vector to be chosen as the start of the vector span to be
+ masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the
+ actual percentage of masked vectors. This is only relevant if `apply_spec_augment == True`.
+ mask_time_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the time axis.
+ mask_time_min_masks (`int`, *optional*, defaults to 2),:
+ The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step,
+ irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length <
+ mask_time_min_masks''
+ mask_feature_prob (`float`, *optional*, defaults to 0.0):
+ Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The
+ masking procedure generates `mask_feature_prob*len(feature_axis)/mask_time_length` independent masks over
+ the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector
+ span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap
+ may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is
+ True`.
+ mask_feature_length (`int`, *optional*, defaults to 10):
+ Length of vector span along the feature axis.
+ mask_feature_min_masks (`int`, *optional*, defaults to 0),:
+ The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time
+ step, irrespectively of `mask_feature_prob`. Only relevant if
+ `mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks`.
+ median_filter_width (`int`, *optional*, defaults to 7):
+ Width of the median filter used to smoothen to cross-attention outputs when computing token timestamps.
+ Should be an odd number.
+
+ Example:
+
+ ```python
+ >>> from transformers import WhisperConfig, WhisperModel
+
+ >>> # Initializing a Whisper tiny style configuration
+ >>> configuration = WhisperConfig()
+
+ >>> # Initializing a model (with random weights) from the tiny style configuration
+ >>> model = WhisperModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "whisper"
+ keys_to_ignore_at_inference = ["past_key_values"]
+ attribute_map = {
+ "num_key_value_heads": "encoder_attention_heads",
+ "num_attention_heads": "encoder_attention_heads",
+ "hidden_size": "d_model",
+ }
+
+ def __init__(
+ self,
+ vocab_size=51865,
+ num_mel_bins=80,
+ encoder_layers=4,
+ encoder_attention_heads=6,
+ decoder_layers=4,
+ decoder_attention_heads=6,
+ decoder_ffn_dim=1536,
+ encoder_ffn_dim=1536,
+ encoder_layerdrop=0.0,
+ decoder_layerdrop=0.0,
+ decoder_start_token_id=50257,
+ use_cache=True,
+ is_encoder_decoder=True,
+ activation_function="gelu",
+ d_model=384,
+ dropout=0.0,
+ attention_dropout=0.0,
+ activation_dropout=0.0,
+ init_std=0.02,
+ scale_embedding=False,
+ max_source_positions=1500,
+ max_target_positions=448,
+ pad_token_id=50256,
+ bos_token_id=50256,
+ eos_token_id=50256,
+ suppress_tokens=None,
+ begin_suppress_tokens=[220, 50256],
+ use_weighted_layer_sum=False,
+ classifier_proj_size=256,
+ apply_spec_augment=False,
+ mask_time_prob=0.05,
+ mask_time_length=10,
+ mask_time_min_masks=2,
+ mask_feature_prob=0.0,
+ mask_feature_length=10,
+ mask_feature_min_masks=0,
+ median_filter_width=7,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.num_mel_bins = num_mel_bins
+ self.d_model = d_model
+ self.encoder_layers = encoder_layers
+ self.encoder_attention_heads = encoder_attention_heads
+ self.decoder_layers = decoder_layers
+ self.decoder_attention_heads = decoder_attention_heads
+ self.decoder_ffn_dim = decoder_ffn_dim
+ self.encoder_ffn_dim = encoder_ffn_dim
+ self.dropout = dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.activation_function = activation_function
+ self.init_std = init_std
+ self.encoder_layerdrop = encoder_layerdrop
+ self.decoder_layerdrop = decoder_layerdrop
+ self.use_cache = use_cache
+ self.num_hidden_layers = encoder_layers
+ self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True
+ self.max_source_positions = max_source_positions
+ self.max_target_positions = max_target_positions
+
+ # Audio Classification-specific parameters. Feel free to ignore for other classes.
+ self.classifier_proj_size = classifier_proj_size
+ self.use_weighted_layer_sum = use_weighted_layer_sum
+
+ # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779
+ self.apply_spec_augment = apply_spec_augment
+ self.mask_time_prob = mask_time_prob
+ self.mask_time_length = mask_time_length
+ self.mask_time_min_masks = mask_time_min_masks
+ self.mask_feature_prob = mask_feature_prob
+ self.mask_feature_length = mask_feature_length
+ self.mask_feature_min_masks = mask_feature_min_masks
+
+ self.median_filter_width = median_filter_width
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ is_encoder_decoder=is_encoder_decoder,
+ decoder_start_token_id=decoder_start_token_id,
+ suppress_tokens=suppress_tokens,
+ begin_suppress_tokens=begin_suppress_tokens,
+ **kwargs,
+ )
+
+
+class WhisperOnnxConfig(OnnxSeq2SeqConfigWithPast):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ common_inputs = OrderedDict(
+ [
+ ("input_features", {0: "batch", 1: "feature_size", 2: "encoder_sequence"}),
+ ]
+ )
+ if self.use_past:
+ common_inputs["decoder_input_ids"] = {0: "batch"}
+ else:
+ common_inputs["decoder_input_ids"] = {0: "batch", 1: "decoder_sequence"}
+
+ if self.use_past:
+ self.fill_with_past_key_values_(common_inputs, direction="inputs")
+
+ return common_inputs
+
+ def generate_dummy_inputs(
+ self,
+ preprocessor: Union["PreTrainedTokenizerBase", "FeatureExtractionMixin"],
+ batch_size: int = -1,
+ seq_length: int = -1,
+ is_pair: bool = False,
+ framework: Optional["TensorType"] = None,
+ sampling_rate: int = 22050,
+ time_duration: float = 5.0,
+ frequency: int = 220,
+ ) -> Mapping[str, Any]:
+ dummy_inputs = OrderedDict()
+ encoder_inputs = OnnxConfig.generate_dummy_inputs(
+ self,
+ preprocessor=preprocessor.feature_extractor,
+ batch_size=batch_size,
+ framework=framework,
+ sampling_rate=sampling_rate,
+ time_duration=time_duration,
+ frequency=frequency,
+ )
+ encoder_sequence_length = encoder_inputs["input_features"].shape[2]
+ seq_length = encoder_sequence_length // 2 if self.use_past else seq_length
+
+ decoder_inputs = super().generate_dummy_inputs(
+ preprocessor.tokenizer, batch_size, seq_length, is_pair, framework
+ )
+
+ dummy_inputs["input_features"] = encoder_inputs.pop("input_features")
+ dummy_inputs["decoder_input_ids"] = decoder_inputs.pop("decoder_input_ids")
+
+ if "past_key_values" in decoder_inputs:
+ dummy_inputs["past_key_values"] = decoder_inputs.pop("past_key_values")
+
+ return dummy_inputs
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 1e-3
+
+
+__all__ = ["WhisperConfig", "WhisperOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/english_normalizer.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/english_normalizer.py
new file mode 100644
index 0000000000000000000000000000000000000000..265ea04b5334e4e0c15294c881a5cc17609e1ff9
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/english_normalizer.py
@@ -0,0 +1,597 @@
+# Copyright 2022 The OpenAI team and The HuggingFace Team. All rights reserved.
+# Most of the code is copy pasted from the original whisper repository
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import re
+import unicodedata
+from collections.abc import Iterator
+from fractions import Fraction
+from re import Match
+from typing import Optional, Union
+
+import regex
+
+
+# non-ASCII letters that are not separated by "NFKD" normalization
+ADDITIONAL_DIACRITICS = {
+ "œ": "oe",
+ "Œ": "OE",
+ "ø": "o",
+ "Ø": "O",
+ "æ": "ae",
+ "Æ": "AE",
+ "ß": "ss",
+ "ẞ": "SS",
+ "đ": "d",
+ "Đ": "D",
+ "ð": "d",
+ "Ð": "D",
+ "þ": "th",
+ "Þ": "th",
+ "ł": "l",
+ "Ł": "L",
+}
+
+
+def remove_symbols_and_diacritics(s: str, keep=""):
+ """
+ Replace any other markers, symbols, and punctuations with a space, and drop any diacritics (category 'Mn' and some
+ manual mappings)
+ """
+
+ def replace_character(char):
+ if char in keep:
+ return char
+ elif char in ADDITIONAL_DIACRITICS:
+ return ADDITIONAL_DIACRITICS[char]
+
+ elif unicodedata.category(char) == "Mn":
+ return ""
+
+ elif unicodedata.category(char)[0] in "MSP":
+ return " "
+
+ return char
+
+ return "".join(replace_character(c) for c in unicodedata.normalize("NFKD", s))
+
+
+def remove_symbols(s: str):
+ """
+ Replace any other markers, symbols, punctuations with a space, keeping diacritics
+ """
+ return "".join(" " if unicodedata.category(c)[0] in "MSP" else c for c in unicodedata.normalize("NFKC", s))
+
+
+class BasicTextNormalizer:
+ def __init__(self, remove_diacritics: bool = False, split_letters: bool = False):
+ self.clean = remove_symbols_and_diacritics if remove_diacritics else remove_symbols
+ self.split_letters = split_letters
+
+ def __call__(self, s: str):
+ s = s.lower()
+ s = re.sub(r"[<\[][^>\]]*[>\]]", "", s) # remove words between brackets
+ s = re.sub(r"\(([^)]+?)\)", "", s) # remove words between parenthesis
+ s = self.clean(s).lower()
+
+ if self.split_letters:
+ s = " ".join(regex.findall(r"\X", s, regex.U))
+
+ s = re.sub(r"\s+", " ", s) # replace any successive whitespace characters with a space
+
+ return s
+
+
+class EnglishNumberNormalizer:
+ """
+ Convert any spelled-out numbers into arabic numbers, while handling:
+
+ - remove any commas
+ - keep the suffixes such as: `1960s`, `274th`, `32nd`, etc.
+ - spell out currency symbols after the number. e.g. `$20 million` -> `20000000 dollars`
+ - spell out `one` and `ones`
+ - interpret successive single-digit numbers as nominal: `one oh one` -> `101`
+ """
+
+ def __init__(self):
+ super().__init__()
+
+ self.zeros = {"o", "oh", "zero"}
+ # fmt: off
+ self.ones = {
+ name: i
+ for i, name in enumerate(
+ ["one", "two", "three", "four", "five", "six", "seven", "eight", "nine", "ten", "eleven", "twelve", "thirteen", "fourteen", "fifteen", "sixteen", "seventeen", "eighteen", "nineteen"],
+ start=1,
+ )
+ }
+ # fmt: on
+ self.ones_plural = {
+ "sixes" if name == "six" else name + "s": (value, "s") for name, value in self.ones.items()
+ }
+ self.ones_ordinal = {
+ "zeroth": (0, "th"),
+ "first": (1, "st"),
+ "second": (2, "nd"),
+ "third": (3, "rd"),
+ "fifth": (5, "th"),
+ "twelfth": (12, "th"),
+ **{
+ name + ("h" if name.endswith("t") else "th"): (value, "th")
+ for name, value in self.ones.items()
+ if value > 3 and value != 5 and value != 12
+ },
+ }
+ self.ones_suffixed = {**self.ones_plural, **self.ones_ordinal}
+
+ self.tens = {
+ "twenty": 20,
+ "thirty": 30,
+ "forty": 40,
+ "fifty": 50,
+ "sixty": 60,
+ "seventy": 70,
+ "eighty": 80,
+ "ninety": 90,
+ }
+ self.tens_plural = {name.replace("y", "ies"): (value, "s") for name, value in self.tens.items()}
+ self.tens_ordinal = {name.replace("y", "ieth"): (value, "th") for name, value in self.tens.items()}
+ self.tens_suffixed = {**self.tens_plural, **self.tens_ordinal}
+
+ self.multipliers = {
+ "hundred": 100,
+ "thousand": 1_000,
+ "million": 1_000_000,
+ "billion": 1_000_000_000,
+ "trillion": 1_000_000_000_000,
+ "quadrillion": 1_000_000_000_000_000,
+ "quintillion": 1_000_000_000_000_000_000,
+ "sextillion": 1_000_000_000_000_000_000_000,
+ "septillion": 1_000_000_000_000_000_000_000_000,
+ "octillion": 1_000_000_000_000_000_000_000_000_000,
+ "nonillion": 1_000_000_000_000_000_000_000_000_000_000,
+ "decillion": 1_000_000_000_000_000_000_000_000_000_000_000,
+ }
+ self.multipliers_plural = {name + "s": (value, "s") for name, value in self.multipliers.items()}
+ self.multipliers_ordinal = {name + "th": (value, "th") for name, value in self.multipliers.items()}
+ self.multipliers_suffixed = {**self.multipliers_plural, **self.multipliers_ordinal}
+ self.decimals = {*self.ones, *self.tens, *self.zeros}
+
+ self.preceding_prefixers = {
+ "minus": "-",
+ "negative": "-",
+ "plus": "+",
+ "positive": "+",
+ }
+ self.following_prefixers = {
+ "pound": "£",
+ "pounds": "£",
+ "euro": "€",
+ "euros": "€",
+ "dollar": "$",
+ "dollars": "$",
+ "cent": "¢",
+ "cents": "¢",
+ }
+ self.prefixes = set(list(self.preceding_prefixers.values()) + list(self.following_prefixers.values()))
+ self.suffixers = {
+ "per": {"cent": "%"},
+ "percent": "%",
+ }
+ self.specials = {"and", "double", "triple", "point"}
+
+ self.words = {
+ key
+ for mapping in [
+ self.zeros,
+ self.ones,
+ self.ones_suffixed,
+ self.tens,
+ self.tens_suffixed,
+ self.multipliers,
+ self.multipliers_suffixed,
+ self.preceding_prefixers,
+ self.following_prefixers,
+ self.suffixers,
+ self.specials,
+ ]
+ for key in mapping
+ }
+ self.literal_words = {"one", "ones"}
+
+ def process_words(self, words: list[str]) -> Iterator[str]:
+ prefix: Optional[str] = None
+ value: Optional[Union[str, int]] = None
+ skip = False
+
+ def to_fraction(s: str):
+ try:
+ return Fraction(s)
+ except ValueError:
+ return None
+
+ def output(result: Union[str, int]):
+ nonlocal prefix, value
+ result = str(result)
+ if prefix is not None:
+ result = prefix + result
+ value = None
+ prefix = None
+ return result
+
+ if len(words) == 0:
+ return
+
+ for i, current in enumerate(words):
+ prev = words[i - 1] if i != 0 else None
+ next = words[i + 1] if i != len(words) - 1 else None
+ if skip:
+ skip = False
+ continue
+
+ next_is_numeric = next is not None and re.match(r"^\d+(\.\d+)?$", next)
+ has_prefix = current[0] in self.prefixes
+ current_without_prefix = current[1:] if has_prefix else current
+ if re.match(r"^\d+(\.\d+)?$", current_without_prefix):
+ # arabic numbers (potentially with signs and fractions)
+ f = to_fraction(current_without_prefix)
+ if f is None:
+ raise ValueError("Converting the fraction failed")
+
+ if value is not None:
+ if isinstance(value, str) and value.endswith("."):
+ # concatenate decimals / ip address components
+ value = str(value) + str(current)
+ continue
+ else:
+ yield output(value)
+
+ prefix = current[0] if has_prefix else prefix
+ if f.denominator == 1:
+ value = f.numerator # store integers as int
+ else:
+ value = current_without_prefix
+ elif current not in self.words:
+ # non-numeric words
+ if value is not None:
+ yield output(value)
+ yield output(current)
+ elif current in self.zeros:
+ value = str(value or "") + "0"
+ elif current in self.ones:
+ ones = self.ones[current]
+
+ if value is None:
+ value = ones
+ elif isinstance(value, str) or prev in self.ones:
+ if prev in self.tens and ones < 10: # replace the last zero with the digit
+ value = value[:-1] + str(ones)
+ else:
+ value = str(value) + str(ones)
+ elif ones < 10:
+ if value % 10 == 0:
+ value += ones
+ else:
+ value = str(value) + str(ones)
+ else: # eleven to nineteen
+ if value % 100 == 0:
+ value += ones
+ else:
+ value = str(value) + str(ones)
+ elif current in self.ones_suffixed:
+ # ordinal or cardinal; yield the number right away
+ ones, suffix = self.ones_suffixed[current]
+ if value is None:
+ yield output(str(ones) + suffix)
+ elif isinstance(value, str) or prev in self.ones:
+ if prev in self.tens and ones < 10:
+ yield output(value[:-1] + str(ones) + suffix)
+ else:
+ yield output(str(value) + str(ones) + suffix)
+ elif ones < 10:
+ if value % 10 == 0:
+ yield output(str(value + ones) + suffix)
+ else:
+ yield output(str(value) + str(ones) + suffix)
+ else: # eleven to nineteen
+ if value % 100 == 0:
+ yield output(str(value + ones) + suffix)
+ else:
+ yield output(str(value) + str(ones) + suffix)
+ value = None
+ elif current in self.tens:
+ tens = self.tens[current]
+ if value is None:
+ value = tens
+ elif isinstance(value, str):
+ value = str(value) + str(tens)
+ else:
+ if value % 100 == 0:
+ value += tens
+ else:
+ value = str(value) + str(tens)
+ elif current in self.tens_suffixed:
+ # ordinal or cardinal; yield the number right away
+ tens, suffix = self.tens_suffixed[current]
+ if value is None:
+ yield output(str(tens) + suffix)
+ elif isinstance(value, str):
+ yield output(str(value) + str(tens) + suffix)
+ else:
+ if value % 100 == 0:
+ yield output(str(value + tens) + suffix)
+ else:
+ yield output(str(value) + str(tens) + suffix)
+ elif current in self.multipliers:
+ multiplier = self.multipliers[current]
+ if value is None:
+ value = multiplier
+ elif isinstance(value, str) or value == 0:
+ f = to_fraction(value)
+ p = f * multiplier if f is not None else None
+ if f is not None and p.denominator == 1:
+ value = p.numerator
+ else:
+ yield output(value)
+ value = multiplier
+ else:
+ before = value // 1000 * 1000
+ residual = value % 1000
+ value = before + residual * multiplier
+ elif current in self.multipliers_suffixed:
+ multiplier, suffix = self.multipliers_suffixed[current]
+ if value is None:
+ yield output(str(multiplier) + suffix)
+ elif isinstance(value, str):
+ f = to_fraction(value)
+ p = f * multiplier if f is not None else None
+ if f is not None and p.denominator == 1:
+ yield output(str(p.numerator) + suffix)
+ else:
+ yield output(value)
+ yield output(str(multiplier) + suffix)
+ else: # int
+ before = value // 1000 * 1000
+ residual = value % 1000
+ value = before + residual * multiplier
+ yield output(str(value) + suffix)
+ value = None
+ elif current in self.preceding_prefixers:
+ # apply prefix (positive, minus, etc.) if it precedes a number
+ if value is not None:
+ yield output(value)
+
+ if next in self.words or next_is_numeric:
+ prefix = self.preceding_prefixers[current]
+ else:
+ yield output(current)
+ elif current in self.following_prefixers:
+ # apply prefix (dollars, cents, etc.) only after a number
+ if value is not None:
+ prefix = self.following_prefixers[current]
+ yield output(value)
+ else:
+ yield output(current)
+ elif current in self.suffixers:
+ # apply suffix symbols (percent -> '%')
+ if value is not None:
+ suffix = self.suffixers[current]
+ if isinstance(suffix, dict):
+ if next in suffix:
+ yield output(str(value) + suffix[next])
+ skip = True
+ else:
+ yield output(value)
+ yield output(current)
+ else:
+ yield output(str(value) + suffix)
+ else:
+ yield output(current)
+ elif current in self.specials:
+ if next not in self.words and not next_is_numeric:
+ # apply special handling only if the next word can be numeric
+ if value is not None:
+ yield output(value)
+ yield output(current)
+ elif current == "and":
+ # ignore "and" after hundreds, thousands, etc.
+ if prev not in self.multipliers:
+ if value is not None:
+ yield output(value)
+ yield output(current)
+ elif current == "double" or current == "triple":
+ if next in self.ones or next in self.zeros:
+ repeats = 2 if current == "double" else 3
+ ones = self.ones.get(next, 0)
+ value = str(value or "") + str(ones) * repeats
+ skip = True
+ else:
+ if value is not None:
+ yield output(value)
+ yield output(current)
+ elif current == "point":
+ if next in self.decimals or next_is_numeric:
+ value = str(value or "") + "."
+ else:
+ # should all have been covered at this point
+ raise ValueError(f"Unexpected token: {current}")
+ else:
+ # all should have been covered at this point
+ raise ValueError(f"Unexpected token: {current}")
+
+ if value is not None:
+ yield output(value)
+
+ def preprocess(self, s: str):
+ # replace " and a half" with " point five"
+ results = []
+
+ segments = re.split(r"\band\s+a\s+half\b", s)
+ for i, segment in enumerate(segments):
+ if len(segment.strip()) == 0:
+ continue
+ if i == len(segments) - 1:
+ results.append(segment)
+ else:
+ results.append(segment)
+ last_word = segment.rsplit(maxsplit=2)[-1]
+ if last_word in self.decimals or last_word in self.multipliers:
+ results.append("point five")
+ else:
+ results.append("and a half")
+
+ s = " ".join(results)
+
+ # put a space at number/letter boundary
+ s = re.sub(r"([a-z])([0-9])", r"\1 \2", s)
+ s = re.sub(r"([0-9])([a-z])", r"\1 \2", s)
+
+ # but remove spaces which could be a suffix
+ s = re.sub(r"([0-9])\s+(st|nd|rd|th|s)\b", r"\1\2", s)
+
+ return s
+
+ def postprocess(self, s: str):
+ def combine_cents(m: Match):
+ try:
+ currency = m.group(1)
+ integer = m.group(2)
+ cents = int(m.group(3))
+ return f"{currency}{integer}.{cents:02d}"
+ except ValueError:
+ return m.string
+
+ def extract_cents(m: Match):
+ try:
+ return f"¢{int(m.group(1))}"
+ except ValueError:
+ return m.string
+
+ # apply currency postprocessing; "$2 and ¢7" -> "$2.07"
+ s = re.sub(r"([€£$])([0-9]+) (?:and )?¢([0-9]{1,2})\b", combine_cents, s)
+ s = re.sub(r"[€£$]0.([0-9]{1,2})\b", extract_cents, s)
+
+ # write "one(s)" instead of "1(s)", just for the readability
+ s = re.sub(r"\b1(s?)\b", r"one\1", s)
+
+ return s
+
+ def __call__(self, s: str):
+ s = self.preprocess(s)
+ s = " ".join(word for word in self.process_words(s.split()) if word is not None)
+ s = self.postprocess(s)
+
+ return s
+
+
+class EnglishSpellingNormalizer:
+ """
+ Applies British-American spelling mappings as listed in [1].
+
+ [1] https://www.tysto.com/uk-us-spelling-list.html
+ """
+
+ def __init__(self, english_spelling_mapping):
+ self.mapping = english_spelling_mapping
+
+ def __call__(self, s: str):
+ return " ".join(self.mapping.get(word, word) for word in s.split())
+
+
+class EnglishTextNormalizer:
+ def __init__(self, english_spelling_mapping):
+ self.ignore_patterns = r"\b(hmm|mm|mhm|mmm|uh|um)\b"
+ self.replacers = {
+ # common contractions
+ r"\bwon't\b": "will not",
+ r"\bcan't\b": "can not",
+ r"\blet's\b": "let us",
+ r"\bain't\b": "aint",
+ r"\by'all\b": "you all",
+ r"\bwanna\b": "want to",
+ r"\bgotta\b": "got to",
+ r"\bgonna\b": "going to",
+ r"\bi'ma\b": "i am going to",
+ r"\bimma\b": "i am going to",
+ r"\bwoulda\b": "would have",
+ r"\bcoulda\b": "could have",
+ r"\bshoulda\b": "should have",
+ r"\bma'am\b": "madam",
+ # contractions in titles/prefixes
+ r"\bmr\b": "mister ",
+ r"\bmrs\b": "missus ",
+ r"\bst\b": "saint ",
+ r"\bdr\b": "doctor ",
+ r"\bprof\b": "professor ",
+ r"\bcapt\b": "captain ",
+ r"\bgov\b": "governor ",
+ r"\bald\b": "alderman ",
+ r"\bgen\b": "general ",
+ r"\bsen\b": "senator ",
+ r"\brep\b": "representative ",
+ r"\bpres\b": "president ",
+ r"\brev\b": "reverend ",
+ r"\bhon\b": "honorable ",
+ r"\basst\b": "assistant ",
+ r"\bassoc\b": "associate ",
+ r"\blt\b": "lieutenant ",
+ r"\bcol\b": "colonel ",
+ r"\bjr\b": "junior ",
+ r"\bsr\b": "senior ",
+ r"\besq\b": "esquire ",
+ # prefect tenses, ideally it should be any past participles, but it's harder..
+ r"'d been\b": " had been",
+ r"'s been\b": " has been",
+ r"'d gone\b": " had gone",
+ r"'s gone\b": " has gone",
+ r"'d done\b": " had done", # "'s done" is ambiguous
+ r"'s got\b": " has got",
+ # general contractions
+ r"n't\b": " not",
+ r"'re\b": " are",
+ r"'s\b": " is",
+ r"'d\b": " would",
+ r"'ll\b": " will",
+ r"'t\b": " not",
+ r"'ve\b": " have",
+ r"'m\b": " am",
+ }
+ self.standardize_numbers = EnglishNumberNormalizer()
+ self.standardize_spellings = EnglishSpellingNormalizer(english_spelling_mapping)
+
+ def __call__(self, s: str):
+ s = s.lower()
+
+ s = re.sub(r"[<\[][^>\]]*[>\]]", "", s) # remove words between brackets
+ s = re.sub(r"\(([^)]+?)\)", "", s) # remove words between parenthesis
+ s = re.sub(self.ignore_patterns, "", s)
+ s = re.sub(r"\s+'", "'", s) # standardize when there's a space before an apostrophe
+
+ for pattern, replacement in self.replacers.items():
+ s = re.sub(pattern, replacement, s)
+
+ s = re.sub(r"(\d),(\d)", r"\1\2", s) # remove commas between digits
+ s = re.sub(r"\.([^0-9]|$)", r" \1", s) # remove periods not followed by numbers
+ s = remove_symbols_and_diacritics(s, keep=".%$¢€£") # keep some symbols for numerics
+
+ s = self.standardize_numbers(s)
+ s = self.standardize_spellings(s)
+
+ # now remove prefix/suffix symbols that are not preceded/followed by numbers
+ s = re.sub(r"[.$¢€£]([^0-9])", r" \1", s)
+ s = re.sub(r"([^0-9])%", r"\1 ", s)
+
+ s = re.sub(r"\s+", " ", s) # replace any successive whitespace characters with a space
+
+ return s
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/feature_extraction_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/feature_extraction_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..68c52c6eb3c82f7ffbf2a008b48d428584f2ed7e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/feature_extraction_whisper.py
@@ -0,0 +1,343 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Feature extractor class for Whisper
+"""
+
+from typing import Optional, Union
+
+import numpy as np
+
+from ... import is_torch_available
+from ...audio_utils import mel_filter_bank, spectrogram, window_function
+from ...feature_extraction_sequence_utils import SequenceFeatureExtractor
+from ...feature_extraction_utils import BatchFeature
+from ...utils import TensorType, logging
+
+
+if is_torch_available():
+ import torch
+
+logger = logging.get_logger(__name__)
+
+
+class WhisperFeatureExtractor(SequenceFeatureExtractor):
+ r"""
+ Constructs a Whisper feature extractor.
+
+ This feature extractor inherits from [`~feature_extraction_sequence_utils.SequenceFeatureExtractor`] which contains
+ most of the main methods. Users should refer to this superclass for more information regarding those methods.
+
+ This class extracts mel-filter bank features from raw speech using a custom numpy implementation of the `Short Time
+ Fourier Transform` which should match pytorch's `torch.stft` equivalent.
+
+ Args:
+ feature_size (`int`, *optional*, defaults to 80):
+ The feature dimension of the extracted features.
+ sampling_rate (`int`, *optional*, defaults to 16000):
+ The sampling rate at which the audio files should be digitalized expressed in hertz (Hz).
+ hop_length (`int`, *optional*, defaults to 160):
+ Length of the overlapping windows for the STFT used to obtain the Mel Frequency coefficients.
+ chunk_length (`int`, *optional*, defaults to 30):
+ The maximum number of chunks of `sampling_rate` samples used to trim and pad longer or shorter audio
+ sequences.
+ n_fft (`int`, *optional*, defaults to 400):
+ Size of the Fourier transform.
+ padding_value (`float`, *optional*, defaults to 0.0):
+ Padding value used to pad the audio. Should correspond to silences.
+ dither (`float`, *optional*, defaults to 0.0):
+ Adds dithering. In other words, adds a small Gaussian noise to each frame.
+ E.g. use 0.0001 to add dithering with a normal distribution centered
+ around 0.0 with standard deviation 0.0001 (assuming [-1,+1] range of raw_speech).
+ The value 0.0 means no dithering.
+ Dithering has similar effect as `spectrogram(mel_floor=...)`. It reduces
+ the high log_mel_fbank values for signals with hard-zero sections,
+ when VAD cutoff is present in the signal.
+ """
+
+ model_input_names = ["input_features"]
+
+ def __init__(
+ self,
+ feature_size=80,
+ sampling_rate=16000,
+ hop_length=160,
+ chunk_length=30,
+ n_fft=400,
+ padding_value=0.0,
+ dither=0.0,
+ return_attention_mask=False, # pad inputs to max length with silence token (zero) and no attention mask
+ **kwargs,
+ ):
+ super().__init__(
+ feature_size=feature_size,
+ sampling_rate=sampling_rate,
+ padding_value=padding_value,
+ return_attention_mask=return_attention_mask,
+ **kwargs,
+ )
+ self.n_fft = n_fft
+ self.hop_length = hop_length
+ self.chunk_length = chunk_length
+ self.n_samples = chunk_length * sampling_rate
+ self.nb_max_frames = self.n_samples // hop_length
+ self.sampling_rate = sampling_rate
+ self.dither = dither
+ self.mel_filters = mel_filter_bank(
+ num_frequency_bins=1 + n_fft // 2,
+ num_mel_filters=feature_size,
+ min_frequency=0.0,
+ max_frequency=8000.0,
+ sampling_rate=sampling_rate,
+ norm="slaney",
+ mel_scale="slaney",
+ )
+
+ def _np_extract_fbank_features(self, waveform_batch: np.array, device: str) -> np.ndarray:
+ """
+ Compute the log-mel spectrogram of the provided audio, gives similar results to Whisper's original torch
+ implementation with 1e-5 tolerance.
+ """
+ if device != "cpu":
+ raise ValueError(
+ f"Got device `{device}` for feature extraction, but feature extraction on CUDA accelerator "
+ "devices requires torch, which is not installed. Either set `device='cpu'`, or "
+ "install torch according to the official instructions: https://pytorch.org/get-started/locally/"
+ )
+ log_spec_batch = []
+ for waveform in waveform_batch:
+ log_spec = spectrogram(
+ waveform,
+ window_function(self.n_fft, "hann"),
+ frame_length=self.n_fft,
+ hop_length=self.hop_length,
+ power=2.0,
+ dither=self.dither,
+ mel_filters=self.mel_filters,
+ log_mel="log10",
+ )
+ log_spec = log_spec[:, :-1]
+ log_spec = np.maximum(log_spec, log_spec.max() - 8.0)
+ log_spec = (log_spec + 4.0) / 4.0
+ log_spec_batch.append(log_spec)
+ log_spec_batch = np.array(log_spec_batch)
+ return log_spec_batch
+
+ def _torch_extract_fbank_features(self, waveform: np.array, device: str = "cpu") -> np.ndarray:
+ """
+ Compute the log-mel spectrogram of the audio using PyTorch's GPU-accelerated STFT implementation with batching,
+ yielding results similar to cpu computing with 1e-5 tolerance.
+ """
+ waveform = torch.from_numpy(waveform).to(device, torch.float32)
+ window = torch.hann_window(self.n_fft, device=device)
+
+ # Note: it would be better to dither the chunked waveform,
+ # so overlapping signal does not get the same dithering.
+ # But, chunking is happening inside pytorch, so it is here.
+ if self.dither != 0.0:
+ waveform += self.dither * torch.randn(waveform.shape, dtype=waveform.dtype, device=waveform.device)
+
+ stft = torch.stft(waveform, self.n_fft, self.hop_length, window=window, return_complex=True)
+ magnitudes = stft[..., :-1].abs() ** 2
+
+ mel_filters = torch.from_numpy(self.mel_filters).to(device, torch.float32)
+ mel_spec = mel_filters.T @ magnitudes
+
+ log_spec = torch.clamp(mel_spec, min=1e-10).log10()
+ if waveform.dim() == 2:
+ max_val = log_spec.max(dim=2, keepdim=True)[0].max(dim=1, keepdim=True)[0]
+ log_spec = torch.maximum(log_spec, max_val - 8.0)
+ else:
+ log_spec = torch.maximum(log_spec, log_spec.max() - 8.0)
+ log_spec = (log_spec + 4.0) / 4.0
+ if device != "cpu":
+ log_spec = log_spec.detach().cpu()
+ return log_spec.numpy()
+
+ @staticmethod
+ # Copied from transformers.models.wav2vec2.feature_extraction_wav2vec2.Wav2Vec2FeatureExtractor.zero_mean_unit_var_norm
+ def zero_mean_unit_var_norm(
+ input_values: list[np.ndarray], attention_mask: list[np.ndarray], padding_value: float = 0.0
+ ) -> list[np.ndarray]:
+ """
+ Every array in the list is normalized to have zero mean and unit variance
+ """
+ if attention_mask is not None:
+ attention_mask = np.array(attention_mask, np.int32)
+ normed_input_values = []
+
+ for vector, length in zip(input_values, attention_mask.sum(-1)):
+ normed_slice = (vector - vector[:length].mean()) / np.sqrt(vector[:length].var() + 1e-7)
+ if length < normed_slice.shape[0]:
+ normed_slice[length:] = padding_value
+
+ normed_input_values.append(normed_slice)
+ else:
+ normed_input_values = [(x - x.mean()) / np.sqrt(x.var() + 1e-7) for x in input_values]
+
+ return normed_input_values
+
+ def __call__(
+ self,
+ raw_speech: Union[np.ndarray, list[float], list[np.ndarray], list[list[float]]],
+ truncation: bool = True,
+ pad_to_multiple_of: Optional[int] = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ return_attention_mask: Optional[bool] = None,
+ padding: Optional[str] = "max_length",
+ max_length: Optional[int] = None,
+ sampling_rate: Optional[int] = None,
+ do_normalize: Optional[bool] = None,
+ device: Optional[str] = "cpu",
+ return_token_timestamps: Optional[bool] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Main method to featurize and prepare for the model one or several sequence(s). Implementation uses PyTorch for
+ the STFT computation if available, otherwise a slower NumPy based one.
+
+ Args:
+ raw_speech (`np.ndarray`, `list[float]`, `list[np.ndarray]`, `list[list[float]]`):
+ The sequence or batch of sequences to be padded. Each sequence can be a numpy array, a list of float
+ values, a list of numpy arrays or a list of list of float values. Must be mono channel audio, not
+ stereo, i.e. single float per timestep.
+ truncation (`bool`, *optional*, default to `True`):
+ Activates truncation to cut input sequences longer than *max_length* to *max_length*.
+ pad_to_multiple_of (`int`, *optional*, defaults to None):
+ If set will pad the sequence to a multiple of the provided value.
+
+ This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability
+ `>= 7.5` (Volta), or on TPUs which benefit from having sequence lengths be a multiple of 128.
+ return_attention_mask (`bool`, *optional*):
+ Whether to return the attention mask. If left to the default, will return the attention mask according
+ to the specific feature_extractor's default.
+
+ [What are attention masks?](../glossary#attention-mask)
+
+
+
+ For Whisper models, `attention_mask` should always be passed for batched inference, to avoid subtle
+ bugs.
+
+
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors instead of list of python integers. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return Numpy `np.ndarray` objects.
+ sampling_rate (`int`, *optional*):
+ The sampling rate at which the `raw_speech` input was sampled. It is strongly recommended to pass
+ `sampling_rate` at the forward call to prevent silent errors and allow automatic speech recognition
+ pipeline.
+ padding_value (`float`, *optional*, defaults to 0.0):
+ The value that is used to fill the padding values / vectors.
+ do_normalize (`bool`, *optional*, defaults to `False`):
+ Whether or not to zero-mean unit-variance normalize the input. Normalizing can help to significantly
+ improve the performance of the model.
+ device (`str`, *optional*, defaults to `'cpu'`):
+ Specifies the device for computation of the log-mel spectrogram of audio signals in the
+ `_torch_extract_fbank_features` method. (e.g., "cpu", "cuda")
+ return_token_timestamps (`bool`, *optional*, defaults to `None`):
+ Deprecated. Use `return_attention_mask` instead from which the number of frames can be inferred.
+
+ Whether or not to return the number of frames of the input raw_speech.
+ These num_frames can be used by the model to compute word level timestamps.
+ """
+ if sampling_rate is not None:
+ if sampling_rate != self.sampling_rate:
+ raise ValueError(
+ f"The model corresponding to this feature extractor: {self.__class__.__name__} was trained using a"
+ f" sampling rate of {self.sampling_rate}. Please make sure that the provided `raw_speech` input"
+ f" was sampled with {self.sampling_rate} and not {sampling_rate}."
+ )
+ else:
+ logger.warning(
+ f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. "
+ "Failing to do so can result in silent errors that might be hard to debug."
+ )
+
+ is_batched_numpy = isinstance(raw_speech, np.ndarray) and len(raw_speech.shape) > 1
+ if is_batched_numpy and len(raw_speech.shape) > 2:
+ raise ValueError(f"Only mono-channel audio is supported for input to {self}")
+ is_batched = is_batched_numpy or (
+ isinstance(raw_speech, (list, tuple)) and (isinstance(raw_speech[0], (np.ndarray, tuple, list)))
+ )
+
+ if is_batched:
+ raw_speech = [np.asarray([speech], dtype=np.float32).T for speech in raw_speech]
+ elif not is_batched and not isinstance(raw_speech, np.ndarray):
+ raw_speech = np.asarray(raw_speech, dtype=np.float32)
+ elif isinstance(raw_speech, np.ndarray) and raw_speech.dtype is np.dtype(np.float64):
+ raw_speech = raw_speech.astype(np.float32)
+
+ # always return batch
+ if not is_batched:
+ raw_speech = [np.asarray([raw_speech]).T]
+
+ batched_speech = BatchFeature({"input_features": raw_speech})
+
+ # convert into correct format for padding
+
+ padded_inputs = self.pad(
+ batched_speech,
+ padding=padding,
+ max_length=max_length if max_length else self.n_samples,
+ truncation=truncation,
+ pad_to_multiple_of=pad_to_multiple_of,
+ return_attention_mask=return_attention_mask or do_normalize,
+ )
+
+ # zero-mean and unit-variance normalization
+ if do_normalize:
+ padded_inputs["input_features"] = self.zero_mean_unit_var_norm(
+ padded_inputs["input_features"],
+ attention_mask=padded_inputs["attention_mask"],
+ padding_value=self.padding_value,
+ )
+ padded_inputs["input_features"] = np.stack(padded_inputs["input_features"], axis=0)
+
+ # make sure list is in array format
+ input_features = padded_inputs.get("input_features").transpose(2, 0, 1)
+
+ extract_fbank_features = (
+ self._torch_extract_fbank_features if is_torch_available() else self._np_extract_fbank_features
+ )
+ input_features = extract_fbank_features(input_features[0], device)
+
+ if isinstance(input_features[0], list):
+ padded_inputs["input_features"] = [np.asarray(feature, dtype=np.float32) for feature in input_features]
+
+ else:
+ padded_inputs["input_features"] = input_features
+
+ if return_attention_mask:
+ # rescale from sample (48000) to feature (3000)
+ padded_inputs["attention_mask"] = padded_inputs["attention_mask"][:, :: self.hop_length]
+
+ if return_token_timestamps is not None:
+ logger.warning_once(
+ f"`return_token_timestamps` is deprecated for {self.__class__.__name__} and will be removed in Transformers v5. Use `return_attention_mask` instead, as the number of frames can be inferred from it."
+ )
+ padded_inputs["num_frames"] = [len(raw_speech_i) // self.hop_length for raw_speech_i in raw_speech]
+
+ if return_tensors is not None:
+ padded_inputs = padded_inputs.convert_to_tensors(return_tensors)
+
+ return padded_inputs
+
+
+__all__ = ["WhisperFeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/generation_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/generation_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..93dd29ae0fed13d88e7be93ca8f9cfc0f199d1ce
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/generation_whisper.py
@@ -0,0 +1,2096 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import copy
+import math
+import warnings
+import zlib
+from collections.abc import Iterator
+from typing import Callable, Optional, Union
+
+import numpy as np
+import torch
+import torch.nn.functional as F
+from torch import nn
+
+from transformers.cache_utils import EncoderDecoderCache
+
+from ...generation import GenerationConfig, GenerationMixin
+from ...generation.logits_process import (
+ LogitsProcessorList,
+ SuppressTokensAtBeginLogitsProcessor,
+ SuppressTokensLogitsProcessor,
+ WhisperNoSpeechDetection,
+ WhisperTimeStampLogitsProcessor,
+)
+from ...generation.stopping_criteria import StoppingCriteriaList
+from ...modeling_outputs import BaseModelOutput
+from ...utils import logging
+from .tokenization_whisper import TASK_IDS, TO_LANGUAGE_CODE
+
+
+logger = logging.get_logger(__name__)
+
+
+def _median_filter(inputs: torch.Tensor, filter_width: int) -> torch.Tensor:
+ """
+ Applies a median filter of width `filter_width` along the last dimension of the input.
+
+ The `inputs` tensor is assumed to be 3- or 4-dimensional.
+ """
+ if filter_width <= 0 or filter_width % 2 != 1:
+ raise ValueError("`filter_width` should be an odd number")
+
+ pad_width = filter_width // 2
+ if inputs.shape[-1] <= pad_width:
+ return inputs
+
+ # Pad the left and right edges.
+ inputs = nn.functional.pad(inputs, (pad_width, pad_width, 0, 0), mode="reflect")
+
+ # sort() is faster than torch.median (https://github.com/pytorch/pytorch/issues/51450)
+ result = inputs.unfold(-1, filter_width, 1).sort()[0][..., pad_width]
+ return result
+
+
+def _dynamic_time_warping(matrix: np.ndarray):
+ """
+ Measures similarity between two temporal sequences: the input audio and the output tokens. Used to generate
+ token-level timestamps.
+ """
+ output_length, input_length = matrix.shape
+ cost = np.ones((output_length + 1, input_length + 1), dtype=np.float32) * np.inf
+ trace = -np.ones((output_length + 1, input_length + 1), dtype=np.float32)
+
+ cost[0, 0] = 0
+ for j in range(1, input_length + 1):
+ for i in range(1, output_length + 1):
+ c0 = cost[i - 1, j - 1]
+ c1 = cost[i - 1, j]
+ c2 = cost[i, j - 1]
+
+ if c0 < c1 and c0 < c2:
+ c, t = c0, 0
+ elif c1 < c0 and c1 < c2:
+ c, t = c1, 1
+ else:
+ c, t = c2, 2
+
+ cost[i, j] = matrix[i - 1, j - 1] + c
+ trace[i, j] = t
+
+ # backtrace
+ i = trace.shape[0] - 1
+ j = trace.shape[1] - 1
+ trace[0, :] = 2
+ trace[:, 0] = 1
+
+ text_indices = []
+ time_indices = []
+ while i > 0 or j > 0:
+ text_indices.append(i - 1)
+ time_indices.append(j - 1)
+ if trace[i, j] == 0:
+ i -= 1
+ j -= 1
+ elif trace[i, j] == 1:
+ i -= 1
+ elif trace[i, j] == 2:
+ j -= 1
+ else:
+ raise RuntimeError(
+ f"Internal error in dynamic time warping. Unexpected trace[{i}, {j}]. Please file a bug report."
+ )
+
+ text_indices = np.array(text_indices)[::-1]
+ time_indices = np.array(time_indices)[::-1]
+ return text_indices, time_indices
+
+
+def _get_attr_from_logit_processors(logits_processor, logit_processor_class, attribute_name):
+ if logits_processor is not None:
+ logit_processor = next((cls for cls in logits_processor if isinstance(cls, logit_processor_class)), None)
+ if logit_processor:
+ return getattr(logit_processor, attribute_name, None)
+ return None
+
+
+def _pad_to_max_length(
+ current_segments,
+ pad_token_id,
+ device,
+ padding_side="right",
+ padding="longest",
+ bos_token_tensor=None,
+ cut_off_length=None,
+ return_token_timestamps=False,
+ force_unique_generate_call=False,
+ skip_ending_double_timestamps=False,
+ timestamp_begin=None,
+):
+ """
+ skip_ending_double_timestamps: when the segement ended with two timestamp tokens, whether to ignore the last timestamp token
+ see https://github.com/huggingface/transformers/pull/35750
+
+ _pad_to_max_length is used in different contexts:
+ 1. At the end of generation: we need to keep both ending timestamp tokens in the segment (see https://github.com/huggingface/transformers/pull/34537).
+ 2. In the middle of generation, e.g. when condition_on_prev_tokens=True and we want to use the last generated tokens as decoder_input_ids:
+ we must skip one of the double ending timestamp tokens (see https://github.com/huggingface/transformers/pull/35750).
+ """
+ max_total_length = 0
+ sequences = []
+ token_timestamps_list = []
+
+ if padding_side not in ["right", "left"]:
+ raise ValueError(f"`padding_side` must be either 'right' or 'left', not {padding_side}")
+
+ if padding not in ["longest", "max_length"]:
+ raise ValueError(f"`padding` must be either 'longest' or 'max_length', not {padding}")
+ elif padding == "max_length" and cut_off_length is None:
+ raise ValueError("`cut_off_length` must be specified when `padding='max_length'`")
+
+ if force_unique_generate_call:
+ sequences_list = []
+ timestamps_list = []
+ for segments in current_segments:
+ result = segments[0]["result"]
+ sequences_list.append(result if isinstance(result, torch.Tensor) else result["sequences"])
+ if return_token_timestamps:
+ timestamps_list.append(result["token_timestamps"])
+
+ sequences = torch.stack(sequences_list, dim=0)
+ if return_token_timestamps:
+ token_timestamps = torch.stack(timestamps_list, dim=0)
+ return sequences, token_timestamps
+ return sequences
+
+ for current_segment_list in current_segments:
+ if current_segment_list is not None and len([d["tokens"] for d in current_segment_list]) > 0:
+ sequences_list = []
+ for d in current_segment_list:
+ if skip_ending_double_timestamps and len(d["tokens"]) > 2 and d["tokens"][-2] >= timestamp_begin:
+ # the segment finishes with two timestamp tokens
+ # we need to ignore the last timestamp token
+ # see https://github.com/huggingface/transformers/pull/34537
+ sequences_list.append(d["tokens"][:-1])
+ else:
+ sequences_list.append(d["tokens"])
+ sequence = torch.cat(sequences_list, dim=-1)
+
+ if return_token_timestamps:
+ token_timestamps = torch.cat(
+ [d["result"]["token_timestamps"][d["idxs"][0] : d["idxs"][1]] for d in current_segment_list],
+ dim=-1,
+ )
+
+ if cut_off_length is not None:
+ sequence = sequence[-cut_off_length:]
+ if return_token_timestamps:
+ token_timestamps = token_timestamps[-cut_off_length:]
+
+ if bos_token_tensor is not None:
+ sequence = torch.cat([bos_token_tensor, sequence])
+ if return_token_timestamps:
+ token_timestamps = torch.cat(
+ [torch.ones_like(bos_token_tensor, device=device) * 0.0, token_timestamps]
+ )
+ sequences.append(sequence)
+ if return_token_timestamps:
+ token_timestamps_list.append(token_timestamps)
+ max_total_length = max(max_total_length, len(sequences[-1]))
+ elif bos_token_tensor is not None:
+ sequences.append(bos_token_tensor)
+ if return_token_timestamps:
+ token_timestamps_list.append(torch.ones_like(bos_token_tensor, device=device) * 0.0)
+ else:
+ sequences.append(torch.tensor([], device=device))
+ if return_token_timestamps:
+ token_timestamps_list.append(torch.tensor([], device=device))
+
+ max_total_length = cut_off_length + 1 if padding == "max_length" else max_total_length
+ for i in range(len(current_segments)):
+ pad_length = max_total_length - len(sequences[i])
+ pad = (0, pad_length) if padding_side == "right" else (pad_length, 0)
+
+ sequences[i] = F.pad(sequences[i], pad=pad, value=pad_token_id)
+ if return_token_timestamps:
+ token_timestamps_list[i] = F.pad(
+ token_timestamps_list[i],
+ pad=pad,
+ value=token_timestamps_list[i][-1] if len(token_timestamps_list[i]) > 0 else 0.0,
+ )
+
+ sequences = torch.stack(sequences, dim=0)
+
+ if return_token_timestamps:
+ token_timestamps = torch.stack(token_timestamps_list, dim=0)
+ return sequences, token_timestamps
+ else:
+ return sequences
+
+
+class WhisperGenerationMixin(GenerationMixin):
+ def _extract_token_timestamps(
+ self, generate_outputs, alignment_heads, time_precision=0.02, num_frames=None, num_input_ids=None
+ ):
+ """
+ Calculates token-level timestamps using the encoder-decoder cross-attentions and dynamic time-warping (DTW) to
+ map each output token to a position in the input audio. If `num_frames` is specified, the encoder-decoder
+ cross-attentions will be cropped before applying DTW.
+
+ Returns:
+ tensor containing the timestamps in seconds for each predicted token
+ """
+ # Create a list with `decoder_layers` elements, each a tensor of shape
+ # (batch size * num beams, attention_heads, output length, input length).
+ cross_attentions = []
+ for i in range(self.config.decoder_layers):
+ cross_attentions.append(torch.cat([x[i] for x in generate_outputs.cross_attentions], dim=2))
+
+ # Select specific cross-attention layers and heads. This is a tensor
+ # of shape (batch size * num beams, num selected heads, output length, input length).
+ weights = torch.stack([cross_attentions[l][:, h] for l, h in alignment_heads])
+ weights = weights.permute([1, 0, 2, 3])
+
+ weight_length = None
+
+ if "beam_indices" in generate_outputs:
+ # If beam search was used, the sequence length of the outputs may not be the real sequence length:
+ # beam search may end up returning a sequence that finished a few steps earlier while decoding.
+ # In that case, the `cross_attentions` weights are too long and we have to make sure that they have
+ # the right `output_length`
+
+ # get the real sequence length of the longest sequence, crop the beam_indices to the real length
+ weight_length = (generate_outputs.beam_indices != -1).sum(-1).max()
+ beam_indices = generate_outputs.beam_indices[:, :weight_length]
+
+ # The first forward pass (prefill) may have processed more than one token and, therefore, contain
+ # cross-attention weights for several tokens.
+ # Let's unroll the first `beam_indices` accordingly, so we can use it to gather the weights.
+ if num_input_ids is not None and num_input_ids > 1:
+ # `-1`: `beam_indices` can be used as-is to gather the weights when `num_input_ids` is 1
+ weight_length += num_input_ids - 1
+ beam_indices_first_step_unrolled = (
+ torch.ones(beam_indices.shape[0], num_input_ids - 1, device=beam_indices.device, dtype=torch.long)
+ * (beam_indices[:, 0:1])
+ )
+ unrolled_beam_indices = torch.cat([beam_indices_first_step_unrolled, beam_indices], dim=-1)
+ else:
+ unrolled_beam_indices = beam_indices
+
+ # If beam index is still -1, it means that the associated token id is EOS
+ # We need to replace the index with 0 since index_select gives an error if any of the indexes is -1.
+ unrolled_beam_indices = unrolled_beam_indices.masked_fill(unrolled_beam_indices == -1, 0)
+
+ # Select the cross attention from the right beam for each output sequence, up to the real sequence
+ # length (`weight_length`)
+ weights = torch.stack(
+ [
+ torch.index_select(weights[:, :, i, :], dim=0, index=unrolled_beam_indices[:, i])
+ for i in range(unrolled_beam_indices.shape[1])
+ ],
+ dim=2,
+ )
+
+ # make sure timestamps are as long as weights
+ input_length = weight_length or cross_attentions[0].shape[2]
+ batch_size = generate_outputs.sequences.shape[0]
+ timestamps = torch.zeros(
+ (batch_size, input_length + 1), dtype=torch.float32, device=generate_outputs.sequences.device
+ )
+
+ if num_frames is not None:
+ # two cases:
+ # 1. num_frames is the same for each sample -> compute the DTW matrix for each sample in parallel
+ # 2. num_frames is different, compute the DTW matrix for each sample sequentially
+
+ # we're using np.unique because num_frames can be int/list/tuple
+ if isinstance(num_frames, int):
+ weights = weights[..., : num_frames // 2]
+
+ elif isinstance(num_frames, (list, tuple, np.ndarray)) and len(np.unique(num_frames)) == 1:
+ weights = weights[..., : num_frames[0] // 2]
+
+ elif isinstance(num_frames, (torch.Tensor)) and len(torch.unique(num_frames)) == 1:
+ weights = weights[..., : num_frames[0] // 2]
+
+ else:
+ # num_frames is of shape (batch_size,) whereas batch_size is truly batch_size*num_return_sequences
+ repeat_time = batch_size if isinstance(num_frames, int) else batch_size // len(num_frames)
+ num_frames = num_frames.cpu() if isinstance(num_frames, (torch.Tensor)) else num_frames
+ num_frames = np.repeat(num_frames, repeat_time)
+
+ # let's ignore decoder_input_ids that can negatively impact the DTW while we know they have timestamps 0.0s
+ # (they are not taken into account for the DTW in OAI implementation)
+ if num_input_ids is not None:
+ weights = weights[:, :, num_input_ids:, :]
+
+ # Since we ignore `decoder_input_ids` in the DTW and in the case where we generated only one token (for which we don't have cross attentions, see below comments),
+ # the DTW sequence length is 0 and we should return only 0.0s for the token timestamps
+ if weights.shape[2] == 0:
+ return timestamps
+
+ if num_frames is None or isinstance(num_frames, int):
+ # Normalize and smoothen the weights.
+ std = torch.std(weights, dim=-2, keepdim=True, unbiased=False)
+ mean = torch.mean(weights, dim=-2, keepdim=True)
+ weights = (weights - mean) / std
+ weights = _median_filter(weights, self.config.median_filter_width)
+
+ # Average the different cross-attention heads.
+ weights = weights.mean(dim=1)
+
+ # Perform dynamic time warping on each element of the batch.
+ for batch_idx in range(batch_size):
+ if num_frames is not None and isinstance(num_frames, (tuple, list, np.ndarray, torch.Tensor)):
+ matrix = weights[batch_idx, ..., : num_frames[batch_idx] // 2]
+
+ # Normalize and smoothen the weights.
+ std = torch.std(matrix, dim=-2, keepdim=True, unbiased=False)
+ mean = torch.mean(matrix, dim=-2, keepdim=True)
+ matrix = (matrix - mean) / std
+ matrix = _median_filter(matrix, self.config.median_filter_width)
+
+ # Average the different cross-attention heads.
+ matrix = matrix.mean(dim=0)
+ else:
+ matrix = weights[batch_idx]
+
+ text_indices, time_indices = _dynamic_time_warping(-matrix.cpu().double().numpy())
+ jumps = np.pad(np.diff(text_indices), (1, 0), constant_values=1).astype(bool)
+ jump_times = time_indices[jumps] * time_precision
+
+ # each predicted token has a corresponding timestamp, expect the eos token (or last predicted token) for which we don't retrieve cross attentions
+ # (indeed contrary to OAI that re-run a full foward to retreive cross attentions for each token and therefore also the last one predicted, we retreive
+ # cross attentions directly from the auto-regressive generation, so we don't have cross attentiosn for the token at the end of the sequence. Nevertheless,
+ # that is not important since we expect this last token to be the eos token)
+ # 1. for decoder_input_ids, we set the timestamps to 0.0
+ # 2. for the eos token (or last predicted token), we simply duplicate the timestamp of the last non-eos token
+ timestamps[batch_idx] = torch.cat(
+ [torch.zeros(num_input_ids), torch.tensor(jump_times), torch.tensor([jump_times[-1]])]
+ )
+
+ return timestamps
+
+ def generate(
+ self,
+ input_features: Optional[torch.Tensor] = None,
+ generation_config: Optional[GenerationConfig] = None,
+ logits_processor: Optional[LogitsProcessorList] = None,
+ stopping_criteria: Optional[StoppingCriteriaList] = None,
+ prefix_allowed_tokens_fn: Optional[Callable[[int, torch.Tensor], list[int]]] = None,
+ synced_gpus: bool = False,
+ return_timestamps: Optional[bool] = None,
+ task: Optional[str] = None,
+ language: Optional[Union[str, list[str]]] = None,
+ is_multilingual: Optional[bool] = None,
+ prompt_ids: Optional[torch.Tensor] = None,
+ prompt_condition_type: Optional[str] = None, # first-segment, all-segments
+ condition_on_prev_tokens: Optional[bool] = None,
+ temperature: Optional[Union[float, tuple[float, ...]]] = None,
+ compression_ratio_threshold: Optional[float] = None,
+ logprob_threshold: Optional[float] = None,
+ no_speech_threshold: Optional[float] = None,
+ num_segment_frames: Optional[int] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ time_precision: float = 0.02,
+ time_precision_features: float = 0.01,
+ return_token_timestamps: Optional[bool] = None,
+ return_segments: bool = False,
+ return_dict_in_generate: Optional[bool] = None,
+ force_unique_generate_call: Optional[bool] = None,
+ monitor_progress: Optional[Callable[[torch.Tensor], None]] = None,
+ **kwargs,
+ ):
+ """
+ Transcribes or translates log-mel input features to a sequence of auto-regressively generated token ids.
+
+
+
+ Most generation-controlling parameters are set in `generation_config` which, if not passed, will be set to the
+ model's default generation configuration. You can override any `generation_config` by passing the corresponding
+ parameters to generate(), e.g. `.generate(inputs, num_beams=4, do_sample=True)`.
+
+ For an overview of generation strategies and code examples, check out the [following
+ guide](./generation_strategies).
+
+
+
+ Parameters:
+ input_features (`torch.Tensor` of shape `(batch_size, feature_size, sequence_length)`, *optional*):
+ Float values of log-mel features extracted from the raw speech waveform. The raw speech waveform can be obtained by
+ loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`,
+ *e.g.* via the torchcodec library (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the mel
+ features, padding and conversion into a tensor of type `torch.FloatTensor`.
+ See [`~WhisperFeatureExtractor.__call__`] for details.
+ generation_config ([`~generation.GenerationConfig`], *optional*):
+ The generation configuration to be used as base parametrization for the generation call. `**kwargs`
+ passed to generate matching the attributes of `generation_config` will override them. If
+ `generation_config` is not provided, the default will be used, which had the following loading
+ priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model
+ configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s
+ default values, whose documentation should be checked to parameterize generation.
+ logits_processor (`LogitsProcessorList`, *optional*):
+ Custom logits processors that complement the default logits processors built from arguments and
+ generation config. If a logit processor is passed that is already created with the arguments or a
+ generation config an error is thrown. This feature is intended for advanced users.
+ stopping_criteria (`StoppingCriteriaList`, *optional*):
+ Custom stopping criteria that complement the default stopping criteria built from arguments and a
+ generation config. If a stopping criteria is passed that is already created with the arguments or a
+ generation config an error is thrown. This feature is intended for advanced users.
+ prefix_allowed_tokens_fn (`Callable[[int, torch.Tensor], list[int]]`, *optional*):
+ If provided, this function constraints the beam search to allowed tokens only at each step. If not
+ provided no constraint is applied. This function takes 2 arguments: the batch ID `batch_id` and
+ `input_ids`. It has to return a list with the allowed tokens for the next generation step conditioned
+ on the batch ID `batch_id` and the previously generated tokens `inputs_ids`. This argument is useful
+ for constrained generation conditioned on the prefix, as described in [Autoregressive Entity
+ Retrieval](https://huggingface.co/papers/2010.00904).
+ synced_gpus (`bool`, *optional*, defaults to `False`):
+ Whether to continue running the while loop until max_length (needed to avoid deadlocking with
+ `FullyShardedDataParallel` and DeepSpeed ZeRO Stage 3).
+ return_timestamps (`bool`, *optional*):
+ Whether to return the timestamps with the text. This enables the `WhisperTimestampsLogitsProcessor`.
+ For audios longer than 30 seconds, it is necessary to set `return_timestamps=True`.
+ task (`str`, *optional*):
+ Task to use for generation, either "translate" or "transcribe".
+ language (`str` or list of `str`, *optional*):
+ Language token to use for generation, can be either in the form of `<|en|>`, `en` or `english`. For
+ batched generation, a list of language tokens can be passed. You can find all the possible language
+ tokens in the `model.generation_config.lang_to_id` dictionary.
+ is_multilingual (`bool`, *optional*):
+ Whether or not the model is multilingual.
+ prompt_ids (`torch.Tensor`, *optional*):
+ Rank-1 tensor of token IDs created by passing text to [`~WhisperProcessor.get_prompt_ids`] that is
+ provided as a prompt to each chunk. This can be used to provide or "prompt-engineer" a context for
+ transcription, e.g. custom vocabularies or proper nouns to make it more likely to predict those words
+ correctly. It cannot be used in conjunction with `decoder_start_token_id` as it overwrites this value.
+ prompt_condition_type (`str`, *optional*):
+ Only relevant for long-form transcription. Condition type of `prompt_ids`. 'first-segment' means only the first segment is conditioned on `prompt_ids`. 'all-segments' means each segment is conditioned on `prompt_ids`. Make sure to enable `condition_on_prev_tokens` for 'all-segments'.
+ Defaults to 'first-segment'. For short-term transcription only 'first-segment' is possible.
+ condition_on_prev_tokens (`bool`, *optional*):
+ Only relevant for long-form transcription. Whether to condition each segment on the previous segment.
+ As shown in the [the Whisper paper](https://cdn.openai.com/papers/whisper.pdf), this can help to improve
+ performance.
+ temperature (`float` or list of `float`, *optional*):
+ The temperature to be used for generation. Passing a single `float` value and `do_sample=True` activates
+ generation using sampling. For long-form transcription, temperature fallback can be activated by passing
+ a list of float values such as (0.0, 0.2, 0.4, 0.6, 0.8, 1.0). As shown in the [the Whisper paper](https://cdn.openai.com/papers/whisper.pdf), this can help to improve
+ performance.
+ compression_ratio_threshold (`float`, *optional*):
+ Only relevant for long-form transcription. If defined, the zlib compression rate of each segment will be computed. If the compression rate of
+ a segment is higher than `compression_ratio_threshold`, temperature fallback is activated: the generated segment is discarded and the generation is
+ repeated using a higher temperature. The intuition behind this feature is that segments with very high compression rates
+ suffer from a lot of repetition. The unwanted repetition can be reduced by injecting more randomness by increasing the temperature. If `compression_ratio_threshold` is defined
+ make sure that `temperature` is a list of values. A common value for `compression_ratio_threshold` is 1.35.
+ As shown in the [the Whisper paper](https://cdn.openai.com/papers/whisper.pdf), this can help to improve
+ performance.
+ logprob_threshold (`float`, *optional*):
+ Only relevant for long-form transcription. If defined, the average log-probability of each segment will be computed. If the log-probability of
+ a given segment is lower than `logprob_threshold`, temperature fallback is activated: the generated segment is discarded and the generation is
+ repeated using a higher temperature. The intuition behind this feature is that segments of low log-probability
+ can be improved by injecting more randomness by increasing the temperature. If `logprob_threshold` is defined
+ make sure that `temperature` is a list of values. A common value for `logprob_threshold` is -1.0.
+ As shown in the [the Whisper paper](https://cdn.openai.com/papers/whisper.pdf), this can help to improve
+ performance.
+ no_speech_threshold (`float`, *optional*):
+ Only relevant for long-form transcription. If defined, the "no-speech" token combined with the `logprob_threshold`
+ is used to determine whether a segment contains only silence. In this case, the transcription for this segment
+ is skipped.
+ As shown in the [the Whisper paper](https://cdn.openai.com/papers/whisper.pdf), this can help to improve
+ performance.
+ num_segment_frames (`int`, *optional*):
+ The number of frames a single segment is made of. If not defined, `num_segment_frames` defaults to the model's stride
+ times the maximum input length.
+ attention_mask (`torch.Tensor`, *optional*):
+ `attention_mask` needs to be passed when doing long-form transcription using a batch size > 1.
+ time_precision (`int`, *optional*, defaults to 0.02):
+ The duration of output token in seconds. *E.g.* 0.02 means that a generated token on average accounts
+ for 20 ms.
+ time_precision_features (`int`, *optional*, defaults to 0.01):
+ The duration represented by a feature frame in seconds.
+ return_token_timestamps (`bool`, *optional*):
+ Whether to return token-level timestamps with the text. This can be used with or without the
+ `return_timestamps` option. To get word-level timestamps, use the tokenizer to group the tokens into
+ words.
+ return_segments (`bool`, *optional*, defaults to `False`):
+ Whether to additionally return a list of all segments. Note that this option can only be enabled
+ when doing long-form transcription.
+ return_dict_in_generate (`bool`, *optional*, defaults to `False`):
+ Whether or not to return a [`~utils.ModelOutput`] instead of just returning the generated tokens.
+ Note that when doing long-form transcription, `return_dict_in_generate` can only be enabled when
+ `return_segments` is set True. In this case the generation outputs of each segment is added to each
+ segment.
+ force_unique_generate_call (`bool`, *optional*):
+ Whether to force a unique call to the underlying GenerationMixin's [`~generation.GenerationMixin.generate`] method. This is useful for assisted decoding and testing purposes to ensure
+ that only one call to [`~generation.GenerationMixin.generate`] is made and therefore decoder input token ids and eos token ids are returned.
+ monitor_progress (`Callable[[torch.Tensor], None]`, *optional*):
+ If provided, this function can be called to report the progress of the audio transcription. The function
+ takes a tensor argument `p` of shape `(n, 2)`, where `n` is the batch size. `p[i, 0]` contains the
+ index of the audio frame that is currently being transcribed for batch item `i`. `p[i, 1]` contains
+ the total number of frames for batch item `i`. No return value is expected.
+ kwargs (`dict[str, Any]`, *optional*):
+ Ad hoc parametrization of `generate_config` and/or additional model-specific kwargs that will be
+ forwarded to the `forward` function of the model. If the model is an encoder-decoder model, encoder
+ specific kwargs should not be prefixed and decoder specific kwargs should be prefixed with *decoder_*.
+ Return:
+ [`~utils.ModelOutput`] or `dict[str, Any]` or `torch.LongTensor`:
+
+ One of the following:
+ - [`~utils.ModelOutput`] when `return_dict_in_generate=True` and (`return_timestamps=False` or `force_unique_generate_call=True`), including the decoder input ids and end of sequence id.
+ - `dict[str, Any]` when (`return_dict_in_generate=True` and `return_timestamps=True`) or `return_segments=True` or `return_token_timestamps=True`.
+ - `torch.LongTensor` in all other cases, excluding the decoder input ids and end of sequence id.
+
+ The possible [`~utils.ModelOutput`] types are:
+ - [`~generation.GenerateEncoderDecoderOutput`]
+ - [`~generation.GenerateBeamEncoderDecoderOutput`]
+
+ `segments` is a list of lists (one list per batch element) of `segment`.
+ A `segment` is a dictionary with keys `start`, `end`, `tokens`, `idxs`, and `result`.
+ - `start`: the start timestamp of the segment.
+ - `end`: the end timestamp of the segment.
+ - `tokens`: the tokens of the segment, excluding the decoder input ids and end of sequence id.
+ - `idxs`: the start (included) and end (excluded) indices of the `tokens` of the segment in the underlying call to GenerationMixin's [`~generation.GenerationMixin.generate`] (present in `result`).
+ - `result`: the result of the underlying call to GenerationMixin's [`~generation.GenerationMixin.generate`].
+
+ When `return_timestamps=True`, `return_dict_in_generate=True` applies to each call of the underlying GenerationMixin's [`~generation.GenerationMixin.generate`], with outputs stored in `result` of each `segment`.
+
+ Example:
+
+ - *Longform transcription*: To transcribe or translate audios longer than 30 seconds, process the audio files without truncation and pass all mel features at once to generate. It is necessary to set `return_timestamps=True`.
+ Indeed, long-form transcription uses a sequential algorithm based on timestamps predictions, with heuristics like compression ratio threshold, log probability threshold and temperature fallback. This algorithm is described in the [the Whisper original paper](https://cdn.openai.com/papers/whisper.pdf), section *3.8. Long-form Transcription*.
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoProcessor, WhisperForConditionalGeneration
+ >>> from datasets import load_dataset, Audio
+
+ >>> processor = AutoProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = WhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en")
+ >>> model.cuda() # doctest: +IGNORE_RESULT
+
+ >>> # load audios > 30 seconds
+ >>> ds = load_dataset("distil-whisper/meanwhile", "default")["test"]
+ >>> # resample to 16kHz
+ >>> ds = ds.cast_column("audio", Audio(sampling_rate=16000))
+ >>> # take first 8 audios and retrieve array
+ >>> audio = ds[:8]["audio"]
+ >>> audio = [x["array"] for x in audio]
+
+ >>> # make sure to NOT truncate the input audio, to return the `attention_mask` and to pad to the longest audio
+ >>> inputs = processor(audio, return_tensors="pt", truncation=False, padding="longest", return_attention_mask=True, sampling_rate=16_000)
+ >>> inputs = inputs.to("cuda", torch.float32)
+
+ >>> # transcribe audio to ids
+ >>> generated_ids = model.generate(**inputs, return_timestamps=True)
+
+ >>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)
+ >>> transcription[0]
+ " Folks, if you watch the show, you know, I spent a lot of time right over there. Patiently and astutely scrutinizing the boxwood and mahogany chest set of the day's biggest stories developing the central headline pawns, definitely maneuvering an oso topical night to F6, fainting a classic Sicilian, nade door variation on the news, all the while seeing eight moves deep and patiently marshalling the latest press releases into a fisher's shows in Lip Nitsky attack that culminates in the elegant lethal slow-played, all-passant checkmate that is my nightly monologue. But sometimes, sometimes, folks, I. CHEERING AND APPLAUSE Sometimes I startle away, cubside down in the monkey bars of a condemned playground on a super fun site. Get all hept up on goofballs. Rummage that were discarded tag bag of defective toys. Yank out a fist bowl of disembodied doll limbs, toss them on a stained kid's place mat from a defunct dennies. set up a table inside a rusty cargo container down by the Wharf and challenged toothless drifters to the godless bughouse blitz of tournament that is my segment. Meanwhile."
+ ```
+
+ The `monitor_progress` callback can be used to monitor the progress of the transcription:
+ ```python
+ >>> from tqdm import tqdm
+
+ >>> # prepare inputs like above
+
+ >>> # define a callback to monitor the progress of the transcription.
+ >>> with tqdm(desc="Progress") as pbar:
+ >>> def monitor_progress(p_batch):
+ >>> i = torch.argmax(p_batch[:, 1])
+ >>> p = p_batch[i].detach().cpu()
+ >>> pbar.total = int(p[1])
+ >>> pbar.n = int(p[0])
+ >>> pbar.update()
+
+ >>> # transcribe audio to ids
+ >>> generated_ids = model.generate(**inputs, return_timestamps=True, monitor_progress=monitor_progress)
+
+ >>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)
+ >>> transcription[0]
+ Progress: 95%|█████████████████████████████████████████████████████████████████████████████████████████████████▎ | 8497/8901 [00:04<00:00, 2052.79it/s]
+ " Folks, if you watch the show, you know, I spent a lot of time right over there. Patiently and astutely scrutinizing the boxwood and mahogany chest set of the day's biggest stories developing the central headline pawns, definitely maneuvering an oso topical night to F6, fainting a classic Sicilian, nade door variation on the news, all the while seeing eight moves deep and patiently marshalling the latest press releases into a fisher's shows in Lip Nitsky attack that culminates in the elegant lethal slow-played, all-passant checkmate that is my nightly monologue. But sometimes, sometimes, folks, I. CHEERING AND APPLAUSE Sometimes I startle away, cubside down in the monkey bars of a condemned playground on a super fun site. Get all hept up on goofballs. Rummage that were discarded tag bag of defective toys. Yank out a fist bowl of disembodied doll limbs, toss them on a stained kid's place mat from a defunct dennies. set up a table inside a rusty cargo container down by the Wharf and challenged toothless drifters to the godless bughouse blitz of tournament that is my segment. Meanwhile."
+ ```
+
+ - *Shortform transcription*: If passed mel input features are <= 30 seconds, there are two possibilities:
+ - `return_timestamps=False`: the whole audio will be transcribed with a single call to GenerationMixin's [`~generation.GenerationMixin.generate`].
+ - `return_timestamps=True`: the audio will be transcribed using the same logic as long-form transcription.
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoProcessor, WhisperForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> processor = AutoProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = WhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+ >>> inputs = processor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+
+ >>> generated_ids = model.generate(inputs=input_features)
+
+ >>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+ >>> transcription
+ ' Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel.'
+ ```
+
+ """
+ # 0. deprecate old inputs
+ if "inputs" in kwargs:
+ input_features = kwargs.pop("inputs")
+ warnings.warn(
+ "The input name `inputs` is deprecated. Please make sure to use `input_features` instead.",
+ FutureWarning,
+ )
+
+ # 1. prepare generation config
+ generation_config, kwargs = self._prepare_generation_config(generation_config, **kwargs)
+
+ # 2. set global generate variables
+ input_stride = self.model.encoder.conv1.stride[0] * self.model.encoder.conv2.stride[0]
+ num_segment_frames = input_stride * self.config.max_source_positions
+ batch_size, total_input_frames = self._retrieve_total_input_frames(
+ input_features=input_features, input_stride=input_stride, kwargs=kwargs
+ )
+ is_shortform = total_input_frames <= num_segment_frames
+
+ # 3. Make sure generation config is correctly set
+ # Make sure the generation config is correctly set depending on whether timestamps are to be returned or not
+ return_dict_in_generate = self._set_return_outputs(
+ return_dict_in_generate=return_dict_in_generate,
+ return_token_timestamps=return_token_timestamps,
+ logprob_threshold=logprob_threshold,
+ generation_config=generation_config,
+ )
+ timestamp_begin = self._set_return_timestamps(
+ return_timestamps=return_timestamps, is_shortform=is_shortform, generation_config=generation_config
+ )
+ self._set_language_and_task(
+ language=language, task=task, is_multilingual=is_multilingual, generation_config=generation_config
+ )
+ self._set_num_frames(
+ return_token_timestamps=return_token_timestamps,
+ generation_config=generation_config,
+ attention_mask=attention_mask,
+ kwargs=kwargs,
+ )
+ self._set_thresholds_and_condition(
+ generation_config=generation_config,
+ logprob_threshold=logprob_threshold,
+ compression_ratio_threshold=compression_ratio_threshold,
+ no_speech_threshold=no_speech_threshold,
+ condition_on_prev_tokens=condition_on_prev_tokens,
+ )
+ self._set_prompt_condition_type(
+ generation_config=generation_config,
+ prompt_condition_type=prompt_condition_type,
+ )
+
+ # pass self.config for backward compatibility
+ init_tokens = self._retrieve_init_tokens(
+ input_features,
+ batch_size=batch_size,
+ generation_config=generation_config,
+ config=self.config,
+ num_segment_frames=num_segment_frames,
+ kwargs=kwargs,
+ )
+ # passing `decoder_input_ids` is deprecated - the only exception is for assisted generation
+ # where the input ids are handled explicitly by the generate method
+ self._check_decoder_input_ids(kwargs=kwargs)
+ # `output_attentions` is deprecated - we force eager attention if this feature is
+ # indirectly requested, e.g. through return_token_timestamps
+ if return_token_timestamps:
+ self.model.config._attn_implementation = "eager"
+
+ # 3. Retrieve logits processors
+ device = kwargs["encoder_outputs"][0].device if "encoder_outputs" in kwargs else input_features.device
+ begin_index = init_tokens.shape[1]
+ num_beams = kwargs.get(
+ "num_beams",
+ generation_config.num_beams
+ if hasattr(generation_config, "num_beams") and generation_config.num_beams is not None
+ else 1,
+ )
+ if "assistant_model" in kwargs:
+ # speculative decoding: the model should be able to return eos token
+ generation_config.begin_suppress_tokens = None
+
+ logits_processor = self._retrieve_logit_processors(
+ generation_config=generation_config,
+ logits_processor=logits_processor,
+ begin_index=begin_index, # begin index is index of first generated decoder token
+ num_beams=num_beams,
+ device=device,
+ )
+
+ # 4 Set and retrieve global generation variables
+ self._set_condition_on_prev_tokens(
+ condition_on_prev_tokens=condition_on_prev_tokens, generation_config=generation_config
+ )
+
+ temperatures = [temperature] if not isinstance(temperature, (list, tuple)) else temperature
+ temperature = temperatures[0]
+
+ max_frames, seek = self._retrieve_max_frames_and_seek(
+ batch_size=batch_size,
+ attention_mask=attention_mask,
+ total_input_frames=total_input_frames,
+ is_shortform=is_shortform,
+ )
+
+ # 5 Prepare running variables, list for generation
+ num_return_sequences = generation_config.num_return_sequences
+ (
+ batch_idx_map,
+ cur_bsz,
+ input_features,
+ seek,
+ max_frames,
+ init_tokens,
+ do_condition_on_prev_tokens,
+ ) = self._expand_variables_for_generation(
+ input_features=input_features,
+ seek=seek,
+ max_frames=max_frames,
+ init_tokens=init_tokens,
+ batch_size=batch_size,
+ condition_on_prev_tokens=condition_on_prev_tokens,
+ generation_config=generation_config,
+ )
+
+ current_segments = self._prepare_segments(
+ prompt_ids=prompt_ids,
+ batch_size=cur_bsz,
+ generation_config=generation_config,
+ )
+ # 5bis speculative decoding: ensure the assistant model does only one call to generate and therefore returns decoder input token ids and eos token id
+ # we set a flag in the generation config to force the model to make only one call to generate and return the decoder input token ids and eos token id
+ if "assistant_model" in kwargs:
+ assistant_model = kwargs["assistant_model"]
+ assistant_model.generation_config.force_unique_generate_call = True
+
+ if force_unique_generate_call is None:
+ if hasattr(generation_config, "force_unique_generate_call"):
+ force_unique_generate_call = generation_config.force_unique_generate_call
+ elif hasattr(self.generation_config, "force_unique_generate_call"):
+ force_unique_generate_call = self.generation_config.force_unique_generate_call
+ else:
+ force_unique_generate_call = False
+
+ # 6 Transcribe audio until we reach the end of all input audios
+ while (seek < max_frames).any():
+ if monitor_progress is not None:
+ monitor_progress(torch.stack((seek, max_frames), dim=1))
+
+ # 6.1 NOTE: When in longform transcription mode and batch size > 1 we need to dynamically reduce the batch size during the loop
+ # in case one audio finished earlier than another one. Thus, we need to keep a table of "previous-index-2-current-index" in order
+ # to know which original audio is being decoded
+ # Set updated index map, duration of previously decoded chunks and number of max frames of current decoding chunk
+ input_features, cur_bsz, batch_idx_map = self._maybe_reduce_batch(
+ input_features=input_features,
+ seek=seek,
+ max_frames=max_frames,
+ cur_bsz=cur_bsz,
+ batch_idx_map=batch_idx_map,
+ )
+ time_offset = (
+ seek.to(torch.float32 if device.type == "mps" else torch.float64) * time_precision / input_stride
+ )
+ seek_num_frames = (max_frames - seek).clamp(max=num_segment_frames)
+
+ # 6.2 cut out next 30s segment from input features
+ segment_input = self._get_input_segment(
+ input_features=input_features,
+ seek=seek,
+ seek_num_frames=seek_num_frames,
+ num_segment_frames=num_segment_frames,
+ cur_bsz=cur_bsz,
+ batch_idx_map=batch_idx_map,
+ )
+
+ # 6.3 prepare decoder input ids
+ suppress_tokens = _get_attr_from_logit_processors(
+ logits_processor, SuppressTokensLogitsProcessor, "suppress_tokens"
+ )
+
+ decoder_input_ids, kwargs = self._prepare_decoder_input_ids(
+ cur_bsz=cur_bsz,
+ init_tokens=init_tokens,
+ current_segments=current_segments,
+ batch_idx_map=batch_idx_map,
+ do_condition_on_prev_tokens=do_condition_on_prev_tokens,
+ prompt_ids=prompt_ids,
+ generation_config=generation_config,
+ config=self.config,
+ device=init_tokens.device,
+ suppress_tokens=suppress_tokens,
+ timestamp_begin=timestamp_begin,
+ kwargs=kwargs,
+ )
+
+ # 6.4 set max new tokens or max length
+ self._set_max_new_tokens_and_length(
+ config=self.config,
+ decoder_input_ids=decoder_input_ids,
+ generation_config=generation_config,
+ )
+
+ # 6.5 Set current `begin_index` for all logit processors
+ if logits_processor is not None:
+ for proc in logits_processor:
+ if hasattr(proc, "set_begin_index"):
+ proc.set_begin_index(decoder_input_ids.shape[-1])
+
+ # 6.6 Run generate with fallback
+ (
+ seek_sequences,
+ seek_outputs,
+ should_skip,
+ do_condition_on_prev_tokens,
+ model_output_type,
+ ) = self.generate_with_fallback(
+ segment_input=segment_input,
+ decoder_input_ids=decoder_input_ids,
+ cur_bsz=cur_bsz,
+ seek=seek,
+ batch_idx_map=batch_idx_map,
+ temperatures=temperatures,
+ generation_config=generation_config,
+ logits_processor=logits_processor,
+ stopping_criteria=stopping_criteria,
+ prefix_allowed_tokens_fn=prefix_allowed_tokens_fn,
+ synced_gpus=synced_gpus,
+ return_token_timestamps=return_token_timestamps,
+ do_condition_on_prev_tokens=do_condition_on_prev_tokens,
+ is_shortform=is_shortform,
+ batch_size=batch_size,
+ attention_mask=attention_mask,
+ kwargs=kwargs,
+ )
+
+ # 6.7 In every generated sequence, split by timestamp tokens and extract segments
+ for i, seek_sequence in enumerate(seek_sequences):
+ prev_i = batch_idx_map[i]
+
+ if should_skip[i]:
+ seek[prev_i] += seek_num_frames[prev_i]
+ continue
+
+ segments, segment_offset = self._retrieve_segment(
+ seek_sequence=seek_sequence,
+ seek_outputs=seek_outputs,
+ time_offset=time_offset,
+ timestamp_begin=timestamp_begin,
+ seek_num_frames=seek_num_frames,
+ time_precision=time_precision,
+ time_precision_features=time_precision_features,
+ input_stride=input_stride,
+ prev_idx=prev_i,
+ idx=i,
+ return_token_timestamps=return_token_timestamps,
+ decoder_input_ids=decoder_input_ids,
+ )
+
+ seek[prev_i] += segment_offset
+
+ current_segments[prev_i] += segments
+
+ if force_unique_generate_call:
+ break
+
+ # 7. Once all segments are added to the list of all segments, called `current_segments`, we extract the predicted
+ # output tokens from the list of dicts. If we use batch size > 1, we make sure to pad the output
+ final_segments = (
+ [x[1:] for x in current_segments]
+ if (prompt_ids is not None and generation_config.prompt_condition_type == "first-segment")
+ else current_segments
+ )
+
+ # if return_dict_in_generate=True and we forced a unique call to generate or return_timestamps=False, meaning we are sure only one call to generate has been made,
+ # -> we can return a ModelOutput
+ # otherwise, return_dict_in_generate is applied in the 'result' of each segment in final_segments
+ if (
+ return_dict_in_generate
+ and generation_config.return_dict_in_generate
+ and (force_unique_generate_call or not return_timestamps)
+ ):
+ # only one call to generate_with_fallback, we can return a ModelOutput
+ outputs = self._stack_split_outputs(seek_outputs, model_output_type, self.device, kwargs)
+ if num_return_sequences > 1:
+ if hasattr(outputs, "encoder_attentions") and outputs.encoder_attentions is not None:
+ outputs.encoder_attentions = tuple(
+ outputs.encoder_attentions[i][::num_return_sequences]
+ for i in range(len(outputs.encoder_attentions))
+ )
+ if hasattr(outputs, "encoder_hidden_states") and outputs.encoder_hidden_states is not None:
+ outputs.encoder_hidden_states = tuple(
+ outputs.encoder_hidden_states[i][::num_return_sequences]
+ for i in range(len(outputs.encoder_hidden_states))
+ )
+ return outputs
+
+ padded_outputs = _pad_to_max_length(
+ current_segments=final_segments,
+ pad_token_id=generation_config.pad_token_id,
+ device=self.device,
+ padding_side="right",
+ return_token_timestamps=return_token_timestamps,
+ force_unique_generate_call=force_unique_generate_call,
+ )
+
+ if return_dict_in_generate and generation_config.return_dict_in_generate:
+ logger.warning_once(
+ "You have passed `return_dict_in_generate=True` and `return_timestamps=True`, this automatically sets `return_segments=True` to access the results of the underlying calls to GenerationMixin's generate in the returned `segments`."
+ )
+ return_segments = True
+ elif not return_segments and not return_token_timestamps:
+ return padded_outputs
+
+ if return_token_timestamps:
+ sequences, token_timestamps = padded_outputs
+ outputs = {
+ "sequences": sequences,
+ "token_timestamps": token_timestamps,
+ }
+ else:
+ sequences = padded_outputs
+ outputs = {
+ "sequences": sequences,
+ }
+
+ if return_segments:
+ outputs["segments"] = final_segments
+
+ return outputs
+
+ def generate_with_fallback(
+ self,
+ segment_input,
+ decoder_input_ids,
+ cur_bsz,
+ seek,
+ batch_idx_map,
+ temperatures,
+ generation_config,
+ logits_processor,
+ stopping_criteria,
+ prefix_allowed_tokens_fn,
+ synced_gpus,
+ return_token_timestamps,
+ do_condition_on_prev_tokens,
+ is_shortform,
+ batch_size,
+ attention_mask,
+ kwargs,
+ ):
+ kwargs = copy.copy(kwargs)
+
+ # 6.6 Batch generate current chunk
+ seek_sequence_list = [None for _ in range(cur_bsz)]
+ seek_outputs_list = [None for _ in range(cur_bsz)]
+ needs_fallback = [False for _ in range(cur_bsz)]
+ should_skip = [False for _ in range(cur_bsz)]
+ fallback_index_map = list(range(cur_bsz))
+ if generation_config.no_speech_threshold is not None:
+ self._setup_no_speech_detection(logits_processor, segment_input, decoder_input_ids, kwargs)
+
+ for fallback_idx, temperature in enumerate(temperatures):
+ generation_config.do_sample = temperature is not None and temperature > 0.0
+ generation_config.temperature = temperature if generation_config.do_sample else 1.0
+ if generation_config.do_sample:
+ generation_config.num_beams = 1
+
+ generate_kwargs = copy.copy(kwargs)
+ for key in ["do_sample", "temperature", "num_beams"]:
+ if key in generate_kwargs:
+ del generate_kwargs[key]
+
+ cur_bsz = decoder_input_ids.shape[0]
+ if generation_config.cache_implementation == "static" and cur_bsz < batch_size:
+ segment_input = F.pad(segment_input, (0, 0, 0, 0, 0, batch_size - cur_bsz), value=0)
+ decoder_input_ids = F.pad(
+ decoder_input_ids, (0, 0, 0, batch_size - cur_bsz), value=generation_config.pad_token_id
+ )
+ if generate_kwargs.get("decoder_attention_mask") is not None:
+ generate_kwargs["decoder_attention_mask"] = F.pad(
+ generate_kwargs["decoder_attention_mask"], (0, 0, 0, batch_size - cur_bsz), value=True
+ )
+ if generate_kwargs.get("encoder_outputs") is not None:
+ generate_kwargs["encoder_outputs"] = F.pad(
+ generate_kwargs["encoder_outputs"], (0, 0, 0, 0, 0, batch_size - cur_bsz), value=0
+ )
+
+ seek_outputs = super().generate(
+ segment_input,
+ generation_config=generation_config,
+ logits_processor=logits_processor,
+ stopping_criteria=stopping_criteria,
+ prefix_allowed_tokens_fn=prefix_allowed_tokens_fn,
+ synced_gpus=synced_gpus,
+ decoder_input_ids=decoder_input_ids,
+ attention_mask=attention_mask,
+ **generate_kwargs,
+ )
+
+ model_output_type = type(seek_outputs)
+
+ # post-process sequence tokens and outputs to be in list form
+ seek_sequences, seek_outputs = self._postprocess_outputs(
+ seek_outputs=seek_outputs,
+ decoder_input_ids=decoder_input_ids,
+ return_token_timestamps=return_token_timestamps,
+ generation_config=generation_config,
+ is_shortform=is_shortform,
+ seek=seek,
+ batch_idx_map=batch_idx_map,
+ )
+
+ if cur_bsz < batch_size:
+ seek_sequences = seek_sequences[:cur_bsz]
+ seek_outputs = seek_outputs[:cur_bsz]
+
+ # 6.7 Extract cut sequences from every sequence and check if fallback should be applied
+ # Loop over each decoded audio individually as each decoding can be of a different length
+ new_fallback_index_map = []
+ new_segment_input = []
+ new_decoder_input_ids = []
+ new_decoder_attention_mask = []
+
+ for i, seek_sequence in enumerate(seek_sequences):
+ # remove all padding tokens, except for the eos token
+ if seek_sequence[-1] == generation_config.pad_token_id:
+ num_paddings = (seek_sequence == generation_config.pad_token_id).sum()
+ if generation_config.pad_token_id == generation_config.eos_token_id:
+ # we do not remove the eos token id since it is needed for avg logprob calculation in _need_fallback
+ num_paddings -= 1
+ if num_paddings != 0:
+ seek_sequence = seek_sequence[:-num_paddings]
+
+ # check which sequences in batch need fallback & which should be skipped
+ needs_fallback[i], should_skip[i] = self._need_fallback(
+ seek_sequence,
+ seek_outputs,
+ i,
+ logits_processor,
+ generation_config,
+ self.config.vocab_size,
+ temperature,
+ )
+
+ # remove eos token
+ if seek_sequence[-1] == generation_config.eos_token_id:
+ seek_sequence = seek_sequence[:-1]
+
+ seek_sequence_list[fallback_index_map[i]] = seek_sequence
+ seek_outputs_list[fallback_index_map[i]] = seek_outputs[i]
+ is_low_temperature = temperature is None or temperature < 0.5
+ do_condition_on_prev_tokens[fallback_index_map[i]] = (
+ generation_config.condition_on_prev_tokens and is_low_temperature
+ )
+
+ if needs_fallback[i]:
+ new_fallback_index_map.append(fallback_index_map[i])
+ new_segment_input.append(segment_input[i])
+ new_decoder_input_ids.append(decoder_input_ids[i])
+ if "decoder_attention_mask" in kwargs:
+ new_decoder_attention_mask.append(kwargs["decoder_attention_mask"][i])
+
+ fallback_index_map = new_fallback_index_map
+
+ # if no sequence needs to be run with temperature fallback, we're finished
+ if len(fallback_index_map) == 0 or fallback_idx == len(temperatures) - 1:
+ seek_sequences = seek_sequence_list
+ seek_outputs = seek_outputs_list
+ break
+
+ # if we're still in the loop, make sure that decoder_input_ids and segment inputs are tensors
+ decoder_input_ids = torch.stack(new_decoder_input_ids)
+ segment_input = torch.stack(new_segment_input)
+ if "decoder_attention_mask" in kwargs:
+ kwargs["decoder_attention_mask"] = torch.stack(new_decoder_attention_mask)
+
+ return seek_sequences, seek_outputs, should_skip, do_condition_on_prev_tokens, model_output_type
+
+ @staticmethod
+ def _prepare_segments(prompt_ids, batch_size, generation_config):
+ if prompt_ids is not None and generation_config.prompt_condition_type == "first-segment":
+ prev_sot_token_id = getattr(generation_config, "prev_sot_token_id", None)
+ prompt_ids = prompt_ids[1:] if prompt_ids[0] == prev_sot_token_id else prompt_ids
+ current_segments = [[{"tokens": prompt_ids}] for _ in range(batch_size)]
+ else:
+ current_segments = [[] for _ in range(batch_size)]
+
+ return current_segments
+
+ def _postprocess_outputs(
+ self,
+ seek_outputs,
+ decoder_input_ids,
+ return_token_timestamps,
+ generation_config,
+ is_shortform,
+ seek,
+ batch_idx_map,
+ ):
+ # remove all previously passed decoder input ids
+ # should happen only if it is the first generated segment
+ start_idx = decoder_input_ids.shape[-1]
+
+ if isinstance(seek_outputs, torch.Tensor):
+ return seek_outputs[:, start_idx:], seek_outputs
+
+ if return_token_timestamps and hasattr(generation_config, "alignment_heads"):
+ num_frames = getattr(generation_config, "num_frames")
+ if num_frames is not None:
+ num_frames = num_frames - seek
+ num_frames = num_frames[batch_idx_map]
+
+ seek_outputs["token_timestamps"] = self._extract_token_timestamps(
+ seek_outputs,
+ generation_config.alignment_heads,
+ num_frames=num_frames,
+ num_input_ids=decoder_input_ids.shape[-1],
+ )
+
+ def split_by_batch_index(values, key, batch_idx, is_shortform, beam_indices=None):
+ if beam_indices is not None and key == "scores":
+ return [v[beam_idx].cpu() for (v, beam_idx) in zip(values, beam_indices[batch_idx][: len(values)])]
+ if key in ["scores", "encoder_attentions", "encoder_hidden_states", "logits"]:
+ return [v[batch_idx].cpu() for v in values]
+ if key in ["decoder_attentions", "decoder_hidden_states", "cross_attentions"]:
+ return tuple(tuple(w[batch_idx][None].cpu() for w in v) for v in values)
+ elif key == "past_key_values":
+ if not is_shortform:
+ # we don't save `past_key_values` as this is too costly for longform
+ return None
+ elif isinstance(values, EncoderDecoderCache):
+ all_past_key_values = []
+ for layer_idx in range(self.config.decoder_layers):
+ layer_past_key_values = []
+ for cache_cls in [values.self_attention_cache, values.cross_attention_cache]:
+ for v in [cache_cls.layers[layer_idx].keys, cache_cls.layers[layer_idx].values]:
+ layer_past_key_values.append(v[batch_idx][None].cpu())
+ all_past_key_values.append(tuple(layer_past_key_values))
+ return EncoderDecoderCache.from_legacy_cache(tuple(all_past_key_values))
+ else:
+ all_past_key_values = []
+ for v in range(len(values)):
+ layer_past_key_values = []
+ for w in values[v]:
+ if len(w) != 0:
+ layer_past_key_values.append(w[batch_idx][None].cpu())
+ else:
+ layer_past_key_values.append(w)
+ all_past_key_values.append(tuple(layer_past_key_values))
+ return tuple(all_past_key_values)
+
+ return values[batch_idx].cpu()
+
+ sequence_tokens = seek_outputs["sequences"][:, start_idx:]
+ seek_outputs = [
+ {
+ k: split_by_batch_index(v, k, i, is_shortform, beam_indices=seek_outputs.get("beam_indices"))
+ for k, v in seek_outputs.items()
+ }
+ for i in range(sequence_tokens.shape[0])
+ ]
+
+ return sequence_tokens, seek_outputs
+
+ def _stack_split_outputs(self, seek_outputs, model_output_type, device, kwargs):
+ # Stack back seek_outputs tensors after splitting them with the split_by_batch_index method
+ outputs = {}
+ for key in seek_outputs[0]:
+ if key in ["sequences", "beam_indices", "token_timestamps"]:
+ outputs[key] = torch.stack([v[key] for v in seek_outputs], dim=0).to(device)
+ elif key in ["scores", "encoder_attentions", "encoder_hidden_states", "logits"]:
+ outputs[key] = tuple(
+ torch.stack([v[key][i] for v in seek_outputs]).to(device) for i in range(len(seek_outputs[0][key]))
+ )
+ elif key == "sequences_scores":
+ outputs[key] = torch.stack([v[key] for v in seek_outputs], dim=0).to(device)
+ elif key in ["decoder_attentions", "decoder_hidden_states", "cross_attentions"]:
+ outputs[key] = tuple(
+ tuple(
+ torch.stack([v[key][i][j] for v in seek_outputs]).squeeze(1).to(device)
+ for j in range(len(seek_outputs[0][key][0]))
+ )
+ for i in range(len(seek_outputs[0][key]))
+ )
+ elif key == "past_key_values":
+ if seek_outputs[0][key] is not None:
+ outputs[key] = tuple(
+ tuple(
+ torch.stack([v[key][i][j] for v in seek_outputs]).squeeze(1).to(device)
+ for j in range(len(seek_outputs[0][key][0]))
+ )
+ for i in range(len(seek_outputs[0][key]))
+ )
+ if isinstance(seek_outputs[0][key], EncoderDecoderCache):
+ outputs[key] = EncoderDecoderCache.from_legacy_cache(outputs[key])
+ else:
+ outputs[key] = None
+
+ token_timestamps = outputs.get("token_timestamps")
+ if token_timestamps is not None:
+ model_output_type = dict
+
+ return model_output_type(**outputs)
+
+ def _need_fallback(
+ self,
+ seek_sequence,
+ seek_outputs,
+ index,
+ logits_processor,
+ generation_config,
+ vocab_size,
+ temperature,
+ ):
+ needs_fallback = False
+ should_skip = False
+ if generation_config.compression_ratio_threshold is not None:
+ compression_ratio = self._retrieve_compression_ratio(seek_sequence, vocab_size)
+
+ if compression_ratio > generation_config.compression_ratio_threshold:
+ needs_fallback = True
+
+ if generation_config.logprob_threshold is not None:
+ if hasattr(seek_outputs[0], "sequences_scores"):
+ logprobs = [s["sequences_scores"] for s in seek_outputs][index]
+ else:
+ scores = seek_outputs[index]["scores"]
+ logprobs = self._retrieve_avg_logprobs(
+ scores,
+ seek_sequence,
+ temperature,
+ )
+
+ if logprobs < generation_config.logprob_threshold:
+ needs_fallback = True
+
+ if generation_config.no_speech_threshold is not None:
+ no_speech_prob = _get_attr_from_logit_processors(
+ logits_processor, WhisperNoSpeechDetection, "no_speech_prob"
+ )
+
+ if (
+ logprobs < generation_config.logprob_threshold
+ and no_speech_prob[index] > generation_config.no_speech_threshold
+ ):
+ needs_fallback = False
+ should_skip = True
+
+ return needs_fallback, should_skip
+
+ def _expand_variables_for_generation(
+ self, input_features, seek, max_frames, init_tokens, batch_size, condition_on_prev_tokens, generation_config
+ ):
+ if generation_config.num_return_sequences is not None and generation_config.num_return_sequences > 1:
+ batch_idx_map = list(range(batch_size * generation_config.num_return_sequences))
+ cur_bsz = len(batch_idx_map)
+ do_condition_on_prev_tokens = [condition_on_prev_tokens for _ in range(len(batch_idx_map))]
+ input_features = input_features.repeat_interleave(generation_config.num_return_sequences, dim=0)
+ seek = seek.repeat_interleave(generation_config.num_return_sequences, dim=0)
+ max_frames = max_frames.repeat_interleave(generation_config.num_return_sequences, dim=0)
+ init_tokens = init_tokens.repeat_interleave(generation_config.num_return_sequences, dim=0)
+ generation_config.num_return_sequences = 1
+ else:
+ cur_bsz = batch_size
+ batch_idx_map = list(range(cur_bsz))
+ do_condition_on_prev_tokens = [condition_on_prev_tokens for _ in range(cur_bsz)]
+
+ return (
+ batch_idx_map,
+ cur_bsz,
+ input_features,
+ seek,
+ max_frames,
+ init_tokens,
+ do_condition_on_prev_tokens,
+ )
+
+ @staticmethod
+ def _setup_no_speech_detection(logits_processor, segment_input, decoder_input_ids, kwargs):
+ set_inputs = _get_attr_from_logit_processors(logits_processor, WhisperNoSpeechDetection, "set_inputs")
+ extra_kwargs = {k: v for k, v in kwargs.items() if torch.is_tensor(v)}
+ set_inputs({"inputs": segment_input, "input_ids": decoder_input_ids, **extra_kwargs})
+
+ @staticmethod
+ def _retrieve_total_input_frames(input_features, input_stride, kwargs):
+ if input_features is not None:
+ return input_features.shape[0], input_features.shape[-1]
+
+ if "encoder_outputs" in kwargs:
+ encoder_outputs_shape = (
+ kwargs["encoder_outputs"][0].shape
+ if isinstance(kwargs["encoder_outputs"], BaseModelOutput)
+ else kwargs["encoder_outputs"].shape
+ )
+ return encoder_outputs_shape[0], encoder_outputs_shape[1] * input_stride
+
+ raise ValueError("Make sure to provide either `input_features` or `encoder_outputs` to `generate`.")
+
+ @staticmethod
+ def _maybe_warn_unused_inputs(
+ condition_on_prev_tokens,
+ temperature,
+ compression_ratio_threshold,
+ logprob_threshold,
+ no_speech_threshold,
+ total_input_frames,
+ ):
+ warning_prefix = (
+ f"Audio input consists of only {total_input_frames}. "
+ "Short-form transcription is activated."
+ "{}, but will be ignored."
+ )
+ if condition_on_prev_tokens is not None:
+ logger.warning(warning_prefix.format(f"condition_on_prev_tokens is set to {condition_on_prev_tokens}"))
+
+ if compression_ratio_threshold is not None:
+ logger.warning(
+ warning_prefix.format(f"compression_ratio_threshold is set to {compression_ratio_threshold}")
+ )
+
+ if logprob_threshold is not None:
+ logger.warning(warning_prefix.format(f"logprob_threshold is set to {logprob_threshold}"))
+
+ if no_speech_threshold is not None:
+ logger.warning(warning_prefix.format(f"no_speech_threshold is set to {no_speech_threshold}"))
+
+ @staticmethod
+ def _set_return_outputs(return_dict_in_generate, return_token_timestamps, logprob_threshold, generation_config):
+ if return_dict_in_generate is None:
+ return_dict_in_generate = generation_config.return_dict_in_generate
+ else:
+ generation_config.return_dict_in_generate = return_dict_in_generate
+
+ generation_config.return_token_timestamps = return_token_timestamps
+ if return_token_timestamps:
+ generation_config.return_dict_in_generate = True
+ generation_config.output_attentions = True
+ generation_config.output_scores = True
+
+ if logprob_threshold is not None:
+ generation_config.return_dict_in_generate = True
+ generation_config.output_scores = True
+
+ return return_dict_in_generate
+
+ def _set_return_timestamps(self, return_timestamps, is_shortform, generation_config):
+ if return_timestamps is None and hasattr(generation_config, "return_timestamps"):
+ return_timestamps = generation_config.return_timestamps
+
+ if not is_shortform:
+ if return_timestamps is False:
+ raise ValueError(
+ "You have passed more than 3000 mel input features (> 30 seconds) which automatically "
+ "enables long-form generation which requires the model to predict timestamp tokens. Please "
+ "either pass `return_timestamps=True` or make sure to pass no more than 3000 mel input features."
+ )
+
+ logger.info("Setting `return_timestamps=True` for long-form generation.")
+ return_timestamps = True
+
+ if return_timestamps and not hasattr(generation_config, "no_timestamps_token_id"):
+ raise ValueError(
+ "You are trying to return timestamps, but the generation config is not properly set. "
+ "Make sure to initialize the generation config with the correct attributes that are needed such as "
+ "`no_timestamps_token_id`. For more details on how to generate the approtiate config, refer to "
+ "https://github.com/huggingface/transformers/issues/21878#issuecomment-1451902363"
+ )
+
+ generation_config.return_timestamps = return_timestamps
+
+ if hasattr(generation_config, "no_timestamps_token_id"):
+ timestamp_begin = generation_config.no_timestamps_token_id + 1
+ else:
+ # BC for models missing the `no_timestamps_token_id` in the generation config when generating short-form
+ # with no timestamps. We set the timestamp begin token larger than the vocab size, such that the
+ # timestamp condition is never met in the decoding loop
+ timestamp_begin = self.config.vocab_size + 1
+
+ return timestamp_begin
+
+ @staticmethod
+ def _set_language_and_task(language, task, is_multilingual, generation_config):
+ if is_multilingual is not None:
+ if not hasattr(generation_config, "is_multilingual"):
+ raise ValueError(
+ "The generation config is outdated and is thus not compatible with the `is_multilingual` argument "
+ "to `generate`. Please update the generation config as per the instructions "
+ "https://github.com/huggingface/transformers/issues/25084#issuecomment-1664398224"
+ )
+ generation_config.is_multilingual = is_multilingual
+
+ if hasattr(generation_config, "is_multilingual") and not generation_config.is_multilingual:
+ if task is not None or language is not None:
+ raise ValueError(
+ "Cannot specify `task` or `language` for an English-only model. If the model is intended to be "
+ "multilingual, pass `is_multilingual=True` to generate, or update the generation config."
+ )
+
+ if language is not None:
+ if not hasattr(generation_config, "lang_to_id"):
+ raise ValueError(
+ "The generation config is outdated and is thus not compatible with the `language` argument "
+ "to `generate`. Please update the generation config as per the instructions "
+ "https://github.com/huggingface/transformers/issues/25084#issuecomment-1664398224"
+ )
+ generation_config.language = language
+
+ if task is not None:
+ if not hasattr(generation_config, "task_to_id"):
+ raise ValueError(
+ "The generation config is outdated and is thus not compatible with the `task` argument "
+ "to `generate`. Please update the generation config as per the instructions "
+ "https://github.com/huggingface/transformers/issues/25084#issuecomment-1664398224"
+ )
+ generation_config.task = task
+
+ def _retrieve_init_tokens(self, input_features, batch_size, generation_config, config, num_segment_frames, kwargs):
+ def replace_or_add(lst: list[int], num: int, itr: Iterator[int]):
+ """short function to replace num with a itr in lst"""
+ found = any(i in lst for i in itr)
+ if found:
+ lst = [num if i in itr else i for i in lst]
+ else:
+ lst.append(num)
+ return lst
+
+ def language_to_id(language: str) -> int:
+ language = language.lower()
+ if language in generation_config.lang_to_id:
+ language_token = language
+ elif language in TO_LANGUAGE_CODE:
+ language_token = f"<|{TO_LANGUAGE_CODE[language]}|>"
+ elif language in TO_LANGUAGE_CODE.values():
+ language_token = f"<|{language}|>"
+ else:
+ is_language_code = len(language) == 2
+ raise ValueError(
+ f"Unsupported language: {language}. Language should be one of:"
+ f" {list(TO_LANGUAGE_CODE.values()) if is_language_code else list(TO_LANGUAGE_CODE.keys())}."
+ )
+ if language_token not in generation_config.lang_to_id:
+ raise ValueError(
+ f"{language_token} is not supported by this specific model as it is not in the "
+ "`generation_config.lang_to_id`. (You should just add it to the generation config)"
+ )
+
+ return generation_config.lang_to_id[language_token]
+
+ task = getattr(generation_config, "task", None)
+ language = getattr(generation_config, "language", None)
+ init_tokens = [generation_config.decoder_start_token_id]
+
+ # TL;DR we silently ignore `forced_decoder_ids` (old flag) when `task` or `language` (new flags) are set.
+ # `forced_decoder_ids` is an old generation config attribute that is now deprecated in favor of `task` and
+ # `language` (see https://github.com/huggingface/transformers/pull/28687). Nevertheless, keep in mind that
+ # the original checkpoints all contain this attribute, and thus we should maintain backwards compatibility.
+ if task is None and language is None:
+ forced_decoder_ids = getattr(generation_config, "forced_decoder_ids", None)
+ # fallback: check the model config for forced_decoder_ids
+ if forced_decoder_ids is None and getattr(config, "forced_decoder_ids", None) is not None:
+ forced_decoder_ids = config.forced_decoder_ids
+
+ if forced_decoder_ids is not None:
+ logger.warning_once(
+ "Using custom `forced_decoder_ids` from the (generation) config. This is deprecated in favor of "
+ "the `task` and `language` flags/config options."
+ )
+
+ if forced_decoder_ids is not None and forced_decoder_ids[0][1] is None:
+ logger.warning_once(
+ "Transcription using a multilingual Whisper will default to language detection followed by "
+ "transcription instead of translation to English. This might be a breaking change for your "
+ "use case. If you want to instead always translate your audio to English, make sure to pass "
+ "`language='en'`. See https://github.com/huggingface/transformers/pull/28687 for more details."
+ )
+
+ if forced_decoder_ids is not None and forced_decoder_ids[0][0] == 1:
+ i = 1
+ while len(forced_decoder_ids) > 0 and forced_decoder_ids[0][0] == i:
+ init_tokens += [forced_decoder_ids[0][1]]
+ forced_decoder_ids = forced_decoder_ids[1:]
+ i += 1
+
+ if len(forced_decoder_ids) > 0:
+ raise ValueError(
+ f"You are using token ids in `forced_decoder_ids` that do not seem to correctly follow "
+ f"the prompt pattern of Whisper. Make sure that {forced_decoder_ids} has an entry for all "
+ f"indices >= 1 and < {forced_decoder_ids[0][0]}.",
+ )
+
+ is_lang_id_undefined = len(init_tokens) <= 1 or (len(init_tokens) > 1 and init_tokens[1] is None)
+
+ # Make sure language is a list of strings of the correct length
+ if isinstance(language, (list, tuple)):
+ if any(l is None for l in language):
+ raise TypeError(
+ "Expected `language` to be `None`, a single string (e.g. `'en'`), or a list of strings with "
+ "length equal to the batch size (e.g. `('en', 'fr')` for a batch size of 2). Got a list "
+ "containing `None`."
+ )
+ if len(language) != batch_size:
+ raise ValueError(
+ "When passing a list of languages, the length of the list must match the batch size. "
+ f"Expected length of {batch_size}, but got {len(language)} languages."
+ )
+ languages = language
+ elif language is None:
+ # Language will be detected for each item in batch
+ languages = [None] * batch_size
+ else:
+ languages = [language] # Use a length-1 list now, broadcast later
+
+ # Separate init_tokens for each language
+ init_tokens = [copy.copy(init_tokens) for _ in languages]
+
+ # Update init_tokens with languages
+ lang_ids = None
+ if language is not None:
+ lang_ids = [language_to_id(l) for l in languages]
+ elif hasattr(generation_config, "lang_to_id") and is_lang_id_undefined:
+ # language is not defined or intentionally set to `None` to trigger language detection
+ lang_ids = self.detect_language(
+ input_features=input_features,
+ encoder_outputs=kwargs.get("encoder_outputs", None),
+ generation_config=generation_config,
+ num_segment_frames=num_segment_frames,
+ ).tolist()
+ if lang_ids is not None:
+ # append or replace lang_ids to init_tokens
+ for i in range(len(init_tokens)):
+ if len(init_tokens[i]) > 1:
+ init_tokens[i][1] = lang_ids[i]
+ else:
+ init_tokens[i].append(lang_ids[i])
+ del languages
+
+ # Update init_tokens with task
+ for i in range(len(init_tokens)):
+ if task is not None:
+ if task in TASK_IDS:
+ init_tokens[i].append(generation_config.task_to_id[generation_config.task])
+ task_id = generation_config.task_to_id[generation_config.task]
+
+ # if task is defined it'll overwrite task ids that might have already been defined via the generation_config
+ replace_or_add(init_tokens[i], task_id, generation_config.task_to_id.values())
+ else:
+ raise ValueError(f"The `{task}`task is not supported. The task should be one of `{TASK_IDS}`")
+ elif language is not None and hasattr(generation_config, "task_to_id"):
+ # if language is defined, but no task id is in `init_tokens`, default to transcribe
+ if not any(ti in init_tokens[i] for ti in generation_config.task_to_id.values()):
+ init_tokens[i].append(generation_config.task_to_id["transcribe"])
+
+ if (
+ not generation_config.return_timestamps
+ and hasattr(generation_config, "no_timestamps_token_id")
+ and init_tokens[i][-1] != generation_config.no_timestamps_token_id
+ ):
+ init_tokens[i].append(generation_config.no_timestamps_token_id)
+ elif (
+ generation_config.return_timestamps and init_tokens[i][-1] == generation_config.no_timestamps_token_id
+ ):
+ logger.info(
+ "<|notimestamps|> prompt token is removed from generation_config since `return_timestamps` is set to `'True'`."
+ )
+ init_tokens[i] = init_tokens[i][:-1]
+
+ # let's make sure we don't pass `None` tokens as prompt tokens
+ init_tokens[i] = [t for t in init_tokens[i] if t is not None]
+
+ return torch.as_tensor(init_tokens, dtype=torch.long, device=self.device).expand(batch_size, -1)
+
+ def detect_language(
+ self,
+ input_features: Optional[torch.FloatTensor] = None,
+ encoder_outputs: Optional[Union[torch.FloatTensor, BaseModelOutput]] = None,
+ generation_config: Optional[GenerationConfig] = None,
+ num_segment_frames: int = 3000,
+ ) -> torch.Tensor:
+ """
+ Detects language from log-mel input features or encoder_outputs
+
+ Parameters:
+ input_features (`torch.Tensor` of shape `(batch_size, feature_size, sequence_length)`, *optional*):
+ Float values of log-mel features extracted from the raw speech waveform. The raw speech waveform can be obtained by
+ loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via
+ the soundfile library (`pip install soundfile`). To prepare the array into `input_features`, the
+ [`AutoFeatureExtractor`] should be used for extracting the mel features, padding and conversion into a
+ tensor of type `torch.FloatTensor`. See [`~WhisperFeatureExtractor.__call__`] for details.
+ encoder_outputs (`tuple(tuple(torch.FloatTensor)`, *optional*):
+ Tuple consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*: `attentions`)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ generation_config (`~generation.GenerationConfig`, *optional*):
+ The generation configuration to be used as base parametrization for the generation call. `**kwargs`
+ passed to generate matching the attributes of `generation_config` will override them. If
+ `generation_config` is not provided, the default will be used, which had the following loading
+ priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model
+ configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s
+ default values, whose documentation should be checked to parameterize generation.
+ num_segment_frames (`int`, *optional*, defaults to 3000):
+ The number of log-mel frames the model expects
+
+ Return:
+ A `torch.LongTensor` representing the detected language ids.
+ """
+ if input_features is None and encoder_outputs is None:
+ raise ValueError("You have to specify either `input_features` or `encoder_outputs`")
+ elif input_features is not None and encoder_outputs is not None:
+ raise ValueError("Make sure to specify only one of `input_features` or `encoder_outputs` - not both!")
+ elif input_features is not None:
+ inputs = {"input_features": input_features[:, :, :num_segment_frames]}
+ batch_size = input_features.shape[0]
+ elif encoder_outputs is not None:
+ inputs = {"encoder_outputs": encoder_outputs}
+ batch_size = (
+ encoder_outputs[0].shape[0] if isinstance(encoder_outputs, BaseModelOutput) else encoder_outputs[0]
+ )
+
+ generation_config = generation_config or self.generation_config
+ decoder_input_ids = (
+ torch.ones((batch_size, 1), device=self.device, dtype=torch.long)
+ * generation_config.decoder_start_token_id
+ )
+
+ with torch.no_grad():
+ logits = self(**inputs, decoder_input_ids=decoder_input_ids, use_cache=False).logits[:, -1]
+
+ non_lang_mask = torch.ones_like(logits[0], dtype=torch.bool)
+ non_lang_mask[list(generation_config.lang_to_id.values())] = False
+
+ logits[:, non_lang_mask] = -np.inf
+
+ lang_ids = logits.argmax(-1)
+
+ return lang_ids
+
+ @staticmethod
+ def _check_decoder_input_ids(kwargs):
+ decoder_input_ids = kwargs.get("decoder_input_ids", None)
+ assistant_model = kwargs.get("assistant_model", None)
+ if decoder_input_ids is not None and assistant_model is not None:
+ raise ValueError(
+ "Passing `decoder_input_ids` is deprecated. Consider passing `prompt_ids` instead.",
+ )
+
+ @staticmethod
+ def _set_num_frames(return_token_timestamps, generation_config, attention_mask, kwargs):
+ if return_token_timestamps:
+ if getattr(generation_config, "task", None) == "translate":
+ logger.warning("Token-level timestamps may not be reliable for task 'translate'.")
+ if not hasattr(generation_config, "alignment_heads"):
+ raise ValueError(
+ "Model generation config has no `alignment_heads`, token-level timestamps not available. "
+ "See https://gist.github.com/hollance/42e32852f24243b748ae6bc1f985b13a on how to add this property to the generation config."
+ )
+ if "num_frames" in kwargs:
+ generation_config.num_frames = kwargs.pop("num_frames")
+ if isinstance(generation_config.num_frames, torch.Tensor):
+ generation_config.num_frames = generation_config.num_frames.cpu()
+ else:
+ generation_config.num_frames = torch.tensor(generation_config.num_frames)
+
+ logger.warning_once(
+ "`num_frames` is deprecated and will be removed in Transformers v5. Use `attention_mask` instead, as it can be used to infer the number of frames. "
+ "You can retrieve the `attention_mask` by doing `processor(audio, ..., return_attention_mask=True"
+ )
+ elif attention_mask is not None:
+ generation_config.num_frames = attention_mask.sum(-1).cpu()
+ else:
+ logger.warning_once(
+ "When setting `return_token_timestamps` to `True`, make sure to pass an `attention_mask` to get precise token-level timestamps. You can retrieve the `attention_mask` by doing `processor(audio, ..., return_attention_mask=True)` "
+ )
+ generation_config.num_frames = None
+
+ @staticmethod
+ def _set_thresholds_and_condition(
+ generation_config,
+ logprob_threshold,
+ compression_ratio_threshold,
+ no_speech_threshold,
+ condition_on_prev_tokens,
+ ):
+ generation_config.logprob_threshold = (
+ logprob_threshold
+ if logprob_threshold is not None
+ else getattr(generation_config, "logprob_threshold", None)
+ )
+ generation_config.compression_ratio_threshold = (
+ compression_ratio_threshold
+ if compression_ratio_threshold is not None
+ else getattr(generation_config, "compression_ratio_threshold", None)
+ )
+ generation_config.no_speech_threshold = (
+ no_speech_threshold
+ if no_speech_threshold is not None
+ else getattr(generation_config, "no_speech_threshold", None)
+ )
+ generation_config.condition_on_prev_tokens = (
+ condition_on_prev_tokens
+ if condition_on_prev_tokens is not None
+ else getattr(generation_config, "condition_on_prev_tokens", None)
+ )
+
+ @staticmethod
+ def _set_prompt_condition_type(generation_config, prompt_condition_type):
+ allowed_cond_types = ["first-segment", "all-segments"]
+
+ # default to "first-segment"
+ prompt_condition_type = prompt_condition_type or allowed_cond_types[0]
+
+ if prompt_condition_type not in allowed_cond_types:
+ raise ValueError(
+ f"`prompt_condition_type={prompt_condition_type} does not exist. Make sure to set `prompt_condition_type` to one of {', '.join(allowed_cond_types)}"
+ )
+
+ if generation_config.condition_on_prev_tokens is not True and prompt_condition_type == "all-segments":
+ raise ValueError(
+ "Make sure to set `condition_on_prev_tokens=True` when setting `prompt_condition_type='all-segments'`."
+ )
+
+ generation_config.prompt_condition_type = prompt_condition_type
+
+ @staticmethod
+ def _set_condition_on_prev_tokens(condition_on_prev_tokens, generation_config):
+ condition_on_prev_tokens = (
+ condition_on_prev_tokens
+ if condition_on_prev_tokens is not None
+ else getattr(generation_config, "condition_on_prev_tokens", False)
+ )
+ generation_config.condition_on_prev_tokens = condition_on_prev_tokens
+
+ @staticmethod
+ def _retrieve_max_frames_and_seek(batch_size, attention_mask, total_input_frames, is_shortform):
+ if batch_size > 1 and not is_shortform and attention_mask is None:
+ raise ValueError(
+ "When doing batched long-form audio transcription, make sure to pass an `attention_mask`. You can retrieve the `attention_mask` by doing `processor(audio, ..., return_attention_mask=True)` "
+ )
+ elif batch_size > 1 and not is_shortform:
+ max_frames = attention_mask.sum(-1).cpu().to(torch.long)
+ seek = torch.zeros((batch_size,), dtype=torch.long)
+ else:
+ max_frames = torch.ones((batch_size,), dtype=torch.long) * total_input_frames
+ seek = torch.zeros((batch_size,), dtype=torch.long)
+
+ return max_frames, seek
+
+ def _retrieve_logit_processors(self, generation_config, logits_processor, begin_index, num_beams, device):
+ if generation_config.return_timestamps is True:
+ timestamp_processor = WhisperTimeStampLogitsProcessor(generation_config, begin_index=begin_index)
+ logits_processor = (
+ [timestamp_processor] if logits_processor is None else [timestamp_processor] + logits_processor
+ )
+
+ if generation_config.suppress_tokens is not None:
+ suppress_tokens_processor = SuppressTokensLogitsProcessor(generation_config.suppress_tokens, device=device)
+ logits_processor = (
+ [suppress_tokens_processor]
+ if logits_processor is None
+ else [suppress_tokens_processor] + logits_processor
+ )
+ generation_config.suppress_tokens = None
+
+ if generation_config.begin_suppress_tokens is not None:
+ begin_suppress_processor = SuppressTokensAtBeginLogitsProcessor(
+ generation_config.begin_suppress_tokens, begin_index=begin_index, device=device
+ )
+ logits_processor = (
+ [begin_suppress_processor]
+ if logits_processor is None
+ else [begin_suppress_processor] + logits_processor
+ )
+ generation_config.begin_suppress_tokens = None
+
+ if generation_config.no_speech_threshold is not None:
+ no_speech_detector = WhisperNoSpeechDetection(
+ no_speech_token=generation_config.no_timestamps_token_id - 1,
+ begin_index=begin_index,
+ scores_is_logprobs=num_beams > 1,
+ )
+ logits_processor = (
+ [no_speech_detector] if logits_processor is None else [no_speech_detector] + logits_processor
+ )
+ no_speech_detector.set_model(self)
+
+ return logits_processor
+
+ @staticmethod
+ def _maybe_reduce_batch(input_features, seek, max_frames, cur_bsz, batch_idx_map):
+ prev_bsz = cur_bsz
+ new_batch_idx_map = []
+ for i in range(prev_bsz):
+ prev_i = batch_idx_map[i]
+ if seek[prev_i] >= max_frames[prev_i]:
+ cut_index = i + (cur_bsz - prev_bsz)
+ cur_bsz -= 1
+ input_features = torch.cat([input_features[:cut_index], input_features[cut_index + 1 :]], dim=0)
+ else:
+ # cut out index that goes away
+ new_batch_idx_map.append(prev_i)
+
+ return input_features, cur_bsz, new_batch_idx_map
+
+ @staticmethod
+ def _get_input_segment(input_features, seek, seek_num_frames, num_segment_frames, cur_bsz, batch_idx_map):
+ if input_features is None:
+ return None
+
+ segment_input = []
+ for i in range(cur_bsz):
+ prev_i = batch_idx_map[i]
+ segment_input_slice = input_features[i : i + 1, :, seek[prev_i] : seek[prev_i] + seek_num_frames[prev_i]]
+
+ if segment_input_slice.shape[-1] < num_segment_frames:
+ # pad to 3000 if necessary
+ segment_input_slice = F.pad(
+ segment_input_slice, pad=(0, num_segment_frames - segment_input_slice.shape[-1])
+ )
+
+ segment_input.append(segment_input_slice)
+
+ segment_input = torch.cat(segment_input, dim=0)
+
+ return segment_input
+
+ @staticmethod
+ def _prepare_decoder_input_ids(
+ cur_bsz,
+ init_tokens,
+ current_segments,
+ batch_idx_map,
+ do_condition_on_prev_tokens,
+ prompt_ids,
+ generation_config,
+ config,
+ device,
+ suppress_tokens,
+ timestamp_begin,
+ kwargs,
+ ):
+ if "decoder_input_ids" in kwargs:
+ decoder_input_ids = kwargs.pop("decoder_input_ids")
+
+ return decoder_input_ids, kwargs
+
+ cut_off_length = config.max_target_positions // 2 - 1
+
+ decoder_input_ids = init_tokens[batch_idx_map]
+
+ prev_start_of_text = getattr(generation_config, "prev_sot_token_id", None)
+ if prev_start_of_text is None:
+ if suppress_tokens is not None and len(suppress_tokens) >= 2:
+ prev_start_of_text = suppress_tokens[-2]
+ else:
+ prev_start_of_text = None
+
+ if any(do_condition_on_prev_tokens) and len(current_segments[0]) > 0:
+ # according to https://github.com/openai/whisper/blob/e58f28804528831904c3b6f2c0e473f346223433/whisper/decoding.py#L609
+ active_segments = [current_segments[i] if do_condition_on_prev_tokens[i] else None for i in batch_idx_map]
+
+ if prompt_ids is not None and generation_config.prompt_condition_type == "all-segments":
+ prev_ids = prompt_ids
+ else:
+ one_tensor = torch.ones((cur_bsz, 1), device=device, dtype=torch.long)
+ prev_ids = prev_start_of_text * one_tensor[0] if prev_start_of_text is not None else None
+
+ padding = "max_length" if generation_config.cache_implementation == "static" else "longest"
+
+ prev_tokens = _pad_to_max_length(
+ active_segments,
+ generation_config.pad_token_id,
+ device=device,
+ padding_side="left",
+ padding=padding,
+ bos_token_tensor=prev_ids,
+ cut_off_length=cut_off_length,
+ skip_ending_double_timestamps=True,
+ timestamp_begin=timestamp_begin,
+ )
+ decoder_input_ids = torch.cat([prev_tokens, decoder_input_ids], dim=-1)
+
+ kwargs["decoder_attention_mask"] = decoder_input_ids != generation_config.pad_token_id
+ elif prompt_ids is not None:
+ prev_tokens = prompt_ids[None].repeat(decoder_input_ids.shape[0], 1)
+ decoder_input_ids = torch.cat([prev_tokens, decoder_input_ids], dim=-1)
+ # make sure `"decoder_attention_mask"` is not passed to forward
+ kwargs.pop("decoder_attention_mask", None)
+ else:
+ # make sure `"decoder_attention_mask"` is not passed to forward
+ kwargs.pop("decoder_attention_mask", None)
+
+ return decoder_input_ids, kwargs
+
+ def _set_max_new_tokens_and_length(self, config, decoder_input_ids, generation_config):
+ max_new_tokens = generation_config.max_new_tokens if generation_config.max_new_tokens is not None else 0
+ if max_new_tokens + decoder_input_ids.shape[-1] > self.config.max_target_positions:
+ raise ValueError(
+ f"The length of `decoder_input_ids`, including special start tokens, prompt tokens, and previous tokens, is {decoder_input_ids.shape[-1]}, "
+ f" and `max_new_tokens` is {max_new_tokens}. Thus, the combined length of "
+ f"`decoder_input_ids` and `max_new_tokens` is: {max_new_tokens + decoder_input_ids.shape[-1]}. This exceeds the "
+ f"`max_target_positions` of the Whisper model: {self.config.max_target_positions}. "
+ "You should either reduce the length of your prompt, or reduce the value of `max_new_tokens`, "
+ f"so that their combined length is less than {self.config.max_target_positions}."
+ )
+
+ num_initial_tokens = min(config.max_target_positions // 2 - 1, decoder_input_ids.shape[-1] - 1)
+
+ # Make sure we don't get larger than `max_length`
+ if generation_config.max_length is not None and generation_config.max_new_tokens is None:
+ max_length = min(generation_config.max_length + num_initial_tokens, config.max_target_positions)
+ logger.info(
+ f"Increase max_length from {generation_config.max_length} to {max_length} since input is conditioned on previous segment."
+ )
+ elif (
+ generation_config.max_new_tokens is not None
+ and generation_config.max_new_tokens + decoder_input_ids.shape[-1] > config.max_target_positions
+ ):
+ max_new_tokens = config.max_target_positions - decoder_input_ids.shape[-1]
+ generation_config.max_new_tokens = max_new_tokens
+
+ @staticmethod
+ def _retrieve_compression_ratio(tokens, vocab_size):
+ """Compute byte length of zlib compressed token bytes vs. byte length of raw token bytes"""
+ length = int(math.log2(vocab_size) / 8) + 1
+ token_bytes = b"".join([t.to_bytes(length, "little") for t in tokens.tolist()])
+ compression_ratio = len(token_bytes) / len(zlib.compress(token_bytes))
+
+ return compression_ratio
+
+ @staticmethod
+ def _retrieve_avg_logprobs(scores, tokens, temperature):
+ rescale_temperature = temperature if temperature > 0.0 else 1
+ scores = torch.stack(scores).to(tokens.device)
+
+ if scores.shape[0] > tokens.shape[0]:
+ scores = scores[: tokens.shape[0]]
+ else:
+ tokens = tokens[-scores.shape[0] :]
+
+ logprobs = F.log_softmax((scores * rescale_temperature).float(), dim=-1).to(scores.dtype)
+
+ # retrieve logprob of selected tokens and sum
+ # don't remove the eos token logprob! it counts in avg_logprob calculation in the original implementation
+ sum_logprobs = sum(logprobs[i][tokens[i]] for i in range(logprobs.shape[0]))
+
+ avg_logprobs = sum_logprobs / len(tokens)
+ return avg_logprobs
+
+ @staticmethod
+ def _retrieve_segment(
+ seek_sequence,
+ seek_outputs,
+ time_offset,
+ timestamp_begin,
+ seek_num_frames,
+ time_precision,
+ time_precision_features,
+ input_stride,
+ prev_idx,
+ idx,
+ return_token_timestamps,
+ decoder_input_ids,
+ ):
+ # find the predicted "end of segment" predictions of Whisper
+ # "end of segment" predictions occur whenever Whisper predicts a timestamp token
+ timestamp_tokens: torch.Tensor = seek_sequence.ge(timestamp_begin)
+ single_timestamp_ending = timestamp_tokens[-2:].tolist() == [False, True]
+ timestamp_segment_indices = torch.where(timestamp_tokens[:-1] & timestamp_tokens[1:])[0]
+ timestamp_segment_indices.add_(1)
+ token_timestamps = seek_outputs[idx]["token_timestamps"] if return_token_timestamps else []
+ idx_offset = decoder_input_ids.shape[-1]
+ device = seek_sequence.device
+
+ # If whisper predicted a "end of segment" via a timestep token, let's go ever each
+ # "end of segment" prediction and slice the decoding into segments accordingly
+ if len(timestamp_segment_indices) > 0:
+ # if the output contains two consecutive timestamp tokens
+ slices = timestamp_segment_indices.tolist()
+ segments = []
+ if single_timestamp_ending:
+ slices.append(len(seek_sequence))
+ else:
+ # we want to include the last timestamp token in the last segment to know it was no single ending
+ slices[-1] += 1
+
+ last_slice = 0
+ # Add each segment to list of all segments
+ for i, current_slice in enumerate(slices):
+ is_last_slice = i == len(slices) - 1
+ sliced_tokens = seek_sequence[last_slice:current_slice]
+ start_timestamp_pos = sliced_tokens[0] - timestamp_begin
+ idx_sliced_tokens = -1 if not is_last_slice or single_timestamp_ending else -2
+ end_timestamp_pos = sliced_tokens[idx_sliced_tokens] - timestamp_begin
+ segments.append(
+ {
+ "start": time_offset[prev_idx]
+ + start_timestamp_pos.to(torch.float32 if device.type == "mps" else torch.float64)
+ * time_precision,
+ "end": time_offset[prev_idx]
+ + end_timestamp_pos.to(torch.float32 if device.type == "mps" else torch.float64)
+ * time_precision,
+ "tokens": sliced_tokens,
+ "idxs": (idx_offset + last_slice, idx_offset + current_slice),
+ "result": seek_outputs[idx],
+ }
+ )
+ if return_token_timestamps:
+ segments[-1]["token_timestamps"] = (
+ token_timestamps[idx_offset + last_slice : idx_offset + current_slice] + time_offset[prev_idx]
+ )
+ last_slice = current_slice
+
+ if single_timestamp_ending:
+ # single timestamp at the end means no speech after the last timestamp.
+ segment_offset = seek_num_frames[prev_idx]
+ else:
+ # otherwise, ignore the unfinished segment and seek to the last timestamp
+ # here we throw away all predictions after the last predicted "end of segment"
+ # since we are cutting right in the middle of an audio
+ last_timestamp_pos = seek_sequence[last_slice - 2].item() - timestamp_begin
+ segment_offset = last_timestamp_pos * input_stride
+ else:
+ # If whisper does not predict any "end of segment" token, then
+ # the whole decoding is considered a segment and we add it to the list of segments
+ timestamps = seek_sequence[timestamp_tokens.nonzero().flatten()]
+ last_timestamp_pos = int(seek_num_frames[prev_idx] * time_precision_features / time_precision)
+ if timestamps.numel() > 0 and timestamps[-1] != timestamp_begin:
+ # no consecutive timestamps but it has a timestamp; use the last one.
+ last_timestamp_pos = (timestamps[-1] - timestamp_begin).to(
+ torch.float32 if device.type == "mps" else torch.float64
+ )
+ segments = [
+ {
+ "start": time_offset[prev_idx],
+ "end": time_offset[prev_idx] + last_timestamp_pos * time_precision,
+ "tokens": seek_sequence,
+ "idxs": (idx_offset, idx_offset + len(seek_sequence)),
+ "result": seek_outputs[idx],
+ }
+ ]
+ if return_token_timestamps:
+ segments[-1]["token_timestamps"] = (
+ token_timestamps[idx_offset : idx_offset + len(seek_sequence)] + time_offset[prev_idx]
+ )
+ segment_offset = seek_num_frames[prev_idx]
+
+ return segments, segment_offset
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_flax_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_flax_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..183fdd58f42cac2e8767c002193dcafd1bb3744c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_flax_whisper.py
@@ -0,0 +1,1707 @@
+# coding=utf-8
+# Copyright 2022 The OpenAI Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Flax whisper model."""
+
+import math
+import random
+from functools import partial
+from typing import Optional
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.linen import combine_masks, make_causal_mask
+from flax.linen import partitioning as nn_partitioning
+from flax.linen.attention import dot_product_attention_weights
+from flax.traverse_util import flatten_dict, unflatten_dict
+from jax import lax
+from jax.random import PRNGKey
+
+from ...generation.flax_logits_process import FlaxWhisperTimeStampLogitsProcessor
+from ...modeling_flax_outputs import (
+ FlaxBaseModelOutput,
+ FlaxBaseModelOutputWithPastAndCrossAttentions,
+ FlaxCausalLMOutputWithCrossAttentions,
+ FlaxSeq2SeqLMOutput,
+ FlaxSeq2SeqModelOutput,
+ FlaxSequenceClassifierOutput,
+)
+from ...modeling_flax_utils import (
+ ACT2FN,
+ FlaxPreTrainedModel,
+ append_call_sample_docstring,
+ append_replace_return_docstrings,
+ overwrite_call_docstring,
+)
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging, replace_return_docstrings
+from .configuration_whisper import WhisperConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+_CHECKPOINT_FOR_DOC = "openai/whisper-tiny"
+_CONFIG_FOR_DOC = "WhisperConfig"
+
+remat = nn_partitioning.remat
+
+
+def sinusoidal_embedding_init(key, shape, dtype=jnp.float_) -> jax.Array:
+ """Returns sinusoids for positional embedding"""
+ length, channels = shape
+ if channels % 2 != 0:
+ raise ValueError(
+ f"Number of channels has to be divisible by 2 for sinusoidal positional embeddings, got {channels} channels."
+ )
+ log_timescale_increment = math.log(10000) / (channels // 2 - 1)
+ inv_timescales = jnp.exp(-log_timescale_increment * jnp.arange(channels // 2))
+ scaled_time = jnp.arange(length).reshape(-1, 1) * inv_timescales.reshape(1, -1)
+ return jnp.concatenate([jnp.sin(scaled_time), jnp.cos(scaled_time)], axis=1).astype(dtype)
+
+
+WHISPER_START_DOCSTRING = r"""
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its models (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.) This model is also a Flax Linen
+ [flax.nn.Module](https://flax.readthedocs.io/en/latest/_autosummary/flax.nn.module.html) subclass. Use it as a
+ regular Flax Module and refer to the Flax documentation for all matter related to general usage and behavior.
+ Finally, this model supports inherent JAX features such as:
+ - [Just-In-Time (JIT) compilation](https://jax.readthedocs.io/en/latest/jax.html#just-in-time-compilation-jit)
+ - [Automatic Differentiation](https://jax.readthedocs.io/en/latest/jax.html#automatic-differentiation)
+ - [Vectorization](https://jax.readthedocs.io/en/latest/jax.html#vectorization-vmap)
+ - [Parallelization](https://jax.readthedocs.io/en/latest/jax.html#parallelization-pmap)
+
+ Parameters:
+ config ([`WhisperConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs). This can be used to enable mixed-precision training or half-precision
+ inference on GPUs or TPUs. If specified all the computation will be performed with the given `dtype`.
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.** If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`]
+ and [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+WHISPER_INPUTS_DOCSTRING = r"""
+ Args:
+ input_features (`numpy.ndarray` of shape `(batch_size, feature_size, sequence_length)`):
+ Float values mel features extracted from the raw speech waveform. Raw speech waveform can be obtained by
+ loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray` or a
+ `torch.Tensor`, *e.g.* via the torchcodec library (`pip install torchcodec`) or the soundfile library
+ (`pip install soundfile`).
+ To prepare the array into `input_features`, the [`WhisperFeatureExtractor`] should be used for extracting
+ the features, padding and conversion into a tensor of type `numpy.ndarray`.
+ See [`~WhisperFeatureExtractor.__call__`]
+ attention_mask (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Whisper does not support masking of the `input_features`, this argument is preserved for compatibility, but
+ is not used. By default the silence in the input log mel spectrogram are ignored.
+ decoder_input_ids (`numpy.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary. Indices can be obtained using
+ [`WhisperTokenizer`]. See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details.
+ [What are decoder input IDs?](../glossary#decoder-input-ids) Whisper uses the `decoder_start_token_id` as
+ the starting token for `decoder_input_ids` generation.
+ decoder_attention_mask (`numpy.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default. If you want to change padding behavior, you should modify to your needs. See diagram 1
+ in [the paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ position_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Whisper does not use `position_ids` in the encoder as `input_features` is always the same size and doesn't
+ use masking, but this argument is preserved for compatibility. By default the silence in the input log mel
+ spectrogram are ignored.
+ decoder_position_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the
+ range `[0, config.max_position_embeddings - 1]`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+WHISPER_ENCODE_INPUTS_DOCSTRING = r"""
+ Args:
+ input_features (`numpy.ndarray` of shape `(batch_size, feature_size, sequence_length)`):
+ Float values mel features extracted from the raw speech waveform. Raw speech waveform can be obtained by
+ loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via
+ the torchcodec library (`pip install torchcodec`) or the soundfile library (`pip install soundfile`).
+ To prepare the array into `input_features`, the [`WhisperFeatureExtractor`] should be used for extracting
+ the mel features, padding and conversion into a tensor of type `numpy.ndarray`.
+ See [`~WhisperFeatureExtractor.__call__`].
+ attention_mask (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Whisper does not support masking of the `input_features`, this argument is preserved for compatibility, but
+ is not used. By default the silence in the input log mel spectrogram are ignored.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+WHISPER_DECODE_INPUTS_DOCSTRING = r"""
+ Args:
+ decoder_input_ids (`numpy.ndarray` of shape `(batch_size, target_sequence_length)`):
+ Indices of decoder input sequence tokens in the vocabulary. Indices can be obtained using
+ [`WhisperTokenizer`]. See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details.
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+ encoder_outputs (`tuple(tuple(numpy.ndarray)`):
+ Tuple consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*: `attentions`)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ encoder_attention_mask (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Whisper does not support masking of the `input_features`, this argument is preserved for compatibility,
+ but it is not used. By default the silence in the input log mel spectrogram are ignored.
+ decoder_attention_mask (`numpy.ndarray` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default. If you want to change padding behavior, you should modify to your needs. See diagram 1
+ in [the paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ decoder_position_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the
+ range `[0, config.max_position_embeddings - 1]`.
+ past_key_values (`dict[str, numpy.ndarray]`, *optional*, returned by `init_cache` or when passing previous `past_key_values`):
+ Dictionary of pre-computed hidden-states (key and values in the attention blocks) that can be used for fast
+ auto-regressive decoding. Pre-computed key and value hidden-states are of shape *[batch_size, max_length]*.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+class FlaxWhisperAttention(nn.Module):
+ config: WhisperConfig
+ embed_dim: int
+ num_heads: int
+ dropout: float = 0.0
+ causal: bool = False
+ bias: bool = True
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self) -> None:
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {self.num_heads})."
+ )
+
+ dense = partial(
+ nn.Dense,
+ self.embed_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+
+ self.q_proj = dense(use_bias=self.bias)
+ self.k_proj = dense(use_bias=False)
+ self.v_proj = dense(use_bias=self.bias)
+ self.out_proj = dense(use_bias=self.bias)
+
+ if self.causal:
+ self.causal_mask = make_causal_mask(
+ jnp.ones((1, self.config.max_target_positions), dtype="bool"), dtype="bool"
+ )
+
+ def __call__(
+ self,
+ hidden_states: jnp.ndarray,
+ key_value_states: Optional[jnp.ndarray] = None,
+ attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ is_cross_attention = key_value_states is not None
+ batch_size = hidden_states.shape[0]
+
+ query_states = self.q_proj(hidden_states)
+
+ if is_cross_attention:
+ key_states = self.k_proj(key_value_states)
+ value_states = self.v_proj(key_value_states)
+ else:
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ query_states = self._split_heads(query_states)
+ key_states = self._split_heads(key_states)
+ value_states = self._split_heads(value_states)
+
+ if self.causal:
+ query_length, key_length = query_states.shape[1], key_states.shape[1]
+ if self.has_variable("cache", "cached_key"):
+ mask_shift = self.variables["cache"]["cache_index"]
+ max_decoder_length = self.variables["cache"]["cached_key"].shape[1]
+ causal_mask = lax.dynamic_slice(
+ self.causal_mask,
+ (0, 0, mask_shift, 0),
+ (1, 1, query_length, max_decoder_length),
+ )
+ else:
+ causal_mask = self.causal_mask[:, :, :query_length, :key_length]
+ causal_mask = jnp.broadcast_to(causal_mask, (batch_size,) + causal_mask.shape[1:])
+
+ # combine masks if needed
+ if attention_mask is not None and self.causal:
+ attention_mask = jnp.broadcast_to(jnp.expand_dims(attention_mask, axis=(-3, -2)), causal_mask.shape)
+ attention_mask = combine_masks(attention_mask, causal_mask)
+ elif self.causal:
+ attention_mask = causal_mask
+ elif attention_mask is not None:
+ attention_mask = jnp.expand_dims(attention_mask, axis=(-3, -2))
+
+ # During fast autoregressive decoding, we feed one position at a time,
+ # and cache the keys and values step by step.
+
+ if self.causal and (self.has_variable("cache", "cached_key") or init_cache):
+ key_states, value_states, attention_mask = self._concatenate_to_cache(
+ key_states, value_states, query_states, attention_mask
+ )
+
+ # Convert the boolean attention mask to an attention bias.
+ if attention_mask is not None:
+ # attention mask in the form of attention bias
+ attention_bias = lax.select(
+ attention_mask > 0,
+ jnp.full(attention_mask.shape, 0.0).astype(self.dtype),
+ jnp.full(attention_mask.shape, jnp.finfo(self.dtype).min).astype(self.dtype),
+ )
+ else:
+ attention_bias = None
+
+ dropout_rng = None
+ if not deterministic and self.dropout > 0.0:
+ dropout_rng = self.make_rng("dropout")
+
+ attn_weights = dot_product_attention_weights(
+ query_states,
+ key_states,
+ bias=attention_bias,
+ dropout_rng=dropout_rng,
+ dropout_rate=self.dropout,
+ broadcast_dropout=True,
+ deterministic=deterministic,
+ dtype=self.dtype,
+ precision=None,
+ )
+
+ attn_output = jnp.einsum("...hqk,...khd->...qhd", attn_weights, value_states)
+ attn_output = self._merge_heads(attn_output)
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+ def _split_heads(self, hidden_state) -> jnp.ndarray:
+ return hidden_state.reshape(hidden_state.shape[:2] + (self.num_heads, self.head_dim))
+
+ def _merge_heads(self, hidden_state) -> jnp.ndarray:
+ return hidden_state.reshape(hidden_state.shape[:2] + (self.embed_dim,))
+
+ @nn.compact
+ def _concatenate_to_cache(self, key, value, query, attention_mask) -> tuple[jnp.ndarray, jnp.ndarray, jnp.ndarray]:
+ # detect if we're initializing by absence of existing cache data.
+ is_initialized = self.has_variable("cache", "cached_key")
+ cached_key = self.variable("cache", "cached_key", jnp.zeros, key.shape, key.dtype)
+ cached_value = self.variable("cache", "cached_value", jnp.zeros, value.shape, value.dtype)
+ cache_index = self.variable("cache", "cache_index", lambda: jnp.array(0, dtype=jnp.int32))
+
+ if is_initialized:
+ *batch_dims, max_length, num_heads, depth_per_head = cached_key.value.shape
+ # update key, value caches with our new 1d spatial slices
+ cur_index = cache_index.value
+ indices = (0,) * len(batch_dims) + (cur_index, 0, 0)
+ key = lax.dynamic_update_slice(cached_key.value, key, indices)
+ value = lax.dynamic_update_slice(cached_value.value, value, indices)
+ cached_key.value = key
+ cached_value.value = value
+ num_updated_cache_vectors = query.shape[1]
+ cache_index.value = cache_index.value + num_updated_cache_vectors
+ # causal mask for cached decoder self-attention: our single query position should only
+ # attend to those key positions that have already been generated and cached, not the
+ # remaining zero elements.
+ pad_mask = jnp.broadcast_to(
+ jnp.arange(max_length) < cur_index + num_updated_cache_vectors,
+ tuple(batch_dims) + (1, num_updated_cache_vectors, max_length),
+ )
+ attention_mask = combine_masks(pad_mask, attention_mask)
+
+ return key, value, attention_mask
+
+
+# Copied from transformers.models.mbart.modeling_flax_mbart.FlaxMBartEncoderLayer with MBart->Whisper
+class FlaxWhisperEncoderLayer(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self) -> None:
+ self.embed_dim = self.config.d_model
+ self.self_attn = FlaxWhisperAttention(
+ config=self.config,
+ embed_dim=self.embed_dim,
+ num_heads=self.config.encoder_attention_heads,
+ dropout=self.config.attention_dropout,
+ dtype=self.dtype,
+ )
+ self.self_attn_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+ self.dropout_layer = nn.Dropout(rate=self.config.dropout)
+ self.activation_fn = ACT2FN[self.config.activation_function]
+ self.activation_dropout_layer = nn.Dropout(rate=self.config.activation_dropout)
+ self.fc1 = nn.Dense(
+ self.config.encoder_ffn_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+ self.fc2 = nn.Dense(
+ self.embed_dim, dtype=self.dtype, kernel_init=jax.nn.initializers.normal(self.config.init_std)
+ )
+ self.final_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+
+ def __call__(
+ self,
+ hidden_states: jnp.ndarray,
+ attention_mask: jnp.ndarray,
+ output_attentions: bool = True,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weights = self.self_attn(hidden_states=hidden_states, attention_mask=attention_mask)
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+class FlaxWhisperEncoderLayerCollection(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ if self.gradient_checkpointing:
+ FlaxWhisperEncoderCheckpointLayer = remat(FlaxWhisperEncoderLayer, static_argnums=(2, 3))
+ self.layers = [
+ FlaxWhisperEncoderCheckpointLayer(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.encoder_layers)
+ ]
+ else:
+ self.layers = [
+ FlaxWhisperEncoderLayer(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.encoder_layers)
+ ]
+ self.layerdrop = self.config.encoder_layerdrop
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ all_attentions = () if output_attentions else None
+ all_hidden_states = () if output_hidden_states else None
+
+ for encoder_layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = random.uniform(0, 1)
+ if not deterministic and (dropout_probability < self.layerdrop): # skip the layer
+ layer_outputs = (None, None)
+ else:
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ output_attentions,
+ deterministic,
+ )
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ outputs = (hidden_states, all_hidden_states, all_attentions)
+
+ if not return_dict:
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=all_hidden_states, attentions=all_attentions
+ )
+
+
+# Copied from transformers.models.mbart.modeling_flax_mbart.FlaxMBartDecoderLayer with MBart->Whisper
+class FlaxWhisperDecoderLayer(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self) -> None:
+ self.embed_dim = self.config.d_model
+ self.self_attn = FlaxWhisperAttention(
+ config=self.config,
+ embed_dim=self.embed_dim,
+ num_heads=self.config.decoder_attention_heads,
+ dropout=self.config.attention_dropout,
+ causal=True,
+ dtype=self.dtype,
+ )
+ self.dropout_layer = nn.Dropout(rate=self.config.dropout)
+ self.activation_fn = ACT2FN[self.config.activation_function]
+ self.activation_dropout_layer = nn.Dropout(rate=self.config.activation_dropout)
+
+ self.self_attn_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+ self.encoder_attn = FlaxWhisperAttention(
+ config=self.config,
+ embed_dim=self.embed_dim,
+ num_heads=self.config.decoder_attention_heads,
+ dropout=self.config.attention_dropout,
+ dtype=self.dtype,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+ self.fc1 = nn.Dense(
+ self.config.decoder_ffn_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+ self.fc2 = nn.Dense(
+ self.embed_dim, dtype=self.dtype, kernel_init=jax.nn.initializers.normal(self.config.init_std)
+ )
+ self.final_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+
+ def __call__(
+ self,
+ hidden_states: jnp.ndarray,
+ attention_mask: jnp.ndarray,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ output_attentions: bool = True,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states, attention_mask=attention_mask, init_cache=init_cache
+ )
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ )
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+class FlaxWhisperDecoderLayerCollection(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ if self.gradient_checkpointing:
+ FlaxWhisperDecoderCheckpointLayer = remat(FlaxWhisperDecoderLayer, static_argnums=(4, 5, 6))
+ self.layers = [
+ FlaxWhisperDecoderCheckpointLayer(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.decoder_layers)
+ ]
+ else:
+ self.layers = [
+ FlaxWhisperDecoderLayer(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.decoder_layers)
+ ]
+ self.layerdrop = self.config.decoder_layerdrop
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ deterministic: bool = True,
+ init_cache: bool = False,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ for decoder_layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = random.uniform(0, 1)
+ if not deterministic and (dropout_probability < self.layerdrop):
+ layer_outputs = (None, None, None)
+ else:
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ init_cache,
+ output_attentions,
+ deterministic,
+ )
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ outputs = [hidden_states, all_hidden_states, all_self_attns, all_cross_attentions]
+
+ if not return_dict:
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+class FlaxWhisperEncoder(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self) -> None:
+ self.conv1 = nn.Conv(
+ self.config.d_model,
+ kernel_size=(3,),
+ padding=1,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ dtype=self.dtype,
+ )
+ self.conv2 = nn.Conv(
+ self.config.d_model,
+ kernel_size=(3,),
+ strides=2,
+ padding=1,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ dtype=self.dtype,
+ )
+
+ self.dropout_layer = nn.Dropout(rate=self.config.dropout)
+
+ self.layers = FlaxWhisperEncoderLayerCollection(
+ self.config,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+
+ self.embed_positions = nn.Embed(
+ self.config.max_source_positions,
+ self.config.d_model,
+ dtype=self.dtype,
+ embedding_init=sinusoidal_embedding_init,
+ )
+
+ self.layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+
+ def __call__(
+ self,
+ input_features: jnp.ndarray,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ if input_features.shape[1:] != (self.config.num_mel_bins, self.config.max_source_positions * 2):
+ raise ValueError(
+ "input_features.shape[1:], must be equal to (self.config.num_mel_bins,"
+ f" self.config.max_source_positions * 2) (got {input_features.shape[1:]}, but should be"
+ f" ({self.config.num_mel_bins}, {self.config.max_source_positions * 2}))"
+ )
+
+ input_features = input_features.transpose(0, 2, 1)
+ hidden_states = jax.nn.gelu(self.conv1(input_features), approximate=False)
+ hidden_states = jax.nn.gelu(self.conv2(hidden_states), approximate=False)
+
+ embed_positions = self.embed_positions(jnp.arange(self.config.max_source_positions))
+ # freeze the sinusoidal embeddings by stopping the back-prop
+ embed_positions = jax.lax.stop_gradient(embed_positions)
+ hidden_states = hidden_states + embed_positions
+
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+
+ outputs = self.layers(
+ hidden_states,
+ attention_mask=None,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_states = outputs[0]
+ last_hidden_states = self.layer_norm(last_hidden_states)
+
+ # update the last element in `hidden_states` after applying `layernorm` above
+ hidden_states = None
+ if output_hidden_states:
+ hidden_states = outputs[1]
+ hidden_states = hidden_states[:-1] + (last_hidden_states,)
+
+ if not return_dict:
+ outputs = (last_hidden_states, hidden_states) + (outputs[2:] if output_hidden_states else outputs[1:])
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutput(
+ last_hidden_state=last_hidden_states,
+ hidden_states=hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class FlaxWhisperDecoder(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self) -> None:
+ self.embed_tokens = nn.Embed(self.config.vocab_size, self.config.d_model, dtype=self.dtype)
+ self.embed_positions = nn.Embed(self.config.max_target_positions, self.config.d_model, dtype=self.dtype)
+
+ self.layers = FlaxWhisperDecoderLayerCollection(
+ self.config, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+
+ self.dropout_layer = nn.Dropout(rate=self.config.dropout)
+
+ self.layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-5)
+
+ def __call__(
+ self,
+ input_ids: jnp.ndarray,
+ attention_mask: jnp.ndarray,
+ position_ids: jnp.ndarray,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ input_embeds = self.embed_tokens(input_ids)
+ position_embeds = self.embed_positions(position_ids)
+
+ hidden_states = input_embeds + position_embeds
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+
+ outputs = self.layers(
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ deterministic=deterministic,
+ init_cache=init_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_states = outputs[0]
+ last_hidden_states = self.layer_norm(last_hidden_states)
+
+ # update the last element in `hidden_states` after applying `layernorm` above
+ hidden_states = None
+ if output_hidden_states:
+ hidden_states = outputs[1]
+ hidden_states = hidden_states[:-1] + (last_hidden_states,)
+
+ if not return_dict:
+ outputs = (last_hidden_states, hidden_states) + (outputs[2:] if output_hidden_states else outputs[1:])
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=last_hidden_states,
+ hidden_states=hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+class FlaxWhisperModule(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self) -> None:
+ self.encoder = FlaxWhisperEncoder(
+ self.config, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+ self.decoder = FlaxWhisperDecoder(
+ self.config, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+
+ def __call__(
+ self,
+ input_features: jnp.ndarray,
+ decoder_input_ids: jnp.ndarray,
+ decoder_attention_mask: jnp.ndarray,
+ decoder_position_ids: jnp.ndarray,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ):
+ encoder_outputs = self.encoder(
+ input_features,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ encoder_hidden_states=encoder_outputs[0],
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return FlaxSeq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def _get_encoder_module(self):
+ return self.encoder
+
+ def _get_decoder_module(self):
+ return self.decoder
+
+
+class FlaxWhisperPreTrainedModel(FlaxPreTrainedModel):
+ config_class = WhisperConfig
+ base_model_prefix: str = "model"
+ main_input_name = "input_features"
+ module_class: nn.Module = None
+
+ def __init__(
+ self,
+ config: WhisperConfig,
+ input_shape: Optional[tuple[int]] = None,
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ gradient_checkpointing: bool = False,
+ **kwargs,
+ ):
+ module = self.module_class(config=config, dtype=dtype, gradient_checkpointing=gradient_checkpointing, **kwargs)
+ if input_shape is None:
+ input_shape = (1, config.num_mel_bins, 2 * config.max_source_positions)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ def enable_gradient_checkpointing(self):
+ self._module = self.module_class(
+ config=self.config,
+ dtype=self.dtype,
+ gradient_checkpointing=True,
+ )
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensors
+ input_features = jnp.zeros(input_shape, dtype="f4")
+ input_features = input_features.at[(..., -1)].set(self.config.eos_token_id)
+
+ decoder_input_ids = jnp.zeros((input_shape[0], 1), dtype="i4")
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+
+ batch_size, sequence_length = decoder_input_ids.shape
+ decoder_position_ids = jnp.broadcast_to(jnp.arange(sequence_length)[None, :], (batch_size, sequence_length))
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(
+ rngs,
+ input_features=input_features,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ )["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ # Copied from transformers.models.bart.modeling_flax_bart.FlaxBartPreTrainedModel.init_cache with Bart->Whisper
+ def init_cache(self, batch_size, max_length, encoder_outputs):
+ r"""
+ Args:
+ batch_size (`int`):
+ batch_size used for fast auto-regressive decoding. Defines the batch size of the initialized cache.
+ max_length (`int`):
+ maximum possible length for auto-regressive decoding. Defines the sequence length of the initialized
+ cache.
+ encoder_outputs (`Union[FlaxBaseModelOutput, tuple(tuple(jnp.ndarray)]`):
+ `encoder_outputs` consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*:
+ `attentions`). `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*)
+ is a sequence of hidden-states at the output of the last layer of the encoder. Used in the
+ cross-attention of the decoder.
+ """
+ # init input variables to retrieve cache
+ decoder_input_ids = jnp.ones((batch_size, max_length), dtype="i4")
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(jnp.atleast_2d(decoder_input_ids).shape[-1]), decoder_input_ids.shape
+ )
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, decoder_position_ids, **kwargs):
+ decoder_module = module._get_decoder_module()
+ return decoder_module(
+ decoder_input_ids,
+ decoder_attention_mask,
+ decoder_position_ids,
+ **kwargs,
+ )
+
+ init_variables = self.module.init(
+ jax.random.PRNGKey(0),
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ encoder_hidden_states=encoder_outputs[0],
+ init_cache=True,
+ method=_decoder_forward, # we only need to call the decoder to init the cache
+ )
+ return unfreeze(init_variables["cache"])
+
+ @add_start_docstrings(WHISPER_ENCODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxBaseModelOutput, config_class=WhisperConfig)
+ def encode(
+ self,
+ input_features: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ **kwargs,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import WhisperProcessor, FlaxWhisperForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> processor = WhisperProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = FlaxWhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en", from_pt=True)
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = processor(ds[0]["audio"]["array"], return_tensors="np")
+ >>> input_features = inputs.input_features
+ >>> encoder_outputs = model.encode(input_features=input_features)
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ def _encoder_forward(module, input_features, **kwargs):
+ encode_module = module._get_encoder_module()
+ return encode_module(input_features, **kwargs)
+
+ return self.module.apply(
+ {"params": params or self.params},
+ input_features=jnp.array(input_features, dtype="f4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ method=_encoder_forward,
+ )
+
+ @add_start_docstrings(WHISPER_DECODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxBaseModelOutputWithPastAndCrossAttentions, config_class=WhisperConfig)
+ def decode(
+ self,
+ decoder_input_ids,
+ encoder_outputs,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_position_ids: Optional[jnp.ndarray] = None,
+ past_key_values: Optional[dict] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import WhisperProcessor, FlaxWhisperForConditionalGeneration
+ >>> from datasets import load_dataset
+ >>> import jax.numpy as jnp
+
+ >>> processor = WhisperProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = FlaxWhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en", from_pt=True)
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> input_features = processor(ds[0]["audio"]["array"], return_tensors="np").input_features
+
+ >>> encoder_outputs = model.encode(input_features=input_features)
+ >>> decoder_start_token_id = model.config.decoder_start_token_id
+
+ >>> decoder_input_ids = jnp.ones((input_features.shape[0], 1), dtype="i4") * decoder_start_token_id
+
+ >>> outputs = model.decode(decoder_input_ids, encoder_outputs)
+ >>> last_decoder_hidden_states = outputs.last_hidden_state
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ batch_size, sequence_length = decoder_input_ids.shape
+ if decoder_position_ids is None:
+ if past_key_values is not None:
+ raise ValueError("Make sure to provide `decoder_position_ids` when passing `past_key_values`.")
+
+ if decoder_attention_mask is not None:
+ decoder_position_ids = (decoder_attention_mask.cumsum(-1) * decoder_attention_mask) - 1
+ else:
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(sequence_length)[None, :], (batch_size, sequence_length)
+ )
+
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ inputs = {"params": params or self.params}
+
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be
+ # passed down to ensure cache is used. It has to be made sure that cache is marked as mutable so that
+ # it can be changed by FlaxWhisperAttention module
+ if past_key_values:
+ inputs["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, decoder_position_ids, **kwargs):
+ decoder_module = module._get_decoder_module()
+ return decoder_module(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ **kwargs,
+ )
+
+ outputs = self.module.apply(
+ inputs,
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ decoder_position_ids=jnp.array(decoder_position_ids, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ mutable=mutable,
+ method=_decoder_forward,
+ )
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs, past = outputs
+ outputs["past_key_values"] = unfreeze(past["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs, past = outputs
+ outputs = outputs[:1] + (unfreeze(past["cache"]),) + outputs[1:]
+
+ return outputs
+
+ @add_start_docstrings_to_model_forward(WHISPER_INPUTS_DOCSTRING)
+ def __call__(
+ self,
+ input_features: jnp.ndarray,
+ decoder_input_ids: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ position_ids: Optional[jnp.ndarray] = None,
+ decoder_position_ids: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # prepare decoder inputs
+ if decoder_position_ids is None:
+ if decoder_attention_mask is not None:
+ decoder_position_ids = (decoder_attention_mask.cumsum(-1) * decoder_attention_mask) - 1
+ else:
+ batch_size, sequence_length = decoder_input_ids.shape
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(sequence_length)[None, :], (batch_size, sequence_length)
+ )
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones_like(decoder_input_ids)
+
+ # Handle any PRNG if needed
+ rngs = {"dropout": dropout_rng} if dropout_rng is not None else {}
+
+ return self.module.apply(
+ {"params": params or self.params},
+ input_features=jnp.array(input_features, dtype="f4"),
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ decoder_position_ids=jnp.array(decoder_position_ids, dtype="i4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ )
+
+
+@add_start_docstrings(
+ "The bare Whisper Model transformer outputting raw hidden-states without any specific head on top.",
+ WHISPER_START_DOCSTRING,
+)
+class FlaxWhisperModel(FlaxWhisperPreTrainedModel):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ module_class = FlaxWhisperModule
+
+
+append_call_sample_docstring(FlaxWhisperModel, _CHECKPOINT_FOR_DOC, FlaxSeq2SeqModelOutput, _CONFIG_FOR_DOC)
+
+
+class FlaxWhisperForConditionalGenerationModule(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self) -> None:
+ self.model = FlaxWhisperModule(
+ config=self.config, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+ self.lm_head = nn.Dense(
+ self.config.vocab_size,
+ use_bias=False,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+
+ def _get_encoder_module(self):
+ return self.model.encoder
+
+ def _get_decoder_module(self):
+ return self.model.decoder
+
+ def __call__(
+ self,
+ input_features,
+ decoder_input_ids,
+ decoder_attention_mask: jnp.ndarray = None,
+ decoder_position_ids: jnp.ndarray = None,
+ position_ids: jnp.ndarray = None,
+ attention_mask: jnp.ndarray = None,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ):
+ outputs = self.model(
+ input_features=input_features,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=deterministic,
+ )
+
+ hidden_states = outputs[0]
+
+ if self.config.tie_word_embeddings:
+ shared_embedding = self.model.decoder.embed_tokens.variables["params"]["embedding"]
+ lm_logits = self.lm_head.apply({"params": {"kernel": shared_embedding.T}}, hidden_states)
+ else:
+ lm_logits = self.lm_head(hidden_states)
+
+ if not return_dict:
+ output = (lm_logits,) + outputs[1:]
+ return output
+
+ return FlaxSeq2SeqLMOutput(
+ logits=lm_logits,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+
+@add_start_docstrings("The Whisper Model with a language modeling head.", WHISPER_START_DOCSTRING)
+class FlaxWhisperForConditionalGeneration(FlaxWhisperPreTrainedModel):
+ module_class = FlaxWhisperForConditionalGenerationModule
+ dtype: jnp.dtype = jnp.float32
+
+ @add_start_docstrings(WHISPER_DECODE_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=FlaxCausalLMOutputWithCrossAttentions, config_class=WhisperConfig)
+ def decode(
+ self,
+ decoder_input_ids,
+ encoder_outputs,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_attention_mask: Optional[jnp.ndarray] = None,
+ decoder_position_ids: Optional[jnp.ndarray] = None,
+ past_key_values: Optional[dict] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> from transformers import WhisperProcessor, FlaxWhisperForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> processor = WhisperProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = FlaxWhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en", from_pt=True)
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = processor(ds[0]["audio"]["array"], return_tensors="np")
+ >>> input_features = inputs.input_features
+ >>> encoder_outputs = model.encode(input_features=input_features)
+ >>> decoder_start_token_id = model.config.decoder_start_token_id
+
+ >>> decoder_input_ids = jnp.ones((inputs.input_ids.shape[0], 1), dtype="i4") * decoder_start_token_id
+
+ >>> outputs = model.decode(decoder_input_ids, encoder_outputs)
+ >>> last_decoder_hidden_states = outputs.last_hidden_state
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ encoder_hidden_states = encoder_outputs[0]
+
+ batch_size, sequence_length = decoder_input_ids.shape
+ if decoder_position_ids is None:
+ if past_key_values is not None:
+ raise ValueError("Make sure to provide `decoder_position_ids` when passing `past_key_values`.")
+
+ if decoder_attention_mask is not None:
+ decoder_position_ids = (decoder_attention_mask.cumsum(-1) * decoder_attention_mask) - 1
+ else:
+ decoder_position_ids = jnp.broadcast_to(
+ jnp.arange(sequence_length)[None, :], (batch_size, sequence_length)
+ )
+ if decoder_attention_mask is None:
+ decoder_attention_mask = jnp.ones((batch_size, sequence_length), dtype="i4")
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ inputs = {"params": params or self.params}
+
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be
+ # passed down to ensure cache is used. It has to be made sure that cache is marked as mutable so that
+ # it can be changed by FlaxWhisperAttention module
+ if past_key_values:
+ inputs["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ def _decoder_forward(module, decoder_input_ids, decoder_attention_mask, decoder_position_ids, **kwargs):
+ decoder_module = module._get_decoder_module()
+ outputs = decoder_module(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ **kwargs,
+ )
+ hidden_states = outputs[0]
+
+ if self.config.tie_word_embeddings:
+ shared_embedding = module.model.decoder.embed_tokens.variables["params"]["embedding"]
+ lm_logits = module.lm_head.apply({"params": {"kernel": shared_embedding.T}}, hidden_states)
+ else:
+ lm_logits = module.lm_head(hidden_states)
+
+ return lm_logits, outputs
+
+ outputs = self.module.apply(
+ inputs,
+ decoder_input_ids=jnp.array(decoder_input_ids, dtype="i4"),
+ decoder_attention_mask=jnp.array(decoder_attention_mask, dtype="i4"),
+ decoder_position_ids=jnp.array(decoder_position_ids, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ mutable=mutable,
+ method=_decoder_forward,
+ )
+
+ if past_key_values is None:
+ lm_logits, decoder_outputs = outputs
+ else:
+ (lm_logits, decoder_outputs), past = outputs
+
+ if return_dict:
+ outputs = FlaxCausalLMOutputWithCrossAttentions(
+ logits=lm_logits,
+ hidden_states=decoder_outputs.hidden_states,
+ attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ )
+ else:
+ outputs = (lm_logits,) + decoder_outputs[1:]
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs["past_key_values"] = unfreeze(past["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs = outputs[:1] + (unfreeze(past["cache"]),) + outputs[1:]
+
+ return outputs
+
+ def generate(
+ self,
+ input_features,
+ generation_config=None,
+ logits_processor=None,
+ return_timestamps=None,
+ task=None,
+ language=None,
+ is_multilingual=None,
+ **kwargs,
+ ):
+ if generation_config is None:
+ generation_config = self.generation_config
+
+ if return_timestamps is not None:
+ generation_config.return_timestamps = return_timestamps
+
+ if task is not None:
+ generation_config.task = task
+
+ if is_multilingual is not None:
+ generation_config.is_multilingual = is_multilingual
+
+ if language is not None:
+ generation_config.language = language
+
+ if kwargs is not None and "decoder_input_ids" in kwargs:
+ decoder_input_length = len(kwargs["decoder_input_ids"])
+ else:
+ decoder_input_length = 1
+
+ forced_decoder_ids = []
+
+ if hasattr(generation_config, "is_multilingual") and generation_config.is_multilingual:
+ if hasattr(generation_config, "language"):
+ forced_decoder_ids.append((1, generation_config.lang_to_id[generation_config.language]))
+ else:
+ forced_decoder_ids.append((1, None))
+
+ if hasattr(generation_config, "task"):
+ forced_decoder_ids.append((2, generation_config.task_to_id[generation_config.task]))
+ else:
+ forced_decoder_ids.append((2, generation_config.task_to_id["transcribe"]))
+
+ if (
+ hasattr(generation_config, "return_timestamps") and generation_config.return_timestamps
+ ) or return_timestamps:
+ logits_processor = [
+ FlaxWhisperTimeStampLogitsProcessor(generation_config, self.config, decoder_input_length)
+ ]
+ else:
+ if forced_decoder_ids and forced_decoder_ids[-1][0] != generation_config.no_timestamps_token_id:
+ idx = forced_decoder_ids[-1][0] + 1 if forced_decoder_ids else 1
+ forced_decoder_ids.append((idx, generation_config.no_timestamps_token_id))
+
+ if len(forced_decoder_ids) > 0:
+ generation_config.forced_decoder_ids = forced_decoder_ids
+
+ return super().generate(
+ input_features,
+ generation_config,
+ logits_processor=logits_processor,
+ **kwargs,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ decoder_input_ids,
+ max_length,
+ attention_mask: Optional[jax.Array] = None,
+ decoder_attention_mask: Optional[jax.Array] = None,
+ encoder_outputs=None,
+ **kwargs,
+ ):
+ # initializing the cache
+ batch_size, seq_length = decoder_input_ids.shape
+
+ past_key_values = self.init_cache(batch_size, max_length, encoder_outputs)
+ # Note that usually one would have to put 0's in the attention_mask for x > input_ids.shape[-1] and x < cache_length.
+ # But since the decoder uses a causal mask, those positions are masked anyways.
+ # Thus we can create a single static attention_mask here, which is more efficient for compilation
+ extended_attention_mask = jnp.ones((batch_size, max_length), dtype="i4")
+ if decoder_attention_mask is not None:
+ position_ids = decoder_attention_mask.cumsum(-1) - 1
+ extended_attention_mask = lax.dynamic_update_slice(extended_attention_mask, decoder_attention_mask, (0, 0))
+ else:
+ position_ids = jnp.broadcast_to(jnp.arange(seq_length, dtype="i4")[None, :], (batch_size, seq_length))
+
+ return {
+ "past_key_values": past_key_values,
+ "encoder_outputs": encoder_outputs,
+ "encoder_attention_mask": attention_mask,
+ "decoder_attention_mask": extended_attention_mask,
+ "decoder_position_ids": position_ids,
+ }
+
+ def update_inputs_for_generation(self, model_outputs, model_kwargs):
+ model_kwargs["past_key_values"] = model_outputs.past_key_values
+ model_kwargs["decoder_position_ids"] = model_kwargs["decoder_position_ids"][:, -1:] + 1
+ return model_kwargs
+
+
+FLAX_WHISPER_CONDITIONAL_GENERATION_DOCSTRING = r"""
+ Returns:
+
+ Transcription example:
+
+ ```python
+ >>> from transformers import WhisperProcessor, FlaxWhisperForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> processor = WhisperProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = FlaxWhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en", from_pt=True)
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = processor(ds[0]["audio"]["array"], return_tensors="np")
+ >>> input_features = inputs.input_features
+ >>> generated_ids = model.generate(input_ids=input_features)
+ >>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+ >>> transcription
+ ' Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel.'
+ ```
+"""
+
+overwrite_call_docstring(
+ FlaxWhisperForConditionalGeneration, WHISPER_INPUTS_DOCSTRING + FLAX_WHISPER_CONDITIONAL_GENERATION_DOCSTRING
+)
+append_replace_return_docstrings(
+ FlaxWhisperForConditionalGeneration, output_type=FlaxSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC
+)
+
+
+class FlaxWhisperForAudioClassificationModule(nn.Module):
+ config: WhisperConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self) -> None:
+ self.encoder = FlaxWhisperEncoder(
+ config=self.config, dtype=self.dtype, gradient_checkpointing=self.gradient_checkpointing
+ )
+ self.config.is_encoder_decoder = False
+ num_layers = self.config.num_hidden_layers + 1
+ if self.config.use_weighted_layer_sum:
+ self.layer_weights = jnp.repeat(1 / num_layers, num_layers)
+ self.projector = nn.Dense(self.config.classifier_proj_size, dtype=self.dtype)
+ self.classifier = nn.Dense(self.config.num_labels, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_features,
+ encoder_outputs=None,
+ output_attentions=None,
+ output_hidden_states: bool = True,
+ return_dict: bool = True,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_features,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = jnp.stack(encoder_outputs, axis=1)
+ norm_weights = jax.nn.softmax(self.layer_weights, axis=-1)
+ hidden_states = jnp.sum(hidden_states * jnp.reshape(norm_weights, [-1, 1, 1]), axis=1)
+ else:
+ hidden_states = encoder_outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ pooled_output = jnp.mean(hidden_states, axis=1)
+
+ logits = self.classifier(pooled_output)
+
+ if not return_dict:
+ return (logits,) + encoder_outputs[1:]
+
+ return FlaxSequenceClassifierOutput(
+ logits=logits,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+@add_start_docstrings("The Whisper Model with an audio classification head on top.", WHISPER_START_DOCSTRING)
+class FlaxWhisperForAudioClassification(FlaxWhisperPreTrainedModel):
+ module_class = FlaxWhisperForAudioClassificationModule
+ dtype: jnp.dtype = jnp.float32
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensors
+ input_features = jnp.zeros(input_shape, dtype="f4")
+ input_features = input_features.at[(..., -1)].set(self.config.eos_token_id)
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ random_params = self.module.init(
+ rngs,
+ input_features=input_features,
+ )["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ @add_start_docstrings_to_model_forward(WHISPER_INPUTS_DOCSTRING)
+ def __call__(
+ self,
+ input_features: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ **kwargs,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ return self.module.apply(
+ {"params": params or self.params},
+ input_features=jnp.array(input_features, dtype="f4"),
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ rngs=rngs,
+ )
+
+
+FLAX_WHISPER_AUDIO_CLASSIFICATION_DOCSTRING = r"""
+ Returns:
+
+ Transcription example:
+
+ ```python
+ >>> import jax.numpy as jnp
+ >>> from transformers import AutoFeatureExtractor, FlaxWhisperForAudioClassification
+ >>> from datasets import load_dataset
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("sanchit-gandhi/whisper-medium-fleurs-lang-id")
+ >>> model = FlaxWhisperForAudioClassification.from_pretrained(
+ ... "sanchit-gandhi/whisper-medium-fleurs-lang-id", from_pt=True
+ ... )
+ >>> ds = load_dataset("google/fleurs", "all", split="validation", streaming=True)
+
+ >>> sample = next(iter(ds))
+
+ >>> inputs = feature_extractor(
+ ... sample["audio"]["array"], sampling_rate=sample["audio"]["sampling_rate"], return_tensors="np"
+ ... )
+ >>> input_features = inputs.input_features
+
+ >>> logits = model(input_features).logits
+
+ >>> predicted_class_ids = jnp.argmax(logits).item()
+ >>> predicted_label = model.config.id2label[predicted_class_ids]
+ >>> predicted_label
+ 'af_za'
+ ```
+"""
+
+overwrite_call_docstring(
+ FlaxWhisperForAudioClassification, WHISPER_INPUTS_DOCSTRING + FLAX_WHISPER_AUDIO_CLASSIFICATION_DOCSTRING
+)
+append_replace_return_docstrings(
+ FlaxWhisperForAudioClassification, output_type=FlaxSequenceClassifierOutput, config_class=_CONFIG_FOR_DOC
+)
+
+
+__all__ = [
+ "FlaxWhisperForConditionalGeneration",
+ "FlaxWhisperModel",
+ "FlaxWhisperPreTrainedModel",
+ "FlaxWhisperForAudioClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_tf_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_tf_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..c768db3c3070438347eaa63571e657e078fc3824
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_tf_whisper.py
@@ -0,0 +1,1754 @@
+# coding=utf-8
+# Copyright 2022 The OpenAI Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TensorFlow Whisper model."""
+
+from __future__ import annotations
+
+import math
+import random
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...generation.configuration_utils import GenerationConfig
+from ...generation.tf_logits_process import TFLogitsProcessorList
+from ...modeling_tf_outputs import (
+ TFBaseModelOutput,
+ TFBaseModelOutputWithPastAndCrossAttentions,
+ TFSeq2SeqLMOutput,
+ TFSeq2SeqModelOutput,
+)
+from ...modeling_tf_utils import (
+ TFCausalLanguageModelingLoss,
+ TFModelInputType,
+ TFPreTrainedModel,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging, replace_return_docstrings
+from .configuration_whisper import WhisperConfig
+from .tokenization_whisper import TASK_IDS, TO_LANGUAGE_CODE
+
+
+logger = logging.get_logger(__name__)
+
+_CONFIG_FOR_DOC = "WhisperConfig"
+
+
+LARGE_NEGATIVE = -1e8
+
+
+def sinusoidal_embedding_init(shape, dtype=tf.float32) -> tf.Tensor:
+ """Returns sinusoids for positional embedding"""
+ length, channels = shape
+ if channels % 2 != 0:
+ raise ValueError(
+ f"Number of channels has to be divisible by 2 for sinusoidal positional embeddings, got {channels} channels."
+ )
+ log_timescale_increment = math.log(10000) / (channels // 2 - 1)
+ inv_timescales = tf.exp(-log_timescale_increment * tf.range(channels // 2, dtype=tf.float32))
+ scaled_time = tf.reshape(tf.range(length, dtype=tf.float32), (-1, 1)) * tf.reshape(inv_timescales, (1, -1))
+ return tf.cast(tf.concat([tf.sin(scaled_time), tf.cos(scaled_time)], axis=1), dtype)
+
+
+# Copied from transformers.models.bart.modeling_tf_bart.shift_tokens_right
+def shift_tokens_right(input_ids: tf.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ pad_token_id = tf.cast(pad_token_id, input_ids.dtype)
+ decoder_start_token_id = tf.cast(decoder_start_token_id, input_ids.dtype)
+ start_tokens = tf.fill(
+ (shape_list(input_ids)[0], 1), tf.convert_to_tensor(decoder_start_token_id, input_ids.dtype)
+ )
+ shifted_input_ids = tf.concat([start_tokens, input_ids[:, :-1]], -1)
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids = tf.where(
+ shifted_input_ids == -100,
+ tf.fill(shape_list(shifted_input_ids), tf.convert_to_tensor(pad_token_id, input_ids.dtype)),
+ shifted_input_ids,
+ )
+
+ # "Verify that `labels` has only positive values and -100"
+ assert_gte0 = tf.debugging.assert_greater_equal(shifted_input_ids, tf.constant(0, dtype=input_ids.dtype))
+
+ # Make sure the assertion op is called by wrapping the result in an identity no-op
+ with tf.control_dependencies([assert_gte0]):
+ shifted_input_ids = tf.identity(shifted_input_ids)
+
+ return shifted_input_ids
+
+
+# Copied from transformers.models.bart.modeling_tf_bart._make_causal_mask
+def _make_causal_mask(input_ids_shape: tf.TensorShape, past_key_values_length: int = 0):
+ """
+ Make causal mask used for bi-directional self-attention.
+ """
+ bsz = input_ids_shape[0]
+ tgt_len = input_ids_shape[1]
+ mask = tf.ones((tgt_len, tgt_len)) * LARGE_NEGATIVE
+ mask_cond = tf.range(shape_list(mask)[-1])
+
+ mask = tf.where(mask_cond < tf.reshape(mask_cond + 1, (shape_list(mask)[-1], 1)), 0.0, mask)
+
+ if past_key_values_length > 0:
+ mask = tf.concat([tf.zeros((tgt_len, past_key_values_length)), mask], axis=-1)
+
+ return tf.tile(mask[None, None, :, :], (bsz, 1, 1, 1))
+
+
+# Copied from transformers.models.bart.modeling_tf_bart._expand_mask
+def _expand_mask(mask: tf.Tensor, tgt_len: int | None = None):
+ """
+ Expands attention_mask from `[bsz, seq_len]` to `[bsz, 1, tgt_seq_len, src_seq_len]`.
+ """
+ src_len = shape_list(mask)[1]
+ tgt_len = tgt_len if tgt_len is not None else src_len
+ one_cst = tf.constant(1.0)
+ mask = tf.cast(mask, dtype=one_cst.dtype)
+ expanded_mask = tf.tile(mask[:, None, None, :], (1, 1, tgt_len, 1))
+
+ return (one_cst - expanded_mask) * LARGE_NEGATIVE
+
+
+class TFWhisperPositionalEmbedding(keras.layers.Layer):
+ def __init__(
+ self,
+ num_positions: int,
+ embedding_dim: int,
+ padding_idx: int | None = None,
+ embedding_initializer=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.num_positions = num_positions
+ self.embedding_dim = embedding_dim
+ self.padding_idx = padding_idx
+ self.embedding_initializer = keras.initializers.get(embedding_initializer)
+
+ def build(self, input_shape):
+ self.weight = self.add_weight(
+ name="weight",
+ shape=[self.num_positions, self.embedding_dim],
+ initializer=self.embedding_initializer,
+ trainable=True,
+ )
+ super().build(input_shape)
+
+ def call(self, input_ids, past_key_values_length=0):
+ past_key_values_length = tf.cast(past_key_values_length, tf.int32)
+ gather_indices = tf.range(tf.shape(input_ids)[1], delta=1) + past_key_values_length
+ return tf.gather(self.weight, gather_indices)
+
+
+class TFWhisperAttention(keras.layers.Layer):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = keras.layers.Dropout(dropout)
+ self.head_dim = embed_dim // num_heads
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+
+ self.k_proj = keras.layers.Dense(embed_dim, use_bias=False, name="k_proj")
+ self.v_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="v_proj")
+ self.q_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="q_proj")
+ self.out_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="out_proj")
+
+ # Copied from transformers.models.bart.modeling_tf_bart.TFBartAttention._shape with BART->whisper
+ def _shape(self, tensor: tf.Tensor, seq_len: int, bsz: int):
+ return tf.transpose(tf.reshape(tensor, (bsz, seq_len, self.num_heads, self.head_dim)), (0, 2, 1, 3))
+
+ # Copied from transformers.models.bart.modeling_tf_bart.TFBartAttention.call with BART->whisper
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ key_value_states: tf.Tensor | None = None,
+ past_key_value: tuple[tuple[tf.Tensor]] | None = None,
+ attention_mask: tf.Tensor | None = None,
+ layer_head_mask: tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> tuple[tf.Tensor, tf.Tensor | None]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ bsz, tgt_len, embed_dim = shape_list(hidden_states)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+ # get key, value proj
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_states = past_key_value[0]
+ value_states = past_key_value[1]
+ elif is_cross_attention:
+ # cross_attentions
+ key_states = self._shape(self.k_proj(key_value_states), -1, bsz)
+ value_states = self._shape(self.v_proj(key_value_states), -1, bsz)
+ elif past_key_value is not None:
+ # reuse k, v, self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+ key_states = tf.concat([past_key_value[0], key_states], axis=2)
+ value_states = tf.concat([past_key_value[1], value_states], axis=2)
+ else:
+ # self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(tf.Tensor, tf.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(tf.Tensor, tf.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_states, value_states)
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = tf.reshape(self._shape(query_states, tgt_len, bsz), proj_shape)
+ key_states = tf.reshape(key_states, proj_shape)
+ value_states = tf.reshape(value_states, proj_shape)
+
+ src_len = shape_list(key_states)[1]
+ attn_weights = tf.matmul(query_states, key_states, transpose_b=True)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_weights),
+ [bsz * self.num_heads, tgt_len, src_len],
+ message=(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {shape_list(attn_weights)}"
+ ),
+ )
+
+ if attention_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(attention_mask),
+ [bsz, 1, tgt_len, src_len],
+ message=(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is"
+ f" {shape_list(attention_mask)}"
+ ),
+ )
+
+ attention_mask = tf.cast(attention_mask, dtype=attn_weights.dtype)
+ attn_weights = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len)) + attention_mask
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_weights = stable_softmax(attn_weights, axis=-1)
+
+ if layer_head_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(layer_head_mask),
+ [self.num_heads],
+ message=(
+ f"Head mask for a single layer should be of size {(self.num_heads)}, but is"
+ f" {shape_list(layer_head_mask)}"
+ ),
+ )
+
+ attn_weights = tf.reshape(layer_head_mask, (1, -1, 1, 1)) * tf.reshape(
+ attn_weights, (bsz, self.num_heads, tgt_len, src_len)
+ )
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_probs = self.dropout(attn_weights, training=training)
+ attn_output = tf.matmul(attn_probs, value_states)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_output),
+ [bsz * self.num_heads, tgt_len, self.head_dim],
+ message=(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {shape_list(attn_output)}"
+ ),
+ )
+
+ attn_output = tf.transpose(
+ tf.reshape(attn_output, (bsz, self.num_heads, tgt_len, self.head_dim)), (0, 2, 1, 3)
+ )
+ attn_output = tf.reshape(attn_output, (bsz, tgt_len, embed_dim))
+
+ attn_output = self.out_proj(attn_output)
+ attn_weights: tf.Tensor = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len))
+
+ return attn_output, attn_weights, past_key_value
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "k_proj", None) is not None:
+ with tf.name_scope(self.k_proj.name):
+ self.k_proj.build([None, None, self.embed_dim])
+ if getattr(self, "v_proj", None) is not None:
+ with tf.name_scope(self.v_proj.name):
+ self.v_proj.build([None, None, self.embed_dim])
+ if getattr(self, "q_proj", None) is not None:
+ with tf.name_scope(self.q_proj.name):
+ self.q_proj.build([None, None, self.embed_dim])
+ if getattr(self, "out_proj", None) is not None:
+ with tf.name_scope(self.out_proj.name):
+ self.out_proj.build([None, None, self.embed_dim])
+
+
+# Copied from transformers.models.speech_to_text.modeling_tf_speech_to_text.TFSpeech2TextEncoderLayer with Speech2Text->Whisper
+class TFWhisperEncoderLayer(keras.layers.Layer):
+ def __init__(self, config: WhisperConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.embed_dim = config.d_model
+ self.self_attn = TFWhisperAttention(
+ self.embed_dim, config.encoder_attention_heads, dropout=config.attention_dropout, name="self_attn"
+ )
+ self.self_attn_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="self_attn_layer_norm")
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.activation_fn = get_tf_activation(config.activation_function)
+ self.activation_dropout = keras.layers.Dropout(config.activation_dropout)
+ self.fc1 = keras.layers.Dense(config.encoder_ffn_dim, name="fc1")
+ self.fc2 = keras.layers.Dense(self.embed_dim, name="fc2")
+ self.final_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="final_layer_norm")
+ self.config = config
+
+ def call(
+ self, hidden_states: tf.Tensor, attention_mask: tf.Tensor, layer_head_mask: tf.Tensor, training: bool = False
+ ):
+ """
+ Args:
+ hidden_states (`tf.Tensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`tf.Tensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`tf.Tensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, self_attn_weights, _ = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ training=training,
+ )
+
+ tf.debugging.assert_equal(
+ shape_list(hidden_states),
+ shape_list(residual),
+ message=f"Self attn modified the shape of query {shape_list(residual)} to {shape_list(hidden_states)}",
+ )
+
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout(hidden_states, training=training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ return hidden_states, self_attn_weights
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attn", None) is not None:
+ with tf.name_scope(self.self_attn.name):
+ self.self_attn.build(None)
+ if getattr(self, "self_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.self_attn_layer_norm.name):
+ self.self_attn_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "fc1", None) is not None:
+ with tf.name_scope(self.fc1.name):
+ self.fc1.build([None, None, self.embed_dim])
+ if getattr(self, "fc2", None) is not None:
+ with tf.name_scope(self.fc2.name):
+ self.fc2.build([None, None, self.config.encoder_ffn_dim])
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build([None, None, self.embed_dim])
+
+
+# Copied from transformers.models.speech_to_text.modeling_tf_speech_to_text.TFSpeech2TextDecoderLayer with Speech2Text->Whisper
+class TFWhisperDecoderLayer(keras.layers.Layer):
+ def __init__(self, config: WhisperConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.embed_dim = config.d_model
+
+ self.self_attn = TFWhisperAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ name="self_attn",
+ is_decoder=True,
+ )
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.activation_fn = get_tf_activation(config.activation_function)
+ self.activation_dropout = keras.layers.Dropout(config.activation_dropout)
+
+ self.self_attn_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="self_attn_layer_norm")
+ self.encoder_attn = TFWhisperAttention(
+ self.embed_dim,
+ config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ name="encoder_attn",
+ is_decoder=True,
+ )
+ self.encoder_attn_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="encoder_attn_layer_norm")
+ self.fc1 = keras.layers.Dense(config.decoder_ffn_dim, name="fc1")
+ self.fc2 = keras.layers.Dense(self.embed_dim, name="fc2")
+ self.final_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="final_layer_norm")
+ self.config = config
+
+ def call(
+ self,
+ hidden_states,
+ attention_mask: tf.Tensor | None = None,
+ encoder_hidden_states: tf.Tensor | None = None,
+ encoder_attention_mask: tf.Tensor | None = None,
+ layer_head_mask: tf.Tensor | None = None,
+ cross_attn_layer_head_mask: tf.Tensor | None = None,
+ past_key_value: tuple[tf.Tensor] | None = None,
+ training=False,
+ ) -> tuple[tf.Tensor, tf.Tensor, tuple[tuple[tf.Tensor]]]:
+ """
+ Args:
+ hidden_states (`tf.Tensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`tf.Tensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`tf.Tensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`tf.Tensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`tf.Tensor`): mask for attention heads in a given layer of size
+ `(decoder_attention_heads,)`
+ cross_attn_layer_head_mask (`tf.Tensor`): mask for heads of the cross-attention module.
+ `(decoder_attention_heads,)`
+ past_key_value (`Tuple(tf.Tensor)`): cached past key and value projection states
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ # decoder uni-directional self-attention cached key/values tuple is at positions 1,2
+ self_attn_past_key_value = past_key_value[:2] if past_key_value is not None else None
+ # add present self-attn cache to positions 1,2 of present_key_value tuple
+ hidden_states, self_attn_weights, present_key_value = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_value=self_attn_past_key_value,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ training=training,
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_present_key_value = None
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ # cross_attn cached key/values tuple is at positions 3,4 of present_key_value tuple
+ cross_attn_past_key_value = past_key_value[-2:] if past_key_value is not None else None
+ hidden_states, cross_attn_weights, cross_attn_present_key_value = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_value=cross_attn_past_key_value,
+ training=training,
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ # add cross-attn to positions 3,4 of present_key_value tuple
+ present_key_value = present_key_value + cross_attn_present_key_value
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout(hidden_states, training=training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ return (
+ hidden_states,
+ self_attn_weights,
+ cross_attn_weights,
+ present_key_value,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attn", None) is not None:
+ with tf.name_scope(self.self_attn.name):
+ self.self_attn.build(None)
+ if getattr(self, "self_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.self_attn_layer_norm.name):
+ self.self_attn_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "encoder_attn", None) is not None:
+ with tf.name_scope(self.encoder_attn.name):
+ self.encoder_attn.build(None)
+ if getattr(self, "encoder_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.encoder_attn_layer_norm.name):
+ self.encoder_attn_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "fc1", None) is not None:
+ with tf.name_scope(self.fc1.name):
+ self.fc1.build([None, None, self.embed_dim])
+ if getattr(self, "fc2", None) is not None:
+ with tf.name_scope(self.fc2.name):
+ self.fc2.build([None, None, self.config.decoder_ffn_dim])
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build([None, None, self.embed_dim])
+
+
+class TFWhisperPreTrainedModel(TFPreTrainedModel):
+ config_class = WhisperConfig
+ base_model_prefix = "model"
+ main_input_name = "input_features"
+
+ def _get_feat_extract_output_lengths(self, input_lengths: tf.Tensor) -> int:
+ """
+ Computes the output length of the convolutional layers
+ """
+ input_lengths = (input_lengths - 1) // 2 + 1
+
+ return input_lengths
+
+ @property
+ def dummy_inputs(self) -> dict[str, tf.Tensor]:
+ """
+ Dummy inputs to build the network.
+
+ Returns:
+ `dict[str, tf.Tensor]`: The dummy inputs.
+ """
+ return {
+ self.main_input_name: tf.random.uniform(
+ [1, self.config.num_mel_bins, self.config.max_source_positions * 2 - 1], dtype=tf.float32
+ ),
+ "decoder_input_ids": tf.constant([[1, 3]], dtype=tf.int32),
+ }
+
+ @property
+ def input_signature(self):
+ return {
+ "input_features": tf.TensorSpec((None, self.config.num_mel_bins, None), tf.float32, name="input_features"),
+ "decoder_input_ids": tf.TensorSpec((None, None), tf.int32, name="decoder_input_ids"),
+ "decoder_attention_mask": tf.TensorSpec((None, None), tf.int32, name="decoder_attention_mask"),
+ }
+
+
+WHISPER_START_DOCSTRING = r"""
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+ Parameters:
+ config ([`WhisperConfig`]):
+ Model configuration class with all the parameters of the model. Initializing with a config file does not
+ load the weights associated with the model, only the configuration. Check out the
+ [`~TFPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+WHISPER_INPUTS_DOCSTRING = r"""
+ Args:
+ input_features (`tf.Tensor` of shape `(batch_size, feature_size, sequence_length)`):
+ Float values of fbank features extracted from the raw speech waveform. Raw speech waveform can be obtained
+ by loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a `numpy.ndarray` or a
+ `torch.Tensor`, *e.g.* via the torchcodec library (`pip install torchcodec`) or the soundfile library
+ (`pip install soundfile`).
+ To prepare the array into `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the
+ fbank features, padding and conversion into a tensor of type `tf.Tensor`.
+ See [`~WhisperFeatureExtractor.__call__`]
+ decoder_input_ids (`tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`SpeechToTextTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ SpeechToText uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`tf.Tensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+
+ If you want to change padding behavior, you should read
+ [`modeling_whisper._prepare_decoder_attention_mask`] and modify to your needs. See diagram 1 in [the
+ paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ head_mask (`tf.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in the encoder. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ decoder_head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in the decoder. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ encoder_outputs (`tuple(tuple(tf.Tensor)`, *optional*):
+ Tuple consists of (`last_hidden_state`, *optional*: `hidden_states`, *optional*: `attentions`)
+ `last_hidden_state` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) is a sequence of
+ hidden-states at the output of the last layer of the encoder. Used in the cross-attention of the decoder.
+ past_key_values (`tuple(tuple(tf.Tensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(tf.Tensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of shape
+ `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and in the cross-attention
+ blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ decoder_inputs_embeds (`tf.Tensor` of shape `(batch_size, target_sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `decoder_input_ids` you can choose to directly pass an embedded
+ representation. If `past_key_values` is used, optionally only the last `decoder_inputs_embeds` have to be
+ input (see `past_key_values`). This is useful if you want more control over how to convert
+ `decoder_input_ids` indices into associated vectors than the model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`).
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+@keras_serializable
+class TFWhisperEncoder(keras.layers.Layer):
+ config_class = WhisperConfig
+ """
+ Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a
+ [`TFWhisperEncoderLayer`].
+
+ Args:
+ config: WhisperConfig
+ embed_tokens (TFWhisperEmbedding): output embedding
+ """
+
+ def __init__(self, config: WhisperConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.layerdrop = config.encoder_layerdrop
+
+ self.embed_dim = config.d_model
+ self.num_mel_bins = config.num_mel_bins
+ self.padding_idx = config.pad_token_id
+ self.max_source_positions = config.max_source_positions
+ self.embed_scale = math.sqrt(self.embed_dim) if config.scale_embedding else 1.0
+
+ # Padding is added in call() to match the PyTorch implementation
+ self.conv1 = keras.layers.Conv1D(self.embed_dim, kernel_size=3, strides=1, padding="valid", name="conv1")
+ self.conv2 = keras.layers.Conv1D(self.embed_dim, kernel_size=3, strides=2, padding="valid", name="conv2")
+
+ self.embed_positions = TFWhisperPositionalEmbedding(
+ num_positions=self.max_source_positions,
+ embedding_dim=self.embed_dim,
+ embedding_initializer=sinusoidal_embedding_init,
+ name="embed_positions",
+ )
+ self.embed_positions.trainable = False
+
+ self.encoder_layers = [TFWhisperEncoderLayer(config, name=f"layers.{i}") for i in range(config.encoder_layers)]
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="layer_norm")
+
+ self.dropout = keras.layers.Dropout(config.dropout)
+
+ @unpack_inputs
+ def call(
+ self,
+ input_features=None,
+ head_mask=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ ):
+ r"""
+ Args:
+ input_features (`tf.Tensor` of shape `(batch_size, feature_size, sequence_length)`):
+ Float values of fbank features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a
+ `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library (`pip install torchcodec`) or
+ the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the fbank features,
+ padding and conversion into a tensor of type `tf.Tensor`. See [`~WhisperFeatureExtractor.__call__`]
+ head_mask (`tf.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # TF 2.0 layers can't use channels first format when running on CPU.
+ input_features = tf.transpose(input_features, perm=(0, 2, 1))
+ input_features = tf.pad(input_features, [[0, 0], [1, 1], [0, 0]])
+ inputs_embeds = keras.activations.gelu(self.conv1(input_features))
+ inputs_embeds = tf.pad(inputs_embeds, [[0, 0], [1, 1], [0, 0]])
+ inputs_embeds = keras.activations.gelu(self.conv2(inputs_embeds))
+ inputs_embeds = tf.transpose(inputs_embeds, perm=(0, 1, 2))
+
+ embed_pos = self.embed_positions(input_ids=tf.zeros((1, self.max_source_positions), dtype=tf.int32))
+
+ hidden_states = inputs_embeds + embed_pos
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ # check if head_mask has a correct number of layers specified if desired
+ if head_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(head_mask)[0],
+ len(self.encoder_layers),
+ message=(
+ f"The head_mask should be specified for {len(self.encoder_layers)} layers, but it is for"
+ f" {shape_list(head_mask)[0]}."
+ ),
+ )
+
+ for idx, encoder_layer in enumerate(self.encoder_layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = random.uniform(0, 1)
+ if training and (dropout_probability < self.layerdrop): # skip the layer
+ continue
+
+ hidden_states, attn = encoder_layer(
+ hidden_states,
+ None,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ training=training,
+ )
+
+ if output_attentions:
+ all_attentions += (attn,)
+
+ hidden_states = self.layer_norm(hidden_states)
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return TFBaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "conv1", None) is not None:
+ with tf.name_scope(self.conv1.name):
+ self.conv1.build([None, None, self.num_mel_bins])
+ if getattr(self, "conv2", None) is not None:
+ with tf.name_scope(self.conv2.name):
+ self.conv2.build([None, None, self.embed_dim])
+ if getattr(self, "embed_positions", None) is not None:
+ with tf.name_scope(self.embed_positions.name):
+ self.embed_positions.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.d_model])
+ if getattr(self, "encoder_layers", None) is not None:
+ for layer in self.encoder_layers:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@keras_serializable
+class TFWhisperDecoder(keras.layers.Layer):
+ config_class = WhisperConfig
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`TFWhisperDecoderLayer`]
+
+ Args:
+ config: WhisperConfig
+ """
+
+ def __init__(self, config: WhisperConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.layerdrop = config.decoder_layerdrop
+ self.padding_idx = config.pad_token_id
+ self.max_target_positions = config.max_target_positions
+ self.max_source_positions = config.max_source_positions
+ self.embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0
+
+ self.embed_tokens = keras.layers.Embedding(
+ input_dim=config.vocab_size,
+ output_dim=config.d_model,
+ embeddings_initializer=keras.initializers.TruncatedNormal(stddev=self.config.init_std),
+ name="embed_tokens",
+ )
+ self.embed_positions = TFWhisperPositionalEmbedding(
+ self.max_target_positions, config.d_model, name="embed_positions"
+ )
+
+ self.decoder_layers = [TFWhisperDecoderLayer(config, name=f"layers.{i}") for i in range(config.decoder_layers)]
+
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="layer_norm")
+
+ def _prepare_decoder_attention_mask(self, attention_mask, input_shape, past_key_values_length):
+ # create causal mask
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ batch_size, seq_len = input_shape[0], input_shape[1]
+
+ combined_attention_mask = tf.cond(
+ tf.math.greater(seq_len, 1),
+ lambda: _make_causal_mask(input_shape, past_key_values_length=past_key_values_length),
+ lambda: _expand_mask(tf.ones((batch_size, seq_len + past_key_values_length)), tgt_len=seq_len),
+ )
+
+ if attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ expanded_attn_mask = _expand_mask(attention_mask, tgt_len=input_shape[-1])
+ combined_attention_mask = (
+ expanded_attn_mask if combined_attention_mask is None else expanded_attn_mask + combined_attention_mask
+ )
+ return combined_attention_mask
+
+ @unpack_inputs
+ def call(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ position_ids=None,
+ encoder_hidden_states=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ inputs_embeds=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ ):
+ r"""
+ Args:
+ input_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you
+ provide it.
+
+ Indices can be obtained using [`WhisperTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ position_ids (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each decoder input sequence tokens in the position embeddings. Selected in the
+ range `[0, config.max_position_embeddings - 1]`.
+ encoder_hidden_states (`tf.Tensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`tf.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in encoder to avoid performing cross-attention
+ on hidden heads. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`tuple(tuple(tf.Tensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`):
+ Tuple of `tuple(tf.Tensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape
+ `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of shape
+ `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ Contains pre-computed hidden-states (key and values in the self-attention blocks and in the
+ cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those
+ that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of
+ all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = tf.shape(input_ids)
+ input_ids = tf.reshape(input_ids, (-1, input_shape[-1]))
+ elif inputs_embeds is not None:
+ input_shape = tf.shape(inputs_embeds)[:-1]
+ else:
+ raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds")
+
+ # past_key_values_length
+ past_key_values_length = tf.shape(past_key_values[0][0])[2] if past_key_values is not None else 0
+
+ if inputs_embeds is None:
+ check_embeddings_within_bounds(input_ids, self.embed_tokens.input_dim)
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ attention_mask = self._prepare_decoder_attention_mask(attention_mask, input_shape, past_key_values_length)
+
+ # embed positions
+ filled_past_positions = past_key_values_length if position_ids is None else position_ids[0, -1]
+ positions = self.embed_positions(input_ids, past_key_values_length=filled_past_positions)
+
+ hidden_states = inputs_embeds + positions
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+ next_decoder_cache = () if use_cache else None
+
+ # check if head_mask/cross_attn_head_mask has a correct number of layers specified if desired
+ for attn_mask_name, attn_mask in [("head_mask", head_mask), ("cross_attn_head_mask", cross_attn_head_mask)]:
+ if attn_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(attn_mask)[0],
+ len(self.decoder_layers),
+ message=(
+ f"The {attn_mask_name} should be specified for {len(self.decoder_layers)} layers, but it is"
+ f" for {shape_list(attn_mask)[0]}."
+ ),
+ )
+
+ for idx, decoder_layer in enumerate(self.decoder_layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ dropout_probability = random.uniform(0, 1)
+ if training and (dropout_probability < self.layerdrop):
+ continue
+
+ past_key_value = past_key_values[idx] if past_key_values is not None else None
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_value=past_key_value,
+ training=training,
+ )
+ hidden_states = layer_outputs[0]
+
+ if use_cache:
+ next_decoder_cache += (layer_outputs[3],)
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ hidden_states = self.layer_norm(hidden_states)
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ next_cache = next_decoder_cache if use_cache else None
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, next_cache, all_hidden_states, all_self_attns, all_cross_attentions]
+ if v is not None
+ )
+ return TFBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "embed_tokens", None) is not None:
+ with tf.name_scope(self.embed_tokens.name):
+ self.embed_tokens.build(None)
+ if getattr(self, "embed_positions", None) is not None:
+ with tf.name_scope(self.embed_positions.name):
+ self.embed_positions.build(None)
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.d_model])
+ if getattr(self, "decoder_layers", None) is not None:
+ for layer in self.decoder_layers:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@add_start_docstrings(
+ "The bare Whisper Model outputting raw hidden-states without any specific head on top.",
+ WHISPER_START_DOCSTRING,
+)
+@keras_serializable
+class TFWhisperMainLayer(keras.layers.Layer):
+ config_class = WhisperConfig
+
+ def __init__(self, config: WhisperConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.encoder = TFWhisperEncoder(config, name="encoder")
+ self.decoder = TFWhisperDecoder(config, name="decoder")
+
+ def get_input_embeddings(self):
+ return self.decoder.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.decoder.embed_tokens = value
+
+ def get_encoder(self):
+ return self.encoder
+
+ @add_start_docstrings_to_model_forward(WHISPER_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+ @unpack_inputs
+ def call(
+ self,
+ input_features=None,
+ decoder_input_ids=None,
+ decoder_attention_mask=None,
+ decoder_position_ids=None,
+ head_mask=None,
+ decoder_head_mask=None,
+ cross_attn_head_mask=None,
+ encoder_outputs=None,
+ past_key_values=None,
+ decoder_inputs_embeds=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ ):
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> import tensorflow as tf
+ >>> from transformers import TFWhisperModel, AutoFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = TFWhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="tf")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = tf.convert_to_tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_features,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ # If the user passed a tuple for encoder_outputs, we wrap it in a TFBaseModelOutput when return_dict=True
+ elif return_dict and not isinstance(encoder_outputs, TFBaseModelOutput):
+ encoder_outputs = TFBaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ # decoder outputs consists of (dec_features, past_key_value, dec_hidden, dec_attn)
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ position_ids=decoder_position_ids,
+ encoder_hidden_states=encoder_outputs[0],
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return TFSeq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "decoder", None) is not None:
+ with tf.name_scope(self.decoder.name):
+ self.decoder.build(None)
+
+
+@add_start_docstrings(
+ "The bare Whisper Model outputting raw hidden-states without any specific head on top.",
+ WHISPER_START_DOCSTRING,
+)
+class TFWhisperModel(TFWhisperPreTrainedModel):
+ def __init__(self, config: WhisperConfig, **kwargs):
+ super().__init__(config, **kwargs)
+
+ self.model = TFWhisperMainLayer(config, name="model")
+
+ def get_input_embeddings(self):
+ return self.model.decoder.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.model.decoder.embed_tokens = value
+
+ def get_encoder(self):
+ return self.model.encoder
+
+ def get_decoder(self):
+ return self.model.decoder
+
+ def decoder(self):
+ return self.model.decoder
+
+ def encoder(self):
+ return self.model.encoder
+
+ @add_start_docstrings_to_model_forward(WHISPER_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFSeq2SeqModelOutput, config_class=_CONFIG_FOR_DOC)
+ @unpack_inputs
+ def call(
+ self,
+ input_features: TFModelInputType | None = None,
+ decoder_input_ids: np.ndarray | tf.Tensor | None = None,
+ decoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_head_mask: np.ndarray | tf.Tensor | None = None,
+ cross_attn_head_mask: np.ndarray | tf.Tensor | None = None,
+ encoder_outputs: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ decoder_inputs_embeds: tuple[np.ndarray | tf.Tensor] | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> tuple[tf.Tensor] | TFSeq2SeqModelOutput:
+ r"""
+ Returns:
+
+ Example:
+
+ ```python
+ >>> import tensorflow as tf
+ >>> from transformers import TFWhisperModel, AutoFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = TFWhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="tf")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = tf.convert_to_tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+ outputs = self.model(
+ input_features=input_features,
+ decoder_input_ids=decoder_input_ids,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ encoder_outputs=encoder_outputs,
+ past_key_values=past_key_values,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ return outputs
+
+ def serving_output(self, output):
+ pkv = tf.tuple(output.past_key_values)[1] if self.config.use_cache else None
+ dec_hs = tf.convert_to_tensor(output.decoder_hidden_states) if self.config.output_hidden_states else None
+ dec_attns = tf.convert_to_tensor(output.decoder_attentions) if self.config.output_attentions else None
+ cross_attns = tf.convert_to_tensor(output.cross_attentions) if self.config.output_attentions else None
+ enc_hs = tf.convert_to_tensor(output.encoder_hidden_states) if self.config.output_hidden_states else None
+ enc_attns = tf.convert_to_tensor(output.encoder_attentions) if self.config.output_attentions else None
+
+ return TFSeq2SeqModelOutput(
+ last_hidden_state=output.last_hidden_state,
+ past_key_values=pkv,
+ decoder_hidden_states=dec_hs,
+ decoder_attentions=dec_attns,
+ cross_attentions=cross_attns,
+ encoder_last_hidden_state=output.encoder_last_hidden_state,
+ encoder_hidden_states=enc_hs,
+ encoder_attentions=enc_attns,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "model", None) is not None:
+ with tf.name_scope(self.model.name):
+ self.model.build(None)
+
+
+@add_start_docstrings(
+ "The Whisper Model with a language modeling head. Can be used for automatic speech recognition.",
+ WHISPER_START_DOCSTRING,
+)
+class TFWhisperForConditionalGeneration(TFWhisperPreTrainedModel, TFCausalLanguageModelingLoss):
+ base_model_prefix = "model"
+ _keys_to_ignore_on_load_missing = [
+ r"encoder.version",
+ r"decoder.version",
+ r"proj_out.weight",
+ ]
+ _keys_to_ignore_on_save = [
+ r"proj_out.weight",
+ ]
+
+ def __init__(self, config: WhisperConfig, **kwargs):
+ super().__init__(config, **kwargs)
+ self.model = TFWhisperMainLayer(config, name="model")
+
+ def get_encoder(self):
+ return self.model.get_encoder()
+
+ def get_decoder(self):
+ return self.model.get_decoder()
+
+ def get_output_embeddings(self):
+ return self.get_input_embeddings()
+
+ def set_output_embeddings(self, value):
+ self.set_input_embeddings(value)
+
+ def resize_token_embeddings(self, new_num_tokens: int) -> keras.layers.Embedding:
+ new_embeddings = super().resize_token_embeddings(new_num_tokens)
+ return new_embeddings
+
+ @add_start_docstrings_to_model_forward(WHISPER_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFSeq2SeqLMOutput, config_class=_CONFIG_FOR_DOC)
+ @unpack_inputs
+ def call(
+ self,
+ input_features: TFModelInputType | None = None,
+ decoder_input_ids: np.ndarray | tf.Tensor | None = None,
+ decoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ decoder_head_mask: np.ndarray | tf.Tensor | None = None,
+ cross_attn_head_mask: np.ndarray | tf.Tensor | None = None,
+ encoder_outputs: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ decoder_inputs_embeds: tuple[np.ndarray | tf.Tensor] | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> tuple[tf.Tensor] | TFSeq2SeqLMOutput:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the language modeling loss. Indices should either be in `[0, ..., config.vocab_size]`
+ or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored (masked), the loss is
+ only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Returns:
+
+ Example:
+
+ ```python
+ >>> import tensorflow as tf
+ >>> from transformers import AutoProcessor, TFWhisperForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> processor = AutoProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = TFWhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+ >>> inputs = processor(ds[0]["audio"]["array"], return_tensors="tf")
+ >>> input_features = inputs.input_features
+
+ >>> generated_ids = model.generate(input_features=input_features)
+
+ >>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+ >>> transcription
+ ' Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel.'
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ outputs = self.model(
+ input_features,
+ decoder_input_ids=decoder_input_ids,
+ encoder_outputs=encoder_outputs,
+ decoder_attention_mask=decoder_attention_mask,
+ decoder_position_ids=decoder_position_ids,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ decoder_last_hidden_state = outputs[0]
+ # Decoder and encoder embeddings are tied
+ lm_logits = tf.matmul(decoder_last_hidden_state, self.get_output_embeddings().weights, transpose_b=True)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, lm_logits)
+
+ if not return_dict:
+ output = (lm_logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFSeq2SeqLMOutput(
+ loss=loss,
+ logits=lm_logits,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+ def generate(
+ self,
+ inputs: tf.Tensor | None = None,
+ generation_config: GenerationConfig | None = None,
+ logits_processor: TFLogitsProcessorList | None = None,
+ seed: list[int] | None = None,
+ return_timestamps: bool | None = None,
+ task: str | None = None,
+ language: str | None = None,
+ is_multilingual: bool | None = None,
+ prompt_ids: tf.Tensor | None = None,
+ return_token_timestamps=None,
+ **kwargs,
+ ):
+ r"""
+ Generates sequences of token ids for models with a language modeling head.
+
+
+
+ Most generation-controlling parameters are set in `generation_config` which, if not passed, will be set to the
+ model's default generation configuration. You can override any `generation_config` by passing the corresponding
+ parameters to generate, e.g. `.generate(inputs, num_beams=4, do_sample=True)`.
+
+ For an overview of generation strategies and code examples, check out the [following
+ guide](../generation_strategies).
+
+
+
+ Parameters:
+ inputs (`tf.Tensor` of varying shape depending on the modality, *optional*):
+ The sequence used as a prompt for the generation or as model inputs to the encoder. If unset the method
+ initializes it with `bos_token_id` and a batch size of 1. For decoder-only models `inputs` should of in
+ the format of `input_ids`. For encoder-decoder models *inputs* can represent any of `input_ids`,
+ `input_values`, `input_features`, or `pixel_values`.
+ generation_config (`~generation.GenerationConfig`, *optional*):
+ The generation configuration to be used as base parametrization for the generation call. `**kwargs`
+ passed to generate matching the attributes of `generation_config` will override them. If
+ `generation_config` is not provided, the default will be used, which had the following loading
+ priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model
+ configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s
+ default values, whose documentation should be checked to parameterize generation.
+ logits_processor (`LogitsProcessorList`, *optional*):
+ Custom logits processors that complement the default logits processors built from arguments and
+ generation config. If a logit processor is passed that is already created with the arguments or a
+ generation config an error is thrown. This feature is intended for advanced users.
+ seed (`list[int]`, *optional*):
+ Random seed to control sampling, containing two integers, used when `do_sample` is `True`. See the
+ `seed` argument from stateless functions in `tf.random`.
+ return_timestamps (`bool`, *optional*):
+ Whether to return the timestamps with the text. This enables the `TFWhisperTimestampsLogitsProcessor`.
+ task (`str`, *optional*):
+ Task to use for generation, either "translate" or "transcribe". The `model.config.forced_decoder_ids`
+ will be updated accordingly.
+ language (`str`, *optional*):
+ Language token to use for generation, can be either in the form of `<|en|>`, `en` or `english`. You can
+ find all the possible language tokens in the `model.generation_config.lang_to_id` dictionary.
+ is_multilingual (`bool`, *optional*):
+ Whether or not the model is multilingual.
+ prompt_ids (`tf.Tensor`, *optional*):
+ Rank-1 tensor of token IDs created by passing text to [`~WhisperProcessor.get_prompt_ids`] that is
+ provided as a prompt to each chunk. This can be used to provide or "prompt-engineer" a context for
+ transcription, e.g. custom vocabularies or proper nouns to make it more likely to predict those words
+ correctly. It cannot be used in conjunction with `decoder_start_token_id` as it overwrites this value.
+ return_token_timestamps (`bool`, *optional*):
+ Whether to return token-level timestamps with the text. This can be used with or without the
+ `return_timestamps` option. To get word-level timestamps, use the tokenizer to group the tokens into
+ words.
+ kwargs (`dict[str, Any]`, *optional*):
+ Ad hoc parametrization of `generate_config` and/or additional model-specific kwargs that will be
+ forwarded to the `forward` function of the model. If the model is an encoder-decoder model, encoder
+ specific kwargs should not be prefixed and decoder specific kwargs should be prefixed with *decoder_*.
+
+ Return:
+ [`~utils.ModelOutput`] or `tf.Tensor`: A [`~utils.ModelOutput`] (if `return_dict_in_generate=True` or when
+ `config.return_dict_in_generate=True`) or a `tf.Tensor`.
+
+ If the model is *not* an encoder-decoder model (`model.config.is_encoder_decoder=False`), the possible
+ [`~utils.ModelOutput`] types are:
+
+ - [`~generation.TFGreedySearchDecoderOnlyOutput`],
+ - [`~generation.TFSampleDecoderOnlyOutput`],
+ - [`~generation.TFBeamSearchDecoderOnlyOutput`],
+ - [`~generation.TFBeamSampleDecoderOnlyOutput`]
+
+ If the model is an encoder-decoder model (`model.config.is_encoder_decoder=True`), the possible
+ [`~utils.ModelOutput`] types are:
+
+ - [`~generation.TFGreedySearchEncoderDecoderOutput`],
+ - [`~generation.TFSampleEncoderDecoderOutput`],
+ - [`~generation.TFBeamSearchEncoderDecoderOutput`],
+ - [`~generation.TFBeamSampleEncoderDecoderOutput`]
+
+ """
+ if generation_config is None:
+ generation_config = self.generation_config
+
+ if return_timestamps is not None:
+ if not hasattr(generation_config, "no_timestamps_token_id"):
+ raise ValueError(
+ "You are trying to return timestamps, but the generation config is not properly set. "
+ "Make sure to initialize the generation config with the correct attributes that are needed such as `no_timestamps_token_id`. "
+ "For more details on how to generate the approtiate config, refer to https://github.com/huggingface/transformers/issues/21878#issuecomment-1451902363"
+ )
+
+ generation_config.return_timestamps = return_timestamps
+ else:
+ generation_config.return_timestamps = False
+
+ if language is not None:
+ language = language.lower()
+ generation_config.language = language
+ if task is not None:
+ generation_config.task = task
+
+ forced_decoder_ids = None
+
+ # Legacy code for backward compatibility
+ if hasattr(self.config, "forced_decoder_ids") and self.config.forced_decoder_ids is not None:
+ forced_decoder_ids = self.config.forced_decoder_ids
+ elif (
+ hasattr(self.generation_config, "forced_decoder_ids")
+ and self.generation_config.forced_decoder_ids is not None
+ ):
+ forced_decoder_ids = self.generation_config.forced_decoder_ids
+ else:
+ forced_decoder_ids = kwargs.get("forced_decoder_ids")
+
+ if task is not None or language is not None or (forced_decoder_ids is None and prompt_ids is not None):
+ forced_decoder_ids = []
+ if hasattr(generation_config, "language"):
+ if generation_config.language in generation_config.lang_to_id:
+ language_token = generation_config.language
+ elif generation_config.language in TO_LANGUAGE_CODE:
+ language_token = f"<|{TO_LANGUAGE_CODE[generation_config.language]}|>"
+ elif generation_config.language in TO_LANGUAGE_CODE.values():
+ language_token = f"<|{generation_config.language}|>"
+ else:
+ is_language_code = len(generation_config.language) == 2
+ raise ValueError(
+ f"Unsupported language: {generation_config.language}. Language should be one of:"
+ f" {list(TO_LANGUAGE_CODE.values()) if is_language_code else list(TO_LANGUAGE_CODE.keys())}."
+ )
+ if language_token not in generation_config.lang_to_id:
+ raise ValueError(
+ f"{language_token} is not supported by this specific model as it is not in the `generation_config.lang_to_id`."
+ "(You should just add it to the generation config)"
+ )
+ forced_decoder_ids.append((1, generation_config.lang_to_id[language_token]))
+ else:
+ forced_decoder_ids.append((1, None)) # automatically detect the language
+
+ if hasattr(generation_config, "task"):
+ if generation_config.task in TASK_IDS:
+ forced_decoder_ids.append((2, generation_config.task_to_id[generation_config.task]))
+ else:
+ raise ValueError(
+ f"The `{generation_config.task}`task is not supported. The task should be one of `{TASK_IDS}`"
+ )
+ elif hasattr(generation_config, "task_to_id"):
+ forced_decoder_ids.append((2, generation_config.task_to_id["transcribe"])) # defaults to transcribe
+ if hasattr(generation_config, "no_timestamps_token_id") and not generation_config.return_timestamps:
+ idx = forced_decoder_ids[-1][0] + 1 if forced_decoder_ids else 1
+ forced_decoder_ids.append((idx, generation_config.no_timestamps_token_id))
+
+ if forced_decoder_ids is not None:
+ generation_config.forced_decoder_ids = forced_decoder_ids
+
+ if prompt_ids is not None:
+ if kwargs.get("decoder_start_token_id") is not None:
+ raise ValueError(
+ "When specifying `prompt_ids`, you cannot also specify `decoder_start_token_id` as it gets overwritten."
+ )
+ prompt_ids = prompt_ids.tolist()
+ decoder_start_token_id, *text_prompt_ids = prompt_ids
+ # Slicing the text prompt ids in a manner consistent with the OpenAI implementation
+ # to accommodate context space for the prefix (see https://github.com/openai/whisper/blob/c09a7ae299c4c34c5839a76380ae407e7d785914/whisper/decoding.py#L599)
+ text_prompt_ids = text_prompt_ids[-self.config.max_length // 2 - 1 :]
+ # Set the decoder_start_token_id to <|startofprev|>
+ kwargs.update({"decoder_start_token_id": decoder_start_token_id})
+
+ # Update the max generation length to include the prompt
+ specified_max_length = kwargs.pop("max_new_tokens", None) or kwargs.pop("max_length", None)
+ default_max_length = generation_config.max_new_tokens or generation_config.max_length
+ non_prompt_max_length = specified_max_length or default_max_length
+ kwargs["max_new_tokens"] = non_prompt_max_length + len(text_prompt_ids)
+
+ # Reformat the forced_decoder_ids to incorporate the prompt
+ non_prompt_forced_decoder_ids = (
+ kwargs.pop("forced_decoder_ids", None) or generation_config.forced_decoder_ids
+ )
+ forced_decoder_ids = [
+ *text_prompt_ids,
+ generation_config.decoder_start_token_id,
+ *[token for _rank, token in non_prompt_forced_decoder_ids],
+ ]
+ forced_decoder_ids = [(rank + 1, token) for rank, token in enumerate(forced_decoder_ids)]
+ generation_config.forced_decoder_ids = forced_decoder_ids
+
+ # TODO: Implement `WhisperTimeStampLogitsProcessor`.
+ if generation_config.return_timestamps:
+ # logits_processor = [TFWhisperTimeStampLogitsProcessor(generation_config)]
+ raise ValueError("`TFWhisperForConditionalGeneration` doesn't support returning the timestamps yet.")
+
+ if return_token_timestamps:
+ kwargs["output_attentions"] = True
+ kwargs["return_dict_in_generate"] = True
+
+ if getattr(generation_config, "task", None) == "translate":
+ logger.warning("Token-level timestamps may not be reliable for task 'translate'.")
+ if not hasattr(generation_config, "alignment_heads"):
+ raise ValueError(
+ "Model generation config has no `alignment_heads`, token-level timestamps not available. "
+ "See https://gist.github.com/hollance/42e32852f24243b748ae6bc1f985b13a on how to add this property to the generation config."
+ )
+
+ outputs = super().generate(
+ inputs,
+ generation_config,
+ logits_processor,
+ **kwargs,
+ )
+
+ if return_token_timestamps and hasattr(generation_config, "alignment_heads"):
+ outputs["token_timestamps"] = self._extract_token_timestamps(outputs, generation_config.alignment_heads)
+
+ return outputs
+
+ def serving_output(self, output):
+ pkv = tf.tuple(output.past_key_values)[1] if self.config.use_cache else None
+ dec_hs = tf.convert_to_tensor(output.decoder_hidden_states) if self.config.output_hidden_states else None
+ dec_attns = tf.convert_to_tensor(output.decoder_attentions) if self.config.output_attentions else None
+ cross_attns = tf.convert_to_tensor(output.cross_attentions) if self.config.output_attentions else None
+ enc_hs = tf.convert_to_tensor(output.encoder_hidden_states) if self.config.output_hidden_states else None
+ enc_attns = tf.convert_to_tensor(output.encoder_attentions) if self.config.output_attentions else None
+
+ return TFSeq2SeqLMOutput(
+ logits=output.logits,
+ past_key_values=pkv,
+ decoder_hidden_states=dec_hs,
+ decoder_attentions=dec_attns,
+ cross_attentions=cross_attns,
+ encoder_last_hidden_state=output.encoder_last_hidden_state,
+ encoder_hidden_states=enc_hs,
+ encoder_attentions=enc_attns,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ decoder_input_ids,
+ past_key_values=None,
+ use_cache=None,
+ encoder_outputs=None,
+ attention_mask=None,
+ decoder_attention_mask=None,
+ **kwargs,
+ ):
+ # cut decoder_input_ids if past is used
+ if past_key_values is not None:
+ decoder_input_ids = decoder_input_ids[:, -1:]
+
+ if decoder_attention_mask is not None: # xla
+ decoder_position_ids = tf.math.cumsum(decoder_attention_mask, axis=-1, exclusive=True)[:, -1:]
+ elif past_key_values is not None: # no xla + past
+ decoder_position_ids = past_key_values[0][0].shape[2]
+ else: # no xla + no past
+ decoder_position_ids = tf.range(decoder_input_ids.shape[1])
+ decoder_position_ids = tf.broadcast_to(decoder_position_ids, decoder_input_ids.shape)
+
+ return {
+ "input_features": None, # Needs to be passed to make Keras.layer.__call__ happy
+ "encoder_outputs": encoder_outputs,
+ "past_key_values": past_key_values,
+ "decoder_input_ids": decoder_input_ids,
+ "use_cache": use_cache,
+ "decoder_attention_mask": decoder_attention_mask,
+ "decoder_position_ids": decoder_position_ids,
+ }
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "model", None) is not None:
+ with tf.name_scope(self.model.name):
+ self.model.build(None)
+
+
+__all__ = ["TFWhisperForConditionalGeneration", "TFWhisperModel", "TFWhisperPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..a64dcc95374b4347204eccedeb616d0e3c1dda3e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/modeling_whisper.py
@@ -0,0 +1,1642 @@
+# coding=utf-8
+# Copyright 2022 The OpenAI Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Whisper model."""
+
+import math
+from typing import Callable, Optional, Union
+
+import numpy as np
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...masking_utils import create_causal_mask
+from ...modeling_flash_attention_utils import (
+ FlashAttentionKwargs,
+)
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutput,
+ BaseModelOutputWithPastAndCrossAttentions,
+ CausalLMOutputWithCrossAttentions,
+ Seq2SeqLMOutput,
+ Seq2SeqModelOutput,
+ SequenceClassifierOutput,
+)
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_whisper import WhisperConfig
+from .generation_whisper import WhisperGenerationMixin
+
+
+logger = logging.get_logger(__name__)
+
+_HIDDEN_STATES_START_POSITION = 1
+
+
+def sinusoids(length: int, channels: int, max_timescale: float = 10000) -> torch.Tensor:
+ """Returns sinusoids for positional embedding"""
+ if channels % 2 != 0:
+ raise ValueError(
+ f"Number of channels has to be divisible by 2 for sinusoidal positional embeddings, got {channels} channels."
+ )
+ log_timescale_increment = math.log(max_timescale) / (channels // 2 - 1)
+ inv_timescales = torch.exp(-log_timescale_increment * torch.arange(channels // 2))
+ scaled_time = torch.arange(length).view(-1, 1) * inv_timescales.view(1, -1)
+ return torch.cat([scaled_time.sin(), scaled_time.cos()], dim=1)
+
+
+# Copied from transformers.models.bart.modeling_bart.shift_tokens_right
+def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int):
+ """
+ Shift input ids one token to the right.
+ """
+ shifted_input_ids = input_ids.new_zeros(input_ids.shape)
+ shifted_input_ids[:, 1:] = input_ids[:, :-1].clone()
+ shifted_input_ids[:, 0] = decoder_start_token_id
+
+ if pad_token_id is None:
+ raise ValueError("self.model.config.pad_token_id has to be defined.")
+ # replace possible -100 values in labels by `pad_token_id`
+ shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
+
+ return shifted_input_ids
+
+
+# Copied from transformers.models.wav2vec2.modeling_wav2vec2._compute_mask_indices
+def _compute_mask_indices(
+ shape: tuple[int, int],
+ mask_prob: float,
+ mask_length: int,
+ attention_mask: Optional[torch.LongTensor] = None,
+ min_masks: int = 0,
+) -> np.ndarray:
+ """
+ Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for
+ ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on
+ CPU as part of the preprocessing during training.
+
+ Args:
+ shape: The shape for which to compute masks. This should be of a tuple of size 2 where
+ the first element is the batch size and the second element is the length of the axis to span.
+ mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of
+ independently generated mask spans of length `mask_length` is computed by
+ `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the
+ actual percentage will be smaller.
+ mask_length: size of the mask
+ min_masks: minimum number of masked spans
+ attention_mask: A (right-padded) attention mask which independently shortens the feature axis of
+ each batch dimension.
+ """
+ batch_size, sequence_length = shape
+
+ if mask_length < 1:
+ raise ValueError("`mask_length` has to be bigger than 0.")
+
+ if mask_length > sequence_length:
+ raise ValueError(
+ f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}"
+ f" and `sequence_length`: {sequence_length}`"
+ )
+
+ # epsilon is used for probabilistic rounding
+ epsilon = np.random.rand(1).item()
+
+ def compute_num_masked_span(input_length):
+ """Given input length, compute how many spans should be masked"""
+ num_masked_span = int(mask_prob * input_length / mask_length + epsilon)
+ num_masked_span = max(num_masked_span, min_masks)
+
+ # make sure num masked span <= sequence_length
+ if num_masked_span * mask_length > sequence_length:
+ num_masked_span = sequence_length // mask_length
+
+ # make sure num_masked span is also <= input_length - (mask_length - 1)
+ if input_length - (mask_length - 1) < num_masked_span:
+ num_masked_span = max(input_length - (mask_length - 1), 0)
+
+ return num_masked_span
+
+ # compute number of masked spans in batch
+ input_lengths = (
+ attention_mask.detach().sum(-1).tolist()
+ if attention_mask is not None
+ else [sequence_length for _ in range(batch_size)]
+ )
+
+ # SpecAugment mask to fill
+ spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool)
+ spec_aug_mask_idxs = []
+
+ max_num_masked_span = compute_num_masked_span(sequence_length)
+
+ if max_num_masked_span == 0:
+ return spec_aug_mask
+
+ for input_length in input_lengths:
+ # compute num of masked spans for this input
+ num_masked_span = compute_num_masked_span(input_length)
+
+ # get random indices to mask
+ spec_aug_mask_idx = np.random.choice(
+ np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False
+ )
+
+ # pick first sampled index that will serve as a dummy index to pad vector
+ # to ensure same dimension for all batches due to probabilistic rounding
+ # Picking first sample just pads those vectors twice.
+ if len(spec_aug_mask_idx) == 0:
+ # this case can only happen if `input_length` is strictly smaller then
+ # `sequence_length` in which case the last token has to be a padding
+ # token which we can use as a dummy mask id
+ dummy_mask_idx = sequence_length - 1
+ else:
+ dummy_mask_idx = spec_aug_mask_idx[0]
+
+ spec_aug_mask_idx = np.concatenate(
+ [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx]
+ )
+ spec_aug_mask_idxs.append(spec_aug_mask_idx)
+
+ spec_aug_mask_idxs = np.array(spec_aug_mask_idxs)
+
+ # expand masked indices to masked spans
+ spec_aug_mask_idxs = np.broadcast_to(
+ spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length)
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length)
+
+ # add offset to the starting indexes so that indexes now create a span
+ offsets = np.arange(mask_length)[None, None, :]
+ offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape(
+ batch_size, max_num_masked_span * mask_length
+ )
+ spec_aug_mask_idxs = spec_aug_mask_idxs + offsets
+
+ # ensure that we cannot have indices larger than sequence_length
+ if spec_aug_mask_idxs.max() > sequence_length - 1:
+ spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1
+
+ # scatter indices to mask
+ np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1)
+
+ return spec_aug_mask
+
+
+class WhisperPositionalEmbedding(nn.Embedding):
+ def __init__(self, num_positions: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ super().__init__(num_positions, embedding_dim)
+
+ def forward(self, input_ids, past_key_values_length=0, position_ids=None):
+ if position_ids is None:
+ return self.weight[past_key_values_length : past_key_values_length + input_ids.shape[1]]
+ else:
+ return self.weight[position_ids]
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: Optional[float] = None,
+ dropout: float = 0.0,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs,
+):
+ if scaling is None:
+ scaling = query.size(-1) ** -0.5
+
+ attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling
+ if attention_mask is not None and attention_mask.ndim == 4:
+ attn_weights = attn_weights + attention_mask[:, :, :, : key.shape[-2]]
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if head_mask is not None:
+ attn_weights = attn_weights * head_mask.view(1, -1, 1, 1)
+
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class WhisperAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ is_causal: bool = False,
+ layer_idx: Optional[int] = None,
+ config: Optional[WhisperConfig] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+ self.config = config
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.is_causal = is_causal
+
+ if layer_idx is None and is_decoder:
+ logger.warning_once(
+ f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and "
+ "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` "
+ "when creating this class."
+ )
+ self.layer_idx = layer_idx
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=False)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ cache_position: Optional[torch.Tensor] = None,
+ # TODO: we need a refactor so that the different attention modules can get their specific kwargs
+ # ATM, we have mixed things encoder, decoder, and encoder-decoder attn
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ # determine input shapes
+ bsz, tgt_len = hidden_states.shape[:-1]
+ q_input_shape = (bsz, tgt_len, -1, self.head_dim)
+
+ # Scaling is susceptible to floating point arithmetics' inprecisions
+ # which can lead to different results (this is dependent from model
+ # to model, e.g. whisper is one such case). We therefore keep the
+ # original order of scaling to follow the original implementation
+ # and enforce no scaling (1.0) in the attention call below.
+ query_states = self.q_proj(hidden_states) * self.scaling
+ query_states = query_states.view(*q_input_shape)
+ query_states = query_states.transpose(1, 2).contiguous()
+
+ # Check is encoder-decoder model is being used. Otherwise we'll get `DynamicCache`
+ if past_key_values is not None and isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ past_key_values.is_updated[self.layer_idx] = True
+ past_key_values = past_key_values.cross_attention_cache
+ else:
+ past_key_values = past_key_values.self_attention_cache
+
+ # use key_value_states if cross attention
+ current_states = key_value_states if key_value_states is not None else hidden_states
+ if is_cross_attention and past_key_values and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = past_key_values.layers[self.layer_idx].keys
+ value_states = past_key_values.layers[self.layer_idx].values
+ else:
+ key_states = self.k_proj(current_states).view(bsz, -1, self.num_heads, self.head_dim)
+ value_states = self.v_proj(current_states).view(bsz, -1, self.num_heads, self.head_dim)
+ key_states = key_states.transpose(1, 2).contiguous()
+ value_states = value_states.transpose(1, 2).contiguous()
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = past_key_values.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.dropout,
+ scaling=1.0,
+ output_attentions=output_attentions,
+ head_mask=layer_head_mask,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous()
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.mbart.modeling_mbart.MBartEncoderLayer with MBart->Whisper, MBART->WHISPER
+class WhisperEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: WhisperConfig):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = WhisperAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.encoder_attention_heads,
+ dropout=config.attention_dropout,
+ config=config,
+ )
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+ self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim)
+ self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ layer_head_mask: torch.Tensor,
+ output_attentions: bool = False,
+ ) -> torch.Tensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ if hidden_states.dtype == torch.float16:
+ clamp_value = torch.finfo(hidden_states.dtype).max - 1000
+ hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value)
+
+ return hidden_states, attn_weights
+
+
+class WhisperDecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: WhisperConfig, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = WhisperAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ is_causal=True,
+ layer_idx=layer_idx,
+ config=config,
+ )
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.encoder_attn = WhisperAttention(
+ self.embed_dim,
+ config.decoder_attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ layer_idx=layer_idx,
+ config=config,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim)
+ self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_layer_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[EncoderDecoderCache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = True,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> torch.Tensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`torch.FloatTensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ cross_attn_layer_head_mask (`torch.FloatTensor`): mask for cross-attention heads in a given layer of
+ size `(decoder_attention_heads,)`.
+ past_key_values (`Tuple(torch.FloatTensor)`): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_values=past_key_values,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+@auto_docstring
+class WhisperPreTrainedModel(PreTrainedModel):
+ config: WhisperConfig
+ base_model_prefix = "model"
+ main_input_name = "input_features"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["WhisperEncoderLayer", "WhisperDecoderLayer"]
+ _supports_flash_attn = True
+ _supports_sdpa = True
+ _supports_flex_attn = True
+
+ _can_compile_fullgraph = True
+
+ def _init_weights(self, module):
+ std = self.config.init_std
+ if isinstance(module, (nn.Linear, nn.Conv1d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.weight.data.fill_(1.0)
+ module.bias.data.zero_()
+ elif isinstance(module, WhisperEncoder):
+ module.embed_positions.weight.copy_(sinusoids(*module.embed_positions.weight.shape))
+ elif isinstance(module, WhisperForAudioClassification):
+ if self.config.use_weighted_layer_sum:
+ module.layer_weights.data.fill_(1.0 / (self.config.num_hidden_layers + 1))
+
+ def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor):
+ """
+ Computes the output length of the convolutional layers
+ """
+ input_lengths = (input_lengths - 1) // 2 + 1
+
+ return input_lengths
+
+
+class WhisperEncoder(WhisperPreTrainedModel):
+ """
+ Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a
+ [`WhisperEncoderLayer`].
+
+ Args:
+ config: WhisperConfig
+ """
+
+ def __init__(self, config: WhisperConfig):
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.encoder_layerdrop
+
+ embed_dim = config.d_model
+ self.num_mel_bins = config.num_mel_bins
+ self.padding_idx = config.pad_token_id
+ self.max_source_positions = config.max_source_positions
+ self.embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0
+
+ self.conv1 = nn.Conv1d(self.num_mel_bins, embed_dim, kernel_size=3, padding=1)
+ self.conv2 = nn.Conv1d(embed_dim, embed_dim, kernel_size=3, stride=2, padding=1)
+
+ self.embed_positions = nn.Embedding(self.max_source_positions, embed_dim)
+ self.embed_positions.requires_grad_(False)
+
+ self.layers = nn.ModuleList([WhisperEncoderLayer(config) for _ in range(config.encoder_layers)])
+ self.layer_norm = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def _freeze_parameters(self):
+ for param in self.parameters():
+ param.requires_grad = False
+ self._requires_grad = False
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.conv1
+
+ def set_input_embeddings(self, value: nn.Module):
+ self.conv1 = value
+
+ def forward(
+ self,
+ input_features,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ r"""
+ Args:
+ input_features (`torch.LongTensor` of shape `(batch_size, feature_size, sequence_length)`):
+ Float values of mel features extracted from the raw speech waveform. Raw speech waveform can be
+ obtained by loading a `.flac` or `.wav` audio file into an array of type `list[float]`, a
+ `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library (`pip install torchcodec`) or
+ the soundfile library (`pip install soundfile`). To prepare the array into
+ `input_features`, the [`AutoFeatureExtractor`] should be used for extracting the mel features, padding
+ and conversion into a tensor of type `torch.FloatTensor`. See [`~WhisperFeatureExtractor.__call__`]
+ attention_mask (`torch.Tensor`)`, *optional*):
+ Whisper does not support masking of the `input_features`, this argument is preserved for compatibility,
+ but it is not used. By default the silence in the input log mel spectrogram are ignored.
+ head_mask (`torch.Tensor` of shape `(encoder_layers, encoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+
+ expected_seq_length = self.config.max_source_positions * self.conv1.stride[0] * self.conv2.stride[0]
+ if input_features.shape[-1] != expected_seq_length:
+ raise ValueError(
+ f"Whisper expects the mel input features to be of length {expected_seq_length}, but found {input_features.shape[-1]}. Make sure to pad the input mel features to {expected_seq_length}."
+ )
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ inputs_embeds = nn.functional.gelu(self.conv1(input_features))
+ inputs_embeds = nn.functional.gelu(self.conv2(inputs_embeds))
+
+ inputs_embeds = inputs_embeds.permute(0, 2, 1)
+ all_positions = torch.arange(self.embed_positions.num_embeddings, device=inputs_embeds.device)
+
+ hidden_states = inputs_embeds + self.embed_positions(all_positions)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ # check if head_mask has a correct number of layers specified if desired
+ if head_mask is not None:
+ assert head_mask.size()[0] == (len(self.layers)), (
+ f"The head_mask should be specified for {len(self.layers)} layers, but it is for {head_mask.size()[0]}."
+ )
+
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ to_drop = False
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop: # skip the layer
+ to_drop = True
+
+ if to_drop:
+ layer_outputs = (None, None)
+ else:
+ layer_outputs = encoder_layer(
+ hidden_states,
+ None,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ hidden_states = self.layer_norm(hidden_states)
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+
+class WhisperDecoder(WhisperPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`WhisperDecoderLayer`]
+
+ Args:
+ config: WhisperConfig
+ """
+
+ main_input_name = "input_ids"
+
+ def __init__(self, config: WhisperConfig):
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.decoder_layerdrop
+ self.padding_idx = config.pad_token_id
+ self.max_target_positions = config.max_target_positions
+ self.max_source_positions = config.max_source_positions
+ self.embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.d_model, self.padding_idx)
+ self.embed_positions = WhisperPositionalEmbedding(self.max_target_positions, config.d_model)
+
+ self.layers = nn.ModuleList(
+ [WhisperDecoderLayer(config, layer_idx) for layer_idx in range(config.decoder_layers)]
+ )
+ self._use_flash_attention_2 = config._attn_implementation == "flash_attention_2"
+ self._use_sdpa = config._attn_implementation == "sdpa"
+
+ self.layer_norm = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def forward(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ encoder_hidden_states=None,
+ head_mask=None,
+ cross_attn_head_mask=None,
+ past_key_values=None,
+ inputs_embeds=None,
+ position_ids=None,
+ use_cache=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ cache_position=None,
+ ):
+ r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you
+ provide it.
+
+ Indices can be obtained using [`WhisperTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ of the decoder.
+ head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in encoder to avoid performing cross-attention
+ on hidden heads. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`EncoderDecoderCache` or `tuple(tuple(torch.FloatTensor))`, *optional*):
+ Pre-computed hidden-states that can be used to speed up auto-regressive (sequential) decoding. There are
+ four sets of pre-computed hidden-states: key and values states in the self-attention blocks (2) and
+ in the cross-attention blocks (2). The `past_key_values` are returned when `use_cache=True` is passed or
+ when `config.use_cache=True`
+
+ Two formats are allowed:
+ - An [`~cache_utils.EncoderDecoderCache`] instance;
+ - Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of
+ shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of shape
+ `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
+
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those
+ that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of
+ all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`torch.FloatTensor` of
+ shape `(batch_size, sequence_length, hidden_size)`, *optional*): Optionally, instead of passing
+ `input_ids` you can choose to directly pass an embedded representation. This is useful if you want more
+ control over how to convert `input_ids` indices into associated vectors than the model's internal
+ embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence. It is used to update the
+ cache in the correct position and to infer the complete sequence length.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if use_cache and past_key_values is None:
+ if self.config.is_encoder_decoder:
+ past_key_values = EncoderDecoderCache(
+ DynamicCache(config=self.config), DynamicCache(config=self.config)
+ )
+ else:
+ past_key_values = DynamicCache(config=self.config)
+
+ past_key_values_length = 0
+ if cache_position is not None:
+ past_key_values_length = cache_position[0]
+ elif past_key_values is not None:
+ past_key_values_length = past_key_values.get_seq_length()
+
+ if cache_position is None:
+ cache_position = torch.arange(
+ past_key_values_length, past_key_values_length + input_shape[1], device=inputs_embeds.device
+ )
+
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0).repeat(input_shape[0], 1)
+
+ # embed positions
+ if input_ids is not None:
+ positions = self.embed_positions(
+ input_ids, past_key_values_length=past_key_values_length, position_ids=position_ids
+ )
+ else:
+ positions = self.embed_positions(
+ inputs_embeds, past_key_values_length=past_key_values_length, position_ids=position_ids
+ )
+
+ hidden_states = inputs_embeds + positions.to(inputs_embeds.device)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+
+ causal_mask = create_causal_mask(
+ config=self.config,
+ input_embeds=inputs_embeds,
+ attention_mask=attention_mask,
+ cache_position=cache_position,
+ past_key_values=past_key_values,
+ position_ids=position_ids,
+ )
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache = True` is incompatible with gradient checkpointing. Setting `use_cache = False`..."
+ )
+ use_cache = False
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ # check if head_mask/cross_attn_head_mask has a correct number of layers specified if desired
+ for attn_mask, mask_name in zip([head_mask, cross_attn_head_mask], ["head_mask", "cross_attn_head_mask"]):
+ if attn_mask is not None:
+ assert attn_mask.size()[0] == (len(self.layers)), (
+ f"The `{mask_name}` should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop:
+ continue
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask=causal_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_values=past_key_values if use_cache else None,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ hidden_states = self.layer_norm(hidden_states)
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ next_cache = past_key_values if use_cache else None
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, next_cache, all_hidden_states, all_self_attns, all_cross_attentions]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+@auto_docstring
+class WhisperModel(WhisperPreTrainedModel):
+ def __init__(self, config: WhisperConfig):
+ super().__init__(config)
+
+ self.encoder = WhisperEncoder(config)
+ self.decoder = WhisperDecoder(config)
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.decoder.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.decoder.embed_tokens = value
+
+ def get_encoder(self):
+ return self.encoder
+
+ def freeze_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the Whisper encoder so that its parameters will
+ not be updated during training.
+ """
+ self.encoder._freeze_parameters()
+
+ def _mask_input_features(
+ self,
+ input_features: torch.FloatTensor,
+ attention_mask: Optional[torch.LongTensor] = None,
+ ):
+ """
+ Masks extracted features along time axis and/or along feature axis according to
+ [SpecAugment](https://huggingface.co/papers/1904.08779).
+ """
+
+ # `config.apply_spec_augment` can set masking to False
+ if not getattr(self.config, "apply_spec_augment", True):
+ return input_features
+
+ # generate indices & apply SpecAugment along time axis
+ batch_size, hidden_size, sequence_length = input_features.size()
+
+ if self.config.mask_time_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along time axis
+ mask_time_indices = _compute_mask_indices(
+ (batch_size, sequence_length),
+ mask_prob=self.config.mask_time_prob,
+ mask_length=self.config.mask_time_length,
+ attention_mask=attention_mask,
+ min_masks=self.config.mask_time_min_masks,
+ )
+ mask_time_indices = torch.tensor(mask_time_indices, device=input_features.device, dtype=torch.bool)
+ mask_time_indices = mask_time_indices[:, None].expand(-1, hidden_size, -1)
+ input_features[mask_time_indices] = 0
+
+ if self.config.mask_feature_prob > 0 and self.training:
+ # generate indices & apply SpecAugment along feature axis
+ mask_feature_indices = _compute_mask_indices(
+ (batch_size, hidden_size),
+ mask_prob=self.config.mask_feature_prob,
+ mask_length=self.config.mask_feature_length,
+ min_masks=self.config.mask_feature_min_masks,
+ )
+ mask_feature_indices = torch.tensor(mask_feature_indices, device=input_features.device, dtype=torch.bool)
+ input_features[mask_feature_indices] = 0
+
+ return input_features
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[Union[Cache]] = None,
+ decoder_inputs_embeds: Optional[tuple[torch.FloatTensor]] = None,
+ decoder_position_ids: Optional[tuple[torch.LongTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.Tensor], Seq2SeqModelOutput]:
+ r"""
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`WhisperTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ Whisper uses the `decoder_start_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+
+ If you want to change padding behavior, you should read
+ [`modeling_whisper._prepare_decoder_attention_mask`] and modify to your needs. See diagram 1 in [the BART
+ paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.n_positions - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+
+ Example:
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, WhisperModel
+ >>> from datasets import load_dataset
+
+ >>> model = WhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = torch.tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if encoder_outputs is None:
+ input_features = self._mask_input_features(input_features, attention_mask=attention_mask)
+
+ encoder_outputs = self.encoder(
+ input_features,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True
+ elif return_dict and not isinstance(encoder_outputs, BaseModelOutput):
+ encoder_outputs = BaseModelOutput(
+ last_hidden_state=encoder_outputs[0],
+ hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None,
+ attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None,
+ )
+
+ # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn)
+ decoder_outputs = self.decoder(
+ input_ids=decoder_input_ids,
+ attention_mask=decoder_attention_mask,
+ encoder_hidden_states=encoder_outputs[0],
+ head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=decoder_inputs_embeds,
+ position_ids=decoder_position_ids,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ if not return_dict:
+ return decoder_outputs + encoder_outputs
+
+ return Seq2SeqModelOutput(
+ last_hidden_state=decoder_outputs.last_hidden_state,
+ past_key_values=decoder_outputs.past_key_values,
+ decoder_hidden_states=decoder_outputs.hidden_states,
+ decoder_attentions=decoder_outputs.attentions,
+ cross_attentions=decoder_outputs.cross_attentions,
+ encoder_last_hidden_state=encoder_outputs.last_hidden_state,
+ encoder_hidden_states=encoder_outputs.hidden_states,
+ encoder_attentions=encoder_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The Whisper Model with a language modeling head. Can be used for automatic speech recognition.
+ """
+)
+class WhisperForConditionalGeneration(WhisperGenerationMixin, WhisperPreTrainedModel):
+ base_model_prefix = "model"
+ _tied_weights_keys = ["proj_out.weight"]
+
+ def __init__(self, config: WhisperConfig):
+ super().__init__(config)
+ self.model = WhisperModel(config)
+ self.proj_out = nn.Linear(config.d_model, config.vocab_size, bias=False)
+ self.max_target_positions = config.max_target_positions
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_encoder(self):
+ return self.model.get_encoder()
+
+ def get_decoder(self):
+ return self.model.get_decoder()
+
+ def get_output_embeddings(self):
+ return self.proj_out
+
+ def set_output_embeddings(self, new_embeddings):
+ self.proj_out = new_embeddings
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.model.get_input_embeddings()
+
+ def freeze_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the Whisper encoder so that its parameters will
+ not be updated during training.
+ """
+ self.model.encoder._freeze_parameters()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.LongTensor] = None,
+ decoder_input_ids: Optional[torch.LongTensor] = None,
+ decoder_attention_mask: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ decoder_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ past_key_values: Optional[Union[Cache]] = None,
+ decoder_inputs_embeds: Optional[tuple[torch.FloatTensor]] = None,
+ decoder_position_ids: Optional[tuple[torch.LongTensor]] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple[torch.Tensor], Seq2SeqLMOutput]:
+ r"""
+ decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Indices of decoder input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`WhisperTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are decoder input IDs?](../glossary#decoder-input-ids)
+
+ Whisper uses the `decoder_start_token_id` as the starting token for `decoder_input_ids` generation. If
+ `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see
+ `past_key_values`).
+ decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*):
+ Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also
+ be used by default.
+
+ If you want to change padding behavior, you should read
+ [`modeling_whisper._prepare_decoder_attention_mask`] and modify to your needs. See diagram 1 in [the BART
+ paper](https://huggingface.co/papers/1910.13461) for more information on the default strategy.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ decoder_position_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.n_positions - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the language modeling loss. Indices should either be in `[0, ..., config.vocab_size]`
+ or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored (masked), the loss is
+ only computed for the tokens with labels in `[0, ..., config.vocab_size]`. `sequence_length` should be smaller than or equal to `config.max_target_positions`.
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoProcessor, WhisperForConditionalGeneration
+ >>> from datasets import load_dataset
+
+ >>> processor = AutoProcessor.from_pretrained("openai/whisper-tiny.en")
+ >>> model = WhisperForConditionalGeneration.from_pretrained("openai/whisper-tiny.en")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+ >>> inputs = processor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+
+ >>> generated_ids = model.generate(inputs=input_features)
+
+ >>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+ >>> transcription
+ ' Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel.'
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if labels is not None:
+ if labels.shape[1] > self.max_target_positions:
+ raise ValueError(
+ f"Labels' sequence length {labels.shape[1]} cannot exceed the maximum allowed length of {self.max_target_positions} tokens."
+ )
+ if decoder_input_ids is None and decoder_inputs_embeds is None:
+ decoder_input_ids = shift_tokens_right(
+ labels, self.config.pad_token_id, self.config.decoder_start_token_id
+ )
+
+ outputs = self.model(
+ input_features,
+ attention_mask=attention_mask,
+ decoder_input_ids=decoder_input_ids,
+ encoder_outputs=encoder_outputs,
+ decoder_attention_mask=decoder_attention_mask,
+ head_mask=head_mask,
+ decoder_head_mask=decoder_head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ decoder_inputs_embeds=decoder_inputs_embeds,
+ decoder_position_ids=decoder_position_ids,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+ lm_logits = self.proj_out(outputs[0])
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ # move labels to correct device to enable PP
+ labels = labels.to(lm_logits.device)
+ loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.reshape(-1))
+
+ if not return_dict:
+ output = (lm_logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return Seq2SeqLMOutput(
+ loss=loss,
+ logits=lm_logits,
+ past_key_values=outputs.past_key_values,
+ decoder_hidden_states=outputs.decoder_hidden_states,
+ decoder_attentions=outputs.decoder_attentions,
+ cross_attentions=outputs.cross_attentions,
+ encoder_last_hidden_state=outputs.encoder_last_hidden_state,
+ encoder_hidden_states=outputs.encoder_hidden_states,
+ encoder_attentions=outputs.encoder_attentions,
+ )
+
+
+class WhisperDecoderWrapper(WhisperPreTrainedModel):
+ """
+ This wrapper class is a helper class to correctly load pretrained checkpoints when the causal language model is
+ used in combination with the [`EncoderDecoderModel`] framework.
+ """
+
+ def __init__(self, config):
+ super().__init__(config)
+ config.is_encoder_decoder = False
+ self.decoder = WhisperDecoder(config)
+
+ def get_input_embeddings(self):
+ return self.decoder.embed_tokens
+
+ def set_input_embeddings(self, value):
+ self.decoder.embed_tokens = value
+
+ def forward(self, *args, **kwargs):
+ return self.decoder(*args, **kwargs)
+
+
+@auto_docstring(
+ custom_intro="""
+ Whisper decoder with a language modeling head on top (linear layer with weights tied to the input embeddings).
+ """
+)
+class WhisperForCausalLM(WhisperPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["proj_out.weight"]
+ main_input_name = "input_ids"
+
+ def __init__(self, config):
+ super().__init__(config)
+ config.is_encoder_decoder = False
+ self.model = WhisperDecoderWrapper(config)
+
+ self.proj_out = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.proj_out
+
+ def set_output_embeddings(self, new_embeddings):
+ self.proj_out = new_embeddings
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.model.get_input_embeddings()
+
+ def set_input_embeddings(self, value):
+ self.model.set_input_embeddings(value)
+
+ def set_decoder(self, decoder):
+ self.model.decoder = decoder
+
+ def get_decoder(self):
+ return self.model.decoder
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[torch.FloatTensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple, CausalLMOutputWithCrossAttentions]:
+ r"""
+ encoder_outputs (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention
+ if the model is configured as a decoder.
+ cross_attn_head_mask (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> from transformers import WhisperForCausalLM, WhisperForConditionalGeneration, WhisperProcessor
+ >>> import torch
+ >>> from datasets import load_dataset
+
+ >>> processor = WhisperProcessor.from_pretrained("openai/whisper-large-v2")
+ >>> model = WhisperForConditionalGeneration.from_pretrained("openai/whisper-large-v2")
+
+ >>> assistant_model = WhisperForCausalLM.from_pretrained("distil-whisper/distil-large-v2")
+
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> sample = ds[0]["audio"]
+ >>> input_features = processor(
+ ... sample["array"], sampling_rate=sample["sampling_rate"], return_tensors="pt"
+ ... ).input_features
+
+ >>> predicted_ids = model.generate(input_features, assistant_model=assistant_model)
+
+ >>> # decode token ids to text
+ >>> transcription = processor.batch_decode(predicted_ids, skip_special_tokens=True)[0]
+ >>> transcription
+ ' Mr. Quilter is the apostle of the middle classes and we are glad to welcome his gospel.'
+ ```"""
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # If the user passed a tuple or `BaseModelOutput` for encoder_outputs, we extract only the hidden states
+ if isinstance(encoder_outputs, (BaseModelOutput, tuple, list)):
+ encoder_outputs = encoder_outputs[0]
+
+ # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
+ outputs = self.model.decoder(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_outputs,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ logits = self.proj_out(outputs[0])
+
+ loss = None
+ if labels is not None:
+ labels = labels.to(logits.device)
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return (loss,) + output if loss is not None else output
+
+ return CausalLMOutputWithCrossAttentions(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ Whisper Encoder Model with a sequence classification head on top (a linear layer over the pooled output) for tasks
+ like SUPERB Keyword Spotting.
+ """
+)
+class WhisperForAudioClassification(WhisperPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.encoder = WhisperEncoder(config)
+ num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings
+ if config.use_weighted_layer_sum:
+ self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers)
+ self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size)
+ self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def freeze_encoder(self):
+ """
+ Calling this function will disable the gradient computation for the Whisper encoder so that its parameters will
+ not be updated during training. Only the projection layers and classification head will be updated.
+ """
+ self.encoder._freeze_parameters()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.encoder.get_input_embeddings()
+
+ def set_input_embeddings(self, value: nn.Module):
+ self.encoder.set_input_embeddings(value)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_features: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ encoder_outputs: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], SequenceClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+
+ Example:
+
+ ```python
+ >>> import torch
+ >>> from transformers import AutoFeatureExtractor, WhisperForAudioClassification
+ >>> from datasets import load_dataset
+
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained("sanchit-gandhi/whisper-medium-fleurs-lang-id")
+ >>> model = WhisperForAudioClassification.from_pretrained("sanchit-gandhi/whisper-medium-fleurs-lang-id")
+
+ >>> ds = load_dataset("google/fleurs", "all", split="validation", streaming=True)
+ >>> sample = next(iter(ds))
+
+ >>> inputs = feature_extractor(
+ ... sample["audio"]["array"], sampling_rate=sample["audio"]["sampling_rate"], return_tensors="pt"
+ ... )
+ >>> input_features = inputs.input_features
+
+ >>> with torch.no_grad():
+ ... logits = model(input_features).logits
+
+ >>> predicted_class_ids = torch.argmax(logits).item()
+ >>> predicted_label = model.config.id2label[predicted_class_ids]
+ >>> predicted_label
+ 'Afrikaans'
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ if self.config.use_weighted_layer_sum:
+ output_hidden_states = True
+ elif output_hidden_states is None:
+ output_hidden_states = self.config.output_hidden_states
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if encoder_outputs is None:
+ encoder_outputs = self.encoder(
+ input_features,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ if self.config.use_weighted_layer_sum:
+ hidden_states = encoder_outputs[_HIDDEN_STATES_START_POSITION]
+ hidden_states = torch.stack(hidden_states, dim=1)
+ norm_weights = nn.functional.softmax(self.layer_weights, dim=-1)
+ hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1)
+ else:
+ hidden_states = encoder_outputs[0]
+
+ hidden_states = self.projector(hidden_states)
+ pooled_output = hidden_states.mean(dim=1)
+
+ logits = self.classifier(pooled_output)
+
+ loss = None
+
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ # move labels to correct device to enable PP
+ labels = labels.to(logits.device)
+ loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + encoder_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+__all__ = [
+ "WhisperForCausalLM",
+ "WhisperForConditionalGeneration",
+ "WhisperModel",
+ "WhisperPreTrainedModel",
+ "WhisperForAudioClassification",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/processing_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/processing_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..26dd02d3c40a9351c0fb7fc5f6e8f5137df9e449
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/processing_whisper.py
@@ -0,0 +1,86 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Speech processor class for Whisper
+"""
+
+from ...processing_utils import ProcessorMixin
+
+
+class WhisperProcessor(ProcessorMixin):
+ r"""
+ Constructs a Whisper processor which wraps a Whisper feature extractor and a Whisper tokenizer into a single
+ processor.
+
+ [`WhisperProcessor`] offers all the functionalities of [`WhisperFeatureExtractor`] and [`WhisperTokenizer`]. See
+ the [`~WhisperProcessor.__call__`] and [`~WhisperProcessor.decode`] for more information.
+
+ Args:
+ feature_extractor (`WhisperFeatureExtractor`):
+ An instance of [`WhisperFeatureExtractor`]. The feature extractor is a required input.
+ tokenizer (`WhisperTokenizer`):
+ An instance of [`WhisperTokenizer`]. The tokenizer is a required input.
+ """
+
+ feature_extractor_class = "WhisperFeatureExtractor"
+ tokenizer_class = ("WhisperTokenizer", "WhisperTokenizerFast")
+
+ def __init__(self, feature_extractor, tokenizer):
+ super().__init__(feature_extractor, tokenizer)
+ self.current_processor = self.feature_extractor
+ self._in_target_context_manager = False
+
+ def get_decoder_prompt_ids(self, task=None, language=None, no_timestamps=True):
+ return self.tokenizer.get_decoder_prompt_ids(task=task, language=language, no_timestamps=no_timestamps)
+
+ def __call__(self, *args, **kwargs):
+ """
+ Forwards the `audio` argument to WhisperFeatureExtractor's [`~WhisperFeatureExtractor.__call__`] and the `text`
+ argument to [`~WhisperTokenizer.__call__`]. Please refer to the docstring of the above two methods for more
+ information.
+ """
+ # For backward compatibility
+ if self._in_target_context_manager:
+ return self.current_processor(*args, **kwargs)
+
+ audio = kwargs.pop("audio", None)
+ sampling_rate = kwargs.pop("sampling_rate", None)
+ text = kwargs.pop("text", None)
+ if len(args) > 0:
+ audio = args[0]
+ args = args[1:]
+
+ if audio is None and text is None:
+ raise ValueError("You need to specify either an `audio` or `text` input to process.")
+
+ if audio is not None:
+ inputs = self.feature_extractor(audio, *args, sampling_rate=sampling_rate, **kwargs)
+ if text is not None:
+ encodings = self.tokenizer(text, **kwargs)
+
+ if text is None:
+ return inputs
+
+ elif audio is None:
+ return encodings
+ else:
+ inputs["labels"] = encodings["input_ids"]
+ return inputs
+
+ def get_prompt_ids(self, text: str, return_tensors="np"):
+ return self.tokenizer.get_prompt_ids(text, return_tensors=return_tensors)
+
+
+__all__ = ["WhisperProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/tokenization_whisper.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/tokenization_whisper.py
new file mode 100644
index 0000000000000000000000000000000000000000..4147f14d86bd2ec95228ab5334098abf9e5920b6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/tokenization_whisper.py
@@ -0,0 +1,1420 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for Whisper."""
+
+import json
+import os
+import warnings
+from functools import lru_cache
+from typing import Optional, Union
+
+import numpy as np
+import regex as re
+
+from ...tokenization_utils import AddedToken, PreTrainedTokenizer
+from ...utils import logging
+from .english_normalizer import BasicTextNormalizer, EnglishTextNormalizer
+
+
+VOCAB_FILES_NAMES = {
+ "vocab_file": "vocab.json",
+ "tokenizer_file": "tokenizer.json",
+ "merges_file": "merges.txt",
+ "normalizer_file": "normalizer.json",
+}
+
+
+MAX_MODEL_INPUT_SIZES = {
+ "openai/whisper-base": 448,
+}
+
+
+# Copied from transformers.models.gpt2.tokenization_gpt2.bytes_to_unicode
+def bytes_to_unicode():
+ """
+ Returns list of utf-8 byte and a mapping to unicode strings. We specifically avoids mapping to whitespace/control
+ characters the bpe code barfs on.
+
+ The reversible bpe codes work on unicode strings. This means you need a large # of unicode characters in your vocab
+ if you want to avoid UNKs. When you're at something like a 10B token dataset you end up needing around 5K for
+ decent coverage. This is a significant percentage of your normal, say, 32K bpe vocab. To avoid that, we want lookup
+ tables between utf-8 bytes and unicode strings.
+ """
+ bs = (
+ list(range(ord("!"), ord("~") + 1)) + list(range(ord("¡"), ord("¬") + 1)) + list(range(ord("®"), ord("ÿ") + 1))
+ )
+ cs = bs[:]
+ n = 0
+ for b in range(2**8):
+ if b not in bs:
+ bs.append(b)
+ cs.append(2**8 + n)
+ n += 1
+ cs = [chr(n) for n in cs]
+ return dict(zip(bs, cs))
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.gpt2.tokenization_gpt2.get_pairs
+def get_pairs(word):
+ """
+ Return set of symbol pairs in a word.
+
+ Word is represented as tuple of symbols (symbols being variable-length strings).
+ """
+ pairs = set()
+ prev_char = word[0]
+ for char in word[1:]:
+ pairs.add((prev_char, char))
+ prev_char = char
+ return pairs
+
+
+LANGUAGES = {
+ "en": "english",
+ "zh": "chinese",
+ "de": "german",
+ "es": "spanish",
+ "ru": "russian",
+ "ko": "korean",
+ "fr": "french",
+ "ja": "japanese",
+ "pt": "portuguese",
+ "tr": "turkish",
+ "pl": "polish",
+ "ca": "catalan",
+ "nl": "dutch",
+ "ar": "arabic",
+ "sv": "swedish",
+ "it": "italian",
+ "id": "indonesian",
+ "hi": "hindi",
+ "fi": "finnish",
+ "vi": "vietnamese",
+ "he": "hebrew",
+ "uk": "ukrainian",
+ "el": "greek",
+ "ms": "malay",
+ "cs": "czech",
+ "ro": "romanian",
+ "da": "danish",
+ "hu": "hungarian",
+ "ta": "tamil",
+ "no": "norwegian",
+ "th": "thai",
+ "ur": "urdu",
+ "hr": "croatian",
+ "bg": "bulgarian",
+ "lt": "lithuanian",
+ "la": "latin",
+ "mi": "maori",
+ "ml": "malayalam",
+ "cy": "welsh",
+ "sk": "slovak",
+ "te": "telugu",
+ "fa": "persian",
+ "lv": "latvian",
+ "bn": "bengali",
+ "sr": "serbian",
+ "az": "azerbaijani",
+ "sl": "slovenian",
+ "kn": "kannada",
+ "et": "estonian",
+ "mk": "macedonian",
+ "br": "breton",
+ "eu": "basque",
+ "is": "icelandic",
+ "hy": "armenian",
+ "ne": "nepali",
+ "mn": "mongolian",
+ "bs": "bosnian",
+ "kk": "kazakh",
+ "sq": "albanian",
+ "sw": "swahili",
+ "gl": "galician",
+ "mr": "marathi",
+ "pa": "punjabi",
+ "si": "sinhala",
+ "km": "khmer",
+ "sn": "shona",
+ "yo": "yoruba",
+ "so": "somali",
+ "af": "afrikaans",
+ "oc": "occitan",
+ "ka": "georgian",
+ "be": "belarusian",
+ "tg": "tajik",
+ "sd": "sindhi",
+ "gu": "gujarati",
+ "am": "amharic",
+ "yi": "yiddish",
+ "lo": "lao",
+ "uz": "uzbek",
+ "fo": "faroese",
+ "ht": "haitian creole",
+ "ps": "pashto",
+ "tk": "turkmen",
+ "nn": "nynorsk",
+ "mt": "maltese",
+ "sa": "sanskrit",
+ "lb": "luxembourgish",
+ "my": "myanmar",
+ "bo": "tibetan",
+ "tl": "tagalog",
+ "mg": "malagasy",
+ "as": "assamese",
+ "tt": "tatar",
+ "haw": "hawaiian",
+ "ln": "lingala",
+ "ha": "hausa",
+ "ba": "bashkir",
+ "jw": "javanese",
+ "su": "sundanese",
+ "yue": "cantonese",
+}
+
+# language code lookup by name, with a few language aliases
+TO_LANGUAGE_CODE = {
+ **{language: code for code, language in LANGUAGES.items()},
+ "burmese": "my",
+ "valencian": "ca",
+ "flemish": "nl",
+ "haitian": "ht",
+ "letzeburgesch": "lb",
+ "pushto": "ps",
+ "panjabi": "pa",
+ "moldavian": "ro",
+ "moldovan": "ro",
+ "sinhalese": "si",
+ "castilian": "es",
+ "mandarin": "zh",
+}
+
+TASK_IDS = ["translate", "transcribe"]
+
+
+class WhisperTokenizer(PreTrainedTokenizer):
+ """
+ Construct a Whisper tokenizer.
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains some of the main methods. Users should refer to
+ the superclass for more information regarding such methods.
+
+ Args:
+ vocab_file (`str`):
+ Path to the vocabulary file.
+ merges_file (`str`):
+ Path to the merges file.
+ normalizer_file (`str`, *optional*):
+ Path to the normalizer_file file.
+ errors (`str`, *optional*, defaults to `"replace"`):
+ Paradigm to follow when decoding bytes to UTF-8. See
+ [bytes.decode](https://docs.python.org/3/library/stdtypes.html#bytes.decode) for more information.
+ unk_token (`str`, *optional*, defaults to `"<|endoftext|>"`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ bos_token (`str`, *optional*, defaults to `"<|endoftext|>"`):
+ The beginning of sequence token. The `decoder_start_token_id` is used to set the first token as
+ `"<|startoftranscript|>"` when generating.
+ eos_token (`str`, *optional*, defaults to `"<|endoftext|>"`):
+ The end of sequence token.
+ pad_token (`str`, *optional*):
+ The token used for padding, for example when batching sequences of different lengths.
+ add_prefix_space (`bool`, *optional*, defaults to `False`):
+ Whether or not to add an initial space to the input. This allows to treat the leading word just as any
+ other word.
+ language (`str`, *optional*):
+ The language of the transcription text. The corresponding language id token is appended to the start of the
+ sequence for multilingual speech recognition and speech translation tasks, e.g. for Spanish the token
+ `"<|es|>"` is appended to the start of sequence. This should be used for multilingual fine-tuning only.
+ task (`str`, *optional*):
+ Task identifier to append at the start of sequence (if any). This should be used for mulitlingual
+ fine-tuning, with `"transcribe"` for speech recognition and `"translate"` for speech translation.
+ predict_timestamps (`bool`, *optional*, defaults to `False`):
+ Whether to omit the `<|notimestamps|>` token at the start of the sequence.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ merges_file,
+ normalizer_file=None,
+ errors="replace",
+ unk_token="<|endoftext|>",
+ bos_token="<|endoftext|>",
+ eos_token="<|endoftext|>",
+ pad_token=None,
+ add_prefix_space=False,
+ language=None,
+ task=None,
+ predict_timestamps=False,
+ **kwargs,
+ ):
+ bos_token = (
+ AddedToken(bos_token, lstrip=False, rstrip=False, normalized=False, special=True)
+ if isinstance(bos_token, str)
+ else bos_token
+ )
+ eos_token = (
+ AddedToken(eos_token, lstrip=False, rstrip=False, normalized=False, special=True)
+ if isinstance(eos_token, str)
+ else eos_token
+ )
+ unk_token = (
+ AddedToken(unk_token, lstrip=False, rstrip=False, normalized=False, special=True)
+ if isinstance(unk_token, str)
+ else unk_token
+ )
+ pad_token = (
+ AddedToken(pad_token, lstrip=False, rstrip=False, normalized=False, special=True)
+ if isinstance(pad_token, str)
+ else pad_token
+ )
+
+ with open(vocab_file, encoding="utf-8") as vocab_handle:
+ self.encoder = json.load(vocab_handle)
+ self.decoder = {v: k for k, v in self.encoder.items()}
+ self.errors = errors # how to handle errors in decoding
+ self.byte_encoder = bytes_to_unicode()
+ self.byte_decoder = {v: k for k, v in self.byte_encoder.items()}
+ with open(merges_file, encoding="utf-8") as merges_handle:
+ bpe_merges = merges_handle.read().split("\n")[1:-1]
+ bpe_merges = [tuple(merge.split()) for merge in bpe_merges]
+ self.bpe_ranks = dict(zip(bpe_merges, range(len(bpe_merges))))
+ self.cache = {}
+ self.add_prefix_space = add_prefix_space
+
+ if normalizer_file is not None:
+ with open(normalizer_file, encoding="utf-8") as vocab_handle:
+ self.english_spelling_normalizer = json.load(vocab_handle)
+ else:
+ self.english_spelling_normalizer = None
+
+ # Should have added re.IGNORECASE so BPE merges can happen for capitalized versions of contractions
+ self.pat = re.compile(r"""'s|'t|'re|'ve|'m|'ll|'d| ?\p{L}+| ?\p{N}+| ?[^\s\p{L}\p{N}]+|\s+(?!\S)|\s+""")
+ self.timestamp_pat = re.compile(r"<\|(\d+\.\d+)\|>")
+
+ self.language = language
+ super().__init__(
+ errors=errors,
+ unk_token=unk_token,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ pad_token=pad_token,
+ add_prefix_space=add_prefix_space,
+ **kwargs,
+ )
+
+ self.task = task
+ self.predict_timestamps = predict_timestamps
+
+ @property
+ def vocab_size(self) -> int:
+ return len(self.encoder)
+
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ # Copied from transformers.models.gpt2.tokenization_gpt2.GPT2Tokenizer.bpe with GPT2 -> Whisper
+ def bpe(self, token):
+ if token in self.cache:
+ return self.cache[token]
+ word = tuple(token)
+ pairs = get_pairs(word)
+
+ if not pairs:
+ return token
+
+ while True:
+ bigram = min(pairs, key=lambda pair: self.bpe_ranks.get(pair, float("inf")))
+ if bigram not in self.bpe_ranks:
+ break
+ first, second = bigram
+ new_word = []
+ i = 0
+ while i < len(word):
+ try:
+ j = word.index(first, i)
+ except ValueError:
+ new_word.extend(word[i:])
+ break
+ else:
+ new_word.extend(word[i:j])
+ i = j
+
+ if word[i] == first and i < len(word) - 1 and word[i + 1] == second:
+ new_word.append(first + second)
+ i += 2
+ else:
+ new_word.append(word[i])
+ i += 1
+ new_word = tuple(new_word)
+ word = new_word
+ if len(word) == 1:
+ break
+ else:
+ pairs = get_pairs(word)
+ word = " ".join(word)
+ self.cache[token] = word
+ return word
+
+ def set_prefix_tokens(
+ self, language: Optional[str] = None, task: Optional[str] = None, predict_timestamps: Optional[bool] = None
+ ):
+ """
+ Override the prefix tokens appended to the start of the label sequence. This method can be used standalone to
+ update the prefix tokens as required when fine-tuning. Example:
+
+ ```python
+ >>> # instantiate the tokenizer and set the prefix token to Spanish
+ >>> tokenizer = WhisperTokenizer.from_pretrained("openai/whisper-tiny", language="spanish")
+ >>> # now switch the prefix token from Spanish to French
+ >>> tokenizer.set_prefix_tokens(language="french")
+ ```
+
+ Args:
+ language (`str`, *optional*, defaults to `None`):
+ The language of the transcription text.
+ task (`str`, *optional*, defaults to `None`):
+ Task identifier to append at the start of sequence (if any).
+ predict_timestamps (`bool`, *optional*, defaults to `None`):
+ Whether to omit the `<|notimestamps|>` token at the start of the sequence.
+ """
+ self.language = language if language is not None else self.language
+ self.task = task if task is not None else self.task
+ self.predict_timestamps = predict_timestamps if predict_timestamps is not None else self.predict_timestamps
+
+ @property
+ def prefix_tokens(self) -> list[int]:
+ bos_token_id = self.convert_tokens_to_ids("<|startoftranscript|>")
+ translate_token_id = self.convert_tokens_to_ids("<|translate|>")
+ transcribe_token_id = self.convert_tokens_to_ids("<|transcribe|>")
+ notimestamps_token_id = self.convert_tokens_to_ids("<|notimestamps|>")
+ langs = tuple(LANGUAGES.keys())
+
+ if self.language is not None:
+ self.language = self.language.lower()
+ if self.language in TO_LANGUAGE_CODE:
+ language_id = TO_LANGUAGE_CODE[self.language]
+ elif self.language in TO_LANGUAGE_CODE.values():
+ language_id = self.language
+ else:
+ is_language_code = len(self.language) == 2
+ raise ValueError(
+ f"Unsupported language: {self.language}. Language should be one of:"
+ f" {list(TO_LANGUAGE_CODE.values()) if is_language_code else list(TO_LANGUAGE_CODE.keys())}."
+ )
+
+ if self.task is not None:
+ if self.task not in TASK_IDS:
+ raise ValueError(f"Unsupported task: {self.task}. Task should be in: {TASK_IDS}")
+
+ bos_sequence = [bos_token_id]
+ if self.language is not None:
+ bos_sequence.append(bos_token_id + 1 + langs.index(language_id))
+ if self.task is not None:
+ bos_sequence.append(transcribe_token_id if self.task == "transcribe" else translate_token_id)
+ if not self.predict_timestamps:
+ bos_sequence.append(notimestamps_token_id)
+ return bos_sequence
+
+ # Copied from transformers.models.speech_to_text.tokenization_speech_to_text.Speech2TextTokenizer.build_inputs_with_special_tokens
+ def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None) -> list[int]:
+ """Build model inputs from a sequence by appending eos_token_id."""
+ if token_ids_1 is None:
+ return self.prefix_tokens + token_ids_0 + [self.eos_token_id]
+ # We don't expect to process pairs, but leave the pair logic for API consistency
+ return self.prefix_tokens + token_ids_0 + token_ids_1 + [self.eos_token_id]
+
+ # Copied from transformers.models.speech_to_text.tokenization_speech_to_text.Speech2TextTokenizer.get_special_tokens_mask
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ prefix_ones = [1] * len(self.prefix_tokens)
+ suffix_ones = [1]
+ if token_ids_1 is None:
+ return prefix_ones + ([0] * len(token_ids_0)) + suffix_ones
+ return prefix_ones + ([0] * len(token_ids_0)) + ([0] * len(token_ids_1)) + suffix_ones
+
+ # Copied from transformers.models.gpt2.tokenization_gpt2.GPT2Tokenizer._tokenize with GPT2 -> Whisper
+ def _tokenize(self, text):
+ """Tokenize a string."""
+ bpe_tokens = []
+ for token in re.findall(self.pat, text):
+ token = "".join(
+ self.byte_encoder[b] for b in token.encode("utf-8")
+ ) # Maps all our bytes to unicode strings, avoiding control tokens of the BPE (spaces in our case)
+ bpe_tokens.extend(bpe_token for bpe_token in self.bpe(token).split(" "))
+ return bpe_tokens
+
+ # Copied from transformers.models.gpt2.tokenization_gpt2.GPT2Tokenizer._convert_token_to_id with GPT2 -> Whisper
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.encoder.get(token, self.encoder.get(self.unk_token))
+
+ def _convert_id_to_token(self, index):
+ """
+ Converts an index (integer) in a token (str) using the vocab. Whisper's base tokenizer always decodes OOV
+ tokens as "", thus we do not use the `unk_token` here.
+ """
+ return self.decoder.get(index, "")
+
+ def _normalize(self, text):
+ warnings.warn(
+ "The private method `_normalize` is deprecated and will be removed in v5 of Transformers."
+ "You can normalize an input string using the Whisper English normalizer using the `normalize` method."
+ )
+ return self.normalize(text)
+
+ def _basic_normalize(self, text, remove_diacritics=False):
+ warnings.warn(
+ "The private method `_basic_normalize` is deprecated and will be removed in v5 of Transformers."
+ "You can normalize an input string using the Whisper basic normalizer using the `basic_normalize` method."
+ )
+ return self.basic_normalize(text, remove_diacritics=remove_diacritics)
+
+ def normalize(self, text):
+ """
+ Normalize a given string using the `EnglishTextNormalizer` class, which performs commons transformation on
+ english text.
+ """
+ normalizer = EnglishTextNormalizer(self.english_spelling_normalizer)
+ return normalizer(text)
+
+ @staticmethod
+ def basic_normalize(text, remove_diacritics=False):
+ """
+ Normalize a given string using the `BasicTextNormalizer` class, which performs commons transformation on
+ multilingual text.
+ """
+ normalizer = BasicTextNormalizer(remove_diacritics=remove_diacritics)
+ return normalizer(text)
+
+ def _decode_with_timestamps(
+ self, token_ids, skip_special_tokens=False, time_precision=0.02, segment_size=1500
+ ) -> str:
+ """
+ Timestamp tokens are above the special tokens' id range and are ignored by `decode()`. This method decodes
+ given tokens with timestamps tokens annotated, e.g. "<|1.08|>".
+ """
+ timestamp_begin = self.all_special_ids[-1] + 1
+ outputs = [[]]
+
+ cur_max_timestamp = 0.0
+ prev_segments_len = 0.0
+ penultimate_timestamp = 0.0
+
+ for i, token in enumerate(token_ids):
+ if token >= timestamp_begin:
+ timestamp = float((token - timestamp_begin) * time_precision)
+
+ if timestamp < cur_max_timestamp:
+ # next segment has started
+ last_was_single_ending = i >= 2 and not (
+ token_ids[i - 1] >= timestamp_begin and token_ids[i - 2] >= timestamp_begin
+ )
+ if last_was_single_ending:
+ prev_segments_len += time_precision * segment_size
+ else:
+ cur_max_timestamp = penultimate_timestamp
+ prev_segments_len += penultimate_timestamp
+ outputs = outputs[:-2]
+
+ penultimate_timestamp = cur_max_timestamp
+ cur_max_timestamp = timestamp
+
+ outputs.append(f"<|{(timestamp + prev_segments_len):.2f}|>")
+ outputs.append([])
+ else:
+ outputs[-1].append(token)
+ outputs = [
+ s if isinstance(s, str) else self.decode(s, skip_special_tokens=skip_special_tokens) for s in outputs
+ ]
+ return "".join(outputs)
+
+ def _compute_offsets(self, token_ids, time_precision=0.02, segment_size=1500):
+ """
+ Compute offsets for a given tokenized input
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ time_precision (`float`, *optional*, defaults to 0.02):
+ The time ratio to convert from token to time.
+ segment_size (`int`, *optional*, defaults to 1500):
+ The number of features in the input mel spectrogram.
+ """
+ offsets = []
+ # ensure torch tensor of token ids is placed on cpu
+ if "torch" in str(type(token_ids)) and (hasattr(token_ids, "cpu") and callable(token_ids.cpu)):
+ token_ids = token_ids.cpu()
+ token_ids = np.array(token_ids)
+ if token_ids.shape[0] > 1 and len(token_ids.shape) > 1:
+ raise ValueError("Can only process a single input at a time")
+ timestamp_begin = self.all_special_ids[-1] + 1
+ timestamp_tokens = token_ids >= timestamp_begin
+
+ consecutive = np.where(timestamp_tokens[:-1] & timestamp_tokens[1:])[0] + 1
+ if consecutive.shape[0] == 0 and timestamp_tokens.sum() <= 1:
+ # either there are no timestamps or there are no consecutive ones
+ return []
+ elif np.where(timestamp_tokens)[0][-1] + 1 not in consecutive:
+ # we add the final timestamp if it is not already in the list
+ consecutive = np.append(consecutive, np.where(timestamp_tokens)[0][-1] + 1)
+
+ last_slice = np.where(timestamp_tokens)[0][0]
+ cur_max_timestamp = 0
+ prev_segments_len = 0
+ for current_slice in consecutive:
+ sliced_tokens = token_ids[last_slice:current_slice]
+ if len(sliced_tokens) > 1:
+ start_timestamp_position = sliced_tokens[0].item() - timestamp_begin
+ end_timestamp_position = sliced_tokens[-1].item() - timestamp_begin
+
+ if start_timestamp_position < cur_max_timestamp:
+ # next segment has started
+ is_single_ending = last_slice >= 2 and not (
+ token_ids[last_slice - 2] >= timestamp_begin and token_ids[last_slice - 1] >= timestamp_begin
+ )
+ if is_single_ending:
+ prev_segments_len += segment_size
+ else:
+ prev_segments_len += cur_max_timestamp
+
+ cur_max_timestamp = end_timestamp_position
+
+ # strip timestamp tokens from the text output
+ sliced_tokens = self._preprocess_token_ids(sliced_tokens)
+ text = self._decode(sliced_tokens)
+ text = self._filter_timestamp_ids(text)
+ offsets.append(
+ {
+ "text": text,
+ "timestamp": (
+ start_timestamp_position * time_precision + prev_segments_len * time_precision,
+ end_timestamp_position * time_precision + prev_segments_len * time_precision,
+ ),
+ }
+ )
+ last_slice = current_slice
+
+ return offsets
+
+ @lru_cache
+ def timestamp_ids(self, time_precision=0.02):
+ """
+ Compute the timestamp token ids for a given precision and save to least-recently used (LRU) cache.
+
+ Args:
+ time_precision (`float`, *optional*, defaults to 0.02):
+ The time ratio to convert from token to time.
+ """
+ return self.convert_tokens_to_ids([("<|%.2f|>" % (i * time_precision)) for i in range(1500 + 1)])
+
+ def _preprocess_token_ids(self, token_ids, skip_special_tokens: bool = False):
+ """
+ Pre-process the token ids for decoding by removing the prompt tokens ids and timestamp token ids.
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Typically, obtained using the `__call__` method of the tokenizer.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens from the token ids. If `True`, the prompt token ids will be
+ removed.
+ """
+ if skip_special_tokens:
+ prompt_token_id = self.convert_tokens_to_ids("<|startofprev|>")
+ decoder_start_token_id = self.convert_tokens_to_ids("<|startoftranscript|>")
+ token_ids = self._strip_prompt(token_ids, prompt_token_id, decoder_start_token_id)
+
+ return token_ids
+
+ def _filter_timestamp_ids(self, token_ids):
+ return re.sub(self.timestamp_pat, "", token_ids)
+
+ def decode(
+ self,
+ token_ids,
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ output_offsets: bool = False,
+ time_precision: float = 0.02,
+ decode_with_timestamps: bool = False,
+ normalize: bool = False,
+ basic_normalize: bool = False,
+ remove_diacritics: bool = False,
+ **kwargs,
+ ) -> str:
+ """
+ Converts a sequence of ids in a string, using the tokenizer and vocabulary with options to remove special
+ tokens and clean up tokenization spaces.
+
+ Similar to doing `self.convert_tokens_to_string(self.convert_ids_to_tokens(token_ids))`.
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens in the decoding. Will remove the previous tokens (pre-prompt)
+ if present.
+ clean_up_tokenization_spaces (`bool`, *optional*):
+ Whether or not to clean up the tokenization spaces. If `None`, will default to
+ `self.clean_up_tokenization_spaces` (available in the `tokenizer_config`).
+ output_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output the offsets of the tokens. This should only be set if the model predicted
+ timestamps. If there are previous tokens (pre-prompt) to decode, they will only appear in the decoded
+ text if they contain timestamp tokens.
+ time_precision (`float`, *optional*, defaults to 0.02):
+ The time ratio to convert from token to time.
+ decode_with_timestamps (`bool`, *optional*, defaults to `False`):
+ Whether or not to decode with timestamps included in the raw text.
+ normalize (`bool`, *optional*, defaults to `False`):
+ Whether or not to apply the English text normalizer to the decoded text. Only applicable when the
+ target text is in English. Otherwise, the basic text normalizer should be applied.
+ basic_normalize (`bool`, *optional*, defaults to `False`):
+ Whether or not to apply the Basic text normalizer to the decoded text. Applicable to multilingual
+ target text.
+ remove_diacritics (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove diacritics when applying the Basic text normalizer. Removing diacritics may
+ destroy information in the decoded text, hence it should be used with caution.
+ kwargs (additional keyword arguments, *optional*):
+ Will be passed to the underlying model specific decode method.
+ Returns:
+ `str`: The decoded sentence.
+ """
+ filtered_ids = self._preprocess_token_ids(
+ token_ids,
+ skip_special_tokens=skip_special_tokens,
+ )
+
+ text = super().decode(
+ filtered_ids,
+ skip_special_tokens=skip_special_tokens,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ normalize=normalize,
+ basic_normalize=basic_normalize,
+ remove_diacritics=remove_diacritics,
+ **kwargs,
+ )
+ if decode_with_timestamps:
+ # legacy method to decode timestamps when not included in the tokenizer vocabulary
+ text = self._decode_with_timestamps(
+ filtered_ids, time_precision=time_precision, skip_special_tokens=skip_special_tokens
+ )
+ else:
+ text = self._filter_timestamp_ids(text)
+
+ # retrieve offsets
+ if output_offsets:
+ offsets = self._compute_offsets(token_ids, time_precision=time_precision)
+ return {"text": text, "offsets": offsets}
+ return text
+
+ def _decode(
+ self,
+ token_ids: Union[int, list[int]],
+ skip_special_tokens: bool = False,
+ normalize: bool = False,
+ basic_normalize: bool = False,
+ remove_diacritics: bool = False,
+ **kwargs,
+ ) -> str:
+ self._decode_use_source_tokenizer = kwargs.pop("use_source_tokenizer", False)
+ filtered_tokens = self.convert_ids_to_tokens(token_ids, skip_special_tokens=skip_special_tokens)
+
+ # To avoid mixing byte-level and unicode for byte-level BPT
+ # we need to build string separately for added tokens and byte-level tokens
+ # cf. https://github.com/huggingface/transformers/issues/1133
+ sub_texts = []
+ current_sub_text = []
+ for token in filtered_tokens:
+ if skip_special_tokens and token in self.all_special_ids:
+ continue
+ if token in self.added_tokens_encoder:
+ if current_sub_text:
+ sub_texts.append(self.convert_tokens_to_string(current_sub_text))
+ current_sub_text = []
+ sub_texts.append(token)
+ else:
+ current_sub_text.append(token)
+ if current_sub_text:
+ sub_texts.append(self.convert_tokens_to_string(current_sub_text))
+
+ text = "".join(sub_texts)
+
+ if normalize:
+ clean_text = self.normalize(text)
+ return clean_text
+ elif basic_normalize:
+ clean_text = self.basic_normalize(text, remove_diacritics=remove_diacritics)
+ return clean_text
+ else:
+ return text
+
+ # Copied from transformers.models.gpt2.tokenization_gpt2.GPT2Tokenizer.convert_tokens_to_string with GPT2 -> Whisper
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ text = "".join(tokens)
+ text = bytearray([self.byte_decoder[c] for c in text]).decode("utf-8", errors=self.errors)
+ return text
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+ merge_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["merges_file"]
+ )
+ normalizer_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["normalizer_file"]
+ )
+
+ with open(vocab_file, "w", encoding="utf-8") as f:
+ f.write(json.dumps(self.encoder, indent=2, sort_keys=True, ensure_ascii=False) + "\n")
+
+ index = 0
+ with open(merge_file, "w", encoding="utf-8") as writer:
+ writer.write("#version: 0.2\n")
+ for bpe_tokens, token_index in sorted(self.bpe_ranks.items(), key=lambda kv: kv[1]):
+ if index != token_index:
+ logger.warning(
+ f"Saving vocabulary to {merge_file}: BPE merge indices are not consecutive."
+ " Please check that the tokenizer is not corrupted!"
+ )
+ index = token_index
+ writer.write(" ".join(bpe_tokens) + "\n")
+ index += 1
+
+ if self.english_spelling_normalizer is not None:
+ with open(normalizer_file, "w", encoding="utf-8") as f:
+ f.write(
+ json.dumps(self.english_spelling_normalizer, indent=2, sort_keys=True, ensure_ascii=False) + "\n"
+ )
+
+ return vocab_file, merge_file, normalizer_file
+
+ # Copied from transformers.models.gpt2.tokenization_gpt2.GPT2Tokenizer.prepare_for_tokenization with GPT2 -> Whisper
+ def prepare_for_tokenization(self, text, is_split_into_words=False, **kwargs):
+ add_prefix_space = kwargs.pop("add_prefix_space", self.add_prefix_space)
+ if is_split_into_words or add_prefix_space:
+ text = " " + text
+ return (text, kwargs)
+
+ def get_decoder_prompt_ids(self, task=None, language=None, no_timestamps=True):
+ self.set_prefix_tokens(task=task, language=language, predict_timestamps=not no_timestamps)
+ # prefix tokens are of the form: <|startoftranscript|> <|lang_id|> <|task|> <|notimestamps|>
+ # we don't want to force the bos token at position 1, as this is the starting token
+ # when we generate, so we slice the prefix tokens to: <|lang_id|> <|task|> <|notimestamps|>
+ # to get the forced tokens
+ forced_tokens = self.prefix_tokens[1:]
+ forced_decoder_ids = [(rank + 1, token) for rank, token in enumerate(forced_tokens)]
+ return forced_decoder_ids
+
+ def _decode_asr(self, model_outputs, *, return_timestamps, return_language, time_precision):
+ return _decode_asr(
+ self,
+ model_outputs,
+ return_timestamps=return_timestamps,
+ return_language=return_language,
+ time_precision=time_precision,
+ )
+
+ def get_prompt_ids(self, text: str, return_tensors="np"):
+ """Converts prompt text to IDs that can be passed to [`~WhisperForConditionalGeneration.generate`]."""
+ batch_encoding = self("<|startofprev|>", " " + text.strip(), add_special_tokens=False)
+
+ # Check for special tokens
+ prompt_text_ids = batch_encoding["input_ids"][1:]
+ special_token_id = next((x for x in prompt_text_ids if x >= self.all_special_ids[0]), None)
+ if special_token_id is not None:
+ token = self.convert_ids_to_tokens(special_token_id)
+ raise ValueError(f"Encountered text in the prompt corresponding to disallowed special token: {token}.")
+
+ batch_encoding.convert_to_tensors(tensor_type=return_tensors)
+ return batch_encoding["input_ids"]
+
+ def _strip_prompt(self, token_ids: list[int], prompt_token_id: int, decoder_start_token_id: int):
+ if not isinstance(token_ids, list):
+ token_ids = self._convert_to_list(token_ids)
+
+ # handle case of empty token_ids for decoding with timestamps.
+ # at this point token_ids is a list, so it is safe to use if not check.
+ if not token_ids:
+ return token_ids
+
+ has_prompt = token_ids[0] == prompt_token_id
+ if has_prompt:
+ if decoder_start_token_id in token_ids:
+ return token_ids[token_ids.index(decoder_start_token_id) :]
+ else:
+ return []
+
+ return token_ids
+
+ @staticmethod
+ def _convert_to_list(token_ids):
+ # convert type to ndarray if necessary
+ if hasattr(token_ids, "numpy"):
+ if "torch" in str(type(token_ids)):
+ token_ids = token_ids.cpu().numpy()
+ elif "tensorflow" in str(type(token_ids)):
+ token_ids = token_ids.numpy()
+ elif "jaxlib" in str(type(token_ids)):
+ token_ids = token_ids.tolist()
+ # now the token ids are either a numpy array, or a list of lists
+ if isinstance(token_ids, np.ndarray):
+ token_ids = token_ids.tolist()
+ return token_ids
+
+
+def _decode_asr(tokenizer, model_outputs, *, return_timestamps, return_language, time_precision, segment_size=1500):
+ """
+ Internal method meant to only be used by asr pipeline. Handles all the little quirks specific to whisper to handle
+ the various options not allowed in other seq2seq models
+ """
+
+ # =========== Overview ============
+ # - iterate over all outputs
+ # - all tokens within output
+ # - Each token can be
+ # - language token
+ # - special token
+ # - timestamp token
+ # - text token
+ # - We accumulate the text tokens.
+ # - We split on end timestamps
+ # - Lots of complexity comes from stride and timestamps
+
+ last_language = None
+
+ def new_chunk():
+ return {"language": last_language, "timestamp": [None, None], "text": ""}
+
+ # Welcome to the state machine !
+ chunks = []
+ chunk = new_chunk()
+ time_offset = 0.0
+ timestamp_begin = tokenizer.convert_tokens_to_ids("<|notimestamps|>") + 1
+ previous_tokens = []
+ previous_token_timestamps = []
+ skip = False
+ right_stride_start = None
+
+ all_special_ids = set(tokenizer.all_special_ids)
+ prompt_token_id = tokenizer.convert_tokens_to_ids("<|startofprev|>")
+ decoder_start_token_id = tokenizer.convert_tokens_to_ids("<|startoftranscript|>")
+ # - iterate over all outputs
+ for chunk_id, output in enumerate(model_outputs):
+ # We can drop everything to Python list, it's going to make
+ # our lives easier
+ token_ids = output["tokens"][0].tolist()
+ # (possibly) remove the prompt from the token ids
+ token_ids = tokenizer._strip_prompt(token_ids, prompt_token_id, decoder_start_token_id)
+ if return_timestamps == "word":
+ token_timestamps = output["token_timestamps"][0].tolist()
+
+ # Those keep track of timestamps within strides
+ # Which need to be skipped and resolve all tokens in a single
+ # chunk.
+ last_timestamp = None
+ first_timestamp = timestamp_begin
+
+ # long form generation: we need to handle the case where the call to generate returns concatenated segments,
+ # with underlying multiple calls to generate
+ cur_max_timestamp = 0.0
+ prev_segments_len = 0.0
+ penultimate_timestamp = 0.0
+
+ if "stride" in output:
+ chunk_len, stride_left, stride_right = output["stride"]
+ # Offset the timings to account for the other `model_outputs`.
+ time_offset -= stride_left
+ right_stride_start = chunk_len - stride_right
+
+ # Keeping track of timestamps within strides
+ # We're going to NOT split on those, and delay until we're
+ # out of BOTH stride. Otherwise lots of issues occur and
+ # corner cases
+ if stride_left:
+ first_timestamp = stride_left / time_precision + timestamp_begin
+ if stride_right:
+ for token in reversed(token_ids):
+ if token >= timestamp_begin:
+ # There can be several token in the right stride
+ # But the last one is ALWAYS going to be skipped
+ if (
+ last_timestamp is not None
+ and (token - timestamp_begin) * time_precision < right_stride_start
+ ):
+ break
+ last_timestamp = token
+
+ current_tokens = []
+ current_token_timestamps = []
+
+ # - all tokens within output
+ for i, token in enumerate(token_ids):
+ # 4 possible states for each token
+ # - 1/ Language code
+ # - 2/ all other special tokens (which we ignore)
+ # - 3/ Timestamp
+ # - 4/ Regular text
+ if token in all_special_ids:
+ # Either language code or other
+ text = tokenizer.decode([token])
+ # Removing outer shell <|XX|>
+ text = text[2:-2]
+ language = LANGUAGES.get(text)
+ if language is not None:
+ # 1/ Indeed some language
+ # TODO Handle when language is different from the previous
+ # one, and we cannot use timestamped tokens to create chunks
+ if last_language and language != last_language and not return_timestamps:
+ previous_tokens.append(current_tokens)
+ resolved_tokens = _find_longest_common_sequence(previous_tokens)
+ resolved_text = tokenizer.decode(resolved_tokens)
+ chunk["text"] = resolved_text
+ chunks.append(chunk)
+
+ # Flush all our temporary context
+ previous_tokens = []
+ current_tokens = []
+ chunk = new_chunk()
+ chunk["language"] = language
+ last_language = language
+ else:
+ # 2/ This is a regular special token, ignoring it
+ pass
+ elif token >= timestamp_begin:
+ # 3/ Timestamp token
+
+ timestamp = float((token - timestamp_begin) * time_precision)
+ if timestamp < cur_max_timestamp:
+ # next segment has started
+ last_was_single_ending = i >= 2 and not (
+ token_ids[i - 1] >= timestamp_begin and token_ids[i - 2] >= timestamp_begin
+ )
+ if last_was_single_ending:
+ prev_segments_len += time_precision * segment_size
+ else:
+ cur_max_timestamp = penultimate_timestamp
+ prev_segments_len += penultimate_timestamp
+
+ penultimate_timestamp = cur_max_timestamp
+ cur_max_timestamp = timestamp
+
+ time = (token - timestamp_begin) * time_precision + time_offset + prev_segments_len
+
+ time = round(time, 2)
+ if last_timestamp and token >= last_timestamp:
+ # Whisper outputted a timestamp token, but it falls within
+ # our stride, so we're going to skip it for the time being
+ # and resolve this later
+ # Skip is necessary because timestamp tokens always come
+ # by pair, so we need to skip the next one too (which would mark the start of another chunk).
+ skip = True
+ elif skip or (previous_tokens and token < first_timestamp):
+ skip = False
+ elif chunk["timestamp"][0] is None:
+ chunk["timestamp"][0] = time
+ else:
+ # This is the end of the timestamp chunk
+ if time == chunk["timestamp"][0]:
+ # This is a bug in timestamp token output
+ # where we're taking the duplicate token
+ # as a stop where it should be a start.
+ # This is an issue in the underlying model output
+ # Let's just skip it so it becomes de-factor
+ # a start again
+ pass
+ else:
+ chunk["timestamp"][1] = time
+ # Handling merges.
+ previous_tokens.append(current_tokens)
+ if return_timestamps == "word":
+ previous_token_timestamps.append(current_token_timestamps)
+ resolved_tokens, resolved_token_timestamps = _find_longest_common_sequence(
+ previous_tokens, previous_token_timestamps
+ )
+ resolved_text = tokenizer.decode(resolved_tokens)
+ chunk["text"] = resolved_text
+ if return_timestamps == "word":
+ chunk["words"] = _collate_word_timestamps(
+ tokenizer, resolved_tokens, resolved_token_timestamps, last_language, return_language
+ )
+ chunks.append(chunk)
+
+ # Flush all our temporary context
+ previous_tokens = []
+ current_tokens = []
+ previous_token_timestamps = []
+ current_token_timestamps = []
+ chunk = new_chunk()
+ else:
+ # 4/ Regular token
+ # We just append to the list of all tokens so we can handle
+ # merges later and decode into text.
+ current_tokens.append(token)
+ if return_timestamps == "word":
+ if i == 0:
+ start_time = round(0.0 + time_offset, 2)
+ else:
+ start_time = round(token_timestamps[i - 1] + time_offset, 2)
+ end_time = round(token_timestamps[i] + time_offset, 2)
+ current_token_timestamps.append((start_time, end_time))
+
+ if "stride" in output:
+ time_offset += chunk_len - stride_right
+
+ # Leftover tokens
+ if current_tokens:
+ previous_tokens.append(current_tokens)
+ if return_timestamps == "word":
+ previous_token_timestamps.append(current_token_timestamps)
+ elif not (any(p for p in previous_tokens)):
+ chunk = new_chunk()
+ previous_tokens = []
+ current_tokens = []
+ previous_token_timestamps = []
+ current_token_timestamps = []
+
+ if previous_tokens:
+ if return_timestamps:
+ logger.warning(
+ "Whisper did not predict an ending timestamp, which can happen if audio is cut off in the middle of a word. "
+ "Also make sure WhisperTimeStampLogitsProcessor was used during generation."
+ )
+ # Happens when we don't use timestamps
+ resolved_tokens, resolved_token_timestamps = _find_longest_common_sequence(
+ previous_tokens, previous_token_timestamps
+ )
+ resolved_text = tokenizer.decode(resolved_tokens)
+ chunk["text"] = resolved_text
+ if return_timestamps == "word":
+ chunk["words"] = _collate_word_timestamps(
+ tokenizer, resolved_tokens, resolved_token_timestamps, last_language, return_language
+ )
+ chunks.append(chunk)
+
+ # Preparing and cleaning up the pipeline output
+ full_text = "".join(chunk["text"] for chunk in chunks)
+ if return_timestamps or return_language:
+ for chunk in chunks:
+ if not return_timestamps:
+ chunk.pop("timestamp")
+ else:
+ chunk["timestamp"] = tuple(chunk["timestamp"])
+ if not return_language:
+ chunk.pop("language")
+
+ if return_timestamps == "word":
+ new_chunks = []
+ for chunk in chunks:
+ new_chunks.extend(chunk["words"])
+ optional = {"chunks": new_chunks}
+ else:
+ optional = {"chunks": chunks}
+ else:
+ optional = {}
+ return full_text, optional
+
+
+def _find_longest_common_sequence(sequences, token_timestamp_sequences=None):
+ # It would be much harder to do O(n) because of fault tolerance.
+ # We actually have a really good property which is that the total sequence
+ # MUST be those subsequences in order.
+ # If token_timestamp_sequences is provided, will split those sequences in
+ # exactly the same way.
+
+ left_sequence = sequences[0]
+ left_length = len(left_sequence)
+ total_sequence = []
+
+ if token_timestamp_sequences:
+ left_token_timestamp_sequence = token_timestamp_sequences[0]
+ total_token_timestamp_sequence = []
+
+ for seq_idx, right_sequence in enumerate(sequences[1:]):
+ # index = 0
+ max_ = 0.0
+ max_indices = (left_length, left_length, 0, 0)
+ # Here we're sliding matches
+ # [a, b, c, d]
+ # [c, d, f]
+ # = [c] == [d]
+ #
+ # [a, b, c, d]
+ # [c, d, f]
+ # = [c, d] == [c, d]
+ #
+ #
+ # [a, b, c, d]
+ # [c, d, f]
+ #
+ # = [b, c, d] == [c, d, f]
+ #
+ # [a, b, c, d]
+ # [c, d, f]
+ #
+ # [a, b, c] == [c, d, f]
+ #
+ # [a, b, c, d]
+ # [d, f]
+ #
+ # [a, b] == [d, f]
+ #
+ # [a, b, c, d]
+ # [f]
+ #
+ # [a] == [f]
+ right_length = len(right_sequence)
+ for i in range(1, left_length + right_length):
+ # epsilon to favor long perfect matches
+ eps = i / 10000.0
+
+ # Slightly convoluted because we don't want out of bound indices
+ # This will be necessary for a small conflict resolution optimization
+ # later
+ left_start = max(0, left_length - i)
+ left_stop = min(left_length, left_length + right_length - i)
+ left = np.array(left_sequence[left_start:left_stop])
+
+ right_start = max(0, i - left_length)
+ right_stop = min(right_length, i)
+ right = np.array(right_sequence[right_start:right_stop])
+
+ # We can only match subsequences of the same size.
+ if len(left) != len(right):
+ raise RuntimeError(
+ "There is a bug within whisper `decode_asr` function, please report it. Dropping to prevent bad inference."
+ )
+
+ if token_timestamp_sequences:
+ # Get length of longest subsequence of tokens that match
+ # and have timestamps that are in order
+ matches = sum(
+ 1
+ for idx, elem in enumerate(left)
+ if (
+ elem == right[idx]
+ and left_token_timestamp_sequence[left_start + idx]
+ <= token_timestamp_sequences[seq_idx + 1][right_start + idx]
+ )
+ )
+
+ else:
+ matches = np.sum(left == right)
+
+ matching = matches / i + eps
+ if matches > 1 and matching > max_:
+ max_ = matching
+ max_indices = (left_start, left_stop, right_start, right_stop)
+
+ (left_start, left_stop, right_start, right_stop) = max_indices
+
+ # This is a small conflict optimization since those sequences overlap
+ # in audio.
+ # We're going to give more confidence to the left sequence
+ # for the left of the overlap,
+ # and to the right of the sequence, for the right of the overlap
+ left_mid = (left_stop + left_start) // 2
+ right_mid = (right_stop + right_start) // 2
+ total_sequence.extend(left_sequence[:left_mid])
+ left_sequence = right_sequence[right_mid:]
+ left_length = len(left_sequence)
+
+ if token_timestamp_sequences:
+ total_token_timestamp_sequence.extend(left_token_timestamp_sequence[:left_mid])
+ left_token_timestamp_sequence = token_timestamp_sequences[seq_idx + 1][right_mid:]
+
+ total_sequence.extend(left_sequence)
+
+ if token_timestamp_sequences is None:
+ return total_sequence
+
+ if len(token_timestamp_sequences) > 0:
+ total_token_timestamp_sequence.extend(left_token_timestamp_sequence)
+ return total_sequence, total_token_timestamp_sequence
+ else:
+ return total_sequence, []
+
+
+def _collate_word_timestamps(tokenizer, tokens, token_timestamps, language, return_language):
+ words, _, token_indices = _combine_tokens_into_words(tokenizer, tokens, language)
+
+ optional_language_field = {"language": language} if return_language else {}
+
+ timings = [
+ {
+ "text": word,
+ "timestamp": (token_timestamps[indices[0]][0], token_timestamps[indices[-1]][1]),
+ **optional_language_field,
+ }
+ for word, indices in zip(words, token_indices)
+ ]
+ return timings
+
+
+def _combine_tokens_into_words(
+ tokenizer,
+ tokens: list[int],
+ language: Optional[str] = None,
+ prepend_punctuations: str = "\"'“¡¿([{-",
+ append_punctuations: str = "\"'.。,,!!??::”)]}、",
+):
+ """
+ Groups tokens by word. Returns a tuple containing a list of strings with the words, and a list of `token_id`
+ sequences with the tokens making up each word.
+ """
+ if language is None:
+ language = tokenizer.language
+ if language is None:
+ language = "english"
+
+ if language in {"chinese", "japanese", "thai", "lao", "myanmar", "cantonese"}:
+ # These languages don't typically use spaces.
+ words, word_tokens, token_indices = _split_tokens_on_unicode(tokenizer, tokens)
+ else:
+ words, word_tokens, token_indices = _split_tokens_on_spaces(tokenizer, tokens)
+
+ _merge_punctuations(words, word_tokens, token_indices, prepend_punctuations, append_punctuations)
+ return words, word_tokens, token_indices
+
+
+def _split_tokens_on_unicode(tokenizer, tokens: list[int]):
+ """Combine tokens into words by splitting at any position where the tokens are decoded as valid unicode points."""
+ decoded_full = tokenizer.decode(tokens, decode_with_timestamps=True)
+ replacement_char = "\ufffd"
+
+ words = []
+ word_tokens = []
+ token_indices = []
+ current_tokens = []
+ current_indices = []
+ unicode_offset = 0
+
+ for token_idx, token in enumerate(tokens):
+ current_tokens.append(token)
+ current_indices.append(token_idx)
+ decoded = tokenizer.decode(current_tokens, decode_with_timestamps=True)
+
+ if (
+ replacement_char not in decoded
+ or decoded_full[unicode_offset + decoded.index(replacement_char)] == replacement_char
+ ):
+ words.append(decoded)
+ word_tokens.append(current_tokens)
+ token_indices.append(current_indices)
+ current_tokens = []
+ current_indices = []
+ unicode_offset += len(decoded)
+
+ return words, word_tokens, token_indices
+
+
+def _split_tokens_on_spaces(tokenizer, tokens: list[int]):
+ """Combine tokens into words by splitting at whitespace and punctuation tokens."""
+ subwords, subword_tokens_list, subword_indices_list = _split_tokens_on_unicode(tokenizer, tokens)
+ words = []
+ word_tokens = []
+ token_indices = []
+
+ for subword, subword_tokens, subword_indices in zip(subwords, subword_tokens_list, subword_indices_list):
+ special = subword_tokens[0] >= tokenizer.eos_token_id
+ with_space = subword.startswith(" ")
+ punctuation = subword.strip() in "!\"#$%&'()*+,-./:;<=>?@[\\]^_`{|}~"
+
+ if special or with_space or punctuation or len(words) == 0:
+ words.append(subword)
+ word_tokens.append(subword_tokens)
+ token_indices.append(subword_indices)
+ else:
+ words[-1] = words[-1] + subword
+ word_tokens[-1].extend(subword_tokens)
+ token_indices[-1].extend(subword_indices)
+
+ return words, word_tokens, token_indices
+
+
+def _merge_punctuations(words, tokens, indices, prepended, appended):
+ """Merges punctuation tokens with neighboring words."""
+ # prepend punctuations
+ i = len(words) - 2
+ j = len(words) - 1
+ while i >= 0:
+ if words[i].startswith(" ") and words[i].strip() in prepended:
+ words[j] = words[i] + words[j]
+ tokens[j] = tokens[i] + tokens[j]
+ indices[j] = indices[i] + indices[j]
+ words[i] = ""
+ tokens[i] = []
+ indices[i] = []
+ else:
+ j = i
+ i -= 1
+
+ # append punctuations
+ i = 0
+ j = 1
+ while j < len(words):
+ if not words[i].endswith(" ") and words[j] in appended:
+ words[i] += words[j]
+ tokens[i] += tokens[j]
+ indices[i] += indices[j]
+ words[j] = ""
+ tokens[j] = []
+ indices[j] = []
+ else:
+ i = j
+ j += 1
+
+ # remove elements that are now empty
+ words[:] = [word for word in words if word]
+ tokens[:] = [token for token in tokens if token]
+ indices[:] = [idx for idx in indices if idx]
+
+
+__all__ = ["WhisperTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/tokenization_whisper_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/tokenization_whisper_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..07f4fdfcb002bb08c6ae01b2005d4ba78b24e1b4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/whisper/tokenization_whisper_fast.py
@@ -0,0 +1,639 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for Whisper."""
+
+import json
+import os
+import re
+import warnings
+from functools import lru_cache
+from typing import Optional
+
+import numpy as np
+from tokenizers import AddedToken, processors
+
+from ...tokenization_utils_base import BatchEncoding
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import logging
+from .english_normalizer import BasicTextNormalizer, EnglishTextNormalizer
+from .tokenization_whisper import LANGUAGES, TASK_IDS, TO_LANGUAGE_CODE, WhisperTokenizer, _decode_asr
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {
+ "vocab_file": "vocab.json",
+ "tokenizer_file": "tokenizer.json",
+ "merges_file": "merges.txt",
+ "normalizer_file": "normalizer.json",
+}
+
+
+class WhisperTokenizerFast(PreTrainedTokenizerFast):
+ """
+ Construct a "fast" Whisper tokenizer (backed by HuggingFace's *tokenizers* library).
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`, *optional*):
+ Path to the vocabulary file.
+ merges_file (`str`, *optional*):
+ Path to the merges file.
+ normalizer_file (`str`, *optional*):
+ Path to the normalizer_file file.
+ tokenizer_file (`str`, *optional*):
+ Path to [tokenizers](https://github.com/huggingface/tokenizers) file (generally has a .json extension) that
+ contains everything needed to load the tokenizer.
+ unk_token (`str`, *optional*, defaults to `"<|endoftext|>"`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ bos_token (`str`, *optional*, defaults to `"<|endoftext|>"`):
+ The beginning of sequence token. The `decoder_start_token_id` is used to set the first token as
+ `"<|startoftranscript|>"` when generating.
+ eos_token (`str`, *optional*, defaults to `"<|endoftext|>"`):
+ The end of sequence token.
+ add_prefix_space (`bool`, *optional*, defaults to `False`):
+ Whether or not to add an initial space to the input. This allows to treat the leading word just as any
+ other word. (Whisper tokenizer detect beginning of words by the preceding space).
+ language (`str`, *optional*):
+ The language of the transcription text. The corresponding language id token is appended to the start of the
+ sequence for multilingual speech recognition and speech translation tasks, e.g. for Spanish the token
+ `"<|es|>"` is appended to the start of sequence. This should be used for multilingual fine-tuning only.
+ task (`str`, *optional*):
+ Task identifier to append at the start of sequence (if any). This should be used for mulitlingual
+ fine-tuning, with `"transcribe"` for speech recognition and `"translate"` for speech translation.
+ predict_timestamps (`bool`, *optional*, defaults to `False`):
+ Whether to omit the `<|notimestamps|>` token at the start of the sequence.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+ slow_tokenizer_class = WhisperTokenizer
+
+ def __init__(
+ self,
+ vocab_file=None,
+ merges_file=None,
+ normalizer_file=None,
+ tokenizer_file=None,
+ unk_token="<|endoftext|>",
+ bos_token="<|endoftext|>",
+ eos_token="<|endoftext|>",
+ add_prefix_space=False,
+ language=None,
+ task=None,
+ predict_timestamps=False,
+ **kwargs,
+ ):
+ bos_token = (
+ AddedToken(bos_token, lstrip=False, rstrip=False, normalized=False, special=True)
+ if isinstance(bos_token, str)
+ else bos_token
+ )
+ eos_token = (
+ AddedToken(eos_token, lstrip=False, rstrip=False, normalized=False, special=True)
+ if isinstance(eos_token, str)
+ else eos_token
+ )
+ unk_token = (
+ AddedToken(unk_token, lstrip=False, rstrip=False, normalized=False, special=True)
+ if isinstance(unk_token, str)
+ else unk_token
+ )
+
+ super().__init__(
+ vocab_file,
+ merges_file,
+ tokenizer_file=tokenizer_file,
+ unk_token=unk_token,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ add_prefix_space=add_prefix_space,
+ **kwargs,
+ )
+
+ self.add_bos_token = kwargs.pop("add_bos_token", False)
+
+ if normalizer_file is not None:
+ with open(normalizer_file, encoding="utf-8") as vocab_handle:
+ self.english_spelling_normalizer = json.load(vocab_handle)
+ else:
+ self.english_spelling_normalizer = None
+
+ self.timestamp_pat = re.compile(r"<\|(\d+\.\d+)\|>")
+
+ self.language = language
+ self.task = task
+ self.predict_timestamps = predict_timestamps
+
+ # Copied from transformers.models.gpt2.tokenization_gpt2_fast.GPT2TokenizerFast._batch_encode_plus
+ def _batch_encode_plus(self, *args, **kwargs) -> BatchEncoding:
+ is_split_into_words = kwargs.get("is_split_into_words", False)
+ assert self.add_prefix_space or not is_split_into_words, (
+ f"You need to instantiate {self.__class__.__name__} with add_prefix_space=True "
+ "to use it with pretokenized inputs."
+ )
+
+ return super()._batch_encode_plus(*args, **kwargs)
+
+ # Copied from transformers.models.gpt2.tokenization_gpt2_fast.GPT2TokenizerFast._encode_plus
+ def _encode_plus(self, *args, **kwargs) -> BatchEncoding:
+ is_split_into_words = kwargs.get("is_split_into_words", False)
+
+ assert self.add_prefix_space or not is_split_into_words, (
+ f"You need to instantiate {self.__class__.__name__} with add_prefix_space=True "
+ "to use it with pretokenized inputs."
+ )
+
+ return super()._encode_plus(*args, **kwargs)
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._decode_with_timestamps
+ def _decode_with_timestamps(
+ self, token_ids, skip_special_tokens=False, time_precision=0.02, segment_size=1500
+ ) -> str:
+ """
+ Timestamp tokens are above the special tokens' id range and are ignored by `decode()`. This method decodes
+ given tokens with timestamps tokens annotated, e.g. "<|1.08|>".
+ """
+ timestamp_begin = self.all_special_ids[-1] + 1
+ outputs = [[]]
+
+ cur_max_timestamp = 0.0
+ prev_segments_len = 0.0
+ penultimate_timestamp = 0.0
+
+ for i, token in enumerate(token_ids):
+ if token >= timestamp_begin:
+ timestamp = float((token - timestamp_begin) * time_precision)
+
+ if timestamp < cur_max_timestamp:
+ # next segment has started
+ last_was_single_ending = i >= 2 and not (
+ token_ids[i - 1] >= timestamp_begin and token_ids[i - 2] >= timestamp_begin
+ )
+ if last_was_single_ending:
+ prev_segments_len += time_precision * segment_size
+ else:
+ cur_max_timestamp = penultimate_timestamp
+ prev_segments_len += penultimate_timestamp
+ outputs = outputs[:-2]
+
+ penultimate_timestamp = cur_max_timestamp
+ cur_max_timestamp = timestamp
+
+ outputs.append(f"<|{(timestamp + prev_segments_len):.2f}|>")
+ outputs.append([])
+ else:
+ outputs[-1].append(token)
+ outputs = [
+ s if isinstance(s, str) else self.decode(s, skip_special_tokens=skip_special_tokens) for s in outputs
+ ]
+ return "".join(outputs)
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._compute_offsets
+ def _compute_offsets(self, token_ids, time_precision=0.02, segment_size=1500):
+ """
+ Compute offsets for a given tokenized input
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ time_precision (`float`, *optional*, defaults to 0.02):
+ The time ratio to convert from token to time.
+ segment_size (`int`, *optional*, defaults to 1500):
+ The number of features in the input mel spectrogram.
+ """
+ offsets = []
+ # ensure torch tensor of token ids is placed on cpu
+ if "torch" in str(type(token_ids)) and (hasattr(token_ids, "cpu") and callable(token_ids.cpu)):
+ token_ids = token_ids.cpu()
+ token_ids = np.array(token_ids)
+ if token_ids.shape[0] > 1 and len(token_ids.shape) > 1:
+ raise ValueError("Can only process a single input at a time")
+ timestamp_begin = self.all_special_ids[-1] + 1
+ timestamp_tokens = token_ids >= timestamp_begin
+
+ consecutive = np.where(timestamp_tokens[:-1] & timestamp_tokens[1:])[0] + 1
+ if consecutive.shape[0] == 0 and timestamp_tokens.sum() <= 1:
+ # either there are no timestamps or there are no consecutive ones
+ return []
+ elif np.where(timestamp_tokens)[0][-1] + 1 not in consecutive:
+ # we add the final timestamp if it is not already in the list
+ consecutive = np.append(consecutive, np.where(timestamp_tokens)[0][-1] + 1)
+
+ last_slice = np.where(timestamp_tokens)[0][0]
+ cur_max_timestamp = 0
+ prev_segments_len = 0
+ for current_slice in consecutive:
+ sliced_tokens = token_ids[last_slice:current_slice]
+ if len(sliced_tokens) > 1:
+ start_timestamp_position = sliced_tokens[0].item() - timestamp_begin
+ end_timestamp_position = sliced_tokens[-1].item() - timestamp_begin
+
+ if start_timestamp_position < cur_max_timestamp:
+ # next segment has started
+ is_single_ending = last_slice >= 2 and not (
+ token_ids[last_slice - 2] >= timestamp_begin and token_ids[last_slice - 1] >= timestamp_begin
+ )
+ if is_single_ending:
+ prev_segments_len += segment_size
+ else:
+ prev_segments_len += cur_max_timestamp
+
+ cur_max_timestamp = end_timestamp_position
+
+ # strip timestamp tokens from the text output
+ sliced_tokens = self._preprocess_token_ids(sliced_tokens)
+ text = self._decode(sliced_tokens)
+ text = self._filter_timestamp_ids(text)
+ offsets.append(
+ {
+ "text": text,
+ "timestamp": (
+ start_timestamp_position * time_precision + prev_segments_len * time_precision,
+ end_timestamp_position * time_precision + prev_segments_len * time_precision,
+ ),
+ }
+ )
+ last_slice = current_slice
+
+ return offsets
+
+ @lru_cache
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.timestamp_ids
+ def timestamp_ids(self, time_precision=0.02):
+ """
+ Compute the timestamp token ids for a given precision and save to least-recently used (LRU) cache.
+
+ Args:
+ time_precision (`float`, *optional*, defaults to 0.02):
+ The time ratio to convert from token to time.
+ """
+ return self.convert_tokens_to_ids([("<|%.2f|>" % (i * time_precision)) for i in range(1500 + 1)])
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._preprocess_token_ids
+ def _preprocess_token_ids(self, token_ids, skip_special_tokens: bool = False):
+ """
+ Pre-process the token ids for decoding by removing the prompt tokens ids and timestamp token ids.
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Typically, obtained using the `__call__` method of the tokenizer.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens from the token ids. If `True`, the prompt token ids will be
+ removed.
+ """
+ if skip_special_tokens:
+ prompt_token_id = self.convert_tokens_to_ids("<|startofprev|>")
+ decoder_start_token_id = self.convert_tokens_to_ids("<|startoftranscript|>")
+ token_ids = self._strip_prompt(token_ids, prompt_token_id, decoder_start_token_id)
+
+ return token_ids
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._filter_timestamp_ids
+ def _filter_timestamp_ids(self, token_ids):
+ return re.sub(self.timestamp_pat, "", token_ids)
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.decode
+ def decode(
+ self,
+ token_ids,
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ output_offsets: bool = False,
+ time_precision: float = 0.02,
+ decode_with_timestamps: bool = False,
+ normalize: bool = False,
+ basic_normalize: bool = False,
+ remove_diacritics: bool = False,
+ **kwargs,
+ ) -> str:
+ """
+ Converts a sequence of ids in a string, using the tokenizer and vocabulary with options to remove special
+ tokens and clean up tokenization spaces.
+
+ Similar to doing `self.convert_tokens_to_string(self.convert_ids_to_tokens(token_ids))`.
+
+ Args:
+ token_ids (`Union[int, list[int], np.ndarray, torch.Tensor, tf.Tensor]`):
+ List of tokenized input ids. Can be obtained using the `__call__` method.
+ skip_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove special tokens in the decoding. Will remove the previous tokens (pre-prompt)
+ if present.
+ clean_up_tokenization_spaces (`bool`, *optional*):
+ Whether or not to clean up the tokenization spaces. If `None`, will default to
+ `self.clean_up_tokenization_spaces` (available in the `tokenizer_config`).
+ output_offsets (`bool`, *optional*, defaults to `False`):
+ Whether or not to output the offsets of the tokens. This should only be set if the model predicted
+ timestamps. If there are previous tokens (pre-prompt) to decode, they will only appear in the decoded
+ text if they contain timestamp tokens.
+ time_precision (`float`, *optional*, defaults to 0.02):
+ The time ratio to convert from token to time.
+ decode_with_timestamps (`bool`, *optional*, defaults to `False`):
+ Whether or not to decode with timestamps included in the raw text.
+ normalize (`bool`, *optional*, defaults to `False`):
+ Whether or not to apply the English text normalizer to the decoded text. Only applicable when the
+ target text is in English. Otherwise, the basic text normalizer should be applied.
+ basic_normalize (`bool`, *optional*, defaults to `False`):
+ Whether or not to apply the Basic text normalizer to the decoded text. Applicable to multilingual
+ target text.
+ remove_diacritics (`bool`, *optional*, defaults to `False`):
+ Whether or not to remove diacritics when applying the Basic text normalizer. Removing diacritics may
+ destroy information in the decoded text, hence it should be used with caution.
+ kwargs (additional keyword arguments, *optional*):
+ Will be passed to the underlying model specific decode method.
+ Returns:
+ `str`: The decoded sentence.
+ """
+ filtered_ids = self._preprocess_token_ids(
+ token_ids,
+ skip_special_tokens=skip_special_tokens,
+ )
+
+ text = super().decode(
+ filtered_ids,
+ skip_special_tokens=skip_special_tokens,
+ clean_up_tokenization_spaces=clean_up_tokenization_spaces,
+ normalize=normalize,
+ basic_normalize=basic_normalize,
+ remove_diacritics=remove_diacritics,
+ **kwargs,
+ )
+ if decode_with_timestamps:
+ # legacy method to decode timestamps when not included in the tokenizer vocabulary
+ text = self._decode_with_timestamps(
+ filtered_ids, time_precision=time_precision, skip_special_tokens=skip_special_tokens
+ )
+ else:
+ text = self._filter_timestamp_ids(text)
+
+ # retrieve offsets
+ if output_offsets:
+ offsets = self._compute_offsets(token_ids, time_precision=time_precision)
+ return {"text": text, "offsets": offsets}
+ return text
+
+ def _decode(
+ self, *args, normalize: bool = False, basic_normalize: bool = False, remove_diacritics: bool = False, **kwargs
+ ) -> str:
+ text = super()._decode(*args, **kwargs)
+
+ if normalize:
+ clean_text = self._normalize(text)
+ return clean_text
+ elif basic_normalize:
+ clean_text = self._basic_normalize(text, remove_diacritics=remove_diacritics)
+ return clean_text
+ else:
+ return text
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._normalize
+ def _normalize(self, text):
+ warnings.warn(
+ "The private method `_normalize` is deprecated and will be removed in v5 of Transformers."
+ "You can normalize an input string using the Whisper English normalizer using the `normalize` method."
+ )
+ return self.normalize(text)
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._basic_normalize
+ def _basic_normalize(self, text, remove_diacritics=False):
+ warnings.warn(
+ "The private method `_basic_normalize` is deprecated and will be removed in v5 of Transformers."
+ "You can normalize an input string using the Whisper basic normalizer using the `basic_normalize` method."
+ )
+ return self.basic_normalize(text, remove_diacritics=remove_diacritics)
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.normalize
+ def normalize(self, text):
+ """
+ Normalize a given string using the `EnglishTextNormalizer` class, which performs commons transformation on
+ english text.
+ """
+ normalizer = EnglishTextNormalizer(self.english_spelling_normalizer)
+ return normalizer(text)
+
+ @staticmethod
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.basic_normalize
+ def basic_normalize(text, remove_diacritics=False):
+ """
+ Normalize a given string using the `BasicTextNormalizer` class, which performs commons transformation on
+ multilingual text.
+ """
+ normalizer = BasicTextNormalizer(remove_diacritics=remove_diacritics)
+ return normalizer(text)
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ files = self._tokenizer.model.save(save_directory, name=filename_prefix)
+
+ normalizer_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["normalizer_file"]
+ )
+
+ if self.english_spelling_normalizer is not None:
+ with open(normalizer_file, "w", encoding="utf-8") as f:
+ f.write(
+ json.dumps(self.english_spelling_normalizer, indent=2, sort_keys=True, ensure_ascii=False) + "\n"
+ )
+
+ return tuple(files) + (normalizer_file,)
+
+ def set_prefix_tokens(
+ self, language: Optional[str] = None, task: Optional[str] = None, predict_timestamps: Optional[bool] = None
+ ):
+ """
+ Override the prefix tokens appended to the start of the label sequence. This method can be used standalone to
+ update the prefix tokens as required when fine-tuning. Example:
+
+ ```python
+ >>> # instantiate the tokenizer and set the prefix token to Spanish
+ >>> tokenizer = WhisperTokenizerFast.from_pretrained("openai/whisper-tiny", language="spanish")
+ >>> # now switch the prefix token from Spanish to French
+ >>> tokenizer.set_prefix_tokens(language="french")
+ ```
+
+ Args:
+ language (`str`, *optional*, defaults to `None`):
+ The language of the transcription text.
+ task (`str`, *optional*, defaults to `None`):
+ Task identifier to append at the start of sequence (if any).
+ predict_timestamps (`bool`, *optional*, defaults to `None`):
+ Whether to omit the `<|notimestamps|>` token at the start of the sequence.
+ """
+ self.language = language if language is not None else self.language
+ self.task = task if task is not None else self.task
+ self.predict_timestamps = predict_timestamps if predict_timestamps is not None else self.predict_timestamps
+
+ prefix_token_ids = self.prefix_tokens
+ prefixes = self.convert_ids_to_tokens(prefix_token_ids)
+ eos = self.eos_token
+ eos_token_id = self.eos_token_id
+ prefix_template = " ".join([f"{token}:0" for token in prefixes])
+ self.backend_tokenizer.post_processor = processors.TemplateProcessing(
+ single=f"{prefix_template} $A:0 {eos}:0",
+ pair=f"{prefix_template} $A:0 $B:1 {eos}:1",
+ special_tokens=[
+ (eos, eos_token_id),
+ *zip(prefixes, prefix_token_ids),
+ ],
+ )
+
+ @property
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.prefix_tokens
+ def prefix_tokens(self) -> list[int]:
+ bos_token_id = self.convert_tokens_to_ids("<|startoftranscript|>")
+ translate_token_id = self.convert_tokens_to_ids("<|translate|>")
+ transcribe_token_id = self.convert_tokens_to_ids("<|transcribe|>")
+ notimestamps_token_id = self.convert_tokens_to_ids("<|notimestamps|>")
+ langs = tuple(LANGUAGES.keys())
+
+ if self.language is not None:
+ self.language = self.language.lower()
+ if self.language in TO_LANGUAGE_CODE:
+ language_id = TO_LANGUAGE_CODE[self.language]
+ elif self.language in TO_LANGUAGE_CODE.values():
+ language_id = self.language
+ else:
+ is_language_code = len(self.language) == 2
+ raise ValueError(
+ f"Unsupported language: {self.language}. Language should be one of:"
+ f" {list(TO_LANGUAGE_CODE.values()) if is_language_code else list(TO_LANGUAGE_CODE.keys())}."
+ )
+
+ if self.task is not None:
+ if self.task not in TASK_IDS:
+ raise ValueError(f"Unsupported task: {self.task}. Task should be in: {TASK_IDS}")
+
+ bos_sequence = [bos_token_id]
+ if self.language is not None:
+ bos_sequence.append(bos_token_id + 1 + langs.index(language_id))
+ if self.task is not None:
+ bos_sequence.append(transcribe_token_id if self.task == "transcribe" else translate_token_id)
+ if not self.predict_timestamps:
+ bos_sequence.append(notimestamps_token_id)
+ return bos_sequence
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.build_inputs_with_special_tokens
+ def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None) -> list[int]:
+ """Build model inputs from a sequence by appending eos_token_id."""
+ if token_ids_1 is None:
+ return self.prefix_tokens + token_ids_0 + [self.eos_token_id]
+ # We don't expect to process pairs, but leave the pair logic for API consistency
+ return self.prefix_tokens + token_ids_0 + token_ids_1 + [self.eos_token_id]
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.get_special_tokens_mask
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ prefix_ones = [1] * len(self.prefix_tokens)
+ suffix_ones = [1]
+ if token_ids_1 is None:
+ return prefix_ones + ([0] * len(token_ids_0)) + suffix_ones
+ return prefix_ones + ([0] * len(token_ids_0)) + ([0] * len(token_ids_1)) + suffix_ones
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.get_decoder_prompt_ids
+ def get_decoder_prompt_ids(self, task=None, language=None, no_timestamps=True):
+ self.set_prefix_tokens(task=task, language=language, predict_timestamps=not no_timestamps)
+ # prefix tokens are of the form: <|startoftranscript|> <|lang_id|> <|task|> <|notimestamps|>
+ # we don't want to force the bos token at position 1, as this is the starting token
+ # when we generate, so we slice the prefix tokens to: <|lang_id|> <|task|> <|notimestamps|>
+ # to get the forced tokens
+ forced_tokens = self.prefix_tokens[1:]
+ forced_decoder_ids = [(rank + 1, token) for rank, token in enumerate(forced_tokens)]
+ return forced_decoder_ids
+
+ def _decode_asr(self, model_outputs, *, return_timestamps, return_language, time_precision):
+ return _decode_asr(
+ self,
+ model_outputs,
+ return_timestamps=return_timestamps,
+ return_language=return_language,
+ time_precision=time_precision,
+ )
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer.get_prompt_ids
+ def get_prompt_ids(self, text: str, return_tensors="np"):
+ """Converts prompt text to IDs that can be passed to [`~WhisperForConditionalGeneration.generate`]."""
+ batch_encoding = self("<|startofprev|>", " " + text.strip(), add_special_tokens=False)
+
+ # Check for special tokens
+ prompt_text_ids = batch_encoding["input_ids"][1:]
+ special_token_id = next((x for x in prompt_text_ids if x >= self.all_special_ids[0]), None)
+ if special_token_id is not None:
+ token = self.convert_ids_to_tokens(special_token_id)
+ raise ValueError(f"Encountered text in the prompt corresponding to disallowed special token: {token}.")
+
+ batch_encoding.convert_to_tensors(tensor_type=return_tensors)
+ return batch_encoding["input_ids"]
+
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._strip_prompt
+ def _strip_prompt(self, token_ids: list[int], prompt_token_id: int, decoder_start_token_id: int):
+ if not isinstance(token_ids, list):
+ token_ids = self._convert_to_list(token_ids)
+
+ # handle case of empty token_ids for decoding with timestamps.
+ # at this point token_ids is a list, so it is safe to use if not check.
+ if not token_ids:
+ return token_ids
+
+ has_prompt = token_ids[0] == prompt_token_id
+ if has_prompt:
+ if decoder_start_token_id in token_ids:
+ return token_ids[token_ids.index(decoder_start_token_id) :]
+ else:
+ return []
+
+ return token_ids
+
+ @staticmethod
+ # Copied from transformers.models.whisper.tokenization_whisper.WhisperTokenizer._convert_to_list
+ def _convert_to_list(token_ids):
+ # convert type to ndarray if necessary
+ if hasattr(token_ids, "numpy"):
+ if "torch" in str(type(token_ids)):
+ token_ids = token_ids.cpu().numpy()
+ elif "tensorflow" in str(type(token_ids)):
+ token_ids = token_ids.numpy()
+ elif "jaxlib" in str(type(token_ids)):
+ token_ids = token_ids.tolist()
+ # now the token ids are either a numpy array, or a list of lists
+ if isinstance(token_ids, np.ndarray):
+ token_ids = token_ids.tolist()
+ return token_ids
+
+
+__all__ = ["WhisperTokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..d9c5fea1b3147333041a432f8d50861104dc9140
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/__init__.py
@@ -0,0 +1,28 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_x_clip import *
+ from .modeling_x_clip import *
+ from .processing_x_clip import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/configuration_x_clip.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/configuration_x_clip.py
new file mode 100644
index 0000000000000000000000000000000000000000..66db819168e5f74fbc2f5db0f4bb5a43dce6fa28
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/configuration_x_clip.py
@@ -0,0 +1,369 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""X-CLIP model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XCLIPTextConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`XCLIPModel`]. It is used to instantiate an X-CLIP
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the X-CLIP
+ [microsoft/xclip-base-patch32](https://huggingface.co/microsoft/xclip-base-patch32) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 49408):
+ Vocabulary size of the X-CLIP text model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`XCLIPModel`].
+ hidden_size (`int`, *optional*, defaults to 512):
+ Dimensionality of the encoder layers and the pooler layer.
+ intermediate_size (`int`, *optional*, defaults to 2048):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 8):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ max_position_embeddings (`int`, *optional*, defaults to 77):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ hidden_act (`str` or `function`, *optional*, defaults to `"quick_gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-5):
+ The epsilon used by the layer normalization layers.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ initializer_factor (`float`, *optional*, defaults to 1):
+ A factor for initializing all weight matrices (should be kept to 1, used internally for initialization
+ testing).
+
+ Example:
+
+ ```python
+ >>> from transformers import XCLIPTextModel, XCLIPTextConfig
+
+ >>> # Initializing a XCLIPTextModel with microsoft/xclip-base-patch32 style configuration
+ >>> configuration = XCLIPTextConfig()
+
+ >>> # Initializing a XCLIPTextConfig from the microsoft/xclip-base-patch32 style configuration
+ >>> model = XCLIPTextModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xclip_text_model"
+ base_config_key = "text_config"
+
+ def __init__(
+ self,
+ vocab_size=49408,
+ hidden_size=512,
+ intermediate_size=2048,
+ num_hidden_layers=12,
+ num_attention_heads=8,
+ max_position_embeddings=77,
+ hidden_act="quick_gelu",
+ layer_norm_eps=1e-5,
+ attention_dropout=0.0,
+ initializer_range=0.02,
+ initializer_factor=1.0,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.max_position_embeddings = max_position_embeddings
+ self.layer_norm_eps = layer_norm_eps
+ self.hidden_act = hidden_act
+ self.initializer_range = initializer_range
+ self.initializer_factor = initializer_factor
+ self.attention_dropout = attention_dropout
+
+
+class XCLIPVisionConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`XCLIPModel`]. It is used to instantiate an X-CLIP
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the X-CLIP
+ [microsoft/xclip-base-patch32](https://huggingface.co/microsoft/xclip-base-patch32) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ mit_hidden_size (`int`, *optional*, defaults to 512):
+ Dimensionality of the encoder layers of the Multiframe Integration Transformer (MIT).
+ mit_intermediate_size (`int`, *optional*, defaults to 2048):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Multiframe Integration Transformer
+ (MIT).
+ mit_num_hidden_layers (`int`, *optional*, defaults to 1):
+ Number of hidden layers in the Multiframe Integration Transformer (MIT).
+ mit_num_attention_heads (`int`, *optional*, defaults to 8):
+ Number of attention heads for each attention layer in the Multiframe Integration Transformer (MIT).
+ image_size (`int`, *optional*, defaults to 224):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 32):
+ The size (resolution) of each patch.
+ hidden_act (`str` or `function`, *optional*, defaults to `"quick_gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"`, `"gelu_new"` and `"quick_gelu"` are supported.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-5):
+ The epsilon used by the layer normalization layers.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ initializer_factor (`float`, *optional*, defaults to 1):
+ A factor for initializing all weight matrices (should be kept to 1, used internally for initialization
+ testing).
+ drop_path_rate (`float`, *optional*, defaults to 0.0):
+ Stochastic depth rate.
+
+ Example:
+
+ ```python
+ >>> from transformers import XCLIPVisionModel, XCLIPVisionConfig
+
+ >>> # Initializing a XCLIPVisionModel with microsoft/xclip-base-patch32 style configuration
+ >>> configuration = XCLIPVisionConfig()
+
+ >>> # Initializing a XCLIPVisionModel model from the microsoft/xclip-base-patch32 style configuration
+ >>> model = XCLIPVisionModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xclip_vision_model"
+ base_config_key = "vision_config"
+
+ def __init__(
+ self,
+ hidden_size=768,
+ intermediate_size=3072,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ mit_hidden_size=512,
+ mit_intermediate_size=2048,
+ mit_num_hidden_layers=1,
+ mit_num_attention_heads=8,
+ num_channels=3,
+ image_size=224,
+ patch_size=32,
+ num_frames=8,
+ hidden_act="quick_gelu",
+ layer_norm_eps=1e-5,
+ attention_dropout=0.0,
+ initializer_range=0.02,
+ initializer_factor=1.0,
+ drop_path_rate=0.0,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.mit_hidden_size = mit_hidden_size
+ self.mit_intermediate_size = mit_intermediate_size
+ self.mit_num_hidden_layers = mit_num_hidden_layers
+ self.mit_num_attention_heads = mit_num_attention_heads
+ self.num_channels = num_channels
+ self.patch_size = patch_size
+ self.num_frames = num_frames
+ self.image_size = image_size
+ self.initializer_range = initializer_range
+ self.initializer_factor = initializer_factor
+ self.attention_dropout = attention_dropout
+ self.layer_norm_eps = layer_norm_eps
+ self.hidden_act = hidden_act
+ self.drop_path_rate = drop_path_rate
+
+
+class XCLIPConfig(PretrainedConfig):
+ r"""
+ [`XCLIPConfig`] is the configuration class to store the configuration of a [`XCLIPModel`]. It is used to
+ instantiate X-CLIP model according to the specified arguments, defining the text model and vision model configs.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the X-CLIP
+ [microsoft/xclip-base-patch32](https://huggingface.co/microsoft/xclip-base-patch32) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ text_config (`dict`, *optional*):
+ Dictionary of configuration options used to initialize [`XCLIPTextConfig`].
+ vision_config (`dict`, *optional*):
+ Dictionary of configuration options used to initialize [`XCLIPVisionConfig`].
+ projection_dim (`int`, *optional*, defaults to 512):
+ Dimensionality of text and vision projection layers.
+ prompt_layers (`int`, *optional*, defaults to 2):
+ Number of layers in the video specific prompt generator.
+ prompt_alpha (`float`, *optional*, defaults to 0.1):
+ Alpha value to use in the video specific prompt generator.
+ prompt_hidden_act (`str` or `function`, *optional*, defaults to `"quick_gelu"`):
+ The non-linear activation function (function or string) in the video specific prompt generator. If string,
+ `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported.
+ prompt_num_attention_heads (`int`, *optional*, defaults to 8):
+ Number of attention heads in the cross-attention of the video specific prompt generator.
+ prompt_attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the attention layers in the video specific prompt generator.
+ prompt_projection_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout probability for the projection layers in the video specific prompt generator.
+ logit_scale_init_value (`float`, *optional*, defaults to 2.6592):
+ The initial value of the *logit_scale* parameter. Default is used as per the original XCLIP implementation.
+ kwargs (*optional*):
+ Dictionary of keyword arguments.
+ """
+
+ model_type = "xclip"
+ sub_configs = {"text_config": XCLIPTextConfig, "vision_config": XCLIPVisionConfig}
+
+ def __init__(
+ self,
+ text_config=None,
+ vision_config=None,
+ projection_dim=512,
+ prompt_layers=2,
+ prompt_alpha=0.1,
+ prompt_hidden_act="quick_gelu",
+ prompt_num_attention_heads=8,
+ prompt_attention_dropout=0.0,
+ prompt_projection_dropout=0.0,
+ logit_scale_init_value=2.6592,
+ **kwargs,
+ ):
+ # If `_config_dict` exist, we use them for the backward compatibility.
+ # We pop out these 2 attributes before calling `super().__init__` to avoid them being saved (which causes a lot
+ # of confusion!).
+ text_config_dict = kwargs.pop("text_config_dict", None)
+ vision_config_dict = kwargs.pop("vision_config_dict", None)
+
+ super().__init__(**kwargs)
+
+ # Instead of simply assigning `[text|vision]_config_dict` to `[text|vision]_config`, we use the values in
+ # `[text|vision]_config_dict` to update the values in `[text|vision]_config`. The values should be same in most
+ # cases, but we don't want to break anything regarding `_config_dict` that existed before commit `8827e1b2`.
+ if text_config_dict is not None:
+ if text_config is None:
+ text_config = {}
+
+ # This is the complete result when using `text_config_dict`.
+ _text_config_dict = XCLIPTextConfig(**text_config_dict).to_dict()
+
+ # Give a warning if the values exist in both `_text_config_dict` and `text_config` but being different.
+ for key, value in _text_config_dict.items():
+ if key in text_config and value != text_config[key] and key not in ["transformers_version"]:
+ # If specified in `text_config_dict`
+ if key in text_config_dict:
+ message = (
+ f"`{key}` is found in both `text_config_dict` and `text_config` but with different values. "
+ f'The value `text_config_dict["{key}"]` will be used instead.'
+ )
+ # If inferred from default argument values (just to be super careful)
+ else:
+ message = (
+ f"`text_config_dict` is provided which will be used to initialize `XCLIPTextConfig`. The "
+ f'value `text_config["{key}"]` will be overridden.'
+ )
+ logger.info(message)
+
+ # Update all values in `text_config` with the ones in `_text_config_dict`.
+ text_config.update(_text_config_dict)
+
+ if vision_config_dict is not None:
+ if vision_config is None:
+ vision_config = {}
+
+ # This is the complete result when using `vision_config_dict`.
+ _vision_config_dict = XCLIPVisionConfig(**vision_config_dict).to_dict()
+ # convert keys to string instead of integer
+ if "id2label" in _vision_config_dict:
+ _vision_config_dict["id2label"] = {
+ str(key): value for key, value in _vision_config_dict["id2label"].items()
+ }
+
+ # Give a warning if the values exist in both `_vision_config_dict` and `vision_config` but being different.
+ for key, value in _vision_config_dict.items():
+ if key in vision_config and value != vision_config[key] and key not in ["transformers_version"]:
+ # If specified in `vision_config_dict`
+ if key in vision_config_dict:
+ message = (
+ f"`{key}` is found in both `vision_config_dict` and `vision_config` but with different "
+ f'values. The value `vision_config_dict["{key}"]` will be used instead.'
+ )
+ # If inferred from default argument values (just to be super careful)
+ else:
+ message = (
+ f"`vision_config_dict` is provided which will be used to initialize `XCLIPVisionConfig`. "
+ f'The value `vision_config["{key}"]` will be overridden.'
+ )
+ logger.info(message)
+
+ # Update all values in `vision_config` with the ones in `_vision_config_dict`.
+ vision_config.update(_vision_config_dict)
+
+ if text_config is None:
+ text_config = {}
+ logger.info("`text_config` is `None`. Initializing the `XCLIPTextConfig` with default values.")
+
+ if vision_config is None:
+ vision_config = {}
+ logger.info("`vision_config` is `None`. initializing the `XCLIPVisionConfig` with default values.")
+
+ self.text_config = XCLIPTextConfig(**text_config)
+ self.vision_config = XCLIPVisionConfig(**vision_config)
+
+ self.projection_dim = projection_dim
+ self.prompt_layers = prompt_layers
+ self.prompt_alpha = prompt_alpha
+ self.prompt_hidden_act = prompt_hidden_act
+ self.prompt_num_attention_heads = prompt_num_attention_heads
+ self.prompt_attention_dropout = prompt_attention_dropout
+ self.prompt_projection_dropout = prompt_projection_dropout
+ self.logit_scale_init_value = logit_scale_init_value
+ self.initializer_factor = 1.0
+
+
+__all__ = ["XCLIPConfig", "XCLIPTextConfig", "XCLIPVisionConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/modeling_x_clip.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/modeling_x_clip.py
new file mode 100644
index 0000000000000000000000000000000000000000..f6c5c51a27c5727a726882060855621b201f5416
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/modeling_x_clip.py
@@ -0,0 +1,1547 @@
+# coding=utf-8
+# Copyright 2022 Microsoft Research and The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch X-CLIP model."""
+
+import copy
+from dataclasses import dataclass
+from typing import Any, Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_attn_mask_utils import _create_4d_causal_attention_mask, _prepare_4d_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...utils import (
+ ModelOutput,
+ auto_docstring,
+ can_return_tuple,
+ logging,
+ torch_int,
+)
+from .configuration_x_clip import XCLIPConfig, XCLIPTextConfig, XCLIPVisionConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# contrastive loss function, adapted from
+# https://sachinruk.github.io/blog/pytorch/pytorch%20lightning/loss%20function/gpu/2021/03/07/CLIP.html
+def contrastive_loss(logits: torch.Tensor) -> torch.Tensor:
+ return nn.functional.cross_entropy(logits, torch.arange(len(logits), device=logits.device))
+
+
+# Copied from transformers.models.clip.modeling_clip.clip_loss with clip->x_clip
+def x_clip_loss(similarity: torch.Tensor) -> torch.Tensor:
+ caption_loss = contrastive_loss(similarity)
+ image_loss = contrastive_loss(similarity.t())
+ return (caption_loss + image_loss) / 2.0
+
+
+@dataclass
+@auto_docstring
+class XCLIPOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `return_loss` is `True`):
+ Contrastive loss for video-text similarity.
+ logits_per_video (`torch.FloatTensor` of shape `(video_batch_size, text_batch_size)`):
+ The scaled dot product scores between `video_embeds` and `text_embeds`. This represents the video-text
+ similarity scores.
+ logits_per_text (`torch.FloatTensor` of shape `(text_batch_size, video_batch_size)`):
+ The scaled dot product scores between `text_embeds` and `video_embeds`. This represents the text-video
+ similarity scores.
+ text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`):
+ The text embeddings obtained by applying the projection layer to the pooled output of [`XCLIPTextModel`].
+ video_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`):
+ The video embeddings obtained by applying the projection layer to the pooled output of
+ [`XCLIPVisionModel`].
+ text_model_output (`BaseModelOutputWithPooling`):
+ The output of the [`XCLIPTextModel`].
+ vision_model_output (`BaseModelOutputWithPooling`):
+ The output of the [`XCLIPVisionModel`].
+ mit_output (`BaseModelOutputWithPooling`):
+ The output of `XCLIPMultiframeIntegrationTransformer` (MIT for short).
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits_per_video: Optional[torch.FloatTensor] = None
+ logits_per_text: Optional[torch.FloatTensor] = None
+ text_embeds: Optional[torch.FloatTensor] = None
+ video_embeds: Optional[torch.FloatTensor] = None
+ text_model_output: BaseModelOutputWithPooling = None
+ vision_model_output: BaseModelOutputWithPooling = None
+ mit_output: BaseModelOutputWithPooling = None
+
+ def to_tuple(self) -> tuple[Any]:
+ return tuple(
+ self[k]
+ if k not in ["text_model_output", "vision_model_output", "mit_output"]
+ else getattr(self, k).to_tuple()
+ for k in self.keys()
+ )
+
+
+# Copied from transformers.models.clip.modeling_clip.CLIPVisionEmbeddings with CLIP->XCLIP
+class XCLIPVisionEmbeddings(nn.Module):
+ def __init__(self, config: XCLIPVisionConfig):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.image_size = config.image_size
+ self.patch_size = config.patch_size
+
+ self.class_embedding = nn.Parameter(torch.randn(self.embed_dim))
+
+ self.patch_embedding = nn.Conv2d(
+ in_channels=config.num_channels,
+ out_channels=self.embed_dim,
+ kernel_size=self.patch_size,
+ stride=self.patch_size,
+ bias=False,
+ )
+
+ self.num_patches = (self.image_size // self.patch_size) ** 2
+ self.num_positions = self.num_patches + 1
+ self.position_embedding = nn.Embedding(self.num_positions, self.embed_dim)
+ self.register_buffer("position_ids", torch.arange(self.num_positions).expand((1, -1)), persistent=False)
+
+ def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor:
+ """
+ This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution
+ images. This method is also adapted to support torch.jit tracing.
+
+ Adapted from:
+ - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and
+ - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211
+ """
+
+ num_patches = embeddings.shape[1] - 1
+ position_embedding = self.position_embedding.weight.unsqueeze(0)
+ num_positions = position_embedding.shape[1] - 1
+
+ # always interpolate when tracing to ensure the exported model works for dynamic input shapes
+ if not torch.jit.is_tracing() and num_patches == num_positions and height == width:
+ return self.position_embedding(self.position_ids)
+
+ class_pos_embed = position_embedding[:, :1]
+ patch_pos_embed = position_embedding[:, 1:]
+
+ dim = embeddings.shape[-1]
+
+ new_height = height // self.patch_size
+ new_width = width // self.patch_size
+
+ sqrt_num_positions = torch_int(num_positions**0.5)
+ patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim)
+ patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2)
+
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed,
+ size=(new_height, new_width),
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim)
+
+ return torch.cat((class_pos_embed, patch_pos_embed), dim=1)
+
+ def forward(self, pixel_values: torch.FloatTensor, interpolate_pos_encoding=False) -> torch.Tensor:
+ batch_size, _, height, width = pixel_values.shape
+ if not interpolate_pos_encoding and (height != self.image_size or width != self.image_size):
+ raise ValueError(
+ f"Input image size ({height}*{width}) doesn't match model ({self.image_size}*{self.image_size})."
+ )
+ target_dtype = self.patch_embedding.weight.dtype
+ patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype)) # shape = [*, width, grid, grid]
+ patch_embeds = patch_embeds.flatten(2).transpose(1, 2)
+
+ class_embeds = self.class_embedding.expand(batch_size, 1, -1)
+ embeddings = torch.cat([class_embeds, patch_embeds], dim=1)
+ if interpolate_pos_encoding:
+ embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width)
+ else:
+ embeddings = embeddings + self.position_embedding(self.position_ids)
+ return embeddings
+
+
+# Copied from transformers.models.clip.modeling_clip.CLIPTextEmbeddings with CLIP->XCLIP
+class XCLIPTextEmbeddings(nn.Module):
+ def __init__(self, config: XCLIPTextConfig):
+ super().__init__()
+ embed_dim = config.hidden_size
+
+ self.token_embedding = nn.Embedding(config.vocab_size, embed_dim)
+ self.position_embedding = nn.Embedding(config.max_position_embeddings, embed_dim)
+
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ ) -> torch.Tensor:
+ seq_length = input_ids.shape[-1] if input_ids is not None else inputs_embeds.shape[-2]
+ max_position_embedding = self.position_embedding.weight.shape[0]
+
+ if seq_length > max_position_embedding:
+ raise ValueError(
+ f"Sequence length must be less than max_position_embeddings (got `sequence length`: "
+ f"{seq_length} and max_position_embeddings: {max_position_embedding}"
+ )
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ if inputs_embeds is None:
+ inputs_embeds = self.token_embedding(input_ids)
+
+ position_embeddings = self.position_embedding(position_ids)
+ embeddings = inputs_embeds + position_embeddings
+
+ return embeddings
+
+
+# Copied from transformers.models.siglip.modeling_siglip.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+ if attention_mask is not None:
+ attn_weights = attn_weights + attention_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class XCLIPAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.embed_dim = config.hidden_size
+ self.num_heads = config.num_attention_heads
+ self.head_dim = self.embed_dim // self.num_heads
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
+ f" {self.num_heads})."
+ )
+ self.scale = self.head_dim**-0.5
+ self.dropout = config.attention_dropout
+ self.is_causal = False
+
+ self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
+ self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
+ """Input shape: Batch x Time x Channel"""
+
+ batch_size, seq_length, embed_dim = hidden_states.shape
+
+ queries = self.q_proj(hidden_states)
+ keys = self.k_proj(hidden_states)
+ values = self.v_proj(hidden_states)
+
+ queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2)
+ # CLIP text model uses both `causal_attention_mask` and `attention_mask`
+ # in case FA2 kernel is called, `is_causal` should be inferred from `causal_attention_mask`
+ if self.config._attn_implementation != "flash_attention_2":
+ if attention_mask is not None and causal_attention_mask is not None:
+ attention_mask = attention_mask + causal_attention_mask
+ elif causal_attention_mask is not None:
+ attention_mask = causal_attention_mask
+ else:
+ self.is_causal = causal_attention_mask is not None
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ if self.config._attn_implementation == "sdpa" and output_attentions:
+ logger.warning_once(
+ "`torch.nn.functional.scaled_dot_product_attention` does not support `output_attentions=True`. Falling back to "
+ 'eager attention. This warning can be removed using the argument `attn_implementation="eager"` when loading the model.'
+ )
+ else:
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ queries,
+ keys,
+ values,
+ attention_mask,
+ is_causal=self.is_causal,
+ scaling=self.scale,
+ dropout=0.0 if not self.training else self.dropout,
+ )
+
+ attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous()
+ attn_output = self.out_proj(attn_output)
+ if not output_attentions:
+ attn_weights = None
+
+ return attn_output, attn_weights
+
+
+class XCLIPMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.activation_fn = ACT2FN[config.hidden_act]
+ self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size)
+ self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.fc1(hidden_states)
+ hidden_states = self.activation_fn(hidden_states)
+ hidden_states = self.fc2(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.altclip.modeling_altclip.AltCLIPEncoderLayer with AltCLIP->XCLIP
+class XCLIPEncoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: XCLIPConfig):
+ super().__init__()
+ self.embed_dim = config.hidden_size
+ self.self_attn = XCLIPAttention(config)
+ self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.mlp = XCLIPMLP(config)
+ self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ causal_attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.FloatTensor]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ `(config.encoder_attention_heads,)`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ causal_attention_mask=causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+# Copied from transformers.models.beit.modeling_beit.drop_path
+def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor:
+ """
+ Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
+
+ Comment by Ross Wightman: This is the same as the DropConnect impl I created for EfficientNet, etc networks,
+ however, the original name is misleading as 'Drop Connect' is a different form of dropout in a separate paper...
+ See discussion: https://github.com/tensorflow/tpu/issues/494#issuecomment-532968956 ... I've opted for changing the
+ layer and argument names to 'drop path' rather than mix DropConnect as a layer name and use 'survival rate' as the
+ argument.
+ """
+ if drop_prob == 0.0 or not training:
+ return input
+ keep_prob = 1 - drop_prob
+ shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
+ random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device)
+ random_tensor.floor_() # binarize
+ output = input.div(keep_prob) * random_tensor
+ return output
+
+
+# Copied from transformers.models.beit.modeling_beit.BeitDropPath with Beit->XCLIP
+class XCLIPDropPath(nn.Module):
+ """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks)."""
+
+ def __init__(self, drop_prob: Optional[float] = None) -> None:
+ super().__init__()
+ self.drop_prob = drop_prob
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ return drop_path(hidden_states, self.drop_prob, self.training)
+
+ def extra_repr(self) -> str:
+ return f"p={self.drop_prob}"
+
+
+class XCLIPVisionEncoderLayer(GradientCheckpointingLayer):
+ """
+ This corresponds to the `CrossFramelAttentionBlock` class in the original implementation.
+ """
+
+ def __init__(self, config: XCLIPConfig):
+ super().__init__()
+ self.num_frames = config.num_frames
+ self.embed_dim = config.hidden_size
+
+ self.message_fc = nn.Linear(self.embed_dim, self.embed_dim)
+ self.message_ln = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.message_attn = XCLIPAttention(config)
+
+ self.drop_path = XCLIPDropPath(config.drop_path_rate) if config.drop_path_rate > 0.0 else nn.Identity()
+
+ self.self_attn = XCLIPAttention(config)
+ self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+ self.mlp = XCLIPMLP(config)
+ self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: torch.Tensor,
+ causal_attention_mask: torch.Tensor,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.FloatTensor]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ `(config.encoder_attention_heads,)`.
+ causal_attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Causal mask for the text model. Mask values selected in `[0, 1]`:
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ batch_time, seq_length, hidden_size = hidden_states.size()
+ batch_size = batch_time // self.num_frames
+ msg_token = self.message_fc(hidden_states[:, 0, :])
+ msg_token = msg_token.view(batch_size, self.num_frames, hidden_size)
+
+ msg_token = msg_token + self.drop_path(self.message_attn(self.message_ln(msg_token))[0])
+ # add dummy sequence dimension
+ msg_token = msg_token.view(-1, 1, hidden_size)
+
+ hidden_states = torch.cat([hidden_states, msg_token], dim=1)
+
+ residual = hidden_states
+
+ hidden_states = self.layer_norm1(hidden_states)
+ hidden_states, attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ causal_attention_mask=causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+ hidden_states = residual + hidden_states
+
+ hidden_states = hidden_states[:, :seq_length, :]
+
+ residual = hidden_states
+ hidden_states = self.layer_norm2(hidden_states)
+ hidden_states = self.mlp(hidden_states)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_weights,)
+
+ return outputs
+
+
+@auto_docstring
+class XCLIPPreTrainedModel(PreTrainedModel):
+ config: XCLIPConfig
+ base_model_prefix = "x_clip"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ factor = self.config.initializer_factor
+ if isinstance(module, XCLIPTextEmbeddings):
+ module.token_embedding.weight.data.normal_(mean=0.0, std=factor * 0.02)
+ module.position_embedding.weight.data.normal_(mean=0.0, std=factor * 0.02)
+ elif isinstance(module, XCLIPVisionEmbeddings):
+ factor = self.config.initializer_factor
+ nn.init.normal_(module.class_embedding, mean=0.0, std=module.embed_dim**-0.5 * factor)
+ nn.init.normal_(module.patch_embedding.weight, std=module.config.initializer_range * factor)
+ nn.init.normal_(module.position_embedding.weight, std=module.config.initializer_range * factor)
+ elif isinstance(module, XCLIPAttention):
+ factor = self.config.initializer_factor
+ in_proj_std = (module.embed_dim**-0.5) * ((2 * module.config.num_hidden_layers) ** -0.5) * factor
+ out_proj_std = (module.embed_dim**-0.5) * factor
+ nn.init.normal_(module.q_proj.weight, std=in_proj_std)
+ nn.init.normal_(module.k_proj.weight, std=in_proj_std)
+ nn.init.normal_(module.v_proj.weight, std=in_proj_std)
+ nn.init.normal_(module.out_proj.weight, std=out_proj_std)
+ elif isinstance(module, XCLIPMLP):
+ factor = self.config.initializer_factor
+ in_proj_std = (module.config.hidden_size**-0.5) * ((2 * module.config.num_hidden_layers) ** -0.5) * factor
+ fc_std = (2 * module.config.hidden_size) ** -0.5 * factor
+ nn.init.normal_(module.fc1.weight, std=fc_std)
+ nn.init.normal_(module.fc2.weight, std=in_proj_std)
+ elif isinstance(module, XCLIPModel):
+ factor = self.config.initializer_factor
+ nn.init.normal_(
+ module.text_projection.weight,
+ std=module.text_embed_dim**-0.5 * factor,
+ )
+ nn.init.normal_(
+ module.visual_projection.weight,
+ std=module.vision_embed_dim**-0.5 * factor,
+ )
+ nn.init.normal_(module.prompts_visual_projection, mean=0.0, std=module.vision_embed_dim**-0.5 * factor)
+ elif isinstance(module, XCLIPMultiframeIntegrationTransformer):
+ nn.init.normal_(module.position_embedding, std=self.config.initializer_factor)
+
+ if isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_factor)
+ if module.bias is not None:
+ module.bias.data.zero_()
+
+
+# Copied from transformers.models.altclip.modeling_altclip.AltCLIPEncoder with AltCLIP->XCLIP
+class XCLIPEncoder(nn.Module):
+ """
+ Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a
+ [`XCLIPEncoderLayer`].
+
+ Args:
+ config: XCLIPConfig
+ """
+
+ def __init__(self, config: XCLIPConfig):
+ super().__init__()
+ self.config = config
+ self.layers = nn.ModuleList([XCLIPEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ @can_return_tuple
+ def forward(
+ self,
+ inputs_embeds,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ causal_attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Causal mask for the text model. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ hidden_states = inputs_embeds
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+
+class XCLIPTextTransformer(nn.Module):
+ def __init__(self, config: XCLIPTextConfig):
+ super().__init__()
+ self.config = config
+ embed_dim = config.hidden_size
+ self.embeddings = XCLIPTextEmbeddings(config)
+ self.encoder = XCLIPEncoder(config)
+ self.final_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithPooling]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is None:
+ raise ValueError("You have to specify either input_ids")
+
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+
+ hidden_states = self.embeddings(input_ids=input_ids, position_ids=position_ids)
+
+ # X_CLIP's text model uses causal mask, prepare it here.
+ # https://github.com/openai/CLIP/blob/cfcffb90e69f37bf2ff1e988237a0fbe41f33c04/clip/model.py#L324
+ causal_attention_mask = _create_4d_causal_attention_mask(
+ input_shape, hidden_states.dtype, device=hidden_states.device
+ )
+ # expand attention_mask
+ if attention_mask is not None:
+ # [batch_size, seq_len] -> [batch_size, 1, tgt_seq_len, src_seq_len]
+ attention_mask = _prepare_4d_attention_mask(attention_mask, hidden_states.dtype)
+
+ encoder_outputs = self.encoder(
+ inputs_embeds=hidden_states,
+ attention_mask=attention_mask,
+ causal_attention_mask=causal_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_state = encoder_outputs[0]
+ last_hidden_state = self.final_layer_norm(last_hidden_state)
+
+ # text_embeds.shape = [batch_size, sequence_length, transformer.width]
+ # take features from the eot embedding (eot_token is the highest number in each sequence)
+ pooled_output = last_hidden_state[torch.arange(last_hidden_state.shape[0]), input_ids.argmax(dim=-1)]
+
+ if not return_dict:
+ return (last_hidden_state, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class XCLIPTextModel(XCLIPPreTrainedModel):
+ config: XCLIPTextConfig
+
+ def __init__(self, config: XCLIPTextConfig):
+ super().__init__(config)
+ self.text_model = XCLIPTextTransformer(config)
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.text_model.embeddings.token_embedding
+
+ def set_input_embeddings(self, value):
+ self.text_model.embeddings.token_embedding = value
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithPooling]:
+ r"""
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, XCLIPTextModel
+
+ >>> model = XCLIPTextModel.from_pretrained("microsoft/xclip-base-patch32")
+ >>> tokenizer = AutoTokenizer.from_pretrained("microsoft/xclip-base-patch32")
+
+ >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding=True, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> last_hidden_state = outputs.last_hidden_state
+ >>> pooled_output = outputs.pooler_output # pooled (EOS token) states
+ ```"""
+ return self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+
+class XCLIPVisionEncoder(nn.Module):
+ """
+ Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a
+ [`XCLIPVisionEncoderLayer`].
+
+ Args:
+ config: XCLIPConfig
+ """
+
+ def __init__(self, config: XCLIPConfig):
+ super().__init__()
+ self.config = config
+ self.layers = nn.ModuleList([XCLIPVisionEncoderLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ inputs_embeds,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_attention_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ r"""
+ Args:
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
+ This is useful if you want more control over how to convert `input_ids` indices into associated vectors
+ than the model's internal embedding lookup matrix.
+ attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ causal_attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Causal mask for the text model. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
+ for more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ encoder_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+
+ hidden_states = inputs_embeds
+ for idx, encoder_layer in enumerate(self.layers):
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+ layer_outputs = encoder_layer(
+ hidden_states,
+ attention_mask,
+ causal_attention_mask,
+ output_attentions=output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ encoder_states = encoder_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None)
+ return BaseModelOutput(
+ last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions
+ )
+
+
+class XCLIPVisionTransformer(nn.Module):
+ """
+ This corresponds to the `CrossFrameCommunicationTransformer` class in the original implementation.
+ """
+
+ def __init__(self, config: XCLIPVisionConfig):
+ super().__init__()
+ self.config = config
+ embed_dim = config.hidden_size
+
+ self.embeddings = XCLIPVisionEmbeddings(config)
+ self.pre_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+ self.encoder = XCLIPVisionEncoder(config)
+ self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithPooling]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ hidden_states = self.embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding)
+ hidden_states = self.pre_layernorm(hidden_states)
+
+ encoder_outputs = self.encoder(
+ inputs_embeds=hidden_states,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_state = encoder_outputs[0]
+ pooled_output = last_hidden_state[:, 0, :]
+ pooled_output = self.post_layernorm(pooled_output)
+
+ if not return_dict:
+ return (last_hidden_state, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class XCLIPVisionModel(XCLIPPreTrainedModel):
+ config: XCLIPVisionConfig
+ main_input_name = "pixel_values"
+
+ def __init__(self, config: XCLIPVisionConfig):
+ super().__init__(config)
+ self.vision_model = XCLIPVisionTransformer(config)
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> nn.Module:
+ return self.vision_model.embeddings.patch_embedding
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithPooling]:
+ r"""
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import torch
+ >>> import numpy as np
+
+ >>> from transformers import AutoProcessor, XCLIPVisionModel
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 16 frames
+ >>> indices = sample_frame_indices(clip_len=8, frame_sample_rate=1, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container, indices)
+
+ >>> processor = AutoProcessor.from_pretrained("microsoft/xclip-base-patch32")
+ >>> model = XCLIPVisionModel.from_pretrained("microsoft/xclip-base-patch32")
+
+ >>> pixel_values = processor(videos=list(video), return_tensors="pt").pixel_values
+
+ >>> batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ >>> pixel_values = pixel_values.reshape(-1, num_channels, height, width)
+
+ >>> outputs = model(pixel_values)
+ >>> last_hidden_state = outputs.last_hidden_state
+ ```"""
+ return self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+
+class XCLIPMultiframeIntegrationTransformer(nn.Module):
+ """
+ This corresponds to the `MultiframeIntegrationTransformer` class in the original implementation.
+ """
+
+ def __init__(self, config: XCLIPVisionConfig):
+ super().__init__()
+
+ self.position_embedding = nn.Parameter(torch.empty(1, config.num_frames, config.hidden_size))
+ self.encoder = XCLIPEncoder(config)
+
+ def forward(
+ self,
+ hidden_states,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutput]:
+ residual = hidden_states
+
+ # add position embeddings
+ hidden_states = hidden_states + self.position_embedding
+
+ encoder_outputs = self.encoder(
+ inputs_embeds=hidden_states,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ last_hidden_state = encoder_outputs[0]
+
+ last_hidden_state = last_hidden_state.type(hidden_states.dtype) + residual
+
+ pooled_output = last_hidden_state.mean(dim=1, keepdim=False)
+
+ if not return_dict:
+ return (last_hidden_state, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPooling(
+ last_hidden_state=last_hidden_state,
+ pooler_output=pooled_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+class XCLIPCrossAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(self, config):
+ super().__init__()
+ self.num_heads = config.prompt_num_attention_heads
+
+ dim = config.projection_dim
+ head_dim = dim // self.num_heads
+ self.scale = head_dim**-0.5
+
+ self.q_proj = nn.Linear(dim, dim, bias=False)
+ self.k_proj = nn.Linear(dim, dim, bias=False)
+ self.v_proj = nn.Linear(dim, dim, bias=False)
+
+ self.attn_drop = nn.Dropout(config.prompt_attention_dropout)
+ self.proj = nn.Linear(dim, dim)
+ self.proj_drop = nn.Dropout(config.prompt_projection_dropout)
+
+ def _shape(self, tensor: torch.Tensor, seq_len: int, batch_size: int):
+ return tensor.view(batch_size, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
+
+ def forward(self, queries, keys, values):
+ """Input shape: Batch x Time x Channel"""
+ batch_size, query_seq_len, hidden_size = queries.shape
+ batch_size, key_seq_len, hidden_size = keys.shape
+ queries = (
+ self.q_proj(queries)
+ .reshape(batch_size, query_seq_len, self.num_heads, hidden_size // self.num_heads)
+ .permute(0, 2, 1, 3)
+ )
+ keys = (
+ self.k_proj(keys)
+ .reshape(batch_size, key_seq_len, self.num_heads, hidden_size // self.num_heads)
+ .permute(0, 2, 1, 3)
+ )
+ values = (
+ self.v_proj(values)
+ .reshape(batch_size, key_seq_len, self.num_heads, hidden_size // self.num_heads)
+ .permute(0, 2, 1, 3)
+ )
+
+ attn = (queries @ keys.transpose(-2, -1)) * self.scale
+ attn = attn.softmax(dim=-1)
+ attn = self.attn_drop(attn)
+
+ x = (attn @ values).transpose(1, 2).reshape(batch_size, query_seq_len, hidden_size)
+ x = self.proj(x)
+ x = self.proj_drop(x)
+ return x
+
+
+class PromptGeneratorLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+
+ embed_dim = config.projection_dim
+ self.cross_attn = XCLIPCrossAttention(config)
+ self.norm1 = nn.LayerNorm(embed_dim, eps=config.text_config.layer_norm_eps)
+ self.norm3 = nn.LayerNorm(embed_dim, eps=config.text_config.layer_norm_eps)
+ self.mlp = nn.Sequential(
+ nn.Linear(embed_dim, embed_dim * 4),
+ ACT2FN[config.prompt_hidden_act],
+ nn.Dropout(config.prompt_attention_dropout),
+ nn.Linear(embed_dim * 4, embed_dim),
+ )
+
+ def forward(self, x, visual):
+ x = x + self.cross_attn(self.norm1(x), visual, visual)
+ x = x + self.mlp(self.norm3(x))
+ return x
+
+
+class XCLIPPromptGenerator(nn.Module):
+ """This corresponds to the `VideoSpecificPrompt` class in the original implementation."""
+
+ def __init__(self, config):
+ super().__init__()
+ embed_dim = config.projection_dim
+ self.layernorm = nn.LayerNorm(embed_dim, eps=config.vision_config.layer_norm_eps)
+ self.decoder = nn.ModuleList([PromptGeneratorLayer(config) for _ in range(config.prompt_layers)])
+ self.alpha = nn.Parameter(torch.ones(embed_dim) * config.prompt_alpha)
+
+ def forward(self, text, visual):
+ visual = self.layernorm(visual)
+ for layer in self.decoder:
+ text = layer(text, visual)
+
+ return self.alpha * text
+
+
+@auto_docstring
+class XCLIPModel(XCLIPPreTrainedModel):
+ config: XCLIPConfig
+
+ def __init__(self, config: XCLIPConfig):
+ super().__init__(config)
+
+ if not isinstance(config.text_config, XCLIPTextConfig):
+ raise TypeError(
+ "config.text_config is expected to be of type XCLIPTextConfig but is of type"
+ f" {type(config.text_config)}."
+ )
+
+ if not isinstance(config.vision_config, XCLIPVisionConfig):
+ raise TypeError(
+ "config.vision_config is expected to be of type XCLIPVisionConfig but is of type"
+ f" {type(config.vision_config)}."
+ )
+
+ text_config = config.text_config
+ vision_config = config.vision_config
+ # The module using it is not a PreTrainedModel subclass so we need this
+ text_config._attn_implementation = config._attn_implementation
+ # The module using it is not a PreTrainedModel subclass so we need this
+ vision_config._attn_implementation = config._attn_implementation
+
+ self.projection_dim = config.projection_dim
+ self.text_embed_dim = text_config.hidden_size
+ self.vision_embed_dim = vision_config.hidden_size
+
+ self.text_model = XCLIPTextTransformer(text_config)
+ self.vision_model = XCLIPVisionTransformer(vision_config)
+
+ self.visual_projection = nn.Linear(self.vision_embed_dim, self.projection_dim, bias=False)
+ self.text_projection = nn.Linear(self.text_embed_dim, self.projection_dim, bias=False)
+ self.logit_scale = nn.Parameter(torch.tensor(self.config.logit_scale_init_value))
+
+ self.prompts_visual_layernorm = nn.LayerNorm(self.vision_embed_dim, eps=config.vision_config.layer_norm_eps)
+ self.prompts_visual_projection = nn.Parameter(torch.randn(self.vision_embed_dim, self.projection_dim))
+ mit_config = copy.copy(vision_config)
+ mit_config.hidden_size = vision_config.mit_hidden_size
+ mit_config.intermediate_size = vision_config.mit_intermediate_size
+ mit_config.num_hidden_layers = vision_config.mit_num_hidden_layers
+ mit_config.num_attention_heads = vision_config.mit_num_attention_heads
+ self.mit = XCLIPMultiframeIntegrationTransformer(mit_config)
+
+ self.prompts_generator = XCLIPPromptGenerator(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def get_text_features(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> torch.FloatTensor:
+ r"""
+ Returns:
+ text_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The text embeddings obtained by
+ applying the projection layer to the pooled output of [`XCLIPTextModel`].
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, AutoModel
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("microsoft/xclip-base-patch32")
+ >>> model = AutoModel.from_pretrained("microsoft/xclip-base-patch32")
+
+ >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding=True, return_tensors="pt")
+ >>> text_features = model.get_text_features(**inputs)
+ ```"""
+ # Use X_CLIP model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ text_embeds = text_outputs[1]
+ text_embeds = self.text_projection(text_embeds)
+
+ return text_embeds
+
+ @auto_docstring
+ def get_video_features(
+ self,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> torch.FloatTensor:
+ r"""
+ Returns:
+ video_features (`torch.FloatTensor` of shape `(batch_size, output_dim`): The video embeddings obtained by
+ applying the projection layer to the pooled output of [`XCLIPVisionModel`] and
+ [`XCLIPMultiframeIntegrationTransformer`].
+
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import torch
+ >>> import numpy as np
+
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 8 frames
+ >>> indices = sample_frame_indices(clip_len=8, frame_sample_rate=1, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container, indices)
+
+ >>> processor = AutoProcessor.from_pretrained("microsoft/xclip-base-patch32")
+ >>> model = AutoModel.from_pretrained("microsoft/xclip-base-patch32")
+
+ >>> inputs = processor(videos=list(video), return_tensors="pt")
+
+ >>> video_features = model.get_video_features(**inputs)
+ ```"""
+ # Use X_CLIP model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ pixel_values = pixel_values.reshape(-1, num_channels, height, width)
+
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ video_embeds = vision_outputs[1]
+ video_embeds = self.visual_projection(video_embeds)
+
+ cls_features = video_embeds.view(batch_size, num_frames, -1)
+
+ mit_outputs = self.mit(
+ cls_features,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ video_embeds = mit_outputs[1]
+
+ return video_embeds
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ pixel_values: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ return_loss: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ interpolate_pos_encoding: bool = False,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, XCLIPOutput]:
+ r"""
+ return_loss (`bool`, *optional*):
+ Whether or not to return the contrastive loss.
+
+ Examples:
+
+ ```python
+ >>> import av
+ >>> import torch
+ >>> import numpy as np
+
+ >>> from transformers import AutoProcessor, AutoModel
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> np.random.seed(0)
+
+
+ >>> def read_video_pyav(container, indices):
+ ... '''
+ ... Decode the video with PyAV decoder.
+ ... Args:
+ ... container (`av.container.input.InputContainer`): PyAV container.
+ ... indices (`list[int]`): List of frame indices to decode.
+ ... Returns:
+ ... result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ ... '''
+ ... frames = []
+ ... container.seek(0)
+ ... start_index = indices[0]
+ ... end_index = indices[-1]
+ ... for i, frame in enumerate(container.decode(video=0)):
+ ... if i > end_index:
+ ... break
+ ... if i >= start_index and i in indices:
+ ... frames.append(frame)
+ ... return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+
+ >>> def sample_frame_indices(clip_len, frame_sample_rate, seg_len):
+ ... '''
+ ... Sample a given number of frame indices from the video.
+ ... Args:
+ ... clip_len (`int`): Total number of frames to sample.
+ ... frame_sample_rate (`int`): Sample every n-th frame.
+ ... seg_len (`int`): Maximum allowed index of sample's last frame.
+ ... Returns:
+ ... indices (`list[int]`): List of sampled frame indices
+ ... '''
+ ... converted_len = int(clip_len * frame_sample_rate)
+ ... end_idx = np.random.randint(converted_len, seg_len)
+ ... start_idx = end_idx - converted_len
+ ... indices = np.linspace(start_idx, end_idx, num=clip_len)
+ ... indices = np.clip(indices, start_idx, end_idx - 1).astype(np.int64)
+ ... return indices
+
+
+ >>> # video clip consists of 300 frames (10 seconds at 30 FPS)
+ >>> file_path = hf_hub_download(
+ ... repo_id="nielsr/video-demo", filename="eating_spaghetti.mp4", repo_type="dataset"
+ ... )
+ >>> container = av.open(file_path)
+
+ >>> # sample 8 frames
+ >>> indices = sample_frame_indices(clip_len=8, frame_sample_rate=1, seg_len=container.streams.video[0].frames)
+ >>> video = read_video_pyav(container, indices)
+
+ >>> processor = AutoProcessor.from_pretrained("microsoft/xclip-base-patch32")
+ >>> model = AutoModel.from_pretrained("microsoft/xclip-base-patch32")
+
+ >>> inputs = processor(
+ ... text=["playing sports", "eating spaghetti", "go shopping"],
+ ... videos=list(video),
+ ... return_tensors="pt",
+ ... padding=True,
+ ... )
+
+ >>> # forward pass
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+
+ >>> logits_per_video = outputs.logits_per_video # this is the video-text similarity score
+ >>> probs = logits_per_video.softmax(dim=1) # we can take the softmax to get the label probabilities
+ >>> print(probs)
+ tensor([[1.9496e-04, 9.9960e-01, 2.0825e-04]])
+ ```"""
+ # Use X_CLIP model's config for some fields (if specified) instead of those of vision & text components.
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ batch_size, num_frames, num_channels, height, width = pixel_values.shape
+ pixel_values = pixel_values.reshape(-1, num_channels, height, width)
+
+ vision_outputs = self.vision_model(
+ pixel_values=pixel_values,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ interpolate_pos_encoding=interpolate_pos_encoding,
+ return_dict=return_dict,
+ )
+
+ video_embeds = vision_outputs[1]
+ video_embeds = self.visual_projection(video_embeds)
+
+ cls_features = video_embeds.view(batch_size, num_frames, -1)
+
+ mit_outputs = self.mit(
+ cls_features,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ video_embeds = mit_outputs[1]
+
+ img_features = vision_outputs[0][:, 1:, :]
+ img_features = self.prompts_visual_layernorm(img_features)
+ img_features = img_features @ self.prompts_visual_projection
+ img_features = img_features.view(batch_size, num_frames, -1, video_embeds.shape[-1])
+ img_features = img_features.mean(dim=1, keepdim=False)
+
+ text_outputs = self.text_model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ text_embeds = text_outputs[1]
+ text_embeds = self.text_projection(text_embeds)
+
+ text_embeds = text_embeds.unsqueeze(0).expand(batch_size, -1, -1)
+ text_embeds = text_embeds + self.prompts_generator(text_embeds, img_features)
+
+ # normalized features
+ video_embeds = video_embeds / video_embeds.norm(p=2, dim=-1, keepdim=True)
+ text_embeds = text_embeds / text_embeds.norm(p=2, dim=-1, keepdim=True)
+
+ # cosine similarity as logits
+ logit_scale = self.logit_scale.exp()
+ logits_per_video = torch.einsum("bd,bkd->bk", video_embeds, logit_scale * text_embeds)
+ logits_per_text = logits_per_video.T
+
+ loss = None
+ if return_loss:
+ loss = x_clip_loss(logits_per_text)
+
+ if not return_dict:
+ output = (logits_per_video, logits_per_text, text_embeds, video_embeds, text_outputs, vision_outputs)
+ return ((loss,) + output) if loss is not None else output
+
+ return XCLIPOutput(
+ loss=loss,
+ logits_per_video=logits_per_video,
+ logits_per_text=logits_per_text,
+ text_embeds=text_embeds,
+ video_embeds=video_embeds,
+ text_model_output=text_outputs,
+ vision_model_output=vision_outputs,
+ mit_output=mit_outputs,
+ )
+
+
+__all__ = ["XCLIPModel", "XCLIPPreTrainedModel", "XCLIPTextModel", "XCLIPVisionModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/processing_x_clip.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/processing_x_clip.py
new file mode 100644
index 0000000000000000000000000000000000000000..d8c947f3abbee39077470045ccd122ba77cfa1e7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/x_clip/processing_x_clip.py
@@ -0,0 +1,133 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+Image/Text processor class for XCLIP
+"""
+
+import warnings
+
+from ...processing_utils import ProcessorMixin
+from ...tokenization_utils_base import BatchEncoding
+
+
+class XCLIPProcessor(ProcessorMixin):
+ r"""
+ Constructs an X-CLIP processor which wraps a VideoMAE image processor and a CLIP tokenizer into a single processor.
+
+ [`XCLIPProcessor`] offers all the functionalities of [`VideoMAEImageProcessor`] and [`CLIPTokenizerFast`]. See the
+ [`~XCLIPProcessor.__call__`] and [`~XCLIPProcessor.decode`] for more information.
+
+ Args:
+ image_processor ([`VideoMAEImageProcessor`], *optional*):
+ The image processor is a required input.
+ tokenizer ([`CLIPTokenizerFast`], *optional*):
+ The tokenizer is a required input.
+ """
+
+ attributes = ["image_processor", "tokenizer"]
+ image_processor_class = "VideoMAEImageProcessor"
+ tokenizer_class = ("CLIPTokenizer", "CLIPTokenizerFast")
+
+ def __init__(self, image_processor=None, tokenizer=None, **kwargs):
+ feature_extractor = None
+ if "feature_extractor" in kwargs:
+ warnings.warn(
+ "The `feature_extractor` argument is deprecated and will be removed in v5, use `image_processor`"
+ " instead.",
+ FutureWarning,
+ )
+ feature_extractor = kwargs.pop("feature_extractor")
+
+ image_processor = image_processor if image_processor is not None else feature_extractor
+ if image_processor is None:
+ raise ValueError("You need to specify an `image_processor`.")
+ if tokenizer is None:
+ raise ValueError("You need to specify a `tokenizer`.")
+
+ super().__init__(image_processor, tokenizer)
+ self.current_processor = self.image_processor
+
+ def __call__(self, text=None, videos=None, return_tensors=None, **kwargs):
+ """
+ Main method to prepare for the model one or several sequences(s) and image(s). This method forwards the `text`
+ and `kwargs` arguments to CLIPTokenizerFast's [`~CLIPTokenizerFast.__call__`] if `text` is not `None` to encode
+ the text. To prepare the image(s), this method forwards the `videos` and `kwargs` arguments to
+ VideoMAEImageProcessor's [`~VideoMAEImageProcessor.__call__`] if `videos` is not `None`. Please refer to the
+ docstring of the above two methods for more information.
+
+ Args:
+ text (`str`, `list[str]`, `list[list[str]]`):
+ The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings
+ (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set
+ `is_split_into_words=True` (to lift the ambiguity with a batch of sequences).
+ videos (`list[PIL.Image.Image]`, `list[np.ndarray]`, `list[torch.Tensor]`, `list[list[PIL.Image.Image]]`, `list[list[np.ndarray]]`,:
+ `list[list[torch.Tensor]]`): The video or batch of videos to be prepared. Each video should be a list
+ of frames, which can be either PIL images or NumPy arrays. In case of NumPy arrays/PyTorch tensors,
+ each frame should be of shape (H, W, C), where H and W are frame height and width, and C is a number of
+ channels.
+
+ return_tensors (`str` or [`~utils.TensorType`], *optional*):
+ If set, will return tensors of a particular framework. Acceptable values are:
+
+ - `'tf'`: Return TensorFlow `tf.constant` objects.
+ - `'pt'`: Return PyTorch `torch.Tensor` objects.
+ - `'np'`: Return NumPy `np.ndarray` objects.
+ - `'jax'`: Return JAX `jnp.ndarray` objects.
+
+ Returns:
+ [`BatchEncoding`]: A [`BatchEncoding`] with the following fields:
+
+ - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`.
+ - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when
+ `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not
+ `None`).
+ - **pixel_values** -- Pixel values to be fed to a model. Returned when `videos` is not `None`.
+ """
+
+ if text is None and videos is None:
+ raise ValueError("You have to specify either text or videos. Both cannot be none.")
+
+ if text is not None:
+ encoding = self.tokenizer(text, return_tensors=return_tensors, **kwargs)
+
+ if videos is not None:
+ image_features = self.image_processor(videos, return_tensors=return_tensors, **kwargs)
+
+ if text is not None and videos is not None:
+ encoding["pixel_values"] = image_features.pixel_values
+ return encoding
+ elif text is not None:
+ return encoding
+ else:
+ return BatchEncoding(data=dict(**image_features), tensor_type=return_tensors)
+
+ @property
+ def feature_extractor_class(self):
+ warnings.warn(
+ "`feature_extractor_class` is deprecated and will be removed in v5. Use `image_processor_class` instead.",
+ FutureWarning,
+ )
+ return self.image_processor_class
+
+ @property
+ def feature_extractor(self):
+ warnings.warn(
+ "`feature_extractor` is deprecated and will be removed in v5. Use `image_processor` instead.",
+ FutureWarning,
+ )
+ return self.image_processor
+
+
+__all__ = ["XCLIPProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..17c79e8aeeed547655d59eb8543333b0b7425319
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2025 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_xcodec import *
+ from .modeling_xcodec import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/configuration_xcodec.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/configuration_xcodec.py
new file mode 100644
index 0000000000000000000000000000000000000000..959838cc1d575f6bad7b10a68acbbeec2d25b9ec
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/configuration_xcodec.py
@@ -0,0 +1,186 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Xcodec model configuration"""
+
+import math
+from typing import Optional, Union
+
+import numpy as np
+
+from transformers import AutoConfig, DacConfig, HubertConfig, WavLMConfig
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XcodecConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of an [`XcodecModel`]. It is used to instantiate a
+ Xcodec model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the
+ [Manel/X-Codec](https://huggingface.co/Manel/X-Codec) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ target_bandwidths (`List[float]`, *optional*, defaults to `[0.5, 1, 1.5, 2, 4]`):
+ The range of different bandwidths (in kbps) the model can encode audio with.
+ sample_rate (`int`, *optional*, defaults to 16000):
+ The sampling rate at which the audio waveform should be digitalized, in hertz (Hz).
+ kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size for the initial semantic convolution.
+ channel_ratios (`List[float]`, *optional*, defaults to `[1, 1]`):
+ Expansion factors for the number of output channels in each semantic block.
+ strides (`List[int]`, *optional*, defaults to `[1, 1]`):
+ Strides for each semantic encoder block.
+ block_dilations (`List[int]`, *optional*, defaults to `[1, 1]`):
+ Dilation factors for the residual units in semantic blocks.
+ unit_kernel_size (`int`, *optional*, defaults to 3):
+ Kernel size inside each ResidualUnit in semantic blocks.
+ codebook_size (`int`, *optional*, defaults to 1024):
+ Number of entries in each residual quantizer's codebook.
+ codebook_dim (`int`, *optional*):
+ Dimensionality of each codebook vector. Defaults to sum of hidden size of acoustic and semantic models.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ Standard deviation of the truncated normal initializer for all weight matrices.
+ acoustic_model_config (`Union[Dict, DacConfig]`, *optional*):
+ An instance of the configuration for the acoustic (DAC) model.
+ semantic_model_config (`Union[Dict, HubertConfig, WavLMConfig]`, *optional*):
+ An instance of the configuration object for the semantic (HuBERT) model.
+
+ Example:
+
+ ```python
+ >>> from transformers import XcodecModel, XcodecConfig
+
+ >>> # Initializing configuration
+ >>> configuration = XcodecConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = XcodecModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xcodec"
+
+ sub_configs = {
+ "acoustic_model_config": DacConfig,
+ "semantic_model_config": AutoConfig,
+ }
+
+ def __init__(
+ self,
+ target_bandwidths: Optional[list[float]] = None,
+ sample_rate: int = 16000,
+ kernel_size: int = 3,
+ channel_ratios: list[float] = [1, 1],
+ strides: list[int] = [1, 1],
+ block_dilations: list[int] = [1, 1],
+ unit_kernel_size: int = 3,
+ codebook_size: int = 1024,
+ codebook_dim: Optional[int] = None,
+ initializer_range: float = 0.02,
+ acoustic_model_config: Union[dict, DacConfig] = None,
+ semantic_model_config: Union[dict, HubertConfig] = None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ if acoustic_model_config is None:
+ self.acoustic_model_config = DacConfig(
+ encoder_hidden_size=64,
+ # NOTE: original DAC uses [2, 4, 8, 8] `downsampling ratios`, namely reverse of `upsampling_ratios`
+ # (not sure if intentional by Xcodec but we keep it)
+ downsampling_ratios=[8, 5, 4, 2],
+ decoder_hidden_size=1024,
+ upsampling_ratios=[8, 5, 4, 2],
+ hidden_size=256,
+ )
+ elif isinstance(acoustic_model_config, dict):
+ self.acoustic_model_config = DacConfig(**acoustic_model_config)
+ elif isinstance(acoustic_model_config, DacConfig):
+ self.acoustic_model_config = acoustic_model_config
+ else:
+ raise ValueError(
+ f"acoustic_model_config must be a dict or DacConfig instance, but got {type(acoustic_model_config)}"
+ )
+
+ if semantic_model_config is None:
+ self.semantic_model_config = HubertConfig()
+ elif isinstance(semantic_model_config, dict):
+ if "_name_or_path" in semantic_model_config:
+ # If the config is a path, load it using AutoConfig
+ self.semantic_model_config = AutoConfig.from_pretrained(semantic_model_config["_name_or_path"])
+ else:
+ # assume HubertConfig as probably created from scratch
+ logger.warning(
+ "Could not determine semantic model type from config architecture. Defaulting to `HubertConfig`."
+ )
+ self.semantic_model_config = HubertConfig(**semantic_model_config)
+ elif isinstance(semantic_model_config, WavLMConfig) or isinstance(semantic_model_config, HubertConfig):
+ self.semantic_model_config = semantic_model_config
+ else:
+ raise ValueError(
+ f"semantic_model_config must be a dict, HubertConfig, or WavLMConfig instance, but got {type(semantic_model_config)}"
+ )
+
+ if target_bandwidths is None:
+ target_bandwidths = [0.5, 1, 1.5, 2, 4]
+
+ self.target_bandwidths = target_bandwidths
+ self.sample_rate = sample_rate
+ self.kernel_size = kernel_size
+ self.channel_ratios = channel_ratios
+ self.strides = strides
+ self.block_dilations = block_dilations
+ self.unit_kernel_size = unit_kernel_size
+ self.codebook_size = codebook_size
+ self.initializer_range = initializer_range
+ if codebook_dim is None:
+ codebook_dim = self.acoustic_model_config.hidden_size + self.semantic_model_config.hidden_size
+ self.codebook_dim = codebook_dim
+
+ @property
+ def frame_rate(self) -> int:
+ return math.ceil(self.sample_rate / self.hop_length)
+
+ @property
+ def semantic_hidden_size(self) -> int:
+ return self.semantic_model_config.hidden_size
+
+ @property
+ def hop_length(self) -> int:
+ return int(np.prod(self.acoustic_model_config.downsampling_ratios))
+
+ @property
+ def codebook_nbits(self) -> int:
+ return math.ceil(math.log2(self.codebook_size))
+
+ @property
+ def hidden_size(self) -> int:
+ return self.acoustic_model_config.hidden_size + self.semantic_model_config.hidden_size
+
+ @property
+ def num_quantizers(self) -> int:
+ return int(1000 * self.target_bandwidths[-1] // (self.frame_rate * self.codebook_nbits))
+
+
+__all__ = ["XcodecConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/modeling_xcodec.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/modeling_xcodec.py
new file mode 100644
index 0000000000000000000000000000000000000000..8909162db7240a9cea6c67c53a69ce3b781b9a96
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xcodec/modeling_xcodec.py
@@ -0,0 +1,561 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Transformers Xcodec model."""
+
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ...modeling_utils import PreTrainedAudioTokenizerBase
+from ...utils import ModelOutput, auto_docstring
+from ..auto import AutoModel
+from .configuration_xcodec import XcodecConfig
+
+
+@dataclass
+class XcodecOutput(ModelOutput):
+ """
+ Args:
+ audio_codes (`torch.LongTensor` of shape `(batch_size, num_quantizers, codes_length)`, *optional*):
+ Discrete code indices computed using `model.encode`.
+ audio_values (`torch.FloatTensor` of shape `(batch_size, channels, num_samples)`, *optional*)
+ Decoded audio values obtained using the decoder part of Xcodec.
+ """
+
+ audio_codes: Optional[torch.LongTensor] = None
+ audio_values: Optional[torch.FloatTensor] = None
+
+
+@dataclass
+class XcodecEncoderOutput(ModelOutput):
+ """
+ Args:
+ audio_codes (`torch.LongTensor` of shape `(batch_size, num_quantizers, codes_length)`, *optional*):
+ Discrete code indices computed using `model.encode`.
+ """
+
+ audio_codes: Optional[torch.LongTensor] = None
+
+
+@dataclass
+class XcodecDecoderOutput(ModelOutput):
+ """
+ Args:
+ audio_values (`torch.FloatTensor` of shape `(batch_size, channels, num_samples)`, *optional*):
+ Decoded audio values obtained using the decoder part of Xcodec.
+ """
+
+ audio_values: Optional[torch.FloatTensor] = None
+
+
+class ResidualUnit(nn.Module):
+ """Residual block for SemanticEncoder and SemanticDecoder used in Xcodec."""
+
+ def __init__(self, config: XcodecConfig, in_channels: int, out_channels: int, dilation: int):
+ super().__init__()
+ self.activation = nn.ELU()
+ padding = ((config.unit_kernel_size - 1) // 2) * dilation
+ self.conv1 = nn.Conv1d(
+ in_channels,
+ out_channels,
+ config.unit_kernel_size,
+ stride=1,
+ padding=padding,
+ dilation=dilation,
+ groups=1,
+ bias=False,
+ )
+ self.conv2 = nn.Conv1d(in_channels=out_channels, out_channels=out_channels, kernel_size=1, bias=False)
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ output_tensor = self.activation(hidden_state)
+ output_tensor = self.conv1(output_tensor)
+ output_tensor = self.activation(output_tensor)
+ output_tensor = self.conv2(output_tensor)
+ return hidden_state + output_tensor
+
+
+class SemanticEncoderBlock(nn.Module):
+ def __init__(self, config: XcodecConfig, in_channels: int, out_channels: int, stride: int):
+ super().__init__()
+ self.res_units = nn.ModuleList(
+ [ResidualUnit(config, in_channels, in_channels, dilation) for dilation in config.block_dilations]
+ )
+
+ # special case: stride=1, do not use kernel=2
+ kernel = 3 if stride == 1 else (2 * stride)
+ padding = (kernel - 1) // 2
+ self.conv = nn.Conv1d(in_channels, out_channels, kernel_size=kernel, stride=stride, padding=padding, bias=True)
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ for unit in self.res_units:
+ hidden_state = unit(hidden_state)
+ hidden_state = self.conv(hidden_state)
+ return hidden_state
+
+
+class SemanticEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ if len(config.strides) != len(config.channel_ratios):
+ raise ValueError("Number of strides must match the number of channel_ratios.")
+ self.conv = nn.Conv1d(
+ config.semantic_hidden_size,
+ config.semantic_hidden_size,
+ config.kernel_size,
+ 1,
+ config.kernel_size // 2,
+ bias=False,
+ )
+
+ in_channels = config.semantic_hidden_size
+ conv_blocks = []
+ for i, stride in enumerate(config.strides):
+ out_channels = int(config.semantic_hidden_size * config.channel_ratios[i])
+ conv_blocks += [SemanticEncoderBlock(config, in_channels, out_channels, stride)]
+ in_channels = out_channels
+
+ self.conv_blocks = nn.ModuleList(conv_blocks)
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ hidden_state = self.conv(hidden_state)
+ for block in self.conv_blocks:
+ hidden_state = block(hidden_state)
+ return hidden_state
+
+
+class SemanticDecoderBlock(nn.Module):
+ def __init__(self, config: XcodecConfig, in_channels: int, out_channels: int, stride: int):
+ super().__init__()
+ if stride == 1:
+ self.conv = nn.Conv1d(
+ in_channels,
+ out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ bias=True,
+ )
+ else:
+ kernel_size = 2 * stride
+ padding = (stride + 1) // 2
+ output_padding = 1 if stride % 2 == 1 else 0
+ self.conv = nn.ConvTranspose1d(
+ in_channels, out_channels, kernel_size, stride, padding, output_padding, bias=False
+ )
+
+ self.res_units = nn.ModuleList(
+ [ResidualUnit(config, out_channels, out_channels, dilation) for dilation in config.block_dilations]
+ )
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ hidden_state = self.conv(hidden_state)
+ for unit in self.res_units:
+ hidden_state = unit(hidden_state)
+ return hidden_state
+
+
+class SemanticDecoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.conv1 = nn.Conv1d(
+ in_channels=config.semantic_hidden_size,
+ out_channels=int(config.semantic_hidden_size * config.channel_ratios[0]),
+ kernel_size=config.kernel_size,
+ stride=1,
+ padding=config.kernel_size // 2,
+ bias=False,
+ )
+ conv_blocks = []
+ for i, stride in enumerate(config.strides):
+ in_channels = int(config.semantic_hidden_size * config.channel_ratios[i])
+
+ if i < (len(config.channel_ratios) - 1):
+ out_channels = int(config.semantic_hidden_size * config.channel_ratios[i + 1])
+ else:
+ out_channels = config.semantic_hidden_size
+
+ conv_blocks += [SemanticDecoderBlock(config, in_channels, out_channels, stride)]
+
+ self.conv_blocks = nn.ModuleList(conv_blocks)
+ self.conv2 = nn.Conv1d(
+ config.semantic_hidden_size,
+ config.semantic_hidden_size,
+ config.kernel_size,
+ stride=1,
+ padding=config.kernel_size // 2,
+ bias=False,
+ )
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ hidden_state = self.conv1(hidden_state)
+ for block in self.conv_blocks:
+ hidden_state = block(hidden_state)
+ hidden_state = self.conv2(hidden_state)
+ return hidden_state
+
+
+class XcodecEuclideanCodebook(nn.Module):
+ """Codebook with Euclidean distance."""
+
+ def __init__(self, config):
+ super().__init__()
+ embed = torch.zeros(config.codebook_size, config.codebook_dim)
+ self.codebook_size = config.codebook_size
+ self.register_buffer("inited", torch.Tensor([True]))
+ self.register_buffer("cluster_size", torch.zeros(config.codebook_size))
+ self.register_buffer("embed", embed)
+ self.register_buffer("embed_avg", embed.clone())
+
+ # Copied from transformers.models.encodec.modeling_encodec.EncodecEuclideanCodebook.quantize
+ def quantize(self, hidden_states):
+ embed = self.embed.t()
+ scaled_states = hidden_states.pow(2).sum(1, keepdim=True)
+ dist = -(scaled_states - 2 * hidden_states @ embed + embed.pow(2).sum(0, keepdim=True))
+ embed_ind = dist.max(dim=-1).indices
+ return embed_ind
+
+ def encode(self, hidden_states):
+ shape = hidden_states.shape
+ hidden_states = hidden_states.reshape((-1, shape[-1]))
+ embed_ind = self.quantize(hidden_states)
+ embed_ind = embed_ind.view(*shape[:-1])
+ return embed_ind
+
+ def decode(self, embed_ind):
+ quantized = F.embedding(embed_ind, self.embed)
+ return quantized
+
+
+class XcodecVectorQuantization(nn.Module):
+ """
+ Vector quantization implementation. Currently supports only euclidean distance.
+ """
+
+ def __init__(self, config: XcodecConfig):
+ super().__init__()
+ self.codebook = XcodecEuclideanCodebook(config)
+
+ # Copied from transformers.models.encodec.modeling_encodec.EncodecVectorQuantization.encode
+ def encode(self, hidden_states):
+ hidden_states = hidden_states.permute(0, 2, 1)
+ embed_in = self.codebook.encode(hidden_states)
+ return embed_in
+
+ # Copied from transformers.models.encodec.modeling_encodec.EncodecVectorQuantization.decode
+ def decode(self, embed_ind):
+ quantize = self.codebook.decode(embed_ind)
+ quantize = quantize.permute(0, 2, 1)
+ return quantize
+
+
+class XcodecResidualVectorQuantization(nn.Module):
+ """
+ Residual vector quantization implementation. Follows Algorithm 1 in https://huggingface.co/papers/2107.03312
+ """
+
+ def __init__(self, config: XcodecConfig):
+ super().__init__()
+ self.quantizers = nn.ModuleList([XcodecVectorQuantization(config) for _ in range(config.num_quantizers)])
+ self.frame_rate = config.frame_rate
+ self.codebook_size = config.codebook_size
+ self.num_quantizers = config.num_quantizers
+
+ def get_bandwidth_per_quantizer(self):
+ """Return bandwidth per quantizer."""
+ return math.log2(self.codebook_size) * self.frame_rate / 1000
+
+ def get_num_quantizers_for_bandwidth(self, bandwidth=None) -> int:
+ """Return num_quantizers based on specified target bandwidth."""
+ bw_per_q = self.get_bandwidth_per_quantizer()
+ num_quantizers = self.num_quantizers
+ if bandwidth is not None and bandwidth > 0.0:
+ num_quantizers = int(max(1, math.floor(bandwidth / bw_per_q)))
+ return num_quantizers
+
+ def encode(self, embeddings: torch.Tensor, bandwidth=None) -> torch.Tensor:
+ """
+ Encode the input tensor into discrete indices using RVQ, with the number of quantizers selected based on the given bandwidth.
+ Each quantizer /codebook residually quantizes the input and returns the nearest indices in terms of Euclidian distance.
+ """
+ num_quantizers = self.get_num_quantizers_for_bandwidth(bandwidth)
+ residual = embeddings
+ all_indices = []
+ for quantizer in self.quantizers[:num_quantizers]:
+ indices = quantizer.encode(residual)
+ quantized = quantizer.decode(indices)
+ residual = residual - quantized
+ all_indices.append(indices)
+ out_indices = torch.stack(all_indices)
+ return out_indices
+
+ def decode(self, codes: torch.Tensor) -> torch.Tensor:
+ """Decode the given codes to their quantized representation."""
+ quantized_out = torch.tensor(0.0, device=codes.device)
+ for i, indices in enumerate(codes):
+ quantizer = self.quantizers[i]
+ quantized = quantizer.decode(indices)
+ quantized_out = quantized_out + quantized
+ return quantized_out
+
+
+@auto_docstring
+class XcodecPreTrainedModel(PreTrainedAudioTokenizerBase):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = XcodecConfig
+ base_model_prefix = "xcodec"
+ main_input_name = "input_values"
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+
+ elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, nn.Conv1d):
+ nn.init.kaiming_normal_(module.weight)
+ if module.bias is not None:
+ k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0]))
+ nn.init.uniform_(module.bias, a=-k, b=k)
+
+ def apply_weight_norm(self):
+ """Apply weight norm in the acoustic encoder and decoder because the original checkpoint has weight norm applied."""
+ weight_norm = torch.nn.utils.weight_norm
+ if hasattr(torch.nn.utils.parametrizations, "weight_norm"):
+ weight_norm = torch.nn.utils.parametrizations.weight_norm
+
+ weight_norm(self.acoustic_encoder.conv1)
+ weight_norm(self.acoustic_encoder.conv2)
+
+ for block in self.acoustic_encoder.block:
+ weight_norm(block.conv1)
+ for res_unit in (block.res_unit1, block.res_unit2, block.res_unit3):
+ weight_norm(res_unit.conv1)
+ weight_norm(res_unit.conv2)
+
+ weight_norm(self.acoustic_decoder.conv1, name="weight")
+ weight_norm(self.acoustic_decoder.conv2, name="weight")
+
+ for block in self.acoustic_decoder.block:
+ weight_norm(block.conv_t1, name="weight")
+ for res_unit in (block.res_unit1, block.res_unit2, block.res_unit3):
+ weight_norm(res_unit.conv1, name="weight")
+ weight_norm(res_unit.conv2, name="weight")
+
+ def remove_weight_norm(self):
+ """Remove the weight norm from the acoustic encoder and decoder."""
+ for module in (self.acoustic_encoder, self.acoustic_decoder):
+ for m in module.modules():
+ try:
+ torch.nn.utils.remove_weight_norm(m, name="weight")
+ except (ValueError, AttributeError):
+ pass
+ if hasattr(m, "parametrizations") and "weight" in m.parametrizations:
+ torch.nn.utils.parametrize.remove_parametrizations(m, "weight", leave_parametrized=True)
+
+
+@auto_docstring(custom_intro="""The Xcodec neural audio codec model.""")
+class XcodecModel(XcodecPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+ self.pad = config.hop_length // 2
+ acoustic_model = AutoModel.from_config(config.acoustic_model_config)
+ self.acoustic_encoder = acoustic_model.encoder
+ self.acoustic_decoder = acoustic_model.decoder
+ self._adjust_dac_decoder(self.acoustic_decoder)
+ self.encoder_semantic = SemanticEncoder(config)
+ self.decoder_semantic = SemanticDecoder(config)
+ self.semantic_model = AutoModel.from_config(config.semantic_model_config).eval()
+ self.fc = nn.Linear(config.hidden_size, config.hidden_size)
+ self.fc1 = nn.Linear(config.hidden_size, config.semantic_model_config.hidden_size)
+ self.fc2 = nn.Linear(config.hidden_size, config.acoustic_model_config.hidden_size)
+ self.quantizer = XcodecResidualVectorQuantization(config)
+
+ @staticmethod
+ def _adjust_dac_decoder(decoder: nn.Module):
+ r"""
+ DAC implemented in Xcodec is slightly different from the HF version.
+ DAC in Xcodec adjusts the output padding in every ConvTranspose1d in the decoder and removes
+ the final `nn.Tanh` activation function.
+ """
+ for module in decoder.modules():
+ if isinstance(module, nn.ConvTranspose1d):
+ stride = module.stride[0] if isinstance(module.stride, tuple) else module.stride
+ module.output_padding = (stride % 2,)
+ if hasattr(decoder, "tanh") and isinstance(decoder.tanh, nn.Tanh):
+ decoder.tanh = nn.Identity()
+
+ def _extract_semantic_features(self, input_values: torch.FloatTensor) -> torch.FloatTensor:
+ input_values = input_values[:, 0, :]
+ input_values = F.pad(input_values, (self.pad, self.pad))
+ with torch.no_grad():
+ outputs = self.semantic_model(input_values, output_hidden_states=True)
+ hidden_states = outputs.hidden_states
+
+ stacked = torch.stack(hidden_states, dim=1)
+ return stacked.mean(dim=1)
+
+ @auto_docstring
+ def encode(
+ self,
+ input_values: torch.Tensor,
+ bandwidth: Optional[float] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[torch.Tensor, XcodecEncoderOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, channels, num_samples)`):
+ Float values of the input audio waveform.
+ bandwidth (`float`, *optional*):
+ The target bandwidth in (kbps) supports only values in `config.target_bandwidths`.
+ Defaults to the highest available bandwidth `4.0` kbps.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`].
+
+ Returns:
+ `torch.LongTensor` of shape `(batch_size, num_quantizers, codes_length)` containing the discrete encoded audio codes.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ channels = input_values.shape[1]
+ if channels != 1:
+ raise ValueError(f"Audio must be mono, but got {channels}")
+
+ if bandwidth is None:
+ bandwidth = self.config.target_bandwidths[-1]
+ elif bandwidth not in self.config.target_bandwidths:
+ raise ValueError(
+ f"This model doesn't support the bandwidth {bandwidth}. Select one of {self.config.target_bandwidths}."
+ )
+
+ e_semantic_input = self._extract_semantic_features(input_values).detach()
+ e_semantic = self.encoder_semantic(e_semantic_input.transpose(1, 2))
+ e_acoustic = self.acoustic_encoder(input_values)
+
+ if e_acoustic.shape[2] != e_semantic.shape[2]:
+ # make sure they line up if frames don't match
+ e_acoustic = self.acoustic_encoder(F.pad(input_values[:, 0, :], (self.pad, self.pad)).unsqueeze(1))
+
+ embeddings = torch.cat([e_acoustic, e_semantic], dim=1)
+ embeddings = self.fc(embeddings.transpose(1, 2)).transpose(1, 2)
+ audio_codes = self.quantizer.encode(embeddings, bandwidth)
+ audio_codes = audio_codes.transpose(0, 1)
+
+ if not return_dict:
+ return audio_codes
+
+ return XcodecEncoderOutput(audio_codes)
+
+ @auto_docstring
+ def decode(
+ self,
+ audio_codes: torch.Tensor,
+ return_dict: Optional[bool] = None,
+ ) -> Union[torch.Tensor, XcodecDecoderOutput]:
+ r"""
+ audio_codes (`torch.LongTensor` of shape `(batch_size, num_quantizers, codes_length)`):
+ Discrete code indices computed using `model.encode`.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`]
+
+ Returns:
+ Decoded audio values of shape `(batch_size, channels, num_samples)` obtained using the decoder part of
+ Xcodec.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ audio_codes = audio_codes.transpose(0, 1)
+ quantized = self.quantizer.decode(audio_codes)
+ quantized_acoustic = self.fc2(quantized.transpose(1, 2)).transpose(1, 2)
+ audio_values = self.acoustic_decoder(quantized_acoustic)
+
+ if not return_dict:
+ return audio_values
+
+ return XcodecDecoderOutput(audio_values)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_values: torch.Tensor,
+ audio_codes: Optional[torch.Tensor] = None,
+ bandwidth: Optional[float] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor, torch.Tensor], XcodecOutput]:
+ r"""
+ input_values (`torch.FloatTensor` of shape `(batch_size, channels, num_samples)`):
+ The raw float values of the input audio waveform.
+ audio_codes (`torch.LongTensor` of shape `(batch_size, num_quantizers, codes_length)`:
+ Discrete code indices computed using `model.encode`.
+ bandwidth (`float`, *optional*):
+ Target bandwidth in kbps. Must be one of `config.target_bandwidths`. Defaults to the highest available bandwidth.
+ bandwidth (`float`, *optional*):
+ Target bandwidth in kbps. Must be one of `config.target_bandwidths`. Defaults to the highest available bandwidth.
+ return_dict (`bool`, *optional*):
+ Whether to return a [`XcodecOutput`] instead of a plain tuple.
+
+ Returns:
+ `XcodecOutput` or tuple `(audio_codes, audio_values)`:
+ - `audio_codes` of shape `(batch_size, num_quantizers, codes_length)`: the quantized discrete codes.
+ - `audio_values` of shape `(batch_size, channels, num_samples)`: the reconstructed audio waveform given the codes.
+
+ Example:
+
+ ```python
+ >>> from datasets import load_dataset
+ >>> from transformers import AutoFeatureExtractor, XcodecModel
+
+ >>> model_id = "hf-audio/xcodec-hubert-librispeech"
+ >>> model = XcodecModel.from_pretrained(model_id)
+ >>> feature_extractor = AutoFeatureExtractor.from_pretrained(model_id)
+
+ >>> dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> dataset = dataset.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+ >>> audio_sample = dataset[0]['audio']['array']
+
+ >>> inputs = feature_extractor(raw_audio=audio_sample, return_tensors="pt")
+
+ >>> outputs = model(**inputs)
+ >>> audio_codes = outputs.audio_codes
+ >>> audio_values = outputs.audio_values
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+ length = input_values.shape[-1]
+
+ if audio_codes is None:
+ audio_codes = self.encode(input_values, bandwidth, return_dict=False)
+
+ audio_values = self.decode(audio_codes, return_dict=return_dict)[0][..., :length]
+
+ if not return_dict:
+ return (audio_codes, audio_values)
+
+ return XcodecOutput(audio_codes=audio_codes, audio_values=audio_values)
+
+
+__all__ = ["XcodecModel", "XcodecPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1eefd79d4cf7c3e9a24aa2f06d40f354a8fc28b2
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/__init__.py
@@ -0,0 +1,31 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_xglm import *
+ from .modeling_flax_xglm import *
+ from .modeling_tf_xglm import *
+ from .modeling_xglm import *
+ from .tokenization_xglm import *
+ from .tokenization_xglm_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/configuration_xglm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/configuration_xglm.py
new file mode 100644
index 0000000000000000000000000000000000000000..d8a3be370b7f479e0bd60a7d3e9468a3eed3ea9e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/configuration_xglm.py
@@ -0,0 +1,139 @@
+# coding=utf-8
+# Copyright The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""XGLM model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XGLMConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`XGLMModel`]. It is used to instantiate an XGLM
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the XGLM
+ [facebook/xglm-564M](https://huggingface.co/facebook/xglm-564M) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 256008):
+ Vocabulary size of the XGLM model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`XGLMModel`] or [`FlaxXGLMModel`].
+ max_position_embeddings (`int`, *optional*, defaults to 2048):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ d_model (`int`, *optional*, defaults to 1024):
+ Dimension of the layers and the pooler layer.
+ ffn_dim (`int`, *optional*, defaults to 4096):
+ Dimension of the "intermediate" (often named feed-forward) layer in decoder.
+ num_layers (`int`, *optional*, defaults to 24):
+ Number of hidden layers Transformer decoder.
+ attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ activation_function (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, dencoder, and pooler.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ activation_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for activations inside the fully connected layer.
+ layerdrop (`float`, *optional*, defaults to 0.0):
+ The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556)
+ for more details.
+ init_std (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ scale_embedding (`bool`, *optional*, defaults to `True`):
+ Scale embeddings by diving by sqrt(d_model).
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models).
+
+ Example:
+
+ ```python
+ >>> from transformers import XGLMModel, XGLMConfig
+
+ >>> # Initializing a XGLM facebook/xglm-564M style configuration
+ >>> configuration = XGLMConfig()
+
+ >>> # Initializing a model from the facebook/xglm-564M style configuration
+ >>> model = XGLMModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xglm"
+ keys_to_ignore_at_inference = ["past_key_values"]
+
+ attribute_map = {
+ "num_attention_heads": "attention_heads",
+ "hidden_size": "d_model",
+ "num_hidden_layers": "num_layers",
+ }
+
+ def __init__(
+ self,
+ vocab_size=256008,
+ max_position_embeddings=2048,
+ d_model=1024,
+ ffn_dim=4096,
+ num_layers=24,
+ attention_heads=16,
+ activation_function="gelu",
+ dropout=0.1,
+ attention_dropout=0.1,
+ activation_dropout=0.0,
+ layerdrop=0.0,
+ init_std=0.02,
+ scale_embedding=True,
+ use_cache=True,
+ decoder_start_token_id=2,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.d_model = d_model
+ self.ffn_dim = ffn_dim
+ self.num_layers = num_layers
+ self.attention_heads = attention_heads
+ self.activation_function = activation_function
+ self.dropout = dropout
+ self.attention_dropout = attention_dropout
+ self.activation_dropout = activation_dropout
+ self.layerdrop = layerdrop
+ self.init_std = init_std
+ self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True
+ self.use_cache = use_cache
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ decoder_start_token_id=decoder_start_token_id,
+ **kwargs,
+ )
+
+
+__all__ = ["XGLMConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_flax_xglm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_flax_xglm.py
new file mode 100644
index 0000000000000000000000000000000000000000..1366148d9a3dbcbf1eea9affb027634038149b4d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_flax_xglm.py
@@ -0,0 +1,803 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Flax XGLM model."""
+
+import math
+import random
+from functools import partial
+from typing import Optional
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+import numpy as np
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.linen import combine_masks, make_causal_mask
+from flax.linen.attention import dot_product_attention_weights
+from flax.traverse_util import flatten_dict, unflatten_dict
+from jax import lax
+from jax.random import PRNGKey
+
+from ...modeling_flax_outputs import (
+ FlaxBaseModelOutputWithPastAndCrossAttentions,
+ FlaxCausalLMOutputWithCrossAttentions,
+)
+from ...modeling_flax_utils import ACT2FN, FlaxPreTrainedModel, append_call_sample_docstring
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_xglm import XGLMConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "facebook/xglm-564M"
+_CONFIG_FOR_DOC = "XGLMConfig"
+
+XGLM_START_DOCSTRING = r"""
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a Flax Linen
+ [flax.nn.Module](https://flax.readthedocs.io/en/latest/_autosummary/flax.nn.module.html) subclass. Use it as a
+ regular Flax Module and refer to the Flax documentation for all matter related to general usage and behavior.
+
+ Finally, this model supports inherent JAX features such as:
+
+ - [Just-In-Time (JIT) compilation](https://jax.readthedocs.io/en/latest/jax.html#just-in-time-compilation-jit)
+ - [Automatic Differentiation](https://jax.readthedocs.io/en/latest/jax.html#automatic-differentiation)
+ - [Vectorization](https://jax.readthedocs.io/en/latest/jax.html#vectorization-vmap)
+ - [Parallelization](https://jax.readthedocs.io/en/latest/jax.html#parallelization-pmap)
+
+ Parameters:
+ config ([`XGLMConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+ dtype (`jax.numpy.dtype`, *optional*, defaults to `jax.numpy.float32`):
+ The data type of the computation. Can be one of `jax.numpy.float32`, `jax.numpy.float16` (on GPUs) and
+ `jax.numpy.bfloat16` (on TPUs).
+
+ This can be used to enable mixed-precision training or half-precision inference on GPUs or TPUs. If
+ specified all the computation will be performed with the given `dtype`.
+
+ **Note that this only specifies the dtype of the computation and does not influence the dtype of model
+ parameters.**
+
+ If you wish to change the dtype of the model parameters, see [`~FlaxPreTrainedModel.to_fp16`] and
+ [`~FlaxPreTrainedModel.to_bf16`].
+"""
+
+XGLM_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`jnp.ndarray` of shape `(batch_size, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide
+ it.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`jnp.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ position_ids (`numpy.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+def create_sinusoidal_positions(n_pos, dim, padding_idx=1):
+ half_dim = dim // 2
+ emb = math.log(10000) / (half_dim - 1)
+ emb = np.exp(np.arange(half_dim) * -emb)
+ emb = np.expand_dims(np.arange(n_pos), 1) * np.expand_dims(emb, 0)
+ emb = np.concatenate([np.sin(emb), np.cos(emb)], 1)
+ emb = np.reshape(emb, (n_pos, dim))
+
+ if padding_idx is not None:
+ emb[padding_idx, :] = 0
+
+ return jnp.array(emb)
+
+
+class FlaxXGLMAttention(nn.Module):
+ config: XGLMConfig
+ embed_dim: int
+ num_heads: int
+ dropout: float = 0.0
+ causal: bool = False
+ bias: bool = True
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self) -> None:
+ self.head_dim = self.embed_dim // self.num_heads
+
+ if self.head_dim * self.num_heads != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} "
+ f"and `num_heads`: {self.num_heads})."
+ )
+
+ dense = partial(
+ nn.Dense,
+ self.embed_dim,
+ use_bias=self.bias,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+
+ self.q_proj, self.k_proj, self.v_proj = dense(), dense(), dense()
+ self.out_proj = dense()
+
+ self.dropout_layer = nn.Dropout(rate=self.dropout)
+
+ if self.causal:
+ self.causal_mask = make_causal_mask(
+ jnp.ones((1, self.config.max_position_embeddings), dtype="bool"), dtype="bool"
+ )
+
+ def _split_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.num_heads, self.head_dim))
+
+ def _merge_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.embed_dim,))
+
+ @nn.compact
+ def _concatenate_to_cache(self, key, value, query, attention_mask):
+ """
+ This function takes projected key, value states from a single input token and concatenates the states to cached
+ states from previous steps. This function is slightly adapted from the official Flax repository:
+ https://github.com/google/flax/blob/491ce18759622506588784b4fca0e4bf05f8c8cd/flax/linen/attention.py#L252
+ """
+ # detect if we're initializing by absence of existing cache data.
+ is_initialized = self.has_variable("cache", "cached_key")
+ cached_key = self.variable("cache", "cached_key", jnp.zeros, key.shape, key.dtype)
+ cached_value = self.variable("cache", "cached_value", jnp.zeros, value.shape, value.dtype)
+ cache_index = self.variable("cache", "cache_index", lambda: jnp.array(0, dtype=jnp.int32))
+
+ if is_initialized:
+ *batch_dims, max_length, num_heads, depth_per_head = cached_key.value.shape
+ # update key, value caches with our new 1d spatial slices
+ cur_index = cache_index.value
+ indices = (0,) * len(batch_dims) + (cur_index, 0, 0)
+ key = lax.dynamic_update_slice(cached_key.value, key, indices)
+ value = lax.dynamic_update_slice(cached_value.value, value, indices)
+ cached_key.value = key
+ cached_value.value = value
+ num_updated_cache_vectors = query.shape[1]
+ cache_index.value = cache_index.value + num_updated_cache_vectors
+ # causal mask for cached decoder self-attention: our single query position should only attend
+ # to those key positions that have already been generated and cached, not the remaining zero elements.
+ pad_mask = jnp.broadcast_to(
+ jnp.arange(max_length) < cur_index + num_updated_cache_vectors,
+ tuple(batch_dims) + (1, num_updated_cache_vectors, max_length),
+ )
+ attention_mask = combine_masks(pad_mask, attention_mask)
+ return key, value, attention_mask
+
+ def __call__(
+ self,
+ hidden_states: jnp.ndarray,
+ key_value_states: Optional[jnp.ndarray] = None,
+ attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ batch_size = hidden_states.shape[0]
+
+ # get query proj
+ query_states = self.q_proj(hidden_states)
+ # get key, value proj
+ if is_cross_attention:
+ # cross_attentions
+ key_states = self.k_proj(key_value_states)
+ value_states = self.v_proj(key_value_states)
+ else:
+ # self_attention
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+
+ query_states = self._split_heads(query_states)
+ key_states = self._split_heads(key_states)
+ value_states = self._split_heads(value_states)
+
+ # handle cache prepare causal attention mask
+ if self.causal:
+ query_length, key_length = query_states.shape[1], key_states.shape[1]
+ if self.has_variable("cache", "cached_key"):
+ mask_shift = self.variables["cache"]["cache_index"]
+ max_decoder_length = self.variables["cache"]["cached_key"].shape[1]
+ causal_mask = lax.dynamic_slice(
+ self.causal_mask, (0, 0, mask_shift, 0), (1, 1, query_length, max_decoder_length)
+ )
+ else:
+ causal_mask = self.causal_mask[:, :, :query_length, :key_length]
+ causal_mask = jnp.broadcast_to(causal_mask, (batch_size,) + causal_mask.shape[1:])
+
+ # combine masks if needed
+ if attention_mask is not None and self.causal:
+ attention_mask = jnp.broadcast_to(jnp.expand_dims(attention_mask, axis=(-3, -2)), causal_mask.shape)
+ attention_mask = combine_masks(attention_mask, causal_mask)
+ elif self.causal:
+ attention_mask = causal_mask
+ elif attention_mask is not None:
+ attention_mask = jnp.expand_dims(attention_mask, axis=(-3, -2))
+
+ # During fast autoregressive decoding, we feed one position at a time,
+ # and cache the keys and values step by step.
+ if self.causal and (self.has_variable("cache", "cached_key") or init_cache):
+ key_states, value_states, attention_mask = self._concatenate_to_cache(
+ key_states, value_states, query_states, attention_mask
+ )
+
+ # Convert the boolean attention mask to an attention bias.
+ if attention_mask is not None:
+ # attention mask in the form of attention bias
+ attention_bias = lax.select(
+ attention_mask > 0,
+ jnp.full(attention_mask.shape, 0.0).astype(self.dtype),
+ jnp.full(attention_mask.shape, jnp.finfo(self.dtype).min).astype(self.dtype),
+ )
+ else:
+ attention_bias = None
+
+ dropout_rng = None
+ if not deterministic and self.dropout > 0.0:
+ dropout_rng = self.make_rng("dropout")
+
+ attn_weights = dot_product_attention_weights(
+ query_states,
+ key_states,
+ bias=attention_bias,
+ dropout_rng=dropout_rng,
+ dropout_rate=self.dropout,
+ broadcast_dropout=True,
+ deterministic=deterministic,
+ dtype=self.dtype,
+ precision=None,
+ )
+
+ attn_output = jnp.einsum("...hqk,...khd->...qhd", attn_weights, value_states)
+ attn_output = self._merge_heads(attn_output)
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights
+
+
+class FlaxXGLMDecoderLayer(nn.Module):
+ config: XGLMConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self) -> None:
+ self.embed_dim = self.config.d_model
+ self.self_attn = FlaxXGLMAttention(
+ config=self.config,
+ embed_dim=self.embed_dim,
+ num_heads=self.config.attention_heads,
+ dropout=self.config.attention_dropout,
+ causal=True,
+ dtype=self.dtype,
+ )
+ self.self_attn_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+ self.dropout_layer = nn.Dropout(rate=self.config.dropout)
+ self.activation_fn = ACT2FN[self.config.activation_function]
+ self.activation_dropout_layer = nn.Dropout(rate=self.config.activation_dropout)
+
+ if self.config.add_cross_attention:
+ self.encoder_attn = FlaxXGLMAttention(
+ config=self.config,
+ embed_dim=self.embed_dim,
+ num_heads=self.config.decoder_attention_heads,
+ dropout=self.config.attention_dropout,
+ dtype=self.dtype,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+
+ self.fc1 = nn.Dense(
+ self.config.ffn_dim,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+ self.fc2 = nn.Dense(
+ self.embed_dim, dtype=self.dtype, kernel_init=jax.nn.initializers.normal(self.config.init_std)
+ )
+ self.final_layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+
+ # Copied from transformers.models.mbart.modeling_flax_mbart.FlaxMBartDecoderLayer.__call__
+ def __call__(
+ self,
+ hidden_states: jnp.ndarray,
+ attention_mask: jnp.ndarray,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ output_attentions: bool = True,
+ deterministic: bool = True,
+ ) -> tuple[jnp.ndarray]:
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states, attention_mask=attention_mask, init_cache=init_cache
+ )
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ )
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+class FlaxXGLMDecoderLayerCollection(nn.Module):
+ config: XGLMConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.layers = [
+ FlaxXGLMDecoderLayer(self.config, name=str(i), dtype=self.dtype) for i in range(self.config.num_layers)
+ ]
+ self.layerdrop = self.config.layerdrop
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ deterministic: bool = True,
+ init_cache: bool = False,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ for decoder_layer in self.layers:
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ dropout_probability = random.uniform(0, 1)
+ if not deterministic and (dropout_probability < self.layerdrop):
+ layer_outputs = (None, None, None)
+ else:
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ init_cache=init_cache,
+ output_attentions=output_attentions,
+ deterministic=deterministic,
+ )
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ outputs = (hidden_states, all_hidden_states, all_self_attns, all_cross_attentions)
+
+ if not return_dict:
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+class FlaxXGLMModule(nn.Module):
+ config: XGLMConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dropout_layer = nn.Dropout(rate=self.config.dropout)
+
+ embed_dim = self.config.d_model
+ self.padding_idx = self.config.pad_token_id
+ self.max_target_positions = self.config.max_position_embeddings
+ self.embed_scale = math.sqrt(self.config.d_model) if self.config.scale_embedding else 1.0
+
+ self.embed_tokens = nn.Embed(
+ self.config.vocab_size,
+ embed_dim,
+ embedding_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+
+ # XGLM is set up so that if padding_idx is specified then offset the embedding ids by 2
+ # and adjust num_embeddings appropriately. Other models don't have this hack
+ self.offset = 2
+ self.embed_positions = create_sinusoidal_positions(
+ self.config.max_position_embeddings + self.offset, embed_dim
+ )
+ self.layers = FlaxXGLMDecoderLayerCollection(self.config, self.dtype)
+ self.layer_norm = nn.LayerNorm(dtype=self.dtype, epsilon=1e-05)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ position_ids,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ):
+ input_shape = input_ids.shape
+ input_ids = input_ids.reshape(-1, input_shape[-1])
+
+ inputs_embeds = self.embed_tokens(input_ids) * self.embed_scale
+
+ # embed positions
+ position_ids = position_ids + self.offset
+ positions = jnp.take(self.embed_positions, position_ids, axis=0)
+
+ hidden_states = inputs_embeds + positions
+ hidden_states = self.dropout_layer(hidden_states, deterministic=deterministic)
+
+ outputs = self.layers(
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ deterministic=deterministic,
+ init_cache=init_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ last_hidden_states = outputs[0]
+ last_hidden_states = self.layer_norm(last_hidden_states)
+
+ hidden_states = None
+ if output_hidden_states:
+ hidden_states = outputs[1]
+ hidden_states = hidden_states[:-1] + (last_hidden_states,)
+
+ if not return_dict:
+ outputs = (last_hidden_states, hidden_states) + (outputs[2:] if output_hidden_states else outputs[1:])
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=last_hidden_states,
+ hidden_states=hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+class FlaxXGLMPreTrainedModel(FlaxPreTrainedModel):
+ config_class = XGLMConfig
+ base_model_prefix: str = "model"
+ module_class: nn.Module = None
+
+ def __init__(
+ self,
+ config: XGLMConfig,
+ input_shape: tuple[int] = (1, 1),
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ **kwargs,
+ ):
+ module = self.module_class(config=config, dtype=dtype, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensors
+ input_ids = jnp.zeros(input_shape, dtype="i4")
+ attention_mask = jnp.ones_like(input_ids)
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_shape)
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ if self.config.add_cross_attention:
+ encoder_hidden_states = jnp.zeros(input_shape + (self.config.n_embd,))
+ encoder_attention_mask = attention_mask
+ module_init_outputs = self.module.init(
+ rngs,
+ input_ids,
+ attention_mask,
+ position_ids,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ return_dict=False,
+ )
+ else:
+ module_init_outputs = self.module.init(rngs, input_ids, attention_mask, position_ids, return_dict=False)
+
+ random_params = module_init_outputs["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ def init_cache(self, batch_size, max_length):
+ r"""
+ Args:
+ batch_size (`int`):
+ batch_size used for fast auto-regressive decoding. Defines the batch size of the initialized cache.
+ max_length (`int`):
+ maximum possible length for auto-regressive decoding. Defines the sequence length of the initialized
+ cache.
+ """
+ # init input variables to retrieve cache
+ input_ids = jnp.ones((batch_size, max_length), dtype="i4")
+ attention_mask = jnp.ones_like(input_ids, dtype="i4")
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_ids.shape)
+
+ init_variables = self.module.init(
+ jax.random.PRNGKey(0), input_ids, attention_mask, position_ids, return_dict=False, init_cache=True
+ )
+ return unfreeze(init_variables["cache"])
+
+ @add_start_docstrings_to_model_forward(XGLM_INPUTS_DOCSTRING)
+ def __call__(
+ self,
+ input_ids: jnp.ndarray,
+ attention_mask: Optional[jnp.ndarray] = None,
+ position_ids: Optional[jnp.ndarray] = None,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ train: bool = False,
+ params: Optional[dict] = None,
+ past_key_values: Optional[dict] = None,
+ dropout_rng: PRNGKey = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ if encoder_hidden_states is not None and encoder_attention_mask is None:
+ batch_size, sequence_length = encoder_hidden_states.shape[:2]
+ encoder_attention_mask = jnp.ones((batch_size, sequence_length))
+
+ # prepare encoder inputs
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+ if position_ids is None:
+ batch_size, sequence_length = input_ids.shape
+ position_ids = jnp.broadcast_to(jnp.arange(sequence_length)[None, :], (batch_size, sequence_length))
+
+ # Handle any PRNG if needed
+ rngs = {"dropout": dropout_rng} if dropout_rng is not None else {}
+
+ inputs = {"params": params or self.params}
+
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be passed
+ # down to ensure cache is used. It has to be made sure that cache is marked as mutable so that it can be
+ # changed by FlaxXGLMAttention module
+ if past_key_values:
+ inputs["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ outputs = self.module.apply(
+ inputs,
+ input_ids=jnp.array(input_ids, dtype="i4"),
+ attention_mask=jnp.array(attention_mask, dtype="i4"),
+ position_ids=jnp.array(position_ids, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ deterministic=not train,
+ rngs=rngs,
+ mutable=mutable,
+ )
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs, past_key_values = outputs
+ outputs["past_key_values"] = unfreeze(past_key_values["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs, past_key_values = outputs
+ outputs = outputs[:1] + (unfreeze(past_key_values["cache"]),) + outputs[1:]
+
+ return outputs
+
+
+@add_start_docstrings(
+ "The bare XGLM Model transformer outputting raw hidden-states without any specific head on top.",
+ XGLM_START_DOCSTRING,
+)
+class FlaxXGLMModel(FlaxXGLMPreTrainedModel):
+ module_class = FlaxXGLMModule
+
+
+append_call_sample_docstring(
+ FlaxXGLMModel,
+ _CHECKPOINT_FOR_DOC,
+ FlaxBaseModelOutputWithPastAndCrossAttentions,
+ _CONFIG_FOR_DOC,
+)
+
+
+class FlaxXGLMForCausalLMModule(nn.Module):
+ config: XGLMConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.model = FlaxXGLMModule(self.config, self.dtype)
+ self.lm_head = nn.Dense(
+ self.config.vocab_size,
+ use_bias=False,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.init_std),
+ )
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ position_ids,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ deterministic: bool = True,
+ ):
+ outputs = self.model(
+ input_ids,
+ attention_mask,
+ position_ids,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ deterministic=deterministic,
+ init_cache=init_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+
+ if self.config.tie_word_embeddings:
+ shared_embedding = self.model.variables["params"]["embed_tokens"]["embedding"]
+ lm_logits = self.lm_head.apply({"params": {"kernel": shared_embedding.T}}, hidden_states)
+ else:
+ lm_logits = self.lm_head(hidden_states)
+
+ if not return_dict:
+ return (lm_logits,) + outputs[1:]
+
+ return FlaxCausalLMOutputWithCrossAttentions(
+ logits=lm_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+@add_start_docstrings(
+ """
+ The XGLM Model transformer with a language modeling head on top (linear layer with weights tied to the input
+ embeddings).
+ """,
+ XGLM_START_DOCSTRING,
+)
+class FlaxXGLMForCausalLM(FlaxXGLMPreTrainedModel):
+ module_class = FlaxXGLMForCausalLMModule
+
+ def prepare_inputs_for_generation(self, input_ids, max_length, attention_mask: Optional[jax.Array] = None):
+ # initializing the cache
+ batch_size, seq_length = input_ids.shape
+
+ past_key_values = self.init_cache(batch_size, max_length)
+ # Note that usually one would have to put 0's in the attention_mask for x > input_ids.shape[-1] and x < cache_length.
+ # But since GPT2 uses a causal mask, those positions are masked anyways.
+ # Thus we can create a single static attention_mask here, which is more efficient for compilation
+ extended_attention_mask = jnp.ones((batch_size, max_length), dtype="i4")
+ if attention_mask is not None:
+ position_ids = attention_mask.cumsum(axis=-1) - 1
+ extended_attention_mask = lax.dynamic_update_slice(extended_attention_mask, attention_mask, (0, 0))
+ else:
+ position_ids = jnp.broadcast_to(jnp.arange(seq_length, dtype="i4")[None, :], (batch_size, seq_length))
+
+ return {
+ "past_key_values": past_key_values,
+ "attention_mask": extended_attention_mask,
+ "position_ids": position_ids,
+ }
+
+ def update_inputs_for_generation(self, model_outputs, model_kwargs):
+ model_kwargs["past_key_values"] = model_outputs.past_key_values
+ model_kwargs["position_ids"] = model_kwargs["position_ids"][:, -1:] + 1
+ return model_kwargs
+
+
+append_call_sample_docstring(
+ FlaxXGLMForCausalLM,
+ _CHECKPOINT_FOR_DOC,
+ FlaxCausalLMOutputWithCrossAttentions,
+ _CONFIG_FOR_DOC,
+)
+
+
+__all__ = ["FlaxXGLMForCausalLM", "FlaxXGLMModel", "FlaxXGLMPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_tf_xglm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_tf_xglm.py
new file mode 100644
index 0000000000000000000000000000000000000000..d799ced792080d6df30a14e787f187c4484c62c8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_tf_xglm.py
@@ -0,0 +1,1002 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TF 2.0 XGLM model."""
+
+from __future__ import annotations
+
+import math
+import random
+from typing import Any
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+
+# Public API
+from ...file_utils import (
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ replace_return_docstrings,
+)
+from ...modeling_tf_outputs import TFBaseModelOutputWithPastAndCrossAttentions, TFCausalLMOutputWithCrossAttentions
+from ...modeling_tf_utils import (
+ TFCausalLanguageModelingLoss,
+ TFModelInputType,
+ TFPreTrainedModel,
+ TFSharedEmbeddings,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import logging
+from .configuration_xglm import XGLMConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "facebook/xglm-564M"
+_CONFIG_FOR_DOC = "XGLMConfig"
+
+
+LARGE_NEGATIVE = -1e8
+
+
+def create_sinusoidal_positions(num_positions: int, embedding_dim: int, padding_idx: int | None) -> tf.Tensor:
+ half_dim = embedding_dim // 2
+ emb = math.log(10000) / (half_dim - 1)
+ emb = tf.exp(tf.range(half_dim, dtype=tf.float32) * -emb)
+ emb = tf.expand_dims(tf.range(num_positions, dtype=tf.float32), axis=1) * tf.expand_dims(emb, axis=0)
+ emb = tf.reshape(tf.concat([tf.sin(emb), tf.cos(emb)], axis=1), (num_positions, -1))
+ if embedding_dim % 2 == 1:
+ # zero pad
+ emb = tf.concat([emb, tf.zeros((num_positions, 1))], axis=1)
+ if padding_idx is not None:
+ _padding_mask = tf.concat(
+ [
+ tf.ones((padding_idx, shape_list(emb)[1])),
+ tf.zeros((1, shape_list(emb)[1])),
+ tf.ones((shape_list(emb)[0] - padding_idx - 1, shape_list(emb)[1])),
+ ],
+ axis=0,
+ )
+ emb *= _padding_mask
+
+ return tf.constant(emb, name="embed_positions")
+
+
+def _create_position_ids_from_input_ids(
+ input_ids: tf.Tensor, past_key_values_length: int, padding_idx: int | None
+) -> tf.Tensor:
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols
+ are ignored. This is modified from fairseq's `utils.make_positions`.
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = tf.where(input_ids != padding_idx, 1, 0)
+ incremental_indices = (tf.cast(tf.cumsum(mask, axis=1), dtype=mask.dtype) + past_key_values_length) * mask
+ return tf.cast(incremental_indices, dtype=tf.int64) + padding_idx
+
+
+def _create_position_ids_from_inputs_embeds(
+ inputs_embeds: tf.Tensor, past_key_values_length: int, padding_idx: int | None
+) -> tf.Tensor:
+ """
+ Args:
+ We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids.
+ inputs_embeds: tf.Tensor
+ Returns: tf.Tensor
+ """
+ input_shape = shape_list(inputs_embeds)[:-1]
+ sequence_length = input_shape[1]
+
+ position_ids = tf.range(padding_idx + 1, sequence_length + padding_idx + 1, dtype=tf.int64)
+
+ return tf.broadcast_to(tf.expand_dims(position_ids, axis=0), input_shape) + past_key_values_length
+
+
+# Copied from transformers.models.bart.modeling_tf_bart._make_causal_mask
+def _make_causal_mask(input_ids_shape: tf.TensorShape, past_key_values_length: int = 0):
+ """
+ Make causal mask used for bi-directional self-attention.
+ """
+ bsz = input_ids_shape[0]
+ tgt_len = input_ids_shape[1]
+ mask = tf.ones((tgt_len, tgt_len)) * LARGE_NEGATIVE
+ mask_cond = tf.range(shape_list(mask)[-1])
+
+ mask = tf.where(mask_cond < tf.reshape(mask_cond + 1, (shape_list(mask)[-1], 1)), 0.0, mask)
+
+ if past_key_values_length > 0:
+ mask = tf.concat([tf.zeros((tgt_len, past_key_values_length)), mask], axis=-1)
+
+ return tf.tile(mask[None, None, :, :], (bsz, 1, 1, 1))
+
+
+# Copied from transformers.models.bart.modeling_tf_bart._expand_mask
+def _expand_mask(mask: tf.Tensor, tgt_len: int | None = None):
+ """
+ Expands attention_mask from `[bsz, seq_len]` to `[bsz, 1, tgt_seq_len, src_seq_len]`.
+ """
+ src_len = shape_list(mask)[1]
+ tgt_len = tgt_len if tgt_len is not None else src_len
+ one_cst = tf.constant(1.0)
+ mask = tf.cast(mask, dtype=one_cst.dtype)
+ expanded_mask = tf.tile(mask[:, None, None, :], (1, 1, tgt_len, 1))
+
+ return (one_cst - expanded_mask) * LARGE_NEGATIVE
+
+
+# Copied from transformers.models.bart.modeling_tf_bart.TFBartAttention with Bart->XGLM
+class TFXGLMAttention(keras.layers.Layer):
+ """Multi-headed attention from "Attention Is All You Need"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: float = 0.0,
+ is_decoder: bool = False,
+ bias: bool = True,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+ self.embed_dim = embed_dim
+
+ self.num_heads = num_heads
+ self.dropout = keras.layers.Dropout(dropout)
+ self.head_dim = embed_dim // num_heads
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+
+ self.k_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="k_proj")
+ self.q_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="q_proj")
+ self.v_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="v_proj")
+ self.out_proj = keras.layers.Dense(embed_dim, use_bias=bias, name="out_proj")
+
+ def _shape(self, tensor: tf.Tensor, seq_len: int, bsz: int):
+ return tf.transpose(tf.reshape(tensor, (bsz, seq_len, self.num_heads, self.head_dim)), (0, 2, 1, 3))
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ key_value_states: tf.Tensor | None = None,
+ past_key_value: tuple[tuple[tf.Tensor]] | None = None,
+ attention_mask: tf.Tensor | None = None,
+ layer_head_mask: tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> tuple[tf.Tensor, tf.Tensor | None]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ bsz, tgt_len, embed_dim = shape_list(hidden_states)
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+ # get key, value proj
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_states = past_key_value[0]
+ value_states = past_key_value[1]
+ elif is_cross_attention:
+ # cross_attentions
+ key_states = self._shape(self.k_proj(key_value_states), -1, bsz)
+ value_states = self._shape(self.v_proj(key_value_states), -1, bsz)
+ elif past_key_value is not None:
+ # reuse k, v, self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+ key_states = tf.concat([past_key_value[0], key_states], axis=2)
+ value_states = tf.concat([past_key_value[1], value_states], axis=2)
+ else:
+ # self_attention
+ key_states = self._shape(self.k_proj(hidden_states), -1, bsz)
+ value_states = self._shape(self.v_proj(hidden_states), -1, bsz)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(tf.Tensor, tf.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(tf.Tensor, tf.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_states, value_states)
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = tf.reshape(self._shape(query_states, tgt_len, bsz), proj_shape)
+ key_states = tf.reshape(key_states, proj_shape)
+ value_states = tf.reshape(value_states, proj_shape)
+
+ src_len = shape_list(key_states)[1]
+ attn_weights = tf.matmul(query_states, key_states, transpose_b=True)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_weights),
+ [bsz * self.num_heads, tgt_len, src_len],
+ message=(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {shape_list(attn_weights)}"
+ ),
+ )
+
+ if attention_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(attention_mask),
+ [bsz, 1, tgt_len, src_len],
+ message=(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is"
+ f" {shape_list(attention_mask)}"
+ ),
+ )
+
+ attention_mask = tf.cast(attention_mask, dtype=attn_weights.dtype)
+ attn_weights = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len)) + attention_mask
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_weights = stable_softmax(attn_weights, axis=-1)
+
+ if layer_head_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(layer_head_mask),
+ [self.num_heads],
+ message=(
+ f"Head mask for a single layer should be of size {(self.num_heads)}, but is"
+ f" {shape_list(layer_head_mask)}"
+ ),
+ )
+
+ attn_weights = tf.reshape(layer_head_mask, (1, -1, 1, 1)) * tf.reshape(
+ attn_weights, (bsz, self.num_heads, tgt_len, src_len)
+ )
+ attn_weights = tf.reshape(attn_weights, (bsz * self.num_heads, tgt_len, src_len))
+
+ attn_probs = self.dropout(attn_weights, training=training)
+ attn_output = tf.matmul(attn_probs, value_states)
+
+ tf.debugging.assert_equal(
+ shape_list(attn_output),
+ [bsz * self.num_heads, tgt_len, self.head_dim],
+ message=(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {shape_list(attn_output)}"
+ ),
+ )
+
+ attn_output = tf.transpose(
+ tf.reshape(attn_output, (bsz, self.num_heads, tgt_len, self.head_dim)), (0, 2, 1, 3)
+ )
+ attn_output = tf.reshape(attn_output, (bsz, tgt_len, embed_dim))
+
+ attn_output = self.out_proj(attn_output)
+ attn_weights: tf.Tensor = tf.reshape(attn_weights, (bsz, self.num_heads, tgt_len, src_len))
+
+ return attn_output, attn_weights, past_key_value
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "k_proj", None) is not None:
+ with tf.name_scope(self.k_proj.name):
+ self.k_proj.build([None, None, self.embed_dim])
+ if getattr(self, "q_proj", None) is not None:
+ with tf.name_scope(self.q_proj.name):
+ self.q_proj.build([None, None, self.embed_dim])
+ if getattr(self, "v_proj", None) is not None:
+ with tf.name_scope(self.v_proj.name):
+ self.v_proj.build([None, None, self.embed_dim])
+ if getattr(self, "out_proj", None) is not None:
+ with tf.name_scope(self.out_proj.name):
+ self.out_proj.build([None, None, self.embed_dim])
+
+
+class TFXGLMDecoderLayer(keras.layers.Layer):
+ def __init__(self, config: XGLMConfig, **kwargs: Any) -> None:
+ super().__init__(**kwargs)
+ self.embed_dim = config.d_model
+ self.self_attn = TFXGLMAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ name="self_attn",
+ )
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.activation_fn = get_tf_activation(config.activation_function)
+ self.activation_dropout = keras.layers.Dropout(config.activation_dropout)
+
+ if config.add_cross_attention:
+ self.encoder_attn = TFXGLMAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ name="encoder_attn",
+ )
+ self.encoder_attn_layer_norm = keras.layers.LayerNormalization(
+ epsilon=1e-5, name="encoder_attn_layer_norm"
+ )
+
+ self.self_attn_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="self_attn_layer_norm")
+ self.fc1 = keras.layers.Dense(config.ffn_dim, name="fc1")
+ self.fc2 = keras.layers.Dense(self.embed_dim, name="fc2")
+ self.final_layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="final_layer_norm")
+ self.config = config
+
+ # Copied from transformers.models.mbart.modeling_tf_mbart.TFMBartDecoderLayer.call
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor | None = None,
+ encoder_hidden_states: tf.Tensor | None = None,
+ encoder_attention_mask: tf.Tensor | None = None,
+ layer_head_mask: tf.Tensor | None = None,
+ cross_attn_layer_head_mask: tf.Tensor | None = None,
+ past_key_value: tuple[tf.Tensor] | None = None,
+ training: bool | None = False,
+ ) -> tuple[tf.Tensor, tf.Tensor, tuple[tuple[tf.Tensor]]]:
+ """
+ Args:
+ hidden_states (`tf.Tensor`): input to the layer of shape *(batch, seq_len, embed_dim)*
+ attention_mask (`tf.Tensor`): attention mask of size
+ *(batch, 1, tgt_len, src_len)* where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`tf.Tensor`):
+ cross attention input to the layer of shape *(batch, seq_len, embed_dim)*
+ encoder_attention_mask (`tf.Tensor`): encoder attention mask of size
+ *(batch, 1, tgt_len, src_len)* where padding elements are indicated by very large negative values.
+ layer_head_mask (`tf.Tensor`): mask for attention heads in a given layer of size
+ *(decoder_attention_heads,)*
+ cross_attn_layer_head_mask (`tf.Tensor`): mask for heads of the cross-attention module.
+ *(decoder_attention_heads,)*
+ past_key_value (`Tuple(tf.Tensor)`): cached past key and value projection states
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ # decoder uni-directional self-attention cached key/values tuple is at positions 1,2
+ self_attn_past_key_value = past_key_value[:2] if past_key_value is not None else None
+ # add present self-attn cache to positions 1,2 of present_key_value tuple
+ hidden_states, self_attn_weights, present_key_value = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_value=self_attn_past_key_value,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_present_key_value = None
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ # cross_attn cached key/values tuple is at positions 3,4 of present_key_value tuple
+ cross_attn_past_key_value = past_key_value[-2:] if past_key_value is not None else None
+ hidden_states, cross_attn_weights, cross_attn_present_key_value = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_value=cross_attn_past_key_value,
+ )
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ # add cross-attn to positions 3,4 of present_key_value tuple
+ present_key_value = present_key_value + cross_attn_present_key_value
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = self.activation_dropout(hidden_states, training=training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = self.dropout(hidden_states, training=training)
+ hidden_states = residual + hidden_states
+
+ return (
+ hidden_states,
+ self_attn_weights,
+ cross_attn_weights,
+ present_key_value,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attn", None) is not None:
+ with tf.name_scope(self.self_attn.name):
+ self.self_attn.build(None)
+ if getattr(self, "self_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.self_attn_layer_norm.name):
+ self.self_attn_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "fc1", None) is not None:
+ with tf.name_scope(self.fc1.name):
+ self.fc1.build([None, None, self.embed_dim])
+ if getattr(self, "fc2", None) is not None:
+ with tf.name_scope(self.fc2.name):
+ self.fc2.build([None, None, self.config.ffn_dim])
+ if getattr(self, "final_layer_norm", None) is not None:
+ with tf.name_scope(self.final_layer_norm.name):
+ self.final_layer_norm.build([None, None, self.embed_dim])
+ if getattr(self, "encoder_attn", None) is not None:
+ with tf.name_scope(self.encoder_attn.name):
+ self.encoder_attn.build(None)
+ if getattr(self, "encoder_attn_layer_norm", None) is not None:
+ with tf.name_scope(self.encoder_attn_layer_norm.name):
+ self.encoder_attn_layer_norm.build([None, None, self.embed_dim])
+
+
+@keras_serializable
+class TFXGLMMainLayer(keras.layers.Layer):
+ config_class = XGLMConfig
+
+ def __init__(
+ self, config: XGLMConfig, embed_tokens: TFSharedEmbeddings | None = None, *inputs, **kwargs: Any
+ ) -> None:
+ super().__init__(*inputs, **kwargs)
+
+ self.config = config
+ self.padding_idx = config.pad_token_id
+ self.max_target_positions = config.max_position_embeddings
+ self.embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0
+
+ if embed_tokens is not None:
+ self.embed_tokens = embed_tokens
+ else:
+ self.embed_tokens = TFSharedEmbeddings(
+ config.vocab_size, config.d_model, self.padding_idx, name="embed_tokens"
+ )
+
+ self.offset = 2
+ self._embed_positions_weights = create_sinusoidal_positions(
+ num_positions=config.max_position_embeddings + self.offset,
+ embedding_dim=config.d_model,
+ padding_idx=config.pad_token_id,
+ )
+
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.layers = [TFXGLMDecoderLayer(config, name=f"layers.{i}") for i in range(config.num_layers)]
+ self.layerdrop = config.layerdrop
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=1e-5, name="layer_norm")
+
+ def get_input_embeddings(self) -> TFSharedEmbeddings:
+ return self.embed_tokens
+
+ def set_input_embeddings(self, value: TFSharedEmbeddings) -> None:
+ self.embed_tokens = value
+
+ def _prepare_decoder_attention_mask(
+ self,
+ attention_mask: tf.Tensor | None,
+ input_shape: tf.TensorShape,
+ past_key_values_length: int,
+ ) -> tf.Tensor:
+ # create causal mask
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ combined_attention_mask = _make_causal_mask(input_shape, past_key_values_length)
+ combined_attention_mask = tf.cond(
+ input_shape[-1] > 1, lambda: combined_attention_mask, lambda: tf.ones_like(combined_attention_mask)
+ )
+ if attention_mask is None:
+ return combined_attention_mask
+ expand_attention_mask = _expand_mask(attention_mask, tgt_len=input_shape[-1])
+ return expand_attention_mask + combined_attention_mask
+
+ def embed_positions(self, position_ids: np.ndarray | tf.Tensor | None = None) -> tf.Tensor:
+ position_ids += self.offset
+ positions = tf.gather(self._embed_positions_weights, position_ids, axis=0)
+ return positions
+
+ @unpack_inputs
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ encoder_hidden_states: np.ndarray | tf.Tensor | None = None,
+ encoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ cross_attn_head_mask: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ **kwargs: Any,
+ ) -> TFBaseModelOutputWithPastAndCrossAttentions | tuple[tf.Tensor]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = tf.shape(input_ids)
+ input_ids = tf.reshape(input_ids, (-1, input_shape[-1]))
+ elif inputs_embeds is not None:
+ input_shape = tf.shape(inputs_embeds)[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ past_key_values_length = past_key_values[0][0].shape[2] if past_key_values is not None else 0
+
+ if position_ids is None:
+ position_ids = tf.expand_dims(
+ tf.range(past_key_values_length, input_shape[-1] + past_key_values_length), axis=0
+ )
+ position_ids = tf.reshape(position_ids, [-1, shape_list(position_ids)[-1]])
+
+ if inputs_embeds is None:
+ check_embeddings_within_bounds(input_ids, self.embed_tokens.vocab_size)
+ inputs_embeds = self.embed_tokens(input_ids) * self.embed_scale
+
+ attention_mask = self._prepare_decoder_attention_mask(attention_mask, input_shape, past_key_values_length)
+
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _expand_mask(encoder_attention_mask, tgt_len=input_shape[-1])
+
+ # embed positions
+ positions = self.embed_positions(position_ids)
+
+ hidden_states = tf.cast(inputs_embeds, dtype=tf.float32) + positions
+
+ hidden_states = self.dropout(hidden_states, training=training)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+ next_decoder_cache = () if use_cache else None
+
+ # check if head_mask and cross_attn_head_mask have a correct number of layers specified if desired
+ for attn_mask_name, attn_mask in [("head_mask", head_mask), ("cross_attn_head_mask", cross_attn_head_mask)]:
+ if attn_mask is not None:
+ tf.debugging.assert_equal(
+ shape_list(attn_mask)[0],
+ len(self.layers),
+ message=(
+ f"The {attn_mask_name} should be specified for {len(self.layers)} layers, but it is for"
+ f" {shape_list(attn_mask)[0]}."
+ ),
+ )
+
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ dropout_probability = random.uniform(0, 1)
+ if training and (dropout_probability < self.layerdrop):
+ continue
+
+ past_key_value = past_key_values[idx] if past_key_values is not None else None
+
+ hidden_states, layer_self_attn, layer_cross_attn, present_key_value = decoder_layer(
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_value=past_key_value,
+ )
+
+ if use_cache:
+ next_decoder_cache += (present_key_value,)
+
+ if output_attentions:
+ all_self_attns += (layer_self_attn,)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_cross_attn,)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ next_cache = next_decoder_cache if use_cache else None
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, next_cache, all_hidden_states, all_self_attns, all_cross_attentions]
+ if v is not None
+ )
+ return TFBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.d_model])
+ if getattr(self, "embed_tokens", None) is not None:
+ with tf.name_scope(self.embed_tokens.name):
+ self.embed_tokens.build(None)
+ if getattr(self, "layers", None) is not None:
+ for layer in self.layers:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+class TFXGLMPreTrainedModel(TFPreTrainedModel):
+ config_class = XGLMConfig
+ base_model_prefix = "model"
+
+
+XGLM_START_DOCSTRING = r"""
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Args:
+ config ([`XGLMConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~TFPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+XGLM_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`tf.Tensor` of shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`tf.Tensor` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ position_ids (`tf.Tensor` or `Numpy array` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ encoder_hidden_states (`tf.Tensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention of
+ the decoder.
+ encoder_attention_mask (`tf.Tensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ head_mask (`tf.Tensor` of shape `(num_layers, attention_heads)`, *optional*):
+ Mask to nullify selected heads of the attention modules in the encoder. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ cross_attn_head_mask (`tf.Tensor` of shape `(num_layers, attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ past_key_values (`tuple[tuple[tf.Tensor]]` of length `config.num_layers`)
+ contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ inputs_embeds (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`). Set to `False` during training, `True` during generation
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+
+@add_start_docstrings(
+ "The bare XGLM Model transformer outputting raw hidden-states without any specific head on top.",
+ XGLM_START_DOCSTRING,
+)
+class TFXGLMModel(TFXGLMPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.num_layers* layers. Each layer is a [`TFXGLMDecoderLayer`]
+
+ Args:
+ config: XGLMConfig
+ embed_tokens: [TFSharedEmbeddings]: output embedding
+ """
+
+ def __init__(
+ self, config: XGLMConfig, embed_tokens: TFSharedEmbeddings | None = None, *inputs: Any, **kwargs: Any
+ ) -> None:
+ super().__init__(config, *inputs, **kwargs)
+
+ self.model = TFXGLMMainLayer(config, embed_tokens=embed_tokens, name="model")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XGLM_INPUTS_DOCSTRING)
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFBaseModelOutputWithPastAndCrossAttentions,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ encoder_hidden_states: np.ndarray | tf.Tensor | None = None,
+ encoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ cross_attn_head_mask: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ **kwargs: Any,
+ ) -> TFBaseModelOutputWithPastAndCrossAttentions | tuple[tf.Tensor]:
+ outputs = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "model", None) is not None:
+ with tf.name_scope(self.model.name):
+ self.model.build(None)
+
+
+@add_start_docstrings(
+ """
+ The XGLM Model transformer with a language modeling head on top (linear layer with weights tied to the input
+ embeddings).
+ """,
+ XGLM_START_DOCSTRING,
+)
+class TFXGLMForCausalLM(TFXGLMPreTrainedModel, TFCausalLanguageModelingLoss):
+ base_model_prefix = "model"
+ _keys_to_ignore_on_load_missing = [
+ r"model.embed_positions.weights",
+ r"lm_head.weight",
+ ]
+ _keys_to_ignore_on_save = [
+ r"model.embed_positions.weights",
+ ]
+
+ def __init__(
+ self, config: XGLMConfig, embed_tokens: TFSharedEmbeddings | None = None, *inputs: Any, **kwargs: Any
+ ) -> None:
+ super().__init__(config, *inputs, **kwargs)
+
+ self.model = TFXGLMMainLayer(config, embed_tokens=embed_tokens, name="model")
+ self.lm_head = keras.layers.Dense(
+ config.vocab_size,
+ use_bias=False,
+ kernel_initializer=get_initializer(config.init_std),
+ name="lm_head",
+ )
+ self.config = config
+
+ def prepare_inputs_for_generation(self, inputs, past_key_values=None, use_cache=None, **kwargs):
+ # only last token for inputs_ids if past is defined in kwargs
+ if past_key_values:
+ inputs = tf.expand_dims(inputs[:, -1], -1)
+
+ position_ids = kwargs.get("position_ids")
+ attention_mask = kwargs.get("attention_mask")
+
+ if attention_mask is not None and position_ids is None:
+ position_ids = tf.math.cumsum(attention_mask, axis=-1, exclusive=True)
+ if past_key_values:
+ position_ids = tf.expand_dims(position_ids[:, -1], -1)
+
+ return {
+ "input_ids": inputs,
+ "attention_mask": attention_mask,
+ "position_ids": position_ids,
+ "past_key_values": past_key_values,
+ "use_cache": use_cache,
+ }
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XGLM_INPUTS_DOCSTRING)
+ @replace_return_docstrings(output_type=TFCausalLMOutputWithCrossAttentions, config_class=_CONFIG_FOR_DOC)
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFCausalLMOutputWithCrossAttentions,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ encoder_hidden_states: np.ndarray | tf.Tensor | None = None,
+ encoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ cross_attn_head_mask: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ **kwargs: Any,
+ ) -> TFCausalLMOutputWithCrossAttentions | tuple[tf.Tensor]:
+ r"""
+ labels (`np.ndarray` or `tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for language modeling. Note that the labels **are shifted** inside the model, i.e. you can set
+ `labels = input_ids` Indices are selected in `[-100, 0, ..., config.vocab_size]` All labels set to `-100`
+ are ignored (masked), the loss is only computed for labels in `[0, ..., config.vocab_size]`
+ """
+
+ outputs = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ hidden_states = outputs[0]
+ lm_logits = self.lm_head(hidden_states)
+
+ loss = None
+ if labels is not None:
+ # shift labels to the left and cut last logit token
+ labels = tf.concat(
+ [labels[:, 1:], tf.fill((labels.shape[0], 1), tf.cast(-100, labels.dtype))],
+ axis=-1,
+ )
+ loss = self.hf_compute_loss(labels, lm_logits)
+
+ if not return_dict:
+ output = (lm_logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFCausalLMOutputWithCrossAttentions(
+ loss=loss,
+ logits=lm_logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "model", None) is not None:
+ with tf.name_scope(self.model.name):
+ self.model.build(None)
+ if getattr(self, "lm_head", None) is not None:
+ with tf.name_scope(self.lm_head.name):
+ self.lm_head.build([None, None, self.config.hidden_size])
+
+ def tf_to_pt_weight_rename(self, tf_weight):
+ if tf_weight == "lm_head.weight":
+ return tf_weight, "model.embed_tokens.weight"
+ else:
+ return (tf_weight,)
+
+
+__all__ = ["TFXGLMForCausalLM", "TFXGLMModel", "TFXGLMPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_xglm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_xglm.py
new file mode 100644
index 0000000000000000000000000000000000000000..244135b7d2e50565b4ab84b05a30bcd0fbc8da66
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/modeling_xglm.py
@@ -0,0 +1,711 @@
+# coding=utf-8
+# Copyright 2021 The Fairseq Authors The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch XGLM model."""
+
+import math
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask, _prepare_4d_causal_attention_mask
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutputWithPastAndCrossAttentions, CausalLMOutputWithCrossAttentions
+from ...modeling_utils import PreTrainedModel
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_xglm import XGLMConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.bart.modeling_bart.BartScaledWordEmbedding with Bart->XGLM
+class XGLMScaledWordEmbedding(nn.Embedding):
+ """
+ This module overrides nn.Embeddings' forward by multiplying with embeddings scale.
+ """
+
+ def __init__(self, num_embeddings: int, embedding_dim: int, padding_idx: int, embed_scale: Optional[float] = 1.0):
+ super().__init__(num_embeddings, embedding_dim, padding_idx)
+ self.embed_scale = embed_scale
+
+ def forward(self, input_ids: torch.Tensor):
+ return super().forward(input_ids) * self.embed_scale
+
+
+class XGLMSinusoidalPositionalEmbedding(nn.Module):
+ """This module produces sinusoidal positional embeddings of any length."""
+
+ def __init__(self, num_positions: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ super().__init__()
+ self.offset = 2
+ self.embedding_dim = embedding_dim
+ self.padding_idx = padding_idx
+ self.make_weights(num_positions + self.offset, embedding_dim, padding_idx)
+
+ def make_weights(self, num_embeddings: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ emb_weights = self.get_embedding(num_embeddings, embedding_dim, padding_idx)
+ if hasattr(self, "weights"):
+ # in forward put the weights on the correct dtype and device of the param
+ emb_weights = emb_weights.to(dtype=self.weights.dtype, device=self.weights.device)
+
+ self.register_buffer("weights", emb_weights, persistent=False)
+
+ @staticmethod
+ def get_embedding(num_embeddings: int, embedding_dim: int, padding_idx: Optional[int] = None):
+ """
+ Build sinusoidal embeddings.
+
+ This matches the implementation in tensor2tensor, but differs slightly from the description in Section 3.5 of
+ "Attention Is All You Need".
+ """
+ half_dim = embedding_dim // 2
+ emb = math.log(10000) / (half_dim - 1)
+ emb = torch.exp(torch.arange(half_dim, dtype=torch.int64).float() * -emb)
+ emb = torch.arange(num_embeddings, dtype=torch.int64).float().unsqueeze(1) * emb.unsqueeze(0)
+ emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1).view(num_embeddings, -1)
+ if embedding_dim % 2 == 1:
+ # zero pad
+ emb = torch.cat([emb, torch.zeros(num_embeddings, 1)], dim=1)
+ if padding_idx is not None:
+ emb[padding_idx, :] = 0
+
+ return emb.to(torch.get_default_dtype())
+
+ @torch.no_grad()
+ def forward(self, position_ids: Optional[torch.Tensor] = None, past_key_values_length: int = 0):
+ bsz, seq_len = position_ids.size()
+ position_ids += self.offset
+
+ # Expand embeddings if needed. `position_ids.max()` is NOT used to keep torch.fx compatibility.
+ max_pos = 2 + seq_len + past_key_values_length
+ if max_pos > self.weights.size(0):
+ self.make_weights(max_pos, self.embedding_dim, self.padding_idx)
+
+ return self.weights.index_select(0, position_ids.view(-1)).view(bsz, seq_len, self.weights.shape[-1]).detach()
+
+
+class XGLMAttention(nn.Module):
+ """Multi-headed attention from 'Attention Is All You Need' paper"""
+
+ def __init__(
+ self,
+ embed_dim: int,
+ num_heads: int,
+ dropout: Optional[float] = 0.0,
+ is_decoder: Optional[bool] = False,
+ bias: Optional[bool] = True,
+ layer_idx: Optional[bool] = None,
+ ):
+ super().__init__()
+ self.embed_dim = embed_dim
+ self.num_heads = num_heads
+ self.dropout = dropout
+ self.head_dim = embed_dim // num_heads
+
+ if (self.head_dim * num_heads) != self.embed_dim:
+ raise ValueError(
+ f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}"
+ f" and `num_heads`: {num_heads})."
+ )
+ self.scaling = self.head_dim**-0.5
+ self.is_decoder = is_decoder
+ self.layer_idx = layer_idx
+
+ self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+ self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ key_value_states: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ output_attentions: bool = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ """Input shape: Batch x Time x Channel"""
+
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+
+ bsz, tgt_len, _ = hidden_states.size()
+ src_len = key_value_states.shape[1] if is_cross_attention else tgt_len
+
+ # get query proj
+ query_states = self.q_proj(hidden_states) * self.scaling
+
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = key_value_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_states = curr_past_key_value.layers[self.layer_idx].keys
+ value_states = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_states = self.k_proj(current_states)
+ value_states = self.v_proj(current_states)
+ key_states = key_states.view(bsz, src_len, -1, self.head_dim).transpose(1, 2)
+ value_states = value_states.view(bsz, src_len, -1, self.head_dim).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_states, value_states = curr_past_key_value.update(
+ key_states, value_states, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ proj_shape = (bsz * self.num_heads, -1, self.head_dim)
+ query_states = query_states.view(bsz, tgt_len, self.num_heads, self.head_dim).transpose(1, 2)
+ query_states = query_states.reshape(*proj_shape)
+ key_states = key_states.reshape(*proj_shape)
+ value_states = value_states.reshape(*proj_shape)
+
+ src_len = key_states.size(1)
+ attn_weights = torch.bmm(query_states, key_states.transpose(1, 2))
+
+ if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len):
+ raise ValueError(
+ f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is"
+ f" {attn_weights.size()}"
+ )
+
+ if attention_mask is not None:
+ if attention_mask.size() != (bsz, 1, tgt_len, src_len):
+ raise ValueError(
+ f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is {attention_mask.size()}"
+ )
+ attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attention_mask
+ attn_weights = torch.max(
+ attn_weights, torch.tensor(torch.finfo(attn_weights.dtype).min, device=attn_weights.device)
+ )
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ # upcast to fp32 if the weights are in fp16. Please see https://github.com/huggingface/transformers/pull/17437
+ if attn_weights.dtype == torch.float16:
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(torch.float16)
+ else:
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1)
+
+ if layer_head_mask is not None:
+ if layer_head_mask.size() != (self.num_heads,):
+ raise ValueError(
+ f"Head mask for a single layer should be of size {(self.num_heads,)}, but is"
+ f" {layer_head_mask.size()}"
+ )
+ attn_weights = layer_head_mask.view(1, -1, 1, 1) * attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
+
+ if output_attentions:
+ # this operation is a bit awkward, but it's required to
+ # make sure that attn_weights keeps its gradient.
+ # In order to do so, attn_weights have to be reshaped
+ # twice and have to be reused in the following
+ attn_weights_reshaped = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
+ attn_weights = attn_weights_reshaped.view(bsz * self.num_heads, tgt_len, src_len)
+ else:
+ attn_weights_reshaped = None
+
+ attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training)
+
+ attn_output = torch.bmm(attn_probs, value_states)
+
+ if attn_output.size() != (bsz * self.num_heads, tgt_len, self.head_dim):
+ raise ValueError(
+ f"`attn_output` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is"
+ f" {attn_output.size()}"
+ )
+
+ attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim)
+ attn_output = attn_output.transpose(1, 2)
+
+ # Use the `embed_dim` from the config (stored in the class) rather than `hidden_state` because `attn_output` can be
+ # partitioned aross GPUs when using tensor-parallelism.
+ attn_output = attn_output.reshape(bsz, tgt_len, self.embed_dim)
+
+ attn_output = self.out_proj(attn_output)
+
+ return attn_output, attn_weights_reshaped
+
+
+class XGLMDecoderLayer(GradientCheckpointingLayer):
+ def __init__(self, config: XGLMConfig, layer_idx=None):
+ super().__init__()
+ self.embed_dim = config.d_model
+
+ self.self_attn = XGLMAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ layer_idx=layer_idx,
+ )
+ self.dropout = config.dropout
+ self.activation_fn = ACT2FN[config.activation_function]
+ self.activation_dropout = config.activation_dropout
+
+ if config.add_cross_attention:
+ self.encoder_attn = XGLMAttention(
+ embed_dim=self.embed_dim,
+ num_heads=config.attention_heads,
+ dropout=config.attention_dropout,
+ is_decoder=True,
+ layer_idx=layer_idx,
+ )
+ self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim)
+ self.fc1 = nn.Linear(self.embed_dim, config.ffn_dim)
+ self.fc2 = nn.Linear(config.ffn_dim, self.embed_dim)
+ self.final_layer_norm = nn.LayerNorm(self.embed_dim)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ # Copied from transformers.models.musicgen.modeling_musicgen.MusicgenDecoderLayer.forward
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ layer_head_mask: Optional[torch.Tensor] = None,
+ cross_attn_layer_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = True,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> torch.Tensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`): attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ encoder_hidden_states (`torch.FloatTensor`):
+ cross attention input to the layer of shape `(batch, seq_len, embed_dim)`
+ encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size
+ `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values.
+ layer_head_mask (`torch.FloatTensor`): mask for attention heads in a given layer of size
+ `(encoder_attention_heads,)`.
+ cross_attn_layer_head_mask (`torch.FloatTensor`): mask for cross-attention heads in a given layer of
+ size `(decoder_attention_heads,)`.
+ past_key_values (`Tuple(torch.FloatTensor)`): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ """
+ residual = hidden_states
+ hidden_states = self.self_attn_layer_norm(hidden_states)
+
+ # Self Attention
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ past_key_values=past_key_values,
+ attention_mask=attention_mask,
+ layer_head_mask=layer_head_mask,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ # Cross-Attention Block
+ cross_attn_weights = None
+ if encoder_hidden_states is not None:
+ residual = hidden_states
+ hidden_states = self.encoder_attn_layer_norm(hidden_states)
+
+ hidden_states, cross_attn_weights = self.encoder_attn(
+ hidden_states=hidden_states,
+ key_value_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=cross_attn_layer_head_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ # Fully Connected
+ residual = hidden_states
+ hidden_states = self.final_layer_norm(hidden_states)
+ hidden_states = self.activation_fn(self.fc1(hidden_states))
+ hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training)
+ hidden_states = self.fc2(hidden_states)
+ hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training)
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights, cross_attn_weights)
+
+ return outputs
+
+
+@auto_docstring
+class XGLMPreTrainedModel(PreTrainedModel):
+ config: XGLMConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["XGLMDecoderLayer"]
+
+ def _init_weights(self, module):
+ std = self.config.init_std
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+
+
+@auto_docstring
+class XGLMModel(XGLMPreTrainedModel):
+ def __init__(self, config: XGLMConfig, embed_tokens: Optional[nn.Embedding] = None):
+ r"""
+ embed_tokens (`nn.Embedding`, *optional*):
+ output embeddings
+ """
+ super().__init__(config)
+ self.dropout = config.dropout
+ self.layerdrop = config.layerdrop
+ self.padding_idx = config.pad_token_id
+ self.max_target_positions = config.max_position_embeddings
+ embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0
+
+ if embed_tokens is not None:
+ self.embed_tokens = embed_tokens
+ else:
+ self.embed_tokens = XGLMScaledWordEmbedding(
+ config.vocab_size, config.d_model, self.padding_idx, embed_scale=embed_scale
+ )
+
+ self.embed_positions = XGLMSinusoidalPositionalEmbedding(
+ config.max_position_embeddings,
+ config.d_model,
+ config.pad_token_id,
+ )
+ self.layers = nn.ModuleList([XGLMDecoderLayer(config, layer_idx=i) for i in range(config.num_layers)])
+ self.layer_norm = nn.LayerNorm(config.d_model)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutputWithPastAndCrossAttentions]:
+ r"""
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention of
+ the decoder.
+ encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_layers, attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # retrieve input_ids and inputs_embeds
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ input_ids = input_ids.view(-1, input_shape[-1])
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache = True` is incompatible with gradient checkpointing`. Setting `use_cache = False`..."
+ )
+ use_cache = False
+
+ # initialize `past_key_values`
+ if use_cache and past_key_values is None:
+ past_key_values = (
+ EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if encoder_hidden_states is not None
+ else DynamicCache(config=self.config)
+ )
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0
+ attention_mask = _prepare_4d_causal_attention_mask(
+ attention_mask, input_shape, inputs_embeds, past_key_values_length
+ )
+
+ if position_ids is None:
+ position_ids = torch.arange(
+ past_key_values_length,
+ input_shape[-1] + past_key_values_length,
+ dtype=torch.long,
+ device=input_ids.device if input_ids is not None else inputs_embeds.device,
+ )
+ position_ids = position_ids.unsqueeze(0)
+
+ # expand encoder attention mask
+ if encoder_hidden_states is not None and encoder_attention_mask is not None:
+ # [bsz, seq_len] -> [bsz, 1, tgt_seq_len, src_seq_len]
+ encoder_attention_mask = _prepare_4d_attention_mask(
+ encoder_attention_mask, inputs_embeds.dtype, tgt_len=input_shape[-1]
+ )
+
+ hidden_states = inputs_embeds + self.embed_positions(position_ids, past_key_values_length).to(
+ inputs_embeds.device
+ )
+ hidden_states = nn.functional.dropout(hidden_states, p=float(self.dropout), training=self.training)
+
+ # decoder layers
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ # check if head_mask/cross_attn_head_mask has a correct number of layers specified if desired
+ for attn_mask, mask_name in zip([head_mask, cross_attn_head_mask], ["head_mask", "cross_attn_head_mask"]):
+ if attn_mask is not None:
+ if attn_mask.size()[0] != len(self.layers):
+ raise ValueError(
+ f"The `{mask_name}` should be specified for {len(self.layers)} layers, but it is for"
+ f" {head_mask.size()[0]}."
+ )
+ for idx, decoder_layer in enumerate(self.layers):
+ # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description)
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+ if self.training:
+ dropout_probability = torch.rand([])
+ if dropout_probability < self.layerdrop:
+ continue
+
+ layer_outputs = decoder_layer(
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ layer_head_mask=(head_mask[idx] if head_mask is not None else None),
+ cross_attn_layer_head_mask=(cross_attn_head_mask[idx] if cross_attn_head_mask is not None else None),
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_self_attns += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ hidden_states = self.layer_norm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ The XGLM Model transformer with a language modeling head on top (linear layer with weights tied to the input
+ embeddings).
+ """
+)
+class XGLMForCausalLM(XGLMPreTrainedModel, GenerationMixin):
+ base_model_prefix = "model"
+ _tied_weights_keys = ["lm_head.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = XGLMModel(config)
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ cross_attn_head_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> Union[tuple[torch.Tensor], CausalLMOutputWithCrossAttentions]:
+ r"""
+ encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention of
+ the decoder.
+ encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*):
+ Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values
+ selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ cross_attn_head_mask (`torch.Tensor` of shape `(num_layers, attention_heads)`, *optional*):
+ Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+ """
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
+ outputs = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ cross_attn_head_mask=cross_attn_head_mask,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ logits = self.lm_head(outputs[0])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(
+ logits,
+ labels,
+ vocab_size=self.config.vocab_size,
+ pad_token_id=self.config.pad_token_id,
+ **kwargs,
+ )
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return (loss,) + output if loss is not None else output
+
+ return CausalLMOutputWithCrossAttentions(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+__all__ = ["XGLMForCausalLM", "XGLMModel", "XGLMPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/tokenization_xglm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/tokenization_xglm.py
new file mode 100644
index 0000000000000000000000000000000000000000..9e0a8706683f9695001a71bcbe87e697666333e1
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/tokenization_xglm.py
@@ -0,0 +1,302 @@
+# coding=utf-8
+# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for ."""
+
+import os
+from shutil import copyfile
+from typing import Any, Optional
+
+import sentencepiece as spm
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...utils import logging
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+SPIECE_UNDERLINE = "▁"
+
+VOCAB_FILES_NAMES = {"vocab_file": "sentencepiece.bpe.model"}
+
+
+@requires(backends=("sentencepiece",))
+class XGLMTokenizer(PreTrainedTokenizer):
+ """
+ Adapted from [`RobertaTokenizer`] and [`XLNetTokenizer`]. Based on
+ [SentencePiece](https://github.com/google/sentencepiece).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ Path to the vocabulary file.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the beginning of
+ sequence. The token used is the `cls_token`.
+
+
+
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ sep_token (`str`, *optional*, defaults to `""`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ cls_token (`str`, *optional*, defaults to `""`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+
+ Attributes:
+ sp_model (`SentencePieceProcessor`):
+ The *SentencePiece* processor that is used for every conversion (string, tokens and IDs).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ bos_token="",
+ eos_token=" ",
+ sep_token=" ",
+ cls_token="",
+ unk_token="",
+ pad_token="",
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ **kwargs,
+ ) -> None:
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+
+ # Compatibility with the original tokenizer
+ self.num_madeup_words = 7
+ madeup_words = [f"" for i in range(self.num_madeup_words)]
+
+ kwargs["additional_special_tokens"] = kwargs.get("additional_special_tokens", []) or []
+ kwargs["additional_special_tokens"] += [
+ word for word in madeup_words if word not in kwargs["additional_special_tokens"]
+ ]
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(str(vocab_file))
+ self.vocab_file = vocab_file
+
+ # Original fairseq vocab and spm vocab must be "aligned":
+ # Vocab | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9
+ # -------- | ------- | ------- | ------ | ------- | --- | --- | --- | ----- | ----- | ----
+ # fairseq | '' | '' | ' ' | '' | ',' | '.' | '▁' | 's' | '▁de' | '-'
+ # spm | '' | '' | ' ' | ',' | '.' | '▁' | 's' | '▁de' | '-' | '▁a'
+
+ # The first "real" token "," has position 4 in the original fairseq vocab and position 3 in the spm vocab
+ self.fairseq_offset = 1
+
+ # Mimic fairseq token-to-id alignment for the first 4 token
+ self.fairseq_tokens_to_ids = {"": 0, "": 1, " ": 2, "": 3}
+
+ sp_size = len(self.sp_model)
+ madeup_words = {f"": sp_size + i + self.fairseq_offset for i in range(self.num_madeup_words)}
+ self.fairseq_tokens_to_ids.update(madeup_words)
+
+ self.fairseq_ids_to_tokens = {v: k for k, v in self.fairseq_tokens_to_ids.items()}
+
+ super().__init__(
+ bos_token=bos_token,
+ eos_token=eos_token,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ cls_token=cls_token,
+ pad_token=pad_token,
+ sp_model_kwargs=self.sp_model_kwargs,
+ **kwargs,
+ )
+
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ state["sp_model_proto"] = self.sp_model.serialized_model_proto()
+ return state
+
+ def __setstate__(self, d):
+ self.__dict__ = d
+
+ # for backward compatibility
+ if not hasattr(self, "sp_model_kwargs"):
+ self.sp_model_kwargs = {}
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.LoadFromSerializedProto(self.sp_model_proto)
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLM-RoBERTa sequence has the following format:
+
+ - single sequence: ` X `
+ - pair of sequences: ` A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+
+ if token_ids_1 is None:
+ return [self.sep_token_id] + token_ids_0
+ sep = [self.sep_token_id]
+ return sep + token_ids_0 + sep + sep + token_ids_1
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ if token_ids_1 is None:
+ return [1] + ([0] * len(token_ids_0))
+ return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1))
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. XLM-RoBERTa does
+ not make use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+
+ """
+
+ sep = [self.sep_token_id]
+
+ if token_ids_1 is None:
+ return len(sep + token_ids_0) * [0]
+ return len(sep + token_ids_0 + sep + sep + token_ids_1) * [0]
+
+ @property
+ def vocab_size(self):
+ return len(self.sp_model) + self.fairseq_offset + self.num_madeup_words
+
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def _tokenize(self, text: str) -> list[str]:
+ return self.sp_model.encode(text, out_type=str)
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ if token in self.fairseq_tokens_to_ids:
+ return self.fairseq_tokens_to_ids[token]
+ spm_id = self.sp_model.PieceToId(token)
+
+ # Need to return unknown token if the SP model returned 0
+ return spm_id + self.fairseq_offset if spm_id else self.unk_token_id
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ if index in self.fairseq_ids_to_tokens:
+ return self.fairseq_ids_to_tokens[index]
+ return self.sp_model.IdToPiece(index - self.fairseq_offset)
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (strings for sub-words) in a single string."""
+ out_string = "".join(tokens).replace(SPIECE_UNDERLINE, " ").strip()
+ return out_string
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ elif not os.path.isfile(self.vocab_file):
+ with open(out_vocab_file, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["XGLMTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/tokenization_xglm_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/tokenization_xglm_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..a9c8b3aac257abcd2e67bc2302b148bb943cb373
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xglm/tokenization_xglm_fast.py
@@ -0,0 +1,192 @@
+# coding=utf-8
+# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for XGLM."""
+
+import os
+from shutil import copyfile
+from typing import Optional
+
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import is_sentencepiece_available, logging
+
+
+if is_sentencepiece_available():
+ from .tokenization_xglm import XGLMTokenizer
+else:
+ XGLMTokenizer = None
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "sentencepiece.bpe.model", "tokenizer_file": "tokenizer.json"}
+
+
+class XGLMTokenizerFast(PreTrainedTokenizerFast):
+ """
+ Construct a "fast" XGLM tokenizer (backed by HuggingFace's *tokenizers* library). Adapted from [`RobertaTokenizer`]
+ and [`XLNetTokenizer`]. Based on
+ [BPE](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=BPE#models).
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ Path to the vocabulary file.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the beginning of
+ sequence. The token used is the `cls_token`.
+
+
+
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ sep_token (`str`, *optional*, defaults to `""`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ cls_token (`str`, *optional*, defaults to `""`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ additional_special_tokens (`list[str]`, *optional*, defaults to `["NOTUSED", " NOTUSED"]`):
+ Additional special tokens used by the tokenizer.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+ slow_tokenizer_class = XGLMTokenizer
+
+ def __init__(
+ self,
+ vocab_file=None,
+ tokenizer_file=None,
+ bos_token="",
+ eos_token=" ",
+ sep_token=" ",
+ cls_token="",
+ unk_token="",
+ pad_token="",
+ **kwargs,
+ ):
+ # Compatibility with the original tokenizer
+ self.num_madeup_words = 7
+ madeup_words = [f"" for i in range(self.num_madeup_words)]
+
+ kwargs["additional_special_tokens"] = kwargs.get("additional_special_tokens", []) or []
+ kwargs["additional_special_tokens"] += [
+ word for word in madeup_words if word not in kwargs["additional_special_tokens"]
+ ]
+
+ super().__init__(
+ vocab_file,
+ tokenizer_file=tokenizer_file,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ sep_token=sep_token,
+ cls_token=cls_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ **kwargs,
+ )
+
+ self.vocab_file = vocab_file
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLM-RoBERTa sequence has the following format:
+
+ - single sequence: ` X `
+ - pair of sequences: ` A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+
+ if token_ids_1 is None:
+ return [self.sep_token_id] + token_ids_0
+ sep = [self.sep_token_id]
+ return sep + token_ids_0 + sep + sep + token_ids_1
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. XLM-RoBERTa does
+ not make use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+
+ """
+
+ sep = [self.sep_token_id]
+
+ if token_ids_1 is None:
+ return len(sep + token_ids_0) * [0]
+ return len(sep + token_ids_0 + sep + sep + token_ids_1) * [0]
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not self.can_save_slow_tokenizer:
+ raise ValueError(
+ "Your fast tokenizer does not have the necessary information to save the vocabulary for a slow "
+ "tokenizer."
+ )
+
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory.")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["XGLMTokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1167fc93a10101636288751b692a4daf8a0cf2b4
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_xlm import *
+ from .modeling_tf_xlm import *
+ from .modeling_xlm import *
+ from .tokenization_xlm import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/configuration_xlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/configuration_xlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..d4c85bf582703663c4f4eff99a49c9cc394e0854
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/configuration_xlm.py
@@ -0,0 +1,241 @@
+# coding=utf-8
+# Copyright 2019-present, Facebook, Inc and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""XLM configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XLMConfig(PretrainedConfig):
+ """
+ This is the configuration class to store the configuration of a [`XLMModel`] or a [`TFXLMModel`]. It is used to
+ instantiate a XLM model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the
+ [FacebookAI/xlm-mlm-en-2048](https://huggingface.co/FacebookAI/xlm-mlm-en-2048) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30145):
+ Vocabulary size of the BERT model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`XLMModel`] or [`TFXLMModel`].
+ emb_dim (`int`, *optional*, defaults to 2048):
+ Dimensionality of the encoder layers and the pooler layer.
+ n_layer (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ n_head (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for the attention mechanism
+ gelu_activation (`bool`, *optional*, defaults to `True`):
+ Whether or not to use *gelu* for the activations instead of *relu*.
+ sinusoidal_embeddings (`bool`, *optional*, defaults to `False`):
+ Whether or not to use sinusoidal positional embeddings instead of absolute positional embeddings.
+ causal (`bool`, *optional*, defaults to `False`):
+ Whether or not the model should behave in a causal manner. Causal models use a triangular attention mask in
+ order to only attend to the left-side context instead if a bidirectional context.
+ asm (`bool`, *optional*, defaults to `False`):
+ Whether or not to use an adaptive log softmax projection layer instead of a linear layer for the prediction
+ layer.
+ n_langs (`int`, *optional*, defaults to 1):
+ The number of languages the model handles. Set to 1 for monolingual models.
+ use_lang_emb (`bool`, *optional*, defaults to `True`)
+ Whether to use language embeddings. Some models use additional language embeddings, see [the multilingual
+ models page](http://huggingface.co/transformers/multilingual.html#xlm-language-embeddings) for information
+ on how to use them.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ embed_init_std (`float`, *optional*, defaults to 2048^-0.5):
+ The standard deviation of the truncated_normal_initializer for initializing the embedding matrices.
+ init_std (`int`, *optional*, defaults to 50257):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices except the
+ embedding matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ bos_index (`int`, *optional*, defaults to 0):
+ The index of the beginning of sentence token in the vocabulary.
+ eos_index (`int`, *optional*, defaults to 1):
+ The index of the end of sentence token in the vocabulary.
+ pad_index (`int`, *optional*, defaults to 2):
+ The index of the padding token in the vocabulary.
+ unk_index (`int`, *optional*, defaults to 3):
+ The index of the unknown token in the vocabulary.
+ mask_index (`int`, *optional*, defaults to 5):
+ The index of the masking token in the vocabulary.
+ is_encoder(`bool`, *optional*, defaults to `True`):
+ Whether or not the initialized model should be a transformer encoder or decoder as seen in Vaswani et al.
+ summary_type (`string`, *optional*, defaults to "first"):
+ Argument used when doing sequence summary. Used in the sequence classification and multiple choice models.
+
+ Has to be one of the following options:
+
+ - `"last"`: Take the last token hidden state (like XLNet).
+ - `"first"`: Take the first token hidden state (like BERT).
+ - `"mean"`: Take the mean of all tokens hidden states.
+ - `"cls_index"`: Supply a Tensor of classification token position (like GPT/GPT-2).
+ - `"attn"`: Not implemented now, use multi-head attention.
+ summary_use_proj (`bool`, *optional*, defaults to `True`):
+ Argument used when doing sequence summary. Used in the sequence classification and multiple choice models.
+
+ Whether or not to add a projection after the vector extraction.
+ summary_activation (`str`, *optional*):
+ Argument used when doing sequence summary. Used in the sequence classification and multiple choice models.
+
+ Pass `"tanh"` for a tanh activation to the output, any other value will result in no activation.
+ summary_proj_to_labels (`bool`, *optional*, defaults to `True`):
+ Used in the sequence classification and multiple choice models.
+
+ Whether the projection outputs should have `config.num_labels` or `config.hidden_size` classes.
+ summary_first_dropout (`float`, *optional*, defaults to 0.1):
+ Used in the sequence classification and multiple choice models.
+
+ The dropout ratio to be used after the projection and activation.
+ start_n_top (`int`, *optional*, defaults to 5):
+ Used in the SQuAD evaluation script.
+ end_n_top (`int`, *optional*, defaults to 5):
+ Used in the SQuAD evaluation script.
+ mask_token_id (`int`, *optional*, defaults to 0):
+ Model agnostic parameter to identify masked tokens when generating text in an MLM context.
+ lang_id (`int`, *optional*, defaults to 1):
+ The ID of the language used by the model. This parameter is used when generating text in a given language.
+
+ Examples:
+
+ ```python
+ >>> from transformers import XLMConfig, XLMModel
+
+ >>> # Initializing a XLM configuration
+ >>> configuration = XLMConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = XLMModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xlm"
+ attribute_map = {
+ "hidden_size": "emb_dim",
+ "num_attention_heads": "n_heads",
+ "num_hidden_layers": "n_layers",
+ "n_words": "vocab_size", # For backward compatibility
+ }
+
+ def __init__(
+ self,
+ vocab_size=30145,
+ emb_dim=2048,
+ n_layers=12,
+ n_heads=16,
+ dropout=0.1,
+ attention_dropout=0.1,
+ gelu_activation=True,
+ sinusoidal_embeddings=False,
+ causal=False,
+ asm=False,
+ n_langs=1,
+ use_lang_emb=True,
+ max_position_embeddings=512,
+ embed_init_std=2048**-0.5,
+ layer_norm_eps=1e-12,
+ init_std=0.02,
+ bos_index=0,
+ eos_index=1,
+ pad_index=2,
+ unk_index=3,
+ mask_index=5,
+ is_encoder=True,
+ summary_type="first",
+ summary_use_proj=True,
+ summary_activation=None,
+ summary_proj_to_labels=True,
+ summary_first_dropout=0.1,
+ start_n_top=5,
+ end_n_top=5,
+ mask_token_id=0,
+ lang_id=0,
+ pad_token_id=2,
+ bos_token_id=0,
+ **kwargs,
+ ):
+ """Constructs XLMConfig."""
+ self.vocab_size = vocab_size
+ self.emb_dim = emb_dim
+ self.n_layers = n_layers
+ self.n_heads = n_heads
+ self.dropout = dropout
+ self.attention_dropout = attention_dropout
+ self.gelu_activation = gelu_activation
+ self.sinusoidal_embeddings = sinusoidal_embeddings
+ self.causal = causal
+ self.asm = asm
+ self.n_langs = n_langs
+ self.use_lang_emb = use_lang_emb
+ self.layer_norm_eps = layer_norm_eps
+ self.bos_index = bos_index
+ self.eos_index = eos_index
+ self.pad_index = pad_index
+ self.unk_index = unk_index
+ self.mask_index = mask_index
+ self.is_encoder = is_encoder
+ self.max_position_embeddings = max_position_embeddings
+ self.embed_init_std = embed_init_std
+ self.init_std = init_std
+ self.summary_type = summary_type
+ self.summary_use_proj = summary_use_proj
+ self.summary_activation = summary_activation
+ self.summary_proj_to_labels = summary_proj_to_labels
+ self.summary_first_dropout = summary_first_dropout
+ self.start_n_top = start_n_top
+ self.end_n_top = end_n_top
+ self.mask_token_id = mask_token_id
+ self.lang_id = lang_id
+
+ if "n_words" in kwargs:
+ self.n_words = kwargs["n_words"]
+
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, **kwargs)
+
+
+# Copied from transformers.models.bert.configuration_bert.BertOnnxConfig
+class XLMOnnxConfig(OnnxConfig):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ if self.task == "multiple-choice":
+ dynamic_axis = {0: "batch", 1: "choice", 2: "sequence"}
+ else:
+ dynamic_axis = {0: "batch", 1: "sequence"}
+ return OrderedDict(
+ [
+ ("input_ids", dynamic_axis),
+ ("attention_mask", dynamic_axis),
+ ("token_type_ids", dynamic_axis),
+ ]
+ )
+
+
+__all__ = ["XLMConfig", "XLMOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/modeling_tf_xlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/modeling_tf_xlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..db89b4686f84bd6e19fdb340cbe91e3b9573c678
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/modeling_tf_xlm.py
@@ -0,0 +1,1356 @@
+# coding=utf-8
+# Copyright 2019-present, Facebook, Inc and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+TF 2.0 XLM model.
+"""
+
+from __future__ import annotations
+
+import itertools
+import warnings
+from dataclasses import dataclass
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_outputs import (
+ TFBaseModelOutput,
+ TFMultipleChoiceModelOutput,
+ TFQuestionAnsweringModelOutput,
+ TFSequenceClassifierOutput,
+ TFTokenClassifierOutput,
+)
+from ...modeling_tf_utils import (
+ TFModelInputType,
+ TFMultipleChoiceLoss,
+ TFPreTrainedModel,
+ TFQuestionAnsweringLoss,
+ TFSequenceClassificationLoss,
+ TFSequenceSummary,
+ TFSharedEmbeddings,
+ TFTokenClassificationLoss,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import (
+ MULTIPLE_CHOICE_DUMMY_INPUTS,
+ ModelOutput,
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+)
+from .configuration_xlm import XLMConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "FacebookAI/xlm-mlm-en-2048"
+_CONFIG_FOR_DOC = "XLMConfig"
+
+
+def create_sinusoidal_embeddings(n_pos, dim, out):
+ position_enc = np.array([[pos / np.power(10000, 2 * (j // 2) / dim) for j in range(dim)] for pos in range(n_pos)])
+ out[:, 0::2] = tf.constant(np.sin(position_enc[:, 0::2]))
+ out[:, 1::2] = tf.constant(np.cos(position_enc[:, 1::2]))
+
+
+def get_masks(slen, lengths, causal, padding_mask=None):
+ """
+ Generate hidden states mask, and optionally an attention mask.
+ """
+ bs = shape_list(lengths)[0]
+ if padding_mask is not None:
+ mask = padding_mask
+ else:
+ # assert lengths.max().item() <= slen
+ alen = tf.range(slen, dtype=lengths.dtype)
+ mask = alen < tf.expand_dims(lengths, axis=1)
+
+ # attention mask is the same as mask, or triangular inferior attention (causal)
+ if causal:
+ attn_mask = tf.less_equal(
+ tf.tile(tf.reshape(alen, (1, 1, slen)), (bs, slen, 1)), tf.reshape(alen, (1, slen, 1))
+ )
+ else:
+ attn_mask = mask
+
+ # sanity check
+ # assert shape_list(mask) == [bs, slen]
+ tf.debugging.assert_equal(shape_list(mask), [bs, slen])
+ if causal:
+ tf.debugging.assert_equal(shape_list(attn_mask), [bs, slen, slen])
+
+ return mask, attn_mask
+
+
+class TFXLMMultiHeadAttention(keras.layers.Layer):
+ NEW_ID = itertools.count()
+
+ def __init__(self, n_heads, dim, config, **kwargs):
+ super().__init__(**kwargs)
+ self.layer_id = next(TFXLMMultiHeadAttention.NEW_ID)
+ self.dim = dim
+ self.n_heads = n_heads
+ self.output_attentions = config.output_attentions
+ assert self.dim % self.n_heads == 0
+
+ self.q_lin = keras.layers.Dense(dim, kernel_initializer=get_initializer(config.init_std), name="q_lin")
+ self.k_lin = keras.layers.Dense(dim, kernel_initializer=get_initializer(config.init_std), name="k_lin")
+ self.v_lin = keras.layers.Dense(dim, kernel_initializer=get_initializer(config.init_std), name="v_lin")
+ self.out_lin = keras.layers.Dense(dim, kernel_initializer=get_initializer(config.init_std), name="out_lin")
+ self.dropout = keras.layers.Dropout(config.attention_dropout)
+ self.pruned_heads = set()
+ self.dim = dim
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ def call(self, input, mask, kv, cache, head_mask, output_attentions, training=False):
+ """
+ Self-attention (if kv is None) or attention over source sentence (provided by kv).
+ """
+ # Input is (bs, qlen, dim)
+ # Mask is (bs, klen) (non-causal) or (bs, klen, klen)
+ bs, qlen, dim = shape_list(input)
+
+ if kv is None:
+ klen = qlen if cache is None else cache["slen"] + qlen
+ else:
+ klen = shape_list(kv)[1]
+
+ # assert dim == self.dim, f'Dimensions do not match: {dim} input vs {self.dim} configured'
+ dim_per_head = self.dim // self.n_heads
+ mask_reshape = (bs, 1, qlen, klen) if len(shape_list(mask)) == 3 else (bs, 1, 1, klen)
+
+ def shape(x):
+ """projection"""
+ return tf.transpose(tf.reshape(x, (bs, -1, self.n_heads, dim_per_head)), perm=(0, 2, 1, 3))
+
+ def unshape(x):
+ """compute context"""
+ return tf.reshape(tf.transpose(x, perm=(0, 2, 1, 3)), (bs, -1, self.n_heads * dim_per_head))
+
+ q = shape(self.q_lin(input)) # (bs, n_heads, qlen, dim_per_head)
+
+ if kv is None:
+ k = shape(self.k_lin(input)) # (bs, n_heads, qlen, dim_per_head)
+ v = shape(self.v_lin(input)) # (bs, n_heads, qlen, dim_per_head)
+ elif cache is None or self.layer_id not in cache:
+ k = v = kv
+ k = shape(self.k_lin(k)) # (bs, n_heads, qlen, dim_per_head)
+ v = shape(self.v_lin(v)) # (bs, n_heads, qlen, dim_per_head)
+
+ if cache is not None:
+ if self.layer_id in cache:
+ if kv is None:
+ k_, v_ = cache[self.layer_id]
+ k = tf.concat([k_, k], axis=2) # (bs, n_heads, klen, dim_per_head)
+ v = tf.concat([v_, v], axis=2) # (bs, n_heads, klen, dim_per_head)
+ else:
+ k, v = cache[self.layer_id]
+
+ cache[self.layer_id] = (k, v)
+
+ f_dim_per_head = tf.cast(dim_per_head, dtype=q.dtype)
+ q = tf.multiply(q, tf.math.rsqrt(f_dim_per_head)) # (bs, n_heads, qlen, dim_per_head)
+ k = tf.cast(k, dtype=q.dtype)
+ scores = tf.matmul(q, k, transpose_b=True) # (bs, n_heads, qlen, klen)
+ mask = tf.reshape(mask, mask_reshape) # (bs, n_heads, qlen, klen)
+ # scores.masked_fill_(mask, -float('inf')) # (bs, n_heads, qlen, klen)
+ mask = tf.cast(mask, dtype=scores.dtype)
+ scores = scores - 1e30 * (1.0 - mask)
+ weights = stable_softmax(scores, axis=-1) # (bs, n_heads, qlen, klen)
+ weights = self.dropout(weights, training=training) # (bs, n_heads, qlen, klen)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ weights = weights * head_mask
+
+ context = tf.matmul(weights, v) # (bs, n_heads, qlen, dim_per_head)
+ context = unshape(context) # (bs, qlen, dim)
+ outputs = (self.out_lin(context),)
+
+ if output_attentions:
+ outputs = outputs + (weights,)
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "q_lin", None) is not None:
+ with tf.name_scope(self.q_lin.name):
+ self.q_lin.build([None, None, self.dim])
+ if getattr(self, "k_lin", None) is not None:
+ with tf.name_scope(self.k_lin.name):
+ self.k_lin.build([None, None, self.dim])
+ if getattr(self, "v_lin", None) is not None:
+ with tf.name_scope(self.v_lin.name):
+ self.v_lin.build([None, None, self.dim])
+ if getattr(self, "out_lin", None) is not None:
+ with tf.name_scope(self.out_lin.name):
+ self.out_lin.build([None, None, self.dim])
+
+
+class TFXLMTransformerFFN(keras.layers.Layer):
+ def __init__(self, in_dim, dim_hidden, out_dim, config, **kwargs):
+ super().__init__(**kwargs)
+
+ self.lin1 = keras.layers.Dense(dim_hidden, kernel_initializer=get_initializer(config.init_std), name="lin1")
+ self.lin2 = keras.layers.Dense(out_dim, kernel_initializer=get_initializer(config.init_std), name="lin2")
+ self.act = get_tf_activation("gelu") if config.gelu_activation else get_tf_activation("relu")
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.in_dim = in_dim
+ self.dim_hidden = dim_hidden
+
+ def call(self, input, training=False):
+ x = self.lin1(input)
+ x = self.act(x)
+ x = self.lin2(x)
+ x = self.dropout(x, training=training)
+
+ return x
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "lin1", None) is not None:
+ with tf.name_scope(self.lin1.name):
+ self.lin1.build([None, None, self.in_dim])
+ if getattr(self, "lin2", None) is not None:
+ with tf.name_scope(self.lin2.name):
+ self.lin2.build([None, None, self.dim_hidden])
+
+
+@keras_serializable
+class TFXLMMainLayer(keras.layers.Layer):
+ config_class = XLMConfig
+
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+ self.output_hidden_states = config.output_hidden_states
+ self.output_attentions = config.output_attentions
+ self.return_dict = config.use_return_dict
+
+ # encoder / decoder, output layer
+ self.is_encoder = config.is_encoder
+ self.is_decoder = not config.is_encoder
+
+ if self.is_decoder:
+ raise NotImplementedError("Currently XLM can only be used as an encoder")
+
+ # self.with_output = with_output
+ self.causal = config.causal
+
+ # dictionary / languages
+ self.n_langs = config.n_langs
+ self.use_lang_emb = config.use_lang_emb
+ self.n_words = config.n_words
+ self.eos_index = config.eos_index
+ self.pad_index = config.pad_index
+ # self.dico = dico
+ # self.id2lang = config.id2lang
+ # self.lang2id = config.lang2id
+ # assert len(self.dico) == self.n_words
+ # assert len(self.id2lang) == len(self.lang2id) == self.n_langs
+
+ # model parameters
+ self.dim = config.emb_dim # 512 by default
+ self.hidden_dim = self.dim * 4 # 2048 by default
+ self.n_heads = config.n_heads # 8 by default
+ self.n_layers = config.n_layers
+ self.max_position_embeddings = config.max_position_embeddings
+ self.embed_init_std = config.embed_init_std
+ if self.dim % self.n_heads != 0:
+ raise ValueError("transformer dim must be a multiple of n_heads")
+
+ # embeddings
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.attention_dropout = keras.layers.Dropout(config.attention_dropout)
+
+ if config.sinusoidal_embeddings:
+ raise NotImplementedError
+ # create_sinusoidal_embeddings(config.max_position_embeddings, self.dim, out=self.position_embeddings.weight)
+
+ self.embeddings = TFSharedEmbeddings(
+ self.n_words, self.dim, initializer_range=config.embed_init_std, name="embeddings"
+ ) # padding_idx=self.pad_index)
+ self.layer_norm_emb = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm_emb")
+
+ # transformer layers
+ self.attentions = []
+ self.layer_norm1 = []
+ self.ffns = []
+ self.layer_norm2 = []
+ # if self.is_decoder:
+ # self.layer_norm15 = []
+ # self.encoder_attn = []
+
+ for i in range(self.n_layers):
+ self.attentions.append(
+ TFXLMMultiHeadAttention(self.n_heads, self.dim, config=config, name=f"attentions_._{i}")
+ )
+ self.layer_norm1.append(
+ keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name=f"layer_norm1_._{i}")
+ )
+ # if self.is_decoder:
+ # self.layer_norm15.append(nn.LayerNorm(self.dim, eps=config.layer_norm_eps))
+ # self.encoder_attn.append(MultiHeadAttention(self.n_heads, self.dim, dropout=self.attention_dropout))
+ self.ffns.append(
+ TFXLMTransformerFFN(self.dim, self.hidden_dim, self.dim, config=config, name=f"ffns_._{i}")
+ )
+ self.layer_norm2.append(
+ keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name=f"layer_norm2_._{i}")
+ )
+
+ if hasattr(config, "pruned_heads"):
+ pruned_heads = config.pruned_heads.copy().items()
+ config.pruned_heads = {}
+
+ for layer, heads in pruned_heads:
+ if self.attentions[int(layer)].n_heads == config.n_heads:
+ self.prune_heads({int(layer): list(map(int, heads))})
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ with tf.name_scope("position_embeddings"):
+ self.position_embeddings = self.add_weight(
+ name="embeddings",
+ shape=[self.max_position_embeddings, self.dim],
+ initializer=get_initializer(self.embed_init_std),
+ )
+
+ if self.n_langs > 1 and self.use_lang_emb:
+ with tf.name_scope("lang_embeddings"):
+ self.lang_embeddings = self.add_weight(
+ name="embeddings",
+ shape=[self.n_langs, self.dim],
+ initializer=get_initializer(self.embed_init_std),
+ )
+ if getattr(self, "embeddings", None) is not None:
+ with tf.name_scope(self.embeddings.name):
+ self.embeddings.build(None)
+ if getattr(self, "layer_norm_emb", None) is not None:
+ with tf.name_scope(self.layer_norm_emb.name):
+ self.layer_norm_emb.build([None, None, self.dim])
+ for layer in self.attentions:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+ for layer in self.layer_norm1:
+ with tf.name_scope(layer.name):
+ layer.build([None, None, self.dim])
+ for layer in self.ffns:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+ for layer in self.layer_norm2:
+ with tf.name_scope(layer.name):
+ layer.build([None, None, self.dim])
+
+ def get_input_embeddings(self):
+ return self.embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.weight = value
+ self.embeddings.vocab_size = shape_list(value)[0]
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ raise NotImplementedError
+
+ @unpack_inputs
+ def call(
+ self,
+ input_ids=None,
+ attention_mask=None,
+ langs=None,
+ token_type_ids=None,
+ position_ids=None,
+ lengths=None,
+ cache=None,
+ head_mask=None,
+ inputs_embeds=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ training=False,
+ ) -> TFBaseModelOutput | tuple[tf.Tensor]:
+ # removed: src_enc=None, src_len=None
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ bs, slen = shape_list(input_ids)
+ elif inputs_embeds is not None:
+ bs, slen = shape_list(inputs_embeds)[:2]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ if lengths is None:
+ if input_ids is not None:
+ lengths = tf.reduce_sum(
+ tf.cast(tf.not_equal(input_ids, self.pad_index), dtype=input_ids.dtype), axis=1
+ )
+ else:
+ lengths = tf.convert_to_tensor([slen] * bs)
+ # mask = input_ids != self.pad_index
+
+ # check inputs
+ # assert shape_list(lengths)[0] == bs
+ (
+ tf.debugging.assert_equal(shape_list(lengths)[0], bs),
+ f"Expected batch size {shape_list(lengths)[0]} and received batch size {bs} mismatched",
+ )
+ # assert lengths.max().item() <= slen
+ # input_ids = input_ids.transpose(0, 1) # batch size as dimension 0
+ # assert (src_enc is None) == (src_len is None)
+ # if src_enc is not None:
+ # assert self.is_decoder
+ # assert src_enc.size(0) == bs
+
+ # generate masks
+ mask, attn_mask = get_masks(slen, lengths, self.causal, padding_mask=attention_mask)
+ # if self.is_decoder and src_enc is not None:
+ # src_mask = torch.arange(src_len.max(), dtype=torch.long, device=lengths.device) < src_len[:, None]
+
+ # position_ids
+ if position_ids is None:
+ position_ids = tf.expand_dims(tf.range(slen), axis=0)
+ position_ids = tf.tile(position_ids, (bs, 1))
+
+ # assert shape_list(position_ids) == [bs, slen] # (slen, bs)
+ (
+ tf.debugging.assert_equal(shape_list(position_ids), [bs, slen]),
+ f"Position id shape {shape_list(position_ids)} and input shape {[bs, slen]} mismatched",
+ )
+ # position_ids = position_ids.transpose(0, 1)
+
+ # langs
+ if langs is not None:
+ # assert shape_list(langs) == [bs, slen] # (slen, bs)
+ (
+ tf.debugging.assert_equal(shape_list(langs), [bs, slen]),
+ f"Lang shape {shape_list(langs)} and input shape {[bs, slen]} mismatched",
+ )
+ # langs = langs.transpose(0, 1)
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x qlen x klen]
+ if head_mask is not None:
+ raise NotImplementedError
+ else:
+ head_mask = [None] * self.n_layers
+
+ # do not recompute cached elements
+ if cache is not None and input_ids is not None:
+ _slen = slen - cache["slen"]
+ input_ids = input_ids[:, -_slen:]
+ position_ids = position_ids[:, -_slen:]
+ if langs is not None:
+ langs = langs[:, -_slen:]
+ mask = mask[:, -_slen:]
+ attn_mask = attn_mask[:, -_slen:]
+
+ # embeddings
+ if inputs_embeds is None:
+ check_embeddings_within_bounds(input_ids, self.embeddings.vocab_size)
+ inputs_embeds = self.embeddings(input_ids)
+
+ tensor = inputs_embeds + tf.gather(self.position_embeddings, position_ids)
+
+ if langs is not None and self.use_lang_emb and self.n_langs > 1:
+ tensor = tensor + tf.gather(self.lang_embeddings, langs)
+ if token_type_ids is not None:
+ tensor = tensor + self.embeddings(token_type_ids)
+
+ tensor = self.layer_norm_emb(tensor)
+ tensor = self.dropout(tensor, training=training)
+ mask = tf.cast(mask, dtype=tensor.dtype)
+ tensor = tensor * tf.expand_dims(mask, axis=-1)
+
+ # transformer layers
+ hidden_states = () if output_hidden_states else None
+ attentions = () if output_attentions else None
+
+ for i in range(self.n_layers):
+ if output_hidden_states:
+ hidden_states = hidden_states + (tensor,)
+
+ # self attention
+ attn_outputs = self.attentions[i](
+ tensor,
+ attn_mask,
+ None,
+ cache,
+ head_mask[i],
+ output_attentions,
+ training=training,
+ )
+ attn = attn_outputs[0]
+
+ if output_attentions:
+ attentions = attentions + (attn_outputs[1],)
+
+ attn = self.dropout(attn, training=training)
+ tensor = tensor + attn
+ tensor = self.layer_norm1[i](tensor)
+
+ # encoder attention (for decoder only)
+ # if self.is_decoder and src_enc is not None:
+ # attn = self.encoder_attn[i](tensor, src_mask, kv=src_enc, cache=cache)
+ # attn = nn.functional.dropout(attn, p=self.dropout, training=self.training)
+ # tensor = tensor + attn
+ # tensor = self.layer_norm15[i](tensor)
+
+ # FFN
+ tensor = tensor + self.ffns[i](tensor)
+ tensor = self.layer_norm2[i](tensor)
+ tensor = tensor * tf.expand_dims(mask, axis=-1)
+
+ # Add last hidden state
+ if output_hidden_states:
+ hidden_states = hidden_states + (tensor,)
+
+ # update cache length
+ if cache is not None:
+ cache["slen"] += tensor.size(1)
+
+ # move back sequence length to dimension 0
+ # tensor = tensor.transpose(0, 1)
+
+ if not return_dict:
+ return tuple(v for v in [tensor, hidden_states, attentions] if v is not None)
+
+ return TFBaseModelOutput(last_hidden_state=tensor, hidden_states=hidden_states, attentions=attentions)
+
+
+class TFXLMPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = XLMConfig
+ base_model_prefix = "transformer"
+
+ @property
+ def dummy_inputs(self):
+ # Sometimes XLM has language embeddings so don't forget to build them as well if needed
+ inputs_list = tf.constant([[7, 6, 0, 0, 1], [1, 2, 3, 0, 0], [0, 0, 0, 4, 5]], dtype=tf.int32)
+ attns_list = tf.constant([[1, 1, 0, 0, 1], [1, 1, 1, 0, 0], [1, 0, 0, 1, 1]], dtype=tf.int32)
+ if self.config.use_lang_emb and self.config.n_langs > 1:
+ return {
+ "input_ids": inputs_list,
+ "attention_mask": attns_list,
+ "langs": tf.constant([[1, 1, 0, 0, 1], [1, 1, 1, 0, 0], [1, 0, 0, 1, 1]], dtype=tf.int32),
+ }
+ else:
+ return {"input_ids": inputs_list, "attention_mask": attns_list}
+
+
+# Remove when XLMWithLMHead computes loss like other LM models
+@dataclass
+class TFXLMWithLMHeadModelOutput(ModelOutput):
+ """
+ Base class for [`TFXLMWithLMHeadModel`] outputs.
+
+ Args:
+ logits (`tf.Tensor` of shape `(batch_size, sequence_length, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ logits: tf.Tensor | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+
+
+XLM_START_DOCSTRING = r"""
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Parameters:
+ config ([`XLMConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+XLM_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`Numpy array` or `tf.Tensor` of shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.__call__`] and
+ [`PreTrainedTokenizer.encode`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`Numpy array` or `tf.Tensor` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ langs (`tf.Tensor` or `Numpy array` of shape `({0})`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ token_type_ids (`Numpy array` or `tf.Tensor` of shape `({0})`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`Numpy array` or `tf.Tensor` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ lengths (`tf.Tensor` or `Numpy array` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, tf.Tensor]`, *optional*):
+ Dictionary string to `tf.Tensor` that contains precomputed hidden states (key and values in the attention
+ blocks) as computed by the model (see `cache` output below). Can be used to speed up sequential decoding.
+
+ The dictionary object will be modified in-place during the forward pass to add newly computed
+ hidden-states.
+ head_mask (`Numpy array` or `tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ inputs_embeds (`tf.Tensor` of shape `({0}, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+
+@add_start_docstrings(
+ "The bare XLM Model transformer outputting raw hidden-states without any specific head on top.",
+ XLM_START_DOCSTRING,
+)
+class TFXLMModel(TFXLMPreTrainedModel):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.transformer = TFXLMMainLayer(config, name="transformer")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFBaseModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: tf.Tensor | None = None,
+ langs: tf.Tensor | None = None,
+ token_type_ids: tf.Tensor | None = None,
+ position_ids: tf.Tensor | None = None,
+ lengths: tf.Tensor | None = None,
+ cache: dict[str, tf.Tensor] | None = None,
+ head_mask: tf.Tensor | None = None,
+ inputs_embeds: tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFBaseModelOutput | tuple[tf.Tensor]:
+ outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+
+
+class TFXLMPredLayer(keras.layers.Layer):
+ """
+ Prediction layer (cross_entropy or adaptive_softmax).
+ """
+
+ def __init__(self, config, input_embeddings, **kwargs):
+ super().__init__(**kwargs)
+
+ self.asm = config.asm
+ self.n_words = config.n_words
+ self.pad_index = config.pad_index
+
+ if config.asm is False:
+ self.input_embeddings = input_embeddings
+ else:
+ raise NotImplementedError
+ # self.proj = nn.AdaptiveLogSoftmaxWithLoss(
+ # in_features=dim,
+ # n_classes=config.n_words,
+ # cutoffs=config.asm_cutoffs,
+ # div_value=config.asm_div_value,
+ # head_bias=True, # default is False
+ # )
+
+ def build(self, input_shape):
+ # The output weights are the same as the input embeddings, but there is an output-only bias for each token.
+ self.bias = self.add_weight(shape=(self.n_words,), initializer="zeros", trainable=True, name="bias")
+
+ super().build(input_shape)
+
+ def get_output_embeddings(self):
+ return self.input_embeddings
+
+ def set_output_embeddings(self, value):
+ self.input_embeddings.weight = value
+ self.input_embeddings.vocab_size = shape_list(value)[0]
+
+ def get_bias(self):
+ return {"bias": self.bias}
+
+ def set_bias(self, value):
+ self.bias = value["bias"]
+ self.vocab_size = shape_list(value["bias"])[0]
+
+ def call(self, hidden_states):
+ hidden_states = self.input_embeddings(hidden_states, mode="linear")
+ hidden_states = hidden_states + self.bias
+
+ return hidden_states
+
+
+@add_start_docstrings(
+ """
+ The XLM Model transformer with a language modeling head on top (linear layer with weights tied to the input
+ embeddings).
+ """,
+ XLM_START_DOCSTRING,
+)
+class TFXLMWithLMHeadModel(TFXLMPreTrainedModel):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.transformer = TFXLMMainLayer(config, name="transformer")
+ self.pred_layer = TFXLMPredLayer(config, self.transformer.embeddings, name="pred_layer_._proj")
+ # XLM does not have past caching features
+ self.supports_xla_generation = False
+
+ def get_lm_head(self):
+ return self.pred_layer
+
+ def get_prefix_bias_name(self):
+ warnings.warn("The method get_prefix_bias_name is deprecated. Please use `get_bias` instead.", FutureWarning)
+ return self.name + "/" + self.pred_layer.name
+
+ def prepare_inputs_for_generation(self, inputs, **kwargs):
+ mask_token_id = self.config.mask_token_id
+ lang_id = self.config.lang_id
+
+ effective_batch_size = inputs.shape[0]
+ mask_token = tf.fill((effective_batch_size, 1), 1) * mask_token_id
+ inputs = tf.concat([inputs, mask_token], axis=1)
+
+ if lang_id is not None:
+ langs = tf.ones_like(inputs) * lang_id
+ else:
+ langs = None
+ return {"input_ids": inputs, "langs": langs}
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFXLMWithLMHeadModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ langs: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ lengths: np.ndarray | tf.Tensor | None = None,
+ cache: dict[str, tf.Tensor] | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFXLMWithLMHeadModelOutput | tuple[tf.Tensor]:
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ output = transformer_outputs[0]
+ outputs = self.pred_layer(output)
+
+ if not return_dict:
+ return (outputs,) + transformer_outputs[1:]
+
+ return TFXLMWithLMHeadModelOutput(
+ logits=outputs, hidden_states=transformer_outputs.hidden_states, attentions=transformer_outputs.attentions
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "pred_layer", None) is not None:
+ with tf.name_scope(self.pred_layer.name):
+ self.pred_layer.build(None)
+
+
+@add_start_docstrings(
+ """
+ XLM Model with a sequence classification/regression head on top (a linear layer on top of the pooled output) e.g.
+ for GLUE tasks.
+ """,
+ XLM_START_DOCSTRING,
+)
+class TFXLMForSequenceClassification(TFXLMPreTrainedModel, TFSequenceClassificationLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.transformer = TFXLMMainLayer(config, name="transformer")
+ self.sequence_summary = TFSequenceSummary(config, initializer_range=config.init_std, name="sequence_summary")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFSequenceClassifierOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ langs: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ lengths: np.ndarray | tf.Tensor | None = None,
+ cache: dict[str, tf.Tensor] | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFSequenceClassifierOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ output = transformer_outputs[0]
+
+ logits = self.sequence_summary(output)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFSequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "sequence_summary", None) is not None:
+ with tf.name_scope(self.sequence_summary.name):
+ self.sequence_summary.build(None)
+
+
+@add_start_docstrings(
+ """
+ XLM Model with a multiple choice classification head on top (a linear layer on top of the pooled output and a
+ softmax) e.g. for RocStories/SWAG tasks.
+ """,
+ XLM_START_DOCSTRING,
+)
+class TFXLMForMultipleChoice(TFXLMPreTrainedModel, TFMultipleChoiceLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.transformer = TFXLMMainLayer(config, name="transformer")
+ self.sequence_summary = TFSequenceSummary(config, initializer_range=config.init_std, name="sequence_summary")
+ self.logits_proj = keras.layers.Dense(
+ 1, kernel_initializer=get_initializer(config.initializer_range), name="logits_proj"
+ )
+ self.config = config
+
+ @property
+ def dummy_inputs(self):
+ """
+ Dummy inputs to build the network.
+
+ Returns:
+ tf.Tensor with dummy inputs
+ """
+ # Sometimes XLM has language embeddings so don't forget to build them as well if needed
+ if self.config.use_lang_emb and self.config.n_langs > 1:
+ return {
+ "input_ids": tf.constant(MULTIPLE_CHOICE_DUMMY_INPUTS, dtype=tf.int32),
+ "langs": tf.constant(MULTIPLE_CHOICE_DUMMY_INPUTS, dtype=tf.int32),
+ }
+ else:
+ return {
+ "input_ids": tf.constant(MULTIPLE_CHOICE_DUMMY_INPUTS, dtype=tf.int32),
+ }
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_INPUTS_DOCSTRING.format("batch_size, num_choices, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFMultipleChoiceModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ langs: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ lengths: np.ndarray | tf.Tensor | None = None,
+ cache: dict[str, tf.Tensor] | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFMultipleChoiceModelOutput | tuple[tf.Tensor]:
+ if input_ids is not None:
+ num_choices = shape_list(input_ids)[1]
+ seq_length = shape_list(input_ids)[2]
+ else:
+ num_choices = shape_list(inputs_embeds)[1]
+ seq_length = shape_list(inputs_embeds)[2]
+
+ flat_input_ids = tf.reshape(input_ids, (-1, seq_length)) if input_ids is not None else None
+ flat_attention_mask = tf.reshape(attention_mask, (-1, seq_length)) if attention_mask is not None else None
+ flat_token_type_ids = tf.reshape(token_type_ids, (-1, seq_length)) if token_type_ids is not None else None
+ flat_position_ids = tf.reshape(position_ids, (-1, seq_length)) if position_ids is not None else None
+ flat_langs = tf.reshape(langs, (-1, seq_length)) if langs is not None else None
+ flat_inputs_embeds = (
+ tf.reshape(inputs_embeds, (-1, seq_length, shape_list(inputs_embeds)[3]))
+ if inputs_embeds is not None
+ else None
+ )
+
+ if lengths is not None:
+ logger.warning(
+ "The `lengths` parameter cannot be used with the XLM multiple choice models. Please use the "
+ "attention mask instead.",
+ )
+ lengths = None
+
+ transformer_outputs = self.transformer(
+ flat_input_ids,
+ flat_attention_mask,
+ flat_langs,
+ flat_token_type_ids,
+ flat_position_ids,
+ lengths,
+ cache,
+ head_mask,
+ flat_inputs_embeds,
+ output_attentions,
+ output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ output = transformer_outputs[0]
+ logits = self.sequence_summary(output)
+ logits = self.logits_proj(logits)
+ reshaped_logits = tf.reshape(logits, (-1, num_choices))
+
+ loss = None if labels is None else self.hf_compute_loss(labels, reshaped_logits)
+
+ if not return_dict:
+ output = (reshaped_logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFMultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "sequence_summary", None) is not None:
+ with tf.name_scope(self.sequence_summary.name):
+ self.sequence_summary.build(None)
+ if getattr(self, "logits_proj", None) is not None:
+ with tf.name_scope(self.logits_proj.name):
+ self.logits_proj.build([None, None, self.config.num_labels])
+
+
+@add_start_docstrings(
+ """
+ XLM Model with a token classification head on top (a linear layer on top of the hidden-states output) e.g. for
+ Named-Entity-Recognition (NER) tasks.
+ """,
+ XLM_START_DOCSTRING,
+)
+class TFXLMForTokenClassification(TFXLMPreTrainedModel, TFTokenClassificationLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.transformer = TFXLMMainLayer(config, name="transformer")
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.classifier = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.init_std), name="classifier"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFTokenClassifierOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ langs: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ lengths: np.ndarray | tf.Tensor | None = None,
+ cache: dict[str, tf.Tensor] | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFTokenClassifierOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = transformer_outputs[0]
+
+ sequence_output = self.dropout(sequence_output, training=training)
+ logits = self.classifier(sequence_output)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFTokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.config.hidden_size])
+
+
+@add_start_docstrings(
+ """
+ XLM Model with a span classification head on top for extractive question-answering tasks like SQuAD (a linear layer
+ on top of the hidden-states output to compute `span start logits` and `span end logits`).
+ """,
+ XLM_START_DOCSTRING,
+)
+class TFXLMForQuestionAnsweringSimple(TFXLMPreTrainedModel, TFQuestionAnsweringLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.transformer = TFXLMMainLayer(config, name="transformer")
+ self.qa_outputs = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.init_std), name="qa_outputs"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFQuestionAnsweringModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ langs: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ lengths: np.ndarray | tf.Tensor | None = None,
+ cache: dict[str, tf.Tensor] | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ start_positions: np.ndarray | tf.Tensor | None = None,
+ end_positions: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFQuestionAnsweringModelOutput | tuple[tf.Tensor]:
+ r"""
+ start_positions (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the start of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ end_positions (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the end of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ """
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = transformer_outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = tf.split(logits, 2, axis=-1)
+ start_logits = tf.squeeze(start_logits, axis=-1)
+ end_logits = tf.squeeze(end_logits, axis=-1)
+
+ loss = None
+ if start_positions is not None and end_positions is not None:
+ labels = {"start_position": start_positions}
+ labels["end_position"] = end_positions
+ loss = self.hf_compute_loss(labels, (start_logits, end_logits))
+
+ if not return_dict:
+ output = (start_logits, end_logits) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFQuestionAnsweringModelOutput(
+ loss=loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "qa_outputs", None) is not None:
+ with tf.name_scope(self.qa_outputs.name):
+ self.qa_outputs.build([None, None, self.config.hidden_size])
+
+
+__all__ = [
+ "TFXLMForMultipleChoice",
+ "TFXLMForQuestionAnsweringSimple",
+ "TFXLMForSequenceClassification",
+ "TFXLMForTokenClassification",
+ "TFXLMMainLayer",
+ "TFXLMModel",
+ "TFXLMPreTrainedModel",
+ "TFXLMWithLMHeadModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/modeling_xlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/modeling_xlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..4e7316fb781bfdf5b93a06c97c3577719e5da54d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/modeling_xlm.py
@@ -0,0 +1,1635 @@
+# coding=utf-8
+# Copyright 2019-present, Facebook, Inc and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+PyTorch XLM model.
+"""
+
+import math
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import numpy as np
+import torch
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import gelu, get_activation
+from ...cache_utils import DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_outputs import (
+ BaseModelOutput,
+ MaskedLMOutput,
+ MultipleChoiceModelOutput,
+ QuestionAnsweringModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import ModelOutput, auto_docstring, logging
+from .configuration_xlm import XLMConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+def create_sinusoidal_embeddings(n_pos, dim, out):
+ position_enc = np.array([[pos / np.power(10000, 2 * (j // 2) / dim) for j in range(dim)] for pos in range(n_pos)])
+ out.requires_grad = False
+ out[:, 0::2] = torch.FloatTensor(np.sin(position_enc[:, 0::2]))
+ out[:, 1::2] = torch.FloatTensor(np.cos(position_enc[:, 1::2]))
+ out.detach_()
+
+
+def get_masks(slen, lengths, causal, padding_mask=None):
+ """
+ Generate hidden states mask, and optionally an attention mask.
+ """
+ alen = torch.arange(slen, dtype=torch.long, device=lengths.device)
+ if padding_mask is not None:
+ mask = padding_mask
+ else:
+ assert lengths.max().item() <= slen
+ mask = alen < lengths[:, None]
+
+ # attention mask is the same as mask, or triangular inferior attention (causal)
+ bs = lengths.size(0)
+ if causal:
+ attn_mask = alen[None, None, :].repeat(bs, slen, 1) <= alen[None, :, None]
+ else:
+ attn_mask = mask
+
+ # sanity check
+ assert mask.size() == (bs, slen)
+ assert causal is False or attn_mask.size() == (bs, slen, slen)
+
+ return mask, attn_mask
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for outputs of question answering models using a [`~modeling_utils.XLMSQuADHead`].
+ """
+)
+class XLMSquadHeadOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned if both `start_positions` and `end_positions` are provided):
+ Classification loss as the sum of start token, end token (and is_impossible if provided) classification
+ losses.
+ start_top_log_probs (`torch.FloatTensor` of shape `(batch_size, config.start_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the top config.start_n_top start token possibilities (beam-search).
+ start_top_index (`torch.LongTensor` of shape `(batch_size, config.start_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Indices for the top config.start_n_top start token possibilities (beam-search).
+ end_top_log_probs (`torch.FloatTensor` of shape `(batch_size, config.start_n_top * config.end_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the top `config.start_n_top * config.end_n_top` end token possibilities
+ (beam-search).
+ end_top_index (`torch.LongTensor` of shape `(batch_size, config.start_n_top * config.end_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Indices for the top `config.start_n_top * config.end_n_top` end token possibilities (beam-search).
+ cls_logits (`torch.FloatTensor` of shape `(batch_size,)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the `is_impossible` label of the answers.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ start_top_log_probs: Optional[torch.FloatTensor] = None
+ start_top_index: Optional[torch.LongTensor] = None
+ end_top_log_probs: Optional[torch.FloatTensor] = None
+ end_top_index: Optional[torch.LongTensor] = None
+ cls_logits: Optional[torch.FloatTensor] = None
+
+
+class XLMPoolerStartLogits(nn.Module):
+ """
+ Compute SQuAD start logits from sequence hidden states.
+
+ Args:
+ config ([`XLMConfig`]):
+ The config used by the model, will be used to grab the `hidden_size` of the model.
+ """
+
+ def __init__(self, config: XLMConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, 1)
+
+ def forward(
+ self, hidden_states: torch.FloatTensor, p_mask: Optional[torch.FloatTensor] = None
+ ) -> torch.FloatTensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`):
+ The final hidden states of the model.
+ p_mask (`torch.FloatTensor` of shape `(batch_size, seq_len)`, *optional*):
+ Mask for tokens at invalid position, such as query and special symbols (PAD, SEP, CLS). 1.0 means token
+ should be masked.
+
+ Returns:
+ `torch.FloatTensor`: The start logits for SQuAD.
+ """
+ x = self.dense(hidden_states).squeeze(-1)
+
+ if p_mask is not None:
+ if p_mask.dtype == torch.float16:
+ x = x * (1 - p_mask) - 65500 * p_mask
+ else:
+ x = x * (1 - p_mask) - 1e30 * p_mask
+
+ return x
+
+
+class XLMPoolerEndLogits(nn.Module):
+ """
+ Compute SQuAD end logits from sequence hidden states.
+
+ Args:
+ config ([`XLMConfig`]):
+ The config used by the model, will be used to grab the `hidden_size` of the model and the `layer_norm_eps`
+ to use.
+ """
+
+ def __init__(self, config: XLMConfig):
+ super().__init__()
+ self.dense_0 = nn.Linear(config.hidden_size * 2, config.hidden_size)
+ self.activation = nn.Tanh()
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dense_1 = nn.Linear(config.hidden_size, 1)
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ start_states: Optional[torch.FloatTensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ p_mask: Optional[torch.FloatTensor] = None,
+ ) -> torch.FloatTensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`):
+ The final hidden states of the model.
+ start_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`, *optional*):
+ The hidden states of the first tokens for the labeled span.
+ start_positions (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ The position of the first token for the labeled span.
+ p_mask (`torch.FloatTensor` of shape `(batch_size, seq_len)`, *optional*):
+ Mask for tokens at invalid position, such as query and special symbols (PAD, SEP, CLS). 1.0 means token
+ should be masked.
+
+
+
+ One of `start_states` or `start_positions` should be not `None`. If both are set, `start_positions` overrides
+ `start_states`.
+
+
+
+ Returns:
+ `torch.FloatTensor`: The end logits for SQuAD.
+ """
+ assert start_states is not None or start_positions is not None, (
+ "One of start_states, start_positions should be not None"
+ )
+ if start_positions is not None:
+ slen, hsz = hidden_states.shape[-2:]
+ start_positions = start_positions[:, None, None].expand(-1, -1, hsz) # shape (bsz, 1, hsz)
+ start_states = hidden_states.gather(-2, start_positions) # shape (bsz, 1, hsz)
+ start_states = start_states.expand(-1, slen, -1) # shape (bsz, slen, hsz)
+
+ x = self.dense_0(torch.cat([hidden_states, start_states], dim=-1))
+ x = self.activation(x)
+ x = self.LayerNorm(x)
+ x = self.dense_1(x).squeeze(-1)
+
+ if p_mask is not None:
+ if p_mask.dtype == torch.float16:
+ x = x * (1 - p_mask) - 65500 * p_mask
+ else:
+ x = x * (1 - p_mask) - 1e30 * p_mask
+
+ return x
+
+
+class XLMPoolerAnswerClass(nn.Module):
+ """
+ Compute SQuAD 2.0 answer class from classification and start tokens hidden states.
+
+ Args:
+ config ([`XLMConfig`]):
+ The config used by the model, will be used to grab the `hidden_size` of the model.
+ """
+
+ def __init__(self, config: XLMConfig):
+ super().__init__()
+ self.dense_0 = nn.Linear(config.hidden_size * 2, config.hidden_size)
+ self.activation = nn.Tanh()
+ self.dense_1 = nn.Linear(config.hidden_size, 1, bias=False)
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ start_states: Optional[torch.FloatTensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ cls_index: Optional[torch.LongTensor] = None,
+ ) -> torch.FloatTensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`):
+ The final hidden states of the model.
+ start_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`, *optional*):
+ The hidden states of the first tokens for the labeled span.
+ start_positions (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ The position of the first token for the labeled span.
+ cls_index (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Position of the CLS token for each sentence in the batch. If `None`, takes the last token.
+
+
+
+ One of `start_states` or `start_positions` should be not `None`. If both are set, `start_positions` overrides
+ `start_states`.
+
+
+
+ Returns:
+ `torch.FloatTensor`: The SQuAD 2.0 answer class.
+ """
+ # No dependency on end_feature so that we can obtain one single `cls_logits` for each sample.
+ hsz = hidden_states.shape[-1]
+ assert start_states is not None or start_positions is not None, (
+ "One of start_states, start_positions should be not None"
+ )
+ if start_positions is not None:
+ start_positions = start_positions[:, None, None].expand(-1, -1, hsz) # shape (bsz, 1, hsz)
+ start_states = hidden_states.gather(-2, start_positions).squeeze(-2) # shape (bsz, hsz)
+
+ if cls_index is not None:
+ cls_index = cls_index[:, None, None].expand(-1, -1, hsz) # shape (bsz, 1, hsz)
+ cls_token_state = hidden_states.gather(-2, cls_index).squeeze(-2) # shape (bsz, hsz)
+ else:
+ cls_token_state = hidden_states[:, -1, :] # shape (bsz, hsz)
+
+ x = self.dense_0(torch.cat([start_states, cls_token_state], dim=-1))
+ x = self.activation(x)
+ x = self.dense_1(x).squeeze(-1)
+
+ return x
+
+
+class XLMSQuADHead(nn.Module):
+ r"""
+ A SQuAD head inspired by XLNet.
+
+ Args:
+ config ([`XLMConfig`]):
+ The config used by the model, will be used to grab the `hidden_size` of the model and the `layer_norm_eps`
+ to use.
+ """
+
+ def __init__(self, config: XLMConfig):
+ super().__init__()
+ self.start_n_top = config.start_n_top
+ self.end_n_top = config.end_n_top
+
+ self.start_logits = XLMPoolerStartLogits(config)
+ self.end_logits = XLMPoolerEndLogits(config)
+ self.answer_class = XLMPoolerAnswerClass(config)
+
+ @auto_docstring
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ cls_index: Optional[torch.LongTensor] = None,
+ is_impossible: Optional[torch.LongTensor] = None,
+ p_mask: Optional[torch.FloatTensor] = None,
+ return_dict: bool = False,
+ ) -> Union[XLMSquadHeadOutput, tuple[torch.FloatTensor]]:
+ r"""
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`):
+ Final hidden states of the model on the sequence tokens.
+ start_positions (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Positions of the first token for the labeled span.
+ end_positions (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Positions of the last token for the labeled span.
+ cls_index (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Position of the CLS token for each sentence in the batch. If `None`, takes the last token.
+ is_impossible (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Whether the question has a possible answer in the paragraph or not.
+ p_mask (`torch.FloatTensor` of shape `(batch_size, seq_len)`, *optional*):
+ Mask for tokens at invalid position, such as query and special symbols (PAD, SEP, CLS). 1.0 means token
+ should be masked.
+ """
+ start_logits = self.start_logits(hidden_states, p_mask=p_mask)
+
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, let's remove the dimension added by batch splitting
+ for x in (start_positions, end_positions, cls_index, is_impossible):
+ if x is not None and x.dim() > 1:
+ x.squeeze_(-1)
+
+ # during training, compute the end logits based on the ground truth of the start position
+ end_logits = self.end_logits(hidden_states, start_positions=start_positions, p_mask=p_mask)
+
+ loss_fct = CrossEntropyLoss()
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if cls_index is not None and is_impossible is not None:
+ # Predict answerability from the representation of CLS and START
+ cls_logits = self.answer_class(hidden_states, start_positions=start_positions, cls_index=cls_index)
+ loss_fct_cls = nn.BCEWithLogitsLoss()
+ cls_loss = loss_fct_cls(cls_logits, is_impossible)
+
+ # note(zhiliny): by default multiply the loss by 0.5 so that the scale is comparable to start_loss and end_loss
+ total_loss += cls_loss * 0.5
+
+ return XLMSquadHeadOutput(loss=total_loss) if return_dict else (total_loss,)
+
+ else:
+ # during inference, compute the end logits based on beam search
+ bsz, slen, hsz = hidden_states.size()
+ start_log_probs = nn.functional.softmax(start_logits, dim=-1) # shape (bsz, slen)
+
+ start_top_log_probs, start_top_index = torch.topk(
+ start_log_probs, self.start_n_top, dim=-1
+ ) # shape (bsz, start_n_top)
+ start_top_index_exp = start_top_index.unsqueeze(-1).expand(-1, -1, hsz) # shape (bsz, start_n_top, hsz)
+ start_states = torch.gather(hidden_states, -2, start_top_index_exp) # shape (bsz, start_n_top, hsz)
+ start_states = start_states.unsqueeze(1).expand(-1, slen, -1, -1) # shape (bsz, slen, start_n_top, hsz)
+
+ hidden_states_expanded = hidden_states.unsqueeze(2).expand_as(
+ start_states
+ ) # shape (bsz, slen, start_n_top, hsz)
+ p_mask = p_mask.unsqueeze(-1) if p_mask is not None else None
+ end_logits = self.end_logits(hidden_states_expanded, start_states=start_states, p_mask=p_mask)
+ end_log_probs = nn.functional.softmax(end_logits, dim=1) # shape (bsz, slen, start_n_top)
+
+ end_top_log_probs, end_top_index = torch.topk(
+ end_log_probs, self.end_n_top, dim=1
+ ) # shape (bsz, end_n_top, start_n_top)
+ end_top_log_probs = end_top_log_probs.view(-1, self.start_n_top * self.end_n_top)
+ end_top_index = end_top_index.view(-1, self.start_n_top * self.end_n_top)
+
+ start_states = torch.einsum("blh,bl->bh", hidden_states, start_log_probs)
+ cls_logits = self.answer_class(hidden_states, start_states=start_states, cls_index=cls_index)
+
+ if not return_dict:
+ return (start_top_log_probs, start_top_index, end_top_log_probs, end_top_index, cls_logits)
+ else:
+ return XLMSquadHeadOutput(
+ start_top_log_probs=start_top_log_probs,
+ start_top_index=start_top_index,
+ end_top_log_probs=end_top_log_probs,
+ end_top_index=end_top_index,
+ cls_logits=cls_logits,
+ )
+
+
+class XLMSequenceSummary(nn.Module):
+ r"""
+ Compute a single vector summary of a sequence hidden states.
+
+ Args:
+ config ([`XLMConfig`]):
+ The config used by the model. Relevant arguments in the config class of the model are (refer to the actual
+ config class of your model for the default values it uses):
+
+ - **summary_type** (`str`) -- The method to use to make this summary. Accepted values are:
+
+ - `"last"` -- Take the last token hidden state (like XLNet)
+ - `"first"` -- Take the first token hidden state (like Bert)
+ - `"mean"` -- Take the mean of all tokens hidden states
+ - `"cls_index"` -- Supply a Tensor of classification token position (GPT/GPT-2)
+ - `"attn"` -- Not implemented now, use multi-head attention
+
+ - **summary_use_proj** (`bool`) -- Add a projection after the vector extraction.
+ - **summary_proj_to_labels** (`bool`) -- If `True`, the projection outputs to `config.num_labels` classes
+ (otherwise to `config.hidden_size`).
+ - **summary_activation** (`Optional[str]`) -- Set to `"tanh"` to add a tanh activation to the output,
+ another string or `None` will add no activation.
+ - **summary_first_dropout** (`float`) -- Optional dropout probability before the projection and activation.
+ - **summary_last_dropout** (`float`)-- Optional dropout probability after the projection and activation.
+ """
+
+ def __init__(self, config: XLMConfig):
+ super().__init__()
+
+ self.summary_type = getattr(config, "summary_type", "last")
+ if self.summary_type == "attn":
+ # We should use a standard multi-head attention module with absolute positional embedding for that.
+ # Cf. https://github.com/zihangdai/xlnet/blob/master/modeling.py#L253-L276
+ # We can probably just use the multi-head attention module of PyTorch >=1.1.0
+ raise NotImplementedError
+
+ self.summary = nn.Identity()
+ if hasattr(config, "summary_use_proj") and config.summary_use_proj:
+ if hasattr(config, "summary_proj_to_labels") and config.summary_proj_to_labels and config.num_labels > 0:
+ num_classes = config.num_labels
+ else:
+ num_classes = config.hidden_size
+ self.summary = nn.Linear(config.hidden_size, num_classes)
+
+ activation_string = getattr(config, "summary_activation", None)
+ self.activation: Callable = get_activation(activation_string) if activation_string else nn.Identity()
+
+ self.first_dropout = nn.Identity()
+ if hasattr(config, "summary_first_dropout") and config.summary_first_dropout > 0:
+ self.first_dropout = nn.Dropout(config.summary_first_dropout)
+
+ self.last_dropout = nn.Identity()
+ if hasattr(config, "summary_last_dropout") and config.summary_last_dropout > 0:
+ self.last_dropout = nn.Dropout(config.summary_last_dropout)
+
+ def forward(
+ self, hidden_states: torch.FloatTensor, cls_index: Optional[torch.LongTensor] = None
+ ) -> torch.FloatTensor:
+ """
+ Compute a single vector summary of a sequence hidden states.
+
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `[batch_size, seq_len, hidden_size]`):
+ The hidden states of the last layer.
+ cls_index (`torch.LongTensor` of shape `[batch_size]` or `[batch_size, ...]` where ... are optional leading dimensions of `hidden_states`, *optional*):
+ Used if `summary_type == "cls_index"` and takes the last token of the sequence as classification token.
+
+ Returns:
+ `torch.FloatTensor`: The summary of the sequence hidden states.
+ """
+ if self.summary_type == "last":
+ output = hidden_states[:, -1]
+ elif self.summary_type == "first":
+ output = hidden_states[:, 0]
+ elif self.summary_type == "mean":
+ output = hidden_states.mean(dim=1)
+ elif self.summary_type == "cls_index":
+ if cls_index is None:
+ cls_index = torch.full_like(
+ hidden_states[..., :1, :],
+ hidden_states.shape[-2] - 1,
+ dtype=torch.long,
+ )
+ else:
+ cls_index = cls_index.unsqueeze(-1).unsqueeze(-1)
+ cls_index = cls_index.expand((-1,) * (cls_index.dim() - 1) + (hidden_states.size(-1),))
+ # shape of cls_index: (bsz, XX, 1, hidden_size) where XX are optional leading dim of hidden_states
+ output = hidden_states.gather(-2, cls_index).squeeze(-2) # shape (bsz, XX, hidden_size)
+ elif self.summary_type == "attn":
+ raise NotImplementedError
+
+ output = self.first_dropout(output)
+ output = self.summary(output)
+ output = self.activation(output)
+ output = self.last_dropout(output)
+
+ return output
+
+
+class MultiHeadAttention(nn.Module):
+ def __init__(self, n_heads, dim, config, layer_idx: int = 0):
+ super().__init__()
+ self.layer_id = layer_idx
+ self.dim = dim
+ self.n_heads = n_heads
+ self.head_dim = dim // n_heads
+ self.dropout = config.attention_dropout
+ assert self.dim % self.n_heads == 0
+
+ self.q_lin = nn.Linear(dim, dim)
+ self.k_lin = nn.Linear(dim, dim)
+ self.v_lin = nn.Linear(dim, dim)
+ self.out_lin = nn.Linear(dim, dim)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ attention_head_size = self.dim // self.n_heads
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(heads, self.n_heads, attention_head_size, self.pruned_heads)
+ # Prune linear layers
+ self.q_lin = prune_linear_layer(self.q_lin, index)
+ self.k_lin = prune_linear_layer(self.k_lin, index)
+ self.v_lin = prune_linear_layer(self.v_lin, index)
+ self.out_lin = prune_linear_layer(self.out_lin, index, dim=1)
+ # Update hyper params
+ self.n_heads = self.n_heads - len(heads)
+ self.dim = attention_head_size * self.n_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(
+ self,
+ input,
+ mask,
+ kv=None,
+ cache=None,
+ head_mask=None,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ """
+ Self-attention (if kv is None) or attention over source sentence (provided by kv).
+ """
+ # Input is (bs, qlen, dim)
+ # Mask is (bs, klen) (non-causal) or (bs, klen, klen)
+ bs, qlen, dim = input.size()
+ is_cross_attention = kv is not None
+ mask_reshape = (bs, 1, qlen, -1) if mask.dim() == 3 else (bs, 1, 1, -1)
+
+ q = self.q_lin(input).view(bs, -1, self.n_heads, self.head_dim).transpose(1, 2)
+ if cache is not None:
+ if isinstance(cache, EncoderDecoderCache):
+ is_updated = cache.is_updated.get(self.layer_id)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = cache.cross_attention_cache
+ else:
+ curr_past_key_value = cache.self_attention_cache
+ else:
+ curr_past_key_value = cache
+
+ current_states = kv if is_cross_attention else input
+ if is_cross_attention and cache is not None and is_updated:
+ # reuse k,v, cross_attentions
+ k = curr_past_key_value.key_cache[self.layer_id]
+ v = curr_past_key_value.value_cache[self.layer_id]
+ else:
+ k = self.k_lin(current_states)
+ v = self.v_lin(current_states)
+ k = k.view(bs, -1, self.n_heads, self.head_dim).transpose(1, 2)
+ v = v.view(bs, -1, self.n_heads, self.head_dim).transpose(1, 2)
+
+ if cache is not None:
+ # save all key/value_states to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ k, v = curr_past_key_value.update(k, v, self.layer_id, {"cache_position": cache_position})
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ cache.is_updated[self.layer_id] = True
+
+ q = q / math.sqrt(self.head_dim) # (bs, n_heads, qlen, head_dim)
+ scores = torch.matmul(q, k.transpose(2, 3)) # (bs, n_heads, qlen, klen)
+ mask = (mask == 0).view(mask_reshape).expand_as(scores) # (bs, n_heads, qlen, klen)
+ scores.masked_fill_(mask, torch.finfo(scores.dtype).min) # (bs, n_heads, qlen, klen)
+
+ weights = nn.functional.softmax(scores.float(), dim=-1).type_as(scores) # (bs, n_heads, qlen, klen)
+ weights = nn.functional.dropout(weights, p=self.dropout, training=self.training) # (bs, n_heads, qlen, klen)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ weights = weights * head_mask
+
+ context = torch.matmul(weights, v) # (bs, n_heads, qlen, head_dim)
+ context = context.transpose(1, 2).contiguous().view(bs, -1, self.n_heads * self.head_dim)
+
+ outputs = (self.out_lin(context),)
+ if output_attentions:
+ outputs = outputs + (weights,)
+ return outputs
+
+
+class TransformerFFN(nn.Module):
+ def __init__(self, in_dim, dim_hidden, out_dim, config):
+ super().__init__()
+ self.dropout = config.dropout
+ self.lin1 = nn.Linear(in_dim, dim_hidden)
+ self.lin2 = nn.Linear(dim_hidden, out_dim)
+ self.act = gelu if config.gelu_activation else nn.functional.relu
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+
+ def forward(self, input):
+ return apply_chunking_to_forward(self.ff_chunk, self.chunk_size_feed_forward, self.seq_len_dim, input)
+
+ def ff_chunk(self, input):
+ x = self.lin1(input)
+ x = self.act(x)
+ x = self.lin2(x)
+ x = nn.functional.dropout(x, p=self.dropout, training=self.training)
+ return x
+
+
+@auto_docstring
+class XLMPreTrainedModel(PreTrainedModel):
+ config: XLMConfig
+ load_tf_weights = None
+ base_model_prefix = "transformer"
+
+ def __init__(self, *inputs, **kwargs):
+ super().__init__(*inputs, **kwargs)
+
+ @property
+ def dummy_inputs(self):
+ inputs_list = torch.tensor([[7, 6, 0, 0, 1], [1, 2, 3, 0, 0], [0, 0, 0, 4, 5]])
+ attns_list = torch.tensor([[1, 1, 0, 0, 1], [1, 1, 1, 0, 0], [1, 0, 0, 1, 1]])
+ if self.config.use_lang_emb and self.config.n_langs > 1:
+ langs_list = torch.tensor([[1, 1, 0, 0, 1], [1, 1, 1, 0, 0], [1, 0, 0, 1, 1]])
+ else:
+ langs_list = None
+ return {"input_ids": inputs_list, "attention_mask": attns_list, "langs": langs_list}
+
+ def _init_weights(self, module):
+ """Initialize the weights."""
+ if isinstance(module, nn.Embedding):
+ if self.config is not None and self.config.embed_init_std is not None:
+ nn.init.normal_(module.weight, mean=0, std=self.config.embed_init_std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ if isinstance(module, nn.Linear):
+ if self.config is not None and self.config.init_std is not None:
+ nn.init.normal_(module.weight, mean=0, std=self.config.init_std)
+ if module.bias is not None:
+ nn.init.constant_(module.bias, 0.0)
+ if isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ if isinstance(module, XLMModel) and self.config.sinusoidal_embeddings:
+ create_sinusoidal_embeddings(
+ self.config.max_position_embeddings, self.config.emb_dim, out=module.position_embeddings.weight
+ )
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Base class for outputs of question answering models using a `XLMSQuADHead`.
+ """
+)
+class XLMForQuestionAnsweringOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned if both `start_positions` and `end_positions` are provided):
+ Classification loss as the sum of start token, end token (and is_impossible if provided) classification
+ losses.
+ start_top_log_probs (`torch.FloatTensor` of shape `(batch_size, config.start_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the top config.start_n_top start token possibilities (beam-search).
+ start_top_index (`torch.LongTensor` of shape `(batch_size, config.start_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Indices for the top config.start_n_top start token possibilities (beam-search).
+ end_top_log_probs (`torch.FloatTensor` of shape `(batch_size, config.start_n_top * config.end_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the top `config.start_n_top * config.end_n_top` end token possibilities
+ (beam-search).
+ end_top_index (`torch.LongTensor` of shape `(batch_size, config.start_n_top * config.end_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Indices for the top `config.start_n_top * config.end_n_top` end token possibilities (beam-search).
+ cls_logits (`torch.FloatTensor` of shape `(batch_size,)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the `is_impossible` label of the answers.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ start_top_log_probs: Optional[torch.FloatTensor] = None
+ start_top_index: Optional[torch.LongTensor] = None
+ end_top_log_probs: Optional[torch.FloatTensor] = None
+ end_top_index: Optional[torch.LongTensor] = None
+ cls_logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@auto_docstring
+class XLMModel(XLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ # encoder / decoder, output layer
+ self.is_encoder = config.is_encoder
+ self.is_decoder = not config.is_encoder
+ if self.is_decoder:
+ raise NotImplementedError("Currently XLM can only be used as an encoder")
+ # self.with_output = with_output
+ self.causal = config.causal
+
+ # dictionary / languages
+ self.n_langs = config.n_langs
+ self.use_lang_emb = config.use_lang_emb
+ self.n_words = config.n_words
+ self.eos_index = config.eos_index
+ self.pad_index = config.pad_index
+ # self.dico = dico
+ # self.id2lang = config.id2lang
+ # self.lang2id = config.lang2id
+ # assert len(self.dico) == self.n_words
+ # assert len(self.id2lang) == len(self.lang2id) == self.n_langs
+
+ # model parameters
+ self.dim = config.emb_dim # 512 by default
+ self.hidden_dim = self.dim * 4 # 2048 by default
+ self.n_heads = config.n_heads # 8 by default
+ self.n_layers = config.n_layers
+ self.dropout = config.dropout
+ self.attention_dropout = config.attention_dropout
+ assert self.dim % self.n_heads == 0, "transformer dim must be a multiple of n_heads"
+
+ # embeddings
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, self.dim)
+ if config.n_langs > 1 and config.use_lang_emb:
+ self.lang_embeddings = nn.Embedding(self.n_langs, self.dim)
+ self.embeddings = nn.Embedding(self.n_words, self.dim, padding_idx=self.pad_index)
+ self.layer_norm_emb = nn.LayerNorm(self.dim, eps=config.layer_norm_eps)
+
+ # transformer layers
+ self.attentions = nn.ModuleList()
+ self.layer_norm1 = nn.ModuleList()
+ self.ffns = nn.ModuleList()
+ self.layer_norm2 = nn.ModuleList()
+ # if self.is_decoder:
+ # self.layer_norm15 = nn.ModuleList()
+ # self.encoder_attn = nn.ModuleList()
+
+ for i in range(self.n_layers):
+ self.attentions.append(MultiHeadAttention(self.n_heads, self.dim, config=config, layer_idx=i))
+ self.layer_norm1.append(nn.LayerNorm(self.dim, eps=config.layer_norm_eps))
+ # if self.is_decoder:
+ # self.layer_norm15.append(nn.LayerNorm(self.dim, eps=config.layer_norm_eps))
+ # self.encoder_attn.append(MultiHeadAttention(self.n_heads, self.dim, dropout=self.attention_dropout))
+ self.ffns.append(TransformerFFN(self.dim, self.hidden_dim, self.dim, config=config))
+ self.layer_norm2.append(nn.LayerNorm(self.dim, eps=config.layer_norm_eps))
+
+ if hasattr(config, "pruned_heads"):
+ pruned_heads = config.pruned_heads.copy().items()
+ config.pruned_heads = {}
+ for layer, heads in pruned_heads:
+ if self.attentions[int(layer)].n_heads == config.n_heads:
+ self.prune_heads({int(layer): list(map(int, heads))})
+
+ # Initialize weights and apply final processing
+ self.post_init()
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+
+ def get_input_embeddings(self):
+ return self.embeddings
+
+ def set_input_embeddings(self, new_embeddings):
+ self.embeddings = new_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.attentions[layer].prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ langs: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ lengths: Optional[torch.Tensor] = None,
+ cache: Optional[dict[str, torch.Tensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ **kwargs, # Dummy kwargs for now
+ ) -> Union[tuple, BaseModelOutput]:
+ r"""
+ langs (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ lengths (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, torch.FloatTensor]`, *optional*):
+ Instance of `EncoderDecoderCache` that contains precomputed KV states. Can be used to speed up sequential
+ decoding.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None:
+ bs, slen = input_ids.size()
+ else:
+ bs, slen = inputs_embeds.size()[:-1]
+
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if cache is None:
+ cache = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+
+ if isinstance(cache, tuple):
+ cache = EncoderDecoderCache.from_legacy_cache(cache)
+
+ if lengths is None:
+ if input_ids is not None:
+ lengths = (input_ids != self.pad_index).sum(dim=1).long()
+ else:
+ lengths = torch.tensor([slen] * bs, device=device)
+
+ # check inputs
+ assert lengths.size(0) == bs
+ assert lengths.max().item() <= slen
+
+ # generate masks
+ mask, attn_mask = get_masks(slen, lengths, self.causal, padding_mask=attention_mask)
+
+ # position_ids
+ if position_ids is None:
+ position_ids = self.position_ids[:, :slen]
+ else:
+ assert position_ids.size() == (bs, slen) # (slen, bs)
+
+ # langs
+ if langs is not None:
+ assert langs.size() == (bs, slen) # (slen, bs)
+
+ # Prepare head mask if needed
+ head_mask = self.get_head_mask(head_mask, self.config.n_layers)
+
+ # do not recompute cached elements
+ if cache is not None and input_ids is not None:
+ _slen = slen - cache.get_seq_length()
+ input_ids = input_ids[:, -_slen:]
+ position_ids = position_ids[:, -_slen:]
+ if langs is not None:
+ langs = langs[:, -_slen:]
+ mask = mask[:, -_slen:]
+ attn_mask = attn_mask[:, -_slen:]
+
+ # embeddings
+ if inputs_embeds is None:
+ inputs_embeds = self.embeddings(input_ids)
+
+ tensor = inputs_embeds + self.position_embeddings(position_ids).expand_as(inputs_embeds)
+ if langs is not None and self.use_lang_emb and self.n_langs > 1:
+ tensor = tensor + self.lang_embeddings(langs)
+ if token_type_ids is not None:
+ tensor = tensor + self.embeddings(token_type_ids)
+ tensor = self.layer_norm_emb(tensor)
+ tensor = nn.functional.dropout(tensor, p=self.dropout, training=self.training)
+ tensor *= mask.unsqueeze(-1).to(tensor.dtype)
+
+ # transformer layers
+ hidden_states = () if output_hidden_states else None
+ attentions = () if output_attentions else None
+ for i in range(self.n_layers):
+ if output_hidden_states:
+ hidden_states = hidden_states + (tensor,)
+
+ # self attention
+ attn_outputs = self.attentions[i](
+ tensor,
+ attn_mask,
+ cache=cache,
+ head_mask=head_mask[i],
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ attn = attn_outputs[0]
+ if output_attentions:
+ attentions = attentions + (attn_outputs[1],)
+ attn = nn.functional.dropout(attn, p=self.dropout, training=self.training)
+ tensor = tensor + attn
+ tensor = self.layer_norm1[i](tensor)
+
+ # FFN
+ tensor = tensor + self.ffns[i](tensor)
+ tensor = self.layer_norm2[i](tensor)
+ tensor *= mask.unsqueeze(-1).to(tensor.dtype)
+
+ # Add last hidden state
+ if output_hidden_states:
+ hidden_states = hidden_states + (tensor,)
+
+ if not return_dict:
+ return tuple(v for v in [tensor, hidden_states, attentions] if v is not None)
+ return BaseModelOutput(last_hidden_state=tensor, hidden_states=hidden_states, attentions=attentions)
+
+
+class XLMPredLayer(nn.Module):
+ """
+ Prediction layer (cross_entropy or adaptive_softmax).
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.asm = config.asm
+ self.n_words = config.n_words
+ self.pad_index = config.pad_index
+ dim = config.emb_dim
+
+ if config.asm is False:
+ self.proj = nn.Linear(dim, config.n_words, bias=True)
+ else:
+ self.proj = nn.AdaptiveLogSoftmaxWithLoss(
+ in_features=dim,
+ n_classes=config.n_words,
+ cutoffs=config.asm_cutoffs,
+ div_value=config.asm_div_value,
+ head_bias=True, # default is False
+ )
+
+ def forward(self, x, y=None):
+ """Compute the loss, and optionally the scores."""
+ outputs = ()
+ if self.asm is False:
+ scores = self.proj(x)
+ outputs = (scores,) + outputs
+ if y is not None:
+ loss = nn.functional.cross_entropy(scores.view(-1, self.n_words), y.view(-1), reduction="mean")
+ outputs = (loss,) + outputs
+ else:
+ scores = self.proj.log_prob(x)
+ outputs = (scores,) + outputs
+ if y is not None:
+ _, loss = self.proj(x, y)
+ outputs = (loss,) + outputs
+
+ return outputs
+
+
+@auto_docstring(
+ custom_intro="""
+ The XLM Model transformer with a language modeling head on top (linear layer with weights tied to the input
+ embeddings).
+ """
+)
+class XLMWithLMHeadModel(XLMPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["pred_layer.proj.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.transformer = XLMModel(config)
+ self.pred_layer = XLMPredLayer(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.pred_layer.proj
+
+ def set_output_embeddings(self, new_embeddings):
+ self.pred_layer.proj = new_embeddings
+
+ def prepare_inputs_for_generation(self, input_ids, **kwargs):
+ # Overwritten -- this model uses config options to prepare inputs
+
+ mask_token_id = self.config.mask_token_id
+ lang_id = self.config.lang_id
+
+ effective_batch_size = input_ids.shape[0]
+ mask_token = torch.full((effective_batch_size, 1), mask_token_id, dtype=torch.long, device=input_ids.device)
+ input_ids = torch.cat([input_ids, mask_token], dim=1)
+ if lang_id is not None:
+ langs = torch.full_like(input_ids, lang_id)
+ else:
+ langs = None
+ return {"input_ids": input_ids, "langs": langs}
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ langs: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ lengths: Optional[torch.Tensor] = None,
+ cache: Optional[dict[str, torch.Tensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> Union[tuple, MaskedLMOutput]:
+ r"""
+ langs (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ lengths (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, torch.FloatTensor]`, *optional*):
+ Instance of `EncoderDecoderCache` that contains precomputed KV states. Can be used to speed up sequential
+ decoding.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for language modeling. Note that the labels **are shifted** inside the model, i.e. you can set
+ `labels = input_ids` Indices are selected in `[-100, 0, ..., config.vocab_size]` All labels set to `-100`
+ are ignored (masked), the loss is only computed for labels in `[0, ..., config.vocab_size]`
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ **kwargs,
+ )
+
+ output = transformer_outputs[0]
+ outputs = self.pred_layer(output, labels) # (loss, logits) or (logits,) depending on if labels are provided.
+
+ if not return_dict:
+ return outputs + transformer_outputs[1:]
+
+ return MaskedLMOutput(
+ loss=outputs[0] if labels is not None else None,
+ logits=outputs[0] if labels is None else outputs[1],
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ XLM Model with a sequence classification/regression head on top (a linear layer on top of the pooled output) e.g.
+ for GLUE tasks.
+ """
+)
+class XLMForSequenceClassification(XLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.config = config
+
+ self.transformer = XLMModel(config)
+ self.sequence_summary = XLMSequenceSummary(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ langs: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ lengths: Optional[torch.Tensor] = None,
+ cache: Optional[dict[str, torch.Tensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ langs (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ lengths (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, torch.FloatTensor]`, *optional*):
+ Instance of `EncoderDecoderCache` that contains precomputed KV states. Can be used to speed up sequential
+ decoding.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ output = transformer_outputs[0]
+ logits = self.sequence_summary(output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ XLM Model with a span classification head on top for extractive question-answering tasks like SQuAD (a linear
+ layers on top of the hidden-states output to compute `span start logits` and `span end logits`).
+ """
+)
+class XLMForQuestionAnsweringSimple(XLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.transformer = XLMModel(config)
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ langs: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ lengths: Optional[torch.Tensor] = None,
+ cache: Optional[dict[str, torch.Tensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.Tensor] = None,
+ end_positions: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, QuestionAnsweringModelOutput]:
+ r"""
+ langs (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ lengths (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, torch.FloatTensor]`, *optional*):
+ Instance of `EncoderDecoderCache` that contains precomputed KV states. Can be used to speed up sequential
+ decoding.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = transformer_outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + transformer_outputs[1:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return QuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLMForQuestionAnswering(XLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.transformer = XLMModel(config)
+ self.qa_outputs = XLMSQuADHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ langs: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ lengths: Optional[torch.Tensor] = None,
+ cache: Optional[dict[str, torch.Tensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.Tensor] = None,
+ end_positions: Optional[torch.Tensor] = None,
+ is_impossible: Optional[torch.Tensor] = None,
+ cls_index: Optional[torch.Tensor] = None,
+ p_mask: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, XLMForQuestionAnsweringOutput]:
+ r"""
+ langs (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ lengths (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, torch.FloatTensor]`, *optional*):
+ Instance of `EncoderDecoderCache` that contains precomputed KV states. Can be used to speed up sequential
+ decoding.
+ is_impossible (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels whether a question has an answer or no answer (SQuAD 2.0)
+ cls_index (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the classification token to use as input for computing plausibility of the
+ answer.
+ p_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Optional mask of tokens which can't be in answers (e.g. [CLS], [PAD], ...). 1.0 means token should be
+ masked. 0.0 mean token is not masked.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, XLMForQuestionAnswering
+ >>> import torch
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("FacebookAI/xlm-mlm-en-2048")
+ >>> model = XLMForQuestionAnswering.from_pretrained("FacebookAI/xlm-mlm-en-2048")
+
+ >>> input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(
+ ... 0
+ ... ) # Batch size 1
+ >>> start_positions = torch.tensor([1])
+ >>> end_positions = torch.tensor([3])
+
+ >>> outputs = model(input_ids, start_positions=start_positions, end_positions=end_positions)
+ >>> loss = outputs.loss
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ output = transformer_outputs[0]
+
+ outputs = self.qa_outputs(
+ output,
+ start_positions=start_positions,
+ end_positions=end_positions,
+ cls_index=cls_index,
+ is_impossible=is_impossible,
+ p_mask=p_mask,
+ return_dict=return_dict,
+ )
+
+ if not return_dict:
+ return outputs + transformer_outputs[1:]
+
+ return XLMForQuestionAnsweringOutput(
+ loss=outputs.loss,
+ start_top_log_probs=outputs.start_top_log_probs,
+ start_top_index=outputs.start_top_index,
+ end_top_log_probs=outputs.end_top_log_probs,
+ end_top_index=outputs.end_top_index,
+ cls_logits=outputs.cls_logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLMForTokenClassification(XLMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.transformer = XLMModel(config)
+ self.dropout = nn.Dropout(config.dropout)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ langs: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ lengths: Optional[torch.Tensor] = None,
+ cache: Optional[dict[str, torch.Tensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ langs (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ lengths (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, torch.FloatTensor]`, *optional*):
+ Instance of `EncoderDecoderCache` that contains precomputed KV states. Can be used to speed up sequential
+ decoding.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ sequence_output = self.dropout(sequence_output)
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLMForMultipleChoice(XLMPreTrainedModel):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.transformer = XLMModel(config)
+ self.sequence_summary = XLMSequenceSummary(config)
+ self.logits_proj = nn.Linear(config.num_labels, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ langs: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ lengths: Optional[torch.Tensor] = None,
+ cache: Optional[dict[str, torch.Tensor]] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, MultipleChoiceModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ langs (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ A parallel sequence of tokens to be used to indicate the language of each token in the input. Indices are
+ languages ids which can be obtained from the language names by using two conversion mappings provided in
+ the configuration of the model (only provided for multilingual models). More precisely, the *language name
+ to language id* mapping is in `model.config.lang2id` (which is a dictionary string to int) and the
+ *language id to language name* mapping is in `model.config.id2lang` (dictionary int to string).
+
+ See usage examples detailed in the [multilingual documentation](../multilingual).
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ lengths (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Length of each sentence that can be used to avoid performing attention on padding token indices. You can
+ also use *attention_mask* for the same result (see above), kept here for compatibility. Indices selected in
+ `[0, ..., input_ids.size(-1)]`.
+ cache (`dict[str, torch.FloatTensor]`, *optional*):
+ Instance of `EncoderDecoderCache` that contains precomputed KV states. Can be used to speed up sequential
+ decoding.
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See
+ `input_ids` above)
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None
+ langs = langs.view(-1, langs.size(-1)) if langs is not None else None
+ inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ if lengths is not None:
+ logger.warning(
+ "The `lengths` parameter cannot be used with the XLM multiple choice models. Please use the "
+ "attention mask instead."
+ )
+ lengths = None
+
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ langs=langs,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ lengths=lengths,
+ cache=cache,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ output = transformer_outputs[0]
+ logits = self.sequence_summary(output)
+ logits = self.logits_proj(logits)
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels)
+
+ if not return_dict:
+ output = (reshaped_logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return MultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+__all__ = [
+ "XLMForMultipleChoice",
+ "XLMForQuestionAnswering",
+ "XLMForQuestionAnsweringSimple",
+ "XLMForSequenceClassification",
+ "XLMForTokenClassification",
+ "XLMModel",
+ "XLMPreTrainedModel",
+ "XLMWithLMHeadModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/tokenization_xlm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/tokenization_xlm.py
new file mode 100644
index 0000000000000000000000000000000000000000..14d8aae2764b71b23b2a88374262cbd8d360ceb8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm/tokenization_xlm.py
@@ -0,0 +1,577 @@
+# coding=utf-8
+# Copyright 2019 The Open AI Team Authors and The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for XLM."""
+
+import json
+import os
+import re
+import sys
+import unicodedata
+from typing import Optional
+
+from ...tokenization_utils import PreTrainedTokenizer
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {
+ "vocab_file": "vocab.json",
+ "merges_file": "merges.txt",
+}
+
+
+def get_pairs(word):
+ """
+ Return set of symbol pairs in a word. word is represented as tuple of symbols (symbols being variable-length
+ strings)
+ """
+ pairs = set()
+ prev_char = word[0]
+ for char in word[1:]:
+ pairs.add((prev_char, char))
+ prev_char = char
+ return pairs
+
+
+def lowercase_and_remove_accent(text):
+ """
+ Lowercase and strips accents from a piece of text based on
+ https://github.com/facebookresearch/XLM/blob/master/tools/lowercase_and_remove_accent.py
+ """
+ text = " ".join(text)
+ text = text.lower()
+ text = unicodedata.normalize("NFD", text)
+ output = []
+ for char in text:
+ cat = unicodedata.category(char)
+ if cat == "Mn":
+ continue
+ output.append(char)
+ return "".join(output).lower().split(" ")
+
+
+def replace_unicode_punct(text):
+ """
+ Port of https://github.com/moses-smt/mosesdecoder/blob/master/scripts/tokenizer/replace-unicode-punctuation.perl
+ """
+ text = text.replace(",", ",")
+ text = re.sub(r"。\s*", ". ", text)
+ text = text.replace("、", ",")
+ text = text.replace("”", '"')
+ text = text.replace("“", '"')
+ text = text.replace("∶", ":")
+ text = text.replace(":", ":")
+ text = text.replace("?", "?")
+ text = text.replace("《", '"')
+ text = text.replace("》", '"')
+ text = text.replace(")", ")")
+ text = text.replace("!", "!")
+ text = text.replace("(", "(")
+ text = text.replace(";", ";")
+ text = text.replace("1", "1")
+ text = text.replace("」", '"')
+ text = text.replace("「", '"')
+ text = text.replace("0", "0")
+ text = text.replace("3", "3")
+ text = text.replace("2", "2")
+ text = text.replace("5", "5")
+ text = text.replace("6", "6")
+ text = text.replace("9", "9")
+ text = text.replace("7", "7")
+ text = text.replace("8", "8")
+ text = text.replace("4", "4")
+ text = re.sub(r".\s*", ". ", text)
+ text = text.replace("~", "~")
+ text = text.replace("’", "'")
+ text = text.replace("…", "...")
+ text = text.replace("━", "-")
+ text = text.replace("〈", "<")
+ text = text.replace("〉", ">")
+ text = text.replace("【", "[")
+ text = text.replace("】", "]")
+ text = text.replace("%", "%")
+ return text
+
+
+def remove_non_printing_char(text):
+ """
+ Port of https://github.com/moses-smt/mosesdecoder/blob/master/scripts/tokenizer/remove-non-printing-char.perl
+ """
+ output = []
+ for char in text:
+ cat = unicodedata.category(char)
+ if cat.startswith("C"):
+ continue
+ output.append(char)
+ return "".join(output)
+
+
+def romanian_preprocessing(text):
+ """Sennrich's WMT16 scripts for Romanian preprocessing, used by model `FacebookAI/xlm-mlm-enro-1024`"""
+ # https://github.com/rsennrich/wmt16-scripts/blob/master/preprocess/normalise-romanian.py
+ text = text.replace("\u015e", "\u0218").replace("\u015f", "\u0219")
+ text = text.replace("\u0162", "\u021a").replace("\u0163", "\u021b")
+ # https://github.com/rsennrich/wmt16-scripts/blob/master/preprocess/remove-diacritics.py
+ text = text.replace("\u0218", "S").replace("\u0219", "s") # s-comma
+ text = text.replace("\u021a", "T").replace("\u021b", "t") # t-comma
+ text = text.replace("\u0102", "A").replace("\u0103", "a")
+ text = text.replace("\u00c2", "A").replace("\u00e2", "a")
+ text = text.replace("\u00ce", "I").replace("\u00ee", "i")
+ return text
+
+
+class XLMTokenizer(PreTrainedTokenizer):
+ """
+ Construct an XLM tokenizer. Based on Byte-Pair Encoding. The tokenization process is the following:
+
+ - Moses preprocessing and tokenization for most supported languages.
+ - Language specific tokenization for Chinese (Jieba), Japanese (KyTea) and Thai (PyThaiNLP).
+ - Optionally lowercases and normalizes all inputs text.
+ - The arguments `special_tokens` and the function `set_special_tokens`, can be used to add additional symbols (like
+ "__classify__") to a vocabulary.
+ - The `lang2id` attribute maps the languages supported by the model with their IDs if provided (automatically set
+ for pretrained vocabularies).
+ - The `id2lang` attributes does reverse mapping if provided (automatically set for pretrained vocabularies).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ Vocabulary file.
+ merges_file (`str`):
+ Merges file.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the beginning of
+ sequence. The token used is the `cls_token`.
+
+
+
+ sep_token (`str`, *optional*, defaults to `" "`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `""`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `""`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ additional_special_tokens (`List[str]`, *optional*, defaults to `['', '', '', '', '', '', '', '', '', '']`):
+ List of additional special tokens.
+ lang2id (`Dict[str, int]`, *optional*):
+ Dictionary mapping languages string identifiers to their IDs.
+ id2lang (`Dict[int, str]`, *optional*):
+ Dictionary mapping language IDs to their string identifiers.
+ do_lowercase_and_remove_accent (`bool`, *optional*, defaults to `True`):
+ Whether to lowercase and remove accents when tokenizing.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+
+ def __init__(
+ self,
+ vocab_file,
+ merges_file,
+ unk_token="",
+ bos_token="",
+ sep_token=" ",
+ pad_token="",
+ cls_token="",
+ mask_token="",
+ additional_special_tokens=[
+ "",
+ "",
+ "",
+ "",
+ "",
+ "",
+ "",
+ "",
+ "",
+ "",
+ ],
+ lang2id=None,
+ id2lang=None,
+ do_lowercase_and_remove_accent=True,
+ **kwargs,
+ ):
+ try:
+ import sacremoses
+ except ImportError:
+ raise ImportError(
+ "You need to install sacremoses to use XLMTokenizer. "
+ "See https://pypi.org/project/sacremoses/ for installation."
+ )
+
+ self.sm = sacremoses
+
+ # cache of sm.MosesPunctNormalizer instance
+ self.cache_moses_punct_normalizer = {}
+ # cache of sm.MosesTokenizer instance
+ self.cache_moses_tokenizer = {}
+ self.lang_with_custom_tokenizer = {"zh", "th", "ja"}
+ # True for current supported model (v1.2.0), False for XLM-17 & 100
+ self.do_lowercase_and_remove_accent = do_lowercase_and_remove_accent
+ self.lang2id = lang2id
+ self.id2lang = id2lang
+ if lang2id is not None and id2lang is not None:
+ assert len(lang2id) == len(id2lang)
+
+ self.ja_word_tokenizer = None
+ self.zh_word_tokenizer = None
+
+ with open(vocab_file, encoding="utf-8") as vocab_handle:
+ self.encoder = json.load(vocab_handle)
+ self.decoder = {v: k for k, v in self.encoder.items()}
+ with open(merges_file, encoding="utf-8") as merges_handle:
+ merges = merges_handle.read().split("\n")[:-1]
+ merges = [tuple(merge.split()[:2]) for merge in merges]
+ self.bpe_ranks = dict(zip(merges, range(len(merges))))
+ self.cache = {}
+ super().__init__(
+ unk_token=unk_token,
+ bos_token=bos_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ additional_special_tokens=additional_special_tokens,
+ lang2id=lang2id,
+ id2lang=id2lang,
+ do_lowercase_and_remove_accent=do_lowercase_and_remove_accent,
+ **kwargs,
+ )
+
+ @property
+ def do_lower_case(self):
+ return self.do_lowercase_and_remove_accent
+
+ def moses_punct_norm(self, text, lang):
+ if lang not in self.cache_moses_punct_normalizer:
+ punct_normalizer = self.sm.MosesPunctNormalizer(lang=lang)
+ self.cache_moses_punct_normalizer[lang] = punct_normalizer
+ else:
+ punct_normalizer = self.cache_moses_punct_normalizer[lang]
+ return punct_normalizer.normalize(text)
+
+ def moses_tokenize(self, text, lang):
+ if lang not in self.cache_moses_tokenizer:
+ moses_tokenizer = self.sm.MosesTokenizer(lang=lang)
+ self.cache_moses_tokenizer[lang] = moses_tokenizer
+ else:
+ moses_tokenizer = self.cache_moses_tokenizer[lang]
+ return moses_tokenizer.tokenize(text, return_str=False, escape=False)
+
+ def moses_pipeline(self, text, lang):
+ text = replace_unicode_punct(text)
+ text = self.moses_punct_norm(text, lang)
+ text = remove_non_printing_char(text)
+ return text
+
+ def ja_tokenize(self, text):
+ if self.ja_word_tokenizer is None:
+ try:
+ import Mykytea
+
+ self.ja_word_tokenizer = Mykytea.Mykytea(
+ f"-model {os.path.expanduser('~')}/local/share/kytea/model.bin"
+ )
+ except (AttributeError, ImportError):
+ logger.error(
+ "Make sure you install KyTea (https://github.com/neubig/kytea) and it's python wrapper"
+ " (https://github.com/chezou/Mykytea-python) with the following steps"
+ )
+ logger.error("1. git clone git@github.com:neubig/kytea.git && cd kytea")
+ logger.error("2. autoreconf -i")
+ logger.error("3. ./configure --prefix=$HOME/local")
+ logger.error("4. make && make install")
+ logger.error("5. pip install kytea")
+ raise
+ return list(self.ja_word_tokenizer.getWS(text))
+
+ @property
+ def vocab_size(self):
+ return len(self.encoder)
+
+ def get_vocab(self):
+ return dict(self.encoder, **self.added_tokens_encoder)
+
+ def bpe(self, token):
+ word = tuple(token[:-1]) + (token[-1] + "",)
+ if token in self.cache:
+ return self.cache[token]
+ pairs = get_pairs(word)
+
+ if not pairs:
+ return token + ""
+
+ while True:
+ bigram = min(pairs, key=lambda pair: self.bpe_ranks.get(pair, float("inf")))
+ if bigram not in self.bpe_ranks:
+ break
+ first, second = bigram
+ new_word = []
+ i = 0
+ while i < len(word):
+ try:
+ j = word.index(first, i)
+ except ValueError:
+ new_word.extend(word[i:])
+ break
+ else:
+ new_word.extend(word[i:j])
+ i = j
+
+ if word[i] == first and i < len(word) - 1 and word[i + 1] == second:
+ new_word.append(first + second)
+ i += 2
+ else:
+ new_word.append(word[i])
+ i += 1
+ new_word = tuple(new_word)
+ word = new_word
+ if len(word) == 1:
+ break
+ else:
+ pairs = get_pairs(word)
+ word = " ".join(word)
+ if word == "\n ":
+ word = "\n"
+ self.cache[token] = word
+ return word
+
+ def _tokenize(self, text, lang="en", bypass_tokenizer=False):
+ """
+ Tokenize a string given language code. For Chinese, Japanese and Thai, we use a language specific tokenizer.
+ Otherwise, we use Moses.
+
+ Details of tokenization:
+
+ - [sacremoses](https://github.com/alvations/sacremoses): port of Moses
+ - Install with `pip install sacremoses`
+ - [pythainlp](https://github.com/PyThaiNLP/pythainlp): Thai tokenizer
+ - Install with `pip install pythainlp`
+ - [kytea](https://github.com/chezou/Mykytea-python): Japanese tokenizer, wrapper of
+ [KyTea](https://github.com/neubig/kytea)
+ - Install with the following steps:
+
+ ::
+
+ git clone git@github.com:neubig/kytea.git && cd kytea autoreconf -i ./configure --prefix=$HOME/local
+ make && make install pip install kytea
+
+ - [jieba](https://github.com/fxsjy/jieba): Chinese tokenizer (*)
+ - Install with `pip install jieba`
+
+ (*) The original XLM used [Stanford
+ Segmenter](https://nlp.stanford.edu/software/stanford-segmenter-2018-10-16.zip). However, the wrapper
+ (`nltk.tokenize.stanford_segmenter`) is slow due to JVM overhead, and it will be deprecated. Jieba is a lot
+ faster and pip-installable. Note there is some mismatch with the Stanford Segmenter. It should be fine if you
+ fine-tune the model with Chinese supervisionself. If you want the same exact behaviour, use the original XLM
+ [preprocessing script](https://github.com/facebookresearch/XLM/tree/master/tools) to tokenize the sentence
+ externally, and set `bypass_tokenizer=True` to bypass the tokenizer.
+
+ Args:
+ - lang: ISO language code (default = 'en') (string). Languages should belong of the model supported
+ languages. However, we don't enforce it.
+ - bypass_tokenizer: Allow users to preprocess and tokenize the sentences externally (default = False)
+ (bool). If True, we only apply BPE.
+
+ Returns:
+ List of tokens.
+ """
+ if lang and self.lang2id and lang not in self.lang2id:
+ logger.error(
+ "Supplied language code not found in lang2id mapping. Please check that your language is supported by"
+ " the loaded pretrained model."
+ )
+ if bypass_tokenizer:
+ text = text.split()
+ elif lang not in self.lang_with_custom_tokenizer:
+ text = self.moses_pipeline(text, lang=lang)
+ # TODO: make sure we are using `FacebookAI/xlm-mlm-enro-1024`, since XLM-100 doesn't have this step
+ if lang == "ro":
+ text = romanian_preprocessing(text)
+ text = self.moses_tokenize(text, lang=lang)
+ elif lang == "th":
+ text = self.moses_pipeline(text, lang=lang)
+ try:
+ if "pythainlp" not in sys.modules:
+ from pythainlp.tokenize import word_tokenize as th_word_tokenize
+ else:
+ th_word_tokenize = sys.modules["pythainlp"].word_tokenize
+ except (AttributeError, ImportError):
+ logger.error(
+ "Make sure you install PyThaiNLP (https://github.com/PyThaiNLP/pythainlp) with the following steps"
+ )
+ logger.error("1. pip install pythainlp")
+ raise
+ text = th_word_tokenize(text)
+ elif lang == "zh":
+ try:
+ if "jieba" not in sys.modules:
+ import jieba
+ else:
+ jieba = sys.modules["jieba"]
+ except (AttributeError, ImportError):
+ logger.error("Make sure you install Jieba (https://github.com/fxsjy/jieba) with the following steps")
+ logger.error("1. pip install jieba")
+ raise
+ text = " ".join(jieba.cut(text))
+ text = self.moses_pipeline(text, lang=lang)
+ text = text.split()
+ elif lang == "ja":
+ text = self.moses_pipeline(text, lang=lang)
+ text = self.ja_tokenize(text)
+ else:
+ raise ValueError("It should not reach here")
+
+ if self.do_lowercase_and_remove_accent and not bypass_tokenizer:
+ text = lowercase_and_remove_accent(text)
+
+ split_tokens = []
+ for token in text:
+ if token:
+ split_tokens.extend(list(self.bpe(token).split(" ")))
+
+ return split_tokens
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.encoder.get(token, self.encoder.get(self.unk_token))
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ return self.decoder.get(index, self.unk_token)
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (string) in a single string."""
+ out_string = "".join(tokens).replace("", " ").strip()
+ return out_string
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLM sequence has the following format:
+
+ - single sequence: ` X `
+ - pair of sequences: ` A B `
+
+ Args:
+ token_ids_0 (`List[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`List[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `List[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+
+ """
+ bos = [self.bos_token_id]
+ sep = [self.sep_token_id]
+
+ if token_ids_1 is None:
+ return bos + token_ids_0 + sep
+ return bos + token_ids_0 + sep + token_ids_1 + sep
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`List[int]`):
+ List of IDs.
+ token_ids_1 (`List[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `List[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ if token_ids_1 is not None:
+ return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
+ return [1] + ([0] * len(token_ids_0)) + [1]
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+ merge_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["merges_file"]
+ )
+
+ with open(vocab_file, "w", encoding="utf-8") as f:
+ f.write(json.dumps(self.encoder, indent=2, sort_keys=True, ensure_ascii=False) + "\n")
+
+ index = 0
+ with open(merge_file, "w", encoding="utf-8") as writer:
+ for bpe_tokens, token_index in sorted(self.bpe_ranks.items(), key=lambda kv: kv[1]):
+ if index != token_index:
+ logger.warning(
+ f"Saving vocabulary to {merge_file}: BPE merge indices are not consecutive."
+ " Please check that the tokenizer is not corrupted!"
+ )
+ index = token_index
+ writer.write(" ".join(bpe_tokens) + "\n")
+ index += 1
+
+ return vocab_file, merge_file
+
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sm"] = None
+ return state
+
+ def __setstate__(self, d):
+ self.__dict__ = d
+
+ try:
+ import sacremoses
+ except ImportError:
+ raise ImportError(
+ "You need to install sacremoses to use XLMTokenizer. "
+ "See https://pypi.org/project/sacremoses/ for installation."
+ )
+
+ self.sm = sacremoses
+
+
+__all__ = ["XLMTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..0e684c6c9b2c2c261fb4e6ad6998daa9bea6191e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/__init__.py
@@ -0,0 +1,31 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_xlm_roberta import *
+ from .modeling_flax_xlm_roberta import *
+ from .modeling_tf_xlm_roberta import *
+ from .modeling_xlm_roberta import *
+ from .tokenization_xlm_roberta import *
+ from .tokenization_xlm_roberta_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/configuration_xlm_roberta.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/configuration_xlm_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..97d6245cb1d7ea772a3606ca5c8d981f8f8ffdf7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/configuration_xlm_roberta.py
@@ -0,0 +1,157 @@
+# coding=utf-8
+# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""XLM-RoBERTa configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XLMRobertaConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`XLMRobertaModel`] or a [`TFXLMRobertaModel`]. It
+ is used to instantiate a XLM-RoBERTa model according to the specified arguments, defining the model architecture.
+ Instantiating a configuration with the defaults will yield a similar configuration to that of the XLMRoBERTa
+ [FacebookAI/xlm-roberta-base](https://huggingface.co/FacebookAI/xlm-roberta-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the XLM-RoBERTa model. Defines the number of different tokens that can be represented by
+ the `inputs_ids` passed when calling [`XLMRobertaModel`] or [`TFXLMRobertaModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the `token_type_ids` passed when calling [`XLMRobertaModel`] or
+ [`TFXLMRobertaModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ position_embedding_type (`str`, *optional*, defaults to `"absolute"`):
+ Type of position embedding. Choose one of `"absolute"`, `"relative_key"`, `"relative_key_query"`. For
+ positional embeddings use `"absolute"`. For more information on `"relative_key"`, please refer to
+ [Self-Attention with Relative Position Representations (Shaw et al.)](https://huggingface.co/papers/1803.02155).
+ For more information on `"relative_key_query"`, please refer to *Method 4* in [Improve Transformer Models
+ with Better Relative Position Embeddings (Huang et al.)](https://huggingface.co/papers/2009.13658).
+ is_decoder (`bool`, *optional*, defaults to `False`):
+ Whether the model is used as a decoder or not. If `False`, the model is used as an encoder.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ classifier_dropout (`float`, *optional*):
+ The dropout ratio for the classification head.
+
+ Examples:
+
+ ```python
+ >>> from transformers import XLMRobertaConfig, XLMRobertaModel
+
+ >>> # Initializing a XLM-RoBERTa FacebookAI/xlm-roberta-base style configuration
+ >>> configuration = XLMRobertaConfig()
+
+ >>> # Initializing a model (with random weights) from the FacebookAI/xlm-roberta-base style configuration
+ >>> model = XLMRobertaModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xlm-roberta"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=512,
+ type_vocab_size=2,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ position_embedding_type="absolute",
+ use_cache=True,
+ classifier_dropout=None,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.hidden_act = hidden_act
+ self.intermediate_size = intermediate_size
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.max_position_embeddings = max_position_embeddings
+ self.type_vocab_size = type_vocab_size
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.position_embedding_type = position_embedding_type
+ self.use_cache = use_cache
+ self.classifier_dropout = classifier_dropout
+
+
+# Copied from transformers.models.roberta.configuration_roberta.RobertaOnnxConfig with Roberta->XLMRoberta
+class XLMRobertaOnnxConfig(OnnxConfig):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ if self.task == "multiple-choice":
+ dynamic_axis = {0: "batch", 1: "choice", 2: "sequence"}
+ else:
+ dynamic_axis = {0: "batch", 1: "sequence"}
+ return OrderedDict(
+ [
+ ("input_ids", dynamic_axis),
+ ("attention_mask", dynamic_axis),
+ ]
+ )
+
+
+__all__ = ["XLMRobertaConfig", "XLMRobertaOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_flax_xlm_roberta.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_flax_xlm_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..bdbc06620a1bf85c0a752eb6f64a8a6e351afbf3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_flax_xlm_roberta.py
@@ -0,0 +1,1511 @@
+# coding=utf-8
+# Copyright 2022 Facebook AI Research and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Flax XLM-RoBERTa model."""
+
+from typing import Callable, Optional
+
+import flax.linen as nn
+import jax
+import jax.numpy as jnp
+import numpy as np
+from flax.core.frozen_dict import FrozenDict, freeze, unfreeze
+from flax.linen import combine_masks, make_causal_mask
+from flax.linen import partitioning as nn_partitioning
+from flax.linen.attention import dot_product_attention_weights
+from flax.traverse_util import flatten_dict, unflatten_dict
+from jax import lax
+
+from ...modeling_flax_outputs import (
+ FlaxBaseModelOutputWithPastAndCrossAttentions,
+ FlaxBaseModelOutputWithPooling,
+ FlaxBaseModelOutputWithPoolingAndCrossAttentions,
+ FlaxCausalLMOutputWithCrossAttentions,
+ FlaxMaskedLMOutput,
+ FlaxMultipleChoiceModelOutput,
+ FlaxQuestionAnsweringModelOutput,
+ FlaxSequenceClassifierOutput,
+ FlaxTokenClassifierOutput,
+)
+from ...modeling_flax_utils import ACT2FN, FlaxPreTrainedModel, append_call_sample_docstring, overwrite_call_docstring
+from ...utils import add_start_docstrings, add_start_docstrings_to_model_forward, logging
+from .configuration_xlm_roberta import XLMRobertaConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "FacebookAI/xlm-roberta-base"
+_CONFIG_FOR_DOC = "XLMRobertaConfig"
+
+remat = nn_partitioning.remat
+
+
+# Copied from transformers.models.roberta.modeling_flax_roberta.create_position_ids_from_input_ids
+def create_position_ids_from_input_ids(input_ids, padding_idx):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols
+ are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ input_ids: jnp.ndarray
+ padding_idx: int
+
+ Returns: jnp.ndarray
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = (input_ids != padding_idx).astype("i4")
+
+ if mask.ndim > 2:
+ mask = mask.reshape((-1, mask.shape[-1]))
+ incremental_indices = jnp.cumsum(mask, axis=1).astype("i4") * mask
+ incremental_indices = incremental_indices.reshape(input_ids.shape)
+ else:
+ incremental_indices = jnp.cumsum(mask, axis=1).astype("i4") * mask
+
+ return incremental_indices.astype("i4") + padding_idx
+
+
+XLM_ROBERTA_START_DOCSTRING = r"""
+
+ This model inherits from [`FlaxPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading, saving and converting weights from PyTorch models)
+
+ This model is also a
+ [flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html) subclass. Use it as
+ a regular Flax linen Module and refer to the Flax documentation for all matter related to general usage and
+ behavior.
+
+ Finally, this model supports inherent JAX features such as:
+
+ - [Just-In-Time (JIT) compilation](https://jax.readthedocs.io/en/latest/jax.html#just-in-time-compilation-jit)
+ - [Automatic Differentiation](https://jax.readthedocs.io/en/latest/jax.html#automatic-differentiation)
+ - [Vectorization](https://jax.readthedocs.io/en/latest/jax.html#vectorization-vmap)
+ - [Parallelization](https://jax.readthedocs.io/en/latest/jax.html#parallelization-pmap)
+
+ Parameters:
+ config ([`XLMRobertaConfig`]): Model configuration class with all the parameters of the
+ model. Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~FlaxPreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+XLM_ROBERTA_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`numpy.ndarray` of shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`numpy.ndarray` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ token_type_ids (`numpy.ndarray` of shape `({0})`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`numpy.ndarray` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+ head_mask (`numpy.ndarray` of shape `({0})`, `optional):
+ Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertEmbeddings with Bert->XLMRoberta
+class FlaxXLMRobertaEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.word_embeddings = nn.Embed(
+ self.config.vocab_size,
+ self.config.hidden_size,
+ embedding_init=jax.nn.initializers.normal(stddev=self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.position_embeddings = nn.Embed(
+ self.config.max_position_embeddings,
+ self.config.hidden_size,
+ embedding_init=jax.nn.initializers.normal(stddev=self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.token_type_embeddings = nn.Embed(
+ self.config.type_vocab_size,
+ self.config.hidden_size,
+ embedding_init=jax.nn.initializers.normal(stddev=self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.LayerNorm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout_prob)
+
+ def __call__(self, input_ids, token_type_ids, position_ids, attention_mask, deterministic: bool = True):
+ # Embed
+ inputs_embeds = self.word_embeddings(input_ids.astype("i4"))
+ position_embeds = self.position_embeddings(position_ids.astype("i4"))
+ token_type_embeddings = self.token_type_embeddings(token_type_ids.astype("i4"))
+
+ # Sum all embeddings
+ hidden_states = inputs_embeds + token_type_embeddings + position_embeds
+
+ # Layer Norm
+ hidden_states = self.LayerNorm(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertSelfAttention with Bert->XLMRoberta
+class FlaxXLMRobertaSelfAttention(nn.Module):
+ config: XLMRobertaConfig
+ causal: bool = False
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.head_dim = self.config.hidden_size // self.config.num_attention_heads
+ if self.config.hidden_size % self.config.num_attention_heads != 0:
+ raise ValueError(
+ "`config.hidden_size`: {self.config.hidden_size} has to be a multiple of `config.num_attention_heads` "
+ " : {self.config.num_attention_heads}"
+ )
+
+ self.query = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+ self.key = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+ self.value = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+
+ if self.causal:
+ self.causal_mask = make_causal_mask(
+ jnp.ones((1, self.config.max_position_embeddings), dtype="bool"), dtype="bool"
+ )
+
+ def _split_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.config.num_attention_heads, self.head_dim))
+
+ def _merge_heads(self, hidden_states):
+ return hidden_states.reshape(hidden_states.shape[:2] + (self.config.hidden_size,))
+
+ @nn.compact
+ # Copied from transformers.models.bart.modeling_flax_bart.FlaxBartAttention._concatenate_to_cache
+ def _concatenate_to_cache(self, key, value, query, attention_mask):
+ """
+ This function takes projected key, value states from a single input token and concatenates the states to cached
+ states from previous steps. This function is slightly adapted from the official Flax repository:
+ https://github.com/google/flax/blob/491ce18759622506588784b4fca0e4bf05f8c8cd/flax/linen/attention.py#L252
+ """
+ # detect if we're initializing by absence of existing cache data.
+ is_initialized = self.has_variable("cache", "cached_key")
+ cached_key = self.variable("cache", "cached_key", jnp.zeros, key.shape, key.dtype)
+ cached_value = self.variable("cache", "cached_value", jnp.zeros, value.shape, value.dtype)
+ cache_index = self.variable("cache", "cache_index", lambda: jnp.array(0, dtype=jnp.int32))
+
+ if is_initialized:
+ *batch_dims, max_length, num_heads, depth_per_head = cached_key.value.shape
+ # update key, value caches with our new 1d spatial slices
+ cur_index = cache_index.value
+ indices = (0,) * len(batch_dims) + (cur_index, 0, 0)
+ key = lax.dynamic_update_slice(cached_key.value, key, indices)
+ value = lax.dynamic_update_slice(cached_value.value, value, indices)
+ cached_key.value = key
+ cached_value.value = value
+ num_updated_cache_vectors = query.shape[1]
+ cache_index.value = cache_index.value + num_updated_cache_vectors
+ # causal mask for cached decoder self-attention: our single query position should only attend to those key positions that have already been generated and cached, not the remaining zero elements.
+ pad_mask = jnp.broadcast_to(
+ jnp.arange(max_length) < cur_index + num_updated_cache_vectors,
+ tuple(batch_dims) + (1, num_updated_cache_vectors, max_length),
+ )
+ attention_mask = combine_masks(pad_mask, attention_mask)
+ return key, value, attention_mask
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ key_value_states: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic=True,
+ output_attentions: bool = False,
+ ):
+ # if key_value_states are provided this layer is used as a cross-attention layer
+ # for the decoder
+ is_cross_attention = key_value_states is not None
+ batch_size = hidden_states.shape[0]
+
+ # get query proj
+ query_states = self.query(hidden_states)
+ # get key, value proj
+ if is_cross_attention:
+ # cross_attentions
+ key_states = self.key(key_value_states)
+ value_states = self.value(key_value_states)
+ else:
+ # self_attention
+ key_states = self.key(hidden_states)
+ value_states = self.value(hidden_states)
+
+ query_states = self._split_heads(query_states)
+ key_states = self._split_heads(key_states)
+ value_states = self._split_heads(value_states)
+
+ # handle cache prepare causal attention mask
+ if self.causal:
+ query_length, key_length = query_states.shape[1], key_states.shape[1]
+ if self.has_variable("cache", "cached_key"):
+ mask_shift = self.variables["cache"]["cache_index"]
+ max_decoder_length = self.variables["cache"]["cached_key"].shape[1]
+ causal_mask = lax.dynamic_slice(
+ self.causal_mask, (0, 0, mask_shift, 0), (1, 1, query_length, max_decoder_length)
+ )
+ else:
+ causal_mask = self.causal_mask[:, :, :query_length, :key_length]
+ causal_mask = jnp.broadcast_to(causal_mask, (batch_size,) + causal_mask.shape[1:])
+
+ # combine masks if needed
+ if attention_mask is not None and self.causal:
+ attention_mask = jnp.broadcast_to(jnp.expand_dims(attention_mask, axis=(-3, -2)), causal_mask.shape)
+ attention_mask = combine_masks(attention_mask, causal_mask)
+ elif self.causal:
+ attention_mask = causal_mask
+ elif attention_mask is not None:
+ attention_mask = jnp.expand_dims(attention_mask, axis=(-3, -2))
+
+ # During fast autoregressive decoding, we feed one position at a time,
+ # and cache the keys and values step by step.
+ if self.causal and (self.has_variable("cache", "cached_key") or init_cache):
+ key_states, value_states, attention_mask = self._concatenate_to_cache(
+ key_states, value_states, query_states, attention_mask
+ )
+
+ # Convert the boolean attention mask to an attention bias.
+ if attention_mask is not None:
+ # attention mask in the form of attention bias
+ attention_bias = lax.select(
+ attention_mask > 0,
+ jnp.full(attention_mask.shape, 0.0).astype(self.dtype),
+ jnp.full(attention_mask.shape, jnp.finfo(self.dtype).min).astype(self.dtype),
+ )
+ else:
+ attention_bias = None
+
+ dropout_rng = None
+ if not deterministic and self.config.attention_probs_dropout_prob > 0.0:
+ dropout_rng = self.make_rng("dropout")
+
+ attn_weights = dot_product_attention_weights(
+ query_states,
+ key_states,
+ bias=attention_bias,
+ dropout_rng=dropout_rng,
+ dropout_rate=self.config.attention_probs_dropout_prob,
+ broadcast_dropout=True,
+ deterministic=deterministic,
+ dtype=self.dtype,
+ precision=None,
+ )
+
+ # Mask heads if we want to
+ if layer_head_mask is not None:
+ attn_weights = jnp.einsum("...hqk,h->...hqk", attn_weights, layer_head_mask)
+
+ attn_output = jnp.einsum("...hqk,...khd->...qhd", attn_weights, value_states)
+ attn_output = attn_output.reshape(attn_output.shape[:2] + (-1,))
+
+ outputs = (attn_output, attn_weights) if output_attentions else (attn_output,)
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertSelfOutput with Bert->XLMRoberta
+class FlaxXLMRobertaSelfOutput(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.LayerNorm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout_prob)
+
+ def __call__(self, hidden_states, input_tensor, deterministic: bool = True):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertAttention with Bert->XLMRoberta
+class FlaxXLMRobertaAttention(nn.Module):
+ config: XLMRobertaConfig
+ causal: bool = False
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.self = FlaxXLMRobertaSelfAttention(self.config, causal=self.causal, dtype=self.dtype)
+ self.output = FlaxXLMRobertaSelfOutput(self.config, dtype=self.dtype)
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ key_value_states=None,
+ init_cache=False,
+ deterministic=True,
+ output_attentions: bool = False,
+ ):
+ # Attention mask comes in as attention_mask.shape == (*batch_sizes, kv_length)
+ # FLAX expects: attention_mask.shape == (*batch_sizes, 1, 1, kv_length) such that it is broadcastable
+ # with attn_weights.shape == (*batch_sizes, num_heads, q_length, kv_length)
+ attn_outputs = self.self(
+ hidden_states,
+ attention_mask,
+ layer_head_mask=layer_head_mask,
+ key_value_states=key_value_states,
+ init_cache=init_cache,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ )
+ attn_output = attn_outputs[0]
+ hidden_states = self.output(attn_output, hidden_states, deterministic=deterministic)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attn_outputs[1],)
+
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertIntermediate with Bert->XLMRoberta
+class FlaxXLMRobertaIntermediate(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.intermediate_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.activation = ACT2FN[self.config.hidden_act]
+
+ def __call__(self, hidden_states):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.activation(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertOutput with Bert->XLMRoberta
+class FlaxXLMRobertaOutput(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout_prob)
+ self.LayerNorm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+
+ def __call__(self, hidden_states, attention_output, deterministic: bool = True):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = self.LayerNorm(hidden_states + attention_output)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertLayer with Bert->XLMRoberta
+class FlaxXLMRobertaLayer(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.attention = FlaxXLMRobertaAttention(self.config, causal=self.config.is_decoder, dtype=self.dtype)
+ self.intermediate = FlaxXLMRobertaIntermediate(self.config, dtype=self.dtype)
+ self.output = FlaxXLMRobertaOutput(self.config, dtype=self.dtype)
+ if self.config.add_cross_attention:
+ self.crossattention = FlaxXLMRobertaAttention(self.config, causal=False, dtype=self.dtype)
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ ):
+ # Self Attention
+ attention_outputs = self.attention(
+ hidden_states,
+ attention_mask,
+ layer_head_mask=layer_head_mask,
+ init_cache=init_cache,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ )
+ attention_output = attention_outputs[0]
+
+ # Cross-Attention Block
+ if encoder_hidden_states is not None:
+ cross_attention_outputs = self.crossattention(
+ attention_output,
+ attention_mask=encoder_attention_mask,
+ layer_head_mask=layer_head_mask,
+ key_value_states=encoder_hidden_states,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ )
+ attention_output = cross_attention_outputs[0]
+
+ hidden_states = self.intermediate(attention_output)
+ hidden_states = self.output(hidden_states, attention_output, deterministic=deterministic)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (attention_outputs[1],)
+ if encoder_hidden_states is not None:
+ outputs += (cross_attention_outputs[1],)
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertLayerCollection with Bert->XLMRoberta
+class FlaxXLMRobertaLayerCollection(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ if self.gradient_checkpointing:
+ FlaxXLMRobertaCheckpointLayer = remat(FlaxXLMRobertaLayer, static_argnums=(5, 6, 7))
+ self.layers = [
+ FlaxXLMRobertaCheckpointLayer(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.num_hidden_layers)
+ ]
+ else:
+ self.layers = [
+ FlaxXLMRobertaLayer(self.config, name=str(i), dtype=self.dtype)
+ for i in range(self.config.num_hidden_layers)
+ ]
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ all_attentions = () if output_attentions else None
+ all_hidden_states = () if output_hidden_states else None
+ all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None
+
+ # Check if head_mask has a correct number of layers specified if desired
+ if head_mask is not None:
+ if head_mask.shape[0] != (len(self.layers)):
+ raise ValueError(
+ f"The head_mask should be specified for {len(self.layers)} layers, but it is for "
+ f" {head_mask.shape[0]}."
+ )
+
+ for i, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ layer_outputs = layer(
+ hidden_states,
+ attention_mask,
+ head_mask[i] if head_mask is not None else None,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ init_cache,
+ deterministic,
+ output_attentions,
+ )
+
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ all_attentions += (layer_outputs[1],)
+
+ if encoder_hidden_states is not None:
+ all_cross_attentions += (layer_outputs[2],)
+
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ outputs = (hidden_states, all_hidden_states, all_attentions, all_cross_attentions)
+
+ if not return_dict:
+ return tuple(v for v in outputs if v is not None)
+
+ return FlaxBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertEncoder with Bert->XLMRoberta
+class FlaxXLMRobertaEncoder(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.layer = FlaxXLMRobertaLayerCollection(
+ self.config,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+
+ def __call__(
+ self,
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ return self.layer(
+ hidden_states,
+ attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ init_cache=init_cache,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertPooler with Bert->XLMRoberta
+class FlaxXLMRobertaPooler(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.hidden_size,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ dtype=self.dtype,
+ )
+
+ def __call__(self, hidden_states):
+ cls_hidden_state = hidden_states[:, 0]
+ cls_hidden_state = self.dense(cls_hidden_state)
+ return nn.tanh(cls_hidden_state)
+
+
+# Copied from transformers.models.roberta.modeling_flax_roberta.FlaxRobertaLMHead with Roberta->XLMRoberta
+class FlaxXLMRobertaLMHead(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+ bias_init: Callable[..., np.ndarray] = jax.nn.initializers.zeros
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+ self.layer_norm = nn.LayerNorm(epsilon=self.config.layer_norm_eps, dtype=self.dtype)
+ self.decoder = nn.Dense(
+ self.config.vocab_size,
+ dtype=self.dtype,
+ use_bias=False,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+ self.bias = self.param("bias", self.bias_init, (self.config.vocab_size,))
+
+ def __call__(self, hidden_states, shared_embedding=None):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = ACT2FN["gelu"](hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+
+ if shared_embedding is not None:
+ hidden_states = self.decoder.apply({"params": {"kernel": shared_embedding.T}}, hidden_states)
+ else:
+ hidden_states = self.decoder(hidden_states)
+
+ bias = jnp.asarray(self.bias, self.dtype)
+ hidden_states += bias
+ return hidden_states
+
+
+# Copied from transformers.models.roberta.modeling_flax_roberta.FlaxRobertaClassificationHead with Roberta->XLMRoberta
+class FlaxXLMRobertaClassificationHead(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+
+ def setup(self):
+ self.dense = nn.Dense(
+ self.config.hidden_size,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+ classifier_dropout = (
+ self.config.classifier_dropout
+ if self.config.classifier_dropout is not None
+ else self.config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(rate=classifier_dropout)
+ self.out_proj = nn.Dense(
+ self.config.num_labels,
+ dtype=self.dtype,
+ kernel_init=jax.nn.initializers.normal(self.config.initializer_range),
+ )
+
+ def __call__(self, hidden_states, deterministic=True):
+ hidden_states = hidden_states[:, 0, :] # take token (equiv. to [CLS])
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = self.dense(hidden_states)
+ hidden_states = nn.tanh(hidden_states)
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ hidden_states = self.out_proj(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.roberta.modeling_flax_roberta.FlaxRobertaPreTrainedModel with Roberta->XLMRoberta, roberta->xlm-roberta, ROBERTA->XLM_ROBERTA
+class FlaxXLMRobertaPreTrainedModel(FlaxPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = XLMRobertaConfig
+ base_model_prefix = "xlm-roberta"
+
+ module_class: nn.Module = None
+
+ def __init__(
+ self,
+ config: XLMRobertaConfig,
+ input_shape: tuple = (1, 1),
+ seed: int = 0,
+ dtype: jnp.dtype = jnp.float32,
+ _do_init: bool = True,
+ gradient_checkpointing: bool = False,
+ **kwargs,
+ ):
+ module = self.module_class(config=config, dtype=dtype, gradient_checkpointing=gradient_checkpointing, **kwargs)
+ super().__init__(config, module, input_shape=input_shape, seed=seed, dtype=dtype, _do_init=_do_init)
+
+ # Copied from transformers.models.bert.modeling_flax_bert.FlaxBertPreTrainedModel.enable_gradient_checkpointing
+ def enable_gradient_checkpointing(self):
+ self._module = self.module_class(
+ config=self.config,
+ dtype=self.dtype,
+ gradient_checkpointing=True,
+ )
+
+ def init_weights(self, rng: jax.random.PRNGKey, input_shape: tuple, params: FrozenDict = None) -> FrozenDict:
+ # init input tensors
+ input_ids = jnp.zeros(input_shape, dtype="i4")
+ token_type_ids = jnp.ones_like(input_ids)
+ position_ids = create_position_ids_from_input_ids(input_ids, self.config.pad_token_id)
+ attention_mask = jnp.ones_like(input_ids)
+ head_mask = jnp.ones((self.config.num_hidden_layers, self.config.num_attention_heads))
+
+ params_rng, dropout_rng = jax.random.split(rng)
+ rngs = {"params": params_rng, "dropout": dropout_rng}
+
+ if self.config.add_cross_attention:
+ encoder_hidden_states = jnp.zeros(input_shape + (self.config.hidden_size,))
+ encoder_attention_mask = attention_mask
+ module_init_outputs = self.module.init(
+ rngs,
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ return_dict=False,
+ )
+ else:
+ module_init_outputs = self.module.init(
+ rngs, input_ids, attention_mask, token_type_ids, position_ids, head_mask, return_dict=False
+ )
+
+ random_params = module_init_outputs["params"]
+
+ if params is not None:
+ random_params = flatten_dict(unfreeze(random_params))
+ params = flatten_dict(unfreeze(params))
+ for missing_key in self._missing_keys:
+ params[missing_key] = random_params[missing_key]
+ self._missing_keys = set()
+ return freeze(unflatten_dict(params))
+ else:
+ return random_params
+
+ # Copied from transformers.models.bart.modeling_flax_bart.FlaxBartDecoderPreTrainedModel.init_cache
+ def init_cache(self, batch_size, max_length):
+ r"""
+ Args:
+ batch_size (`int`):
+ batch_size used for fast auto-regressive decoding. Defines the batch size of the initialized cache.
+ max_length (`int`):
+ maximum possible length for auto-regressive decoding. Defines the sequence length of the initialized
+ cache.
+ """
+ # init input variables to retrieve cache
+ input_ids = jnp.ones((batch_size, max_length), dtype="i4")
+ attention_mask = jnp.ones_like(input_ids, dtype="i4")
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_ids.shape)
+
+ init_variables = self.module.init(
+ jax.random.PRNGKey(0), input_ids, attention_mask, position_ids, return_dict=False, init_cache=True
+ )
+ return unfreeze(init_variables["cache"])
+
+ @add_start_docstrings_to_model_forward(XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ def __call__(
+ self,
+ input_ids,
+ attention_mask=None,
+ token_type_ids=None,
+ position_ids=None,
+ head_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ params: Optional[dict] = None,
+ dropout_rng: jax.random.PRNGKey = None,
+ train: bool = False,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ past_key_values: Optional[dict] = None,
+ ):
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.return_dict
+
+ # init input tensors if not passed
+ if token_type_ids is None:
+ token_type_ids = jnp.zeros_like(input_ids)
+
+ if position_ids is None:
+ position_ids = create_position_ids_from_input_ids(input_ids, self.config.pad_token_id)
+
+ if attention_mask is None:
+ attention_mask = jnp.ones_like(input_ids)
+
+ if head_mask is None:
+ head_mask = jnp.ones((self.config.num_hidden_layers, self.config.num_attention_heads))
+
+ # Handle any PRNG if needed
+ rngs = {}
+ if dropout_rng is not None:
+ rngs["dropout"] = dropout_rng
+
+ inputs = {"params": params or self.params}
+
+ if self.config.add_cross_attention:
+ # if past_key_values are passed then cache is already initialized a private flag init_cache has to be passed
+ # down to ensure cache is used. It has to be made sure that cache is marked as mutable so that it can be
+ # changed by FlaxXLMRobertaAttention module
+ if past_key_values:
+ inputs["cache"] = past_key_values
+ mutable = ["cache"]
+ else:
+ mutable = False
+
+ outputs = self.module.apply(
+ inputs,
+ jnp.array(input_ids, dtype="i4"),
+ jnp.array(attention_mask, dtype="i4"),
+ token_type_ids=jnp.array(token_type_ids, dtype="i4"),
+ position_ids=jnp.array(position_ids, dtype="i4"),
+ head_mask=jnp.array(head_mask, dtype="i4"),
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ deterministic=not train,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ rngs=rngs,
+ mutable=mutable,
+ )
+
+ # add updated cache to model output
+ if past_key_values is not None and return_dict:
+ outputs, past_key_values = outputs
+ outputs["past_key_values"] = unfreeze(past_key_values["cache"])
+ return outputs
+ elif past_key_values is not None and not return_dict:
+ outputs, past_key_values = outputs
+ outputs = outputs[:1] + (unfreeze(past_key_values["cache"]),) + outputs[1:]
+
+ else:
+ outputs = self.module.apply(
+ inputs,
+ jnp.array(input_ids, dtype="i4"),
+ jnp.array(attention_mask, dtype="i4"),
+ token_type_ids=jnp.array(token_type_ids, dtype="i4"),
+ position_ids=jnp.array(position_ids, dtype="i4"),
+ head_mask=jnp.array(head_mask, dtype="i4"),
+ deterministic=not train,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ rngs=rngs,
+ )
+
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertModule with Bert->XLMRoberta
+class FlaxXLMRobertaModule(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32 # the dtype of the computation
+ add_pooling_layer: bool = True
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.embeddings = FlaxXLMRobertaEmbeddings(self.config, dtype=self.dtype)
+ self.encoder = FlaxXLMRobertaEncoder(
+ self.config,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+ self.pooler = FlaxXLMRobertaPooler(self.config, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ token_type_ids: Optional[jnp.ndarray] = None,
+ position_ids: Optional[jnp.ndarray] = None,
+ head_mask: Optional[jnp.ndarray] = None,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # make sure `token_type_ids` is correctly initialized when not passed
+ if token_type_ids is None:
+ token_type_ids = jnp.zeros_like(input_ids)
+
+ # make sure `position_ids` is correctly initialized when not passed
+ if position_ids is None:
+ position_ids = jnp.broadcast_to(jnp.arange(jnp.atleast_2d(input_ids).shape[-1]), input_ids.shape)
+
+ hidden_states = self.embeddings(
+ input_ids, token_type_ids, position_ids, attention_mask, deterministic=deterministic
+ )
+ outputs = self.encoder(
+ hidden_states,
+ attention_mask,
+ head_mask=head_mask,
+ deterministic=deterministic,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ init_cache=init_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ hidden_states = outputs[0]
+ pooled = self.pooler(hidden_states) if self.add_pooling_layer else None
+
+ if not return_dict:
+ # if pooled is None, don't return it
+ if pooled is None:
+ return (hidden_states,) + outputs[1:]
+ return (hidden_states, pooled) + outputs[1:]
+
+ return FlaxBaseModelOutputWithPoolingAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ pooler_output=pooled,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+@add_start_docstrings(
+ "The bare XLM RoBERTa Model transformer outputting raw hidden-states without any specific head on top.",
+ XLM_ROBERTA_START_DOCSTRING,
+)
+class FlaxXLMRobertaModel(FlaxXLMRobertaPreTrainedModel):
+ module_class = FlaxXLMRobertaModule
+
+
+append_call_sample_docstring(FlaxXLMRobertaModel, _CHECKPOINT_FOR_DOC, FlaxBaseModelOutputWithPooling, _CONFIG_FOR_DOC)
+
+
+# Copied from transformers.models.roberta.modeling_flax_roberta.FlaxRobertaForMaskedLMModule with Roberta->XLMRoberta
+class FlaxXLMRobertaForMaskedLMModule(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.roberta = FlaxXLMRobertaModule(
+ config=self.config,
+ add_pooling_layer=False,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+ self.lm_head = FlaxXLMRobertaLMHead(config=self.config, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # Model
+ outputs = self.roberta(
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ if self.config.tie_word_embeddings:
+ shared_embedding = self.roberta.variables["params"]["embeddings"]["word_embeddings"]["embedding"]
+ else:
+ shared_embedding = None
+
+ # Compute the prediction scores
+ logits = self.lm_head(hidden_states, shared_embedding=shared_embedding)
+
+ if not return_dict:
+ return (logits,) + outputs[1:]
+
+ return FlaxMaskedLMOutput(
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@add_start_docstrings("""XLM RoBERTa Model with a `language modeling` head on top.""", XLM_ROBERTA_START_DOCSTRING)
+class FlaxXLMRobertaForMaskedLM(FlaxXLMRobertaPreTrainedModel):
+ module_class = FlaxXLMRobertaForMaskedLMModule
+
+
+append_call_sample_docstring(
+ FlaxXLMRobertaForMaskedLM,
+ _CHECKPOINT_FOR_DOC,
+ FlaxBaseModelOutputWithPooling,
+ _CONFIG_FOR_DOC,
+ mask="",
+)
+
+
+# Copied from transformers.models.roberta.modeling_flax_roberta.FlaxRobertaForSequenceClassificationModule with Roberta->XLMRoberta
+class FlaxXLMRobertaForSequenceClassificationModule(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.roberta = FlaxXLMRobertaModule(
+ config=self.config,
+ dtype=self.dtype,
+ add_pooling_layer=False,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+ self.classifier = FlaxXLMRobertaClassificationHead(config=self.config, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # Model
+ outputs = self.roberta(
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ logits = self.classifier(sequence_output, deterministic=deterministic)
+
+ if not return_dict:
+ return (logits,) + outputs[1:]
+
+ return FlaxSequenceClassifierOutput(
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@add_start_docstrings(
+ """
+ XLM Roberta Model transformer with a sequence classification/regression head on top (a linear layer on top of the
+ pooled output) e.g. for GLUE tasks.
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+class FlaxXLMRobertaForSequenceClassification(FlaxXLMRobertaPreTrainedModel):
+ module_class = FlaxXLMRobertaForSequenceClassificationModule
+
+
+append_call_sample_docstring(
+ FlaxXLMRobertaForSequenceClassification,
+ _CHECKPOINT_FOR_DOC,
+ FlaxSequenceClassifierOutput,
+ _CONFIG_FOR_DOC,
+)
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertForMultipleChoiceModule with Bert->XLMRoberta, with self.bert->self.roberta
+class FlaxXLMRobertaForMultipleChoiceModule(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.roberta = FlaxXLMRobertaModule(
+ config=self.config,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+ self.dropout = nn.Dropout(rate=self.config.hidden_dropout_prob)
+ self.classifier = nn.Dense(1, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ num_choices = input_ids.shape[1]
+ input_ids = input_ids.reshape(-1, input_ids.shape[-1]) if input_ids is not None else None
+ attention_mask = attention_mask.reshape(-1, attention_mask.shape[-1]) if attention_mask is not None else None
+ token_type_ids = token_type_ids.reshape(-1, token_type_ids.shape[-1]) if token_type_ids is not None else None
+ position_ids = position_ids.reshape(-1, position_ids.shape[-1]) if position_ids is not None else None
+
+ # Model
+ outputs = self.roberta(
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ pooled_output = outputs[1]
+ pooled_output = self.dropout(pooled_output, deterministic=deterministic)
+ logits = self.classifier(pooled_output)
+
+ reshaped_logits = logits.reshape(-1, num_choices)
+
+ if not return_dict:
+ return (reshaped_logits,) + outputs[2:]
+
+ return FlaxMultipleChoiceModelOutput(
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@add_start_docstrings(
+ """
+ XLM Roberta Model with a multiple choice classification head on top (a linear layer on top of the pooled output and
+ a softmax) e.g. for RocStories/SWAG tasks.
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+class FlaxXLMRobertaForMultipleChoice(FlaxXLMRobertaPreTrainedModel):
+ module_class = FlaxXLMRobertaForMultipleChoiceModule
+
+
+overwrite_call_docstring(
+ FlaxXLMRobertaForMultipleChoice, XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, num_choices, sequence_length")
+)
+append_call_sample_docstring(
+ FlaxXLMRobertaForMultipleChoice,
+ _CHECKPOINT_FOR_DOC,
+ FlaxMultipleChoiceModelOutput,
+ _CONFIG_FOR_DOC,
+)
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertForTokenClassificationModule with Bert->XLMRoberta, with self.bert->self.roberta
+class FlaxXLMRobertaForTokenClassificationModule(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.roberta = FlaxXLMRobertaModule(
+ config=self.config,
+ dtype=self.dtype,
+ add_pooling_layer=False,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+ classifier_dropout = (
+ self.config.classifier_dropout
+ if self.config.classifier_dropout is not None
+ else self.config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(rate=classifier_dropout)
+ self.classifier = nn.Dense(self.config.num_labels, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # Model
+ outputs = self.roberta(
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ hidden_states = self.dropout(hidden_states, deterministic=deterministic)
+ logits = self.classifier(hidden_states)
+
+ if not return_dict:
+ return (logits,) + outputs[1:]
+
+ return FlaxTokenClassifierOutput(
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@add_start_docstrings(
+ """
+ XLM Roberta Model with a token classification head on top (a linear layer on top of the hidden-states output) e.g.
+ for Named-Entity-Recognition (NER) tasks.
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+class FlaxXLMRobertaForTokenClassification(FlaxXLMRobertaPreTrainedModel):
+ module_class = FlaxXLMRobertaForTokenClassificationModule
+
+
+append_call_sample_docstring(
+ FlaxXLMRobertaForTokenClassification,
+ _CHECKPOINT_FOR_DOC,
+ FlaxTokenClassifierOutput,
+ _CONFIG_FOR_DOC,
+)
+
+
+# Copied from transformers.models.bert.modeling_flax_bert.FlaxBertForQuestionAnsweringModule with Bert->XLMRoberta, with self.bert->self.roberta
+class FlaxXLMRobertaForQuestionAnsweringModule(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.roberta = FlaxXLMRobertaModule(
+ config=self.config,
+ dtype=self.dtype,
+ add_pooling_layer=False,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+ self.qa_outputs = nn.Dense(self.config.num_labels, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # Model
+ outputs = self.roberta(
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+
+ logits = self.qa_outputs(hidden_states)
+ start_logits, end_logits = jnp.split(logits, self.config.num_labels, axis=-1)
+ start_logits = start_logits.squeeze(-1)
+ end_logits = end_logits.squeeze(-1)
+
+ if not return_dict:
+ return (start_logits, end_logits) + outputs[1:]
+
+ return FlaxQuestionAnsweringModelOutput(
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@add_start_docstrings(
+ """
+ XLM Roberta Model with a span classification head on top for extractive question-answering tasks like SQuAD (a
+ linear layers on top of the hidden-states output to compute `span start logits` and `span end logits`).
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+class FlaxXLMRobertaForQuestionAnswering(FlaxXLMRobertaPreTrainedModel):
+ module_class = FlaxXLMRobertaForQuestionAnsweringModule
+
+
+append_call_sample_docstring(
+ FlaxXLMRobertaForQuestionAnswering,
+ _CHECKPOINT_FOR_DOC,
+ FlaxQuestionAnsweringModelOutput,
+ _CONFIG_FOR_DOC,
+)
+
+
+# Copied from transformers.models.roberta.modeling_flax_roberta.FlaxRobertaForCausalLMModule with Roberta->XLMRoberta
+class FlaxXLMRobertaForCausalLMModule(nn.Module):
+ config: XLMRobertaConfig
+ dtype: jnp.dtype = jnp.float32
+ gradient_checkpointing: bool = False
+
+ def setup(self):
+ self.roberta = FlaxXLMRobertaModule(
+ config=self.config,
+ add_pooling_layer=False,
+ dtype=self.dtype,
+ gradient_checkpointing=self.gradient_checkpointing,
+ )
+ self.lm_head = FlaxXLMRobertaLMHead(config=self.config, dtype=self.dtype)
+
+ def __call__(
+ self,
+ input_ids,
+ attention_mask,
+ position_ids,
+ token_type_ids: Optional[jnp.ndarray] = None,
+ head_mask: Optional[jnp.ndarray] = None,
+ encoder_hidden_states: Optional[jnp.ndarray] = None,
+ encoder_attention_mask: Optional[jnp.ndarray] = None,
+ init_cache: bool = False,
+ deterministic: bool = True,
+ output_attentions: bool = False,
+ output_hidden_states: bool = False,
+ return_dict: bool = True,
+ ):
+ # Model
+ outputs = self.roberta(
+ input_ids,
+ attention_mask,
+ token_type_ids,
+ position_ids,
+ head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ init_cache=init_cache,
+ deterministic=deterministic,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ if self.config.tie_word_embeddings:
+ shared_embedding = self.roberta.variables["params"]["embeddings"]["word_embeddings"]["embedding"]
+ else:
+ shared_embedding = None
+
+ # Compute the prediction scores
+ logits = self.lm_head(hidden_states, shared_embedding=shared_embedding)
+
+ if not return_dict:
+ return (logits,) + outputs[1:]
+
+ return FlaxCausalLMOutputWithCrossAttentions(
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+@add_start_docstrings(
+ """
+ XLM Roberta Model with a language modeling head on top (a linear layer on top of the hidden-states output) e.g for
+ autoregressive tasks.
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+# Copied from transformers.models.roberta.modeling_flax_roberta.FlaxRobertaForCausalLM with Roberta->XLMRoberta
+class FlaxXLMRobertaForCausalLM(FlaxXLMRobertaPreTrainedModel):
+ module_class = FlaxXLMRobertaForCausalLMModule
+
+ def prepare_inputs_for_generation(self, input_ids, max_length, attention_mask: Optional[jax.Array] = None):
+ # initializing the cache
+ batch_size, seq_length = input_ids.shape
+
+ past_key_values = self.init_cache(batch_size, max_length)
+ # Note that usually one would have to put 0's in the attention_mask for x > input_ids.shape[-1] and x < cache_length.
+ # But since the decoder uses a causal mask, those positions are masked anyway.
+ # Thus, we can create a single static attention_mask here, which is more efficient for compilation
+ extended_attention_mask = jnp.ones((batch_size, max_length), dtype="i4")
+ if attention_mask is not None:
+ position_ids = attention_mask.cumsum(axis=-1) - 1
+ extended_attention_mask = lax.dynamic_update_slice(extended_attention_mask, attention_mask, (0, 0))
+ else:
+ position_ids = jnp.broadcast_to(jnp.arange(seq_length, dtype="i4")[None, :], (batch_size, seq_length))
+
+ return {
+ "past_key_values": past_key_values,
+ "attention_mask": extended_attention_mask,
+ "position_ids": position_ids,
+ }
+
+ def update_inputs_for_generation(self, model_outputs, model_kwargs):
+ model_kwargs["past_key_values"] = model_outputs.past_key_values
+ model_kwargs["position_ids"] = model_kwargs["position_ids"][:, -1:] + 1
+ return model_kwargs
+
+
+append_call_sample_docstring(
+ FlaxXLMRobertaForCausalLM,
+ _CHECKPOINT_FOR_DOC,
+ FlaxCausalLMOutputWithCrossAttentions,
+ _CONFIG_FOR_DOC,
+)
+
+
+__all__ = [
+ "FlaxXLMRobertaForMaskedLM",
+ "FlaxXLMRobertaForCausalLM",
+ "FlaxXLMRobertaForMultipleChoice",
+ "FlaxXLMRobertaForQuestionAnswering",
+ "FlaxXLMRobertaForSequenceClassification",
+ "FlaxXLMRobertaForTokenClassification",
+ "FlaxXLMRobertaModel",
+ "FlaxXLMRobertaPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_tf_xlm_roberta.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_tf_xlm_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..0def1bfdb00da7422d0957f330936ebc74e99e38
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_tf_xlm_roberta.py
@@ -0,0 +1,1790 @@
+# coding=utf-8
+# Copyright 2019 Facebook AI Research and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""TF 2.0 XLM-RoBERTa model."""
+
+from __future__ import annotations
+
+import math
+import warnings
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_outputs import (
+ TFBaseModelOutputWithPastAndCrossAttentions,
+ TFBaseModelOutputWithPoolingAndCrossAttentions,
+ TFCausalLMOutputWithCrossAttentions,
+ TFMaskedLMOutput,
+ TFMultipleChoiceModelOutput,
+ TFQuestionAnsweringModelOutput,
+ TFSequenceClassifierOutput,
+ TFTokenClassifierOutput,
+)
+from ...modeling_tf_utils import (
+ TFCausalLanguageModelingLoss,
+ TFMaskedLanguageModelingLoss,
+ TFModelInputType,
+ TFMultipleChoiceLoss,
+ TFPreTrainedModel,
+ TFQuestionAnsweringLoss,
+ TFSequenceClassificationLoss,
+ TFTokenClassificationLoss,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import (
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+)
+from .configuration_xlm_roberta import XLMRobertaConfig
+
+
+logger = logging.get_logger(__name__)
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "FacebookAI/xlm-roberta-base"
+_CONFIG_FOR_DOC = "XLMRobertaConfig"
+
+
+XLM_ROBERTA_START_DOCSTRING = r"""
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Parameters:
+ config ([`XLMRobertaConfig`]): Model configuration class with all the parameters of the
+ model. Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+XLM_ROBERTA_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`Numpy array` or `tf.Tensor` of shape `({0})`):
+ Indices of input sequence tokens in the vocabulary. Indices can be obtained using [`AutoTokenizer`]. See
+ [`PreTrainedTokenizer.__call__`] and [`PreTrainedTokenizer.encode`] for details. [What are input
+ IDs?](../glossary#input-ids)
+ attention_mask (`Numpy array` or `tf.Tensor` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+ [What are attention masks?](../glossary#attention-mask)
+ token_type_ids (`Numpy array` or `tf.Tensor` of shape `({0})`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`Numpy array` or `tf.Tensor` of shape `({0})`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`. [What are position IDs?](../glossary#position-ids)
+ head_mask (`Numpy array` or `tf.Tensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+ inputs_embeds (`tf.Tensor` of shape `({0}, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail. This argument can be used only in eager mode, in graph mode the value in the
+ config will be used instead.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail. This argument can be used only in eager mode, in graph mode the value in the config will be
+ used instead.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. This argument can be used in
+ eager mode, in graph mode the value will always be set to True.
+ training (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the model in training mode (some modules like dropout modules have different
+ behaviors between training and evaluation).
+"""
+
+
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaEmbeddings with Roberta->XLMRoberta
+class TFXLMRobertaEmbeddings(keras.layers.Layer):
+ """
+ Same as BertEmbeddings with a tiny tweak for positional embeddings indexing.
+ """
+
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+
+ self.padding_idx = 1
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.max_position_embeddings = config.max_position_embeddings
+ self.initializer_range = config.initializer_range
+ self.LayerNorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="LayerNorm")
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+
+ def build(self, input_shape=None):
+ with tf.name_scope("word_embeddings"):
+ self.weight = self.add_weight(
+ name="weight",
+ shape=[self.config.vocab_size, self.hidden_size],
+ initializer=get_initializer(self.initializer_range),
+ )
+
+ with tf.name_scope("token_type_embeddings"):
+ self.token_type_embeddings = self.add_weight(
+ name="embeddings",
+ shape=[self.config.type_vocab_size, self.hidden_size],
+ initializer=get_initializer(self.initializer_range),
+ )
+
+ with tf.name_scope("position_embeddings"):
+ self.position_embeddings = self.add_weight(
+ name="embeddings",
+ shape=[self.max_position_embeddings, self.hidden_size],
+ initializer=get_initializer(self.initializer_range),
+ )
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "LayerNorm", None) is not None:
+ with tf.name_scope(self.LayerNorm.name):
+ self.LayerNorm.build([None, None, self.config.hidden_size])
+
+ def create_position_ids_from_input_ids(self, input_ids, past_key_values_length=0):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding
+ symbols are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ input_ids: tf.Tensor
+ Returns: tf.Tensor
+ """
+ mask = tf.cast(tf.math.not_equal(input_ids, self.padding_idx), dtype=input_ids.dtype)
+ incremental_indices = (tf.math.cumsum(mask, axis=1) + past_key_values_length) * mask
+
+ return incremental_indices + self.padding_idx
+
+ def call(
+ self,
+ input_ids=None,
+ position_ids=None,
+ token_type_ids=None,
+ inputs_embeds=None,
+ past_key_values_length=0,
+ training=False,
+ ):
+ """
+ Applies embedding based on inputs tensor.
+
+ Returns:
+ final_embeddings (`tf.Tensor`): output embedding tensor.
+ """
+ assert not (input_ids is None and inputs_embeds is None)
+
+ if input_ids is not None:
+ check_embeddings_within_bounds(input_ids, self.config.vocab_size)
+ inputs_embeds = tf.gather(params=self.weight, indices=input_ids)
+
+ input_shape = shape_list(inputs_embeds)[:-1]
+
+ if token_type_ids is None:
+ token_type_ids = tf.fill(dims=input_shape, value=0)
+
+ if position_ids is None:
+ if input_ids is not None:
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = self.create_position_ids_from_input_ids(
+ input_ids=input_ids, past_key_values_length=past_key_values_length
+ )
+ else:
+ position_ids = tf.expand_dims(
+ tf.range(start=self.padding_idx + 1, limit=input_shape[-1] + self.padding_idx + 1), axis=0
+ )
+
+ position_embeds = tf.gather(params=self.position_embeddings, indices=position_ids)
+ token_type_embeds = tf.gather(params=self.token_type_embeddings, indices=token_type_ids)
+ final_embeddings = inputs_embeds + position_embeds + token_type_embeds
+ final_embeddings = self.LayerNorm(inputs=final_embeddings)
+ final_embeddings = self.dropout(inputs=final_embeddings, training=training)
+
+ return final_embeddings
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertPooler with Bert->XLMRoberta
+class TFXLMRobertaPooler(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ activation="tanh",
+ name="dense",
+ )
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(inputs=first_token_tensor)
+
+ return pooled_output
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertSelfAttention with Bert->XLMRoberta
+class TFXLMRobertaSelfAttention(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ if config.hidden_size % config.num_attention_heads != 0:
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number "
+ f"of attention heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.sqrt_att_head_size = math.sqrt(self.attention_head_size)
+
+ self.query = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="query"
+ )
+ self.key = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="key"
+ )
+ self.value = keras.layers.Dense(
+ units=self.all_head_size, kernel_initializer=get_initializer(config.initializer_range), name="value"
+ )
+ self.dropout = keras.layers.Dropout(rate=config.attention_probs_dropout_prob)
+
+ self.is_decoder = config.is_decoder
+ self.config = config
+
+ def transpose_for_scores(self, tensor: tf.Tensor, batch_size: int) -> tf.Tensor:
+ # Reshape from [batch_size, seq_length, all_head_size] to [batch_size, seq_length, num_attention_heads, attention_head_size]
+ tensor = tf.reshape(tensor=tensor, shape=(batch_size, -1, self.num_attention_heads, self.attention_head_size))
+
+ # Transpose the tensor from [batch_size, seq_length, num_attention_heads, attention_head_size] to [batch_size, num_attention_heads, seq_length, attention_head_size]
+ return tf.transpose(tensor, perm=[0, 2, 1, 3])
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor,
+ encoder_attention_mask: tf.Tensor,
+ past_key_value: tuple[tf.Tensor],
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ batch_size = shape_list(hidden_states)[0]
+ mixed_query_layer = self.query(inputs=hidden_states)
+
+ # If this is instantiated as a cross-attention module, the keys
+ # and values come from an encoder; the attention mask needs to be
+ # such that the encoder's padding tokens are not attended to.
+ is_cross_attention = encoder_hidden_states is not None
+
+ if is_cross_attention and past_key_value is not None:
+ # reuse k,v, cross_attentions
+ key_layer = past_key_value[0]
+ value_layer = past_key_value[1]
+ attention_mask = encoder_attention_mask
+ elif is_cross_attention:
+ key_layer = self.transpose_for_scores(self.key(inputs=encoder_hidden_states), batch_size)
+ value_layer = self.transpose_for_scores(self.value(inputs=encoder_hidden_states), batch_size)
+ attention_mask = encoder_attention_mask
+ elif past_key_value is not None:
+ key_layer = self.transpose_for_scores(self.key(inputs=hidden_states), batch_size)
+ value_layer = self.transpose_for_scores(self.value(inputs=hidden_states), batch_size)
+ key_layer = tf.concat([past_key_value[0], key_layer], axis=2)
+ value_layer = tf.concat([past_key_value[1], value_layer], axis=2)
+ else:
+ key_layer = self.transpose_for_scores(self.key(inputs=hidden_states), batch_size)
+ value_layer = self.transpose_for_scores(self.value(inputs=hidden_states), batch_size)
+
+ query_layer = self.transpose_for_scores(mixed_query_layer, batch_size)
+
+ if self.is_decoder:
+ # if cross_attention save Tuple(tf.Tensor, tf.Tensor) of all cross attention key/value_states.
+ # Further calls to cross_attention layer can then reuse all cross-attention
+ # key/value_states (first "if" case)
+ # if uni-directional self-attention (decoder) save Tuple(tf.Tensor, tf.Tensor) of
+ # all previous decoder key/value_states. Further calls to uni-directional self-attention
+ # can concat previous decoder key/value_states to current projected key/value_states (third "elif" case)
+ # if encoder bi-directional self-attention `past_key_value` is always `None`
+ past_key_value = (key_layer, value_layer)
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ # (batch size, num_heads, seq_len_q, seq_len_k)
+ attention_scores = tf.matmul(query_layer, key_layer, transpose_b=True)
+ dk = tf.cast(self.sqrt_att_head_size, dtype=attention_scores.dtype)
+ attention_scores = tf.divide(attention_scores, dk)
+
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in TFXLMRobertaModel call() function)
+ attention_scores = tf.add(attention_scores, attention_mask)
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = stable_softmax(logits=attention_scores, axis=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(inputs=attention_probs, training=training)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = tf.multiply(attention_probs, head_mask)
+
+ attention_output = tf.matmul(attention_probs, value_layer)
+ attention_output = tf.transpose(attention_output, perm=[0, 2, 1, 3])
+
+ # (batch_size, seq_len_q, all_head_size)
+ attention_output = tf.reshape(tensor=attention_output, shape=(batch_size, -1, self.all_head_size))
+ outputs = (attention_output, attention_probs) if output_attentions else (attention_output,)
+
+ if self.is_decoder:
+ outputs = outputs + (past_key_value,)
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "query", None) is not None:
+ with tf.name_scope(self.query.name):
+ self.query.build([None, None, self.config.hidden_size])
+ if getattr(self, "key", None) is not None:
+ with tf.name_scope(self.key.name):
+ self.key.build([None, None, self.config.hidden_size])
+ if getattr(self, "value", None) is not None:
+ with tf.name_scope(self.value.name):
+ self.value.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertSelfOutput with Bert->XLMRoberta
+class TFXLMRobertaSelfOutput(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.LayerNorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="LayerNorm")
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+ hidden_states = self.LayerNorm(inputs=hidden_states + input_tensor)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+ if getattr(self, "LayerNorm", None) is not None:
+ with tf.name_scope(self.LayerNorm.name):
+ self.LayerNorm.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertAttention with Bert->XLMRoberta
+class TFXLMRobertaAttention(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.self_attention = TFXLMRobertaSelfAttention(config, name="self")
+ self.dense_output = TFXLMRobertaSelfOutput(config, name="output")
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ def call(
+ self,
+ input_tensor: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor,
+ encoder_attention_mask: tf.Tensor,
+ past_key_value: tuple[tf.Tensor],
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ self_outputs = self.self_attention(
+ hidden_states=input_tensor,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = self.dense_output(
+ hidden_states=self_outputs[0], input_tensor=input_tensor, training=training
+ )
+ # add attentions (possibly with past_key_value) if we output them
+ outputs = (attention_output,) + self_outputs[1:]
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "self_attention", None) is not None:
+ with tf.name_scope(self.self_attention.name):
+ self.self_attention.build(None)
+ if getattr(self, "dense_output", None) is not None:
+ with tf.name_scope(self.dense_output.name):
+ self.dense_output.build(None)
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertIntermediate with Bert->XLMRoberta
+class TFXLMRobertaIntermediate(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.intermediate_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = get_tf_activation(config.hidden_act)
+ else:
+ self.intermediate_act_fn = config.hidden_act
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertOutput with Bert->XLMRoberta
+class TFXLMRobertaOutput(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.dense = keras.layers.Dense(
+ units=config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.LayerNorm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="LayerNorm")
+ self.dropout = keras.layers.Dropout(rate=config.hidden_dropout_prob)
+ self.config = config
+
+ def call(self, hidden_states: tf.Tensor, input_tensor: tf.Tensor, training: bool = False) -> tf.Tensor:
+ hidden_states = self.dense(inputs=hidden_states)
+ hidden_states = self.dropout(inputs=hidden_states, training=training)
+ hidden_states = self.LayerNorm(inputs=hidden_states + input_tensor)
+
+ return hidden_states
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.intermediate_size])
+ if getattr(self, "LayerNorm", None) is not None:
+ with tf.name_scope(self.LayerNorm.name):
+ self.LayerNorm.build([None, None, self.config.hidden_size])
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertLayer with Bert->XLMRoberta
+class TFXLMRobertaLayer(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+
+ self.attention = TFXLMRobertaAttention(config, name="attention")
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = TFXLMRobertaAttention(config, name="crossattention")
+ self.intermediate = TFXLMRobertaIntermediate(config, name="intermediate")
+ self.bert_output = TFXLMRobertaOutput(config, name="output")
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor | None,
+ encoder_attention_mask: tf.Tensor | None,
+ past_key_value: tuple[tf.Tensor] | None,
+ output_attentions: bool,
+ training: bool = False,
+ ) -> tuple[tf.Tensor]:
+ # decoder uni-directional self-attention cached key/values tuple is at positions 1,2
+ self_attn_past_key_value = past_key_value[:2] if past_key_value is not None else None
+ self_attention_outputs = self.attention(
+ input_tensor=hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ past_key_value=self_attn_past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = self_attention_outputs[0]
+
+ # if decoder, the last output is tuple of self-attn cache
+ if self.is_decoder:
+ outputs = self_attention_outputs[1:-1]
+ present_key_value = self_attention_outputs[-1]
+ else:
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ cross_attn_present_key_value = None
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ # cross_attn cached key/values tuple is at positions 3,4 of past_key_value tuple
+ cross_attn_past_key_value = past_key_value[-2:] if past_key_value is not None else None
+ cross_attention_outputs = self.crossattention(
+ input_tensor=attention_output,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_value=cross_attn_past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:-1] # add cross attentions if we output attention weights
+
+ # add cross-attn cache to positions 3,4 of present_key_value tuple
+ cross_attn_present_key_value = cross_attention_outputs[-1]
+ present_key_value = present_key_value + cross_attn_present_key_value
+
+ intermediate_output = self.intermediate(hidden_states=attention_output)
+ layer_output = self.bert_output(
+ hidden_states=intermediate_output, input_tensor=attention_output, training=training
+ )
+ outputs = (layer_output,) + outputs # add attentions if we output them
+
+ # if decoder, return the attn key/values as the last output
+ if self.is_decoder:
+ outputs = outputs + (present_key_value,)
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "attention", None) is not None:
+ with tf.name_scope(self.attention.name):
+ self.attention.build(None)
+ if getattr(self, "intermediate", None) is not None:
+ with tf.name_scope(self.intermediate.name):
+ self.intermediate.build(None)
+ if getattr(self, "bert_output", None) is not None:
+ with tf.name_scope(self.bert_output.name):
+ self.bert_output.build(None)
+ if getattr(self, "crossattention", None) is not None:
+ with tf.name_scope(self.crossattention.name):
+ self.crossattention.build(None)
+
+
+# Copied from transformers.models.bert.modeling_tf_bert.TFBertEncoder with Bert->XLMRoberta
+class TFXLMRobertaEncoder(keras.layers.Layer):
+ def __init__(self, config: XLMRobertaConfig, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ self.layer = [TFXLMRobertaLayer(config, name=f"layer_._{i}") for i in range(config.num_hidden_layers)]
+
+ def call(
+ self,
+ hidden_states: tf.Tensor,
+ attention_mask: tf.Tensor,
+ head_mask: tf.Tensor,
+ encoder_hidden_states: tf.Tensor | None,
+ encoder_attention_mask: tf.Tensor | None,
+ past_key_values: tuple[tuple[tf.Tensor]] | None,
+ use_cache: bool | None,
+ output_attentions: bool,
+ output_hidden_states: bool,
+ return_dict: bool,
+ training: bool = False,
+ ) -> TFBaseModelOutputWithPastAndCrossAttentions | tuple[tf.Tensor]:
+ all_hidden_states = () if output_hidden_states else None
+ all_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None
+
+ next_decoder_cache = () if use_cache else None
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ past_key_value = past_key_values[i] if past_key_values is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states=hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask[i],
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_value=past_key_value,
+ output_attentions=output_attentions,
+ training=training,
+ )
+ hidden_states = layer_outputs[0]
+
+ if use_cache:
+ next_decoder_cache += (layer_outputs[-1],)
+
+ if output_attentions:
+ all_attentions = all_attentions + (layer_outputs[1],)
+ if self.config.add_cross_attention and encoder_hidden_states is not None:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ # Add last layer
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v for v in [hidden_states, all_hidden_states, all_attentions, all_cross_attentions] if v is not None
+ )
+
+ return TFBaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=next_decoder_cache,
+ hidden_states=all_hidden_states,
+ attentions=all_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer", None) is not None:
+ for layer in self.layer:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+
+@keras_serializable
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaMainLayer with Roberta->XLMRoberta
+class TFXLMRobertaMainLayer(keras.layers.Layer):
+ config_class = XLMRobertaConfig
+
+ def __init__(self, config, add_pooling_layer=True, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+ self.is_decoder = config.is_decoder
+
+ self.num_hidden_layers = config.num_hidden_layers
+ self.initializer_range = config.initializer_range
+ self.output_attentions = config.output_attentions
+ self.output_hidden_states = config.output_hidden_states
+ self.return_dict = config.use_return_dict
+ self.encoder = TFXLMRobertaEncoder(config, name="encoder")
+ self.pooler = TFXLMRobertaPooler(config, name="pooler") if add_pooling_layer else None
+ # The embeddings must be the last declaration in order to follow the weights order
+ self.embeddings = TFXLMRobertaEmbeddings(config, name="embeddings")
+
+ # Copied from transformers.models.bert.modeling_tf_bert.TFBertMainLayer.get_input_embeddings
+ def get_input_embeddings(self) -> keras.layers.Layer:
+ return self.embeddings
+
+ # Copied from transformers.models.bert.modeling_tf_bert.TFBertMainLayer.set_input_embeddings
+ def set_input_embeddings(self, value: tf.Variable):
+ self.embeddings.weight = value
+ self.embeddings.vocab_size = shape_list(value)[0]
+
+ # Copied from transformers.models.bert.modeling_tf_bert.TFBertMainLayer._prune_heads
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ raise NotImplementedError
+
+ @unpack_inputs
+ # Copied from transformers.models.bert.modeling_tf_bert.TFBertMainLayer.call
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ encoder_hidden_states: np.ndarray | tf.Tensor | None = None,
+ encoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFBaseModelOutputWithPoolingAndCrossAttentions | tuple[tf.Tensor]:
+ if not self.config.is_decoder:
+ use_cache = False
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_shape = shape_list(input_ids)
+ elif inputs_embeds is not None:
+ input_shape = shape_list(inputs_embeds)[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+
+ if past_key_values is None:
+ past_key_values_length = 0
+ past_key_values = [None] * len(self.encoder.layer)
+ else:
+ past_key_values_length = shape_list(past_key_values[0][0])[-2]
+
+ if attention_mask is None:
+ attention_mask = tf.fill(dims=(batch_size, seq_length + past_key_values_length), value=1)
+
+ if token_type_ids is None:
+ token_type_ids = tf.fill(dims=input_shape, value=0)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ past_key_values_length=past_key_values_length,
+ training=training,
+ )
+
+ # We create a 3D attention mask from a 2D tensor mask.
+ # Sizes are [batch_size, 1, 1, to_seq_length]
+ # So we can broadcast to [batch_size, num_heads, from_seq_length, to_seq_length]
+ # this attention mask is more simple than the triangular masking of causal attention
+ # used in OpenAI GPT, we just need to prepare the broadcast dimension here.
+ attention_mask_shape = shape_list(attention_mask)
+
+ mask_seq_length = seq_length + past_key_values_length
+ # Copied from `modeling_tf_t5.py`
+ # Provided a padding mask of dimensions [batch_size, mask_seq_length]
+ # - if the model is a decoder, apply a causal mask in addition to the padding mask
+ # - if the model is an encoder, make the mask broadcastable to [batch_size, num_heads, mask_seq_length, mask_seq_length]
+ if self.is_decoder:
+ seq_ids = tf.range(mask_seq_length)
+ causal_mask = tf.less_equal(
+ tf.tile(seq_ids[None, None, :], (batch_size, mask_seq_length, 1)),
+ seq_ids[None, :, None],
+ )
+ causal_mask = tf.cast(causal_mask, dtype=attention_mask.dtype)
+ extended_attention_mask = causal_mask * attention_mask[:, None, :]
+ attention_mask_shape = shape_list(extended_attention_mask)
+ extended_attention_mask = tf.reshape(
+ extended_attention_mask, (attention_mask_shape[0], 1, attention_mask_shape[1], attention_mask_shape[2])
+ )
+ if past_key_values[0] is not None:
+ # attention_mask needs to be sliced to the shape `[batch_size, 1, from_seq_length - cached_seq_length, to_seq_length]
+ extended_attention_mask = extended_attention_mask[:, :, -seq_length:, :]
+ else:
+ extended_attention_mask = tf.reshape(
+ attention_mask, (attention_mask_shape[0], 1, 1, attention_mask_shape[1])
+ )
+
+ # Since attention_mask is 1.0 for positions we want to attend and 0.0 for
+ # masked positions, this operation will create a tensor which is 0.0 for
+ # positions we want to attend and -10000.0 for masked positions.
+ # Since we are adding it to the raw scores before the softmax, this is
+ # effectively the same as removing these entirely.
+ extended_attention_mask = tf.cast(extended_attention_mask, dtype=embedding_output.dtype)
+ one_cst = tf.constant(1.0, dtype=embedding_output.dtype)
+ ten_thousand_cst = tf.constant(-10000.0, dtype=embedding_output.dtype)
+ extended_attention_mask = tf.multiply(tf.subtract(one_cst, extended_attention_mask), ten_thousand_cst)
+
+ # Copied from `modeling_tf_t5.py` with -1e9 -> -10000
+ if self.is_decoder and encoder_attention_mask is not None:
+ # If a 2D ou 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, mask_seq_length, mask_seq_length]
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ encoder_attention_mask = tf.cast(encoder_attention_mask, dtype=extended_attention_mask.dtype)
+ num_dims_encoder_attention_mask = len(shape_list(encoder_attention_mask))
+ if num_dims_encoder_attention_mask == 3:
+ encoder_extended_attention_mask = encoder_attention_mask[:, None, :, :]
+ if num_dims_encoder_attention_mask == 2:
+ encoder_extended_attention_mask = encoder_attention_mask[:, None, None, :]
+
+ # T5 has a mask that can compare sequence ids, we can simulate this here with this transposition
+ # Cf. https://github.com/tensorflow/mesh/blob/8d2465e9bc93129b913b5ccc6a59aa97abd96ec6/mesh_tensorflow/transformer/transformer_layers.py#L270
+ # encoder_extended_attention_mask = tf.math.equal(encoder_extended_attention_mask,
+ # tf.transpose(encoder_extended_attention_mask, perm=(-1, -2)))
+
+ encoder_extended_attention_mask = (1.0 - encoder_extended_attention_mask) * -10000.0
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ if head_mask is not None:
+ raise NotImplementedError
+ else:
+ head_mask = [None] * self.config.num_hidden_layers
+
+ encoder_outputs = self.encoder(
+ hidden_states=embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(hidden_states=sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (
+ sequence_output,
+ pooled_output,
+ ) + encoder_outputs[1:]
+
+ return TFBaseModelOutputWithPoolingAndCrossAttentions(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ past_key_values=encoder_outputs.past_key_values,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ cross_attentions=encoder_outputs.cross_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "encoder", None) is not None:
+ with tf.name_scope(self.encoder.name):
+ self.encoder.build(None)
+ if getattr(self, "pooler", None) is not None:
+ with tf.name_scope(self.pooler.name):
+ self.pooler.build(None)
+ if getattr(self, "embeddings", None) is not None:
+ with tf.name_scope(self.embeddings.name):
+ self.embeddings.build(None)
+
+
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaPreTrainedModel with Roberta->XLMRoberta
+class TFXLMRobertaPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = XLMRobertaConfig
+ base_model_prefix = "roberta"
+
+
+@add_start_docstrings(
+ "The bare XLM RoBERTa Model transformer outputting raw hidden-states without any specific head on top.",
+ XLM_ROBERTA_START_DOCSTRING,
+)
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaModel with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class TFXLMRobertaModel(TFXLMRobertaPreTrainedModel):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.roberta = TFXLMRobertaMainLayer(config, name="roberta")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFBaseModelOutputWithPoolingAndCrossAttentions,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ encoder_hidden_states: np.ndarray | tf.Tensor | None = None,
+ encoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool | None = False,
+ ) -> tuple | TFBaseModelOutputWithPoolingAndCrossAttentions:
+ r"""
+ encoder_hidden_states (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention if
+ the model is configured as a decoder.
+ encoder_attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on the padding token indices of the encoder input. This mask is used in
+ the cross-attention if the model is configured as a decoder. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ past_key_values (`tuple[tuple[tf.Tensor]]` of length `config.n_layers`)
+ contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`). Set to `False` during training, `True` during generation
+ """
+ outputs = self.roberta(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "roberta", None) is not None:
+ with tf.name_scope(self.roberta.name):
+ self.roberta.build(None)
+
+
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaLMHead with Roberta->XLMRoberta
+class TFXLMRobertaLMHead(keras.layers.Layer):
+ """XLMRoberta Head for masked language modeling."""
+
+ def __init__(self, config, input_embeddings, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.dense = keras.layers.Dense(
+ config.hidden_size, kernel_initializer=get_initializer(config.initializer_range), name="dense"
+ )
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.act = get_tf_activation("gelu")
+
+ # The output weights are the same as the input embeddings, but there is
+ # an output-only bias for each token.
+ self.decoder = input_embeddings
+
+ def build(self, input_shape=None):
+ self.bias = self.add_weight(shape=(self.config.vocab_size,), initializer="zeros", trainable=True, name="bias")
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.hidden_size])
+
+ def get_output_embeddings(self):
+ return self.decoder
+
+ def set_output_embeddings(self, value):
+ self.decoder.weight = value
+ self.decoder.vocab_size = shape_list(value)[0]
+
+ def get_bias(self):
+ return {"bias": self.bias}
+
+ def set_bias(self, value):
+ self.bias = value["bias"]
+ self.config.vocab_size = shape_list(value["bias"])[0]
+
+ def call(self, hidden_states):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.act(hidden_states)
+ hidden_states = self.layer_norm(hidden_states)
+
+ # project back to size of vocabulary with bias
+ seq_length = shape_list(tensor=hidden_states)[1]
+ hidden_states = tf.reshape(tensor=hidden_states, shape=[-1, self.hidden_size])
+ hidden_states = tf.matmul(a=hidden_states, b=self.decoder.weight, transpose_b=True)
+ hidden_states = tf.reshape(tensor=hidden_states, shape=[-1, seq_length, self.config.vocab_size])
+ hidden_states = tf.nn.bias_add(value=hidden_states, bias=self.bias)
+
+ return hidden_states
+
+
+@add_start_docstrings("""XLM RoBERTa Model with a `language modeling` head on top.""", XLM_ROBERTA_START_DOCSTRING)
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaForMaskedLM with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class TFXLMRobertaForMaskedLM(TFXLMRobertaPreTrainedModel, TFMaskedLanguageModelingLoss):
+ # names with a '.' represents the authorized unexpected/missing layers when a TF model is loaded from a PT model
+ _keys_to_ignore_on_load_unexpected = [r"pooler", r"lm_head.decoder.weight"]
+
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.roberta = TFXLMRobertaMainLayer(config, add_pooling_layer=False, name="roberta")
+ self.lm_head = TFXLMRobertaLMHead(config, self.roberta.embeddings, name="lm_head")
+
+ def get_lm_head(self):
+ return self.lm_head
+
+ def get_prefix_bias_name(self):
+ warnings.warn("The method get_prefix_bias_name is deprecated. Please use `get_bias` instead.", FutureWarning)
+ return self.name + "/" + self.lm_head.name
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFMaskedLMOutput,
+ config_class=_CONFIG_FOR_DOC,
+ mask="",
+ expected_output="' Paris'",
+ expected_loss=0.1,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFMaskedLMOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ """
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, prediction_scores)
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFMaskedLMOutput(
+ loss=loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "roberta", None) is not None:
+ with tf.name_scope(self.roberta.name):
+ self.roberta.build(None)
+ if getattr(self, "lm_head", None) is not None:
+ with tf.name_scope(self.lm_head.name):
+ self.lm_head.build(None)
+
+
+@add_start_docstrings(
+ "XLM-RoBERTa Model with a `language modeling` head on top for CLM fine-tuning.",
+ XLM_ROBERTA_START_DOCSTRING,
+)
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaForCausalLM with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class TFXLMRobertaForCausalLM(TFXLMRobertaPreTrainedModel, TFCausalLanguageModelingLoss):
+ # names with a '.' represents the authorized unexpected/missing layers when a TF model is loaded from a PT model
+ _keys_to_ignore_on_load_unexpected = [r"pooler", r"lm_head.decoder.weight"]
+
+ def __init__(self, config: XLMRobertaConfig, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ if not config.is_decoder:
+ logger.warning("If you want to use `TFXLMRobertaLMHeadModel` as a standalone, add `is_decoder=True.`")
+
+ self.roberta = TFXLMRobertaMainLayer(config, add_pooling_layer=False, name="roberta")
+ self.lm_head = TFXLMRobertaLMHead(config, input_embeddings=self.roberta.embeddings, name="lm_head")
+
+ def get_lm_head(self):
+ return self.lm_head
+
+ def get_prefix_bias_name(self):
+ warnings.warn("The method get_prefix_bias_name is deprecated. Please use `get_bias` instead.", FutureWarning)
+ return self.name + "/" + self.lm_head.name
+
+ # Copied from transformers.models.bert.modeling_tf_bert.TFBertLMHeadModel.prepare_inputs_for_generation
+ def prepare_inputs_for_generation(self, input_ids, past_key_values=None, attention_mask=None, **model_kwargs):
+ input_shape = input_ids.shape
+ # if model is used as a decoder in encoder-decoder model, the decoder attention mask is created on the fly
+ if attention_mask is None:
+ attention_mask = tf.ones(input_shape)
+
+ # cut decoder_input_ids if past is used
+ if past_key_values is not None:
+ input_ids = input_ids[:, -1:]
+
+ return {"input_ids": input_ids, "attention_mask": attention_mask, "past_key_values": past_key_values}
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFCausalLMOutputWithCrossAttentions,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ encoder_hidden_states: np.ndarray | tf.Tensor | None = None,
+ encoder_attention_mask: np.ndarray | tf.Tensor | None = None,
+ past_key_values: tuple[tuple[np.ndarray | tf.Tensor]] | None = None,
+ use_cache: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFCausalLMOutputWithCrossAttentions | tuple[tf.Tensor]:
+ r"""
+ encoder_hidden_states (`tf.Tensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention if
+ the model is configured as a decoder.
+ encoder_attention_mask (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Mask to avoid performing attention on the padding token indices of the encoder input. This mask is used in
+ the cross-attention if the model is configured as a decoder. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ past_key_values (`tuple[tuple[tf.Tensor]]` of length `config.n_layers`)
+ contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
+ If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that
+ don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of all
+ `decoder_input_ids` of shape `(batch_size, sequence_length)`.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see
+ `past_key_values`). Set to `False` during training, `True` during generation
+ labels (`tf.Tensor` or `np.ndarray` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the cross entropy classification loss. Indices should be in `[0, ...,
+ config.vocab_size - 1]`.
+ """
+ outputs = self.roberta(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ sequence_output = outputs[0]
+ logits = self.lm_head(hidden_states=sequence_output, training=training)
+ loss = None
+
+ if labels is not None:
+ # shift labels to the left and cut last logit token
+ shifted_logits = logits[:, :-1]
+ labels = labels[:, 1:]
+ loss = self.hf_compute_loss(labels=labels, logits=shifted_logits)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFCausalLMOutputWithCrossAttentions(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "roberta", None) is not None:
+ with tf.name_scope(self.roberta.name):
+ self.roberta.build(None)
+ if getattr(self, "lm_head", None) is not None:
+ with tf.name_scope(self.lm_head.name):
+ self.lm_head.build(None)
+
+
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaClassificationHead with Roberta->XLMRoberta
+class TFXLMRobertaClassificationHead(keras.layers.Layer):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ self.dense = keras.layers.Dense(
+ config.hidden_size,
+ kernel_initializer=get_initializer(config.initializer_range),
+ activation="tanh",
+ name="dense",
+ )
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = keras.layers.Dropout(classifier_dropout)
+ self.out_proj = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="out_proj"
+ )
+ self.config = config
+
+ def call(self, features, training=False):
+ x = features[:, 0, :] # take token (equiv. to [CLS])
+ x = self.dropout(x, training=training)
+ x = self.dense(x)
+ x = self.dropout(x, training=training)
+ x = self.out_proj(x)
+ return x
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "dense", None) is not None:
+ with tf.name_scope(self.dense.name):
+ self.dense.build([None, None, self.config.hidden_size])
+ if getattr(self, "out_proj", None) is not None:
+ with tf.name_scope(self.out_proj.name):
+ self.out_proj.build([None, None, self.config.hidden_size])
+
+
+@add_start_docstrings(
+ """
+ XLM RoBERTa Model transformer with a sequence classification/regression head on top (a linear layer on top of the
+ pooled output) e.g. for GLUE tasks.
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaForSequenceClassification with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class TFXLMRobertaForSequenceClassification(TFXLMRobertaPreTrainedModel, TFSequenceClassificationLoss):
+ # names with a '.' represents the authorized unexpected/missing layers when a TF model is loaded from a PT model
+ _keys_to_ignore_on_load_unexpected = [r"pooler", r"lm_head"]
+
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.roberta = TFXLMRobertaMainLayer(config, add_pooling_layer=False, name="roberta")
+ self.classifier = TFXLMRobertaClassificationHead(config, name="classifier")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint="cardiffnlp/twitter-roberta-base-emotion",
+ output_type=TFSequenceClassifierOutput,
+ config_class=_CONFIG_FOR_DOC,
+ expected_output="'optimism'",
+ expected_loss=0.08,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFSequenceClassifierOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = outputs[0]
+ logits = self.classifier(sequence_output, training=training)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFSequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "roberta", None) is not None:
+ with tf.name_scope(self.roberta.name):
+ self.roberta.build(None)
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build(None)
+
+
+@add_start_docstrings(
+ """
+ XLM Roberta Model with a multiple choice classification head on top (a linear layer on top of the pooled output and
+ a softmax) e.g. for RocStories/SWAG tasks.
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaForMultipleChoice with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class TFXLMRobertaForMultipleChoice(TFXLMRobertaPreTrainedModel, TFMultipleChoiceLoss):
+ # names with a '.' represents the authorized unexpected/missing layers when a TF model is loaded from a PT model
+ _keys_to_ignore_on_load_unexpected = [r"lm_head"]
+ _keys_to_ignore_on_load_missing = [r"dropout"]
+
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.roberta = TFXLMRobertaMainLayer(config, name="roberta")
+ self.dropout = keras.layers.Dropout(config.hidden_dropout_prob)
+ self.classifier = keras.layers.Dense(
+ 1, kernel_initializer=get_initializer(config.initializer_range), name="classifier"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(
+ XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, num_choices, sequence_length")
+ )
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFMultipleChoiceModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFMultipleChoiceModelOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., num_choices]`
+ where `num_choices` is the size of the second dimension of the input tensors. (See `input_ids` above)
+ """
+
+ if input_ids is not None:
+ num_choices = shape_list(input_ids)[1]
+ seq_length = shape_list(input_ids)[2]
+ else:
+ num_choices = shape_list(inputs_embeds)[1]
+ seq_length = shape_list(inputs_embeds)[2]
+
+ flat_input_ids = tf.reshape(input_ids, (-1, seq_length)) if input_ids is not None else None
+ flat_attention_mask = tf.reshape(attention_mask, (-1, seq_length)) if attention_mask is not None else None
+ flat_token_type_ids = tf.reshape(token_type_ids, (-1, seq_length)) if token_type_ids is not None else None
+ flat_position_ids = tf.reshape(position_ids, (-1, seq_length)) if position_ids is not None else None
+ outputs = self.roberta(
+ flat_input_ids,
+ flat_attention_mask,
+ flat_token_type_ids,
+ flat_position_ids,
+ head_mask,
+ inputs_embeds,
+ output_attentions,
+ output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ pooled_output = outputs[1]
+ pooled_output = self.dropout(pooled_output, training=training)
+ logits = self.classifier(pooled_output)
+ reshaped_logits = tf.reshape(logits, (-1, num_choices))
+
+ loss = None if labels is None else self.hf_compute_loss(labels, reshaped_logits)
+
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFMultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "roberta", None) is not None:
+ with tf.name_scope(self.roberta.name):
+ self.roberta.build(None)
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.config.hidden_size])
+
+
+@add_start_docstrings(
+ """
+ XLM RoBERTa Model with a token classification head on top (a linear layer on top of the hidden-states output) e.g.
+ for Named-Entity-Recognition (NER) tasks.
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaForTokenClassification with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class TFXLMRobertaForTokenClassification(TFXLMRobertaPreTrainedModel, TFTokenClassificationLoss):
+ # names with a '.' represents the authorized unexpected/missing layers when a TF model is loaded from a PT model
+ _keys_to_ignore_on_load_unexpected = [r"pooler", r"lm_head"]
+ _keys_to_ignore_on_load_missing = [r"dropout"]
+
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.roberta = TFXLMRobertaMainLayer(config, add_pooling_layer=False, name="roberta")
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = keras.layers.Dropout(classifier_dropout)
+ self.classifier = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="classifier"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint="ydshieh/roberta-large-ner-english",
+ output_type=TFTokenClassifierOutput,
+ config_class=_CONFIG_FOR_DOC,
+ expected_output="['O', 'ORG', 'ORG', 'O', 'O', 'O', 'O', 'O', 'LOC', 'O', 'LOC', 'LOC']",
+ expected_loss=0.01,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFTokenClassifierOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = outputs[0]
+
+ sequence_output = self.dropout(sequence_output, training=training)
+ logits = self.classifier(sequence_output)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFTokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "roberta", None) is not None:
+ with tf.name_scope(self.roberta.name):
+ self.roberta.build(None)
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.config.hidden_size])
+
+
+@add_start_docstrings(
+ """
+ XLM RoBERTa Model with a span classification head on top for extractive question-answering tasks like SQuAD (a
+ linear layers on top of the hidden-states output to compute `span start logits` and `span end logits`).
+ """,
+ XLM_ROBERTA_START_DOCSTRING,
+)
+# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaForQuestionAnswering with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class TFXLMRobertaForQuestionAnswering(TFXLMRobertaPreTrainedModel, TFQuestionAnsweringLoss):
+ # names with a '.' represents the authorized unexpected/missing layers when a TF model is loaded from a PT model
+ _keys_to_ignore_on_load_unexpected = [r"pooler", r"lm_head"]
+
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.roberta = TFXLMRobertaMainLayer(config, add_pooling_layer=False, name="roberta")
+ self.qa_outputs = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="qa_outputs"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLM_ROBERTA_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint="ydshieh/roberta-base-squad2",
+ output_type=TFQuestionAnsweringModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ expected_output="' puppet'",
+ expected_loss=0.86,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ position_ids: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ start_positions: np.ndarray | tf.Tensor | None = None,
+ end_positions: np.ndarray | tf.Tensor | None = None,
+ training: bool | None = False,
+ ) -> TFQuestionAnsweringModelOutput | tuple[tf.Tensor]:
+ r"""
+ start_positions (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the start of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ end_positions (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the end of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ """
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = tf.split(logits, 2, axis=-1)
+ start_logits = tf.squeeze(start_logits, axis=-1)
+ end_logits = tf.squeeze(end_logits, axis=-1)
+
+ loss = None
+ if start_positions is not None and end_positions is not None:
+ labels = {"start_position": start_positions}
+ labels["end_position"] = end_positions
+ loss = self.hf_compute_loss(labels, (start_logits, end_logits))
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFQuestionAnsweringModelOutput(
+ loss=loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "roberta", None) is not None:
+ with tf.name_scope(self.roberta.name):
+ self.roberta.build(None)
+ if getattr(self, "qa_outputs", None) is not None:
+ with tf.name_scope(self.qa_outputs.name):
+ self.qa_outputs.build([None, None, self.config.hidden_size])
+
+
+__all__ = [
+ "TFXLMRobertaForCausalLM",
+ "TFXLMRobertaForMaskedLM",
+ "TFXLMRobertaForMultipleChoice",
+ "TFXLMRobertaForQuestionAnswering",
+ "TFXLMRobertaForSequenceClassification",
+ "TFXLMRobertaForTokenClassification",
+ "TFXLMRobertaModel",
+ "TFXLMRobertaPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_xlm_roberta.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_xlm_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..facfd3a6003914d2cef9a4606067131631392871
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/modeling_xlm_roberta.py
@@ -0,0 +1,1561 @@
+# coding=utf-8
+# Copyright 2019 Facebook AI Research and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch XLM-RoBERTa model."""
+
+import math
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN, gelu
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask_for_sdpa, _prepare_4d_causal_attention_mask_for_sdpa
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutputWithPastAndCrossAttentions,
+ BaseModelOutputWithPoolingAndCrossAttentions,
+ CausalLMOutputWithCrossAttentions,
+ MaskedLMOutput,
+ MultipleChoiceModelOutput,
+ QuestionAnsweringModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_xlm_roberta import XLMRobertaConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaEmbeddings with Roberta->XLMRoberta
+class XLMRobertaEmbeddings(nn.Module):
+ """
+ Same as BertEmbeddings with a tiny tweak for positional embeddings indexing.
+ """
+
+ # Copied from transformers.models.bert.modeling_bert.BertEmbeddings.__init__
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+ self.register_buffer(
+ "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False
+ )
+
+ # End copy
+ self.padding_idx = config.pad_token_id
+ self.position_embeddings = nn.Embedding(
+ config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx
+ )
+
+ def forward(
+ self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None, past_key_values_length=0
+ ):
+ if position_ids is None:
+ if input_ids is not None:
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = create_position_ids_from_input_ids(input_ids, self.padding_idx, past_key_values_length)
+ else:
+ position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds)
+
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs
+ # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves
+ # issue #5664
+ if token_type_ids is None:
+ if hasattr(self, "token_type_ids"):
+ buffered_token_type_ids = self.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(input_shape[0], seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+ def create_position_ids_from_inputs_embeds(self, inputs_embeds):
+ """
+ We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids.
+
+ Args:
+ inputs_embeds: torch.Tensor
+
+ Returns: torch.Tensor
+ """
+ input_shape = inputs_embeds.size()[:-1]
+ sequence_length = input_shape[1]
+
+ position_ids = torch.arange(
+ self.padding_idx + 1, sequence_length + self.padding_idx + 1, dtype=torch.long, device=inputs_embeds.device
+ )
+ return position_ids.unsqueeze(0).expand(input_shape)
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaSelfAttention with Roberta->XLMRoberta
+class XLMRobertaSelfAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.position_embedding_type = position_embedding_type or getattr(
+ config, "position_embedding_type", "absolute"
+ )
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ self.max_position_embeddings = config.max_position_embeddings
+ self.distance_embedding = nn.Embedding(2 * config.max_position_embeddings - 1, self.attention_head_size)
+
+ self.is_decoder = config.is_decoder
+ self.layer_idx = layer_idx
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = self.query(hidden_states)
+ query_layer = query_layer.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(
+ 1, 2
+ )
+
+ is_cross_attention = encoder_hidden_states is not None
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_layer from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_layer = curr_past_key_value.layers[self.layer_idx].keys
+ value_layer = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_layer = self.key(current_states)
+ key_layer = key_layer.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(
+ 1, 2
+ )
+ value_layer = self.value(current_states)
+ value_layer = value_layer.view(
+ batch_size, -1, self.num_attention_heads, self.attention_head_size
+ ).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_layer to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_layer, value_layer = curr_past_key_value.update(
+ key_layer, value_layer, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ query_length, key_length = query_layer.shape[2], key_layer.shape[2]
+ if past_key_values is not None:
+ position_ids_l = torch.tensor(key_length - 1, dtype=torch.long, device=hidden_states.device).view(
+ -1, 1
+ )
+ else:
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_l - position_ids_r
+
+ positional_embedding = self.distance_embedding(distance + self.max_position_embeddings - 1)
+ positional_embedding = positional_embedding.to(dtype=query_layer.dtype) # fp16 compatibility
+
+ if self.position_embedding_type == "relative_key":
+ relative_position_scores = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores
+ elif self.position_embedding_type == "relative_key_query":
+ relative_position_scores_query = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ relative_position_scores_key = torch.einsum("bhrd,lrd->bhlr", key_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores_query + relative_position_scores_key
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in XLMRobertaModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaSdpaSelfAttention with Roberta->XLMRoberta
+class XLMRobertaSdpaSelfAttention(XLMRobertaSelfAttention):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__(config, position_embedding_type=position_embedding_type, layer_idx=layer_idx)
+ self.dropout_prob = config.attention_probs_dropout_prob
+
+ # Adapted from XLMRobertaSelfAttention
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ if self.position_embedding_type != "absolute" or output_attentions or head_mask is not None:
+ # TODO: Improve this warning with e.g. `model.config._attn_implementation = "manual"` once implemented.
+ logger.warning_once(
+ "XLMRobertaSdpaSelfAttention is used but `torch.nn.functional.scaled_dot_product_attention` does not support "
+ "non-absolute `position_embedding_type` or `output_attentions=True` or `head_mask`. Falling back to "
+ "the manual attention implementation, but specifying the manual implementation will be required from "
+ "Transformers version v5.0.0 onwards. This warning can be removed using the argument "
+ '`attn_implementation="eager"` when loading the model.'
+ )
+ return super().forward(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ past_key_values,
+ output_attentions,
+ cache_position,
+ )
+
+ bsz, tgt_len, _ = hidden_states.size()
+
+ query_layer = (
+ self.query(hidden_states).view(bsz, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ )
+
+ is_cross_attention = encoder_hidden_states is not None
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_layer = curr_past_key_value.layers[self.layer_idx].keys
+ value_layer = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_layer = (
+ self.key(current_states)
+ .view(bsz, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(current_states)
+ .view(bsz, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ if past_key_values is not None:
+ # save all key/value_layer to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_layer, value_layer = curr_past_key_value.update(
+ key_layer, value_layer, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # We dispatch to SDPA's Flash Attention or Efficient kernels via this `is_causal` if statement instead of an inline conditional assignment
+ # in SDPA to support both torch.compile's dynamic shapes and full graph options. An inline conditional prevents dynamic shapes from compiling.
+ # The tgt_len > 1 is necessary to match with AttentionMaskConverter.to_causal_4d that does not create
+ # a causal mask in case tgt_len == 1.
+ is_causal = self.is_decoder and not is_cross_attention and attention_mask is None and tgt_len > 1
+
+ attn_output = torch.nn.functional.scaled_dot_product_attention(
+ query_layer,
+ key_layer,
+ value_layer,
+ attn_mask=attention_mask,
+ dropout_p=self.dropout_prob if self.training else 0.0,
+ is_causal=is_causal,
+ )
+
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, self.all_head_size)
+
+ return attn_output, None
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaSelfOutput with Roberta->XLMRoberta
+class XLMRobertaSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+XLM_ROBERTA_SELF_ATTENTION_CLASSES = {
+ "eager": XLMRobertaSelfAttention,
+ "sdpa": XLMRobertaSdpaSelfAttention,
+}
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaAttention with Roberta->XLMRoberta,ROBERTA->XLM_ROBERTA
+class XLMRobertaAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__()
+ self.self = XLM_ROBERTA_SELF_ATTENTION_CLASSES[config._attn_implementation](
+ config,
+ position_embedding_type=position_embedding_type,
+ layer_idx=layer_idx,
+ )
+ self.output = XLMRobertaSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaIntermediate with Roberta->XLMRoberta
+class XLMRobertaIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaOutput with Roberta->XLMRoberta
+class XLMRobertaOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaLayer with Roberta->XLMRoberta
+class XLMRobertaLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_idx=None):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = XLMRobertaAttention(config, layer_idx=layer_idx)
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = XLMRobertaAttention(config, position_embedding_type="absolute", layer_idx=layer_idx)
+ self.intermediate = XLMRobertaIntermediate(config)
+ self.output = XLMRobertaOutput(config)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+ attention_output = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ cross_attention_outputs = self.crossattention(
+ attention_output,
+ attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:] # add cross attentions if we output attention weights
+
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaEncoder with Roberta->XLMRoberta
+class XLMRobertaEncoder(nn.Module):
+ def __init__(self, config, layer_idx=None):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([XLMRobertaLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutputWithPastAndCrossAttentions]:
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None
+
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ if use_cache and self.config.is_decoder and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+
+ if use_cache and self.config.is_decoder and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states, # as a positional argument for gradient checkpointing
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+ if self.config.add_cross_attention:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ past_key_values,
+ all_hidden_states,
+ all_self_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaPooler with Roberta->XLMRoberta
+class XLMRobertaPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+@auto_docstring
+# Copied from transformers.models.roberta.modeling_roberta.RobertaPreTrainedModel with Roberta->XLMRoberta
+class XLMRobertaPreTrainedModel(PreTrainedModel):
+ config: XLMRobertaConfig
+ base_model_prefix = "roberta"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["XLMRobertaEmbeddings", "XLMRobertaSelfAttention", "XLMRobertaSdpaSelfAttention"]
+ _supports_sdpa = True
+
+ # Copied from transformers.models.bert.modeling_bert.BertPreTrainedModel._init_weights with BertLMPredictionHead->XLMRobertaLMHead
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, XLMRobertaLMHead):
+ module.bias.data.zero_()
+
+
+@auto_docstring
+# Copied from transformers.models.roberta.modeling_roberta.RobertaModel with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class XLMRobertaModel(XLMRobertaPreTrainedModel):
+ _no_split_modules = ["XLMRobertaEmbeddings", "XLMRobertaLayer"]
+
+ def __init__(self, config, add_pooling_layer=True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = XLMRobertaEmbeddings(config)
+ self.encoder = XLMRobertaEncoder(config)
+
+ self.pooler = XLMRobertaPooler(config) if add_pooling_layer else None
+
+ self.attn_implementation = config._attn_implementation
+ self.position_embedding_type = config.position_embedding_type
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutputWithPoolingAndCrossAttentions]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if self.config.is_decoder:
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ else:
+ use_cache = False
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ past_key_values_length = 0
+ if past_key_values is not None:
+ past_key_values_length = (
+ past_key_values[0][0].shape[-2]
+ if not isinstance(past_key_values, Cache)
+ else past_key_values.get_seq_length()
+ )
+
+ if token_type_ids is None:
+ if hasattr(self.embeddings, "token_type_ids"):
+ buffered_token_type_ids = self.embeddings.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(batch_size, seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ past_key_values_length=past_key_values_length,
+ )
+
+ if attention_mask is None:
+ attention_mask = torch.ones((batch_size, seq_length + past_key_values_length), device=device)
+
+ use_sdpa_attention_masks = (
+ self.attn_implementation == "sdpa"
+ and self.position_embedding_type == "absolute"
+ and head_mask is None
+ and not output_attentions
+ )
+
+ # Expand the attention mask
+ if use_sdpa_attention_masks and attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ if self.config.is_decoder:
+ extended_attention_mask = _prepare_4d_causal_attention_mask_for_sdpa(
+ attention_mask,
+ input_shape,
+ embedding_output,
+ past_key_values_length,
+ )
+ else:
+ extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.config.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
+
+ if use_sdpa_attention_masks and encoder_attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ encoder_extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ encoder_attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPoolingAndCrossAttentions(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ past_key_values=encoder_outputs.past_key_values,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ cross_attentions=encoder_outputs.cross_attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ XLM-RoBERTa Model with a `language modeling` head on top for CLM fine-tuning.
+ """
+)
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForCausalLM with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class XLMRobertaForCausalLM(XLMRobertaPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.decoder.weight", "lm_head.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ if not config.is_decoder:
+ logger.warning("If you want to use `XLMRobertaLMHeadModel` as a standalone, add `is_decoder=True.`")
+
+ self.roberta = XLMRobertaModel(config, add_pooling_layer=False)
+ self.lm_head = XLMRobertaLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.lm_head.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.decoder = new_embeddings
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[tuple[torch.Tensor], CausalLMOutputWithCrossAttentions]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value
+ >= 2. All the value in this tensor should be always < type_vocab_size.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in
+ `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are
+ ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, XLMRobertaForCausalLM, AutoConfig
+ >>> import torch
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("FacebookAI/roberta-base")
+ >>> config = AutoConfig.from_pretrained("FacebookAI/roberta-base")
+ >>> config.is_decoder = True
+ >>> model = XLMRobertaForCausalLM.from_pretrained("FacebookAI/roberta-base", config=config)
+
+ >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt")
+ >>> outputs = model(**inputs)
+
+ >>> prediction_logits = outputs.logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ if labels is not None:
+ use_cache = False
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+
+ lm_loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(prediction_scores.device)
+ lm_loss = self.loss_function(
+ prediction_scores,
+ labels,
+ vocab_size=self.config.vocab_size,
+ **kwargs,
+ )
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((lm_loss,) + output) if lm_loss is not None else output
+
+ return CausalLMOutputWithCrossAttentions(
+ loss=lm_loss,
+ logits=prediction_scores,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+@auto_docstring
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class XLMRobertaForMaskedLM(XLMRobertaPreTrainedModel):
+ _tied_weights_keys = ["lm_head.decoder.weight", "lm_head.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ if config.is_decoder:
+ logger.warning(
+ "If you want to use `XLMRobertaForMaskedLM` make sure `config.is_decoder=False` for "
+ "bi-directional self-attention."
+ )
+
+ self.roberta = XLMRobertaModel(config, add_pooling_layer=False)
+ self.lm_head = XLMRobertaLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.lm_head.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.decoder = new_embeddings
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], MaskedLMOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value
+ >= 2. All the value in this tensor should be always < type_vocab_size.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+
+ masked_lm_loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(prediction_scores.device)
+ loss_fct = CrossEntropyLoss()
+ masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return MaskedLMOutput(
+ loss=masked_lm_loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaLMHead
+class XLMRobertaLMHead(nn.Module):
+ """Roberta Head for masked language modeling."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size)
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+ self.decoder.bias = self.bias
+
+ def forward(self, features, **kwargs):
+ x = self.dense(features)
+ x = gelu(x)
+ x = self.layer_norm(x)
+
+ # project back to size of vocabulary with bias
+ x = self.decoder(x)
+
+ return x
+
+ def _tie_weights(self):
+ # To tie those two weights if they get disconnected (on TPU or when the bias is resized)
+ # For accelerate compatibility and to not break backward compatibility
+ if self.decoder.bias.device.type == "meta":
+ self.decoder.bias = self.bias
+ else:
+ self.bias = self.decoder.bias
+
+
+@auto_docstring(
+ custom_intro="""
+ XLM-RoBERTa Model transformer with a sequence classification/regression head on top (a linear layer on top of the
+ pooled output) e.g. for GLUE tasks.
+ """
+)
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForSequenceClassification with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class XLMRobertaForSequenceClassification(XLMRobertaPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.config = config
+
+ self.roberta = XLMRobertaModel(config, add_pooling_layer=False)
+ self.classifier = XLMRobertaClassificationHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], SequenceClassifierOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value
+ >= 2. All the value in this tensor should be always < type_vocab_size.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForMultipleChoice with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class XLMRobertaForMultipleChoice(XLMRobertaPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.roberta = XLMRobertaModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], MultipleChoiceModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value
+ >= 2. All the value in this tensor should be always < type_vocab_size.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See
+ `input_ids` above)
+ position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ flat_input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ flat_position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None
+ flat_token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ flat_attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ flat_inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ outputs = self.roberta(
+ flat_input_ids,
+ position_ids=flat_position_ids,
+ token_type_ids=flat_token_type_ids,
+ attention_mask=flat_attention_mask,
+ head_mask=head_mask,
+ inputs_embeds=flat_inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(reshaped_logits.device)
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels)
+
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return MultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForTokenClassification with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class XLMRobertaForTokenClassification(XLMRobertaPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.roberta = XLMRobertaModel(config, add_pooling_layer=False)
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(classifier_dropout)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], TokenClassifierOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value
+ >= 2. All the value in this tensor should be always < type_vocab_size.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ sequence_output = self.dropout(sequence_output)
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(logits.device)
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaClassificationHead with Roberta->XLMRoberta
+class XLMRobertaClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(classifier_dropout)
+ self.out_proj = nn.Linear(config.hidden_size, config.num_labels)
+
+ def forward(self, features, **kwargs):
+ x = features[:, 0, :] # take token (equiv. to [CLS])
+ x = self.dropout(x)
+ x = self.dense(x)
+ x = torch.tanh(x)
+ x = self.dropout(x)
+ x = self.out_proj(x)
+ return x
+
+
+@auto_docstring
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForQuestionAnswering with Roberta->XLMRoberta, ROBERTA->XLM_ROBERTA
+class XLMRobertaForQuestionAnswering(XLMRobertaPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.roberta = XLMRobertaModel(config, add_pooling_layer=False)
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], QuestionAnsweringModelOutput]:
+ r"""
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value
+ >= 2. All the value in this tensor should be always < type_vocab_size.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[2:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return QuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.create_position_ids_from_input_ids
+def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols
+ are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ x: torch.Tensor x:
+
+ Returns: torch.Tensor
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = input_ids.ne(padding_idx).int()
+ incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask
+ return incremental_indices.long() + padding_idx
+
+
+__all__ = [
+ "XLMRobertaForCausalLM",
+ "XLMRobertaForMaskedLM",
+ "XLMRobertaForMultipleChoice",
+ "XLMRobertaForQuestionAnswering",
+ "XLMRobertaForSequenceClassification",
+ "XLMRobertaForTokenClassification",
+ "XLMRobertaModel",
+ "XLMRobertaPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/tokenization_xlm_roberta.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/tokenization_xlm_roberta.py
new file mode 100644
index 0000000000000000000000000000000000000000..149a09f5ed61a67e52f7f0a1170b5d70b99a6bb6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/tokenization_xlm_roberta.py
@@ -0,0 +1,301 @@
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License
+"""Tokenization classes for XLM-RoBERTa model."""
+
+import os
+from shutil import copyfile
+from typing import Any, Optional
+
+import sentencepiece as spm
+
+from ...tokenization_utils import AddedToken, PreTrainedTokenizer
+from ...utils import logging
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+SPIECE_UNDERLINE = "▁"
+
+VOCAB_FILES_NAMES = {"vocab_file": "sentencepiece.bpe.model"}
+
+
+@requires(backends=("sentencepiece",))
+class XLMRobertaTokenizer(PreTrainedTokenizer):
+ """
+ Adapted from [`RobertaTokenizer`] and [`XLNetTokenizer`]. Based on
+ [SentencePiece](https://github.com/google/sentencepiece).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ Path to the vocabulary file.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the beginning of
+ sequence. The token used is the `cls_token`.
+
+
+
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ sep_token (`str`, *optional*, defaults to `" "`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ cls_token (`str`, *optional*, defaults to `""`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ mask_token (`str`, *optional*, defaults to `""`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+
+ Attributes:
+ sp_model (`SentencePieceProcessor`):
+ The *SentencePiece* processor that is used for every conversion (string, tokens and IDs).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+
+ def __init__(
+ self,
+ vocab_file,
+ bos_token="",
+ eos_token=" ",
+ sep_token=" ",
+ cls_token="",
+ unk_token="",
+ pad_token="",
+ mask_token="",
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ **kwargs,
+ ) -> None:
+ # Mask token behave like a normal word, i.e. include the space before it
+ mask_token = AddedToken(mask_token, lstrip=True, special=True) if isinstance(mask_token, str) else mask_token
+
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(str(vocab_file))
+ self.vocab_file = vocab_file
+
+ # Original fairseq vocab and spm vocab must be "aligned":
+ # Vocab | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9
+ # -------- | ------- | ------- | ------ | ------- | --- | --- | --- | ----- | ----- | ----
+ # fairseq | '' | '' | ' ' | '' | ',' | '.' | '▁' | 's' | '▁de' | '-'
+ # spm | '' | '' | ' ' | ',' | '.' | '▁' | 's' | '▁de' | '-' | '▁a'
+
+ # Mimic fairseq token-to-id alignment for the first 4 token
+ self.fairseq_tokens_to_ids = {"": 0, "": 1, " ": 2, "": 3}
+
+ # The first "real" token "," has position 4 in the original fairseq vocab and position 3 in the spm vocab
+ self.fairseq_offset = 1
+
+ self.fairseq_tokens_to_ids[""] = len(self.sp_model) + self.fairseq_offset
+ self.fairseq_ids_to_tokens = {v: k for k, v in self.fairseq_tokens_to_ids.items()}
+
+ super().__init__(
+ bos_token=bos_token,
+ eos_token=eos_token,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ cls_token=cls_token,
+ pad_token=pad_token,
+ mask_token=mask_token,
+ sp_model_kwargs=self.sp_model_kwargs,
+ **kwargs,
+ )
+
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ state["sp_model_proto"] = self.sp_model.serialized_model_proto()
+ return state
+
+ def __setstate__(self, d):
+ self.__dict__ = d
+
+ # for backward compatibility
+ if not hasattr(self, "sp_model_kwargs"):
+ self.sp_model_kwargs = {}
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.LoadFromSerializedProto(self.sp_model_proto)
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLM-RoBERTa sequence has the following format:
+
+ - single sequence: ` X `
+ - pair of sequences: ` A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+
+ if token_ids_1 is None:
+ return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
+ cls = [self.cls_token_id]
+ sep = [self.sep_token_id]
+ return cls + token_ids_0 + sep + sep + token_ids_1 + sep
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ if token_ids_1 is None:
+ return [1] + ([0] * len(token_ids_0)) + [1]
+ return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1]
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. XLM-RoBERTa does
+ not make use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+
+ """
+
+ sep = [self.sep_token_id]
+ cls = [self.cls_token_id]
+
+ if token_ids_1 is None:
+ return len(cls + token_ids_0 + sep) * [0]
+ return len(cls + token_ids_0 + sep + sep + token_ids_1 + sep) * [0]
+
+ @property
+ def vocab_size(self):
+ return len(self.sp_model) + self.fairseq_offset + 1 # Add the token
+
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def _tokenize(self, text: str) -> list[str]:
+ # TODO check if the t5/llama PR also applies here
+ return self.sp_model.encode(text, out_type=str)
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ if token in self.fairseq_tokens_to_ids:
+ return self.fairseq_tokens_to_ids[token]
+ spm_id = self.sp_model.PieceToId(token)
+
+ # Need to return unknown token if the SP model returned 0
+ return spm_id + self.fairseq_offset if spm_id else self.unk_token_id
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ if index in self.fairseq_ids_to_tokens:
+ return self.fairseq_ids_to_tokens[index]
+ return self.sp_model.IdToPiece(index - self.fairseq_offset)
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (strings for sub-words) in a single string."""
+ out_string = "".join(tokens).replace(SPIECE_UNDERLINE, " ").strip()
+ return out_string
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ elif not os.path.isfile(self.vocab_file):
+ with open(out_vocab_file, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["XLMRobertaTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/tokenization_xlm_roberta_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/tokenization_xlm_roberta_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..bcdea2325fc1ed14bd1b152f06ed619582e5e65c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta/tokenization_xlm_roberta_fast.py
@@ -0,0 +1,194 @@
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License
+"""Tokenization classes for XLM-RoBERTa model."""
+
+import os
+from shutil import copyfile
+from typing import Optional
+
+from ...tokenization_utils import AddedToken
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import is_sentencepiece_available, logging
+
+
+if is_sentencepiece_available():
+ from .tokenization_xlm_roberta import XLMRobertaTokenizer
+else:
+ XLMRobertaTokenizer = None
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "sentencepiece.bpe.model", "tokenizer_file": "tokenizer.json"}
+
+
+class XLMRobertaTokenizerFast(PreTrainedTokenizerFast):
+ """
+ Construct a "fast" XLM-RoBERTa tokenizer (backed by HuggingFace's *tokenizers* library). Adapted from
+ [`RobertaTokenizer`] and [`XLNetTokenizer`]. Based on
+ [BPE](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=BPE#models).
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ Path to the vocabulary file.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the beginning of
+ sequence. The token used is the `cls_token`.
+
+
+
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ sep_token (`str`, *optional*, defaults to `" "`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ cls_token (`str`, *optional*, defaults to `""`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ mask_token (`str`, *optional*, defaults to `""`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ additional_special_tokens (`list[str]`, *optional*, defaults to `["NOTUSED", " NOTUSED"]`):
+ Additional special tokens used by the tokenizer.
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ model_input_names = ["input_ids", "attention_mask"]
+ slow_tokenizer_class = XLMRobertaTokenizer
+
+ def __init__(
+ self,
+ vocab_file=None,
+ tokenizer_file=None,
+ bos_token="",
+ eos_token=" ",
+ sep_token=" ",
+ cls_token="",
+ unk_token="",
+ pad_token="",
+ mask_token="",
+ **kwargs,
+ ):
+ # Mask token behave like a normal word, i.e. include the space before it
+ mask_token = AddedToken(mask_token, lstrip=True, rstrip=False) if isinstance(mask_token, str) else mask_token
+
+ super().__init__(
+ vocab_file,
+ tokenizer_file=tokenizer_file,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ sep_token=sep_token,
+ cls_token=cls_token,
+ unk_token=unk_token,
+ pad_token=pad_token,
+ mask_token=mask_token,
+ **kwargs,
+ )
+
+ self.vocab_file = vocab_file
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLM-RoBERTa sequence has the following format:
+
+ - single sequence: ` X `
+ - pair of sequences: ` A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+
+ if token_ids_1 is None:
+ return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
+ cls = [self.cls_token_id]
+ sep = [self.sep_token_id]
+ return cls + token_ids_0 + sep + sep + token_ids_1 + sep
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. XLM-RoBERTa does
+ not make use of token type ids, therefore a list of zeros is returned.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of zeros.
+
+ """
+
+ sep = [self.sep_token_id]
+ cls = [self.cls_token_id]
+
+ if token_ids_1 is None:
+ return len(cls + token_ids_0 + sep) * [0]
+ return len(cls + token_ids_0 + sep + sep + token_ids_1 + sep) * [0]
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not self.can_save_slow_tokenizer:
+ raise ValueError(
+ "Your fast tokenizer does not have the necessary information to save the vocabulary for a slow "
+ "tokenizer."
+ )
+
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory.")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["XLMRobertaTokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..57aaceadacea8342c64364f5b712089228a0ab66
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_xlm_roberta_xl import *
+ from .modeling_xlm_roberta_xl import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/configuration_xlm_roberta_xl.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/configuration_xlm_roberta_xl.py
new file mode 100644
index 0000000000000000000000000000000000000000..4111a61d4e26b6756a7b439bcdd390dc85227f6b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/configuration_xlm_roberta_xl.py
@@ -0,0 +1,153 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""XLM_ROBERTa_XL configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XLMRobertaXLConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`XLMRobertaXLModel`] or a [`TFXLMRobertaXLModel`].
+ It is used to instantiate a XLM_ROBERTA_XL model according to the specified arguments, defining the model
+ architecture. Instantiating a configuration with the defaults will yield a similar configuration to that of the
+ XLM_ROBERTA_XL [facebook/xlm-roberta-xl](https://huggingface.co/facebook/xlm-roberta-xl) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 250880):
+ Vocabulary size of the XLM_ROBERTA_XL model. Defines the number of different tokens that can be represented
+ by the `inputs_ids` passed when calling [`XLMRobertaXLModel`].
+ hidden_size (`int`, *optional*, defaults to 2560):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 36):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 32):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 10240):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 514):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_size (`int`, *optional*, defaults to 1):
+ The vocabulary size of the `token_type_ids` passed when calling [`XLMRobertaXLModel`] or
+ [`TFXLMRobertaXLModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-5):
+ The epsilon used by the layer normalization layers.
+ position_embedding_type (`str`, *optional*, defaults to `"absolute"`):
+ Type of position embedding. Choose one of `"absolute"`, `"relative_key"`, `"relative_key_query"`. For
+ positional embeddings use `"absolute"`. For more information on `"relative_key"`, please refer to
+ [Self-Attention with Relative Position Representations (Shaw et al.)](https://huggingface.co/papers/1803.02155).
+ For more information on `"relative_key_query"`, please refer to *Method 4* in [Improve Transformer Models
+ with Better Relative Position Embeddings (Huang et al.)](https://huggingface.co/papers/2009.13658).
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ classifier_dropout (`float`, *optional*):
+ The dropout ratio for the classification head.
+
+ Examples:
+
+ ```python
+ >>> from transformers import XLMRobertaXLConfig, XLMRobertaXLModel
+
+ >>> # Initializing a XLM_ROBERTA_XL google-bert/bert-base-uncased style configuration
+ >>> configuration = XLMRobertaXLConfig()
+
+ >>> # Initializing a model (with random weights) from the google-bert/bert-base-uncased style configuration
+ >>> model = XLMRobertaXLModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xlm-roberta-xl"
+
+ def __init__(
+ self,
+ vocab_size=250880,
+ hidden_size=2560,
+ num_hidden_layers=36,
+ num_attention_heads=32,
+ intermediate_size=10240,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=514,
+ type_vocab_size=1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-05,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ position_embedding_type="absolute",
+ use_cache=True,
+ classifier_dropout=None,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.hidden_act = hidden_act
+ self.intermediate_size = intermediate_size
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.max_position_embeddings = max_position_embeddings
+ self.type_vocab_size = type_vocab_size
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.position_embedding_type = position_embedding_type
+ self.use_cache = use_cache
+ self.classifier_dropout = classifier_dropout
+
+
+# Copied from transformers.models.roberta.configuration_roberta.RobertaOnnxConfig with Roberta->XLMRobertaXL
+class XLMRobertaXLOnnxConfig(OnnxConfig):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ if self.task == "multiple-choice":
+ dynamic_axis = {0: "batch", 1: "choice", 2: "sequence"}
+ else:
+ dynamic_axis = {0: "batch", 1: "sequence"}
+ return OrderedDict(
+ [
+ ("input_ids", dynamic_axis),
+ ("attention_mask", dynamic_axis),
+ ]
+ )
+
+
+__all__ = ["XLMRobertaXLConfig", "XLMRobertaXLOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/modeling_xlm_roberta_xl.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/modeling_xlm_roberta_xl.py
new file mode 100644
index 0000000000000000000000000000000000000000..4bbe7591f779293eafba4d650778f72037d06ee6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlm_roberta_xl/modeling_xlm_roberta_xl.py
@@ -0,0 +1,1522 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch XLM RoBERTa xl,xxl model."""
+
+import math
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN, gelu
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import _prepare_4d_attention_mask_for_sdpa, _prepare_4d_causal_attention_mask_for_sdpa
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutputWithPastAndCrossAttentions,
+ BaseModelOutputWithPoolingAndCrossAttentions,
+ CausalLMOutputWithCrossAttentions,
+ MaskedLMOutput,
+ MultipleChoiceModelOutput,
+ QuestionAnsweringModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_xlm_roberta_xl import XLMRobertaXLConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+class XLMRobertaXLEmbeddings(nn.Module):
+ """
+ Same as BertEmbeddings with a tiny tweak for positional embeddings indexing.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+ self.register_buffer(
+ "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False
+ )
+
+ # End copy
+ self.padding_idx = config.pad_token_id
+ self.position_embeddings = nn.Embedding(
+ config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx
+ )
+
+ def forward(
+ self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None, past_key_values_length=0
+ ):
+ if position_ids is None:
+ if input_ids is not None:
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = create_position_ids_from_input_ids(input_ids, self.padding_idx, past_key_values_length)
+ else:
+ position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds)
+
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs
+ # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves
+ # issue #5664
+ if token_type_ids is None:
+ if hasattr(self, "token_type_ids"):
+ buffered_token_type_ids = self.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(input_shape[0], seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaEmbeddings.create_position_ids_from_inputs_embeds
+ def create_position_ids_from_inputs_embeds(self, inputs_embeds):
+ """
+ We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids.
+
+ Args:
+ inputs_embeds: torch.Tensor
+
+ Returns: torch.Tensor
+ """
+ input_shape = inputs_embeds.size()[:-1]
+ sequence_length = input_shape[1]
+
+ position_ids = torch.arange(
+ self.padding_idx + 1, sequence_length + self.padding_idx + 1, dtype=torch.long, device=inputs_embeds.device
+ )
+ return position_ids.unsqueeze(0).expand(input_shape)
+
+
+# Copied from transformers.models.bert.modeling_bert.BertSelfAttention with Bert->XLMRobertaXL
+class XLMRobertaXLSelfAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.position_embedding_type = position_embedding_type or getattr(
+ config, "position_embedding_type", "absolute"
+ )
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ self.max_position_embeddings = config.max_position_embeddings
+ self.distance_embedding = nn.Embedding(2 * config.max_position_embeddings - 1, self.attention_head_size)
+
+ self.is_decoder = config.is_decoder
+ self.layer_idx = layer_idx
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = self.query(hidden_states)
+ query_layer = query_layer.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(
+ 1, 2
+ )
+
+ is_cross_attention = encoder_hidden_states is not None
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_layer from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_layer = curr_past_key_value.layers[self.layer_idx].keys
+ value_layer = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_layer = self.key(current_states)
+ key_layer = key_layer.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(
+ 1, 2
+ )
+ value_layer = self.value(current_states)
+ value_layer = value_layer.view(
+ batch_size, -1, self.num_attention_heads, self.attention_head_size
+ ).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_layer to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_layer, value_layer = curr_past_key_value.update(
+ key_layer, value_layer, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ query_length, key_length = query_layer.shape[2], key_layer.shape[2]
+ if past_key_values is not None:
+ position_ids_l = torch.tensor(key_length - 1, dtype=torch.long, device=hidden_states.device).view(
+ -1, 1
+ )
+ else:
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_l - position_ids_r
+
+ positional_embedding = self.distance_embedding(distance + self.max_position_embeddings - 1)
+ positional_embedding = positional_embedding.to(dtype=query_layer.dtype) # fp16 compatibility
+
+ if self.position_embedding_type == "relative_key":
+ relative_position_scores = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores
+ elif self.position_embedding_type == "relative_key_query":
+ relative_position_scores_query = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ relative_position_scores_key = torch.einsum("bhrd,lrd->bhlr", key_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores_query + relative_position_scores_key
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in XLMRobertaXLModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertSdpaSelfAttention with Bert->XLMRobertaXL
+class XLMRobertaXLSdpaSelfAttention(XLMRobertaXLSelfAttention):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__(config, position_embedding_type=position_embedding_type, layer_idx=layer_idx)
+ self.dropout_prob = config.attention_probs_dropout_prob
+
+ # Adapted from XLMRobertaXLSelfAttention
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ if self.position_embedding_type != "absolute" or output_attentions or head_mask is not None:
+ # TODO: Improve this warning with e.g. `model.config._attn_implementation = "manual"` once implemented.
+ logger.warning_once(
+ "XLMRobertaXLSdpaSelfAttention is used but `torch.nn.functional.scaled_dot_product_attention` does not support "
+ "non-absolute `position_embedding_type` or `output_attentions=True` or `head_mask`. Falling back to "
+ "the manual attention implementation, but specifying the manual implementation will be required from "
+ "Transformers version v5.0.0 onwards. This warning can be removed using the argument "
+ '`attn_implementation="eager"` when loading the model.'
+ )
+ return super().forward(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ past_key_values,
+ output_attentions,
+ cache_position,
+ )
+
+ bsz, tgt_len, _ = hidden_states.size()
+
+ query_layer = (
+ self.query(hidden_states).view(bsz, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ )
+
+ is_cross_attention = encoder_hidden_states is not None
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_states from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_layer = curr_past_key_value.layers[self.layer_idx].keys
+ value_layer = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_layer = (
+ self.key(current_states)
+ .view(bsz, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(current_states)
+ .view(bsz, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ if past_key_values is not None:
+ # save all key/value_layer to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_layer, value_layer = curr_past_key_value.update(
+ key_layer, value_layer, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # We dispatch to SDPA's Flash Attention or Efficient kernels via this `is_causal` if statement instead of an inline conditional assignment
+ # in SDPA to support both torch.compile's dynamic shapes and full graph options. An inline conditional prevents dynamic shapes from compiling.
+ # The tgt_len > 1 is necessary to match with AttentionMaskConverter.to_causal_4d that does not create
+ # a causal mask in case tgt_len == 1.
+ is_causal = self.is_decoder and not is_cross_attention and attention_mask is None and tgt_len > 1
+
+ attn_output = torch.nn.functional.scaled_dot_product_attention(
+ query_layer,
+ key_layer,
+ value_layer,
+ attn_mask=attention_mask,
+ dropout_p=self.dropout_prob if self.training else 0.0,
+ is_causal=is_causal,
+ )
+
+ attn_output = attn_output.transpose(1, 2)
+ attn_output = attn_output.reshape(bsz, tgt_len, self.all_head_size)
+
+ return attn_output, None
+
+
+class XLMRobertaXLSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states, input_tensor):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+XLMROBERTAXL_SELF_ATTENTION_CLASSES = {
+ "eager": XLMRobertaXLSelfAttention,
+ "sdpa": XLMRobertaXLSdpaSelfAttention,
+}
+
+
+class XLMRobertaXLAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__()
+ self.self_attn_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.self = XLMROBERTAXL_SELF_ATTENTION_CLASSES[config._attn_implementation](
+ config,
+ position_embedding_type=position_embedding_type,
+ layer_idx=layer_idx,
+ )
+ self.output = XLMRobertaXLSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ encoder_hidden_states=None,
+ past_key_values=None,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ intermediate = self.self_attn_layer_norm(hidden_states)
+ self_outputs = self.self(
+ intermediate,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ past_key_values,
+ output_attentions,
+ cache_position,
+ )
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertIntermediate
+class XLMRobertaXLIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+class XLMRobertaXLOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+
+ def forward(self, hidden_states, input_tensor):
+ hidden_states = self.dense(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+class XLMRobertaXLLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_idx=None):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = XLMRobertaXLAttention(config, layer_idx=layer_idx)
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = XLMRobertaXLAttention(
+ config, position_embedding_type="absolute", layer_idx=layer_idx
+ )
+ self.intermediate = XLMRobertaXLIntermediate(config)
+ self.output = XLMRobertaXLOutput(config)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ past_key_values=None,
+ output_attentions=False,
+ cache_position=None,
+ ):
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+ attention_output = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ cross_attention_outputs = self.crossattention(
+ attention_output,
+ attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:] # add cross attentions if we output attention weights
+
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ return (layer_output,) + outputs
+
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.LayerNorm(attention_output)
+ intermediate_output = self.intermediate(intermediate_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+class XLMRobertaXLEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([XLMRobertaXLLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)])
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ encoder_hidden_states=None,
+ encoder_attention_mask=None,
+ past_key_values=None,
+ use_cache=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ cache_position=None,
+ ):
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ if use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_values,
+ output_attentions,
+ cache_position,
+ )
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+ if self.config.add_cross_attention:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ hidden_states = self.LayerNorm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ past_key_values,
+ all_hidden_states,
+ all_self_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPooler
+class XLMRobertaXLPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+@auto_docstring
+class XLMRobertaXLPreTrainedModel(PreTrainedModel):
+ config: XLMRobertaXLConfig
+ base_model_prefix = "roberta"
+ _no_split_modules = ["XLMRobertaXLEmbeddings", "XLMRobertaXLLayer"]
+ _supports_sdpa = True
+
+ # Copied from transformers.models.bert.modeling_bert.BertPreTrainedModel._init_weights with BertLMPredictionHead->XLMRobertaXLLMHead
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, XLMRobertaXLLMHead):
+ module.bias.data.zero_()
+
+
+@auto_docstring
+# Copied from transformers.models.bert.modeling_bert.BertModel with Bert->XLMRobertaXL, BERT->XLM_ROBERTA_XL
+class XLMRobertaXLModel(XLMRobertaXLPreTrainedModel):
+ _no_split_modules = ["XLMRobertaXLEmbeddings", "XLMRobertaXLLayer"]
+
+ def __init__(self, config, add_pooling_layer=True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = XLMRobertaXLEmbeddings(config)
+ self.encoder = XLMRobertaXLEncoder(config)
+
+ self.pooler = XLMRobertaXLPooler(config) if add_pooling_layer else None
+
+ self.attn_implementation = config._attn_implementation
+ self.position_embedding_type = config.position_embedding_type
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutputWithPoolingAndCrossAttentions]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if self.config.is_decoder:
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ else:
+ use_cache = False
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ past_key_values_length = 0
+ if past_key_values is not None:
+ past_key_values_length = (
+ past_key_values[0][0].shape[-2]
+ if not isinstance(past_key_values, Cache)
+ else past_key_values.get_seq_length()
+ )
+
+ if token_type_ids is None:
+ if hasattr(self.embeddings, "token_type_ids"):
+ buffered_token_type_ids = self.embeddings.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(batch_size, seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ past_key_values_length=past_key_values_length,
+ )
+
+ if attention_mask is None:
+ attention_mask = torch.ones((batch_size, seq_length + past_key_values_length), device=device)
+
+ use_sdpa_attention_masks = (
+ self.attn_implementation == "sdpa"
+ and self.position_embedding_type == "absolute"
+ and head_mask is None
+ and not output_attentions
+ )
+
+ # Expand the attention mask
+ if use_sdpa_attention_masks and attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ if self.config.is_decoder:
+ extended_attention_mask = _prepare_4d_causal_attention_mask_for_sdpa(
+ attention_mask,
+ input_shape,
+ embedding_output,
+ past_key_values_length,
+ )
+ else:
+ extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.config.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
+
+ if use_sdpa_attention_masks and encoder_attention_mask.dim() == 2:
+ # Expand the attention mask for SDPA.
+ # [bsz, seq_len] -> [bsz, 1, seq_len, seq_len]
+ encoder_extended_attention_mask = _prepare_4d_attention_mask_for_sdpa(
+ encoder_attention_mask, embedding_output.dtype, tgt_len=seq_length
+ )
+ else:
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPoolingAndCrossAttentions(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ past_key_values=encoder_outputs.past_key_values,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ cross_attentions=encoder_outputs.cross_attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ XLM-RoBERTa-XL Model with a `language modeling` head on top for CLM fine-tuning.
+ """
+)
+class XLMRobertaXLForCausalLM(XLMRobertaXLPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.decoder.weight", "lm_head.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ if not config.is_decoder:
+ logger.warning("If you want to use `RobertaLMHeadModel` as a standalone, add `is_decoder=True.`")
+
+ self.roberta = XLMRobertaXLModel(config, add_pooling_layer=False)
+ self.lm_head = XLMRobertaXLLMHead(config)
+
+ self.init_weights()
+
+ def get_output_embeddings(self):
+ return self.lm_head.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.decoder = new_embeddings
+ self.lm_head.bias = new_embeddings.bias
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[tuple, CausalLMOutputWithCrossAttentions]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in
+ `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are
+ ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, RobertaForCausalLM, RobertaConfig
+ >>> import torch
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("FacebookAI/roberta-base")
+ >>> config = RobertaConfig.from_pretrained("FacebookAI/roberta-base")
+ >>> config.is_decoder = True
+ >>> model = RobertaForCausalLM.from_pretrained("FacebookAI/roberta-base", config=config)
+ >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt")
+ >>> outputs = model(**inputs)
+ >>> prediction_logits = outputs.logits
+ ```
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ if labels is not None:
+ use_cache = False
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+
+ lm_loss = None
+ if labels is not None:
+ lm_loss = self.loss_function(
+ prediction_scores,
+ labels,
+ vocab_size=self.config.vocab_size,
+ **kwargs,
+ )
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((lm_loss,) + output) if lm_loss is not None else output
+
+ return CausalLMOutputWithCrossAttentions(
+ loss=lm_loss,
+ logits=prediction_scores,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+ def prepare_inputs_for_generation(self, input_ids, past_key_values=None, attention_mask=None, **model_kwargs):
+ # Overwritten -- model logic breaks when `inputs_embeds` are passed from this function
+
+ input_shape = input_ids.shape
+ # if model is used as a decoder in encoder-decoder model, the decoder attention mask is created on the fly
+ if attention_mask is None:
+ attention_mask = input_ids.new_ones(input_shape)
+
+ # Create missing `position_ids` on the fly
+ position_ids = None
+ if model_kwargs.get("position_ids") is None:
+ position_ids = create_position_ids_from_input_ids(
+ input_ids, padding_idx=self.config.pad_token_id
+ ) # placed in kwargs for further processing (see below)
+
+ # cut decoder_input_ids if past_key_values is used
+ if past_key_values is not None:
+ past_length = past_key_values.get_seq_length()
+
+ # Some generation methods already pass only the last input ID
+ if input_ids.shape[1] > past_length:
+ remove_prefix_length = past_length
+ else:
+ # Default to old behavior: keep only final ID
+ remove_prefix_length = input_ids.shape[1] - 1
+
+ input_ids = input_ids[:, remove_prefix_length:]
+ if position_ids is not None:
+ position_ids = position_ids[:, remove_prefix_length:]
+
+ return {
+ "input_ids": input_ids,
+ "attention_mask": attention_mask,
+ "position_ids": position_ids,
+ "past_key_values": past_key_values,
+ }
+
+
+@auto_docstring
+class XLMRobertaXLForMaskedLM(XLMRobertaXLPreTrainedModel):
+ _tied_weights_keys = ["lm_head.decoder.weight", "lm_head.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ if config.is_decoder:
+ logger.warning(
+ "If you want to use `RobertaForMaskedLM` make sure `config.is_decoder=False` for "
+ "bi-directional self-attention."
+ )
+
+ self.roberta = XLMRobertaXLModel(config, add_pooling_layer=False)
+ self.lm_head = XLMRobertaXLLMHead(config)
+
+ self.init_weights()
+
+ def get_output_embeddings(self):
+ return self.lm_head.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.decoder = new_embeddings
+ self.lm_head.bias = new_embeddings.bias
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, MaskedLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+
+ masked_lm_loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return MaskedLMOutput(
+ loss=masked_lm_loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class XLMRobertaXLLMHead(nn.Module):
+ """XLM-RoBERTa-XL Head for masked language modeling."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size)
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+ self.decoder.bias = self.bias
+
+ def forward(self, features, **kwargs):
+ x = self.dense(features)
+ x = gelu(x)
+ x = self.layer_norm(x)
+
+ # project back to size of vocabulary with bias
+ x = self.decoder(x)
+
+ return x
+
+ def _tie_weights(self) -> None:
+ # For accelerate compatibility and to not break backward compatibility
+ if self.decoder.bias.device.type == "meta":
+ self.decoder.bias = self.bias
+ else:
+ # To tie those two weights if they get disconnected (on TPU or when the bias is resized)
+ self.bias = self.decoder.bias
+
+
+@auto_docstring(
+ custom_intro="""
+ XLM-RoBERTa-XL Model transformer with a sequence classification/regression head on top (a linear layer on top
+ of the pooled output) e.g. for GLUE tasks.
+ """
+)
+class XLMRobertaXLForSequenceClassification(XLMRobertaXLPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.config = config
+
+ self.roberta = XLMRobertaXLModel(config, add_pooling_layer=False)
+ self.classifier = XLMRobertaXLClassificationHead(config)
+
+ self.init_weights()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLMRobertaXLForMultipleChoice(XLMRobertaXLPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.roberta = XLMRobertaXLModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, 1)
+
+ self.init_weights()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, MultipleChoiceModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary. Indices can be obtained using [`AutoTokenizer`]. See
+ [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. [What are input
+ IDs?](../glossary#input-ids)
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+ [What are token type IDs?](../glossary#token-type-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See
+ `input_ids` above)
+ position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`. [What are position IDs?](../glossary#position-ids)
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ flat_input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ flat_position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None
+ flat_token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ flat_attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ flat_inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ outputs = self.roberta(
+ flat_input_ids,
+ position_ids=flat_position_ids,
+ token_type_ids=flat_token_type_ids,
+ attention_mask=flat_attention_mask,
+ head_mask=head_mask,
+ inputs_embeds=flat_inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels)
+
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return MultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLMRobertaXLForTokenClassification(XLMRobertaXLPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.roberta = XLMRobertaXLModel(config, add_pooling_layer=False)
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(classifier_dropout)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ self.init_weights()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ sequence_output = self.dropout(sequence_output)
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ # Only keep active parts of the loss
+ if attention_mask is not None:
+ active_loss = attention_mask.view(-1) == 1
+ active_logits = logits.view(-1, self.num_labels)
+ active_labels = torch.where(
+ active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
+ )
+ loss = loss_fct(active_logits, active_labels)
+ else:
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class XLMRobertaXLClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(classifier_dropout)
+ self.out_proj = nn.Linear(config.hidden_size, config.num_labels)
+
+ def forward(self, features, **kwargs):
+ x = features[:, 0, :] # take token (equiv. to [CLS])
+ x = self.dropout(x)
+ x = self.dense(x)
+ x = torch.tanh(x)
+ x = self.dropout(x)
+ x = self.out_proj(x)
+ return x
+
+
+@auto_docstring
+class XLMRobertaXLForQuestionAnswering(XLMRobertaXLPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.roberta = XLMRobertaXLModel(config, add_pooling_layer=False)
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ self.init_weights()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, QuestionAnsweringModelOutput]:
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[2:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return QuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.create_position_ids_from_input_ids
+def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols
+ are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ x: torch.Tensor x:
+
+ Returns: torch.Tensor
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = input_ids.ne(padding_idx).int()
+ incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask
+ return incremental_indices.long() + padding_idx
+
+
+__all__ = [
+ "XLMRobertaXLForCausalLM",
+ "XLMRobertaXLForMaskedLM",
+ "XLMRobertaXLForMultipleChoice",
+ "XLMRobertaXLForQuestionAnswering",
+ "XLMRobertaXLForSequenceClassification",
+ "XLMRobertaXLForTokenClassification",
+ "XLMRobertaXLModel",
+ "XLMRobertaXLPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..3f453455925328db06bf86ecc85c5acc8762dd26
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_xlnet import *
+ from .modeling_tf_xlnet import *
+ from .modeling_xlnet import *
+ from .tokenization_xlnet import *
+ from .tokenization_xlnet_fast import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/configuration_xlnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/configuration_xlnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..4a7238eb4c098b93c7aa911bb958ebe771a4539c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/configuration_xlnet.py
@@ -0,0 +1,240 @@
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""XLNet configuration"""
+
+import warnings
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XLNetConfig(PretrainedConfig):
+ """
+ This is the configuration class to store the configuration of a [`XLNetModel`] or a [`TFXLNetModel`]. It is used to
+ instantiate a XLNet model according to the specified arguments, defining the model architecture. Instantiating a
+ configuration with the defaults will yield a similar configuration to that of the
+ [xlnet/xlnet-large-cased](https://huggingface.co/xlnet/xlnet-large-cased) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32000):
+ Vocabulary size of the XLNet model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`XLNetModel`] or [`TFXLNetModel`].
+ d_model (`int`, *optional*, defaults to 1024):
+ Dimensionality of the encoder layers and the pooler layer.
+ n_layer (`int`, *optional*, defaults to 24):
+ Number of hidden layers in the Transformer encoder.
+ n_head (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ d_inner (`int`, *optional*, defaults to 4096):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder.
+ ff_activation (`str` or `Callable`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the If string, `"gelu"`, `"relu"`, `"silu"` and
+ `"gelu_new"` are supported.
+ untie_r (`bool`, *optional*, defaults to `True`):
+ Whether or not to untie relative position biases
+ attn_type (`str`, *optional*, defaults to `"bi"`):
+ The attention type used by the model. Set `"bi"` for XLNet, `"uni"` for Transformer-XL.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ dropout (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ mem_len (`int` or `None`, *optional*):
+ The number of tokens to cache. The key/value pairs that have already been pre-computed in a previous
+ forward pass won't be re-computed. See the
+ [quickstart](https://huggingface.co/transformers/quickstart.html#using-the-past) for more information.
+ reuse_len (`int`, *optional*):
+ The number of tokens in the current batch to be cached and reused in the future.
+ bi_data (`bool`, *optional*, defaults to `False`):
+ Whether or not to use bidirectional input pipeline. Usually set to `True` during pretraining and `False`
+ during finetuning.
+ clamp_len (`int`, *optional*, defaults to -1):
+ Clamp all relative distances larger than clamp_len. Setting this attribute to -1 means no clamping.
+ same_length (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the same attention length for each token.
+ summary_type (`str`, *optional*, defaults to "last"):
+ Argument used when doing sequence summary. Used in the sequence classification and multiple choice models.
+
+ Has to be one of the following options:
+
+ - `"last"`: Take the last token hidden state (like XLNet).
+ - `"first"`: Take the first token hidden state (like BERT).
+ - `"mean"`: Take the mean of all tokens hidden states.
+ - `"cls_index"`: Supply a Tensor of classification token position (like GPT/GPT-2).
+ - `"attn"`: Not implemented now, use multi-head attention.
+ summary_use_proj (`bool`, *optional*, defaults to `True`):
+ Argument used when doing sequence summary. Used in the sequence classification and multiple choice models.
+
+ Whether or not to add a projection after the vector extraction.
+ summary_activation (`str`, *optional*):
+ Argument used when doing sequence summary. Used in the sequence classification and multiple choice models.
+
+ Pass `"tanh"` for a tanh activation to the output, any other value will result in no activation.
+ summary_proj_to_labels (`boo`, *optional*, defaults to `True`):
+ Used in the sequence classification and multiple choice models.
+
+ Whether the projection outputs should have `config.num_labels` or `config.hidden_size` classes.
+ summary_last_dropout (`float`, *optional*, defaults to 0.1):
+ Used in the sequence classification and multiple choice models.
+
+ The dropout ratio to be used after the projection and activation.
+ start_n_top (`int`, *optional*, defaults to 5):
+ Used in the SQuAD evaluation script.
+ end_n_top (`int`, *optional*, defaults to 5):
+ Used in the SQuAD evaluation script.
+ use_mems_eval (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should make use of the recurrent memory mechanism in evaluation mode.
+ use_mems_train (`bool`, *optional*, defaults to `False`):
+ Whether or not the model should make use of the recurrent memory mechanism in train mode.
+
+
+
+ For pretraining, it is recommended to set `use_mems_train` to `True`. For fine-tuning, it is recommended to
+ set `use_mems_train` to `False` as discussed
+ [here](https://github.com/zihangdai/xlnet/issues/41#issuecomment-505102587). If `use_mems_train` is set to
+ `True`, one has to make sure that the train batches are correctly pre-processed, *e.g.* `batch_1 = [[This
+ line is], [This is the]]` and `batch_2 = [[ the first line], [ second line]]` and that all batches are of
+ equal size.
+
+
+
+ Examples:
+
+ ```python
+ >>> from transformers import XLNetConfig, XLNetModel
+
+ >>> # Initializing a XLNet configuration
+ >>> configuration = XLNetConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = XLNetModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xlnet"
+ keys_to_ignore_at_inference = ["mems"]
+ attribute_map = {
+ "n_token": "vocab_size", # Backward compatibility
+ "hidden_size": "d_model",
+ "num_attention_heads": "n_head",
+ "num_hidden_layers": "n_layer",
+ }
+
+ def __init__(
+ self,
+ vocab_size=32000,
+ d_model=1024,
+ n_layer=24,
+ n_head=16,
+ d_inner=4096,
+ ff_activation="gelu",
+ untie_r=True,
+ attn_type="bi",
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ dropout=0.1,
+ mem_len=512,
+ reuse_len=None,
+ use_mems_eval=True,
+ use_mems_train=False,
+ bi_data=False,
+ clamp_len=-1,
+ same_length=False,
+ summary_type="last",
+ summary_use_proj=True,
+ summary_activation="tanh",
+ summary_last_dropout=0.1,
+ start_n_top=5,
+ end_n_top=5,
+ pad_token_id=5,
+ bos_token_id=1,
+ eos_token_id=2,
+ **kwargs,
+ ):
+ """Constructs XLNetConfig."""
+ self.vocab_size = vocab_size
+ self.d_model = d_model
+ self.n_layer = n_layer
+ self.n_head = n_head
+ if d_model % n_head != 0:
+ raise ValueError(f"'d_model % n_head' ({d_model % n_head}) should be equal to 0")
+ if "d_head" in kwargs:
+ if kwargs["d_head"] != d_model // n_head:
+ raise ValueError(
+ f"`d_head` ({kwargs['d_head']}) should be equal to `d_model // n_head` ({d_model // n_head})"
+ )
+ self.d_head = d_model // n_head
+ self.ff_activation = ff_activation
+ self.d_inner = d_inner
+ self.untie_r = untie_r
+ self.attn_type = attn_type
+
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+
+ self.dropout = dropout
+ self.mem_len = mem_len
+ self.reuse_len = reuse_len
+ self.bi_data = bi_data
+ self.clamp_len = clamp_len
+ self.same_length = same_length
+
+ self.summary_type = summary_type
+ self.summary_use_proj = summary_use_proj
+ self.summary_activation = summary_activation
+ self.summary_last_dropout = summary_last_dropout
+ self.start_n_top = start_n_top
+ self.end_n_top = end_n_top
+
+ self.bos_token_id = bos_token_id
+ self.pad_token_id = pad_token_id
+ self.eos_token_id = eos_token_id
+
+ if "use_cache" in kwargs:
+ warnings.warn(
+ "The `use_cache` argument is deprecated and will be removed in a future version, use `use_mems_eval`"
+ " instead.",
+ FutureWarning,
+ )
+ use_mems_eval = kwargs["use_cache"]
+
+ self.use_mems_eval = use_mems_eval
+ self.use_mems_train = use_mems_train
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+
+ @property
+ def max_position_embeddings(self):
+ logger.info(f"The model {self.model_type} is one of the few models that has no sequence length limit.")
+ return -1
+
+ @max_position_embeddings.setter
+ def max_position_embeddings(self, value):
+ # Message copied from Transformer-XL documentation
+ raise NotImplementedError(
+ f"The model {self.model_type} is one of the few models that has no sequence length limit."
+ )
+
+
+__all__ = ["XLNetConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/modeling_tf_xlnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/modeling_tf_xlnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..451d26c844d8dc3c054a26c532e070e00460e22c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/modeling_tf_xlnet.py
@@ -0,0 +1,1820 @@
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+TF 2.0 XLNet model.
+"""
+
+from __future__ import annotations
+
+import warnings
+from dataclasses import dataclass
+
+import numpy as np
+import tensorflow as tf
+
+from ...activations_tf import get_tf_activation
+from ...modeling_tf_utils import (
+ TFCausalLanguageModelingLoss,
+ TFModelInputType,
+ TFMultipleChoiceLoss,
+ TFPreTrainedModel,
+ TFQuestionAnsweringLoss,
+ TFSequenceClassificationLoss,
+ TFSequenceSummary,
+ TFSharedEmbeddings,
+ TFTokenClassificationLoss,
+ get_initializer,
+ keras,
+ keras_serializable,
+ unpack_inputs,
+)
+from ...tf_utils import check_embeddings_within_bounds, shape_list, stable_softmax
+from ...utils import (
+ ModelOutput,
+ add_code_sample_docstrings,
+ add_start_docstrings,
+ add_start_docstrings_to_model_forward,
+ logging,
+ replace_return_docstrings,
+)
+from .configuration_xlnet import XLNetConfig
+
+
+logger = logging.get_logger(__name__)
+
+_CHECKPOINT_FOR_DOC = "xlnet/xlnet-base-cased"
+_CONFIG_FOR_DOC = "XLNetConfig"
+
+
+class TFXLNetRelativeAttention(keras.layers.Layer):
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+
+ if config.d_model % config.n_head != 0:
+ raise ValueError(
+ f"The hidden size ({config.d_model}) is not a multiple of the number of attention "
+ f"heads ({config.n_head}"
+ )
+
+ self.n_head = config.n_head
+ self.d_head = config.d_head
+ self.d_model = config.d_model
+ self.scale = 1 / (config.d_head**0.5)
+ self.initializer_range = config.initializer_range
+ self.output_attentions = config.output_attentions
+
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.dropout = keras.layers.Dropout(config.dropout)
+ self.config = config
+
+ def build(self, input_shape=None):
+ initializer = get_initializer(self.initializer_range)
+ self.q = self.add_weight(
+ shape=(self.d_model, self.n_head, self.d_head), initializer=initializer, trainable=True, name="q"
+ )
+ self.k = self.add_weight(
+ shape=(self.d_model, self.n_head, self.d_head), initializer=initializer, trainable=True, name="k"
+ )
+ self.v = self.add_weight(
+ shape=(self.d_model, self.n_head, self.d_head), initializer=initializer, trainable=True, name="v"
+ )
+ self.o = self.add_weight(
+ shape=(self.d_model, self.n_head, self.d_head), initializer=initializer, trainable=True, name="o"
+ )
+ self.r = self.add_weight(
+ shape=(self.d_model, self.n_head, self.d_head), initializer=initializer, trainable=True, name="r"
+ )
+ self.r_r_bias = self.add_weight(
+ shape=(self.n_head, self.d_head), initializer="zeros", trainable=True, name="r_r_bias"
+ )
+ self.r_s_bias = self.add_weight(
+ shape=(self.n_head, self.d_head), initializer="zeros", trainable=True, name="r_s_bias"
+ )
+ self.r_w_bias = self.add_weight(
+ shape=(self.n_head, self.d_head), initializer="zeros", trainable=True, name="r_w_bias"
+ )
+ self.seg_embed = self.add_weight(
+ shape=(2, self.n_head, self.d_head), initializer=initializer, trainable=True, name="seg_embed"
+ )
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.d_model])
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ def rel_shift(self, x, klen=-1):
+ """perform relative shift to form the relative attention score."""
+ x_size = shape_list(x)
+
+ x = tf.reshape(x, (x_size[1], x_size[0], x_size[2], x_size[3]))
+ x = x[1:, ...]
+ x = tf.reshape(x, (x_size[0], x_size[1] - 1, x_size[2], x_size[3]))
+ x = x[:, 0:klen, :, :]
+ # x = torch.index_select(x, 1, torch.arange(klen, device=x.device, dtype=torch.long))
+
+ return x
+
+ def rel_attn_core(
+ self, q_head, k_head_h, v_head_h, k_head_r, seg_mat, attn_mask, head_mask, output_attentions, training=False
+ ):
+ """Core relative positional attention operations."""
+ # content based attention score
+ ac = tf.einsum("ibnd,jbnd->ijbn", q_head + self.r_w_bias, k_head_h)
+
+ # position based attention score
+ bd = tf.einsum("ibnd,jbnd->ijbn", q_head + self.r_r_bias, k_head_r)
+ bd = self.rel_shift(bd, klen=shape_list(ac)[1])
+
+ # segment based attention score
+ if seg_mat is None:
+ ef = 0
+ else:
+ ef = tf.einsum("ibnd,snd->ibns", q_head + self.r_s_bias, self.seg_embed)
+ ef = tf.einsum("ijbs,ibns->ijbn", seg_mat, ef)
+
+ # merge attention scores and perform masking
+ attn_score = (ac + bd + ef) * self.scale
+ if attn_mask is not None:
+ # attn_score = attn_score * (1 - attn_mask) - 1e30 * attn_mask
+ if attn_mask.dtype == tf.float16 or attn_mask.dtype == tf.bfloat16:
+ attn_score = attn_score - 65500 * attn_mask
+ else:
+ attn_score = attn_score - 1e30 * attn_mask
+
+ # attention probability
+ attn_prob = stable_softmax(attn_score, axis=1)
+
+ attn_prob = self.dropout(attn_prob, training=training)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attn_prob = attn_prob * head_mask
+
+ # attention output
+ attn_vec = tf.einsum("ijbn,jbnd->ibnd", attn_prob, v_head_h)
+
+ if output_attentions:
+ return attn_vec, attn_prob
+
+ return attn_vec
+
+ def post_attention(self, h, attn_vec, residual=True, training=False):
+ """Post-attention processing."""
+ # post-attention projection (back to `d_model`)
+ attn_out = tf.einsum("ibnd,hnd->ibh", attn_vec, self.o)
+
+ attn_out = self.dropout(attn_out, training=training)
+
+ if residual:
+ attn_out = attn_out + h
+ output = self.layer_norm(attn_out)
+
+ return output
+
+ def call(
+ self,
+ h,
+ g,
+ attn_mask_h,
+ attn_mask_g,
+ r,
+ seg_mat,
+ mems: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = False,
+ training: bool = False,
+ ):
+ if g is not None:
+ # Two-stream attention with relative positional encoding.
+ # content based attention score
+ if mems is not None and len(shape_list(mems)) > 1:
+ cat = tf.concat([mems, h], axis=0)
+ else:
+ cat = h
+
+ # content-based key head
+ k_head_h = tf.einsum("ibh,hnd->ibnd", cat, self.k)
+
+ # content-based value head
+ v_head_h = tf.einsum("ibh,hnd->ibnd", cat, self.v)
+
+ # position-based key head
+ k_head_r = tf.einsum("ibh,hnd->ibnd", r, self.r)
+
+ # h-stream
+ # content-stream query head
+ q_head_h = tf.einsum("ibh,hnd->ibnd", h, self.q)
+
+ # core attention ops
+ attn_vec_h = self.rel_attn_core(
+ q_head_h,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat,
+ attn_mask_h,
+ head_mask,
+ output_attentions,
+ training=training,
+ )
+
+ if output_attentions:
+ attn_vec_h, attn_prob_h = attn_vec_h
+
+ # post processing
+ output_h = self.post_attention(h, attn_vec_h, training=training)
+
+ # g-stream
+ # query-stream query head
+ q_head_g = tf.einsum("ibh,hnd->ibnd", g, self.q)
+
+ # core attention ops
+ if target_mapping is not None:
+ q_head_g = tf.einsum("mbnd,mlb->lbnd", q_head_g, target_mapping)
+ attn_vec_g = self.rel_attn_core(
+ q_head_g,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat,
+ attn_mask_g,
+ head_mask,
+ output_attentions,
+ training=training,
+ )
+
+ if output_attentions:
+ attn_vec_g, attn_prob_g = attn_vec_g
+
+ attn_vec_g = tf.einsum("lbnd,mlb->mbnd", attn_vec_g, target_mapping)
+ else:
+ attn_vec_g = self.rel_attn_core(
+ q_head_g,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat,
+ attn_mask_g,
+ head_mask,
+ output_attentions,
+ training=training,
+ )
+
+ if output_attentions:
+ attn_vec_g, attn_prob_g = attn_vec_g
+
+ # post processing
+ output_g = self.post_attention(g, attn_vec_g, training=training)
+
+ if output_attentions:
+ attn_prob = attn_prob_h, attn_prob_g
+
+ else:
+ # Multi-head attention with relative positional encoding
+ if mems is not None and len(shape_list(mems)) > 1:
+ cat = tf.concat([mems, h], axis=0)
+ else:
+ cat = h
+
+ # content heads
+ q_head_h = tf.einsum("ibh,hnd->ibnd", h, self.q)
+ k_head_h = tf.einsum("ibh,hnd->ibnd", cat, self.k)
+ v_head_h = tf.einsum("ibh,hnd->ibnd", cat, self.v)
+
+ # positional heads
+ k_head_r = tf.einsum("ibh,hnd->ibnd", r, self.r)
+
+ # core attention ops
+ attn_vec = self.rel_attn_core(
+ q_head_h,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat,
+ attn_mask_h,
+ head_mask,
+ output_attentions,
+ training=training,
+ )
+
+ if output_attentions:
+ attn_vec, attn_prob = attn_vec
+
+ # post processing
+ output_h = self.post_attention(h, attn_vec, training=training)
+ output_g = None
+
+ outputs = (output_h, output_g)
+ if output_attentions:
+ outputs = outputs + (attn_prob,)
+ return outputs
+
+
+class TFXLNetFeedForward(keras.layers.Layer):
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ self.layer_norm = keras.layers.LayerNormalization(epsilon=config.layer_norm_eps, name="layer_norm")
+ self.layer_1 = keras.layers.Dense(
+ config.d_inner, kernel_initializer=get_initializer(config.initializer_range), name="layer_1"
+ )
+ self.layer_2 = keras.layers.Dense(
+ config.d_model, kernel_initializer=get_initializer(config.initializer_range), name="layer_2"
+ )
+ self.dropout = keras.layers.Dropout(config.dropout)
+ if isinstance(config.ff_activation, str):
+ self.activation_function = get_tf_activation(config.ff_activation)
+ else:
+ self.activation_function = config.ff_activation
+ self.config = config
+
+ def call(self, inp, training=False):
+ output = inp
+ output = self.layer_1(output)
+ output = self.activation_function(output)
+ output = self.dropout(output, training=training)
+ output = self.layer_2(output)
+ output = self.dropout(output, training=training)
+ output = self.layer_norm(output + inp)
+ return output
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "layer_norm", None) is not None:
+ with tf.name_scope(self.layer_norm.name):
+ self.layer_norm.build([None, None, self.config.d_model])
+ if getattr(self, "layer_1", None) is not None:
+ with tf.name_scope(self.layer_1.name):
+ self.layer_1.build([None, None, self.config.d_model])
+ if getattr(self, "layer_2", None) is not None:
+ with tf.name_scope(self.layer_2.name):
+ self.layer_2.build([None, None, self.config.d_inner])
+
+
+class TFXLNetLayer(keras.layers.Layer):
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+ self.rel_attn = TFXLNetRelativeAttention(config, name="rel_attn")
+ self.ff = TFXLNetFeedForward(config, name="ff")
+ self.dropout = keras.layers.Dropout(config.dropout)
+
+ def call(
+ self,
+ output_h,
+ output_g,
+ non_tgt_mask,
+ attn_mask,
+ pos_emb,
+ seg_mat,
+ mems: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ output_attentions: bool | None = False,
+ training: bool = False,
+ ):
+ outputs = self.rel_attn(
+ output_h,
+ output_g,
+ non_tgt_mask,
+ attn_mask,
+ pos_emb,
+ seg_mat,
+ mems,
+ target_mapping,
+ head_mask,
+ output_attentions,
+ training=training,
+ )
+ output_h, output_g = outputs[:2]
+
+ if output_g is not None:
+ output_g = self.ff(output_g, training=training)
+ output_h = self.ff(output_h, training=training)
+
+ outputs = (output_h, output_g) + outputs[2:] # Add again attentions if there are there
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "rel_attn", None) is not None:
+ with tf.name_scope(self.rel_attn.name):
+ self.rel_attn.build(None)
+ if getattr(self, "ff", None) is not None:
+ with tf.name_scope(self.ff.name):
+ self.ff.build(None)
+
+
+class TFXLNetLMHead(keras.layers.Layer):
+ def __init__(self, config, input_embeddings, **kwargs):
+ super().__init__(**kwargs)
+ self.config = config
+ # The output weights are the same as the input embeddings, but there is
+ # an output-only bias for each token.
+ self.input_embeddings = input_embeddings
+
+ def build(self, input_shape):
+ self.bias = self.add_weight(shape=(self.config.vocab_size,), initializer="zeros", trainable=True, name="bias")
+ super().build(input_shape)
+
+ def get_output_embeddings(self):
+ return self.input_embeddings
+
+ def set_output_embeddings(self, value):
+ self.input_embeddings.weight = value
+ self.input_embeddings.vocab_size = shape_list(value)[0]
+
+ def get_bias(self):
+ return {"bias": self.bias}
+
+ def set_bias(self, value):
+ self.bias = value["bias"]
+ self.config.vocab_size = shape_list(value["bias"])[0]
+
+ def call(self, hidden_states):
+ hidden_states = self.input_embeddings(hidden_states, mode="linear")
+ hidden_states = hidden_states + self.bias
+ return hidden_states
+
+
+@keras_serializable
+class TFXLNetMainLayer(keras.layers.Layer):
+ config_class = XLNetConfig
+
+ def __init__(self, config, **kwargs):
+ super().__init__(**kwargs)
+
+ self.config = config
+ self.output_hidden_states = config.output_hidden_states
+ self.output_attentions = config.output_attentions
+ self.return_dict = config.return_dict
+
+ self.mem_len = config.mem_len
+ self.reuse_len = config.reuse_len
+ self.d_model = config.d_model
+ self.same_length = config.same_length
+ self.attn_type = config.attn_type
+ self.bi_data = config.bi_data
+ self.clamp_len = config.clamp_len
+ self.n_layer = config.n_layer
+ self.use_bfloat16 = config.use_bfloat16
+ self.initializer_range = config.initializer_range
+
+ self.word_embedding = TFSharedEmbeddings(
+ config.vocab_size, config.d_model, initializer_range=config.initializer_range, name="word_embedding"
+ )
+ self.layer = [TFXLNetLayer(config, name=f"layer_._{i}") for i in range(config.n_layer)]
+ self.dropout = keras.layers.Dropout(config.dropout)
+
+ self.use_mems_eval = config.use_mems_eval
+ self.use_mems_train = config.use_mems_train
+
+ def get_input_embeddings(self):
+ return self.word_embedding
+
+ def set_input_embeddings(self, value):
+ self.word_embedding.weight = value
+ self.word_embedding.vocab_size = shape_list(value)[0]
+
+ def build(self, input_shape=None):
+ initializer = get_initializer(self.initializer_range)
+ self.mask_emb = self.add_weight(
+ shape=(1, 1, self.d_model), initializer=initializer, trainable=True, name="mask_emb"
+ )
+
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "word_embedding", None) is not None:
+ with tf.name_scope(self.word_embedding.name):
+ self.word_embedding.build(None)
+ if getattr(self, "layer", None) is not None:
+ for layer in self.layer:
+ with tf.name_scope(layer.name):
+ layer.build(None)
+
+ def _prune_heads(self, heads_to_prune):
+ raise NotImplementedError
+
+ def create_mask(self, qlen, mlen):
+ """
+ Creates causal attention mask. Float mask where 1.0 indicates masked, 0.0 indicates not-masked.
+
+ Args:
+ qlen: TODO Lysandre didn't fill
+ mlen: TODO Lysandre didn't fill
+
+ ```
+
+ same_length=False: same_length=True:
+ < qlen > < qlen >
+ ^ [0 0 0 0 0 1 1 1 1] [0 0 0 0 0 1 1 1 1]
+ [0 0 0 0 0 0 1 1 1] [1 0 0 0 0 0 1 1 1]
+ qlen [0 0 0 0 0 0 0 1 1] [1 1 0 0 0 0 0 1 1]
+ [0 0 0 0 0 0 0 0 1] [1 1 1 0 0 0 0 0 1]
+ v [0 0 0 0 0 0 0 0 0] [1 1 1 1 0 0 0 0 0]
+ ```
+ """
+ attn_mask = tf.ones([qlen, qlen])
+ mask_u = tf.linalg.band_part(attn_mask, 0, -1)
+ mask_dia = tf.linalg.band_part(attn_mask, 0, 0)
+ attn_mask_pad = tf.zeros([qlen, mlen])
+ ret = tf.concat([attn_mask_pad, mask_u - mask_dia], 1)
+ if self.same_length:
+ mask_l = tf.linalg.band_part(attn_mask, -1, 0)
+ ret = tf.concat([ret[:, :qlen] + mask_l - mask_dia, ret[:, qlen:]], 1)
+ return ret
+
+ def cache_mem(self, curr_out, prev_mem):
+ # cache hidden states into memory.
+ if self.reuse_len is not None and self.reuse_len > 0:
+ curr_out = curr_out[: self.reuse_len]
+
+ if self.mem_len is None or self.mem_len == 0:
+ # If `use_mems` is active but no `mem_len` is defined, the model behaves like GPT-2 at inference time
+ # and returns all of the past and current hidden states.
+ cutoff = 0
+ else:
+ # If `use_mems` is active and `mem_len` is defined, the model returns the last `mem_len` hidden
+ # states. This is the preferred setting for training and long-form generation.
+ cutoff = -self.mem_len
+ if prev_mem is None:
+ # if `use_mems` is active and `mem_len` is defined, the model
+ new_mem = curr_out[cutoff:]
+ else:
+ new_mem = tf.concat([prev_mem, curr_out], 0)[cutoff:]
+
+ return tf.stop_gradient(new_mem)
+
+ @staticmethod
+ def positional_embedding(pos_seq, inv_freq, bsz=None):
+ sinusoid_inp = tf.einsum("i,d->id", pos_seq, inv_freq)
+ pos_emb = tf.concat([tf.sin(sinusoid_inp), tf.cos(sinusoid_inp)], axis=-1)
+ pos_emb = pos_emb[:, None, :]
+
+ if bsz is not None:
+ pos_emb = tf.tile(pos_emb, [1, bsz, 1])
+
+ return pos_emb
+
+ def relative_positional_encoding(self, qlen, klen, bsz=None):
+ """create relative positional encoding."""
+ freq_seq = tf.range(0, self.d_model, 2.0)
+ inv_freq = 1 / (10000 ** (freq_seq / self.d_model))
+
+ if self.attn_type == "bi":
+ # beg, end = klen - 1, -qlen
+ beg, end = klen, -qlen
+ elif self.attn_type == "uni":
+ # beg, end = klen - 1, -1
+ beg, end = klen, -1
+ else:
+ raise ValueError(f"Unknown `attn_type` {self.attn_type}.")
+
+ if self.bi_data:
+ fwd_pos_seq = tf.range(beg, end, -1.0)
+ bwd_pos_seq = tf.range(-beg, -end, 1.0)
+
+ if self.clamp_len > 0:
+ fwd_pos_seq = tf.clip_by_value(fwd_pos_seq, -self.clamp_len, self.clamp_len)
+ bwd_pos_seq = tf.clip_by_value(bwd_pos_seq, -self.clamp_len, self.clamp_len)
+
+ if bsz is not None:
+ if bsz % 2 != 0:
+ raise ValueError(f"With bi_data, the batch size {bsz} should be divisible by 2")
+ fwd_pos_emb = self.positional_embedding(fwd_pos_seq, inv_freq, bsz // 2)
+ bwd_pos_emb = self.positional_embedding(bwd_pos_seq, inv_freq, bsz // 2)
+ else:
+ fwd_pos_emb = self.positional_embedding(fwd_pos_seq, inv_freq)
+ bwd_pos_emb = self.positional_embedding(bwd_pos_seq, inv_freq)
+
+ pos_emb = tf.concat([fwd_pos_emb, bwd_pos_emb], axis=1)
+ else:
+ fwd_pos_seq = tf.range(beg, end, -1.0)
+ if self.clamp_len > 0:
+ fwd_pos_seq = tf.clip_by_value(fwd_pos_seq, -self.clamp_len, self.clamp_len)
+ pos_emb = self.positional_embedding(fwd_pos_seq, inv_freq, bsz)
+
+ return pos_emb
+
+ @unpack_inputs
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ mems: np.ndarray | tf.Tensor | None = None,
+ perm_mask: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ input_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_mems: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ):
+ if training and use_mems is None:
+ use_mems = self.use_mems_train
+ else:
+ use_mems = self.use_mems_eval
+
+ # the original code for XLNet uses shapes [len, bsz] with the batch dimension at the end
+ # but we want a unified interface in the library with the batch size on the first dimension
+ # so we move here the first dimension (batch) to the end
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_ids = tf.transpose(input_ids, perm=(1, 0))
+ qlen, bsz = shape_list(input_ids)[:2]
+ elif inputs_embeds is not None:
+ inputs_embeds = tf.transpose(inputs_embeds, perm=(1, 0, 2))
+ qlen, bsz = shape_list(inputs_embeds)[:2]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ token_type_ids = tf.transpose(token_type_ids, perm=(1, 0)) if token_type_ids is not None else None
+ input_mask = tf.transpose(input_mask, perm=(1, 0)) if input_mask is not None else None
+ attention_mask = tf.transpose(attention_mask, perm=(1, 0)) if attention_mask is not None else None
+ perm_mask = tf.transpose(perm_mask, perm=(1, 2, 0)) if perm_mask is not None else None
+ target_mapping = tf.transpose(target_mapping, perm=(1, 2, 0)) if target_mapping is not None else None
+
+ mlen = shape_list(mems[0])[0] if mems is not None and mems[0] is not None else 0
+ klen = mlen + qlen
+
+ # Attention mask
+ # causal attention mask
+ if self.attn_type == "uni":
+ attn_mask = self.create_mask(qlen, mlen)
+ attn_mask = attn_mask[:, :, None, None]
+ elif self.attn_type == "bi":
+ attn_mask = None
+ else:
+ raise ValueError(f"Unsupported attention type: {self.attn_type}")
+
+ # data mask: input mask & perm mask
+ assert input_mask is None or attention_mask is None, (
+ "You can only use one of input_mask (uses 1 for padding) "
+ "or attention_mask (uses 0 for padding, added for compatibility with BERT). Please choose one."
+ )
+ if input_mask is None and attention_mask is not None:
+ one_cst = tf.constant(1.0)
+ input_mask = 1.0 - tf.cast(attention_mask, dtype=one_cst.dtype)
+ if input_mask is not None and perm_mask is not None:
+ data_mask = input_mask[None] + perm_mask
+ elif input_mask is not None and perm_mask is None:
+ data_mask = input_mask[None]
+ elif input_mask is None and perm_mask is not None:
+ data_mask = perm_mask
+ else:
+ data_mask = None
+
+ if data_mask is not None:
+ # all mems can be attended to
+ if mlen > 0:
+ mems_mask = tf.zeros([shape_list(data_mask)[0], mlen, bsz])
+ data_mask = tf.concat([mems_mask, data_mask], axis=1)
+ if attn_mask is None:
+ attn_mask = data_mask[:, :, :, None]
+ else:
+ attn_mask += data_mask[:, :, :, None]
+
+ if attn_mask is not None:
+ attn_mask = tf.cast(attn_mask > 0, dtype=attn_mask.dtype)
+
+ if attn_mask is not None:
+ non_tgt_mask = -tf.eye(qlen)
+ if mlen > 0:
+ non_tgt_mask = tf.concat([tf.zeros([qlen, mlen]), non_tgt_mask], axis=-1)
+ non_tgt_mask = tf.cast((attn_mask + non_tgt_mask[:, :, None, None]) > 0, dtype=non_tgt_mask.dtype)
+ else:
+ non_tgt_mask = None
+
+ # Word embeddings and prepare h & g hidden states
+ if inputs_embeds is not None:
+ word_emb_k = inputs_embeds
+ else:
+ check_embeddings_within_bounds(input_ids, self.word_embedding.vocab_size)
+ word_emb_k = self.word_embedding(input_ids)
+ output_h = self.dropout(word_emb_k, training=training)
+ if target_mapping is not None:
+ word_emb_q = tf.tile(self.mask_emb, [shape_list(target_mapping)[0], bsz, 1])
+ # else: # We removed the inp_q input which was same as target mapping
+ # inp_q_ext = inp_q[:, :, None]
+ # word_emb_q = inp_q_ext * self.mask_emb + (1 - inp_q_ext) * word_emb_k
+ output_g = self.dropout(word_emb_q, training=training)
+ else:
+ output_g = None
+
+ # Segment embedding
+ if token_type_ids is not None:
+ # Convert `token_type_ids` to one-hot `seg_mat`
+ if mlen > 0:
+ mem_pad = tf.zeros([mlen, bsz], dtype=token_type_ids.dtype)
+ cat_ids = tf.concat([mem_pad, token_type_ids], 0)
+ else:
+ cat_ids = token_type_ids
+
+ # `1` indicates not in the same segment [qlen x klen x bsz]
+ seg_mat = tf.cast(
+ tf.logical_not(tf.equal(token_type_ids[:, None], cat_ids[None, :])),
+ dtype=token_type_ids.dtype,
+ )
+ seg_mat = tf.one_hot(seg_mat, 2)
+ else:
+ seg_mat = None
+
+ # Positional encoding
+ pos_emb = self.relative_positional_encoding(qlen, klen, bsz=bsz)
+ pos_emb = self.dropout(pos_emb, training=training)
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads] (a head_mask for each layer)
+ # and head_mask is converted to shape [num_hidden_layers x qlen x klen x bsz x n_head]
+ if head_mask is not None:
+ raise NotImplementedError
+ else:
+ head_mask = [None] * self.n_layer
+
+ new_mems = ()
+ if mems is None:
+ mems = [None] * len(self.layer)
+
+ attentions = [] if output_attentions else None
+ hidden_states = [] if output_hidden_states else None
+ for i, layer_module in enumerate(self.layer):
+ # cache new mems
+ if use_mems:
+ new_mems = new_mems + (self.cache_mem(output_h, mems[i]),)
+ if output_hidden_states:
+ hidden_states.append((output_h, output_g) if output_g is not None else output_h)
+
+ outputs = layer_module(
+ output_h,
+ output_g,
+ non_tgt_mask,
+ attn_mask,
+ pos_emb,
+ seg_mat,
+ mems[i],
+ target_mapping,
+ head_mask[i],
+ output_attentions,
+ training=training,
+ )
+ output_h, output_g = outputs[:2]
+ if output_attentions:
+ attentions.append(outputs[2])
+
+ # Add last hidden state
+ if output_hidden_states:
+ hidden_states.append((output_h, output_g) if output_g is not None else output_h)
+
+ output = self.dropout(output_g if output_g is not None else output_h, training=training)
+
+ # Prepare outputs, we transpose back here to shape [bsz, len, hidden_dim] (cf. beginning of forward() method)
+ output = tf.transpose(output, perm=(1, 0, 2))
+
+ if not use_mems:
+ new_mems = None
+ if output_hidden_states:
+ if output_g is not None:
+ hidden_states = tuple(tf.transpose(h, perm=(1, 0, 2)) for hs in hidden_states for h in hs)
+ else:
+ hidden_states = tuple(tf.transpose(hs, perm=(1, 0, 2)) for hs in hidden_states)
+ if output_attentions:
+ if target_mapping is not None:
+ # when target_mapping is provided, there are 2-tuple of attentions
+ attentions = tuple(
+ tuple(tf.transpose(attn_stream, perm=(2, 3, 0, 1)) for attn_stream in t) for t in attentions
+ )
+ else:
+ attentions = tuple(tf.transpose(t, perm=(2, 3, 0, 1)) for t in attentions)
+
+ if not return_dict:
+ return tuple(v for v in [output, new_mems, hidden_states, attentions] if v is not None)
+
+ return TFXLNetModelOutput(
+ last_hidden_state=output, mems=new_mems, hidden_states=hidden_states, attentions=attentions
+ )
+
+
+class TFXLNetPreTrainedModel(TFPreTrainedModel):
+ """
+ An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained
+ models.
+ """
+
+ config_class = XLNetConfig
+ base_model_prefix = "transformer"
+
+
+@dataclass
+class TFXLNetModelOutput(ModelOutput):
+ """
+ Output type of [`TFXLNetModel`].
+
+ Args:
+ last_hidden_state (`tf.Tensor` of shape `(batch_size, num_predict, hidden_size)`):
+ Sequence of hidden-states at the last layer of the model.
+
+ `num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict`
+ corresponds to `sequence_length`.
+ mems (`list[tf.Tensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ last_hidden_state: tf.Tensor | None = None
+ mems: list[tf.Tensor] | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+
+
+@dataclass
+class TFXLNetLMHeadModelOutput(ModelOutput):
+ """
+ Output type of [`TFXLNetLMHeadModel`].
+
+ Args:
+ loss (`tf.Tensor` of shape *(1,)*, *optional*, returned when `labels` is provided)
+ Language modeling loss (for next-token prediction).
+ logits (`tf.Tensor` of shape `(batch_size, num_predict, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+
+ `num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict`
+ corresponds to `sequence_length`.
+ mems (`list[tf.Tensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ loss: tf.Tensor | None = None
+ logits: tf.Tensor | None = None
+ mems: list[tf.Tensor] | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+
+
+@dataclass
+class TFXLNetForSequenceClassificationOutput(ModelOutput):
+ """
+ Output type of [`TFXLNetForSequenceClassification`].
+
+ Args:
+ loss (`tf.Tensor` of shape `(1,)`, *optional*, returned when `label` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (`tf.Tensor` of shape `(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ mems (`list[tf.Tensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ loss: tf.Tensor | None = None
+ logits: tf.Tensor | None = None
+ mems: list[tf.Tensor] | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+
+
+@dataclass
+class TFXLNetForTokenClassificationOutput(ModelOutput):
+ """
+ Output type of [`TFXLNetForTokenClassificationOutput`].
+
+ Args:
+ loss (`tf.Tensor` of shape `(1,)`, *optional*, returned when `labels` is provided) :
+ Classification loss.
+ logits (`tf.Tensor` of shape `(batch_size, sequence_length, config.num_labels)`):
+ Classification scores (before SoftMax).
+ mems (`list[tf.Tensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ loss: tf.Tensor | None = None
+ logits: tf.Tensor | None = None
+ mems: list[tf.Tensor] | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+
+
+@dataclass
+class TFXLNetForMultipleChoiceOutput(ModelOutput):
+ """
+ Output type of [`TFXLNetForMultipleChoice`].
+
+ Args:
+ loss (`tf.Tensor` of shape *(1,)*, *optional*, returned when `labels` is provided):
+ Classification loss.
+ logits (`tf.Tensor` of shape `(batch_size, num_choices)`):
+ *num_choices* is the second dimension of the input tensors. (see *input_ids* above).
+
+ Classification scores (before SoftMax).
+ mems (`list[tf.Tensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ loss: tf.Tensor | None = None
+ logits: tf.Tensor | None = None
+ mems: list[tf.Tensor] | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+
+
+@dataclass
+class TFXLNetForQuestionAnsweringSimpleOutput(ModelOutput):
+ """
+ Output type of [`TFXLNetForQuestionAnsweringSimple`].
+
+ Args:
+ loss (`tf.Tensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Total span extraction loss is the sum of a Cross-Entropy for the start and end positions.
+ start_logits (`tf.Tensor` of shape `(batch_size, sequence_length,)`):
+ Span-start scores (before SoftMax).
+ end_logits (`tf.Tensor` of shape `(batch_size, sequence_length,)`):
+ Span-end scores (before SoftMax).
+ mems (`list[tf.Tensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ hidden_states (`tuple(tf.Tensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`):
+ Tuple of `tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of shape
+ `(batch_size, sequence_length, hidden_size)`.
+
+ Hidden-states of the model at the output of each layer plus the initial embedding outputs.
+ attentions (`tuple(tf.Tensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`):
+ Tuple of `tf.Tensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length,
+ sequence_length)`.
+
+ Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
+ heads.
+ """
+
+ loss: tf.Tensor | None = None
+ start_logits: tf.Tensor | None = None
+ end_logits: tf.Tensor | None = None
+ mems: list[tf.Tensor] | None = None
+ hidden_states: tuple[tf.Tensor, ...] | None = None
+ attentions: tuple[tf.Tensor, ...] | None = None
+
+
+XLNET_START_DOCSTRING = r"""
+
+ This model inherits from [`TFPreTrainedModel`]. Check the superclass documentation for the generic methods the
+ library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads
+ etc.)
+
+ This model is also a [keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model) subclass. Use it
+ as a regular TF 2.0 Keras Model and refer to the TF 2.0 documentation for all matter related to general usage and
+ behavior.
+
+
+
+ TensorFlow models and layers in `transformers` accept two formats as input:
+
+ - having all inputs as keyword arguments (like PyTorch models), or
+ - having all inputs as a list, tuple or dict in the first positional argument.
+
+ The reason the second format is supported is that Keras methods prefer this format when passing inputs to models
+ and layers. Because of this support, when using methods like `model.fit()` things should "just work" for you - just
+ pass your inputs and labels in any format that `model.fit()` supports! If, however, you want to use the second
+ format outside of Keras methods like `fit()` and `predict()`, such as when creating your own layers or models with
+ the Keras `Functional` API, there are three possibilities you can use to gather all the input Tensors in the first
+ positional argument:
+
+ - a single Tensor with `input_ids` only and nothing else: `model(input_ids)`
+ - a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
+ `model([input_ids, attention_mask])` or `model([input_ids, attention_mask, token_type_ids])`
+ - a dictionary with one or several input Tensors associated to the input names given in the docstring:
+ `model({"input_ids": input_ids, "token_type_ids": token_type_ids})`
+
+ Note that when creating models and layers with
+ [subclassing](https://keras.io/guides/making_new_layers_and_models_via_subclassing/) then you don't need to worry
+ about any of this, as you can just pass inputs like you would to any other Python function!
+
+
+
+ Parameters:
+ config ([`XLNetConfig`]): Model configuration class with all the parameters of the model.
+ Initializing with a config file does not load the weights associated with the model, only the
+ configuration. Check out the [`~PreTrainedModel.from_pretrained`] method to load the model weights.
+"""
+
+XLNET_INPUTS_DOCSTRING = r"""
+ Args:
+ input_ids (`torch.LongTensor` of shape `({0})`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ attention_mask (`torch.FloatTensor` of shape `({0})`, *optional*):
+ Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **not masked**,
+ - 0 for tokens that are **masked**.
+
+ [What are attention masks?](../glossary#attention-mask)
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ token_type_ids (`torch.LongTensor` of shape `({0})`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ input_mask (`torch.FloatTensor` of shape `{0}`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ head_mask (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*):
+ Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`:
+
+ - 1 indicates the head is **not masked**,
+ - 0 indicates the head is **masked**.
+
+ inputs_embeds (`torch.FloatTensor` of shape `({0}, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned
+ tensors for more detail.
+ output_hidden_states (`bool`, *optional*):
+ Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for
+ more detail.
+ return_dict (`bool`, *optional*):
+ Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
+"""
+
+
+@add_start_docstrings(
+ "The bare XLNet Model transformer outputting raw hidden-states without any specific head on top.",
+ XLNET_START_DOCSTRING,
+)
+class TFXLNetModel(TFXLNetPreTrainedModel):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.transformer = TFXLNetMainLayer(config, name="transformer")
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLNET_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFXLNetModelOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ mems: np.ndarray | tf.Tensor | None = None,
+ perm_mask: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ input_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_mems: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ training: bool = False,
+ ) -> TFXLNetModelOutput | tuple[tf.Tensor]:
+ outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+
+ return outputs
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+
+
+@add_start_docstrings(
+ """
+ XLNet Model with a language modeling head on top (linear layer with weights tied to the input embeddings).
+ """,
+ XLNET_START_DOCSTRING,
+)
+class TFXLNetLMHeadModel(TFXLNetPreTrainedModel, TFCausalLanguageModelingLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.transformer = TFXLNetMainLayer(config, name="transformer")
+ self.lm_loss = TFXLNetLMHead(config, self.transformer.word_embedding, name="lm_loss")
+ # generate fails to convert to a graph with XLNet
+ self.supports_xla_generation = False
+
+ def get_lm_head(self):
+ return self.lm_loss
+
+ def get_prefix_bias_name(self):
+ warnings.warn("The method get_prefix_bias_name is deprecated. Please use `get_bias` instead.", FutureWarning)
+ return self.name + "/" + self.lm_loss.name
+
+ def prepare_inputs_for_generation(self, inputs, past_key_values=None, use_mems=None, **kwargs):
+ # Add dummy token at the end (no attention on this one)
+ effective_batch_size = inputs.shape[0]
+ dummy_token = tf.zeros((effective_batch_size, 1), dtype=inputs.dtype)
+
+ # At every pass, the attention values for the new token and the two last generated tokens
+ # are computed, the rest is reloaded from the `past` cache. A purely auto-regressive model would have
+ # offset = 1; offset = 2 seems to have slightly better computation.
+ offset = 2
+
+ if past_key_values:
+ input_ids = tf.concat([inputs[:, -offset:], dummy_token], axis=1)
+ else:
+ input_ids = tf.concat([inputs, dummy_token], axis=1)
+
+ # Build permutation mask so that previous tokens don't see last token
+ sequence_length = input_ids.shape[1]
+ perm_mask = tf.zeros((effective_batch_size, sequence_length, sequence_length - 1))
+ perm_mask_seq_end = tf.ones((effective_batch_size, sequence_length, 1))
+ perm_mask = tf.concat([perm_mask, perm_mask_seq_end], axis=-1)
+
+ # We'll only predict the last token
+ target_mapping = tf.zeros((effective_batch_size, 1, sequence_length - 1))
+ target_mapping_seq_end = tf.ones((effective_batch_size, 1, 1))
+ target_mapping = tf.concat([target_mapping, target_mapping_seq_end], axis=-1)
+
+ inputs = {
+ "input_ids": input_ids,
+ "perm_mask": perm_mask,
+ "target_mapping": target_mapping,
+ "use_mems": use_mems,
+ }
+
+ # if past is defined in model kwargs then use it for faster decoding
+ if past_key_values:
+ inputs["mems"] = tuple(layer_past[:-offset, :, :] for layer_past in past_key_values)
+
+ return inputs
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLNET_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @replace_return_docstrings(output_type=TFXLNetLMHeadModelOutput, config_class=_CONFIG_FOR_DOC)
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ mems: np.ndarray | tf.Tensor | None = None,
+ perm_mask: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ input_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_mems: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFXLNetLMHeadModelOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the cross entropy classification loss. Indices should be in `[0, ...,
+ config.vocab_size - 1]`.
+
+ Return:
+
+ Examples:
+
+ ```python
+ >>> import tensorflow as tf
+ >>> import numpy as np
+ >>> from transformers import AutoTokenizer, TFXLNetLMHeadModel
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("xlnet/xlnet-large-cased")
+ >>> model = TFXLNetLMHeadModel.from_pretrained("xlnet/xlnet-large-cased")
+
+ >>> # We show how to setup inputs to predict a next token using a bi-directional context.
+ >>> input_ids = tf.constant(tokenizer.encode("Hello, my dog is very ", add_special_tokens=True))[
+ ... None, :
+ ... ] # We will predict the masked token
+
+ >>> perm_mask = np.zeros((1, input_ids.shape[1], input_ids.shape[1]))
+ >>> perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token
+
+ >>> target_mapping = np.zeros(
+ ... (1, 1, input_ids.shape[1])
+ ... ) # Shape [1, 1, seq_length] => let's predict one token
+ >>> target_mapping[
+ ... 0, 0, -1
+ ... ] = 1.0 # Our first (and only) prediction will be the last token of the sequence (the masked token)
+
+ >>> outputs = model(
+ ... input_ids,
+ ... perm_mask=tf.constant(perm_mask, dtype=tf.float32),
+ ... target_mapping=tf.constant(target_mapping, dtype=tf.float32),
+ ... )
+
+ >>> next_token_logits = outputs[
+ ... 0
+ ... ] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
+ ```"""
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ hidden_state = transformer_outputs[0]
+ logits = self.lm_loss(hidden_state, training=training)
+
+ loss = None
+ if labels is not None:
+ loss = self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFXLNetLMHeadModelOutput(
+ loss=loss,
+ logits=logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "lm_loss", None) is not None:
+ with tf.name_scope(self.lm_loss.name):
+ self.lm_loss.build(None)
+
+
+@add_start_docstrings(
+ """
+ XLNet Model with a sequence classification/regression head on top (a linear layer on top of the pooled output) e.g.
+ for GLUE tasks.
+ """,
+ XLNET_START_DOCSTRING,
+)
+class TFXLNetForSequenceClassification(TFXLNetPreTrainedModel, TFSequenceClassificationLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.transformer = TFXLNetMainLayer(config, name="transformer")
+ self.sequence_summary = TFSequenceSummary(
+ config, initializer_range=config.initializer_range, name="sequence_summary"
+ )
+ self.logits_proj = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="logits_proj"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLNET_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFXLNetForSequenceClassificationOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ mems: np.ndarray | tf.Tensor | None = None,
+ perm_mask: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ input_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_mems: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFXLNetForSequenceClassificationOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ output = transformer_outputs[0]
+
+ output = self.sequence_summary(output)
+ logits = self.logits_proj(output)
+
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFXLNetForSequenceClassificationOutput(
+ loss=loss,
+ logits=logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "sequence_summary", None) is not None:
+ with tf.name_scope(self.sequence_summary.name):
+ self.sequence_summary.build(None)
+ if getattr(self, "logits_proj", None) is not None:
+ with tf.name_scope(self.logits_proj.name):
+ self.logits_proj.build([None, None, self.config.d_model])
+
+
+@add_start_docstrings(
+ """
+ XLNET Model with a multiple choice classification head on top (a linear layer on top of the pooled output and a
+ softmax) e.g. for RocStories/SWAG tasks.
+ """,
+ XLNET_START_DOCSTRING,
+)
+class TFXLNetForMultipleChoice(TFXLNetPreTrainedModel, TFMultipleChoiceLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+
+ self.transformer = TFXLNetMainLayer(config, name="transformer")
+ self.sequence_summary = TFSequenceSummary(
+ config, initializer_range=config.initializer_range, name="sequence_summary"
+ )
+ self.logits_proj = keras.layers.Dense(
+ 1, kernel_initializer=get_initializer(config.initializer_range), name="logits_proj"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLNET_INPUTS_DOCSTRING.format("batch_size, num_choices, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFXLNetForMultipleChoiceOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ input_mask: np.ndarray | tf.Tensor | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ mems: np.ndarray | tf.Tensor | None = None,
+ perm_mask: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_mems: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFXLNetForMultipleChoiceOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., num_choices]`
+ where `num_choices` is the size of the second dimension of the input tensors. (See `input_ids` above)
+ """
+
+ if input_ids is not None:
+ num_choices = shape_list(input_ids)[1]
+ seq_length = shape_list(input_ids)[2]
+ else:
+ num_choices = shape_list(inputs_embeds)[1]
+ seq_length = shape_list(inputs_embeds)[2]
+
+ flat_input_ids = tf.reshape(input_ids, (-1, seq_length)) if input_ids is not None else None
+ flat_attention_mask = tf.reshape(attention_mask, (-1, seq_length)) if attention_mask is not None else None
+ flat_token_type_ids = tf.reshape(token_type_ids, (-1, seq_length)) if token_type_ids is not None else None
+ flat_input_mask = tf.reshape(input_mask, (-1, seq_length)) if input_mask is not None else None
+ flat_inputs_embeds = (
+ tf.reshape(inputs_embeds, (-1, seq_length, shape_list(inputs_embeds)[3]))
+ if inputs_embeds is not None
+ else None
+ )
+ transformer_outputs = self.transformer(
+ flat_input_ids,
+ flat_attention_mask,
+ mems,
+ perm_mask,
+ target_mapping,
+ flat_token_type_ids,
+ flat_input_mask,
+ head_mask,
+ flat_inputs_embeds,
+ use_mems,
+ output_attentions,
+ output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ output = transformer_outputs[0]
+ logits = self.sequence_summary(output)
+ logits = self.logits_proj(logits)
+ reshaped_logits = tf.reshape(logits, (-1, num_choices))
+ loss = None if labels is None else self.hf_compute_loss(labels, reshaped_logits)
+
+ if not return_dict:
+ output = (reshaped_logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFXLNetForMultipleChoiceOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "sequence_summary", None) is not None:
+ with tf.name_scope(self.sequence_summary.name):
+ self.sequence_summary.build(None)
+ if getattr(self, "logits_proj", None) is not None:
+ with tf.name_scope(self.logits_proj.name):
+ self.logits_proj.build([None, None, self.config.d_model])
+
+
+@add_start_docstrings(
+ """
+ XLNet Model with a token classification head on top (a linear layer on top of the hidden-states output) e.g. for
+ Named-Entity-Recognition (NER) tasks.
+ """,
+ XLNET_START_DOCSTRING,
+)
+class TFXLNetForTokenClassification(TFXLNetPreTrainedModel, TFTokenClassificationLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.num_labels = config.num_labels
+
+ self.transformer = TFXLNetMainLayer(config, name="transformer")
+ self.classifier = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="classifier"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLNET_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFXLNetForTokenClassificationOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ mems: np.ndarray | tf.Tensor | None = None,
+ perm_mask: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ input_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_mems: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ labels: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFXLNetForTokenClassificationOutput | tuple[tf.Tensor]:
+ r"""
+ labels (`tf.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ output = transformer_outputs[0]
+ logits = self.classifier(output)
+ loss = None if labels is None else self.hf_compute_loss(labels, logits)
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFXLNetForTokenClassificationOutput(
+ loss=loss,
+ logits=logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "classifier", None) is not None:
+ with tf.name_scope(self.classifier.name):
+ self.classifier.build([None, None, self.config.hidden_size])
+
+
+@add_start_docstrings(
+ """
+ XLNet Model with a span classification head on top for extractive question-answering tasks like SQuAD (a linear
+ layers on top of the hidden-states output to compute `span start logits` and `span end logits`).
+ """,
+ XLNET_START_DOCSTRING,
+)
+class TFXLNetForQuestionAnsweringSimple(TFXLNetPreTrainedModel, TFQuestionAnsweringLoss):
+ def __init__(self, config, *inputs, **kwargs):
+ super().__init__(config, *inputs, **kwargs)
+ self.transformer = TFXLNetMainLayer(config, name="transformer")
+ self.qa_outputs = keras.layers.Dense(
+ config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="qa_outputs"
+ )
+ self.config = config
+
+ @unpack_inputs
+ @add_start_docstrings_to_model_forward(XLNET_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
+ @add_code_sample_docstrings(
+ checkpoint=_CHECKPOINT_FOR_DOC,
+ output_type=TFXLNetForQuestionAnsweringSimpleOutput,
+ config_class=_CONFIG_FOR_DOC,
+ )
+ def call(
+ self,
+ input_ids: TFModelInputType | None = None,
+ attention_mask: np.ndarray | tf.Tensor | None = None,
+ mems: np.ndarray | tf.Tensor | None = None,
+ perm_mask: np.ndarray | tf.Tensor | None = None,
+ target_mapping: np.ndarray | tf.Tensor | None = None,
+ token_type_ids: np.ndarray | tf.Tensor | None = None,
+ input_mask: np.ndarray | tf.Tensor | None = None,
+ head_mask: np.ndarray | tf.Tensor | None = None,
+ inputs_embeds: np.ndarray | tf.Tensor | None = None,
+ use_mems: bool | None = None,
+ output_attentions: bool | None = None,
+ output_hidden_states: bool | None = None,
+ return_dict: bool | None = None,
+ start_positions: np.ndarray | tf.Tensor | None = None,
+ end_positions: np.ndarray | tf.Tensor | None = None,
+ training: bool = False,
+ ) -> TFXLNetForQuestionAnsweringSimpleOutput | tuple[tf.Tensor]:
+ r"""
+ start_positions (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the start of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ end_positions (`tf.Tensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the end of the labelled span for computing the token classification loss.
+ Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence
+ are not taken into account for computing the loss.
+ """
+ transformer_outputs = self.transformer(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ training=training,
+ )
+ sequence_output = transformer_outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = tf.split(logits, 2, axis=-1)
+ start_logits = tf.squeeze(start_logits, axis=-1)
+ end_logits = tf.squeeze(end_logits, axis=-1)
+
+ loss = None
+ if start_positions is not None and end_positions is not None:
+ labels = {"start_position": start_positions}
+ labels["end_position"] = end_positions
+ loss = self.hf_compute_loss(labels, (start_logits, end_logits))
+
+ if not return_dict:
+ output = (start_logits, end_logits) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TFXLNetForQuestionAnsweringSimpleOutput(
+ loss=loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ def build(self, input_shape=None):
+ if self.built:
+ return
+ self.built = True
+ if getattr(self, "transformer", None) is not None:
+ with tf.name_scope(self.transformer.name):
+ self.transformer.build(None)
+ if getattr(self, "qa_outputs", None) is not None:
+ with tf.name_scope(self.qa_outputs.name):
+ self.qa_outputs.build([None, None, self.config.hidden_size])
+
+
+__all__ = [
+ "TFXLNetForMultipleChoice",
+ "TFXLNetForQuestionAnsweringSimple",
+ "TFXLNetForSequenceClassification",
+ "TFXLNetForTokenClassification",
+ "TFXLNetLMHeadModel",
+ "TFXLNetMainLayer",
+ "TFXLNetModel",
+ "TFXLNetPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/modeling_xlnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/modeling_xlnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..736521ee9561d985a2e17eb41246f0e3ff6615e3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/modeling_xlnet.py
@@ -0,0 +1,2380 @@
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+PyTorch XLNet model.
+"""
+
+import warnings
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN, get_activation
+from ...generation import GenerationMixin
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward
+from ...utils import ModelOutput, auto_docstring, logging
+from .configuration_xlnet import XLNetConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+def build_tf_xlnet_to_pytorch_map(model, config, tf_weights=None):
+ """
+ A map of modules from TF to PyTorch. I use a map to keep the PyTorch model as identical to the original PyTorch
+ model as possible.
+ """
+
+ tf_to_pt_map = {}
+
+ if hasattr(model, "transformer"):
+ if hasattr(model, "lm_loss"):
+ # We will load also the output bias
+ tf_to_pt_map["model/lm_loss/bias"] = model.lm_loss.bias
+ if hasattr(model, "sequence_summary") and "model/sequnece_summary/summary/kernel" in tf_weights:
+ # We will load also the sequence summary
+ tf_to_pt_map["model/sequnece_summary/summary/kernel"] = model.sequence_summary.summary.weight
+ tf_to_pt_map["model/sequnece_summary/summary/bias"] = model.sequence_summary.summary.bias
+ if (
+ hasattr(model, "logits_proj")
+ and config.finetuning_task is not None
+ and f"model/regression_{config.finetuning_task}/logit/kernel" in tf_weights
+ ):
+ tf_to_pt_map[f"model/regression_{config.finetuning_task}/logit/kernel"] = model.logits_proj.weight
+ tf_to_pt_map[f"model/regression_{config.finetuning_task}/logit/bias"] = model.logits_proj.bias
+
+ # Now load the rest of the transformer
+ model = model.transformer
+
+ # Embeddings and output
+ tf_to_pt_map.update(
+ {
+ "model/transformer/word_embedding/lookup_table": model.word_embedding.weight,
+ "model/transformer/mask_emb/mask_emb": model.mask_emb,
+ }
+ )
+
+ # Transformer blocks
+ for i, b in enumerate(model.layer):
+ layer_str = f"model/transformer/layer_{i}/"
+ tf_to_pt_map.update(
+ {
+ layer_str + "rel_attn/LayerNorm/gamma": b.rel_attn.layer_norm.weight,
+ layer_str + "rel_attn/LayerNorm/beta": b.rel_attn.layer_norm.bias,
+ layer_str + "rel_attn/o/kernel": b.rel_attn.o,
+ layer_str + "rel_attn/q/kernel": b.rel_attn.q,
+ layer_str + "rel_attn/k/kernel": b.rel_attn.k,
+ layer_str + "rel_attn/r/kernel": b.rel_attn.r,
+ layer_str + "rel_attn/v/kernel": b.rel_attn.v,
+ layer_str + "ff/LayerNorm/gamma": b.ff.layer_norm.weight,
+ layer_str + "ff/LayerNorm/beta": b.ff.layer_norm.bias,
+ layer_str + "ff/layer_1/kernel": b.ff.layer_1.weight,
+ layer_str + "ff/layer_1/bias": b.ff.layer_1.bias,
+ layer_str + "ff/layer_2/kernel": b.ff.layer_2.weight,
+ layer_str + "ff/layer_2/bias": b.ff.layer_2.bias,
+ }
+ )
+
+ # Relative positioning biases
+ if config.untie_r:
+ r_r_list = []
+ r_w_list = []
+ r_s_list = []
+ seg_embed_list = []
+ for b in model.layer:
+ r_r_list.append(b.rel_attn.r_r_bias)
+ r_w_list.append(b.rel_attn.r_w_bias)
+ r_s_list.append(b.rel_attn.r_s_bias)
+ seg_embed_list.append(b.rel_attn.seg_embed)
+ else:
+ r_r_list = [model.r_r_bias]
+ r_w_list = [model.r_w_bias]
+ r_s_list = [model.r_s_bias]
+ seg_embed_list = [model.seg_embed]
+ tf_to_pt_map.update(
+ {
+ "model/transformer/r_r_bias": r_r_list,
+ "model/transformer/r_w_bias": r_w_list,
+ "model/transformer/r_s_bias": r_s_list,
+ "model/transformer/seg_embed": seg_embed_list,
+ }
+ )
+ return tf_to_pt_map
+
+
+def load_tf_weights_in_xlnet(model, config, tf_path):
+ """Load tf checkpoints in a pytorch model"""
+ try:
+ import numpy as np
+ import tensorflow as tf
+ except ImportError:
+ logger.error(
+ "Loading a TensorFlow models in PyTorch, requires TensorFlow to be installed. Please see "
+ "https://www.tensorflow.org/install/ for installation instructions."
+ )
+ raise
+ # Load weights from TF model
+ init_vars = tf.train.list_variables(tf_path)
+ tf_weights = {}
+ for name, shape in init_vars:
+ logger.info(f"Loading TF weight {name} with shape {shape}")
+ array = tf.train.load_variable(tf_path, name)
+ tf_weights[name] = array
+
+ # Build TF to PyTorch weights loading map
+ tf_to_pt_map = build_tf_xlnet_to_pytorch_map(model, config, tf_weights)
+
+ for name, pointer in tf_to_pt_map.items():
+ logger.info(f"Importing {name}")
+ if name not in tf_weights:
+ logger.info(f"{name} not in tf pre-trained weights, skipping")
+ continue
+ array = tf_weights[name]
+ # adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
+ # which are not required for using pretrained model
+ if "kernel" in name and ("ff" in name or "summary" in name or "logit" in name):
+ logger.info("Transposing")
+ array = np.transpose(array)
+ if isinstance(pointer, list):
+ # Here we will split the TF weights
+ assert len(pointer) == array.shape[0], (
+ f"Pointer length {len(pointer)} and array length {array.shape[0]} mismatched"
+ )
+ for i, p_i in enumerate(pointer):
+ arr_i = array[i, ...]
+ try:
+ assert p_i.shape == arr_i.shape, (
+ f"Pointer shape {p_i.shape} and array shape {arr_i.shape} mismatched"
+ )
+ except AssertionError as e:
+ e.args += (p_i.shape, arr_i.shape)
+ raise
+ logger.info(f"Initialize PyTorch weight {name} for layer {i}")
+ p_i.data = torch.from_numpy(arr_i)
+ else:
+ try:
+ assert pointer.shape == array.shape, (
+ f"Pointer shape {pointer.shape} and array shape {array.shape} mismatched"
+ )
+ except AssertionError as e:
+ e.args += (pointer.shape, array.shape)
+ raise
+ logger.info(f"Initialize PyTorch weight {name}")
+ pointer.data = torch.from_numpy(array)
+ tf_weights.pop(name, None)
+ tf_weights.pop(name + "/Adam", None)
+ tf_weights.pop(name + "/Adam_1", None)
+
+ logger.info(f"Weights not copied to PyTorch model: {', '.join(tf_weights.keys())}")
+ return model
+
+
+class XLNetRelativeAttention(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+
+ if config.d_model % config.n_head != 0:
+ raise ValueError(
+ f"The hidden size ({config.d_model}) is not a multiple of the number of attention "
+ f"heads ({config.n_head}"
+ )
+
+ self.n_head = config.n_head
+ self.d_head = config.d_head
+ self.d_model = config.d_model
+ self.scale = 1 / (config.d_head**0.5)
+
+ self.q = nn.Parameter(torch.FloatTensor(config.d_model, self.n_head, self.d_head))
+ self.k = nn.Parameter(torch.FloatTensor(config.d_model, self.n_head, self.d_head))
+ self.v = nn.Parameter(torch.FloatTensor(config.d_model, self.n_head, self.d_head))
+ self.o = nn.Parameter(torch.FloatTensor(config.d_model, self.n_head, self.d_head))
+ self.r = nn.Parameter(torch.FloatTensor(config.d_model, self.n_head, self.d_head))
+
+ self.r_r_bias = nn.Parameter(torch.FloatTensor(self.n_head, self.d_head))
+ self.r_s_bias = nn.Parameter(torch.FloatTensor(self.n_head, self.d_head))
+ self.r_w_bias = nn.Parameter(torch.FloatTensor(self.n_head, self.d_head))
+ self.seg_embed = nn.Parameter(torch.FloatTensor(2, self.n_head, self.d_head))
+
+ self.layer_norm = nn.LayerNorm(config.d_model, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.dropout)
+
+ def prune_heads(self, heads):
+ raise NotImplementedError
+
+ @staticmethod
+ def rel_shift(x, klen=-1):
+ """perform relative shift to form the relative attention score."""
+ x_size = x.shape
+
+ x = x.reshape(x_size[1], x_size[0], x_size[2], x_size[3])
+ x = x[1:, ...]
+ x = x.reshape(x_size[0], x_size[1] - 1, x_size[2], x_size[3])
+ # x = x[:, 0:klen, :, :]
+ x = torch.index_select(x, 1, torch.arange(klen, device=x.device, dtype=torch.long))
+
+ return x
+
+ @staticmethod
+ def rel_shift_bnij(x, klen=-1):
+ x_size = x.shape
+
+ x = x.reshape(x_size[0], x_size[1], x_size[3], x_size[2])
+ x = x[:, :, 1:, :]
+ x = x.reshape(x_size[0], x_size[1], x_size[2], x_size[3] - 1)
+ # Note: the tensor-slice form was faster in my testing than torch.index_select
+ # However, tracing doesn't like the nature of the slice, and if klen changes
+ # during the run then it'll fail, whereas index_select will be fine.
+ x = torch.index_select(x, 3, torch.arange(klen, device=x.device, dtype=torch.long))
+ # x = x[:, :, :, :klen]
+
+ return x
+
+ def rel_attn_core(
+ self,
+ q_head,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat=None,
+ attn_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ ):
+ """Core relative positional attention operations."""
+
+ # content based attention score
+ ac = torch.einsum("ibnd,jbnd->bnij", q_head + self.r_w_bias, k_head_h)
+
+ # position based attention score
+ bd = torch.einsum("ibnd,jbnd->bnij", q_head + self.r_r_bias, k_head_r)
+ bd = self.rel_shift_bnij(bd, klen=ac.shape[3])
+
+ # segment based attention score
+ if seg_mat is None:
+ ef = 0
+ else:
+ ef = torch.einsum("ibnd,snd->ibns", q_head + self.r_s_bias, self.seg_embed)
+ ef = torch.einsum("ijbs,ibns->bnij", seg_mat, ef)
+
+ # merge attention scores and perform masking
+ attn_score = (ac + bd + ef) * self.scale
+ if attn_mask is not None:
+ # attn_score = attn_score * (1 - attn_mask) - 1e30 * attn_mask
+ if attn_mask.dtype == torch.float16:
+ attn_score = attn_score - 65500 * torch.einsum("ijbn->bnij", attn_mask)
+ else:
+ attn_score = attn_score - 1e30 * torch.einsum("ijbn->bnij", attn_mask)
+
+ # attention probability
+ attn_prob = nn.functional.softmax(attn_score, dim=3)
+ attn_prob = self.dropout(attn_prob)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attn_prob = attn_prob * torch.einsum("ijbn->bnij", head_mask)
+
+ # attention output
+ attn_vec = torch.einsum("bnij,jbnd->ibnd", attn_prob, v_head_h)
+
+ if output_attentions:
+ return attn_vec, torch.einsum("bnij->ijbn", attn_prob)
+
+ return attn_vec
+
+ def post_attention(self, h, attn_vec, residual=True):
+ """Post-attention processing."""
+ # post-attention projection (back to `d_model`)
+ attn_out = torch.einsum("ibnd,hnd->ibh", attn_vec, self.o)
+
+ attn_out = self.dropout(attn_out)
+ if residual:
+ attn_out = attn_out + h
+ output = self.layer_norm(attn_out)
+
+ return output
+
+ def forward(
+ self,
+ h,
+ g,
+ attn_mask_h,
+ attn_mask_g,
+ r,
+ seg_mat,
+ mems=None,
+ target_mapping=None,
+ head_mask=None,
+ output_attentions=False,
+ ):
+ if g is not None:
+ # Two-stream attention with relative positional encoding.
+ # content based attention score
+ if mems is not None and mems.dim() > 1:
+ cat = torch.cat([mems, h], dim=0)
+ else:
+ cat = h
+
+ # content-based key head
+ k_head_h = torch.einsum("ibh,hnd->ibnd", cat, self.k)
+
+ # content-based value head
+ v_head_h = torch.einsum("ibh,hnd->ibnd", cat, self.v)
+
+ # position-based key head
+ k_head_r = torch.einsum("ibh,hnd->ibnd", r, self.r)
+
+ # h-stream
+ # content-stream query head
+ q_head_h = torch.einsum("ibh,hnd->ibnd", h, self.q)
+
+ # core attention ops
+ attn_vec_h = self.rel_attn_core(
+ q_head_h,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat=seg_mat,
+ attn_mask=attn_mask_h,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ )
+
+ if output_attentions:
+ attn_vec_h, attn_prob_h = attn_vec_h
+
+ # post processing
+ output_h = self.post_attention(h, attn_vec_h)
+
+ # g-stream
+ # query-stream query head
+ q_head_g = torch.einsum("ibh,hnd->ibnd", g, self.q)
+
+ # core attention ops
+ if target_mapping is not None:
+ q_head_g = torch.einsum("mbnd,mlb->lbnd", q_head_g, target_mapping)
+ attn_vec_g = self.rel_attn_core(
+ q_head_g,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat=seg_mat,
+ attn_mask=attn_mask_g,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ )
+
+ if output_attentions:
+ attn_vec_g, attn_prob_g = attn_vec_g
+
+ attn_vec_g = torch.einsum("lbnd,mlb->mbnd", attn_vec_g, target_mapping)
+ else:
+ attn_vec_g = self.rel_attn_core(
+ q_head_g,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat=seg_mat,
+ attn_mask=attn_mask_g,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ )
+
+ if output_attentions:
+ attn_vec_g, attn_prob_g = attn_vec_g
+
+ # post processing
+ output_g = self.post_attention(g, attn_vec_g)
+
+ if output_attentions:
+ attn_prob = attn_prob_h, attn_prob_g
+
+ else:
+ # Multi-head attention with relative positional encoding
+ if mems is not None and mems.dim() > 1:
+ cat = torch.cat([mems, h], dim=0)
+ else:
+ cat = h
+
+ # content heads
+ q_head_h = torch.einsum("ibh,hnd->ibnd", h, self.q)
+ k_head_h = torch.einsum("ibh,hnd->ibnd", cat, self.k)
+ v_head_h = torch.einsum("ibh,hnd->ibnd", cat, self.v)
+
+ # positional heads
+ # type casting for fp16 support
+ k_head_r = torch.einsum("ibh,hnd->ibnd", r.type(self.r.dtype), self.r)
+
+ # core attention ops
+ attn_vec = self.rel_attn_core(
+ q_head_h,
+ k_head_h,
+ v_head_h,
+ k_head_r,
+ seg_mat=seg_mat,
+ attn_mask=attn_mask_h,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ )
+
+ if output_attentions:
+ attn_vec, attn_prob = attn_vec
+
+ # post processing
+ output_h = self.post_attention(h, attn_vec)
+ output_g = None
+
+ outputs = (output_h, output_g)
+ if output_attentions:
+ outputs = outputs + (attn_prob,)
+ return outputs
+
+
+class XLNetFeedForward(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.layer_norm = nn.LayerNorm(config.d_model, eps=config.layer_norm_eps)
+ self.layer_1 = nn.Linear(config.d_model, config.d_inner)
+ self.layer_2 = nn.Linear(config.d_inner, config.d_model)
+ self.dropout = nn.Dropout(config.dropout)
+ if isinstance(config.ff_activation, str):
+ self.activation_function = ACT2FN[config.ff_activation]
+ else:
+ self.activation_function = config.ff_activation
+
+ def forward(self, inp):
+ output = inp
+ output = self.layer_1(output)
+ output = self.activation_function(output)
+ output = self.dropout(output)
+ output = self.layer_2(output)
+ output = self.dropout(output)
+ output = self.layer_norm(output + inp)
+ return output
+
+
+class XLNetLayer(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.rel_attn = XLNetRelativeAttention(config)
+ self.ff = XLNetFeedForward(config)
+ self.dropout = nn.Dropout(config.dropout)
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+
+ def forward(
+ self,
+ output_h,
+ output_g,
+ attn_mask_h,
+ attn_mask_g,
+ r,
+ seg_mat,
+ mems=None,
+ target_mapping=None,
+ head_mask=None,
+ output_attentions=False,
+ ):
+ outputs = self.rel_attn(
+ output_h,
+ output_g,
+ attn_mask_h,
+ attn_mask_g,
+ r,
+ seg_mat,
+ mems=mems,
+ target_mapping=target_mapping,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ )
+ output_h, output_g = outputs[:2]
+
+ if output_g is not None:
+ output_g = apply_chunking_to_forward(
+ self.ff_chunk, self.chunk_size_feed_forward, self.seq_len_dim, output_g
+ )
+ output_h = apply_chunking_to_forward(self.ff_chunk, self.chunk_size_feed_forward, self.seq_len_dim, output_h)
+
+ outputs = (output_h, output_g) + outputs[2:] # Add again attentions if there are there
+ return outputs
+
+ def ff_chunk(self, output_x):
+ output_x = self.ff(output_x)
+ return output_x
+
+
+# Copied from transformers.models.xlm.modeling_xlm.XLMPoolerStartLogits with XLM->XLNet
+class XLNetPoolerStartLogits(nn.Module):
+ """
+ Compute SQuAD start logits from sequence hidden states.
+
+ Args:
+ config ([`XLNetConfig`]):
+ The config used by the model, will be used to grab the `hidden_size` of the model.
+ """
+
+ def __init__(self, config: XLNetConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, 1)
+
+ def forward(
+ self, hidden_states: torch.FloatTensor, p_mask: Optional[torch.FloatTensor] = None
+ ) -> torch.FloatTensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`):
+ The final hidden states of the model.
+ p_mask (`torch.FloatTensor` of shape `(batch_size, seq_len)`, *optional*):
+ Mask for tokens at invalid position, such as query and special symbols (PAD, SEP, CLS). 1.0 means token
+ should be masked.
+
+ Returns:
+ `torch.FloatTensor`: The start logits for SQuAD.
+ """
+ x = self.dense(hidden_states).squeeze(-1)
+
+ if p_mask is not None:
+ if p_mask.dtype == torch.float16:
+ x = x * (1 - p_mask) - 65500 * p_mask
+ else:
+ x = x * (1 - p_mask) - 1e30 * p_mask
+
+ return x
+
+
+# Copied from transformers.models.xlm.modeling_xlm.XLMPoolerEndLogits with XLM->XLNet
+class XLNetPoolerEndLogits(nn.Module):
+ """
+ Compute SQuAD end logits from sequence hidden states.
+
+ Args:
+ config ([`XLNetConfig`]):
+ The config used by the model, will be used to grab the `hidden_size` of the model and the `layer_norm_eps`
+ to use.
+ """
+
+ def __init__(self, config: XLNetConfig):
+ super().__init__()
+ self.dense_0 = nn.Linear(config.hidden_size * 2, config.hidden_size)
+ self.activation = nn.Tanh()
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dense_1 = nn.Linear(config.hidden_size, 1)
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ start_states: Optional[torch.FloatTensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ p_mask: Optional[torch.FloatTensor] = None,
+ ) -> torch.FloatTensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`):
+ The final hidden states of the model.
+ start_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`, *optional*):
+ The hidden states of the first tokens for the labeled span.
+ start_positions (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ The position of the first token for the labeled span.
+ p_mask (`torch.FloatTensor` of shape `(batch_size, seq_len)`, *optional*):
+ Mask for tokens at invalid position, such as query and special symbols (PAD, SEP, CLS). 1.0 means token
+ should be masked.
+
+
+
+ One of `start_states` or `start_positions` should be not `None`. If both are set, `start_positions` overrides
+ `start_states`.
+
+
+
+ Returns:
+ `torch.FloatTensor`: The end logits for SQuAD.
+ """
+ assert start_states is not None or start_positions is not None, (
+ "One of start_states, start_positions should be not None"
+ )
+ if start_positions is not None:
+ slen, hsz = hidden_states.shape[-2:]
+ start_positions = start_positions[:, None, None].expand(-1, -1, hsz) # shape (bsz, 1, hsz)
+ start_states = hidden_states.gather(-2, start_positions) # shape (bsz, 1, hsz)
+ start_states = start_states.expand(-1, slen, -1) # shape (bsz, slen, hsz)
+
+ x = self.dense_0(torch.cat([hidden_states, start_states], dim=-1))
+ x = self.activation(x)
+ x = self.LayerNorm(x)
+ x = self.dense_1(x).squeeze(-1)
+
+ if p_mask is not None:
+ if p_mask.dtype == torch.float16:
+ x = x * (1 - p_mask) - 65500 * p_mask
+ else:
+ x = x * (1 - p_mask) - 1e30 * p_mask
+
+ return x
+
+
+# Copied from transformers.models.xlm.modeling_xlm.XLMPoolerAnswerClass with XLM->XLNet
+class XLNetPoolerAnswerClass(nn.Module):
+ """
+ Compute SQuAD 2.0 answer class from classification and start tokens hidden states.
+
+ Args:
+ config ([`XLNetConfig`]):
+ The config used by the model, will be used to grab the `hidden_size` of the model.
+ """
+
+ def __init__(self, config: XLNetConfig):
+ super().__init__()
+ self.dense_0 = nn.Linear(config.hidden_size * 2, config.hidden_size)
+ self.activation = nn.Tanh()
+ self.dense_1 = nn.Linear(config.hidden_size, 1, bias=False)
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ start_states: Optional[torch.FloatTensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ cls_index: Optional[torch.LongTensor] = None,
+ ) -> torch.FloatTensor:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`):
+ The final hidden states of the model.
+ start_states (`torch.FloatTensor` of shape `(batch_size, seq_len, hidden_size)`, *optional*):
+ The hidden states of the first tokens for the labeled span.
+ start_positions (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ The position of the first token for the labeled span.
+ cls_index (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Position of the CLS token for each sentence in the batch. If `None`, takes the last token.
+
+
+
+ One of `start_states` or `start_positions` should be not `None`. If both are set, `start_positions` overrides
+ `start_states`.
+
+
+
+ Returns:
+ `torch.FloatTensor`: The SQuAD 2.0 answer class.
+ """
+ # No dependency on end_feature so that we can obtain one single `cls_logits` for each sample.
+ hsz = hidden_states.shape[-1]
+ assert start_states is not None or start_positions is not None, (
+ "One of start_states, start_positions should be not None"
+ )
+ if start_positions is not None:
+ start_positions = start_positions[:, None, None].expand(-1, -1, hsz) # shape (bsz, 1, hsz)
+ start_states = hidden_states.gather(-2, start_positions).squeeze(-2) # shape (bsz, hsz)
+
+ if cls_index is not None:
+ cls_index = cls_index[:, None, None].expand(-1, -1, hsz) # shape (bsz, 1, hsz)
+ cls_token_state = hidden_states.gather(-2, cls_index).squeeze(-2) # shape (bsz, hsz)
+ else:
+ cls_token_state = hidden_states[:, -1, :] # shape (bsz, hsz)
+
+ x = self.dense_0(torch.cat([start_states, cls_token_state], dim=-1))
+ x = self.activation(x)
+ x = self.dense_1(x).squeeze(-1)
+
+ return x
+
+
+# Copied from transformers.models.xlm.modeling_xlm.XLMSequenceSummary with XLM->XLNet
+class XLNetSequenceSummary(nn.Module):
+ r"""
+ Compute a single vector summary of a sequence hidden states.
+
+ Args:
+ config ([`XLNetConfig`]):
+ The config used by the model. Relevant arguments in the config class of the model are (refer to the actual
+ config class of your model for the default values it uses):
+
+ - **summary_type** (`str`) -- The method to use to make this summary. Accepted values are:
+
+ - `"last"` -- Take the last token hidden state (like XLNet)
+ - `"first"` -- Take the first token hidden state (like Bert)
+ - `"mean"` -- Take the mean of all tokens hidden states
+ - `"cls_index"` -- Supply a Tensor of classification token position (GPT/GPT-2)
+ - `"attn"` -- Not implemented now, use multi-head attention
+
+ - **summary_use_proj** (`bool`) -- Add a projection after the vector extraction.
+ - **summary_proj_to_labels** (`bool`) -- If `True`, the projection outputs to `config.num_labels` classes
+ (otherwise to `config.hidden_size`).
+ - **summary_activation** (`Optional[str]`) -- Set to `"tanh"` to add a tanh activation to the output,
+ another string or `None` will add no activation.
+ - **summary_first_dropout** (`float`) -- Optional dropout probability before the projection and activation.
+ - **summary_last_dropout** (`float`)-- Optional dropout probability after the projection and activation.
+ """
+
+ def __init__(self, config: XLNetConfig):
+ super().__init__()
+
+ self.summary_type = getattr(config, "summary_type", "last")
+ if self.summary_type == "attn":
+ # We should use a standard multi-head attention module with absolute positional embedding for that.
+ # Cf. https://github.com/zihangdai/xlnet/blob/master/modeling.py#L253-L276
+ # We can probably just use the multi-head attention module of PyTorch >=1.1.0
+ raise NotImplementedError
+
+ self.summary = nn.Identity()
+ if hasattr(config, "summary_use_proj") and config.summary_use_proj:
+ if hasattr(config, "summary_proj_to_labels") and config.summary_proj_to_labels and config.num_labels > 0:
+ num_classes = config.num_labels
+ else:
+ num_classes = config.hidden_size
+ self.summary = nn.Linear(config.hidden_size, num_classes)
+
+ activation_string = getattr(config, "summary_activation", None)
+ self.activation: Callable = get_activation(activation_string) if activation_string else nn.Identity()
+
+ self.first_dropout = nn.Identity()
+ if hasattr(config, "summary_first_dropout") and config.summary_first_dropout > 0:
+ self.first_dropout = nn.Dropout(config.summary_first_dropout)
+
+ self.last_dropout = nn.Identity()
+ if hasattr(config, "summary_last_dropout") and config.summary_last_dropout > 0:
+ self.last_dropout = nn.Dropout(config.summary_last_dropout)
+
+ def forward(
+ self, hidden_states: torch.FloatTensor, cls_index: Optional[torch.LongTensor] = None
+ ) -> torch.FloatTensor:
+ """
+ Compute a single vector summary of a sequence hidden states.
+
+ Args:
+ hidden_states (`torch.FloatTensor` of shape `[batch_size, seq_len, hidden_size]`):
+ The hidden states of the last layer.
+ cls_index (`torch.LongTensor` of shape `[batch_size]` or `[batch_size, ...]` where ... are optional leading dimensions of `hidden_states`, *optional*):
+ Used if `summary_type == "cls_index"` and takes the last token of the sequence as classification token.
+
+ Returns:
+ `torch.FloatTensor`: The summary of the sequence hidden states.
+ """
+ if self.summary_type == "last":
+ output = hidden_states[:, -1]
+ elif self.summary_type == "first":
+ output = hidden_states[:, 0]
+ elif self.summary_type == "mean":
+ output = hidden_states.mean(dim=1)
+ elif self.summary_type == "cls_index":
+ if cls_index is None:
+ cls_index = torch.full_like(
+ hidden_states[..., :1, :],
+ hidden_states.shape[-2] - 1,
+ dtype=torch.long,
+ )
+ else:
+ cls_index = cls_index.unsqueeze(-1).unsqueeze(-1)
+ cls_index = cls_index.expand((-1,) * (cls_index.dim() - 1) + (hidden_states.size(-1),))
+ # shape of cls_index: (bsz, XX, 1, hidden_size) where XX are optional leading dim of hidden_states
+ output = hidden_states.gather(-2, cls_index).squeeze(-2) # shape (bsz, XX, hidden_size)
+ elif self.summary_type == "attn":
+ raise NotImplementedError
+
+ output = self.first_dropout(output)
+ output = self.summary(output)
+ output = self.activation(output)
+ output = self.last_dropout(output)
+
+ return output
+
+
+@auto_docstring
+class XLNetPreTrainedModel(PreTrainedModel):
+ config: XLNetConfig
+ load_tf_weights = load_tf_weights_in_xlnet
+ base_model_prefix = "transformer"
+
+ def _init_weights(self, module):
+ """Initialize the weights."""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, XLNetRelativeAttention):
+ for param in [
+ module.q,
+ module.k,
+ module.v,
+ module.o,
+ module.r,
+ module.r_r_bias,
+ module.r_s_bias,
+ module.r_w_bias,
+ module.seg_embed,
+ ]:
+ param.data.normal_(mean=0.0, std=self.config.initializer_range)
+ elif isinstance(module, XLNetModel):
+ module.mask_emb.data.normal_(mean=0.0, std=self.config.initializer_range)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`XLNetModel`].
+ """
+)
+class XLNetModelOutput(ModelOutput):
+ r"""
+ last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_predict, hidden_size)`):
+ Sequence of hidden-states at the last layer of the model.
+
+ `num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict`
+ corresponds to `sequence_length`.
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ """
+
+ last_hidden_state: torch.FloatTensor
+ mems: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`XLNetLMHeadModel`].
+ """
+)
+class XLNetLMHeadModelOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape *(1,)*, *optional*, returned when `labels` is provided):
+ Language modeling loss (for next-token prediction).
+ logits (`torch.FloatTensor` of shape `(batch_size, num_predict, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+
+ `num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict`
+ corresponds to `sequence_length`.
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ mems: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`XLNetForSequenceClassification`].
+ """
+)
+class XLNetForSequenceClassificationOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `label` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, config.num_labels)`):
+ Classification (or regression if config.num_labels==1) scores (before SoftMax).
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ mems: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`XLNetForTokenClassificationOutput`].
+ """
+)
+class XLNetForTokenClassificationOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Classification loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`):
+ Classification scores (before SoftMax).
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ mems: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`XLNetForMultipleChoice`].
+ """
+)
+class XLNetForMultipleChoiceOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape *(1,)*, *optional*, returned when `labels` is provided):
+ Classification loss.
+ logits (`torch.FloatTensor` of shape `(batch_size, num_choices)`):
+ *num_choices* is the second dimension of the input tensors. (see *input_ids* above).
+
+ Classification scores (before SoftMax).
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ mems: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`XLNetForQuestionAnsweringSimple`].
+ """
+)
+class XLNetForQuestionAnsweringSimpleOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Total span extraction loss is the sum of a Cross-Entropy for the start and end positions.
+ start_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length,)`):
+ Span-start scores (before SoftMax).
+ end_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length,)`):
+ Span-end scores (before SoftMax).
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ start_logits: Optional[torch.FloatTensor] = None
+ end_logits: Optional[torch.FloatTensor] = None
+ mems: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`XLNetForQuestionAnswering`].
+ """
+)
+class XLNetForQuestionAnsweringOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned if both `start_positions` and `end_positions` are provided):
+ Classification loss as the sum of start token, end token (and is_impossible if provided) classification
+ losses.
+ start_top_log_probs (`torch.FloatTensor` of shape `(batch_size, config.start_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the top config.start_n_top start token possibilities (beam-search).
+ start_top_index (`torch.LongTensor` of shape `(batch_size, config.start_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Indices for the top config.start_n_top start token possibilities (beam-search).
+ end_top_log_probs (`torch.FloatTensor` of shape `(batch_size, config.start_n_top * config.end_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the top `config.start_n_top * config.end_n_top` end token possibilities
+ (beam-search).
+ end_top_index (`torch.LongTensor` of shape `(batch_size, config.start_n_top * config.end_n_top)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Indices for the top `config.start_n_top * config.end_n_top` end token possibilities (beam-search).
+ cls_logits (`torch.FloatTensor` of shape `(batch_size,)`, *optional*, returned if `start_positions` or `end_positions` is not provided):
+ Log probabilities for the `is_impossible` label of the answers.
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states. Can be used (see `mems` input) to speed up sequential decoding. The
+ token ids which have their past given to this model should not be passed as `input_ids` as they have
+ already been computed.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ start_top_log_probs: Optional[torch.FloatTensor] = None
+ start_top_index: Optional[torch.LongTensor] = None
+ end_top_log_probs: Optional[torch.FloatTensor] = None
+ end_top_index: Optional[torch.LongTensor] = None
+ cls_logits: Optional[torch.FloatTensor] = None
+ mems: Optional[list[torch.FloatTensor]] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+@auto_docstring
+class XLNetModel(XLNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.mem_len = config.mem_len
+ self.reuse_len = config.reuse_len
+ self.d_model = config.d_model
+ self.same_length = config.same_length
+ self.attn_type = config.attn_type
+ self.bi_data = config.bi_data
+ self.clamp_len = config.clamp_len
+ self.n_layer = config.n_layer
+
+ self.word_embedding = nn.Embedding(config.vocab_size, config.d_model)
+ self.mask_emb = nn.Parameter(torch.FloatTensor(1, 1, config.d_model))
+ self.layer = nn.ModuleList([XLNetLayer(config) for _ in range(config.n_layer)])
+ self.dropout = nn.Dropout(config.dropout)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.word_embedding
+
+ def set_input_embeddings(self, new_embeddings):
+ self.word_embedding = new_embeddings
+
+ def _prune_heads(self, heads_to_prune):
+ raise NotImplementedError
+
+ def create_mask(self, qlen, mlen):
+ """
+ Creates causal attention mask. Float mask where 1.0 indicates masked, 0.0 indicates not-masked.
+
+ Args:
+ qlen: Sequence length
+ mlen: Mask length
+
+ ::
+
+ same_length=False: same_length=True: < qlen > < qlen >
+ ^ [0 0 0 0 0 1 1 1 1] [0 0 0 0 0 1 1 1 1]
+ [0 0 0 0 0 0 1 1 1] [1 0 0 0 0 0 1 1 1]
+ qlen [0 0 0 0 0 0 0 1 1] [1 1 0 0 0 0 0 1 1]
+ [0 0 0 0 0 0 0 0 1] [1 1 1 0 0 0 0 0 1]
+ v [0 0 0 0 0 0 0 0 0] [1 1 1 1 0 0 0 0 0]
+
+ """
+ mask = torch.ones((qlen, qlen + mlen), device=self.device)
+ if self.same_length:
+ mask_lo = mask[:, :qlen].tril(-1)
+ mask.triu_(mlen + 1)
+ mask[:, :qlen] += mask_lo
+ else:
+ mask.triu_(mlen + 1)
+
+ return mask
+
+ def cache_mem(self, curr_out, prev_mem):
+ # cache hidden states into memory.
+ if self.reuse_len is not None and self.reuse_len > 0:
+ curr_out = curr_out[: self.reuse_len]
+
+ if self.mem_len is None or self.mem_len == 0:
+ # If `use_mems` is active but no `mem_len` is defined, the model behaves like GPT-2 at inference time
+ # and returns all of the past and current hidden states.
+ cutoff = 0
+ else:
+ # If `use_mems` is active and `mem_len` is defined, the model returns the last `mem_len` hidden
+ # states. This is the preferred setting for training and long-form generation.
+ cutoff = -self.mem_len
+ if prev_mem is None:
+ # if `use_mems` is active and `mem_len` is defined, the model
+ new_mem = curr_out[cutoff:]
+ else:
+ new_mem = torch.cat([prev_mem, curr_out], dim=0)[cutoff:]
+
+ return new_mem.detach()
+
+ @staticmethod
+ def positional_embedding(pos_seq, inv_freq, bsz=None):
+ sinusoid_inp = torch.einsum("i,d->id", pos_seq, inv_freq)
+ pos_emb = torch.cat([torch.sin(sinusoid_inp), torch.cos(sinusoid_inp)], dim=-1)
+ pos_emb = pos_emb[:, None, :]
+
+ if bsz is not None:
+ pos_emb = pos_emb.expand(-1, bsz, -1)
+
+ return pos_emb
+
+ def relative_positional_encoding(self, qlen, klen, bsz=None):
+ # create relative positional encoding.
+ freq_seq = torch.arange(0, self.d_model, 2.0, dtype=torch.int64).float()
+ inv_freq = 1 / torch.pow(10000, (freq_seq / self.d_model))
+
+ if self.attn_type == "bi":
+ # beg, end = klen - 1, -qlen
+ beg, end = klen, -qlen
+ elif self.attn_type == "uni":
+ # beg, end = klen - 1, -1
+ beg, end = klen, -1
+ else:
+ raise ValueError(f"Unknown `attn_type` {self.attn_type}.")
+
+ if self.bi_data:
+ fwd_pos_seq = torch.arange(beg, end, -1.0, dtype=torch.int64).float()
+ bwd_pos_seq = torch.arange(-beg, -end, 1.0, dtype=torch.int64).float()
+
+ if self.clamp_len > 0:
+ fwd_pos_seq = fwd_pos_seq.clamp(-self.clamp_len, self.clamp_len)
+ bwd_pos_seq = bwd_pos_seq.clamp(-self.clamp_len, self.clamp_len)
+
+ if bsz is not None:
+ fwd_pos_emb = self.positional_embedding(fwd_pos_seq, inv_freq, bsz // 2)
+ bwd_pos_emb = self.positional_embedding(bwd_pos_seq, inv_freq, bsz // 2)
+ else:
+ fwd_pos_emb = self.positional_embedding(fwd_pos_seq, inv_freq)
+ bwd_pos_emb = self.positional_embedding(bwd_pos_seq, inv_freq)
+
+ pos_emb = torch.cat([fwd_pos_emb, bwd_pos_emb], dim=1)
+ else:
+ fwd_pos_seq = torch.arange(beg, end, -1.0, dtype=torch.int64).float()
+ if self.clamp_len > 0:
+ fwd_pos_seq = fwd_pos_seq.clamp(-self.clamp_len, self.clamp_len)
+ pos_emb = self.positional_embedding(fwd_pos_seq, inv_freq, bsz)
+
+ return pos_emb
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ mems: Optional[torch.Tensor] = None,
+ perm_mask: Optional[torch.Tensor] = None,
+ target_mapping: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ input_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ use_mems: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs, # delete after depreciation warning is removed
+ ) -> Union[tuple, XLNetModelOutput]:
+ r"""
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ input_mask (`torch.FloatTensor` of shape `batch_size, sequence_length`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ use_mems (`bool`, *optional*):
+ Whether to use memory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if "use_cache" in kwargs:
+ warnings.warn(
+ "The `use_cache` argument is deprecated and will be removed in a future version, use `use_mems`"
+ " instead.",
+ FutureWarning,
+ )
+ use_mems = kwargs["use_cache"]
+
+ if self.training:
+ use_mems = use_mems if use_mems is not None else self.config.use_mems_train
+ else:
+ use_mems = use_mems if use_mems is not None else self.config.use_mems_eval
+
+ # the original code for XLNet uses shapes [len, bsz] with the batch dimension at the end
+ # but we want a unified interface in the library with the batch size on the first dimension
+ # so we move here the first dimension (batch) to the end
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ input_ids = input_ids.transpose(0, 1).contiguous()
+ qlen, bsz = input_ids.shape[0], input_ids.shape[1]
+ elif inputs_embeds is not None:
+ inputs_embeds = inputs_embeds.transpose(0, 1).contiguous()
+ qlen, bsz = inputs_embeds.shape[0], inputs_embeds.shape[1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ token_type_ids = token_type_ids.transpose(0, 1).contiguous() if token_type_ids is not None else None
+ input_mask = input_mask.transpose(0, 1).contiguous() if input_mask is not None else None
+ attention_mask = attention_mask.transpose(0, 1).contiguous() if attention_mask is not None else None
+ perm_mask = perm_mask.permute(1, 2, 0).contiguous() if perm_mask is not None else None
+ target_mapping = target_mapping.permute(1, 2, 0).contiguous() if target_mapping is not None else None
+
+ mlen = mems[0].shape[0] if mems is not None and mems[0] is not None else 0
+ klen = mlen + qlen
+
+ dtype_float = self.dtype
+ device = self.device
+
+ # Attention mask
+ # causal attention mask
+ if self.attn_type == "uni":
+ attn_mask = self.create_mask(qlen, mlen)
+ attn_mask = attn_mask[:, :, None, None]
+ elif self.attn_type == "bi":
+ attn_mask = None
+ else:
+ raise ValueError(f"Unsupported attention type: {self.attn_type}")
+
+ # data mask: input mask & perm mask
+ assert input_mask is None or attention_mask is None, "You can only use one of input_mask (uses 1 for padding) "
+ "or attention_mask (uses 0 for padding, added for compatibility with BERT). Please choose one."
+ if input_mask is None and attention_mask is not None:
+ input_mask = 1.0 - attention_mask
+ if input_mask is not None and perm_mask is not None:
+ data_mask = input_mask[None] + perm_mask
+ elif input_mask is not None and perm_mask is None:
+ data_mask = input_mask[None]
+ elif input_mask is None and perm_mask is not None:
+ data_mask = perm_mask
+ else:
+ data_mask = None
+
+ if data_mask is not None:
+ # all mems can be attended to
+ if mlen > 0:
+ mems_mask = torch.zeros([data_mask.shape[0], mlen, bsz]).to(data_mask)
+ data_mask = torch.cat([mems_mask, data_mask], dim=1)
+ if attn_mask is None:
+ attn_mask = data_mask[:, :, :, None]
+ else:
+ attn_mask += data_mask[:, :, :, None]
+
+ if attn_mask is not None:
+ attn_mask = (attn_mask > 0).to(dtype_float)
+
+ if attn_mask is not None:
+ non_tgt_mask = -torch.eye(qlen).to(attn_mask)
+ if mlen > 0:
+ non_tgt_mask = torch.cat([torch.zeros([qlen, mlen]).to(attn_mask), non_tgt_mask], dim=-1)
+ non_tgt_mask = ((attn_mask + non_tgt_mask[:, :, None, None]) > 0).to(attn_mask)
+ else:
+ non_tgt_mask = None
+
+ # Word embeddings and prepare h & g hidden states
+ if inputs_embeds is not None:
+ word_emb_k = inputs_embeds
+ else:
+ word_emb_k = self.word_embedding(input_ids)
+ output_h = self.dropout(word_emb_k)
+ if target_mapping is not None:
+ word_emb_q = self.mask_emb.expand(target_mapping.shape[0], bsz, -1)
+ # else: # We removed the inp_q input which was same as target mapping
+ # inp_q_ext = inp_q[:, :, None]
+ # word_emb_q = inp_q_ext * self.mask_emb + (1 - inp_q_ext) * word_emb_k
+ output_g = self.dropout(word_emb_q)
+ else:
+ output_g = None
+
+ # Segment embedding
+ if token_type_ids is not None:
+ # Convert `token_type_ids` to one-hot `seg_mat`
+ if mlen > 0:
+ mem_pad = torch.zeros([mlen, bsz], dtype=torch.long, device=device)
+ cat_ids = torch.cat([mem_pad, token_type_ids], dim=0)
+ else:
+ cat_ids = token_type_ids
+
+ # `1` indicates not in the same segment [qlen x klen x bsz]
+ seg_mat = (token_type_ids[:, None] != cat_ids[None, :]).long()
+ seg_mat = nn.functional.one_hot(seg_mat, num_classes=2).to(dtype_float)
+ else:
+ seg_mat = None
+
+ # Positional encoding
+ pos_emb = self.relative_positional_encoding(qlen, klen, bsz=bsz)
+ pos_emb = pos_emb.to(output_h.device)
+ pos_emb = self.dropout(pos_emb)
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads] (a head_mask for each layer)
+ # and head_mask is converted to shape [num_hidden_layers x qlen x klen x bsz x n_head]
+ if head_mask is not None:
+ if head_mask.dim() == 1:
+ head_mask = head_mask.unsqueeze(0).unsqueeze(0).unsqueeze(0).unsqueeze(0)
+ head_mask = head_mask.expand(self.n_layer, -1, -1, -1, -1)
+ elif head_mask.dim() == 2:
+ head_mask = head_mask.unsqueeze(1).unsqueeze(1).unsqueeze(1)
+ head_mask = head_mask.to(
+ dtype=next(self.parameters()).dtype
+ ) # switch to float if need + fp16 compatibility
+ else:
+ head_mask = [None] * self.n_layer
+
+ new_mems = ()
+ if mems is None:
+ mems = [None] * len(self.layer)
+
+ attentions = [] if output_attentions else None
+ hidden_states = [] if output_hidden_states else None
+ for i, layer_module in enumerate(self.layer):
+ if use_mems:
+ # cache new mems
+ new_mems = new_mems + (self.cache_mem(output_h, mems[i]),)
+ if output_hidden_states:
+ hidden_states.append((output_h, output_g) if output_g is not None else output_h)
+
+ outputs = layer_module(
+ output_h,
+ output_g,
+ attn_mask_h=non_tgt_mask,
+ attn_mask_g=attn_mask,
+ r=pos_emb,
+ seg_mat=seg_mat,
+ mems=mems[i],
+ target_mapping=target_mapping,
+ head_mask=head_mask[i],
+ output_attentions=output_attentions,
+ )
+ output_h, output_g = outputs[:2]
+ if output_attentions:
+ attentions.append(outputs[2])
+
+ # Add last hidden state
+ if output_hidden_states:
+ hidden_states.append((output_h, output_g) if output_g is not None else output_h)
+
+ output = self.dropout(output_g if output_g is not None else output_h)
+
+ # Prepare outputs, we transpose back here to shape [bsz, len, hidden_dim] (cf. beginning of forward() method)
+ output = output.permute(1, 0, 2).contiguous()
+
+ if not use_mems:
+ new_mems = None
+
+ if output_hidden_states:
+ if output_g is not None:
+ hidden_states = tuple(h.permute(1, 0, 2).contiguous() for hs in hidden_states for h in hs)
+ else:
+ hidden_states = tuple(hs.permute(1, 0, 2).contiguous() for hs in hidden_states)
+
+ if output_attentions:
+ if target_mapping is not None:
+ # when target_mapping is provided, there are 2-tuple of attentions
+ attentions = tuple(
+ tuple(att_stream.permute(2, 3, 0, 1).contiguous() for att_stream in t) for t in attentions
+ )
+ else:
+ attentions = tuple(t.permute(2, 3, 0, 1).contiguous() for t in attentions)
+
+ if not return_dict:
+ return tuple(v for v in [output, new_mems, hidden_states, attentions] if v is not None)
+
+ return XLNetModelOutput(
+ last_hidden_state=output, mems=new_mems, hidden_states=hidden_states, attentions=attentions
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ XLNet Model with a language modeling head on top (linear layer with weights tied to the input embeddings).
+ """
+)
+class XLNetLMHeadModel(XLNetPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_loss.weight"]
+
+ def __init__(self, config):
+ super().__init__(config)
+ self.attn_type = config.attn_type
+ self.same_length = config.same_length
+
+ self.transformer = XLNetModel(config)
+ self.lm_loss = nn.Linear(config.d_model, config.vocab_size, bias=True)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.lm_loss
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_loss = new_embeddings
+
+ def prepare_inputs_for_generation(self, input_ids, past_key_values=None, use_mems=None, **kwargs):
+ # Overwritten -- this model has unique input preparation
+
+ # Add dummy token at the end (no attention on this one)
+
+ effective_batch_size = input_ids.shape[0]
+ dummy_token = torch.zeros((effective_batch_size, 1), dtype=torch.long, device=input_ids.device)
+
+ # At every pass, the attention values for the new token and the two last generated tokens
+ # are computed, the rest is reloaded from the `past` cache. A purely auto-regressive model would have
+ # offset = 1; offset = 2 seems to have slightly better computation.
+ offset = 2
+
+ if past_key_values:
+ input_ids = torch.cat([input_ids[:, -offset:], dummy_token], dim=1)
+ else:
+ input_ids = torch.cat([input_ids, dummy_token], dim=1)
+
+ # Build permutation mask so that previous tokens don't see last token
+ sequence_length = input_ids.shape[1]
+ perm_mask = torch.zeros(
+ (effective_batch_size, sequence_length, sequence_length), dtype=torch.float, device=input_ids.device
+ )
+ perm_mask[:, :, -1] = 1.0
+
+ # We'll only predict the last token
+ target_mapping = torch.zeros(
+ (effective_batch_size, 1, sequence_length), dtype=torch.float, device=input_ids.device
+ )
+ target_mapping[:, 0, -1] = 1.0
+
+ inputs = {
+ "input_ids": input_ids,
+ "perm_mask": perm_mask,
+ "target_mapping": target_mapping,
+ "use_mems": use_mems,
+ }
+
+ # if past is defined in model kwargs then use it for faster decoding
+ if past_key_values:
+ inputs["mems"] = tuple(layer_past[:-offset, :, :] for layer_past in past_key_values)
+
+ return inputs
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ mems: Optional[torch.Tensor] = None,
+ perm_mask: Optional[torch.Tensor] = None,
+ target_mapping: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ input_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ use_mems: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs, # delete when `use_cache` is removed in XLNetModel
+ ) -> Union[tuple, XLNetLMHeadModelOutput]:
+ r"""
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ input_mask (`torch.FloatTensor` of shape `batch_size, sequence_length`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ labels (`torch.LongTensor` of shape `(batch_size, num_predict)`, *optional*):
+ Labels for masked language modeling. `num_predict` corresponds to `target_mapping.shape[1]`. If
+ `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
+
+ The labels should correspond to the masked input words that should be predicted and depends on
+ `target_mapping`. Note in order to perform standard auto-regressive language modeling a ** token has
+ to be added to the `input_ids` (see the `prepare_inputs_for_generation` function and examples below)
+
+ Indices are selected in `[-100, 0, ..., config.vocab_size]` All labels set to `-100` are ignored, the loss
+ is only computed for labels in `[0, ..., config.vocab_size]`
+ use_mems (`bool`, *optional*):
+ Whether to use memory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoTokenizer, XLNetLMHeadModel
+ >>> import torch
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("xlnet/xlnet-large-cased")
+ >>> model = XLNetLMHeadModel.from_pretrained("xlnet/xlnet-large-cased")
+
+ >>> # We show how to setup inputs to predict a next token using a bi-directional context.
+ >>> input_ids = torch.tensor(
+ ... tokenizer.encode("Hello, my dog is very ", add_special_tokens=False)
+ ... ).unsqueeze(
+ ... 0
+ ... ) # We will predict the masked token
+ >>> perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
+ >>> perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token
+ >>> target_mapping = torch.zeros(
+ ... (1, 1, input_ids.shape[1]), dtype=torch.float
+ ... ) # Shape [1, 1, seq_length] => let's predict one token
+ >>> target_mapping[
+ ... 0, 0, -1
+ ... ] = 1.0 # Our first (and only) prediction will be the last token of the sequence (the masked token)
+
+ >>> outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping)
+ >>> next_token_logits = outputs[
+ ... 0
+ ... ] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
+
+ >>> # The same way can the XLNetLMHeadModel be used to be trained by standard auto-regressive language modeling.
+ >>> input_ids = torch.tensor(
+ ... tokenizer.encode("Hello, my dog is very ", add_special_tokens=False)
+ ... ).unsqueeze(
+ ... 0
+ ... ) # We will predict the masked token
+ >>> labels = torch.tensor(tokenizer.encode("cute", add_special_tokens=False)).unsqueeze(0)
+ >>> assert labels.shape[0] == 1, "only one word will be predicted"
+ >>> perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
+ >>> perm_mask[
+ ... :, :, -1
+ ... ] = 1.0 # Previous tokens don't see last token as is done in standard auto-regressive lm training
+ >>> target_mapping = torch.zeros(
+ ... (1, 1, input_ids.shape[1]), dtype=torch.float
+ ... ) # Shape [1, 1, seq_length] => let's predict one token
+ >>> target_mapping[
+ ... 0, 0, -1
+ ... ] = 1.0 # Our first (and only) prediction will be the last token of the sequence (the masked token)
+
+ >>> outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping, labels=labels)
+ >>> loss = outputs.loss
+ >>> next_token_logits = (
+ ... outputs.logits
+ ... ) # Logits have shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ **kwargs,
+ )
+
+ logits = self.lm_loss(transformer_outputs[0])
+
+ loss = None
+ if labels is not None:
+ # Flatten the tokens
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, logits.size(-1)), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XLNetLMHeadModelOutput(
+ loss=loss,
+ logits=logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ @staticmethod
+ def _reorder_cache(mems: list[torch.Tensor], beam_idx: torch.Tensor) -> list[torch.Tensor]:
+ """
+ This function is used to re-order the `mems` cache if [`~PreTrainedModel.beam_search`] or
+ [`~PreTrainedModel.beam_sample`] is called. This is required to match `mems` with the correct beam_idx at every
+ generation step.
+ """
+ return [layer_past.index_select(1, beam_idx.to(layer_past.device)) for layer_past in mems]
+
+
+@auto_docstring(
+ custom_intro="""
+ XLNet Model with a sequence classification/regression head on top (a linear layer on top of the pooled output) e.g.
+ for GLUE tasks.
+ """
+)
+class XLNetForSequenceClassification(XLNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.config = config
+
+ self.transformer = XLNetModel(config)
+ self.sequence_summary = XLNetSequenceSummary(config)
+ self.logits_proj = nn.Linear(config.d_model, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ mems: Optional[torch.Tensor] = None,
+ perm_mask: Optional[torch.Tensor] = None,
+ target_mapping: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ input_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ use_mems: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs, # delete when `use_cache` is removed in XLNetModel
+ ) -> Union[tuple, XLNetForSequenceClassificationOutput]:
+ r"""
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ input_mask (`torch.FloatTensor` of shape `batch_size, sequence_length`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ use_mems (`bool`, *optional*):
+ Whether to use memory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ **kwargs,
+ )
+ output = transformer_outputs[0]
+
+ output = self.sequence_summary(output)
+ logits = self.logits_proj(output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XLNetForSequenceClassificationOutput(
+ loss=loss,
+ logits=logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLNetForTokenClassification(XLNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.transformer = XLNetModel(config)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ mems: Optional[torch.Tensor] = None,
+ perm_mask: Optional[torch.Tensor] = None,
+ target_mapping: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ input_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ use_mems: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs, # delete when `use_cache` is removed in XLNetModel
+ ) -> Union[tuple, XLNetForTokenClassificationOutput]:
+ r"""
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ input_mask (`torch.FloatTensor` of shape `batch_size, sequence_length`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., num_choices]`
+ where *num_choices* is the size of the second dimension of the input tensors. (see *input_ids* above)
+ use_mems (`bool`, *optional*):
+ Whether to use memory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.emory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XLNetForTokenClassificationOutput(
+ loss=loss,
+ logits=logits,
+ mems=outputs.mems,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLNetForMultipleChoice(XLNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.transformer = XLNetModel(config)
+ self.sequence_summary = XLNetSequenceSummary(config)
+ self.logits_proj = nn.Linear(config.d_model, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ input_mask: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ mems: Optional[torch.Tensor] = None,
+ perm_mask: Optional[torch.Tensor] = None,
+ target_mapping: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ use_mems: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs, # delete when `use_cache` is removed in XLNetModel
+ ) -> Union[tuple, XLNetForMultipleChoiceOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ input_mask (`torch.FloatTensor` of shape `batch_size, num_choices, sequence_length`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ use_mems (`bool`, *optional*):
+ Whether to use memory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ flat_input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ flat_token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ flat_attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ flat_input_mask = input_mask.view(-1, input_mask.size(-1)) if input_mask is not None else None
+ flat_inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ transformer_outputs = self.transformer(
+ flat_input_ids,
+ token_type_ids=flat_token_type_ids,
+ input_mask=flat_input_mask,
+ attention_mask=flat_attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ head_mask=head_mask,
+ inputs_embeds=flat_inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ **kwargs,
+ )
+
+ output = transformer_outputs[0]
+
+ output = self.sequence_summary(output)
+ logits = self.logits_proj(output)
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels.view(-1))
+
+ if not return_dict:
+ output = (reshaped_logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return XLNetForMultipleChoiceOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ XLNet Model with a span classification head on top for extractive question-answering tasks like SQuAD (a linear
+ layers on top of the hidden-states output to compute `span start logits` and `span end logits`).
+ """
+)
+class XLNetForQuestionAnsweringSimple(XLNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.transformer = XLNetModel(config)
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ mems: Optional[torch.Tensor] = None,
+ perm_mask: Optional[torch.Tensor] = None,
+ target_mapping: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ input_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.Tensor] = None,
+ end_positions: Optional[torch.Tensor] = None,
+ use_mems: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs, # delete when `use_cache` is removed in XLNetModel
+ ) -> Union[tuple, XLNetForQuestionAnsweringSimpleOutput]:
+ r"""
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ input_mask (`torch.FloatTensor` of shape `batch_size, sequence_length`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ use_mems (`bool`, *optional*):
+ Whether to use memory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ **kwargs,
+ )
+
+ sequence_output = outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[1:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return XLNetForQuestionAnsweringSimpleOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ mems=outputs.mems,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class XLNetForQuestionAnswering(XLNetPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.start_n_top = config.start_n_top
+ self.end_n_top = config.end_n_top
+
+ self.transformer = XLNetModel(config)
+ self.start_logits = XLNetPoolerStartLogits(config)
+ self.end_logits = XLNetPoolerEndLogits(config)
+ self.answer_class = XLNetPoolerAnswerClass(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ mems: Optional[torch.Tensor] = None,
+ perm_mask: Optional[torch.Tensor] = None,
+ target_mapping: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ input_mask: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.Tensor] = None,
+ end_positions: Optional[torch.Tensor] = None,
+ is_impossible: Optional[torch.Tensor] = None,
+ cls_index: Optional[torch.Tensor] = None,
+ p_mask: Optional[torch.Tensor] = None,
+ use_mems: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ **kwargs, # delete when `use_cache` is removed in XLNetModel
+ ) -> Union[tuple, XLNetForQuestionAnsweringOutput]:
+ r"""
+ mems (`list[torch.FloatTensor]` of length `config.n_layers`):
+ Contains pre-computed hidden-states (see `mems` output below) . Can be used to speed up sequential
+ decoding. The token ids which have their past given to this model should not be passed as `input_ids` as
+ they have already been computed.
+
+ `use_mems` has to be set to `True` to make use of `mems`.
+ perm_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, sequence_length)`, *optional*):
+ Mask to indicate the attention pattern for each input token with values selected in `[0, 1]`:
+
+ - if `perm_mask[k, i, j] = 0`, i attend to j in batch k;
+ - if `perm_mask[k, i, j] = 1`, i does not attend to j in batch k.
+
+ If not set, each token attends to all the others (full bidirectional attention). Only used during
+ pretraining (to define factorization order) or for sequential decoding (generation).
+ target_mapping (`torch.FloatTensor` of shape `(batch_size, num_predict, sequence_length)`, *optional*):
+ Mask to indicate the output tokens to use. If `target_mapping[k, i, j] = 1`, the i-th predict in batch k is
+ on the j-th token. Only used during pretraining for partial prediction or for sequential decoding
+ (generation).
+ input_mask (`torch.FloatTensor` of shape `batch_size, sequence_length`, *optional*):
+ Mask to avoid performing attention on padding token indices. Negative of `attention_mask`, i.e. with 0 for
+ real tokens and 1 for padding which is kept for compatibility with the original code base.
+
+ Mask values selected in `[0, 1]`:
+
+ - 1 for tokens that are **masked**,
+ - 0 for tokens that are **not masked**.
+
+ You can only uses one of `input_mask` and `attention_mask`.
+ is_impossible (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels whether a question has an answer or no answer (SQuAD 2.0)
+ cls_index (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for position (index) of the classification token to use as input for computing plausibility of the
+ answer.
+ p_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Optional mask of tokens which can't be in answers (e.g. [CLS], [PAD], ...). 1.0 means token should be
+ masked. 0.0 mean token is not masked.
+ use_mems (`bool`, *optional*):
+ Whether to use memory states to speed up sequential decoding. If set to `True`, the model will use the hidden
+ states from previous forward passes to compute attention, which can significantly improve performance for
+ sequential decoding tasks.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, XLNetForQuestionAnswering
+ >>> import torch
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("xlnet/xlnet-base-cased")
+ >>> model = XLNetForQuestionAnswering.from_pretrained("xlnet/xlnet-base-cased")
+
+ >>> input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(
+ ... 0
+ ... ) # Batch size 1
+ >>> start_positions = torch.tensor([1])
+ >>> end_positions = torch.tensor([3])
+ >>> outputs = model(input_ids, start_positions=start_positions, end_positions=end_positions)
+
+ >>> loss = outputs.loss
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.transformer(
+ input_ids,
+ attention_mask=attention_mask,
+ mems=mems,
+ perm_mask=perm_mask,
+ target_mapping=target_mapping,
+ token_type_ids=token_type_ids,
+ input_mask=input_mask,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ use_mems=use_mems,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ **kwargs,
+ )
+ hidden_states = transformer_outputs[0]
+ start_logits = self.start_logits(hidden_states, p_mask=p_mask)
+
+ outputs = transformer_outputs[1:] # Keep mems, hidden states, attentions if there are in it
+
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, let's remove the dimension added by batch splitting
+ for x in (start_positions, end_positions, cls_index, is_impossible):
+ if x is not None and x.dim() > 1:
+ x.squeeze_(-1)
+
+ # during training, compute the end logits based on the ground truth of the start position
+ end_logits = self.end_logits(hidden_states, start_positions=start_positions, p_mask=p_mask)
+
+ loss_fct = CrossEntropyLoss()
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if cls_index is not None and is_impossible is not None:
+ # Predict answerability from the representation of CLS and START
+ cls_logits = self.answer_class(hidden_states, start_positions=start_positions, cls_index=cls_index)
+ loss_fct_cls = nn.BCEWithLogitsLoss()
+ cls_loss = loss_fct_cls(cls_logits, is_impossible)
+
+ # note(zhiliny): by default multiply the loss by 0.5 so that the scale is comparable to start_loss and end_loss
+ total_loss += cls_loss * 0.5
+
+ if not return_dict:
+ return (total_loss,) + transformer_outputs[1:]
+ else:
+ return XLNetForQuestionAnsweringOutput(
+ loss=total_loss,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+ else:
+ # during inference, compute the end logits based on beam search
+ bsz, slen, hsz = hidden_states.size()
+ start_log_probs = nn.functional.softmax(start_logits, dim=-1) # shape (bsz, slen)
+
+ start_top_log_probs, start_top_index = torch.topk(
+ start_log_probs, self.start_n_top, dim=-1
+ ) # shape (bsz, start_n_top)
+ start_top_index_exp = start_top_index.unsqueeze(-1).expand(-1, -1, hsz) # shape (bsz, start_n_top, hsz)
+ start_states = torch.gather(hidden_states, -2, start_top_index_exp) # shape (bsz, start_n_top, hsz)
+ start_states = start_states.unsqueeze(1).expand(-1, slen, -1, -1) # shape (bsz, slen, start_n_top, hsz)
+
+ hidden_states_expanded = hidden_states.unsqueeze(2).expand_as(
+ start_states
+ ) # shape (bsz, slen, start_n_top, hsz)
+ p_mask = p_mask.unsqueeze(-1) if p_mask is not None else None
+ end_logits = self.end_logits(hidden_states_expanded, start_states=start_states, p_mask=p_mask)
+ end_log_probs = nn.functional.softmax(end_logits, dim=1) # shape (bsz, slen, start_n_top)
+
+ end_top_log_probs, end_top_index = torch.topk(
+ end_log_probs, self.end_n_top, dim=1
+ ) # shape (bsz, end_n_top, start_n_top)
+ end_top_log_probs = end_top_log_probs.view(-1, self.start_n_top * self.end_n_top)
+ end_top_index = end_top_index.view(-1, self.start_n_top * self.end_n_top)
+
+ start_states = torch.einsum(
+ "blh,bl->bh", hidden_states, start_log_probs
+ ) # get the representation of START as weighted sum of hidden states
+ cls_logits = self.answer_class(
+ hidden_states, start_states=start_states, cls_index=cls_index
+ ) # Shape (batch size,): one single `cls_logits` for each sample
+
+ if not return_dict:
+ outputs = (start_top_log_probs, start_top_index, end_top_log_probs, end_top_index, cls_logits)
+ return outputs + transformer_outputs[1:]
+ else:
+ return XLNetForQuestionAnsweringOutput(
+ start_top_log_probs=start_top_log_probs,
+ start_top_index=start_top_index,
+ end_top_log_probs=end_top_log_probs,
+ end_top_index=end_top_index,
+ cls_logits=cls_logits,
+ mems=transformer_outputs.mems,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+__all__ = [
+ "XLNetForMultipleChoice",
+ "XLNetForQuestionAnswering",
+ "XLNetForQuestionAnsweringSimple",
+ "XLNetForSequenceClassification",
+ "XLNetForTokenClassification",
+ "XLNetLMHeadModel",
+ "XLNetModel",
+ "XLNetPreTrainedModel",
+ "load_tf_weights_in_xlnet",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/tokenization_xlnet.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/tokenization_xlnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..9186db33d788e2766755c0d1ec51614e95173a0f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/tokenization_xlnet.py
@@ -0,0 +1,387 @@
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for XLNet model."""
+
+import os
+import unicodedata
+from shutil import copyfile
+from typing import Any, Optional
+
+import sentencepiece as spm
+
+from ...tokenization_utils import AddedToken, PreTrainedTokenizer
+from ...utils import SPIECE_UNDERLINE, logging
+from ...utils.import_utils import requires
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "spiece.model"}
+
+
+# Segments (not really needed)
+SEG_ID_A = 0
+SEG_ID_B = 1
+SEG_ID_CLS = 2
+SEG_ID_SEP = 3
+SEG_ID_PAD = 4
+
+
+@requires(backends=("sentencepiece",))
+class XLNetTokenizer(PreTrainedTokenizer):
+ """
+ Construct an XLNet tokenizer. Based on [SentencePiece](https://github.com/google/sentencepiece).
+
+ This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to
+ this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ [SentencePiece](https://github.com/google/sentencepiece) file (generally has a .spm extension) that
+ contains the vocabulary necessary to instantiate a tokenizer.
+ do_lower_case (`bool`, *optional*, defaults to `False`):
+ Whether to lowercase the input when tokenizing.
+ remove_space (`bool`, *optional*, defaults to `True`):
+ Whether to strip the text when tokenizing (removing excess spaces before and after the string).
+ keep_accents (`bool`, *optional*, defaults to `False`):
+ Whether to keep accents when tokenizing.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the beginning of
+ sequence. The token used is the `cls_token`.
+
+
+
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ sep_token (`str`, *optional*, defaults to `""`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `""`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `""`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ additional_special_tokens (`list[str]`, *optional*, defaults to `['', '']`):
+ Additional special tokens used by the tokenizer.
+ sp_model_kwargs (`dict`, *optional*):
+ Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for
+ SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things,
+ to set:
+
+ - `enable_sampling`: Enable subword regularization.
+ - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout.
+
+ - `nbest_size = {0,1}`: No sampling is performed.
+ - `nbest_size > 1`: samples from the nbest_size results.
+ - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice)
+ using forward-filtering-and-backward-sampling algorithm.
+
+ - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for
+ BPE-dropout.
+
+ Attributes:
+ sp_model (`SentencePieceProcessor`):
+ The *SentencePiece* processor that is used for every conversion (string, tokens and IDs).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ padding_side = "left"
+
+ def __init__(
+ self,
+ vocab_file,
+ do_lower_case=False,
+ remove_space=True,
+ keep_accents=False,
+ bos_token="",
+ eos_token=" ",
+ unk_token="",
+ sep_token="",
+ pad_token="",
+ cls_token="",
+ mask_token="",
+ additional_special_tokens=["", ""],
+ sp_model_kwargs: Optional[dict[str, Any]] = None,
+ **kwargs,
+ ) -> None:
+ # Mask token behave like a normal word, i.e. include the space before it
+ mask_token = AddedToken(mask_token, lstrip=True, special=True) if isinstance(mask_token, str) else mask_token
+
+ self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
+
+ self.do_lower_case = do_lower_case
+ self.remove_space = remove_space
+ self.keep_accents = keep_accents
+ self.vocab_file = vocab_file
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(vocab_file)
+
+ super().__init__(
+ do_lower_case=do_lower_case,
+ remove_space=remove_space,
+ keep_accents=keep_accents,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ additional_special_tokens=additional_special_tokens,
+ sp_model_kwargs=self.sp_model_kwargs,
+ **kwargs,
+ )
+
+ self._pad_token_type_id = 3
+
+ @property
+ def vocab_size(self):
+ return len(self.sp_model)
+
+ def get_vocab(self):
+ vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
+ vocab.update(self.added_tokens_encoder)
+ return vocab
+
+ def __getstate__(self):
+ state = self.__dict__.copy()
+ state["sp_model"] = None
+ return state
+
+ def __setstate__(self, d):
+ self.__dict__ = d
+
+ # for backward compatibility
+ if not hasattr(self, "sp_model_kwargs"):
+ self.sp_model_kwargs = {}
+
+ self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
+ self.sp_model.Load(self.vocab_file)
+
+ def preprocess_text(self, inputs):
+ if self.remove_space:
+ outputs = " ".join(inputs.strip().split())
+ else:
+ outputs = inputs
+ outputs = outputs.replace("``", '"').replace("''", '"')
+
+ if not self.keep_accents:
+ outputs = unicodedata.normalize("NFKD", outputs)
+ outputs = "".join([c for c in outputs if not unicodedata.combining(c)])
+ if self.do_lower_case:
+ outputs = outputs.lower()
+
+ return outputs
+
+ def _tokenize(self, text: str) -> list[str]:
+ """Tokenize a string."""
+ text = self.preprocess_text(text)
+ pieces = self.sp_model.encode(text, out_type=str)
+ new_pieces = []
+ for piece in pieces:
+ if len(piece) > 1 and piece[-1] == "," and piece[-2].isdigit():
+ cur_pieces = self.sp_model.EncodeAsPieces(piece[:-1].replace(SPIECE_UNDERLINE, ""))
+ if piece[0] != SPIECE_UNDERLINE and cur_pieces[0][0] == SPIECE_UNDERLINE:
+ if len(cur_pieces[0]) == 1:
+ cur_pieces = cur_pieces[1:]
+ else:
+ cur_pieces[0] = cur_pieces[0][1:]
+ cur_pieces.append(piece[-1])
+ new_pieces.extend(cur_pieces)
+ else:
+ new_pieces.append(piece)
+
+ return new_pieces
+
+ def _convert_token_to_id(self, token):
+ """Converts a token (str) in an id using the vocab."""
+ return self.sp_model.PieceToId(token)
+
+ def _convert_id_to_token(self, index):
+ """Converts an index (integer) in a token (str) using the vocab."""
+ return self.sp_model.IdToPiece(index)
+
+ def convert_tokens_to_string(self, tokens):
+ """Converts a sequence of tokens (strings for sub-words) in a single string."""
+ out_string = "".join(tokens).replace(SPIECE_UNDERLINE, " ").strip()
+ return out_string
+
+ def _decode(
+ self,
+ token_ids: list[int],
+ skip_special_tokens: bool = False,
+ clean_up_tokenization_spaces: Optional[bool] = None,
+ spaces_between_special_tokens: bool = True,
+ **kwargs,
+ ) -> str:
+ self._decode_use_source_tokenizer = kwargs.pop("use_source_tokenizer", False)
+
+ filtered_tokens = self.convert_ids_to_tokens(token_ids, skip_special_tokens=skip_special_tokens)
+
+ # To avoid mixing byte-level and unicode for byte-level BPT
+ # we need to build string separately for added tokens and byte-level tokens
+ # cf. https://github.com/huggingface/transformers/issues/1133
+ sub_texts = []
+ current_sub_text = []
+ for token in filtered_tokens:
+ if skip_special_tokens and token in self.all_special_ids:
+ continue
+ if token in self.added_tokens_encoder:
+ if current_sub_text:
+ sub_texts.append(self.convert_tokens_to_string(current_sub_text))
+ current_sub_text = []
+ sub_texts.append(token)
+ else:
+ current_sub_text.append(token)
+ if current_sub_text:
+ sub_texts.append(self.convert_tokens_to_string(current_sub_text))
+
+ # Mimic the behavior of the Rust tokenizer:
+ # By default, there are no spaces between special tokens
+ text = "".join(sub_texts)
+
+ clean_up_tokenization_spaces = (
+ clean_up_tokenization_spaces
+ if clean_up_tokenization_spaces is not None
+ else self.clean_up_tokenization_spaces
+ )
+ if clean_up_tokenization_spaces:
+ clean_text = self.clean_up_tokenization(text)
+ return clean_text
+ else:
+ return text
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLNet sequence has the following format:
+
+ - single sequence: `X `
+ - pair of sequences: `A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ sep = [self.sep_token_id]
+ cls = [self.cls_token_id]
+ if token_ids_1 is None:
+ return token_ids_0 + sep + cls
+ return token_ids_0 + sep + token_ids_1 + sep + cls
+
+ def get_special_tokens_mask(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None, already_has_special_tokens: bool = False
+ ) -> list[int]:
+ """
+ Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
+ special tokens using the tokenizer `prepare_for_model` method.
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+ already_has_special_tokens (`bool`, *optional*, defaults to `False`):
+ Whether or not the token list is already formatted with special tokens for the model.
+
+ Returns:
+ `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
+ """
+
+ if already_has_special_tokens:
+ return super().get_special_tokens_mask(
+ token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
+ )
+
+ if token_ids_1 is not None:
+ return ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1, 1]
+ return ([0] * len(token_ids_0)) + [1, 1]
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. An XLNet
+ sequence pair mask has the following format:
+
+ ```
+ 0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
+ | first sequence | second sequence |
+ ```
+
+ If `token_ids_1` is `None`, this method only returns the first portion of the mask (0s).
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [token type IDs](../glossary#token-type-ids) according to the given sequence(s).
+ """
+ sep = [self.sep_token_id]
+ cls_segment_id = [2]
+
+ if token_ids_1 is None:
+ return len(token_ids_0 + sep) * [0] + cls_segment_id
+ return len(token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1] + cls_segment_id
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+ elif not os.path.isfile(self.vocab_file):
+ with open(out_vocab_file, "wb") as fi:
+ content_spiece_model = self.sp_model.serialized_model_proto()
+ fi.write(content_spiece_model)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["XLNetTokenizer"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/tokenization_xlnet_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/tokenization_xlnet_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..56cd2a50e1b26552d60e4e41a86cd5780a766363
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlnet/tokenization_xlnet_fast.py
@@ -0,0 +1,230 @@
+# coding=utf-8
+# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Tokenization classes for XLNet model."""
+
+import os
+from shutil import copyfile
+from typing import Optional
+
+from ...tokenization_utils import AddedToken
+from ...tokenization_utils_fast import PreTrainedTokenizerFast
+from ...utils import is_sentencepiece_available, logging
+
+
+if is_sentencepiece_available():
+ from .tokenization_xlnet import XLNetTokenizer
+else:
+ XLNetTokenizer = None
+
+
+logger = logging.get_logger(__name__)
+
+VOCAB_FILES_NAMES = {"vocab_file": "spiece.model", "tokenizer_file": "tokenizer.json"}
+
+
+SPIECE_UNDERLINE = "▁"
+
+# Segments (not really needed)
+SEG_ID_A = 0
+SEG_ID_B = 1
+SEG_ID_CLS = 2
+SEG_ID_SEP = 3
+SEG_ID_PAD = 4
+
+
+class XLNetTokenizerFast(PreTrainedTokenizerFast):
+ """
+ Construct a "fast" XLNet tokenizer (backed by HuggingFace's *tokenizers* library). Based on
+ [Unigram](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=unigram#models).
+
+ This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should
+ refer to this superclass for more information regarding those methods.
+
+ Args:
+ vocab_file (`str`):
+ [SentencePiece](https://github.com/google/sentencepiece) file (generally has a .spm extension) that
+ contains the vocabulary necessary to instantiate a tokenizer.
+ do_lower_case (`bool`, *optional*, defaults to `True`):
+ Whether to lowercase the input when tokenizing.
+ remove_space (`bool`, *optional*, defaults to `True`):
+ Whether to strip the text when tokenizing (removing excess spaces before and after the string).
+ keep_accents (`bool`, *optional*, defaults to `False`):
+ Whether to keep accents when tokenizing.
+ bos_token (`str`, *optional*, defaults to `""`):
+ The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the beginning of
+ sequence. The token used is the `cls_token`.
+
+
+
+ eos_token (`str`, *optional*, defaults to `" "`):
+ The end of sequence token.
+
+
+
+ When building a sequence using special tokens, this is not the token that is used for the end of sequence.
+ The token used is the `sep_token`.
+
+
+
+ unk_token (`str`, *optional*, defaults to `""`):
+ The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
+ token instead.
+ sep_token (`str`, *optional*, defaults to `""`):
+ The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for
+ sequence classification or for a text and a question for question answering. It is also used as the last
+ token of a sequence built with special tokens.
+ pad_token (`str`, *optional*, defaults to `""`):
+ The token used for padding, for example when batching sequences of different lengths.
+ cls_token (`str`, *optional*, defaults to `""`):
+ The classifier token which is used when doing sequence classification (classification of the whole sequence
+ instead of per-token classification). It is the first token of the sequence when built with special tokens.
+ mask_token (`str`, *optional*, defaults to `""`):
+ The token used for masking values. This is the token used when training this model with masked language
+ modeling. This is the token which the model will try to predict.
+ additional_special_tokens (`list[str]`, *optional*, defaults to `["", ""]`):
+ Additional special tokens used by the tokenizer.
+
+ Attributes:
+ sp_model (`SentencePieceProcessor`):
+ The *SentencePiece* processor that is used for every conversion (string, tokens and IDs).
+ """
+
+ vocab_files_names = VOCAB_FILES_NAMES
+ padding_side = "left"
+ slow_tokenizer_class = XLNetTokenizer
+
+ def __init__(
+ self,
+ vocab_file=None,
+ tokenizer_file=None,
+ do_lower_case=False,
+ remove_space=True,
+ keep_accents=False,
+ bos_token="",
+ eos_token=" ",
+ unk_token="",
+ sep_token="",
+ pad_token="",
+ cls_token="",
+ mask_token="",
+ additional_special_tokens=["", ""],
+ **kwargs,
+ ):
+ # Mask token behave like a normal word, i.e. include the space before it
+ mask_token = AddedToken(mask_token, lstrip=True, rstrip=False) if isinstance(mask_token, str) else mask_token
+
+ super().__init__(
+ vocab_file=vocab_file,
+ tokenizer_file=tokenizer_file,
+ do_lower_case=do_lower_case,
+ remove_space=remove_space,
+ keep_accents=keep_accents,
+ bos_token=bos_token,
+ eos_token=eos_token,
+ unk_token=unk_token,
+ sep_token=sep_token,
+ pad_token=pad_token,
+ cls_token=cls_token,
+ mask_token=mask_token,
+ additional_special_tokens=additional_special_tokens,
+ **kwargs,
+ )
+
+ self._pad_token_type_id = 3
+ self.do_lower_case = do_lower_case
+ self.remove_space = remove_space
+ self.keep_accents = keep_accents
+ self.vocab_file = vocab_file
+
+ def build_inputs_with_special_tokens(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and
+ adding special tokens. An XLNet sequence has the following format:
+
+ - single sequence: `X `
+ - pair of sequences: `A B `
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs to which the special tokens will be added.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens.
+ """
+ sep = [self.sep_token_id]
+ cls = [self.cls_token_id]
+ if token_ids_1 is None:
+ return token_ids_0 + sep + cls
+ return token_ids_0 + sep + token_ids_1 + sep + cls
+
+ def create_token_type_ids_from_sequences(
+ self, token_ids_0: list[int], token_ids_1: Optional[list[int]] = None
+ ) -> list[int]:
+ """
+ Create a mask from the two sequences passed to be used in a sequence-pair classification task. An XLNet
+ sequence pair mask has the following format:
+
+ ```
+ 0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
+ | first sequence | second sequence |
+ ```
+
+ If `token_ids_1` is `None`, this method only returns the first portion of the mask (0s).
+
+ Args:
+ token_ids_0 (`list[int]`):
+ List of IDs.
+ token_ids_1 (`list[int]`, *optional*):
+ Optional second list of IDs for sequence pairs.
+
+ Returns:
+ `list[int]`: List of [token type IDs](../glossary#token-type-ids) according to the given sequence(s).
+ """
+ sep = [self.sep_token_id]
+ cls_segment_id = [2]
+
+ if token_ids_1 is None:
+ return len(token_ids_0 + sep) * [0] + cls_segment_id
+ return len(token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1] + cls_segment_id
+
+ def save_vocabulary(self, save_directory: str, filename_prefix: Optional[str] = None) -> tuple[str]:
+ if not self.can_save_slow_tokenizer:
+ raise ValueError(
+ "Your fast tokenizer does not have the necessary information to save the vocabulary for a slow "
+ "tokenizer."
+ )
+
+ if not os.path.isdir(save_directory):
+ logger.error(f"Vocabulary path ({save_directory}) should be a directory")
+ return
+ out_vocab_file = os.path.join(
+ save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
+ )
+
+ if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file):
+ copyfile(self.vocab_file, out_vocab_file)
+
+ return (out_vocab_file,)
+
+
+__all__ = ["XLNetTokenizerFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..00e206973a908d82e9b8fe38a3d016fcced9ecd3
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/__init__.py
@@ -0,0 +1,31 @@
+# Copyright 2025 NXAI GmbH. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import (
+ OptionalDependencyNotAvailable,
+ _LazyModule,
+ is_torch_available,
+)
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from configuration_xlstm import *
+ from modeling_xlstm import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/configuration_xlstm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/configuration_xlstm.py
new file mode 100644
index 0000000000000000000000000000000000000000..80c513adde69d3511bea2ede9c1834b45e1eb166
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/configuration_xlstm.py
@@ -0,0 +1,302 @@
+# Copyright 2025 NXAI GmbH. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+"""xLSTM configuration."""
+
+from typing import Optional
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import is_xlstm_available, logging
+
+
+if is_xlstm_available():
+ from xlstm.xlstm_large.model import (
+ BackendModeType,
+ ChunkwiseKernelType,
+ DtypeType,
+ SequenceKernelType,
+ StepKernelType,
+ WeightModeType,
+ round_up_to_next_multiple_of,
+ xLSTMLargeConfig,
+ )
+
+ external_xlstm = True
+else:
+ from typing import Literal
+
+ BackendModeType = Literal["train", "train_with_padding", "inference"]
+ ChunkwiseKernelType = Literal[
+ "chunkwise--native_autograd",
+ "parallel--native_autograd",
+ ]
+ DtypeType = Literal["float32", "bfloat16", "float16"]
+ SequenceKernelType = Literal["native_sequence__native"]
+ StepKernelType = Literal["native"]
+ WeightModeType = Literal["single", "fused"]
+
+ def round_up_to_next_multiple_of(x: int, multiple_of: int) -> int:
+ """Rounds up x to the next multiple of multiple_of."""
+ return int(((x + multiple_of - 1) // multiple_of) * multiple_of)
+
+ external_xlstm = False
+
+
+logger = logging.get_logger(__name__)
+
+
+class xLSTMConfig(PretrainedConfig):
+ """
+ This is the configuration class to store the configuration of a [`xLSTM`]. It is used to instantiate a xLSTM
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the xLSTM-7b [NX-AI/xLSTM-7b](https://huggingface.co/NX-AI/xLSTM-7b) model.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (int, optional, *optional*, defaults to 50304):
+ Vocabulary size of the xLSTM model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`xLSTMModel`]. Defaults to the GPT2-NeoX tokenizer size.
+ hidden_size (int, optional, *optional*, defaults to 4096):
+ Dimensionality of the embeddings or hidden states.
+ embedding_dim (int, optional, *optional*, defaults to 4096):
+ Dimensionality of the embeddings or hidden states, use hidde_size if None.
+ num_hidden_layers (int, optional, *optional*, defaults to 32):
+ Number of blocks of the xLSTM model.
+ num_blocks (int, optional, *optional*, defaults to 32):
+ Number of blocks of the xLSTM model, use num_hidden_layers if None.
+ num_heads (int, optional, *optional*, defaults to 8):
+ Number of heads for the xLSTM Layer/Cell.
+ use_bias (bool, optional, *optional*, defaults to `False`):
+ Whether to use biases in the xLSTM model.
+ norm_reduction_force_float32 (bool, optional, *optional*, defaults to `True`):
+ Whether to force the float32 norm reduction op to be done in fp32 precision.
+ tie_word_embeddings (bool, optional, *optional*, defaults to `False`):
+ Whether to tie word embeddings to the lm head weights.
+ add_out_norm (bool, optional, *optional*, defaults to `True`):
+ Whether to add an output norm after the blocks before the LMHead.
+ norm_eps (float, optional, *optional*, defaults to 1e-06):
+ Norm eps for RMSNorm and Layer Norm.
+ qk_dim_factor (float, optional, *optional*, defaults to 0.5):
+ Scale factor for the query and key dimension.
+ v_dim_factor (float, optional, *optional*, defaults to 1.0):
+ Scale factor for the value dimension.
+ chunkwise_kernel (ChunkwiseKernelType, optional, *optional*, defaults to `"chunkwise--native_autograd"`):
+ Kernel type for chunkwise processing mode.
+ sequence_kernel (SequenceKernelType, optional, *optional*, defaults to `"native_sequence__native"`):
+ Kernel type for sequence processing mode.
+ step_kernel (StepKernelType, optional, *optional*, defaults to `"native"`):
+ Kernel type for step processing mode.
+ mode (BackendModeType, optional, *optional*, defaults to `"inference"`):
+ Operation mode (inference is needed for generation).
+ chunk_size (int, optional, *optional*, defaults to 64):
+ Internal chunk size.
+ return_last_states (bool, optional, *optional*, defaults to `True`):
+ If to return the last states / cache internally. Needed as True for generation.
+ autocast_kernel_dtype (DtypeType, optional, *optional*, defaults to `"bfloat16"`):
+ Kernel dtype for the states.
+ eps (float, optional, *optional*, defaults to 1e-06):
+ Epsilon for the mLSTM cell post norm.
+ inference_state_dtype (DtypeType, optional, *optional*, defaults to `"float32"`):
+ Kernel dtype for states in inference.
+ ffn_proj_factor (float, optional, *optional*, defaults to 2.667):
+ Size factor of the post-up projection gated Feed Forward network.
+ ffn_round_up_to_multiple_of (int, optional, *optional*, defaults to 64):
+ Size factor round value of the post-up projection gated Feed Forward network.
+ gate_soft_cap (float, optional, *optional*, defaults to 15.0):
+ Gate soft cap scale.
+ output_logit_soft_cap (float, optional, *optional*, defaults to 30.0):
+ Output logit soft cap scale.
+ weight_mode (`Literal`, *optional*, defaults to `"single"`):
+ Whether parallel linear layers are separated or fused (single).
+ use_cache (bool, optional, *optional*, defaults to `True`):
+ Whether to use the cache (xLSTMCache).
+ pad_token_id (int, optional, *optional*, defaults to 1):
+ Pad token id needed for generation.
+ bos_token_id (int, optional, *optional*, defaults to 0):
+ BOS token id needed for generation.
+ eos_token_id (int, optional, *optional*, defaults to 2):
+ EOS token id needed for generation.
+ max_inference_chunksize (int, optional, *optional*, defaults to 16384):
+ Limit the chunk size for inference to save memory.
+
+ Example:
+
+ ```python
+ >>> from transformers import xLSTMConfig, xLSTMModel
+
+ >>> # Initializing a xLSTM configuration
+ >>> configuration = xLSTMConfig()
+
+ >>> # Initializing a model (with random weights) from the configuration
+ >>> model = xLSTMModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xlstm"
+
+ def __init__(
+ self,
+ vocab_size: int = 50304,
+ hidden_size: int = 4096,
+ embedding_dim: Optional[int] = None,
+ num_hidden_layers: Optional[int] = 32,
+ num_blocks: Optional[int] = None,
+ num_heads: int = 8,
+ use_bias: bool = False,
+ norm_reduction_force_float32: bool = True,
+ tie_word_embeddings: bool = False,
+ add_out_norm: bool = True,
+ norm_eps: float = 1e-6,
+ # mlstm_layer
+ qk_dim_factor: float = 0.5,
+ v_dim_factor: float = 1.0,
+ # mlstm backend
+ chunkwise_kernel: ChunkwiseKernelType = "chunkwise--native_autograd",
+ sequence_kernel: SequenceKernelType = "native_sequence__native",
+ step_kernel: StepKernelType = "native",
+ # nedded to enable generation
+ mode: BackendModeType = "inference",
+ chunk_size: int = 64,
+ # needed to be true for generation
+ return_last_states: bool = True,
+ autocast_kernel_dtype: DtypeType = "bfloat16",
+ eps: float = 1e-6,
+ inference_state_dtype: DtypeType = "float32",
+ # feedforward
+ ffn_proj_factor: float = 2.667,
+ ffn_round_up_to_multiple_of: int = 64,
+ # capping
+ gate_soft_cap: float = 15.0,
+ output_logit_soft_cap: float = 30.0,
+ # weights
+ weight_mode: WeightModeType = "single",
+ # HF interface
+ use_cache: bool = True,
+ pad_token_id: int = 1,
+ bos_token_id: int = 0,
+ eos_token_id: int = 2,
+ max_inference_chunksize: int = 16384,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size if hidden_size is not None else embedding_dim
+ self.embedding_dim = embedding_dim if embedding_dim is not None else hidden_size
+ self.num_hidden_layers = num_hidden_layers if num_hidden_layers is not None else num_blocks
+ self.num_blocks = num_blocks if num_blocks is not None else num_hidden_layers
+ self.num_heads = num_heads
+ self.use_bias = use_bias
+ self.tie_word_embeddings = tie_word_embeddings
+ self.add_out_norm = add_out_norm
+ self.norm_eps = norm_eps
+ self.norm_reduction_force_float32 = norm_reduction_force_float32
+ # mlstm_layer
+ self.qk_dim_factor = qk_dim_factor
+ self.v_dim_factor = v_dim_factor
+ # mlstm backend
+ self.chunkwise_kernel = chunkwise_kernel
+ self.sequence_kernel = sequence_kernel
+ self.step_kernel = step_kernel
+ self.mode = mode
+ self.chunk_size = chunk_size
+ self.return_last_states = return_last_states
+ self.autocast_kernel_dtype = autocast_kernel_dtype
+ self.eps = eps
+ self.inference_state_dtype = inference_state_dtype
+ # feedforward
+ self.ffn_proj_factor = ffn_proj_factor
+ self.ffn_round_up_to_multiple_of = ffn_round_up_to_multiple_of
+ # capping
+ self.gate_soft_cap = gate_soft_cap
+ self.output_logit_soft_cap = output_logit_soft_cap
+ self.weight_mode = weight_mode
+
+ self.use_cache = use_cache
+ self.pad_token_id = pad_token_id
+ self.bos_token_id = bos_token_id
+ self.eos_token_id = eos_token_id
+ self.max_inference_chunksize = max_inference_chunksize
+
+ super().__init__(
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ pad_token_id=pad_token_id,
+ tie_word_embeddings=tie_word_embeddings,
+ **kwargs,
+ )
+
+ @property
+ def qk_dim(self):
+ return round_up_to_next_multiple_of(
+ self.hidden_size * self.qk_dim_factor,
+ multiple_of=64,
+ )
+
+ @property
+ def v_dim(self):
+ return round_up_to_next_multiple_of(
+ self.hidden_size * self.v_dim_factor,
+ multiple_of=64,
+ )
+
+ @property
+ def qk_head_dim(self):
+ return self.qk_dim // self.num_heads
+
+ @property
+ def v_head_dim(self):
+ return self.v_dim // self.num_heads
+
+ def to_xlstm_block_config(self):
+ if external_xlstm:
+ return xLSTMLargeConfig(
+ vocab_size=self.vocab_size,
+ embedding_dim=self.hidden_size,
+ num_blocks=self.num_hidden_layers,
+ num_heads=self.num_heads,
+ use_bias=self.use_bias,
+ add_out_norm=self.add_out_norm,
+ norm_eps=self.norm_eps,
+ norm_reduction_force_float32=self.norm_reduction_force_float32,
+ # mlstm_layer
+ qk_dim_factor=self.qk_dim_factor,
+ v_dim_factor=self.v_dim_factor,
+ # mlstm backend
+ chunkwise_kernel=self.chunkwise_kernel,
+ sequence_kernel=self.sequence_kernel,
+ step_kernel=self.step_kernel,
+ mode=self.mode,
+ chunk_size=self.chunk_size,
+ return_last_states=self.return_last_states,
+ autocast_kernel_dtype=self.autocast_kernel_dtype,
+ eps=self.eps,
+ inference_state_dtype=self.inference_state_dtype,
+ # feedforward
+ ffn_proj_factor=self.ffn_proj_factor,
+ ffn_round_up_to_multiple_of=self.ffn_round_up_to_multiple_of,
+ # capping
+ gate_soft_cap=self.gate_soft_cap,
+ output_logit_soft_cap=self.output_logit_soft_cap,
+ weight_mode=self.weight_mode,
+ )
+ else:
+ return self
+
+
+__all__ = ["xLSTMConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/modeling_xlstm.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/modeling_xlstm.py
new file mode 100644
index 0000000000000000000000000000000000000000..14f189d2f1ccfe2b83a0dbeab4b34d05af5623a8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xlstm/modeling_xlstm.py
@@ -0,0 +1,1624 @@
+# Copyright 2025 NXAI GmbH. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch xLSTM Model."""
+
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.nn.functional as F
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import CrossEntropyLoss
+
+from ...generation import GenerationMixin
+from ...modeling_utils import PreTrainedModel
+from ...utils import ModelOutput, auto_docstring, can_return_tuple, is_xlstm_available
+from .configuration_xlstm import xLSTMConfig
+
+
+if is_xlstm_available():
+ from xlstm.xlstm_large.model import RMSNorm as xLSTMRMSNorm
+ from xlstm.xlstm_large.model import mLSTMBlock as xLSTMBlock
+ from xlstm.xlstm_large.model import mLSTMStateType, soft_cap
+
+ external_xlstm = True
+else:
+ from functools import partial
+ from typing import Callable, Literal
+
+ from .configuration_xlstm import round_up_to_next_multiple_of
+
+ mLSTMLayerStateType = tuple[torch.Tensor, torch.Tensor, torch.Tensor]
+ mLSTMStateType = dict[int, mLSTMLayerStateType]
+
+ external_xlstm = False
+
+ def soft_cap(values: torch.Tensor, cap_value: Optional[Union[float, torch.Tensor]] = None) -> torch.Tensor:
+ """
+ Soft caps a tensor to a value.
+
+ Performs a tanh operation on the logits and scales the result to the cap value. Common technique in attention
+ and output language heads to prevent large logits from dominating the softmax. See for example Gemma2:
+ https://huggingface.co/papers/2408.00118
+
+ Args:
+ values: The tensor to cap.
+ cap_value: The value to cap the values to. If None, no cap is applied.
+
+ Returns:
+ The capped values.
+ """
+ if cap_value is None:
+ return values
+ return cap_value * torch.tanh(values / cap_value)
+
+ def mlstm_chunkwise_recurrent_fw_C(
+ matK: torch.Tensor,
+ matV: torch.Tensor,
+ vecB: torch.Tensor,
+ vecI: torch.Tensor,
+ matC_states: torch.Tensor = None,
+ vecN_states: torch.Tensor = None,
+ scaMinter_states: torch.Tensor = None,
+ matC_initial: torch.Tensor = None,
+ vecN_initial: torch.Tensor = None,
+ scaMinter_initial: torch.Tensor = None,
+ qk_scale: Optional[float] = None,
+ chunk_size: int = 64,
+ num_chunks: int = 1,
+ ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
+ batch_size, nh, _, dhqk, dhhv = *matK.shape, matV.shape[-1]
+ nc = num_chunks
+ _dtype, _device = matK.dtype, matK.device
+
+ if qk_scale is None:
+ qk_scale = dhqk**-0.5
+
+ # initialize the states tensors
+ if matC_states is None:
+ matC_states = torch.zeros((batch_size, nh, (nc + 1) * dhqk, dhhv), dtype=_dtype, device=_device)
+ if vecN_states is None:
+ vecN_states = torch.zeros((batch_size, nh, (nc + 1) * dhqk), dtype=_dtype, device=_device)
+ if scaMinter_states is None:
+ scaMinter_states = torch.zeros((batch_size, nh, (nc + 1)), dtype=_dtype, device=_device)
+
+ # assign the initial states to the running states
+ matC_k = (
+ torch.zeros((batch_size, nh, dhqk, dhhv), dtype=_dtype, device=_device)
+ if matC_initial is None
+ else matC_initial
+ )
+ vecN_k = (
+ torch.zeros((batch_size, nh, dhqk), dtype=_dtype, device=_device) if vecN_initial is None else vecN_initial
+ )
+ scaM_inter_k = (
+ torch.zeros((batch_size, nh, 1), dtype=_dtype, device=_device)
+ if scaMinter_initial is None
+ else scaMinter_initial
+ )
+ vecA = vecB[..., -1, None] - vecB + vecI
+ scaG = vecB[..., -1]
+ scaA_max = vecA.max(-1).values
+
+ scaM_inter_k = scaM_inter_k.squeeze(-1)
+
+ for key in range(0, num_chunks):
+ # store the states from the previous iteration before updating them
+ # in the first iteration, these are the initial states
+ matC_states[:, :, key * dhqk : (key + 1) * dhqk, :] = matC_k
+ vecN_states[:, :, key * dhqk : (key + 1) * dhqk] = vecN_k
+ scaMinter_states[:, :, key] = scaM_inter_k
+
+ # m_k update
+ scaA_max_k = scaA_max[:, :, key]
+ scaG_k = scaG[:, :, key]
+ scaM_inter_k_next = torch.max(scaG_k + scaM_inter_k, scaA_max_k)
+ # C_k update
+ matK_chunk = matK[:, :, key * chunk_size : (key + 1) * chunk_size, :] # * qk_scale
+ matV_chunk = matV[:, :, key * chunk_size : (key + 1) * chunk_size, :]
+ vecA_k = vecA[:, :, key, :]
+
+ vecAbar_k = torch.exp(vecA_k - scaM_inter_k_next[..., None])[:, :, :, None]
+
+ matK_chunk_gated = matK_chunk * vecAbar_k
+
+ scaGbar_k = torch.exp(scaG_k + scaM_inter_k - scaM_inter_k_next)[:, :, None]
+
+ # NOTE: no update in-place (i.e. +=) as this gives error for autograd backward
+ matC_k_next = scaGbar_k[..., None] * matC_k + matK_chunk_gated.transpose(-2, -1) @ (matV_chunk)
+
+ # n_k update
+ vecN_k_next = scaGbar_k * vecN_k + matK_chunk_gated.transpose(-2, -1).sum(-1)
+
+ # move to the next iteration
+ scaM_inter_k = scaM_inter_k_next
+ matC_k = matC_k_next
+ vecN_k = vecN_k_next
+
+ # store the states from the last iteration
+ matC_states[:, :, -dhqk:, :] = matC_k
+ vecN_states[:, :, -dhqk:] = vecN_k
+ scaMinter_states[:, :, -1] = scaM_inter_k
+
+ return matC_states, vecN_states, scaMinter_states
+
+ def mlstm_chunkwise_parallel_fw_H(
+ matQ: torch.Tensor,
+ matK: torch.Tensor,
+ matV: torch.Tensor,
+ # these states must be all states up to the last chunk, i.e. :-1
+ matC_states: torch.Tensor,
+ vecN_states: torch.Tensor,
+ scaMinter_states: torch.Tensor,
+ vecI: torch.Tensor,
+ vecB: torch.Tensor,
+ qk_scale: float,
+ chunk_size: int = 64,
+ num_chunks: int = 1,
+ eps: float = 1e-6,
+ ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
+ _device = matQ.device
+ nc, chunk_size = num_chunks, chunk_size
+ batch_size, nh, dqk, dhv = matC_states.shape
+ matC_k_states = matC_states.view(batch_size, nh, nc, dqk // nc, dhv)
+ vecN_k_states = vecN_states.view(batch_size, nh, nc, dqk // nc)
+ scaMinter_k_states = scaMinter_states
+
+ matQ = matQ.view(batch_size, nh, nc, chunk_size, dqk)
+ matK = matK.view(batch_size, nh, nc, chunk_size, dqk)
+ matV = matV.view(batch_size, nh, nc, chunk_size, dhv)
+
+ ltr = torch.tril(
+ torch.ones(
+ (chunk_size, chunk_size),
+ dtype=torch.bool,
+ device=_device,
+ )
+ )
+
+ # Compute intra chunk contribution: H_intra
+ matF_logsig_chunk = vecB[:, :, :, :, None] - vecB[:, :, :, None, :]
+
+ matF_logsig_mask_chunk = torch.where(ltr, matF_logsig_chunk, -float("inf"))
+
+ matLogD_chunk = matF_logsig_mask_chunk + vecI[:, :, :, None, :]
+
+ # max_state intra
+ vecMintra_k = torch.max(matLogD_chunk, dim=-1, keepdim=False).values
+
+ # max_state combined
+ vecM_b_inter = vecB + scaMinter_k_states[:, :, :, None]
+ vecM_k_combine = torch.maximum(vecM_b_inter, vecMintra_k)
+
+ vecM_k_combine = vecM_k_combine[:, :, :, :, None]
+ vecM_b_inter = vecM_b_inter[:, :, :, :, None]
+
+ matLogD_stabilized_chunk = matLogD_chunk - vecM_k_combine
+ matD_chunk = torch.exp(matLogD_stabilized_chunk)
+
+ matS_chunk = (matQ @ matK.transpose(-2, -1)) * qk_scale
+
+ matM_chunk = matS_chunk * matD_chunk
+
+ # ? Combine H_intra with H_inter
+ vecBbar = torch.exp(vecM_b_inter - vecM_k_combine)
+ matQ_chunk_gated = matQ * vecBbar * qk_scale
+
+ matNumerator_common = matQ_chunk_gated @ matC_k_states + matM_chunk @ matV
+
+ vecDenom_l_common = matQ_chunk_gated @ vecN_k_states.unsqueeze(-1) + matM_chunk.sum(dim=-1, keepdim=True)
+
+ vecDenom_max_common = torch.maximum(torch.abs(vecDenom_l_common), torch.exp(-vecM_k_combine))
+
+ matH_k_chunk = matNumerator_common / (vecDenom_max_common + eps)
+
+ matH_out = matH_k_chunk.view(batch_size, nh, nc * chunk_size, dhv)
+
+ # we need the denominator and the overall max state for the backward pass
+ vecN_out = vecDenom_max_common.reshape(batch_size, nh, nc * chunk_size)
+ vecM_out = vecM_k_combine(batch_size, nh, nc * chunk_size)
+ return matH_out, vecN_out, vecM_out
+
+ def mlstm_chunkwise_fw(
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ igate: torch.Tensor,
+ fgate: torch.Tensor,
+ cstate: torch.Tensor = None,
+ nstate: torch.Tensor = None,
+ mstate: torch.Tensor = None,
+ qk_scale: Optional[float] = None,
+ return_last_states: bool = False,
+ return_all_states: bool = False,
+ chunk_size: int = 64,
+ eps: float = 1e-6,
+ ) -> tuple[
+ torch.Tensor,
+ torch.Tensor,
+ torch.Tensor,
+ Optional[tuple[torch.Tensor, torch.Tensor, torch.Tensor]],
+ Optional[tuple[torch.Tensor, torch.Tensor, torch.Tensor]],
+ ]:
+ batch_size, nh, sequence_length, dhqk = query.shape
+ if sequence_length % chunk_size != 0:
+ raise ValueError(f"Sequence length {sequence_length} is not divisible by chunk size {chunk_size}.")
+ nc = sequence_length // chunk_size
+
+ vecI = igate.view(batch_size, nh, nc, chunk_size)
+ vecF = fgate.view(batch_size, nh, nc, chunk_size)
+
+ # compute the gates, the g and the a and b vectors
+ vecF_logsig = fgate.logsigmoid(vecF)
+ vecB = vecF_logsig.cumsum(-1)
+
+ if qk_scale is None:
+ qk_scale = dhqk**-0.5
+
+ #! materialize the C_k, n_k, m_k states for each chunk
+ matC_k_states, vecN_k_states, scaMinter_k_states = mlstm_chunkwise_recurrent_fw_C(
+ matK=key,
+ matV=value,
+ vecB=vecB,
+ vecI=vecI,
+ matC_initial=cstate,
+ vecN_initial=nstate,
+ scaMinter_initial=mstate,
+ qk_scale=qk_scale,
+ chunk_size=chunk_size,
+ num_chunks=nc,
+ )
+
+ #! compute the outputs within each chunk
+ matH_out, vecN_out, vecM_out = mlstm_chunkwise_parallel_fw_H(
+ matQ=query,
+ matK=key,
+ matV=value,
+ matC_states=matC_k_states[:, :, :-dhqk, :],
+ vecN_states=vecN_k_states[:, :, :-dhqk],
+ scaMinter_states=scaMinter_k_states[:, :, :-1],
+ vecI=vecI,
+ vecB=vecB,
+ qk_scale=qk_scale,
+ chunk_size=chunk_size,
+ num_chunks=nc,
+ eps=eps,
+ )
+
+ ret_tuple = (matH_out, vecN_out, vecM_out)
+ if return_last_states:
+ ret_tuple += (
+ (matC_k_states[:, :, -dhqk:, :], vecN_k_states[:, :, -dhqk:], scaMinter_k_states[:, :, -1:]),
+ )
+ else:
+ ret_tuple += (None,)
+
+ if return_all_states:
+ ret_tuple += ((matC_k_states, vecN_k_states, scaMinter_k_states),)
+ else:
+ ret_tuple += (None,)
+
+ return ret_tuple
+
+ def mlstm_chunkwise_native_autograd(
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ igate: torch.Tensor,
+ fgate: torch.Tensor,
+ c_initial: torch.Tensor = None,
+ n_initial: torch.Tensor = None,
+ m_initial: torch.Tensor = None,
+ return_last_states: bool = False,
+ eps: float = 1e-6,
+ chunk_size: int = 64,
+ **kwargs,
+ ) -> Union[torch.Tensor, tuple[torch.Tensor, tuple[torch.Tensor, torch.Tensor, torch.Tensor]]]:
+ batch_size, nh, sequence_length, dhqk = query.shape
+ if sequence_length % chunk_size != 0:
+ raise ValueError(f"Sequence length {sequence_length} is not divisible by chunk size {chunk_size}.")
+ nc = sequence_length // chunk_size
+
+ vecI = igate.view(batch_size, nh, nc, chunk_size)
+ vecF = fgate.view(batch_size, nh, nc, chunk_size)
+
+ # compute the gates, the g and the a and b vectors
+ vecF_logsig = F.logsigmoid(vecF)
+ vecB = vecF_logsig.cumsum(-1)
+
+ qk_scale = dhqk**-0.5
+
+ #! materialize the C_k, n_k, m_k states for each chunk
+ matC_k_states, vecN_k_states, scaMinter_k_states = mlstm_chunkwise_recurrent_fw_C(
+ matK=key,
+ matV=value,
+ vecB=vecB,
+ vecI=vecI,
+ matC_initial=c_initial,
+ vecN_initial=n_initial,
+ scaMinter_initial=m_initial,
+ qk_scale=qk_scale,
+ chunk_size=chunk_size,
+ num_chunks=nc,
+ )
+
+ #! compute the outputs within each chunk
+ matH_out, vecN_out, vecM_out = mlstm_chunkwise_parallel_fw_H(
+ matQ=query,
+ matK=key,
+ matV=value,
+ matC_states=matC_k_states[:, :, :-dhqk, :],
+ vecN_states=vecN_k_states[:, :, :-dhqk],
+ scaMinter_states=scaMinter_k_states[:, :, :-1],
+ vecI=vecI,
+ vecB=vecB,
+ qk_scale=qk_scale,
+ chunk_size=chunk_size,
+ num_chunks=nc,
+ eps=eps,
+ )
+
+ last_states = (matC_k_states[:, :, -dhqk:, :], vecN_k_states[:, :, -dhqk:], scaMinter_k_states[:, :, -1:])
+
+ if return_last_states:
+ return matH_out, last_states
+ else:
+ return matH_out
+
+ def mlstm_recurrent_step_native(
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ igate: torch.Tensor,
+ fgate: torch.Tensor,
+ cstate: torch.Tensor,
+ nstate: torch.Tensor,
+ mstate: torch.Tensor,
+ eps: float = 1e-6,
+ dtype_state: torch.dtype = torch.float32,
+ **kwargs,
+ ) -> tuple[torch.Tensor, tuple[torch.Tensor, torch.Tensor, torch.Tensor]]:
+ """This is a single step of the mLSTM operation in recurrent form."""
+ dtype_qkv = query.dtype
+ matC_old = cstate.to(dtype=dtype_state)
+ vecN_old = nstate.to(dtype=dtype_state)
+ scaM_old = mstate.to(dtype=dtype_state)
+
+ batch_size, nh, dhqk = query.shape
+ _, _, dhhv = value.shape
+ if query.shape != key.shape:
+ raise ValueError("query and key must have the same shape")
+ if matC_old.shape != (batch_size, nh, dhqk, dhhv):
+ raise ValueError(f"matC_old has wrong shape, got {matC_old.shape}")
+ if vecN_old.shape != (batch_size, nh, dhqk):
+ raise ValueError(f"vecN_old has wrong shape, got {vecN_old.shape}")
+ if scaM_old.shape != (batch_size, nh, 1):
+ raise ValueError(f"scaM_old has wrong shape, got {scaM_old.shape}")
+ if igate.shape != (batch_size, nh, 1):
+ raise ValueError(f"scaI has wrong shape, got {igate.shape}")
+ if fgate.shape != (batch_size, nh, 1):
+ raise ValueError(f"scaF has wrong shape, got {fgate.shape}")
+
+ # gates
+ scaF_log = torch.nn.functional.logsigmoid(fgate)
+
+ # update rule
+ scaM_state_new = torch.max(scaF_log + scaM_old, igate)
+
+ scaF_act = torch.exp(scaF_log + scaM_old - scaM_state_new)
+ scaI_act = torch.exp(igate - scaM_state_new)
+
+ vecQ_scaled = query * (dhqk ** (-0.5))
+ matC_state_new = scaF_act[:, :, :, None] * matC_old + scaI_act[:, :, :, None] * (
+ key[:, :, :, None] @ value[:, :, None, :]
+ )
+ vecN_state_new = scaF_act * vecN_old + scaI_act * key
+ h_num = vecQ_scaled[:, :, None, :] @ matC_state_new.to(dtype=dtype_qkv)
+ h_num = h_num.squeeze(2).to(dtype=dtype_state)
+
+ qn_dotproduct = vecQ_scaled[:, :, None, :] @ vecN_state_new[:, :, :, None].to(dtype=dtype_qkv)
+ qn_dotproduct = qn_dotproduct.squeeze(2)
+ max_val = torch.exp(-scaM_state_new)
+ h_denom = (torch.maximum(qn_dotproduct.abs(), max_val) + eps).to(dtype=dtype_state)
+ h = h_num / h_denom
+
+ h = h.to(dtype=dtype_qkv)
+ matC_state_new = matC_state_new.to(dtype=dtype_state)
+ vecN_state_new = vecN_state_new.to(dtype=dtype_state)
+ scaM_state_new = scaM_state_new.to(dtype=dtype_state)
+ return h, (matC_state_new, vecN_state_new, scaM_state_new)
+
+ def mlstm_recurrent_sequence_native(
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ igate: torch.Tensor,
+ fgate: torch.Tensor,
+ c_initial: torch.Tensor = None,
+ n_initial: torch.Tensor = None,
+ m_initial: torch.Tensor = None,
+ return_last_states: bool = False,
+ eps: float = 1e-6,
+ dtype_state: torch.dtype = torch.float32,
+ **kwargs,
+ ) -> tuple[
+ torch.Tensor,
+ torch.Tensor,
+ torch.Tensor,
+ Optional[tuple[torch.Tensor, torch.Tensor, torch.Tensor]],
+ Optional[tuple[torch.Tensor, torch.Tensor, torch.Tensor]],
+ ]:
+ batch_size, nh, sequence_length, dhqk = query.shape
+ dhv = value.shape[-1]
+ device = query.device
+
+ if c_initial is not None:
+ if n_initial is None or m_initial is None:
+ raise ValueError("Initial states must be provided together.")
+ if n_initial is None or m_initial is None:
+ raise ValueError("Initial states must be provided together.")
+ matC_state, vecN_state, vecM_state = (
+ c_initial.to(dtype=dtype_state),
+ n_initial.to(dtype=dtype_state),
+ m_initial.to(dtype=dtype_state),
+ )
+ else:
+ # memory state
+ matC_state = torch.zeros((batch_size, nh, dhqk, dhv), dtype=dtype_state, device=device)
+ # normalizer state
+ vecN_state = torch.zeros((batch_size, nh, dhqk), dtype=dtype_state, device=device)
+ # max state
+ vecM_state = torch.zeros((batch_size, nh, 1), dtype=dtype_state, device=device)
+
+ vecH_list = []
+ for t in range(sequence_length):
+ # gates
+ vecF_t, vecI_t = fgate[:, :, t, None], igate[:, :, t, None]
+
+ # projections
+ vecQ_t, vecK_t, vecV_t = query[:, :, t, :], key[:, :, t, :], value[:, :, t, :]
+
+ # step
+ vecH, (matC_state, vecN_state, vecM_state) = mlstm_recurrent_step_native(
+ cstate=matC_state,
+ nstate=vecN_state,
+ mstate=vecM_state,
+ query=vecQ_t,
+ key=vecK_t,
+ value=vecV_t,
+ igate=vecI_t,
+ fgate=vecF_t,
+ eps=eps,
+ dtype_state=dtype_state,
+ **kwargs,
+ )
+ vecH_list.append(vecH)
+
+ matH = torch.stack(vecH_list, dim=-2)
+
+ if return_last_states:
+ return matH, (matC_state, vecN_state, vecM_state)
+ else:
+ return matH
+
+ def wrap_chunkwise_pad_zeros(
+ mlstm_chunkwise_kernel: Callable,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ fgate: torch.Tensor,
+ igate: torch.Tensor,
+ c_initial: torch.Tensor = None,
+ n_initial: torch.Tensor = None,
+ m_initial: torch.Tensor = None,
+ return_last_states: bool = False,
+ eps: float = 1e-6,
+ autocast_kernel_dtype: torch.dtype = torch.bfloat16,
+ chunk_size: int = 64,
+ **kwargs,
+ ) -> Union[torch.Tensor, tuple[torch.Tensor, tuple[torch.Tensor, torch.Tensor, torch.Tensor]]]:
+ if return_last_states:
+ raise ValueError(
+ "We are padding zeros, so we cannot return last states,",
+ "as they would be not the true last states.",
+ )
+
+ batch_size, nh, sequence_length, dhqk = query.shape
+ S_unpadded = sequence_length
+ # padding to chunk size for kernels
+ if sequence_length % chunk_size != 0:
+ S_padded = ((sequence_length + chunk_size - 1) // chunk_size) * chunk_size
+ q_pad = query.new_zeros(batch_size, nh, S_padded, query.shape[3])
+ k_pad = key.new_zeros(batch_size, nh, S_padded, key.shape[3])
+ v_pad = value.new_zeros(batch_size, nh, S_padded, value.shape[3])
+ i_pad = igate.new_zeros(batch_size, nh, S_padded)
+ f_pad = fgate.new_zeros(batch_size, nh, S_padded)
+ q_pad[:, :, :S_unpadded, :] = query
+ k_pad[:, :, :S_unpadded, :] = key
+ v_pad[:, :, :S_unpadded, :] = value
+ i_pad[:, :, :S_unpadded] = igate
+ f_pad[:, :, :S_unpadded] = fgate
+ else:
+ q_pad = query
+ k_pad = key
+ v_pad = value
+ i_pad = igate
+ f_pad = fgate
+
+ matH = mlstm_chunkwise_kernel(
+ query=q_pad,
+ key=k_pad,
+ value=v_pad,
+ igate=i_pad,
+ fgate=f_pad,
+ c_initial=c_initial,
+ n_initial=n_initial,
+ m_initial=m_initial,
+ return_last_states=return_last_states,
+ eps=eps,
+ autocast_kernel_dtype=autocast_kernel_dtype,
+ chunk_size=chunk_size,
+ **kwargs,
+ )
+ matH = matH[:, :, :S_unpadded, :]
+ return matH
+
+ def wrap_chunkwise_arbitrary_sequence_length(
+ mlstm_chunkwise_kernel: Callable,
+ mlstm_sequence_kernel: Callable,
+ mlstm_step_kernel: Callable,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ fgate: torch.Tensor,
+ igate: torch.Tensor,
+ c_initial: torch.Tensor = None,
+ n_initial: torch.Tensor = None,
+ m_initial: torch.Tensor = None,
+ return_last_states: bool = True,
+ eps: float = 1e-6,
+ autocast_kernel_dtype: torch.dtype = torch.bfloat16,
+ chunk_size: int = 64,
+ enable_logging: bool = False,
+ ) -> Union[torch.Tensor, tuple[torch.Tensor, tuple[torch.Tensor, torch.Tensor, torch.Tensor]]]:
+ """This function computes the last hidden state and matH outputs of the mLSTM, independently of the sequence length.
+
+ For this it uses three kernels:
+ - mlstm_chunkwise_kernel: mlstm chunkwise kernels that processes chunks of a given chunk size in parallel.
+ - mlstm_sequence_kernel: mlstm kernel that processes the remaining sequence length in a single step recurrence.
+ - mlstm_step_kernel: mlstm kernel that processes a sequence length of 1 in a single step.
+
+ It tries to maximize the chunksizes to improve performance.
+ It will start with the given chunk size and then divides the chunksize by 2 until the chunk size is smaller than 16.
+ At every chunksize it will process the maximal number of chunks that fit into the remaining sequence length.
+
+ E.g. for chunk_size = 64, this function will try the chunksizes [64, 32, 16] if necessary.
+
+ For the remaining sequence length, which is smaller than 16, we use a different kernel that computes the mLSTM
+ in a single step and loop over this in pytorch.
+
+ Args:
+ mlstm_chunkwise_kernel: The mLSTM chunkwise kernel that processes chunks of a given chunk size in parallel
+ mlstm_sequence_kernel: The mLSTM kernel that processes the remaining sequence length in a single step recurrence
+ query: The query tensor (batch_size, nh, sequence_length, dhqk)
+ key: The key tensor (batch_size, nh, sequence_length, dhqk)
+ value: The value tensor (batch_size, nh, sequence_length, dhhv)
+ fgate: The forget gate tensor (batch_size, nh, sequence_length)
+ igate: The input gate tensor (batch_size, nh, sequence_length)
+ c_initial: The initial cell state tensor (batch_size, nh, dhqk, dhhv)
+ n_initial: The initial hidden state tensor (batch_size, nh, dhqk)
+ m_initial: The initial memory state tensor (batch_size, nh, 1)
+ return_last_states: If True, the function will return the last states of the mLSTM
+ eps: The epsilon value used for numerical stability
+ autocast_kernel_dtype: The dtype used for the kernel computation
+ chunk_size: The chunk size used for the chunkwise kernel
+ enable_logging: If True, the function will log debug information. Default is False.
+
+ Returns:
+ The last hidden state tensor (batch_size, nh, sequence_length, dhhv) or a tuple containing the last hidden state tensor and the last states of the mLSTM
+ Last states are (cstate (batch_size, nh, dhqk, dhhv), nstate (batch_size, nh, dhqk), mstate (batch_size, nh, 1)).
+ """
+
+ batch_size, nh, sequence_length, dhqk = key.shape
+ dhhv = value.shape[-1]
+
+ c_state = (
+ c_initial
+ if c_initial is not None
+ else torch.zeros(batch_size, nh, dhqk, dhhv, device=key.device, dtype=torch.float32)
+ )
+ n_state = (
+ n_initial
+ if n_initial is not None
+ else torch.zeros(batch_size, nh, dhqk, device=key.device, dtype=torch.float32)
+ )
+ m_state = (
+ m_initial
+ if m_initial is not None
+ else torch.zeros(batch_size, nh, 1, device=key.device, dtype=torch.float32)
+ )
+
+ if sequence_length > 1:
+ # process the sequence length in chunks
+ h_outs = []
+ seq_len_start_idx = 0
+ remaining_seq_len = sequence_length - seq_len_start_idx
+ num_chunks = remaining_seq_len // chunk_size
+ if num_chunks > 0:
+ iter_seq_len = chunk_size * num_chunks
+ seq_len_idx = seq_len_start_idx + iter_seq_len
+ h_out, (c_state, n_state, m_state) = mlstm_chunkwise_kernel(
+ query=query[..., seq_len_start_idx:seq_len_idx, :].contiguous(),
+ key=key[..., seq_len_start_idx:seq_len_idx, :].contiguous(),
+ value=value[..., seq_len_start_idx:seq_len_idx, :].contiguous(),
+ fgate=fgate[..., seq_len_start_idx:seq_len_idx].contiguous(),
+ igate=igate[..., seq_len_start_idx:seq_len_idx].contiguous(),
+ c_initial=c_state,
+ n_initial=n_state,
+ m_initial=m_state,
+ chunk_size=chunk_size,
+ return_last_states=True,
+ autocast_kernel_dtype=autocast_kernel_dtype,
+ eps=eps,
+ )
+ seq_len_start_idx += iter_seq_len
+ h_outs.append(h_out)
+
+ remaining_seq_len = sequence_length - seq_len_start_idx
+
+ if remaining_seq_len > 0:
+ # we use here matK as query as this kernel does not need a query, since we do not care about the outputs only about the last state
+ h_out, (c_state, n_state, m_state) = mlstm_sequence_kernel(
+ query=query[..., seq_len_start_idx:sequence_length, :].contiguous(),
+ key=key[..., seq_len_start_idx:sequence_length, :].contiguous(),
+ value=value[..., seq_len_start_idx:sequence_length, :].contiguous(),
+ igate=igate[..., seq_len_start_idx:sequence_length].contiguous(),
+ fgate=fgate[..., seq_len_start_idx:sequence_length].contiguous(),
+ c_initial=c_state,
+ n_initial=n_state,
+ m_initial=m_state,
+ return_last_states=True,
+ eps=eps,
+ )
+ h_outs.append(h_out)
+ h_out = torch.concatenate(h_outs, dim=2)
+
+ else:
+ if sequence_length != 1:
+ raise ValueError(
+ f"Received empty sequence (sequence_length={sequence_length}), require at least single element in the sequence."
+ )
+ # process the sequence length in a single step
+ # while this case is also captured by the regular mode above,
+ # it avoids the overhead of the loop and calls the step kernel directly
+ # The step function does not want a sequence dimension
+ # qkv shape is (batch_size, nh, dhqk/dhv)
+ # igate, fgate shape is (batch_size, nh, 1)
+ h_out, (c_state, n_state, m_state) = mlstm_step_kernel(
+ query=query.squeeze(2),
+ key=key.squeeze(2),
+ value=value.squeeze(2),
+ igate=igate,
+ fgate=fgate,
+ cstate=c_state,
+ nstate=n_state,
+ mstate=m_state,
+ eps=eps,
+ )
+ h_out = h_out[:, :, None, :]
+
+ if return_last_states:
+ return h_out, (c_state, n_state, m_state)
+ else:
+ return h_out
+
+ class xLSTMBackend(nn.Module):
+ """xLSTM Backend Module for PyTorch.
+
+ This module wraps the xLSTM kernels and provides a high-level interface for training and inference.
+ """
+
+ config_class = xLSTMConfig
+
+ def __init__(self, config: xLSTMConfig):
+ super().__init__()
+ self.config = config
+ self.chunkwise_kernel_fn = mlstm_chunkwise_native_autograd
+ self.sequence_kernel_fn = mlstm_recurrent_sequence_native
+ self.step_kernel_fn = mlstm_recurrent_step_native
+
+ self._inference_fn = partial(
+ wrap_chunkwise_arbitrary_sequence_length,
+ mlstm_chunkwise_kernel=self.chunkwise_kernel_fn,
+ mlstm_sequence_kernel=partial(
+ self.sequence_kernel_fn,
+ dtype_state=getattr(torch, config.inference_state_dtype),
+ ),
+ mlstm_step_kernel=partial(
+ self.step_kernel_fn,
+ dtype_state=getattr(torch, config.inference_state_dtype),
+ ),
+ chunk_size=config.chunk_size,
+ eps=config.eps,
+ autocast_kernel_dtype=getattr(torch, config.autocast_kernel_dtype),
+ return_last_states=True,
+ )
+
+ train_kernel_fn = partial(
+ self.chunkwise_kernel_fn,
+ autocast_kernel_dtype=getattr(torch, config.autocast_kernel_dtype),
+ eps=config.eps,
+ chunk_size=config.chunk_size,
+ )
+ if "with_padding" in config.mode:
+ train_kernel_fn = partial(wrap_chunkwise_pad_zeros, mlstm_chunkwise_kernel=train_kernel_fn)
+ self._train_fn = train_kernel_fn
+
+ def forward(
+ self,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ igate: torch.Tensor,
+ fgate: torch.Tensor,
+ c_initial: torch.Tensor = None,
+ n_initial: torch.Tensor = None,
+ m_initial: torch.Tensor = None,
+ return_last_states: bool = False,
+ mode: Optional[Literal["train", "inference"]] = None,
+ ) -> Union[torch.Tensor, tuple[torch.Tensor, tuple[torch.Tensor, torch.Tensor, torch.Tensor]]]:
+ """Forward pass of the mLSTM backend.
+
+ Depending on the configured mode, this method will call the appropriate kernel function.
+
+ Args:
+ query: The query tensor of shape (batch_size, nh, sequence_length, dhqk).
+ key: The key tensor of shape (batch_size, nh, sequence_length, dhqk).
+ value: The value tensor of shape (batch_size, nh, sequence_length, dhhv).
+ igate: The input gate preactivation tensor of shape (batch_size, nh, sequence_length).
+ fgate: The forget gate preactivation tensor of shape (batch_size, nh, sequence_length).
+ c_initial: The initial cell state tensor of shape (batch_size, nh, dhqk, dhhv).
+ Defaults to None.
+ n_initial: The initial hidden state tensor of shape (batch_size, nh, dhqk). Defaults to None.
+ m_initial: The initial memory tensor of shape (batch_size, nh, 1). Defaults to None.
+ return_last_states: Whether to return the last states of the sequence. Defaults to None.
+ If None, the value from the config is used.
+
+ Returns:
+ hidden states of shape (batch_size, nh, sequence_length, dhhv)
+ hidden states and last states the last states are the cell state cstate (batch_size, nh, dhqk, dhhv),
+ the normalizer state nstate (batch_size, nh, dhqk), and the max state mstate (batch_size, nh, 1)
+ """
+ if mode is None:
+ mode = self.config.mode
+
+ if "train" in mode:
+ if return_last_states is None:
+ return_last_states = self.config.return_last_states
+
+ if self.config.mode == "train_with_padding":
+ if return_last_states:
+ raise ValueError("return_last_states=True is not supported with train_with_padding mode.")
+
+ return self._train_fn(
+ query=query,
+ key=key,
+ value=value,
+ igate=igate,
+ fgate=fgate,
+ c_initial=c_initial,
+ n_initial=n_initial,
+ m_initial=m_initial,
+ return_last_states=return_last_states,
+ )
+
+ elif "inference" in mode:
+ # inference mode always returns the last states
+ return self._inference_fn(
+ query=query,
+ key=key,
+ value=value,
+ igate=igate,
+ fgate=fgate,
+ c_initial=c_initial,
+ n_initial=n_initial,
+ m_initial=m_initial,
+ )
+ else:
+ raise ValueError(f"Unknown mode: {self.config.mode}")
+
+ def extra_repr(self) -> str:
+ return f"{self.config}"
+
+ class xLSTMRMSNorm(nn.Module):
+ """Root mean square normalization layer implementation similar
+ to https://pytorch.org/docs/stable/generated/torch.nn.RMSNorm.html.
+
+ It normalizes the input tensor by the root mean square of the last dimension.
+
+ Args:
+ num_features: The number of features in the input tensor.
+ eps: A small value to avoid division by zero.
+ use_weight: Whether to use a learnable weight.
+ use_bias: Whether to use a learnable bias.
+ force_float32_reductions: Whether to force float32 reductions.
+ """
+
+ def __init__(
+ self,
+ num_features: int,
+ eps: float = 1e-6,
+ use_weight: bool = True,
+ use_bias: bool = False,
+ force_float32_reductions: bool = True,
+ ):
+ super().__init__()
+ self.num_features = num_features
+ self.eps = eps
+ self.force_float32_reductions = force_float32_reductions
+
+ if use_weight:
+ self.weight = nn.Parameter(torch.ones(num_features))
+ else:
+ self.weight = None
+
+ if use_bias:
+ self.bias = nn.Parameter(torch.zeros(num_features))
+ else:
+ self.bias = None
+
+ def _apply_weight_bias(self, x: torch.Tensor) -> torch.Tensor:
+ if self.weight is not None:
+ x = x * self.weight
+ if self.bias is not None:
+ x = x + self.bias
+ return x
+
+ def _rms_normalize(self, x: torch.Tensor) -> torch.Tensor:
+ # apply rms norm over the last dimension, i.e. HD dimension
+ in_dtype = x.dtype
+ if self.force_float32_reductions:
+ x = x.float()
+ x = x * torch.rsqrt(x.pow(2).mean(dim=-1, keepdim=True) + self.eps)
+ return x.to(in_dtype)
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ x = self._rms_normalize(x)
+ x = self._apply_weight_bias(x)
+ return x
+
+ class xLSTMMultiHeadLayerNorm(nn.Module):
+ """Multi-head version of the LayerNorm layer.
+
+ It normalizes the last dimension of the input tensor.
+
+ The input is assumed to have the shape (batch_size, sequence_length, nh, DH), where:
+ batch_size: batch size
+ sequence_length: sequence length
+ nh: number of heads
+ DH: head dimension
+
+ The normalization is applied over the last dimension (DH) of the input tensor.
+
+ Args:
+ num_heads: The number of heads.
+ head_dim: The head dimension.
+ eps: A small value to avoid division by zero.
+ use_weight: Whether to use a learnable weight.
+ use_bias: Whether to use a learnable bias.
+ force_float32_reductions: Whether to force float32 reductions
+
+ Returns:
+ The normalized tensor with the shape (batch_size, sequence_length, nh * DH).
+ """
+
+ def __init__(
+ self,
+ num_heads: int,
+ head_dim: int,
+ eps: float = 1e-6,
+ use_weight: bool = True,
+ use_bias: bool = False,
+ force_float32_reductions: bool = True,
+ ):
+ super().__init__()
+ self.num_features = num_heads * head_dim
+ self.eps = eps
+ self.force_float32_reductions = force_float32_reductions
+
+ if use_weight:
+ self.weight = nn.Parameter(torch.ones(self.num_features))
+ else:
+ self.weight = None
+
+ if use_bias:
+ self.bias = nn.Parameter(torch.zeros(self.num_features))
+ else:
+ self.bias = None
+ self.num_heads = num_heads
+ self.head_dim = head_dim
+
+ def _apply_weight_bias(self, x: torch.Tensor) -> torch.Tensor:
+ if self.weight is not None:
+ x = x * self.weight
+ if self.bias is not None:
+ x = x + self.bias
+ return x
+
+ def _layer_normalize(self, x: torch.Tensor) -> torch.Tensor:
+ # apply layer norm over the last dimension, i.e. HD dimension
+ in_dtype = x.dtype
+ if self.force_float32_reductions:
+ x = x.float()
+ x_centered = x - x.mean(dim=-1, keepdim=True)
+ y = x_centered * torch.rsqrt(x.var(dim=-1, keepdim=True, unbiased=False) + self.eps)
+ return y.to(in_dtype)
+
+ def forward(
+ self,
+ x: torch.Tensor,
+ ) -> torch.Tensor:
+ batch_size, sequence_length, nh, DH = x.shape
+ if nh != self.num_heads:
+ raise ValueError(f"Expected {self.num_heads} heads, got {nh}, input shape: {x.shape}")
+ if DH != self.head_dim:
+ raise ValueError(f"Expected {self.head_dim} head dimension, got {DH}, input shape: {x.shape}")
+
+ x = self._layer_normalize(x)
+ x = x.reshape(batch_size, sequence_length, -1)
+ x = self._apply_weight_bias(x)
+ return x
+
+ class xLSTMFeedForward(nn.Module):
+ def __init__(self, config: xLSTMConfig):
+ super().__init__()
+ self.config = config
+
+ self.up_proj_dim = round_up_to_next_multiple_of(
+ config.hidden_size * config.ffn_proj_factor,
+ config.ffn_round_up_to_multiple_of,
+ )
+
+ if self.config.weight_mode == "single":
+ self.proj_up_gate = nn.Linear(
+ in_features=config.hidden_size,
+ out_features=self.up_proj_dim,
+ bias=self.config.use_bias,
+ )
+ self.proj_up = nn.Linear(
+ in_features=config.hidden_size,
+ out_features=self.up_proj_dim,
+ bias=self.config.use_bias,
+ )
+ elif self.config.weight_mode == "fused":
+ self.proj_up_gate_z = nn.Linear(
+ in_features=config.hidden_size,
+ out_features=2 * self.up_proj_dim,
+ bias=self.config.use_bias,
+ )
+
+ self.proj_down = nn.Linear(
+ in_features=self.up_proj_dim,
+ out_features=config.hidden_size,
+ bias=self.config.use_bias,
+ )
+
+ self.act_fn = nn.SiLU()
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ if self.config.weight_mode == "single":
+ x = self.act_fn(self.proj_up_gate(x)) * self.proj_up(x)
+ elif self.config.weight_mode == "fused":
+ x = self.proj_up_gate_z(x)
+ gate, z = torch.tensor_split(x, (self.up_proj_dim,), dim=-1)
+ x = self.act_fn(gate) * z
+
+ y = self.proj_down(x)
+ return y
+
+ class xLSTMLayer(nn.Module):
+ def __init__(self, config: xLSTMConfig):
+ super().__init__()
+ self.config = config
+
+ self.v_dim = int(config.hidden_size * config.v_dim_factor)
+ self.qk_dim = int(config.hidden_size * config.qk_dim_factor)
+
+ if self.config.weight_mode == "single":
+ self.q = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=self.qk_dim,
+ bias=self.config.use_bias,
+ )
+ self.k = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=self.qk_dim,
+ bias=self.config.use_bias,
+ )
+ self.v = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=self.v_dim,
+ bias=self.config.use_bias,
+ )
+
+ self.ogate_preact = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=self.v_dim,
+ bias=self.config.use_bias,
+ )
+ self.igate_preact = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=self.config.num_heads,
+ bias=True,
+ )
+ self.fgate_preact = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=self.config.num_heads,
+ bias=True,
+ )
+ elif self.config.weight_mode == "fused":
+ self.qkv_opreact = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=2 * self.qk_dim + 2 * self.v_dim,
+ bias=self.config.use_bias,
+ )
+ self.ifgate_preact = nn.Linear(
+ in_features=self.config.hidden_size,
+ out_features=2 * self.config.num_heads,
+ bias=True,
+ )
+
+ self.ogate_act_fn = nn.Sigmoid()
+ self.mlstm_backend = xLSTMBackend(config=self.config)
+
+ self.multihead_norm = xLSTMMultiHeadLayerNorm(
+ num_heads=self.config.num_heads,
+ head_dim=self.v_dim // self.config.num_heads,
+ eps=self.config.norm_eps,
+ use_weight=True,
+ use_bias=self.config.use_bias,
+ force_float32_reductions=self.config.norm_reduction_force_float32,
+ )
+ self.out_proj = nn.Linear(
+ in_features=self.v_dim,
+ out_features=self.config.hidden_size,
+ bias=self.config.use_bias,
+ )
+
+ def forward(
+ self, x: torch.Tensor, state: Optional[mLSTMLayerStateType] = None
+ ) -> tuple[torch.Tensor, Optional[mLSTMLayerStateType]]:
+ if x.ndim != 3:
+ raise ValueError(f"Input must have shape [batch_size, sequence_length, HD], got {x.shape}")
+ batch_size, sequence_length, _ = x.shape
+ if self.config.weight_mode == "single":
+ query = self.q(x)
+ key = self.k(x)
+ value = self.v(x)
+ o_preact = self.ogate_preact(x)
+ i_preact = soft_cap(self.igate_preact(x), cap_value=self.config.gate_soft_cap)
+ f_preact = soft_cap(self.fgate_preact(x), cap_value=self.config.gate_soft_cap)
+
+ elif self.config.weight_mode == "fused":
+ qkv_opreact = self.qkv_opreact(x)
+ query, key, value, o_preact = torch.tensor_split(
+ qkv_opreact,
+ (
+ self.qk_dim,
+ 2 * self.qk_dim,
+ 2 * self.qk_dim + self.v_dim,
+ ),
+ dim=-1,
+ )
+
+ if_preact = soft_cap(self.ifgate_preact(x), cap_value=self.config.gate_soft_cap)
+ i_preact, f_preact = torch.tensor_split(if_preact, (self.config.num_heads,), dim=-1)
+
+ query = query.reshape(batch_size, sequence_length, self.config.num_heads, -1).transpose(1, 2)
+ key = key.reshape(batch_size, sequence_length, self.config.num_heads, -1).transpose(1, 2)
+ value = value.reshape(batch_size, sequence_length, self.config.num_heads, -1).transpose(1, 2)
+ i_preact = i_preact.transpose(1, 2)
+ f_preact = f_preact.transpose(1, 2)
+ if state is None:
+ c_initial, n_initial, m_initial = None, None, None
+ else:
+ c_initial, n_initial, m_initial = state
+
+ h, state = self.mlstm_backend(
+ query=query,
+ key=key,
+ value=value,
+ igate=i_preact,
+ fgate=f_preact,
+ c_initial=c_initial,
+ n_initial=n_initial,
+ m_initial=m_initial,
+ )
+ expected_h_shape = (
+ batch_size,
+ self.config.num_heads,
+ sequence_length,
+ self.v_dim // self.config.num_heads,
+ )
+ if h.shape != expected_h_shape:
+ raise ValueError(f"Got {h.shape}, expected {expected_h_shape}")
+
+ h = h.transpose(1, 2)
+ h_norm = self.multihead_norm(h)
+ h_norm = h_norm.reshape(batch_size, sequence_length, -1)
+
+ h_out = self.ogate_act_fn(o_preact) * h_norm
+
+ y = self.out_proj(h_out)
+ return y, state
+
+ class xLSTMBlock(nn.Module):
+ def __init__(self, config: xLSTMConfig):
+ super().__init__()
+ self.config = config
+ self.norm_mlstm = xLSTMRMSNorm(
+ num_features=config.hidden_size,
+ eps=config.norm_eps,
+ use_weight=True,
+ use_bias=config.use_bias,
+ force_float32_reductions=config.norm_reduction_force_float32,
+ )
+ self.mlstm_layer = xLSTMLayer(config)
+ self.norm_ffn = xLSTMRMSNorm(
+ num_features=config.hidden_size,
+ eps=config.norm_eps,
+ use_weight=True,
+ use_bias=config.use_bias,
+ force_float32_reductions=config.norm_reduction_force_float32,
+ )
+ self.ffn = xLSTMFeedForward(config)
+
+ def forward(
+ self, x: torch.Tensor, state: Optional[mLSTMStateType] = None
+ ) -> tuple[torch.Tensor, mLSTMStateType]:
+ x_mlstm = self.norm_mlstm(x)
+ x_mlstm, state = self.mlstm_layer(x_mlstm, state)
+ x = x + x_mlstm
+
+ x_ffn = self.norm_ffn(x)
+ x_ffn = self.ffn(x_ffn)
+ x = x + x_ffn
+
+ return x, state
+
+
+def small_init_method(dim):
+ """
+ Adapted from: https://github.com/EleutherAI/gpt-neox/blob/main/megatron/model/init_functions.py
+ Fills the input Tensor with values according to the method described in Transformers without Tears: Improving
+ the Normalization of Self-Attention - Nguyen, T. & Salazar, J. (2019), using a normal distribution."""
+ std = (2 / (5 * dim)) ** (1 / 2)
+
+ def init_(tensor):
+ return torch.nn.init.normal_(tensor, mean=0.0, std=std)
+
+ return init_
+
+
+def wang_init_method(n_layers, dim):
+ """
+ Adapted from https://github.com/EleutherAI/gpt-neox/blob/main/megatron/model/init_functions.py
+ """
+ std = 2 / n_layers / dim ** (1 / 2)
+
+ def init_(tensor):
+ return torch.nn.init.normal_(tensor, mean=0.0, std=std)
+
+ return init_
+
+
+class xLSTMPreTrainedModel(PreTrainedModel):
+ """
+ An abstract class for an interface to loading a pre-trained xLSTM model.
+ """
+
+ config_class = xLSTMConfig
+ base_model_prefix = "backbone"
+ _no_split_modules = ["xLSTMBlock"]
+ supports_gradient_checkpointing = True
+ _is_stateful = True
+
+ def _module_name_map(self, module):
+ for name, mod in self.named_modules():
+ if mod is module:
+ return name
+ return ""
+
+ def _init_weights(self, module):
+ if isinstance(module, nn.Embedding):
+ small_init_method(self.config.hidden_size)(self.embeddings.weight)
+ elif isinstance(module, nn.Linear):
+ if module.bias is not None:
+ torch.nn.init.zeros_(module.bias)
+ if self.config.weight_mode == "single" and "gate" in self._module_name_map(module):
+ torch.nn.init.zeros_(module.weight)
+ with torch.no_grad():
+ if "igate" in self._module_name_map(module):
+ module.bias.copy_(-10.0 * torch.ones_like(module.bias))
+ elif "fgate" in self._module_name_map(module):
+ module.bias.copy_(
+ torch.linspace(
+ 3.0,
+ 6.0,
+ module.bias.shape[-1],
+ ).to(
+ device=module.bias.device,
+ dtype=module.bias.dtype,
+ )
+ )
+ elif self.config.weight_mode == "fused" and "gate" in self._module_name_map(module):
+ torch.nn.init.zeros_(module.weight)
+ with torch.no_grad():
+ module.bias[: self.config.num_heads] += -module.bias[
+ : self.config.num_heads
+ ] - 10.0 * torch.ones_like(module.bias)
+ module.bias[: self.config.num_heads] += -module.bias[self.config.num_heads :] + torch.linspace(
+ 3.0,
+ 6.0,
+ module.bias.shape[-1],
+ ).to(
+ device=module.bias.device,
+ dtype=module.bias.dtype,
+ )
+ elif "proj_down" in self._module_name_map(module):
+ wang_init_method(dim=module.weight.shape[1], n_layers=self.config.num_hidden_layers)(module.weight)
+ elif "out_proj" in self._module_name_map(module):
+ wang_init_method(dim=self.config.hidden_size, n_layers=self.config.num_hidden_layers)(module.weight)
+ elif module.weight is not None:
+ small_init_method(self.config.hidden_size)(module.weight)
+ elif isinstance(module, xLSTMRMSNorm) or hasattr(module, "_layer_normalize"):
+ torch.nn.init.ones_(module.weight)
+ if hasattr(module, "bias") and module.bias is not None:
+ torch.nn.init.zeros_(module.bias)
+
+
+class xLSTMCache:
+ """
+ Cache for xLSTM model which does not have attention mechanism and key value states.
+
+ Arguments:
+ config (`PretrainedConfig):
+ The configuration file defining the shape-related attributes required to initialize the static cache.
+ max_batch_size (`int`):
+ The batch size with which the model will be used.
+ dtype (`torch.dtype`, *optional*, defaults to `torch.bfloat16`):
+ The default `dtype` to use when initializing the layer.
+ device (`torch.device` or `str`, *optional*):
+ The device on which the cache should be initialized. Should be the same as the layer.
+
+ Attributes:
+ seqlen_offset: int
+ dtype: torch.dtype
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, xLSTMForCausalLM, xLSTMCache
+
+ >>> model = xLSTMForCausalLM.from_pretrained("NX-AI/xLSTM-7b")
+ >>> tokenizer = xLSTMTokenizer.from_pretrained("NX-AI/xLSTM-7b")
+
+ >>> inputs = tokenizer(text="I am an xLSTM", return_tensors="pt")
+
+ >>> # Prepare a cache class and pass it to model's forward
+ >>> cache_params = xLSTMCache(config=model.config, max_batch_size=1, device=model.device, dtype=model.dtype)
+ >>> outputs = model(**inputs, cache_params=cache_params, use_cache=True)
+ >>> outputs.cache_params
+ xLSTMCache()
+ """
+
+ def __init__(
+ self,
+ config: xLSTMConfig,
+ max_batch_size: int,
+ dtype: torch.dtype = torch.bfloat16,
+ device: Optional[str] = None,
+ **kwargs,
+ ):
+ self.seqlen_offset = 0
+ self.dtype = dtype
+ self.config = config
+ self.rnn_state = {
+ layer: (
+ torch.zeros(
+ [max_batch_size, config.num_heads, config.qk_head_dim, config.v_head_dim],
+ dtype=dtype,
+ device=device,
+ ),
+ torch.zeros([max_batch_size, config.num_heads, config.qk_head_dim], dtype=dtype, device=device),
+ torch.zeros([max_batch_size, config.num_heads, 1], dtype=dtype, device=device),
+ )
+ for layer in range(config.num_hidden_layers)
+ }
+
+ def reset(self):
+ self.rnn_state = {
+ layer: (
+ torch.zeros_like(self.rnn_state[layer][0]),
+ torch.zeros_like(self.rnn_state[layer][1]),
+ torch.zeros_like(self.rnn_state[layer][2]),
+ )
+ for layer in self.rnn_state
+ }
+
+
+@dataclass
+@auto_docstring
+class xLSTMOutput(ModelOutput):
+ r"""
+ cache_params (`xLSTMCache`):
+ The state of the model at the last time step. Can be used in a forward method with the next `input_ids` to
+ avoid providing the old `input_ids`.
+ """
+
+ last_hidden_state: Optional[torch.FloatTensor]
+ cache_params: Optional[xLSTMCache] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+
+
+@auto_docstring
+class xLSTMModel(xLSTMPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ # use embbeding_dim and num_blocks once here to make use of them
+ self.embeddings = nn.Embedding(config.vocab_size, config.embedding_dim)
+ self.blocks = nn.ModuleList([xLSTMBlock(config) for _ in range(config.num_blocks)])
+ self.out_norm = xLSTMRMSNorm(config.hidden_size, eps=config.norm_eps)
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings
+
+ def set_input_embeddings(self, new_embedding):
+ self.embeddings = new_embedding
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.LongTensor] = None,
+ cache_params: Optional[xLSTMCache] = None,
+ use_cache: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[tuple, xLSTMOutput]:
+ r"""
+ cache_params (`xLSTMCache`, *optional*):
+ The xLSTMCache that carries the RNN states.
+ """
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else (self.config.use_cache if not self.training else False)
+ if self.gradient_checkpointing and self.training and use_cache:
+ use_cache = False
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError("You must specify exactly one of input_ids or inputs_embeds")
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embeddings(input_ids)
+
+ if use_cache and cache_params is None:
+ cache_params = xLSTMCache(
+ self.config, inputs_embeds.size(0), device=inputs_embeds.device, dtype=inputs_embeds.dtype
+ )
+
+ hidden_states = inputs_embeds
+
+ if (
+ not self.training
+ and self.config.max_inference_chunksize < hidden_states.shape[1]
+ and not output_hidden_states
+ ):
+ offset = 0
+ with torch.no_grad():
+ if cache_params is None:
+ cache_params = xLSTMCache(config=self.config, max_batch_size=hidden_states.shape[0])
+ final_state = torch.zeros_like(hidden_states)
+ while offset < hidden_states.shape[1]:
+ hidden_states_chunk = hidden_states[
+ :, offset : min(offset + self.config.max_inference_chunksize, hidden_states.shape[1])
+ ]
+ for layer_idx, xlstm_block in enumerate(self.blocks):
+ hidden_states_chunk, rnn_state = xlstm_block(
+ hidden_states_chunk,
+ state=cache_params.rnn_state[layer_idx],
+ )
+ for state_idx in range(len(cache_params.rnn_state[layer_idx])):
+ local_rnn_state = rnn_state[state_idx]
+ cache_params.rnn_state[layer_idx][state_idx].copy_(local_rnn_state)
+ cache_params.rnn_state_initial = False
+ final_state[
+ :, offset : min(offset + self.config.max_inference_chunksize, hidden_states.shape[1])
+ ] = hidden_states_chunk
+ offset += self.config.max_inference_chunksize
+ hidden_states = final_state
+ else:
+ all_hidden_states = () if output_hidden_states else None
+ for layer_idx, xlstm_block in enumerate(self.blocks):
+ if self.gradient_checkpointing and self.training:
+ hidden_states, rnn_state = self._gradient_checkpointing_func(
+ xlstm_block.__call__,
+ hidden_states,
+ cache_params.rnn_state[layer_idx] if cache_params is not None else None,
+ )
+ else:
+ hidden_states, rnn_state = xlstm_block(
+ hidden_states,
+ state=cache_params.rnn_state[layer_idx] if cache_params is not None else None,
+ )
+ if cache_params:
+ for state_idx in range(len(cache_params.rnn_state[layer_idx])):
+ local_rnn_state = rnn_state[state_idx]
+ cache_params.rnn_state[layer_idx][state_idx].copy_(local_rnn_state)
+ cache_params.rnn_state_initial = False
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if use_cache:
+ cache_params.seqlen_offset += inputs_embeds.shape[1]
+
+ hidden_states = self.out_norm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ return xLSTMOutput(
+ last_hidden_state=hidden_states,
+ cache_params=cache_params,
+ hidden_states=all_hidden_states,
+ )
+
+
+@dataclass
+@auto_docstring
+class xLSTMCausalLMOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Language modeling loss (for next-token prediction).
+ logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`):
+ Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
+ cache_params (`xLSTMCache`, *optional*, carrying the RNN states):
+ The state of the model at the last time step. Can be used in a forward method with the next `input_ids` to
+ avoid providing the old `input_ids`.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ logits: Optional[torch.FloatTensor] = None
+ cache_params: Optional[xLSTMCache] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+
+
+@auto_docstring
+class xLSTMForCausalLM(xLSTMPreTrainedModel, GenerationMixin):
+ def __init__(self, config):
+ super().__init__(config)
+ self.backbone = xLSTMModel(config)
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.lm_head
+
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head = new_embeddings
+
+ def get_input_embeddings(self):
+ return self.backbone.get_input_embeddings()
+
+ def set_input_embeddings(self, new_embeddings):
+ return self.backbone.set_input_embeddings(new_embeddings)
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ attention_mask=None, # not used but needed, otherwise generate complains when passing tokenizer inputs
+ inputs_embeds=None,
+ use_cache=None,
+ cache_params: Optional[xLSTMCache] = None,
+ **kwargs,
+ ):
+ if use_cache and cache_params is not None:
+ # If the first cache position is non-zero, we assume we are in generation mode.
+ # Thus, the cache_params state is assumed to be the state before the last token
+ # (lastly generated token), and all previous tokens are already ingested.
+ # This should as well support generation from scratch with the [BOS] token inserted first.
+ input_ids = input_ids[:, -1:]
+ if inputs_embeds is not None:
+ inputs_embeds = inputs_embeds[:, -1:]
+
+ if inputs_embeds is not None and cache_params is None:
+ model_inputs = {"inputs_embeds": inputs_embeds}
+ else:
+ model_inputs = {"input_ids": input_ids}
+
+ model_inputs.update({"cache_params": cache_params, "use_cache": use_cache})
+ return model_inputs
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ cache_params: Optional[xLSTMCache] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ **kwargs,
+ ) -> Union[tuple, xLSTMCausalLMOutput]:
+ r"""
+ cache_params (`xLSTMCache`, *optional*):
+ The xLSTMCache that carries the RNN states.
+ """
+ xlstm_outputs = self.backbone(
+ input_ids,
+ cache_params=cache_params,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_hidden_states=output_hidden_states,
+ **kwargs,
+ )
+ hidden_states = xlstm_outputs[0]
+
+ logits = self.lm_head(hidden_states.to(self.lm_head.weight.dtype)).float()
+
+ if not self.training and self.config.max_inference_chunksize < logits.shape[1]:
+ offset = 0
+ with torch.no_grad():
+ while offset < logits.shape[1]:
+ logits[:, offset : min(offset + self.config.max_inference_chunksize, logits.shape[1])] = soft_cap(
+ logits[:, offset : min(offset + self.config.max_inference_chunksize, logits.shape[1])],
+ self.config.output_logit_soft_cap,
+ )
+ offset += self.config.max_inference_chunksize
+ else:
+ logits = soft_cap(logits, self.config.output_logit_soft_cap)
+
+ loss = None
+ if labels is not None:
+ # move labels to correct device to enable model parallelism
+ labels = labels.to(logits.device)
+ # Shift so that tokens < nstate predict nstate
+ shift_logits = logits[..., :-1, :].contiguous()
+ shift_labels = labels[..., 1:].contiguous()
+ # Flatten the tokens
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(shift_logits.view(-1, shift_logits.size(-1)), shift_labels.view(-1))
+
+ return xLSTMCausalLMOutput(
+ loss=loss,
+ logits=logits,
+ cache_params=xlstm_outputs.cache_params,
+ hidden_states=xlstm_outputs.hidden_states,
+ )
+
+
+__all__ = [
+ "xLSTMForCausalLM",
+ "xLSTMModel",
+ "xLSTMPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..13cf20cbe49cbafadbcaa3b8aa8eba9d34238f14
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_xmod import *
+ from .modeling_xmod import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/configuration_xmod.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/configuration_xmod.py
new file mode 100644
index 0000000000000000000000000000000000000000..41bad38a45deab92598a7af4b198031c4674505c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/configuration_xmod.py
@@ -0,0 +1,185 @@
+# coding=utf-8
+# Copyright 2023 The Meta AI Team Authors and The HuggingFace Inc. team.
+# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""X-MOD configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class XmodConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`XmodModel`]. It is used to instantiate an X-MOD
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the
+ [facebook/xmod-base](https://huggingface.co/facebook/xmod-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 30522):
+ Vocabulary size of the X-MOD model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`XmodModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"silu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the `token_type_ids` passed when calling [`XmodModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ position_embedding_type (`str`, *optional*, defaults to `"absolute"`):
+ Type of position embedding. Choose one of `"absolute"`, `"relative_key"`, `"relative_key_query"`. For
+ positional embeddings use `"absolute"`. For more information on `"relative_key"`, please refer to
+ [Self-Attention with Relative Position Representations (Shaw et al.)](https://huggingface.co/papers/1803.02155).
+ For more information on `"relative_key_query"`, please refer to *Method 4* in [Improve Transformer Models
+ with Better Relative Position Embeddings (Huang et al.)](https://huggingface.co/papers/2009.13658).
+ is_decoder (`bool`, *optional*, defaults to `False`):
+ Whether the model is used as a decoder or not. If `False`, the model is used as an encoder.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ classifier_dropout (`float`, *optional*):
+ The dropout ratio for the classification head.
+ pre_norm (`bool`, *optional*, defaults to `False`):
+ Whether to apply layer normalization before each block.
+ adapter_reduction_factor (`int` or `float`, *optional*, defaults to 2):
+ The factor by which the dimensionality of the adapter is reduced relative to `hidden_size`.
+ adapter_layer_norm (`bool`, *optional*, defaults to `False`):
+ Whether to apply a new layer normalization before the adapter modules (shared across all adapters).
+ adapter_reuse_layer_norm (`bool`, *optional*, defaults to `True`):
+ Whether to reuse the second layer normalization and apply it before the adapter modules as well.
+ ln_before_adapter (`bool`, *optional*, defaults to `True`):
+ Whether to apply the layer normalization before the residual connection around the adapter module.
+ languages (`Iterable[str]`, *optional*, defaults to `["en_XX"]`):
+ An iterable of language codes for which adapter modules should be initialized.
+ default_language (`str`, *optional*):
+ Language code of a default language. It will be assumed that the input is in this language if no language
+ codes are explicitly passed to the forward method.
+
+ Examples:
+
+ ```python
+ >>> from transformers import XmodConfig, XmodModel
+
+ >>> # Initializing an X-MOD facebook/xmod-base style configuration
+ >>> configuration = XmodConfig()
+
+ >>> # Initializing a model (with random weights) from the facebook/xmod-base style configuration
+ >>> model = XmodModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "xmod"
+
+ def __init__(
+ self,
+ vocab_size=30522,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=512,
+ type_vocab_size=2,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ position_embedding_type="absolute",
+ use_cache=True,
+ classifier_dropout=None,
+ pre_norm=False,
+ adapter_reduction_factor=2,
+ adapter_layer_norm=False,
+ adapter_reuse_layer_norm=True,
+ ln_before_adapter=True,
+ languages=("en_XX",),
+ default_language=None,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.hidden_act = hidden_act
+ self.intermediate_size = intermediate_size
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.max_position_embeddings = max_position_embeddings
+ self.type_vocab_size = type_vocab_size
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.position_embedding_type = position_embedding_type
+ self.use_cache = use_cache
+ self.classifier_dropout = classifier_dropout
+ self.pre_norm = pre_norm
+ self.adapter_reduction_factor = adapter_reduction_factor
+ self.adapter_layer_norm = adapter_layer_norm
+ self.adapter_reuse_layer_norm = adapter_reuse_layer_norm
+ self.ln_before_adapter = ln_before_adapter
+ self.languages = list(languages)
+ self.default_language = default_language
+
+
+# Copied from transformers.models.roberta.configuration_roberta.RobertaOnnxConfig with Roberta->Xmod
+class XmodOnnxConfig(OnnxConfig):
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ if self.task == "multiple-choice":
+ dynamic_axis = {0: "batch", 1: "choice", 2: "sequence"}
+ else:
+ dynamic_axis = {0: "batch", 1: "sequence"}
+ return OrderedDict(
+ [
+ ("input_ids", dynamic_axis),
+ ("attention_mask", dynamic_axis),
+ ]
+ )
+
+
+__all__ = ["XmodConfig", "XmodOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/modeling_xmod.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/modeling_xmod.py
new file mode 100644
index 0000000000000000000000000000000000000000..7ddf15bdb5963a3e5631bd02256704e7d48cba3e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/xmod/modeling_xmod.py
@@ -0,0 +1,1517 @@
+# coding=utf-8
+# Copyright 2023 Meta AI Team and the HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch X-MOD model."""
+
+import math
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN, gelu
+from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache
+from ...generation import GenerationMixin
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutputWithPastAndCrossAttentions,
+ BaseModelOutputWithPoolingAndCrossAttentions,
+ CausalLMOutputWithCrossAttentions,
+ MaskedLMOutput,
+ MultipleChoiceModelOutput,
+ QuestionAnsweringModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from .configuration_xmod import XmodConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaEmbeddings with Roberta->Xmod
+class XmodEmbeddings(nn.Module):
+ """
+ Same as BertEmbeddings with a tiny tweak for positional embeddings indexing.
+ """
+
+ # Copied from transformers.models.bert.modeling_bert.BertEmbeddings.__init__
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False
+ )
+ self.register_buffer(
+ "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False
+ )
+
+ # End copy
+ self.padding_idx = config.pad_token_id
+ self.position_embeddings = nn.Embedding(
+ config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx
+ )
+
+ def forward(
+ self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None, past_key_values_length=0
+ ):
+ if position_ids is None:
+ if input_ids is not None:
+ # Create the position ids from the input token ids. Any padded tokens remain padded.
+ position_ids = create_position_ids_from_input_ids(input_ids, self.padding_idx, past_key_values_length)
+ else:
+ position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds)
+
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs
+ # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves
+ # issue #5664
+ if token_type_ids is None:
+ if hasattr(self, "token_type_ids"):
+ buffered_token_type_ids = self.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(input_shape[0], seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+ def create_position_ids_from_inputs_embeds(self, inputs_embeds):
+ """
+ We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids.
+
+ Args:
+ inputs_embeds: torch.Tensor
+
+ Returns: torch.Tensor
+ """
+ input_shape = inputs_embeds.size()[:-1]
+ sequence_length = input_shape[1]
+
+ position_ids = torch.arange(
+ self.padding_idx + 1, sequence_length + self.padding_idx + 1, dtype=torch.long, device=inputs_embeds.device
+ )
+ return position_ids.unsqueeze(0).expand(input_shape)
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaSelfAttention with Roberta->Xmod
+class XmodSelfAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.position_embedding_type = position_embedding_type or getattr(
+ config, "position_embedding_type", "absolute"
+ )
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ self.max_position_embeddings = config.max_position_embeddings
+ self.distance_embedding = nn.Embedding(2 * config.max_position_embeddings - 1, self.attention_head_size)
+
+ self.is_decoder = config.is_decoder
+ self.layer_idx = layer_idx
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = self.query(hidden_states)
+ query_layer = query_layer.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(
+ 1, 2
+ )
+
+ is_cross_attention = encoder_hidden_states is not None
+ if past_key_values is not None:
+ if isinstance(past_key_values, EncoderDecoderCache):
+ is_updated = past_key_values.is_updated.get(self.layer_idx)
+ if is_cross_attention:
+ # after the first generated id, we can subsequently re-use all key/value_layer from cache
+ curr_past_key_value = past_key_values.cross_attention_cache
+ else:
+ curr_past_key_value = past_key_values.self_attention_cache
+ else:
+ curr_past_key_value = past_key_values
+
+ current_states = encoder_hidden_states if is_cross_attention else hidden_states
+ if is_cross_attention and past_key_values is not None and is_updated:
+ # reuse k,v, cross_attentions
+ key_layer = curr_past_key_value.layers[self.layer_idx].keys
+ value_layer = curr_past_key_value.layers[self.layer_idx].values
+ else:
+ key_layer = self.key(current_states)
+ key_layer = key_layer.view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(
+ 1, 2
+ )
+ value_layer = self.value(current_states)
+ value_layer = value_layer.view(
+ batch_size, -1, self.num_attention_heads, self.attention_head_size
+ ).transpose(1, 2)
+
+ if past_key_values is not None:
+ # save all key/value_layer to cache to be re-used for fast auto-regressive generation
+ cache_position = cache_position if not is_cross_attention else None
+ key_layer, value_layer = curr_past_key_value.update(
+ key_layer, value_layer, self.layer_idx, {"cache_position": cache_position}
+ )
+ # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls
+ if is_cross_attention:
+ past_key_values.is_updated[self.layer_idx] = True
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ if self.position_embedding_type == "relative_key" or self.position_embedding_type == "relative_key_query":
+ query_length, key_length = query_layer.shape[2], key_layer.shape[2]
+ if past_key_values is not None:
+ position_ids_l = torch.tensor(key_length - 1, dtype=torch.long, device=hidden_states.device).view(
+ -1, 1
+ )
+ else:
+ position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1)
+ position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1)
+ distance = position_ids_l - position_ids_r
+
+ positional_embedding = self.distance_embedding(distance + self.max_position_embeddings - 1)
+ positional_embedding = positional_embedding.to(dtype=query_layer.dtype) # fp16 compatibility
+
+ if self.position_embedding_type == "relative_key":
+ relative_position_scores = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores
+ elif self.position_embedding_type == "relative_key_query":
+ relative_position_scores_query = torch.einsum("bhld,lrd->bhlr", query_layer, positional_embedding)
+ relative_position_scores_key = torch.einsum("bhrd,lrd->bhlr", key_layer, positional_embedding)
+ attention_scores = attention_scores + relative_position_scores_query + relative_position_scores_key
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in XmodModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ # Mask heads if we want to
+ if head_mask is not None:
+ attention_probs = attention_probs * head_mask
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+class XmodSelfOutput(nn.Module):
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaSelfOutput.__init__
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+class XmodAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None, layer_idx=None):
+ super().__init__()
+ self.self = XmodSelfAttention(config, position_embedding_type=position_embedding_type, layer_idx=layer_idx)
+ self.output = XmodSelfOutput(config)
+ self.pruned_heads = set()
+ self.pre_norm = config.pre_norm
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaAttention.prune_heads
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ residual = hidden_states
+ if self.pre_norm:
+ hidden_states = self.output.LayerNorm(hidden_states)
+ self_outputs = self.self(
+ hidden_states,
+ attention_mask,
+ head_mask,
+ encoder_hidden_states,
+ past_key_values,
+ output_attentions,
+ cache_position,
+ )
+ attention_output = self.output(self_outputs[0], residual)
+ if not self.pre_norm:
+ attention_output = self.output.LayerNorm(attention_output)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaIntermediate
+class XmodIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+class XmodAdapter(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.bottleneck_size = config.hidden_size // config.adapter_reduction_factor
+ self.dense1 = nn.Linear(config.hidden_size, self.bottleneck_size)
+ self.dense2 = nn.Linear(self.bottleneck_size, config.hidden_size)
+ if isinstance(config.hidden_act, str):
+ self.adapter_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.adapter_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense1(hidden_states)
+ hidden_states = self.adapter_act_fn(hidden_states)
+ hidden_states = self.dense2(hidden_states)
+ return hidden_states
+
+
+class XmodOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.ln_before_adapter = config.ln_before_adapter
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ if config.adapter_layer_norm:
+ self.adapter_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ else:
+ self.adapter_layer_norm = None
+ self.adapter_reuse_layer_norm = config.adapter_reuse_layer_norm
+ self.adapter_modules = nn.ModuleDict({})
+ for language in config.languages:
+ self.adapter_modules[str(language)] = XmodAdapter(config)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor, lang_ids: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ hidden_states = self.lang_adapter(lang_ids, hidden_states)
+ return hidden_states
+
+ def lang_adapter(self, lang_ids: torch.Tensor, hidden_states: torch.Tensor):
+ # Process subsequent samples with the same lang_id in parallel
+ lang_ids, lang_lengths = torch.unique_consecutive(lang_ids, return_counts=True)
+
+ if not self.ln_before_adapter:
+ residual = hidden_states
+
+ if self.adapter_layer_norm is not None:
+ hidden_states = self.adapter_layer_norm(hidden_states)
+ elif self.adapter_reuse_layer_norm:
+ hidden_states = self.LayerNorm(hidden_states)
+
+ if self.ln_before_adapter:
+ residual = hidden_states
+
+ split_hidden_states = torch.split(hidden_states, lang_lengths.tolist(), 0)
+ lang_wise_outputs = []
+ for i, (lang_id, split_hidden_state) in enumerate(zip(lang_ids, split_hidden_states)):
+ lang = list(self.adapter_modules.keys())[int(lang_id.item())]
+ lang_wise_outputs.append(self.adapter_modules[lang](split_hidden_state))
+ hidden_states = torch.cat(lang_wise_outputs, 0)
+
+ hidden_states = self.dropout(hidden_states)
+ hidden_states += residual
+ return hidden_states
+
+
+class XmodLayer(GradientCheckpointingLayer):
+ def __init__(self, config, layer_idx=None):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = XmodAttention(config, layer_idx=layer_idx)
+ self.is_decoder = config.is_decoder
+ self.add_cross_attention = config.add_cross_attention
+ if self.add_cross_attention:
+ if not self.is_decoder:
+ raise ValueError(f"{self} should be used as a decoder model if cross attention is added")
+ self.crossattention = XmodAttention(config, position_embedding_type="absolute", layer_idx=layer_idx)
+ self.intermediate = XmodIntermediate(config)
+ self.output = XmodOutput(config)
+ self.pre_norm = config.pre_norm
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ lang_ids: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[Cache] = None,
+ output_attentions: Optional[bool] = False,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> tuple[torch.Tensor]:
+ self_attention_outputs = self.attention(
+ hidden_states,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ past_key_values=past_key_values,
+ cache_position=cache_position,
+ )
+ attention_output = self_attention_outputs[0]
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ if self.is_decoder and encoder_hidden_states is not None:
+ if not hasattr(self, "crossattention"):
+ raise ValueError(
+ f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers"
+ " by setting `config.add_cross_attention=True`"
+ )
+
+ cross_attention_outputs = self.crossattention(
+ attention_output,
+ attention_mask=encoder_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ cache_position=cache_position,
+ )
+ attention_output = cross_attention_outputs[0]
+ outputs = outputs + cross_attention_outputs[1:] # add cross attentions if we output attention weights
+
+ residual = attention_output
+ if self.pre_norm:
+ attention_output = self.output.LayerNorm(attention_output)
+ intermediate_output = apply_chunking_to_forward(
+ self.feed_forward_chunk,
+ self.chunk_size_feed_forward,
+ self.seq_len_dim,
+ attention_output,
+ )
+ layer_output = self.output(intermediate_output, residual, lang_ids)
+ if not self.pre_norm:
+ layer_output = self.output.LayerNorm(layer_output)
+ return (layer_output,) + outputs
+
+ def feed_forward_chunk(self, attention_output):
+ return self.intermediate(attention_output)
+
+
+class XmodEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([XmodLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)])
+ self.is_pre_norm = config.pre_norm
+ if self.is_pre_norm:
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ lang_ids: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = False,
+ output_hidden_states: Optional[bool] = False,
+ return_dict: Optional[bool] = True,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutputWithPastAndCrossAttentions]:
+ if self.gradient_checkpointing and self.training:
+ if use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..."
+ )
+ use_cache = False
+
+ if use_cache and past_key_values is None:
+ past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config))
+ if use_cache and isinstance(past_key_values, tuple):
+ logger.warning_once(
+ "Passing a tuple of `past_key_values` is deprecated and will be removed in Transformers v4.58.0. "
+ "You should pass an instance of `EncoderDecoderCache` instead, e.g. "
+ "`past_key_values=EncoderDecoderCache.from_legacy_cache(past_key_values)`."
+ )
+ past_key_values = EncoderDecoderCache.from_legacy_cache(past_key_values)
+
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+ all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+
+ layer_outputs = layer_module(
+ hidden_states,
+ lang_ids,
+ attention_mask,
+ layer_head_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ past_key_values,
+ output_attentions,
+ cache_position,
+ )
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+ if self.config.add_cross_attention:
+ all_cross_attentions = all_cross_attentions + (layer_outputs[2],)
+
+ if self.is_pre_norm:
+ hidden_states = self.LayerNorm(hidden_states)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(
+ v
+ for v in [
+ hidden_states,
+ past_key_values,
+ all_hidden_states,
+ all_self_attentions,
+ all_cross_attentions,
+ ]
+ if v is not None
+ )
+ return BaseModelOutputWithPastAndCrossAttentions(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ cross_attentions=all_cross_attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaPooler
+class XmodPooler(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+@auto_docstring
+class XmodPreTrainedModel(PreTrainedModel):
+ config: XmodConfig
+ base_model_prefix = "roberta"
+ supports_gradient_checkpointing = True
+
+ # Copied from transformers.models.bert.modeling_bert.BertPreTrainedModel._init_weights with BertLMPredictionHead->XmodLMHead
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, XmodLMHead):
+ module.bias.data.zero_()
+
+ def set_default_language(self, language: str):
+ """
+ Set the default language code for the model. This is used when the language is not specified in the input.
+
+ Args:
+ language (`str`): The language code, such as `"en_XX"` or `"de_DE"`.
+ """
+ if language not in self.config.languages:
+ raise ValueError(
+ f"{self} does not have an adapter for {language}. Supported languages: {list(self.config.languages)}"
+ )
+ self.config.default_language = language
+
+ def freeze_embeddings_and_language_adapters(self):
+ """
+ Freeze the embeddings and language adapters of the model. Usually, this is applied before the model is
+ fine-tuned on a downstream task.
+ """
+ logger.info("Freezing embeddings")
+ for parameter in self.roberta.embeddings.parameters():
+ parameter.requires_grad = False
+ logger.info("Freezing adapters")
+ for layer in self.roberta.encoder.layer:
+ if layer.output.adapter_layer_norm is not None:
+ for parameter in layer.output.adapter_layer_norm.parameters():
+ parameter.requires_grad = False
+ for parameter in layer.output.adapter_modules.parameters():
+ parameter.requires_grad = False
+
+
+@auto_docstring(
+ custom_intro="""
+ The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of
+ cross-attention is added between the self-attention layers, following the architecture described in *Attention is
+ all you need*_ by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz
+ Kaiser and Illia Polosukhin.
+
+ To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set
+ to `True`. To be used in a Seq2Seq model, the model needs to initialized with both `is_decoder` argument and
+ `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass.
+
+ .. _*Attention is all you need*: https://huggingface.co/papers/1706.03762
+ """
+)
+class XmodModel(XmodPreTrainedModel):
+ # Copied from transformers.models.clap.modeling_clap.ClapTextModel.__init__ with ClapText->Xmod
+ def __init__(self, config, add_pooling_layer=True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = XmodEmbeddings(config)
+ self.encoder = XmodEncoder(config)
+
+ self.pooler = XmodPooler(config) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaModel.get_input_embeddings
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaModel.set_input_embeddings
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaModel._prune_heads
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ lang_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[list[torch.FloatTensor]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ ) -> Union[tuple[torch.Tensor], BaseModelOutputWithPoolingAndCrossAttentions]:
+ r"""
+ lang_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of the language adapters that should be activated for each sample, respectively. Default: the index
+ that corresponds to `self.config.default_language`.
+ """
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if self.config.is_decoder:
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+ else:
+ use_cache = False
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ past_key_values_length = 0
+ if past_key_values is not None:
+ past_key_values_length = (
+ past_key_values[0][0].shape[-2]
+ if not isinstance(past_key_values, Cache)
+ else past_key_values.get_seq_length()
+ )
+
+ if lang_ids is None:
+ if self.config.default_language is None:
+ raise ValueError("Input language unknown. Please call `XmodPreTrainedModel.set_default_language()`")
+ adapter_languages = list(self.encoder.layer[0].output.adapter_modules.keys())
+ default_lang_id = adapter_languages.index(self.config.default_language)
+ lang_ids = default_lang_id * torch.ones(batch_size, device=device)
+
+ if attention_mask is None:
+ attention_mask = torch.ones(((batch_size, seq_length + past_key_values_length)), device=device)
+
+ if token_type_ids is None:
+ if hasattr(self.embeddings, "token_type_ids"):
+ buffered_token_type_ids = self.embeddings.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(batch_size, seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
+ # ourselves in which case we just need to make it broadcastable to all heads.
+ extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape)
+
+ # If a 2D or 3D attention mask is provided for the cross-attention
+ # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
+ if self.config.is_decoder and encoder_hidden_states is not None:
+ encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
+ encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
+ if encoder_attention_mask is None:
+ encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
+ encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
+ else:
+ encoder_extended_attention_mask = None
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ past_key_values_length=past_key_values_length,
+ )
+ encoder_outputs = self.encoder(
+ embedding_output,
+ lang_ids=lang_ids,
+ attention_mask=extended_attention_mask,
+ head_mask=head_mask,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_extended_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+ sequence_output = encoder_outputs[0]
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ if not return_dict:
+ return (sequence_output, pooled_output) + encoder_outputs[1:]
+
+ return BaseModelOutputWithPoolingAndCrossAttentions(
+ last_hidden_state=sequence_output,
+ pooler_output=pooled_output,
+ past_key_values=encoder_outputs.past_key_values,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ cross_attentions=encoder_outputs.cross_attentions,
+ )
+
+
+@auto_docstring(
+ custom_intro="""
+ X-MOD Model with a `language modeling` head on top for CLM fine-tuning.
+ """
+)
+class XmodForCausalLM(XmodPreTrainedModel, GenerationMixin):
+ _tied_weights_keys = ["lm_head.decoder.weight", "lm_head.decoder.bias"]
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForCausalLM.__init__ with Roberta->Xmod
+ def __init__(self, config):
+ super().__init__(config)
+
+ if not config.is_decoder:
+ logger.warning("If you want to use `XmodLMHeadModel` as a standalone, add `is_decoder=True.`")
+
+ self.roberta = XmodModel(config, add_pooling_layer=False)
+ self.lm_head = XmodLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForCausalLM.get_output_embeddings
+ def get_output_embeddings(self):
+ return self.lm_head.decoder
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForCausalLM.set_output_embeddings
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.decoder = new_embeddings
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ lang_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[tuple[tuple[torch.FloatTensor]]] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> Union[tuple[torch.Tensor], CausalLMOutputWithCrossAttentions]:
+ r"""
+ lang_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of the language adapters that should be activated for each sample, respectively. Default: the index
+ that corresponds to `self.config.default_language`.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in
+ `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are
+ ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, XmodForCausalLM, AutoConfig
+ >>> import torch
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("FacebookAI/xlm-roberta-base")
+ >>> config = AutoConfig.from_pretrained("facebook/xmod-base")
+ >>> config.is_decoder = True
+ >>> model = XmodForCausalLM.from_pretrained("facebook/xmod-base", config=config)
+ >>> model.set_default_language("en_XX")
+
+ >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt")
+ >>> outputs = model(**inputs)
+
+ >>> prediction_logits = outputs.logits
+ ```"""
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ if labels is not None:
+ use_cache = False
+
+ outputs = self.roberta(
+ input_ids,
+ lang_ids=lang_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ past_key_values=past_key_values,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ cache_position=cache_position,
+ )
+
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+
+ lm_loss = None
+ if labels is not None:
+ lm_loss = self.loss_function(
+ prediction_scores,
+ labels,
+ vocab_size=self.config.vocab_size,
+ **kwargs,
+ )
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((lm_loss,) + output) if lm_loss is not None else output
+
+ return CausalLMOutputWithCrossAttentions(
+ loss=lm_loss,
+ logits=prediction_scores,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ cross_attentions=outputs.cross_attentions,
+ )
+
+
+@auto_docstring
+class XmodForMaskedLM(XmodPreTrainedModel):
+ _tied_weights_keys = ["lm_head.decoder.weight", "lm_head.decoder.bias"]
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM.__init__ with Roberta->Xmod
+ def __init__(self, config):
+ super().__init__(config)
+
+ if config.is_decoder:
+ logger.warning(
+ "If you want to use `XmodForMaskedLM` make sure `config.is_decoder=False` for "
+ "bi-directional self-attention."
+ )
+
+ self.roberta = XmodModel(config, add_pooling_layer=False)
+ self.lm_head = XmodLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM.get_output_embeddings
+ def get_output_embeddings(self):
+ return self.lm_head.decoder
+
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM.set_output_embeddings
+ def set_output_embeddings(self, new_embeddings):
+ self.lm_head.decoder = new_embeddings
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ lang_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], MaskedLMOutput]:
+ r"""
+ lang_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of the language adapters that should be activated for each sample, respectively. Default: the index
+ that corresponds to `self.config.default_language`.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ lang_ids=lang_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ encoder_hidden_states=encoder_hidden_states,
+ encoder_attention_mask=encoder_attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+ prediction_scores = self.lm_head(sequence_output)
+
+ masked_lm_loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[2:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return MaskedLMOutput(
+ loss=masked_lm_loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaLMHead
+class XmodLMHead(nn.Module):
+ """Roberta Head for masked language modeling."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size)
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+ self.decoder.bias = self.bias
+
+ def forward(self, features, **kwargs):
+ x = self.dense(features)
+ x = gelu(x)
+ x = self.layer_norm(x)
+
+ # project back to size of vocabulary with bias
+ x = self.decoder(x)
+
+ return x
+
+ def _tie_weights(self):
+ # To tie those two weights if they get disconnected (on TPU or when the bias is resized)
+ # For accelerate compatibility and to not break backward compatibility
+ if self.decoder.bias.device.type == "meta":
+ self.decoder.bias = self.bias
+ else:
+ self.bias = self.decoder.bias
+
+
+@auto_docstring(
+ custom_intro="""
+ X-MOD Model transformer with a sequence classification/regression head on top (a linear layer on top of the pooled
+ output) e.g. for GLUE tasks.
+ """
+)
+class XmodForSequenceClassification(XmodPreTrainedModel):
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForSequenceClassification.__init__ with Roberta->Xmod
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.config = config
+
+ self.roberta = XmodModel(config, add_pooling_layer=False)
+ self.classifier = XmodClassificationHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ lang_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], SequenceClassifierOutput]:
+ r"""
+ lang_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of the language adapters that should be activated for each sample, respectively. Default: the index
+ that corresponds to `self.config.default_language`.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ lang_ids=lang_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = outputs[0]
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class XmodForMultipleChoice(XmodPreTrainedModel):
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForMultipleChoice.__init__ with Roberta->Xmod
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.roberta = XmodModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ lang_ids: Optional[torch.LongTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], MultipleChoiceModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ lang_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of the language adapters that should be activated for each sample, respectively. Default: the index
+ that corresponds to `self.config.default_language`.
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See
+ `input_ids` above)
+ position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert `input_ids` indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ flat_input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ flat_lang_ids = lang_ids.repeat(input_ids.size(0) * input_ids.size(1)) if lang_ids is not None else None
+ flat_position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None
+ flat_token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ flat_attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ flat_inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ outputs = self.roberta(
+ flat_input_ids,
+ lang_ids=flat_lang_ids,
+ position_ids=flat_position_ids,
+ token_type_ids=flat_token_type_ids,
+ attention_mask=flat_attention_mask,
+ head_mask=head_mask,
+ inputs_embeds=flat_inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ pooled_output = outputs[1]
+
+ pooled_output = self.dropout(pooled_output)
+ logits = self.classifier(pooled_output)
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels)
+
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return MultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class XmodForTokenClassification(XmodPreTrainedModel):
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForTokenClassification.__init__ with Roberta->Xmod
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.roberta = XmodModel(config, add_pooling_layer=False)
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(classifier_dropout)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ lang_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], TokenClassifierOutput]:
+ r"""
+ lang_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of the language adapters that should be activated for each sample, respectively. Default: the index
+ that corresponds to `self.config.default_language`.
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ lang_ids=lang_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ sequence_output = self.dropout(sequence_output)
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[2:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.RobertaClassificationHead
+class XmodClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ classifier_dropout = (
+ config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob
+ )
+ self.dropout = nn.Dropout(classifier_dropout)
+ self.out_proj = nn.Linear(config.hidden_size, config.num_labels)
+
+ def forward(self, features, **kwargs):
+ x = features[:, 0, :] # take token (equiv. to [CLS])
+ x = self.dropout(x)
+ x = self.dense(x)
+ x = torch.tanh(x)
+ x = self.dropout(x)
+ x = self.out_proj(x)
+ return x
+
+
+@auto_docstring
+class XmodForQuestionAnswering(XmodPreTrainedModel):
+ # Copied from transformers.models.roberta.modeling_roberta.RobertaForQuestionAnswering.__init__ with Roberta->Xmod
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.roberta = XmodModel(config, add_pooling_layer=False)
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ lang_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ token_type_ids: Optional[torch.LongTensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ head_mask: Optional[torch.FloatTensor] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ start_positions: Optional[torch.LongTensor] = None,
+ end_positions: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], QuestionAnsweringModelOutput]:
+ r"""
+ lang_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Indices of the language adapters that should be activated for each sample, respectively. Default: the index
+ that corresponds to `self.config.default_language`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.roberta(
+ input_ids,
+ lang_ids=lang_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1).contiguous()
+ end_logits = end_logits.squeeze(-1).contiguous()
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[2:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return QuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+# Copied from transformers.models.roberta.modeling_roberta.create_position_ids_from_input_ids
+def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0):
+ """
+ Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols
+ are ignored. This is modified from fairseq's `utils.make_positions`.
+
+ Args:
+ x: torch.Tensor x:
+
+ Returns: torch.Tensor
+ """
+ # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
+ mask = input_ids.ne(padding_idx).int()
+ incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask
+ return incremental_indices.long() + padding_idx
+
+
+__all__ = [
+ "XmodForCausalLM",
+ "XmodForMaskedLM",
+ "XmodForMultipleChoice",
+ "XmodForQuestionAnswering",
+ "XmodForSequenceClassification",
+ "XmodForTokenClassification",
+ "XmodModel",
+ "XmodPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..c7ce96987e40700eb32f32e3aa0ae6c29d850b54
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/__init__.py
@@ -0,0 +1,30 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_yolos import *
+ from .feature_extraction_yolos import *
+ from .image_processing_yolos import *
+ from .image_processing_yolos_fast import *
+ from .modeling_yolos import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/configuration_yolos.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/configuration_yolos.py
new file mode 100644
index 0000000000000000000000000000000000000000..3d2fdb2ba34c839dee6795481022551fa15f8545
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/configuration_yolos.py
@@ -0,0 +1,178 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""YOLOS model configuration"""
+
+from collections import OrderedDict
+from collections.abc import Mapping
+
+from packaging import version
+
+from ...configuration_utils import PretrainedConfig
+from ...onnx import OnnxConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class YolosConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`YolosModel`]. It is used to instantiate a YOLOS
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the YOLOS
+ [hustvl/yolos-base](https://huggingface.co/hustvl/yolos-base) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimensionality of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ image_size (`list[int]`, *optional*, defaults to `[512, 864]`):
+ The size (resolution) of each image.
+ patch_size (`int`, *optional*, defaults to 16):
+ The size (resolution) of each patch.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ qkv_bias (`bool`, *optional*, defaults to `True`):
+ Whether to add a bias to the queries, keys and values.
+ num_detection_tokens (`int`, *optional*, defaults to 100):
+ The number of detection tokens.
+ use_mid_position_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether to use the mid-layer position encodings.
+ auxiliary_loss (`bool`, *optional*, defaults to `False`):
+ Whether auxiliary decoding losses (loss at each decoder layer) are to be used.
+ class_cost (`float`, *optional*, defaults to 1):
+ Relative weight of the classification error in the Hungarian matching cost.
+ bbox_cost (`float`, *optional*, defaults to 5):
+ Relative weight of the L1 error of the bounding box coordinates in the Hungarian matching cost.
+ giou_cost (`float`, *optional*, defaults to 2):
+ Relative weight of the generalized IoU loss of the bounding box in the Hungarian matching cost.
+ bbox_loss_coefficient (`float`, *optional*, defaults to 5):
+ Relative weight of the L1 bounding box loss in the object detection loss.
+ giou_loss_coefficient (`float`, *optional*, defaults to 2):
+ Relative weight of the generalized IoU loss in the object detection loss.
+ eos_coefficient (`float`, *optional*, defaults to 0.1):
+ Relative classification weight of the 'no-object' class in the object detection loss.
+
+ Example:
+
+ ```python
+ >>> from transformers import YolosConfig, YolosModel
+
+ >>> # Initializing a YOLOS hustvl/yolos-base style configuration
+ >>> configuration = YolosConfig()
+
+ >>> # Initializing a model (with random weights) from the hustvl/yolos-base style configuration
+ >>> model = YolosModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "yolos"
+
+ def __init__(
+ self,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.0,
+ attention_probs_dropout_prob=0.0,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ image_size=[512, 864],
+ patch_size=16,
+ num_channels=3,
+ qkv_bias=True,
+ num_detection_tokens=100,
+ use_mid_position_embeddings=True,
+ auxiliary_loss=False,
+ class_cost=1,
+ bbox_cost=5,
+ giou_cost=2,
+ bbox_loss_coefficient=5,
+ giou_loss_coefficient=2,
+ eos_coefficient=0.1,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.layer_norm_eps = layer_norm_eps
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.qkv_bias = qkv_bias
+ self.num_detection_tokens = num_detection_tokens
+ self.use_mid_position_embeddings = use_mid_position_embeddings
+ self.auxiliary_loss = auxiliary_loss
+ # Hungarian matcher
+ self.class_cost = class_cost
+ self.bbox_cost = bbox_cost
+ self.giou_cost = giou_cost
+ # Loss coefficients
+ self.bbox_loss_coefficient = bbox_loss_coefficient
+ self.giou_loss_coefficient = giou_loss_coefficient
+ self.eos_coefficient = eos_coefficient
+
+
+class YolosOnnxConfig(OnnxConfig):
+ torch_onnx_minimum_version = version.parse("1.11")
+
+ @property
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ return OrderedDict(
+ [
+ ("pixel_values", {0: "batch", 1: "num_channels", 2: "height", 3: "width"}),
+ ]
+ )
+
+ @property
+ def atol_for_validation(self) -> float:
+ return 1e-4
+
+ @property
+ def default_onnx_opset(self) -> int:
+ return 12
+
+
+__all__ = ["YolosConfig", "YolosOnnxConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/feature_extraction_yolos.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/feature_extraction_yolos.py
new file mode 100644
index 0000000000000000000000000000000000000000..a1c9165832f7b181503e48af42eae559400f170a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/feature_extraction_yolos.py
@@ -0,0 +1,48 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Feature extractor class for YOLOS."""
+
+import warnings
+
+from ...image_transforms import rgb_to_id as _rgb_to_id
+from ...utils import logging
+from ...utils.import_utils import requires
+from .image_processing_yolos import YolosImageProcessor
+
+
+logger = logging.get_logger(__name__)
+
+
+def rgb_to_id(x):
+ warnings.warn(
+ "rgb_to_id has moved and will not be importable from this module from v5. "
+ "Please import from transformers.image_transforms instead.",
+ FutureWarning,
+ )
+ return _rgb_to_id(x)
+
+
+@requires(backends=("vision",))
+class YolosFeatureExtractor(YolosImageProcessor):
+ def __init__(self, *args, **kwargs) -> None:
+ warnings.warn(
+ "The class YolosFeatureExtractor is deprecated and will be removed in version 5 of Transformers. Please"
+ " use YolosImageProcessor instead.",
+ FutureWarning,
+ )
+ super().__init__(*args, **kwargs)
+
+
+__all__ = ["YolosFeatureExtractor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/image_processing_yolos.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/image_processing_yolos.py
new file mode 100644
index 0000000000000000000000000000000000000000..4a716036d4003ce8b63ebe917f2d79849fac780a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/image_processing_yolos.py
@@ -0,0 +1,1537 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for YOLOS."""
+
+import pathlib
+from collections.abc import Iterable
+from typing import Any, Callable, Optional, Union
+
+import numpy as np
+
+from ...feature_extraction_utils import BatchFeature
+from ...image_processing_utils import BaseImageProcessor, get_size_dict
+from ...image_transforms import (
+ PaddingMode,
+ center_to_corners_format,
+ corners_to_center_format,
+ id_to_rgb,
+ pad,
+ rescale,
+ resize,
+ rgb_to_id,
+ to_channel_dimension_format,
+)
+from ...image_utils import (
+ IMAGENET_DEFAULT_MEAN,
+ IMAGENET_DEFAULT_STD,
+ AnnotationFormat,
+ AnnotationType,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ get_image_size,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_annotations,
+ validate_kwargs,
+ validate_preprocess_arguments,
+)
+from ...utils import (
+ TensorType,
+ is_flax_available,
+ is_jax_tensor,
+ is_scipy_available,
+ is_tf_available,
+ is_tf_tensor,
+ is_torch_available,
+ is_torch_tensor,
+ is_vision_available,
+ logging,
+)
+from ...utils.import_utils import requires
+
+
+if is_torch_available():
+ import torch
+ from torch import nn
+
+
+if is_vision_available():
+ import PIL
+
+
+if is_scipy_available():
+ import scipy.special
+ import scipy.stats
+
+logger = logging.get_logger(__name__)
+
+SUPPORTED_ANNOTATION_FORMATS = (AnnotationFormat.COCO_DETECTION, AnnotationFormat.COCO_PANOPTIC)
+
+
+# Copied from transformers.models.detr.image_processing_detr.get_max_height_width
+def get_max_height_width(
+ images: list[np.ndarray], input_data_format: Optional[Union[str, ChannelDimension]] = None
+) -> list[int]:
+ """
+ Get the maximum height and width across all images in a batch.
+ """
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if input_data_format == ChannelDimension.FIRST:
+ _, max_height, max_width = max_across_indices([img.shape for img in images])
+ elif input_data_format == ChannelDimension.LAST:
+ max_height, max_width, _ = max_across_indices([img.shape for img in images])
+ else:
+ raise ValueError(f"Invalid channel dimension format: {input_data_format}")
+ return (max_height, max_width)
+
+
+def get_size_with_aspect_ratio(
+ image_size: tuple[int, int], size: int, max_size: Optional[int] = None, mod_size: int = 16
+) -> tuple[int, int]:
+ """
+ Computes the output image size given the input image size and the desired output size with multiple of divisible_size.
+
+ Args:
+ image_size (`tuple[int, int]`):
+ The input image size.
+ size (`int`):
+ The desired output size.
+ max_size (`int`, *optional*):
+ The maximum allowed output size.
+ mod_size (`int`, *optional*):
+ The size to make multiple of mod_size.
+ """
+ height, width = image_size
+ raw_size = None
+ if max_size is not None:
+ min_original_size = float(min((height, width)))
+ max_original_size = float(max((height, width)))
+ if max_original_size / min_original_size * size > max_size:
+ raw_size = max_size * min_original_size / max_original_size
+ size = int(round(raw_size))
+
+ if width < height:
+ ow = size
+ if max_size is not None and raw_size is not None:
+ oh = int(raw_size * height / width)
+ else:
+ oh = int(size * height / width)
+ elif (height <= width and height == size) or (width <= height and width == size):
+ oh, ow = height, width
+ else:
+ oh = size
+ if max_size is not None and raw_size is not None:
+ ow = int(raw_size * width / height)
+ else:
+ ow = int(size * width / height)
+
+ if mod_size is not None:
+ ow_mod = np.mod(ow, mod_size)
+ oh_mod = np.mod(oh, mod_size)
+ ow = ow - ow_mod
+ oh = oh - oh_mod
+
+ return (oh, ow)
+
+
+# Copied from transformers.models.detr.image_processing_detr.get_image_size_for_max_height_width
+def get_image_size_for_max_height_width(
+ input_image: np.ndarray,
+ max_height: int,
+ max_width: int,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> tuple[int, int]:
+ """
+ Computes the output image size given the input image and the maximum allowed height and width. Keep aspect ratio.
+ Important, even if image_height < max_height and image_width < max_width, the image will be resized
+ to at least one of the edges be equal to max_height or max_width.
+
+ For example:
+ - input_size: (100, 200), max_height: 50, max_width: 50 -> output_size: (25, 50)
+ - input_size: (100, 200), max_height: 200, max_width: 500 -> output_size: (200, 400)
+
+ Args:
+ input_image (`np.ndarray`):
+ The image to resize.
+ max_height (`int`):
+ The maximum allowed height.
+ max_width (`int`):
+ The maximum allowed width.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred from the input image.
+ """
+ image_size = get_image_size(input_image, input_data_format)
+ height, width = image_size
+ height_scale = max_height / height
+ width_scale = max_width / width
+ min_scale = min(height_scale, width_scale)
+ new_height = int(height * min_scale)
+ new_width = int(width * min_scale)
+ return new_height, new_width
+
+
+# Copied from transformers.models.detr.image_processing_detr.get_resize_output_image_size
+def get_resize_output_image_size(
+ input_image: np.ndarray,
+ size: Union[int, tuple[int, int], list[int]],
+ max_size: Optional[int] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> tuple[int, int]:
+ """
+ Computes the output image size given the input image size and the desired output size. If the desired output size
+ is a tuple or list, the output image size is returned as is. If the desired output size is an integer, the output
+ image size is computed by keeping the aspect ratio of the input image size.
+
+ Args:
+ input_image (`np.ndarray`):
+ The image to resize.
+ size (`int` or `tuple[int, int]` or `list[int]`):
+ The desired output size.
+ max_size (`int`, *optional*):
+ The maximum allowed output size.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred from the input image.
+ """
+ image_size = get_image_size(input_image, input_data_format)
+ if isinstance(size, (list, tuple)):
+ return size
+
+ return get_size_with_aspect_ratio(image_size, size, max_size)
+
+
+# Copied from transformers.models.detr.image_processing_detr.get_numpy_to_framework_fn
+def get_numpy_to_framework_fn(arr) -> Callable:
+ """
+ Returns a function that converts a numpy array to the framework of the input array.
+
+ Args:
+ arr (`np.ndarray`): The array to convert.
+ """
+ if isinstance(arr, np.ndarray):
+ return np.array
+ if is_tf_available() and is_tf_tensor(arr):
+ import tensorflow as tf
+
+ return tf.convert_to_tensor
+ if is_torch_available() and is_torch_tensor(arr):
+ import torch
+
+ return torch.tensor
+ if is_flax_available() and is_jax_tensor(arr):
+ import jax.numpy as jnp
+
+ return jnp.array
+ raise ValueError(f"Cannot convert arrays of type {type(arr)}")
+
+
+# Copied from transformers.models.detr.image_processing_detr.safe_squeeze
+def safe_squeeze(arr: np.ndarray, axis: Optional[int] = None) -> np.ndarray:
+ """
+ Squeezes an array, but only if the axis specified has dim 1.
+ """
+ if axis is None:
+ return arr.squeeze()
+
+ try:
+ return arr.squeeze(axis=axis)
+ except ValueError:
+ return arr
+
+
+# Copied from transformers.models.detr.image_processing_detr.normalize_annotation
+def normalize_annotation(annotation: dict, image_size: tuple[int, int]) -> dict:
+ image_height, image_width = image_size
+ norm_annotation = {}
+ for key, value in annotation.items():
+ if key == "boxes":
+ boxes = value
+ boxes = corners_to_center_format(boxes)
+ boxes /= np.asarray([image_width, image_height, image_width, image_height], dtype=np.float32)
+ norm_annotation[key] = boxes
+ else:
+ norm_annotation[key] = value
+ return norm_annotation
+
+
+# Copied from transformers.models.detr.image_processing_detr.max_across_indices
+def max_across_indices(values: Iterable[Any]) -> list[Any]:
+ """
+ Return the maximum value across all indices of an iterable of values.
+ """
+ return [max(values_i) for values_i in zip(*values)]
+
+
+# Copied from transformers.models.detr.image_processing_detr.make_pixel_mask
+def make_pixel_mask(
+ image: np.ndarray, output_size: tuple[int, int], input_data_format: Optional[Union[str, ChannelDimension]] = None
+) -> np.ndarray:
+ """
+ Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding.
+
+ Args:
+ image (`np.ndarray`):
+ Image to make the pixel mask for.
+ output_size (`tuple[int, int]`):
+ Output size of the mask.
+ """
+ input_height, input_width = get_image_size(image, channel_dim=input_data_format)
+ mask = np.zeros(output_size, dtype=np.int64)
+ mask[:input_height, :input_width] = 1
+ return mask
+
+
+# Copied from transformers.models.detr.image_processing_detr.convert_coco_poly_to_mask
+def convert_coco_poly_to_mask(segmentations, height: int, width: int) -> np.ndarray:
+ """
+ Convert a COCO polygon annotation to a mask.
+
+ Args:
+ segmentations (`list[list[float]]`):
+ List of polygons, each polygon represented by a list of x-y coordinates.
+ height (`int`):
+ Height of the mask.
+ width (`int`):
+ Width of the mask.
+ """
+ try:
+ from pycocotools import mask as coco_mask
+ except ImportError:
+ raise ImportError("Pycocotools is not installed in your environment.")
+
+ masks = []
+ for polygons in segmentations:
+ rles = coco_mask.frPyObjects(polygons, height, width)
+ mask = coco_mask.decode(rles)
+ if len(mask.shape) < 3:
+ mask = mask[..., None]
+ mask = np.asarray(mask, dtype=np.uint8)
+ mask = np.any(mask, axis=2)
+ masks.append(mask)
+ if masks:
+ masks = np.stack(masks, axis=0)
+ else:
+ masks = np.zeros((0, height, width), dtype=np.uint8)
+
+ return masks
+
+
+# Copied from transformers.models.detr.image_processing_detr.prepare_coco_detection_annotation
+def prepare_coco_detection_annotation(
+ image,
+ target,
+ return_segmentation_masks: bool = False,
+ input_data_format: Optional[Union[ChannelDimension, str]] = None,
+):
+ """
+ Convert the target in COCO format into the format expected by DETR.
+ """
+ image_height, image_width = get_image_size(image, channel_dim=input_data_format)
+
+ image_id = target["image_id"]
+ image_id = np.asarray([image_id], dtype=np.int64)
+
+ # Get all COCO annotations for the given image.
+ annotations = target["annotations"]
+ annotations = [obj for obj in annotations if "iscrowd" not in obj or obj["iscrowd"] == 0]
+
+ classes = [obj["category_id"] for obj in annotations]
+ classes = np.asarray(classes, dtype=np.int64)
+
+ # for conversion to coco api
+ area = np.asarray([obj["area"] for obj in annotations], dtype=np.float32)
+ iscrowd = np.asarray([obj.get("iscrowd", 0) for obj in annotations], dtype=np.int64)
+
+ boxes = [obj["bbox"] for obj in annotations]
+ # guard against no boxes via resizing
+ boxes = np.asarray(boxes, dtype=np.float32).reshape(-1, 4)
+ boxes[:, 2:] += boxes[:, :2]
+ boxes[:, 0::2] = boxes[:, 0::2].clip(min=0, max=image_width)
+ boxes[:, 1::2] = boxes[:, 1::2].clip(min=0, max=image_height)
+
+ keep = (boxes[:, 3] > boxes[:, 1]) & (boxes[:, 2] > boxes[:, 0])
+
+ new_target = {}
+ new_target["image_id"] = image_id
+ new_target["class_labels"] = classes[keep]
+ new_target["boxes"] = boxes[keep]
+ new_target["area"] = area[keep]
+ new_target["iscrowd"] = iscrowd[keep]
+ new_target["orig_size"] = np.asarray([int(image_height), int(image_width)], dtype=np.int64)
+
+ if annotations and "keypoints" in annotations[0]:
+ keypoints = [obj["keypoints"] for obj in annotations]
+ # Converting the filtered keypoints list to a numpy array
+ keypoints = np.asarray(keypoints, dtype=np.float32)
+ # Apply the keep mask here to filter the relevant annotations
+ keypoints = keypoints[keep]
+ num_keypoints = keypoints.shape[0]
+ keypoints = keypoints.reshape((-1, 3)) if num_keypoints else keypoints
+ new_target["keypoints"] = keypoints
+
+ if return_segmentation_masks:
+ segmentation_masks = [obj["segmentation"] for obj in annotations]
+ masks = convert_coco_poly_to_mask(segmentation_masks, image_height, image_width)
+ new_target["masks"] = masks[keep]
+
+ return new_target
+
+
+# Copied from transformers.models.detr.image_processing_detr.masks_to_boxes
+def masks_to_boxes(masks: np.ndarray) -> np.ndarray:
+ """
+ Compute the bounding boxes around the provided panoptic segmentation masks.
+
+ Args:
+ masks: masks in format `[number_masks, height, width]` where N is the number of masks
+
+ Returns:
+ boxes: bounding boxes in format `[number_masks, 4]` in xyxy format
+ """
+ if masks.size == 0:
+ return np.zeros((0, 4))
+
+ h, w = masks.shape[-2:]
+ y = np.arange(0, h, dtype=np.float32)
+ x = np.arange(0, w, dtype=np.float32)
+ # see https://github.com/pytorch/pytorch/issues/50276
+ y, x = np.meshgrid(y, x, indexing="ij")
+
+ x_mask = masks * np.expand_dims(x, axis=0)
+ x_max = x_mask.reshape(x_mask.shape[0], -1).max(-1)
+ x = np.ma.array(x_mask, mask=~(np.array(masks, dtype=bool)))
+ x_min = x.filled(fill_value=1e8)
+ x_min = x_min.reshape(x_min.shape[0], -1).min(-1)
+
+ y_mask = masks * np.expand_dims(y, axis=0)
+ y_max = y_mask.reshape(x_mask.shape[0], -1).max(-1)
+ y = np.ma.array(y_mask, mask=~(np.array(masks, dtype=bool)))
+ y_min = y.filled(fill_value=1e8)
+ y_min = y_min.reshape(y_min.shape[0], -1).min(-1)
+
+ return np.stack([x_min, y_min, x_max, y_max], 1)
+
+
+# Copied from transformers.models.detr.image_processing_detr.prepare_coco_panoptic_annotation with DETR->YOLOS
+def prepare_coco_panoptic_annotation(
+ image: np.ndarray,
+ target: dict,
+ masks_path: Union[str, pathlib.Path],
+ return_masks: bool = True,
+ input_data_format: Union[ChannelDimension, str] = None,
+) -> dict:
+ """
+ Prepare a coco panoptic annotation for YOLOS.
+ """
+ image_height, image_width = get_image_size(image, channel_dim=input_data_format)
+ annotation_path = pathlib.Path(masks_path) / target["file_name"]
+
+ new_target = {}
+ new_target["image_id"] = np.asarray([target["image_id"] if "image_id" in target else target["id"]], dtype=np.int64)
+ new_target["size"] = np.asarray([image_height, image_width], dtype=np.int64)
+ new_target["orig_size"] = np.asarray([image_height, image_width], dtype=np.int64)
+
+ if "segments_info" in target:
+ masks = np.asarray(PIL.Image.open(annotation_path), dtype=np.uint32)
+ masks = rgb_to_id(masks)
+
+ ids = np.array([segment_info["id"] for segment_info in target["segments_info"]])
+ masks = masks == ids[:, None, None]
+ masks = masks.astype(np.uint8)
+ if return_masks:
+ new_target["masks"] = masks
+ new_target["boxes"] = masks_to_boxes(masks)
+ new_target["class_labels"] = np.array(
+ [segment_info["category_id"] for segment_info in target["segments_info"]], dtype=np.int64
+ )
+ new_target["iscrowd"] = np.asarray(
+ [segment_info["iscrowd"] for segment_info in target["segments_info"]], dtype=np.int64
+ )
+ new_target["area"] = np.asarray(
+ [segment_info["area"] for segment_info in target["segments_info"]], dtype=np.float32
+ )
+
+ return new_target
+
+
+# Copied from transformers.models.detr.image_processing_detr.get_segmentation_image
+def get_segmentation_image(
+ masks: np.ndarray, input_size: tuple, target_size: tuple, stuff_equiv_classes, deduplicate=False
+):
+ h, w = input_size
+ final_h, final_w = target_size
+
+ m_id = scipy.special.softmax(masks.transpose(0, 1), -1)
+
+ if m_id.shape[-1] == 0:
+ # We didn't detect any mask :(
+ m_id = np.zeros((h, w), dtype=np.int64)
+ else:
+ m_id = m_id.argmax(-1).reshape(h, w)
+
+ if deduplicate:
+ # Merge the masks corresponding to the same stuff class
+ for equiv in stuff_equiv_classes.values():
+ for eq_id in equiv:
+ m_id[m_id == eq_id] = equiv[0]
+
+ seg_img = id_to_rgb(m_id)
+ seg_img = resize(seg_img, (final_w, final_h), resample=PILImageResampling.NEAREST)
+ return seg_img
+
+
+# Copied from transformers.models.detr.image_processing_detr.get_mask_area
+def get_mask_area(seg_img: np.ndarray, target_size: tuple[int, int], n_classes: int) -> np.ndarray:
+ final_h, final_w = target_size
+ np_seg_img = seg_img.astype(np.uint8)
+ np_seg_img = np_seg_img.reshape(final_h, final_w, 3)
+ m_id = rgb_to_id(np_seg_img)
+ area = [(m_id == i).sum() for i in range(n_classes)]
+ return area
+
+
+# Copied from transformers.models.detr.image_processing_detr.score_labels_from_class_probabilities
+def score_labels_from_class_probabilities(logits: np.ndarray) -> tuple[np.ndarray, np.ndarray]:
+ probs = scipy.special.softmax(logits, axis=-1)
+ labels = probs.argmax(-1, keepdims=True)
+ scores = np.take_along_axis(probs, labels, axis=-1)
+ scores, labels = scores.squeeze(-1), labels.squeeze(-1)
+ return scores, labels
+
+
+# Copied from transformers.models.detr.image_processing_detr.resize_annotation
+def resize_annotation(
+ annotation: dict[str, Any],
+ orig_size: tuple[int, int],
+ target_size: tuple[int, int],
+ threshold: float = 0.5,
+ resample: PILImageResampling = PILImageResampling.NEAREST,
+):
+ """
+ Resizes an annotation to a target size.
+
+ Args:
+ annotation (`dict[str, Any]`):
+ The annotation dictionary.
+ orig_size (`tuple[int, int]`):
+ The original size of the input image.
+ target_size (`tuple[int, int]`):
+ The target size of the image, as returned by the preprocessing `resize` step.
+ threshold (`float`, *optional*, defaults to 0.5):
+ The threshold used to binarize the segmentation masks.
+ resample (`PILImageResampling`, defaults to `PILImageResampling.NEAREST`):
+ The resampling filter to use when resizing the masks.
+ """
+ ratios = tuple(float(s) / float(s_orig) for s, s_orig in zip(target_size, orig_size))
+ ratio_height, ratio_width = ratios
+
+ new_annotation = {}
+ new_annotation["size"] = target_size
+
+ for key, value in annotation.items():
+ if key == "boxes":
+ boxes = value
+ scaled_boxes = boxes * np.asarray([ratio_width, ratio_height, ratio_width, ratio_height], dtype=np.float32)
+ new_annotation["boxes"] = scaled_boxes
+ elif key == "area":
+ area = value
+ scaled_area = area * (ratio_width * ratio_height)
+ new_annotation["area"] = scaled_area
+ elif key == "masks":
+ masks = value[:, None]
+ masks = np.array([resize(mask, target_size, resample=resample) for mask in masks])
+ masks = masks.astype(np.float32)
+ masks = masks[:, 0] > threshold
+ new_annotation["masks"] = masks
+ elif key == "size":
+ new_annotation["size"] = target_size
+ else:
+ new_annotation[key] = value
+
+ return new_annotation
+
+
+# Copied from transformers.models.detr.image_processing_detr.binary_mask_to_rle
+def binary_mask_to_rle(mask):
+ """
+ Converts given binary mask of shape `(height, width)` to the run-length encoding (RLE) format.
+
+ Args:
+ mask (`torch.Tensor` or `numpy.array`):
+ A binary mask tensor of shape `(height, width)` where 0 denotes background and 1 denotes the target
+ segment_id or class_id.
+ Returns:
+ `List`: Run-length encoded list of the binary mask. Refer to COCO API for more information about the RLE
+ format.
+ """
+ if is_torch_tensor(mask):
+ mask = mask.numpy()
+
+ pixels = mask.flatten()
+ pixels = np.concatenate([[0], pixels, [0]])
+ runs = np.where(pixels[1:] != pixels[:-1])[0] + 1
+ runs[1::2] -= runs[::2]
+ return list(runs)
+
+
+# Copied from transformers.models.detr.image_processing_detr.convert_segmentation_to_rle
+def convert_segmentation_to_rle(segmentation):
+ """
+ Converts given segmentation map of shape `(height, width)` to the run-length encoding (RLE) format.
+
+ Args:
+ segmentation (`torch.Tensor` or `numpy.array`):
+ A segmentation map of shape `(height, width)` where each value denotes a segment or class id.
+ Returns:
+ `list[List]`: A list of lists, where each list is the run-length encoding of a segment / class id.
+ """
+ segment_ids = torch.unique(segmentation)
+
+ run_length_encodings = []
+ for idx in segment_ids:
+ mask = torch.where(segmentation == idx, 1, 0)
+ rle = binary_mask_to_rle(mask)
+ run_length_encodings.append(rle)
+
+ return run_length_encodings
+
+
+# Copied from transformers.models.detr.image_processing_detr.remove_low_and_no_objects
+def remove_low_and_no_objects(masks, scores, labels, object_mask_threshold, num_labels):
+ """
+ Binarize the given masks using `object_mask_threshold`, it returns the associated values of `masks`, `scores` and
+ `labels`.
+
+ Args:
+ masks (`torch.Tensor`):
+ A tensor of shape `(num_queries, height, width)`.
+ scores (`torch.Tensor`):
+ A tensor of shape `(num_queries)`.
+ labels (`torch.Tensor`):
+ A tensor of shape `(num_queries)`.
+ object_mask_threshold (`float`):
+ A number between 0 and 1 used to binarize the masks.
+ Raises:
+ `ValueError`: Raised when the first dimension doesn't match in all input tensors.
+ Returns:
+ `tuple[`torch.Tensor`, `torch.Tensor`, `torch.Tensor`]`: The `masks`, `scores` and `labels` without the region
+ < `object_mask_threshold`.
+ """
+ if not (masks.shape[0] == scores.shape[0] == labels.shape[0]):
+ raise ValueError("mask, scores and labels must have the same shape!")
+
+ to_keep = labels.ne(num_labels) & (scores > object_mask_threshold)
+
+ return masks[to_keep], scores[to_keep], labels[to_keep]
+
+
+# Copied from transformers.models.detr.image_processing_detr.check_segment_validity
+def check_segment_validity(mask_labels, mask_probs, k, mask_threshold=0.5, overlap_mask_area_threshold=0.8):
+ # Get the mask associated with the k class
+ mask_k = mask_labels == k
+ mask_k_area = mask_k.sum()
+
+ # Compute the area of all the stuff in query k
+ original_area = (mask_probs[k] >= mask_threshold).sum()
+ mask_exists = mask_k_area > 0 and original_area > 0
+
+ # Eliminate disconnected tiny segments
+ if mask_exists:
+ area_ratio = mask_k_area / original_area
+ if not area_ratio.item() > overlap_mask_area_threshold:
+ mask_exists = False
+
+ return mask_exists, mask_k
+
+
+# Copied from transformers.models.detr.image_processing_detr.compute_segments
+def compute_segments(
+ mask_probs,
+ pred_scores,
+ pred_labels,
+ mask_threshold: float = 0.5,
+ overlap_mask_area_threshold: float = 0.8,
+ label_ids_to_fuse: Optional[set[int]] = None,
+ target_size: Optional[tuple[int, int]] = None,
+):
+ height = mask_probs.shape[1] if target_size is None else target_size[0]
+ width = mask_probs.shape[2] if target_size is None else target_size[1]
+
+ segmentation = torch.zeros((height, width), dtype=torch.int32, device=mask_probs.device)
+ segments: list[dict] = []
+
+ if target_size is not None:
+ mask_probs = nn.functional.interpolate(
+ mask_probs.unsqueeze(0), size=target_size, mode="bilinear", align_corners=False
+ )[0]
+
+ current_segment_id = 0
+
+ # Weigh each mask by its prediction score
+ mask_probs *= pred_scores.view(-1, 1, 1)
+ mask_labels = mask_probs.argmax(0) # [height, width]
+
+ # Keep track of instances of each class
+ stuff_memory_list: dict[str, int] = {}
+ for k in range(pred_labels.shape[0]):
+ pred_class = pred_labels[k].item()
+ should_fuse = pred_class in label_ids_to_fuse
+
+ # Check if mask exists and large enough to be a segment
+ mask_exists, mask_k = check_segment_validity(
+ mask_labels, mask_probs, k, mask_threshold, overlap_mask_area_threshold
+ )
+
+ if mask_exists:
+ if pred_class in stuff_memory_list:
+ current_segment_id = stuff_memory_list[pred_class]
+ else:
+ current_segment_id += 1
+
+ # Add current object segment to final segmentation map
+ segmentation[mask_k] = current_segment_id
+ segment_score = round(pred_scores[k].item(), 6)
+ segments.append(
+ {
+ "id": current_segment_id,
+ "label_id": pred_class,
+ "was_fused": should_fuse,
+ "score": segment_score,
+ }
+ )
+ if should_fuse:
+ stuff_memory_list[pred_class] = current_segment_id
+
+ return segmentation, segments
+
+
+@requires(backends=("vision",))
+class YolosImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a Detr image processor.
+
+ Args:
+ format (`str`, *optional*, defaults to `"coco_detection"`):
+ Data format of the annotations. One of "coco_detection" or "coco_panoptic".
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Controls whether to resize the image's (height, width) dimensions to the specified `size`. Can be
+ overridden by the `do_resize` parameter in the `preprocess` method.
+ size (`dict[str, int]` *optional*, defaults to `{"shortest_edge": 800, "longest_edge": 1333}`):
+ Size of the image's `(height, width)` dimensions after resizing. Can be overridden by the `size` parameter
+ in the `preprocess` method. Available options are:
+ - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`.
+ Do NOT keep the aspect ratio.
+ - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting
+ the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge
+ less or equal to `longest_edge`.
+ - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the
+ aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to
+ `max_width`.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ Resampling filter to use if resizing the image.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Controls whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the
+ `do_rescale` parameter in the `preprocess` method.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the
+ `preprocess` method.
+ do_normalize:
+ Controls whether to normalize the image. Can be overridden by the `do_normalize` parameter in the
+ `preprocess` method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_MEAN`):
+ Mean values to use when normalizing the image. Can be a single value or a list of values, one for each
+ channel. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_STD`):
+ Standard deviation values to use when normalizing the image. Can be a single value or a list of values, one
+ for each channel. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Controls whether to pad the image. Can be overridden by the `do_pad` parameter in the `preprocess`
+ method. If `True`, padding will be applied to the bottom and right of the image with zeros.
+ If `pad_size` is provided, the image will be padded to the specified dimensions.
+ Otherwise, the image will be padded to the maximum height and width of the batch.
+ pad_size (`dict[str, int]`, *optional*):
+ The size `{"height": int, "width" int}` to pad the images to. Must be larger than any image size
+ provided for preprocessing. If `pad_size` is not provided, images will be padded to the largest
+ height and width in the batch.
+ """
+
+ model_input_names = ["pixel_values", "pixel_mask"]
+
+ def __init__(
+ self,
+ format: Union[str, AnnotationFormat] = AnnotationFormat.COCO_DETECTION,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_annotations: Optional[bool] = None,
+ do_pad: bool = True,
+ pad_size: Optional[dict[str, int]] = None,
+ **kwargs,
+ ) -> None:
+ if "pad_and_return_pixel_mask" in kwargs:
+ do_pad = kwargs.pop("pad_and_return_pixel_mask")
+
+ if "max_size" in kwargs:
+ logger.warning_once(
+ "The `max_size` parameter is deprecated and will be removed in v4.26. "
+ "Please specify in `size['longest_edge'] instead`.",
+ )
+ max_size = kwargs.pop("max_size")
+ else:
+ max_size = None if size is None else 1333
+
+ size = size if size is not None else {"shortest_edge": 800, "longest_edge": 1333}
+ size = get_size_dict(size, max_size=max_size, default_to_square=False)
+
+ # Backwards compatibility
+ if do_convert_annotations is None:
+ do_convert_annotations = do_normalize
+
+ super().__init__(**kwargs)
+ self.format = format
+ self.do_resize = do_resize
+ self.size = size
+ self.resample = resample
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_normalize = do_normalize
+ self.do_convert_annotations = do_convert_annotations
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD
+ self.do_pad = do_pad
+ self.pad_size = pad_size
+ self._valid_processor_keys = [
+ "images",
+ "annotations",
+ "return_segmentation_masks",
+ "masks_path",
+ "do_resize",
+ "size",
+ "resample",
+ "do_rescale",
+ "rescale_factor",
+ "do_normalize",
+ "image_mean",
+ "image_std",
+ "do_convert_annotations",
+ "do_pad",
+ "pad_size",
+ "format",
+ "return_tensors",
+ "data_format",
+ "input_data_format",
+ ]
+
+ @classmethod
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.from_dict with Detr->Yolos
+ def from_dict(cls, image_processor_dict: dict[str, Any], **kwargs):
+ """
+ Overrides the `from_dict` method from the base class to make sure parameters are updated if image processor is
+ created using from_dict and kwargs e.g. `YolosImageProcessor.from_pretrained(checkpoint, size=600,
+ max_size=800)`
+ """
+ image_processor_dict = image_processor_dict.copy()
+ if "max_size" in kwargs:
+ image_processor_dict["max_size"] = kwargs.pop("max_size")
+ if "pad_and_return_pixel_mask" in kwargs:
+ image_processor_dict["pad_and_return_pixel_mask"] = kwargs.pop("pad_and_return_pixel_mask")
+ return super().from_dict(image_processor_dict, **kwargs)
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.prepare_annotation
+ def prepare_annotation(
+ self,
+ image: np.ndarray,
+ target: dict,
+ format: Optional[AnnotationFormat] = None,
+ return_segmentation_masks: Optional[bool] = None,
+ masks_path: Optional[Union[str, pathlib.Path]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> dict:
+ """
+ Prepare an annotation for feeding into DETR model.
+ """
+ format = format if format is not None else self.format
+
+ if format == AnnotationFormat.COCO_DETECTION:
+ return_segmentation_masks = False if return_segmentation_masks is None else return_segmentation_masks
+ target = prepare_coco_detection_annotation(
+ image, target, return_segmentation_masks, input_data_format=input_data_format
+ )
+ elif format == AnnotationFormat.COCO_PANOPTIC:
+ return_segmentation_masks = True if return_segmentation_masks is None else return_segmentation_masks
+ target = prepare_coco_panoptic_annotation(
+ image,
+ target,
+ masks_path=masks_path,
+ return_masks=return_segmentation_masks,
+ input_data_format=input_data_format,
+ )
+ else:
+ raise ValueError(f"Format {format} is not supported.")
+ return target
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.resize
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ **kwargs,
+ ) -> np.ndarray:
+ """
+ Resize the image to the given size. Size can be `min_size` (scalar) or `(height, width)` tuple. If size is an
+ int, smaller edge of the image will be matched to this number.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Size of the image's `(height, width)` dimensions after resizing. Available options are:
+ - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`.
+ Do NOT keep the aspect ratio.
+ - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting
+ the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge
+ less or equal to `longest_edge`.
+ - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the
+ aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to
+ `max_width`.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ Resampling filter to use if resizing the image.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format for the output image. If unset, the channel dimension format of the input
+ image is used.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ if "max_size" in kwargs:
+ logger.warning_once(
+ "The `max_size` parameter is deprecated and will be removed in v4.26. "
+ "Please specify in `size['longest_edge'] instead`.",
+ )
+ max_size = kwargs.pop("max_size")
+ else:
+ max_size = None
+ size = get_size_dict(size, max_size=max_size, default_to_square=False)
+ if "shortest_edge" in size and "longest_edge" in size:
+ new_size = get_resize_output_image_size(
+ image, size["shortest_edge"], size["longest_edge"], input_data_format=input_data_format
+ )
+ elif "max_height" in size and "max_width" in size:
+ new_size = get_image_size_for_max_height_width(
+ image, size["max_height"], size["max_width"], input_data_format=input_data_format
+ )
+ elif "height" in size and "width" in size:
+ new_size = (size["height"], size["width"])
+ else:
+ raise ValueError(
+ "Size must contain 'height' and 'width' keys or 'shortest_edge' and 'longest_edge' keys. Got"
+ f" {size.keys()}."
+ )
+ image = resize(
+ image,
+ size=new_size,
+ resample=resample,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ **kwargs,
+ )
+ return image
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.resize_annotation
+ def resize_annotation(
+ self,
+ annotation,
+ orig_size,
+ size,
+ resample: PILImageResampling = PILImageResampling.NEAREST,
+ ) -> dict:
+ """
+ Resize the annotation to match the resized image. If size is an int, smaller edge of the mask will be matched
+ to this number.
+ """
+ return resize_annotation(annotation, orig_size=orig_size, target_size=size, resample=resample)
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.rescale
+ def rescale(
+ self,
+ image: np.ndarray,
+ rescale_factor: float,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ """
+ Rescale the image by the given factor. image = image * rescale_factor.
+
+ Args:
+ image (`np.ndarray`):
+ Image to rescale.
+ rescale_factor (`float`):
+ The value to use for rescaling.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format for the output image. If unset, the channel dimension format of the input
+ image is used. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format for the input image. If unset, is inferred from the input image. Can be
+ one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ """
+ return rescale(image, rescale_factor, data_format=data_format, input_data_format=input_data_format)
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.normalize_annotation
+ def normalize_annotation(self, annotation: dict, image_size: tuple[int, int]) -> dict:
+ """
+ Normalize the boxes in the annotation from `[top_left_x, top_left_y, bottom_right_x, bottom_right_y]` to
+ `[center_x, center_y, width, height]` format and from absolute to relative pixel values.
+ """
+ return normalize_annotation(annotation, image_size=image_size)
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor._update_annotation_for_padded_image
+ def _update_annotation_for_padded_image(
+ self,
+ annotation: dict,
+ input_image_size: tuple[int, int],
+ output_image_size: tuple[int, int],
+ padding,
+ update_bboxes,
+ ) -> dict:
+ """
+ Update the annotation for a padded image.
+ """
+ new_annotation = {}
+ new_annotation["size"] = output_image_size
+
+ for key, value in annotation.items():
+ if key == "masks":
+ masks = value
+ masks = pad(
+ masks,
+ padding,
+ mode=PaddingMode.CONSTANT,
+ constant_values=0,
+ input_data_format=ChannelDimension.FIRST,
+ )
+ masks = safe_squeeze(masks, 1)
+ new_annotation["masks"] = masks
+ elif key == "boxes" and update_bboxes:
+ boxes = value
+ boxes *= np.asarray(
+ [
+ input_image_size[1] / output_image_size[1],
+ input_image_size[0] / output_image_size[0],
+ input_image_size[1] / output_image_size[1],
+ input_image_size[0] / output_image_size[0],
+ ]
+ )
+ new_annotation["boxes"] = boxes
+ elif key == "size":
+ new_annotation["size"] = output_image_size
+ else:
+ new_annotation[key] = value
+ return new_annotation
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor._pad_image
+ def _pad_image(
+ self,
+ image: np.ndarray,
+ output_size: tuple[int, int],
+ annotation: Optional[dict[str, Any]] = None,
+ constant_values: Union[float, Iterable[float]] = 0,
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ update_bboxes: bool = True,
+ ) -> np.ndarray:
+ """
+ Pad an image with zeros to the given size.
+ """
+ input_height, input_width = get_image_size(image, channel_dim=input_data_format)
+ output_height, output_width = output_size
+
+ pad_bottom = output_height - input_height
+ pad_right = output_width - input_width
+ padding = ((0, pad_bottom), (0, pad_right))
+ padded_image = pad(
+ image,
+ padding,
+ mode=PaddingMode.CONSTANT,
+ constant_values=constant_values,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+ if annotation is not None:
+ annotation = self._update_annotation_for_padded_image(
+ annotation, (input_height, input_width), (output_height, output_width), padding, update_bboxes
+ )
+ return padded_image, annotation
+
+ def pad(
+ self,
+ images: list[np.ndarray],
+ annotations: Optional[list[dict[str, Any]]] = None,
+ constant_values: Union[float, Iterable[float]] = 0,
+ return_pixel_mask: bool = False,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: Optional[ChannelDimension] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ update_bboxes: bool = True,
+ pad_size: Optional[dict[str, int]] = None,
+ ) -> BatchFeature:
+ """
+ Pads a batch of images to the bottom and right of the image with zeros to the size of largest height and width
+ in the batch and optionally returns their corresponding pixel mask.
+
+ Args:
+ image (`np.ndarray`):
+ Image to pad.
+ annotations (`list[dict[str, any]]`, *optional*):
+ Annotations to pad along with the images. If provided, the bounding boxes will be updated to match the
+ padded images.
+ constant_values (`float` or `Iterable[float]`, *optional*):
+ The value to use for the padding if `mode` is `"constant"`.
+ return_pixel_mask (`bool`, *optional*, defaults to `True`):
+ Whether to return a pixel mask.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ update_bboxes (`bool`, *optional*, defaults to `True`):
+ Whether to update the bounding boxes in the annotations to match the padded images. If the
+ bounding boxes have not been converted to relative coordinates and `(centre_x, centre_y, width, height)`
+ format, the bounding boxes will not be updated.
+ pad_size (`dict[str, int]`, *optional*):
+ The size `{"height": int, "width" int}` to pad the images to. Must be larger than any image size
+ provided for preprocessing. If `pad_size` is not provided, images will be padded to the largest
+ height and width in the batch.
+ """
+ pad_size = pad_size if pad_size is not None else self.pad_size
+ if pad_size is not None:
+ padded_size = (pad_size["height"], pad_size["width"])
+ else:
+ padded_size = get_max_height_width(images, input_data_format=input_data_format)
+
+ annotation_list = annotations if annotations is not None else [None] * len(images)
+ padded_images = []
+ padded_annotations = []
+ for image, annotation in zip(images, annotation_list):
+ padded_image, padded_annotation = self._pad_image(
+ image,
+ padded_size,
+ annotation,
+ constant_values=constant_values,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ update_bboxes=update_bboxes,
+ )
+ padded_images.append(padded_image)
+ padded_annotations.append(padded_annotation)
+
+ data = {"pixel_values": padded_images}
+
+ if return_pixel_mask:
+ masks = [
+ make_pixel_mask(image=image, output_size=padded_size, input_data_format=input_data_format)
+ for image in images
+ ]
+ data["pixel_mask"] = masks
+
+ encoded_inputs = BatchFeature(data=data, tensor_type=return_tensors)
+
+ if annotations is not None:
+ encoded_inputs["labels"] = [
+ BatchFeature(annotation, tensor_type=return_tensors) for annotation in padded_annotations
+ ]
+
+ return encoded_inputs
+
+ def preprocess(
+ self,
+ images: ImageInput,
+ annotations: Optional[Union[AnnotationType, list[AnnotationType]]] = None,
+ return_segmentation_masks: Optional[bool] = None,
+ masks_path: Optional[Union[str, pathlib.Path]] = None,
+ do_resize: Optional[bool] = None,
+ size: Optional[dict[str, int]] = None,
+ resample=None, # PILImageResampling
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[Union[int, float]] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_convert_annotations: Optional[bool] = None,
+ do_pad: Optional[bool] = None,
+ format: Optional[Union[str, AnnotationFormat]] = None,
+ return_tensors: Optional[Union[TensorType, str]] = None,
+ data_format: Union[str, ChannelDimension] = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ pad_size: Optional[dict[str, int]] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Preprocess an image or a batch of images so that it can be used by the model.
+
+ Args:
+ images (`ImageInput`):
+ Image or batch of images to preprocess. Expects a single or batch of images with pixel values ranging
+ from 0 to 255. If passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ annotations (`AnnotationType` or `list[AnnotationType]`, *optional*):
+ List of annotations associated with the image or batch of images. If annotation is for object
+ detection, the annotations should be a dictionary with the following keys:
+ - "image_id" (`int`): The image id.
+ - "annotations" (`list[Dict]`): List of annotations for an image. Each annotation should be a
+ dictionary. An image can have no annotations, in which case the list should be empty.
+ If annotation is for segmentation, the annotations should be a dictionary with the following keys:
+ - "image_id" (`int`): The image id.
+ - "segments_info" (`list[Dict]`): List of segments for an image. Each segment should be a dictionary.
+ An image can have no segments, in which case the list should be empty.
+ - "file_name" (`str`): The file name of the image.
+ return_segmentation_masks (`bool`, *optional*, defaults to self.return_segmentation_masks):
+ Whether to return segmentation masks.
+ masks_path (`str` or `pathlib.Path`, *optional*):
+ Path to the directory containing the segmentation masks.
+ do_resize (`bool`, *optional*, defaults to self.do_resize):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to self.size):
+ Size of the image's `(height, width)` dimensions after resizing. Available options are:
+ - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`.
+ Do NOT keep the aspect ratio.
+ - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting
+ the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge
+ less or equal to `longest_edge`.
+ - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the
+ aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to
+ `max_width`.
+ resample (`PILImageResampling`, *optional*, defaults to self.resample):
+ Resampling filter to use when resizing the image.
+ do_rescale (`bool`, *optional*, defaults to self.do_rescale):
+ Whether to rescale the image.
+ rescale_factor (`float`, *optional*, defaults to self.rescale_factor):
+ Rescale factor to use when rescaling the image.
+ do_normalize (`bool`, *optional*, defaults to self.do_normalize):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to self.image_mean):
+ Mean to use when normalizing the image.
+ image_std (`float` or `list[float]`, *optional*, defaults to self.image_std):
+ Standard deviation to use when normalizing the image.
+ do_convert_annotations (`bool`, *optional*, defaults to self.do_convert_annotations):
+ Whether to convert the annotations to the format expected by the model. Converts the bounding
+ boxes from the format `(top_left_x, top_left_y, width, height)` to `(center_x, center_y, width, height)`
+ and in relative coordinates.
+ do_pad (`bool`, *optional*, defaults to self.do_pad):
+ Whether to pad the image. If `True`, padding will be applied to the bottom and right of
+ the image with zeros. If `pad_size` is provided, the image will be padded to the specified
+ dimensions. Otherwise, the image will be padded to the maximum height and width of the batch.
+ format (`str` or `AnnotationFormat`, *optional*, defaults to self.format):
+ Format of the annotations.
+ return_tensors (`str` or `TensorType`, *optional*, defaults to self.return_tensors):
+ Type of tensors to return. If `None`, will return the list of images.
+ data_format (`str` or `ChannelDimension`, *optional*, defaults to self.data_format):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ pad_size (`dict[str, int]`, *optional*):
+ The size `{"height": int, "width" int}` to pad the images to. Must be larger than any image size
+ provided for preprocessing. If `pad_size` is not provided, images will be padded to the largest
+ height and width in the batch.
+ """
+ if "pad_and_return_pixel_mask" in kwargs:
+ logger.warning_once(
+ "The `pad_and_return_pixel_mask` argument is deprecated and will be removed in v4.33, "
+ "use `do_pad` instead.",
+ )
+ do_pad = kwargs.pop("pad_and_return_pixel_mask")
+
+ if "max_size" in kwargs:
+ logger.warning_once(
+ "The `max_size` argument is deprecated and will be removed in v4.33, use"
+ " `size['longest_edge']` instead.",
+ )
+ size = kwargs.pop("max_size")
+
+ do_resize = self.do_resize if do_resize is None else do_resize
+ size = self.size if size is None else size
+ size = get_size_dict(size=size, default_to_square=False)
+ resample = self.resample if resample is None else resample
+ do_rescale = self.do_rescale if do_rescale is None else do_rescale
+ rescale_factor = self.rescale_factor if rescale_factor is None else rescale_factor
+ do_normalize = self.do_normalize if do_normalize is None else do_normalize
+ image_mean = self.image_mean if image_mean is None else image_mean
+ image_std = self.image_std if image_std is None else image_std
+ do_convert_annotations = (
+ self.do_convert_annotations if do_convert_annotations is None else do_convert_annotations
+ )
+ do_pad = self.do_pad if do_pad is None else do_pad
+ pad_size = self.pad_size if pad_size is None else pad_size
+ format = self.format if format is None else format
+ validate_kwargs(captured_kwargs=kwargs.keys(), valid_processor_keys=self._valid_processor_keys)
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ # Here the pad() method pads using the max of (width, height) and does not need to be validated.
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+
+ if annotations is not None and isinstance(annotations, dict):
+ annotations = [annotations]
+
+ if annotations is not None and len(images) != len(annotations):
+ raise ValueError(
+ f"The number of images ({len(images)}) and annotations ({len(annotations)}) do not match."
+ )
+
+ format = AnnotationFormat(format)
+ if annotations is not None:
+ validate_annotations(format, SUPPORTED_ANNOTATION_FORMATS, annotations)
+
+ if (
+ masks_path is not None
+ and format == AnnotationFormat.COCO_PANOPTIC
+ and not isinstance(masks_path, (pathlib.Path, str))
+ ):
+ raise ValueError(
+ "The path to the directory containing the mask PNG files should be provided as a"
+ f" `pathlib.Path` or string object, but is {type(masks_path)} instead."
+ )
+
+ # All transformations expect numpy arrays
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ # prepare (COCO annotations as a list of Dict -> DETR target as a single Dict per image)
+ if annotations is not None:
+ prepared_images = []
+ prepared_annotations = []
+ for image, target in zip(images, annotations):
+ target = self.prepare_annotation(
+ image,
+ target,
+ format,
+ return_segmentation_masks=return_segmentation_masks,
+ masks_path=masks_path,
+ input_data_format=input_data_format,
+ )
+ prepared_images.append(image)
+ prepared_annotations.append(target)
+ images = prepared_images
+ annotations = prepared_annotations
+ del prepared_images, prepared_annotations
+
+ # transformations
+ if do_resize:
+ if annotations is not None:
+ resized_images, resized_annotations = [], []
+ for image, target in zip(images, annotations):
+ orig_size = get_image_size(image, input_data_format)
+ resized_image = self.resize(
+ image, size=size, resample=resample, input_data_format=input_data_format
+ )
+ resized_annotation = self.resize_annotation(
+ target, orig_size, get_image_size(resized_image, input_data_format)
+ )
+ resized_images.append(resized_image)
+ resized_annotations.append(resized_annotation)
+ images = resized_images
+ annotations = resized_annotations
+ del resized_images, resized_annotations
+ else:
+ images = [
+ self.resize(image, size=size, resample=resample, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_rescale:
+ images = [self.rescale(image, rescale_factor, input_data_format=input_data_format) for image in images]
+
+ if do_normalize:
+ images = [
+ self.normalize(image, image_mean, image_std, input_data_format=input_data_format) for image in images
+ ]
+
+ if do_convert_annotations and annotations is not None:
+ annotations = [
+ self.normalize_annotation(annotation, get_image_size(image, input_data_format))
+ for annotation, image in zip(annotations, images)
+ ]
+
+ if do_pad:
+ # Pads images and returns their mask: {'pixel_values': ..., 'pixel_mask': ...}
+ encoded_inputs = self.pad(
+ images,
+ annotations=annotations,
+ return_pixel_mask=False,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ update_bboxes=do_convert_annotations,
+ return_tensors=return_tensors,
+ pad_size=pad_size,
+ )
+ else:
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format)
+ for image in images
+ ]
+ encoded_inputs = BatchFeature(data={"pixel_values": images}, tensor_type=return_tensors)
+ if annotations is not None:
+ encoded_inputs["labels"] = [
+ BatchFeature(annotation, tensor_type=return_tensors) for annotation in annotations
+ ]
+
+ return encoded_inputs
+
+ # POSTPROCESSING METHODS - TODO: add support for other frameworks
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.post_process with Detr->Yolos
+ def post_process(self, outputs, target_sizes):
+ """
+ Converts the raw output of [`YolosForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y,
+ bottom_right_x, bottom_right_y) format. Only supports PyTorch.
+
+ Args:
+ outputs ([`YolosObjectDetectionOutput`]):
+ Raw outputs of the model.
+ target_sizes (`torch.Tensor` of shape `(batch_size, 2)`):
+ Tensor containing the size (height, width) of each image of the batch. For evaluation, this must be the
+ original image size (before any data augmentation). For visualization, this should be the image size
+ after data augment, but before padding.
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image
+ in the batch as predicted by the model.
+ """
+ logger.warning_once(
+ "`post_process` is deprecated and will be removed in v5 of Transformers, please use"
+ " `post_process_object_detection` instead, with `threshold=0.` for equivalent results.",
+ )
+
+ out_logits, out_bbox = outputs.logits, outputs.pred_boxes
+
+ if len(out_logits) != len(target_sizes):
+ raise ValueError("Make sure that you pass in as many target sizes as the batch dimension of the logits")
+ if target_sizes.shape[1] != 2:
+ raise ValueError("Each element of target_sizes must contain the size (h, w) of each image of the batch")
+
+ prob = nn.functional.softmax(out_logits, -1)
+ scores, labels = prob[..., :-1].max(-1)
+
+ # convert to [x0, y0, x1, y1] format
+ boxes = center_to_corners_format(out_bbox)
+ # and from relative [0, 1] to absolute [0, height] coordinates
+ img_h, img_w = target_sizes.unbind(1)
+ scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1).to(boxes.device)
+ boxes = boxes * scale_fct[:, None, :]
+
+ results = [{"scores": s, "labels": l, "boxes": b} for s, l, b in zip(scores, labels, boxes)]
+ return results
+
+ # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.post_process_object_detection with Detr->Yolos
+ def post_process_object_detection(
+ self, outputs, threshold: float = 0.5, target_sizes: Union[TensorType, list[tuple]] = None
+ ):
+ """
+ Converts the raw output of [`YolosForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y,
+ bottom_right_x, bottom_right_y) format. Only supports PyTorch.
+
+ Args:
+ outputs ([`YolosObjectDetectionOutput`]):
+ Raw outputs of the model.
+ threshold (`float`, *optional*):
+ Score threshold to keep object detection predictions.
+ target_sizes (`torch.Tensor` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size
+ `(height, width)` of each image in the batch. If unset, predictions will not be resized.
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image
+ in the batch as predicted by the model.
+ """
+ out_logits, out_bbox = outputs.logits, outputs.pred_boxes
+
+ if target_sizes is not None:
+ if len(out_logits) != len(target_sizes):
+ raise ValueError(
+ "Make sure that you pass in as many target sizes as the batch dimension of the logits"
+ )
+
+ prob = nn.functional.softmax(out_logits, -1)
+ scores, labels = prob[..., :-1].max(-1)
+
+ # Convert to [x0, y0, x1, y1] format
+ boxes = center_to_corners_format(out_bbox)
+
+ # Convert from relative [0, 1] to absolute [0, height] coordinates
+ if target_sizes is not None:
+ if isinstance(target_sizes, list):
+ img_h = torch.Tensor([i[0] for i in target_sizes])
+ img_w = torch.Tensor([i[1] for i in target_sizes])
+ else:
+ img_h, img_w = target_sizes.unbind(1)
+
+ scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1).to(boxes.device)
+ boxes = boxes * scale_fct[:, None, :]
+
+ results = []
+ for s, l, b in zip(scores, labels, boxes):
+ score = s[s > threshold]
+ label = l[s > threshold]
+ box = b[s > threshold]
+ results.append({"scores": score, "labels": label, "boxes": box})
+
+ return results
+
+
+__all__ = ["YolosImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/image_processing_yolos_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/image_processing_yolos_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..85aeba94bfcc5ab3f02ad39e83e89e91c0bfb0a7
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/image_processing_yolos_fast.py
@@ -0,0 +1,876 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/yolos/modular_yolos.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_yolos.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+import pathlib
+from typing import Any, Optional, Union
+
+from ...image_processing_utils import BatchFeature, get_size_dict
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ SizeDict,
+ get_image_size_for_max_height_width,
+ get_max_height_width,
+ safe_squeeze,
+)
+from ...image_transforms import center_to_corners_format, corners_to_center_format
+from ...image_utils import (
+ IMAGENET_DEFAULT_MEAN,
+ IMAGENET_DEFAULT_STD,
+ AnnotationFormat,
+ AnnotationType,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ get_image_size,
+ validate_annotations,
+)
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+ logging,
+)
+from ...utils.import_utils import requires
+
+
+if is_torch_available():
+ import torch
+
+
+if is_torchvision_v2_available():
+ from torchvision.io import read_image
+ from torchvision.transforms.v2 import functional as F
+
+elif is_torchvision_available():
+ from torchvision.io import read_image
+ from torchvision.transforms import functional as F
+
+
+logger = logging.get_logger(__name__)
+
+
+class YolosFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ r"""
+ format (`str`, *optional*, defaults to `AnnotationFormat.COCO_DETECTION`):
+ Data format of the annotations. One of "coco_detection" or "coco_panoptic".
+ do_convert_annotations (`bool`, *optional*, defaults to `True`):
+ Controls whether to convert the annotations to the format expected by the YOLOS model. Converts the
+ bounding boxes to the format `(center_x, center_y, width, height)` and in the range `[0, 1]`.
+ Can be overridden by the `do_convert_annotations` parameter in the `preprocess` method.
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Controls whether to pad the image. Can be overridden by the `do_pad` parameter in the `preprocess`
+ method. If `True`, padding will be applied to the bottom and right of the image with zeros.
+ If `pad_size` is provided, the image will be padded to the specified dimensions.
+ Otherwise, the image will be padded to the maximum height and width of the batch.
+ pad_size (`dict[str, int]`, *optional*):
+ The size `{"height": int, "width" int}` to pad the images to. Must be larger than any image size
+ provided for preprocessing. If `pad_size` is not provided, images will be padded to the largest
+ height and width in the batch.
+ return_segmentation_masks (`bool`, *optional*, defaults to `False`):
+ Whether to return segmentation masks.
+ """
+
+ format: Optional[Union[str, AnnotationFormat]]
+ do_convert_annotations: Optional[bool]
+ do_pad: Optional[bool]
+ pad_size: Optional[dict[str, int]]
+ return_segmentation_masks: Optional[bool]
+
+
+SUPPORTED_ANNOTATION_FORMATS = (AnnotationFormat.COCO_DETECTION, AnnotationFormat.COCO_PANOPTIC)
+
+
+# inspired by https://github.com/facebookresearch/yolos/blob/master/datasets/coco.py#L33
+def convert_coco_poly_to_mask(segmentations, height: int, width: int, device: torch.device) -> torch.Tensor:
+ """
+ Convert a COCO polygon annotation to a mask.
+
+ Args:
+ segmentations (`list[list[float]]`):
+ List of polygons, each polygon represented by a list of x-y coordinates.
+ height (`int`):
+ Height of the mask.
+ width (`int`):
+ Width of the mask.
+ """
+ try:
+ from pycocotools import mask as coco_mask
+ except ImportError:
+ raise ImportError("Pycocotools is not installed in your environment.")
+
+ masks = []
+ for polygons in segmentations:
+ rles = coco_mask.frPyObjects(polygons, height, width)
+ mask = coco_mask.decode(rles)
+ if len(mask.shape) < 3:
+ mask = mask[..., None]
+ mask = torch.as_tensor(mask, dtype=torch.uint8, device=device)
+ mask = torch.any(mask, axis=2)
+ masks.append(mask)
+ if masks:
+ masks = torch.stack(masks, axis=0)
+ else:
+ masks = torch.zeros((0, height, width), dtype=torch.uint8, device=device)
+
+ return masks
+
+
+# inspired by https://github.com/facebookresearch/yolos/blob/master/datasets/coco.py#L50
+def prepare_coco_detection_annotation(
+ image,
+ target,
+ return_segmentation_masks: bool = False,
+ input_data_format: Optional[Union[ChannelDimension, str]] = None,
+):
+ """
+ Convert the target in COCO format into the format expected by YOLOS.
+ """
+ image_height, image_width = image.size()[-2:]
+
+ image_id = target["image_id"]
+ image_id = torch.as_tensor([image_id], dtype=torch.int64, device=image.device)
+
+ # Get all COCO annotations for the given image.
+ annotations = target["annotations"]
+ classes = []
+ area = []
+ boxes = []
+ keypoints = []
+ for obj in annotations:
+ if "iscrowd" not in obj or obj["iscrowd"] == 0:
+ classes.append(obj["category_id"])
+ area.append(obj["area"])
+ boxes.append(obj["bbox"])
+ if "keypoints" in obj:
+ keypoints.append(obj["keypoints"])
+
+ classes = torch.as_tensor(classes, dtype=torch.int64, device=image.device)
+ area = torch.as_tensor(area, dtype=torch.float32, device=image.device)
+ iscrowd = torch.zeros_like(classes, dtype=torch.int64, device=image.device)
+ # guard against no boxes via resizing
+ boxes = torch.as_tensor(boxes, dtype=torch.float32, device=image.device).reshape(-1, 4)
+ boxes[:, 2:] += boxes[:, :2]
+ boxes[:, 0::2] = boxes[:, 0::2].clip(min=0, max=image_width)
+ boxes[:, 1::2] = boxes[:, 1::2].clip(min=0, max=image_height)
+
+ keep = (boxes[:, 3] > boxes[:, 1]) & (boxes[:, 2] > boxes[:, 0])
+
+ new_target = {
+ "image_id": image_id,
+ "class_labels": classes[keep],
+ "boxes": boxes[keep],
+ "area": area[keep],
+ "iscrowd": iscrowd[keep],
+ "orig_size": torch.as_tensor([int(image_height), int(image_width)], dtype=torch.int64, device=image.device),
+ }
+
+ if keypoints:
+ keypoints = torch.as_tensor(keypoints, dtype=torch.float32, device=image.device)
+ # Apply the keep mask here to filter the relevant annotations
+ keypoints = keypoints[keep]
+ num_keypoints = keypoints.shape[0]
+ keypoints = keypoints.reshape((-1, 3)) if num_keypoints else keypoints
+ new_target["keypoints"] = keypoints
+
+ if return_segmentation_masks:
+ segmentation_masks = [obj["segmentation"] for obj in annotations]
+ masks = convert_coco_poly_to_mask(segmentation_masks, image_height, image_width, device=image.device)
+ new_target["masks"] = masks[keep]
+
+ return new_target
+
+
+def masks_to_boxes(masks: torch.Tensor) -> torch.Tensor:
+ """
+ Compute the bounding boxes around the provided panoptic segmentation masks.
+
+ Args:
+ masks: masks in format `[number_masks, height, width]` where N is the number of masks
+
+ Returns:
+ boxes: bounding boxes in format `[number_masks, 4]` in xyxy format
+ """
+ if masks.numel() == 0:
+ return torch.zeros((0, 4), device=masks.device)
+
+ h, w = masks.shape[-2:]
+ y = torch.arange(0, h, dtype=torch.float32, device=masks.device)
+ x = torch.arange(0, w, dtype=torch.float32, device=masks.device)
+ # see https://github.com/pytorch/pytorch/issues/50276
+ y, x = torch.meshgrid(y, x, indexing="ij")
+
+ x_mask = masks * torch.unsqueeze(x, 0)
+ x_max = x_mask.view(x_mask.shape[0], -1).max(-1)[0]
+ x_min = (
+ torch.where(masks, x.unsqueeze(0), torch.tensor(1e8, device=masks.device)).view(masks.shape[0], -1).min(-1)[0]
+ )
+
+ y_mask = masks * torch.unsqueeze(y, 0)
+ y_max = y_mask.view(y_mask.shape[0], -1).max(-1)[0]
+ y_min = (
+ torch.where(masks, y.unsqueeze(0), torch.tensor(1e8, device=masks.device)).view(masks.shape[0], -1).min(-1)[0]
+ )
+
+ return torch.stack([x_min, y_min, x_max, y_max], 1)
+
+
+# 2 functions below adapted from https://github.com/cocodataset/panopticapi/blob/master/panopticapi/utils.py
+# Copyright (c) 2018, Alexander Kirillov
+# All rights reserved.
+def rgb_to_id(color):
+ """
+ Converts RGB color to unique ID.
+ """
+ if isinstance(color, torch.Tensor) and len(color.shape) == 3:
+ if color.dtype == torch.uint8:
+ color = color.to(torch.int32)
+ return color[:, :, 0] + 256 * color[:, :, 1] + 256 * 256 * color[:, :, 2]
+ return int(color[0] + 256 * color[1] + 256 * 256 * color[2])
+
+
+def prepare_coco_panoptic_annotation(
+ image: torch.Tensor,
+ target: dict,
+ masks_path: Union[str, pathlib.Path],
+ return_masks: bool = True,
+ input_data_format: Union[ChannelDimension, str] = None,
+) -> dict:
+ """
+ Prepare a coco panoptic annotation for YOLOS.
+ """
+ image_height, image_width = get_image_size(image, channel_dim=input_data_format)
+ annotation_path = pathlib.Path(masks_path) / target["file_name"]
+
+ new_target = {}
+ new_target["image_id"] = torch.as_tensor(
+ [target["image_id"] if "image_id" in target else target["id"]], dtype=torch.int64, device=image.device
+ )
+ new_target["size"] = torch.as_tensor([image_height, image_width], dtype=torch.int64, device=image.device)
+ new_target["orig_size"] = torch.as_tensor([image_height, image_width], dtype=torch.int64, device=image.device)
+
+ if "segments_info" in target:
+ masks = read_image(annotation_path).permute(1, 2, 0).to(dtype=torch.int32, device=image.device)
+ masks = rgb_to_id(masks)
+
+ ids = torch.as_tensor([segment_info["id"] for segment_info in target["segments_info"]], device=image.device)
+ masks = masks == ids[:, None, None]
+ masks = masks.to(torch.bool)
+ if return_masks:
+ new_target["masks"] = masks
+ new_target["boxes"] = masks_to_boxes(masks)
+ new_target["class_labels"] = torch.as_tensor(
+ [segment_info["category_id"] for segment_info in target["segments_info"]],
+ dtype=torch.int64,
+ device=image.device,
+ )
+ new_target["iscrowd"] = torch.as_tensor(
+ [segment_info["iscrowd"] for segment_info in target["segments_info"]],
+ dtype=torch.int64,
+ device=image.device,
+ )
+ new_target["area"] = torch.as_tensor(
+ [segment_info["area"] for segment_info in target["segments_info"]],
+ dtype=torch.float32,
+ device=image.device,
+ )
+
+ return new_target
+
+
+def get_size_with_aspect_ratio(
+ image_size: tuple[int, int], size: int, max_size: Optional[int] = None, mod_size: int = 16
+) -> tuple[int, int]:
+ """
+ Computes the output image size given the input image size and the desired output size with multiple of divisible_size.
+
+ Args:
+ image_size (`tuple[int, int]`):
+ The input image size.
+ size (`int`):
+ The desired output size.
+ max_size (`int`, *optional*):
+ The maximum allowed output size.
+ mod_size (`int`, *optional*):
+ The size to make multiple of mod_size.
+ """
+ height, width = image_size
+ raw_size = None
+ if max_size is not None:
+ min_original_size = float(min((height, width)))
+ max_original_size = float(max((height, width)))
+ if max_original_size / min_original_size * size > max_size:
+ raw_size = max_size * min_original_size / max_original_size
+ size = int(round(raw_size))
+
+ if width < height:
+ ow = size
+ if max_size is not None and raw_size is not None:
+ oh = int(raw_size * height / width)
+ else:
+ oh = int(size * height / width)
+ elif (height <= width and height == size) or (width <= height and width == size):
+ oh, ow = height, width
+ else:
+ oh = size
+ if max_size is not None and raw_size is not None:
+ ow = int(raw_size * width / height)
+ else:
+ ow = int(size * width / height)
+
+ if mod_size is not None:
+ ow_mod = torch.remainder(torch.tensor(ow), mod_size).item()
+ oh_mod = torch.remainder(torch.tensor(oh), mod_size).item()
+ ow = ow - ow_mod
+ oh = oh - oh_mod
+
+ return (oh, ow)
+
+
+@auto_docstring
+@requires(backends=("torchvision", "torch"))
+class YolosImageProcessorFast(BaseImageProcessorFast):
+ resample = PILImageResampling.BILINEAR
+ image_mean = IMAGENET_DEFAULT_MEAN
+ image_std = IMAGENET_DEFAULT_STD
+ format = AnnotationFormat.COCO_DETECTION
+ do_resize = True
+ do_rescale = True
+ do_normalize = True
+ do_pad = True
+ size = {"shortest_edge": 800, "longest_edge": 1333}
+ default_to_square = False
+ model_input_names = ["pixel_values", "pixel_mask"]
+ valid_kwargs = YolosFastImageProcessorKwargs
+
+ def __init__(self, **kwargs: Unpack[YolosFastImageProcessorKwargs]) -> None:
+ if "pad_and_return_pixel_mask" in kwargs:
+ kwargs["do_pad"] = kwargs.pop("pad_and_return_pixel_mask")
+
+ size = kwargs.pop("size", None)
+ if "max_size" in kwargs:
+ logger.warning_once(
+ "The `max_size` parameter is deprecated and will be removed in v4.26. "
+ "Please specify in `size['longest_edge'] instead`.",
+ )
+ max_size = kwargs.pop("max_size")
+ else:
+ max_size = None if size is None else 1333
+
+ size = size if size is not None else {"shortest_edge": 800, "longest_edge": 1333}
+ self.size = get_size_dict(size, max_size=max_size, default_to_square=False)
+
+ # Backwards compatibility
+ do_convert_annotations = kwargs.get("do_convert_annotations")
+ do_normalize = kwargs.get("do_normalize")
+ if do_convert_annotations is None and getattr(self, "do_convert_annotations", None) is None:
+ self.do_convert_annotations = do_normalize if do_normalize is not None else self.do_normalize
+
+ super().__init__(**kwargs)
+
+ @classmethod
+ def from_dict(cls, image_processor_dict: dict[str, Any], **kwargs):
+ """
+ Overrides the `from_dict` method from the base class to make sure parameters are updated if image processor is
+ created using from_dict and kwargs e.g. `YolosImageProcessorFast.from_pretrained(checkpoint, size=600,
+ max_size=800)`
+ """
+ image_processor_dict = image_processor_dict.copy()
+ if "max_size" in kwargs:
+ image_processor_dict["max_size"] = kwargs.pop("max_size")
+ if "pad_and_return_pixel_mask" in kwargs:
+ image_processor_dict["pad_and_return_pixel_mask"] = kwargs.pop("pad_and_return_pixel_mask")
+ return super().from_dict(image_processor_dict, **kwargs)
+
+ def prepare_annotation(
+ self,
+ image: torch.Tensor,
+ target: dict,
+ format: Optional[AnnotationFormat] = None,
+ return_segmentation_masks: Optional[bool] = None,
+ masks_path: Optional[Union[str, pathlib.Path]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> dict:
+ """
+ Prepare an annotation for feeding into YOLOS model.
+ """
+ format = format if format is not None else self.format
+
+ if format == AnnotationFormat.COCO_DETECTION:
+ return_segmentation_masks = False if return_segmentation_masks is None else return_segmentation_masks
+ target = prepare_coco_detection_annotation(
+ image, target, return_segmentation_masks, input_data_format=input_data_format
+ )
+ elif format == AnnotationFormat.COCO_PANOPTIC:
+ return_segmentation_masks = True if return_segmentation_masks is None else return_segmentation_masks
+ target = prepare_coco_panoptic_annotation(
+ image,
+ target,
+ masks_path=masks_path,
+ return_masks=return_segmentation_masks,
+ input_data_format=input_data_format,
+ )
+ else:
+ raise ValueError(f"Format {format} is not supported.")
+ return target
+
+ def resize(
+ self,
+ image: torch.Tensor,
+ size: SizeDict,
+ interpolation: "F.InterpolationMode" = None,
+ **kwargs,
+ ) -> torch.Tensor:
+ """
+ Resize the image to the given size. Size can be `min_size` (scalar) or `(height, width)` tuple. If size is an
+ int, smaller edge of the image will be matched to this number.
+
+ Args:
+ image (`torch.Tensor`):
+ Image to resize.
+ size (`SizeDict`):
+ Size of the image's `(height, width)` dimensions after resizing. Available options are:
+ - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`.
+ Do NOT keep the aspect ratio.
+ - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting
+ the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge
+ less or equal to `longest_edge`.
+ - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the
+ aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to
+ `max_width`.
+ interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`):
+ Resampling filter to use if resizing the image.
+ """
+ interpolation = interpolation if interpolation is not None else F.InterpolationMode.BILINEAR
+ if size.shortest_edge and size.longest_edge:
+ # Resize the image so that the shortest edge or the longest edge is of the given size
+ # while maintaining the aspect ratio of the original image.
+ new_size = get_size_with_aspect_ratio(
+ image.size()[-2:],
+ size["shortest_edge"],
+ size["longest_edge"],
+ )
+ elif size.max_height and size.max_width:
+ new_size = get_image_size_for_max_height_width(image.size()[-2:], size["max_height"], size["max_width"])
+ elif size.height and size.width:
+ new_size = (size["height"], size["width"])
+ else:
+ raise ValueError(
+ "Size must contain 'height' and 'width' keys or 'shortest_edge' and 'longest_edge' keys. Got"
+ f" {size.keys()}."
+ )
+
+ image = F.resize(
+ image,
+ size=new_size,
+ interpolation=interpolation,
+ **kwargs,
+ )
+ return image
+
+ def resize_annotation(
+ self,
+ annotation: dict[str, Any],
+ orig_size: tuple[int, int],
+ target_size: tuple[int, int],
+ threshold: float = 0.5,
+ interpolation: "F.InterpolationMode" = None,
+ ):
+ """
+ Resizes an annotation to a target size.
+
+ Args:
+ annotation (`dict[str, Any]`):
+ The annotation dictionary.
+ orig_size (`tuple[int, int]`):
+ The original size of the input image.
+ target_size (`tuple[int, int]`):
+ The target size of the image, as returned by the preprocessing `resize` step.
+ threshold (`float`, *optional*, defaults to 0.5):
+ The threshold used to binarize the segmentation masks.
+ resample (`InterpolationMode`, defaults to `F.InterpolationMode.NEAREST_EXACT`):
+ The resampling filter to use when resizing the masks.
+ """
+ interpolation = (
+ interpolation
+ if interpolation is not None
+ else F.InterpolationMode.NEAREST_EXACT
+ if is_torchvision_v2_available()
+ else F.InterpolationMode.NEAREST
+ )
+ ratio_height, ratio_width = [target / orig for target, orig in zip(target_size, orig_size)]
+
+ new_annotation = {}
+ new_annotation["size"] = target_size
+
+ for key, value in annotation.items():
+ if key == "boxes":
+ boxes = value
+ scaled_boxes = boxes * torch.as_tensor(
+ [ratio_width, ratio_height, ratio_width, ratio_height], dtype=torch.float32, device=boxes.device
+ )
+ new_annotation["boxes"] = scaled_boxes
+ elif key == "area":
+ area = value
+ scaled_area = area * (ratio_width * ratio_height)
+ new_annotation["area"] = scaled_area
+ elif key == "masks":
+ masks = value[:, None]
+ masks = [F.resize(mask, target_size, interpolation=interpolation) for mask in masks]
+ masks = torch.stack(masks).to(torch.float32)
+ masks = masks[:, 0] > threshold
+ new_annotation["masks"] = masks
+ elif key == "size":
+ new_annotation["size"] = target_size
+ else:
+ new_annotation[key] = value
+
+ return new_annotation
+
+ def normalize_annotation(self, annotation: dict, image_size: tuple[int, int]) -> dict:
+ image_height, image_width = image_size
+ norm_annotation = {}
+ for key, value in annotation.items():
+ if key == "boxes":
+ boxes = value
+ boxes = corners_to_center_format(boxes)
+ boxes /= torch.as_tensor(
+ [image_width, image_height, image_width, image_height], dtype=torch.float32, device=boxes.device
+ )
+ norm_annotation[key] = boxes
+ else:
+ norm_annotation[key] = value
+ return norm_annotation
+
+ def _update_annotation_for_padded_image(
+ self,
+ annotation: dict,
+ input_image_size: tuple[int, int],
+ output_image_size: tuple[int, int],
+ padding,
+ update_bboxes,
+ ) -> dict:
+ """
+ Update the annotation for a padded image.
+ """
+ new_annotation = {}
+ new_annotation["size"] = output_image_size
+ ratio_height, ratio_width = (input / output for output, input in zip(output_image_size, input_image_size))
+
+ for key, value in annotation.items():
+ if key == "masks":
+ masks = value
+ masks = F.pad(
+ masks,
+ padding,
+ fill=0,
+ )
+ masks = safe_squeeze(masks, 1)
+ new_annotation["masks"] = masks
+ elif key == "boxes" and update_bboxes:
+ boxes = value
+ boxes *= torch.as_tensor([ratio_width, ratio_height, ratio_width, ratio_height], device=boxes.device)
+ new_annotation["boxes"] = boxes
+ elif key == "size":
+ new_annotation["size"] = output_image_size
+ else:
+ new_annotation[key] = value
+ return new_annotation
+
+ def pad(
+ self,
+ image: torch.Tensor,
+ padded_size: tuple[int, int],
+ annotation: Optional[dict[str, Any]] = None,
+ update_bboxes: bool = True,
+ fill: int = 0,
+ ):
+ original_size = image.size()[-2:]
+ padding_bottom = padded_size[0] - original_size[0]
+ padding_right = padded_size[1] - original_size[1]
+ if padding_bottom < 0 or padding_right < 0:
+ raise ValueError(
+ f"Padding dimensions are negative. Please make sure that the padded size is larger than the "
+ f"original size. Got padded size: {padded_size}, original size: {original_size}."
+ )
+ if original_size != padded_size:
+ padding = [0, 0, padding_right, padding_bottom]
+ image = F.pad(image, padding, fill=fill)
+ if annotation is not None:
+ annotation = self._update_annotation_for_padded_image(
+ annotation, original_size, padded_size, padding, update_bboxes
+ )
+
+ # Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding.
+ pixel_mask = torch.zeros(padded_size, dtype=torch.int64, device=image.device)
+ pixel_mask[: original_size[0], : original_size[1]] = 1
+
+ return image, pixel_mask, annotation
+
+ @auto_docstring
+ def preprocess(
+ self,
+ images: ImageInput,
+ annotations: Optional[Union[AnnotationType, list[AnnotationType]]] = None,
+ masks_path: Optional[Union[str, pathlib.Path]] = None,
+ **kwargs: Unpack[YolosFastImageProcessorKwargs],
+ ) -> BatchFeature:
+ r"""
+ annotations (`AnnotationType` or `list[AnnotationType]`, *optional*):
+ List of annotations associated with the image or batch of images. If annotation is for object
+ detection, the annotations should be a dictionary with the following keys:
+ - "image_id" (`int`): The image id.
+ - "annotations" (`list[Dict]`): List of annotations for an image. Each annotation should be a
+ dictionary. An image can have no annotations, in which case the list should be empty.
+ If annotation is for segmentation, the annotations should be a dictionary with the following keys:
+ - "image_id" (`int`): The image id.
+ - "segments_info" (`list[Dict]`): List of segments for an image. Each segment should be a dictionary.
+ An image can have no segments, in which case the list should be empty.
+ - "file_name" (`str`): The file name of the image.
+ masks_path (`str` or `pathlib.Path`, *optional*):
+ Path to the directory containing the segmentation masks.
+ """
+ if "pad_and_return_pixel_mask" in kwargs:
+ kwargs["do_pad"] = kwargs.pop("pad_and_return_pixel_mask")
+ logger.warning_once(
+ "The `pad_and_return_pixel_mask` argument is deprecated and will be removed in a future version, "
+ "use `do_pad` instead."
+ )
+
+ if "max_size" in kwargs:
+ logger.warning_once(
+ "The `max_size` argument is deprecated and will be removed in a future version, use"
+ " `size['longest_edge']` instead."
+ )
+ kwargs["size"] = kwargs.pop("max_size")
+
+ return super().preprocess(images, annotations, masks_path, **kwargs)
+
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ annotations: Optional[Union[AnnotationType, list[AnnotationType]]],
+ masks_path: Optional[Union[str, pathlib.Path]],
+ return_segmentation_masks: bool,
+ do_resize: bool,
+ size: SizeDict,
+ interpolation: Optional["F.InterpolationMode"],
+ do_rescale: bool,
+ rescale_factor: float,
+ do_normalize: bool,
+ do_convert_annotations: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ do_pad: bool,
+ pad_size: Optional[dict[str, int]],
+ format: Optional[Union[str, AnnotationFormat]],
+ return_tensors: Optional[Union[str, TensorType]],
+ **kwargs,
+ ) -> BatchFeature:
+ """
+ Preprocess an image or a batch of images so that it can be used by the model.
+ """
+ if annotations is not None and isinstance(annotations, dict):
+ annotations = [annotations]
+
+ if annotations is not None and len(images) != len(annotations):
+ raise ValueError(
+ f"The number of images ({len(images)}) and annotations ({len(annotations)}) do not match."
+ )
+
+ format = AnnotationFormat(format)
+ if annotations is not None:
+ validate_annotations(format, SUPPORTED_ANNOTATION_FORMATS, annotations)
+
+ if (
+ masks_path is not None
+ and format == AnnotationFormat.COCO_PANOPTIC
+ and not isinstance(masks_path, (pathlib.Path, str))
+ ):
+ raise ValueError(
+ "The path to the directory containing the mask PNG files should be provided as a"
+ f" `pathlib.Path` or string object, but is {type(masks_path)} instead."
+ )
+
+ data = {}
+
+ processed_images = []
+ processed_annotations = []
+ pixel_masks = [] # Initialize pixel_masks here
+ for image, annotation in zip(images, annotations if annotations is not None else [None] * len(images)):
+ # prepare (COCO annotations as a list of Dict -> YOLOS target as a single Dict per image)
+ if annotations is not None:
+ annotation = self.prepare_annotation(
+ image,
+ annotation,
+ format,
+ return_segmentation_masks=return_segmentation_masks,
+ masks_path=masks_path,
+ input_data_format=ChannelDimension.FIRST,
+ )
+
+ if do_resize:
+ resized_image = self.resize(image, size=size, interpolation=interpolation)
+ if annotations is not None:
+ annotation = self.resize_annotation(
+ annotation,
+ orig_size=image.size()[-2:],
+ target_size=resized_image.size()[-2:],
+ )
+ image = resized_image
+ # Fused rescale and normalize
+ image = self.rescale_and_normalize(image, do_rescale, rescale_factor, do_normalize, image_mean, image_std)
+ if do_convert_annotations and annotations is not None:
+ annotation = self.normalize_annotation(annotation, get_image_size(image, ChannelDimension.FIRST))
+
+ processed_images.append(image)
+ processed_annotations.append(annotation)
+ images = processed_images
+ annotations = processed_annotations if annotations is not None else None
+
+ if do_pad:
+ # depends on all resized image shapes so we need another loop
+ if pad_size is not None:
+ padded_size = (pad_size["height"], pad_size["width"])
+ else:
+ padded_size = get_max_height_width(images)
+
+ padded_images = []
+ padded_annotations = []
+ for image, annotation in zip(images, annotations if annotations is not None else [None] * len(images)):
+ # Pads images and returns their mask: {'pixel_values': ..., 'pixel_mask': ...}
+ if padded_size == image.size()[-2:]:
+ padded_images.append(image)
+ pixel_masks.append(torch.ones(padded_size, dtype=torch.int64, device=image.device))
+ padded_annotations.append(annotation)
+ continue
+ image, pixel_mask, annotation = self.pad(
+ image, padded_size, annotation=annotation, update_bboxes=do_convert_annotations
+ )
+ padded_images.append(image)
+ padded_annotations.append(annotation)
+ pixel_masks.append(pixel_mask)
+ images = padded_images
+ annotations = padded_annotations if annotations is not None else None
+ data.update({"pixel_mask": torch.stack(pixel_masks, dim=0)})
+
+ data.update({"pixel_values": torch.stack(images, dim=0)})
+ encoded_inputs = BatchFeature(data, tensor_type=return_tensors)
+ if annotations is not None:
+ encoded_inputs["labels"] = [
+ BatchFeature(annotation, tensor_type=return_tensors) for annotation in annotations
+ ]
+ return encoded_inputs
+
+ def post_process(self, outputs, target_sizes):
+ """
+ Converts the raw output of [`YolosForObjectDetection`] into final bounding boxes in (top_left_x,
+ top_left_y, bottom_right_x, bottom_right_y) format. Only supports PyTorch.
+
+ Args:
+ outputs ([`YolosObjectDetectionOutput`]):
+ Raw outputs of the model.
+ target_sizes (`torch.Tensor` of shape `(batch_size, 2)`):
+ Tensor containing the size (height, width) of each image of the batch. For evaluation, this must be the
+ original image size (before any data augmentation). For visualization, this should be the image size
+ after data augment, but before padding.
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image
+ in the batch as predicted by the model.
+ """
+ logger.warning_once(
+ "`post_process` is deprecated and will be removed in v5 of Transformers, please use"
+ " `post_process_object_detection` instead, with `threshold=0.` for equivalent results.",
+ )
+
+ out_logits, out_bbox = outputs.logits, outputs.pred_boxes
+
+ if len(out_logits) != len(target_sizes):
+ raise ValueError("Make sure that you pass in as many target sizes as the batch dimension of the logits")
+ if target_sizes.shape[1] != 2:
+ raise ValueError("Each element of target_sizes must contain the size (h, w) of each image of the batch")
+
+ prob = out_logits.sigmoid()
+ topk_values, topk_indexes = torch.topk(prob.view(out_logits.shape[0], -1), 100, dim=1)
+ scores = topk_values
+ topk_boxes = torch.div(topk_indexes, out_logits.shape[2], rounding_mode="floor")
+ labels = topk_indexes % out_logits.shape[2]
+ boxes = center_to_corners_format(out_bbox)
+ boxes = torch.gather(boxes, 1, topk_boxes.unsqueeze(-1).repeat(1, 1, 4))
+
+ # and from relative [0, 1] to absolute [0, height] coordinates
+ img_h, img_w = target_sizes.unbind(1)
+ scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1)
+ boxes = boxes * scale_fct[:, None, :]
+
+ results = [{"scores": s, "labels": l, "boxes": b} for s, l, b in zip(scores, labels, boxes)]
+
+ return results
+
+ def post_process_object_detection(
+ self, outputs, threshold: float = 0.5, target_sizes: Union[TensorType, list[tuple]] = None, top_k: int = 100
+ ):
+ """
+ Converts the raw output of [`YolosForObjectDetection`] into final bounding boxes in (top_left_x,
+ top_left_y, bottom_right_x, bottom_right_y) format. Only supports PyTorch.
+
+ Args:
+ outputs ([`YolosObjectDetectionOutput`]):
+ Raw outputs of the model.
+ threshold (`float`, *optional*):
+ Score threshold to keep object detection predictions.
+ target_sizes (`torch.Tensor` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size
+ (height, width) of each image in the batch. If left to None, predictions will not be resized.
+ top_k (`int`, *optional*, defaults to 100):
+ Keep only top k bounding boxes before filtering by thresholding.
+
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image
+ in the batch as predicted by the model.
+ """
+ out_logits, out_bbox = outputs.logits, outputs.pred_boxes
+
+ if target_sizes is not None:
+ if len(out_logits) != len(target_sizes):
+ raise ValueError(
+ "Make sure that you pass in as many target sizes as the batch dimension of the logits"
+ )
+
+ prob = out_logits.sigmoid()
+ prob = prob.view(out_logits.shape[0], -1)
+ k_value = min(top_k, prob.size(1))
+ topk_values, topk_indexes = torch.topk(prob, k_value, dim=1)
+ scores = topk_values
+ topk_boxes = torch.div(topk_indexes, out_logits.shape[2], rounding_mode="floor")
+ labels = topk_indexes % out_logits.shape[2]
+ boxes = center_to_corners_format(out_bbox)
+ boxes = torch.gather(boxes, 1, topk_boxes.unsqueeze(-1).repeat(1, 1, 4))
+
+ # and from relative [0, 1] to absolute [0, height] coordinates
+ if target_sizes is not None:
+ if isinstance(target_sizes, list):
+ img_h = torch.Tensor([i[0] for i in target_sizes])
+ img_w = torch.Tensor([i[1] for i in target_sizes])
+ else:
+ img_h, img_w = target_sizes.unbind(1)
+ scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1).to(boxes.device)
+ boxes = boxes * scale_fct[:, None, :]
+
+ results = []
+ for s, l, b in zip(scores, labels, boxes):
+ score = s[s > threshold]
+ label = l[s > threshold]
+ box = b[s > threshold]
+ results.append({"scores": score, "labels": label, "boxes": box})
+
+ return results
+
+
+__all__ = ["YolosImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/modeling_yolos.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/modeling_yolos.py
new file mode 100644
index 0000000000000000000000000000000000000000..2571cf82733d700cea595bb6fd7710f286358dd8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/modeling_yolos.py
@@ -0,0 +1,705 @@
+# coding=utf-8
+# Copyright 2022 School of EIC, Huazhong University of Science & Technology and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch YOLOS model."""
+
+import collections.abc
+from dataclasses import dataclass
+from typing import Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...pytorch_utils import find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import ModelOutput, TransformersKwargs, auto_docstring, logging
+from ...utils.generic import can_return_tuple, check_model_inputs
+from .configuration_yolos import YolosConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Output type of [`YolosForObjectDetection`].
+ """
+)
+class YolosObjectDetectionOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` are provided)):
+ Total loss as a linear combination of a negative log-likehood (cross-entropy) for class prediction and a
+ bounding box loss. The latter is defined as a linear combination of the L1 loss and the generalized
+ scale-invariant IoU loss.
+ loss_dict (`Dict`, *optional*):
+ A dictionary containing the individual losses. Useful for logging.
+ logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`):
+ Classification logits (including no-object) for all queries.
+ pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`):
+ Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These
+ values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding
+ possible padding). You can use [`~YolosImageProcessor.post_process`] to retrieve the unnormalized bounding
+ boxes.
+ auxiliary_outputs (`list[Dict]`, *optional*):
+ Optional, only returned when auxiliary losses are activated (i.e. `config.auxiliary_loss` is set to `True`)
+ and labels are provided. It is a list of dictionaries containing the two above keys (`logits` and
+ `pred_boxes`) for each decoder layer.
+ last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*):
+ Sequence of hidden-states at the output of the last layer of the decoder of the model.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ loss_dict: Optional[dict] = None
+ logits: Optional[torch.FloatTensor] = None
+ pred_boxes: Optional[torch.FloatTensor] = None
+ auxiliary_outputs: Optional[list[dict]] = None
+ last_hidden_state: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor]] = None
+ attentions: Optional[tuple[torch.FloatTensor]] = None
+
+
+class YolosEmbeddings(nn.Module):
+ """
+ Construct the CLS token, detection tokens, position and patch embeddings.
+
+ """
+
+ def __init__(self, config: YolosConfig) -> None:
+ super().__init__()
+
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, config.hidden_size))
+ self.detection_tokens = nn.Parameter(torch.zeros(1, config.num_detection_tokens, config.hidden_size))
+ self.patch_embeddings = YolosPatchEmbeddings(config)
+ num_patches = self.patch_embeddings.num_patches
+ self.position_embeddings = nn.Parameter(
+ torch.zeros(1, num_patches + config.num_detection_tokens + 1, config.hidden_size)
+ )
+
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.interpolation = InterpolateInitialPositionEmbeddings(config)
+ self.config = config
+
+ def forward(self, pixel_values: torch.Tensor) -> torch.Tensor:
+ batch_size, num_channels, height, width = pixel_values.shape
+ embeddings = self.patch_embeddings(pixel_values)
+
+ batch_size, seq_len, _ = embeddings.size()
+
+ # add the [CLS] and detection tokens to the embedded patch tokens
+ cls_tokens = self.cls_token.expand(batch_size, -1, -1)
+ detection_tokens = self.detection_tokens.expand(batch_size, -1, -1)
+ embeddings = torch.cat((cls_tokens, embeddings, detection_tokens), dim=1)
+
+ # add positional encoding to each token
+ # this might require interpolation of the existing position embeddings
+ position_embeddings = self.interpolation(self.position_embeddings, (height, width))
+
+ embeddings = embeddings + position_embeddings
+ embeddings = self.dropout(embeddings)
+
+ return embeddings
+
+
+class InterpolateInitialPositionEmbeddings(nn.Module):
+ def __init__(self, config) -> None:
+ super().__init__()
+ self.config = config
+
+ def forward(self, pos_embed, img_size=(800, 1344)) -> torch.Tensor:
+ cls_pos_embed = pos_embed[:, 0, :]
+ cls_pos_embed = cls_pos_embed[:, None]
+ det_pos_embed = pos_embed[:, -self.config.num_detection_tokens :, :]
+ patch_pos_embed = pos_embed[:, 1 : -self.config.num_detection_tokens, :]
+ patch_pos_embed = patch_pos_embed.transpose(1, 2)
+ batch_size, hidden_size, seq_len = patch_pos_embed.shape
+
+ patch_height, patch_width = (
+ self.config.image_size[0] // self.config.patch_size,
+ self.config.image_size[1] // self.config.patch_size,
+ )
+ patch_pos_embed = patch_pos_embed.view(batch_size, hidden_size, patch_height, patch_width)
+
+ height, width = img_size
+ new_patch_height, new_patch_width = height // self.config.patch_size, width // self.config.patch_size
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed, size=(new_patch_height, new_patch_width), mode="bicubic", align_corners=False
+ )
+ patch_pos_embed = patch_pos_embed.flatten(2).transpose(1, 2)
+ scale_pos_embed = torch.cat((cls_pos_embed, patch_pos_embed, det_pos_embed), dim=1)
+ return scale_pos_embed
+
+
+class InterpolateMidPositionEmbeddings(nn.Module):
+ def __init__(self, config) -> None:
+ super().__init__()
+ self.config = config
+
+ def forward(self, pos_embed, img_size=(800, 1344)) -> torch.Tensor:
+ cls_pos_embed = pos_embed[:, :, 0, :]
+ cls_pos_embed = cls_pos_embed[:, None]
+ det_pos_embed = pos_embed[:, :, -self.config.num_detection_tokens :, :]
+ patch_pos_embed = pos_embed[:, :, 1 : -self.config.num_detection_tokens, :]
+ patch_pos_embed = patch_pos_embed.transpose(2, 3)
+ depth, batch_size, hidden_size, seq_len = patch_pos_embed.shape
+
+ patch_height, patch_width = (
+ self.config.image_size[0] // self.config.patch_size,
+ self.config.image_size[1] // self.config.patch_size,
+ )
+ patch_pos_embed = patch_pos_embed.view(depth * batch_size, hidden_size, patch_height, patch_width)
+ height, width = img_size
+ new_patch_height, new_patch_width = height // self.config.patch_size, width // self.config.patch_size
+ patch_pos_embed = nn.functional.interpolate(
+ patch_pos_embed, size=(new_patch_height, new_patch_width), mode="bicubic", align_corners=False
+ )
+ patch_pos_embed = (
+ patch_pos_embed.flatten(2)
+ .transpose(1, 2)
+ .contiguous()
+ .view(depth, batch_size, new_patch_height * new_patch_width, hidden_size)
+ )
+ scale_pos_embed = torch.cat((cls_pos_embed, patch_pos_embed, det_pos_embed), dim=2)
+ return scale_pos_embed
+
+
+class YolosPatchEmbeddings(nn.Module):
+ """
+ This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial
+ `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a
+ Transformer.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+ image_size, patch_size = config.image_size, config.patch_size
+ num_channels, hidden_size = config.num_channels, config.hidden_size
+
+ image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size)
+ patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size)
+ num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0])
+ self.image_size = image_size
+ self.patch_size = patch_size
+ self.num_channels = num_channels
+ self.num_patches = num_patches
+
+ self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size)
+
+ def forward(self, pixel_values: torch.Tensor) -> torch.Tensor:
+ batch_size, num_channels, height, width = pixel_values.shape
+ if num_channels != self.num_channels:
+ raise ValueError(
+ "Make sure that the channel dimension of the pixel values match with the one set in the configuration."
+ )
+
+ embeddings = self.projection(pixel_values).flatten(2).transpose(1, 2)
+ return embeddings
+
+
+# Copied from transformers.models.vit.modeling_vit.eager_attention_forward
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling
+
+ # Normalize the attention scores to probabilities.
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+
+ # Mask heads if we want to
+ if attention_mask is not None:
+ attn_weights = attn_weights * attention_mask
+
+ attn_output = torch.matmul(attn_weights, value)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfAttention with ViT->Yolos
+class YolosSelfAttention(nn.Module):
+ def __init__(self, config: YolosConfig):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size {config.hidden_size} is not a multiple of the number of attention "
+ f"heads {config.num_attention_heads}."
+ )
+
+ self.config = config
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+ self.dropout_prob = config.attention_probs_dropout_prob
+ self.scaling = self.attention_head_size**-0.5
+ self.is_causal = False
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias)
+
+ def forward(
+ self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ batch_size = hidden_states.shape[0]
+ new_shape = batch_size, -1, self.num_attention_heads, self.attention_head_size
+
+ key_layer = self.key(hidden_states).view(*new_shape).transpose(1, 2)
+ value_layer = self.value(hidden_states).view(*new_shape).transpose(1, 2)
+ query_layer = self.query(hidden_states).view(*new_shape).transpose(1, 2)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ context_layer, attention_probs = attention_interface(
+ self,
+ query_layer,
+ key_layer,
+ value_layer,
+ head_mask,
+ is_causal=self.is_causal,
+ scaling=self.scaling,
+ dropout=0.0 if not self.training else self.dropout_prob,
+ )
+
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.reshape(new_context_layer_shape)
+
+ return context_layer, attention_probs
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTSelfOutput with ViT->Yolos
+class YolosSelfOutput(nn.Module):
+ """
+ The residual connection is defined in YolosLayer instead of here (as is the case with other models), due to the
+ layernorm applied before each block.
+ """
+
+ def __init__(self, config: YolosConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTAttention with ViT->Yolos
+class YolosAttention(nn.Module):
+ def __init__(self, config: YolosConfig):
+ super().__init__()
+ self.attention = YolosSelfAttention(config)
+ self.output = YolosSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads: set[int]):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.attention.num_attention_heads, self.attention.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.attention.query = prune_linear_layer(self.attention.query, index)
+ self.attention.key = prune_linear_layer(self.attention.key, index)
+ self.attention.value = prune_linear_layer(self.attention.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.attention.num_attention_heads = self.attention.num_attention_heads - len(heads)
+ self.attention.all_head_size = self.attention.attention_head_size * self.attention.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ self_attn_output, _ = self.attention(hidden_states, head_mask)
+ output = self.output(self_attn_output, hidden_states)
+ return output
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTIntermediate with ViT->Yolos
+class YolosIntermediate(nn.Module):
+ def __init__(self, config: YolosConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTOutput with ViT->Yolos
+class YolosOutput(nn.Module):
+ def __init__(self, config: YolosConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = hidden_states + input_tensor
+ return hidden_states
+
+
+# Copied from transformers.models.vit.modeling_vit.ViTLayer with ViT->Yolos,VIT->YOLOS
+class YolosLayer(GradientCheckpointingLayer):
+ """This corresponds to the Block class in the timm implementation."""
+
+ def __init__(self, config: YolosConfig):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = YolosAttention(config)
+ self.intermediate = YolosIntermediate(config)
+ self.output = YolosOutput(config)
+ self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor, head_mask: Optional[torch.Tensor] = None) -> torch.Tensor:
+ hidden_states_norm = self.layernorm_before(hidden_states)
+ attention_output = self.attention(hidden_states_norm, head_mask)
+
+ # first residual connection
+ hidden_states = attention_output + hidden_states
+
+ # in Yolos, layernorm is also applied after self-attention
+ layer_output = self.layernorm_after(hidden_states)
+ layer_output = self.intermediate(layer_output)
+
+ # second residual connection is done here
+ layer_output = self.output(layer_output, hidden_states)
+
+ return layer_output
+
+
+class YolosEncoder(nn.Module):
+ def __init__(self, config: YolosConfig) -> None:
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([YolosLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ seq_length = (
+ 1 + (config.image_size[0] * config.image_size[1] // config.patch_size**2) + config.num_detection_tokens
+ )
+ self.mid_position_embeddings = (
+ nn.Parameter(
+ torch.zeros(
+ config.num_hidden_layers - 1,
+ 1,
+ seq_length,
+ config.hidden_size,
+ )
+ )
+ if config.use_mid_position_embeddings
+ else None
+ )
+
+ self.interpolation = InterpolateMidPositionEmbeddings(config) if config.use_mid_position_embeddings else None
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ height: int,
+ width: int,
+ head_mask: Optional[torch.Tensor] = None,
+ ) -> BaseModelOutput:
+ if self.config.use_mid_position_embeddings:
+ interpolated_mid_position_embeddings = self.interpolation(self.mid_position_embeddings, (height, width))
+
+ for i, layer_module in enumerate(self.layer):
+ layer_head_mask = head_mask[i] if head_mask is not None else None
+ hidden_states = layer_module(hidden_states, layer_head_mask)
+
+ if self.config.use_mid_position_embeddings:
+ if i < (self.config.num_hidden_layers - 1):
+ hidden_states = hidden_states + interpolated_mid_position_embeddings[i]
+
+ return BaseModelOutput(last_hidden_state=hidden_states)
+
+
+@auto_docstring
+class YolosPreTrainedModel(PreTrainedModel):
+ config: YolosConfig
+ base_model_prefix = "vit"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+ _no_split_modules = []
+ _supports_sdpa = True
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_attention_backend = True
+ _can_record_outputs = {
+ "hidden_states": YolosLayer,
+ "attentions": YolosSelfAttention,
+ }
+
+ def _init_weights(self, module: Union[nn.Linear, nn.Conv2d, nn.LayerNorm]) -> None:
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+@auto_docstring
+class YolosModel(YolosPreTrainedModel):
+ def __init__(self, config: YolosConfig, add_pooling_layer: bool = True):
+ r"""
+ add_pooling_layer (bool, *optional*, defaults to `True`):
+ Whether to add a pooling layer
+ """
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = YolosEmbeddings(config)
+ self.encoder = YolosEncoder(config)
+
+ self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.pooler = YolosPooler(config) if add_pooling_layer else None
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self) -> YolosPatchEmbeddings:
+ return self.embeddings.patch_embeddings
+
+ def _prune_heads(self, heads_to_prune: dict[int, list[int]]) -> None:
+ """
+ Prunes heads of the model.
+
+ Args:
+ heads_to_prune (`dict`):
+ See base class `PreTrainedModel`. The input dictionary must have the following format: {layer_num:
+ list of heads to prune in this layer}
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @check_model_inputs
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> BaseModelOutputWithPooling:
+ if pixel_values is None:
+ raise ValueError("You have to specify pixel_values")
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(pixel_values)
+
+ height, width = pixel_values.shape[-2:]
+ encoder_outputs: BaseModelOutput = self.encoder(
+ embedding_output, height=height, width=width, head_mask=head_mask
+ )
+ sequence_output = encoder_outputs.last_hidden_state
+ sequence_output = self.layernorm(sequence_output)
+ pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
+
+ return BaseModelOutputWithPooling(last_hidden_state=sequence_output, pooler_output=pooled_output)
+
+
+class YolosPooler(nn.Module):
+ def __init__(self, config: YolosConfig):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.activation = nn.Tanh()
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ # We "pool" the model by simply taking the hidden state corresponding
+ # to the first token.
+ first_token_tensor = hidden_states[:, 0]
+ pooled_output = self.dense(first_token_tensor)
+ pooled_output = self.activation(pooled_output)
+ return pooled_output
+
+
+# Copied from transformers.models.detr.modeling_detr.DetrMLPPredictionHead with Detr->Yolos
+class YolosMLPPredictionHead(nn.Module):
+ """
+ Very simple multi-layer perceptron (MLP, also called FFN), used to predict the normalized center coordinates,
+ height and width of a bounding box w.r.t. an image.
+
+ Copied from https://github.com/facebookresearch/detr/blob/master/models/detr.py
+
+ """
+
+ def __init__(self, input_dim, hidden_dim, output_dim, num_layers):
+ super().__init__()
+ self.num_layers = num_layers
+ h = [hidden_dim] * (num_layers - 1)
+ self.layers = nn.ModuleList(nn.Linear(n, k) for n, k in zip([input_dim] + h, h + [output_dim]))
+
+ def forward(self, x):
+ for i, layer in enumerate(self.layers):
+ x = nn.functional.relu(layer(x)) if i < self.num_layers - 1 else layer(x)
+ return x
+
+
+@auto_docstring(
+ custom_intro="""
+ YOLOS Model (consisting of a ViT encoder) with object detection heads on top, for tasks such as COCO detection.
+ """
+)
+class YolosForObjectDetection(YolosPreTrainedModel):
+ def __init__(self, config: YolosConfig):
+ super().__init__(config)
+
+ # YOLOS (ViT) encoder model
+ self.vit = YolosModel(config, add_pooling_layer=False)
+
+ # Object detection heads
+ # We add one for the "no object" class
+ self.class_labels_classifier = YolosMLPPredictionHead(
+ input_dim=config.hidden_size, hidden_dim=config.hidden_size, output_dim=config.num_labels + 1, num_layers=3
+ )
+ self.bbox_predictor = YolosMLPPredictionHead(
+ input_dim=config.hidden_size, hidden_dim=config.hidden_size, output_dim=4, num_layers=3
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ # taken from https://github.com/facebookresearch/detr/blob/master/models/detr.py
+ @torch.jit.unused
+ def _set_aux_loss(self, outputs_class, outputs_coord):
+ # this is a workaround to make torchscript happy, as torchscript
+ # doesn't support dictionary with non-homogeneous values, such
+ # as a dict having both a Tensor and a list.
+ return [{"logits": a, "pred_boxes": b} for a, b in zip(outputs_class[:-1], outputs_coord[:-1])]
+
+ @can_return_tuple
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ labels: Optional[list[dict]] = None,
+ **kwargs: Unpack[TransformersKwargs],
+ ) -> YolosObjectDetectionOutput:
+ r"""
+ labels (`list[Dict]` of len `(batch_size,)`, *optional*):
+ Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the
+ following 2 keys: `'class_labels'` and `'boxes'` (the class labels and bounding boxes of an image in the
+ batch respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding
+ boxes in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image,
+ 4)`.
+
+ Examples:
+
+ ```python
+ >>> from transformers import AutoImageProcessor, AutoModelForObjectDetection
+ >>> import torch
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("hustvl/yolos-tiny")
+ >>> model = AutoModelForObjectDetection.from_pretrained("hustvl/yolos-tiny")
+
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+ >>> outputs = model(**inputs)
+
+ >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+ >>> target_sizes = torch.tensor([image.size[::-1]])
+ >>> results = image_processor.post_process_object_detection(outputs, threshold=0.9, target_sizes=target_sizes)[
+ ... 0
+ ... ]
+
+ >>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+ ... box = [round(i, 2) for i in box.tolist()]
+ ... print(
+ ... f"Detected {model.config.id2label[label.item()]} with confidence "
+ ... f"{round(score.item(), 3)} at location {box}"
+ ... )
+ Detected remote with confidence 0.991 at location [46.48, 72.78, 178.98, 119.3]
+ Detected remote with confidence 0.908 at location [336.48, 79.27, 368.23, 192.36]
+ Detected cat with confidence 0.934 at location [337.18, 18.06, 638.14, 373.09]
+ Detected cat with confidence 0.979 at location [10.93, 53.74, 313.41, 470.67]
+ Detected remote with confidence 0.974 at location [41.63, 72.23, 178.09, 119.99]
+ ```"""
+
+ # First, sent images through YOLOS base model to obtain hidden states
+ outputs: BaseModelOutputWithPooling = self.vit(pixel_values, **kwargs)
+ sequence_output = outputs.last_hidden_state
+
+ # Take the final hidden states of the detection tokens
+ sequence_output = sequence_output[:, -self.config.num_detection_tokens :, :]
+
+ # Class logits + predicted bounding boxes
+ logits = self.class_labels_classifier(sequence_output)
+ pred_boxes = self.bbox_predictor(sequence_output).sigmoid()
+
+ loss, loss_dict, auxiliary_outputs = None, None, None
+ if labels is not None:
+ outputs_class, outputs_coord = None, None
+ if self.config.auxiliary_loss:
+ intermediate = outputs.hidden_states
+ outputs_class = self.class_labels_classifier(intermediate)
+ outputs_coord = self.bbox_predictor(intermediate).sigmoid()
+ loss, loss_dict, auxiliary_outputs = self.loss_function(
+ logits, labels, self.device, pred_boxes, self.config, outputs_class, outputs_coord
+ )
+
+ return YolosObjectDetectionOutput(
+ loss=loss,
+ loss_dict=loss_dict,
+ logits=logits,
+ pred_boxes=pred_boxes,
+ auxiliary_outputs=auxiliary_outputs,
+ last_hidden_state=outputs.last_hidden_state,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["YolosForObjectDetection", "YolosModel", "YolosPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/modular_yolos.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/modular_yolos.py
new file mode 100644
index 0000000000000000000000000000000000000000..f5fec1ba80ddcf1efeb80739fa960baa91c0ba88
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yolos/modular_yolos.py
@@ -0,0 +1,193 @@
+from typing import Optional, Union
+
+from transformers.models.detr.image_processing_detr_fast import DetrImageProcessorFast
+
+from ...image_transforms import center_to_corners_format
+from ...utils import (
+ TensorType,
+ is_torch_available,
+ logging,
+)
+
+
+if is_torch_available():
+ import torch
+
+
+logger = logging.get_logger(__name__)
+
+
+def get_size_with_aspect_ratio(
+ image_size: tuple[int, int], size: int, max_size: Optional[int] = None, mod_size: int = 16
+) -> tuple[int, int]:
+ """
+ Computes the output image size given the input image size and the desired output size with multiple of divisible_size.
+
+ Args:
+ image_size (`tuple[int, int]`):
+ The input image size.
+ size (`int`):
+ The desired output size.
+ max_size (`int`, *optional*):
+ The maximum allowed output size.
+ mod_size (`int`, *optional*):
+ The size to make multiple of mod_size.
+ """
+ height, width = image_size
+ raw_size = None
+ if max_size is not None:
+ min_original_size = float(min((height, width)))
+ max_original_size = float(max((height, width)))
+ if max_original_size / min_original_size * size > max_size:
+ raw_size = max_size * min_original_size / max_original_size
+ size = int(round(raw_size))
+
+ if width < height:
+ ow = size
+ if max_size is not None and raw_size is not None:
+ oh = int(raw_size * height / width)
+ else:
+ oh = int(size * height / width)
+ elif (height <= width and height == size) or (width <= height and width == size):
+ oh, ow = height, width
+ else:
+ oh = size
+ if max_size is not None and raw_size is not None:
+ ow = int(raw_size * width / height)
+ else:
+ ow = int(size * width / height)
+
+ if mod_size is not None:
+ ow_mod = torch.remainder(torch.tensor(ow), mod_size).item()
+ oh_mod = torch.remainder(torch.tensor(oh), mod_size).item()
+ ow = ow - ow_mod
+ oh = oh - oh_mod
+
+ return (oh, ow)
+
+
+class YolosImageProcessorFast(DetrImageProcessorFast):
+ def post_process(self, outputs, target_sizes):
+ """
+ Converts the raw output of [`YolosForObjectDetection`] into final bounding boxes in (top_left_x,
+ top_left_y, bottom_right_x, bottom_right_y) format. Only supports PyTorch.
+
+ Args:
+ outputs ([`YolosObjectDetectionOutput`]):
+ Raw outputs of the model.
+ target_sizes (`torch.Tensor` of shape `(batch_size, 2)`):
+ Tensor containing the size (height, width) of each image of the batch. For evaluation, this must be the
+ original image size (before any data augmentation). For visualization, this should be the image size
+ after data augment, but before padding.
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image
+ in the batch as predicted by the model.
+ """
+ logger.warning_once(
+ "`post_process` is deprecated and will be removed in v5 of Transformers, please use"
+ " `post_process_object_detection` instead, with `threshold=0.` for equivalent results.",
+ )
+
+ out_logits, out_bbox = outputs.logits, outputs.pred_boxes
+
+ if len(out_logits) != len(target_sizes):
+ raise ValueError("Make sure that you pass in as many target sizes as the batch dimension of the logits")
+ if target_sizes.shape[1] != 2:
+ raise ValueError("Each element of target_sizes must contain the size (h, w) of each image of the batch")
+
+ prob = out_logits.sigmoid()
+ topk_values, topk_indexes = torch.topk(prob.view(out_logits.shape[0], -1), 100, dim=1)
+ scores = topk_values
+ topk_boxes = torch.div(topk_indexes, out_logits.shape[2], rounding_mode="floor")
+ labels = topk_indexes % out_logits.shape[2]
+ boxes = center_to_corners_format(out_bbox)
+ boxes = torch.gather(boxes, 1, topk_boxes.unsqueeze(-1).repeat(1, 1, 4))
+
+ # and from relative [0, 1] to absolute [0, height] coordinates
+ img_h, img_w = target_sizes.unbind(1)
+ scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1)
+ boxes = boxes * scale_fct[:, None, :]
+
+ results = [{"scores": s, "labels": l, "boxes": b} for s, l, b in zip(scores, labels, boxes)]
+
+ return results
+
+ def post_process_object_detection(
+ self, outputs, threshold: float = 0.5, target_sizes: Union[TensorType, list[tuple]] = None, top_k: int = 100
+ ):
+ """
+ Converts the raw output of [`YolosForObjectDetection`] into final bounding boxes in (top_left_x,
+ top_left_y, bottom_right_x, bottom_right_y) format. Only supports PyTorch.
+
+ Args:
+ outputs ([`YolosObjectDetectionOutput`]):
+ Raw outputs of the model.
+ threshold (`float`, *optional*):
+ Score threshold to keep object detection predictions.
+ target_sizes (`torch.Tensor` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size
+ (height, width) of each image in the batch. If left to None, predictions will not be resized.
+ top_k (`int`, *optional*, defaults to 100):
+ Keep only top k bounding boxes before filtering by thresholding.
+
+ Returns:
+ `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image
+ in the batch as predicted by the model.
+ """
+ out_logits, out_bbox = outputs.logits, outputs.pred_boxes
+
+ if target_sizes is not None:
+ if len(out_logits) != len(target_sizes):
+ raise ValueError(
+ "Make sure that you pass in as many target sizes as the batch dimension of the logits"
+ )
+
+ prob = out_logits.sigmoid()
+ prob = prob.view(out_logits.shape[0], -1)
+ k_value = min(top_k, prob.size(1))
+ topk_values, topk_indexes = torch.topk(prob, k_value, dim=1)
+ scores = topk_values
+ topk_boxes = torch.div(topk_indexes, out_logits.shape[2], rounding_mode="floor")
+ labels = topk_indexes % out_logits.shape[2]
+ boxes = center_to_corners_format(out_bbox)
+ boxes = torch.gather(boxes, 1, topk_boxes.unsqueeze(-1).repeat(1, 1, 4))
+
+ # and from relative [0, 1] to absolute [0, height] coordinates
+ if target_sizes is not None:
+ if isinstance(target_sizes, list):
+ img_h = torch.Tensor([i[0] for i in target_sizes])
+ img_w = torch.Tensor([i[1] for i in target_sizes])
+ else:
+ img_h, img_w = target_sizes.unbind(1)
+ scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1).to(boxes.device)
+ boxes = boxes * scale_fct[:, None, :]
+
+ results = []
+ for s, l, b in zip(scores, labels, boxes):
+ score = s[s > threshold]
+ label = l[s > threshold]
+ box = b[s > threshold]
+ results.append({"scores": score, "labels": label, "boxes": box})
+
+ return results
+
+ def post_process_segmentation():
+ raise NotImplementedError("Segmentation post-processing is not implemented for Deformable DETR yet.")
+
+ def post_process_instance():
+ raise NotImplementedError("Instance post-processing is not implemented for Deformable DETR yet.")
+
+ def post_process_panoptic():
+ raise NotImplementedError("Panoptic post-processing is not implemented for Deformable DETR yet.")
+
+ def post_process_instance_segmentation():
+ raise NotImplementedError("Segmentation post-processing is not implemented for Deformable DETR yet.")
+
+ def post_process_semantic_segmentation():
+ raise NotImplementedError("Semantic segmentation post-processing is not implemented for Deformable DETR yet.")
+
+ def post_process_panoptic_segmentation():
+ raise NotImplementedError("Panoptic segmentation post-processing is not implemented for Deformable DETR yet.")
+
+
+__all__ = ["YolosImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..6b865cb93ce1134a1a8761bafd1b3498931d7c83
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_yoso import *
+ from .modeling_yoso import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/configuration_yoso.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/configuration_yoso.py
new file mode 100644
index 0000000000000000000000000000000000000000..9a7fb1218e402e36f6275f81783e00cc79c36a8d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/configuration_yoso.py
@@ -0,0 +1,144 @@
+# coding=utf-8
+# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""YOSO model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class YosoConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`YosoModel`]. It is used to instantiate an YOSO
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the YOSO
+ [uw-madison/yoso-4096](https://huggingface.co/uw-madison/yoso-4096) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 50265):
+ Vocabulary size of the YOSO model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`YosoModel`].
+ hidden_size (`int`, *optional*, defaults to 768):
+ Dimension of the encoder layers and the pooler layer.
+ num_hidden_layers (`int`, *optional*, defaults to 12):
+ Number of hidden layers in the Transformer encoder.
+ num_attention_heads (`int`, *optional*, defaults to 12):
+ Number of attention heads for each attention layer in the Transformer encoder.
+ intermediate_size (`int`, *optional*, defaults to 3072):
+ Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ hidden_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
+ attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1):
+ The dropout ratio for the attention probabilities.
+ max_position_embeddings (`int`, *optional*, defaults to 512):
+ The maximum sequence length that this model might ever be used with. Typically set this to something large
+ just in case (e.g., 512 or 1024 or 2048).
+ type_vocab_size (`int`, *optional*, defaults to 2):
+ The vocabulary size of the `token_type_ids` passed when calling [`YosoModel`].
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ layer_norm_eps (`float`, *optional*, defaults to 1e-12):
+ The epsilon used by the layer normalization layers.
+ position_embedding_type (`str`, *optional*, defaults to `"absolute"`):
+ Type of position embedding. Choose one of `"absolute"`, `"relative_key"`, `"relative_key_query"`.
+ use_expectation (`bool`, *optional*, defaults to `True`):
+ Whether or not to use YOSO Expectation. Overrides any effect of num_hash.
+ hash_code_len (`int`, *optional*, defaults to 9):
+ The length of hashes generated by the hash functions.
+ num_hash (`int`, *optional*, defaults to 64):
+ Number of hash functions used in [`YosoSelfAttention`].
+ conv_window (`int`, *optional*):
+ Kernel size of depth-wise convolution.
+ use_fast_hash (`bool`, *optional*, defaults to `False`):
+ Whether or not to use custom cuda kernels which perform fast random projection via hadamard transform.
+ lsh_backward (`bool`, *optional*, defaults to `True`):
+ Whether or not to perform backpropagation using Locality Sensitive Hashing.
+
+ Example:
+
+ ```python
+ >>> from transformers import YosoConfig, YosoModel
+
+ >>> # Initializing a YOSO uw-madison/yoso-4096 style configuration
+ >>> configuration = YosoConfig()
+
+ >>> # Initializing a model (with random weights) from the uw-madison/yoso-4096 style configuration
+ >>> model = YosoModel(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "yoso"
+
+ def __init__(
+ self,
+ vocab_size=50265,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ hidden_act="gelu",
+ hidden_dropout_prob=0.1,
+ attention_probs_dropout_prob=0.1,
+ max_position_embeddings=4096,
+ type_vocab_size=1,
+ initializer_range=0.02,
+ layer_norm_eps=1e-12,
+ position_embedding_type="absolute",
+ use_expectation=True,
+ hash_code_len=9,
+ num_hash=64,
+ conv_window=None,
+ use_fast_hash=True,
+ lsh_backward=True,
+ pad_token_id=1,
+ bos_token_id=0,
+ eos_token_id=2,
+ **kwargs,
+ ):
+ super().__init__(pad_token_id=pad_token_id, bos_token_id=bos_token_id, eos_token_id=eos_token_id, **kwargs)
+
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.hidden_dropout_prob = hidden_dropout_prob
+ self.attention_probs_dropout_prob = attention_probs_dropout_prob
+ self.initializer_range = initializer_range
+ self.type_vocab_size = type_vocab_size
+ self.layer_norm_eps = layer_norm_eps
+ self.position_embedding_type = position_embedding_type
+ self.use_expectation = use_expectation
+ self.hash_code_len = hash_code_len
+ self.num_hash = num_hash
+ self.conv_window = conv_window
+ self.use_fast_hash = use_fast_hash
+ self.lsh_backward = lsh_backward
+
+
+__all__ = ["YosoConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/modeling_yoso.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/modeling_yoso.py
new file mode 100644
index 0000000000000000000000000000000000000000..221ebaa637feec1e4428085ca11fa204c722c7f6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/yoso/modeling_yoso.py
@@ -0,0 +1,1222 @@
+# coding=utf-8
+# Copyright 2022 University of Wisconsin-Madison and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch YOSO model."""
+
+import math
+from pathlib import Path
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...modeling_layers import GradientCheckpointingLayer
+from ...modeling_outputs import (
+ BaseModelOutputWithCrossAttentions,
+ MaskedLMOutput,
+ MultipleChoiceModelOutput,
+ QuestionAnsweringModelOutput,
+ SequenceClassifierOutput,
+ TokenClassifierOutput,
+)
+from ...modeling_utils import PreTrainedModel
+from ...pytorch_utils import apply_chunking_to_forward, find_pruneable_heads_and_indices, prune_linear_layer
+from ...utils import (
+ auto_docstring,
+ is_ninja_available,
+ is_torch_cuda_available,
+ logging,
+)
+from .configuration_yoso import YosoConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+lsh_cumulation = None
+
+
+def load_cuda_kernels():
+ global lsh_cumulation
+ from torch.utils.cpp_extension import load
+
+ def append_root(files):
+ src_folder = Path(__file__).resolve().parent.parent.parent / "kernels" / "yoso"
+ return [src_folder / file for file in files]
+
+ src_files = append_root(["fast_lsh_cumulation_torch.cpp", "fast_lsh_cumulation.cu", "fast_lsh_cumulation_cuda.cu"])
+
+ load("fast_lsh_cumulation", src_files, verbose=True)
+
+ import fast_lsh_cumulation as lsh_cumulation
+
+
+def to_contiguous(input_tensors):
+ if isinstance(input_tensors, list):
+ out = []
+ for tensor in input_tensors:
+ if not tensor.is_contiguous():
+ tensor = tensor.contiguous()
+ out.append(tensor)
+ return out
+ else:
+ if not input_tensors.is_contiguous():
+ input_tensors = input_tensors.contiguous()
+ return input_tensors
+
+
+def normalize(input_tensors):
+ if isinstance(input_tensors, list):
+ out = []
+ for tensor in input_tensors:
+ out.append(nn.functional.normalize(tensor, p=2, dim=-1))
+ return out
+ else:
+ return nn.functional.normalize(input_tensors, p=2, dim=-1)
+
+
+def hashing(query, key, num_hash, hash_len):
+ if len(query.size()) != 3:
+ raise ValueError("Query has incorrect size.")
+ if len(key.size()) != 3:
+ raise ValueError("Key has incorrect size.")
+
+ rmat = torch.randn(query.size(0), query.size(2), num_hash * hash_len, device=query.device)
+ raise_pow = 2 ** torch.arange(hash_len, device=query.device)
+
+ query_projection = torch.matmul(query, rmat).reshape(query.size(0), query.size(1), num_hash, hash_len)
+ key_projection = torch.matmul(key, rmat).reshape(key.size(0), key.size(1), num_hash, hash_len)
+ query_binary = (query_projection > 0).int()
+ key_binary = (key_projection > 0).int()
+ query_hash = torch.sum(query_binary * raise_pow, dim=-1)
+ query_hash = torch.sum(key_binary * raise_pow, dim=-1)
+
+ return query_hash.int(), query_hash.int()
+
+
+class YosoCumulation(torch.autograd.Function):
+ @staticmethod
+ def forward(ctx, query_mask, key_mask, query, key, value, config):
+ hash_code_len = config["hash_code_len"]
+
+ expectation = (1 - torch.acos(torch.matmul(query, key.transpose(-1, -2))) / math.pi) ** hash_code_len
+ expectation = expectation * query_mask[:, :, None] * key_mask[:, None, :]
+ cumulation_value = torch.matmul(expectation, value)
+
+ ctx.save_for_backward(query_mask, key_mask, expectation, query, key, value)
+ ctx.config = config
+
+ return cumulation_value
+
+ @staticmethod
+ def backward(ctx, grad):
+ grad = to_contiguous(grad)
+
+ query_mask, key_mask, expectation, query, key, value = ctx.saved_tensors
+ config = ctx.config
+
+ hash_code_len = config["hash_code_len"]
+
+ weighted_exp = torch.matmul(grad, value.transpose(-1, -2)) * expectation
+ grad_query = torch.matmul(weighted_exp, (hash_code_len / 2) * key)
+ grad_key = torch.matmul(weighted_exp.transpose(-1, -2), (hash_code_len / 2) * query)
+ grad_value = torch.matmul(expectation.transpose(-1, -2), grad)
+
+ return None, None, grad_query, grad_key, grad_value, None
+
+
+class YosoLSHCumulation(torch.autograd.Function):
+ @staticmethod
+ def forward(ctx, query_mask, key_mask, query, key, value, config):
+ if query_mask.size(0) != key_mask.size(0):
+ raise ValueError("Query mask and Key mask differ in sizes in dimension 0")
+ if query_mask.size(0) != query.size(0):
+ raise ValueError("Query mask and Query differ in sizes in dimension 0")
+ if query_mask.size(0) != key.size(0):
+ raise ValueError("Query mask and Key differ in sizes in dimension 0")
+ if query_mask.size(0) != value.size(0):
+ raise ValueError("Query mask and Value mask differ in sizes in dimension 0")
+ if key.size(1) != value.size(1):
+ raise ValueError("Key and Value differ in sizes in dimension 1")
+ if query.size(2) != key.size(2):
+ raise ValueError("Query and Key differ in sizes in dimension 2")
+
+ query_mask, key_mask, query, key, value = to_contiguous([query_mask, key_mask, query, key, value])
+
+ use_cuda = query_mask.is_cuda
+ num_hash = config["num_hash"]
+ hash_code_len = config["hash_code_len"]
+ hashtable_capacity = int(2**hash_code_len)
+
+ if config["use_fast_hash"]:
+ query_hash_code, key_hash_code = lsh_cumulation.fast_hash(
+ query_mask, query, key_mask, key, num_hash, hash_code_len, use_cuda, 1
+ )
+ else:
+ query_hash_code, key_hash_code = hashing(query, key, num_hash, hash_code_len)
+
+ cumulation_value = lsh_cumulation.lsh_cumulation(
+ query_mask, query_hash_code, key_mask, key_hash_code, value, hashtable_capacity, use_cuda, 1
+ )
+
+ ctx.save_for_backward(query_mask, key_mask, query_hash_code, key_hash_code, query, key, value)
+ ctx.config = config
+
+ return cumulation_value
+
+ @staticmethod
+ def backward(ctx, grad):
+ grad = to_contiguous(grad)
+
+ query_mask, key_mask, query_hash_code, key_hash_code, query, key, value = ctx.saved_tensors
+ config = ctx.config
+
+ use_cuda = grad.is_cuda
+ hash_code_len = config["hash_code_len"]
+ hashtable_capacity = int(2**hash_code_len)
+
+ if config["lsh_backward"]:
+ grad_value = lsh_cumulation.lsh_cumulation(
+ key_mask, key_hash_code, query_mask, query_hash_code, grad, hashtable_capacity, use_cuda, 1
+ )
+ grad_query = lsh_cumulation.lsh_weighted_cumulation(
+ query_mask,
+ query_hash_code,
+ grad,
+ key_mask,
+ key_hash_code,
+ value,
+ (hash_code_len / 2) * key,
+ hashtable_capacity,
+ use_cuda,
+ 4,
+ )
+ grad_key = lsh_cumulation.lsh_weighted_cumulation(
+ key_mask,
+ key_hash_code,
+ value,
+ query_mask,
+ query_hash_code,
+ grad,
+ (hash_code_len / 2) * query,
+ hashtable_capacity,
+ use_cuda,
+ 4,
+ )
+ else:
+ expectation = (1 - torch.acos(torch.matmul(query, key.transpose(-1, -2))) / math.pi) ** hash_code_len
+ expectation = expectation * query_mask[:, :, None] * key_mask[:, None, :]
+ weighted_exp = torch.matmul(grad, value.transpose(-1, -2)) * expectation
+ grad_query = torch.matmul(weighted_exp, (hash_code_len / 2) * key)
+ grad_key = torch.matmul(weighted_exp.transpose(-1, -2), (hash_code_len / 2) * query)
+ grad_value = torch.matmul(expectation.transpose(-1, -2), grad)
+
+ return None, None, grad_query, grad_key, grad_value, None
+
+
+# Copied from transformers.models.nystromformer.modeling_nystromformer.NystromformerEmbeddings
+class YosoEmbeddings(nn.Module):
+ """Construct the embeddings from word, position and token_type embeddings."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id)
+ self.position_embeddings = nn.Embedding(config.max_position_embeddings + 2, config.hidden_size)
+ self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size)
+
+ # self.LayerNorm is not snake-cased to stick with TensorFlow model variable name and be able to load
+ # any TensorFlow checkpoint file
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ # position_ids (1, len position emb) is contiguous in memory and exported when serialized
+ self.register_buffer(
+ "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)) + 2, persistent=False
+ )
+ self.position_embedding_type = getattr(config, "position_embedding_type", "absolute")
+ self.register_buffer(
+ "token_type_ids",
+ torch.zeros(self.position_ids.size(), dtype=torch.long, device=self.position_ids.device),
+ persistent=False,
+ )
+
+ def forward(self, input_ids=None, token_type_ids=None, position_ids=None, inputs_embeds=None):
+ if input_ids is not None:
+ input_shape = input_ids.size()
+ else:
+ input_shape = inputs_embeds.size()[:-1]
+
+ seq_length = input_shape[1]
+
+ if position_ids is None:
+ position_ids = self.position_ids[:, :seq_length]
+
+ # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs
+ # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves
+ # issue #5664
+ if token_type_ids is None:
+ if hasattr(self, "token_type_ids"):
+ buffered_token_type_ids = self.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(input_shape[0], seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device)
+
+ if inputs_embeds is None:
+ inputs_embeds = self.word_embeddings(input_ids)
+ token_type_embeddings = self.token_type_embeddings(token_type_ids)
+
+ embeddings = inputs_embeds + token_type_embeddings
+ if self.position_embedding_type == "absolute":
+ position_embeddings = self.position_embeddings(position_ids)
+ embeddings += position_embeddings
+ embeddings = self.LayerNorm(embeddings)
+ embeddings = self.dropout(embeddings)
+ return embeddings
+
+
+class YosoSelfAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"):
+ raise ValueError(
+ f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention "
+ f"heads ({config.num_attention_heads})"
+ )
+ kernel_loaded = lsh_cumulation is not None
+ if is_torch_cuda_available() and is_ninja_available() and not kernel_loaded:
+ try:
+ load_cuda_kernels()
+ except Exception as e:
+ logger.warning(f"Could not load the custom kernel for multi-scale deformable attention: {e}")
+
+ self.num_attention_heads = config.num_attention_heads
+ self.attention_head_size = int(config.hidden_size / config.num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(config.hidden_size, self.all_head_size)
+ self.key = nn.Linear(config.hidden_size, self.all_head_size)
+ self.value = nn.Linear(config.hidden_size, self.all_head_size)
+
+ self.dropout = nn.Dropout(config.attention_probs_dropout_prob)
+ self.position_embedding_type = (
+ position_embedding_type if position_embedding_type is not None else config.position_embedding_type
+ )
+
+ self.use_expectation = config.use_expectation
+ self.hash_code_len = config.hash_code_len
+ self.use_conv = config.conv_window is not None
+ self.use_fast_hash = config.use_fast_hash
+ self.num_hash = config.num_hash
+ self.lsh_backward = config.lsh_backward
+
+ self.lsh_config = {
+ "hash_code_len": self.hash_code_len,
+ "use_fast_hash": self.use_fast_hash,
+ "num_hash": self.num_hash,
+ "lsh_backward": self.lsh_backward,
+ }
+
+ if config.conv_window is not None:
+ self.conv = nn.Conv2d(
+ in_channels=config.num_attention_heads,
+ out_channels=config.num_attention_heads,
+ kernel_size=(config.conv_window, 1),
+ padding=(config.conv_window // 2, 0),
+ bias=False,
+ groups=config.num_attention_heads,
+ )
+
+ def forward(self, hidden_states, attention_mask=None, output_attentions=False):
+ batch_size, seq_length, _ = hidden_states.shape
+ query_layer = (
+ self.query(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ key_layer = (
+ self.key(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ value_layer = (
+ self.value(hidden_states)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+
+ if self.use_conv:
+ conv_value_layer = self.conv(value_layer * attention_mask[:, None, :, None])
+
+ batch_size, num_heads, seq_len, head_dim = query_layer.size()
+
+ query_layer = query_layer.reshape(batch_size * num_heads, seq_len, head_dim)
+ key_layer = key_layer.reshape(batch_size * num_heads, seq_len, head_dim)
+ value_layer = value_layer.reshape(batch_size * num_heads, seq_len, head_dim)
+
+ attention_mask = 1.0 + attention_mask / 10000.0
+ attention_mask = (
+ attention_mask.unsqueeze(1)
+ .repeat_interleave(num_heads, dim=1)
+ .reshape(batch_size * num_heads, seq_len)
+ .int()
+ )
+
+ # The CUDA kernels are most efficient with inputs whose size is a multiple of a GPU's warp size (32). Inputs
+ # smaller than this are padded with zeros.
+ gpu_warp_size = 32
+
+ if (not self.use_expectation) and head_dim < gpu_warp_size:
+ pad_size = batch_size * num_heads, seq_len, gpu_warp_size - head_dim
+
+ query_layer = torch.cat(
+ [
+ query_layer,
+ torch.zeros(pad_size, device=query_layer.device),
+ ],
+ dim=-1,
+ )
+ key_layer = torch.cat(
+ [
+ key_layer,
+ torch.zeros(pad_size, device=key_layer.device),
+ ],
+ dim=-1,
+ )
+ value_layer = torch.cat(
+ [
+ value_layer,
+ torch.zeros(pad_size, device=value_layer.device),
+ ],
+ dim=-1,
+ )
+
+ if self.use_expectation or self.training:
+ query_layer, key_layer = normalize([query_layer, key_layer])
+
+ if self.use_expectation:
+ context_layer = YosoCumulation.apply(
+ attention_mask, attention_mask, query_layer, key_layer, value_layer, self.lsh_config
+ )
+ else:
+ context_layer = YosoLSHCumulation.apply(
+ attention_mask, attention_mask, query_layer, key_layer, value_layer, self.lsh_config
+ )
+
+ if (not self.use_expectation) and head_dim < gpu_warp_size:
+ context_layer = context_layer[:, :, :head_dim]
+
+ context_layer = normalize(context_layer)
+
+ context_layer = context_layer.reshape(batch_size, num_heads, seq_len, head_dim)
+
+ if self.use_conv:
+ context_layer += conv_value_layer
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(*new_context_layer_shape)
+
+ outputs = (context_layer, context_layer) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertSelfOutput
+class YosoSelfOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class YosoAttention(nn.Module):
+ def __init__(self, config, position_embedding_type=None):
+ super().__init__()
+ self.self = YosoSelfAttention(config, position_embedding_type=position_embedding_type)
+ self.output = YosoSelfOutput(config)
+ self.pruned_heads = set()
+
+ def prune_heads(self, heads):
+ if len(heads) == 0:
+ return
+ heads, index = find_pruneable_heads_and_indices(
+ heads, self.self.num_attention_heads, self.self.attention_head_size, self.pruned_heads
+ )
+
+ # Prune linear layers
+ self.self.query = prune_linear_layer(self.self.query, index)
+ self.self.key = prune_linear_layer(self.self.key, index)
+ self.self.value = prune_linear_layer(self.self.value, index)
+ self.output.dense = prune_linear_layer(self.output.dense, index, dim=1)
+
+ # Update hyper params and store pruned heads
+ self.self.num_attention_heads = self.self.num_attention_heads - len(heads)
+ self.self.all_head_size = self.self.attention_head_size * self.self.num_attention_heads
+ self.pruned_heads = self.pruned_heads.union(heads)
+
+ def forward(self, hidden_states, attention_mask=None, output_attentions=False):
+ self_outputs = self.self(hidden_states, attention_mask, output_attentions)
+ attention_output = self.output(self_outputs[0], hidden_states)
+ outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them
+ return outputs
+
+
+# Copied from transformers.models.bert.modeling_bert.BertIntermediate
+class YosoIntermediate(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.intermediate_size)
+ if isinstance(config.hidden_act, str):
+ self.intermediate_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.intermediate_act_fn = config.hidden_act
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.intermediate_act_fn(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertOutput
+class YosoOutput(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.intermediate_size, config.hidden_size)
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+
+ def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states + input_tensor)
+ return hidden_states
+
+
+class YosoLayer(GradientCheckpointingLayer):
+ def __init__(self, config):
+ super().__init__()
+ self.chunk_size_feed_forward = config.chunk_size_feed_forward
+ self.seq_len_dim = 1
+ self.attention = YosoAttention(config)
+ self.add_cross_attention = config.add_cross_attention
+ self.intermediate = YosoIntermediate(config)
+ self.output = YosoOutput(config)
+
+ def forward(self, hidden_states, attention_mask=None, output_attentions=False):
+ self_attention_outputs = self.attention(hidden_states, attention_mask, output_attentions=output_attentions)
+ attention_output = self_attention_outputs[0]
+
+ outputs = self_attention_outputs[1:] # add self attentions if we output attention weights
+
+ layer_output = apply_chunking_to_forward(
+ self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output
+ )
+ outputs = (layer_output,) + outputs
+
+ return outputs
+
+ def feed_forward_chunk(self, attention_output):
+ intermediate_output = self.intermediate(attention_output)
+ layer_output = self.output(intermediate_output, attention_output)
+ return layer_output
+
+
+class YosoEncoder(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.layer = nn.ModuleList([YosoLayer(config) for _ in range(config.num_hidden_layers)])
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ attention_mask=None,
+ head_mask=None,
+ output_attentions=False,
+ output_hidden_states=False,
+ return_dict=True,
+ ):
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attentions = () if output_attentions else None
+
+ for i, layer_module in enumerate(self.layer):
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ layer_outputs = layer_module(hidden_states, attention_mask, output_attentions)
+
+ hidden_states = layer_outputs[0]
+ if output_attentions:
+ all_self_attentions = all_self_attentions + (layer_outputs[1],)
+
+ if output_hidden_states:
+ all_hidden_states = all_hidden_states + (hidden_states,)
+
+ if not return_dict:
+ return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None)
+ return BaseModelOutputWithCrossAttentions(
+ last_hidden_state=hidden_states,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attentions,
+ )
+
+
+# Copied from transformers.models.bert.modeling_bert.BertPredictionHeadTransform
+class YosoPredictionHeadTransform(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ if isinstance(config.hidden_act, str):
+ self.transform_act_fn = ACT2FN[config.hidden_act]
+ else:
+ self.transform_act_fn = config.hidden_act
+ self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps)
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ hidden_states = self.dense(hidden_states)
+ hidden_states = self.transform_act_fn(hidden_states)
+ hidden_states = self.LayerNorm(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertLMPredictionHead with Bert->Yoso
+class YosoLMPredictionHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.transform = YosoPredictionHeadTransform(config)
+
+ # The output weights are the same as the input embeddings, but there is
+ # an output-only bias for each token.
+ self.decoder = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ self.bias = nn.Parameter(torch.zeros(config.vocab_size))
+
+ # Need a link between the two variables so that the bias is correctly resized with `resize_token_embeddings`
+ self.decoder.bias = self.bias
+
+ def _tie_weights(self):
+ self.decoder.bias = self.bias
+
+ def forward(self, hidden_states):
+ hidden_states = self.transform(hidden_states)
+ hidden_states = self.decoder(hidden_states)
+ return hidden_states
+
+
+# Copied from transformers.models.bert.modeling_bert.BertOnlyMLMHead with Bert->Yoso
+class YosoOnlyMLMHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.predictions = YosoLMPredictionHead(config)
+
+ def forward(self, sequence_output: torch.Tensor) -> torch.Tensor:
+ prediction_scores = self.predictions(sequence_output)
+ return prediction_scores
+
+
+@auto_docstring
+class YosoPreTrainedModel(PreTrainedModel):
+ config: YosoConfig
+ base_model_prefix = "yoso"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module: nn.Module):
+ """Initialize the weights"""
+ std = self.config.initializer_range
+ if isinstance(module, nn.Linear):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, YosoLMPredictionHead):
+ module.bias.data.zero_()
+
+
+@auto_docstring
+class YosoModel(YosoPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.config = config
+
+ self.embeddings = YosoEmbeddings(config)
+ self.encoder = YosoEncoder(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_input_embeddings(self):
+ return self.embeddings.word_embeddings
+
+ def set_input_embeddings(self, value):
+ self.embeddings.word_embeddings = value
+
+ def _prune_heads(self, heads_to_prune):
+ """
+ Prunes heads of the model. heads_to_prune: dict of {layer_num: list of heads to prune in this layer} See base
+ class PreTrainedModel
+ """
+ for layer, heads in heads_to_prune.items():
+ self.encoder.layer[layer].attention.prune_heads(heads)
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, BaseModelOutputWithCrossAttentions]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if input_ids is not None and inputs_embeds is not None:
+ raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
+ elif input_ids is not None:
+ self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask)
+ input_shape = input_ids.size()
+ elif inputs_embeds is not None:
+ input_shape = inputs_embeds.size()[:-1]
+ else:
+ raise ValueError("You have to specify either input_ids or inputs_embeds")
+
+ batch_size, seq_length = input_shape
+ device = input_ids.device if input_ids is not None else inputs_embeds.device
+
+ if attention_mask is None:
+ attention_mask = torch.ones(((batch_size, seq_length)), device=device)
+
+ if token_type_ids is None:
+ if hasattr(self.embeddings, "token_type_ids"):
+ buffered_token_type_ids = self.embeddings.token_type_ids[:, :seq_length]
+ buffered_token_type_ids_expanded = buffered_token_type_ids.expand(batch_size, seq_length)
+ token_type_ids = buffered_token_type_ids_expanded
+ else:
+ token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
+
+ # Prepare head mask if needed
+ # 1.0 in head_mask indicate we keep the head
+ # attention_probs has shape bsz x n_heads x N x N
+ # input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
+ # and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
+ head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
+
+ embedding_output = self.embeddings(
+ input_ids=input_ids,
+ position_ids=position_ids,
+ token_type_ids=token_type_ids,
+ inputs_embeds=inputs_embeds,
+ )
+ encoder_outputs = self.encoder(
+ embedding_output,
+ attention_mask=attention_mask,
+ head_mask=head_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ sequence_output = encoder_outputs[0]
+
+ if not return_dict:
+ return (sequence_output,) + encoder_outputs[1:]
+
+ return BaseModelOutputWithCrossAttentions(
+ last_hidden_state=sequence_output,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ cross_attentions=encoder_outputs.cross_attentions,
+ )
+
+
+@auto_docstring
+class YosoForMaskedLM(YosoPreTrainedModel):
+ _tied_weights_keys = ["cls.predictions.decoder.weight", "cls.predictions.decoder.bias"]
+
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.yoso = YosoModel(config)
+ self.cls = YosoOnlyMLMHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_output_embeddings(self):
+ return self.cls.predictions.decoder
+
+ def set_output_embeddings(self, new_embeddings):
+ self.cls.predictions.decoder = new_embeddings
+ self.cls.predictions.bias = new_embeddings.bias
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, MaskedLMOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ...,
+ config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the
+ loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.yoso(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ prediction_scores = self.cls(sequence_output)
+
+ masked_lm_loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss() # -100 index = padding token
+ masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1))
+
+ if not return_dict:
+ output = (prediction_scores,) + outputs[1:]
+ return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
+
+ return MaskedLMOutput(
+ loss=masked_lm_loss,
+ logits=prediction_scores,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+class YosoClassificationHead(nn.Module):
+ """Head for sentence-level classification tasks."""
+
+ def __init__(self, config):
+ super().__init__()
+ self.dense = nn.Linear(config.hidden_size, config.hidden_size)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.out_proj = nn.Linear(config.hidden_size, config.num_labels)
+
+ self.config = config
+
+ def forward(self, features, **kwargs):
+ x = features[:, 0, :] # take token (equiv. to [CLS])
+ x = self.dropout(x)
+ x = self.dense(x)
+ x = ACT2FN[self.config.hidden_act](x)
+ x = self.dropout(x)
+ x = self.out_proj(x)
+ return x
+
+
+@auto_docstring(
+ custom_intro="""
+ YOSO Model transformer with a sequence classification/regression head on top (a linear layer on top of
+ the pooled output) e.g. for GLUE tasks.
+ """
+)
+class YosoForSequenceClassification(YosoPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.yoso = YosoModel(config)
+ self.classifier = YosoClassificationHead(config)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SequenceClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.yoso(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(logits, labels)
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class YosoForMultipleChoice(YosoPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.yoso = YosoModel(config)
+ self.pre_classifier = nn.Linear(config.hidden_size, config.hidden_size)
+ self.classifier = nn.Linear(config.hidden_size, 1)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, MultipleChoiceModelOutput]:
+ r"""
+ input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`):
+ Indices of input sequence tokens in the vocabulary.
+
+ Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and
+ [`PreTrainedTokenizer.__call__`] for details.
+
+ [What are input IDs?](../glossary#input-ids)
+ token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,
+ 1]`:
+
+ - 0 corresponds to a *sentence A* token,
+ - 1 corresponds to a *sentence B* token.
+
+ [What are token type IDs?](../glossary#token-type-ids)
+ position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*):
+ Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0,
+ config.max_position_embeddings - 1]`.
+
+ [What are position IDs?](../glossary#position-ids)
+ inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*):
+ Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This
+ is useful if you want more control over how to convert *input_ids* indices into associated vectors than the
+ model's internal embedding lookup matrix.
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the multiple choice classification loss. Indices should be in `[0, ...,
+ num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See
+ `input_ids` above)
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1]
+
+ input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None
+ attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None
+ token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None
+ position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None
+ inputs_embeds = (
+ inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1))
+ if inputs_embeds is not None
+ else None
+ )
+
+ outputs = self.yoso(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_state = outputs[0] # (bs * num_choices, seq_len, dim)
+ pooled_output = hidden_state[:, 0] # (bs * num_choices, dim)
+ pooled_output = self.pre_classifier(pooled_output) # (bs * num_choices, dim)
+ pooled_output = nn.ReLU()(pooled_output) # (bs * num_choices, dim)
+ logits = self.classifier(pooled_output)
+
+ reshaped_logits = logits.view(-1, num_choices)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(reshaped_logits, labels)
+
+ if not return_dict:
+ output = (reshaped_logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return MultipleChoiceModelOutput(
+ loss=loss,
+ logits=reshaped_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class YosoForTokenClassification(YosoPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+
+ self.yoso = YosoModel(config)
+ self.dropout = nn.Dropout(config.hidden_dropout_prob)
+ self.classifier = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ labels: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, TokenClassifierOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.yoso(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ sequence_output = self.dropout(sequence_output)
+ logits = self.classifier(sequence_output)
+
+ loss = None
+ if labels is not None:
+ loss_fct = CrossEntropyLoss()
+ # Only keep active parts of the loss
+ if attention_mask is not None:
+ active_loss = attention_mask.view(-1) == 1
+ active_logits = logits.view(-1, self.num_labels)
+ active_labels = torch.where(
+ active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
+ )
+ loss = loss_fct(active_logits, active_labels)
+ else:
+ loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return TokenClassifierOutput(
+ loss=loss,
+ logits=logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+@auto_docstring
+class YosoForQuestionAnswering(YosoPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ config.num_labels = 2
+ self.num_labels = config.num_labels
+
+ self.yoso = YosoModel(config)
+ self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ token_type_ids: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.Tensor] = None,
+ head_mask: Optional[torch.Tensor] = None,
+ inputs_embeds: Optional[torch.Tensor] = None,
+ start_positions: Optional[torch.Tensor] = None,
+ end_positions: Optional[torch.Tensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, QuestionAnsweringModelOutput]:
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ outputs = self.yoso(
+ input_ids,
+ attention_mask=attention_mask,
+ token_type_ids=token_type_ids,
+ position_ids=position_ids,
+ head_mask=head_mask,
+ inputs_embeds=inputs_embeds,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ sequence_output = outputs[0]
+
+ logits = self.qa_outputs(sequence_output)
+ start_logits, end_logits = logits.split(1, dim=-1)
+ start_logits = start_logits.squeeze(-1)
+ end_logits = end_logits.squeeze(-1)
+
+ total_loss = None
+ if start_positions is not None and end_positions is not None:
+ # If we are on multi-GPU, split add a dimension
+ if len(start_positions.size()) > 1:
+ start_positions = start_positions.squeeze(-1)
+ if len(end_positions.size()) > 1:
+ end_positions = end_positions.squeeze(-1)
+ # sometimes the start/end positions are outside our model inputs, we ignore these terms
+ ignored_index = start_logits.size(1)
+ start_positions = start_positions.clamp(0, ignored_index)
+ end_positions = end_positions.clamp(0, ignored_index)
+
+ loss_fct = CrossEntropyLoss(ignore_index=ignored_index)
+ start_loss = loss_fct(start_logits, start_positions)
+ end_loss = loss_fct(end_logits, end_positions)
+ total_loss = (start_loss + end_loss) / 2
+
+ if not return_dict:
+ output = (start_logits, end_logits) + outputs[1:]
+ return ((total_loss,) + output) if total_loss is not None else output
+
+ return QuestionAnsweringModelOutput(
+ loss=total_loss,
+ start_logits=start_logits,
+ end_logits=end_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = [
+ "YosoForMaskedLM",
+ "YosoForMultipleChoice",
+ "YosoForQuestionAnswering",
+ "YosoForSequenceClassification",
+ "YosoForTokenClassification",
+ "YosoLayer",
+ "YosoModel",
+ "YosoPreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..48a233755de26862db8489d083ffc7f2809e821d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_zamba import *
+ from .modeling_zamba import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/configuration_zamba.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/configuration_zamba.py
new file mode 100644
index 0000000000000000000000000000000000000000..3de9a19d1bd73e52b5f9819bbe67cc816bc10503
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/configuration_zamba.py
@@ -0,0 +1,227 @@
+# coding=utf-8
+# Copyright 2024 Zyphra Technologies and the HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Zamba model configuration"""
+
+import math
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+
+
+logger = logging.get_logger(__name__)
+
+
+class ZambaConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`ZambaModel`]. It is used to instantiate a
+ Zamba model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the Zamba-v0.1 model.
+
+ [Zyphra/Zamba-7B-v1](https://huggingface.co/Zyphra/Zamba-7B-v1)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32000):
+ Vocabulary size of the Zamba model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`ZambaModel`]
+ tie_word_embeddings (`bool`, *optional*, defaults to `True`):
+ Whether the model's input and output word embeddings should be tied. Note that this is only relevant if the
+ model has a output word embedding layer.
+ hidden_size (`int`, *optional*, defaults to 3712):
+ Dimension of the hidden representations.
+ attention_hidden_size (`int`, *optional*):
+ Dimension of the hidden representations of the inputs to the Attention layer.
+ intermediate_size (`int`, *optional*, defaults to 14848):
+ Dimension of the MLP representations.
+ num_hidden_layers (`int`, *optional*, defaults to 76):
+ Number of hidden layers in the model.
+ num_attention_heads (`int`, *optional*, defaults to 16):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ attention_head_dim (`int`, *optional*):
+ Dimension of the attention head in the Transformer decoder.
+ num_key_value_heads (`int`, *optional*, defaults to 16):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=None`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1 the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details, check out [this
+ paper](https://huggingface.co/papers/2305.13245).
+ n_mamba_heads (`int`, *optional*, defaults to 2):
+ Number of mamba heads for each mamba layer.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the decoder.
+ hidden_mamba_act (`str` or `function`, *optional*, defaults to `"silu"`):
+ The non-linear activation function (function or string) in the mamba layer.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the rms normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ num_logits_to_keep (`int` or `None`, *optional*, defaults to 1):
+ Number of prompt logits to calculate during generation. If `None`, all logits will be calculated. If an
+ integer value, only last `num_logits_to_keep` logits will be calculated. Default is 1 because only the
+ logits of the last prompt token are needed for generation. For long sequences, the logits for the entire
+ sequence may use a lot of memory so, setting `num_logits_to_keep=1` will reduce memory footprint
+ significantly.
+ pad_token_id (`int`, *optional*, defaults to 0):
+ The id of the padding token.
+ bos_token_id (`int`, *optional*, defaults to 1):
+ The id of the "beginning-of-sequence" token.
+ eos_token_id (`int`, *optional*, defaults to 2):
+ The id of the "end-of-sequence" token.
+ max_position_embeddings (`int`, *optional*, defaults to 4096):
+ This value doesn't have any real effect. The maximum sequence length that this model is intended to be
+ used with. It can be used with longer sequences, but performance may degrade.
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ attn_layer_period (`int`, *optional*, defaults to 6):
+ Once in this many layers, we will have a shared attention layer
+ attn_layer_offset (`int`, *optional*, defaults to 4):
+ Offset of the shared attention layer
+ use_mamba_kernels (`bool`, *optional*, defaults to `True`):
+ Flag indicating whether or not to use the fast mamba kernels. These are available only if `mamba-ssm` and
+ `causal-conv1d` are installed, and the mamba modules are running on a CUDA device. Raises ValueError if
+ `True` and kernels are not available
+ mamba_d_state (`int`, *optional*, defaults to 16):
+ The dimension the mamba state space latents
+ mamba_d_conv (`int`, *optional*, defaults to 4):
+ The size of the mamba convolution kernel
+ mamba_expand (`int`, *optional*, defaults to 2):
+ Expanding factor (relative to hidden_size) used to determine the mamba intermediate size
+ mamba_dt_rank (`Union[int,str]`, *optional*, defaults to `"auto"`):
+ Rank of the mamba discretization projection matrix. `"auto"` means that it will default to `math.ceil(self.hidden_size / 16)`
+ time_step_min (`float`, *optional*, defaults to 0.001):
+ Minimum `time_step` used to bound `dt_proj_bias`.
+ time_step_max (`float`, *optional*, defaults to 0.1):
+ Maximum `time_step` used to bound `dt_proj_bias`.
+ time_step_floor (`float`, *optional*, defaults to 0.0001):
+ Minimum clamping value of the `dt_proj.bias` layer initialization.
+ mamba_conv_bias (`bool`, *optional*, defaults to `True`):
+ Flag indicating whether or not to use bias in the convolution layer of the mamba mixer block.
+ mamba_proj_bias (`bool`, *optional*, defaults to `False`):
+ Flag indicating whether or not to use bias in the input and output projections (["in_proj", "out_proj"]) of the mamba mixer block
+
+ """
+
+ model_type = "zamba"
+ keys_to_ignore_at_inference = ["past_key_values"]
+
+ def __init__(
+ self,
+ vocab_size=32000,
+ tie_word_embeddings=True,
+ hidden_size=3712,
+ attention_hidden_size=None,
+ intermediate_size=14848,
+ num_hidden_layers=76,
+ num_attention_heads=16,
+ attention_head_dim=None,
+ num_key_value_heads=16,
+ n_mamba_heads=2,
+ hidden_act="gelu",
+ hidden_mamba_act="silu",
+ initializer_range=0.02,
+ rms_norm_eps=1e-5,
+ use_cache=True,
+ num_logits_to_keep=1,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ max_position_embeddings=4096,
+ attention_dropout=0.0,
+ attn_layer_period=6,
+ attn_layer_offset=4,
+ use_mamba_kernels=True,
+ mamba_d_state=16,
+ mamba_d_conv=4,
+ mamba_expand=2,
+ mamba_dt_rank="auto",
+ time_step_min=0.001,
+ time_step_max=0.1,
+ time_step_floor=1e-4,
+ mamba_conv_bias=True,
+ mamba_proj_bias=False,
+ **kwargs,
+ ):
+ self.vocab_size = vocab_size
+ self.tie_word_embeddings = tie_word_embeddings
+ self.hidden_size = hidden_size
+ if attention_hidden_size is None:
+ self.attention_hidden_size = 2 * hidden_size
+ else:
+ self.attention_hidden_size = attention_hidden_size
+ self.intermediate_size = intermediate_size
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ if attention_head_dim is None:
+ self.attention_head_dim = 2 * self.hidden_size // self.num_attention_heads
+ else:
+ self.attention_head_dim = attention_head_dim
+ self.max_position_embeddings = max_position_embeddings
+ self.attention_dropout = attention_dropout
+
+ self.num_key_value_heads = num_key_value_heads
+ self.n_mamba_heads = n_mamba_heads
+ self.hidden_act = hidden_act
+ self.hidden_mamba_act = hidden_mamba_act
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+
+ self.use_cache = use_cache
+ self.num_logits_to_keep = num_logits_to_keep
+
+ self.attn_layer_period = attn_layer_period
+ self.attn_layer_offset = attn_layer_offset
+
+ self.use_mamba_kernels = use_mamba_kernels
+ self.mamba_d_state = mamba_d_state
+ self.mamba_d_conv = mamba_d_conv
+ self.mamba_expand = mamba_expand
+ self.mamba_dt_rank = math.ceil(self.hidden_size / 16) if mamba_dt_rank == "auto" else mamba_dt_rank
+ self.time_step_min = time_step_min
+ self.time_step_max = time_step_max
+ self.time_step_floor = time_step_floor
+ self.mamba_conv_bias = mamba_conv_bias
+ self.mamba_proj_bias = mamba_proj_bias
+
+ self.layers_block_type = self._layers_block_type(num_hidden_layers, attn_layer_period, attn_layer_offset)
+
+ assert (self.mamba_expand * self.hidden_size) % self.n_mamba_heads == 0, (
+ "`intermediate_size` should be divisible by `n_mamba_heads`."
+ )
+
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ tie_word_embeddings=tie_word_embeddings,
+ **kwargs,
+ )
+
+ def _layers_block_type(self, num_hidden_layers, attn_layer_period, attn_layer_offset):
+ layers = [
+ "mamba",
+ "mamba",
+ "hybrid",
+ ] + ["hybrid" if i % attn_layer_period == attn_layer_offset else "mamba" for i in range(num_hidden_layers - 3)]
+ return layers
+
+
+__all__ = ["ZambaConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/modeling_zamba.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/modeling_zamba.py
new file mode 100644
index 0000000000000000000000000000000000000000..9c0f86ea44892de3be584f5cfa6abcbbfcf6898c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba/modeling_zamba.py
@@ -0,0 +1,1311 @@
+# coding=utf-8
+# Copyright 2024 Zyphra Technologies and the HuggingFace Inc. team. All rights reserved.
+#
+# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX
+# and OPT implementations in this library. It has been modified from its
+# original forms to accommodate minor architectural differences compared
+# to GPT-NeoX and OPT used by the Meta AI team that trained the model.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch Zamba model."""
+
+import math
+from typing import Any, Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast, SequenceClassifierOutputWithPast
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from ...utils.import_utils import is_causal_conv1d_available, is_mamba_ssm_available
+from .configuration_zamba import ZambaConfig
+
+
+if is_mamba_ssm_available():
+ from mamba_ssm.ops.selective_scan_interface import mamba_inner_fn, selective_scan_fn
+ from mamba_ssm.ops.triton.selective_state_update import selective_state_update
+else:
+ selective_state_update, selective_scan_fn, mamba_inner_fn = None, None, None
+
+if is_causal_conv1d_available():
+ from causal_conv1d import causal_conv1d_fn, causal_conv1d_update
+else:
+ causal_conv1d_update, causal_conv1d_fn = None, None
+
+is_fast_path_available = all(
+ (selective_state_update, selective_scan_fn, causal_conv1d_fn, causal_conv1d_update, mamba_inner_fn)
+)
+
+
+logger = logging.get_logger(__name__)
+
+
+# Copied from transformers.models.llama.modeling_llama.LlamaRMSNorm with Llama->Zamba
+class ZambaRMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ ZambaRMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+# Copied from transformers.models.llama.modeling_llama.repeat_kv
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+class ZambaHybridDynamicCache:
+ """
+ A dynamic cache that can handle both the attention cache (which has a seq_len dimension) and the mamba cache
+ (which has a constant shape regardless of seq_len).
+
+ This cache has two sets of lists of tensors: `key_cache` and `value_cache` for attention cache and `conv_states`
+ and `ssm_states` for mamba cache. Each of these lists has `num_layers` tensors. The expected shape for each tensor
+ For attention layers, `key_cache` and `value_cache` have a shape of `(batch_size, num_heads, seq_len, head_dim)`,
+ while `conv_states` and `ssm_states` have a shape of `(batch_size, 0)` (empty tensors).
+ For mamba layers, `key_cache` and `value_cache` have a shape of `(batch_size, 0)` (empty tensors),
+ while `conv_states` represents the convolution state and has a shape of `(batch_size, d_inner, d_conv)`,
+ and `ssm_states` represents the ssm state and has a shape of `(batch_size, d_inner, d_state)`.
+ """
+
+ is_compileable = False
+
+ def __init__(self, config, batch_size, dtype=torch.float16, device=None):
+ self.dtype = dtype
+ self.is_compileable = False
+ self.layers_block_type = config.layers_block_type
+ self.has_previous_state = False # only used by mamba
+ self.intermediate_size = config.mamba_expand * config.hidden_size
+ self.ssm_state_size = config.mamba_d_state
+ self.conv_kernel_size = config.mamba_d_conv
+ self.n_mamba_heads = config.n_mamba_heads
+ self.conv_states = []
+ self.ssm_states = []
+ self.transformer_layers = []
+ self._modules = {}
+ self._parameters = {}
+ self._buffers = {}
+ for i in range(config.num_hidden_layers):
+ self.conv_states += [
+ torch.zeros(batch_size, self.intermediate_size, self.conv_kernel_size, device=device, dtype=dtype)
+ ]
+ cache_shape = (
+ batch_size,
+ self.n_mamba_heads,
+ self.intermediate_size // self.n_mamba_heads,
+ self.ssm_state_size,
+ )
+ self.ssm_states += [torch.zeros(cache_shape, device=device, dtype=dtype)]
+ if self.layers_block_type[i] == "hybrid":
+ self.transformer_layers.append(i)
+
+ self.key_cache = [torch.tensor([[]] * batch_size, device=device) for _ in range(config.num_hidden_layers)]
+ self.value_cache = [torch.tensor([[]] * batch_size, device=device) for _ in range(config.num_hidden_layers)]
+
+ def __len__(self):
+ return len(self.key_cache)
+
+ def __getitem__(self, layer_idx: int) -> tuple[torch.Tensor, torch.Tensor]:
+ return self.key_cache[layer_idx], self.value_cache[layer_idx]
+
+ # Copied from transformers.models.jamba.modeling_jamba.HybridMambaAttentionDynamicCache.update
+ def update(
+ self,
+ key_states: torch.Tensor,
+ value_states: torch.Tensor,
+ layer_idx: int,
+ cache_kwargs: Optional[dict[str, Any]] = None,
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ # Update the cache
+ if self.key_cache[layer_idx].shape[-1] == 0:
+ self.key_cache[layer_idx] = key_states
+ self.value_cache[layer_idx] = value_states
+ else:
+ self.key_cache[layer_idx] = torch.cat([self.key_cache[layer_idx], key_states], dim=2)
+ self.value_cache[layer_idx] = torch.cat([self.value_cache[layer_idx], value_states], dim=2)
+
+ return self.key_cache[layer_idx], self.value_cache[layer_idx]
+
+ # Copied from transformers.models.jamba.modeling_jamba.HybridMambaAttentionDynamicCache.reorder_cache
+ def reorder_cache(self, beam_idx: torch.LongTensor):
+ """Reorders the cache for beam search, given the selected beam indices."""
+ for layer_idx in range(len(self.key_cache)):
+ device = self.key_cache[layer_idx].device
+ self.key_cache[layer_idx] = self.key_cache[layer_idx].index_select(0, beam_idx.to(device))
+ device = self.value_cache[layer_idx].device
+ self.value_cache[layer_idx] = self.value_cache[layer_idx].index_select(0, beam_idx.to(device))
+
+ device = self.conv_states[layer_idx].device
+ self.conv_states[layer_idx] = self.conv_states[layer_idx].index_select(0, beam_idx.to(device))
+ device = self.ssm_states[layer_idx].device
+ self.ssm_states[layer_idx] = self.ssm_states[layer_idx].index_select(0, beam_idx.to(device))
+
+ # Copied from transformers.models.jamba.modeling_jamba.HybridMambaAttentionDynamicCache.get_seq_length
+ def get_seq_length(self, layer_idx: Optional[int] = 0) -> int:
+ """Returns the sequence length of the cached states. A layer index can be optionally passed."""
+ # take any layer that contains cache and not empty tensor
+ layer_idx = self.transformer_layers[0] if layer_idx not in self.transformer_layers else layer_idx
+ if len(self.key_cache) <= layer_idx:
+ return 0
+ return self.key_cache[layer_idx].shape[-2]
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+class ZambaAttention(nn.Module):
+ """
+ Multi-headed attention from 'Attention Is All You Need' paper. Modified to use sliding window attention: Longformer
+ and "Generating Long Sequences with Sparse Transformers".
+
+ Adapted from transformers.models.mistral.modeling_mistral.MistralAttention:
+ The input dimension here is attention_hidden_size = 2 * hidden_size, and head_dim = attention_hidden_size // num_heads.
+ The extra factor of 2 comes from the input being the concatenation of original_hidden_states with the output of the previous (mamba) layer
+ (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ Additionally, replaced
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim) with
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim/2)
+ """
+
+ def __init__(self, config: ZambaConfig, layer_idx: int):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+
+ self.attention_hidden_size = config.attention_hidden_size
+ self.head_dim = config.attention_head_dim
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.max_position_embeddings = config.max_position_embeddings
+ self.scaling = (self.head_dim / 2) ** -0.5
+ self.is_causal = True
+ self.attention_dropout = config.attention_dropout
+
+ self.q_proj = nn.Linear(config.attention_hidden_size, config.num_attention_heads * self.head_dim, bias=False)
+ self.k_proj = nn.Linear(config.attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=False)
+ self.v_proj = nn.Linear(config.attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=False)
+ self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=False)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ layer_idx: int,
+ attention_mask: Optional[torch.Tensor],
+ past_key_values: Optional[ZambaHybridDynamicCache] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+ value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2)
+
+ if past_key_values is not None:
+ key_states, value_states = past_key_values.update(key_states, value_states, layer_idx)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class ZambaMambaMixer(nn.Module):
+ """
+ Compute ∆, A, B, C, and D the state space parameters and compute the `contextualized_states`.
+ A, D are input independent (see Mamba paper [1] Section 3.5.2 "Interpretation of A" for why A isn't selective)
+ ∆, B, C are input-dependent (this is a key difference between Mamba and the linear time invariant S4,
+ and is why Mamba is called **selective** state spaces)
+
+ This module differs from `transformers.models.mamba.modeling_mamba.MambaMixer` in two ways:
+ - Added multi-head: the output of `self.in_proj` is split into `self.n_mamba_heads` heads, and each head
+ undergoes an independent forward pass, identical to the original `MambaMixer`, up until the pre-activations of
+ `self.out_proj`. The pre-activations, coming from different mamba heads, are then concatenated and fed into `self.out_proj`.
+ """
+
+ def __init__(self, config: ZambaConfig, layer_idx):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+ self.hidden_size = config.hidden_size
+ self.ssm_state_size = config.mamba_d_state
+ self.conv_kernel_size = config.mamba_d_conv
+ self.intermediate_size = config.mamba_expand * config.hidden_size
+ self.time_step_rank = config.mamba_dt_rank
+ self.n_mamba_heads = config.n_mamba_heads
+ self.mamba_head_dim = self.intermediate_size // self.n_mamba_heads
+ self.use_conv_bias = config.mamba_conv_bias
+ self.use_bias = config.mamba_proj_bias
+ self.conv1d = nn.Conv1d(
+ in_channels=self.intermediate_size,
+ out_channels=self.intermediate_size,
+ bias=self.use_conv_bias,
+ kernel_size=self.conv_kernel_size,
+ groups=self.intermediate_size,
+ padding=self.conv_kernel_size - 1,
+ )
+
+ self.activation = config.hidden_mamba_act
+ self.act = ACT2FN[config.hidden_mamba_act]
+
+ self.use_fast_kernels = config.use_mamba_kernels
+
+ # projection of the input hidden states
+ self.in_proj = nn.Linear(self.hidden_size, self.intermediate_size * 2, bias=self.use_bias)
+ # weight associated to the selective projection used to make dt, B and C input dependent
+ # each mamba head is processed independently
+ self.x_proj_weight = nn.Parameter(
+ torch.zeros(
+ self.n_mamba_heads,
+ self.time_step_rank + self.ssm_state_size * 2,
+ self.mamba_head_dim,
+ )
+ )
+ # time step projection (discretization)
+ self.dt_proj_weight = nn.Parameter(
+ (torch.zeros(self.n_mamba_heads, self.mamba_head_dim, self.time_step_rank) - 0.5)
+ * 2
+ / self.time_step_rank**0.5
+ )
+ self.dt_proj_bias = nn.Parameter(torch.zeros(self.n_mamba_heads, self.mamba_head_dim))
+
+ # S4D real initialization. These are not discretized!
+ # The core is to load them, compute the discrete states, then write the updated state. Keeps the memory bounded
+ A = torch.arange(1, self.ssm_state_size + 1, dtype=torch.float32)[None, :]
+ A = A.expand(self.intermediate_size, -1).contiguous()
+ self.A_log = nn.Parameter(torch.log(A).reshape(self.n_mamba_heads, self.mamba_head_dim, -1))
+ self.D = nn.Parameter(torch.ones(self.n_mamba_heads, self.mamba_head_dim))
+ self.out_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=self.use_bias)
+
+ if not is_fast_path_available:
+ logger.warning_once(
+ "The fast path is not available because on of `(selective_state_update, selective_scan_fn, causal_conv1d_fn, causal_conv1d_update, mamba_inner_fn)`"
+ " is None. To install follow https://github.com/state-spaces/mamba/#installation and"
+ " https://github.com/Dao-AILab/causal-conv1d. If you want to use the naive implementation, set `use_mamba_kernels=False` in the model config"
+ )
+
+ def cuda_kernels_forward(
+ self, hidden_states: torch.Tensor, cache_params: ZambaHybridDynamicCache = None, attention_mask=None
+ ):
+ batch_size, seq_len, _ = hidden_states.shape
+ use_precomputed_states = cache_params is not None and cache_params.has_previous_state and seq_len == 1
+
+ # 1. Gated linear projection
+ projected_states = self.in_proj(hidden_states).transpose(1, 2)
+
+ hidden_states, gate = projected_states.view(batch_size, -1, 2, seq_len).chunk(2, dim=2)
+ hidden_states = hidden_states.squeeze(2).contiguous()
+ gate = gate.squeeze(2)
+ gate = gate.reshape(batch_size, self.n_mamba_heads, -1, seq_len).transpose(0, 1)
+
+ # 2. Convolution sequence transformation
+ conv_weights = self.conv1d.weight.view(self.conv1d.weight.size(0), self.conv1d.weight.size(2))
+ if use_precomputed_states:
+ hidden_states = causal_conv1d_update(
+ hidden_states.squeeze(-1),
+ cache_params.conv_states[self.layer_idx],
+ conv_weights,
+ self.conv1d.bias,
+ self.activation,
+ )
+ hidden_states = hidden_states.unsqueeze(-1)
+ else:
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ hidden_states = hidden_states * attention_mask.unsqueeze(1)
+ if cache_params is not None:
+ conv_states = nn.functional.pad(hidden_states, (self.conv_kernel_size - hidden_states.shape[-1], 0))
+ cache_params.conv_states[self.layer_idx].copy_(conv_states)
+ hidden_states = causal_conv1d_fn(hidden_states, conv_weights, self.conv1d.bias, activation=self.activation)
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ hidden_states = hidden_states * attention_mask.unsqueeze(1)
+
+ # 3. SSM sequence transformation
+ # 3.a. input varying initialization of time_step, B and C
+
+ hidden_states = hidden_states.reshape(-1, self.n_mamba_heads, self.mamba_head_dim, seq_len).transpose(0, 1)
+ ssm_parameters = (self.x_proj_weight[:, None, :, :] @ hidden_states).transpose(-1, -2)
+
+ time_step, B, C = torch.split(
+ ssm_parameters, [self.time_step_rank, self.ssm_state_size, self.ssm_state_size], dim=-1
+ )
+
+ discrete_time_step = self.dt_proj_weight[:, None] @ time_step.transpose(-1, -2)
+
+ A = -torch.exp(self.A_log.float())
+
+ # 3.c perform the recurrence y ← SSM(A, B, C)(x)
+ time_proj_bias = self.dt_proj_bias.float() if self.dt_proj_bias is not None else None
+ scan_outputs = torch.empty((batch_size, 0, seq_len), device=hidden_states.device, dtype=hidden_states.dtype)
+
+ if use_precomputed_states:
+ for n in range(self.n_mamba_heads):
+ scan_outputs_ = selective_state_update(
+ cache_params.ssm_states[self.layer_idx][:, n],
+ hidden_states[n, ..., 0],
+ discrete_time_step[n, ..., 0],
+ A[n],
+ B[n, :, 0],
+ C[n, :, 0],
+ self.D[n],
+ gate[n, ..., 0],
+ time_proj_bias[n],
+ dt_softplus=True,
+ ).unsqueeze(-1)
+ scan_outputs = torch.cat((scan_outputs, scan_outputs_), dim=1)
+
+ else:
+ ssm_state = torch.empty(
+ (batch_size, 0, self.mamba_head_dim, self.ssm_state_size),
+ device=hidden_states.device,
+ dtype=hidden_states.dtype,
+ )
+ for n in range(self.n_mamba_heads):
+ scan_outputs_, ssm_state_ = selective_scan_fn(
+ hidden_states[n],
+ discrete_time_step[n],
+ A[n],
+ B[n].transpose(1, 2),
+ C[n].transpose(1, 2),
+ self.D[n].float(),
+ gate[n],
+ time_proj_bias[n],
+ delta_softplus=True,
+ return_last_state=True,
+ )
+ scan_outputs = torch.cat((scan_outputs, scan_outputs_), dim=1).contiguous()
+ ssm_state = torch.cat((ssm_state, ssm_state_.unsqueeze(1)), dim=1)
+ if ssm_state is not None and cache_params is not None:
+ cache_params.ssm_states[self.layer_idx].copy_(ssm_state)
+
+ # 4. Final linear projection
+ contextualized_states = self.out_proj(scan_outputs.transpose(1, 2))
+ return contextualized_states
+
+ def slow_forward(self, input_states, cache_params: ZambaHybridDynamicCache = None, attention_mask=None):
+ batch_size, seq_len, _ = input_states.shape
+ dtype = input_states.dtype
+ # 1. Gated linear projection
+ projected_states = self.in_proj(input_states).transpose(1, 2)
+
+ hidden_states, gate = projected_states.view(batch_size, -1, 2, seq_len).chunk(2, dim=2)
+ hidden_states = hidden_states.squeeze(2).contiguous()
+ gate = gate.squeeze(2)
+ gate = gate.reshape(batch_size, self.n_mamba_heads, -1, seq_len).transpose(0, 1)
+
+ use_cache = isinstance(cache_params, ZambaHybridDynamicCache)
+ # 2. Convolution sequence transformation
+ if use_cache and cache_params.ssm_states[self.layer_idx].shape[0] == batch_size:
+ if self.training:
+ # In training mode, we don't want to perform in-place operations on ssm_state so we can compute the backwards pass
+ ssm_state = cache_params.ssm_states[self.layer_idx].clone()
+ else:
+ ssm_state = cache_params.ssm_states[self.layer_idx]
+
+ ssm_state = ssm_state.to(hidden_states.device)
+
+ if (
+ cache_params.has_previous_state
+ and seq_len == 1
+ and cache_params.conv_states[self.layer_idx].shape[0] == batch_size
+ ):
+ conv_state = cache_params.conv_states[self.layer_idx]
+ conv_state = torch.roll(conv_state, shifts=-1, dims=-1)
+ conv_state[:, :, -1] = hidden_states[:, :, 0]
+ cache_params.conv_states[self.layer_idx] = conv_state
+ hidden_states = torch.sum(conv_state * self.conv1d.weight[:, 0, :], dim=-1)
+ if self.use_conv_bias:
+ hidden_states += self.conv1d.bias
+ hidden_states = self.act(hidden_states).to(dtype).unsqueeze(-1)
+ else:
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ hidden_states = hidden_states * attention_mask[:, -hidden_states.shape[-1] :].unsqueeze(1)
+ conv_state = nn.functional.pad(hidden_states, (self.conv_kernel_size - hidden_states.shape[-1], 0))
+ cache_params.conv_states[self.layer_idx] = conv_state
+ hidden_states = self.act(self.conv1d(hidden_states)[..., :seq_len])
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ hidden_states = hidden_states * attention_mask[:, -hidden_states.shape[-1] :].unsqueeze(1)
+ else:
+ ssm_state = torch.zeros(
+ (batch_size, self.n_mamba_heads, self.mamba_head_dim, self.ssm_state_size),
+ device=hidden_states.device,
+ dtype=dtype,
+ )
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ hidden_states = hidden_states * attention_mask.unsqueeze(1)
+ hidden_states = self.act(self.conv1d(hidden_states)[..., :seq_len])
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ hidden_states = hidden_states * attention_mask.unsqueeze(1)
+
+ # 3. State Space Model sequence transformation
+ # 3.a. Selection: [batch, seq_len, self.time_step_rank + self.ssm_state_size * 2]
+ hidden_states = hidden_states.reshape(-1, self.n_mamba_heads, self.mamba_head_dim, seq_len).transpose(0, 1)
+ ssm_parameters = (self.x_proj_weight[:, None, :, :] @ hidden_states).transpose(-1, -2)
+
+ time_step, B, C = torch.split(
+ ssm_parameters, [self.time_step_rank, self.ssm_state_size, self.ssm_state_size], dim=-1
+ )
+ discrete_time_step = (self.dt_proj_weight[:, None] @ time_step.transpose(-1, -2)) + self.dt_proj_bias[
+ :, None, :, None
+ ]
+
+ discrete_time_step = nn.functional.softplus(discrete_time_step)
+
+ # 3.b. Discretization: B and C to [batch, seq_len, intermediate_size, ssm_state_size] (SRAM)
+ A = -torch.exp(self.A_log.float())
+ discrete_A = torch.exp(A[:, None, :, None, :] * discrete_time_step[:, :, :, :, None])
+ discrete_B = discrete_time_step[:, :, :, :, None] * B[:, :, None, :, :].float()
+ deltaB_u = discrete_B * hidden_states[:, :, :, :, None].float()
+ # 3.c perform the recurrence y ← SSM(A, B, C)(x)
+ scan_outputs = []
+ for i in range(seq_len):
+ ssm_state = discrete_A[:, :, :, i, :].transpose(0, 1) * ssm_state + deltaB_u[:, :, :, i, :].transpose(0, 1)
+ scan_output = torch.matmul(ssm_state.transpose(0, 1).to(dtype), C[:, :, i, :].unsqueeze(-1))
+ scan_outputs.append(scan_output[:, :, :, 0])
+ scan_output = torch.stack(scan_outputs, dim=-1)
+ scan_output = scan_output + (hidden_states * self.D[:, None, :, None])
+ scan_output = scan_output * self.act(gate)
+
+ if use_cache:
+ cache_params.ssm_states[self.layer_idx] = ssm_state
+
+ # 4. Final linear projection
+ contextualized_states = self.out_proj(
+ scan_output.transpose(0, 1).reshape(batch_size, -1, seq_len).transpose(1, 2)
+ )
+ return contextualized_states
+
+ def forward(self, hidden_states, cache_params: ZambaHybridDynamicCache = None, attention_mask=None):
+ if self.use_fast_kernels:
+ if not is_fast_path_available or "cuda" not in self.x_proj_weight.device.type:
+ raise ValueError(
+ "Fast Mamba kernels are not available. Make sure to they are installed and that "
+ "the mamba module is on a CUDA device. lease run 'pip install causal-conv1d>=1.2.0' "
+ "and 'pip install mamba-ssm', or set use_mamba_kernels=False in the model's config."
+ )
+ return self.cuda_kernels_forward(hidden_states, cache_params, attention_mask=attention_mask)
+ return self.slow_forward(hidden_states, cache_params, attention_mask=attention_mask)
+
+
+# Copied from transformers.models.mistral.modeling_mistral.MistralMLP with Mistral->Zamba
+class ZambaMLP(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ def forward(self, x):
+ down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x))
+ return down_proj
+
+
+class ZambaAttentionDecoderLayer(nn.Module):
+ def __init__(self, config: ZambaConfig, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.self_attn = ZambaAttention(config, layer_idx)
+
+ self.feed_forward = ZambaMLP(config)
+ self.input_layernorm = ZambaRMSNorm(config.attention_hidden_size, eps=config.rms_norm_eps)
+ self.pre_ff_layernorm = ZambaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: torch.Tensor,
+ layer_idx: int,
+ attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[ZambaHybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): output of previous Mamba layer of shape `(batch, seq_len, embed_dim)`
+ original_hidden_states (`torch.FloatTensor`): word embedding output of shape `(batch, seq_len, embed_dim)`.
+ This is concatenated with `hidden_states` (which is the output of the previous (mamba) layer). The
+ concatenated tensor is then used as input of the pre-attention RMSNorm
+ (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ layer_idx (`int`): layer_idx in the forward pass. Used to distinguish Zamba's tied transformer layers.
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`ZambaHybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ """
+ hidden_states = torch.concatenate([hidden_states, original_hidden_states], dim=-1)
+ hidden_states = self.input_layernorm(hidden_states)
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ **kwargs,
+ )
+ # feed-forward (MLP)
+ hidden_states = self.pre_ff_layernorm(hidden_states)
+ hidden_states = self.feed_forward(hidden_states)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+class ZambaMambaDecoderLayer(nn.Module):
+ def __init__(self, config: ZambaConfig, layer_idx: int):
+ super().__init__()
+ self.mamba = ZambaMambaMixer(config=config, layer_idx=layer_idx)
+ self.input_layernorm = ZambaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.layer_idx = layer_idx
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: Optional[torch.Tensor] = None,
+ layer_idx: Optional[int] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[ZambaHybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ transformer_hidden_states: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`ZambaHybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ """
+
+ residual = hidden_states
+
+ # `transformer_hidden_states` is the output from shared transformer + linear layer (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ # `transformer_hidden_states` is then added to the input to the mamba layer below (as described in eq. (6) of https://huggingface.co/papers/2405.16712).
+ hidden_states = (
+ hidden_states + transformer_hidden_states if transformer_hidden_states is not None else hidden_states
+ )
+ hidden_states = self.input_layernorm(hidden_states)
+
+ hidden_states = self.mamba(
+ hidden_states=hidden_states,
+ cache_params=past_key_values,
+ attention_mask=attention_mask,
+ )
+
+ self_attn_weights = None
+
+ # residual connection after mamba
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ if use_cache:
+ outputs += (past_key_values,)
+
+ return outputs
+
+
+class ZambaHybridLayer(nn.Module):
+ def __init__(self, shared_transf: ZambaAttentionDecoderLayer, linear: nn.Linear, mamba: ZambaMambaDecoderLayer):
+ super().__init__()
+ self.shared_transf = shared_transf
+ self.linear = linear
+ self.mamba_decoder = mamba
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: Optional[torch.Tensor] = None,
+ layer_idx: Optional[int] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[ZambaHybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ original_hidden_states (`torch.FloatTensor`): word embedding output that will be concatenated with
+ hidden activations to form the input of the shared transformer layer.
+ layer_idx (`int`): layer number.
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`ZambaHybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ """
+
+ layer_outputs = self.shared_transf(
+ hidden_states,
+ original_hidden_states=original_hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=causal_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+
+ transformer_hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ self_attn_weights = layer_outputs[1]
+
+ transformer_hidden_states = self.linear(transformer_hidden_states)
+
+ layer_outputs = self.mamba_decoder(
+ hidden_states,
+ transformer_hidden_states=transformer_hidden_states,
+ attention_mask=attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+
+ if output_attentions:
+ layer_outputs = (layer_outputs[0], self_attn_weights) + layer_outputs[2:]
+
+ return layer_outputs
+
+
+@auto_docstring
+class ZambaPreTrainedModel(PreTrainedModel):
+ config: ZambaConfig
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["ZambaAttentionDecoderLayer", "ZambaMambaDecoderLayer"]
+ _skip_keys_device_placement = "past_key_values"
+ _supports_flash_attn = False
+ _supports_sdpa = False
+ # Note: only supports ZambaHybridDynamicCache
+ _is_stateful = True
+
+ def _init_weights(self, module):
+ std = self.config.initializer_range
+ if isinstance(module, (nn.Linear, nn.Conv1d)):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=std)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, ZambaRMSNorm):
+ module.weight.data.fill_(1.0)
+ elif isinstance(module, ZambaMambaMixer):
+ module.x_proj_weight.data.normal_(mean=0.0, std=std)
+ dt_init_std = self.config.mamba_dt_rank**-0.5
+ nn.init.uniform_(module.dt_proj_weight, -dt_init_std, dt_init_std)
+
+ mamba_head_dim = self.config.mamba_expand * self.config.hidden_size // self.config.n_mamba_heads
+ dt = torch.exp(
+ torch.rand(self.config.n_mamba_heads, mamba_head_dim)
+ * (math.log(self.config.time_step_max) - math.log(self.config.time_step_min))
+ + math.log(self.config.time_step_min)
+ ).clamp(min=self.config.time_step_floor)
+ # # Inverse of softplus: https://github.com/pytorch/pytorch/issues/72759
+ inv_dt = dt + torch.log(-torch.expm1(-dt))
+ module.dt_proj_bias.data.copy_(inv_dt)
+
+ A = torch.arange(1, module.ssm_state_size + 1, dtype=torch.float32)[None, :]
+ A = A.expand(module.intermediate_size, -1).contiguous()
+ module.A_log.data.copy_(torch.log(A).reshape(module.n_mamba_heads, module.mamba_head_dim, -1))
+ module.D.data.fill_(1.0)
+
+
+@auto_docstring
+class ZambaModel(ZambaPreTrainedModel):
+ """
+ Transformer decoder consisting of *config.num_hidden_layers* layers. Each layer is a [`ZambaDecoderLayer`]
+
+ Args:
+ config: ZambaConfig
+ """
+
+ def __init__(self, config: ZambaConfig):
+ super().__init__(config)
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ block = ZambaAttentionDecoderLayer(config)
+ mamba_layers = []
+ linear_layers = []
+ self.layers_block_type = config.layers_block_type
+ for i in range(config.num_hidden_layers):
+ if config.layers_block_type[i] == "mamba":
+ mamba_layers.append(ZambaMambaDecoderLayer(config, layer_idx=i))
+ elif config.layers_block_type[i] == "hybrid":
+ linear_layers.append(nn.Linear(self.config.hidden_size, self.config.hidden_size, bias=False))
+ mamba_layers.append(ZambaMambaDecoderLayer(config, layer_idx=i))
+ mamba_layers = iter(mamba_layers)
+ linear_layers = iter(linear_layers)
+ layers = []
+ self._tied_weights_keys = []
+ for layer_id, layer_type in enumerate(self.layers_block_type):
+ if layer_type == "hybrid":
+ prefix_name = f"layers.{layer_id}."
+ tied_keys = [
+ "shared_transf.self_attn.q_proj.weight",
+ "shared_transf.self_attn.k_proj.weight",
+ "shared_transf.self_attn.v_proj.weight",
+ "shared_transf.self_attn.o_proj.weight",
+ "shared_transf.feed_forward.gate_proj.weight",
+ "shared_transf.feed_forward.up_proj.weight",
+ "shared_transf.feed_forward.down_proj.weight",
+ "shared_transf.input_layernorm.weight",
+ "shared_transf.pre_ff_layernorm.weight",
+ ]
+ self._tied_weights_keys = [*self._tied_weights_keys, *[prefix_name + key for key in tied_keys]]
+ layers.append(ZambaHybridLayer(block, next(linear_layers), next(mamba_layers)))
+ else:
+ layers.append(next(mamba_layers))
+ self.layers = nn.ModuleList(layers)
+
+ self._attn_implementation = config._attn_implementation
+ self.final_layernorm = ZambaRMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ self.gradient_checkpointing = False
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[ZambaHybridDynamicCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPast]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError(
+ "You cannot specify both input_ids and inputs_embeds at the same time, and must specify either one"
+ )
+
+ if self.gradient_checkpointing and self.training and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ hidden_states = inputs_embeds
+
+ original_hidden_states = torch.clone(inputs_embeds)
+ # original_hidden_states: word embedding output that will be concatenated with hidden activations to form the input of the shared transformer layer
+
+ if use_cache and past_key_values is None:
+ logger.warning_once(
+ "Zamba requires an initialized `ZambaHybridDynamicCache` to return a cache. None was "
+ "provided, so no cache will be returned."
+ )
+
+ if cache_position is None:
+ cache_position = torch.arange(hidden_states.shape[1], device=hidden_states.device)
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ causal_mask = self._update_causal_mask(attention_mask, inputs_embeds, cache_position)
+
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+
+ for layer_idx, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ layer.__call__,
+ hidden_states,
+ original_hidden_states,
+ layer_idx,
+ attention_mask,
+ causal_mask,
+ past_key_values,
+ output_attentions,
+ use_cache,
+ cache_position,
+ )
+ else:
+ layer_outputs = layer(
+ hidden_states,
+ original_hidden_states=original_hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=attention_mask,
+ causal_mask=causal_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ cache_position=cache_position,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ if layer_outputs[1] is not None:
+ # append attentions only of attention layers. Mamba layers return `None` as the attention weights
+ all_self_attns += (layer_outputs[1],)
+
+ hidden_states = self.final_layernorm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if past_key_values and not past_key_values.has_previous_state:
+ past_key_values.has_previous_state = True
+
+ output = BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ )
+ return output if return_dict else output.to_tuple()
+
+ # Copied from transformers.models.jamba.modeling_jamba.JambaModel._update_causal_mask
+ def _update_causal_mask(self, attention_mask, input_tensor, cache_position):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and 0.0 in attention_mask:
+ return attention_mask
+ return None
+
+ dtype, device = input_tensor.dtype, input_tensor.device
+ min_dtype = torch.finfo(dtype).min
+ sequence_length = input_tensor.shape[1]
+ target_length = cache_position[-1] + 1
+
+ causal_mask = torch.full((sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=device)
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(input_tensor.shape[0], 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ if attention_mask.dim() == 2:
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[..., :mask_length].eq(0.0) * attention_mask[:, None, None, :].eq(0.0)
+ causal_mask[..., :mask_length] = causal_mask[..., :mask_length].masked_fill(padding_mask, min_dtype)
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type in ["cuda", "xpu", "npu"]
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+
+# Adapted from transformers.models.jamba.modeling_jamba.JambaForCausalLM with Jamba->Zamba, JAMBA->ZAMBA
+class ZambaForCausalLM(ZambaPreTrainedModel, GenerationMixin):
+ def __init__(self, config: ZambaConfig):
+ super().__init__(config)
+ self.model = ZambaModel(config)
+ self._tied_weights_keys = ["lm_head.weight", *self.model._tied_weights_keys]
+ self.vocab_size = config.vocab_size
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[ZambaHybridDynamicCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs,
+ ) -> Union[tuple, CausalLMOutputWithPast]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, ZambaForCausalLM
+
+ >>> model = ZambaForCausalLM.from_pretrained("Zyphra/Zamba-7B-v1")
+ >>> tokenizer = AutoTokenizer.from_pretrained("Zyphra/Zamba-7B-v1")
+
+ >>> prompt = "Hey, are you conscious? Can you talk to me?"
+ >>> inputs = tokenizer(prompt, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(inputs.input_ids, max_length=30)
+ >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+ "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you."
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
+ outputs = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ cache_position=cache_position,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits, labels, self.vocab_size, **kwargs)
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return (loss,) + output if loss is not None else output
+
+ return CausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ past_key_values=None,
+ attention_mask=None,
+ inputs_embeds=None,
+ cache_position=None,
+ position_ids=None,
+ use_cache=True,
+ **kwargs,
+ ):
+ # Overwritten -- has a unique cache type, `ZambaHybridDynamicCache`
+
+ empty_past_kv = past_key_values is None
+
+ # Omit tokens covered by past_key_values
+ if not empty_past_kv:
+ # If we have cache: let's slice `input_ids` through `cache_position`, to keep only the unprocessed tokens
+ # Exception 1: when passing input_embeds, input_ids may be missing entries
+ # Exception 2: some generation methods do special slicing of input_ids, so we don't need to do it here
+ # Exception 3: with synced GPUs cache_position may go out of bounds, but we only want dummy token in that case.
+ # (we can't check exception 3 while compiling)
+ if (
+ inputs_embeds is not None # Exception 1
+ or cache_position[-1] >= input_ids.shape[1] # Exception 3
+ ):
+ input_ids = input_ids[:, -cache_position.shape[0] :]
+ elif input_ids.shape[1] != cache_position.shape[0]: # Default case (the "else", a no op, is Exception 2)
+ input_ids = input_ids[:, cache_position]
+ else:
+ past_key_values = ZambaHybridDynamicCache(
+ self.config, input_ids.shape[0], dtype=self.dtype, device=self.device
+ )
+
+ if attention_mask is not None and position_ids is None:
+ # create position_ids on the fly for batch generation
+ position_ids = attention_mask.long().cumsum(-1) - 1
+ position_ids.masked_fill_(attention_mask == 0, 1)
+ if not empty_past_kv:
+ position_ids = position_ids[:, -input_ids.shape[1] :]
+
+ # if `inputs_embeds` are passed, we only want to use them in the 1st generation step
+ if inputs_embeds is not None and empty_past_kv:
+ model_inputs = {"inputs_embeds": inputs_embeds}
+ else:
+ model_inputs = {"input_ids": input_ids.contiguous()} # `contiguous()` needed for compilation use cases
+
+ model_inputs.update(
+ {
+ "position_ids": position_ids,
+ "past_key_values": past_key_values,
+ "use_cache": use_cache,
+ "attention_mask": attention_mask,
+ "logits_to_keep": self.config.num_logits_to_keep,
+ "cache_position": cache_position,
+ }
+ )
+ return model_inputs
+
+
+@auto_docstring(
+ custom_intro="""
+ The Zamba Model with a sequence classification head on top (linear layer).
+
+ [`ZambaForSequenceClassification`] uses the last token in order to do the classification, as other causal models
+ (e.g. GPT-2) do.
+
+ Since it does classification on the last token, it requires to know the position of the last token. If a
+ `pad_token_id` is defined in the configuration, it finds the last token that is not a padding token in each row. If
+ no `pad_token_id` is defined, it simply takes the last value in each row of the batch. Since it cannot guess the
+ padding tokens when `inputs_embeds` are passed instead of `input_ids`, it does the same (take the last value in
+ each row of the batch).
+ """
+)
+class ZambaForSequenceClassification(ZambaPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.model = ZambaModel(config)
+ self._tied_weights_keys = self.model._tied_weights_keys
+ self.score = nn.Linear(config.hidden_size, self.num_labels, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, list[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SequenceClassifierOutputWithPast]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ hidden_states = transformer_outputs[0]
+ logits = self.score(hidden_states)
+
+ if input_ids is not None:
+ batch_size = input_ids.shape[0]
+ else:
+ batch_size = inputs_embeds.shape[0]
+
+ if self.config.pad_token_id is None and batch_size != 1:
+ raise ValueError("Cannot handle batch sizes > 1 if no padding token is defined.")
+ if self.config.pad_token_id is None:
+ last_non_pad_token = -1
+ elif input_ids is not None:
+ # To handle both left- and right- padding, we take the rightmost token that is not equal to pad_token_id
+ non_pad_mask = (input_ids != self.config.pad_token_id).to(logits.device, torch.int32)
+ token_indices = torch.arange(input_ids.shape[-1], device=logits.device, dtype=torch.int32)
+ last_non_pad_token = (token_indices * non_pad_mask).argmax(-1)
+ else:
+ last_non_pad_token = -1
+ logger.warning_once(
+ f"{self.__class__.__name__} will not detect padding tokens in `inputs_embeds`. Results may be "
+ "unexpected if using padding tokens in conjunction with `inputs_embeds.`"
+ )
+
+ pooled_logits = logits[torch.arange(batch_size, device=logits.device), last_non_pad_token]
+
+ loss = None
+ if labels is not None:
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(pooled_logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(pooled_logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(pooled_logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(pooled_logits, labels)
+ if not return_dict:
+ output = (pooled_logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutputWithPast(
+ loss=loss,
+ logits=pooled_logits,
+ past_key_values=transformer_outputs.past_key_values,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+__all__ = ["ZambaForCausalLM", "ZambaForSequenceClassification", "ZambaModel", "ZambaPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..00db458c72ebd5513d8e8cf1b186f49886745a2a
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/__init__.py
@@ -0,0 +1,27 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_zamba2 import *
+ from .modeling_zamba2 import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/configuration_zamba2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/configuration_zamba2.py
new file mode 100644
index 0000000000000000000000000000000000000000..2789e508f6fa7e4c79de9abefd0da150ec1aeb2e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/configuration_zamba2.py
@@ -0,0 +1,241 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/zamba2/modular_zamba2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_zamba2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2024 Zyphra Technologies and the HuggingFace Inc. team. All rights reserved.
+#
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from ...configuration_utils import PretrainedConfig
+
+
+class Zamba2Config(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`Zamba2Model`]. It is used to instantiate a
+ Zamba2 model according to the specified arguments, defining the model architecture. Instantiating a configuration
+ with the defaults will yield a similar configuration to that of the Zamba2 model.
+
+ [Zyphra/Zamba2-2.7B](https://huggingface.co/Zyphra/Zamba2-2.7B)
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+ Args:
+ vocab_size (`int`, *optional*, defaults to 32000):
+ Vocabulary size of the Zamba2 model. Defines the number of different tokens that can be represented by the
+ `inputs_ids` passed when calling [`Zamba2Model`]
+ max_position_embeddings (`int`, *optional*, defaults to 4096):
+ The maximum sequence length that this model might ever be used with.
+ hidden_size (`int`, *optional*, defaults to 2560):
+ Dimension of the hidden representations.
+ num_hidden_layers (`int`, *optional*, defaults to 54):
+ Number of hidden layers in the model.
+ layers_block_type (`list`, *optional*):
+ List of layer types, which can be either "mamba" or "hybrid".
+ mamba_d_state (`int`, *optional*, defaults to 64): shape of the state space latents.
+ mamba_d_conv (`int`, *optional*, defaults to 4): Size of the convolution kernel.
+ mamba_expand (`int`, *optional*, defaults to 2): Expanding factor used to determine the intermediate size.
+ mamba_ngroups (`int`, *optional*, defaults to 1):
+ Number of groups for the evolution matrices of mamba 2.
+ time_step_min (`float`, *optional*, defaults to 0.001):
+ Minimum `time_step` used to bound `dt_proj.bias`.
+ time_step_max (`float`, *optional*, defaults to 0.1):
+ Maximum `time_step` used to bound `dt_proj.bias`.
+ time_step_floor (`float`, *optional*, defaults to 0.0001):
+ Minimum clamping value of the `dt_proj.bias` layer initialization.
+ time_step_limit (`tuple`, *optional*):
+ Accepted range of time step values.
+ n_mamba_heads (`int`, *optional*, defaults to 8):
+ Number of heads for the evolution matrices of mamba 2.
+ use_conv_bias (`bool`, *optional*, defaults to `True`):
+ Whether or not to use bias in the convolution layer of the mixer block.
+ chunk_size (`int`, *optional*, defaults to 256):
+ Size of the chunks that will comprise the sequence.
+ use_mem_eff_path (`bool`, *optional*, defaults to `False`):
+ Whether or not to use the fused conv1d and scan in mamba2 layers.
+ add_bias_linear (`bool`, *optional*, defaults to `False`):
+ Flag indicating whether or not to use bias in various layers
+ intermediate_size (`int`, *optional*, defaults to 4 * hidden_size):
+ Dimension of the MLP representations.
+ hidden_act (`str`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the MLP.
+ num_attention_heads (`int`, *optional*, defaults to 32):
+ Number of attention heads for each attention layer in the Transformer decoder.
+ num_key_value_heads (`int`, *optional*):
+ This is the number of key_value heads that should be used to implement Grouped Query Attention. If
+ `num_key_value_heads=None`, the model will use Multi Head Attention (MHA), if
+ `num_key_value_heads=1 the model will use Multi Query Attention (MQA) otherwise GQA is used. When
+ converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
+ by meanpooling all the original heads within that group. For more details, check out [this
+ paper](https://huggingface.co/papers/2305.13245).
+ attention_dropout (`float`, *optional*, defaults to 0.0):
+ The dropout ratio for the attention probabilities.
+ num_mem_blocks (`int`, *optional*, defaults to 1):
+ Number of unshared transformer blocks.
+ use_shared_attention_adapter (`bool`, *optional*, defaults to `False`):
+ If True, unshared adapters (formally the same as LoRA but used in the base model) will be added to the q, k, v projectors in the shared attention layers.
+ adapter_rank (`int`, *optional*, defaults to 128):
+ Rank of the adapter in the shared MLP and shared attention layers.
+ use_mem_rope (`bool`, *optional*, defaults to `False`):
+ If True, includes RoPE in the shared attention layers.
+ rope_theta (`float`, *optional*, defaults to `10000.0`):
+ The base period of the RoPE embeddings.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ rms_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the rms normalization layers.
+ use_cache (`bool`, *optional*, defaults to `True`):
+ Whether or not the model should return the last key/values attentions (not used by all models). Only
+ relevant if `config.is_decoder=True`.
+ num_logits_to_keep (`int` or `None`, *optional*, defaults to 1):
+ Number of prompt logits to calculate during generation. If `None`, all logits will be calculated. If an
+ integer value, only last `num_logits_to_keep` logits will be calculated. Default is 1 because only the
+ logits of the last prompt token are needed for generation. For long sequences, the logits for the entire
+ sequence may use a lot of memory so, setting `num_logits_to_keep=1` will reduce memory footprint
+ significantly.
+ pad_token_id (`int`, *optional*, defaults to 0):
+ The id of the padding token.
+ bos_token_id (`int`, *optional*, defaults to 1):
+ The id of the "beginning-of-sequence" token.
+ eos_token_id (`int`, *optional*, defaults to 2):
+ The id of the "end-of-sequence" token.
+ use_long_context (`bool`, *optional*, defaults to `False`):
+ Activates the context-extended version of Zamba by modifying RoPE.
+ ```python
+ >>> from transformers import Zamba2Model, Zamba2Config
+ >>> # Initializing a Zamba2-2.7B style configuration
+ >>> configuration = Zamba2Config()
+ >>> # Initializing a model from the Zamba2-2.7B style configuration
+ >>> model = Zamba2Model(configuration)
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "zamba2"
+ attribute_map = {"head_dim": "attention_head_dim"}
+ keys_to_ignore_at_inference = ["past_key_values"]
+
+ def __init__(
+ self,
+ vocab_size=32000,
+ max_position_embeddings=4096,
+ hidden_size=2560,
+ num_hidden_layers=54,
+ layers_block_type=None,
+ mamba_d_state=64,
+ mamba_d_conv=4,
+ mamba_expand=2,
+ mamba_ngroups=1,
+ time_step_min=0.001,
+ time_step_max=0.1,
+ time_step_floor=1e-4,
+ time_step_limit=None,
+ n_mamba_heads=8,
+ use_conv_bias=True,
+ chunk_size=256,
+ use_mem_eff_path=False,
+ add_bias_linear=False,
+ intermediate_size=None,
+ hidden_act="gelu",
+ num_attention_heads=32,
+ num_key_value_heads=None,
+ attention_dropout=0.0,
+ num_mem_blocks=1,
+ use_shared_attention_adapter=False,
+ adapter_rank=128,
+ use_mem_rope=False,
+ rope_theta=10000,
+ initializer_range=0.02,
+ rms_norm_eps=1e-5,
+ use_cache=True,
+ num_logits_to_keep=1,
+ pad_token_id=0,
+ bos_token_id=1,
+ eos_token_id=2,
+ use_long_context=False,
+ **kwargs,
+ ):
+ super().__init__(
+ pad_token_id=pad_token_id,
+ bos_token_id=bos_token_id,
+ eos_token_id=eos_token_id,
+ **kwargs,
+ )
+ self.vocab_size = vocab_size
+ self.max_position_embeddings = max_position_embeddings
+ self.hidden_size = hidden_size
+ if intermediate_size is None:
+ self.intermediate_size = 4 * hidden_size
+ else:
+ self.intermediate_size = intermediate_size
+ self.hidden_act = hidden_act
+ self.num_hidden_layers = num_hidden_layers
+ self.num_attention_heads = num_attention_heads
+ self.num_mem_blocks = num_mem_blocks
+ self.attention_hidden_size = 2 * hidden_size
+ self.attention_head_dim = 2 * self.hidden_size // self.num_attention_heads
+ self.attention_dropout = attention_dropout
+ self.use_mem_rope = use_mem_rope
+ self.use_long_context = use_long_context
+ if use_mem_rope and use_long_context:
+ a = 8
+ rope_theta = rope_theta * a ** (self.attention_head_dim / (self.attention_head_dim - 2))
+ self.rope_theta = rope_theta
+ self.mamba_d_state = mamba_d_state
+ self.mamba_d_conv = mamba_d_conv
+ self.mamba_expand = mamba_expand
+ self.add_bias_linear = add_bias_linear
+ self.mamba_ngroups = mamba_ngroups
+ self.n_mamba_heads = n_mamba_heads
+ self.mamba_headdim = int(mamba_expand * hidden_size) // n_mamba_heads
+ self.use_conv_bias = use_conv_bias
+ self.chunk_size = chunk_size
+ self.time_step_limit = time_step_limit
+ self.use_shared_attention_adapter = use_shared_attention_adapter
+ self.adapter_rank = adapter_rank
+ self.time_step_min = time_step_min
+ self.time_step_max = time_step_max
+ self.time_step_floor = time_step_floor
+ if use_long_context:
+ self.max_position_embeddings = 16384
+ if num_key_value_heads is None:
+ num_key_value_heads = num_attention_heads
+ self.num_key_value_heads = num_key_value_heads
+ self.num_attention_heads = num_attention_heads
+ self.kv_channels = self.hidden_size // self.num_attention_heads
+ self.num_query_groups = self.num_attention_heads
+ # Below, "mamba" stands for mamba layer, "hybrid" stands for hybrid layer (composed by a shared transformer followed by mamba layer)
+ if layers_block_type is None:
+ self.layers_block_type = (
+ ["mamba"]
+ + (["mamba"] * 5 + ["hybrid"]) * 7
+ + ["mamba"] * 4
+ + ["hybrid"]
+ + ["mamba"] * 3
+ + ["hybrid"]
+ + ["mamba"] * 2
+ )
+ else:
+ self.layers_block_type = layers_block_type
+ self.initializer_range = initializer_range
+ self.rms_norm_eps = rms_norm_eps
+ self.use_cache = use_cache
+ self.num_logits_to_keep = num_logits_to_keep
+ self.hybrid_layer_ids = [index for index, type in enumerate(self.layers_block_type) if type == "hybrid"]
+ self.use_mem_eff_path = use_mem_eff_path
+
+
+__all__ = ["Zamba2Config"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/modeling_zamba2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/modeling_zamba2.py
new file mode 100644
index 0000000000000000000000000000000000000000..6881f1278e6e71e6b15dd469486e5131397ba71e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/modeling_zamba2.py
@@ -0,0 +1,1734 @@
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# This file was automatically generated from src/transformers/models/zamba2/modular_zamba2.py.
+# Do NOT edit this file manually as any edits will be overwritten by the generation of
+# the file from the modular. If any change should be done, please apply the change to the
+# modular_zamba2.py file directly. One of our CI enforces this.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# coding=utf-8
+# Copyright 2024 Zyphra Technologies and the HuggingFace Inc. team. All rights reserved.
+#
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import math
+import re
+from itertools import cycle
+from typing import Any, Callable, Optional, Union
+
+import torch
+from torch import nn
+from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss
+
+from ...activations import ACT2FN
+from ...cache_utils import Cache
+from ...generation import GenerationMixin
+from ...modeling_attn_mask_utils import AttentionMaskConverter
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast, SequenceClassifierOutputWithPast
+from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import auto_docstring, logging
+from ...utils.deprecation import deprecate_kwarg
+from ...utils.import_utils import is_causal_conv1d_available, is_mamba_ssm_available
+from .configuration_zamba2 import Zamba2Config
+
+
+if is_mamba_ssm_available():
+ from mamba_ssm.ops.triton.selective_state_update import selective_state_update
+ from mamba_ssm.ops.triton.ssd_combined import mamba_chunk_scan_combined, mamba_split_conv1d_scan_combined
+else:
+ selective_state_update, mamba_chunk_scan_combined, mamba_split_conv1d_scan_combined = None, None, None
+
+if is_causal_conv1d_available():
+ from causal_conv1d import causal_conv1d_fn, causal_conv1d_update
+else:
+ causal_conv1d_update, causal_conv1d_fn = None, None
+
+logger = logging.get_logger(__name__)
+
+
+class Zamba2RMSNormGated(torch.nn.Module):
+ def __init__(self, hidden_size, group_size, eps=1e-6):
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+ self.group_size = group_size
+
+ def forward(self, hidden_states, gate=None):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ if gate is not None:
+ hidden_states = hidden_states * nn.functional.silu(gate.to(torch.float32))
+ *prefix_dims, last_dim = hidden_states.shape
+ group_count = last_dim // self.group_size
+ hidden_states_group = hidden_states.view(*prefix_dims, group_count, self.group_size)
+ variance = hidden_states_group.pow(2).mean(-1, keepdim=True)
+ hidden_states_group = hidden_states_group * torch.rsqrt(variance + self.variance_epsilon)
+ hidden_states = hidden_states_group.view(*prefix_dims, group_count * self.group_size)
+ return self.weight * hidden_states.to(input_dtype)
+
+
+class Zamba2RMSNorm(nn.Module):
+ def __init__(self, hidden_size, eps=1e-6):
+ """
+ Zamba2RMSNorm is equivalent to T5LayerNorm
+ """
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+
+ def forward(self, hidden_states):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ variance = hidden_states.pow(2).mean(-1, keepdim=True)
+ hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon)
+ return self.weight * hidden_states.to(input_dtype)
+
+ def extra_repr(self):
+ return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}"
+
+
+class Zamba2HybridDynamicCache:
+ """
+ A dynamic cache that can handle both the attention cache (which has a seq_len dimension) and the mamba cache
+ (which has a constant shape regardless of seq_len).
+
+ This cache has two sets of lists of tensors: `key_cache` and `value_cache` for attention cache and `conv_states`
+ and `ssm_states` for mamba cache. Each of these lists has `num_layers` tensors. The expected shape for each tensor
+ For attention layers, `key_cache` and `value_cache` have a shape of `(batch_size, num_heads, seq_len, head_dim)`,
+ while `conv_states` and `ssm_states` have a shape of `(batch_size, 0)` (empty tensors).
+ For mamba layers, `key_cache` and `value_cache` have a shape of `(batch_size, 0)` (empty tensors),
+ while `conv_states` represents the convolution state and has a shape of `(batch_size, d_inner, d_conv)`,
+ and `ssm_states` represents the ssm state and has a shape of `(batch_size, d_inner, d_state)`.
+ """
+
+ is_compileable = False
+
+ def __init__(
+ self, config: Zamba2Config, batch_size: int, dtype: torch.dtype = torch.float16, device: Optional[str] = None
+ ):
+ self.dtype = dtype
+ self.layers_block_type = config.layers_block_type
+ self.has_previous_state = False
+ self.intermediate_size = int(config.mamba_expand * config.hidden_size)
+ self.ssm_state_size = config.mamba_d_state
+ self.conv_kernel_size = config.mamba_d_conv
+ self.n_mamba_heads = config.n_mamba_heads
+ self.transformer_layers = []
+ self._modules = {}
+ self._parameters = {}
+ self._buffers = {}
+ self.conv_states = {}
+ self.ssm_states = {}
+ for i in range(config.num_hidden_layers):
+ self.conv_states[i] = torch.zeros(
+ batch_size,
+ self.intermediate_size + 2 * config.mamba_ngroups * config.mamba_d_state,
+ self.conv_kernel_size,
+ device=device,
+ dtype=dtype,
+ )
+ self.ssm_states[i] = torch.zeros(
+ batch_size, self.n_mamba_heads, config.mamba_headdim, self.ssm_state_size, device=device, dtype=dtype
+ )
+ if self.layers_block_type[i] == "hybrid":
+ self.transformer_layers.append(i)
+ self.key_cache = [torch.tensor([[]] * batch_size, device=device) for _ in range(config.num_hidden_layers)]
+ self.value_cache = [torch.tensor([[]] * batch_size, device=device) for _ in range(config.num_hidden_layers)]
+
+ def __len__(self):
+ return len(self.key_cache)
+
+ def __getitem__(self, layer_idx: int) -> tuple[torch.Tensor, torch.Tensor]:
+ return self.key_cache[layer_idx], self.value_cache[layer_idx]
+
+ def update(
+ self,
+ key_states: torch.Tensor,
+ value_states: torch.Tensor,
+ layer_idx: int,
+ cache_kwargs: Optional[dict[str, Any]] = None,
+ ) -> tuple[torch.Tensor, torch.Tensor]:
+ # Update the cache
+ if self.key_cache[layer_idx].shape[-1] == 0:
+ self.key_cache[layer_idx] = key_states
+ self.value_cache[layer_idx] = value_states
+ else:
+ self.key_cache[layer_idx] = torch.cat([self.key_cache[layer_idx], key_states], dim=2)
+ self.value_cache[layer_idx] = torch.cat([self.value_cache[layer_idx], value_states], dim=2)
+
+ return self.key_cache[layer_idx], self.value_cache[layer_idx]
+
+ def reorder_cache(self, beam_idx: torch.LongTensor):
+ """Reorders the cache for beam search, given the selected beam indices."""
+ for layer_idx in range(len(self.key_cache)):
+ device = self.key_cache[layer_idx].device
+ self.key_cache[layer_idx] = self.key_cache[layer_idx].index_select(0, beam_idx.to(device))
+ device = self.value_cache[layer_idx].device
+ self.value_cache[layer_idx] = self.value_cache[layer_idx].index_select(0, beam_idx.to(device))
+
+ device = self.conv_states[layer_idx].device
+ self.conv_states[layer_idx] = self.conv_states[layer_idx].index_select(0, beam_idx.to(device))
+ device = self.ssm_states[layer_idx].device
+ self.ssm_states[layer_idx] = self.ssm_states[layer_idx].index_select(0, beam_idx.to(device))
+
+ def get_seq_length(self, layer_idx: Optional[int] = 0) -> int:
+ """Returns the sequence length of the cached states. A layer index can be optionally passed."""
+ # take any layer that contains cache and not empty tensor
+ layer_idx = self.transformer_layers[0] if layer_idx not in self.transformer_layers else layer_idx
+ if len(self.key_cache) <= layer_idx or self.key_cache[layer_idx].numel() == 0:
+ return 0
+ return self.key_cache[layer_idx].shape[-2]
+
+ def update_conv_state(
+ self, layer_idx: int, new_conv_state: torch.Tensor, cache_position: torch.LongTensor
+ ) -> torch.Tensor:
+ conv_state = self.conv_states[layer_idx]
+ cache_position = cache_position.clamp(0, self.conv_kernel_size - 1)
+
+ conv_state = conv_state.roll(shifts=-1, dims=-1)
+ conv_state[:, :, cache_position] = new_conv_state.to(conv_state.device)
+ self.conv_states[layer_idx].zero_()
+ self.conv_states[layer_idx] += conv_state
+ return self.conv_states[layer_idx]
+
+ def reset(self):
+ self.conv_states.zero_()
+ self.ssm_states.zero_()
+
+
+class Zamba2RotaryEmbedding(nn.Module):
+ inv_freq: torch.Tensor # fix linting for `register_buffer`
+
+ def __init__(self, config: Zamba2Config, device=None):
+ super().__init__()
+ # BC: "rope_type" was originally "type"
+ if hasattr(config, "rope_scaling") and isinstance(config.rope_scaling, dict):
+ self.rope_type = config.rope_scaling.get("rope_type", config.rope_scaling.get("type"))
+ else:
+ self.rope_type = "default"
+ self.max_seq_len_cached = config.max_position_embeddings
+ self.original_max_seq_len = config.max_position_embeddings
+
+ self.config = config
+ self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type]
+
+ inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device)
+ self.register_buffer("inv_freq", inv_freq, persistent=False)
+ self.original_inv_freq = self.inv_freq
+
+ @torch.no_grad()
+ @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope)
+ def forward(self, x, position_ids):
+ inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device)
+ position_ids_expanded = position_ids[:, None, :].float()
+
+ device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu"
+ with torch.autocast(device_type=device_type, enabled=False): # Force float32
+ freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)
+ emb = torch.cat((freqs, freqs), dim=-1)
+ cos = emb.cos() * self.attention_scaling
+ sin = emb.sin() * self.attention_scaling
+
+ return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype)
+
+
+def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor:
+ """
+ This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch,
+ num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim)
+ """
+ batch, num_key_value_heads, slen, head_dim = hidden_states.shape
+ if n_rep == 1:
+ return hidden_states
+ hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim)
+ return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim)
+
+
+def eager_attention_forward(
+ module: nn.Module,
+ query: torch.Tensor,
+ key: torch.Tensor,
+ value: torch.Tensor,
+ attention_mask: Optional[torch.Tensor],
+ scaling: float,
+ dropout: float = 0.0,
+ **kwargs,
+):
+ key_states = repeat_kv(key, module.num_key_value_groups)
+ value_states = repeat_kv(value, module.num_key_value_groups)
+
+ attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling
+ if attention_mask is not None:
+ causal_mask = attention_mask[:, :, :, : key_states.shape[-2]]
+ attn_weights = attn_weights + causal_mask
+
+ attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype)
+ attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training)
+ attn_output = torch.matmul(attn_weights, value_states)
+ attn_output = attn_output.transpose(1, 2).contiguous()
+
+ return attn_output, attn_weights
+
+
+def rotate_half(x):
+ """Rotates half the hidden dims of the input."""
+ x1 = x[..., : x.shape[-1] // 2]
+ x2 = x[..., x.shape[-1] // 2 :]
+ return torch.cat((-x2, x1), dim=-1)
+
+
+def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
+ """Applies Rotary Position Embedding to the query and key tensors.
+
+ Args:
+ q (`torch.Tensor`): The query tensor.
+ k (`torch.Tensor`): The key tensor.
+ cos (`torch.Tensor`): The cosine part of the rotary embedding.
+ sin (`torch.Tensor`): The sine part of the rotary embedding.
+ position_ids (`torch.Tensor`, *optional*):
+ Deprecated and unused.
+ unsqueeze_dim (`int`, *optional*, defaults to 1):
+ The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and
+ sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note
+ that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and
+ k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes
+ cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have
+ the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2.
+ Returns:
+ `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding.
+ """
+ cos = cos.unsqueeze(unsqueeze_dim)
+ sin = sin.unsqueeze(unsqueeze_dim)
+ q_embed = (q * cos) + (rotate_half(q) * sin)
+ k_embed = (k * cos) + (rotate_half(k) * sin)
+ return q_embed, k_embed
+
+
+class Zamba2Attention(nn.Module):
+ """
+ Multi-headed attention from 'Attention Is All You Need' paper.
+
+ Adapted from transformers.models.mistral.modeling_mistral.MistralAttention:
+ The input dimension here is attention_hidden_size = 2 * hidden_size, and head_dim = attention_hidden_size // num_heads.
+ The extra factor of 2 comes from the input being the concatenation of original_hidden_states with the output of the previous (mamba) layer
+ (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ Additionally, replaced
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim) with
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim/2)
+ Finally, this attention layer contributes to tied transformer blocks aimed to increasing compute without increasing model size. Because this
+ layer is tied, un-tied adapters (formally the same as LoRA but used in the base model) modules are added to the q, k, v projectors to increase
+ expressivity with a small memory overhead (see Fig. 2 of https://huggingface.co/papers/2411.15242).
+ """
+
+ def __init__(
+ self,
+ config: Zamba2Config,
+ layer_idx: Optional[int] = None,
+ num_fwd_mem_blocks: Optional[int] = None,
+ block_id: Optional[int] = None,
+ ):
+ super().__init__()
+ self.config = config
+ self.layer_idx = layer_idx
+
+ self.attention_hidden_size = config.attention_hidden_size
+ self.head_dim = config.attention_head_dim
+ self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads
+ self.max_position_embeddings = config.max_position_embeddings
+ self.scaling = (self.head_dim / 2) ** -0.5
+ self.is_causal = True
+ self.attention_dropout = config.attention_dropout
+
+ self.q_proj = nn.Linear(config.attention_hidden_size, config.num_attention_heads * self.head_dim, bias=False)
+ self.k_proj = nn.Linear(config.attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=False)
+ self.v_proj = nn.Linear(config.attention_hidden_size, config.num_key_value_heads * self.head_dim, bias=False)
+ self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=False)
+ self.num_fwd_mem_blocks = num_fwd_mem_blocks
+ self.layer_block_map = config.hybrid_layer_ids
+ self.block_id = block_id
+
+ if config.use_shared_attention_adapter:
+ self.linear_q_adapter_list = nn.ModuleList([])
+ self.linear_k_adapter_list = nn.ModuleList([])
+ self.linear_v_adapter_list = nn.ModuleList([])
+
+ for i in range(self.num_fwd_mem_blocks):
+ if i % config.num_mem_blocks == block_id:
+ linear_q_adapter = nn.Sequential(
+ nn.Linear(self.attention_hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, self.attention_hidden_size, bias=False),
+ )
+ linear_k_adapter = nn.Sequential(
+ nn.Linear(self.attention_hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, self.attention_hidden_size, bias=False),
+ )
+ linear_v_adapter = nn.Sequential(
+ nn.Linear(self.attention_hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, self.attention_hidden_size, bias=False),
+ )
+ else:
+ linear_q_adapter = nn.Identity()
+ linear_k_adapter = nn.Identity()
+ linear_v_adapter = nn.Identity()
+ self.linear_q_adapter_list.append(linear_q_adapter)
+ self.linear_k_adapter_list.append(linear_k_adapter)
+ self.linear_v_adapter_list.append(linear_v_adapter)
+
+ self.layer_dic = {value: index for index, value in enumerate(self.layer_block_map)}
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ layer_idx: int,
+ attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+ if self.config.use_shared_attention_adapter:
+ adapter_layer_idx = self.layer_dic[layer_idx]
+ query_states = query_states + self.linear_q_adapter_list[adapter_layer_idx](hidden_states)
+ key_states = key_states + self.linear_k_adapter_list[adapter_layer_idx](hidden_states)
+ value_states = value_states + self.linear_v_adapter_list[adapter_layer_idx](hidden_states)
+
+ query_states = query_states.view(hidden_shape).transpose(1, 2)
+ key_states = key_states.view(hidden_shape).transpose(1, 2)
+ value_states = value_states.view(hidden_shape).transpose(1, 2)
+
+ if self.config.use_mem_rope:
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ key_states, value_states = past_key_values.update(key_states, value_states, layer_idx)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+# Helper methods for segment sum computation
+
+
+def pad_tensor_by_size(input_tensor: torch.Tensor, pad_size: int):
+ """
+ Padding x tensor with `pad_size` on the seq_len dim (dim=1)
+
+ Assumes that we only have tensors of either size 4 or 3
+ """
+ pad_shape = (0, 0, 0, 0, 0, pad_size, 0, 0) if len(input_tensor.shape) == 4 else (0, 0, 0, pad_size, 0, 0)
+
+ return torch.nn.functional.pad(input_tensor, pad_shape, mode="constant", value=0)
+
+
+def reshape_into_chunks(input_tensor, pad_size, chunk_size):
+ """
+ Padding input_tensor with `pad_size` on the seq_len dim (dim=1) and
+ simultaneously splitting it into chunk sequences.
+
+ Assumes that we only have tensors of either size 4 or 3
+ """
+ # [bsz, seq_len, ...] -> [bsz, seq_len multiple of chunk_size, ...]
+ input_tensor = pad_tensor_by_size(input_tensor, pad_size)
+
+ if len(input_tensor.shape) == 3:
+ # [bsz, seq_len multiple of chunk_size, num_heads] -> [bsz, -1, chunk_size, num_heads]
+ return input_tensor.reshape(input_tensor.shape[0], -1, chunk_size, input_tensor.shape[2])
+ else:
+ # [bsz, seq_len multiple of chunk_size, num_heads, head_dim or state_size] -> [bsz, -1, chunk_size, num_heads, head_dim or state_size]
+ return input_tensor.reshape(
+ input_tensor.shape[0], -1, chunk_size, input_tensor.shape[2], input_tensor.shape[3]
+ )
+
+
+def segment_sum(input_tensor):
+ """
+ More stable segment sum calculation. Uses cumulative sums and masking instead of direct subtractions.
+ """
+ chunk_size = input_tensor.size(-1)
+ # 1. expand input tensor to have an additional dimension and repeat along that dimension
+ # [..., chunk_size] -> [..., chunk_size, chunk_size]
+ input_tensor = input_tensor[..., None].expand(*input_tensor.size(), chunk_size)
+ # 2. create a lower triangular mask with the diagonal set to 0 to 0 out elements above diag
+ mask = torch.tril(torch.ones(chunk_size, chunk_size, device=input_tensor.device, dtype=torch.bool), diagonal=-1)
+ input_tensor = input_tensor.masked_fill(~mask, 0)
+ # 3. compute actual cumsum
+ tensor_segsum = torch.cumsum(input_tensor, dim=-2)
+
+ # 4. apply mask to keep only the lower triangular part of the cumulative sum result (incl diagonal this time)
+ mask = torch.tril(torch.ones(chunk_size, chunk_size, device=input_tensor.device, dtype=torch.bool), diagonal=0)
+ tensor_segsum = tensor_segsum.masked_fill(~mask, -torch.inf)
+ return tensor_segsum
+
+
+is_fast_path_available = all((selective_state_update, causal_conv1d_fn, causal_conv1d_update))
+
+
+class Zamba2MambaMixer(nn.Module):
+ """
+ Compute ∆, A, B, C, and D the state space parameters and compute the `contextualized_states`.
+ A, D are input independent (see Mamba paper [1] Section 3.5.2 "Interpretation of A" for why A isn't selective)
+ ∆, B, C are input-dependent (this is a key difference between Mamba and the linear time invariant S4,
+ and is why Mamba is called **selective** state spaces)
+ """
+
+ def __init__(self, config: Zamba2Config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.ssm_state_size = config.mamba_d_state
+ self.conv_kernel_size = config.mamba_d_conv
+ self.intermediate_size = int(config.mamba_expand * self.hidden_size)
+ self.layer_idx = layer_idx
+ self.use_conv_bias = config.use_conv_bias
+ self.activation = "silu"
+ self.act = nn.SiLU()
+ self.use_mem_eff_path = config.use_mem_eff_path
+
+ self.n_groups = config.mamba_ngroups
+ self.head_dim = config.mamba_headdim
+ self.num_heads = self.config.n_mamba_heads
+ self.chunk_size = config.chunk_size
+
+ self.time_step_limit = config.time_step_limit
+ self.time_step_min = config.time_step_min
+ self.time_step_max = config.time_step_max
+
+ self.conv_dim = self.intermediate_size + 2 * self.n_groups * self.ssm_state_size
+ self.conv1d = nn.Conv1d(
+ in_channels=self.conv_dim,
+ out_channels=self.conv_dim,
+ bias=True,
+ kernel_size=config.mamba_d_conv,
+ groups=self.conv_dim,
+ padding=config.mamba_d_conv - 1,
+ )
+
+ # projection of the input hidden states
+ projection_size = self.intermediate_size + self.conv_dim + self.num_heads
+ self.in_proj = nn.Linear(
+ self.hidden_size,
+ projection_size,
+ bias=config.add_bias_linear,
+ )
+ # selective projection used to make dt, B and C input dependent
+
+ # time step projection (discretization)
+ # instantiate once and copy inv_dt in init_weights of PretrainedModel
+ self.dt_bias = nn.Parameter(torch.ones(self.num_heads))
+
+ # S4D real initialization. These are not discretized!
+ # The core is to load them, compute the discrete states, then write the updated state. Keeps the memory bounded
+ A = torch.arange(1, self.num_heads + 1)
+ self.A_log = nn.Parameter(torch.log(A))
+ self.A_log._no_weight_decay = True
+ self.norm = Zamba2RMSNormGated(
+ self.intermediate_size, group_size=self.intermediate_size // self.n_groups, eps=1e-5
+ )
+ self.D = nn.Parameter(torch.ones(self.num_heads))
+ self.D._no_weight_decay = True
+
+ self.out_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.add_bias_linear)
+
+ if not is_fast_path_available:
+ logger.warning_once(
+ "The fast path is not available because on of `(selective_state_update, causal_conv1d_fn, causal_conv1d_update)`"
+ " is None. Falling back to the naive implementation. To install follow https://github.com/state-spaces/mamba/#installation and"
+ " https://github.com/Dao-AILab/causal-conv1d"
+ )
+
+ def cuda_kernels_forward(
+ self,
+ hidden_states: torch.Tensor,
+ cache_params: Optional[Zamba2HybridDynamicCache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ ):
+ # set up dimensions for reshapes later
+
+ batch_size, seq_len, _ = hidden_states.shape
+ groups_time_state_size = self.n_groups * self.ssm_state_size
+ d_to_remove = 2 * self.intermediate_size + 2 * self.n_groups * self.ssm_state_size + self.num_heads
+
+ # getting projected states from cache if it exists
+ if cache_params is not None and cache_params.has_previous_state:
+ in_projected_states = self.in_proj(hidden_states.squeeze(1)) # (B 2D)
+ d_mlp = (in_projected_states.shape[-1] - d_to_remove) // 2
+ split_projection_dim = [d_mlp, d_mlp, self.intermediate_size, self.conv_dim, self.num_heads]
+ _, _, gate, hidden_states_B_C, dt = torch.split(in_projected_states, split_projection_dim, dim=-1)
+
+ hidden_states_B_C = causal_conv1d_update(
+ hidden_states_B_C,
+ cache_params.conv_states[self.layer_idx],
+ self.conv1d.weight.squeeze(1),
+ self.conv1d.bias,
+ self.activation,
+ )
+
+ hidden_states, B, C = torch.split(
+ hidden_states_B_C,
+ [self.intermediate_size, groups_time_state_size, groups_time_state_size],
+ dim=-1,
+ )
+ A = -torch.exp(self.A_log.float()) # (nheads,)
+
+ A = A[:, None, ...][:, :, None].expand(-1, self.head_dim, self.ssm_state_size).to(dtype=torch.float32)
+ dt = dt[:, :, None].expand(-1, -1, self.head_dim)
+ dt_bias = self.dt_bias[:, None, ...].expand(-1, self.head_dim)
+ D = self.D[:, None, ...].expand(-1, self.head_dim)
+ B = B.view(batch_size, self.n_groups, B.shape[1] // self.n_groups)
+ C = C.view(batch_size, self.n_groups, C.shape[1] // self.n_groups)
+ hidden_states_reshaped = hidden_states.view(batch_size, self.num_heads, self.head_dim)
+ hidden_states = selective_state_update(
+ cache_params.ssm_states[self.layer_idx],
+ hidden_states_reshaped,
+ dt,
+ A,
+ B,
+ C,
+ D,
+ z=None,
+ dt_bias=dt_bias,
+ dt_softplus=True,
+ )
+ hidden_states = hidden_states.view(batch_size, self.num_heads * self.head_dim)
+ hidden_states = self.norm(hidden_states, gate)
+ out = self.out_proj(hidden_states)[:, None, ...]
+ # if no cache is found, calling the kernel
+ else:
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ dtype = hidden_states.dtype
+ hidden_states = (hidden_states * attention_mask[:, :, None]).to(dtype)
+ # 1. Gated MLP's linear projection
+ projected_states = self.in_proj(hidden_states)
+ A = -torch.exp(self.A_log.float()) # (num_heads) or (intermediate_size, state_size)
+ dt_limit_kwargs = {} if self.time_step_limit is None else {"dt_limit": self.time_step_limit}
+ if attention_mask is not None:
+ input_not_masked = torch.all(attention_mask == 1)
+ else:
+ input_not_masked = True
+
+ if self.use_mem_eff_path and self.training and cache_params is None and input_not_masked:
+ out, ssm_state = mamba_split_conv1d_scan_combined(
+ projected_states,
+ self.conv1d.weight.squeeze(1),
+ self.conv1d.bias,
+ self.dt_bias,
+ A,
+ D=self.D,
+ chunk_size=self.chunk_size,
+ seq_idx=None,
+ activation=self.activation,
+ rmsnorm_weight=self.norm.weight,
+ rmsnorm_eps=self.norm.variance_epsilon,
+ outproj_weight=self.out_proj.weight,
+ outproj_bias=self.out_proj.bias,
+ headdim=self.head_dim,
+ ngroups=self.n_groups,
+ norm_before_gate=False,
+ return_final_states=True,
+ **dt_limit_kwargs,
+ )
+
+ else:
+ gate, hidden_states_B_C, time_step = torch.split(
+ projected_states,
+ [self.intermediate_size, self.conv_dim, self.num_heads],
+ dim=-1,
+ )
+
+ # 1D Convolution
+ if cache_params is not None:
+ hidden_states_B_C_t = hidden_states_B_C.transpose(1, 2)
+ conv_state = nn.functional.pad(
+ hidden_states_B_C_t, (self.conv_kernel_size - hidden_states_B_C_t.shape[-1], 0)
+ )
+ cache_params.conv_states[self.layer_idx].copy_(conv_state)
+ if causal_conv1d_fn is None or self.activation not in ["silu", "swish"]:
+ hidden_states_B_C = self.act(
+ self.conv1d(hidden_states_B_C.transpose(1, 2)).transpose(1, 2)[:, :seq_len]
+ ) # (B, L, self.d_inner + 2 * ngroups * d_state)
+ else:
+ hidden_states_B_C = causal_conv1d_fn(
+ x=hidden_states_B_C.transpose(1, 2),
+ weight=self.conv1d.weight.squeeze(1),
+ bias=self.conv1d.bias,
+ activation=self.activation,
+ ).transpose(1, 2)[:, :seq_len]
+ hidden_states, B, C = torch.split(
+ hidden_states_B_C,
+ [self.intermediate_size, groups_time_state_size, groups_time_state_size],
+ dim=-1,
+ )
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ dtype = hidden_states.dtype
+ hidden_states = (hidden_states * attention_mask[:, :, None]).to(dtype)
+ scan_output, ssm_state = mamba_chunk_scan_combined(
+ hidden_states.view(batch_size, seq_len, -1, self.head_dim),
+ time_step,
+ A,
+ B.view(batch_size, seq_len, self.n_groups, -1),
+ C.view(batch_size, seq_len, self.n_groups, -1),
+ chunk_size=self.chunk_size,
+ D=self.D,
+ z=None,
+ seq_idx=None,
+ return_final_states=True,
+ dt_bias=self.dt_bias,
+ dt_softplus=True,
+ **dt_limit_kwargs,
+ )
+ if ssm_state is not None and cache_params is not None:
+ cache_params.ssm_states[self.layer_idx].copy_(ssm_state)
+ scan_output = scan_output.view(batch_size, seq_len, -1)
+ # Multiply "gate" branch and apply extra normalization layer
+ scan_output = self.norm(scan_output, gate)
+ out = self.out_proj(scan_output)
+ return out
+
+ # fmt: off
+ def torch_forward(self, input_states, cache_params: Optional[Zamba2HybridDynamicCache]=None, attention_mask: Optional[torch.Tensor]=None):
+ batch_size, seq_len, _ = input_states.shape
+ dtype = input_states.dtype
+ # Gated MLP's linear projection
+ if cache_params is not None and cache_params.has_previous_state:
+ projected_states = self.in_proj(input_states.squeeze(1))
+ else:
+ if attention_mask is not None and not torch.all(attention_mask==1):
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ input_states = (input_states * attention_mask[:, :, None]).to(dtype)
+ projected_states = self.in_proj(input_states)
+ d_mlp = (projected_states.shape[-1] - 2 * self.intermediate_size - 2 * self.n_groups * self.ssm_state_size- self.num_heads) // 2
+ _, _, gate, hidden_states, dt = projected_states.split(
+ [d_mlp, d_mlp, self.intermediate_size, self.conv_dim, self.num_heads], dim=-1
+ )
+
+ # Convolution sequence transformation
+ if cache_params is not None:
+ ssm_state = cache_params.ssm_states[self.layer_idx].clone()
+ ssm_state = ssm_state.to(hidden_states.device)
+ if cache_params.has_previous_state:
+ gate = gate.unsqueeze(1)
+ conv_state = cache_params.conv_states[self.layer_idx] # [batch, intermediate_size, conv_kernel_size]
+ conv_state = torch.roll(conv_state, shifts=-1, dims=-1)
+ # handle batched generation - states are copied through
+ conv_state[:, :, -1] = hidden_states[:, 0, :] if hidden_states.ndim == 3 else hidden_states
+ cache_params.conv_states[self.layer_idx].copy_(conv_state)
+ hidden_states = torch.sum(conv_state.to(projected_states.device) * self.conv1d.weight[:, 0, :], dim=-1)
+ if self.use_conv_bias:
+ hidden_states += self.conv1d.bias
+ hidden_states = self.act(hidden_states).to(dtype)[:, None, ...] # [batch, 1, intermediate_size] : decoding
+ else:
+ hidden_states = hidden_states.transpose(1,2)
+ conv_state = nn.functional.pad(
+ hidden_states,
+ (self.conv_kernel_size - hidden_states.shape[-1], 0)
+ )
+ cache_params.conv_states[self.layer_idx].copy_(conv_state)
+ hidden_states = self.act(self.conv1d(hidden_states).transpose(1,2))[:, :seq_len, :] # [batch, intermediate_size, seq_len]
+ if attention_mask is not None and not torch.all(attention_mask==1):
+ dtype = hidden_states.dtype
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ hidden_states = (hidden_states * attention_mask[:, :, None]).to(dtype)
+ else:
+ ssm_state = torch.zeros(
+ (batch_size, self.num_heads, self.head_dim, self.ssm_state_size),
+ device=hidden_states.device, dtype=dtype
+ )
+ hidden_states = self.act(self.conv1d(hidden_states.transpose(1, 2))[..., :seq_len].transpose(1, 2))
+ hidden_states, B, C = torch.split(hidden_states, [self.intermediate_size, self.n_groups * self.ssm_state_size, self.n_groups * self.ssm_state_size], dim=-1)
+ A = -torch.exp(self.A_log.float()) # [num_heads]
+ if cache_params is not None and cache_params.has_previous_state:
+ # Note: there is no need to pad parameter matrices here, as there is just one new token
+ # for batched generation
+ dt = dt[:, None, ...] if dt.ndim == 2 else dt[:, 0, :][:, None, ...]
+ dt = dt.transpose(1, 2).expand(batch_size, dt.shape[-1], self.head_dim)
+ # [num_heads] -> [num_heads, head_dim]
+ dt_bias = self.dt_bias[..., None].expand(self.dt_bias.shape[0], self.head_dim)
+
+ dt = torch.nn.functional.softplus(dt + dt_bias.to(dt.dtype))
+ dt = torch.clamp(dt, self.time_step_min) #, self.time_step_max)
+ A = A[..., None, None].expand(self.num_heads, self.head_dim, self.ssm_state_size).to(dtype=torch.float32)
+ # [bsz, num_heads, head_dim, state_size]
+ dA = torch.exp(dt[..., None] * A)
+
+ # Discretize B
+ # [bsz, n_groups * state_size] -> [bsz, n_groups, 1, state_size] ->
+ # -> [bsz, n_groups, group to head repetition factor, state_size] -> [bsz, num_heads, state_size]
+ B = B.reshape(batch_size, self.n_groups, -1)[..., None, :]
+ B = B.expand(batch_size, self.n_groups, self.num_heads // self.n_groups, B.shape[-1]).contiguous()
+ B = B.reshape(batch_size, -1, B.shape[-1])
+ # [bsz, num_heads, head_dim, state_size]
+ dB = dt[..., None] * B[..., None, :]
+
+ # Discretize x into dB
+ # [bsz, intermediate_size] -> [bsz, num_heads, head_dim]
+ hidden_states = hidden_states.reshape(batch_size, -1, self.head_dim)
+ dBx = dB * hidden_states[..., None]
+
+ # State calculation
+ cache_params.ssm_states[self.layer_idx].copy_(
+ cache_params.ssm_states[self.layer_idx] * dA + dBx
+ )
+
+ # Subsequent output
+ # [bsz, n_groups * state_size] -> [bsz, num_heads, state_size]
+ C = C.reshape(batch_size, self.n_groups, -1)[..., None, :]
+ C = C.expand(batch_size, self.n_groups, self.num_heads // self.n_groups, C.shape[-1]).contiguous()
+ C = C.reshape(batch_size, -1, C.shape[-1])
+ # [bsz, num_heads, head_dim]
+
+ ssm_states = cache_params.ssm_states[self.layer_idx].to(C.dtype) # Shape: [b, h, d, n]
+ # Reshape ssm_states to merge the first two dimensions
+ ssm_states_reshaped = ssm_states.view(batch_size * self.num_heads, self.head_dim, self.ssm_state_size) # Shape: [b*h, d, n]
+ C_reshaped = C.view(batch_size * self.num_heads, self.ssm_state_size, 1) # Shape: [b*h, n, 1]
+ y = torch.bmm(ssm_states_reshaped, C_reshaped)
+ y = y.view(batch_size, self.num_heads, self.head_dim)
+
+ # D skip connection
+ # [num_heads] -> [num_heads, head_dim]
+ D = self.D[..., None].expand(self.D.shape[0], self.head_dim)
+ y = (y + hidden_states * D).to(y.dtype)
+
+ # [bsz, num_heads, head_dim] -> [bsz, 1, intermediate_size]
+ y = y.reshape(batch_size, -1)[:, None, ...]
+ else:
+ # begin ssd naive implementation without einsums
+ dt = nn.functional.softplus(dt + self.dt_bias)
+ dt = torch.clamp(dt, self.time_step_min)
+ hidden_states = hidden_states.reshape(batch_size, seq_len, -1, self.head_dim).float()
+ B = B.reshape(batch_size, seq_len, -1, self.ssm_state_size).float()
+ C = C.reshape(batch_size, seq_len, -1, self.ssm_state_size).float()
+ B = B.repeat_interleave(self.num_heads // self.n_groups, dim=2, output_size=self.num_heads)
+ C = C.repeat_interleave(self.num_heads // self.n_groups, dim=2, output_size=self.num_heads)
+ pad_size = (self.chunk_size - seq_len % self.chunk_size) % self.chunk_size
+
+ D_residual = self.D[..., None] * pad_tensor_by_size(hidden_states, pad_size)
+
+ # Discretize x and A
+ hidden_states = hidden_states * dt[..., None]
+ A = A.to(hidden_states.dtype) * dt
+
+ # Rearrange into blocks/chunks
+ hidden_states, A, B, C = [reshape_into_chunks(t, pad_size, self.chunk_size) for t in (hidden_states, A, B, C)]
+
+
+ # [bsz, -1, chunk_size, num_heads] -> [bsz, num_heads, -1, chunk_size]
+ A = A.permute(0, 3, 1, 2)
+ A_cumsum = torch.cumsum(A, dim=-1)
+
+ # 1. Compute the output for each intra-chunk (diagonal blocks)
+ # This is the analog of a causal mask
+ L = torch.exp(segment_sum(A))
+
+ # First, contraction of C and B to get G (attention-weights like)
+ G_intermediate = C[:, :, :, None, :, :] * B[:, :, None, :, : ,:] # shape: (b, c, l, s, h, n)
+ G = G_intermediate.sum(dim=-1) # shape: (b, c, l, s, h)
+
+
+ # Step 2: Compute M, equivalent to applying attention mask to weights
+ M_intermediate = G[..., None] * L.permute(0, 2, 3, 4, 1)[..., None]
+ M = M_intermediate.sum(dim=-1)
+
+ # Step 3: Compute Y_diag (apply to values)
+ Y_diag = (M[..., None] * hidden_states[:, :, None]).sum(3)
+
+ # (right term of low-rank factorization of off-diagonal blocks; B terms)
+
+ decay_states = torch.exp(A_cumsum[:, :, :, -1:] - A_cumsum)
+ B_decay_contraction = B * decay_states.permute(0, 2, 3, 1)[..., None]
+ # permute back B * decay states
+ states = (B_decay_contraction.permute(0, 1, 3, 2, 4)[..., None] * hidden_states.permute(0, 1, 3, 2, 4)[..., None, :]).sum(dim=3).permute(0, 1, 2, 4, 3)
+ if cache_params is not None and cache_params.has_previous_state:
+ previous_states = cache_params.ssm_states[self.layer_idx][:, None, ...]
+ else:
+ previous_states = torch.zeros_like(states[:, :1])
+ states = torch.cat([previous_states, states], dim=1)
+ decay_chunk = torch.exp(segment_sum(nn.functional.pad(A_cumsum[:, :, :, -1], (1, 0))))
+
+ states_permuted = states.permute(0, 2, 1, 3, 4)
+ result = (decay_chunk[..., None, None] * states_permuted[:, :, None, ...]).sum(dim=2)
+ new_states = result.permute(0, 2, 1, 3, 4)
+ states, ssm_state = new_states[:, :-1], new_states[:, -1]
+
+ # Compute state -> output conversion per chunk
+ # (left term of low-rank factorization of off-diagonal blocks; C terms)
+ state_decay_out = torch.exp(A_cumsum)
+ # compute Yoff
+ C_times_states = (C[..., None, :] * states[:, :, None, ...])
+ state_decay_out_permuted = state_decay_out.permute(0, 2, 3, 1)
+ Y_off = (C_times_states.sum(-1) * state_decay_out_permuted[..., None])
+ # Add output of intra-chunk and inter-chunk terms (diagonal and off-diagonal blocks)
+
+ y = Y_diag + Y_off
+ # [bsz, -1, self.chunk_size, num_heads, head_dim] -> [bsz, (padded) seq_len, num_heads, head_dim]
+ y = y.reshape(batch_size, -1, self.num_heads, self.head_dim)
+
+ y = y + D_residual
+ # Cutting off padded chunks
+ if pad_size > 0:
+ y = y[:, :seq_len, :, :]
+ y = y.reshape(batch_size, seq_len, -1)
+ if ssm_state is not None and cache_params is not None:
+ cache_params.ssm_states[self.layer_idx].copy_(ssm_state)
+
+ scan_output = self.norm(y, gate)
+
+ # end ssd naive
+
+ # 4. Final linear projection
+ contextualized_states = self.out_proj(scan_output.to(dtype)) # [batch, seq_len, hidden_size]
+ return contextualized_states
+ # fmt: on
+
+ def forward(
+ self,
+ hidden_states,
+ cache_params: Optional[Zamba2HybridDynamicCache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ ):
+ if is_fast_path_available and "cuda" in self.in_proj.weight.device.type:
+ return self.cuda_kernels_forward(hidden_states, cache_params, attention_mask)
+
+ return self.torch_forward(hidden_states, cache_params, attention_mask)
+
+
+class Zamba2MLP(nn.Module):
+ def __init__(self, config: Zamba2Config, num_fwd_mem_blocks=None, block_id: Optional[int] = None):
+ """
+ This MLP layer contributes to tied transformer blocks aimed to increasing compute without increasing model size. Because this layer
+ is tied, un-tied adapter modules (formally same as LoRA, but used in the base model) are added to the up and gate projectors to increase expressivity with a small memory overhead.
+ """
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.num_fwd_mem_blocks = num_fwd_mem_blocks
+ self.block_id = block_id
+
+ self.gate_up_proj = nn.Linear(self.hidden_size, 2 * self.intermediate_size, bias=config.add_bias_linear)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.add_bias_linear)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ self.gate_up_proj_adapter_list = nn.ModuleList([])
+ for i in range(self.num_fwd_mem_blocks):
+ if i % config.num_mem_blocks == block_id:
+ gate_up_proj_adapter = nn.Sequential(
+ nn.Linear(self.config.hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, 2 * self.intermediate_size, bias=False),
+ )
+ else:
+ gate_up_proj_adapter = nn.Identity()
+ self.gate_up_proj_adapter_list.append(gate_up_proj_adapter)
+
+ layer_block_map = config.hybrid_layer_ids
+ self.layer_dic = {value: index for index, value in enumerate(layer_block_map)}
+
+ def forward(self, hidden_state, layer_idx=None):
+ gate_up_state = self.gate_up_proj(hidden_state)
+ layer_idx = self.layer_dic[layer_idx]
+ gate_up_state = gate_up_state + self.gate_up_proj_adapter_list[layer_idx](hidden_state)
+
+ gate_up_state = torch.chunk(gate_up_state, 2, dim=-1)
+ hidden_state = self.act_fn(gate_up_state[0]) * gate_up_state[1]
+ output = self.down_proj(hidden_state)
+ return output
+
+
+class Zamba2AttentionDecoderLayer(nn.Module):
+ def __init__(self, config: Zamba2Config, block_id: Optional[int] = None, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.block_id = block_id
+ num_gs = len(config.hybrid_layer_ids)
+ self.self_attn = Zamba2Attention(config, layer_idx=-1, num_fwd_mem_blocks=num_gs, block_id=block_id)
+ self.feed_forward = Zamba2MLP(config, num_fwd_mem_blocks=num_gs, block_id=block_id)
+ self.input_layernorm = Zamba2RMSNorm(config.attention_hidden_size, eps=config.rms_norm_eps)
+ self.pre_ff_layernorm = Zamba2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: torch.Tensor,
+ layer_idx: int,
+ attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ position_embeddings: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): output of previous Mamba layer of shape `(batch, seq_len, embed_dim)`
+ original_hidden_states (`torch.FloatTensor`): word embedding output of shape `(batch, seq_len, embed_dim)`.
+ This is concatenated with `hidden_states` (which is the output of the previous (mamba) layer). The
+ concatenated tensor is then used as input of the pre-attention RMSNorm
+ (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`Zamba2HybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*):
+ Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`,
+ with `head_dim` being the embedding dimension of each attention head.
+ """
+ hidden_states = torch.concatenate([hidden_states, original_hidden_states], dim=-1)
+ hidden_states = self.input_layernorm(hidden_states)
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+
+ hidden_states = self.pre_ff_layernorm(hidden_states)
+ hidden_states = self.feed_forward(hidden_states, layer_idx)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+class Zamba2MambaDecoderLayer(nn.Module):
+ def __init__(self, config: Zamba2Config, layer_idx: int):
+ super().__init__()
+ self.mamba = Zamba2MambaMixer(config=config, layer_idx=layer_idx)
+ self.input_layernorm = Zamba2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ self.layer_idx = layer_idx
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: Optional[torch.Tensor] = None,
+ layer_idx: Optional[int] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ cache_position: Optional[torch.LongTensor] = None,
+ transformer_hidden_states: Optional[torch.Tensor] = None,
+ **kwargs,
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`Zamba2HybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*):
+ Indices depicting the position of the input sequence tokens in the sequence.
+ """
+
+ residual = hidden_states
+
+ # `transformer_hidden_states` is the output from shared transformer + linear layer (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ # `transformer_hidden_states` is then added to the input to the mamba layer below (as described in eq. (6) of https://huggingface.co/papers/2405.16712).
+ hidden_states = (
+ hidden_states + transformer_hidden_states if transformer_hidden_states is not None else hidden_states
+ )
+ hidden_states = self.input_layernorm(hidden_states)
+
+ hidden_states = self.mamba(
+ hidden_states=hidden_states,
+ cache_params=past_key_values,
+ attention_mask=attention_mask,
+ )
+
+ self_attn_weights = None
+
+ # residual connection after mamba
+ hidden_states = residual + hidden_states
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ if use_cache:
+ outputs += (past_key_values,)
+
+ return outputs
+
+
+class Zamba2HybridLayer(nn.Module):
+ def __init__(
+ self, shared_transformer: Zamba2AttentionDecoderLayer, linear: nn.Linear, mamba: Zamba2MambaDecoderLayer
+ ):
+ super().__init__()
+ self.linear = linear
+ self.mamba_decoder = mamba
+ self.shared_transformer = shared_transformer
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: Optional[torch.Tensor] = None,
+ layer_idx: Optional[int] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ position_embeddings: Optional[torch.LongTensor] = None,
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ original_hidden_states (`torch.FloatTensor`): word embedding output that will be concatenated with
+ hidden activations to form the input of the shared transformer layer.
+ layer_idx (`int`): layer number.
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`Zamba2HybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*):
+ Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`,
+ with `head_dim` being the embedding dimension of each attention head.
+ """
+
+ layer_outputs = self.shared_transformer(
+ hidden_states,
+ original_hidden_states=original_hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=causal_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ position_embeddings=position_embeddings,
+ )
+
+ transformer_hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ self_attn_weights = layer_outputs[1]
+
+ transformer_hidden_states = self.linear(transformer_hidden_states)
+
+ layer_outputs = self.mamba_decoder(
+ hidden_states,
+ transformer_hidden_states=transformer_hidden_states,
+ attention_mask=attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ position_embeddings=position_embeddings,
+ )
+
+ if output_attentions:
+ layer_outputs = (layer_outputs[0], self_attn_weights) + layer_outputs[2:]
+
+ return layer_outputs
+
+
+class Zamba2PreTrainedModel(PreTrainedModel):
+ config: Zamba2Config
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["Zamba2AttentionDecoderLayer", "Zamba2MambaDecoderLayer"]
+ _skip_keys_device_placement = "past_key_values"
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_sdpa = True
+ # Note: only supports Zamba2HybridDynamicCache
+ _is_stateful = True
+
+ def _init_weights(self, module):
+ super()._init_weights(module)
+ if isinstance(module, Zamba2MambaMixer):
+ dt = torch.exp(
+ torch.rand(self.config.n_mamba_heads)
+ * (math.log(self.config.time_step_max) - math.log(self.config.time_step_min))
+ + math.log(self.config.time_step_min)
+ ).clamp(min=self.config.time_step_floor)
+ # # Inverse of softplus: https://github.com/pytorch/pytorch/issues/72759
+ inv_dt = dt + torch.log(-torch.expm1(-dt))
+ module.dt_bias.data.copy_(inv_dt)
+
+ A = torch.arange(1, module.num_heads + 1)
+ module.A_log.data.copy_(torch.log(A))
+ module.D.data.fill_(1.0)
+
+
+@auto_docstring
+class Zamba2Model(Zamba2PreTrainedModel):
+ """
+ Model consisting of *config.num_hidden_layers* layers.
+
+ Args:
+ config: Zamba2Config
+ """
+
+ def __init__(self, config: Zamba2Config):
+ super().__init__(config)
+ self.config = config
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ blocks = [Zamba2AttentionDecoderLayer(config, block_id=k) for k in range(config.num_mem_blocks)]
+ mamba_layers = []
+ linear_layers = []
+ self.layers_block_type = config.layers_block_type
+ for i in range(config.num_hidden_layers):
+ if config.layers_block_type[i] == "mamba":
+ mamba_layers.append(Zamba2MambaDecoderLayer(config, layer_idx=i))
+ elif config.layers_block_type[i] == "hybrid":
+ linear_layers.append(nn.Linear(self.config.hidden_size, self.config.hidden_size, bias=False))
+ mamba_layers.append(Zamba2MambaDecoderLayer(config, layer_idx=i))
+ mamba_layers = iter(mamba_layers)
+ linear_layers = iter(linear_layers)
+ blocks = cycle(blocks)
+ layers = self.get_layers(blocks, linear_layers, mamba_layers)
+ self.layers = nn.ModuleList(layers)
+
+ self._attn_implementation = config._attn_implementation
+ self.final_layernorm = Zamba2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ if config.use_mem_rope:
+ if config.use_long_context:
+ logger.warning_once(
+ "`use_long_context` set to `True`: using rescaled `rope_theta` and extended `max_position_embeddings`."
+ )
+ self.rotary_emb = Zamba2RotaryEmbedding(config)
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPast]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError(
+ "You cannot specify both input_ids and inputs_embeds at the same time, and must specify either one"
+ )
+
+ if self.gradient_checkpointing and self.training and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ hidden_states = inputs_embeds
+
+ original_hidden_states = torch.clone(inputs_embeds)
+ # original_hidden_states: word embedding output that will be concatenated with hidden activations to form the input of the shared transformer layer
+
+ if use_cache and past_key_values is None:
+ batch_size = input_ids.shape[0] if input_ids is not None else inputs_embeds.shape[0]
+ past_key_values = Zamba2HybridDynamicCache(self.config, batch_size, dtype=self.dtype, device=self.device)
+
+ if cache_position is None:
+ past_seen_tokens = (
+ past_key_values.get_seq_length(layer_idx=self.first_transformer_layer_id)
+ if past_key_values is not None
+ else 0
+ )
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ causal_mask = self._update_causal_mask(attention_mask, inputs_embeds, cache_position)
+
+ # create position embeddings to be shared across the decoder layers
+ if self.config.use_mem_rope:
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+ else:
+ position_embeddings = None
+
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+
+ for layer_idx, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ layer.__call__,
+ hidden_states,
+ original_hidden_states,
+ layer_idx,
+ attention_mask,
+ causal_mask,
+ past_key_values,
+ output_attentions,
+ use_cache,
+ position_embeddings,
+ )
+ else:
+ layer_outputs = layer(
+ hidden_states,
+ original_hidden_states=original_hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=attention_mask,
+ causal_mask=causal_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ position_embeddings=position_embeddings,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ if layer_outputs[1] is not None:
+ # append attentions only of attention layers. Mamba layers return `None` as the attention weights
+ all_self_attns += (layer_outputs[1],)
+
+ hidden_states = self.final_layernorm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if past_key_values is not None and not past_key_values.has_previous_state:
+ past_key_values.has_previous_state = True
+
+ output = BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ )
+ return output if return_dict else output.to_tuple()
+
+ def _update_causal_mask(self, attention_mask, input_tensor, cache_position):
+ if self.config._attn_implementation == "flash_attention_2":
+ if attention_mask is not None and 0.0 in attention_mask:
+ return attention_mask
+ return None
+
+ dtype, device = input_tensor.dtype, input_tensor.device
+ min_dtype = torch.finfo(dtype).min
+ sequence_length = input_tensor.shape[1]
+ target_length = cache_position[-1] + 1
+
+ causal_mask = torch.full((sequence_length, target_length), fill_value=min_dtype, dtype=dtype, device=device)
+ if sequence_length != 1:
+ causal_mask = torch.triu(causal_mask, diagonal=1)
+ causal_mask *= torch.arange(target_length, device=device) > cache_position.reshape(-1, 1)
+ causal_mask = causal_mask[None, None, :, :].expand(input_tensor.shape[0], 1, -1, -1)
+ if attention_mask is not None:
+ causal_mask = causal_mask.clone() # copy to contiguous memory for in-place edit
+ if attention_mask.dim() == 2:
+ mask_length = attention_mask.shape[-1]
+ padding_mask = causal_mask[..., :mask_length].eq(0.0) * attention_mask[:, None, None, :].eq(0.0)
+ causal_mask[..., :mask_length] = causal_mask[..., :mask_length].masked_fill(padding_mask, min_dtype)
+
+ if (
+ self.config._attn_implementation == "sdpa"
+ and attention_mask is not None
+ and attention_mask.device.type in ["cuda", "xpu", "npu"]
+ ):
+ # Attend to all tokens in fully masked rows in the causal_mask, for example the relevant first rows when
+ # using left padding. This is required by F.scaled_dot_product_attention memory-efficient attention path.
+ # Details: https://github.com/pytorch/pytorch/issues/110213
+ causal_mask = AttentionMaskConverter._unmask_unattended(causal_mask, min_dtype)
+
+ return causal_mask
+
+ def get_layers(self, blocks, linear_layers, mamba_layers):
+ layers = []
+ self._tied_weights_keys = []
+ self.first_transformer_layer_id = 0
+ for layer_id, layer_type in enumerate(self.layers_block_type):
+ if layer_type == "hybrid":
+ if self.first_transformer_layer_id == 0:
+ self.first_transformer_layer_id = layer_id
+ block = next(blocks)
+ if self.config.num_mem_blocks * len(self.config.hybrid_layer_ids) > 1:
+ prefix_pattern = rf"^layers\.{layer_id}\.shared_transformer\."
+ main_keys_pattern = re.compile(
+ prefix_pattern
+ + r"(?:"
+ + r"self_attn\.(?:q_proj|k_proj|v_proj|o_proj)\.weight|"
+ + r"feed_forward\.(?:gate_up_proj|down_proj)\.weight|"
+ + r"(?:input_layernorm|pre_ff_layernorm)\.weight"
+ + r")$"
+ )
+ self._tied_weights_keys.append(main_keys_pattern)
+
+ adapter_id = 0
+ for _layer_type in self.layers_block_type:
+ if _layer_type == "hybrid" and adapter_id % self.config.num_mem_blocks == block.block_id:
+ adapter_pattern = re.compile(
+ r"^shared_transformer\.feed_forward\.gate_up_proj_adapter_list\."
+ + str(adapter_id)
+ + r"\.(?:0|1)\.weight$"
+ )
+ self._tied_weights_keys.append(adapter_pattern)
+ adapter_id += 1
+ if self.config.use_shared_attention_adapter:
+ adapter_id = 0
+ for _layer_type in self.layers_block_type:
+ if _layer_type == "hybrid" and adapter_id % self.config.num_mem_blocks == block.block_id:
+ attn_adapter_pattern = re.compile(
+ r"^shared_transformer\.self_attn\."
+ + r"(?:linear_q_adapter_list|linear_k_adapter_list|linear_v_adapter_list)\."
+ + str(adapter_id)
+ + r"\.(?:0|1)\.weight$"
+ )
+ self._tied_weights_keys.append(attn_adapter_pattern)
+ adapter_id += 1
+ layers.append(Zamba2HybridLayer(block, next(linear_layers), next(mamba_layers)))
+ else:
+ layers.append(next(mamba_layers))
+ return layers
+
+
+# Adapted from transformers.models.jamba.modeling_jamba.JambaForCausalLM with Jamba->Zamba2, JAMBA->ZAMBA2
+class Zamba2ForCausalLM(Zamba2PreTrainedModel, GenerationMixin):
+ def __init__(self, config: Zamba2Config):
+ super().__init__(config)
+ self.model = Zamba2Model(config)
+ self._tied_weights_keys = ["lm_head.weight", *self.model._tied_weights_keys]
+ self.vocab_size = config.vocab_size
+ self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ logits_to_keep: Union[int, torch.Tensor] = 0,
+ **kwargs,
+ ) -> Union[tuple, CausalLMOutputWithPast]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*):
+ Labels for computing the masked language modeling loss. Indices should either be in `[0, ...,
+ config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored
+ (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
+
+ Example:
+
+ ```python
+ >>> from transformers import AutoTokenizer, Zamba2ForCausalLM
+
+ >>> model = Zamba2ForCausalLM.from_pretrained("Zyphra/Zamba2-7B-v1")
+ >>> tokenizer = AutoTokenizer.from_pretrained("Zyphra/Zamba2-7B-v1")
+
+ >>> prompt = "Hey, are you conscious? Can you talk to me?"
+ >>> inputs = tokenizer(prompt, return_tensors="pt")
+
+ >>> # Generate
+ >>> generate_ids = model.generate(inputs.input_ids, max_length=30)
+ >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+ "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you."
+ ```"""
+
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
+ outputs = self.model(
+ input_ids=input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ cache_position=cache_position,
+ return_dict=return_dict,
+ )
+
+ hidden_states = outputs[0]
+ # Only compute necessary logits, and do not upcast them to float if we are not computing the loss
+ slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
+ logits = self.lm_head(hidden_states[:, slice_indices, :])
+
+ loss = None
+ if labels is not None:
+ loss = self.loss_function(logits, labels, self.vocab_size, **kwargs)
+
+ if not return_dict:
+ output = (logits,) + outputs[1:]
+ return (loss,) + output if loss is not None else output
+
+ return CausalLMOutputWithPast(
+ loss=loss,
+ logits=logits,
+ past_key_values=outputs.past_key_values,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+ def prepare_inputs_for_generation(
+ self,
+ input_ids,
+ past_key_values=None,
+ attention_mask=None,
+ inputs_embeds=None,
+ cache_position=None,
+ position_ids=None,
+ use_cache=True,
+ **kwargs,
+ ):
+ # Overwritten -- has a unique cache type, `Zamba2HybridDynamicCache`
+
+ empty_past_kv = past_key_values is None
+
+ # Omit tokens covered by past_key_values
+ if not empty_past_kv:
+ # If we have cache: let's slice `input_ids` through `cache_position`, to keep only the unprocessed tokens
+ # Exception 1: when passing input_embeds, input_ids may be missing entries
+ # Exception 2: some generation methods do special slicing of input_ids, so we don't need to do it here
+ # Exception 3: with synced GPUs cache_position may go out of bounds, but we only want dummy token in that case.
+ # (we can't check exception 3 while compiling)
+ if (
+ inputs_embeds is not None # Exception 1
+ or cache_position[-1] >= input_ids.shape[1] # Exception 3
+ ):
+ input_ids = input_ids[:, -cache_position.shape[0] :]
+ elif input_ids.shape[1] != cache_position.shape[0]: # Default case (the "else", a no op, is Exception 2)
+ input_ids = input_ids[:, cache_position]
+ else:
+ past_key_values = Zamba2HybridDynamicCache(
+ self.config, input_ids.shape[0], dtype=self.dtype, device=self.device
+ )
+
+ if attention_mask is not None and position_ids is None:
+ # create position_ids on the fly for batch generation
+ position_ids = attention_mask.long().cumsum(-1) - 1
+ position_ids.masked_fill_(attention_mask == 0, 1)
+ if not empty_past_kv:
+ position_ids = position_ids[:, -input_ids.shape[1] :]
+
+ # if `inputs_embeds` are passed, we only want to use them in the 1st generation step
+ if inputs_embeds is not None and empty_past_kv:
+ model_inputs = {"inputs_embeds": inputs_embeds}
+ else:
+ model_inputs = {"input_ids": input_ids.contiguous()} # `contiguous()` needed for compilation use cases
+
+ model_inputs.update(
+ {
+ "position_ids": position_ids,
+ "past_key_values": past_key_values,
+ "use_cache": use_cache,
+ "attention_mask": attention_mask,
+ "logits_to_keep": self.config.num_logits_to_keep,
+ "cache_position": cache_position,
+ }
+ )
+ return model_inputs
+
+
+@auto_docstring(
+ custom_intro="""
+ The Zamba2 Model with a sequence classification head on top (linear layer).
+
+ [`Zamba2ForSequenceClassification`] uses the last token in order to do the classification, as other causal models
+ (e.g. GPT-2) do.
+
+ Since it does classification on the last token, it requires to know the position of the last token. If a
+ `pad_token_id` is defined in the configuration, it finds the last token that is not a padding token in each row. If
+ no `pad_token_id` is defined, it simply takes the last value in each row of the batch. Since it cannot guess the
+ padding tokens when `inputs_embeds` are passed instead of `input_ids`, it does the same (take the last value in
+ each row of the batch).
+ """
+)
+class Zamba2ForSequenceClassification(Zamba2PreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.num_labels = config.num_labels
+ self.model = Zamba2Model(config)
+ self._tied_weights_keys = self.model._tied_weights_keys
+ self.score = nn.Linear(config.hidden_size, self.num_labels, bias=False)
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Union[Cache, list[torch.FloatTensor]]] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ labels: Optional[torch.LongTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple, SequenceClassifierOutputWithPast]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*):
+ Labels for computing the sequence classification/regression loss. Indices should be in `[0, ...,
+ config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If
+ `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
+ """
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ transformer_outputs = self.model(
+ input_ids,
+ attention_mask=attention_mask,
+ position_ids=position_ids,
+ past_key_values=past_key_values,
+ inputs_embeds=inputs_embeds,
+ use_cache=use_cache,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+ hidden_states = transformer_outputs[0]
+ logits = self.score(hidden_states)
+
+ if input_ids is not None:
+ batch_size = input_ids.shape[0]
+ else:
+ batch_size = inputs_embeds.shape[0]
+
+ if self.config.pad_token_id is None and batch_size != 1:
+ raise ValueError("Cannot handle batch sizes > 1 if no padding token is defined.")
+ if self.config.pad_token_id is None:
+ last_non_pad_token = -1
+ elif input_ids is not None:
+ # To handle both left- and right- padding, we take the rightmost token that is not equal to pad_token_id
+ non_pad_mask = (input_ids != self.config.pad_token_id).to(logits.device, torch.int32)
+ token_indices = torch.arange(input_ids.shape[-1], device=logits.device, dtype=torch.int32)
+ last_non_pad_token = (token_indices * non_pad_mask).argmax(-1)
+ else:
+ last_non_pad_token = -1
+ logger.warning_once(
+ f"{self.__class__.__name__} will not detect padding tokens in `inputs_embeds`. Results may be "
+ "unexpected if using padding tokens in conjunction with `inputs_embeds.`"
+ )
+
+ pooled_logits = logits[torch.arange(batch_size, device=logits.device), last_non_pad_token]
+
+ loss = None
+ if labels is not None:
+ labels = labels.to(logits.device)
+ if self.config.problem_type is None:
+ if self.num_labels == 1:
+ self.config.problem_type = "regression"
+ elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int):
+ self.config.problem_type = "single_label_classification"
+ else:
+ self.config.problem_type = "multi_label_classification"
+
+ if self.config.problem_type == "regression":
+ loss_fct = MSELoss()
+ if self.num_labels == 1:
+ loss = loss_fct(pooled_logits.squeeze(), labels.squeeze())
+ else:
+ loss = loss_fct(pooled_logits, labels)
+ elif self.config.problem_type == "single_label_classification":
+ loss_fct = CrossEntropyLoss()
+ loss = loss_fct(pooled_logits.view(-1, self.num_labels), labels.view(-1))
+ elif self.config.problem_type == "multi_label_classification":
+ loss_fct = BCEWithLogitsLoss()
+ loss = loss_fct(pooled_logits, labels)
+ if not return_dict:
+ output = (pooled_logits,) + transformer_outputs[1:]
+ return ((loss,) + output) if loss is not None else output
+
+ return SequenceClassifierOutputWithPast(
+ loss=loss,
+ logits=pooled_logits,
+ past_key_values=transformer_outputs.past_key_values,
+ hidden_states=transformer_outputs.hidden_states,
+ attentions=transformer_outputs.attentions,
+ )
+
+
+__all__ = ["Zamba2ForCausalLM", "Zamba2ForSequenceClassification", "Zamba2Model", "Zamba2PreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/modular_zamba2.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/modular_zamba2.py
new file mode 100644
index 0000000000000000000000000000000000000000..acf552a2abb10e4672d2ff5958edcc3998168a8e
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zamba2/modular_zamba2.py
@@ -0,0 +1,1155 @@
+# coding=utf-8
+# Copyright 2024 Zyphra Technologies and the HuggingFace Inc. team. All rights reserved.
+#
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import math
+import re
+from itertools import cycle
+from typing import Callable, Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_flash_attention_utils import FlashAttentionKwargs
+from ...modeling_outputs import BaseModelOutputWithPast
+from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel
+from ...processing_utils import Unpack
+from ...utils import (
+ logging,
+)
+from ...utils.deprecation import deprecate_kwarg
+from ...utils.import_utils import (
+ is_causal_conv1d_available,
+ is_mamba_ssm_available,
+)
+from ..llama.modeling_llama import LlamaRotaryEmbedding, apply_rotary_pos_emb
+from ..mamba2.modeling_mamba2 import pad_tensor_by_size, reshape_into_chunks, segment_sum
+from ..zamba.modeling_zamba import (
+ ZambaAttention,
+ ZambaAttentionDecoderLayer,
+ ZambaForCausalLM,
+ ZambaForSequenceClassification,
+ ZambaHybridDynamicCache,
+ ZambaHybridLayer,
+ ZambaMambaDecoderLayer,
+ ZambaModel,
+ ZambaRMSNorm,
+ eager_attention_forward,
+)
+from .configuration_zamba2 import Zamba2Config
+
+
+if is_mamba_ssm_available():
+ from mamba_ssm.ops.triton.selective_state_update import selective_state_update
+ from mamba_ssm.ops.triton.ssd_combined import mamba_chunk_scan_combined, mamba_split_conv1d_scan_combined
+else:
+ selective_state_update, mamba_chunk_scan_combined, mamba_split_conv1d_scan_combined = None, None, None
+
+if is_causal_conv1d_available():
+ from causal_conv1d import causal_conv1d_fn, causal_conv1d_update
+else:
+ causal_conv1d_update, causal_conv1d_fn = None, None
+
+is_fast_path_available = all((selective_state_update, causal_conv1d_fn, causal_conv1d_update))
+
+
+_CONFIG_FOR_DOC = "Zyphra/Zamba2-2.7B"
+
+logger = logging.get_logger(__name__)
+
+
+class Zamba2RMSNormGated(torch.nn.Module):
+ def __init__(self, hidden_size, group_size, eps=1e-6):
+ super().__init__()
+ self.weight = nn.Parameter(torch.ones(hidden_size))
+ self.variance_epsilon = eps
+ self.group_size = group_size
+
+ def forward(self, hidden_states, gate=None):
+ input_dtype = hidden_states.dtype
+ hidden_states = hidden_states.to(torch.float32)
+ if gate is not None:
+ hidden_states = hidden_states * nn.functional.silu(gate.to(torch.float32))
+ *prefix_dims, last_dim = hidden_states.shape
+ group_count = last_dim // self.group_size
+ hidden_states_group = hidden_states.view(*prefix_dims, group_count, self.group_size)
+ variance = hidden_states_group.pow(2).mean(-1, keepdim=True)
+ hidden_states_group = hidden_states_group * torch.rsqrt(variance + self.variance_epsilon)
+ hidden_states = hidden_states_group.view(*prefix_dims, group_count * self.group_size)
+ return self.weight * hidden_states.to(input_dtype)
+
+
+class Zamba2RMSNorm(ZambaRMSNorm):
+ pass
+
+
+class Zamba2HybridDynamicCache(ZambaHybridDynamicCache):
+ """
+ A dynamic cache that can handle both the attention cache (which has a seq_len dimension) and the mamba cache
+ (which has a constant shape regardless of seq_len).
+
+ This cache has two sets of lists of tensors: `key_cache` and `value_cache` for attention cache and `conv_states`
+ and `ssm_states` for mamba cache. Each of these lists has `num_layers` tensors. The expected shape for each tensor
+ For attention layers, `key_cache` and `value_cache` have a shape of `(batch_size, num_heads, seq_len, head_dim)`,
+ while `conv_states` and `ssm_states` have a shape of `(batch_size, 0)` (empty tensors).
+ For mamba layers, `key_cache` and `value_cache` have a shape of `(batch_size, 0)` (empty tensors),
+ while `conv_states` represents the convolution state and has a shape of `(batch_size, d_inner, d_conv)`,
+ and `ssm_states` represents the ssm state and has a shape of `(batch_size, d_inner, d_state)`.
+ """
+
+ def __init__(
+ self, config: Zamba2Config, batch_size: int, dtype: torch.dtype = torch.float16, device: Optional[str] = None
+ ):
+ self.dtype = dtype
+ self.layers_block_type = config.layers_block_type
+ self.has_previous_state = False
+ self.intermediate_size = int(config.mamba_expand * config.hidden_size)
+ self.ssm_state_size = config.mamba_d_state
+ self.conv_kernel_size = config.mamba_d_conv
+ self.n_mamba_heads = config.n_mamba_heads
+ self.transformer_layers = []
+ self._modules = {}
+ self._parameters = {}
+ self._buffers = {}
+ self.conv_states = {}
+ self.ssm_states = {}
+ for i in range(config.num_hidden_layers):
+ self.conv_states[i] = torch.zeros(
+ batch_size,
+ self.intermediate_size + 2 * config.mamba_ngroups * config.mamba_d_state,
+ self.conv_kernel_size,
+ device=device,
+ dtype=dtype,
+ )
+ self.ssm_states[i] = torch.zeros(
+ batch_size, self.n_mamba_heads, config.mamba_headdim, self.ssm_state_size, device=device, dtype=dtype
+ )
+ if self.layers_block_type[i] == "hybrid":
+ self.transformer_layers.append(i)
+ self.key_cache = [torch.tensor([[]] * batch_size, device=device) for _ in range(config.num_hidden_layers)]
+ self.value_cache = [torch.tensor([[]] * batch_size, device=device) for _ in range(config.num_hidden_layers)]
+
+ def update_conv_state(
+ self, layer_idx: int, new_conv_state: torch.Tensor, cache_position: torch.LongTensor
+ ) -> torch.Tensor:
+ conv_state = self.conv_states[layer_idx]
+ cache_position = cache_position.clamp(0, self.conv_kernel_size - 1)
+
+ conv_state = conv_state.roll(shifts=-1, dims=-1)
+ conv_state[:, :, cache_position] = new_conv_state.to(conv_state.device)
+ self.conv_states[layer_idx].zero_()
+ self.conv_states[layer_idx] += conv_state
+ return self.conv_states[layer_idx]
+
+ def reset(self):
+ self.conv_states.zero_()
+ self.ssm_states.zero_()
+
+ def get_seq_length(self, layer_idx: Optional[int] = 0) -> int:
+ """Returns the sequence length of the cached states. A layer index can be optionally passed."""
+ # take any layer that contains cache and not empty tensor
+ layer_idx = self.transformer_layers[0] if layer_idx not in self.transformer_layers else layer_idx
+ if len(self.key_cache) <= layer_idx or self.key_cache[layer_idx].numel() == 0:
+ return 0
+ return self.key_cache[layer_idx].shape[-2]
+
+
+class Zamba2RotaryEmbedding(LlamaRotaryEmbedding):
+ pass
+
+
+class Zamba2Attention(ZambaAttention):
+ """
+ Multi-headed attention from 'Attention Is All You Need' paper.
+
+ Adapted from transformers.models.mistral.modeling_mistral.MistralAttention:
+ The input dimension here is attention_hidden_size = 2 * hidden_size, and head_dim = attention_hidden_size // num_heads.
+ The extra factor of 2 comes from the input being the concatenation of original_hidden_states with the output of the previous (mamba) layer
+ (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ Additionally, replaced
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim) with
+ attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) / math.sqrt(self.head_dim/2)
+ Finally, this attention layer contributes to tied transformer blocks aimed to increasing compute without increasing model size. Because this
+ layer is tied, un-tied adapters (formally the same as LoRA but used in the base model) modules are added to the q, k, v projectors to increase
+ expressivity with a small memory overhead (see Fig. 2 of https://huggingface.co/papers/2411.15242).
+ """
+
+ def __init__(
+ self,
+ config: Zamba2Config,
+ layer_idx: Optional[int] = None,
+ num_fwd_mem_blocks: Optional[int] = None,
+ block_id: Optional[int] = None,
+ ):
+ super().__init__(config, layer_idx)
+ self.num_fwd_mem_blocks = num_fwd_mem_blocks
+ self.layer_block_map = config.hybrid_layer_ids
+ self.block_id = block_id
+
+ if config.use_shared_attention_adapter:
+ self.linear_q_adapter_list = nn.ModuleList([])
+ self.linear_k_adapter_list = nn.ModuleList([])
+ self.linear_v_adapter_list = nn.ModuleList([])
+
+ for i in range(self.num_fwd_mem_blocks):
+ if i % config.num_mem_blocks == block_id:
+ linear_q_adapter = nn.Sequential(
+ nn.Linear(self.attention_hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, self.attention_hidden_size, bias=False),
+ )
+ linear_k_adapter = nn.Sequential(
+ nn.Linear(self.attention_hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, self.attention_hidden_size, bias=False),
+ )
+ linear_v_adapter = nn.Sequential(
+ nn.Linear(self.attention_hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, self.attention_hidden_size, bias=False),
+ )
+ else:
+ linear_q_adapter = nn.Identity()
+ linear_k_adapter = nn.Identity()
+ linear_v_adapter = nn.Identity()
+ self.linear_q_adapter_list.append(linear_q_adapter)
+ self.linear_k_adapter_list.append(linear_k_adapter)
+ self.linear_v_adapter_list.append(linear_v_adapter)
+
+ self.layer_dic = {value: index for index, value in enumerate(self.layer_block_map)}
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ layer_idx: int,
+ attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ position_embeddings: Optional[tuple[torch.Tensor, torch.Tensor]] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.Tensor, Optional[torch.Tensor], Optional[tuple[torch.Tensor]]]:
+ input_shape = hidden_states.shape[:-1]
+ hidden_shape = (*input_shape, -1, self.head_dim)
+
+ query_states = self.q_proj(hidden_states)
+ key_states = self.k_proj(hidden_states)
+ value_states = self.v_proj(hidden_states)
+ if self.config.use_shared_attention_adapter:
+ adapter_layer_idx = self.layer_dic[layer_idx]
+ query_states = query_states + self.linear_q_adapter_list[adapter_layer_idx](hidden_states)
+ key_states = key_states + self.linear_k_adapter_list[adapter_layer_idx](hidden_states)
+ value_states = value_states + self.linear_v_adapter_list[adapter_layer_idx](hidden_states)
+
+ query_states = query_states.view(hidden_shape).transpose(1, 2)
+ key_states = key_states.view(hidden_shape).transpose(1, 2)
+ value_states = value_states.view(hidden_shape).transpose(1, 2)
+
+ if self.config.use_mem_rope:
+ cos, sin = position_embeddings
+ query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin)
+
+ if past_key_values is not None:
+ key_states, value_states = past_key_values.update(key_states, value_states, layer_idx)
+
+ attention_interface: Callable = eager_attention_forward
+ if self.config._attn_implementation != "eager":
+ attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
+
+ attn_output, attn_weights = attention_interface(
+ self,
+ query_states,
+ key_states,
+ value_states,
+ attention_mask,
+ dropout=0.0 if not self.training else self.attention_dropout,
+ scaling=self.scaling,
+ **kwargs,
+ )
+
+ attn_output = attn_output.reshape(*input_shape, -1).contiguous()
+ attn_output = self.o_proj(attn_output)
+ return attn_output, attn_weights
+
+
+class Zamba2MambaMixer(nn.Module):
+ """
+ Compute ∆, A, B, C, and D the state space parameters and compute the `contextualized_states`.
+ A, D are input independent (see Mamba paper [1] Section 3.5.2 "Interpretation of A" for why A isn't selective)
+ ∆, B, C are input-dependent (this is a key difference between Mamba and the linear time invariant S4,
+ and is why Mamba is called **selective** state spaces)
+ """
+
+ def __init__(self, config: Zamba2Config, layer_idx: Optional[int] = None):
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.ssm_state_size = config.mamba_d_state
+ self.conv_kernel_size = config.mamba_d_conv
+ self.intermediate_size = int(config.mamba_expand * self.hidden_size)
+ self.layer_idx = layer_idx
+ self.use_conv_bias = config.use_conv_bias
+ self.activation = "silu"
+ self.act = nn.SiLU()
+ self.use_mem_eff_path = config.use_mem_eff_path
+
+ self.n_groups = config.mamba_ngroups
+ self.head_dim = config.mamba_headdim
+ self.num_heads = self.config.n_mamba_heads
+ self.chunk_size = config.chunk_size
+
+ self.time_step_limit = config.time_step_limit
+ self.time_step_min = config.time_step_min
+ self.time_step_max = config.time_step_max
+
+ self.conv_dim = self.intermediate_size + 2 * self.n_groups * self.ssm_state_size
+ self.conv1d = nn.Conv1d(
+ in_channels=self.conv_dim,
+ out_channels=self.conv_dim,
+ bias=True,
+ kernel_size=config.mamba_d_conv,
+ groups=self.conv_dim,
+ padding=config.mamba_d_conv - 1,
+ )
+
+ # projection of the input hidden states
+ projection_size = self.intermediate_size + self.conv_dim + self.num_heads
+ self.in_proj = nn.Linear(
+ self.hidden_size,
+ projection_size,
+ bias=config.add_bias_linear,
+ )
+ # selective projection used to make dt, B and C input dependent
+
+ # time step projection (discretization)
+ # instantiate once and copy inv_dt in init_weights of PretrainedModel
+ self.dt_bias = nn.Parameter(torch.ones(self.num_heads))
+
+ # S4D real initialization. These are not discretized!
+ # The core is to load them, compute the discrete states, then write the updated state. Keeps the memory bounded
+ A = torch.arange(1, self.num_heads + 1)
+ self.A_log = nn.Parameter(torch.log(A))
+ self.A_log._no_weight_decay = True
+ self.norm = Zamba2RMSNormGated(
+ self.intermediate_size, group_size=self.intermediate_size // self.n_groups, eps=1e-5
+ )
+ self.D = nn.Parameter(torch.ones(self.num_heads))
+ self.D._no_weight_decay = True
+
+ self.out_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.add_bias_linear)
+
+ if not is_fast_path_available:
+ logger.warning_once(
+ "The fast path is not available because on of `(selective_state_update, causal_conv1d_fn, causal_conv1d_update)`"
+ " is None. Falling back to the naive implementation. To install follow https://github.com/state-spaces/mamba/#installation and"
+ " https://github.com/Dao-AILab/causal-conv1d"
+ )
+
+ def cuda_kernels_forward(
+ self,
+ hidden_states: torch.Tensor,
+ cache_params: Optional[Zamba2HybridDynamicCache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ ):
+ # set up dimensions for reshapes later
+
+ batch_size, seq_len, _ = hidden_states.shape
+ groups_time_state_size = self.n_groups * self.ssm_state_size
+ d_to_remove = 2 * self.intermediate_size + 2 * self.n_groups * self.ssm_state_size + self.num_heads
+
+ # getting projected states from cache if it exists
+ if cache_params is not None and cache_params.has_previous_state:
+ in_projected_states = self.in_proj(hidden_states.squeeze(1)) # (B 2D)
+ d_mlp = (in_projected_states.shape[-1] - d_to_remove) // 2
+ split_projection_dim = [d_mlp, d_mlp, self.intermediate_size, self.conv_dim, self.num_heads]
+ _, _, gate, hidden_states_B_C, dt = torch.split(in_projected_states, split_projection_dim, dim=-1)
+
+ hidden_states_B_C = causal_conv1d_update(
+ hidden_states_B_C,
+ cache_params.conv_states[self.layer_idx],
+ self.conv1d.weight.squeeze(1),
+ self.conv1d.bias,
+ self.activation,
+ )
+
+ hidden_states, B, C = torch.split(
+ hidden_states_B_C,
+ [self.intermediate_size, groups_time_state_size, groups_time_state_size],
+ dim=-1,
+ )
+ A = -torch.exp(self.A_log.float()) # (nheads,)
+
+ A = A[:, None, ...][:, :, None].expand(-1, self.head_dim, self.ssm_state_size).to(dtype=torch.float32)
+ dt = dt[:, :, None].expand(-1, -1, self.head_dim)
+ dt_bias = self.dt_bias[:, None, ...].expand(-1, self.head_dim)
+ D = self.D[:, None, ...].expand(-1, self.head_dim)
+ B = B.view(batch_size, self.n_groups, B.shape[1] // self.n_groups)
+ C = C.view(batch_size, self.n_groups, C.shape[1] // self.n_groups)
+ hidden_states_reshaped = hidden_states.view(batch_size, self.num_heads, self.head_dim)
+ hidden_states = selective_state_update(
+ cache_params.ssm_states[self.layer_idx],
+ hidden_states_reshaped,
+ dt,
+ A,
+ B,
+ C,
+ D,
+ z=None,
+ dt_bias=dt_bias,
+ dt_softplus=True,
+ )
+ hidden_states = hidden_states.view(batch_size, self.num_heads * self.head_dim)
+ hidden_states = self.norm(hidden_states, gate)
+ out = self.out_proj(hidden_states)[:, None, ...]
+ # if no cache is found, calling the kernel
+ else:
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ dtype = hidden_states.dtype
+ hidden_states = (hidden_states * attention_mask[:, :, None]).to(dtype)
+ # 1. Gated MLP's linear projection
+ projected_states = self.in_proj(hidden_states)
+ A = -torch.exp(self.A_log.float()) # (num_heads) or (intermediate_size, state_size)
+ dt_limit_kwargs = {} if self.time_step_limit is None else {"dt_limit": self.time_step_limit}
+ if attention_mask is not None:
+ input_not_masked = torch.all(attention_mask == 1)
+ else:
+ input_not_masked = True
+
+ if self.use_mem_eff_path and self.training and cache_params is None and input_not_masked:
+ out, ssm_state = mamba_split_conv1d_scan_combined(
+ projected_states,
+ self.conv1d.weight.squeeze(1),
+ self.conv1d.bias,
+ self.dt_bias,
+ A,
+ D=self.D,
+ chunk_size=self.chunk_size,
+ seq_idx=None,
+ activation=self.activation,
+ rmsnorm_weight=self.norm.weight,
+ rmsnorm_eps=self.norm.variance_epsilon,
+ outproj_weight=self.out_proj.weight,
+ outproj_bias=self.out_proj.bias,
+ headdim=self.head_dim,
+ ngroups=self.n_groups,
+ norm_before_gate=False,
+ return_final_states=True,
+ **dt_limit_kwargs,
+ )
+
+ else:
+ gate, hidden_states_B_C, time_step = torch.split(
+ projected_states,
+ [self.intermediate_size, self.conv_dim, self.num_heads],
+ dim=-1,
+ )
+
+ # 1D Convolution
+ if cache_params is not None:
+ hidden_states_B_C_t = hidden_states_B_C.transpose(1, 2)
+ conv_state = nn.functional.pad(
+ hidden_states_B_C_t, (self.conv_kernel_size - hidden_states_B_C_t.shape[-1], 0)
+ )
+ cache_params.conv_states[self.layer_idx].copy_(conv_state)
+ if causal_conv1d_fn is None or self.activation not in ["silu", "swish"]:
+ hidden_states_B_C = self.act(
+ self.conv1d(hidden_states_B_C.transpose(1, 2)).transpose(1, 2)[:, :seq_len]
+ ) # (B, L, self.d_inner + 2 * ngroups * d_state)
+ else:
+ hidden_states_B_C = causal_conv1d_fn(
+ x=hidden_states_B_C.transpose(1, 2),
+ weight=self.conv1d.weight.squeeze(1),
+ bias=self.conv1d.bias,
+ activation=self.activation,
+ ).transpose(1, 2)[:, :seq_len]
+ hidden_states, B, C = torch.split(
+ hidden_states_B_C,
+ [self.intermediate_size, groups_time_state_size, groups_time_state_size],
+ dim=-1,
+ )
+ if attention_mask is not None and not torch.all(attention_mask == 1):
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ dtype = hidden_states.dtype
+ hidden_states = (hidden_states * attention_mask[:, :, None]).to(dtype)
+ scan_output, ssm_state = mamba_chunk_scan_combined(
+ hidden_states.view(batch_size, seq_len, -1, self.head_dim),
+ time_step,
+ A,
+ B.view(batch_size, seq_len, self.n_groups, -1),
+ C.view(batch_size, seq_len, self.n_groups, -1),
+ chunk_size=self.chunk_size,
+ D=self.D,
+ z=None,
+ seq_idx=None,
+ return_final_states=True,
+ dt_bias=self.dt_bias,
+ dt_softplus=True,
+ **dt_limit_kwargs,
+ )
+ if ssm_state is not None and cache_params is not None:
+ cache_params.ssm_states[self.layer_idx].copy_(ssm_state)
+ scan_output = scan_output.view(batch_size, seq_len, -1)
+ # Multiply "gate" branch and apply extra normalization layer
+ scan_output = self.norm(scan_output, gate)
+ out = self.out_proj(scan_output)
+ return out
+
+ # fmt: off
+ def torch_forward(self, input_states, cache_params: Optional[Zamba2HybridDynamicCache]=None, attention_mask: Optional[torch.Tensor]=None):
+ batch_size, seq_len, _ = input_states.shape
+ dtype = input_states.dtype
+ # Gated MLP's linear projection
+ if cache_params is not None and cache_params.has_previous_state:
+ projected_states = self.in_proj(input_states.squeeze(1))
+ else:
+ if attention_mask is not None and not torch.all(attention_mask==1):
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ input_states = (input_states * attention_mask[:, :, None]).to(dtype)
+ projected_states = self.in_proj(input_states)
+ d_mlp = (projected_states.shape[-1] - 2 * self.intermediate_size - 2 * self.n_groups * self.ssm_state_size- self.num_heads) // 2
+ _, _, gate, hidden_states, dt = projected_states.split(
+ [d_mlp, d_mlp, self.intermediate_size, self.conv_dim, self.num_heads], dim=-1
+ )
+
+ # Convolution sequence transformation
+ if cache_params is not None:
+ ssm_state = cache_params.ssm_states[self.layer_idx].clone()
+ ssm_state = ssm_state.to(hidden_states.device)
+ if cache_params.has_previous_state:
+ gate = gate.unsqueeze(1)
+ conv_state = cache_params.conv_states[self.layer_idx] # [batch, intermediate_size, conv_kernel_size]
+ conv_state = torch.roll(conv_state, shifts=-1, dims=-1)
+ # handle batched generation - states are copied through
+ conv_state[:, :, -1] = hidden_states[:, 0, :] if hidden_states.ndim == 3 else hidden_states
+ cache_params.conv_states[self.layer_idx].copy_(conv_state)
+ hidden_states = torch.sum(conv_state.to(projected_states.device) * self.conv1d.weight[:, 0, :], dim=-1)
+ if self.use_conv_bias:
+ hidden_states += self.conv1d.bias
+ hidden_states = self.act(hidden_states).to(dtype)[:, None, ...] # [batch, 1, intermediate_size] : decoding
+ else:
+ hidden_states = hidden_states.transpose(1,2)
+ conv_state = nn.functional.pad(
+ hidden_states,
+ (self.conv_kernel_size - hidden_states.shape[-1], 0)
+ )
+ cache_params.conv_states[self.layer_idx].copy_(conv_state)
+ hidden_states = self.act(self.conv1d(hidden_states).transpose(1,2))[:, :seq_len, :] # [batch, intermediate_size, seq_len]
+ if attention_mask is not None and not torch.all(attention_mask==1):
+ dtype = hidden_states.dtype
+ # tune out hidden states for pad tokens, see https://github.com/state-spaces/mamba/issues/66
+ hidden_states = (hidden_states * attention_mask[:, :, None]).to(dtype)
+ else:
+ ssm_state = torch.zeros(
+ (batch_size, self.num_heads, self.head_dim, self.ssm_state_size),
+ device=hidden_states.device, dtype=dtype
+ )
+ hidden_states = self.act(self.conv1d(hidden_states.transpose(1, 2))[..., :seq_len].transpose(1, 2))
+ hidden_states, B, C = torch.split(hidden_states, [self.intermediate_size, self.n_groups * self.ssm_state_size, self.n_groups * self.ssm_state_size], dim=-1)
+ A = -torch.exp(self.A_log.float()) # [num_heads]
+ if cache_params is not None and cache_params.has_previous_state:
+ # Note: there is no need to pad parameter matrices here, as there is just one new token
+ # for batched generation
+ dt = dt[:, None, ...] if dt.ndim == 2 else dt[:, 0, :][:, None, ...]
+ dt = dt.transpose(1, 2).expand(batch_size, dt.shape[-1], self.head_dim)
+ # [num_heads] -> [num_heads, head_dim]
+ dt_bias = self.dt_bias[..., None].expand(self.dt_bias.shape[0], self.head_dim)
+
+ dt = torch.nn.functional.softplus(dt + dt_bias.to(dt.dtype))
+ dt = torch.clamp(dt, self.time_step_min) #, self.time_step_max)
+ A = A[..., None, None].expand(self.num_heads, self.head_dim, self.ssm_state_size).to(dtype=torch.float32)
+ # [bsz, num_heads, head_dim, state_size]
+ dA = torch.exp(dt[..., None] * A)
+
+ # Discretize B
+ # [bsz, n_groups * state_size] -> [bsz, n_groups, 1, state_size] ->
+ # -> [bsz, n_groups, group to head repetition factor, state_size] -> [bsz, num_heads, state_size]
+ B = B.reshape(batch_size, self.n_groups, -1)[..., None, :]
+ B = B.expand(batch_size, self.n_groups, self.num_heads // self.n_groups, B.shape[-1]).contiguous()
+ B = B.reshape(batch_size, -1, B.shape[-1])
+ # [bsz, num_heads, head_dim, state_size]
+ dB = dt[..., None] * B[..., None, :]
+
+ # Discretize x into dB
+ # [bsz, intermediate_size] -> [bsz, num_heads, head_dim]
+ hidden_states = hidden_states.reshape(batch_size, -1, self.head_dim)
+ dBx = dB * hidden_states[..., None]
+
+ # State calculation
+ cache_params.ssm_states[self.layer_idx].copy_(
+ cache_params.ssm_states[self.layer_idx] * dA + dBx
+ )
+
+ # Subsequent output
+ # [bsz, n_groups * state_size] -> [bsz, num_heads, state_size]
+ C = C.reshape(batch_size, self.n_groups, -1)[..., None, :]
+ C = C.expand(batch_size, self.n_groups, self.num_heads // self.n_groups, C.shape[-1]).contiguous()
+ C = C.reshape(batch_size, -1, C.shape[-1])
+ # [bsz, num_heads, head_dim]
+
+ ssm_states = cache_params.ssm_states[self.layer_idx].to(C.dtype) # Shape: [b, h, d, n]
+ # Reshape ssm_states to merge the first two dimensions
+ ssm_states_reshaped = ssm_states.view(batch_size * self.num_heads, self.head_dim, self.ssm_state_size) # Shape: [b*h, d, n]
+ C_reshaped = C.view(batch_size * self.num_heads, self.ssm_state_size, 1) # Shape: [b*h, n, 1]
+ y = torch.bmm(ssm_states_reshaped, C_reshaped)
+ y = y.view(batch_size, self.num_heads, self.head_dim)
+
+ # D skip connection
+ # [num_heads] -> [num_heads, head_dim]
+ D = self.D[..., None].expand(self.D.shape[0], self.head_dim)
+ y = (y + hidden_states * D).to(y.dtype)
+
+ # [bsz, num_heads, head_dim] -> [bsz, 1, intermediate_size]
+ y = y.reshape(batch_size, -1)[:, None, ...]
+ else:
+ # begin ssd naive implementation without einsums
+ dt = nn.functional.softplus(dt + self.dt_bias)
+ dt = torch.clamp(dt, self.time_step_min)
+ hidden_states = hidden_states.reshape(batch_size, seq_len, -1, self.head_dim).float()
+ B = B.reshape(batch_size, seq_len, -1, self.ssm_state_size).float()
+ C = C.reshape(batch_size, seq_len, -1, self.ssm_state_size).float()
+ B = B.repeat_interleave(self.num_heads // self.n_groups, dim=2, output_size=self.num_heads)
+ C = C.repeat_interleave(self.num_heads // self.n_groups, dim=2, output_size=self.num_heads)
+ pad_size = (self.chunk_size - seq_len % self.chunk_size) % self.chunk_size
+
+ D_residual = self.D[..., None] * pad_tensor_by_size(hidden_states, pad_size)
+
+ # Discretize x and A
+ hidden_states = hidden_states * dt[..., None]
+ A = A.to(hidden_states.dtype) * dt
+
+ # Rearrange into blocks/chunks
+ hidden_states, A, B, C = [reshape_into_chunks(t, pad_size, self.chunk_size) for t in (hidden_states, A, B, C)]
+
+
+ # [bsz, -1, chunk_size, num_heads] -> [bsz, num_heads, -1, chunk_size]
+ A = A.permute(0, 3, 1, 2)
+ A_cumsum = torch.cumsum(A, dim=-1)
+
+ # 1. Compute the output for each intra-chunk (diagonal blocks)
+ # This is the analog of a causal mask
+ L = torch.exp(segment_sum(A))
+
+ # First, contraction of C and B to get G (attention-weights like)
+ G_intermediate = C[:, :, :, None, :, :] * B[:, :, None, :, : ,:] # shape: (b, c, l, s, h, n)
+ G = G_intermediate.sum(dim=-1) # shape: (b, c, l, s, h)
+
+
+ # Step 2: Compute M, equivalent to applying attention mask to weights
+ M_intermediate = G[..., None] * L.permute(0, 2, 3, 4, 1)[..., None]
+ M = M_intermediate.sum(dim=-1)
+
+ # Step 3: Compute Y_diag (apply to values)
+ Y_diag = (M[..., None] * hidden_states[:, :, None]).sum(3)
+
+ # (right term of low-rank factorization of off-diagonal blocks; B terms)
+
+ decay_states = torch.exp(A_cumsum[:, :, :, -1:] - A_cumsum)
+ B_decay_contraction = B * decay_states.permute(0, 2, 3, 1)[..., None]
+ # permute back B * decay states
+ states = (B_decay_contraction.permute(0, 1, 3, 2, 4)[..., None] * hidden_states.permute(0, 1, 3, 2, 4)[..., None, :]).sum(dim=3).permute(0, 1, 2, 4, 3)
+ if cache_params is not None and cache_params.has_previous_state:
+ previous_states = cache_params.ssm_states[self.layer_idx][:, None, ...]
+ else:
+ previous_states = torch.zeros_like(states[:, :1])
+ states = torch.cat([previous_states, states], dim=1)
+ decay_chunk = torch.exp(segment_sum(nn.functional.pad(A_cumsum[:, :, :, -1], (1, 0))))
+
+ states_permuted = states.permute(0, 2, 1, 3, 4)
+ result = (decay_chunk[..., None, None] * states_permuted[:, :, None, ...]).sum(dim=2)
+ new_states = result.permute(0, 2, 1, 3, 4)
+ states, ssm_state = new_states[:, :-1], new_states[:, -1]
+
+ # Compute state -> output conversion per chunk
+ # (left term of low-rank factorization of off-diagonal blocks; C terms)
+ state_decay_out = torch.exp(A_cumsum)
+ # compute Yoff
+ C_times_states = (C[..., None, :] * states[:, :, None, ...])
+ state_decay_out_permuted = state_decay_out.permute(0, 2, 3, 1)
+ Y_off = (C_times_states.sum(-1) * state_decay_out_permuted[..., None])
+ # Add output of intra-chunk and inter-chunk terms (diagonal and off-diagonal blocks)
+
+ y = Y_diag + Y_off
+ # [bsz, -1, self.chunk_size, num_heads, head_dim] -> [bsz, (padded) seq_len, num_heads, head_dim]
+ y = y.reshape(batch_size, -1, self.num_heads, self.head_dim)
+
+ y = y + D_residual
+ # Cutting off padded chunks
+ if pad_size > 0:
+ y = y[:, :seq_len, :, :]
+ y = y.reshape(batch_size, seq_len, -1)
+ if ssm_state is not None and cache_params is not None:
+ cache_params.ssm_states[self.layer_idx].copy_(ssm_state)
+
+ scan_output = self.norm(y, gate)
+
+ # end ssd naive
+
+ # 4. Final linear projection
+ contextualized_states = self.out_proj(scan_output.to(dtype)) # [batch, seq_len, hidden_size]
+ return contextualized_states
+ # fmt: on
+
+ def forward(
+ self,
+ hidden_states,
+ cache_params: Optional[Zamba2HybridDynamicCache] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ ):
+ if is_fast_path_available and "cuda" in self.in_proj.weight.device.type:
+ return self.cuda_kernels_forward(hidden_states, cache_params, attention_mask)
+
+ return self.torch_forward(hidden_states, cache_params, attention_mask)
+
+
+class Zamba2MLP(nn.Module):
+ def __init__(self, config: Zamba2Config, num_fwd_mem_blocks=None, block_id: Optional[int] = None):
+ """
+ This MLP layer contributes to tied transformer blocks aimed to increasing compute without increasing model size. Because this layer
+ is tied, un-tied adapter modules (formally same as LoRA, but used in the base model) are added to the up and gate projectors to increase expressivity with a small memory overhead.
+ """
+ super().__init__()
+ self.config = config
+ self.hidden_size = config.hidden_size
+ self.intermediate_size = config.intermediate_size
+ self.num_fwd_mem_blocks = num_fwd_mem_blocks
+ self.block_id = block_id
+
+ self.gate_up_proj = nn.Linear(self.hidden_size, 2 * self.intermediate_size, bias=config.add_bias_linear)
+ self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.add_bias_linear)
+ self.act_fn = ACT2FN[config.hidden_act]
+
+ self.gate_up_proj_adapter_list = nn.ModuleList([])
+ for i in range(self.num_fwd_mem_blocks):
+ if i % config.num_mem_blocks == block_id:
+ gate_up_proj_adapter = nn.Sequential(
+ nn.Linear(self.config.hidden_size, self.config.adapter_rank, bias=False),
+ nn.Linear(self.config.adapter_rank, 2 * self.intermediate_size, bias=False),
+ )
+ else:
+ gate_up_proj_adapter = nn.Identity()
+ self.gate_up_proj_adapter_list.append(gate_up_proj_adapter)
+
+ layer_block_map = config.hybrid_layer_ids
+ self.layer_dic = {value: index for index, value in enumerate(layer_block_map)}
+
+ def forward(self, hidden_state, layer_idx=None):
+ gate_up_state = self.gate_up_proj(hidden_state)
+ layer_idx = self.layer_dic[layer_idx]
+ gate_up_state = gate_up_state + self.gate_up_proj_adapter_list[layer_idx](hidden_state)
+
+ gate_up_state = torch.chunk(gate_up_state, 2, dim=-1)
+ hidden_state = self.act_fn(gate_up_state[0]) * gate_up_state[1]
+ output = self.down_proj(hidden_state)
+ return output
+
+
+class Zamba2AttentionDecoderLayer(ZambaAttentionDecoderLayer):
+ def __init__(self, config: Zamba2Config, block_id: Optional[int] = None, layer_idx: Optional[int] = None):
+ self.block_id = block_id
+ num_gs = len(config.hybrid_layer_ids)
+ super().__init__(config, layer_idx)
+ self.self_attn = Zamba2Attention(config, layer_idx=-1, num_fwd_mem_blocks=num_gs, block_id=block_id)
+ self.feed_forward = Zamba2MLP(config, num_fwd_mem_blocks=num_gs, block_id=block_id)
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: torch.Tensor,
+ layer_idx: int,
+ attention_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ position_embeddings: Optional[torch.LongTensor] = None,
+ **kwargs: Unpack[FlashAttentionKwargs],
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): output of previous Mamba layer of shape `(batch, seq_len, embed_dim)`
+ original_hidden_states (`torch.FloatTensor`): word embedding output of shape `(batch, seq_len, embed_dim)`.
+ This is concatenated with `hidden_states` (which is the output of the previous (mamba) layer). The
+ concatenated tensor is then used as input of the pre-attention RMSNorm
+ (see fig. 2 in https://huggingface.co/papers/2405.16712).
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`Zamba2HybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*):
+ Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`,
+ with `head_dim` being the embedding dimension of each attention head.
+ """
+ hidden_states = torch.concatenate([hidden_states, original_hidden_states], dim=-1)
+ hidden_states = self.input_layernorm(hidden_states)
+ hidden_states, self_attn_weights = self.self_attn(
+ hidden_states=hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ position_embeddings=position_embeddings,
+ **kwargs,
+ )
+
+ hidden_states = self.pre_ff_layernorm(hidden_states)
+ hidden_states = self.feed_forward(hidden_states, layer_idx)
+
+ outputs = (hidden_states,)
+
+ if output_attentions:
+ outputs += (self_attn_weights,)
+
+ return outputs
+
+
+class Zamba2MambaDecoderLayer(ZambaMambaDecoderLayer):
+ def __init__(self, config: Zamba2Config, layer_idx: int):
+ super().__init__(config, layer_idx)
+ self.mamba = Zamba2MambaMixer(config=config, layer_idx=layer_idx)
+ self.input_layernorm = Zamba2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+
+
+class Zamba2HybridLayer(ZambaHybridLayer):
+ def __init__(
+ self, shared_transformer: Zamba2AttentionDecoderLayer, linear: nn.Linear, mamba: Zamba2MambaDecoderLayer
+ ):
+ super().__init__(shared_transformer, linear, mamba)
+ del self.shared_transf
+ self.shared_transformer = shared_transformer
+
+ @deprecate_kwarg("past_key_value", new_name="past_key_values", version="4.58")
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ original_hidden_states: Optional[torch.Tensor] = None,
+ layer_idx: Optional[int] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ causal_mask: Optional[torch.Tensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ output_attentions: Optional[bool] = False,
+ use_cache: Optional[bool] = False,
+ position_embeddings: Optional[torch.LongTensor] = None,
+ ) -> tuple[torch.FloatTensor, Optional[tuple[torch.FloatTensor, torch.FloatTensor]]]:
+ """
+ Args:
+ hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)`
+ original_hidden_states (`torch.FloatTensor`): word embedding output that will be concatenated with
+ hidden activations to form the input of the shared transformer layer.
+ layer_idx (`int`): layer number.
+ attention_mask (`torch.FloatTensor`, *optional*): attention mask of size
+ `(batch, sequence_length)` where padding elements are indicated by 0.
+ past_key_values (`Zamba2HybridDynamicCache`, *optional*): cached past key and value projection states
+ output_attentions (`bool`, *optional*):
+ Whether or not to return the attentions tensors of all attention layers. See `attentions` under
+ returned tensors for more detail.
+ use_cache (`bool`, *optional*):
+ If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding
+ (see `past_key_values`).
+ position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*):
+ Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`,
+ with `head_dim` being the embedding dimension of each attention head.
+ """
+
+ layer_outputs = self.shared_transformer(
+ hidden_states,
+ original_hidden_states=original_hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=causal_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ position_embeddings=position_embeddings,
+ )
+
+ transformer_hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ self_attn_weights = layer_outputs[1]
+
+ transformer_hidden_states = self.linear(transformer_hidden_states)
+
+ layer_outputs = self.mamba_decoder(
+ hidden_states,
+ transformer_hidden_states=transformer_hidden_states,
+ attention_mask=attention_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ position_embeddings=position_embeddings,
+ )
+
+ if output_attentions:
+ layer_outputs = (layer_outputs[0], self_attn_weights) + layer_outputs[2:]
+
+ return layer_outputs
+
+
+class Zamba2PreTrainedModel(PreTrainedModel):
+ config: Zamba2Config
+ base_model_prefix = "model"
+ supports_gradient_checkpointing = True
+ _no_split_modules = ["Zamba2AttentionDecoderLayer", "Zamba2MambaDecoderLayer"]
+ _skip_keys_device_placement = "past_key_values"
+ _supports_flash_attn = True
+ _supports_flex_attn = True
+ _supports_sdpa = True
+ # Note: only supports Zamba2HybridDynamicCache
+ _is_stateful = True
+
+ def _init_weights(self, module):
+ super()._init_weights(module)
+ if isinstance(module, Zamba2MambaMixer):
+ dt = torch.exp(
+ torch.rand(self.config.n_mamba_heads)
+ * (math.log(self.config.time_step_max) - math.log(self.config.time_step_min))
+ + math.log(self.config.time_step_min)
+ ).clamp(min=self.config.time_step_floor)
+ # # Inverse of softplus: https://github.com/pytorch/pytorch/issues/72759
+ inv_dt = dt + torch.log(-torch.expm1(-dt))
+ module.dt_bias.data.copy_(inv_dt)
+
+ A = torch.arange(1, module.num_heads + 1)
+ module.A_log.data.copy_(torch.log(A))
+ module.D.data.fill_(1.0)
+
+
+class Zamba2Model(ZambaModel, Zamba2PreTrainedModel):
+ """
+ Model consisting of *config.num_hidden_layers* layers.
+
+ Args:
+ config: Zamba2Config
+ """
+
+ def __init__(self, config: Zamba2Config):
+ Zamba2PreTrainedModel.__init__(self, config)
+ self.config = config
+ self.padding_idx = config.pad_token_id
+ self.vocab_size = config.vocab_size
+
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx)
+ blocks = [Zamba2AttentionDecoderLayer(config, block_id=k) for k in range(config.num_mem_blocks)]
+ mamba_layers = []
+ linear_layers = []
+ self.layers_block_type = config.layers_block_type
+ for i in range(config.num_hidden_layers):
+ if config.layers_block_type[i] == "mamba":
+ mamba_layers.append(Zamba2MambaDecoderLayer(config, layer_idx=i))
+ elif config.layers_block_type[i] == "hybrid":
+ linear_layers.append(nn.Linear(self.config.hidden_size, self.config.hidden_size, bias=False))
+ mamba_layers.append(Zamba2MambaDecoderLayer(config, layer_idx=i))
+ mamba_layers = iter(mamba_layers)
+ linear_layers = iter(linear_layers)
+ blocks = cycle(blocks)
+ layers = self.get_layers(blocks, linear_layers, mamba_layers)
+ self.layers = nn.ModuleList(layers)
+
+ self._attn_implementation = config._attn_implementation
+ self.final_layernorm = Zamba2RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
+ if config.use_mem_rope:
+ if config.use_long_context:
+ logger.warning_once(
+ "`use_long_context` set to `True`: using rescaled `rope_theta` and extended `max_position_embeddings`."
+ )
+ self.rotary_emb = Zamba2RotaryEmbedding(config)
+ self.gradient_checkpointing = False
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ def get_layers(self, blocks, linear_layers, mamba_layers):
+ layers = []
+ self._tied_weights_keys = []
+ self.first_transformer_layer_id = 0
+ for layer_id, layer_type in enumerate(self.layers_block_type):
+ if layer_type == "hybrid":
+ if self.first_transformer_layer_id == 0:
+ self.first_transformer_layer_id = layer_id
+ block = next(blocks)
+ if self.config.num_mem_blocks * len(self.config.hybrid_layer_ids) > 1:
+ prefix_pattern = rf"^layers\.{layer_id}\.shared_transformer\."
+ main_keys_pattern = re.compile(
+ prefix_pattern
+ + r"(?:"
+ + r"self_attn\.(?:q_proj|k_proj|v_proj|o_proj)\.weight|"
+ + r"feed_forward\.(?:gate_up_proj|down_proj)\.weight|"
+ + r"(?:input_layernorm|pre_ff_layernorm)\.weight"
+ + r")$"
+ )
+ self._tied_weights_keys.append(main_keys_pattern)
+
+ adapter_id = 0
+ for _layer_type in self.layers_block_type:
+ if _layer_type == "hybrid" and adapter_id % self.config.num_mem_blocks == block.block_id:
+ adapter_pattern = re.compile(
+ r"^shared_transformer\.feed_forward\.gate_up_proj_adapter_list\."
+ + str(adapter_id)
+ + r"\.(?:0|1)\.weight$"
+ )
+ self._tied_weights_keys.append(adapter_pattern)
+ adapter_id += 1
+ if self.config.use_shared_attention_adapter:
+ adapter_id = 0
+ for _layer_type in self.layers_block_type:
+ if _layer_type == "hybrid" and adapter_id % self.config.num_mem_blocks == block.block_id:
+ attn_adapter_pattern = re.compile(
+ r"^shared_transformer\.self_attn\."
+ + r"(?:linear_q_adapter_list|linear_k_adapter_list|linear_v_adapter_list)\."
+ + str(adapter_id)
+ + r"\.(?:0|1)\.weight$"
+ )
+ self._tied_weights_keys.append(attn_adapter_pattern)
+ adapter_id += 1
+ layers.append(Zamba2HybridLayer(block, next(linear_layers), next(mamba_layers)))
+ else:
+ layers.append(next(mamba_layers))
+ return layers
+
+ def forward(
+ self,
+ input_ids: Optional[torch.LongTensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ position_ids: Optional[torch.LongTensor] = None,
+ past_key_values: Optional[Zamba2HybridDynamicCache] = None,
+ inputs_embeds: Optional[torch.FloatTensor] = None,
+ use_cache: Optional[bool] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ cache_position: Optional[torch.LongTensor] = None,
+ ) -> Union[tuple, BaseModelOutputWithPast]:
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ use_cache = use_cache if use_cache is not None else self.config.use_cache
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if (input_ids is None) ^ (inputs_embeds is not None):
+ raise ValueError(
+ "You cannot specify both input_ids and inputs_embeds at the same time, and must specify either one"
+ )
+
+ if self.gradient_checkpointing and self.training and use_cache:
+ logger.warning_once(
+ "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`."
+ )
+ use_cache = False
+
+ if inputs_embeds is None:
+ inputs_embeds = self.embed_tokens(input_ids)
+
+ hidden_states = inputs_embeds
+
+ original_hidden_states = torch.clone(inputs_embeds)
+ # original_hidden_states: word embedding output that will be concatenated with hidden activations to form the input of the shared transformer layer
+
+ if use_cache and past_key_values is None:
+ batch_size = input_ids.shape[0] if input_ids is not None else inputs_embeds.shape[0]
+ past_key_values = Zamba2HybridDynamicCache(self.config, batch_size, dtype=self.dtype, device=self.device)
+
+ if cache_position is None:
+ past_seen_tokens = (
+ past_key_values.get_seq_length(layer_idx=self.first_transformer_layer_id)
+ if past_key_values is not None
+ else 0
+ )
+ cache_position = torch.arange(
+ past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device
+ )
+ if position_ids is None:
+ position_ids = cache_position.unsqueeze(0)
+
+ causal_mask = self._update_causal_mask(attention_mask, inputs_embeds, cache_position)
+
+ # create position embeddings to be shared across the decoder layers
+ if self.config.use_mem_rope:
+ position_embeddings = self.rotary_emb(hidden_states, position_ids)
+ else:
+ position_embeddings = None
+
+ all_hidden_states = () if output_hidden_states else None
+ all_self_attns = () if output_attentions else None
+
+ for layer_idx, layer in enumerate(self.layers):
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if self.gradient_checkpointing and self.training:
+ layer_outputs = self._gradient_checkpointing_func(
+ layer.__call__,
+ hidden_states,
+ original_hidden_states,
+ layer_idx,
+ attention_mask,
+ causal_mask,
+ past_key_values,
+ output_attentions,
+ use_cache,
+ position_embeddings,
+ )
+ else:
+ layer_outputs = layer(
+ hidden_states,
+ original_hidden_states=original_hidden_states,
+ layer_idx=layer_idx,
+ attention_mask=attention_mask,
+ causal_mask=causal_mask,
+ past_key_values=past_key_values,
+ output_attentions=output_attentions,
+ use_cache=use_cache,
+ position_embeddings=position_embeddings,
+ )
+ hidden_states = layer_outputs[0]
+
+ if output_attentions:
+ if layer_outputs[1] is not None:
+ # append attentions only of attention layers. Mamba layers return `None` as the attention weights
+ all_self_attns += (layer_outputs[1],)
+
+ hidden_states = self.final_layernorm(hidden_states)
+
+ # add hidden states from the last decoder layer
+ if output_hidden_states:
+ all_hidden_states += (hidden_states,)
+
+ if past_key_values is not None and not past_key_values.has_previous_state:
+ past_key_values.has_previous_state = True
+
+ output = BaseModelOutputWithPast(
+ last_hidden_state=hidden_states,
+ past_key_values=past_key_values if use_cache else None,
+ hidden_states=all_hidden_states,
+ attentions=all_self_attns,
+ )
+ return output if return_dict else output.to_tuple()
+
+
+class Zamba2ForCausalLM(ZambaForCausalLM):
+ pass
+
+
+class Zamba2ForSequenceClassification(ZambaForSequenceClassification):
+ pass
+
+
+__all__ = [
+ "Zamba2ForCausalLM",
+ "Zamba2ForSequenceClassification",
+ "Zamba2Model",
+ "Zamba2PreTrainedModel",
+]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..abc436fa801f8d7f8cf0e6f44504b33f528131ec
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/__init__.py
@@ -0,0 +1,29 @@
+# Copyright 2024 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from typing import TYPE_CHECKING
+
+from ...utils import _LazyModule
+from ...utils.import_utils import define_import_structure
+
+
+if TYPE_CHECKING:
+ from .configuration_zoedepth import *
+ from .image_processing_zoedepth import *
+ from .image_processing_zoedepth_fast import *
+ from .modeling_zoedepth import *
+else:
+ import sys
+
+ _file = globals()["__file__"]
+ sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/configuration_zoedepth.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/configuration_zoedepth.py
new file mode 100644
index 0000000000000000000000000000000000000000..ac89f815f82cca720838257c190bfd0bb034d60d
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/configuration_zoedepth.py
@@ -0,0 +1,245 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""ZoeDepth model configuration"""
+
+from ...configuration_utils import PretrainedConfig
+from ...utils import logging
+from ..auto.configuration_auto import CONFIG_MAPPING
+
+
+logger = logging.get_logger(__name__)
+
+ZOEDEPTH_PRETRAINED_CONFIG_ARCHIVE_MAP = {
+ "Intel/zoedepth-nyu": "https://huggingface.co/Intel/zoedepth-nyu/resolve/main/config.json",
+}
+
+
+class ZoeDepthConfig(PretrainedConfig):
+ r"""
+ This is the configuration class to store the configuration of a [`ZoeDepthForDepthEstimation`]. It is used to instantiate an ZoeDepth
+ model according to the specified arguments, defining the model architecture. Instantiating a configuration with the
+ defaults will yield a similar configuration to that of the ZoeDepth
+ [Intel/zoedepth-nyu](https://huggingface.co/Intel/zoedepth-nyu) architecture.
+
+ Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
+ documentation from [`PretrainedConfig`] for more information.
+
+ Args:
+ backbone_config (`Union[dict[str, Any], PretrainedConfig]`, *optional*, defaults to `BeitConfig()`):
+ The configuration of the backbone model.
+ backbone (`str`, *optional*):
+ Name of backbone to use when `backbone_config` is `None`. If `use_pretrained_backbone` is `True`, this
+ will load the corresponding pretrained weights from the timm or transformers library. If `use_pretrained_backbone`
+ is `False`, this loads the backbone's config and uses that to initialize the backbone with random weights.
+ use_pretrained_backbone (`bool`, *optional*, defaults to `False`):
+ Whether to use pretrained weights for the backbone.
+ backbone_kwargs (`dict`, *optional*):
+ Keyword arguments to be passed to AutoBackbone when loading from a checkpoint
+ e.g. `{'out_indices': (0, 1, 2, 3)}`. Cannot be specified if `backbone_config` is set.
+ hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`):
+ The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`,
+ `"relu"`, `"selu"` and `"gelu_new"` are supported.
+ initializer_range (`float`, *optional*, defaults to 0.02):
+ The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
+ batch_norm_eps (`float`, *optional*, defaults to 1e-05):
+ The epsilon used by the batch normalization layers.
+ readout_type (`str`, *optional*, defaults to `"project"`):
+ The readout type to use when processing the readout token (CLS token) of the intermediate hidden states of
+ the ViT backbone. Can be one of [`"ignore"`, `"add"`, `"project"`].
+
+ - "ignore" simply ignores the CLS token.
+ - "add" passes the information from the CLS token to all other tokens by adding the representations.
+ - "project" passes information to the other tokens by concatenating the readout to all other tokens before
+ projecting the
+ representation to the original feature dimension D using a linear layer followed by a GELU non-linearity.
+ reassemble_factors (`list[int]`, *optional*, defaults to `[4, 2, 1, 0.5]`):
+ The up/downsampling factors of the reassemble layers.
+ neck_hidden_sizes (`list[str]`, *optional*, defaults to `[96, 192, 384, 768]`):
+ The hidden sizes to project to for the feature maps of the backbone.
+ fusion_hidden_size (`int`, *optional*, defaults to 256):
+ The number of channels before fusion.
+ head_in_index (`int`, *optional*, defaults to -1):
+ The index of the features to use in the heads.
+ use_batch_norm_in_fusion_residual (`bool`, *optional*, defaults to `False`):
+ Whether to use batch normalization in the pre-activate residual units of the fusion blocks.
+ use_bias_in_fusion_residual (`bool`, *optional*, defaults to `True`):
+ Whether to use bias in the pre-activate residual units of the fusion blocks.
+ num_relative_features (`int`, *optional*, defaults to 32):
+ The number of features to use in the relative depth estimation head.
+ add_projection (`bool`, *optional*, defaults to `False`):
+ Whether to add a projection layer before the depth estimation head.
+ bottleneck_features (`int`, *optional*, defaults to 256):
+ The number of features in the bottleneck layer.
+ num_attractors (`list[int], *optional*, defaults to `[16, 8, 4, 1]`):
+ The number of attractors to use in each stage.
+ bin_embedding_dim (`int`, *optional*, defaults to 128):
+ The dimension of the bin embeddings.
+ attractor_alpha (`int`, *optional*, defaults to 1000):
+ The alpha value to use in the attractor.
+ attractor_gamma (`int`, *optional*, defaults to 2):
+ The gamma value to use in the attractor.
+ attractor_kind (`str`, *optional*, defaults to `"mean"`):
+ The kind of attractor to use. Can be one of [`"mean"`, `"sum"`].
+ min_temp (`float`, *optional*, defaults to 0.0212):
+ The minimum temperature value to consider.
+ max_temp (`float`, *optional*, defaults to 50.0):
+ The maximum temperature value to consider.
+ bin_centers_type (`str`, *optional*, defaults to `"softplus"`):
+ Activation type used for bin centers. Can be "normed" or "softplus". For "normed" bin centers, linear normalization trick
+ is applied. This results in bounded bin centers. For "softplus", softplus activation is used and thus are unbounded.
+ bin_configurations (`list[dict]`, *optional*, defaults to `[{'n_bins': 64, 'min_depth': 0.001, 'max_depth': 10.0}]`):
+ Configuration for each of the bin heads.
+ Each configuration should consist of the following keys:
+ - name (`str`): The name of the bin head - only required in case of multiple bin configurations.
+ - `n_bins` (`int`): The number of bins to use.
+ - `min_depth` (`float`): The minimum depth value to consider.
+ - `max_depth` (`float`): The maximum depth value to consider.
+ In case only a single configuration is passed, the model will use a single head with the specified configuration.
+ In case multiple configurations are passed, the model will use multiple heads with the specified configurations.
+ num_patch_transformer_layers (`int`, *optional*):
+ The number of transformer layers to use in the patch transformer. Only used in case of multiple bin configurations.
+ patch_transformer_hidden_size (`int`, *optional*):
+ The hidden size to use in the patch transformer. Only used in case of multiple bin configurations.
+ patch_transformer_intermediate_size (`int`, *optional*):
+ The intermediate size to use in the patch transformer. Only used in case of multiple bin configurations.
+ patch_transformer_num_attention_heads (`int`, *optional*):
+ The number of attention heads to use in the patch transformer. Only used in case of multiple bin configurations.
+
+ Example:
+
+ ```python
+ >>> from transformers import ZoeDepthConfig, ZoeDepthForDepthEstimation
+
+ >>> # Initializing a ZoeDepth zoedepth-large style configuration
+ >>> configuration = ZoeDepthConfig()
+
+ >>> # Initializing a model from the zoedepth-large style configuration
+ >>> model = ZoeDepthForDepthEstimation(configuration)
+
+ >>> # Accessing the model configuration
+ >>> configuration = model.config
+ ```"""
+
+ model_type = "zoedepth"
+
+ def __init__(
+ self,
+ backbone_config=None,
+ backbone=None,
+ use_pretrained_backbone=False,
+ backbone_kwargs=None,
+ hidden_act="gelu",
+ initializer_range=0.02,
+ batch_norm_eps=1e-05,
+ readout_type="project",
+ reassemble_factors=[4, 2, 1, 0.5],
+ neck_hidden_sizes=[96, 192, 384, 768],
+ fusion_hidden_size=256,
+ head_in_index=-1,
+ use_batch_norm_in_fusion_residual=False,
+ use_bias_in_fusion_residual=None,
+ num_relative_features=32,
+ add_projection=False,
+ bottleneck_features=256,
+ num_attractors=[16, 8, 4, 1],
+ bin_embedding_dim=128,
+ attractor_alpha=1000,
+ attractor_gamma=2,
+ attractor_kind="mean",
+ min_temp=0.0212,
+ max_temp=50.0,
+ bin_centers_type="softplus",
+ bin_configurations=[{"n_bins": 64, "min_depth": 0.001, "max_depth": 10.0}],
+ num_patch_transformer_layers=None,
+ patch_transformer_hidden_size=None,
+ patch_transformer_intermediate_size=None,
+ patch_transformer_num_attention_heads=None,
+ **kwargs,
+ ):
+ super().__init__(**kwargs)
+
+ if readout_type not in ["ignore", "add", "project"]:
+ raise ValueError("Readout_type must be one of ['ignore', 'add', 'project']")
+
+ if attractor_kind not in ["mean", "sum"]:
+ raise ValueError("Attractor_kind must be one of ['mean', 'sum']")
+
+ if use_pretrained_backbone:
+ raise ValueError("Pretrained backbones are not supported yet.")
+
+ if backbone_config is not None and backbone is not None:
+ raise ValueError("You can't specify both `backbone` and `backbone_config`.")
+
+ if backbone_config is None and backbone is None:
+ logger.info("`backbone_config` is `None`. Initializing the config with the default `BEiT` backbone.")
+ backbone_config = CONFIG_MAPPING["beit"](
+ image_size=384,
+ num_hidden_layers=24,
+ hidden_size=1024,
+ intermediate_size=4096,
+ num_attention_heads=16,
+ use_relative_position_bias=True,
+ reshape_hidden_states=False,
+ out_features=["stage6", "stage12", "stage18", "stage24"],
+ )
+ elif isinstance(backbone_config, dict):
+ backbone_model_type = backbone_config.get("model_type")
+ config_class = CONFIG_MAPPING[backbone_model_type]
+ backbone_config = config_class.from_dict(backbone_config)
+
+ if backbone_kwargs is not None and backbone_kwargs and backbone_config is not None:
+ raise ValueError("You can't specify both `backbone_kwargs` and `backbone_config`.")
+
+ self.backbone_config = backbone_config
+ self.backbone = backbone
+ self.hidden_act = hidden_act
+ self.use_pretrained_backbone = use_pretrained_backbone
+ self.initializer_range = initializer_range
+ self.batch_norm_eps = batch_norm_eps
+ self.readout_type = readout_type
+ self.reassemble_factors = reassemble_factors
+ self.neck_hidden_sizes = neck_hidden_sizes
+ self.fusion_hidden_size = fusion_hidden_size
+ self.head_in_index = head_in_index
+ self.use_batch_norm_in_fusion_residual = use_batch_norm_in_fusion_residual
+ self.use_bias_in_fusion_residual = use_bias_in_fusion_residual
+ self.num_relative_features = num_relative_features
+ self.add_projection = add_projection
+
+ self.bottleneck_features = bottleneck_features
+ self.num_attractors = num_attractors
+ self.bin_embedding_dim = bin_embedding_dim
+ self.attractor_alpha = attractor_alpha
+ self.attractor_gamma = attractor_gamma
+ self.attractor_kind = attractor_kind
+ self.min_temp = min_temp
+ self.max_temp = max_temp
+ self.bin_centers_type = bin_centers_type
+ self.bin_configurations = bin_configurations
+ self.num_patch_transformer_layers = num_patch_transformer_layers
+ self.patch_transformer_hidden_size = patch_transformer_hidden_size
+ self.patch_transformer_intermediate_size = patch_transformer_intermediate_size
+ self.patch_transformer_num_attention_heads = patch_transformer_num_attention_heads
+
+ @property
+ def sub_configs(self):
+ return (
+ {"backbone_config": type(self.backbone_config)}
+ if getattr(self, "backbone_config", None) is not None
+ else {}
+ )
+
+
+__all__ = ["ZOEDEPTH_PRETRAINED_CONFIG_ARCHIVE_MAP", "ZoeDepthConfig"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/image_processing_zoedepth.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/image_processing_zoedepth.py
new file mode 100644
index 0000000000000000000000000000000000000000..2fb125e2b79381e7bcd548e547e5d34ec7c814e6
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/image_processing_zoedepth.py
@@ -0,0 +1,562 @@
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Image processor class for ZoeDepth."""
+
+import math
+from collections.abc import Iterable
+from typing import TYPE_CHECKING, Optional, Union
+
+import numpy as np
+
+
+if TYPE_CHECKING:
+ from .modeling_zoedepth import ZoeDepthDepthEstimatorOutput
+
+from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict
+from ...image_transforms import PaddingMode, pad, to_channel_dimension_format
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ get_image_size,
+ infer_channel_dimension_format,
+ is_scaled_image,
+ make_list_of_images,
+ to_numpy_array,
+ valid_images,
+ validate_preprocess_arguments,
+)
+from ...utils import (
+ TensorType,
+ filter_out_non_signature_kwargs,
+ is_torch_available,
+ is_vision_available,
+ logging,
+ requires_backends,
+)
+
+
+if is_vision_available():
+ import PIL
+
+if is_torch_available():
+ import torch
+ from torch import nn
+
+
+logger = logging.get_logger(__name__)
+
+
+def get_resize_output_image_size(
+ input_image: np.ndarray,
+ output_size: Union[int, Iterable[int]],
+ keep_aspect_ratio: bool,
+ multiple: int,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+) -> tuple[int, int]:
+ def constrain_to_multiple_of(val, multiple, min_val=0):
+ x = (np.round(val / multiple) * multiple).astype(int)
+
+ if x < min_val:
+ x = math.ceil(val / multiple) * multiple
+
+ return x
+
+ output_size = (output_size, output_size) if isinstance(output_size, int) else output_size
+
+ input_height, input_width = get_image_size(input_image, input_data_format)
+ output_height, output_width = output_size
+
+ # determine new height and width
+ scale_height = output_height / input_height
+ scale_width = output_width / input_width
+
+ if keep_aspect_ratio:
+ # scale as little as possible
+ if abs(1 - scale_width) < abs(1 - scale_height):
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+
+ new_height = constrain_to_multiple_of(scale_height * input_height, multiple=multiple)
+ new_width = constrain_to_multiple_of(scale_width * input_width, multiple=multiple)
+
+ return (new_height, new_width)
+
+
+class ZoeDepthImageProcessor(BaseImageProcessor):
+ r"""
+ Constructs a ZoeDepth image processor.
+
+ Args:
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to apply pad the input.
+ do_rescale (`bool`, *optional*, defaults to `True`):
+ Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in
+ `preprocess`.
+ rescale_factor (`int` or `float`, *optional*, defaults to `1/255`):
+ Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in `preprocess`.
+ do_normalize (`bool`, *optional*, defaults to `True`):
+ Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess`
+ method.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`):
+ Mean to use if normalizing the image. This is a float or list of floats the length of the number of
+ channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method.
+ image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`):
+ Standard deviation to use if normalizing the image. This is a float or list of floats the length of the
+ number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method.
+ do_resize (`bool`, *optional*, defaults to `True`):
+ Whether to resize the image's (height, width) dimensions. Can be overridden by `do_resize` in `preprocess`.
+ size (`dict[str, int]` *optional*, defaults to `{"height": 384, "width": 512}`):
+ Size of the image after resizing. Size of the image after resizing. If `keep_aspect_ratio` is `True`,
+ the image is resized by choosing the smaller of the height and width scaling factors and using it for both dimensions.
+ If `ensure_multiple_of` is also set, the image is further resized to a size that is a multiple of this value.
+ Can be overridden by `size` in `preprocess`.
+ resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`):
+ Defines the resampling filter to use if resizing the image. Can be overridden by `resample` in `preprocess`.
+ keep_aspect_ratio (`bool`, *optional*, defaults to `True`):
+ If `True`, the image is resized by choosing the smaller of the height and width scaling factors and using it
+ for both dimensions. This ensures that the image is scaled down as little as possible while still fitting
+ within the desired output size. In case `ensure_multiple_of` is also set, the image is further resized to a
+ size that is a multiple of this value by flooring the height and width to the nearest multiple of this value.
+ Can be overridden by `keep_aspect_ratio` in `preprocess`.
+ ensure_multiple_of (`int`, *optional*, defaults to 32):
+ If `do_resize` is `True`, the image is resized to a size that is a multiple of this value. Works by flooring
+ the height and width to the nearest multiple of this value.
+
+ Works both with and without `keep_aspect_ratio` being set to `True`. Can be overridden by `ensure_multiple_of`
+ in `preprocess`.
+ """
+
+ model_input_names = ["pixel_values"]
+
+ def __init__(
+ self,
+ do_pad: bool = True,
+ do_rescale: bool = True,
+ rescale_factor: Union[int, float] = 1 / 255,
+ do_normalize: bool = True,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_resize: bool = True,
+ size: Optional[dict[str, int]] = None,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ keep_aspect_ratio: bool = True,
+ ensure_multiple_of: int = 32,
+ **kwargs,
+ ) -> None:
+ super().__init__(**kwargs)
+ self.do_rescale = do_rescale
+ self.rescale_factor = rescale_factor
+ self.do_pad = do_pad
+ self.do_normalize = do_normalize
+ self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN
+ self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD
+ size = size if size is not None else {"height": 384, "width": 512}
+ size = get_size_dict(size)
+ self.do_resize = do_resize
+ self.size = size
+ self.keep_aspect_ratio = keep_aspect_ratio
+ self.ensure_multiple_of = ensure_multiple_of
+ self.resample = resample
+
+ def resize(
+ self,
+ image: np.ndarray,
+ size: dict[str, int],
+ keep_aspect_ratio: bool = False,
+ ensure_multiple_of: int = 1,
+ resample: PILImageResampling = PILImageResampling.BILINEAR,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> np.ndarray:
+ """
+ Resize an image to target size `(size["height"], size["width"])`. If `keep_aspect_ratio` is `True`, the image
+ is resized to the largest possible size such that the aspect ratio is preserved. If `ensure_multiple_of` is
+ set, the image is resized to a size that is a multiple of this value.
+
+ Args:
+ image (`np.ndarray`):
+ Image to resize.
+ size (`dict[str, int]`):
+ Target size of the output image.
+ keep_aspect_ratio (`bool`, *optional*, defaults to `False`):
+ If `True`, the image is resized to the largest possible size such that the aspect ratio is preserved.
+ ensure_multiple_of (`int`, *optional*, defaults to 1):
+ The image is resized to a size that is a multiple of this value.
+ resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`):
+ Defines the resampling filter to use if resizing the image. Otherwise, the image is resized to size
+ specified in `size`.
+ data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the image. If not provided, it will be the same as the input image.
+ input_data_format (`str` or `ChannelDimension`, *optional*):
+ The channel dimension format of the input image. If not provided, it will be inferred.
+ """
+ if input_data_format is None:
+ input_data_format = infer_channel_dimension_format(image)
+
+ data_format = data_format if data_format is not None else input_data_format
+
+ size = get_size_dict(size)
+ if "height" not in size or "width" not in size:
+ raise ValueError(f"The size dictionary must contain the keys 'height' and 'width'. Got {size.keys()}")
+
+ output_size = get_resize_output_image_size(
+ image,
+ output_size=(size["height"], size["width"]),
+ keep_aspect_ratio=keep_aspect_ratio,
+ multiple=ensure_multiple_of,
+ input_data_format=input_data_format,
+ )
+
+ height, width = output_size
+
+ torch_image = torch.from_numpy(image).unsqueeze(0)
+ torch_image = torch_image.permute(0, 3, 1, 2) if input_data_format == "channels_last" else torch_image
+
+ # TODO support align_corners=True in image_transforms.resize
+ requires_backends(self, "torch")
+ resample_to_mode = {PILImageResampling.BILINEAR: "bilinear", PILImageResampling.BICUBIC: "bicubic"}
+ mode = resample_to_mode[resample]
+ resized_image = nn.functional.interpolate(
+ torch_image, (int(height), int(width)), mode=mode, align_corners=True
+ )
+ resized_image = resized_image.squeeze().numpy()
+
+ resized_image = to_channel_dimension_format(
+ resized_image, data_format, input_channel_dim=ChannelDimension.FIRST
+ )
+
+ return resized_image
+
+ def pad_image(
+ self,
+ image: np.array,
+ mode: PaddingMode = PaddingMode.REFLECT,
+ data_format: Optional[Union[str, ChannelDimension]] = None,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ):
+ """
+ Pad an image as done in the original ZoeDepth implementation.
+
+ Padding fixes the boundary artifacts in the output depth map.
+ Boundary artifacts are sometimes caused by the fact that the model is trained on NYU raw dataset
+ which has a black or white border around the image. This function pads the input image and crops
+ the prediction back to the original size / view.
+
+ Args:
+ image (`np.ndarray`):
+ Image to pad.
+ mode (`PaddingMode`):
+ The padding mode to use. Can be one of:
+ - `"constant"`: pads with a constant value.
+ - `"reflect"`: pads with the reflection of the vector mirrored on the first and last values of the
+ vector along each axis.
+ - `"replicate"`: pads with the replication of the last value on the edge of the array along each axis.
+ - `"symmetric"`: pads with the reflection of the vector mirrored along the edge of the array.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - Unset: Use the channel dimension format of the input image.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ height, width = get_image_size(image, input_data_format)
+
+ pad_height = int(np.sqrt(height / 2) * 3)
+ pad_width = int(np.sqrt(width / 2) * 3)
+
+ return pad(
+ image,
+ padding=((pad_height, pad_height), (pad_width, pad_width)),
+ mode=mode,
+ data_format=data_format,
+ input_data_format=input_data_format,
+ )
+
+ @filter_out_non_signature_kwargs()
+ def preprocess(
+ self,
+ images: ImageInput,
+ do_pad: Optional[bool] = None,
+ do_rescale: Optional[bool] = None,
+ rescale_factor: Optional[float] = None,
+ do_normalize: Optional[bool] = None,
+ image_mean: Optional[Union[float, list[float]]] = None,
+ image_std: Optional[Union[float, list[float]]] = None,
+ do_resize: Optional[bool] = None,
+ size: Optional[int] = None,
+ keep_aspect_ratio: Optional[bool] = None,
+ ensure_multiple_of: Optional[int] = None,
+ resample: PILImageResampling = None,
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ data_format: ChannelDimension = ChannelDimension.FIRST,
+ input_data_format: Optional[Union[str, ChannelDimension]] = None,
+ ) -> PIL.Image.Image:
+ """
+ Preprocess an image or batch of images.
+
+ Args:
+ images (`ImageInput`):
+ Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If
+ passing in images with pixel values between 0 and 1, set `do_rescale=False`.
+ do_pad (`bool`, *optional*, defaults to `self.do_pad`):
+ Whether to pad the input image.
+ do_rescale (`bool`, *optional*, defaults to `self.do_rescale`):
+ Whether to rescale the image values between [0 - 1].
+ rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`):
+ Rescale factor to rescale the image by if `do_rescale` is set to `True`.
+ do_normalize (`bool`, *optional*, defaults to `self.do_normalize`):
+ Whether to normalize the image.
+ image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`):
+ Image mean.
+ image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`):
+ Image standard deviation.
+ do_resize (`bool`, *optional*, defaults to `self.do_resize`):
+ Whether to resize the image.
+ size (`dict[str, int]`, *optional*, defaults to `self.size`):
+ Size of the image after resizing. If `keep_aspect_ratio` is `True`, he image is resized by choosing the
+ smaller of the height and width scaling factors and using it for both dimensions. If `ensure_multiple_of`
+ is also set, the image is further resized to a size that is a multiple of this value.
+ keep_aspect_ratio (`bool`, *optional*, defaults to `self.keep_aspect_ratio`):
+ If `True` and `do_resize=True`, the image is resized by choosing the smaller of the height and width
+ scaling factors and using it for both dimensions. This ensures that the image is scaled down as little
+ as possible while still fitting within the desired output size. In case `ensure_multiple_of` is also
+ set, the image is further resized to a size that is a multiple of this value by flooring the height and
+ width to the nearest multiple of this value.
+ ensure_multiple_of (`int`, *optional*, defaults to `self.ensure_multiple_of`):
+ If `do_resize` is `True`, the image is resized to a size that is a multiple of this value. Works by
+ flooring the height and width to the nearest multiple of this value.
+
+ Works both with and without `keep_aspect_ratio` being set to `True`. Can be overridden by
+ `ensure_multiple_of` in `preprocess`.
+ resample (`int`, *optional*, defaults to `self.resample`):
+ Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only
+ has an effect if `do_resize` is set to `True`.
+ return_tensors (`str` or `TensorType`, *optional*):
+ The type of tensors to return. Can be one of:
+ - Unset: Return a list of `np.ndarray`.
+ - `TensorType.TENSORFLOW` or `'tf'`: Return a batch of type `tf.Tensor`.
+ - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`.
+ - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`.
+ - `TensorType.JAX` or `'jax'`: Return a batch of type `jax.numpy.ndarray`.
+ data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`):
+ The channel dimension format for the output image. Can be one of:
+ - `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ input_data_format (`ChannelDimension` or `str`, *optional*):
+ The channel dimension format for the input image. If unset, the channel dimension format is inferred
+ from the input image. Can be one of:
+ - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format.
+ - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format.
+ - `"none"` or `ChannelDimension.NONE`: image in (height, width) format.
+ """
+ do_resize = do_resize if do_resize is not None else self.do_resize
+ size = size if size is not None else self.size
+ size = get_size_dict(size)
+ keep_aspect_ratio = keep_aspect_ratio if keep_aspect_ratio is not None else self.keep_aspect_ratio
+ ensure_multiple_of = ensure_multiple_of if ensure_multiple_of is not None else self.ensure_multiple_of
+ resample = resample if resample is not None else self.resample
+ do_rescale = do_rescale if do_rescale is not None else self.do_rescale
+ rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor
+ do_normalize = do_normalize if do_normalize is not None else self.do_normalize
+ image_mean = image_mean if image_mean is not None else self.image_mean
+ image_std = image_std if image_std is not None else self.image_std
+ do_pad = do_pad if do_pad is not None else self.do_pad
+
+ images = make_list_of_images(images)
+
+ if not valid_images(images):
+ raise ValueError(
+ "Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, "
+ "torch.Tensor, tf.Tensor or jax.ndarray."
+ )
+ validate_preprocess_arguments(
+ do_rescale=do_rescale,
+ rescale_factor=rescale_factor,
+ do_normalize=do_normalize,
+ image_mean=image_mean,
+ image_std=image_std,
+ do_resize=do_resize,
+ size=size,
+ resample=resample,
+ )
+ # All transformations expect numpy arrays.
+ images = [to_numpy_array(image) for image in images]
+
+ if do_rescale and is_scaled_image(images[0]):
+ logger.warning_once(
+ "It looks like you are trying to rescale already rescaled images. If the input"
+ " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again."
+ )
+
+ if input_data_format is None:
+ # We assume that all images have the same channel dimension format.
+ input_data_format = infer_channel_dimension_format(images[0])
+
+ if do_rescale:
+ images = [
+ self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ if do_pad:
+ images = [self.pad_image(image=image, input_data_format=input_data_format) for image in images]
+
+ if do_resize:
+ images = [
+ self.resize(
+ image=image,
+ size=size,
+ resample=resample,
+ keep_aspect_ratio=keep_aspect_ratio,
+ ensure_multiple_of=ensure_multiple_of,
+ input_data_format=input_data_format,
+ )
+ for image in images
+ ]
+
+ if do_normalize:
+ images = [
+ self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format)
+ for image in images
+ ]
+
+ images = [
+ to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images
+ ]
+
+ data = {"pixel_values": images}
+ return BatchFeature(data=data, tensor_type=return_tensors)
+
+ def post_process_depth_estimation(
+ self,
+ outputs: "ZoeDepthDepthEstimatorOutput",
+ source_sizes: Optional[Union[TensorType, list[tuple[int, int]], None]] = None,
+ target_sizes: Optional[Union[TensorType, list[tuple[int, int]], None]] = None,
+ outputs_flipped: Optional[Union["ZoeDepthDepthEstimatorOutput", None]] = None,
+ do_remove_padding: Optional[Union[bool, None]] = None,
+ ) -> list[dict[str, TensorType]]:
+ """
+ Converts the raw output of [`ZoeDepthDepthEstimatorOutput`] into final depth predictions and depth PIL images.
+ Only supports PyTorch.
+
+ Args:
+ outputs ([`ZoeDepthDepthEstimatorOutput`]):
+ Raw outputs of the model.
+ source_sizes (`TensorType` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the source size
+ (height, width) of each image in the batch before preprocessing. This argument should be dealt as
+ "required" unless the user passes `do_remove_padding=False` as input to this function.
+ target_sizes (`TensorType` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size
+ (height, width) of each image in the batch. If left to None, predictions will not be resized.
+ outputs_flipped ([`ZoeDepthDepthEstimatorOutput`], *optional*):
+ Raw outputs of the model from flipped input (averaged out in the end).
+ do_remove_padding (`bool`, *optional*):
+ By default ZoeDepth adds padding equal to `int(√(height / 2) * 3)` (and similarly for width) to fix the
+ boundary artifacts in the output depth map, so we need remove this padding during post_processing. The
+ parameter exists here in case the user changed the image preprocessing to not include padding.
+
+ Returns:
+ `list[dict[str, TensorType]]`: A list of dictionaries of tensors representing the processed depth
+ predictions.
+ """
+ requires_backends(self, "torch")
+
+ predicted_depth = outputs.predicted_depth
+
+ if (outputs_flipped is not None) and (predicted_depth.shape != outputs_flipped.predicted_depth.shape):
+ raise ValueError("Make sure that `outputs` and `outputs_flipped` have the same shape")
+
+ if (target_sizes is not None) and (len(predicted_depth) != len(target_sizes)):
+ raise ValueError(
+ "Make sure that you pass in as many target sizes as the batch dimension of the predicted depth"
+ )
+
+ if do_remove_padding is None:
+ do_remove_padding = self.do_pad
+
+ if source_sizes is None and do_remove_padding:
+ raise ValueError(
+ "Either `source_sizes` should be passed in, or `do_remove_padding` should be set to False"
+ )
+
+ if (source_sizes is not None) and (len(predicted_depth) != len(source_sizes)):
+ raise ValueError(
+ "Make sure that you pass in as many source image sizes as the batch dimension of the logits"
+ )
+
+ if outputs_flipped is not None:
+ predicted_depth = (predicted_depth + torch.flip(outputs_flipped.predicted_depth, dims=[-1])) / 2
+
+ predicted_depth = predicted_depth.unsqueeze(1)
+
+ # Zoe Depth model adds padding around the images to fix the boundary artifacts in the output depth map
+ # The padding length is `int(np.sqrt(img_h/2) * fh)` for the height and similar for the width
+ # fh (and fw respectively) are equal to '3' by default
+ # Check [here](https://github.com/isl-org/ZoeDepth/blob/edb6daf45458569e24f50250ef1ed08c015f17a7/zoedepth/models/depth_model.py#L57)
+ # for the original implementation.
+ # In this section, we remove this padding to get the final depth image and depth prediction
+ padding_factor_h = padding_factor_w = 3
+
+ results = []
+ target_sizes = [None] * len(predicted_depth) if target_sizes is None else target_sizes
+ source_sizes = [None] * len(predicted_depth) if source_sizes is None else source_sizes
+ for depth, target_size, source_size in zip(predicted_depth, target_sizes, source_sizes):
+ # depth.shape = [1, H, W]
+ if source_size is not None:
+ pad_h = pad_w = 0
+
+ if do_remove_padding:
+ pad_h = int(np.sqrt(source_size[0] / 2) * padding_factor_h)
+ pad_w = int(np.sqrt(source_size[1] / 2) * padding_factor_w)
+
+ depth = nn.functional.interpolate(
+ depth.unsqueeze(1),
+ size=[source_size[0] + 2 * pad_h, source_size[1] + 2 * pad_w],
+ mode="bicubic",
+ align_corners=False,
+ )
+
+ if pad_h > 0:
+ depth = depth[:, :, pad_h:-pad_h, :]
+ if pad_w > 0:
+ depth = depth[:, :, :, pad_w:-pad_w]
+
+ depth = depth.squeeze(1)
+ # depth.shape = [1, H, W]
+ if target_size is not None:
+ target_size = [target_size[0], target_size[1]]
+ depth = nn.functional.interpolate(
+ depth.unsqueeze(1), size=target_size, mode="bicubic", align_corners=False
+ )
+ depth = depth.squeeze()
+ # depth.shape = [H, W]
+ results.append({"predicted_depth": depth})
+
+ return results
+
+
+__all__ = ["ZoeDepthImageProcessor"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/image_processing_zoedepth_fast.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/image_processing_zoedepth_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..793c386fdc75daa8cad9a54baa68428f08bf91d2
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/image_processing_zoedepth_fast.py
@@ -0,0 +1,326 @@
+# coding=utf-8
+# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Fast Image processor class for ZoeDepth."""
+
+from typing import (
+ Optional,
+ Union,
+)
+
+import numpy as np
+
+from ...image_processing_utils import (
+ BatchFeature,
+)
+from ...image_processing_utils_fast import (
+ BaseImageProcessorFast,
+ DefaultFastImageProcessorKwargs,
+ group_images_by_shape,
+ reorder_images,
+)
+from ...image_utils import (
+ IMAGENET_STANDARD_MEAN,
+ IMAGENET_STANDARD_STD,
+ ChannelDimension,
+ ImageInput,
+ PILImageResampling,
+ SizeDict,
+ get_image_size,
+)
+from ...processing_utils import Unpack
+from ...utils import (
+ TensorType,
+ auto_docstring,
+ is_torch_available,
+ is_torchvision_available,
+ is_torchvision_v2_available,
+ logging,
+ requires_backends,
+)
+from .image_processing_zoedepth import get_resize_output_image_size
+from .modeling_zoedepth import ZoeDepthDepthEstimatorOutput
+
+
+if is_torch_available():
+ import torch
+
+if is_torchvision_available():
+ if is_torchvision_v2_available():
+ from torchvision.transforms.v2 import functional as F
+ else:
+ from torchvision.transforms import functional as F
+
+ from torchvision.transforms import InterpolationMode
+
+
+logger = logging.get_logger(__name__)
+
+
+class ZoeDepthFastImageProcessorKwargs(DefaultFastImageProcessorKwargs):
+ """
+ do_pad (`bool`, *optional*, defaults to `True`):
+ Whether to apply pad the input.
+ keep_aspect_ratio (`bool`, *optional*, defaults to `True`):
+ If `True`, the image is resized by choosing the smaller of the height and width scaling factors and using it
+ for both dimensions. This ensures that the image is scaled down as little as possible while still fitting
+ within the desired output size. In case `ensure_multiple_of` is also set, the image is further resized to a
+ size that is a multiple of this value by flooring the height and width to the nearest multiple of this value.
+ Can be overridden by `keep_aspect_ratio` in `preprocess`.
+ ensure_multiple_of (`int`, *optional*, defaults to 32):
+ If `do_resize` is `True`, the image is resized to a size that is a multiple of this value. Works by flooring
+ the height and width to the nearest multiple of this value.
+ Works both with and without `keep_aspect_ratio` being set to `True`.
+ Can be overridden by `ensure_multiple_of` in `preprocess`.
+ """
+
+ do_pad: Optional[bool]
+ keep_aspect_ratio: Optional[bool]
+ ensure_multiple_of: Optional[int]
+
+
+@auto_docstring
+class ZoeDepthImageProcessorFast(BaseImageProcessorFast):
+ do_pad = True
+ do_rescale = True
+ do_normalize = True
+ image_mean = IMAGENET_STANDARD_MEAN
+ image_std = IMAGENET_STANDARD_STD
+ do_resize = True
+ size = {"height": 384, "width": 512}
+ resample = PILImageResampling.BILINEAR
+ keep_aspect_ratio = True
+ ensure_multiple_of = 1 / 32
+ valid_kwargs = ZoeDepthFastImageProcessorKwargs
+
+ def __init__(self, **kwargs: Unpack[ZoeDepthFastImageProcessorKwargs]) -> None:
+ super().__init__(**kwargs)
+
+ @auto_docstring
+ def preprocess(
+ self,
+ images: ImageInput,
+ **kwargs: Unpack[ZoeDepthFastImageProcessorKwargs],
+ ) -> BatchFeature:
+ return super().preprocess(images, **kwargs)
+
+ def resize(
+ self,
+ images: "torch.Tensor",
+ size: SizeDict,
+ keep_aspect_ratio: bool = False,
+ ensure_multiple_of: int = 1,
+ interpolation: Optional["F.InterpolationMode"] = None,
+ ) -> "torch.Tensor":
+ """
+ Resize an image or batchd images to target size `(size["height"], size["width"])`. If `keep_aspect_ratio` is `True`, the image
+ is resized to the largest possible size such that the aspect ratio is preserved. If `ensure_multiple_of` is
+ set, the image is resized to a size that is a multiple of this value.
+
+ Args:
+ images (`torch.Tensor`):
+ Images to resize.
+ size (`dict[str, int]`):
+ Target size of the output image.
+ keep_aspect_ratio (`bool`, *optional*, defaults to `False`):
+ If `True`, the image is resized to the largest possible size such that the aspect ratio is preserved.
+ ensure_multiple_of (`int`, *optional*, defaults to 1):
+ The image is resized to a size that is a multiple of this value.
+ interpolation (`F.InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`):
+ Defines the resampling filter to use if resizing the image. Otherwise, the image is resized to size
+ specified in `size`.
+ """
+ if not size.height or not size.width:
+ raise ValueError(f"The size dictionary must contain the keys 'height' and 'width'. Got {size}")
+ output_size = get_resize_output_image_size(
+ images,
+ output_size=(size.height, size.width),
+ keep_aspect_ratio=keep_aspect_ratio,
+ multiple=ensure_multiple_of,
+ input_data_format=ChannelDimension.FIRST,
+ )
+ height, width = output_size
+
+ resized_images = torch.nn.functional.interpolate(
+ images, (int(height), int(width)), mode=interpolation.value, align_corners=True
+ )
+
+ return resized_images
+
+ def _pad_images(
+ self,
+ images: "torch.Tensor",
+ ):
+ """
+ Args:
+ image (`torch.Tensor`):
+ Image to pad.
+ """
+ height, width = get_image_size(images, channel_dim=ChannelDimension.FIRST)
+
+ pad_height = int(np.sqrt(height / 2) * 3)
+ pad_width = int(np.sqrt(width / 2) * 3)
+
+ return F.pad(images, padding=(pad_width, pad_height), padding_mode="reflect")
+
+ def _preprocess(
+ self,
+ images: list["torch.Tensor"],
+ do_resize: bool,
+ size: SizeDict,
+ keep_aspect_ratio: Optional[bool],
+ ensure_multiple_of: Optional[int],
+ interpolation: Optional["F.InterpolationMode"],
+ do_pad: bool,
+ do_rescale: bool,
+ rescale_factor: Optional[float],
+ do_normalize: bool,
+ image_mean: Optional[Union[float, list[float]]],
+ image_std: Optional[Union[float, list[float]]],
+ disable_grouping: Optional[bool],
+ return_tensors: Optional[Union[str, TensorType]] = None,
+ **kwargs,
+ ) -> BatchFeature:
+ # Group images by size for batched resizing
+ grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping)
+ resized_images_grouped = {}
+ for shape, stacked_images in grouped_images.items():
+ if do_rescale:
+ stacked_images = self.rescale(stacked_images, rescale_factor)
+ if do_pad:
+ stacked_images = self._pad_images(images=stacked_images)
+ if do_resize:
+ stacked_images = self.resize(
+ stacked_images, size, keep_aspect_ratio, ensure_multiple_of, interpolation
+ )
+ if do_normalize:
+ stacked_images = self.normalize(stacked_images, image_mean, image_std)
+ resized_images_grouped[shape] = stacked_images
+ resized_images = reorder_images(resized_images_grouped, grouped_images_index)
+
+ processed_images = torch.stack(resized_images, dim=0) if return_tensors else resized_images
+
+ return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors)
+
+ def post_process_depth_estimation(
+ self,
+ outputs: "ZoeDepthDepthEstimatorOutput",
+ source_sizes: Optional[Union[TensorType, list[tuple[int, int]], None]] = None,
+ target_sizes: Optional[Union[TensorType, list[tuple[int, int]], None]] = None,
+ outputs_flipped: Optional[Union["ZoeDepthDepthEstimatorOutput", None]] = None,
+ do_remove_padding: Optional[Union[bool, None]] = None,
+ ) -> list[dict[str, TensorType]]:
+ """
+ Converts the raw output of [`ZoeDepthDepthEstimatorOutput`] into final depth predictions and depth PIL images.
+ Only supports PyTorch.
+
+ Args:
+ outputs ([`ZoeDepthDepthEstimatorOutput`]):
+ Raw outputs of the model.
+ source_sizes (`TensorType` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the source size
+ (height, width) of each image in the batch before preprocessing. This argument should be dealt as
+ "required" unless the user passes `do_remove_padding=False` as input to this function.
+ target_sizes (`TensorType` or `list[tuple[int, int]]`, *optional*):
+ Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size
+ (height, width) of each image in the batch. If left to None, predictions will not be resized.
+ outputs_flipped ([`ZoeDepthDepthEstimatorOutput`], *optional*):
+ Raw outputs of the model from flipped input (averaged out in the end).
+ do_remove_padding (`bool`, *optional*):
+ By default ZoeDepth adds padding equal to `int(√(height / 2) * 3)` (and similarly for width) to fix the
+ boundary artifacts in the output depth map, so we need remove this padding during post_processing. The
+ parameter exists here in case the user changed the image preprocessing to not include padding.
+
+ Returns:
+ `list[dict[str, TensorType]]`: A list of dictionaries of tensors representing the processed depth
+ predictions.
+ """
+ requires_backends(self, "torch")
+
+ predicted_depth = outputs.predicted_depth
+
+ if (outputs_flipped is not None) and (predicted_depth.shape != outputs_flipped.predicted_depth.shape):
+ raise ValueError("Make sure that `outputs` and `outputs_flipped` have the same shape")
+
+ if (target_sizes is not None) and (len(predicted_depth) != len(target_sizes)):
+ raise ValueError(
+ "Make sure that you pass in as many target sizes as the batch dimension of the predicted depth"
+ )
+
+ if do_remove_padding is None:
+ do_remove_padding = self.do_pad
+
+ if source_sizes is None and do_remove_padding:
+ raise ValueError(
+ "Either `source_sizes` should be passed in, or `do_remove_padding` should be set to False"
+ )
+
+ if (source_sizes is not None) and (len(predicted_depth) != len(source_sizes)):
+ raise ValueError(
+ "Make sure that you pass in as many source image sizes as the batch dimension of the logits"
+ )
+
+ if outputs_flipped is not None:
+ predicted_depth = (predicted_depth + torch.flip(outputs_flipped.predicted_depth, dims=[-1])) / 2
+
+ predicted_depth = predicted_depth.unsqueeze(1)
+
+ # Zoe Depth model adds padding around the images to fix the boundary artifacts in the output depth map
+ # The padding length is `int(np.sqrt(img_h/2) * fh)` for the height and similar for the width
+ # fh (and fw respectively) are equal to '3' by default
+ # Check [here](https://github.com/isl-org/ZoeDepth/blob/edb6daf45458569e24f50250ef1ed08c015f17a7/zoedepth/models/depth_model.py#L57)
+ # for the original implementation.
+ # In this section, we remove this padding to get the final depth image and depth prediction
+ padding_factor_h = padding_factor_w = 3
+
+ results = []
+ target_sizes = [None] * len(predicted_depth) if target_sizes is None else target_sizes
+ source_sizes = [None] * len(predicted_depth) if source_sizes is None else source_sizes
+ for depth, target_size, source_size in zip(predicted_depth, target_sizes, source_sizes):
+ # depth.shape = [1, H, W]
+ if source_size is not None:
+ pad_h = pad_w = 0
+
+ if do_remove_padding:
+ pad_h = int(np.sqrt(source_size[0] / 2) * padding_factor_h)
+ pad_w = int(np.sqrt(source_size[1] / 2) * padding_factor_w)
+
+ depth = F.resize(
+ depth,
+ size=[source_size[0] + 2 * pad_h, source_size[1] + 2 * pad_w],
+ interpolation=InterpolationMode.BICUBIC,
+ antialias=False,
+ )
+
+ if pad_h > 0:
+ depth = depth[:, pad_h:-pad_h, :]
+ if pad_w > 0:
+ depth = depth[:, :, pad_w:-pad_w]
+
+ if target_size is not None:
+ target_size = [target_size[0], target_size[1]]
+ depth = F.resize(
+ depth,
+ size=target_size,
+ interpolation=InterpolationMode.BICUBIC,
+ antialias=False,
+ )
+ depth = depth.squeeze(0)
+ # depth.shape = [H, W]
+ results.append({"predicted_depth": depth})
+
+ return results
+
+
+__all__ = ["ZoeDepthImageProcessorFast"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/modeling_zoedepth.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/modeling_zoedepth.py
new file mode 100644
index 0000000000000000000000000000000000000000..d79bb27d56c03c0cd04a32c5e0b28116a3b5854c
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/models/zoedepth/modeling_zoedepth.py
@@ -0,0 +1,1353 @@
+# coding=utf-8
+# Copyright 2024 Intel Labs and The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""PyTorch ZoeDepth model."""
+
+import math
+from dataclasses import dataclass
+from typing import Optional, Union
+
+import torch
+import torch.utils.checkpoint
+from torch import nn
+
+from ...activations import ACT2FN
+from ...modeling_outputs import DepthEstimatorOutput
+from ...modeling_utils import PreTrainedModel
+from ...utils import ModelOutput, auto_docstring, logging
+from ...utils.backbone_utils import load_backbone
+from .configuration_zoedepth import ZoeDepthConfig
+
+
+logger = logging.get_logger(__name__)
+
+
+@dataclass
+@auto_docstring(
+ custom_intro="""
+ Extension of `DepthEstimatorOutput` to include domain logits (ZoeDepth specific).
+ """
+)
+class ZoeDepthDepthEstimatorOutput(ModelOutput):
+ r"""
+ loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided):
+ Classification (or regression if config.num_labels==1) loss.
+ domain_logits (`torch.FloatTensor` of shape `(batch_size, num_domains)`):
+ Logits for each domain (e.g. NYU and KITTI) in case multiple metric heads are used.
+ """
+
+ loss: Optional[torch.FloatTensor] = None
+ predicted_depth: Optional[torch.FloatTensor] = None
+ domain_logits: Optional[torch.FloatTensor] = None
+ hidden_states: Optional[tuple[torch.FloatTensor, ...]] = None
+ attentions: Optional[tuple[torch.FloatTensor, ...]] = None
+
+
+class ZoeDepthReassembleStage(nn.Module):
+ """
+ This class reassembles the hidden states of the backbone into image-like feature representations at various
+ resolutions.
+
+ This happens in 3 stages:
+ 1. Map the N + 1 tokens to a set of N tokens, by taking into account the readout ([CLS]) token according to
+ `config.readout_type`.
+ 2. Project the channel dimension of the hidden states according to `config.neck_hidden_sizes`.
+ 3. Resizing the spatial dimensions (height, width).
+
+ Args:
+ config (`[ZoeDepthConfig]`):
+ Model configuration class defining the model architecture.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.readout_type = config.readout_type
+ self.layers = nn.ModuleList()
+
+ for neck_hidden_size, factor in zip(config.neck_hidden_sizes, config.reassemble_factors):
+ self.layers.append(ZoeDepthReassembleLayer(config, channels=neck_hidden_size, factor=factor))
+
+ if config.readout_type == "project":
+ self.readout_projects = nn.ModuleList()
+ hidden_size = config.backbone_hidden_size
+ for _ in config.neck_hidden_sizes:
+ self.readout_projects.append(
+ nn.Sequential(nn.Linear(2 * hidden_size, hidden_size), ACT2FN[config.hidden_act])
+ )
+
+ def forward(self, hidden_states: list[torch.Tensor], patch_height, patch_width) -> list[torch.Tensor]:
+ """
+ Args:
+ hidden_states (`list[torch.FloatTensor]`, each of shape `(batch_size, sequence_length + 1, hidden_size)`):
+ List of hidden states from the backbone.
+ """
+ batch_size = hidden_states[0].shape[0]
+
+ # stack along batch dimension
+ # shape (batch_size*num_stages, sequence_length + 1, hidden_size)
+ hidden_states = torch.cat(hidden_states, dim=0)
+
+ cls_token, hidden_states = hidden_states[:, 0], hidden_states[:, 1:]
+ # reshape hidden_states to (batch_size*num_stages, num_channels, height, width)
+ total_batch_size, sequence_length, num_channels = hidden_states.shape
+ hidden_states = hidden_states.reshape(total_batch_size, patch_height, patch_width, num_channels)
+ hidden_states = hidden_states.permute(0, 3, 1, 2).contiguous()
+
+ if self.readout_type == "project":
+ # reshape to (batch_size*num_stages, height*width, num_channels)
+ hidden_states = hidden_states.flatten(2).permute((0, 2, 1))
+ readout = cls_token.unsqueeze(dim=1).expand_as(hidden_states)
+ # concatenate the readout token to the hidden states
+ # to get (batch_size*num_stages, height*width, 2*num_channels)
+ hidden_states = torch.cat((hidden_states, readout), -1)
+ elif self.readout_type == "add":
+ hidden_states = hidden_states + cls_token.unsqueeze(-1)
+
+ out = []
+ for stage_idx, hidden_state in enumerate(hidden_states.split(batch_size, dim=0)):
+ if self.readout_type == "project":
+ hidden_state = self.readout_projects[stage_idx](hidden_state)
+
+ # reshape back to (batch_size, num_channels, height, width)
+ hidden_state = hidden_state.permute(0, 2, 1).reshape(batch_size, -1, patch_height, patch_width)
+ hidden_state = self.layers[stage_idx](hidden_state)
+ out.append(hidden_state)
+
+ return out
+
+
+class ZoeDepthReassembleLayer(nn.Module):
+ def __init__(self, config, channels, factor):
+ super().__init__()
+ # projection
+ hidden_size = config.backbone_hidden_size
+ self.projection = nn.Conv2d(in_channels=hidden_size, out_channels=channels, kernel_size=1)
+
+ # up/down sampling depending on factor
+ if factor > 1:
+ self.resize = nn.ConvTranspose2d(channels, channels, kernel_size=factor, stride=factor, padding=0)
+ elif factor == 1:
+ self.resize = nn.Identity()
+ elif factor < 1:
+ # so should downsample
+ self.resize = nn.Conv2d(channels, channels, kernel_size=3, stride=int(1 / factor), padding=1)
+
+ # Copied from transformers.models.dpt.modeling_dpt.DPTReassembleLayer.forward with DPT->ZoeDepth
+ def forward(self, hidden_state):
+ hidden_state = self.projection(hidden_state)
+ hidden_state = self.resize(hidden_state)
+ return hidden_state
+
+
+# Copied from transformers.models.dpt.modeling_dpt.DPTFeatureFusionStage with DPT->ZoeDepth
+class ZoeDepthFeatureFusionStage(nn.Module):
+ def __init__(self, config: ZoeDepthConfig):
+ super().__init__()
+ self.layers = nn.ModuleList()
+ for _ in range(len(config.neck_hidden_sizes)):
+ self.layers.append(ZoeDepthFeatureFusionLayer(config))
+
+ def forward(self, hidden_states):
+ # reversing the hidden_states, we start from the last
+ hidden_states = hidden_states[::-1]
+
+ fused_hidden_states = []
+ fused_hidden_state = None
+ for hidden_state, layer in zip(hidden_states, self.layers):
+ if fused_hidden_state is None:
+ # first layer only uses the last hidden_state
+ fused_hidden_state = layer(hidden_state)
+ else:
+ fused_hidden_state = layer(fused_hidden_state, hidden_state)
+ fused_hidden_states.append(fused_hidden_state)
+
+ return fused_hidden_states
+
+
+# Copied from transformers.models.dpt.modeling_dpt.DPTPreActResidualLayer with DPT->ZoeDepth
+class ZoeDepthPreActResidualLayer(nn.Module):
+ """
+ ResidualConvUnit, pre-activate residual unit.
+
+ Args:
+ config (`[ZoeDepthConfig]`):
+ Model configuration class defining the model architecture.
+ """
+
+ # Ignore copy
+ def __init__(self, config):
+ super().__init__()
+
+ self.use_batch_norm = config.use_batch_norm_in_fusion_residual
+ use_bias_in_fusion_residual = (
+ config.use_bias_in_fusion_residual
+ if config.use_bias_in_fusion_residual is not None
+ else not self.use_batch_norm
+ )
+
+ self.activation1 = nn.ReLU()
+ self.convolution1 = nn.Conv2d(
+ config.fusion_hidden_size,
+ config.fusion_hidden_size,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ bias=use_bias_in_fusion_residual,
+ )
+
+ self.activation2 = nn.ReLU()
+ self.convolution2 = nn.Conv2d(
+ config.fusion_hidden_size,
+ config.fusion_hidden_size,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ bias=use_bias_in_fusion_residual,
+ )
+
+ if self.use_batch_norm:
+ self.batch_norm1 = nn.BatchNorm2d(config.fusion_hidden_size, eps=config.batch_norm_eps)
+ self.batch_norm2 = nn.BatchNorm2d(config.fusion_hidden_size, eps=config.batch_norm_eps)
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ residual = hidden_state
+ hidden_state = self.activation1(hidden_state)
+
+ hidden_state = self.convolution1(hidden_state)
+
+ if self.use_batch_norm:
+ hidden_state = self.batch_norm1(hidden_state)
+
+ hidden_state = self.activation2(hidden_state)
+ hidden_state = self.convolution2(hidden_state)
+
+ if self.use_batch_norm:
+ hidden_state = self.batch_norm2(hidden_state)
+
+ return hidden_state + residual
+
+
+# Copied from transformers.models.dpt.modeling_dpt.DPTFeatureFusionLayer with DPT->ZoeDepth
+class ZoeDepthFeatureFusionLayer(nn.Module):
+ """Feature fusion layer, merges feature maps from different stages.
+
+ Args:
+ config (`[ZoeDepthConfig]`):
+ Model configuration class defining the model architecture.
+ align_corners (`bool`, *optional*, defaults to `True`):
+ The align_corner setting for bilinear upsample.
+ """
+
+ def __init__(self, config: ZoeDepthConfig, align_corners: bool = True):
+ super().__init__()
+
+ self.align_corners = align_corners
+
+ self.projection = nn.Conv2d(config.fusion_hidden_size, config.fusion_hidden_size, kernel_size=1, bias=True)
+
+ self.residual_layer1 = ZoeDepthPreActResidualLayer(config)
+ self.residual_layer2 = ZoeDepthPreActResidualLayer(config)
+
+ def forward(self, hidden_state: torch.Tensor, residual: Optional[torch.Tensor] = None) -> torch.Tensor:
+ if residual is not None:
+ if hidden_state.shape != residual.shape:
+ residual = nn.functional.interpolate(
+ residual, size=(hidden_state.shape[2], hidden_state.shape[3]), mode="bilinear", align_corners=False
+ )
+ hidden_state = hidden_state + self.residual_layer1(residual)
+
+ hidden_state = self.residual_layer2(hidden_state)
+ hidden_state = nn.functional.interpolate(
+ hidden_state, scale_factor=2, mode="bilinear", align_corners=self.align_corners
+ )
+ hidden_state = self.projection(hidden_state)
+
+ return hidden_state
+
+
+class ZoeDepthNeck(nn.Module):
+ """
+ ZoeDepthNeck. A neck is a module that is normally used between the backbone and the head. It takes a list of tensors as
+ input and produces another list of tensors as output. For ZoeDepth, it includes 2 stages:
+
+ * ZoeDepthReassembleStage
+ * ZoeDepthFeatureFusionStage.
+
+ Args:
+ config (dict): config dict.
+ """
+
+ # Copied from transformers.models.dpt.modeling_dpt.DPTNeck.__init__ with DPT->ZoeDepth
+ def __init__(self, config: ZoeDepthConfig):
+ super().__init__()
+ self.config = config
+
+ # postprocessing: only required in case of a non-hierarchical backbone (e.g. ViT, BEiT)
+ if config.backbone_config is not None and config.backbone_config.model_type in ["swinv2"]:
+ self.reassemble_stage = None
+ else:
+ self.reassemble_stage = ZoeDepthReassembleStage(config)
+
+ self.convs = nn.ModuleList()
+ for channel in config.neck_hidden_sizes:
+ self.convs.append(nn.Conv2d(channel, config.fusion_hidden_size, kernel_size=3, padding=1, bias=False))
+
+ # fusion
+ self.fusion_stage = ZoeDepthFeatureFusionStage(config)
+
+ def forward(self, hidden_states: list[torch.Tensor], patch_height, patch_width) -> list[torch.Tensor]:
+ """
+ Args:
+ hidden_states (`list[torch.FloatTensor]`, each of shape `(batch_size, sequence_length, hidden_size)` or `(batch_size, hidden_size, height, width)`):
+ List of hidden states from the backbone.
+ """
+ if not isinstance(hidden_states, (tuple, list)):
+ raise TypeError("hidden_states should be a tuple or list of tensors")
+
+ if len(hidden_states) != len(self.config.neck_hidden_sizes):
+ raise ValueError("The number of hidden states should be equal to the number of neck hidden sizes.")
+
+ # postprocess hidden states
+ if self.reassemble_stage is not None:
+ hidden_states = self.reassemble_stage(hidden_states, patch_height, patch_width)
+
+ features = [self.convs[i](feature) for i, feature in enumerate(hidden_states)]
+
+ # fusion blocks
+ output = self.fusion_stage(features)
+
+ return output, features[-1]
+
+
+class ZoeDepthRelativeDepthEstimationHead(nn.Module):
+ """
+ Relative depth estimation head consisting of 3 convolutional layers. It progressively halves the feature dimension and upsamples
+ the predictions to the input resolution after the first convolutional layer (details can be found in DPT's paper's
+ supplementary material).
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ self.head_in_index = config.head_in_index
+
+ self.projection = None
+ if config.add_projection:
+ self.projection = nn.Conv2d(256, 256, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1))
+
+ features = config.fusion_hidden_size
+ self.conv1 = nn.Conv2d(features, features // 2, kernel_size=3, stride=1, padding=1)
+ self.upsample = nn.Upsample(scale_factor=2, mode="bilinear", align_corners=True)
+ self.conv2 = nn.Conv2d(features // 2, config.num_relative_features, kernel_size=3, stride=1, padding=1)
+ self.conv3 = nn.Conv2d(config.num_relative_features, 1, kernel_size=1, stride=1, padding=0)
+
+ def forward(self, hidden_states: list[torch.Tensor]) -> torch.Tensor:
+ # use last features
+ hidden_states = hidden_states[self.head_in_index]
+
+ if self.projection is not None:
+ hidden_states = self.projection(hidden_states)
+ hidden_states = nn.ReLU()(hidden_states)
+
+ hidden_states = self.conv1(hidden_states)
+ hidden_states = self.upsample(hidden_states)
+ hidden_states = self.conv2(hidden_states)
+ hidden_states = nn.ReLU()(hidden_states)
+ # we need the features here (after second conv + ReLu)
+ features = hidden_states
+ hidden_states = self.conv3(hidden_states)
+ hidden_states = nn.ReLU()(hidden_states)
+
+ predicted_depth = hidden_states.squeeze(dim=1)
+
+ return predicted_depth, features
+
+
+def log_binom(n, k, eps=1e-7):
+ """log(nCk) using stirling approximation"""
+ n = n + eps
+ k = k + eps
+ return n * torch.log(n) - k * torch.log(k) - (n - k) * torch.log(n - k + eps)
+
+
+class LogBinomialSoftmax(nn.Module):
+ def __init__(self, n_classes=256, act=torch.softmax):
+ """Compute log binomial distribution for n_classes
+
+ Args:
+ n_classes (`int`, *optional*, defaults to 256):
+ Number of output classes.
+ act (`torch.nn.Module`, *optional*, defaults to `torch.softmax`):
+ Activation function to apply to the output.
+ """
+ super().__init__()
+ self.k = n_classes
+ self.act = act
+ self.register_buffer("k_idx", torch.arange(0, n_classes).view(1, -1, 1, 1), persistent=False)
+ self.register_buffer("k_minus_1", torch.tensor([self.k - 1]).view(1, -1, 1, 1), persistent=False)
+
+ def forward(self, probabilities, temperature=1.0, eps=1e-4):
+ """Compute the log binomial distribution for probabilities.
+
+ Args:
+ probabilities (`torch.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Tensor containing probabilities of each class.
+ temperature (`float` or `torch.Tensor` of shape `(batch_size, num_channels, height, width)`, *optional*, defaults to 1):
+ Temperature of distribution.
+ eps (`float`, *optional*, defaults to 1e-4):
+ Small number for numerical stability.
+
+ Returns:
+ `torch.Tensor` of shape `(batch_size, num_channels, height, width)`:
+ Log binomial distribution logbinomial(p;t).
+ """
+ if probabilities.ndim == 3:
+ probabilities = probabilities.unsqueeze(1) # make it (batch_size, num_channels, height, width)
+
+ one_minus_probabilities = torch.clamp(1 - probabilities, eps, 1)
+ probabilities = torch.clamp(probabilities, eps, 1)
+ y = (
+ log_binom(self.k_minus_1, self.k_idx)
+ + self.k_idx * torch.log(probabilities)
+ + (self.k_minus_1 - self.k_idx) * torch.log(one_minus_probabilities)
+ )
+ return self.act(y / temperature, dim=1)
+
+
+class ZoeDepthConditionalLogBinomialSoftmax(nn.Module):
+ def __init__(
+ self,
+ config,
+ in_features,
+ condition_dim,
+ n_classes=256,
+ bottleneck_factor=2,
+ ):
+ """Per-pixel MLP followed by a Conditional Log Binomial softmax.
+
+ Args:
+ in_features (`int`):
+ Number of input channels in the main feature.
+ condition_dim (`int`):
+ Number of input channels in the condition feature.
+ n_classes (`int`, *optional*, defaults to 256):
+ Number of classes.
+ bottleneck_factor (`int`, *optional*, defaults to 2):
+ Hidden dim factor.
+
+ """
+ super().__init__()
+
+ bottleneck = (in_features + condition_dim) // bottleneck_factor
+ self.mlp = nn.Sequential(
+ nn.Conv2d(in_features + condition_dim, bottleneck, kernel_size=1, stride=1, padding=0),
+ nn.GELU(),
+ # 2 for probabilities linear norm, 2 for temperature linear norm
+ nn.Conv2d(bottleneck, 2 + 2, kernel_size=1, stride=1, padding=0),
+ nn.Softplus(),
+ )
+
+ self.p_eps = 1e-4
+ self.max_temp = config.max_temp
+ self.min_temp = config.min_temp
+ self.log_binomial_transform = LogBinomialSoftmax(n_classes, act=torch.softmax)
+
+ def forward(self, main_feature, condition_feature):
+ """
+ Args:
+ main_feature (`torch.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Main feature.
+ condition_feature (torch.Tensor of shape `(batch_size, num_channels, height, width)`):
+ Condition feature.
+
+ Returns:
+ `torch.Tensor`:
+ Output log binomial distribution
+ """
+ probabilities_and_temperature = self.mlp(torch.concat((main_feature, condition_feature), dim=1))
+ probabilities, temperature = (
+ probabilities_and_temperature[:, :2, ...],
+ probabilities_and_temperature[:, 2:, ...],
+ )
+
+ probabilities = probabilities + self.p_eps
+ probabilities = probabilities[:, 0, ...] / (probabilities[:, 0, ...] + probabilities[:, 1, ...])
+
+ temperature = temperature + self.p_eps
+ temperature = temperature[:, 0, ...] / (temperature[:, 0, ...] + temperature[:, 1, ...])
+ temperature = temperature.unsqueeze(1)
+ temperature = (self.max_temp - self.min_temp) * temperature + self.min_temp
+
+ return self.log_binomial_transform(probabilities, temperature)
+
+
+class ZoeDepthSeedBinRegressor(nn.Module):
+ def __init__(self, config, n_bins=16, mlp_dim=256, min_depth=1e-3, max_depth=10):
+ """Bin center regressor network.
+
+ Can be "normed" or "unnormed". If "normed", bin centers are bounded on the (min_depth, max_depth) interval.
+
+ Args:
+ config (`int`):
+ Model configuration.
+ n_bins (`int`, *optional*, defaults to 16):
+ Number of bin centers.
+ mlp_dim (`int`, *optional*, defaults to 256):
+ Hidden dimension.
+ min_depth (`float`, *optional*, defaults to 1e-3):
+ Min depth value.
+ max_depth (`float`, *optional*, defaults to 10):
+ Max depth value.
+ """
+ super().__init__()
+
+ self.in_features = config.bottleneck_features
+ self.bin_centers_type = config.bin_centers_type
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+
+ self.conv1 = nn.Conv2d(self.in_features, mlp_dim, 1, 1, 0)
+ self.act1 = nn.ReLU(inplace=True)
+ self.conv2 = nn.Conv2d(mlp_dim, n_bins, 1, 1, 0)
+ self.act2 = nn.ReLU(inplace=True) if self.bin_centers_type == "normed" else nn.Softplus()
+
+ def forward(self, x):
+ """
+ Returns tensor of bin_width vectors (centers). One vector b for every pixel
+ """
+ x = self.conv1(x)
+ x = self.act1(x)
+ x = self.conv2(x)
+ bin_centers = self.act2(x)
+
+ if self.bin_centers_type == "normed":
+ bin_centers = bin_centers + 1e-3
+ bin_widths_normed = bin_centers / bin_centers.sum(dim=1, keepdim=True)
+ # shape (batch_size, num_channels, height, width)
+ bin_widths = (self.max_depth - self.min_depth) * bin_widths_normed
+ # pad has the form (left, right, top, bottom, front, back)
+ bin_widths = nn.functional.pad(bin_widths, (0, 0, 0, 0, 1, 0), mode="constant", value=self.min_depth)
+ # shape (batch_size, num_channels, height, width)
+ bin_edges = torch.cumsum(bin_widths, dim=1)
+
+ bin_centers = 0.5 * (bin_edges[:, :-1, ...] + bin_edges[:, 1:, ...])
+ return bin_widths_normed, bin_centers
+
+ else:
+ return bin_centers, bin_centers
+
+
+@torch.jit.script
+def inv_attractor(dx, alpha: float = 300, gamma: int = 2):
+ """Inverse attractor: dc = dx / (1 + alpha*dx^gamma), where dx = a - c, a = attractor point, c = bin center, dc = shift in bin center
+ This is the default one according to the accompanying paper.
+
+ Args:
+ dx (`torch.Tensor`):
+ The difference tensor dx = Ai - Cj, where Ai is the attractor point and Cj is the bin center.
+ alpha (`float`, *optional*, defaults to 300):
+ Proportional Attractor strength. Determines the absolute strength. Lower alpha = greater attraction.
+ gamma (`int`, *optional*, defaults to 2):
+ Exponential Attractor strength. Determines the "region of influence" and indirectly number of bin centers affected.
+ Lower gamma = farther reach.
+
+ Returns:
+ torch.Tensor: Delta shifts - dc; New bin centers = Old bin centers + dc
+ """
+ return dx.div(1 + alpha * dx.pow(gamma))
+
+
+class ZoeDepthAttractorLayer(nn.Module):
+ def __init__(
+ self,
+ config,
+ n_bins,
+ n_attractors=16,
+ min_depth=1e-3,
+ max_depth=10,
+ memory_efficient=False,
+ ):
+ """
+ Attractor layer for bin centers. Bin centers are bounded on the interval (min_depth, max_depth)
+ """
+ super().__init__()
+
+ self.alpha = config.attractor_alpha
+ self.gemma = config.attractor_gamma
+ self.kind = config.attractor_kind
+
+ self.n_attractors = n_attractors
+ self.n_bins = n_bins
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+ self.memory_efficient = memory_efficient
+
+ # MLP to predict attractor points
+ in_features = mlp_dim = config.bin_embedding_dim
+ self.conv1 = nn.Conv2d(in_features, mlp_dim, 1, 1, 0)
+ self.act1 = nn.ReLU(inplace=True)
+ self.conv2 = nn.Conv2d(mlp_dim, n_attractors * 2, 1, 1, 0) # x2 for linear norm
+ self.act2 = nn.ReLU(inplace=True)
+
+ def forward(self, x, prev_bin, prev_bin_embedding=None, interpolate=True):
+ """
+ The forward pass of the attractor layer. This layer predicts the new bin centers based on the previous bin centers
+ and the attractor points (the latter are predicted by the MLP).
+
+ Args:
+ x (`torch.Tensor` of shape `(batch_size, num_channels, height, width)`):
+ Feature block.
+ prev_bin (`torch.Tensor` of shape `(batch_size, prev_number_of_bins, height, width)`):
+ Previous bin centers normed.
+ prev_bin_embedding (`torch.Tensor`, *optional*):
+ Optional previous bin embeddings.
+ interpolate (`bool`, *optional*, defaults to `True`):
+ Whether to interpolate the previous bin embeddings to the size of the input features.
+
+ Returns:
+ `tuple[`torch.Tensor`, `torch.Tensor`]:
+ New bin centers normed and scaled.
+ """
+ if prev_bin_embedding is not None:
+ if interpolate:
+ prev_bin_embedding = nn.functional.interpolate(
+ prev_bin_embedding, x.shape[-2:], mode="bilinear", align_corners=True
+ )
+ x = x + prev_bin_embedding
+
+ x = self.conv1(x)
+ x = self.act1(x)
+ x = self.conv2(x)
+ attractors = self.act2(x)
+
+ attractors = attractors + 1e-3
+ batch_size, _, height, width = attractors.shape
+ attractors = attractors.view(batch_size, self.n_attractors, 2, height, width)
+ # batch_size, num_attractors, 2, height, width
+ # note: original repo had a bug here: https://github.com/isl-org/ZoeDepth/blame/edb6daf45458569e24f50250ef1ed08c015f17a7/zoedepth/models/layers/attractor.py#L105C9-L106C50
+ # we include the bug to maintain compatibility with the weights
+ attractors_normed = attractors[:, :, 0, ...] # batch_size, batch_size*num_attractors, height, width
+
+ bin_centers = nn.functional.interpolate(prev_bin, (height, width), mode="bilinear", align_corners=True)
+
+ # note: only attractor_type = "exp" is supported here, since no checkpoints were released with other attractor types
+
+ if not self.memory_efficient:
+ func = {"mean": torch.mean, "sum": torch.sum}[self.kind]
+ # shape (batch_size, num_bins, height, width)
+ delta_c = func(inv_attractor(attractors_normed.unsqueeze(2) - bin_centers.unsqueeze(1)), dim=1)
+ else:
+ delta_c = torch.zeros_like(bin_centers, device=bin_centers.device)
+ for i in range(self.n_attractors):
+ # shape (batch_size, num_bins, height, width)
+ delta_c += inv_attractor(attractors_normed[:, i, ...].unsqueeze(1) - bin_centers)
+
+ if self.kind == "mean":
+ delta_c = delta_c / self.n_attractors
+
+ bin_new_centers = bin_centers + delta_c
+ bin_centers = (self.max_depth - self.min_depth) * bin_new_centers + self.min_depth
+ bin_centers, _ = torch.sort(bin_centers, dim=1)
+ bin_centers = torch.clip(bin_centers, self.min_depth, self.max_depth)
+ return bin_new_centers, bin_centers
+
+
+class ZoeDepthAttractorLayerUnnormed(nn.Module):
+ def __init__(
+ self,
+ config,
+ n_bins,
+ n_attractors=16,
+ min_depth=1e-3,
+ max_depth=10,
+ memory_efficient=True,
+ ):
+ """
+ Attractor layer for bin centers. Bin centers are unbounded
+ """
+ super().__init__()
+
+ self.n_attractors = n_attractors
+ self.n_bins = n_bins
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+ self.alpha = config.attractor_alpha
+ self.gamma = config.attractor_alpha
+ self.kind = config.attractor_kind
+ self.memory_efficient = memory_efficient
+
+ in_features = mlp_dim = config.bin_embedding_dim
+ self.conv1 = nn.Conv2d(in_features, mlp_dim, 1, 1, 0)
+ self.act1 = nn.ReLU(inplace=True)
+ self.conv2 = nn.Conv2d(mlp_dim, n_attractors, 1, 1, 0)
+ self.act2 = nn.Softplus()
+
+ def forward(self, x, prev_bin, prev_bin_embedding=None, interpolate=True):
+ """
+ The forward pass of the attractor layer. This layer predicts the new bin centers based on the previous bin centers
+ and the attractor points (the latter are predicted by the MLP).
+
+ Args:
+ x (`torch.Tensor` of shape (batch_size, num_channels, height, width)`):
+ Feature block.
+ prev_bin (`torch.Tensor` of shape (batch_size, prev_num_bins, height, width)`):
+ Previous bin centers normed.
+ prev_bin_embedding (`torch.Tensor`, *optional*):
+ Optional previous bin embeddings.
+ interpolate (`bool`, *optional*, defaults to `True`):
+ Whether to interpolate the previous bin embeddings to the size of the input features.
+
+ Returns:
+ `tuple[`torch.Tensor`, `torch.Tensor`]:
+ New bin centers unbounded. Two outputs just to keep the API consistent with the normed version.
+ """
+ if prev_bin_embedding is not None:
+ if interpolate:
+ prev_bin_embedding = nn.functional.interpolate(
+ prev_bin_embedding, x.shape[-2:], mode="bilinear", align_corners=True
+ )
+ x = x + prev_bin_embedding
+
+ x = self.conv1(x)
+ x = self.act1(x)
+ x = self.conv2(x)
+ attractors = self.act2(x)
+
+ height, width = attractors.shape[-2:]
+
+ bin_centers = nn.functional.interpolate(prev_bin, (height, width), mode="bilinear", align_corners=True)
+
+ if not self.memory_efficient:
+ func = {"mean": torch.mean, "sum": torch.sum}[self.kind]
+ # shape batch_size, num_bins, height, width
+ delta_c = func(inv_attractor(attractors.unsqueeze(2) - bin_centers.unsqueeze(1)), dim=1)
+ else:
+ delta_c = torch.zeros_like(bin_centers, device=bin_centers.device)
+ for i in range(self.n_attractors):
+ # shape batch_size, num_bins, height, width
+ delta_c += inv_attractor(attractors[:, i, ...].unsqueeze(1) - bin_centers)
+
+ if self.kind == "mean":
+ delta_c = delta_c / self.n_attractors
+
+ bin_new_centers = bin_centers + delta_c
+ bin_centers = bin_new_centers
+
+ return bin_new_centers, bin_centers
+
+
+class ZoeDepthProjector(nn.Module):
+ def __init__(self, in_features, out_features, mlp_dim=128):
+ """Projector MLP.
+
+ Args:
+ in_features (`int`):
+ Number of input channels.
+ out_features (`int`):
+ Number of output channels.
+ mlp_dim (`int`, *optional*, defaults to 128):
+ Hidden dimension.
+ """
+ super().__init__()
+
+ self.conv1 = nn.Conv2d(in_features, mlp_dim, 1, 1, 0)
+ self.act = nn.ReLU(inplace=True)
+ self.conv2 = nn.Conv2d(mlp_dim, out_features, 1, 1, 0)
+
+ def forward(self, hidden_state: torch.Tensor) -> torch.Tensor:
+ hidden_state = self.conv1(hidden_state)
+ hidden_state = self.act(hidden_state)
+ hidden_state = self.conv2(hidden_state)
+
+ return hidden_state
+
+
+# Copied from transformers.models.grounding_dino.modeling_grounding_dino.GroundingDinoMultiheadAttention with GroundingDino->ZoeDepth
+class ZoeDepthMultiheadAttention(nn.Module):
+ """Equivalent implementation of nn.MultiheadAttention with `batch_first=True`."""
+
+ # Ignore copy
+ def __init__(self, hidden_size, num_attention_heads, dropout):
+ super().__init__()
+ if hidden_size % num_attention_heads != 0:
+ raise ValueError(
+ f"The hidden size ({hidden_size}) is not a multiple of the number of attention "
+ f"heads ({num_attention_heads})"
+ )
+
+ self.num_attention_heads = num_attention_heads
+ self.attention_head_size = int(hidden_size / num_attention_heads)
+ self.all_head_size = self.num_attention_heads * self.attention_head_size
+
+ self.query = nn.Linear(hidden_size, self.all_head_size)
+ self.key = nn.Linear(hidden_size, self.all_head_size)
+ self.value = nn.Linear(hidden_size, self.all_head_size)
+
+ self.out_proj = nn.Linear(hidden_size, hidden_size)
+
+ self.dropout = nn.Dropout(dropout)
+
+ def forward(
+ self,
+ queries: torch.Tensor,
+ keys: torch.Tensor,
+ values: torch.Tensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ output_attentions: Optional[bool] = False,
+ ) -> tuple[torch.Tensor]:
+ batch_size, seq_length, _ = queries.shape
+ query_layer = (
+ self.query(queries)
+ .view(batch_size, -1, self.num_attention_heads, self.attention_head_size)
+ .transpose(1, 2)
+ )
+ key_layer = (
+ self.key(keys).view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ )
+ value_layer = (
+ self.value(values).view(batch_size, -1, self.num_attention_heads, self.attention_head_size).transpose(1, 2)
+ )
+
+ # Take the dot product between "query" and "key" to get the raw attention scores.
+ attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2))
+
+ attention_scores = attention_scores / math.sqrt(self.attention_head_size)
+ if attention_mask is not None:
+ # Apply the attention mask is (precomputed for all layers in ZoeDepthModel forward() function)
+ attention_scores = attention_scores + attention_mask
+
+ # Normalize the attention scores to probabilities.
+ attention_probs = nn.functional.softmax(attention_scores, dim=-1)
+
+ # This is actually dropping out entire tokens to attend to, which might
+ # seem a bit unusual, but is taken from the original Transformer paper.
+ attention_probs = self.dropout(attention_probs)
+
+ context_layer = torch.matmul(attention_probs, value_layer)
+
+ context_layer = context_layer.permute(0, 2, 1, 3).contiguous()
+ new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,)
+ context_layer = context_layer.view(new_context_layer_shape)
+
+ context_layer = self.out_proj(context_layer)
+
+ outputs = (context_layer, attention_probs) if output_attentions else (context_layer,)
+
+ return outputs
+
+
+class ZoeDepthTransformerEncoderLayer(nn.Module):
+ def __init__(self, config, dropout=0.1, activation="relu"):
+ super().__init__()
+
+ hidden_size = config.patch_transformer_hidden_size
+ intermediate_size = config.patch_transformer_intermediate_size
+ num_attention_heads = config.patch_transformer_num_attention_heads
+
+ self.self_attn = ZoeDepthMultiheadAttention(hidden_size, num_attention_heads, dropout=dropout)
+
+ self.linear1 = nn.Linear(hidden_size, intermediate_size)
+ self.dropout = nn.Dropout(dropout)
+ self.linear2 = nn.Linear(intermediate_size, hidden_size)
+
+ self.norm1 = nn.LayerNorm(hidden_size)
+ self.norm2 = nn.LayerNorm(hidden_size)
+ self.dropout1 = nn.Dropout(dropout)
+ self.dropout2 = nn.Dropout(dropout)
+
+ self.activation = ACT2FN[activation]
+
+ def forward(
+ self,
+ src,
+ src_mask: Optional[torch.Tensor] = None,
+ ):
+ queries = keys = src
+ src2 = self.self_attn(queries=queries, keys=keys, values=src, attention_mask=src_mask)[0]
+ src = src + self.dropout1(src2)
+ src = self.norm1(src)
+ src2 = self.linear2(self.dropout(self.activation(self.linear1(src))))
+ src = src + self.dropout2(src2)
+ src = self.norm2(src)
+ return src
+
+
+class ZoeDepthPatchTransformerEncoder(nn.Module):
+ def __init__(self, config):
+ """ViT-like transformer block
+
+ Args:
+ config (`ZoeDepthConfig`):
+ Model configuration class defining the model architecture.
+ """
+ super().__init__()
+
+ in_channels = config.bottleneck_features
+
+ self.transformer_encoder = nn.ModuleList(
+ [ZoeDepthTransformerEncoderLayer(config) for _ in range(config.num_patch_transformer_layers)]
+ )
+
+ self.embedding_convPxP = nn.Conv2d(
+ in_channels, config.patch_transformer_hidden_size, kernel_size=1, stride=1, padding=0
+ )
+
+ def positional_encoding_1d(self, batch_size, sequence_length, embedding_dim, device="cpu", dtype=torch.float32):
+ """Generate positional encodings
+
+ Args:
+ sequence_length (int): Sequence length
+ embedding_dim (int): Embedding dimension
+
+ Returns:
+ torch.Tensor: Positional encodings.
+ """
+ position = torch.arange(0, sequence_length, dtype=dtype, device=device).unsqueeze(1)
+ index = torch.arange(0, embedding_dim, 2, dtype=dtype, device=device).unsqueeze(0)
+ div_term = torch.exp(index * (-torch.log(torch.tensor(10000.0, device=device)) / embedding_dim))
+ pos_encoding = position * div_term
+ pos_encoding = torch.cat([torch.sin(pos_encoding), torch.cos(pos_encoding)], dim=1)
+ pos_encoding = pos_encoding.unsqueeze(dim=0).repeat(batch_size, 1, 1)
+ return pos_encoding
+
+ def forward(self, x):
+ """Forward pass
+
+ Args:
+ x (torch.Tensor - NCHW): Input feature tensor
+
+ Returns:
+ torch.Tensor - Transformer output embeddings of shape (batch_size, sequence_length, embedding_dim)
+ """
+ embeddings = self.embedding_convPxP(x).flatten(2) # shape (batch_size, num_channels, sequence_length)
+ # add an extra special CLS token at the start for global accumulation
+ embeddings = nn.functional.pad(embeddings, (1, 0))
+
+ embeddings = embeddings.permute(0, 2, 1)
+ batch_size, sequence_length, embedding_dim = embeddings.shape
+ embeddings = embeddings + self.positional_encoding_1d(
+ batch_size, sequence_length, embedding_dim, device=embeddings.device, dtype=embeddings.dtype
+ )
+
+ for i in range(4):
+ embeddings = self.transformer_encoder[i](embeddings)
+
+ return embeddings
+
+
+class ZoeDepthMLPClassifier(nn.Module):
+ def __init__(self, in_features, out_features) -> None:
+ super().__init__()
+
+ hidden_features = in_features
+ self.linear1 = nn.Linear(in_features, hidden_features)
+ self.activation = nn.ReLU()
+ self.linear2 = nn.Linear(hidden_features, out_features)
+
+ def forward(self, hidden_state):
+ hidden_state = self.linear1(hidden_state)
+ hidden_state = self.activation(hidden_state)
+ domain_logits = self.linear2(hidden_state)
+
+ return domain_logits
+
+
+class ZoeDepthMultipleMetricDepthEstimationHeads(nn.Module):
+ """
+ Multiple metric depth estimation heads. A MLP classifier is used to route between 2 different heads.
+ """
+
+ def __init__(self, config):
+ super().__init__()
+
+ bin_embedding_dim = config.bin_embedding_dim
+ n_attractors = config.num_attractors
+ self.bin_configurations = config.bin_configurations
+ self.bin_centers_type = config.bin_centers_type
+
+ # Bottleneck convolution
+ bottleneck_features = config.bottleneck_features
+ self.conv2 = nn.Conv2d(bottleneck_features, bottleneck_features, kernel_size=1, stride=1, padding=0)
+
+ # Transformer classifier on the bottleneck
+ self.patch_transformer = ZoeDepthPatchTransformerEncoder(config)
+ # MLP classifier
+ self.mlp_classifier = ZoeDepthMLPClassifier(in_features=128, out_features=2)
+
+ # Regressor and attractor
+ if self.bin_centers_type == "normed":
+ Attractor = ZoeDepthAttractorLayer
+ elif self.bin_centers_type == "softplus":
+ Attractor = ZoeDepthAttractorLayerUnnormed
+ # We have bins for each bin configuration
+ # Create a map (ModuleDict) of 'name' -> seed_bin_regressor
+ self.seed_bin_regressors = nn.ModuleDict(
+ {
+ conf["name"]: ZoeDepthSeedBinRegressor(
+ config,
+ n_bins=conf["n_bins"],
+ mlp_dim=bin_embedding_dim // 2,
+ min_depth=conf["min_depth"],
+ max_depth=conf["max_depth"],
+ )
+ for conf in config.bin_configurations
+ }
+ )
+
+ self.seed_projector = ZoeDepthProjector(
+ in_features=bottleneck_features, out_features=bin_embedding_dim, mlp_dim=bin_embedding_dim // 2
+ )
+ self.projectors = nn.ModuleList(
+ [
+ ZoeDepthProjector(
+ in_features=config.fusion_hidden_size,
+ out_features=bin_embedding_dim,
+ mlp_dim=bin_embedding_dim // 2,
+ )
+ for _ in range(4)
+ ]
+ )
+
+ # Create a map (ModuleDict) of 'name' -> attractors (ModuleList)
+ self.attractors = nn.ModuleDict(
+ {
+ configuration["name"]: nn.ModuleList(
+ [
+ Attractor(
+ config,
+ n_bins=n_attractors[i],
+ min_depth=configuration["min_depth"],
+ max_depth=configuration["max_depth"],
+ )
+ for i in range(len(n_attractors))
+ ]
+ )
+ for configuration in config.bin_configurations
+ }
+ )
+
+ last_in = config.num_relative_features
+ # conditional log binomial for each bin configuration
+ self.conditional_log_binomial = nn.ModuleDict(
+ {
+ configuration["name"]: ZoeDepthConditionalLogBinomialSoftmax(
+ config,
+ last_in,
+ bin_embedding_dim,
+ configuration["n_bins"],
+ bottleneck_factor=4,
+ )
+ for configuration in config.bin_configurations
+ }
+ )
+
+ def forward(self, outconv_activation, bottleneck, feature_blocks, relative_depth):
+ x = self.conv2(bottleneck)
+
+ # Predict which path to take
+ # Embedding is of shape (batch_size, hidden_size)
+ embedding = self.patch_transformer(x)[:, 0, :]
+
+ # MLP classifier to get logits of shape (batch_size, 2)
+ domain_logits = self.mlp_classifier(embedding)
+ domain_vote = torch.softmax(domain_logits.sum(dim=0, keepdim=True), dim=-1)
+
+ # Get the path
+ names = [configuration["name"] for configuration in self.bin_configurations]
+ bin_configurations_name = names[torch.argmax(domain_vote, dim=-1).squeeze().item()]
+
+ try:
+ conf = [config for config in self.bin_configurations if config["name"] == bin_configurations_name][0]
+ except IndexError:
+ raise ValueError(f"bin_configurations_name {bin_configurations_name} not found in bin_configurationss")
+
+ min_depth = conf["min_depth"]
+ max_depth = conf["max_depth"]
+
+ seed_bin_regressor = self.seed_bin_regressors[bin_configurations_name]
+ _, seed_bin_centers = seed_bin_regressor(x)
+ if self.bin_centers_type in ["normed", "hybrid2"]:
+ prev_bin = (seed_bin_centers - min_depth) / (max_depth - min_depth)
+ else:
+ prev_bin = seed_bin_centers
+ prev_bin_embedding = self.seed_projector(x)
+
+ attractors = self.attractors[bin_configurations_name]
+ for projector, attractor, feature in zip(self.projectors, attractors, feature_blocks):
+ bin_embedding = projector(feature)
+ bin, bin_centers = attractor(bin_embedding, prev_bin, prev_bin_embedding, interpolate=True)
+ prev_bin = bin
+ prev_bin_embedding = bin_embedding
+
+ last = outconv_activation
+
+ bin_centers = nn.functional.interpolate(bin_centers, last.shape[-2:], mode="bilinear", align_corners=True)
+ bin_embedding = nn.functional.interpolate(bin_embedding, last.shape[-2:], mode="bilinear", align_corners=True)
+
+ conditional_log_binomial = self.conditional_log_binomial[bin_configurations_name]
+ x = conditional_log_binomial(last, bin_embedding)
+
+ # Now depth value is Sum px * cx , where cx are bin_centers from the last bin tensor
+ out = torch.sum(x * bin_centers, dim=1, keepdim=True)
+
+ return out, domain_logits
+
+
+class ZoeDepthMetricDepthEstimationHead(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+
+ bin_configuration = config.bin_configurations[0]
+ n_bins = bin_configuration["n_bins"]
+ min_depth = bin_configuration["min_depth"]
+ max_depth = bin_configuration["max_depth"]
+ bin_embedding_dim = config.bin_embedding_dim
+ n_attractors = config.num_attractors
+ bin_centers_type = config.bin_centers_type
+
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+ self.bin_centers_type = bin_centers_type
+
+ # Bottleneck convolution
+ bottleneck_features = config.bottleneck_features
+ self.conv2 = nn.Conv2d(bottleneck_features, bottleneck_features, kernel_size=1, stride=1, padding=0)
+
+ # Regressor and attractor
+ if self.bin_centers_type == "normed":
+ Attractor = ZoeDepthAttractorLayer
+ elif self.bin_centers_type == "softplus":
+ Attractor = ZoeDepthAttractorLayerUnnormed
+
+ self.seed_bin_regressor = ZoeDepthSeedBinRegressor(
+ config, n_bins=n_bins, min_depth=min_depth, max_depth=max_depth
+ )
+ self.seed_projector = ZoeDepthProjector(in_features=bottleneck_features, out_features=bin_embedding_dim)
+
+ self.projectors = nn.ModuleList(
+ [
+ ZoeDepthProjector(in_features=config.fusion_hidden_size, out_features=bin_embedding_dim)
+ for _ in range(4)
+ ]
+ )
+ self.attractors = nn.ModuleList(
+ [
+ Attractor(
+ config,
+ n_bins=n_bins,
+ n_attractors=n_attractors[i],
+ min_depth=min_depth,
+ max_depth=max_depth,
+ )
+ for i in range(4)
+ ]
+ )
+
+ last_in = config.num_relative_features + 1 # +1 for relative depth
+
+ # use log binomial instead of softmax
+ self.conditional_log_binomial = ZoeDepthConditionalLogBinomialSoftmax(
+ config,
+ last_in,
+ bin_embedding_dim,
+ n_classes=n_bins,
+ )
+
+ def forward(self, outconv_activation, bottleneck, feature_blocks, relative_depth):
+ x = self.conv2(bottleneck)
+ _, seed_bin_centers = self.seed_bin_regressor(x)
+
+ if self.bin_centers_type in ["normed", "hybrid2"]:
+ prev_bin = (seed_bin_centers - self.min_depth) / (self.max_depth - self.min_depth)
+ else:
+ prev_bin = seed_bin_centers
+
+ prev_bin_embedding = self.seed_projector(x)
+
+ # unroll this loop for better performance
+ for projector, attractor, feature in zip(self.projectors, self.attractors, feature_blocks):
+ bin_embedding = projector(feature)
+ bin, bin_centers = attractor(bin_embedding, prev_bin, prev_bin_embedding, interpolate=True)
+ prev_bin = bin.clone()
+ prev_bin_embedding = bin_embedding.clone()
+
+ last = outconv_activation
+
+ # concatenative relative depth with last. First interpolate relative depth to last size
+ relative_conditioning = relative_depth.unsqueeze(1)
+ relative_conditioning = nn.functional.interpolate(
+ relative_conditioning, size=last.shape[2:], mode="bilinear", align_corners=True
+ )
+ last = torch.cat([last, relative_conditioning], dim=1)
+
+ bin_embedding = nn.functional.interpolate(bin_embedding, last.shape[-2:], mode="bilinear", align_corners=True)
+ x = self.conditional_log_binomial(last, bin_embedding)
+
+ # Now depth value is Sum px * cx , where cx are bin_centers from the last bin tensor
+ bin_centers = nn.functional.interpolate(bin_centers, x.shape[-2:], mode="bilinear", align_corners=True)
+ out = torch.sum(x * bin_centers, dim=1, keepdim=True)
+
+ return out, None
+
+
+# Modified from transformers.models.dpt.modeling_dpt.DPTPreTrainedModel with DPT->ZoeDepth,dpt->zoedepth
+# avoiding sdpa and flash_attn_2 support, it's done int the backend
+@auto_docstring
+class ZoeDepthPreTrainedModel(PreTrainedModel):
+ config: ZoeDepthConfig
+ base_model_prefix = "zoedepth"
+ main_input_name = "pixel_values"
+ supports_gradient_checkpointing = True
+
+ def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, (nn.Linear, nn.Conv2d, nn.ConvTranspose2d)):
+ # Slightly different from the TF version which uses truncated_normal for initialization
+ # cf https://github.com/pytorch/pytorch/pull/5617
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+
+
+@auto_docstring(
+ custom_intro="""
+ ZoeDepth model with one or multiple metric depth estimation head(s) on top.
+ """
+)
+class ZoeDepthForDepthEstimation(ZoeDepthPreTrainedModel):
+ def __init__(self, config):
+ super().__init__(config)
+
+ self.backbone = load_backbone(config)
+
+ if hasattr(self.backbone.config, "hidden_size") and hasattr(self.backbone.config, "patch_size"):
+ config.backbone_hidden_size = self.backbone.config.hidden_size
+ self.patch_size = self.backbone.config.patch_size
+ else:
+ raise ValueError(
+ "ZoeDepth assumes the backbone's config to have `hidden_size` and `patch_size` attributes"
+ )
+
+ self.neck = ZoeDepthNeck(config)
+ self.relative_head = ZoeDepthRelativeDepthEstimationHead(config)
+
+ self.metric_head = (
+ ZoeDepthMultipleMetricDepthEstimationHeads(config)
+ if len(config.bin_configurations) > 1
+ else ZoeDepthMetricDepthEstimationHead(config)
+ )
+
+ # Initialize weights and apply final processing
+ self.post_init()
+
+ @auto_docstring
+ def forward(
+ self,
+ pixel_values: torch.FloatTensor,
+ labels: Optional[torch.LongTensor] = None,
+ output_attentions: Optional[bool] = None,
+ output_hidden_states: Optional[bool] = None,
+ return_dict: Optional[bool] = None,
+ ) -> Union[tuple[torch.Tensor], DepthEstimatorOutput]:
+ r"""
+ labels (`torch.LongTensor` of shape `(batch_size, height, width)`, *optional*):
+ Ground truth depth estimation maps for computing the loss.
+
+ Examples:
+ ```python
+ >>> from transformers import AutoImageProcessor, ZoeDepthForDepthEstimation
+ >>> import torch
+ >>> import numpy as np
+ >>> from PIL import Image
+ >>> import requests
+
+ >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ >>> image = Image.open(requests.get(url, stream=True).raw)
+
+ >>> image_processor = AutoImageProcessor.from_pretrained("Intel/zoedepth-nyu-kitti")
+ >>> model = ZoeDepthForDepthEstimation.from_pretrained("Intel/zoedepth-nyu-kitti")
+
+ >>> # prepare image for the model
+ >>> inputs = image_processor(images=image, return_tensors="pt")
+
+ >>> with torch.no_grad():
+ ... outputs = model(**inputs)
+
+ >>> # interpolate to original size
+ >>> post_processed_output = image_processor.post_process_depth_estimation(
+ ... outputs,
+ ... source_sizes=[(image.height, image.width)],
+ ... )
+
+ >>> # visualize the prediction
+ >>> predicted_depth = post_processed_output[0]["predicted_depth"]
+ >>> depth = predicted_depth * 255 / predicted_depth.max()
+ >>> depth = depth.detach().cpu().numpy()
+ >>> depth = Image.fromarray(depth.astype("uint8"))
+ ```"""
+ loss = None
+ if labels is not None:
+ raise NotImplementedError("Training is not implemented yet")
+
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
+
+ outputs = self.backbone.forward_with_filtered_kwargs(
+ pixel_values, output_hidden_states=output_hidden_states, output_attentions=output_attentions
+ )
+ hidden_states = outputs.feature_maps
+
+ _, _, height, width = pixel_values.shape
+ patch_size = self.patch_size
+ patch_height = height // patch_size
+ patch_width = width // patch_size
+
+ hidden_states, features = self.neck(hidden_states, patch_height, patch_width)
+
+ out = [features] + hidden_states
+
+ relative_depth, features = self.relative_head(hidden_states)
+
+ out = [features] + out
+
+ metric_depth, domain_logits = self.metric_head(
+ outconv_activation=out[0], bottleneck=out[1], feature_blocks=out[2:], relative_depth=relative_depth
+ )
+ metric_depth = metric_depth.squeeze(dim=1)
+
+ if not return_dict:
+ if domain_logits is not None:
+ output = (metric_depth, domain_logits) + outputs[1:]
+ else:
+ output = (metric_depth,) + outputs[1:]
+
+ return ((loss,) + output) if loss is not None else output
+
+ return ZoeDepthDepthEstimatorOutput(
+ loss=loss,
+ predicted_depth=metric_depth,
+ domain_logits=domain_logits,
+ hidden_states=outputs.hidden_states,
+ attentions=outputs.attentions,
+ )
+
+
+__all__ = ["ZoeDepthForDepthEstimation", "ZoeDepthPreTrainedModel"]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..33350c83a2c161ee228677e8f6fc4b495e9c05bb
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/__init__.py
@@ -0,0 +1,49 @@
+# Copyright 2020 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import TYPE_CHECKING
+
+from ..utils import _LazyModule
+
+
+_import_structure = {
+ "config": [
+ "EXTERNAL_DATA_FORMAT_SIZE_LIMIT",
+ "OnnxConfig",
+ "OnnxConfigWithPast",
+ "OnnxSeq2SeqConfigWithPast",
+ "PatchingSpec",
+ ],
+ "convert": ["export", "validate_model_outputs"],
+ "features": ["FeaturesManager"],
+ "utils": ["ParameterFormat", "compute_serialized_parameters_size"],
+}
+
+
+if TYPE_CHECKING:
+ from .config import (
+ EXTERNAL_DATA_FORMAT_SIZE_LIMIT,
+ OnnxConfig,
+ OnnxConfigWithPast,
+ OnnxSeq2SeqConfigWithPast,
+ PatchingSpec,
+ )
+ from .convert import export, validate_model_outputs
+ from .features import FeaturesManager
+ from .utils import ParameterFormat, compute_serialized_parameters_size
+
+else:
+ import sys
+
+ sys.modules[__name__] = _LazyModule(__name__, globals()["__file__"], _import_structure, module_spec=__spec__)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/__main__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/__main__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e3dc6dfb78aa16fa32ea4a30eb4933a0653c7264
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/__main__.py
@@ -0,0 +1,242 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import subprocess
+import sys
+import warnings
+from argparse import ArgumentParser
+from pathlib import Path
+
+from packaging import version
+
+from .. import AutoFeatureExtractor, AutoImageProcessor, AutoProcessor, AutoTokenizer
+from ..utils import logging
+from ..utils.import_utils import is_optimum_available
+from .convert import export, validate_model_outputs
+from .features import FeaturesManager
+from .utils import get_preprocessor
+
+
+MIN_OPTIMUM_VERSION = "1.5.0"
+
+ENCODER_DECODER_MODELS = ["vision-encoder-decoder"]
+
+
+def export_with_optimum(args):
+ if is_optimum_available():
+ from optimum.version import __version__ as optimum_version
+
+ parsed_optimum_version = version.parse(optimum_version)
+ if parsed_optimum_version < version.parse(MIN_OPTIMUM_VERSION):
+ raise RuntimeError(
+ f"transformers.onnx requires optimum >= {MIN_OPTIMUM_VERSION} but {optimum_version} is installed. You "
+ "can upgrade optimum by running: pip install -U optimum[exporters]"
+ )
+ else:
+ raise RuntimeError(
+ "transformers.onnx requires optimum to run, you can install the library by running: pip install "
+ "optimum[exporters]"
+ )
+ cmd_line = [
+ sys.executable,
+ "-m",
+ "optimum.exporters.onnx",
+ f"--model {args.model}",
+ f"--task {args.feature}",
+ f"--framework {args.framework}" if args.framework is not None else "",
+ f"{args.output}",
+ ]
+ proc = subprocess.Popen(cmd_line, stdout=subprocess.PIPE)
+ proc.wait()
+
+ logger.info(
+ "The export was done by optimum.exporters.onnx. We recommend using to use this package directly in future, as "
+ "transformers.onnx is deprecated, and will be removed in v5. You can find more information here: "
+ "https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model."
+ )
+
+
+def export_with_transformers(args):
+ args.output = args.output if args.output.is_file() else args.output.joinpath("model.onnx")
+ if not args.output.parent.exists():
+ args.output.parent.mkdir(parents=True)
+
+ # Allocate the model
+ model = FeaturesManager.get_model_from_feature(
+ args.feature, args.model, framework=args.framework, cache_dir=args.cache_dir
+ )
+
+ model_kind, model_onnx_config = FeaturesManager.check_supported_model_or_raise(model, feature=args.feature)
+ onnx_config = model_onnx_config(model.config)
+
+ if model_kind in ENCODER_DECODER_MODELS:
+ encoder_model = model.get_encoder()
+ decoder_model = model.get_decoder()
+
+ encoder_onnx_config = onnx_config.get_encoder_config(encoder_model.config)
+ decoder_onnx_config = onnx_config.get_decoder_config(
+ encoder_model.config, decoder_model.config, feature=args.feature
+ )
+
+ if args.opset is None:
+ args.opset = max(encoder_onnx_config.default_onnx_opset, decoder_onnx_config.default_onnx_opset)
+
+ if args.opset < min(encoder_onnx_config.default_onnx_opset, decoder_onnx_config.default_onnx_opset):
+ raise ValueError(
+ f"Opset {args.opset} is not sufficient to export {model_kind}. At least "
+ f" {min(encoder_onnx_config.default_onnx_opset, decoder_onnx_config.default_onnx_opset)} is required."
+ )
+
+ preprocessor = AutoFeatureExtractor.from_pretrained(args.model)
+
+ onnx_inputs, onnx_outputs = export(
+ preprocessor,
+ encoder_model,
+ encoder_onnx_config,
+ args.opset,
+ args.output.parent.joinpath("encoder_model.onnx"),
+ )
+
+ validate_model_outputs(
+ encoder_onnx_config,
+ preprocessor,
+ encoder_model,
+ args.output.parent.joinpath("encoder_model.onnx"),
+ onnx_outputs,
+ args.atol if args.atol else encoder_onnx_config.atol_for_validation,
+ )
+
+ preprocessor = AutoTokenizer.from_pretrained(args.model)
+
+ onnx_inputs, onnx_outputs = export(
+ preprocessor,
+ decoder_model,
+ decoder_onnx_config,
+ args.opset,
+ args.output.parent.joinpath("decoder_model.onnx"),
+ )
+
+ validate_model_outputs(
+ decoder_onnx_config,
+ preprocessor,
+ decoder_model,
+ args.output.parent.joinpath("decoder_model.onnx"),
+ onnx_outputs,
+ args.atol if args.atol else decoder_onnx_config.atol_for_validation,
+ )
+ logger.info(
+ f"All good, model saved at: {args.output.parent.joinpath('encoder_model.onnx').as_posix()},"
+ f" {args.output.parent.joinpath('decoder_model.onnx').as_posix()}"
+ )
+
+ else:
+ # Instantiate the appropriate preprocessor
+ if args.preprocessor == "auto":
+ preprocessor = get_preprocessor(args.model)
+ elif args.preprocessor == "tokenizer":
+ preprocessor = AutoTokenizer.from_pretrained(args.model)
+ elif args.preprocessor == "image_processor":
+ preprocessor = AutoImageProcessor.from_pretrained(args.model)
+ elif args.preprocessor == "feature_extractor":
+ preprocessor = AutoFeatureExtractor.from_pretrained(args.model)
+ elif args.preprocessor == "processor":
+ preprocessor = AutoProcessor.from_pretrained(args.model)
+ else:
+ raise ValueError(f"Unknown preprocessor type '{args.preprocessor}'")
+
+ # Ensure the requested opset is sufficient
+ if args.opset is None:
+ args.opset = onnx_config.default_onnx_opset
+
+ if args.opset < onnx_config.default_onnx_opset:
+ raise ValueError(
+ f"Opset {args.opset} is not sufficient to export {model_kind}. "
+ f"At least {onnx_config.default_onnx_opset} is required."
+ )
+
+ onnx_inputs, onnx_outputs = export(
+ preprocessor,
+ model,
+ onnx_config,
+ args.opset,
+ args.output,
+ )
+
+ if args.atol is None:
+ args.atol = onnx_config.atol_for_validation
+
+ validate_model_outputs(onnx_config, preprocessor, model, args.output, onnx_outputs, args.atol)
+ logger.info(f"All good, model saved at: {args.output.as_posix()}")
+ warnings.warn(
+ "The export was done by transformers.onnx which is deprecated and will be removed in v5. We recommend"
+ " using optimum.exporters.onnx in future. You can find more information here:"
+ " https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model.",
+ FutureWarning,
+ )
+
+
+def main():
+ parser = ArgumentParser("Hugging Face Transformers ONNX exporter")
+ parser.add_argument(
+ "-m", "--model", type=str, required=True, help="Model ID on huggingface.co or path on disk to load model from."
+ )
+ parser.add_argument(
+ "--feature",
+ default="default",
+ help="The type of features to export the model with.",
+ )
+ parser.add_argument("--opset", type=int, default=None, help="ONNX opset version to export the model with.")
+ parser.add_argument(
+ "--atol", type=float, default=None, help="Absolute difference tolerance when validating the model."
+ )
+ parser.add_argument(
+ "--framework",
+ type=str,
+ choices=["pt", "tf"],
+ default=None,
+ help=(
+ "The framework to use for the ONNX export."
+ " If not provided, will attempt to use the local checkpoint's original framework"
+ " or what is available in the environment."
+ ),
+ )
+ parser.add_argument("output", type=Path, help="Path indicating where to store generated ONNX model.")
+ parser.add_argument("--cache_dir", type=str, default=None, help="Path indicating where to store cache.")
+ parser.add_argument(
+ "--preprocessor",
+ type=str,
+ choices=["auto", "tokenizer", "feature_extractor", "image_processor", "processor"],
+ default="auto",
+ help="Which type of preprocessor to use. 'auto' tries to automatically detect it.",
+ )
+ parser.add_argument(
+ "--export_with_transformers",
+ action="store_true",
+ help=(
+ "Whether to use transformers.onnx instead of optimum.exporters.onnx to perform the ONNX export. It can be "
+ "useful when exporting a model supported in transformers but not in optimum, otherwise it is not "
+ "recommended."
+ ),
+ )
+
+ args = parser.parse_args()
+ if args.export_with_transformers or not is_optimum_available():
+ export_with_transformers(args)
+ else:
+ export_with_optimum(args)
+
+
+if __name__ == "__main__":
+ logger = logging.get_logger("transformers.onnx") # pylint: disable=invalid-name
+ logger.setLevel(logging.INFO)
+ main()
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/config.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/config.py
new file mode 100644
index 0000000000000000000000000000000000000000..2a47127b3855246c092fcb0d017e381afda84663
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/config.py
@@ -0,0 +1,744 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import copy
+import dataclasses
+import warnings
+from abc import ABC, abstractmethod
+from collections import OrderedDict
+from collections.abc import Iterable, Mapping
+from typing import TYPE_CHECKING, Any, Callable, Optional, Union
+
+import numpy as np
+from packaging import version
+
+from ..utils import TensorType, is_torch_available, is_vision_available, logging
+from .utils import ParameterFormat, compute_effective_axis_dimension, compute_serialized_parameters_size
+
+
+if TYPE_CHECKING:
+ from ..configuration_utils import PretrainedConfig
+ from ..feature_extraction_utils import FeatureExtractionMixin
+ from ..image_processing_utils import ImageProcessingMixin
+ from ..tokenization_utils_base import PreTrainedTokenizerBase
+
+
+if is_vision_available():
+ from PIL import Image
+
+logger = logging.get_logger(__name__)
+
+
+DEFAULT_ONNX_OPSET = 11
+
+# 2 Gb
+EXTERNAL_DATA_FORMAT_SIZE_LIMIT = 2 * 1024 * 1024 * 1024
+
+
+@dataclasses.dataclass
+class PatchingSpec:
+ """
+ Data class that holds patching specifications.
+
+ Args:
+ o: Module / object where the op to patch is located
+ name: Name of the op to monkey patch
+ custom_op: Custom op that patches the original op
+ orig_op: Original op that is being patched
+ op_wrapper: Wrapper (optional) that wraps both the original and custom ops.
+ It is useful for ops that are class or static methods for instance.
+ """
+
+ o: Any
+ name: str
+ custom_op: Callable
+ orig_op: Optional[Callable] = None
+ op_wrapper: Optional[Callable] = None
+
+
+class OnnxConfig(ABC):
+ """
+ Base class for ONNX exportable model describing metadata on how to export the model through the ONNX format.
+ """
+
+ default_fixed_batch = 2
+ default_fixed_sequence = 8
+ default_fixed_num_choices = 4
+ torch_onnx_minimum_version = version.parse("1.8")
+ _tasks_to_common_outputs = {
+ "causal-lm": OrderedDict({"logits": {0: "batch", 1: "sequence"}}),
+ "default": OrderedDict({"last_hidden_state": {0: "batch", 1: "sequence"}}),
+ "image-classification": OrderedDict({"logits": {0: "batch", 1: "sequence"}}),
+ "image-segmentation": OrderedDict(
+ {
+ "logits": {0: "batch", 1: "sequence"},
+ "pred_boxes": {0: "batch", 1: "sequence"},
+ "pred_masks": {0: "batch", 1: "sequence"},
+ }
+ ),
+ "masked-im": OrderedDict({"logits": {0: "batch", 1: "sequence"}}),
+ "masked-lm": OrderedDict({"logits": {0: "batch", 1: "sequence"}}),
+ "multiple-choice": OrderedDict({"logits": {0: "batch"}}),
+ "object-detection": OrderedDict(
+ {
+ "logits": {0: "batch", 1: "sequence"},
+ "pred_boxes": {0: "batch", 1: "sequence"},
+ }
+ ),
+ "question-answering": OrderedDict(
+ {
+ "start_logits": {0: "batch", 1: "sequence"},
+ "end_logits": {0: "batch", 1: "sequence"},
+ }
+ ),
+ "semantic-segmentation": OrderedDict({"logits": {0: "batch", 1: "num_labels", 2: "height", 3: "width"}}),
+ "seq2seq-lm": OrderedDict({"logits": {0: "batch", 1: "decoder_sequence"}}),
+ "sequence-classification": OrderedDict({"logits": {0: "batch"}}),
+ "token-classification": OrderedDict({"logits": {0: "batch", 1: "sequence"}}),
+ "vision2seq-lm": OrderedDict({"logits": {0: "batch", 1: "sequence"}}),
+ "speech2seq-lm": OrderedDict({"logits": {0: "batch", 1: "sequence"}}),
+ }
+
+ def __init__(
+ self, config: "PretrainedConfig", task: str = "default", patching_specs: Optional[list[PatchingSpec]] = None
+ ):
+ self._config = config
+
+ if task not in self._tasks_to_common_outputs:
+ raise ValueError(
+ f"{task} is not a supported task, supported tasks: {self._tasks_to_common_outputs.keys()}"
+ )
+ self.task = task
+
+ self._patching_specs = []
+ for spec in patching_specs if patching_specs is not None else []:
+ final_spec = spec
+ if spec.orig_op is None:
+ final_spec = dataclasses.replace(spec, orig_op=getattr(spec.o, spec.name))
+ self._patching_specs.append(final_spec)
+
+ @classmethod
+ def from_model_config(cls, config: "PretrainedConfig", task: str = "default") -> "OnnxConfig":
+ """
+ Instantiate a OnnxConfig for a specific model
+
+ Args:
+ config: The model's configuration to use when exporting to ONNX
+
+ Returns:
+ OnnxConfig for this model
+ """
+ return cls(config, task=task)
+
+ @property
+ @abstractmethod
+ def inputs(self) -> Mapping[str, Mapping[int, str]]:
+ """
+ Mapping containing the axis definition of the input tensors to provide to the model
+
+ Returns:
+ For each input: its name associated to the axes symbolic name and the axis position within the tensor
+ """
+ raise NotImplementedError()
+
+ @property
+ def outputs(self) -> Mapping[str, Mapping[int, str]]:
+ """
+ Mapping containing the axis definition of the output tensors to provide to the model
+
+ Returns:
+ For each output: its name associated to the axes symbolic name and the axis position within the tensor
+ """
+ common_outputs = self._tasks_to_common_outputs[self.task]
+ return copy.deepcopy(common_outputs)
+
+ @property
+ def values_override(self) -> Optional[Mapping[str, Any]]:
+ """
+ Dictionary of keys to override in the model's config before exporting
+
+ Returns:
+ Dictionary with the keys (and their corresponding values) to override
+ """
+ if hasattr(self._config, "use_cache"):
+ return {"use_cache": False}
+
+ return None
+
+ @property
+ def default_batch_size(self) -> int:
+ """
+ The default batch size to use if no other indication
+
+ Returns:
+ Integer > 0
+ """
+ # Using 2 avoid ONNX making assumption about single sample batch
+ return OnnxConfig.default_fixed_batch
+
+ @property
+ def default_sequence_length(self) -> int:
+ """
+ The default sequence length to use if no other indication
+
+ Returns:
+ Integer > 0
+ """
+ return OnnxConfig.default_fixed_sequence
+
+ @property
+ def default_num_choices(self) -> int:
+ """
+ The default number of choices to use if no other indication
+
+ Returns:
+ Integer > 0
+ """
+ return OnnxConfig.default_fixed_num_choices
+
+ @property
+ def default_onnx_opset(self) -> int:
+ """
+ Which onnx opset to use when exporting the model
+
+ Returns:
+ Integer ONNX Opset version
+ """
+ return DEFAULT_ONNX_OPSET
+
+ @property
+ def atol_for_validation(self) -> float:
+ """
+ What absolute tolerance value to use during model conversion validation.
+
+ Returns:
+ Float absolute tolerance value.
+ """
+ return 1e-5
+
+ @property
+ def is_torch_support_available(self) -> bool:
+ """
+ The minimum PyTorch version required to export the model.
+
+ Returns:
+ `bool`: Whether the installed version of PyTorch is compatible with the model.
+ """
+ if is_torch_available():
+ from transformers.utils import get_torch_version
+
+ return version.parse(get_torch_version()) >= self.torch_onnx_minimum_version
+ else:
+ return False
+
+ @staticmethod
+ def use_external_data_format(num_parameters: int) -> bool:
+ """
+ Flag indicating if the model requires using external data format
+
+ Args:
+ num_parameters: Number of parameter on the model
+
+ Returns:
+ True if model.num_parameters() * size_of(float32) >= 2Gb False otherwise
+ """
+
+ return (
+ compute_serialized_parameters_size(num_parameters, ParameterFormat.Float)
+ >= EXTERNAL_DATA_FORMAT_SIZE_LIMIT
+ )
+
+ def _generate_dummy_images(
+ self, batch_size: int = 2, num_channels: int = 3, image_height: int = 40, image_width: int = 40
+ ):
+ images = []
+ for _ in range(batch_size):
+ data = np.random.rand(image_height, image_width, num_channels) * 255
+ images.append(Image.fromarray(data.astype("uint8")).convert("RGB"))
+ return images
+
+ def _generate_dummy_audio(
+ self, batch_size: int = 2, sampling_rate: int = 22050, time_duration: float = 5.0, frequency: int = 220
+ ):
+ audio_data = []
+ for _ in range(batch_size):
+ # time variable
+ t = np.linspace(0, time_duration, int(time_duration * sampling_rate), endpoint=False)
+
+ # generate pure sine wave at `frequency` Hz
+ audio_data.append(0.5 * np.sin(2 * np.pi * frequency * t))
+
+ return audio_data
+
+ def generate_dummy_inputs(
+ self,
+ preprocessor: Union["PreTrainedTokenizerBase", "FeatureExtractionMixin", "ImageProcessingMixin"],
+ batch_size: int = -1,
+ seq_length: int = -1,
+ num_choices: int = -1,
+ is_pair: bool = False,
+ framework: Optional[TensorType] = None,
+ num_channels: int = 3,
+ image_width: int = 40,
+ image_height: int = 40,
+ sampling_rate: int = 22050,
+ time_duration: float = 5.0,
+ frequency: int = 220,
+ tokenizer: Optional["PreTrainedTokenizerBase"] = None,
+ ) -> Mapping[str, Any]:
+ """
+ Generate inputs to provide to the ONNX exporter for the specific framework
+
+ Args:
+ preprocessor: ([`PreTrainedTokenizerBase`], [`FeatureExtractionMixin`], or [`ImageProcessingMixin`]):
+ The preprocessor associated with this model configuration.
+ batch_size (`int`, *optional*, defaults to -1):
+ The batch size to export the model for (-1 means dynamic axis).
+ num_choices (`int`, *optional*, defaults to -1):
+ The number of candidate answers provided for multiple choice task (-1 means dynamic axis).
+ seq_length (`int`, *optional*, defaults to -1):
+ The sequence length to export the model for (-1 means dynamic axis).
+ is_pair (`bool`, *optional*, defaults to `False`):
+ Indicate if the input is a pair (sentence 1, sentence 2)
+ framework (`TensorType`, *optional*, defaults to `None`):
+ The framework (PyTorch or TensorFlow) that the tokenizer will generate tensors for.
+ num_channels (`int`, *optional*, defaults to 3):
+ The number of channels of the generated images.
+ image_width (`int`, *optional*, defaults to 40):
+ The width of the generated images.
+ image_height (`int`, *optional*, defaults to 40):
+ The height of the generated images.
+ sampling_rate (`int`, *optional* defaults to 22050)
+ The sampling rate for audio data generation.
+ time_duration (`float`, *optional* defaults to 5.0)
+ Total seconds of sampling for audio data generation.
+ frequency (`int`, *optional* defaults to 220)
+ The desired natural frequency of generated audio.
+
+ Returns:
+ Mapping[str, Tensor] holding the kwargs to provide to the model's forward function
+ """
+ from ..feature_extraction_utils import FeatureExtractionMixin
+ from ..image_processing_utils import ImageProcessingMixin
+ from ..tokenization_utils_base import PreTrainedTokenizerBase
+
+ if isinstance(preprocessor, PreTrainedTokenizerBase) and tokenizer is not None:
+ raise ValueError("You cannot provide both a tokenizer and a preprocessor to generate dummy inputs.")
+ if tokenizer is not None:
+ warnings.warn(
+ "The `tokenizer` argument is deprecated and will be removed in version 5 of Transformers. Use"
+ " `preprocessor` instead.",
+ FutureWarning,
+ )
+ logger.warning("Overwriting the `preprocessor` argument with `tokenizer` to generate dummy inputs.")
+ preprocessor = tokenizer
+ if isinstance(preprocessor, PreTrainedTokenizerBase):
+ # If dynamic axis (-1) we forward with a fixed dimension of 2 samples to avoid optimizations made by ONNX
+ batch_size = compute_effective_axis_dimension(
+ batch_size, fixed_dimension=OnnxConfig.default_fixed_batch, num_token_to_add=0
+ )
+ # If dynamic axis (-1) we forward with a fixed dimension of 8 tokens to avoid optimizations made by ONNX
+ token_to_add = preprocessor.num_special_tokens_to_add(is_pair)
+ seq_length = compute_effective_axis_dimension(
+ seq_length, fixed_dimension=OnnxConfig.default_fixed_sequence, num_token_to_add=token_to_add
+ )
+ # Generate dummy inputs according to compute batch and sequence
+ input_token = (
+ preprocessor.unk_token
+ if (preprocessor.unk_token is not None and len(preprocessor.unk_token) > 0)
+ else "0"
+ )
+ dummy_input = [" ".join([input_token]) * seq_length] * batch_size
+ if self.task == "multiple-choice":
+ # If dynamic axis (-1) we forward with a fixed dimension of 4 candidate answers to avoid optimizations
+ # made by ONNX
+ num_choices = compute_effective_axis_dimension(
+ num_choices, fixed_dimension=OnnxConfig.default_fixed_num_choices, num_token_to_add=0
+ )
+ dummy_input = dummy_input * num_choices
+ # The shape of the tokenized inputs values is [batch_size * num_choices, seq_length]
+ tokenized_input = preprocessor(dummy_input, text_pair=dummy_input)
+ # Unflatten the tokenized inputs values expanding it to the shape [batch_size, num_choices, seq_length]
+ for k, v in tokenized_input.items():
+ tokenized_input[k] = [v[i : i + num_choices] for i in range(0, len(v), num_choices)]
+ return dict(tokenized_input.convert_to_tensors(tensor_type=framework))
+ return dict(preprocessor(dummy_input, return_tensors=framework))
+ elif isinstance(preprocessor, ImageProcessingMixin):
+ if preprocessor.model_input_names[0] != "pixel_values":
+ raise ValueError(
+ f"The `preprocessor` is an image processor ({preprocessor.__class__.__name__}) and expects"
+ f' `model_input_names[0]` to be "pixel_values", but got {preprocessor.model_input_names[0]}'
+ )
+ # If dynamic axis (-1) we forward with a fixed dimension of 2 samples to avoid optimizations made by ONNX
+ batch_size = compute_effective_axis_dimension(batch_size, fixed_dimension=OnnxConfig.default_fixed_batch)
+ dummy_input = self._generate_dummy_images(batch_size, num_channels, image_height, image_width)
+ return dict(preprocessor(images=dummy_input, return_tensors=framework))
+ elif isinstance(preprocessor, FeatureExtractionMixin) and preprocessor.model_input_names[0] == "pixel_values":
+ # If dynamic axis (-1) we forward with a fixed dimension of 2 samples to avoid optimizations made by ONNX
+ batch_size = compute_effective_axis_dimension(batch_size, fixed_dimension=OnnxConfig.default_fixed_batch)
+ dummy_input = self._generate_dummy_images(batch_size, num_channels, image_height, image_width)
+ return dict(preprocessor(images=dummy_input, return_tensors=framework))
+ elif (
+ isinstance(preprocessor, FeatureExtractionMixin) and preprocessor.model_input_names[0] == "input_features"
+ ):
+ # If dynamic axis (-1) we forward with a fixed dimension of 2 samples to avoid optimizations made by ONNX
+ batch_size = compute_effective_axis_dimension(batch_size, fixed_dimension=OnnxConfig.default_fixed_batch)
+ dummy_input = self._generate_dummy_audio(batch_size, sampling_rate, time_duration, frequency)
+ return dict(preprocessor(dummy_input, return_tensors=framework))
+ else:
+ raise ValueError(
+ "Unable to generate dummy inputs for the model. Please provide a tokenizer or a preprocessor."
+ )
+
+ def generate_dummy_inputs_onnxruntime(self, reference_model_inputs: Mapping[str, Any]) -> Mapping[str, Any]:
+ """
+ Generate inputs for ONNX Runtime using the reference model inputs. Override this to run inference with seq2seq
+ models which have the encoder and decoder exported as separate ONNX files.
+
+ Args:
+ reference_model_inputs ([`Mapping[str, Tensor]`):
+ Reference inputs for the model.
+
+ Returns:
+ `Mapping[str, Tensor]`: The mapping holding the kwargs to provide to the model's forward function
+ """
+ return reference_model_inputs
+
+ def patch_ops(self):
+ for spec in self._patching_specs:
+ custom_op = spec.custom_op if spec.op_wrapper is None else spec.op_wrapper(spec.custom_op)
+ setattr(spec.o, spec.name, custom_op)
+
+ def restore_ops(self):
+ for spec in self._patching_specs:
+ orig_op = spec.orig_op if spec.op_wrapper is None else spec.op_wrapper(spec.orig_op)
+ setattr(spec.o, spec.name, orig_op)
+
+ @classmethod
+ def flatten_output_collection_property(cls, name: str, field: Iterable[Any]) -> dict[str, Any]:
+ """
+ Flatten any potential nested structure expanding the name of the field with the index of the element within the
+ structure.
+
+ Args:
+ name: The name of the nested structure
+ field: The structure to, potentially, be flattened
+
+ Returns:
+ (dict[str, Any]): Outputs with flattened structure and key mapping this new structure.
+
+ """
+ from itertools import chain
+
+ return {f"{name}.{idx}": item for idx, item in enumerate(chain.from_iterable(field))}
+
+
+class OnnxConfigWithPast(OnnxConfig, ABC):
+ def __init__(
+ self,
+ config: "PretrainedConfig",
+ task: str = "default",
+ patching_specs: Optional[list[PatchingSpec]] = None,
+ use_past: bool = False,
+ ):
+ super().__init__(config, task=task, patching_specs=patching_specs)
+ self.use_past = use_past
+
+ @classmethod
+ def with_past(cls, config: "PretrainedConfig", task: str = "default") -> "OnnxConfigWithPast":
+ """
+ Instantiate a OnnxConfig with `use_past` attribute set to True
+
+ Args:
+ config: The underlying model's config to use when exporting to ONNX
+
+ Returns:
+ OnnxConfig with `.use_past = True`
+ """
+ return cls(config, task=task, use_past=True)
+
+ @property
+ def outputs(self) -> Mapping[str, Mapping[int, str]]:
+ common_outputs = super().outputs
+ if self.use_past:
+ self.fill_with_past_key_values_(common_outputs, direction="outputs")
+
+ return common_outputs
+
+ @property
+ def values_override(self) -> Optional[Mapping[str, Any]]:
+ if hasattr(self._config, "use_cache"):
+ return {"use_cache": self.use_past}
+
+ return None
+
+ @property
+ def num_layers(self) -> int:
+ """
+ The number of layers attribute retrieved from the model config. Override this for model configs where the
+ number of layers attribute is not called `num_layers`.
+ """
+ if not hasattr(self._config, "num_layers"):
+ raise AttributeError(
+ "could not find the number of layers attribute in the model configuration, override the num_layers"
+ " property of the model OnnxConfig to solve this"
+ )
+ return self._config.num_layers
+
+ @property
+ def num_attention_heads(self) -> int:
+ """
+ The number of attention heads attribute retrieved from the model config. Override this for model configs where
+ the number of attention heads attribute is not called `num_attention_heads`.
+ """
+ if not hasattr(self._config, "num_attention_heads"):
+ raise AttributeError(
+ "could not find the number of attention heads attribute in the model configuration, override the"
+ " num_attention_heads property of the model OnnxConfig to solve this"
+ )
+ return self._config.num_attention_heads
+
+ def generate_dummy_inputs(
+ self,
+ tokenizer: "PreTrainedTokenizerBase",
+ batch_size: int = -1,
+ seq_length: int = -1,
+ is_pair: bool = False,
+ framework: Optional[TensorType] = None,
+ ) -> Mapping[str, Any]:
+ # TODO: should we set seq_length = 1 when self.use_past = True?
+ common_inputs = super().generate_dummy_inputs(
+ tokenizer, batch_size=batch_size, seq_length=seq_length, is_pair=is_pair, framework=framework
+ )
+
+ if self.use_past:
+ if not is_torch_available():
+ raise ValueError("Cannot generate dummy past_keys inputs without PyTorch installed.")
+ else:
+ import torch
+
+ batch, seqlen = common_inputs["input_ids"].shape
+ # Not using the same length for past_key_values
+ past_key_values_length = seqlen + 2
+ shape = (
+ batch,
+ self.num_attention_heads,
+ past_key_values_length,
+ self._config.hidden_size // self.num_attention_heads,
+ )
+
+ if "attention_mask" in common_inputs:
+ mask_dtype = common_inputs["attention_mask"].dtype
+ common_inputs["attention_mask"] = torch.cat(
+ [common_inputs["attention_mask"], torch.ones(batch, past_key_values_length, dtype=mask_dtype)],
+ dim=1,
+ )
+
+ common_inputs["past_key_values"] = []
+ for _ in range(self.num_layers):
+ common_inputs["past_key_values"].append((torch.zeros(shape), torch.zeros(shape)))
+
+ return common_inputs
+
+ def fill_with_past_key_values_(
+ self, inputs_or_outputs: Mapping[str, Mapping[int, str]], direction: str, inverted_values_shape: bool = False
+ ):
+ """
+ Fill the input_or_outputs mapping with past_key_values dynamic axes considering.
+
+ Args:
+ inputs_or_outputs: The mapping to fill.
+ direction: either "inputs" or "outputs", it specifies whether input_or_outputs is the input mapping or the
+ output mapping, this is important for axes naming.
+ inverted_values_shape:
+ If `True`, store values on dynamic axis 1, else on axis 2.
+
+ """
+ if direction not in ["inputs", "outputs"]:
+ raise ValueError(f'direction must either be "inputs" or "outputs", but {direction} was given')
+
+ name = "past_key_values" if direction == "inputs" else "present"
+ for i in range(self.num_layers):
+ inputs_or_outputs[f"{name}.{i}.key"] = {0: "batch", 2: "past_sequence + sequence"}
+ if inverted_values_shape:
+ inputs_or_outputs[f"{name}.{i}.value"] = {0: "batch", 1: "past_sequence + sequence"}
+ else:
+ inputs_or_outputs[f"{name}.{i}.value"] = {0: "batch", 2: "past_sequence + sequence"}
+
+ def _flatten_past_key_values_(self, flattened_output, name, idx, t):
+ flattened_output[f"{name}.{idx}.key"] = t[0]
+ flattened_output[f"{name}.{idx}.value"] = t[1]
+
+ def flatten_output_collection_property(self, name: str, field: Iterable[Any]) -> dict[str, Any]:
+ flattened_output = {}
+ if name in ["present", "past_key_values"]:
+ for idx, t in enumerate(field):
+ self._flatten_past_key_values_(flattened_output, name, idx, t)
+ else:
+ flattened_output = super().flatten_output_collection_property(name, field)
+
+ return flattened_output
+
+
+class OnnxSeq2SeqConfigWithPast(OnnxConfigWithPast):
+ @property
+ def outputs(self) -> Mapping[str, Mapping[int, str]]:
+ common_outputs = super(OnnxConfigWithPast, self).outputs
+ # Renaming the outputs axes properly.
+ for name, axes_names in common_outputs.items():
+ sequence_name = "encoder_sequence" if "encoder" in name else "decoder_sequence"
+ for axis_idx, name in axes_names.items():
+ if "sequence" in name:
+ axes_names[axis_idx] = sequence_name
+ # We reset the value as the order in common_outputs (OrderedDict) is lost otherwise
+ else:
+ axes_names[axis_idx] = name
+ if self.use_past:
+ self.fill_with_past_key_values_(common_outputs, direction="outputs")
+
+ return common_outputs
+
+ @property
+ def num_layers(self) -> tuple[int]:
+ try:
+ num_layers = super().num_layers
+ num_layers = (num_layers, num_layers)
+ except AttributeError:
+ if hasattr(self._config, "encoder_layers") and hasattr(self._config, "decoder_layers"):
+ num_layers = (self._config.encoder_layers, self._config.decoder_layers)
+ else:
+ raise AttributeError(
+ "could not find the number of encoder and decoder layers attributes in the model configuration,"
+ " override the num_layers property of the model OnnxConfig to solve this"
+ )
+
+ return num_layers
+
+ @property
+ def num_attention_heads(self) -> tuple[int]:
+ try:
+ num_attention_heads = super().num_attention_heads
+ num_attention_heads = (num_attention_heads, num_attention_heads)
+ except AttributeError:
+ if hasattr(self._config, "encoder_attention_heads") and hasattr(self._config, "decoder_attention_heads"):
+ num_attention_heads = (self._config.encoder_attention_heads, self._config.decoder_attention_heads)
+ else:
+ raise AttributeError(
+ "could not find the number of attention heads for the encoder and the decoder attributes in the"
+ " model configuration, override the num_attention_heads property of the model OnnxConfig to solve"
+ " this"
+ )
+ return num_attention_heads
+
+ def generate_dummy_inputs(
+ self,
+ tokenizer: Optional["PreTrainedTokenizerBase"],
+ batch_size: int = -1,
+ seq_length: int = -1,
+ is_pair: bool = False,
+ framework: Optional[TensorType] = None,
+ ) -> Mapping[str, Any]:
+ encoder_inputs = super(OnnxConfigWithPast, self).generate_dummy_inputs(
+ tokenizer, batch_size=batch_size, seq_length=seq_length, is_pair=is_pair, framework=framework
+ )
+
+ # Generate decoder inputs
+ decoder_seq_length = seq_length if not self.use_past else 1
+ decoder_inputs = super(OnnxConfigWithPast, self).generate_dummy_inputs(
+ tokenizer, batch_size=batch_size, seq_length=decoder_seq_length, is_pair=is_pair, framework=framework
+ )
+ decoder_inputs = {f"decoder_{name}": tensor for name, tensor in decoder_inputs.items()}
+ common_inputs = dict(**encoder_inputs, **decoder_inputs)
+
+ if self.use_past:
+ if not is_torch_available():
+ raise ValueError("Cannot generate dummy past_keys inputs without PyTorch installed.")
+ else:
+ import torch
+ batch = common_inputs["input_ids"].shape[0]
+ encoder_seq_length = common_inputs["input_ids"].shape[1]
+ decoder_seq_length = common_inputs["decoder_input_ids"].shape[1]
+ num_encoder_attention_heads, num_decoder_attention_heads = self.num_attention_heads
+ encoder_shape = (
+ batch,
+ num_encoder_attention_heads,
+ encoder_seq_length,
+ self._config.hidden_size // num_encoder_attention_heads,
+ )
+ decoder_shape = (
+ batch,
+ num_decoder_attention_heads,
+ # Not using the same length for past_key_values
+ decoder_seq_length + 3,
+ self._config.hidden_size // num_decoder_attention_heads,
+ )
+
+ common_inputs["past_key_values"] = []
+ # If the number of encoder and decoder layers are present in the model configuration, both are considered
+ num_encoder_layers, num_decoder_layers = self.num_layers
+ min_num_layers = min(num_encoder_layers, num_decoder_layers)
+ max_num_layers = max(num_encoder_layers, num_decoder_layers) - min_num_layers
+ remaining_side_name = "encoder" if num_encoder_layers > num_decoder_layers else "decoder"
+
+ for _ in range(min_num_layers):
+ # For encoder-decoder models, past_key_values contains pre-computed values for both the encoder and the
+ # decoder layers, hence a tuple of 4 tensors instead of 2
+ common_inputs["past_key_values"].append(
+ (
+ torch.zeros(decoder_shape),
+ torch.zeros(decoder_shape),
+ torch.zeros(encoder_shape),
+ torch.zeros(encoder_shape),
+ )
+ )
+
+ # TODO: test this.
+ shape = encoder_shape if remaining_side_name == "encoder" else decoder_shape
+ for _ in range(min_num_layers, max_num_layers):
+ common_inputs["past_key_values"].append((torch.zeros(shape), torch.zeros(shape)))
+
+ return common_inputs
+
+ def fill_with_past_key_values_(self, inputs_or_outputs: Mapping[str, Mapping[int, str]], direction: str):
+ if direction not in ["inputs", "outputs"]:
+ raise ValueError(f'direction must either be "inputs" or "outputs", but {direction} was given')
+
+ name = "past_key_values" if direction == "inputs" else "present"
+
+ # If the number of encoder and decoder layers are present in the model configuration, both are considered
+ num_encoder_layers, num_decoder_layers = self.num_layers
+ min_num_layers = min(num_encoder_layers, num_decoder_layers)
+ max_num_layers = max(num_encoder_layers, num_decoder_layers) - min_num_layers
+ remaining_side_name = "encoder" if num_encoder_layers > num_decoder_layers else "decoder"
+
+ encoder_sequence = "past_encoder_sequence"
+ decoder_sequence = "past_decoder_sequence" if direction == "inputs" else "past_decoder_sequence + sequence"
+
+ for i in range(min_num_layers):
+ inputs_or_outputs[f"{name}.{i}.decoder.key"] = {0: "batch", 2: decoder_sequence}
+ inputs_or_outputs[f"{name}.{i}.decoder.value"] = {0: "batch", 2: decoder_sequence}
+ inputs_or_outputs[f"{name}.{i}.encoder.key"] = {0: "batch", 2: encoder_sequence}
+ inputs_or_outputs[f"{name}.{i}.encoder.value"] = {0: "batch", 2: encoder_sequence}
+
+ for i in range(min_num_layers, max_num_layers):
+ if remaining_side_name == "encoder":
+ axes_info = {0: "batch", 2: encoder_sequence}
+ else:
+ axes_info = {0: "batch", 2: decoder_sequence}
+ inputs_or_outputs[f"{name}.{i}.{remaining_side_name}.key"] = axes_info
+
+ def _flatten_past_key_values_(self, flattened_output, name, idx, t):
+ flattened_output[f"{name}.{idx}.decoder.key"] = t[0]
+ flattened_output[f"{name}.{idx}.decoder.value"] = t[1]
+ flattened_output[f"{name}.{idx}.encoder.key"] = t[2]
+ flattened_output[f"{name}.{idx}.encoder.value"] = t[3]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/convert.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/convert.py
new file mode 100644
index 0000000000000000000000000000000000000000..778fa7046f7d5dda67140e42210e36d54f319f75
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/convert.py
@@ -0,0 +1,461 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import warnings
+from collections.abc import Iterable
+from inspect import signature
+from itertools import chain
+from pathlib import Path
+from typing import TYPE_CHECKING, Optional, Union
+
+import numpy as np
+from packaging.version import Version, parse
+
+from ..tokenization_utils_base import PreTrainedTokenizerBase
+from ..utils import (
+ TensorType,
+ is_tf_available,
+ is_torch_available,
+ logging,
+)
+from .config import OnnxConfig
+
+
+if is_torch_available():
+ from ..modeling_utils import PreTrainedModel
+
+if is_tf_available():
+ from ..modeling_tf_utils import TFPreTrainedModel
+
+if TYPE_CHECKING:
+ from ..feature_extraction_utils import FeatureExtractionMixin
+ from ..processing_utils import ProcessorMixin
+ from ..tokenization_utils import PreTrainedTokenizer
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+# This is the minimal required version to support some ONNX Runtime features
+ORT_QUANTIZE_MINIMUM_VERSION = parse("1.4.0")
+
+
+def check_onnxruntime_requirements(minimum_version: Version):
+ """
+ Check onnxruntime is installed and if the installed version match is recent enough
+
+ Raises:
+ ImportError: If onnxruntime is not installed or too old version is found
+ """
+ try:
+ import onnxruntime
+
+ # Parse the version of the installed onnxruntime
+ ort_version = parse(onnxruntime.__version__)
+
+ # We require 1.4.0 minimum
+ if ort_version < ORT_QUANTIZE_MINIMUM_VERSION:
+ raise ImportError(
+ f"We found an older version of onnxruntime ({onnxruntime.__version__}) "
+ f"but we require onnxruntime to be >= {minimum_version} to enable all the conversions options.\n"
+ "Please update onnxruntime by running `pip install --upgrade onnxruntime`"
+ )
+
+ except ImportError:
+ raise ImportError(
+ "onnxruntime doesn't seem to be currently installed. "
+ "Please install the onnxruntime by running `pip install onnxruntime`"
+ " and relaunch the conversion."
+ )
+
+
+def export_pytorch(
+ preprocessor: Union["PreTrainedTokenizer", "FeatureExtractionMixin", "ProcessorMixin"],
+ model: "PreTrainedModel",
+ config: OnnxConfig,
+ opset: int,
+ output: Path,
+ tokenizer: Optional["PreTrainedTokenizer"] = None,
+ device: str = "cpu",
+) -> tuple[list[str], list[str]]:
+ """
+ Export a PyTorch model to an ONNX Intermediate Representation (IR)
+
+ Args:
+ preprocessor: ([`PreTrainedTokenizer`], [`FeatureExtractionMixin`] or [`ProcessorMixin`]):
+ The preprocessor used for encoding the data.
+ model ([`PreTrainedModel`]):
+ The model to export.
+ config ([`~onnx.config.OnnxConfig`]):
+ The ONNX configuration associated with the exported model.
+ opset (`int`):
+ The version of the ONNX operator set to use.
+ output (`Path`):
+ Directory to store the exported ONNX model.
+ device (`str`, *optional*, defaults to `cpu`):
+ The device on which the ONNX model will be exported. Either `cpu` or `cuda`.
+
+ Returns:
+ `tuple[list[str], list[str]]`: A tuple with an ordered list of the model's inputs, and the named inputs from
+ the ONNX configuration.
+ """
+
+ if isinstance(preprocessor, PreTrainedTokenizerBase) and tokenizer is not None:
+ raise ValueError("You cannot provide both a tokenizer and a preprocessor to export the model.")
+ if tokenizer is not None:
+ warnings.warn(
+ "The `tokenizer` argument is deprecated and will be removed in version 5 of Transformers. Use"
+ " `preprocessor` instead.",
+ FutureWarning,
+ )
+ logger.info("Overwriting the `preprocessor` argument with `tokenizer` to generate dummy inputs.")
+ preprocessor = tokenizer
+
+ if issubclass(type(model), PreTrainedModel):
+ import torch
+ from torch.onnx import export as onnx_export
+
+ logger.info(f"Using framework PyTorch: {torch.__version__}")
+ with torch.no_grad():
+ model.config.return_dict = True
+ model.eval()
+
+ # Check if we need to override certain configuration item
+ if config.values_override is not None:
+ logger.info(f"Overriding {len(config.values_override)} configuration item(s)")
+ for override_config_key, override_config_value in config.values_override.items():
+ logger.info(f"\t- {override_config_key} -> {override_config_value}")
+ setattr(model.config, override_config_key, override_config_value)
+
+ # Ensure inputs match
+ # TODO: Check when exporting QA we provide "is_pair=True"
+ model_inputs = config.generate_dummy_inputs(preprocessor, framework=TensorType.PYTORCH)
+ device = torch.device(device)
+ if device.type == "cuda" and torch.cuda.is_available():
+ model.to(device)
+ model_inputs_device = {}
+ for k, v in model_inputs.items():
+ if isinstance(v, tuple):
+ model_inputs_device[k] = tuple(
+ x.to(device) if isinstance(x, torch.Tensor) else None for x in v
+ )
+ elif isinstance(v, list):
+ model_inputs_device[k] = [
+ tuple(x.to(device) if isinstance(x, torch.Tensor) else None for x in t) for t in v
+ ]
+ else:
+ model_inputs_device[k] = v.to(device)
+
+ model_inputs = model_inputs_device
+
+ inputs_match, matched_inputs = ensure_model_and_config_inputs_match(model, model_inputs.keys())
+ onnx_outputs = list(config.outputs.keys())
+
+ if not inputs_match:
+ raise ValueError("Model and config inputs doesn't match")
+
+ config.patch_ops()
+
+ onnx_export(
+ model,
+ (model_inputs,),
+ f=output.as_posix(),
+ input_names=list(config.inputs.keys()),
+ output_names=onnx_outputs,
+ dynamic_axes=dict(chain(config.inputs.items(), config.outputs.items())),
+ do_constant_folding=True,
+ opset_version=opset,
+ )
+
+ config.restore_ops()
+
+ return matched_inputs, onnx_outputs
+
+
+def export_tensorflow(
+ preprocessor: Union["PreTrainedTokenizer", "FeatureExtractionMixin"],
+ model: "TFPreTrainedModel",
+ config: OnnxConfig,
+ opset: int,
+ output: Path,
+ tokenizer: Optional["PreTrainedTokenizer"] = None,
+) -> tuple[list[str], list[str]]:
+ """
+ Export a TensorFlow model to an ONNX Intermediate Representation (IR)
+
+ Args:
+ preprocessor: ([`PreTrainedTokenizer`] or [`FeatureExtractionMixin`]):
+ The preprocessor used for encoding the data.
+ model ([`TFPreTrainedModel`]):
+ The model to export.
+ config ([`~onnx.config.OnnxConfig`]):
+ The ONNX configuration associated with the exported model.
+ opset (`int`):
+ The version of the ONNX operator set to use.
+ output (`Path`):
+ Directory to store the exported ONNX model.
+
+ Returns:
+ `tuple[list[str], list[str]]`: A tuple with an ordered list of the model's inputs, and the named inputs from
+ the ONNX configuration.
+ """
+ import onnx
+ import tensorflow as tf
+ import tf2onnx
+
+ if isinstance(preprocessor, PreTrainedTokenizerBase) and tokenizer is not None:
+ raise ValueError("You cannot provide both a tokenizer and preprocessor to export the model.")
+ if tokenizer is not None:
+ warnings.warn(
+ "The `tokenizer` argument is deprecated and will be removed in version 5 of Transformers. Use"
+ " `preprocessor` instead.",
+ FutureWarning,
+ )
+ logger.info("Overwriting the `preprocessor` argument with `tokenizer` to generate dummy inputs.")
+ preprocessor = tokenizer
+
+ model.config.return_dict = True
+
+ # Check if we need to override certain configuration item
+ if config.values_override is not None:
+ logger.info(f"Overriding {len(config.values_override)} configuration item(s)")
+ for override_config_key, override_config_value in config.values_override.items():
+ logger.info(f"\t- {override_config_key} -> {override_config_value}")
+ setattr(model.config, override_config_key, override_config_value)
+
+ # Ensure inputs match
+ model_inputs = config.generate_dummy_inputs(preprocessor, framework=TensorType.TENSORFLOW)
+ inputs_match, matched_inputs = ensure_model_and_config_inputs_match(model, model_inputs.keys())
+ onnx_outputs = list(config.outputs.keys())
+
+ input_signature = [
+ tf.TensorSpec([None] * tensor.ndim, dtype=tensor.dtype, name=key) for key, tensor in model_inputs.items()
+ ]
+ onnx_model, _ = tf2onnx.convert.from_keras(model, input_signature, opset=opset)
+ onnx.save(onnx_model, output.as_posix())
+ config.restore_ops()
+
+ return matched_inputs, onnx_outputs
+
+
+def export(
+ preprocessor: Union["PreTrainedTokenizer", "FeatureExtractionMixin", "ProcessorMixin"],
+ model: Union["PreTrainedModel", "TFPreTrainedModel"],
+ config: OnnxConfig,
+ opset: int,
+ output: Path,
+ tokenizer: Optional["PreTrainedTokenizer"] = None,
+ device: str = "cpu",
+) -> tuple[list[str], list[str]]:
+ """
+ Export a Pytorch or TensorFlow model to an ONNX Intermediate Representation (IR)
+
+ Args:
+ preprocessor: ([`PreTrainedTokenizer`], [`FeatureExtractionMixin`] or [`ProcessorMixin`]):
+ The preprocessor used for encoding the data.
+ model ([`PreTrainedModel`] or [`TFPreTrainedModel`]):
+ The model to export.
+ config ([`~onnx.config.OnnxConfig`]):
+ The ONNX configuration associated with the exported model.
+ opset (`int`):
+ The version of the ONNX operator set to use.
+ output (`Path`):
+ Directory to store the exported ONNX model.
+ device (`str`, *optional*, defaults to `cpu`):
+ The device on which the ONNX model will be exported. Either `cpu` or `cuda`. Only PyTorch is supported for
+ export on CUDA devices.
+
+ Returns:
+ `tuple[list[str], list[str]]`: A tuple with an ordered list of the model's inputs, and the named inputs from
+ the ONNX configuration.
+ """
+ if not (is_torch_available() or is_tf_available()):
+ raise ImportError(
+ "Cannot convert because neither PyTorch nor TensorFlow are not installed. "
+ "Please install torch or tensorflow first."
+ )
+
+ if is_tf_available() and isinstance(model, TFPreTrainedModel) and device == "cuda":
+ raise RuntimeError("`tf2onnx` does not support export on CUDA device.")
+
+ if isinstance(preprocessor, PreTrainedTokenizerBase) and tokenizer is not None:
+ raise ValueError("You cannot provide both a tokenizer and a preprocessor to export the model.")
+ if tokenizer is not None:
+ warnings.warn(
+ "The `tokenizer` argument is deprecated and will be removed in version 5 of Transformers. Use"
+ " `preprocessor` instead.",
+ FutureWarning,
+ )
+ logger.info("Overwriting the `preprocessor` argument with `tokenizer` to generate dummy inputs.")
+ preprocessor = tokenizer
+
+ if is_torch_available():
+ from ..utils import get_torch_version
+
+ if not config.is_torch_support_available:
+ logger.warning(
+ f"Unsupported PyTorch version for this model. Minimum required is {config.torch_onnx_minimum_version},"
+ f" got: {get_torch_version()}"
+ )
+
+ if is_torch_available() and issubclass(type(model), PreTrainedModel):
+ return export_pytorch(preprocessor, model, config, opset, output, tokenizer=tokenizer, device=device)
+ elif is_tf_available() and issubclass(type(model), TFPreTrainedModel):
+ return export_tensorflow(preprocessor, model, config, opset, output, tokenizer=tokenizer)
+
+
+def validate_model_outputs(
+ config: OnnxConfig,
+ preprocessor: Union["PreTrainedTokenizer", "FeatureExtractionMixin", "ProcessorMixin"],
+ reference_model: Union["PreTrainedModel", "TFPreTrainedModel"],
+ onnx_model: Path,
+ onnx_named_outputs: list[str],
+ atol: float,
+ tokenizer: Optional["PreTrainedTokenizer"] = None,
+):
+ from onnxruntime import InferenceSession, SessionOptions
+
+ logger.info("Validating ONNX model...")
+
+ if isinstance(preprocessor, PreTrainedTokenizerBase) and tokenizer is not None:
+ raise ValueError("You cannot provide both a tokenizer and a preprocessor to validate the model outputs.")
+ if tokenizer is not None:
+ warnings.warn(
+ "The `tokenizer` argument is deprecated and will be removed in version 5 of Transformers. Use"
+ " `preprocessor` instead.",
+ FutureWarning,
+ )
+ logger.info("Overwriting the `preprocessor` argument with `tokenizer` to generate dummy inputs.")
+ preprocessor = tokenizer
+
+ # generate inputs with a different batch_size and seq_len that was used for conversion to properly test
+ # dynamic input shapes.
+ if is_torch_available() and issubclass(type(reference_model), PreTrainedModel):
+ reference_model_inputs = config.generate_dummy_inputs(
+ preprocessor,
+ batch_size=config.default_fixed_batch + 1,
+ seq_length=config.default_fixed_sequence + 1,
+ framework=TensorType.PYTORCH,
+ )
+ else:
+ reference_model_inputs = config.generate_dummy_inputs(
+ preprocessor,
+ batch_size=config.default_fixed_batch + 1,
+ seq_length=config.default_fixed_sequence + 1,
+ framework=TensorType.TENSORFLOW,
+ )
+
+ # Create ONNX Runtime session
+ options = SessionOptions()
+ session = InferenceSession(onnx_model.as_posix(), options, providers=["CPUExecutionProvider"])
+
+ # Compute outputs from the reference model
+ if is_torch_available() and issubclass(type(reference_model), PreTrainedModel):
+ reference_model.to("cpu")
+ ref_outputs = reference_model(**reference_model_inputs)
+ ref_outputs_dict = {}
+
+ # We flatten potential collection of outputs (i.e. past_keys) to a flat structure
+ for name, value in ref_outputs.items():
+ # Overwriting the output name as "present" since it is the name used for the ONNX outputs
+ # ("past_key_values" being taken for the ONNX inputs)
+ if name == "past_key_values":
+ name = "present"
+ if isinstance(value, (list, tuple)):
+ value = config.flatten_output_collection_property(name, value)
+ ref_outputs_dict.update(value)
+ else:
+ ref_outputs_dict[name] = value
+
+ # Create onnxruntime inputs from the reference model inputs
+ reference_model_inputs_onnxruntime = config.generate_dummy_inputs_onnxruntime(reference_model_inputs)
+
+ # We flatten potential collection of inputs (i.e. past_keys)
+ onnx_inputs = {}
+ for name, value in reference_model_inputs_onnxruntime.items():
+ if isinstance(value, (list, tuple)):
+ value = config.flatten_output_collection_property(name, value)
+ onnx_inputs.update({tensor_name: pt_tensor.numpy() for tensor_name, pt_tensor in value.items()})
+ else:
+ onnx_inputs[name] = value.numpy()
+
+ # Compute outputs from the ONNX model
+ onnx_outputs = session.run(onnx_named_outputs, onnx_inputs)
+
+ # Check we have a subset of the keys into onnx_outputs against ref_outputs
+ ref_outputs_set, onnx_outputs_set = set(ref_outputs_dict.keys()), set(onnx_named_outputs)
+ if not onnx_outputs_set.issubset(ref_outputs_set):
+ logger.info(
+ f"\t-[x] ONNX model output names {onnx_outputs_set} do not match reference model {ref_outputs_set}"
+ )
+
+ raise ValueError(
+ "Outputs doesn't match between reference model and ONNX exported model: "
+ f"{onnx_outputs_set.difference(ref_outputs_set)}"
+ )
+ else:
+ logger.info(f"\t-[✓] ONNX model output names match reference model ({onnx_outputs_set})")
+
+ # Check the shape and values match
+ for name, ort_value in zip(onnx_named_outputs, onnx_outputs):
+ if is_torch_available() and issubclass(type(reference_model), PreTrainedModel):
+ ref_value = ref_outputs_dict[name].detach().numpy()
+ else:
+ ref_value = ref_outputs_dict[name].numpy()
+ logger.info(f'\t- Validating ONNX Model output "{name}":')
+
+ # Shape
+ if ort_value.shape != ref_value.shape:
+ logger.info(f"\t\t-[x] shape {ort_value.shape} doesn't match {ref_value.shape}")
+ raise ValueError(
+ "Outputs shape doesn't match between reference model and ONNX exported model: "
+ f"Got {ref_value.shape} (reference) and {ort_value.shape} (ONNX)"
+ )
+ else:
+ logger.info(f"\t\t-[✓] {ort_value.shape} matches {ref_value.shape}")
+
+ # Values
+ if not np.allclose(ref_value, ort_value, atol=atol):
+ bad_indices = np.logical_not(np.isclose(ref_value, ort_value, atol=atol))
+ logger.info(f"\t\t-[x] values not close enough (atol: {atol})")
+ raise ValueError(
+ "Outputs values doesn't match between reference model and ONNX exported model: "
+ f"Got max absolute difference of: {np.amax(np.abs(ref_value - ort_value))} for "
+ f"{ref_value[bad_indices]} vs {ort_value[bad_indices]}"
+ )
+ else:
+ logger.info(f"\t\t-[✓] all values close (atol: {atol})")
+
+
+def ensure_model_and_config_inputs_match(
+ model: Union["PreTrainedModel", "TFPreTrainedModel"], model_inputs: Iterable[str]
+) -> tuple[bool, list[str]]:
+ """
+
+ :param model_inputs: :param config_inputs: :return:
+ """
+ if is_torch_available() and issubclass(type(model), PreTrainedModel):
+ forward_parameters = signature(model.forward).parameters
+ else:
+ forward_parameters = signature(model.call).parameters
+ model_inputs_set = set(model_inputs)
+
+ # We are fine if config_inputs has more keys than model_inputs
+ forward_inputs_set = set(forward_parameters.keys())
+ is_ok = model_inputs_set.issubset(forward_inputs_set)
+
+ # Make sure the input order match (VERY IMPORTANT !!!!)
+ matching_inputs = forward_inputs_set.intersection(model_inputs_set)
+ ordered_inputs = [parameter for parameter in forward_parameters if parameter in matching_inputs]
+ return is_ok, ordered_inputs
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/features.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/features.py
new file mode 100644
index 0000000000000000000000000000000000000000..a24aa79a596812a83c64b27e7cfa2be276ef4dbb
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/features.py
@@ -0,0 +1,749 @@
+import os
+from functools import partial, reduce
+from typing import TYPE_CHECKING, Callable, Optional, Union
+
+import transformers
+
+from .. import PretrainedConfig, is_tf_available, is_torch_available
+from ..utils import TF2_WEIGHTS_NAME, WEIGHTS_NAME, logging
+from .config import OnnxConfig
+
+
+if TYPE_CHECKING:
+ from transformers import PreTrainedModel, TFPreTrainedModel
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+if is_torch_available():
+ from transformers.models.auto import (
+ AutoModel,
+ AutoModelForCausalLM,
+ AutoModelForImageClassification,
+ AutoModelForImageSegmentation,
+ AutoModelForMaskedImageModeling,
+ AutoModelForMaskedLM,
+ AutoModelForMultipleChoice,
+ AutoModelForObjectDetection,
+ AutoModelForQuestionAnswering,
+ AutoModelForSemanticSegmentation,
+ AutoModelForSeq2SeqLM,
+ AutoModelForSequenceClassification,
+ AutoModelForSpeechSeq2Seq,
+ AutoModelForTokenClassification,
+ AutoModelForVision2Seq,
+ )
+if is_tf_available():
+ from transformers.models.auto import (
+ TFAutoModel,
+ TFAutoModelForCausalLM,
+ TFAutoModelForMaskedLM,
+ TFAutoModelForMultipleChoice,
+ TFAutoModelForQuestionAnswering,
+ TFAutoModelForSemanticSegmentation,
+ TFAutoModelForSeq2SeqLM,
+ TFAutoModelForSequenceClassification,
+ TFAutoModelForTokenClassification,
+ )
+if not is_torch_available() and not is_tf_available():
+ logger.warning(
+ "The ONNX export features are only supported for PyTorch or TensorFlow. You will not be able to export models"
+ " without one of these libraries installed."
+ )
+
+
+def supported_features_mapping(
+ *supported_features: str, onnx_config_cls: Optional[str] = None
+) -> dict[str, Callable[[PretrainedConfig], OnnxConfig]]:
+ """
+ Generate the mapping between supported the features and their corresponding OnnxConfig for a given model.
+
+ Args:
+ *supported_features: The names of the supported features.
+ onnx_config_cls: The OnnxConfig full name corresponding to the model.
+
+ Returns:
+ The dictionary mapping a feature to an OnnxConfig constructor.
+ """
+ if onnx_config_cls is None:
+ raise ValueError("A OnnxConfig class must be provided")
+
+ config_cls = transformers
+ for attr_name in onnx_config_cls.split("."):
+ config_cls = getattr(config_cls, attr_name)
+ mapping = {}
+ for feature in supported_features:
+ if "-with-past" in feature:
+ task = feature.replace("-with-past", "")
+ mapping[feature] = partial(config_cls.with_past, task=task)
+ else:
+ mapping[feature] = partial(config_cls.from_model_config, task=feature)
+
+ return mapping
+
+
+class FeaturesManager:
+ _TASKS_TO_AUTOMODELS = {}
+ _TASKS_TO_TF_AUTOMODELS = {}
+ if is_torch_available():
+ _TASKS_TO_AUTOMODELS = {
+ "default": AutoModel,
+ "masked-lm": AutoModelForMaskedLM,
+ "causal-lm": AutoModelForCausalLM,
+ "seq2seq-lm": AutoModelForSeq2SeqLM,
+ "sequence-classification": AutoModelForSequenceClassification,
+ "token-classification": AutoModelForTokenClassification,
+ "multiple-choice": AutoModelForMultipleChoice,
+ "object-detection": AutoModelForObjectDetection,
+ "question-answering": AutoModelForQuestionAnswering,
+ "image-classification": AutoModelForImageClassification,
+ "image-segmentation": AutoModelForImageSegmentation,
+ "masked-im": AutoModelForMaskedImageModeling,
+ "semantic-segmentation": AutoModelForSemanticSegmentation,
+ "vision2seq-lm": AutoModelForVision2Seq,
+ "speech2seq-lm": AutoModelForSpeechSeq2Seq,
+ }
+ if is_tf_available():
+ _TASKS_TO_TF_AUTOMODELS = {
+ "default": TFAutoModel,
+ "masked-lm": TFAutoModelForMaskedLM,
+ "causal-lm": TFAutoModelForCausalLM,
+ "seq2seq-lm": TFAutoModelForSeq2SeqLM,
+ "sequence-classification": TFAutoModelForSequenceClassification,
+ "token-classification": TFAutoModelForTokenClassification,
+ "multiple-choice": TFAutoModelForMultipleChoice,
+ "question-answering": TFAutoModelForQuestionAnswering,
+ "semantic-segmentation": TFAutoModelForSemanticSegmentation,
+ }
+
+ # Set of model topologies we support associated to the features supported by each topology and the factory
+ _SUPPORTED_MODEL_TYPE = {
+ "albert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.albert.AlbertOnnxConfig",
+ ),
+ "bart": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ "sequence-classification",
+ "question-answering",
+ onnx_config_cls="models.bart.BartOnnxConfig",
+ ),
+ # BEiT cannot be used with the masked image modeling autoclass, so this feature is excluded here
+ "beit": supported_features_mapping(
+ "default", "image-classification", onnx_config_cls="models.beit.BeitOnnxConfig"
+ ),
+ "bert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.bert.BertOnnxConfig",
+ ),
+ "big-bird": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.big_bird.BigBirdOnnxConfig",
+ ),
+ "bigbird-pegasus": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ "sequence-classification",
+ "question-answering",
+ onnx_config_cls="models.bigbird_pegasus.BigBirdPegasusOnnxConfig",
+ ),
+ "blenderbot": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ onnx_config_cls="models.blenderbot.BlenderbotOnnxConfig",
+ ),
+ "blenderbot-small": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ onnx_config_cls="models.blenderbot_small.BlenderbotSmallOnnxConfig",
+ ),
+ "bloom": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "sequence-classification",
+ "token-classification",
+ onnx_config_cls="models.bloom.BloomOnnxConfig",
+ ),
+ "camembert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.camembert.CamembertOnnxConfig",
+ ),
+ "clip": supported_features_mapping(
+ "default",
+ onnx_config_cls="models.clip.CLIPOnnxConfig",
+ ),
+ "codegen": supported_features_mapping(
+ "default",
+ "causal-lm",
+ onnx_config_cls="models.codegen.CodeGenOnnxConfig",
+ ),
+ "convbert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.convbert.ConvBertOnnxConfig",
+ ),
+ "convnext": supported_features_mapping(
+ "default",
+ "image-classification",
+ onnx_config_cls="models.convnext.ConvNextOnnxConfig",
+ ),
+ "data2vec-text": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.data2vec.Data2VecTextOnnxConfig",
+ ),
+ "data2vec-vision": supported_features_mapping(
+ "default",
+ "image-classification",
+ # ONNX doesn't support `adaptive_avg_pool2d` yet
+ # "semantic-segmentation",
+ onnx_config_cls="models.data2vec.Data2VecVisionOnnxConfig",
+ ),
+ "deberta": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.deberta.DebertaOnnxConfig",
+ ),
+ "deberta-v2": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.deberta_v2.DebertaV2OnnxConfig",
+ ),
+ "deit": supported_features_mapping(
+ "default", "image-classification", onnx_config_cls="models.deit.DeiTOnnxConfig"
+ ),
+ "detr": supported_features_mapping(
+ "default",
+ "object-detection",
+ "image-segmentation",
+ onnx_config_cls="models.detr.DetrOnnxConfig",
+ ),
+ "distilbert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.distilbert.DistilBertOnnxConfig",
+ ),
+ "electra": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.electra.ElectraOnnxConfig",
+ ),
+ "flaubert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.flaubert.FlaubertOnnxConfig",
+ ),
+ "gpt2": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "sequence-classification",
+ "token-classification",
+ onnx_config_cls="models.gpt2.GPT2OnnxConfig",
+ ),
+ "gptj": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "question-answering",
+ "sequence-classification",
+ onnx_config_cls="models.gptj.GPTJOnnxConfig",
+ ),
+ "gpt-neo": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "sequence-classification",
+ onnx_config_cls="models.gpt_neo.GPTNeoOnnxConfig",
+ ),
+ "groupvit": supported_features_mapping(
+ "default",
+ onnx_config_cls="models.groupvit.GroupViTOnnxConfig",
+ ),
+ "ibert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.ibert.IBertOnnxConfig",
+ ),
+ "imagegpt": supported_features_mapping(
+ "default", "image-classification", onnx_config_cls="models.imagegpt.ImageGPTOnnxConfig"
+ ),
+ "layoutlm": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "token-classification",
+ onnx_config_cls="models.layoutlm.LayoutLMOnnxConfig",
+ ),
+ "layoutlmv3": supported_features_mapping(
+ "default",
+ "question-answering",
+ "sequence-classification",
+ "token-classification",
+ onnx_config_cls="models.layoutlmv3.LayoutLMv3OnnxConfig",
+ ),
+ "levit": supported_features_mapping(
+ "default", "image-classification", onnx_config_cls="models.levit.LevitOnnxConfig"
+ ),
+ "longt5": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ onnx_config_cls="models.longt5.LongT5OnnxConfig",
+ ),
+ "longformer": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "multiple-choice",
+ "question-answering",
+ "sequence-classification",
+ "token-classification",
+ onnx_config_cls="models.longformer.LongformerOnnxConfig",
+ ),
+ "marian": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ onnx_config_cls="models.marian.MarianOnnxConfig",
+ ),
+ "mbart": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "causal-lm",
+ "causal-lm-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ "sequence-classification",
+ "question-answering",
+ onnx_config_cls="models.mbart.MBartOnnxConfig",
+ ),
+ "mobilebert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.mobilebert.MobileBertOnnxConfig",
+ ),
+ "mobilenet-v1": supported_features_mapping(
+ "default",
+ "image-classification",
+ onnx_config_cls="models.mobilenet_v1.MobileNetV1OnnxConfig",
+ ),
+ "mobilenet-v2": supported_features_mapping(
+ "default",
+ "image-classification",
+ onnx_config_cls="models.mobilenet_v2.MobileNetV2OnnxConfig",
+ ),
+ "mobilevit": supported_features_mapping(
+ "default",
+ "image-classification",
+ onnx_config_cls="models.mobilevit.MobileViTOnnxConfig",
+ ),
+ "mt5": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ onnx_config_cls="models.mt5.MT5OnnxConfig",
+ ),
+ "m2m-100": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ onnx_config_cls="models.m2m_100.M2M100OnnxConfig",
+ ),
+ "owlvit": supported_features_mapping(
+ "default",
+ onnx_config_cls="models.owlvit.OwlViTOnnxConfig",
+ ),
+ "perceiver": supported_features_mapping(
+ "image-classification",
+ "masked-lm",
+ "sequence-classification",
+ onnx_config_cls="models.perceiver.PerceiverOnnxConfig",
+ ),
+ "poolformer": supported_features_mapping(
+ "default", "image-classification", onnx_config_cls="models.poolformer.PoolFormerOnnxConfig"
+ ),
+ "rembert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.rembert.RemBertOnnxConfig",
+ ),
+ "resnet": supported_features_mapping(
+ "default",
+ "image-classification",
+ onnx_config_cls="models.resnet.ResNetOnnxConfig",
+ ),
+ "roberta": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.roberta.RobertaOnnxConfig",
+ ),
+ "roformer": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "token-classification",
+ "multiple-choice",
+ "question-answering",
+ "token-classification",
+ onnx_config_cls="models.roformer.RoFormerOnnxConfig",
+ ),
+ "segformer": supported_features_mapping(
+ "default",
+ "image-classification",
+ "semantic-segmentation",
+ onnx_config_cls="models.segformer.SegformerOnnxConfig",
+ ),
+ "squeezebert": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.squeezebert.SqueezeBertOnnxConfig",
+ ),
+ "swin": supported_features_mapping(
+ "default", "image-classification", onnx_config_cls="models.swin.SwinOnnxConfig"
+ ),
+ "t5": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "seq2seq-lm",
+ "seq2seq-lm-with-past",
+ onnx_config_cls="models.t5.T5OnnxConfig",
+ ),
+ "vision-encoder-decoder": supported_features_mapping(
+ "vision2seq-lm", onnx_config_cls="models.vision_encoder_decoder.VisionEncoderDecoderOnnxConfig"
+ ),
+ "vit": supported_features_mapping(
+ "default", "image-classification", onnx_config_cls="models.vit.ViTOnnxConfig"
+ ),
+ "whisper": supported_features_mapping(
+ "default",
+ "default-with-past",
+ "speech2seq-lm",
+ "speech2seq-lm-with-past",
+ onnx_config_cls="models.whisper.WhisperOnnxConfig",
+ ),
+ "xlm": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.xlm.XLMOnnxConfig",
+ ),
+ "xlm-roberta": supported_features_mapping(
+ "default",
+ "masked-lm",
+ "causal-lm",
+ "sequence-classification",
+ "multiple-choice",
+ "token-classification",
+ "question-answering",
+ onnx_config_cls="models.xlm_roberta.XLMRobertaOnnxConfig",
+ ),
+ "yolos": supported_features_mapping(
+ "default",
+ "object-detection",
+ onnx_config_cls="models.yolos.YolosOnnxConfig",
+ ),
+ }
+
+ AVAILABLE_FEATURES = sorted(reduce(lambda s1, s2: s1 | s2, (v.keys() for v in _SUPPORTED_MODEL_TYPE.values())))
+
+ @staticmethod
+ def get_supported_features_for_model_type(
+ model_type: str, model_name: Optional[str] = None
+ ) -> dict[str, Callable[[PretrainedConfig], OnnxConfig]]:
+ """
+ Tries to retrieve the feature -> OnnxConfig constructor map from the model type.
+
+ Args:
+ model_type (`str`):
+ The model type to retrieve the supported features for.
+ model_name (`str`, *optional*):
+ The name attribute of the model object, only used for the exception message.
+
+ Returns:
+ The dictionary mapping each feature to a corresponding OnnxConfig constructor.
+ """
+ model_type = model_type.lower()
+ if model_type not in FeaturesManager._SUPPORTED_MODEL_TYPE:
+ model_type_and_model_name = f"{model_type} ({model_name})" if model_name else model_type
+ raise KeyError(
+ f"{model_type_and_model_name} is not supported yet. "
+ f"Only {list(FeaturesManager._SUPPORTED_MODEL_TYPE.keys())} are supported. "
+ f"If you want to support {model_type} please propose a PR or open up an issue."
+ )
+ return FeaturesManager._SUPPORTED_MODEL_TYPE[model_type]
+
+ @staticmethod
+ def feature_to_task(feature: str) -> str:
+ return feature.replace("-with-past", "")
+
+ @staticmethod
+ def _validate_framework_choice(framework: str):
+ """
+ Validates if the framework requested for the export is both correct and available, otherwise throws an
+ exception.
+ """
+ if framework not in ["pt", "tf"]:
+ raise ValueError(
+ f"Only two frameworks are supported for ONNX export: pt or tf, but {framework} was provided."
+ )
+ elif framework == "pt" and not is_torch_available():
+ raise RuntimeError("Cannot export model to ONNX using PyTorch because no PyTorch package was found.")
+ elif framework == "tf" and not is_tf_available():
+ raise RuntimeError("Cannot export model to ONNX using TensorFlow because no TensorFlow package was found.")
+
+ @staticmethod
+ def get_model_class_for_feature(feature: str, framework: str = "pt") -> type:
+ """
+ Attempts to retrieve an AutoModel class from a feature name.
+
+ Args:
+ feature (`str`):
+ The feature required.
+ framework (`str`, *optional*, defaults to `"pt"`):
+ The framework to use for the export.
+
+ Returns:
+ The AutoModel class corresponding to the feature.
+ """
+ task = FeaturesManager.feature_to_task(feature)
+ FeaturesManager._validate_framework_choice(framework)
+ if framework == "pt":
+ task_to_automodel = FeaturesManager._TASKS_TO_AUTOMODELS
+ else:
+ task_to_automodel = FeaturesManager._TASKS_TO_TF_AUTOMODELS
+ if task not in task_to_automodel:
+ raise KeyError(
+ f"Unknown task: {feature}. Possible values are {list(FeaturesManager._TASKS_TO_AUTOMODELS.values())}"
+ )
+
+ return task_to_automodel[task]
+
+ @staticmethod
+ def determine_framework(model: str, framework: Optional[str] = None) -> str:
+ """
+ Determines the framework to use for the export.
+
+ The priority is in the following order:
+ 1. User input via `framework`.
+ 2. If local checkpoint is provided, use the same framework as the checkpoint.
+ 3. Available framework in environment, with priority given to PyTorch
+
+ Args:
+ model (`str`):
+ The name of the model to export.
+ framework (`str`, *optional*, defaults to `None`):
+ The framework to use for the export. See above for priority if none provided.
+
+ Returns:
+ The framework to use for the export.
+
+ """
+ if framework is not None:
+ return framework
+
+ framework_map = {"pt": "PyTorch", "tf": "TensorFlow"}
+ exporter_map = {"pt": "torch", "tf": "tf2onnx"}
+
+ if os.path.isdir(model):
+ if os.path.isfile(os.path.join(model, WEIGHTS_NAME)):
+ framework = "pt"
+ elif os.path.isfile(os.path.join(model, TF2_WEIGHTS_NAME)):
+ framework = "tf"
+ else:
+ raise FileNotFoundError(
+ "Cannot determine framework from given checkpoint location."
+ f" There should be a {WEIGHTS_NAME} for PyTorch"
+ f" or {TF2_WEIGHTS_NAME} for TensorFlow."
+ )
+ logger.info(f"Local {framework_map[framework]} model found.")
+ else:
+ if is_torch_available():
+ framework = "pt"
+ elif is_tf_available():
+ framework = "tf"
+ else:
+ raise OSError("Neither PyTorch nor TensorFlow found in environment. Cannot export to ONNX.")
+
+ logger.info(f"Framework not requested. Using {exporter_map[framework]} to export to ONNX.")
+
+ return framework
+
+ @staticmethod
+ def get_model_from_feature(
+ feature: str, model: str, framework: Optional[str] = None, cache_dir: Optional[str] = None
+ ) -> Union["PreTrainedModel", "TFPreTrainedModel"]:
+ """
+ Attempts to retrieve a model from a model's name and the feature to be enabled.
+
+ Args:
+ feature (`str`):
+ The feature required.
+ model (`str`):
+ The name of the model to export.
+ framework (`str`, *optional*, defaults to `None`):
+ The framework to use for the export. See `FeaturesManager.determine_framework` for the priority should
+ none be provided.
+
+ Returns:
+ The instance of the model.
+
+ """
+ framework = FeaturesManager.determine_framework(model, framework)
+ model_class = FeaturesManager.get_model_class_for_feature(feature, framework)
+ try:
+ model = model_class.from_pretrained(model, cache_dir=cache_dir)
+ except OSError:
+ if framework == "pt":
+ logger.info("Loading TensorFlow model in PyTorch before exporting to ONNX.")
+ model = model_class.from_pretrained(model, from_tf=True, cache_dir=cache_dir)
+ else:
+ logger.info("Loading PyTorch model in TensorFlow before exporting to ONNX.")
+ model = model_class.from_pretrained(model, from_pt=True, cache_dir=cache_dir)
+ return model
+
+ @staticmethod
+ def check_supported_model_or_raise(
+ model: Union["PreTrainedModel", "TFPreTrainedModel"], feature: str = "default"
+ ) -> tuple[str, Callable]:
+ """
+ Check whether or not the model has the requested features.
+
+ Args:
+ model: The model to export.
+ feature: The name of the feature to check if it is available.
+
+ Returns:
+ (str) The type of the model (OnnxConfig) The OnnxConfig instance holding the model export properties.
+
+ """
+ model_type = model.config.model_type.replace("_", "-")
+ model_name = getattr(model, "name", "")
+ model_features = FeaturesManager.get_supported_features_for_model_type(model_type, model_name=model_name)
+ if feature not in model_features:
+ raise ValueError(
+ f"{model.config.model_type} doesn't support feature {feature}. Supported values are: {model_features}"
+ )
+
+ return model.config.model_type, FeaturesManager._SUPPORTED_MODEL_TYPE[model_type][feature]
+
+ def get_config(model_type: str, feature: str) -> OnnxConfig:
+ """
+ Gets the OnnxConfig for a model_type and feature combination.
+
+ Args:
+ model_type (`str`):
+ The model type to retrieve the config for.
+ feature (`str`):
+ The feature to retrieve the config for.
+
+ Returns:
+ `OnnxConfig`: config for the combination
+ """
+ return FeaturesManager._SUPPORTED_MODEL_TYPE[model_type][feature]
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/utils.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..9672b0a96af88ffa2c7e791d1f4d7c818174247f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/onnx/utils.py
@@ -0,0 +1,109 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from ctypes import c_float, sizeof
+from enum import Enum
+from typing import TYPE_CHECKING, Optional, Union
+
+
+if TYPE_CHECKING:
+ from .. import AutoFeatureExtractor, AutoProcessor, AutoTokenizer # tests_ignore
+
+
+class ParameterFormat(Enum):
+ Float = c_float
+
+ @property
+ def size(self) -> int:
+ """
+ Number of byte required for this data type
+
+ Returns:
+ Integer > 0
+ """
+ return sizeof(self.value)
+
+
+def compute_effective_axis_dimension(dimension: int, fixed_dimension: int, num_token_to_add: int = 0) -> int:
+ """
+
+ Args:
+ dimension:
+ fixed_dimension:
+ num_token_to_add:
+
+ Returns:
+
+ """
+ # < 0 is possible if using a dynamic axis
+ if dimension <= 0:
+ dimension = fixed_dimension
+
+ dimension -= num_token_to_add
+ return dimension
+
+
+def compute_serialized_parameters_size(num_parameters: int, dtype: ParameterFormat) -> int:
+ """
+ Compute the size taken by all the parameters in the given the storage format when serializing the model
+
+ Args:
+ num_parameters: Number of parameters to be saved
+ dtype: The data format each parameter will be saved
+
+ Returns:
+ Size (in byte) taken to save all the parameters
+ """
+ return num_parameters * dtype.size
+
+
+def get_preprocessor(model_name: str) -> Optional[Union["AutoTokenizer", "AutoFeatureExtractor", "AutoProcessor"]]:
+ """
+ Gets a preprocessor (tokenizer, feature extractor or processor) that is available for `model_name`.
+
+ Args:
+ model_name (`str`): Name of the model for which a preprocessor are loaded.
+
+ Returns:
+ `Optional[Union[AutoTokenizer, AutoFeatureExtractor, AutoProcessor]]`:
+ If a processor is found, it is returned. Otherwise, if a tokenizer or a feature extractor exists, it is
+ returned. If both a tokenizer and a feature extractor exist, an error is raised. The function returns
+ `None` if no preprocessor is found.
+ """
+ # Avoid circular imports by only importing this here.
+ from .. import AutoFeatureExtractor, AutoProcessor, AutoTokenizer # tests_ignore
+
+ try:
+ return AutoProcessor.from_pretrained(model_name)
+ except (ValueError, OSError, KeyError):
+ tokenizer, feature_extractor = None, None
+ try:
+ tokenizer = AutoTokenizer.from_pretrained(model_name)
+ except (OSError, KeyError):
+ pass
+ try:
+ feature_extractor = AutoFeatureExtractor.from_pretrained(model_name)
+ except (OSError, KeyError):
+ pass
+
+ if tokenizer is not None and feature_extractor is not None:
+ raise ValueError(
+ f"Couldn't auto-detect preprocessor for {model_name}. Found both a tokenizer and a feature extractor."
+ )
+ elif tokenizer is None and feature_extractor is None:
+ return None
+ elif tokenizer is not None:
+ return tokenizer
+ else:
+ return feature_extractor
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/__init__.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..92da22477f55f763d0f53c3bfa5477755a17438f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/__init__.py
@@ -0,0 +1,1230 @@
+# coding=utf-8
+# Copyright 2018 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import json
+import os
+import warnings
+from pathlib import Path
+from typing import TYPE_CHECKING, Any, Optional, Union
+
+from huggingface_hub import model_info
+
+from ..configuration_utils import PretrainedConfig
+from ..dynamic_module_utils import get_class_from_dynamic_module
+from ..feature_extraction_utils import PreTrainedFeatureExtractor
+from ..image_processing_utils import BaseImageProcessor
+from ..models.auto.configuration_auto import AutoConfig
+from ..models.auto.feature_extraction_auto import FEATURE_EXTRACTOR_MAPPING, AutoFeatureExtractor
+from ..models.auto.image_processing_auto import IMAGE_PROCESSOR_MAPPING, AutoImageProcessor
+from ..models.auto.modeling_auto import AutoModelForDepthEstimation, AutoModelForImageToImage
+from ..models.auto.processing_auto import PROCESSOR_MAPPING, AutoProcessor
+from ..models.auto.tokenization_auto import TOKENIZER_MAPPING, AutoTokenizer
+from ..processing_utils import ProcessorMixin
+from ..tokenization_utils import PreTrainedTokenizer
+from ..utils import (
+ CONFIG_NAME,
+ HUGGINGFACE_CO_RESOLVE_ENDPOINT,
+ cached_file,
+ extract_commit_hash,
+ find_adapter_config_file,
+ is_kenlm_available,
+ is_offline_mode,
+ is_peft_available,
+ is_pyctcdecode_available,
+ is_tf_available,
+ is_torch_available,
+ logging,
+)
+from .audio_classification import AudioClassificationPipeline
+from .automatic_speech_recognition import AutomaticSpeechRecognitionPipeline
+from .base import (
+ ArgumentHandler,
+ CsvPipelineDataFormat,
+ JsonPipelineDataFormat,
+ PipedPipelineDataFormat,
+ Pipeline,
+ PipelineDataFormat,
+ PipelineException,
+ PipelineRegistry,
+ get_default_model_and_revision,
+ infer_framework_load_model,
+)
+from .depth_estimation import DepthEstimationPipeline
+from .document_question_answering import DocumentQuestionAnsweringPipeline
+from .feature_extraction import FeatureExtractionPipeline
+from .fill_mask import FillMaskPipeline
+from .image_classification import ImageClassificationPipeline
+from .image_feature_extraction import ImageFeatureExtractionPipeline
+from .image_segmentation import ImageSegmentationPipeline
+from .image_text_to_text import ImageTextToTextPipeline
+from .image_to_image import ImageToImagePipeline
+from .image_to_text import ImageToTextPipeline
+from .keypoint_matching import KeypointMatchingPipeline
+from .mask_generation import MaskGenerationPipeline
+from .object_detection import ObjectDetectionPipeline
+from .question_answering import QuestionAnsweringArgumentHandler, QuestionAnsweringPipeline
+from .table_question_answering import TableQuestionAnsweringArgumentHandler, TableQuestionAnsweringPipeline
+from .text2text_generation import SummarizationPipeline, Text2TextGenerationPipeline, TranslationPipeline
+from .text_classification import TextClassificationPipeline
+from .text_generation import TextGenerationPipeline
+from .text_to_audio import TextToAudioPipeline
+from .token_classification import (
+ AggregationStrategy,
+ NerPipeline,
+ TokenClassificationArgumentHandler,
+ TokenClassificationPipeline,
+)
+from .video_classification import VideoClassificationPipeline
+from .visual_question_answering import VisualQuestionAnsweringPipeline
+from .zero_shot_audio_classification import ZeroShotAudioClassificationPipeline
+from .zero_shot_classification import ZeroShotClassificationArgumentHandler, ZeroShotClassificationPipeline
+from .zero_shot_image_classification import ZeroShotImageClassificationPipeline
+from .zero_shot_object_detection import ZeroShotObjectDetectionPipeline
+
+
+if is_tf_available():
+ import tensorflow as tf
+
+ from ..models.auto.modeling_tf_auto import (
+ TFAutoModel,
+ TFAutoModelForCausalLM,
+ TFAutoModelForImageClassification,
+ TFAutoModelForMaskedLM,
+ TFAutoModelForQuestionAnswering,
+ TFAutoModelForSeq2SeqLM,
+ TFAutoModelForSequenceClassification,
+ TFAutoModelForTableQuestionAnswering,
+ TFAutoModelForTokenClassification,
+ TFAutoModelForVision2Seq,
+ TFAutoModelForZeroShotImageClassification,
+ )
+
+if is_torch_available():
+ import torch
+
+ from ..models.auto.modeling_auto import (
+ AutoModel,
+ AutoModelForAudioClassification,
+ AutoModelForCausalLM,
+ AutoModelForCTC,
+ AutoModelForDocumentQuestionAnswering,
+ AutoModelForImageClassification,
+ AutoModelForImageSegmentation,
+ AutoModelForImageTextToText,
+ AutoModelForKeypointMatching,
+ AutoModelForMaskedLM,
+ AutoModelForMaskGeneration,
+ AutoModelForObjectDetection,
+ AutoModelForQuestionAnswering,
+ AutoModelForSemanticSegmentation,
+ AutoModelForSeq2SeqLM,
+ AutoModelForSequenceClassification,
+ AutoModelForSpeechSeq2Seq,
+ AutoModelForTableQuestionAnswering,
+ AutoModelForTextToSpectrogram,
+ AutoModelForTextToWaveform,
+ AutoModelForTokenClassification,
+ AutoModelForVideoClassification,
+ AutoModelForVision2Seq,
+ AutoModelForVisualQuestionAnswering,
+ AutoModelForZeroShotImageClassification,
+ AutoModelForZeroShotObjectDetection,
+ )
+
+
+if TYPE_CHECKING:
+ from ..modeling_tf_utils import TFPreTrainedModel
+ from ..modeling_utils import PreTrainedModel
+ from ..tokenization_utils_fast import PreTrainedTokenizerFast
+
+
+logger = logging.get_logger(__name__)
+
+
+# Register all the supported tasks here
+TASK_ALIASES = {
+ "sentiment-analysis": "text-classification",
+ "ner": "token-classification",
+ "vqa": "visual-question-answering",
+ "text-to-speech": "text-to-audio",
+}
+SUPPORTED_TASKS = {
+ "audio-classification": {
+ "impl": AudioClassificationPipeline,
+ "tf": (),
+ "pt": (AutoModelForAudioClassification,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("superb/wav2vec2-base-superb-ks", "372e048")}},
+ "type": "audio",
+ },
+ "automatic-speech-recognition": {
+ "impl": AutomaticSpeechRecognitionPipeline,
+ "tf": (),
+ "pt": (AutoModelForCTC, AutoModelForSpeechSeq2Seq) if is_torch_available() else (),
+ "default": {"model": {"pt": ("facebook/wav2vec2-base-960h", "22aad52")}},
+ "type": "multimodal",
+ },
+ "text-to-audio": {
+ "impl": TextToAudioPipeline,
+ "tf": (),
+ "pt": (AutoModelForTextToWaveform, AutoModelForTextToSpectrogram) if is_torch_available() else (),
+ "default": {"model": {"pt": ("suno/bark-small", "1dbd7a1")}},
+ "type": "text",
+ },
+ "feature-extraction": {
+ "impl": FeatureExtractionPipeline,
+ "tf": (TFAutoModel,) if is_tf_available() else (),
+ "pt": (AutoModel,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("distilbert/distilbert-base-cased", "6ea8117"),
+ "tf": ("distilbert/distilbert-base-cased", "6ea8117"),
+ }
+ },
+ "type": "multimodal",
+ },
+ "text-classification": {
+ "impl": TextClassificationPipeline,
+ "tf": (TFAutoModelForSequenceClassification,) if is_tf_available() else (),
+ "pt": (AutoModelForSequenceClassification,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("distilbert/distilbert-base-uncased-finetuned-sst-2-english", "714eb0f"),
+ "tf": ("distilbert/distilbert-base-uncased-finetuned-sst-2-english", "714eb0f"),
+ },
+ },
+ "type": "text",
+ },
+ "token-classification": {
+ "impl": TokenClassificationPipeline,
+ "tf": (TFAutoModelForTokenClassification,) if is_tf_available() else (),
+ "pt": (AutoModelForTokenClassification,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("dbmdz/bert-large-cased-finetuned-conll03-english", "4c53496"),
+ "tf": ("dbmdz/bert-large-cased-finetuned-conll03-english", "4c53496"),
+ },
+ },
+ "type": "text",
+ },
+ "question-answering": {
+ "impl": QuestionAnsweringPipeline,
+ "tf": (TFAutoModelForQuestionAnswering,) if is_tf_available() else (),
+ "pt": (AutoModelForQuestionAnswering,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("distilbert/distilbert-base-cased-distilled-squad", "564e9b5"),
+ "tf": ("distilbert/distilbert-base-cased-distilled-squad", "564e9b5"),
+ },
+ },
+ "type": "text",
+ },
+ "table-question-answering": {
+ "impl": TableQuestionAnsweringPipeline,
+ "pt": (AutoModelForTableQuestionAnswering,) if is_torch_available() else (),
+ "tf": (TFAutoModelForTableQuestionAnswering,) if is_tf_available() else (),
+ "default": {
+ "model": {
+ "pt": ("google/tapas-base-finetuned-wtq", "e3dde19"),
+ "tf": ("google/tapas-base-finetuned-wtq", "e3dde19"),
+ },
+ },
+ "type": "text",
+ },
+ "visual-question-answering": {
+ "impl": VisualQuestionAnsweringPipeline,
+ "pt": (AutoModelForVisualQuestionAnswering,) if is_torch_available() else (),
+ "tf": (),
+ "default": {
+ "model": {"pt": ("dandelin/vilt-b32-finetuned-vqa", "d0a1f6a")},
+ },
+ "type": "multimodal",
+ },
+ "document-question-answering": {
+ "impl": DocumentQuestionAnsweringPipeline,
+ "pt": (AutoModelForDocumentQuestionAnswering,) if is_torch_available() else (),
+ "tf": (),
+ "default": {
+ "model": {"pt": ("impira/layoutlm-document-qa", "beed3c4")},
+ },
+ "type": "multimodal",
+ },
+ "fill-mask": {
+ "impl": FillMaskPipeline,
+ "tf": (TFAutoModelForMaskedLM,) if is_tf_available() else (),
+ "pt": (AutoModelForMaskedLM,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("distilbert/distilroberta-base", "fb53ab8"),
+ "tf": ("distilbert/distilroberta-base", "fb53ab8"),
+ }
+ },
+ "type": "text",
+ },
+ "summarization": {
+ "impl": SummarizationPipeline,
+ "tf": (TFAutoModelForSeq2SeqLM,) if is_tf_available() else (),
+ "pt": (AutoModelForSeq2SeqLM,) if is_torch_available() else (),
+ "default": {
+ "model": {"pt": ("sshleifer/distilbart-cnn-12-6", "a4f8f3e"), "tf": ("google-t5/t5-small", "df1b051")}
+ },
+ "type": "text",
+ },
+ # This task is a special case as it's parametrized by SRC, TGT languages.
+ "translation": {
+ "impl": TranslationPipeline,
+ "tf": (TFAutoModelForSeq2SeqLM,) if is_tf_available() else (),
+ "pt": (AutoModelForSeq2SeqLM,) if is_torch_available() else (),
+ "default": {
+ ("en", "fr"): {"model": {"pt": ("google-t5/t5-base", "a9723ea"), "tf": ("google-t5/t5-base", "a9723ea")}},
+ ("en", "de"): {"model": {"pt": ("google-t5/t5-base", "a9723ea"), "tf": ("google-t5/t5-base", "a9723ea")}},
+ ("en", "ro"): {"model": {"pt": ("google-t5/t5-base", "a9723ea"), "tf": ("google-t5/t5-base", "a9723ea")}},
+ },
+ "type": "text",
+ },
+ "text2text-generation": {
+ "impl": Text2TextGenerationPipeline,
+ "tf": (TFAutoModelForSeq2SeqLM,) if is_tf_available() else (),
+ "pt": (AutoModelForSeq2SeqLM,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("google-t5/t5-base", "a9723ea"), "tf": ("google-t5/t5-base", "a9723ea")}},
+ "type": "text",
+ },
+ "text-generation": {
+ "impl": TextGenerationPipeline,
+ "tf": (TFAutoModelForCausalLM,) if is_tf_available() else (),
+ "pt": (AutoModelForCausalLM,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("openai-community/gpt2", "607a30d"), "tf": ("openai-community/gpt2", "607a30d")}},
+ "type": "text",
+ },
+ "zero-shot-classification": {
+ "impl": ZeroShotClassificationPipeline,
+ "tf": (TFAutoModelForSequenceClassification,) if is_tf_available() else (),
+ "pt": (AutoModelForSequenceClassification,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("facebook/bart-large-mnli", "d7645e1"),
+ "tf": ("FacebookAI/roberta-large-mnli", "2a8f12d"),
+ },
+ "config": {
+ "pt": ("facebook/bart-large-mnli", "d7645e1"),
+ "tf": ("FacebookAI/roberta-large-mnli", "2a8f12d"),
+ },
+ },
+ "type": "text",
+ },
+ "zero-shot-image-classification": {
+ "impl": ZeroShotImageClassificationPipeline,
+ "tf": (TFAutoModelForZeroShotImageClassification,) if is_tf_available() else (),
+ "pt": (AutoModelForZeroShotImageClassification,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("openai/clip-vit-base-patch32", "3d74acf"),
+ "tf": ("openai/clip-vit-base-patch32", "3d74acf"),
+ }
+ },
+ "type": "multimodal",
+ },
+ "zero-shot-audio-classification": {
+ "impl": ZeroShotAudioClassificationPipeline,
+ "tf": (),
+ "pt": (AutoModel,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("laion/clap-htsat-fused", "cca9e28"),
+ }
+ },
+ "type": "multimodal",
+ },
+ "image-classification": {
+ "impl": ImageClassificationPipeline,
+ "tf": (TFAutoModelForImageClassification,) if is_tf_available() else (),
+ "pt": (AutoModelForImageClassification,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("google/vit-base-patch16-224", "3f49326"),
+ "tf": ("google/vit-base-patch16-224", "3f49326"),
+ }
+ },
+ "type": "image",
+ },
+ "image-feature-extraction": {
+ "impl": ImageFeatureExtractionPipeline,
+ "tf": (TFAutoModel,) if is_tf_available() else (),
+ "pt": (AutoModel,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("google/vit-base-patch16-224", "3f49326"),
+ "tf": ("google/vit-base-patch16-224", "3f49326"),
+ }
+ },
+ "type": "image",
+ },
+ "image-segmentation": {
+ "impl": ImageSegmentationPipeline,
+ "tf": (),
+ "pt": (AutoModelForImageSegmentation, AutoModelForSemanticSegmentation) if is_torch_available() else (),
+ "default": {"model": {"pt": ("facebook/detr-resnet-50-panoptic", "d53b52a")}},
+ "type": "multimodal",
+ },
+ "image-to-text": {
+ "impl": ImageToTextPipeline,
+ "tf": (TFAutoModelForVision2Seq,) if is_tf_available() else (),
+ "pt": (AutoModelForVision2Seq,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("ydshieh/vit-gpt2-coco-en", "5bebf1e"),
+ "tf": ("ydshieh/vit-gpt2-coco-en", "5bebf1e"),
+ }
+ },
+ "type": "multimodal",
+ },
+ "image-text-to-text": {
+ "impl": ImageTextToTextPipeline,
+ "tf": (),
+ "pt": (AutoModelForImageTextToText,) if is_torch_available() else (),
+ "default": {
+ "model": {
+ "pt": ("llava-hf/llava-onevision-qwen2-0.5b-ov-hf", "2c9ba3b"),
+ }
+ },
+ "type": "multimodal",
+ },
+ "object-detection": {
+ "impl": ObjectDetectionPipeline,
+ "tf": (),
+ "pt": (AutoModelForObjectDetection,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("facebook/detr-resnet-50", "1d5f47b")}},
+ "type": "multimodal",
+ },
+ "zero-shot-object-detection": {
+ "impl": ZeroShotObjectDetectionPipeline,
+ "tf": (),
+ "pt": (AutoModelForZeroShotObjectDetection,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("google/owlvit-base-patch32", "cbc355f")}},
+ "type": "multimodal",
+ },
+ "depth-estimation": {
+ "impl": DepthEstimationPipeline,
+ "tf": (),
+ "pt": (AutoModelForDepthEstimation,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("Intel/dpt-large", "bc15f29")}},
+ "type": "image",
+ },
+ "video-classification": {
+ "impl": VideoClassificationPipeline,
+ "tf": (),
+ "pt": (AutoModelForVideoClassification,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("MCG-NJU/videomae-base-finetuned-kinetics", "488eb9a")}},
+ "type": "video",
+ },
+ "mask-generation": {
+ "impl": MaskGenerationPipeline,
+ "tf": (),
+ "pt": (AutoModelForMaskGeneration,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("facebook/sam-vit-huge", "87aecf0")}},
+ "type": "multimodal",
+ },
+ "image-to-image": {
+ "impl": ImageToImagePipeline,
+ "tf": (),
+ "pt": (AutoModelForImageToImage,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("caidas/swin2SR-classical-sr-x2-64", "cee1c92")}},
+ "type": "image",
+ },
+ "keypoint-matching": {
+ "impl": KeypointMatchingPipeline,
+ "tf": (),
+ "pt": (AutoModelForKeypointMatching,) if is_torch_available() else (),
+ "default": {"model": {"pt": ("magic-leap-community/superglue_outdoor", "f4041f8")}},
+ "type": "image",
+ },
+}
+
+PIPELINE_REGISTRY = PipelineRegistry(supported_tasks=SUPPORTED_TASKS, task_aliases=TASK_ALIASES)
+
+
+def get_supported_tasks() -> list[str]:
+ """
+ Returns a list of supported task strings.
+ """
+ return PIPELINE_REGISTRY.get_supported_tasks()
+
+
+def get_task(model: str, token: Optional[str] = None, **deprecated_kwargs) -> str:
+ use_auth_token = deprecated_kwargs.pop("use_auth_token", None)
+ if use_auth_token is not None:
+ warnings.warn(
+ "The `use_auth_token` argument is deprecated and will be removed in v5 of Transformers. Please use `token` instead.",
+ FutureWarning,
+ )
+ if token is not None:
+ raise ValueError("`token` and `use_auth_token` are both specified. Please set only the argument `token`.")
+ token = use_auth_token
+
+ if is_offline_mode():
+ raise RuntimeError("You cannot infer task automatically within `pipeline` when using offline mode")
+ try:
+ info = model_info(model, token=token)
+ except Exception as e:
+ raise RuntimeError(f"Instantiating a pipeline without a task set raised an error: {e}")
+ if not info.pipeline_tag:
+ raise RuntimeError(
+ f"The model {model} does not seem to have a correct `pipeline_tag` set to infer the task automatically"
+ )
+ if getattr(info, "library_name", "transformers") not in {"transformers", "timm"}:
+ raise RuntimeError(f"This model is meant to be used with {info.library_name} not with transformers")
+ task = info.pipeline_tag
+ return task
+
+
+def check_task(task: str) -> tuple[str, dict, Any]:
+ """
+ Checks an incoming task string, to validate it's correct and return the default Pipeline and Model classes, and
+ default models if they exist.
+
+ Args:
+ task (`str`):
+ The task defining which pipeline will be returned. Currently accepted tasks are:
+
+ - `"audio-classification"`
+ - `"automatic-speech-recognition"`
+ - `"conversational"`
+ - `"depth-estimation"`
+ - `"document-question-answering"`
+ - `"feature-extraction"`
+ - `"fill-mask"`
+ - `"image-classification"`
+ - `"image-feature-extraction"`
+ - `"image-segmentation"`
+ - `"image-to-text"`
+ - `"image-to-image"`
+ - `"keypoint-matching"`
+ - `"object-detection"`
+ - `"question-answering"`
+ - `"summarization"`
+ - `"table-question-answering"`
+ - `"text2text-generation"`
+ - `"text-classification"` (alias `"sentiment-analysis"` available)
+ - `"text-generation"`
+ - `"text-to-audio"` (alias `"text-to-speech"` available)
+ - `"token-classification"` (alias `"ner"` available)
+ - `"translation"`
+ - `"translation_xx_to_yy"`
+ - `"video-classification"`
+ - `"visual-question-answering"` (alias `"vqa"` available)
+ - `"zero-shot-classification"`
+ - `"zero-shot-image-classification"`
+ - `"zero-shot-object-detection"`
+
+ Returns:
+ (normalized_task: `str`, task_defaults: `dict`, task_options: (`tuple`, None)) The normalized task name
+ (removed alias and options). The actual dictionary required to initialize the pipeline and some extra task
+ options for parametrized tasks like "translation_xx_to_yy"
+
+
+ """
+ return PIPELINE_REGISTRY.check_task(task)
+
+
+def clean_custom_task(task_info):
+ import transformers
+
+ if "impl" not in task_info:
+ raise RuntimeError("This model introduces a custom pipeline without specifying its implementation.")
+ pt_class_names = task_info.get("pt", ())
+ if isinstance(pt_class_names, str):
+ pt_class_names = [pt_class_names]
+ task_info["pt"] = tuple(getattr(transformers, c) for c in pt_class_names)
+ tf_class_names = task_info.get("tf", ())
+ if isinstance(tf_class_names, str):
+ tf_class_names = [tf_class_names]
+ task_info["tf"] = tuple(getattr(transformers, c) for c in tf_class_names)
+ return task_info, None
+
+
+#
+# fmt: off
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# The part of the file below was automatically generated from the code.
+# Do NOT edit this part of the file manually as any edits will be overwritten by the generation
+# of the file. If any change should be done, please apply the changes to the `pipeline` function
+# below and run `python utils/check_pipeline_typing.py --fix_and_overwrite` to update the file.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+
+from typing import Literal, overload
+
+
+@overload
+def pipeline(task: Literal[None], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> Pipeline: ...
+@overload
+def pipeline(task: Literal["audio-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> AudioClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["automatic-speech-recognition"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> AutomaticSpeechRecognitionPipeline: ...
+@overload
+def pipeline(task: Literal["depth-estimation"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> DepthEstimationPipeline: ...
+@overload
+def pipeline(task: Literal["document-question-answering"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> DocumentQuestionAnsweringPipeline: ...
+@overload
+def pipeline(task: Literal["feature-extraction"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> FeatureExtractionPipeline: ...
+@overload
+def pipeline(task: Literal["fill-mask"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> FillMaskPipeline: ...
+@overload
+def pipeline(task: Literal["image-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ImageClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["image-feature-extraction"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ImageFeatureExtractionPipeline: ...
+@overload
+def pipeline(task: Literal["image-segmentation"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ImageSegmentationPipeline: ...
+@overload
+def pipeline(task: Literal["image-text-to-text"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ImageTextToTextPipeline: ...
+@overload
+def pipeline(task: Literal["image-to-image"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ImageToImagePipeline: ...
+@overload
+def pipeline(task: Literal["image-to-text"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ImageToTextPipeline: ...
+@overload
+def pipeline(task: Literal["keypoint-matching"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> KeypointMatchingPipeline: ...
+@overload
+def pipeline(task: Literal["mask-generation"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> MaskGenerationPipeline: ...
+@overload
+def pipeline(task: Literal["object-detection"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ObjectDetectionPipeline: ...
+@overload
+def pipeline(task: Literal["question-answering"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> QuestionAnsweringPipeline: ...
+@overload
+def pipeline(task: Literal["summarization"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> SummarizationPipeline: ...
+@overload
+def pipeline(task: Literal["table-question-answering"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> TableQuestionAnsweringPipeline: ...
+@overload
+def pipeline(task: Literal["text-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> TextClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["text-generation"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> TextGenerationPipeline: ...
+@overload
+def pipeline(task: Literal["text-to-audio"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> TextToAudioPipeline: ...
+@overload
+def pipeline(task: Literal["text2text-generation"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> Text2TextGenerationPipeline: ...
+@overload
+def pipeline(task: Literal["token-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> TokenClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["translation"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> TranslationPipeline: ...
+@overload
+def pipeline(task: Literal["video-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> VideoClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["visual-question-answering"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> VisualQuestionAnsweringPipeline: ...
+@overload
+def pipeline(task: Literal["zero-shot-audio-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ZeroShotAudioClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["zero-shot-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ZeroShotClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["zero-shot-image-classification"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ZeroShotImageClassificationPipeline: ...
+@overload
+def pipeline(task: Literal["zero-shot-object-detection"], model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None, config: Optional[Union[str, PretrainedConfig]] = None, tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None, feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None, image_processor: Optional[Union[str, BaseImageProcessor]] = None, processor: Optional[Union[str, ProcessorMixin]] = None, framework: Optional[str] = None, revision: Optional[str] = None, use_fast: bool = True, token: Optional[Union[str, bool]] = None, device: Optional[Union[int, str, "torch.device"]] = None, device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None, dtype: Optional[Union[str, "torch.dtype"]] = "auto", trust_remote_code: Optional[bool] = None, model_kwargs: Optional[dict[str, Any]] = None, pipeline_class: Optional[Any] = None, **kwargs: Any) -> ZeroShotObjectDetectionPipeline: ...
+
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# The part of the file above was automatically generated from the code.
+# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨
+# fmt: on
+#
+
+
+def pipeline(
+ task: Optional[str] = None,
+ model: Optional[Union[str, "PreTrainedModel", "TFPreTrainedModel"]] = None,
+ config: Optional[Union[str, PretrainedConfig]] = None,
+ tokenizer: Optional[Union[str, PreTrainedTokenizer, "PreTrainedTokenizerFast"]] = None,
+ feature_extractor: Optional[Union[str, PreTrainedFeatureExtractor]] = None,
+ image_processor: Optional[Union[str, BaseImageProcessor]] = None,
+ processor: Optional[Union[str, ProcessorMixin]] = None,
+ framework: Optional[str] = None,
+ revision: Optional[str] = None,
+ use_fast: bool = True,
+ token: Optional[Union[str, bool]] = None,
+ device: Optional[Union[int, str, "torch.device"]] = None,
+ device_map: Optional[Union[str, dict[str, Union[int, str]]]] = None,
+ dtype: Optional[Union[str, "torch.dtype"]] = "auto",
+ trust_remote_code: Optional[bool] = None,
+ model_kwargs: Optional[dict[str, Any]] = None,
+ pipeline_class: Optional[Any] = None,
+ **kwargs: Any,
+) -> Pipeline:
+ """
+ Utility factory method to build a [`Pipeline`].
+
+ A pipeline consists of:
+
+ - One or more components for pre-processing model inputs, such as a [tokenizer](tokenizer),
+ [image_processor](image_processor), [feature_extractor](feature_extractor), or [processor](processors).
+ - A [model](model) that generates predictions from the inputs.
+ - Optional post-processing steps to refine the model's output, which can also be handled by processors.
+
+
+ While there are such optional arguments as `tokenizer`, `feature_extractor`, `image_processor`, and `processor`,
+ they shouldn't be specified all at once. If these components are not provided, `pipeline` will try to load
+ required ones automatically. In case you want to provide these components explicitly, please refer to a
+ specific pipeline in order to get more details regarding what components are required.
+
+
+ Args:
+ task (`str`):
+ The task defining which pipeline will be returned. Currently accepted tasks are:
+
+ - `"audio-classification"`: will return a [`AudioClassificationPipeline`].
+ - `"automatic-speech-recognition"`: will return a [`AutomaticSpeechRecognitionPipeline`].
+ - `"depth-estimation"`: will return a [`DepthEstimationPipeline`].
+ - `"document-question-answering"`: will return a [`DocumentQuestionAnsweringPipeline`].
+ - `"feature-extraction"`: will return a [`FeatureExtractionPipeline`].
+ - `"fill-mask"`: will return a [`FillMaskPipeline`]:.
+ - `"image-classification"`: will return a [`ImageClassificationPipeline`].
+ - `"image-feature-extraction"`: will return an [`ImageFeatureExtractionPipeline`].
+ - `"image-segmentation"`: will return a [`ImageSegmentationPipeline`].
+ - `"image-text-to-text"`: will return a [`ImageTextToTextPipeline`].
+ - `"image-to-image"`: will return a [`ImageToImagePipeline`].
+ - `"image-to-text"`: will return a [`ImageToTextPipeline`].
+ - `"keypoint-matching"`: will return a [`KeypointMatchingPipeline`].
+ - `"mask-generation"`: will return a [`MaskGenerationPipeline`].
+ - `"object-detection"`: will return a [`ObjectDetectionPipeline`].
+ - `"question-answering"`: will return a [`QuestionAnsweringPipeline`].
+ - `"summarization"`: will return a [`SummarizationPipeline`].
+ - `"table-question-answering"`: will return a [`TableQuestionAnsweringPipeline`].
+ - `"text2text-generation"`: will return a [`Text2TextGenerationPipeline`].
+ - `"text-classification"` (alias `"sentiment-analysis"` available): will return a
+ [`TextClassificationPipeline`].
+ - `"text-generation"`: will return a [`TextGenerationPipeline`]:.
+ - `"text-to-audio"` (alias `"text-to-speech"` available): will return a [`TextToAudioPipeline`]:.
+ - `"token-classification"` (alias `"ner"` available): will return a [`TokenClassificationPipeline`].
+ - `"translation"`: will return a [`TranslationPipeline`].
+ - `"translation_xx_to_yy"`: will return a [`TranslationPipeline`].
+ - `"video-classification"`: will return a [`VideoClassificationPipeline`].
+ - `"visual-question-answering"`: will return a [`VisualQuestionAnsweringPipeline`].
+ - `"zero-shot-classification"`: will return a [`ZeroShotClassificationPipeline`].
+ - `"zero-shot-image-classification"`: will return a [`ZeroShotImageClassificationPipeline`].
+ - `"zero-shot-audio-classification"`: will return a [`ZeroShotAudioClassificationPipeline`].
+ - `"zero-shot-object-detection"`: will return a [`ZeroShotObjectDetectionPipeline`].
+
+ model (`str` or [`PreTrainedModel`] or [`TFPreTrainedModel`], *optional*):
+ The model that will be used by the pipeline to make predictions. This can be a model identifier or an
+ actual instance of a pretrained model inheriting from [`PreTrainedModel`] (for PyTorch) or
+ [`TFPreTrainedModel`] (for TensorFlow).
+
+ If not provided, the default for the `task` will be loaded.
+ config (`str` or [`PretrainedConfig`], *optional*):
+ The configuration that will be used by the pipeline to instantiate the model. This can be a model
+ identifier or an actual pretrained model configuration inheriting from [`PretrainedConfig`].
+
+ If not provided, the default configuration file for the requested model will be used. That means that if
+ `model` is given, its default configuration will be used. However, if `model` is not supplied, this
+ `task`'s default model's config is used instead.
+ tokenizer (`str` or [`PreTrainedTokenizer`], *optional*):
+ The tokenizer that will be used by the pipeline to encode data for the model. This can be a model
+ identifier or an actual pretrained tokenizer inheriting from [`PreTrainedTokenizer`].
+
+ If not provided, the default tokenizer for the given `model` will be loaded (if it is a string). If `model`
+ is not specified or not a string, then the default tokenizer for `config` is loaded (if it is a string).
+ However, if `config` is also not given or not a string, then the default tokenizer for the given `task`
+ will be loaded.
+ feature_extractor (`str` or [`PreTrainedFeatureExtractor`], *optional*):
+ The feature extractor that will be used by the pipeline to encode data for the model. This can be a model
+ identifier or an actual pretrained feature extractor inheriting from [`PreTrainedFeatureExtractor`].
+
+ Feature extractors are used for non-NLP models, such as Speech or Vision models as well as multi-modal
+ models. Multi-modal models will also require a tokenizer to be passed.
+
+ If not provided, the default feature extractor for the given `model` will be loaded (if it is a string). If
+ `model` is not specified or not a string, then the default feature extractor for `config` is loaded (if it
+ is a string). However, if `config` is also not given or not a string, then the default feature extractor
+ for the given `task` will be loaded.
+ image_processor (`str` or [`BaseImageProcessor`], *optional*):
+ The image processor that will be used by the pipeline to preprocess images for the model. This can be a
+ model identifier or an actual image processor inheriting from [`BaseImageProcessor`].
+
+ Image processors are used for Vision models and multi-modal models that require image inputs. Multi-modal
+ models will also require a tokenizer to be passed.
+
+ If not provided, the default image processor for the given `model` will be loaded (if it is a string). If
+ `model` is not specified or not a string, then the default image processor for `config` is loaded (if it is
+ a string).
+ processor (`str` or [`ProcessorMixin`], *optional*):
+ The processor that will be used by the pipeline to preprocess data for the model. This can be a model
+ identifier or an actual processor inheriting from [`ProcessorMixin`].
+
+ Processors are used for multi-modal models that require multi-modal inputs, for example, a model that
+ requires both text and image inputs.
+
+ If not provided, the default processor for the given `model` will be loaded (if it is a string). If `model`
+ is not specified or not a string, then the default processor for `config` is loaded (if it is a string).
+ framework (`str`, *optional*):
+ The framework to use, either `"pt"` for PyTorch or `"tf"` for TensorFlow. The specified framework must be
+ installed.
+
+ If no framework is specified, will default to the one currently installed. If no framework is specified and
+ both frameworks are installed, will default to the framework of the `model`, or to PyTorch if no model is
+ provided.
+ revision (`str`, *optional*, defaults to `"main"`):
+ When passing a task name or a string model identifier: The specific model version to use. It can be a
+ branch name, a tag name, or a commit id, since we use a git-based system for storing models and other
+ artifacts on huggingface.co, so `revision` can be any identifier allowed by git.
+ use_fast (`bool`, *optional*, defaults to `True`):
+ Whether or not to use a Fast tokenizer if possible (a [`PreTrainedTokenizerFast`]).
+ use_auth_token (`str` or *bool*, *optional*):
+ The token to use as HTTP bearer authorization for remote files. If `True`, will use the token generated
+ when running `hf auth login` (stored in `~/.huggingface`).
+ device (`int` or `str` or `torch.device`):
+ Defines the device (*e.g.*, `"cpu"`, `"cuda:1"`, `"mps"`, or a GPU ordinal rank like `1`) on which this
+ pipeline will be allocated.
+ device_map (`str` or `dict[str, Union[int, str, torch.device]`, *optional*):
+ Sent directly as `model_kwargs` (just a simpler shortcut). When `accelerate` library is present, set
+ `device_map="auto"` to compute the most optimized `device_map` automatically (see
+ [here](https://huggingface.co/docs/accelerate/main/en/package_reference/big_modeling#accelerate.cpu_offload)
+ for more information).
+
+
+
+ Do not use `device_map` AND `device` at the same time as they will conflict
+
+
+
+ dtype (`str` or `torch.dtype`, *optional*):
+ Sent directly as `model_kwargs` (just a simpler shortcut) to use the available precision for this model
+ (`torch.float16`, `torch.bfloat16`, ... or `"auto"`).
+ trust_remote_code (`bool`, *optional*, defaults to `False`):
+ Whether or not to allow for custom code defined on the Hub in their own modeling, configuration,
+ tokenization or even pipeline files. This option should only be set to `True` for repositories you trust
+ and in which you have read the code, as it will execute code present on the Hub on your local machine.
+ model_kwargs (`dict[str, Any]`, *optional*):
+ Additional dictionary of keyword arguments passed along to the model's `from_pretrained(...,
+ **model_kwargs)` function.
+ kwargs (`dict[str, Any]`, *optional*):
+ Additional keyword arguments passed along to the specific pipeline init (see the documentation for the
+ corresponding pipeline class for possible values).
+
+ Returns:
+ [`Pipeline`]: A suitable pipeline for the task.
+
+ Examples:
+
+ ```python
+ >>> from transformers import pipeline, AutoModelForTokenClassification, AutoTokenizer
+
+ >>> # Sentiment analysis pipeline
+ >>> analyzer = pipeline("sentiment-analysis")
+
+ >>> # Question answering pipeline, specifying the checkpoint identifier
+ >>> oracle = pipeline(
+ ... "question-answering", model="distilbert/distilbert-base-cased-distilled-squad", tokenizer="google-bert/bert-base-cased"
+ ... )
+
+ >>> # Named entity recognition pipeline, passing in a specific model and tokenizer
+ >>> model = AutoModelForTokenClassification.from_pretrained("dbmdz/bert-large-cased-finetuned-conll03-english")
+ >>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+ >>> recognizer = pipeline("ner", model=model, tokenizer=tokenizer)
+ ```"""
+ if model_kwargs is None:
+ model_kwargs = {}
+ # Make sure we only pass use_auth_token once as a kwarg (it used to be possible to pass it in model_kwargs,
+ # this is to keep BC).
+ use_auth_token = model_kwargs.pop("use_auth_token", None)
+ if use_auth_token is not None:
+ warnings.warn(
+ "The `use_auth_token` argument is deprecated and will be removed in v5 of Transformers. Please use `token` instead.",
+ FutureWarning,
+ )
+ if token is not None:
+ raise ValueError("`token` and `use_auth_token` are both specified. Please set only the argument `token`.")
+ token = use_auth_token
+
+ code_revision = kwargs.pop("code_revision", None)
+ commit_hash = kwargs.pop("_commit_hash", None)
+
+ hub_kwargs = {
+ "revision": revision,
+ "token": token,
+ "trust_remote_code": trust_remote_code,
+ "_commit_hash": commit_hash,
+ }
+
+ if task is None and model is None:
+ raise RuntimeError(
+ "Impossible to instantiate a pipeline without either a task or a model "
+ "being specified. "
+ "Please provide a task class or a model"
+ )
+
+ if model is None and tokenizer is not None:
+ raise RuntimeError(
+ "Impossible to instantiate a pipeline with tokenizer specified but not the model as the provided tokenizer"
+ " may not be compatible with the default model. Please provide a PreTrainedModel class or a"
+ " path/identifier to a pretrained model when providing tokenizer."
+ )
+ if model is None and feature_extractor is not None:
+ raise RuntimeError(
+ "Impossible to instantiate a pipeline with feature_extractor specified but not the model as the provided"
+ " feature_extractor may not be compatible with the default model. Please provide a PreTrainedModel class"
+ " or a path/identifier to a pretrained model when providing feature_extractor."
+ )
+ if isinstance(model, Path):
+ model = str(model)
+
+ if commit_hash is None:
+ pretrained_model_name_or_path = None
+ if isinstance(config, str):
+ pretrained_model_name_or_path = config
+ elif config is None and isinstance(model, str):
+ pretrained_model_name_or_path = model
+
+ if not isinstance(config, PretrainedConfig) and pretrained_model_name_or_path is not None:
+ # We make a call to the config file first (which may be absent) to get the commit hash as soon as possible
+ resolved_config_file = cached_file(
+ pretrained_model_name_or_path,
+ CONFIG_NAME,
+ _raise_exceptions_for_gated_repo=False,
+ _raise_exceptions_for_missing_entries=False,
+ _raise_exceptions_for_connection_errors=False,
+ cache_dir=model_kwargs.get("cache_dir"),
+ **hub_kwargs,
+ )
+ hub_kwargs["_commit_hash"] = extract_commit_hash(resolved_config_file, commit_hash)
+ else:
+ hub_kwargs["_commit_hash"] = getattr(config, "_commit_hash", None)
+
+ # Config is the primordial information item.
+ # Instantiate config if needed
+ adapter_path = None
+ if isinstance(config, str):
+ config = AutoConfig.from_pretrained(
+ config, _from_pipeline=task, code_revision=code_revision, **hub_kwargs, **model_kwargs
+ )
+ hub_kwargs["_commit_hash"] = config._commit_hash
+ elif config is None and isinstance(model, str):
+ # Check for an adapter file in the model path if PEFT is available
+ if is_peft_available():
+ # `find_adapter_config_file` doesn't accept `trust_remote_code`
+ _hub_kwargs = {k: v for k, v in hub_kwargs.items() if k != "trust_remote_code"}
+ maybe_adapter_path = find_adapter_config_file(
+ model,
+ token=hub_kwargs["token"],
+ revision=hub_kwargs["revision"],
+ _commit_hash=hub_kwargs["_commit_hash"],
+ )
+
+ if maybe_adapter_path is not None:
+ with open(maybe_adapter_path, "r", encoding="utf-8") as f:
+ adapter_config = json.load(f)
+ adapter_path = model
+ model = adapter_config["base_model_name_or_path"]
+
+ config = AutoConfig.from_pretrained(
+ model, _from_pipeline=task, code_revision=code_revision, **hub_kwargs, **model_kwargs
+ )
+ hub_kwargs["_commit_hash"] = config._commit_hash
+
+ custom_tasks = {}
+ if config is not None and len(getattr(config, "custom_pipelines", {})) > 0:
+ custom_tasks = config.custom_pipelines
+ if task is None and trust_remote_code is not False:
+ if len(custom_tasks) == 1:
+ task = list(custom_tasks.keys())[0]
+ else:
+ raise RuntimeError(
+ "We can't infer the task automatically for this model as there are multiple tasks available. Pick "
+ f"one in {', '.join(custom_tasks.keys())}"
+ )
+
+ if task is None and model is not None:
+ if not isinstance(model, str):
+ raise RuntimeError(
+ "Inferring the task automatically requires to check the hub with a model_id defined as a `str`. "
+ f"{model} is not a valid model_id."
+ )
+ task = get_task(model, token)
+
+ # Retrieve the task
+ if task in custom_tasks:
+ normalized_task = task
+ targeted_task, task_options = clean_custom_task(custom_tasks[task])
+ if pipeline_class is None:
+ if not trust_remote_code:
+ raise ValueError(
+ "Loading this pipeline requires you to execute the code in the pipeline file in that"
+ " repo on your local machine. Make sure you have read the code there to avoid malicious use, then"
+ " set the option `trust_remote_code=True` to remove this error."
+ )
+ class_ref = targeted_task["impl"]
+ pipeline_class = get_class_from_dynamic_module(
+ class_ref,
+ model,
+ code_revision=code_revision,
+ **hub_kwargs,
+ )
+ else:
+ normalized_task, targeted_task, task_options = check_task(task)
+ if pipeline_class is None:
+ pipeline_class = targeted_task["impl"]
+
+ # Use default model/config/tokenizer for the task if no model is provided
+ if model is None:
+ # At that point framework might still be undetermined
+ model, default_revision = get_default_model_and_revision(targeted_task, framework, task_options)
+ revision = revision if revision is not None else default_revision
+ logger.warning(
+ f"No model was supplied, defaulted to {model} and revision"
+ f" {revision} ({HUGGINGFACE_CO_RESOLVE_ENDPOINT}/{model}).\n"
+ "Using a pipeline without specifying a model name and revision in production is not recommended."
+ )
+ hub_kwargs["revision"] = revision
+ if config is None and isinstance(model, str):
+ config = AutoConfig.from_pretrained(model, _from_pipeline=task, **hub_kwargs, **model_kwargs)
+ hub_kwargs["_commit_hash"] = config._commit_hash
+
+ if device_map is not None:
+ if "device_map" in model_kwargs:
+ raise ValueError(
+ 'You cannot use both `pipeline(... device_map=..., model_kwargs={"device_map":...})` as those'
+ " arguments might conflict, use only one.)"
+ )
+ if device is not None:
+ logger.warning(
+ "Both `device` and `device_map` are specified. `device` will override `device_map`. You"
+ " will most likely encounter unexpected behavior. Please remove `device` and keep `device_map`."
+ )
+ model_kwargs["device_map"] = device_map
+
+ # BC for the `torch_dtype` argument
+ if (torch_dtype := kwargs.get("torch_dtype")) is not None:
+ logger.warning_once("`torch_dtype` is deprecated! Use `dtype` instead!")
+ # If both are provided, keep `dtype`
+ dtype = torch_dtype if dtype == "auto" else dtype
+ if "torch_dtype" in model_kwargs or "dtype" in model_kwargs:
+ if "torch_dtype" in model_kwargs:
+ logger.warning_once("`torch_dtype` is deprecated! Use `dtype` instead!")
+ # If the user did not explicitly provide `dtype` (i.e. the function default "auto" is still
+ # present) but a value is supplied inside `model_kwargs`, we silently defer to the latter instead of
+ # raising. This prevents false positives like providing `dtype` only via `model_kwargs` while the
+ # top-level argument keeps its default value "auto".
+ if dtype == "auto":
+ dtype = None
+ else:
+ raise ValueError(
+ 'You cannot use both `pipeline(... dtype=..., model_kwargs={"dtype":...})` as those'
+ " arguments might conflict, use only one.)"
+ )
+ if dtype is not None:
+ if isinstance(dtype, str) and hasattr(torch, dtype):
+ dtype = getattr(torch, dtype)
+ model_kwargs["dtype"] = dtype
+
+ model_name = model if isinstance(model, str) else None
+
+ # Load the correct model if possible
+ # Infer the framework from the model if not already defined
+ if isinstance(model, str) or framework is None:
+ model_classes = {"tf": targeted_task["tf"], "pt": targeted_task["pt"]}
+ framework, model = infer_framework_load_model(
+ adapter_path if adapter_path is not None else model,
+ model_classes=model_classes,
+ config=config,
+ framework=framework,
+ task=task,
+ **hub_kwargs,
+ **model_kwargs,
+ )
+
+ hub_kwargs["_commit_hash"] = model.config._commit_hash
+
+ # Check which preprocessing classes the pipeline uses
+ # None values indicate optional classes that the pipeline can run without, we don't raise errors if loading fails
+ load_tokenizer = pipeline_class._load_tokenizer
+ load_feature_extractor = pipeline_class._load_feature_extractor
+ load_image_processor = pipeline_class._load_image_processor
+ load_processor = pipeline_class._load_processor
+
+ if load_tokenizer or load_tokenizer is None:
+ try:
+ # Try to infer tokenizer from model or config name (if provided as str)
+ if tokenizer is None:
+ if isinstance(model_name, str):
+ tokenizer = model_name
+ elif isinstance(config, str):
+ tokenizer = config
+ else:
+ # Impossible to guess what is the right tokenizer here
+ raise Exception(
+ "Impossible to guess which tokenizer to use. "
+ "Please provide a PreTrainedTokenizer class or a path/identifier to a pretrained tokenizer."
+ )
+
+ # Instantiate tokenizer if needed
+ if isinstance(tokenizer, (str, tuple)):
+ if isinstance(tokenizer, tuple):
+ # For tuple we have (tokenizer name, {kwargs})
+ use_fast = tokenizer[1].pop("use_fast", use_fast)
+ tokenizer_identifier = tokenizer[0]
+ tokenizer_kwargs = tokenizer[1]
+ else:
+ tokenizer_identifier = tokenizer
+ tokenizer_kwargs = model_kwargs.copy()
+ tokenizer_kwargs.pop("torch_dtype", None), tokenizer_kwargs.pop("dtype", None)
+
+ tokenizer = AutoTokenizer.from_pretrained(
+ tokenizer_identifier, use_fast=use_fast, _from_pipeline=task, **hub_kwargs, **tokenizer_kwargs
+ )
+ except Exception as e:
+ if load_tokenizer:
+ raise e
+ else:
+ tokenizer = None
+
+ if load_image_processor or load_image_processor is None:
+ try:
+ # Try to infer image processor from model or config name (if provided as str)
+ if image_processor is None:
+ if isinstance(model_name, str):
+ image_processor = model_name
+ elif isinstance(config, str):
+ image_processor = config
+ # Backward compatibility, as `feature_extractor` used to be the name
+ # for `ImageProcessor`.
+ elif feature_extractor is not None and isinstance(feature_extractor, BaseImageProcessor):
+ image_processor = feature_extractor
+ else:
+ # Impossible to guess what is the right image_processor here
+ raise Exception(
+ "Impossible to guess which image processor to use. "
+ "Please provide a PreTrainedImageProcessor class or a path/identifier "
+ "to a pretrained image processor."
+ )
+
+ # Instantiate image_processor if needed
+ if isinstance(image_processor, (str, tuple)):
+ image_processor = AutoImageProcessor.from_pretrained(
+ image_processor, _from_pipeline=task, **hub_kwargs, **model_kwargs
+ )
+ except Exception as e:
+ if load_image_processor:
+ raise e
+ else:
+ image_processor = None
+
+ if load_feature_extractor or load_feature_extractor is None:
+ try:
+ # Try to infer feature extractor from model or config name (if provided as str)
+ if feature_extractor is None:
+ if isinstance(model_name, str):
+ feature_extractor = model_name
+ elif isinstance(config, str):
+ feature_extractor = config
+ else:
+ # Impossible to guess what is the right feature_extractor here
+ raise Exception(
+ "Impossible to guess which feature extractor to use. "
+ "Please provide a PreTrainedFeatureExtractor class or a path/identifier "
+ "to a pretrained feature extractor."
+ )
+
+ # Instantiate feature_extractor if needed
+ if isinstance(feature_extractor, (str, tuple)):
+ feature_extractor = AutoFeatureExtractor.from_pretrained(
+ feature_extractor, _from_pipeline=task, **hub_kwargs, **model_kwargs
+ )
+
+ if (
+ feature_extractor._processor_class
+ and feature_extractor._processor_class.endswith("WithLM")
+ and isinstance(model_name, str)
+ ):
+ try:
+ import kenlm # to trigger `ImportError` if not installed
+ from pyctcdecode import BeamSearchDecoderCTC
+
+ if os.path.isdir(model_name) or os.path.isfile(model_name):
+ decoder = BeamSearchDecoderCTC.load_from_dir(model_name)
+ else:
+ language_model_glob = os.path.join(
+ BeamSearchDecoderCTC._LANGUAGE_MODEL_SERIALIZED_DIRECTORY, "*"
+ )
+ alphabet_filename = BeamSearchDecoderCTC._ALPHABET_SERIALIZED_FILENAME
+ allow_patterns = [language_model_glob, alphabet_filename]
+ decoder = BeamSearchDecoderCTC.load_from_hf_hub(model_name, allow_patterns=allow_patterns)
+
+ kwargs["decoder"] = decoder
+ except ImportError as e:
+ logger.warning(
+ f"Could not load the `decoder` for {model_name}. Defaulting to raw CTC. Error: {e}"
+ )
+ if not is_kenlm_available():
+ logger.warning("Try to install `kenlm`: `pip install kenlm")
+
+ if not is_pyctcdecode_available():
+ logger.warning("Try to install `pyctcdecode`: `pip install pyctcdecode")
+ except Exception as e:
+ if load_feature_extractor:
+ raise e
+ else:
+ feature_extractor = None
+
+ if load_processor or load_processor is None:
+ try:
+ # Try to infer processor from model or config name (if provided as str)
+ if processor is None:
+ if isinstance(model_name, str):
+ processor = model_name
+ elif isinstance(config, str):
+ processor = config
+ else:
+ # Impossible to guess what is the right processor here
+ raise Exception(
+ "Impossible to guess which processor to use. "
+ "Please provide a processor instance or a path/identifier "
+ "to a processor."
+ )
+
+ # Instantiate processor if needed
+ if isinstance(processor, (str, tuple)):
+ processor = AutoProcessor.from_pretrained(processor, _from_pipeline=task, **hub_kwargs, **model_kwargs)
+ if not isinstance(processor, ProcessorMixin):
+ raise TypeError(
+ "Processor was loaded, but it is not an instance of `ProcessorMixin`. "
+ f"Got type `{type(processor)}` instead. Please check that you specified "
+ "correct pipeline task for the model and model has processor implemented and saved."
+ )
+ except Exception as e:
+ if load_processor:
+ raise e
+ else:
+ processor = None
+
+ if task == "translation" and model.config.task_specific_params:
+ for key in model.config.task_specific_params:
+ if key.startswith("translation"):
+ task = key
+ warnings.warn(
+ f'"translation" task was used, instead of "translation_XX_to_YY", defaulting to "{task}"',
+ UserWarning,
+ )
+ break
+
+ if tokenizer is not None:
+ kwargs["tokenizer"] = tokenizer
+
+ if feature_extractor is not None:
+ kwargs["feature_extractor"] = feature_extractor
+
+ if dtype is not None:
+ kwargs["dtype"] = dtype
+
+ if image_processor is not None:
+ kwargs["image_processor"] = image_processor
+
+ if device is not None:
+ kwargs["device"] = device
+
+ if processor is not None:
+ kwargs["processor"] = processor
+
+ return pipeline_class(model=model, framework=framework, task=task, **kwargs)
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/audio_classification.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/audio_classification.py
new file mode 100644
index 0000000000000000000000000000000000000000..9f4822e2b2be884904d241c09b5c3cc1c2ee39b8
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/audio_classification.py
@@ -0,0 +1,262 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import subprocess
+from typing import Any, Union
+
+import numpy as np
+import requests
+
+from ..utils import add_end_docstrings, is_torch_available, is_torchaudio_available, is_torchcodec_available, logging
+from .base import Pipeline, build_pipeline_init_args
+
+
+if is_torch_available():
+ from ..models.auto.modeling_auto import MODEL_FOR_AUDIO_CLASSIFICATION_MAPPING_NAMES
+
+logger = logging.get_logger(__name__)
+
+
+def ffmpeg_read(bpayload: bytes, sampling_rate: int) -> np.ndarray:
+ """
+ Helper function to read an audio file through ffmpeg.
+ """
+ ar = f"{sampling_rate}"
+ ac = "1"
+ format_for_conversion = "f32le"
+ ffmpeg_command = [
+ "ffmpeg",
+ "-i",
+ "pipe:0",
+ "-ac",
+ ac,
+ "-ar",
+ ar,
+ "-f",
+ format_for_conversion,
+ "-hide_banner",
+ "-loglevel",
+ "quiet",
+ "pipe:1",
+ ]
+
+ try:
+ ffmpeg_process = subprocess.Popen(ffmpeg_command, stdin=subprocess.PIPE, stdout=subprocess.PIPE)
+ except FileNotFoundError:
+ raise ValueError("ffmpeg was not found but is required to load audio files from filename")
+ output_stream = ffmpeg_process.communicate(bpayload)
+ out_bytes = output_stream[0]
+
+ audio = np.frombuffer(out_bytes, np.float32)
+ if audio.shape[0] == 0:
+ raise ValueError("Malformed soundfile")
+ return audio
+
+
+@add_end_docstrings(build_pipeline_init_args(has_feature_extractor=True))
+class AudioClassificationPipeline(Pipeline):
+ """
+ Audio classification pipeline using any `AutoModelForAudioClassification`. This pipeline predicts the class of a
+ raw waveform or an audio file. In case of an audio file, ffmpeg should be installed to support multiple audio
+ formats.
+
+ Example:
+
+ ```python
+ >>> from transformers import pipeline
+
+ >>> classifier = pipeline(model="superb/wav2vec2-base-superb-ks")
+ >>> classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac")
+ [{'score': 0.997, 'label': '_unknown_'}, {'score': 0.002, 'label': 'left'}, {'score': 0.0, 'label': 'yes'}, {'score': 0.0, 'label': 'down'}, {'score': 0.0, 'label': 'stop'}]
+ ```
+
+ Learn more about the basics of using a pipeline in the [pipeline tutorial](../pipeline_tutorial)
+
+
+ This pipeline can currently be loaded from [`pipeline`] using the following task identifier:
+ `"audio-classification"`.
+
+ See the list of available models on
+ [huggingface.co/models](https://huggingface.co/models?filter=audio-classification).
+ """
+
+ _load_processor = False
+ _load_image_processor = False
+ _load_feature_extractor = True
+ _load_tokenizer = False
+
+ def __init__(self, *args, **kwargs):
+ # Only set default top_k if explicitly provided
+ if "top_k" in kwargs and kwargs["top_k"] is None:
+ kwargs["top_k"] = None
+ elif "top_k" not in kwargs:
+ kwargs["top_k"] = 5
+ super().__init__(*args, **kwargs)
+
+ if self.framework != "pt":
+ raise ValueError(f"The {self.__class__} is only available in PyTorch.")
+
+ self.check_model_type(MODEL_FOR_AUDIO_CLASSIFICATION_MAPPING_NAMES)
+
+ def __call__(self, inputs: Union[np.ndarray, bytes, str, dict], **kwargs: Any) -> list[dict[str, Any]]:
+ """
+ Classify the sequence(s) given as inputs. See the [`AutomaticSpeechRecognitionPipeline`] documentation for more
+ information.
+
+ Args:
+ inputs (`np.ndarray` or `bytes` or `str` or `dict`):
+ The inputs is either :
+ - `str` that is the filename of the audio file, the file will be read at the correct sampling rate
+ to get the waveform using *ffmpeg*. This requires *ffmpeg* to be installed on the system.
+ - `bytes` it is supposed to be the content of an audio file and is interpreted by *ffmpeg* in the
+ same way.
+ - (`np.ndarray` of shape (n, ) of type `np.float32` or `np.float64`)
+ Raw audio at the correct sampling rate (no further check will be done)
+ - `dict` form can be used to pass raw audio sampled at arbitrary `sampling_rate` and let this
+ pipeline do the resampling. The dict must be either be in the format `{"sampling_rate": int,
+ "raw": np.array}`, or `{"sampling_rate": int, "array": np.array}`, where the key `"raw"` or
+ `"array"` is used to denote the raw audio waveform.
+ top_k (`int`, *optional*, defaults to None):
+ The number of top labels that will be returned by the pipeline. If the provided number is `None` or
+ higher than the number of labels available in the model configuration, it will default to the number of
+ labels.
+ function_to_apply(`str`, *optional*, defaults to "softmax"):
+ The function to apply to the model output. By default, the pipeline will apply the softmax function to
+ the output of the model. Valid options: ["softmax", "sigmoid", "none"]. Note that passing Python's
+ built-in `None` will default to "softmax", so you need to pass the string "none" to disable any
+ post-processing.
+
+ Return:
+ A list of `dict` with the following keys:
+
+ - **label** (`str`) -- The label predicted.
+ - **score** (`float`) -- The corresponding probability.
+ """
+ return super().__call__(inputs, **kwargs)
+
+ def _sanitize_parameters(self, top_k=None, function_to_apply=None, **kwargs):
+ postprocess_params = {}
+
+ # If top_k is None, use all labels
+ if top_k is None:
+ postprocess_params["top_k"] = self.model.config.num_labels
+ else:
+ if top_k > self.model.config.num_labels:
+ top_k = self.model.config.num_labels
+ postprocess_params["top_k"] = top_k
+
+ if function_to_apply is not None:
+ if function_to_apply not in ["softmax", "sigmoid", "none"]:
+ raise ValueError(
+ f"Invalid value for `function_to_apply`: {function_to_apply}. "
+ "Valid options are ['softmax', 'sigmoid', 'none']"
+ )
+ postprocess_params["function_to_apply"] = function_to_apply
+ else:
+ postprocess_params["function_to_apply"] = "softmax"
+ return {}, {}, postprocess_params
+
+ def preprocess(self, inputs):
+ if isinstance(inputs, str):
+ if inputs.startswith("http://") or inputs.startswith("https://"):
+ # We need to actually check for a real protocol, otherwise it's impossible to use a local file
+ # like http_huggingface_co.png
+ inputs = requests.get(inputs).content
+ else:
+ with open(inputs, "rb") as f:
+ inputs = f.read()
+
+ if isinstance(inputs, bytes):
+ inputs = ffmpeg_read(inputs, self.feature_extractor.sampling_rate)
+
+ if is_torch_available():
+ import torch
+
+ if isinstance(inputs, torch.Tensor):
+ inputs = inputs.cpu().numpy()
+
+ if is_torchcodec_available():
+ import torch
+ import torchcodec
+
+ if isinstance(inputs, torchcodec.decoders.AudioDecoder):
+ _audio_samples = inputs.get_all_samples()
+ _array = _audio_samples.data
+ inputs = {"array": _array, "sampling_rate": _audio_samples.sample_rate}
+
+ if isinstance(inputs, dict):
+ inputs = inputs.copy() # So we don't mutate the original dictionary outside the pipeline
+ # Accepting `"array"` which is the key defined in `datasets` for
+ # better integration
+ if not ("sampling_rate" in inputs and ("raw" in inputs or "array" in inputs)):
+ raise ValueError(
+ "When passing a dictionary to AudioClassificationPipeline, the dict needs to contain a "
+ '"raw" key containing the numpy array or torch tensor representing the audio and a "sampling_rate" key, '
+ "containing the sampling_rate associated with that array"
+ )
+
+ _inputs = inputs.pop("raw", None)
+ if _inputs is None:
+ # Remove path which will not be used from `datasets`.
+ inputs.pop("path", None)
+ _inputs = inputs.pop("array", None)
+ in_sampling_rate = inputs.pop("sampling_rate")
+ inputs = _inputs
+ if in_sampling_rate != self.feature_extractor.sampling_rate:
+ import torch
+
+ if is_torchaudio_available():
+ from torchaudio import functional as F
+ else:
+ raise ImportError(
+ "torchaudio is required to resample audio samples in AudioClassificationPipeline. "
+ "The torchaudio package can be installed through: `pip install torchaudio`."
+ )
+
+ inputs = F.resample(
+ torch.from_numpy(inputs) if isinstance(inputs, np.ndarray) else inputs,
+ in_sampling_rate,
+ self.feature_extractor.sampling_rate,
+ ).numpy()
+
+ if not isinstance(inputs, np.ndarray):
+ raise TypeError("We expect a numpy ndarray or torch tensor as input")
+ if len(inputs.shape) != 1:
+ raise ValueError("We expect a single channel audio input for AudioClassificationPipeline")
+
+ processed = self.feature_extractor(
+ inputs, sampling_rate=self.feature_extractor.sampling_rate, return_tensors="pt"
+ )
+ if self.dtype is not None:
+ processed = processed.to(dtype=self.dtype)
+ return processed
+
+ def _forward(self, model_inputs):
+ model_outputs = self.model(**model_inputs)
+ return model_outputs
+
+ def postprocess(self, model_outputs, top_k=5, function_to_apply="softmax"):
+ if function_to_apply == "softmax":
+ probs = model_outputs.logits[0].softmax(-1)
+ elif function_to_apply == "sigmoid":
+ probs = model_outputs.logits[0].sigmoid()
+ else:
+ probs = model_outputs.logits[0]
+ scores, ids = probs.topk(top_k)
+
+ scores = scores.tolist()
+ ids = ids.tolist()
+
+ labels = [{"score": score, "label": self.model.config.id2label[_id]} for score, _id in zip(scores, ids)]
+
+ return labels
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/audio_utils.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/audio_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..63e18c03524be8d8da0311f5ee085c18f753ff7f
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/audio_utils.py
@@ -0,0 +1,297 @@
+# Copyright 2023 The HuggingFace Team. All rights reserved.
+import datetime
+import platform
+import subprocess
+from typing import Optional, Union
+
+import numpy as np
+
+
+def ffmpeg_read(bpayload: bytes, sampling_rate: int) -> np.array:
+ """
+ Helper function to read an audio file through ffmpeg.
+ """
+ ar = f"{sampling_rate}"
+ ac = "1"
+ format_for_conversion = "f32le"
+ ffmpeg_command = [
+ "ffmpeg",
+ "-i",
+ "pipe:0",
+ "-ac",
+ ac,
+ "-ar",
+ ar,
+ "-f",
+ format_for_conversion,
+ "-hide_banner",
+ "-loglevel",
+ "quiet",
+ "pipe:1",
+ ]
+
+ try:
+ with subprocess.Popen(ffmpeg_command, stdin=subprocess.PIPE, stdout=subprocess.PIPE) as ffmpeg_process:
+ output_stream = ffmpeg_process.communicate(bpayload)
+ except FileNotFoundError as error:
+ raise ValueError("ffmpeg was not found but is required to load audio files from filename") from error
+ out_bytes = output_stream[0]
+ audio = np.frombuffer(out_bytes, np.float32)
+ if audio.shape[0] == 0:
+ raise ValueError(
+ "Soundfile is either not in the correct format or is malformed. Ensure that the soundfile has "
+ "a valid audio file extension (e.g. wav, flac or mp3) and is not corrupted. If reading from a remote "
+ "URL, ensure that the URL is the full address to **download** the audio file."
+ )
+ return audio
+
+
+def ffmpeg_microphone(
+ sampling_rate: int,
+ chunk_length_s: float,
+ format_for_conversion: str = "f32le",
+ ffmpeg_input_device: Optional[str] = None,
+ ffmpeg_additional_args: Optional[list[str]] = None,
+):
+ """
+ Helper function to read audio from a microphone using ffmpeg. The default input device will be used unless another
+ input device is specified using the `ffmpeg_input_device` argument. Uses 'alsa' on Linux, 'avfoundation' on MacOS and
+ 'dshow' on Windows.
+
+ Arguments:
+ sampling_rate (`int`):
+ The sampling_rate to use when reading the data from the microphone. Try using the model's sampling_rate to
+ avoid resampling later.
+ chunk_length_s (`float` or `int`):
+ The length of the maximum chunk of audio to be sent returned.
+ format_for_conversion (`str`, defaults to `f32le`):
+ The name of the format of the audio samples to be returned by ffmpeg. The standard is `f32le`, `s16le`
+ could also be used.
+ ffmpeg_input_device (`str`, *optional*):
+ The identifier of the input device to be used by ffmpeg (i.e. ffmpeg's '-i' argument). If unset,
+ the default input device will be used. See `https://www.ffmpeg.org/ffmpeg-devices.html#Input-Devices`
+ for how to specify and list input devices.
+ ffmpeg_additional_args (`list[str]`, *optional*):
+ Additional arguments to pass to ffmpeg, can include arguments like -nostdin for running as a background
+ process. For example, to pass -nostdin to the ffmpeg process, pass in ["-nostdin"]. If passing in flags
+ with multiple arguments, use the following convention (eg ["flag", "arg1", "arg2]).
+
+ Returns:
+ A generator yielding audio chunks of `chunk_length_s` seconds as `bytes` objects of length
+ `int(round(sampling_rate * chunk_length_s)) * size_of_sample`.
+ """
+ ar = f"{sampling_rate}"
+ ac = "1"
+ if format_for_conversion == "s16le":
+ size_of_sample = 2
+ elif format_for_conversion == "f32le":
+ size_of_sample = 4
+ else:
+ raise ValueError(f"Unhandled format `{format_for_conversion}`. Please use `s16le` or `f32le`")
+
+ system = platform.system()
+
+ if system == "Linux":
+ format_ = "alsa"
+ input_ = ffmpeg_input_device or "default"
+ elif system == "Darwin":
+ format_ = "avfoundation"
+ input_ = ffmpeg_input_device or ":default"
+ elif system == "Windows":
+ format_ = "dshow"
+ input_ = ffmpeg_input_device or _get_microphone_name()
+
+ ffmpeg_additional_args = [] if ffmpeg_additional_args is None else ffmpeg_additional_args
+
+ ffmpeg_command = [
+ "ffmpeg",
+ "-f",
+ format_,
+ "-i",
+ input_,
+ "-ac",
+ ac,
+ "-ar",
+ ar,
+ "-f",
+ format_for_conversion,
+ "-fflags",
+ "nobuffer",
+ "-hide_banner",
+ "-loglevel",
+ "quiet",
+ "pipe:1",
+ ]
+
+ ffmpeg_command.extend(ffmpeg_additional_args)
+
+ chunk_len = int(round(sampling_rate * chunk_length_s)) * size_of_sample
+ iterator = _ffmpeg_stream(ffmpeg_command, chunk_len)
+ for item in iterator:
+ yield item
+
+
+def ffmpeg_microphone_live(
+ sampling_rate: int,
+ chunk_length_s: float,
+ stream_chunk_s: Optional[int] = None,
+ stride_length_s: Optional[Union[tuple[float, float], float]] = None,
+ format_for_conversion: str = "f32le",
+ ffmpeg_input_device: Optional[str] = None,
+ ffmpeg_additional_args: Optional[list[str]] = None,
+):
+ """
+ Helper function to read audio from a microphone using ffmpeg. This will output `partial` overlapping chunks starting
+ from `stream_chunk_s` (if it is defined) until `chunk_length_s` is reached. It will make use of striding to avoid
+ errors on the "sides" of the various chunks. The default input device will be used unless another input device is
+ specified using the `ffmpeg_input_device` argument. Uses 'alsa' on Linux, 'avfoundation' on MacOS and 'dshow' on Windows.
+
+ Arguments:
+ sampling_rate (`int`):
+ The sampling_rate to use when reading the data from the microphone. Try using the model's sampling_rate to
+ avoid resampling later.
+ chunk_length_s (`float` or `int`):
+ The length of the maximum chunk of audio to be sent returned. This includes the eventual striding.
+ stream_chunk_s (`float` or `int`):
+ The length of the minimal temporary audio to be returned.
+ stride_length_s (`float` or `int` or `(float, float)`, *optional*):
+ The length of the striding to be used. Stride is used to provide context to a model on the (left, right) of
+ an audio sample but without using that part to actually make the prediction. Setting this does not change
+ the length of the chunk.
+ format_for_conversion (`str`, *optional*, defaults to `f32le`):
+ The name of the format of the audio samples to be returned by ffmpeg. The standard is `f32le`, `s16le`
+ could also be used.
+ ffmpeg_input_device (`str`, *optional*):
+ The identifier of the input device to be used by ffmpeg (i.e. ffmpeg's '-i' argument). If unset,
+ the default input device will be used. See `https://www.ffmpeg.org/ffmpeg-devices.html#Input-Devices`
+ for how to specify and list input devices.
+ ffmpeg_additional_args (`list[str]`, *optional*):
+ Additional arguments to pass to ffmpeg, can include arguments like -nostdin for running as a background
+ process. For example, to pass -nostdin to the ffmpeg process, pass in ["-nostdin"]. If passing in flags
+ with multiple arguments, use the following convention (eg ["flag", "arg1", "arg2]).
+
+ Return:
+ A generator yielding dictionaries of the following form
+
+ `{"sampling_rate": int, "raw": np.array(), "partial" bool}` With optionally a `"stride" (int, int)` key if
+ `stride_length_s` is defined.
+
+ `stride` and `raw` are all expressed in `samples`, and `partial` is a boolean saying if the current yield item
+ is a whole chunk, or a partial temporary result to be later replaced by another larger chunk.
+ """
+ if stream_chunk_s is not None:
+ chunk_s = stream_chunk_s
+ else:
+ chunk_s = chunk_length_s
+
+ microphone = ffmpeg_microphone(
+ sampling_rate,
+ chunk_s,
+ format_for_conversion=format_for_conversion,
+ ffmpeg_input_device=ffmpeg_input_device,
+ ffmpeg_additional_args=[] if ffmpeg_additional_args is None else ffmpeg_additional_args,
+ )
+
+ if format_for_conversion == "s16le":
+ dtype = np.int16
+ size_of_sample = 2
+ elif format_for_conversion == "f32le":
+ dtype = np.float32
+ size_of_sample = 4
+ else:
+ raise ValueError(f"Unhandled format `{format_for_conversion}`. Please use `s16le` or `f32le`")
+
+ if stride_length_s is None:
+ stride_length_s = chunk_length_s / 6
+ chunk_len = int(round(sampling_rate * chunk_length_s)) * size_of_sample
+ if isinstance(stride_length_s, (int, float)):
+ stride_length_s = [stride_length_s, stride_length_s]
+
+ stride_left = int(round(sampling_rate * stride_length_s[0])) * size_of_sample
+ stride_right = int(round(sampling_rate * stride_length_s[1])) * size_of_sample
+ audio_time = datetime.datetime.now()
+ delta = datetime.timedelta(seconds=chunk_s)
+ for item in chunk_bytes_iter(microphone, chunk_len, stride=(stride_left, stride_right), stream=True):
+ # Put everything back in numpy scale
+ item["raw"] = np.frombuffer(item["raw"], dtype=dtype)
+ item["stride"] = (
+ item["stride"][0] // size_of_sample,
+ item["stride"][1] // size_of_sample,
+ )
+ item["sampling_rate"] = sampling_rate
+ audio_time += delta
+ if datetime.datetime.now() > audio_time + 10 * delta:
+ # We're late !! SKIP
+ continue
+ yield item
+
+
+def chunk_bytes_iter(iterator, chunk_len: int, stride: tuple[int, int], stream: bool = False):
+ """
+ Reads raw bytes from an iterator and does chunks of length `chunk_len`. Optionally adds `stride` to each chunks to
+ get overlaps. `stream` is used to return partial results even if a full `chunk_len` is not yet available.
+ """
+ acc = b""
+ stride_left, stride_right = stride
+ if stride_left + stride_right >= chunk_len:
+ raise ValueError(
+ f"Stride needs to be strictly smaller than chunk_len: ({stride_left}, {stride_right}) vs {chunk_len}"
+ )
+ _stride_left = 0
+ for raw in iterator:
+ acc += raw
+ if stream and len(acc) < chunk_len:
+ stride = (_stride_left, 0)
+ yield {"raw": acc[:chunk_len], "stride": stride, "partial": True}
+ else:
+ while len(acc) >= chunk_len:
+ # We are flushing the accumulator
+ stride = (_stride_left, stride_right)
+ item = {"raw": acc[:chunk_len], "stride": stride}
+ if stream:
+ item["partial"] = False
+ yield item
+ _stride_left = stride_left
+ acc = acc[chunk_len - stride_left - stride_right :]
+ # Last chunk
+ if len(acc) > stride_left:
+ item = {"raw": acc, "stride": (_stride_left, 0)}
+ if stream:
+ item["partial"] = False
+ yield item
+
+
+def _ffmpeg_stream(ffmpeg_command, buflen: int):
+ """
+ Internal function to create the generator of data through ffmpeg
+ """
+ bufsize = 2**24 # 16Mo
+ try:
+ with subprocess.Popen(ffmpeg_command, stdout=subprocess.PIPE, bufsize=bufsize) as ffmpeg_process:
+ while True:
+ raw = ffmpeg_process.stdout.read(buflen)
+ if raw == b"":
+ break
+ yield raw
+ except FileNotFoundError as error:
+ raise ValueError("ffmpeg was not found but is required to stream audio files from filename") from error
+
+
+def _get_microphone_name():
+ """
+ Retrieve the microphone name in Windows .
+ """
+ command = ["ffmpeg", "-list_devices", "true", "-f", "dshow", "-i", ""]
+
+ try:
+ ffmpeg_devices = subprocess.run(command, text=True, stderr=subprocess.PIPE, encoding="utf-8")
+ microphone_lines = [line for line in ffmpeg_devices.stderr.splitlines() if "(audio)" in line]
+
+ if microphone_lines:
+ microphone_name = microphone_lines[0].split('"')[1]
+ print(f"Using microphone: {microphone_name}")
+ return f"audio={microphone_name}"
+ except FileNotFoundError:
+ print("ffmpeg was not found. Please install it or make sure it is in your system PATH.")
+
+ return "default"
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/automatic_speech_recognition.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/automatic_speech_recognition.py
new file mode 100644
index 0000000000000000000000000000000000000000..25d92833eabd468b9d349f1cab1e1015d0bd833b
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/automatic_speech_recognition.py
@@ -0,0 +1,671 @@
+# Copyright 2021 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+from collections import defaultdict
+from typing import TYPE_CHECKING, Any, Optional, Union
+
+import numpy as np
+import requests
+
+from ..generation import GenerationConfig
+from ..tokenization_utils import PreTrainedTokenizer
+from ..utils import is_torch_available, is_torchaudio_available, is_torchcodec_available, logging
+from .audio_utils import ffmpeg_read
+from .base import ChunkPipeline
+
+
+if TYPE_CHECKING:
+ from pyctcdecode import BeamSearchDecoderCTC
+
+ from ..feature_extraction_sequence_utils import SequenceFeatureExtractor
+ from ..modeling_utils import PreTrainedModel
+
+logger = logging.get_logger(__name__)
+
+if is_torch_available():
+ import torch
+
+ from ..models.auto.modeling_auto import MODEL_FOR_SPEECH_SEQ_2_SEQ_MAPPING_NAMES
+
+
+def rescale_stride(stride, ratio):
+ """
+ Rescales the stride values from audio space to tokens/logits space.
+
+ (160_000, 16_000, 16_000) -> (2000, 200, 200) for instance.
+ """
+ # Shape is [B, SEQ] for tokens
+ # [B, SEQ, V] for logits
+
+ new_strides = []
+ for input_n, left, right in stride:
+ token_n = int(round(input_n * ratio))
+ left = int(round(left / input_n * token_n))
+ right = int(round(right / input_n * token_n))
+ new_stride = (token_n, left, right)
+ new_strides.append(new_stride)
+
+ return new_strides
+
+
+def chunk_iter(inputs, feature_extractor, chunk_len, stride_left, stride_right, dtype=None):
+ inputs_len = inputs.shape[0]
+ step = chunk_len - stride_left - stride_right
+ for chunk_start_idx in range(0, inputs_len, step):
+ chunk_end_idx = chunk_start_idx + chunk_len
+ chunk = inputs[chunk_start_idx:chunk_end_idx]
+ processed = feature_extractor(
+ chunk,
+ sampling_rate=feature_extractor.sampling_rate,
+ return_tensors="pt",
+ return_attention_mask=True,
+ )
+ if dtype is not None:
+ processed = processed.to(dtype=dtype)
+ _stride_left = 0 if chunk_start_idx == 0 else stride_left
+ is_last = chunk_end_idx >= inputs_len
+ _stride_right = 0 if is_last else stride_right
+
+ chunk_len = chunk.shape[0]
+ stride = (chunk_len, _stride_left, _stride_right)
+ if chunk.shape[0] > _stride_left:
+ yield {"is_last": is_last, "stride": stride, **processed}
+ if is_last:
+ break
+
+
+def _find_longest_common_sequence(sequences, tokenizer):
+ # TODO Use a faster algorithm this can probably be done in O(n)
+ # using suffix array.
+ # It might be tedious to do because of fault tolerance.
+ # We actually have a really good property which is that the total sequence
+ # MUST be those subsequences in order.
+ # Also the algorithm should be more tolerant to errors.
+ sequence = [tok_id for tok_id in sequences[0][0].tolist() if tok_id not in tokenizer.all_special_ids]
+ for new_seq in sequences[1:]:
+ new_sequence = [tok_id for tok_id in new_seq[0].tolist() if tok_id not in tokenizer.all_special_ids]
+
+ index = 0
+ max_ = 0.0
+ for i in range(1, len(new_sequence) + 1):
+ # epsilon to favor long perfect matches
+ eps = i / 10000.0
+ matches = np.sum(np.array(sequence[-i:]) == np.array(new_sequence[:i]))
+ matching = matches / i + eps
+ if matches > 1 and matching > max_:
+ index = i
+ max_ = matching
+ sequence.extend(new_sequence[index:])
+ return np.array(sequence)
+
+
+class AutomaticSpeechRecognitionPipeline(ChunkPipeline):
+ """
+ Pipeline that aims at extracting spoken text contained within some audio.
+
+ The input can be either a raw waveform or a audio file. In case of the audio file, ffmpeg should be installed for
+ to support multiple audio formats
+
+ Unless the model you're using explicitly sets these generation parameters in its configuration files
+ (`generation_config.json`), the following default values will be used:
+ - max_new_tokens: 256
+ - num_beams: 5
+
+ Example:
+
+ ```python
+ >>> from transformers import pipeline
+
+ >>> transcriber = pipeline(model="openai/whisper-base")
+ >>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac")
+ {'text': ' He hoped there would be stew for dinner, turnips and carrots and bruised potatoes and fat mutton pieces to be ladled out in thick, peppered flour-fatten sauce.'}
+ ```
+
+ Learn more about the basics of using a pipeline in the [pipeline tutorial](../pipeline_tutorial)
+
+ Arguments:
+ model ([`PreTrainedModel`] or [`TFPreTrainedModel`]):
+ The model that will be used by the pipeline to make predictions. This needs to be a model inheriting from
+ [`PreTrainedModel`] for PyTorch and [`TFPreTrainedModel`] for TensorFlow.
+ feature_extractor ([`SequenceFeatureExtractor`]):
+ The feature extractor that will be used by the pipeline to encode waveform for the model.
+ tokenizer ([`PreTrainedTokenizer`]):
+ The tokenizer that will be used by the pipeline to encode data for the model. This object inherits from
+ [`PreTrainedTokenizer`].
+ decoder (`pyctcdecode.BeamSearchDecoderCTC`, *optional*):
+ [PyCTCDecode's
+ BeamSearchDecoderCTC](https://github.com/kensho-technologies/pyctcdecode/blob/2fd33dc37c4111417e08d89ccd23d28e9b308d19/pyctcdecode/decoder.py#L180)
+ can be passed for language model boosted decoding. See [`Wav2Vec2ProcessorWithLM`] for more information.
+ chunk_length_s (`float`, *optional*, defaults to 0):
+ The input length for in each chunk. If `chunk_length_s = 0` then chunking is disabled (default).
+
+
+
+ For more information on how to effectively use `chunk_length_s`, please have a look at the [ASR chunking
+ blog post](https://huggingface.co/blog/asr-chunking).
+
+
+
+ stride_length_s (`float`, *optional*, defaults to `chunk_length_s / 6`):
+ The length of stride on the left and right of each chunk. Used only with `chunk_length_s > 0`. This enables
+ the model to *see* more context and infer letters better than without this context but the pipeline
+ discards the stride bits at the end to make the final reconstitution as perfect as possible.
+
+
+
+ For more information on how to effectively use `stride_length_s`, please have a look at the [ASR chunking
+ blog post](https://huggingface.co/blog/asr-chunking).
+
+
+
+ framework (`str`, *optional*):
+ The framework to use, either `"pt"` for PyTorch or `"tf"` for TensorFlow. The specified framework must be
+ installed. If no framework is specified, will default to the one currently installed. If no framework is
+ specified and both frameworks are installed, will default to the framework of the `model`, or to PyTorch if
+ no model is provided.
+ device (Union[`int`, `torch.device`], *optional*):
+ Device ordinal for CPU/GPU supports. Setting this to `None` will leverage CPU, a positive will run the
+ model on the associated CUDA device id.
+ """
+
+ _pipeline_calls_generate = True
+ _load_processor = False
+ _load_image_processor = False
+ _load_feature_extractor = True
+ _load_tokenizer = True
+ # Make sure the docstring is updated when the default generation config is changed
+ _default_generation_config = GenerationConfig(
+ max_new_tokens=256,
+ num_beams=5, # follows openai's whisper implementation
+ )
+
+ def __init__(
+ self,
+ model: "PreTrainedModel",
+ feature_extractor: Union["SequenceFeatureExtractor", str] = None,
+ tokenizer: Optional[PreTrainedTokenizer] = None,
+ decoder: Optional[Union["BeamSearchDecoderCTC", str]] = None,
+ device: Union[int, "torch.device"] = None,
+ **kwargs,
+ ):
+ # set the model type so we can check we have the right pre- and post-processing parameters
+ if model.config.model_type == "whisper":
+ self.type = "seq2seq_whisper"
+ elif model.__class__.__name__ in MODEL_FOR_SPEECH_SEQ_2_SEQ_MAPPING_NAMES.values():
+ self.type = "seq2seq"
+ elif (
+ feature_extractor._processor_class
+ and feature_extractor._processor_class.endswith("WithLM")
+ and decoder is not None
+ ):
+ self.decoder = decoder
+ self.type = "ctc_with_lm"
+ else:
+ self.type = "ctc"
+
+ super().__init__(model, tokenizer, feature_extractor, device=device, **kwargs)
+
+ def __call__(self, inputs: Union[np.ndarray, bytes, str, dict], **kwargs: Any) -> list[dict[str, Any]]:
+ """
+ Transcribe the audio sequence(s) given as inputs to text. See the [`AutomaticSpeechRecognitionPipeline`]
+ documentation for more information.
+
+ Args:
+ inputs (`np.ndarray` or `bytes` or `str` or `dict`):
+ The inputs is either :
+ - `str` that is either the filename of a local audio file, or a public URL address to download the
+ audio file. The file will be read at the correct sampling rate to get the waveform using
+ *ffmpeg*. This requires *ffmpeg* to be installed on the system.
+ - `bytes` it is supposed to be the content of an audio file and is interpreted by *ffmpeg* in the
+ same way.
+ - (`np.ndarray` of shape (n, ) of type `np.float32` or `np.float64`)
+ Raw audio at the correct sampling rate (no further check will be done)
+ - `dict` form can be used to pass raw audio sampled at arbitrary `sampling_rate` and let this
+ pipeline do the resampling. The dict must be in the format `{"sampling_rate": int, "raw":
+ np.array}` with optionally a `"stride": (left: int, right: int)` than can ask the pipeline to
+ treat the first `left` samples and last `right` samples to be ignored in decoding (but used at
+ inference to provide more context to the model). Only use `stride` with CTC models.
+ return_timestamps (*optional*, `str` or `bool`):
+ Only available for pure CTC models (Wav2Vec2, HuBERT, etc) and the Whisper model. Not available for
+ other sequence-to-sequence models.
+
+ For CTC models, timestamps can take one of two formats:
+ - `"char"`: the pipeline will return timestamps along the text for every character in the text. For
+ instance, if you get `[{"text": "h", "timestamp": (0.5, 0.6)}, {"text": "i", "timestamp": (0.7,
+ 0.9)}]`, then it means the model predicts that the letter "h" was spoken after `0.5` and before
+ `0.6` seconds.
+ - `"word"`: the pipeline will return timestamps along the text for every word in the text. For
+ instance, if you get `[{"text": "hi ", "timestamp": (0.5, 0.9)}, {"text": "there", "timestamp":
+ (1.0, 1.5)}]`, then it means the model predicts that the word "hi" was spoken after `0.5` and
+ before `0.9` seconds.
+
+ For the Whisper model, timestamps can take one of two formats:
+ - `"word"`: same as above for word-level CTC timestamps. Word-level timestamps are predicted
+ through the *dynamic-time warping (DTW)* algorithm, an approximation to word-level timestamps
+ by inspecting the cross-attention weights.
+ - `True`: the pipeline will return timestamps along the text for *segments* of words in the text.
+ For instance, if you get `[{"text": " Hi there!", "timestamp": (0.5, 1.5)}]`, then it means the
+ model predicts that the segment "Hi there!" was spoken after `0.5` and before `1.5` seconds.
+ Note that a segment of text refers to a sequence of one or more words, rather than individual
+ words as with word-level timestamps.
+ generate_kwargs (`dict`, *optional*):
+ The dictionary of ad-hoc parametrization of `generate_config` to be used for the generation call. For a
+ complete overview of generate, check the [following
+ guide](https://huggingface.co/docs/transformers/en/main_classes/text_generation).
+
+ Return:
+ `Dict`: A dictionary with the following keys:
+ - **text** (`str`): The recognized text.
+ - **chunks** (*optional(, `list[Dict]`)
+ When using `return_timestamps`, the `chunks` will become a list containing all the various text
+ chunks identified by the model, *e.g.* `[{"text": "hi ", "timestamp": (0.5, 0.9)}, {"text":
+ "there", "timestamp": (1.0, 1.5)}]`. The original full text can roughly be recovered by doing
+ `"".join(chunk["text"] for chunk in output["chunks"])`.
+ """
+ return super().__call__(inputs, **kwargs)
+
+ def _sanitize_parameters(
+ self,
+ chunk_length_s=None,
+ stride_length_s=None,
+ ignore_warning=None,
+ decoder_kwargs=None,
+ return_timestamps=None,
+ return_language=None,
+ generate_kwargs=None,
+ ):
+ # No parameters on this pipeline right now
+ preprocess_params = {}
+ if chunk_length_s is not None:
+ if self.type in ["seq2seq", "seq2seq_whisper"] and not ignore_warning:
+ type_warning = (
+ "Using `chunk_length_s` is very experimental with seq2seq models. The results will not necessarily"
+ " be entirely accurate and will have caveats. More information:"
+ " https://github.com/huggingface/transformers/pull/20104. Ignore this warning with pipeline(...,"
+ " ignore_warning=True)."
+ )
+ if self.type == "seq2seq_whisper":
+ type_warning += (
+ " To use Whisper for long-form transcription, use rather the model's `generate` method directly "
+ "as the model relies on it's own chunking mechanism (cf. Whisper original paper, section 3.8. "
+ "Long-form Transcription)."
+ )
+ logger.warning(type_warning)
+ preprocess_params["chunk_length_s"] = chunk_length_s
+ if stride_length_s is not None:
+ preprocess_params["stride_length_s"] = stride_length_s
+
+ forward_params = defaultdict(dict)
+ if generate_kwargs is not None:
+ forward_params.update(generate_kwargs)
+
+ postprocess_params = {}
+ if decoder_kwargs is not None:
+ postprocess_params["decoder_kwargs"] = decoder_kwargs
+
+ # in some models like whisper, the generation config has a `return_timestamps` key
+ if hasattr(self, "generation_config") and hasattr(self.generation_config, "return_timestamps"):
+ return_timestamps = return_timestamps or self.generation_config.return_timestamps
+
+ if return_timestamps is not None:
+ # Check whether we have a valid setting for return_timestamps and throw an error before we perform a forward pass
+ if self.type == "seq2seq" and return_timestamps:
+ raise ValueError("We cannot return_timestamps yet on non-CTC models apart from Whisper!")
+ if self.type == "ctc_with_lm" and return_timestamps != "word":
+ raise ValueError("CTC with LM can only predict word level timestamps, set `return_timestamps='word'`")
+ if self.type == "ctc" and return_timestamps not in ["char", "word"]:
+ raise ValueError(
+ "CTC can either predict character level timestamps, or word level timestamps. "
+ "Set `return_timestamps='char'` or `return_timestamps='word'` as required."
+ )
+ if self.type == "seq2seq_whisper" and return_timestamps == "char":
+ raise ValueError(
+ "Whisper cannot return `char` timestamps, only word level or segment level timestamps. "
+ "Use `return_timestamps='word'` or `return_timestamps=True` respectively."
+ )
+ forward_params["return_timestamps"] = return_timestamps
+ postprocess_params["return_timestamps"] = return_timestamps
+ if return_language is not None:
+ if self.type != "seq2seq_whisper":
+ raise ValueError("Only Whisper can return language for now.")
+ postprocess_params["return_language"] = return_language
+
+ if getattr(self, "assistant_model", None) is not None:
+ forward_params["assistant_model"] = self.assistant_model
+ if getattr(self, "assistant_tokenizer", None) is not None:
+ forward_params["tokenizer"] = self.tokenizer
+ forward_params["assistant_tokenizer"] = self.assistant_tokenizer
+
+ return preprocess_params, forward_params, postprocess_params
+
+ def preprocess(self, inputs, chunk_length_s=0, stride_length_s=None):
+ if isinstance(inputs, str):
+ if inputs.startswith("http://") or inputs.startswith("https://"):
+ # We need to actually check for a real protocol, otherwise it's impossible to use a local file
+ # like http_huggingface_co.png
+ inputs = requests.get(inputs).content
+ else:
+ with open(inputs, "rb") as f:
+ inputs = f.read()
+
+ if isinstance(inputs, bytes):
+ inputs = ffmpeg_read(inputs, self.feature_extractor.sampling_rate)
+
+ stride = None
+ extra = {}
+
+ if is_torch_available():
+ import torch
+
+ if isinstance(inputs, torch.Tensor):
+ inputs = inputs.cpu().numpy()
+
+ if is_torchcodec_available():
+ import torchcodec
+
+ if isinstance(inputs, torchcodec.decoders.AudioDecoder):
+ _audio_samples = inputs.get_all_samples()
+
+ # torchcodec always returns (num_channels, num_samples)
+ # while before (datasets < 4.0) we had (2, num_samples) if stereo, (num_samples,) if mono
+ _array = _audio_samples.data
+ _array = _array[0] if _array.ndim == 2 and _array.shape[0] == 1 else _array
+ inputs = {"array": _array, "sampling_rate": _audio_samples.sample_rate}
+
+ if isinstance(inputs, dict):
+ stride = inputs.pop("stride", None)
+ # Accepting `"array"` which is the key defined in `datasets` for
+ # better integration
+ if not ("sampling_rate" in inputs and ("raw" in inputs or "array" in inputs)):
+ raise ValueError(
+ "When passing a dictionary to AutomaticSpeechRecognitionPipeline, the dict needs to contain a "
+ '"raw" key containing the numpy array or torch tensor representing the audio and a "sampling_rate" key, '
+ "containing the sampling_rate associated with that array"
+ )
+
+ _inputs = inputs.pop("raw", None)
+ if _inputs is None:
+ # Remove path which will not be used from `datasets`.
+ inputs.pop("path", None)
+ _inputs = inputs.pop("array", None)
+ in_sampling_rate = inputs.pop("sampling_rate")
+ extra = inputs
+ inputs = _inputs
+ if in_sampling_rate != self.feature_extractor.sampling_rate:
+ if is_torchaudio_available():
+ from torchaudio import functional as F
+ else:
+ raise ImportError(
+ "torchaudio is required to resample audio samples in AutomaticSpeechRecognitionPipeline. "
+ "The torchaudio package can be installed through: `pip install torchaudio`."
+ )
+
+ inputs = F.resample(
+ torch.from_numpy(inputs) if isinstance(inputs, np.ndarray) else inputs,
+ in_sampling_rate,
+ in_sampling_rate,
+ self.feature_extractor.sampling_rate,
+ ).numpy()
+ ratio = self.feature_extractor.sampling_rate / in_sampling_rate
+ else:
+ ratio = 1
+ if stride is not None:
+ if stride[0] + stride[1] > inputs.shape[0]:
+ raise ValueError("Stride is too large for input")
+
+ # Stride needs to get the chunk length here, it's going to get
+ # swallowed by the `feature_extractor` later, and then batching
+ # can add extra data in the inputs, so we need to keep track
+ # of the original length in the stride so we can cut properly.
+ stride = (inputs.shape[0], int(round(stride[0] * ratio)), int(round(stride[1] * ratio)))
+ if not isinstance(inputs, (np.ndarray, torch.Tensor)):
+ raise TypeError(f"We expect a numpy ndarray or torch tensor as input, got `{type(inputs)}`")
+ if inputs.ndim != 1:
+ logger.warning(
+ f"We expect a single channel audio input for AutomaticSpeechRecognitionPipeline, got {inputs.ndim}. Taking the mean of the channels for mono conversion."
+ )
+ inputs = inputs.mean(axis=0)
+
+ if chunk_length_s:
+ if stride_length_s is None:
+ stride_length_s = chunk_length_s / 6
+
+ if isinstance(stride_length_s, (int, float)):
+ stride_length_s = [stride_length_s, stride_length_s]
+
+ # XXX: Carefully, this variable will not exist in `seq2seq` setting.
+ # Currently chunking is not possible at this level for `seq2seq` so
+ # it's ok.
+ align_to = getattr(self.model.config, "inputs_to_logits_ratio", 1)
+ chunk_len = int(round(chunk_length_s * self.feature_extractor.sampling_rate / align_to) * align_to)
+ stride_left = int(round(stride_length_s[0] * self.feature_extractor.sampling_rate / align_to) * align_to)
+ stride_right = int(round(stride_length_s[1] * self.feature_extractor.sampling_rate / align_to) * align_to)
+
+ if chunk_len < stride_left + stride_right:
+ raise ValueError("Chunk length must be superior to stride length")
+
+ for item in chunk_iter(inputs, self.feature_extractor, chunk_len, stride_left, stride_right, self.dtype):
+ yield {**item, **extra}
+ else:
+ if self.type == "seq2seq_whisper" and inputs.shape[0] > self.feature_extractor.n_samples:
+ processed = self.feature_extractor(
+ inputs,
+ sampling_rate=self.feature_extractor.sampling_rate,
+ truncation=False,
+ padding="longest",
+ return_tensors="pt",
+ return_attention_mask=True,
+ )
+ else:
+ if self.type == "seq2seq_whisper" and stride is None:
+ processed = self.feature_extractor(
+ inputs,
+ sampling_rate=self.feature_extractor.sampling_rate,
+ return_tensors="pt",
+ return_token_timestamps=True,
+ return_attention_mask=True,
+ )
+ extra["num_frames"] = processed.pop("num_frames")
+ else:
+ processed = self.feature_extractor(
+ inputs,
+ sampling_rate=self.feature_extractor.sampling_rate,
+ return_tensors="pt",
+ return_attention_mask=True,
+ )
+ if self.dtype is not None:
+ processed = processed.to(dtype=self.dtype)
+ if stride is not None:
+ if self.type == "seq2seq":
+ raise ValueError("Stride is only usable with CTC models, try removing it !")
+
+ processed["stride"] = stride
+ yield {"is_last": True, **processed, **extra}
+
+ def _forward(self, model_inputs, return_timestamps=False, **generate_kwargs):
+ attention_mask = model_inputs.pop("attention_mask", None)
+ stride = model_inputs.pop("stride", None)
+ num_frames = model_inputs.pop("num_frames", None)
+ is_last = model_inputs.pop("is_last")
+
+ if stride is not None and num_frames is not None:
+ raise ValueError("num_frames must be used only when stride is None")
+
+ if self.type in {"seq2seq", "seq2seq_whisper"}:
+ # Consume values so we can let extra information flow freely through
+ # the pipeline (important for `partial` in microphone)
+ if "input_features" in model_inputs:
+ inputs = model_inputs.pop("input_features")
+ elif "input_values" in model_inputs:
+ inputs = model_inputs.pop("input_values")
+ else:
+ raise ValueError(
+ "Seq2Seq speech recognition model requires either a "
+ f"`input_features` or `input_values` key, but only has {model_inputs.keys()}"
+ )
+
+ # custom processing for Whisper timestamps and word-level timestamps
+ return_timestamps = return_timestamps or getattr(self.generation_config, "return_timestamps", False)
+ if return_timestamps and self.type == "seq2seq_whisper":
+ generate_kwargs["return_timestamps"] = bool(return_timestamps)
+ if return_timestamps == "word":
+ generate_kwargs["return_token_timestamps"] = True
+ generate_kwargs["return_segments"] = True
+
+ # User-defined `generation_config` passed to the pipeline call take precedence
+ if "generation_config" not in generate_kwargs:
+ generate_kwargs["generation_config"] = self.generation_config
+
+ main_input_name = self.model.main_input_name if hasattr(self.model, "main_input_name") else "inputs"
+ generate_kwargs = {
+ main_input_name: inputs,
+ "attention_mask": attention_mask,
+ **generate_kwargs,
+ }
+ tokens = self.model.generate(**generate_kwargs)
+
+ # whisper longform generation stores timestamps in "segments"
+ if return_timestamps == "word" and self.type == "seq2seq_whisper":
+ if "segments" not in tokens:
+ out = {"tokens": tokens["sequences"], "token_timestamps": tokens["token_timestamps"]}
+ else:
+ token_timestamps = [
+ torch.cat([segment["token_timestamps"] for segment in segment_list])
+ for segment_list in tokens["segments"]
+ ]
+ out = {"tokens": tokens["sequences"], "token_timestamps": token_timestamps}
+ else:
+ out = {"tokens": tokens}
+ if self.type == "seq2seq_whisper":
+ if stride is not None:
+ out["stride"] = stride
+
+ else:
+ inputs = {
+ self.model.main_input_name: model_inputs.pop(self.model.main_input_name),
+ "attention_mask": attention_mask,
+ }
+ outputs = self.model(**inputs)
+ logits = outputs.logits
+
+ if self.type == "ctc_with_lm":
+ out = {"logits": logits}
+ else:
+ out = {"tokens": logits.argmax(dim=-1)}
+ if stride is not None:
+ # Send stride to `postprocess`.
+ # it needs to be handled there where
+ # the pieces are to be concatenated.
+ ratio = 1 / self.model.config.inputs_to_logits_ratio
+ if isinstance(stride, tuple):
+ out["stride"] = rescale_stride([stride], ratio)[0]
+ else:
+ out["stride"] = rescale_stride(stride, ratio)
+ # Leftover
+ extra = model_inputs
+ return {"is_last": is_last, **out, **extra}
+
+ def postprocess(
+ self, model_outputs, decoder_kwargs: Optional[dict] = None, return_timestamps=None, return_language=None
+ ):
+ # Optional return types
+ optional = {}
+
+ final_items = []
+ key = "logits" if self.type == "ctc_with_lm" else "tokens"
+ stride = None
+ for outputs in model_outputs:
+ if self.framework == "pt" and outputs[key].dtype in (torch.bfloat16, torch.float16):
+ items = outputs[key].to(torch.float32).numpy()
+ else:
+ items = outputs[key].numpy()
+ stride = outputs.get("stride", None)
+ if stride is not None and self.type in {"ctc", "ctc_with_lm"}:
+ total_n, left, right = stride
+ # Total_n might be < logits.shape[1]
+ # because of padding, that's why
+ # we need to reconstruct this information
+ # This won't work with left padding (which doesn't exist right now)
+ right_n = total_n - right
+ items = items[:, left:right_n]
+ final_items.append(items)
+
+ if stride and self.type == "seq2seq":
+ items = _find_longest_common_sequence(final_items, self.tokenizer)
+ elif self.type == "seq2seq_whisper":
+ time_precision = self.feature_extractor.chunk_length / self.model.config.max_source_positions
+ # Send the chunking back to seconds, it's easier to handle in whisper
+ sampling_rate = self.feature_extractor.sampling_rate
+ for output in model_outputs:
+ if "stride" in output:
+ chunk_len, stride_left, stride_right = output["stride"]
+ # Go back in seconds
+ chunk_len /= sampling_rate
+ stride_left /= sampling_rate
+ stride_right /= sampling_rate
+ output["stride"] = chunk_len, stride_left, stride_right
+
+ text, optional = self.tokenizer._decode_asr(
+ model_outputs,
+ return_timestamps=return_timestamps,
+ return_language=return_language,
+ time_precision=time_precision,
+ )
+ else:
+ items = np.concatenate(final_items, axis=1)
+ items = items.squeeze(0)
+
+ if self.type == "ctc_with_lm":
+ if decoder_kwargs is None:
+ decoder_kwargs = {}
+ beams = self.decoder.decode_beams(items, **decoder_kwargs)
+ text = beams[0][0]
+ if return_timestamps:
+ # Simply cast from pyctcdecode format to wav2vec2 format to leverage
+ # pre-existing code later
+ chunk_offset = beams[0][2]
+ offsets = []
+ for word, (start_offset, end_offset) in chunk_offset:
+ offsets.append({"word": word, "start_offset": start_offset, "end_offset": end_offset})
+ elif self.type != "seq2seq_whisper":
+ skip_special_tokens = self.type != "ctc"
+ text = self.tokenizer.decode(items, skip_special_tokens=skip_special_tokens)
+ if return_timestamps:
+ offsets = self.tokenizer.decode(
+ items, skip_special_tokens=skip_special_tokens, output_char_offsets=True
+ )["char_offsets"]
+ if return_timestamps == "word":
+ offsets = self.tokenizer._get_word_offsets(offsets, self.tokenizer.replace_word_delimiter_char)
+
+ if return_timestamps and self.type not in {"seq2seq", "seq2seq_whisper"}:
+ chunks = []
+ for item in offsets:
+ start = item["start_offset"] * self.model.config.inputs_to_logits_ratio
+ start /= self.feature_extractor.sampling_rate
+
+ stop = item["end_offset"] * self.model.config.inputs_to_logits_ratio
+ stop /= self.feature_extractor.sampling_rate
+
+ chunks.append({"text": item[return_timestamps], "timestamp": (start, stop)})
+ optional["chunks"] = chunks
+
+ extra = defaultdict(list)
+ for output in model_outputs:
+ output.pop("tokens", None)
+ output.pop("logits", None)
+ output.pop("is_last", None)
+ output.pop("stride", None)
+ output.pop("token_timestamps", None)
+ for k, v in output.items():
+ extra[k].append(v)
+ return {"text": text, **optional, **extra}
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/base.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/base.py
new file mode 100644
index 0000000000000000000000000000000000000000..8e05eae99ae013e6bcbe7ccd1ff936ed406055d5
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/base.py
@@ -0,0 +1,1590 @@
+# coding=utf-8
+# Copyright 2018 The HuggingFace Inc. team.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import collections
+import copy
+import csv
+import importlib
+import json
+import os
+import pickle
+import sys
+import traceback
+import types
+import warnings
+from abc import ABC, abstractmethod
+from collections import UserDict
+from contextlib import contextmanager
+from os.path import abspath, exists
+from typing import TYPE_CHECKING, Any, Optional, Union
+
+from ..dynamic_module_utils import custom_object_save
+from ..feature_extraction_utils import PreTrainedFeatureExtractor
+from ..generation import GenerationConfig
+from ..image_processing_utils import BaseImageProcessor
+from ..modelcard import ModelCard
+from ..models.auto import AutoConfig, AutoTokenizer
+from ..processing_utils import ProcessorMixin
+from ..tokenization_utils import PreTrainedTokenizer
+from ..utils import (
+ ModelOutput,
+ PushToHubMixin,
+ add_end_docstrings,
+ copy_func,
+ infer_framework,
+ is_tf_available,
+ is_torch_available,
+ is_torch_cuda_available,
+ is_torch_hpu_available,
+ is_torch_mlu_available,
+ is_torch_mps_available,
+ is_torch_musa_available,
+ is_torch_npu_available,
+ is_torch_xpu_available,
+ logging,
+)
+from ..utils.deprecation import deprecate_kwarg
+
+
+GenericTensor = Union[list["GenericTensor"], "torch.Tensor", "tf.Tensor"]
+
+if is_tf_available():
+ import tensorflow as tf
+
+ from ..models.auto.modeling_tf_auto import TFAutoModel
+
+if is_torch_available():
+ import torch
+ from torch.utils.data import DataLoader, Dataset
+
+ from ..modeling_utils import PreTrainedModel
+ from ..models.auto.modeling_auto import AutoModel
+
+ # Re-export for backward compatibility
+ from .pt_utils import KeyDataset
+else:
+ Dataset = None
+ KeyDataset = None
+
+if TYPE_CHECKING:
+ from ..modeling_tf_utils import TFPreTrainedModel
+ from ..modeling_utils import PreTrainedModel
+
+
+logger = logging.get_logger(__name__)
+
+
+def no_collate_fn(items):
+ if len(items) != 1:
+ raise ValueError("This collate_fn is meant to be used with batch_size=1")
+ return items[0]
+
+
+def _pad(items, key, padding_value, padding_side):
+ batch_size = len(items)
+ if isinstance(items[0][key], torch.Tensor):
+ # Others include `attention_mask` etc...
+ shape = items[0][key].shape
+ dim = len(shape)
+ if dim == 1:
+ # We have a list of 1-dim torch tensors, which can be stacked without padding
+ return torch.cat([item[key] for item in items], dim=0)
+ if key in ["pixel_values", "image"]:
+ # This is probable image so padding shouldn't be necessary
+ # B, C, H, W
+ return torch.cat([item[key] for item in items], dim=0)
+ elif dim == 4 and key == "input_features":
+ # this is probably a mel spectrogram batched
+ return torch.cat([item[key] for item in items], dim=0)
+ max_length = max(item[key].shape[1] for item in items)
+ min_length = min(item[key].shape[1] for item in items)
+ dtype = items[0][key].dtype
+
+ if dim == 2:
+ if max_length == min_length:
+ # Bypass for `ImageGPT` which doesn't provide a padding value, yet
+ # we can consistently pad since the size should be matching
+ return torch.cat([item[key] for item in items], dim=0)
+ tensor = torch.zeros((batch_size, max_length), dtype=dtype) + padding_value
+ elif dim == 3:
+ tensor = torch.zeros((batch_size, max_length, shape[-1]), dtype=dtype) + padding_value
+ elif dim == 4:
+ tensor = torch.zeros((batch_size, max_length, shape[-2], shape[-1]), dtype=dtype) + padding_value
+
+ for i, item in enumerate(items):
+ if dim == 2:
+ if padding_side == "left":
+ tensor[i, -len(item[key][0]) :] = item[key][0].clone()
+ else:
+ tensor[i, : len(item[key][0])] = item[key][0].clone()
+ elif dim == 3:
+ if padding_side == "left":
+ tensor[i, -len(item[key][0]) :, :] = item[key][0].clone()
+ else:
+ tensor[i, : len(item[key][0]), :] = item[key][0].clone()
+ elif dim == 4:
+ if padding_side == "left":
+ tensor[i, -len(item[key][0]) :, :, :] = item[key][0].clone()
+ else:
+ tensor[i, : len(item[key][0]), :, :] = item[key][0].clone()
+
+ return tensor
+ else:
+ return [item[key] for item in items]
+
+
+def pad_collate_fn(tokenizer, feature_extractor):
+ # Tokenizer
+ t_padding_side = None
+ # Feature extractor
+ f_padding_side = None
+ if tokenizer is None and feature_extractor is None:
+ raise ValueError("Pipeline without tokenizer or feature_extractor cannot do batching")
+ if tokenizer is not None:
+ if tokenizer.pad_token_id is None:
+ raise ValueError(
+ "Pipeline with tokenizer without pad_token cannot do batching. You can try to set it with "
+ "`pipe.tokenizer.pad_token_id = model.config.eos_token_id`."
+ )
+ else:
+ t_padding_value = tokenizer.pad_token_id
+ t_padding_side = tokenizer.padding_side
+ if feature_extractor is not None:
+ # Feature extractor can be images, where no padding is expected
+ f_padding_value = getattr(feature_extractor, "padding_value", None)
+ f_padding_side = getattr(feature_extractor, "padding_side", None)
+
+ if t_padding_side is not None and f_padding_side is not None and t_padding_side != f_padding_side:
+ raise ValueError(
+ f"The feature extractor, and tokenizer don't agree on padding side {t_padding_side} != {f_padding_side}"
+ )
+ padding_side = "right"
+ if t_padding_side is not None:
+ padding_side = t_padding_side
+ if f_padding_side is not None:
+ padding_side = f_padding_side
+
+ def inner(items):
+ keys = set(items[0].keys())
+ for item in items:
+ if set(item.keys()) != keys:
+ raise ValueError(
+ f"The elements of the batch contain different keys. Cannot batch them ({set(item.keys())} !="
+ f" {keys})"
+ )
+ # input_values, input_pixels, input_ids, ...
+ padded = {}
+ for key in keys:
+ if key in {"input_ids"}:
+ # ImageGPT uses a feature extractor
+ if tokenizer is None and feature_extractor is not None:
+ _padding_value = f_padding_value
+ else:
+ _padding_value = t_padding_value
+ elif key in {"input_values", "pixel_values", "input_features"}:
+ _padding_value = f_padding_value
+ elif key in {"p_mask", "special_tokens_mask"}:
+ _padding_value = 1
+ elif key in {"attention_mask", "token_type_ids"}:
+ _padding_value = 0
+ else:
+ # This is likely another random key maybe even user provided
+ _padding_value = 0
+ padded[key] = _pad(items, key, _padding_value, padding_side)
+ return padded
+
+ return inner
+
+
+def infer_framework_load_model(
+ model,
+ config: AutoConfig,
+ model_classes: Optional[dict[str, tuple[type]]] = None,
+ task: Optional[str] = None,
+ framework: Optional[str] = None,
+ **model_kwargs,
+):
+ """
+ Select framework (TensorFlow or PyTorch) to use from the `model` passed. Returns a tuple (framework, model).
+
+ If `model` is instantiated, this function will just infer the framework from the model class. Otherwise `model` is
+ actually a checkpoint name and this method will try to instantiate it using `model_classes`. Since we don't want to
+ instantiate the model twice, this model is returned for use by the pipeline.
+
+ If both frameworks are installed and available for `model`, PyTorch is selected.
+
+ Args:
+ model (`str`, [`PreTrainedModel`] or [`TFPreTrainedModel]`):
+ The model to infer the framework from. If `str`, a checkpoint name. The model to infer the framewrok from.
+ config ([`AutoConfig`]):
+ The config associated with the model to help using the correct class
+ model_classes (dictionary `str` to `type`, *optional*):
+ A mapping framework to class.
+ task (`str`):
+ The task defining which pipeline will be returned.
+ model_kwargs:
+ Additional dictionary of keyword arguments passed along to the model's `from_pretrained(...,
+ **model_kwargs)` function.
+
+ Returns:
+ `Tuple`: A tuple framework, model.
+ """
+ if not is_tf_available() and not is_torch_available():
+ raise RuntimeError(
+ "At least one of TensorFlow 2.0 or PyTorch should be installed. "
+ "To install TensorFlow 2.0, read the instructions at https://www.tensorflow.org/install/ "
+ "To install PyTorch, read the instructions at https://pytorch.org/."
+ )
+ if isinstance(model, str):
+ model_kwargs["_from_pipeline"] = task
+ class_tuple = ()
+ look_pt = is_torch_available() and framework in {"pt", None}
+ look_tf = is_tf_available() and framework in {"tf", None}
+ if model_classes:
+ if look_pt:
+ class_tuple = class_tuple + model_classes.get("pt", (AutoModel,))
+ if look_tf:
+ class_tuple = class_tuple + model_classes.get("tf", (TFAutoModel,))
+ if config.architectures:
+ classes = []
+ for architecture in config.architectures:
+ transformers_module = importlib.import_module("transformers")
+ if look_pt:
+ _class = getattr(transformers_module, architecture, None)
+ if _class is not None:
+ classes.append(_class)
+ if look_tf:
+ _class = getattr(transformers_module, f"TF{architecture}", None)
+ if _class is not None:
+ classes.append(_class)
+ class_tuple = class_tuple + tuple(classes)
+
+ if len(class_tuple) == 0:
+ raise ValueError(f"Pipeline cannot infer suitable model classes from {model}")
+
+ all_traceback = {}
+ for model_class in class_tuple:
+ kwargs = model_kwargs.copy()
+ if framework == "pt" and model.endswith(".h5"):
+ kwargs["from_tf"] = True
+ logger.warning(
+ "Model might be a TensorFlow model (ending with `.h5`) but TensorFlow is not available. "
+ "Trying to load the model with PyTorch."
+ )
+ elif framework == "tf" and model.endswith(".bin"):
+ kwargs["from_pt"] = True
+ logger.warning(
+ "Model might be a PyTorch model (ending with `.bin`) but PyTorch is not available. "
+ "Trying to load the model with Tensorflow."
+ )
+
+ try:
+ model = model_class.from_pretrained(model, **kwargs)
+ if hasattr(model, "eval"):
+ model = model.eval()
+ # Stop loading on the first successful load.
+ break
+ except (OSError, ValueError, TypeError, RuntimeError):
+ # `from_pretrained` may raise a `TypeError` or `RuntimeError` when the requested `dtype`
+ # is not supported on the execution device (e.g. bf16 on a consumer GPU). We capture those so
+ # we can transparently retry the load in float32 before surfacing an error to the user.
+ fallback_tried = False
+ if is_torch_available() and ("dtype" in kwargs):
+ import torch # local import to avoid unnecessarily importing torch for TF/JAX users
+
+ fallback_tried = True
+ fp32_kwargs = kwargs.copy()
+ fp32_kwargs["dtype"] = torch.float32
+
+ try:
+ model = model_class.from_pretrained(model, **fp32_kwargs)
+ if hasattr(model, "eval"):
+ model = model.eval()
+ logger.warning(
+ "Falling back to torch.float32 because loading with the original dtype failed on the"
+ " target device."
+ )
+ break
+ except Exception:
+ # If it still fails, capture the traceback and continue to the next class.
+ all_traceback[model_class.__name__] = traceback.format_exc()
+ continue
+
+ # If no fallback was attempted or it also failed, record the original traceback.
+ if not fallback_tried:
+ all_traceback[model_class.__name__] = traceback.format_exc()
+ continue
+
+ if isinstance(model, str):
+ error = ""
+ for class_name, trace in all_traceback.items():
+ error += f"while loading with {class_name}, an error is thrown:\n{trace}\n"
+ raise ValueError(
+ f"Could not load model {model} with any of the following classes: {class_tuple}. See the original errors:\n\n{error}\n"
+ )
+
+ if framework is None:
+ framework = infer_framework(model.__class__)
+ return framework, model
+
+
+def infer_framework_from_model(
+ model,
+ model_classes: Optional[dict[str, tuple[type]]] = None,
+ task: Optional[str] = None,
+ framework: Optional[str] = None,
+ **model_kwargs,
+):
+ """
+ Select framework (TensorFlow or PyTorch) to use from the `model` passed. Returns a tuple (framework, model).
+
+ If `model` is instantiated, this function will just infer the framework from the model class. Otherwise `model` is
+ actually a checkpoint name and this method will try to instantiate it using `model_classes`. Since we don't want to
+ instantiate the model twice, this model is returned for use by the pipeline.
+
+ If both frameworks are installed and available for `model`, PyTorch is selected.
+
+ Args:
+ model (`str`, [`PreTrainedModel`] or [`TFPreTrainedModel]`):
+ The model to infer the framework from. If `str`, a checkpoint name. The model to infer the framewrok from.
+ model_classes (dictionary `str` to `type`, *optional*):
+ A mapping framework to class.
+ task (`str`):
+ The task defining which pipeline will be returned.
+ model_kwargs:
+ Additional dictionary of keyword arguments passed along to the model's `from_pretrained(...,
+ **model_kwargs)` function.
+
+ Returns:
+ `Tuple`: A tuple framework, model.
+ """
+ if isinstance(model, str):
+ config = AutoConfig.from_pretrained(model, _from_pipeline=task, **model_kwargs)
+ else:
+ config = model.config
+ return infer_framework_load_model(
+ model, config, model_classes=model_classes, _from_pipeline=task, task=task, framework=framework, **model_kwargs
+ )
+
+
+def get_framework(model, revision: Optional[str] = None):
+ """
+ Select framework (TensorFlow or PyTorch) to use.
+
+ Args:
+ model (`str`, [`PreTrainedModel`] or [`TFPreTrainedModel]`):
+ If both frameworks are installed, picks the one corresponding to the model passed (either a model class or
+ the model name). If no specific model is provided, defaults to using PyTorch.
+ """
+ warnings.warn(
+ "`get_framework` is deprecated and will be removed in v5, use `infer_framework_from_model` instead.",
+ FutureWarning,
+ )
+ if not is_tf_available() and not is_torch_available():
+ raise RuntimeError(
+ "At least one of TensorFlow 2.0 or PyTorch should be installed. "
+ "To install TensorFlow 2.0, read the instructions at https://www.tensorflow.org/install/ "
+ "To install PyTorch, read the instructions at https://pytorch.org/."
+ )
+ if isinstance(model, str):
+ if is_torch_available() and not is_tf_available():
+ model = AutoModel.from_pretrained(model, revision=revision)
+ elif is_tf_available() and not is_torch_available():
+ model = TFAutoModel.from_pretrained(model, revision=revision)
+ else:
+ try:
+ model = AutoModel.from_pretrained(model, revision=revision)
+ except OSError:
+ model = TFAutoModel.from_pretrained(model, revision=revision)
+
+ framework = infer_framework(model.__class__)
+ return framework
+
+
+def get_default_model_and_revision(
+ targeted_task: dict, framework: Optional[str], task_options: Optional[Any]
+) -> tuple[str, str]:
+ """
+ Select a default model to use for a given task. Defaults to pytorch if ambiguous.
+
+ Args:
+ targeted_task (`Dict`):
+ Dictionary representing the given task, that should contain default models
+
+ framework (`str`, None)
+ "pt", "tf" or None, representing a specific framework if it was specified, or None if we don't know yet.
+
+ task_options (`Any`, None)
+ Any further value required by the task to get fully specified, for instance (SRC, TGT) languages for
+ translation task.
+
+ Returns
+
+ Tuple:
+ - `str` The model string representing the default model for this pipeline.
+ - `str` The revision of the model.
+ """
+ if is_torch_available() and not is_tf_available():
+ framework = "pt"
+ elif is_tf_available() and not is_torch_available():
+ framework = "tf"
+
+ defaults = targeted_task["default"]
+ if task_options:
+ if task_options not in defaults:
+ raise ValueError(f"The task does not provide any default models for options {task_options}")
+ default_models = defaults[task_options]["model"]
+ elif "model" in defaults:
+ default_models = targeted_task["default"]["model"]
+ else:
+ # XXX This error message needs to be updated to be more generic if more tasks are going to become
+ # parametrized
+ raise ValueError('The task defaults can\'t be correctly selected. You probably meant "translation_xx_to_yy"')
+
+ if framework is None:
+ framework = "pt"
+
+ return default_models[framework]
+
+
+def load_assistant_model(
+ model: "PreTrainedModel",
+ assistant_model: Optional[Union[str, "PreTrainedModel"]],
+ assistant_tokenizer: Optional[PreTrainedTokenizer],
+) -> tuple[Optional["PreTrainedModel"], Optional[PreTrainedTokenizer]]:
+ """
+ Prepares the assistant model and the assistant tokenizer for a pipeline whose model that can call `generate`.
+
+ Args:
+ model ([`PreTrainedModel`]):
+ The main model that will be used by the pipeline to make predictions.
+ assistant_model (`str` or [`PreTrainedModel`], *optional*):
+ The assistant model that will be used by the pipeline to make predictions.
+ assistant_tokenizer ([`PreTrainedTokenizer`], *optional*):
+ The assistant tokenizer that will be used by the pipeline to encode data for the model.
+
+ Returns:
+ Tuple: The loaded assistant model and (optionally) the loaded tokenizer.
+ """
+ if not model.can_generate() or assistant_model is None:
+ return None, None
+
+ if getattr(model, "framework") != "pt" or not isinstance(model, PreTrainedModel):
+ raise ValueError(
+ "Assisted generation, triggered by the `assistant_model` argument, is only available for "
+ "`PreTrainedModel` model instances. For instance, TF or JAX models are not supported."
+ )
+
+ # If the model is passed as a string, load the model and the corresponding tokenizer
+ if isinstance(assistant_model, str):
+ assistant_config = AutoConfig.from_pretrained(assistant_model)
+ _, loaded_assistant_model = infer_framework_load_model(assistant_model, config=assistant_config)
+ loaded_assistant_model = loaded_assistant_model.to(device=model.device, dtype=model.dtype)
+ loaded_assistant_tokenizer = AutoTokenizer.from_pretrained(assistant_model)
+ else:
+ loaded_assistant_model = assistant_model
+ loaded_assistant_tokenizer = assistant_tokenizer
+
+ # Finally, let's check the tokenizers: if the two models have different tokenizers, we need to keep the assistant
+ # tokenizer
+ same_vocab_size = model.config.vocab_size == loaded_assistant_model.config.vocab_size
+ same_special_tokens = all(
+ getattr(model.config, token) == getattr(loaded_assistant_model.config, token)
+ for token in ("eos_token_id", "pad_token_id", "bos_token_id")
+ )
+ if same_vocab_size and same_special_tokens:
+ loaded_assistant_tokenizer = None
+ elif loaded_assistant_tokenizer is None:
+ raise ValueError(
+ "The assistant model has a different tokenizer than the main model. You should pass the assistant "
+ "tokenizer."
+ )
+
+ return loaded_assistant_model, loaded_assistant_tokenizer
+
+
+class PipelineException(Exception):
+ """
+ Raised by a [`Pipeline`] when handling __call__.
+
+ Args:
+ task (`str`): The task of the pipeline.
+ model (`str`): The model used by the pipeline.
+ reason (`str`): The error message to display.
+ """
+
+ def __init__(self, task: str, model: str, reason: str):
+ super().__init__(reason)
+
+ self.task = task
+ self.model = model
+
+
+class ArgumentHandler(ABC):
+ """
+ Base interface for handling arguments for each [`~pipelines.Pipeline`].
+ """
+
+ @abstractmethod
+ def __call__(self, *args, **kwargs):
+ raise NotImplementedError()
+
+
+class PipelineDataFormat:
+ """
+ Base class for all the pipeline supported data format both for reading and writing. Supported data formats
+ currently includes:
+
+ - JSON
+ - CSV
+ - stdin/stdout (pipe)
+
+ `PipelineDataFormat` also includes some utilities to work with multi-columns like mapping from datasets columns to
+ pipelines keyword arguments through the `dataset_kwarg_1=dataset_column_1` format.
+
+ Args:
+ output_path (`str`): Where to save the outgoing data.
+ input_path (`str`): Where to look for the input data.
+ column (`str`): The column to read.
+ overwrite (`bool`, *optional*, defaults to `False`):
+ Whether or not to overwrite the `output_path`.
+ """
+
+ SUPPORTED_FORMATS = ["json", "csv", "pipe"]
+
+ def __init__(
+ self,
+ output_path: Optional[str],
+ input_path: Optional[str],
+ column: Optional[str],
+ overwrite: bool = False,
+ ):
+ self.output_path = output_path
+ self.input_path = input_path
+ self.column = column.split(",") if column is not None else [""]
+ self.is_multi_columns = len(self.column) > 1
+
+ if self.is_multi_columns:
+ self.column = [tuple(c.split("=")) if "=" in c else (c, c) for c in self.column]
+
+ if output_path is not None and not overwrite:
+ if exists(abspath(self.output_path)):
+ raise OSError(f"{self.output_path} already exists on disk")
+
+ if input_path is not None:
+ if not exists(abspath(self.input_path)):
+ raise OSError(f"{self.input_path} doesn't exist on disk")
+
+ @abstractmethod
+ def __iter__(self):
+ raise NotImplementedError()
+
+ @abstractmethod
+ def save(self, data: Union[dict, list[dict]]):
+ """
+ Save the provided data object with the representation for the current [`~pipelines.PipelineDataFormat`].
+
+ Args:
+ data (`dict` or list of `dict`): The data to store.
+ """
+ raise NotImplementedError()
+
+ def save_binary(self, data: Union[dict, list[dict]]) -> str:
+ """
+ Save the provided data object as a pickle-formatted binary data on the disk.
+
+ Args:
+ data (`dict` or list of `dict`): The data to store.
+
+ Returns:
+ `str`: Path where the data has been saved.
+ """
+ path, _ = os.path.splitext(self.output_path)
+ binary_path = os.path.extsep.join((path, "pickle"))
+
+ with open(binary_path, "wb+") as f_output:
+ pickle.dump(data, f_output)
+
+ return binary_path
+
+ @staticmethod
+ def from_str(
+ format: str,
+ output_path: Optional[str],
+ input_path: Optional[str],
+ column: Optional[str],
+ overwrite=False,
+ ) -> "PipelineDataFormat":
+ """
+ Creates an instance of the right subclass of [`~pipelines.PipelineDataFormat`] depending on `format`.
+
+ Args:
+ format (`str`):
+ The format of the desired pipeline. Acceptable values are `"json"`, `"csv"` or `"pipe"`.
+ output_path (`str`, *optional*):
+ Where to save the outgoing data.
+ input_path (`str`, *optional*):
+ Where to look for the input data.
+ column (`str`, *optional*):
+ The column to read.
+ overwrite (`bool`, *optional*, defaults to `False`):
+ Whether or not to overwrite the `output_path`.
+
+ Returns:
+ [`~pipelines.PipelineDataFormat`]: The proper data format.
+ """
+ if format == "json":
+ return JsonPipelineDataFormat(output_path, input_path, column, overwrite=overwrite)
+ elif format == "csv":
+ return CsvPipelineDataFormat(output_path, input_path, column, overwrite=overwrite)
+ elif format == "pipe":
+ return PipedPipelineDataFormat(output_path, input_path, column, overwrite=overwrite)
+ else:
+ raise KeyError(f"Unknown reader {format} (Available reader are json/csv/pipe)")
+
+
+class CsvPipelineDataFormat(PipelineDataFormat):
+ """
+ Support for pipelines using CSV data format.
+
+ Args:
+ output_path (`str`): Where to save the outgoing data.
+ input_path (`str`): Where to look for the input data.
+ column (`str`): The column to read.
+ overwrite (`bool`, *optional*, defaults to `False`):
+ Whether or not to overwrite the `output_path`.
+ """
+
+ def __init__(
+ self,
+ output_path: Optional[str],
+ input_path: Optional[str],
+ column: Optional[str],
+ overwrite=False,
+ ):
+ super().__init__(output_path, input_path, column, overwrite=overwrite)
+
+ def __iter__(self):
+ with open(self.input_path, "r") as f:
+ reader = csv.DictReader(f)
+ for row in reader:
+ if self.is_multi_columns:
+ yield {k: row[c] for k, c in self.column}
+ else:
+ yield row[self.column[0]]
+
+ def save(self, data: list[dict]):
+ """
+ Save the provided data object with the representation for the current [`~pipelines.PipelineDataFormat`].
+
+ Args:
+ data (`list[dict]`): The data to store.
+ """
+ with open(self.output_path, "w") as f:
+ if len(data) > 0:
+ writer = csv.DictWriter(f, list(data[0].keys()))
+ writer.writeheader()
+ writer.writerows(data)
+
+
+class JsonPipelineDataFormat(PipelineDataFormat):
+ """
+ Support for pipelines using JSON file format.
+
+ Args:
+ output_path (`str`): Where to save the outgoing data.
+ input_path (`str`): Where to look for the input data.
+ column (`str`): The column to read.
+ overwrite (`bool`, *optional*, defaults to `False`):
+ Whether or not to overwrite the `output_path`.
+ """
+
+ def __init__(
+ self,
+ output_path: Optional[str],
+ input_path: Optional[str],
+ column: Optional[str],
+ overwrite=False,
+ ):
+ super().__init__(output_path, input_path, column, overwrite=overwrite)
+
+ with open(input_path, "r") as f:
+ self._entries = json.load(f)
+
+ def __iter__(self):
+ for entry in self._entries:
+ if self.is_multi_columns:
+ yield {k: entry[c] for k, c in self.column}
+ else:
+ yield entry[self.column[0]]
+
+ def save(self, data: dict):
+ """
+ Save the provided data object in a json file.
+
+ Args:
+ data (`dict`): The data to store.
+ """
+ with open(self.output_path, "w") as f:
+ json.dump(data, f)
+
+
+class PipedPipelineDataFormat(PipelineDataFormat):
+ """
+ Read data from piped input to the python process. For multi columns data, columns should separated by \t
+
+ If columns are provided, then the output will be a dictionary with {column_x: value_x}
+
+ Args:
+ output_path (`str`): Where to save the outgoing data.
+ input_path (`str`): Where to look for the input data.
+ column (`str`): The column to read.
+ overwrite (`bool`, *optional*, defaults to `False`):
+ Whether or not to overwrite the `output_path`.
+ """
+
+ def __iter__(self):
+ for line in sys.stdin:
+ # Split for multi-columns
+ if "\t" in line:
+ line = line.split("\t")
+ if self.column:
+ # Dictionary to map arguments
+ yield {kwargs: l for (kwargs, _), l in zip(self.column, line)}
+ else:
+ yield tuple(line)
+
+ # No dictionary to map arguments
+ else:
+ yield line
+
+ def save(self, data: dict):
+ """
+ Print the data.
+
+ Args:
+ data (`dict`): The data to store.
+ """
+ print(data)
+
+ def save_binary(self, data: Union[dict, list[dict]]) -> str:
+ if self.output_path is None:
+ raise KeyError(
+ "When using piped input on pipeline outputting large object requires an output file path. "
+ "Please provide such output path through --output argument."
+ )
+
+ return super().save_binary(data)
+
+
+class _ScikitCompat(ABC):
+ """
+ Interface layer for the Scikit and Keras compatibility.
+ """
+
+ @abstractmethod
+ def transform(self, X):
+ raise NotImplementedError()
+
+ @abstractmethod
+ def predict(self, X):
+ raise NotImplementedError()
+
+
+def build_pipeline_init_args(
+ has_tokenizer: bool = False,
+ has_feature_extractor: bool = False,
+ has_image_processor: bool = False,
+ has_processor: bool = False,
+ supports_binary_output: bool = True,
+) -> str:
+ docstring = r"""
+ Arguments:
+ model ([`PreTrainedModel`] or [`TFPreTrainedModel`]):
+ The model that will be used by the pipeline to make predictions. This needs to be a model inheriting from
+ [`PreTrainedModel`] for PyTorch and [`TFPreTrainedModel`] for TensorFlow."""
+ if has_tokenizer:
+ docstring += r"""
+ tokenizer ([`PreTrainedTokenizer`]):
+ The tokenizer that will be used by the pipeline to encode data for the model. This object inherits from
+ [`PreTrainedTokenizer`]."""
+ if has_feature_extractor:
+ docstring += r"""
+ feature_extractor ([`SequenceFeatureExtractor`]):
+ The feature extractor that will be used by the pipeline to encode data for the model. This object inherits from
+ [`SequenceFeatureExtractor`]."""
+ if has_image_processor:
+ docstring += r"""
+ image_processor ([`BaseImageProcessor`]):
+ The image processor that will be used by the pipeline to encode data for the model. This object inherits from
+ [`BaseImageProcessor`]."""
+ if has_processor:
+ docstring += r"""
+ processor ([`ProcessorMixin`]):
+ The processor that will be used by the pipeline to encode data for the model. This object inherits from
+ [`ProcessorMixin`]. Processor is a composite object that might contain `tokenizer`, `feature_extractor`, and
+ `image_processor`."""
+ docstring += r"""
+ modelcard (`str` or [`ModelCard`], *optional*):
+ Model card attributed to the model for this pipeline.
+ framework (`str`, *optional*):
+ The framework to use, either `"pt"` for PyTorch or `"tf"` for TensorFlow. The specified framework must be
+ installed.
+
+ If no framework is specified, will default to the one currently installed. If no framework is specified and
+ both frameworks are installed, will default to the framework of the `model`, or to PyTorch if no model is
+ provided.
+ task (`str`, defaults to `""`):
+ A task-identifier for the pipeline.
+ num_workers (`int`, *optional*, defaults to 8):
+ When the pipeline will use *DataLoader* (when passing a dataset, on GPU for a Pytorch model), the number of
+ workers to be used.
+ batch_size (`int`, *optional*, defaults to 1):
+ When the pipeline will use *DataLoader* (when passing a dataset, on GPU for a Pytorch model), the size of
+ the batch to use, for inference this is not always beneficial, please read [Batching with
+ pipelines](https://huggingface.co/transformers/main_classes/pipelines.html#pipeline-batching) .
+ args_parser ([`~pipelines.ArgumentHandler`], *optional*):
+ Reference to the object in charge of parsing supplied pipeline parameters.
+ device (`int`, *optional*, defaults to -1):
+ Device ordinal for CPU/GPU supports. Setting this to -1 will leverage CPU, a positive will run the model on
+ the associated CUDA device id. You can pass native `torch.device` or a `str` too
+ dtype (`str` or `torch.dtype`, *optional*):
+ Sent directly as `model_kwargs` (just a simpler shortcut) to use the available precision for this model
+ (`torch.float16`, `torch.bfloat16`, ... or `"auto"`)"""
+ if supports_binary_output:
+ docstring += r"""
+ binary_output (`bool`, *optional*, defaults to `False`):
+ Flag indicating if the output the pipeline should happen in a serialized format (i.e., pickle) or as
+ the raw output data e.g. text."""
+ return docstring
+
+
+PIPELINE_INIT_ARGS = build_pipeline_init_args(
+ has_tokenizer=True,
+ has_feature_extractor=True,
+ has_image_processor=True,
+ has_processor=True,
+ supports_binary_output=True,
+)
+
+SUPPORTED_PEFT_TASKS = {
+ "document-question-answering": ["PeftModelForQuestionAnswering"],
+ "feature-extraction": ["PeftModelForFeatureExtraction", "PeftModel"],
+ "question-answering": ["PeftModelForQuestionAnswering"],
+ "summarization": ["PeftModelForSeq2SeqLM"],
+ "table-question-answering": ["PeftModelForQuestionAnswering"],
+ "text2text-generation": ["PeftModelForSeq2SeqLM"],
+ "text-classification": ["PeftModelForSequenceClassification"],
+ "sentiment-analysis": ["PeftModelForSequenceClassification"],
+ "text-generation": ["PeftModelForCausalLM"],
+ "token-classification": ["PeftModelForTokenClassification"],
+ "ner": ["PeftModelForTokenClassification"],
+ "translation": ["PeftModelForSeq2SeqLM"],
+ "translation_xx_to_yy": ["PeftModelForSeq2SeqLM"],
+ "zero-shot-classification": ["PeftModelForSequenceClassification"],
+}
+
+if is_torch_available():
+ from transformers.pipelines.pt_utils import (
+ PipelineChunkIterator,
+ PipelineDataset,
+ PipelineIterator,
+ PipelinePackIterator,
+ )
+
+
+@add_end_docstrings(
+ build_pipeline_init_args(
+ has_tokenizer=True, has_feature_extractor=True, has_image_processor=True, has_processor=True
+ )
+)
+class Pipeline(_ScikitCompat, PushToHubMixin):
+ """
+ The Pipeline class is the class from which all pipelines inherit. Refer to this class for methods shared across
+ different pipelines.
+
+ Base class implementing pipelined operations. Pipeline workflow is defined as a sequence of the following
+ operations:
+
+ Input -> Tokenization -> Model Inference -> Post-Processing (task dependent) -> Output
+
+ Pipeline supports running on CPU or GPU through the device argument (see below).
+
+ Some pipeline, like for instance [`FeatureExtractionPipeline`] (`'feature-extraction'`) output large tensor object
+ as nested-lists. In order to avoid dumping such large structure as textual data we provide the `binary_output`
+ constructor argument. If set to `True`, the output will be stored in the pickle format.
+ """
+
+ # These flags should be overridden for downstream pipelines. They indicate which preprocessing classes are
+ # used by each pipeline. The possible values are:
+ # - True (the class is mandatory, raise an error if it's not present in the repo)
+ # - None (the class is optional; it should be loaded if present in the repo but the pipeline can work without it)
+ # - False (the class is never used by the pipeline and should not be loaded even if present)
+ _load_processor = None
+ _load_image_processor = None
+ _load_feature_extractor = None
+ _load_tokenizer = None
+
+ # Pipelines that call `generate` have shared logic, e.g. preparing the generation config.
+ _pipeline_calls_generate = False
+
+ default_input_names = None
+
+ def __init__(
+ self,
+ model: Union["PreTrainedModel", "TFPreTrainedModel"],
+ tokenizer: Optional[PreTrainedTokenizer] = None,
+ feature_extractor: Optional[PreTrainedFeatureExtractor] = None,
+ image_processor: Optional[BaseImageProcessor] = None,
+ processor: Optional[ProcessorMixin] = None,
+ modelcard: Optional[ModelCard] = None,
+ framework: Optional[str] = None,
+ task: str = "",
+ device: Union[int, "torch.device"] = None,
+ binary_output: bool = False,
+ **kwargs,
+ ):
+ # We need to pop them for _sanitize_parameters call later
+ _, _, _ = kwargs.pop("args_parser", None), kwargs.pop("torch_dtype", None), kwargs.pop("dtype", None)
+ if framework is None:
+ framework, model = infer_framework_load_model(model, config=model.config)
+ if framework in ("tf", "jax"):
+ logger.warning_once(
+ "TensorFlow and JAX classes are deprecated and will be removed in Transformers v5. We "
+ "recommend migrating to PyTorch classes or pinning your version of Transformers."
+ )
+
+ self.task = task
+ self.model = model
+ self.tokenizer = tokenizer
+ self.feature_extractor = feature_extractor
+ self.image_processor = image_processor
+ self.processor = processor
+ self.modelcard = modelcard
+ self.framework = framework
+
+ # `accelerate` device map
+ hf_device_map = getattr(self.model, "hf_device_map", None)
+
+ if hf_device_map is not None and device is not None:
+ raise ValueError(
+ "The model has been loaded with `accelerate` and therefore cannot be moved to a specific device. Please "
+ "discard the `device` argument when creating your pipeline object."
+ )
+
+ if device is None:
+ if hf_device_map is not None:
+ # Take the first device used by `accelerate`.
+ device = next(iter(hf_device_map.values()))
+ else:
+ device = 0
+
+ if is_torch_available() and self.framework == "pt":
+ if device == -1 and self.model.device is not None:
+ device = self.model.device
+ if isinstance(device, torch.device):
+ if (device.type == "xpu" and not is_torch_xpu_available(check_device=True)) or (
+ device.type == "hpu" and not is_torch_hpu_available()
+ ):
+ raise ValueError(f'{device} is not available, you should use device="cpu" instead')
+
+ self.device = device
+ elif isinstance(device, str):
+ if ("xpu" in device and not is_torch_xpu_available(check_device=True)) or (
+ "hpu" in device and not is_torch_hpu_available()
+ ):
+ raise ValueError(f'{device} is not available, you should use device="cpu" instead')
+
+ self.device = torch.device(device)
+ elif device < 0:
+ self.device = torch.device("cpu")
+ elif is_torch_mlu_available():
+ self.device = torch.device(f"mlu:{device}")
+ elif is_torch_musa_available():
+ self.device = torch.device(f"musa:{device}")
+ elif is_torch_cuda_available():
+ self.device = torch.device(f"cuda:{device}")
+ elif is_torch_npu_available():
+ self.device = torch.device(f"npu:{device}")
+ elif is_torch_hpu_available():
+ self.device = torch.device(f"hpu:{device}")
+ elif is_torch_xpu_available(check_device=True):
+ self.device = torch.device(f"xpu:{device}")
+ elif is_torch_mps_available():
+ self.device = torch.device(f"mps:{device}")
+ else:
+ self.device = torch.device("cpu")
+ else:
+ self.device = device if device is not None else -1
+
+ if is_torch_available() and torch.distributed.is_available() and torch.distributed.is_initialized():
+ self.device = self.model.device
+ logger.warning(f"Device set to use {self.device}")
+
+ self.binary_output = binary_output
+
+ # We shouldn't call `model.to()` for models loaded with accelerate as well as the case that model is already on device
+ if (
+ self.framework == "pt"
+ and self.model.device != self.device
+ and not (isinstance(self.device, int) and self.device < 0)
+ and hf_device_map is None
+ ):
+ self.model.to(self.device)
+
+ # If it's a generation pipeline and the model can generate:
+ # 1 - create a local generation config. This is done to avoid side-effects on the model as we apply local
+ # tweaks to the generation config.
+ # 2 - load the assistant model if it is passed.
+ if self._pipeline_calls_generate and self.model.can_generate():
+ self.assistant_model, self.assistant_tokenizer = load_assistant_model(
+ self.model, kwargs.pop("assistant_model", None), kwargs.pop("assistant_tokenizer", None)
+ )
+ self.prefix = self.model.config.prefix if hasattr(self.model.config, "prefix") else None
+ # each pipeline with text generation capabilities should define its own default generation in a
+ # `_default_generation_config` class attribute
+ default_pipeline_generation_config = getattr(self, "_default_generation_config", GenerationConfig())
+ if hasattr(self.model, "_prepare_generation_config"): # TF doesn't have `_prepare_generation_config`
+ # Uses `generate`'s logic to enforce the following priority of arguments:
+ # 1. user-defined config options in `**kwargs`
+ # 2. model's generation config values
+ # 3. pipeline's default generation config values
+ # NOTE: _prepare_generation_config creates a deep copy of the generation config before updating it,
+ # and returns all kwargs that were not used to update the generation config
+ prepared_generation_config, kwargs = self.model._prepare_generation_config(
+ generation_config=default_pipeline_generation_config, use_model_defaults=True, **kwargs
+ )
+ self.generation_config = prepared_generation_config
+ # if the `max_new_tokens` is set to the pipeline default, but `max_length` is set to a non-default
+ # value: let's honor `max_length`. E.g. we want Whisper's default `max_length=448` take precedence
+ # over over the pipeline's length default.
+ if (
+ default_pipeline_generation_config.max_new_tokens is not None # there's a pipeline default
+ and self.generation_config.max_new_tokens == default_pipeline_generation_config.max_new_tokens
+ and self.generation_config.max_length is not None
+ and self.generation_config.max_length != 20 # global default
+ ):
+ self.generation_config.max_new_tokens = None
+ else:
+ # TODO (joao): no PT model should reach this line. However, some audio models with complex
+ # inheritance patterns do. Streamline those models such that this line is no longer needed.
+ # In those models, the default generation config is not (yet) used.
+ self.generation_config = copy.deepcopy(self.model.generation_config)
+ # Update the generation config with task specific params if they exist.
+ # NOTE: 1. `prefix` is pipeline-specific and doesn't exist in the generation config.
+ # 2. `task_specific_params` is a legacy feature and should be removed in a future version.
+ task_specific_params = self.model.config.task_specific_params
+ if task_specific_params is not None and task in task_specific_params:
+ this_task_params = task_specific_params.get(task)
+ if "prefix" in this_task_params:
+ self.prefix = this_task_params.pop("prefix")
+ self.generation_config.update(**this_task_params)
+ # If the tokenizer has a pad token but the model doesn't, set it so that `generate` is aware of it.
+ if (
+ self.tokenizer is not None
+ and self.tokenizer.pad_token_id is not None
+ and self.generation_config.pad_token_id is None
+ ):
+ self.generation_config.pad_token_id = self.tokenizer.pad_token_id
+
+ self.call_count = 0
+ self._batch_size = kwargs.pop("batch_size", None)
+ self._num_workers = kwargs.pop("num_workers", None)
+ self._preprocess_params, self._forward_params, self._postprocess_params = self._sanitize_parameters(**kwargs)
+
+ # In processor only mode, we can get the modality processors from the processor
+ if self.processor is not None and all(
+ [self.tokenizer is None, self.feature_extractor is None, self.image_processor is None]
+ ):
+ self.tokenizer = getattr(self.processor, "tokenizer", None)
+ self.feature_extractor = getattr(self.processor, "feature_extractor", None)
+ self.image_processor = getattr(self.processor, "image_processor", None)
+
+ if self.image_processor is None and self.feature_extractor is not None:
+ if isinstance(self.feature_extractor, BaseImageProcessor):
+ # Backward compatible change, if users called
+ # ImageSegmentationPipeline(.., feature_extractor=MyFeatureExtractor())
+ # then we should keep working
+ self.image_processor = self.feature_extractor
+
+ def save_pretrained(
+ self,
+ save_directory: Union[str, os.PathLike],
+ safe_serialization: bool = True,
+ **kwargs,
+ ):
+ """
+ Save the pipeline's model and tokenizer.
+
+ Args:
+ save_directory (`str` or `os.PathLike`):
+ A path to the directory where to saved. It will be created if it doesn't exist.
+ safe_serialization (`str`):
+ Whether to save the model using `safetensors` or the traditional way for PyTorch or Tensorflow.
+ kwargs (`dict[str, Any]`, *optional*):
+ Additional key word arguments passed along to the [`~utils.PushToHubMixin.push_to_hub`] method.
+ """
+ use_auth_token = kwargs.pop("use_auth_token", None)
+
+ if use_auth_token is not None:
+ warnings.warn(
+ "The `use_auth_token` argument is deprecated and will be removed in v5 of Transformers. Please use `token` instead.",
+ FutureWarning,
+ )
+ if kwargs.get("token") is not None:
+ raise ValueError(
+ "`token` and `use_auth_token` are both specified. Please set only the argument `token`."
+ )
+ kwargs["token"] = use_auth_token
+
+ if os.path.isfile(save_directory):
+ logger.error(f"Provided path ({save_directory}) should be a directory, not a file")
+ return
+ os.makedirs(save_directory, exist_ok=True)
+
+ if hasattr(self, "_registered_impl"):
+ # Add info to the config
+ pipeline_info = self._registered_impl.copy()
+ custom_pipelines = {}
+ for task, info in pipeline_info.items():
+ if info["impl"] != self.__class__:
+ continue
+
+ info = info.copy()
+ module_name = info["impl"].__module__
+ last_module = module_name.split(".")[-1]
+ # Change classes into their names/full names
+ info["impl"] = f"{last_module}.{info['impl'].__name__}"
+ info["pt"] = tuple(c.__name__ for c in info["pt"])
+ info["tf"] = tuple(c.__name__ for c in info["tf"])
+
+ custom_pipelines[task] = info
+ self.model.config.custom_pipelines = custom_pipelines
+ # Save the pipeline custom code
+ custom_object_save(self, save_directory)
+
+ kwargs["safe_serialization"] = safe_serialization
+ self.model.save_pretrained(save_directory, **kwargs)
+
+ if self.tokenizer is not None:
+ self.tokenizer.save_pretrained(save_directory, **kwargs)
+
+ if self.feature_extractor is not None:
+ self.feature_extractor.save_pretrained(save_directory, **kwargs)
+
+ if self.image_processor is not None:
+ self.image_processor.save_pretrained(save_directory, **kwargs)
+
+ if self.modelcard is not None:
+ self.modelcard.save_pretrained(save_directory)
+
+ def transform(self, X):
+ """
+ Scikit / Keras interface to transformers' pipelines. This method will forward to __call__().
+ """
+ return self(X)
+
+ def predict(self, X):
+ """
+ Scikit / Keras interface to transformers' pipelines. This method will forward to __call__().
+ """
+ return self(X)
+
+ @property
+ def dtype(self) -> Optional["torch.dtype"]:
+ """
+ Dtype of the model (if it's Pytorch model), `None` otherwise.
+ """
+ return getattr(self.model, "dtype", None)
+
+ @property
+ def torch_dtype(self) -> Optional["torch.dtype"]:
+ """
+ Torch dtype of the model (if it's Pytorch model), `None` otherwise.
+ """
+ logger.warning_once("`torch_dtype` attribute is deprecated. Use `dtype` instead!")
+ return getattr(self.model, "dtype", None)
+
+ @contextmanager
+ def device_placement(self):
+ """
+ Context Manager allowing tensor allocation on the user-specified device in framework agnostic way.
+
+ Returns:
+ Context manager
+
+ Examples:
+
+ ```python
+ # Explicitly ask for tensor allocation on CUDA device :0
+ pipe = pipeline(..., device=0)
+ with pipe.device_placement():
+ # Every framework specific tensor allocation will be done on the request device
+ output = pipe(...)
+ ```"""
+ if self.framework == "tf":
+ with tf.device("/CPU:0" if self.device == -1 else f"/device:GPU:{self.device}"):
+ yield
+ else:
+ if self.device.type == "cuda":
+ with torch.cuda.device(self.device):
+ yield
+ elif self.device.type == "mlu":
+ with torch.mlu.device(self.device):
+ yield
+ elif self.device.type == "musa":
+ with torch.musa.device(self.device):
+ yield
+ elif self.device.type == "xpu":
+ with torch.xpu.device(self.device):
+ yield
+ else:
+ yield
+
+ def ensure_tensor_on_device(self, **inputs):
+ """
+ Ensure PyTorch tensors are on the specified device.
+
+ Args:
+ inputs (keyword arguments that should be `torch.Tensor`, the rest is ignored):
+ The tensors to place on `self.device`.
+ Recursive on lists **only**.
+
+ Return:
+ `dict[str, torch.Tensor]`: The same as `inputs` but on the proper device.
+ """
+ return self._ensure_tensor_on_device(inputs, self.device)
+
+ def _ensure_tensor_on_device(self, inputs, device):
+ if isinstance(inputs, ModelOutput):
+ return ModelOutput(
+ {name: self._ensure_tensor_on_device(tensor, device) for name, tensor in inputs.items()}
+ )
+ elif isinstance(inputs, dict):
+ return {name: self._ensure_tensor_on_device(tensor, device) for name, tensor in inputs.items()}
+ elif isinstance(inputs, UserDict):
+ return UserDict({name: self._ensure_tensor_on_device(tensor, device) for name, tensor in inputs.items()})
+ elif isinstance(inputs, list):
+ return [self._ensure_tensor_on_device(item, device) for item in inputs]
+ elif isinstance(inputs, tuple):
+ return tuple(self._ensure_tensor_on_device(item, device) for item in inputs)
+ elif isinstance(inputs, torch.Tensor):
+ return inputs.to(device)
+ else:
+ return inputs
+
+ def check_model_type(self, supported_models: Union[list[str], dict]):
+ """
+ Check if the model class is in supported by the pipeline.
+
+ Args:
+ supported_models (`list[str]` or `dict`):
+ The list of models supported by the pipeline, or a dictionary with model class values.
+ """
+ if not isinstance(supported_models, list): # Create from a model mapping
+ supported_models_names = []
+ if self.task in SUPPORTED_PEFT_TASKS:
+ supported_models_names.extend(SUPPORTED_PEFT_TASKS[self.task])
+
+ for model_name in supported_models.values():
+ # Mapping can now contain tuples of models for the same configuration.
+ if isinstance(model_name, tuple):
+ supported_models_names.extend(list(model_name))
+ else:
+ supported_models_names.append(model_name)
+ if hasattr(supported_models, "_model_mapping"):
+ for model in supported_models._model_mapping._extra_content.values():
+ if isinstance(model_name, tuple):
+ supported_models_names.extend([m.__name__ for m in model])
+ else:
+ supported_models_names.append(model.__name__)
+ supported_models = supported_models_names
+ if self.model.__class__.__name__ not in supported_models:
+ logger.error(
+ f"The model '{self.model.__class__.__name__}' is not supported for {self.task}. Supported models are"
+ f" {supported_models}."
+ )
+
+ @abstractmethod
+ def _sanitize_parameters(self, **pipeline_parameters):
+ """
+ _sanitize_parameters will be called with any excessive named arguments from either `__init__` or `__call__`
+ methods. It should return 3 dictionaries of the resolved parameters used by the various `preprocess`,
+ `forward` and `postprocess` methods. Do not fill dictionaries if the caller didn't specify a kwargs. This
+ lets you keep defaults in function signatures, which is more "natural".
+
+ It is not meant to be called directly, it will be automatically called and the final parameters resolved by
+ `__init__` and `__call__`
+ """
+ raise NotImplementedError("_sanitize_parameters not implemented")
+
+ @abstractmethod
+ def preprocess(self, input_: Any, **preprocess_parameters: dict) -> dict[str, GenericTensor]:
+ """
+ Preprocess will take the `input_` of a specific pipeline and return a dictionary of everything necessary for
+ `_forward` to run properly. It should contain at least one tensor, but might have arbitrary other items.
+ """
+ raise NotImplementedError("preprocess not implemented")
+
+ @abstractmethod
+ def _forward(self, input_tensors: dict[str, GenericTensor], **forward_parameters: dict) -> ModelOutput:
+ """
+ _forward will receive the prepared dictionary from `preprocess` and run it on the model. This method might
+ involve the GPU or the CPU and should be agnostic to it. Isolating this function is the reason for `preprocess`
+ and `postprocess` to exist, so that the hot path, this method generally can run as fast as possible.
+
+ It is not meant to be called directly, `forward` is preferred. It is basically the same but contains additional
+ code surrounding `_forward` making sure tensors and models are on the same device, disabling the training part
+ of the code (leading to faster inference).
+ """
+ raise NotImplementedError("_forward not implemented")
+
+ @abstractmethod
+ def postprocess(self, model_outputs: ModelOutput, **postprocess_parameters: dict) -> Any:
+ """
+ Postprocess will receive the raw outputs of the `_forward` method, generally tensors, and reformat them into
+ something more friendly. Generally it will output a list or a dict or results (containing just strings and
+ numbers).
+ """
+ raise NotImplementedError("postprocess not implemented")
+
+ def get_inference_context(self):
+ return torch.no_grad
+
+ def forward(self, model_inputs, **forward_params):
+ with self.device_placement():
+ if self.framework == "tf":
+ model_inputs["training"] = False
+ model_outputs = self._forward(model_inputs, **forward_params)
+ elif self.framework == "pt":
+ inference_context = self.get_inference_context()
+ with inference_context():
+ model_inputs = self._ensure_tensor_on_device(model_inputs, device=self.device)
+ model_outputs = self._forward(model_inputs, **forward_params)
+ model_outputs = self._ensure_tensor_on_device(model_outputs, device=torch.device("cpu"))
+ else:
+ raise ValueError(f"Framework {self.framework} is not supported")
+ return model_outputs
+
+ def get_iterator(
+ self, inputs, num_workers: int, batch_size: int, preprocess_params, forward_params, postprocess_params
+ ):
+ if isinstance(inputs, collections.abc.Sized):
+ dataset = PipelineDataset(inputs, self.preprocess, preprocess_params)
+ else:
+ if num_workers > 1:
+ logger.warning(
+ "For iterable dataset using num_workers>1 is likely to result"
+ " in errors since everything is iterable, setting `num_workers=1`"
+ " to guarantee correctness."
+ )
+ num_workers = 1
+ dataset = PipelineIterator(inputs, self.preprocess, preprocess_params)
+ if "TOKENIZERS_PARALLELISM" not in os.environ:
+ logger.info("Disabling tokenizer parallelism, we're using DataLoader multithreading already")
+ os.environ["TOKENIZERS_PARALLELISM"] = "false"
+ # TODO hack by collating feature_extractor and image_processor
+ feature_extractor = self.feature_extractor if self.feature_extractor is not None else self.image_processor
+ collate_fn = no_collate_fn if batch_size == 1 else pad_collate_fn(self.tokenizer, feature_extractor)
+ dataloader = DataLoader(dataset, num_workers=num_workers, batch_size=batch_size, collate_fn=collate_fn)
+ model_iterator = PipelineIterator(dataloader, self.forward, forward_params, loader_batch_size=batch_size)
+ final_iterator = PipelineIterator(model_iterator, self.postprocess, postprocess_params)
+ return final_iterator
+
+ def __call__(self, inputs, *args, num_workers=None, batch_size=None, **kwargs):
+ if args:
+ logger.warning(f"Ignoring args : {args}")
+
+ if num_workers is None:
+ if self._num_workers is None:
+ num_workers = 0
+ else:
+ num_workers = self._num_workers
+ if batch_size is None:
+ if self._batch_size is None:
+ batch_size = 1
+ else:
+ batch_size = self._batch_size
+
+ preprocess_params, forward_params, postprocess_params = self._sanitize_parameters(**kwargs)
+
+ # Fuse __init__ params and __call__ params without modifying the __init__ ones.
+ preprocess_params = {**self._preprocess_params, **preprocess_params}
+ forward_params = {**self._forward_params, **forward_params}
+ postprocess_params = {**self._postprocess_params, **postprocess_params}
+
+ self.call_count += 1
+ if self.call_count > 10 and self.framework == "pt" and self.device.type == "cuda":
+ logger.warning_once(
+ "You seem to be using the pipelines sequentially on GPU. In order to maximize efficiency please use a"
+ " dataset",
+ )
+
+ is_dataset = Dataset is not None and isinstance(inputs, Dataset)
+ is_generator = isinstance(inputs, types.GeneratorType)
+ is_list = isinstance(inputs, list)
+
+ is_iterable = is_dataset or is_generator or is_list
+
+ # TODO make the get_iterator work also for `tf` (and `flax`).
+ can_use_iterator = self.framework == "pt" and (is_dataset or is_generator or is_list)
+
+ if is_list:
+ if can_use_iterator:
+ final_iterator = self.get_iterator(
+ inputs, num_workers, batch_size, preprocess_params, forward_params, postprocess_params
+ )
+ outputs = list(final_iterator)
+ return outputs
+ else:
+ return self.run_multi(inputs, preprocess_params, forward_params, postprocess_params)
+ elif can_use_iterator:
+ return self.get_iterator(
+ inputs, num_workers, batch_size, preprocess_params, forward_params, postprocess_params
+ )
+ elif is_iterable:
+ return self.iterate(inputs, preprocess_params, forward_params, postprocess_params)
+ elif self.framework == "pt" and isinstance(self, ChunkPipeline):
+ return next(
+ iter(
+ self.get_iterator(
+ [inputs], num_workers, batch_size, preprocess_params, forward_params, postprocess_params
+ )
+ )
+ )
+ else:
+ return self.run_single(inputs, preprocess_params, forward_params, postprocess_params)
+
+ def run_multi(self, inputs, preprocess_params, forward_params, postprocess_params):
+ return [self.run_single(item, preprocess_params, forward_params, postprocess_params) for item in inputs]
+
+ def run_single(self, inputs, preprocess_params, forward_params, postprocess_params):
+ model_inputs = self.preprocess(inputs, **preprocess_params)
+ model_outputs = self.forward(model_inputs, **forward_params)
+ outputs = self.postprocess(model_outputs, **postprocess_params)
+ return outputs
+
+ def iterate(self, inputs, preprocess_params, forward_params, postprocess_params):
+ # This function should become `get_iterator` again, this is a temporary
+ # easy solution.
+ for input_ in inputs:
+ yield self.run_single(input_, preprocess_params, forward_params, postprocess_params)
+
+
+Pipeline.push_to_hub = copy_func(Pipeline.push_to_hub)
+if Pipeline.push_to_hub.__doc__ is not None:
+ Pipeline.push_to_hub.__doc__ = Pipeline.push_to_hub.__doc__.format(
+ object="pipe", object_class="pipeline", object_files="pipeline file"
+ ).replace(".from_pretrained", "")
+
+
+class ChunkPipeline(Pipeline):
+ def run_single(self, inputs, preprocess_params, forward_params, postprocess_params):
+ all_outputs = []
+ for model_inputs in self.preprocess(inputs, **preprocess_params):
+ model_outputs = self.forward(model_inputs, **forward_params)
+ all_outputs.append(model_outputs)
+ outputs = self.postprocess(all_outputs, **postprocess_params)
+ return outputs
+
+ def get_iterator(
+ self, inputs, num_workers: int, batch_size: int, preprocess_params, forward_params, postprocess_params
+ ):
+ if "TOKENIZERS_PARALLELISM" not in os.environ:
+ logger.info("Disabling tokenizer parallelism, we're using DataLoader multithreading already")
+ os.environ["TOKENIZERS_PARALLELISM"] = "false"
+ if num_workers > 1:
+ logger.warning(
+ "For ChunkPipeline using num_workers>0 is likely to result in errors since everything is iterable,"
+ " setting `num_workers=1` to guarantee correctness."
+ )
+ num_workers = 1
+ dataset = PipelineChunkIterator(inputs, self.preprocess, preprocess_params)
+
+ # TODO hack by collating feature_extractor and image_processor
+ feature_extractor = self.feature_extractor if self.feature_extractor is not None else self.image_processor
+ collate_fn = no_collate_fn if batch_size == 1 else pad_collate_fn(self.tokenizer, feature_extractor)
+ dataloader = DataLoader(dataset, num_workers=num_workers, batch_size=batch_size, collate_fn=collate_fn)
+ model_iterator = PipelinePackIterator(dataloader, self.forward, forward_params, loader_batch_size=batch_size)
+ final_iterator = PipelineIterator(model_iterator, self.postprocess, postprocess_params)
+ return final_iterator
+
+
+class PipelineRegistry:
+ def __init__(self, supported_tasks: dict[str, Any], task_aliases: dict[str, str]) -> None:
+ self.supported_tasks = supported_tasks
+ self.task_aliases = task_aliases
+
+ def get_supported_tasks(self) -> list[str]:
+ supported_task = list(self.supported_tasks.keys()) + list(self.task_aliases.keys())
+ supported_task.sort()
+ return supported_task
+
+ def check_task(self, task: str) -> tuple[str, dict, Any]:
+ if task in self.task_aliases:
+ task = self.task_aliases[task]
+ if task in self.supported_tasks:
+ targeted_task = self.supported_tasks[task]
+ return task, targeted_task, None
+
+ if task.startswith("translation"):
+ tokens = task.split("_")
+ if len(tokens) == 4 and tokens[0] == "translation" and tokens[2] == "to":
+ targeted_task = self.supported_tasks["translation"]
+ task = "translation"
+ return task, targeted_task, (tokens[1], tokens[3])
+ raise KeyError(f"Invalid translation task {task}, use 'translation_XX_to_YY' format")
+
+ raise KeyError(
+ f"Unknown task {task}, available tasks are {self.get_supported_tasks() + ['translation_XX_to_YY']}"
+ )
+
+ @deprecate_kwarg(old_name="tf_model", version="5.0.0")
+ def register_pipeline(
+ self,
+ task: str,
+ pipeline_class: type,
+ pt_model: Optional[Union[type, tuple[type]]] = None,
+ tf_model: Optional[Union[type, tuple[type]]] = None,
+ default: Optional[dict] = None,
+ type: Optional[str] = None,
+ ) -> None:
+ if task in self.supported_tasks:
+ logger.warning(f"{task} is already registered. Overwriting pipeline for task {task}...")
+
+ if pt_model is None:
+ pt_model = ()
+ elif not isinstance(pt_model, tuple):
+ pt_model = (pt_model,)
+
+ if tf_model is None:
+ tf_model = ()
+ elif not isinstance(tf_model, tuple):
+ tf_model = (tf_model,)
+
+ task_impl = {"impl": pipeline_class, "pt": pt_model, "tf": tf_model}
+
+ if default is not None:
+ if "model" not in default and ("pt" in default or "tf" in default):
+ default = {"model": default}
+ task_impl["default"] = default
+
+ if type is not None:
+ task_impl["type"] = type
+
+ self.supported_tasks[task] = task_impl
+ pipeline_class._registered_impl = {task: task_impl}
+
+ def to_dict(self):
+ return self.supported_tasks
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/depth_estimation.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/depth_estimation.py
new file mode 100644
index 0000000000000000000000000000000000000000..588cee770639cc25a7720edc3862f1ec07351a08
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/depth_estimation.py
@@ -0,0 +1,146 @@
+from typing import Any, Union, overload
+
+from ..utils import (
+ add_end_docstrings,
+ is_torch_available,
+ is_vision_available,
+ logging,
+ requires_backends,
+)
+from .base import Pipeline, build_pipeline_init_args
+
+
+if is_vision_available():
+ from PIL import Image
+
+ from ..image_utils import load_image
+
+if is_torch_available():
+ from ..models.auto.modeling_auto import MODEL_FOR_DEPTH_ESTIMATION_MAPPING_NAMES
+
+logger = logging.get_logger(__name__)
+
+
+@add_end_docstrings(build_pipeline_init_args(has_image_processor=True))
+class DepthEstimationPipeline(Pipeline):
+ """
+ Depth estimation pipeline using any `AutoModelForDepthEstimation`. This pipeline predicts the depth of an image.
+
+ Example:
+
+ ```python
+ >>> from transformers import pipeline
+
+ >>> depth_estimator = pipeline(task="depth-estimation", model="LiheYoung/depth-anything-base-hf")
+ >>> output = depth_estimator("http://images.cocodataset.org/val2017/000000039769.jpg")
+ >>> # This is a tensor with the values being the depth expressed in meters for each pixel
+ >>> output["predicted_depth"].shape
+ torch.Size([1, 384, 384])
+ ```
+
+ Learn more about the basics of using a pipeline in the [pipeline tutorial](../pipeline_tutorial)
+
+
+ This depth estimation pipeline can currently be loaded from [`pipeline`] using the following task identifier:
+ `"depth-estimation"`.
+
+ See the list of available models on [huggingface.co/models](https://huggingface.co/models?filter=depth-estimation).
+ """
+
+ _load_processor = False
+ _load_image_processor = True
+ _load_feature_extractor = False
+ _load_tokenizer = False
+
+ def __init__(self, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+ requires_backends(self, "vision")
+ self.check_model_type(MODEL_FOR_DEPTH_ESTIMATION_MAPPING_NAMES)
+
+ @overload
+ def __call__(self, inputs: Union[str, "Image.Image"], **kwargs: Any) -> dict[str, Any]: ...
+
+ @overload
+ def __call__(self, inputs: list[Union[str, "Image.Image"]], **kwargs: Any) -> list[dict[str, Any]]: ...
+
+ def __call__(
+ self, inputs: Union[str, list[str], "Image.Image", list["Image.Image"]], **kwargs: Any
+ ) -> Union[dict[str, Any], list[dict[str, Any]]]:
+ """
+ Predict the depth(s) of the image(s) passed as inputs.
+
+ Args:
+ inputs (`str`, `list[str]`, `PIL.Image` or `list[PIL.Image]`):
+ The pipeline handles three types of images:
+
+ - A string containing a http link pointing to an image
+ - A string containing a local path to an image
+ - An image loaded in PIL directly
+
+ The pipeline accepts either a single image or a batch of images, which must then be passed as a string.
+ Images in a batch must all be in the same format: all as http links, all as local paths, or all as PIL
+ images.
+ parameters (`Dict`, *optional*):
+ A dictionary of argument names to parameter values, to control pipeline behaviour.
+ The only parameter available right now is `timeout`, which is the length of time, in seconds,
+ that the pipeline should wait before giving up on trying to download an image.
+ timeout (`float`, *optional*, defaults to None):
+ The maximum time in seconds to wait for fetching images from the web. If None, no timeout is set and
+ the call may block forever.
+
+ Return:
+ A dictionary or a list of dictionaries containing result. If the input is a single image, will return a
+ dictionary, if the input is a list of several images, will return a list of dictionaries corresponding to
+ the images.
+
+ The dictionaries contain the following keys:
+
+ - **predicted_depth** (`torch.Tensor`) -- The predicted depth by the model as a `torch.Tensor`.
+ - **depth** (`PIL.Image`) -- The predicted depth by the model as a `PIL.Image`.
+ """
+ # After deprecation of this is completed, remove the default `None` value for `images`
+ if "images" in kwargs:
+ inputs = kwargs.pop("images")
+ if inputs is None:
+ raise ValueError("Cannot call the depth-estimation pipeline without an inputs argument!")
+ return super().__call__(inputs, **kwargs)
+
+ def _sanitize_parameters(self, timeout=None, parameters=None, **kwargs):
+ preprocess_params = {}
+ if timeout is not None:
+ preprocess_params["timeout"] = timeout
+ if isinstance(parameters, dict) and "timeout" in parameters:
+ preprocess_params["timeout"] = parameters["timeout"]
+ return preprocess_params, {}, {}
+
+ def preprocess(self, image, timeout=None):
+ image = load_image(image, timeout)
+ model_inputs = self.image_processor(images=image, return_tensors=self.framework)
+ if self.framework == "pt":
+ model_inputs = model_inputs.to(self.dtype)
+ model_inputs["target_size"] = image.size[::-1]
+ return model_inputs
+
+ def _forward(self, model_inputs):
+ target_size = model_inputs.pop("target_size")
+ model_outputs = self.model(**model_inputs)
+ model_outputs["target_size"] = target_size
+ return model_outputs
+
+ def postprocess(self, model_outputs):
+ outputs = self.image_processor.post_process_depth_estimation(
+ model_outputs,
+ # this acts as `source_sizes` for ZoeDepth and as `target_sizes` for the rest of the models so do *not*
+ # replace with `target_sizes = [model_outputs["target_size"]]`
+ [model_outputs["target_size"]],
+ )
+
+ formatted_outputs = []
+ for output in outputs:
+ depth = output["predicted_depth"].detach().cpu().numpy()
+ depth = (depth - depth.min()) / (depth.max() - depth.min())
+ depth = Image.fromarray((depth * 255).astype("uint8"))
+
+ formatted_outputs.append({"predicted_depth": output["predicted_depth"], "depth": depth})
+
+ return formatted_outputs[0] if len(outputs) == 1 else formatted_outputs
diff --git a/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/document_question_answering.py b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/document_question_answering.py
new file mode 100644
index 0000000000000000000000000000000000000000..d45e756b0f3f0a6cd140edd67396e569320f3aa5
--- /dev/null
+++ b/code/LaDi-RL-old-qwen-cod/LaDi-RL-old-qwen-cod/venv/lib64/python3.10/site-packages/transformers/pipelines/document_question_answering.py
@@ -0,0 +1,551 @@
+# Copyright 2022 The Impira Team and the HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import re
+from typing import Any, Optional, Union, overload
+
+import numpy as np
+
+from ..generation import GenerationConfig
+from ..utils import (
+ ExplicitEnum,
+ add_end_docstrings,
+ is_pytesseract_available,
+ is_torch_available,
+ is_vision_available,
+ logging,
+)
+from .base import ChunkPipeline, build_pipeline_init_args
+from .question_answering import select_starts_ends
+
+
+if is_vision_available():
+ from PIL import Image
+
+ from ..image_utils import load_image
+
+if is_torch_available():
+ import torch
+
+ from ..models.auto.modeling_auto import MODEL_FOR_DOCUMENT_QUESTION_ANSWERING_MAPPING_NAMES
+
+TESSERACT_LOADED = False
+if is_pytesseract_available():
+ TESSERACT_LOADED = True
+ import pytesseract
+
+logger = logging.get_logger(__name__)
+
+
+# normalize_bbox() and apply_tesseract() are derived from apply_tesseract in models/layoutlmv3/feature_extraction_layoutlmv3.py.
+# However, because the pipeline may evolve from what layoutlmv3 currently does, it's copied (vs. imported) to avoid creating an
+# unnecessary dependency.
+def normalize_box(box, width, height):
+ return [
+ int(1000 * (box[0] / width)),
+ int(1000 * (box[1] / height)),
+ int(1000 * (box[2] / width)),
+ int(1000 * (box[3] / height)),
+ ]
+
+
+def apply_tesseract(image: "Image.Image", lang: Optional[str], tesseract_config: Optional[str]):
+ """Applies Tesseract OCR on a document image, and returns recognized words + normalized bounding boxes."""
+ # apply OCR
+ data = pytesseract.image_to_data(image, lang=lang, output_type="dict", config=tesseract_config)
+ words, left, top, width, height = data["text"], data["left"], data["top"], data["width"], data["height"]
+
+ # filter empty words and corresponding coordinates
+ irrelevant_indices = [idx for idx, word in enumerate(words) if not word.strip()]
+ words = [word for idx, word in enumerate(words) if idx not in irrelevant_indices]
+ left = [coord for idx, coord in enumerate(left) if idx not in irrelevant_indices]
+ top = [coord for idx, coord in enumerate(top) if idx not in irrelevant_indices]
+ width = [coord for idx, coord in enumerate(width) if idx not in irrelevant_indices]
+ height = [coord for idx, coord in enumerate(height) if idx not in irrelevant_indices]
+
+ # turn coordinates into (left, top, left+width, top+height) format
+ actual_boxes = []
+ for x, y, w, h in zip(left, top, width, height):
+ actual_box = [x, y, x + w, y + h]
+ actual_boxes.append(actual_box)
+
+ image_width, image_height = image.size
+
+ # finally, normalize the bounding boxes
+ normalized_boxes = []
+ for box in actual_boxes:
+ normalized_boxes.append(normalize_box(box, image_width, image_height))
+
+ if len(words) != len(normalized_boxes):
+ raise ValueError("Not as many words as there are bounding boxes")
+
+ return words, normalized_boxes
+
+
+class ModelType(ExplicitEnum):
+ LayoutLM = "layoutlm"
+ LayoutLMv2andv3 = "layoutlmv2andv3"
+ VisionEncoderDecoder = "vision_encoder_decoder"
+
+
+@add_end_docstrings(build_pipeline_init_args(has_image_processor=True, has_tokenizer=True))
+class DocumentQuestionAnsweringPipeline(ChunkPipeline):
+ # TODO: Update task_summary docs to include an example with document QA and then update the first sentence
+ """
+ Document Question Answering pipeline using any `AutoModelForDocumentQuestionAnswering`. The inputs/outputs are
+ similar to the (extractive) question answering pipeline; however, the pipeline takes an image (and optional OCR'd
+ words/boxes) as input instead of text context.
+
+ Unless the model you're using explicitly sets these generation parameters in its configuration files
+ (`generation_config.json`), the following default values will be used:
+ - max_new_tokens: 256
+
+ Example:
+
+ ```python
+ >>> from transformers import pipeline
+
+ >>> document_qa = pipeline(model="impira/layoutlm-document-qa")
+ >>> document_qa(
+ ... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+ ... question="What is the invoice number?",
+ ... )
+ [{'score': 0.425, 'answer': 'us-001', 'start': 16, 'end': 16}]
+ ```
+
+ Learn more about the basics of using a pipeline in the [pipeline tutorial](../pipeline_tutorial)
+
+ This document question answering pipeline can currently be loaded from [`pipeline`] using the following task
+ identifier: `"document-question-answering"`.
+
+ The models that this pipeline can use are models that have been fine-tuned on a document question answering task.
+ See the up-to-date list of available models on
+ [huggingface.co/models](https://huggingface.co/models?filter=document-question-answering).
+ """
+
+ _pipeline_calls_generate = True
+ _load_processor = False
+ _load_image_processor = None
+ _load_feature_extractor = None
+ _load_tokenizer = True
+ # Make sure the docstring is updated when the default generation config is changed
+ _default_generation_config = GenerationConfig(
+ max_new_tokens=256,
+ )
+
+ def __init__(self, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+ if self.tokenizer is not None and not self.tokenizer.__class__.__name__.endswith("Fast"):
+ raise ValueError(
+ "`DocumentQuestionAnsweringPipeline` requires a fast tokenizer, but a slow tokenizer "
+ f"(`{self.tokenizer.__class__.__name__}`) is provided."
+ )
+
+ if self.model.config.__class__.__name__ == "VisionEncoderDecoderConfig":
+ self.model_type = ModelType.VisionEncoderDecoder
+ if self.model.config.encoder.model_type != "donut-swin":
+ raise ValueError("Currently, the only supported VisionEncoderDecoder model is Donut")
+ else:
+ self.check_model_type(MODEL_FOR_DOCUMENT_QUESTION_ANSWERING_MAPPING_NAMES)
+ if self.model.config.__class__.__name__ == "LayoutLMConfig":
+ self.model_type = ModelType.LayoutLM
+ else:
+ self.model_type = ModelType.LayoutLMv2andv3
+
+ def _sanitize_parameters(
+ self,
+ padding=None,
+ doc_stride=None,
+ max_question_len=None,
+ lang: Optional[str] = None,
+ tesseract_config: Optional[str] = None,
+ max_answer_len=None,
+ max_seq_len=None,
+ top_k=None,
+ handle_impossible_answer=None,
+ timeout=None,
+ **kwargs,
+ ):
+ preprocess_params, postprocess_params = {}, {}
+ if padding is not None:
+ preprocess_params["padding"] = padding
+ if doc_stride is not None:
+ preprocess_params["doc_stride"] = doc_stride
+ if max_question_len is not None:
+ preprocess_params["max_question_len"] = max_question_len
+ if max_seq_len is not None:
+ preprocess_params["max_seq_len"] = max_seq_len
+ if lang is not None:
+ preprocess_params["lang"] = lang
+ if tesseract_config is not None:
+ preprocess_params["tesseract_config"] = tesseract_config
+ if timeout is not None:
+ preprocess_params["timeout"] = timeout
+
+ if top_k is not None:
+ if top_k < 1:
+ raise ValueError(f"top_k parameter should be >= 1 (got {top_k})")
+ postprocess_params["top_k"] = top_k
+ if max_answer_len is not None:
+ if max_answer_len < 1:
+ raise ValueError(f"max_answer_len parameter should be >= 1 (got {max_answer_len}")
+ postprocess_params["max_answer_len"] = max_answer_len
+ if handle_impossible_answer is not None:
+ postprocess_params["handle_impossible_answer"] = handle_impossible_answer
+
+ forward_params = {}
+ if getattr(self, "assistant_model", None) is not None:
+ forward_params["assistant_model"] = self.assistant_model
+ if getattr(self, "assistant_tokenizer", None) is not None:
+ forward_params["tokenizer"] = self.tokenizer
+ forward_params["assistant_tokenizer"] = self.assistant_tokenizer
+
+ return preprocess_params, forward_params, postprocess_params
+
+ @overload
+ def __call__(
+ self,
+ image: Union["Image.Image", str],
+ question: str,
+ word_boxes: Optional[tuple[str, list[float]]] = None,
+ **kwargs: Any,
+ ) -> list[dict[str, Any]]: ...
+
+ @overload
+ def __call__(self, image: dict[str, Any], **kwargs: Any) -> list[dict[str, Any]]: ...
+
+ @overload
+ def __call__(self, image: list[dict[str, Any]], **kwargs: Any) -> list[list[dict[str, Any]]]: ...
+
+ def __call__(
+ self,
+ image: Union["Image.Image", str, list[dict[str, Any]]],
+ question: Optional[str] = None,
+ word_boxes: Optional[tuple[str, list[float]]] = None,
+ **kwargs: Any,
+ ) -> Union[dict[str, Any], list[dict[str, Any]]]:
+ """
+ Answer the question(s) given as inputs by using the document(s). A document is defined as an image and an
+ optional list of (word, box) tuples which represent the text in the document. If the `word_boxes` are not
+ provided, it will use the Tesseract OCR engine (if available) to extract the words and boxes automatically for
+ LayoutLM-like models which require them as input. For Donut, no OCR is run.
+
+ You can invoke the pipeline several ways:
+
+ - `pipeline(image=image, question=question)`
+ - `pipeline(image=image, question=question, word_boxes=word_boxes)`
+ - `pipeline([{"image": image, "question": question}])`
+ - `pipeline([{"image": image, "question": question, "word_boxes": word_boxes}])`
+
+ Args:
+ image (`str` or `PIL.Image`):
+ The pipeline handles three types of images:
+
+ - A string containing a http link pointing to an image
+ - A string containing a local path to an image
+ - An image loaded in PIL directly
+
+ The pipeline accepts either a single image or a batch of images. If given a single image, it can be
+ broadcasted to multiple questions.
+ question (`str`):
+ A question to ask of the document.
+ word_boxes (`list[str, tuple[float, float, float, float]]`, *optional*):
+ A list of words and bounding boxes (normalized 0->1000). If you provide this optional input, then the
+ pipeline will use these words and boxes instead of running OCR on the image to derive them for models
+ that need them (e.g. LayoutLM). This allows you to reuse OCR'd results across many invocations of the
+ pipeline without having to re-run it each time.
+ top_k (`int`, *optional*, defaults to 1):
+ The number of answers to return (will be chosen by order of likelihood). Note that we return less than
+ top_k answers if there are not enough options available within the context.
+ doc_stride (`int`, *optional*, defaults to 128):
+ If the words in the document are too long to fit with the question for the model, it will be split in
+ several chunks with some overlap. This argument controls the size of that overlap.
+ max_answer_len (`int`, *optional*, defaults to 15):
+ The maximum length of predicted answers (e.g., only answers with a shorter length are considered).
+ max_seq_len (`int`, *optional*, defaults to 384):
+ The maximum length of the total sentence (context + question) in tokens of each chunk passed to the
+ model. The context will be split in several chunks (using `doc_stride` as overlap) if needed.
+ max_question_len (`int`, *optional*, defaults to 64):
+ The maximum length of the question after tokenization. It will be truncated if needed.
+ handle_impossible_answer (`bool`, *optional*, defaults to `False`):
+ Whether or not we accept impossible as an answer.
+ lang (`str`, *optional*):
+ Language to use while running OCR. Defaults to english.
+ tesseract_config (`str`, *optional*):
+ Additional flags to pass to tesseract while running OCR.
+ timeout (`float`, *optional*, defaults to None):
+ The maximum time in seconds to wait for fetching images from the web. If None, no timeout is set and
+ the call may block forever.
+
+ Return:
+ A `dict` or a list of `dict`: Each result comes as a dictionary with the following keys:
+
+ - **score** (`float`) -- The probability associated to the answer.
+ - **start** (`int`) -- The start word index of the answer (in the OCR'd version of the input or provided
+ `word_boxes`).
+ - **end** (`int`) -- The end word index of the answer (in the OCR'd version of the input or provided
+ `word_boxes`).
+ - **answer** (`str`) -- The answer to the question.
+ - **words** (`list[int]`) -- The index of each word/box pair that is in the answer
+ """
+ if isinstance(question, str):
+ inputs = {"question": question, "image": image}
+ if word_boxes is not None:
+ inputs["word_boxes"] = word_boxes
+ else:
+ inputs = image
+ return super().__call__(inputs, **kwargs)
+
+ def preprocess(
+ self,
+ input,
+ padding="do_not_pad",
+ doc_stride=None,
+ max_seq_len=None,
+ word_boxes: Optional[tuple[str, list[float]]] = None,
+ lang=None,
+ tesseract_config="",
+ timeout=None,
+ ):
+ # NOTE: This code mirrors the code in question answering and will be implemented in a follow up PR
+ # to support documents with enough tokens that overflow the model's window
+ if max_seq_len is None:
+ max_seq_len = self.tokenizer.model_max_length
+
+ if doc_stride is None:
+ doc_stride = min(max_seq_len // 2, 256)
+
+ image = None
+ image_features = {}
+ if input.get("image", None) is not None:
+ image = load_image(input["image"], timeout=timeout)
+ if self.image_processor is not None:
+ image_inputs = self.image_processor(images=image, return_tensors=self.framework)
+ if self.framework == "pt":
+ image_inputs = image_inputs.to(self.dtype)
+ image_features.update(image_inputs)
+ elif self.feature_extractor is not None:
+ image_features.update(self.feature_extractor(images=image, return_tensors=self.framework))
+ elif self.model_type == ModelType.VisionEncoderDecoder:
+ raise ValueError("If you are using a VisionEncoderDecoderModel, you must provide a feature extractor")
+
+ words, boxes = None, None
+ if self.model_type != ModelType.VisionEncoderDecoder:
+ if "word_boxes" in input:
+ words = [x[0] for x in input["word_boxes"]]
+ boxes = [x[1] for x in input["word_boxes"]]
+ elif "words" in image_features and "boxes" in image_features:
+ words = image_features.pop("words")[0]
+ boxes = image_features.pop("boxes")[0]
+ elif image is not None:
+ if not TESSERACT_LOADED:
+ raise ValueError(
+ "If you provide an image without word_boxes, then the pipeline will run OCR using Tesseract,"
+ " but pytesseract is not available"
+ )
+ if TESSERACT_LOADED:
+ words, boxes = apply_tesseract(image, lang=lang, tesseract_config=tesseract_config)
+ else:
+ raise ValueError(
+ "You must provide an image or word_boxes. If you provide an image, the pipeline will automatically"
+ " run OCR to derive words and boxes"
+ )
+
+ if self.tokenizer.padding_side != "right":
+ raise ValueError(
+ "Document question answering only supports tokenizers whose padding side is 'right', not"
+ f" {self.tokenizer.padding_side}"
+ )
+
+ if self.model_type == ModelType.VisionEncoderDecoder:
+ task_prompt = f"{input['question']} "
+ # Adapted from https://huggingface.co/spaces/nielsr/donut-docvqa/blob/main/app.py
+ encoding = {
+ "inputs": image_features["pixel_values"],
+ "decoder_input_ids": self.tokenizer(
+ task_prompt, add_special_tokens=False, return_tensors=self.framework
+ ).input_ids,
+ "return_dict_in_generate": True,
+ }
+ yield {
+ **encoding,
+ "p_mask": None,
+ "word_ids": None,
+ "words": None,
+ "output_attentions": True,
+ "is_last": True,
+ }
+ else:
+ tokenizer_kwargs = {}
+ if self.model_type == ModelType.LayoutLM:
+ tokenizer_kwargs["text"] = input["question"].split()
+ tokenizer_kwargs["text_pair"] = words
+ tokenizer_kwargs["is_split_into_words"] = True
+ else:
+ tokenizer_kwargs["text"] = [input["question"]]
+ tokenizer_kwargs["text_pair"] = [words]
+ tokenizer_kwargs["boxes"] = [boxes]
+
+ encoding = self.tokenizer(
+ padding=padding,
+ max_length=max_seq_len,
+ stride=doc_stride,
+ return_token_type_ids=True,
+ truncation="only_second",
+ return_overflowing_tokens=True,
+ **tokenizer_kwargs,
+ )
+ # TODO: check why slower `LayoutLMTokenizer` and `LayoutLMv2Tokenizer` don't have this key in outputs
+ # FIXME: ydshieh and/or Narsil
+ encoding.pop("overflow_to_sample_mapping", None) # We do not use this
+
+ num_spans = len(encoding["input_ids"])
+
+ # p_mask: mask with 1 for token than cannot be in the answer (0 for token which can be in an answer)
+ # We put 0 on the tokens from the context and 1 everywhere else (question and special tokens)
+ # This logic mirrors the logic in the question_answering pipeline
+ p_mask = [[tok != 1 for tok in encoding.sequence_ids(span_id)] for span_id in range(num_spans)]
+ for span_idx in range(num_spans):
+ if self.framework == "pt":
+ span_encoding = {k: torch.tensor(v[span_idx : span_idx + 1]) for (k, v) in encoding.items()}
+ if "pixel_values" in image_features:
+ span_encoding["image"] = image_features["pixel_values"]
+ else:
+ raise ValueError("Unsupported: Tensorflow preprocessing for DocumentQuestionAnsweringPipeline")
+
+ input_ids_span_idx = encoding["input_ids"][span_idx]
+ # keep the cls_token unmasked (some models use it to indicate unanswerable questions)
+ if self.tokenizer.cls_token_id is not None:
+ cls_indices = np.nonzero(np.array(input_ids_span_idx) == self.tokenizer.cls_token_id)[0]
+ for cls_index in cls_indices:
+ p_mask[span_idx][cls_index] = 0
+
+ # For each span, place a bounding box [0,0,0,0] for question and CLS tokens, [1000,1000,1000,1000]
+ # for SEP tokens, and the word's bounding box for words in the original document.
+ if "boxes" not in tokenizer_kwargs:
+ bbox = []
+ for input_id, sequence_id, word_id in zip(
+ encoding.input_ids[span_idx],
+ encoding.sequence_ids(span_idx),
+ encoding.word_ids(span_idx),
+ ):
+ if sequence_id == 1:
+ bbox.append(boxes[word_id])
+ elif input_id == self.tokenizer.sep_token_id:
+ bbox.append([1000] * 4)
+ else:
+ bbox.append([0] * 4)
+
+ if self.framework == "pt":
+ span_encoding["bbox"] = torch.tensor(bbox).unsqueeze(0)
+ elif self.framework == "tf":
+ raise ValueError("Unsupported: Tensorflow preprocessing for DocumentQuestionAnsweringPipeline")
+ yield {
+ **span_encoding,
+ "p_mask": p_mask[span_idx],
+ "word_ids": encoding.word_ids(span_idx),
+ "words": words,
+ "is_last": span_idx == num_spans - 1,
+ }
+
+ def _forward(self, model_inputs, **generate_kwargs):
+ p_mask = model_inputs.pop("p_mask", None)
+ word_ids = model_inputs.pop("word_ids", None)
+ words = model_inputs.pop("words", None)
+ is_last = model_inputs.pop("is_last", False)
+
+ if self.model_type == ModelType.VisionEncoderDecoder:
+ # User-defined `generation_config` passed to the pipeline call take precedence
+ if "generation_config" not in generate_kwargs:
+ generate_kwargs["generation_config"] = self.generation_config
+
+ model_outputs = self.model.generate(**model_inputs, **generate_kwargs)
+ else:
+ model_outputs = self.model(**model_inputs)
+
+ model_outputs = dict(model_outputs.items())
+ model_outputs["p_mask"] = p_mask
+ model_outputs["word_ids"] = word_ids
+ model_outputs["words"] = words
+ model_outputs["attention_mask"] = model_inputs.get("attention_mask", None)
+ model_outputs["is_last"] = is_last
+ return model_outputs
+
+ def postprocess(self, model_outputs, top_k=1, **kwargs):
+ if self.model_type == ModelType.VisionEncoderDecoder:
+ answers = [self.postprocess_encoder_decoder_single(o) for o in model_outputs]
+ else:
+ answers = self.postprocess_extractive_qa(model_outputs, top_k=top_k, **kwargs)
+
+ answers = sorted(answers, key=lambda x: x.get("score", 0), reverse=True)[:top_k]
+ return answers
+
+ def postprocess_encoder_decoder_single(self, model_outputs, **kwargs):
+ sequence = self.tokenizer.batch_decode(model_outputs["sequences"])[0]
+
+ # TODO: A lot of this logic is specific to Donut and should probably be handled in the tokenizer
+ # (see https://github.com/huggingface/transformers/pull/18414/files#r961747408 for more context).
+ sequence = sequence.replace(self.tokenizer.eos_token, "").replace(self.tokenizer.pad_token, "")
+ sequence = re.sub(r"<.*?>", "", sequence, count=1).strip() # remove first task start token
+ ret = {
+ "answer": None,
+ }
+
+ answer = re.search(r"  +

 +
 +
 +
 +
 +
 +
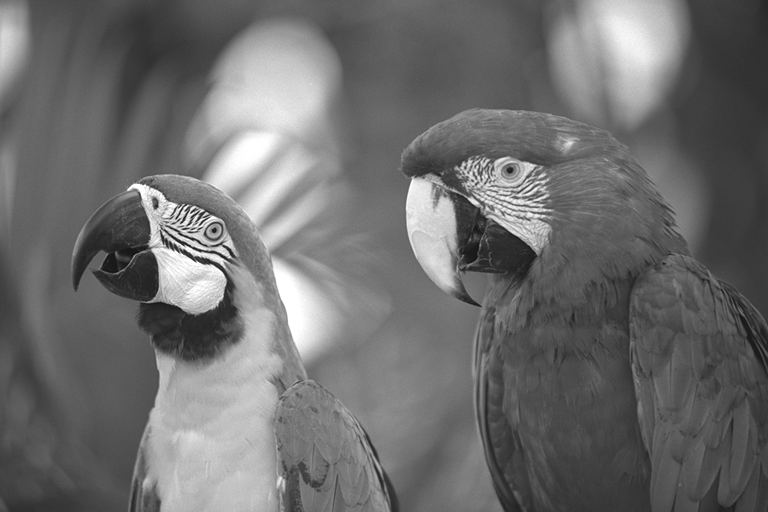 +
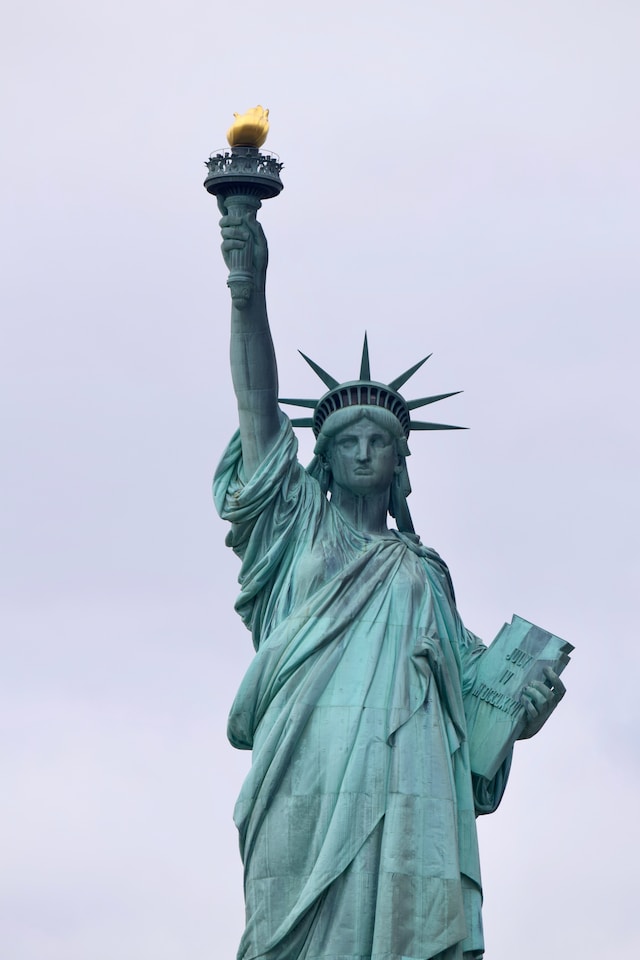 +